
Feature Selection Using Nearest Neighbor Gaussian Processes
 , , ,
 and

Abstract
1. Introduction
2. Related Work
3. Methodology
3.1. Nearest Neighbor Gaussian Process
3.2. Reference Prior
3.3. Feature Selection Model
3.3.1. Likelihood Function
3.3.2. Reference Prior
3.3.3. Prior for the Random Set
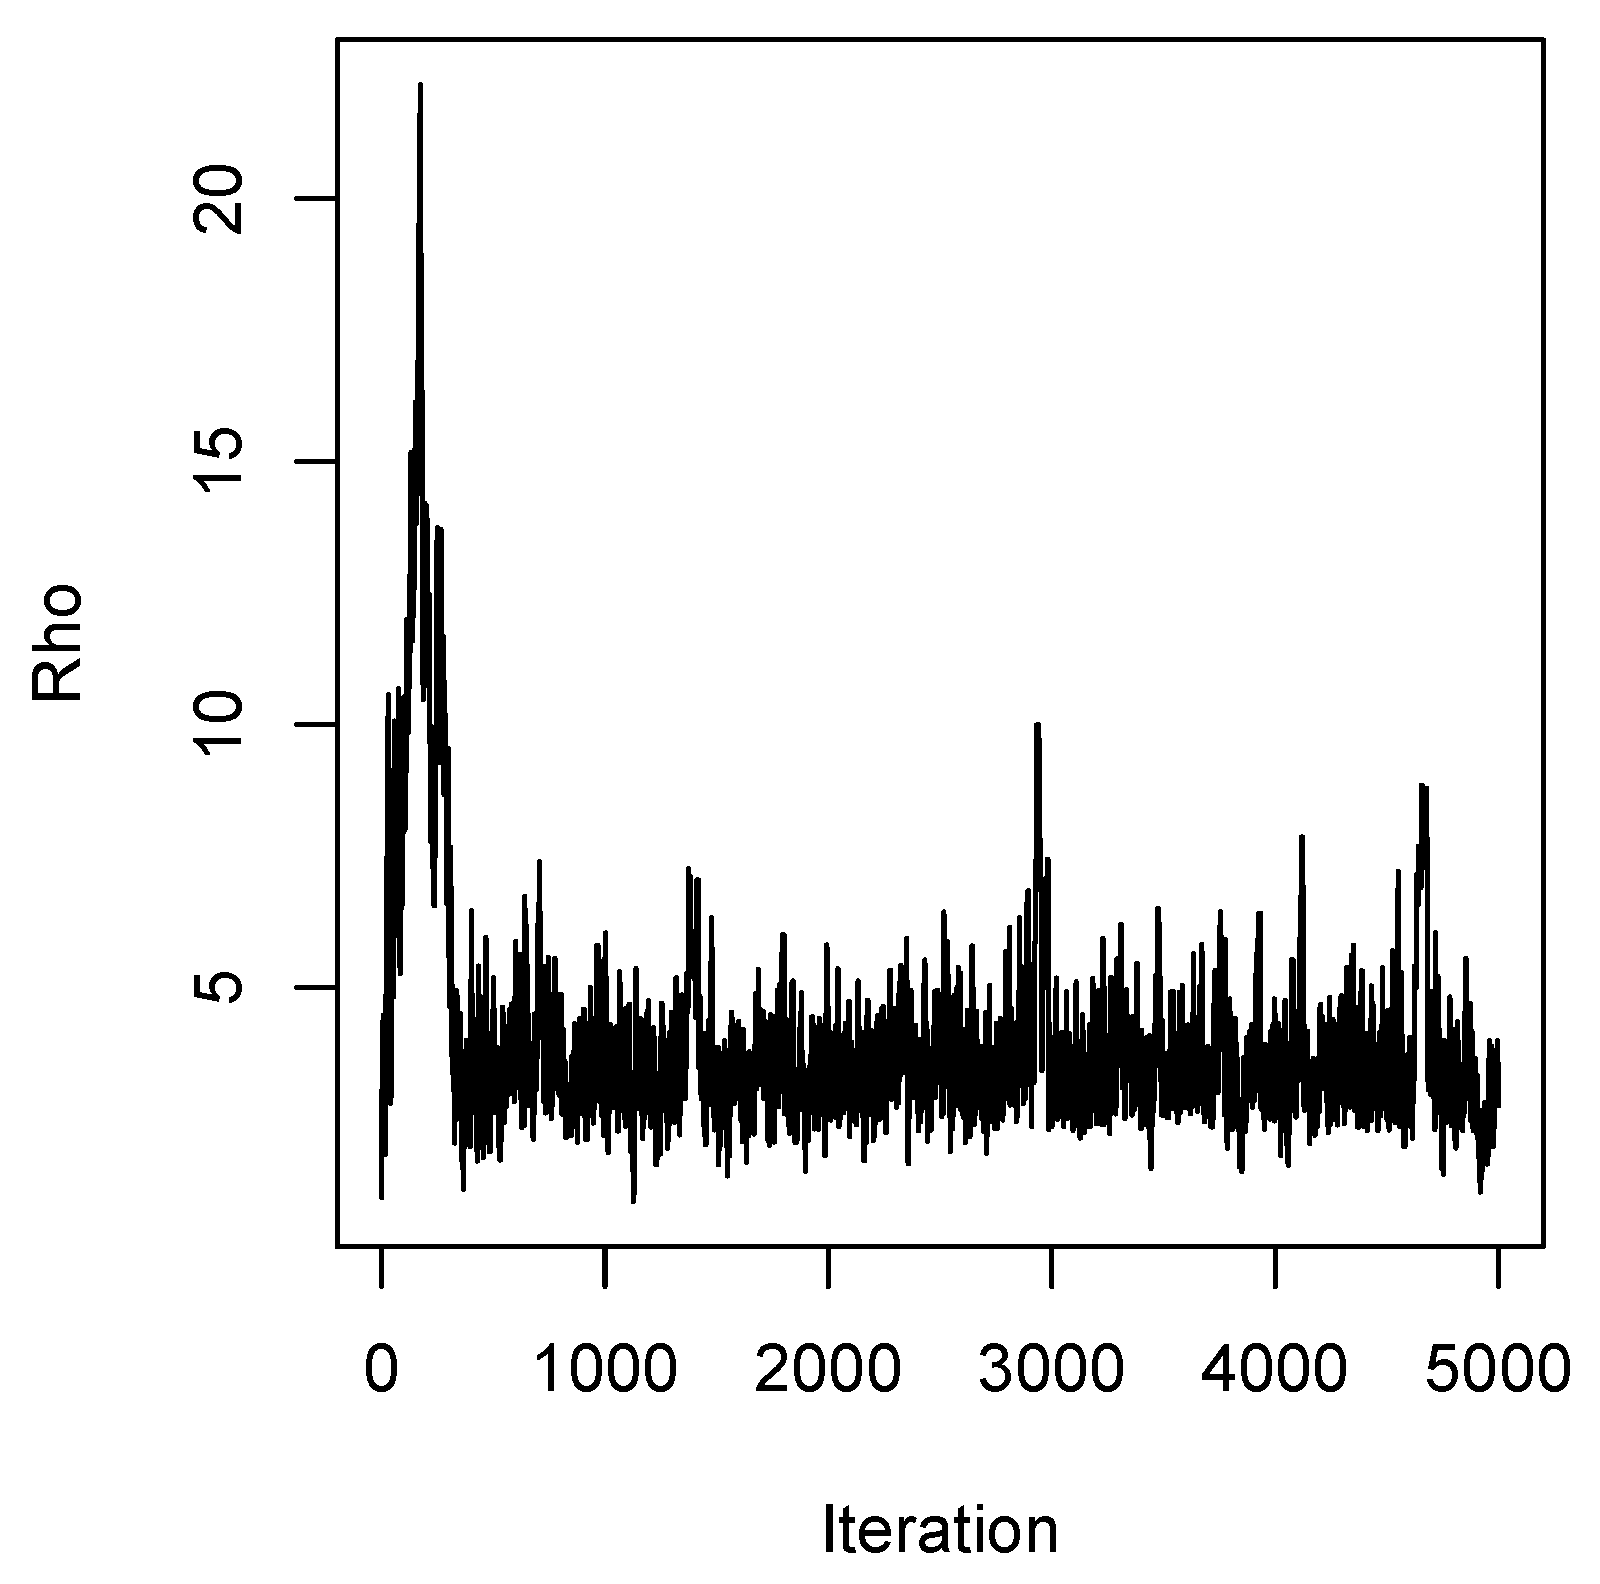
3.4. Model Inference
- Step 1: Sample from the conditional posterior using a classical Metropolis–Hastings (MH) algorithm;
- Step 2: Sample from the conditional posterior ;
- Step 3: Sample from the conditional posterior using Hamiltonian MCMC (HMC).
3.4.1. Step 1
3.4.2. Step 2
3.4.3. Step 3
- 1.
- Draw a sample from .
- 2.
- Use the leapfrog method to simulate .
- (a)
- Set .
- (b)
- For
- i.
- ;
- ii.
- ;
- iii.
- .
- 3.
- Calculate the Hastings ratio .
- 4.
- With probability set . Otherwise, set .
3.5. Prediction
4. Evaluation
- Lasso. The least absolute shrinkage and selection operator (Lasso) [8] penalizes the absolute values of the regression coefficients in a classical linear model to obtain a sparse solution. The method is implemented using the glmnet R package (v4.1-10) [48]. Cross-validation is employed to determine the penalization strength.
- Adaptive Lasso (ALasso). The adaptive Lasso [11] extends the classical Lasso by allowing coefficient-specific penalization strengths. In this study, the individual penalization factors are defined by multiplying a global tuning parameter by the inverse of the absolute values of the regression coefficients obtained from a ridge-penalized model. The glmnet package is again used for implementation.
- Robust Gaussian Process (RGP). The RobustGaSP R package (v0.6.8) [51] implements robust Gaussian process regression models using reference priors and separable (anisotropic) covariance functions. We employ the default settings (e.g., a Matérn kernel), except that we force the method to estimate a nugget term. Note that GP models with anisotropic kernels allow for automatic relevance determination [7]; therefore, predictors are scaled prior to model inference.
- Bayesian Adaptive Sampling (BAS). The BAS R package (v2.0.2) implements Bayesian variable selection for linear models using Zellner’s g-prior or mixtures of g-priors, including the Zellner–Siow Cauchy prior and the mixture of g-priors proposed by Liang et al. [52].
- Variational Inference for Bayesian Variable Selection (VARBVS). The varbvs R package (v2.6-10) applies variational approximations originally developed for genetic association studies. Carbonetto and Stephens [53] demonstrate that this approach can yield posterior inferences that closely match exact values in certain settings.
- Bayesian Additive Regression Trees (BART). The BART R package (v2.9.10) [54] implements a Bayesian nonparametric, machine learning, ensemble predictive modeling method. It is a tree-based method that fits the outcome to an arbitrary random function of the covariates.
- Bayesian Additive Regression Trees Approach using Gaussian Processes (GP-BART). Standard BART models may perform poorly in settings where smoothness assumptions or explicit covariance structures are required. To address this limitation, Maia et al. [55] propose an extension of BART that assumes Gaussian process priors for the predictions at the terminal nodes of each tree.
4.1. Pepelyshev Function
4.2. Sine Function
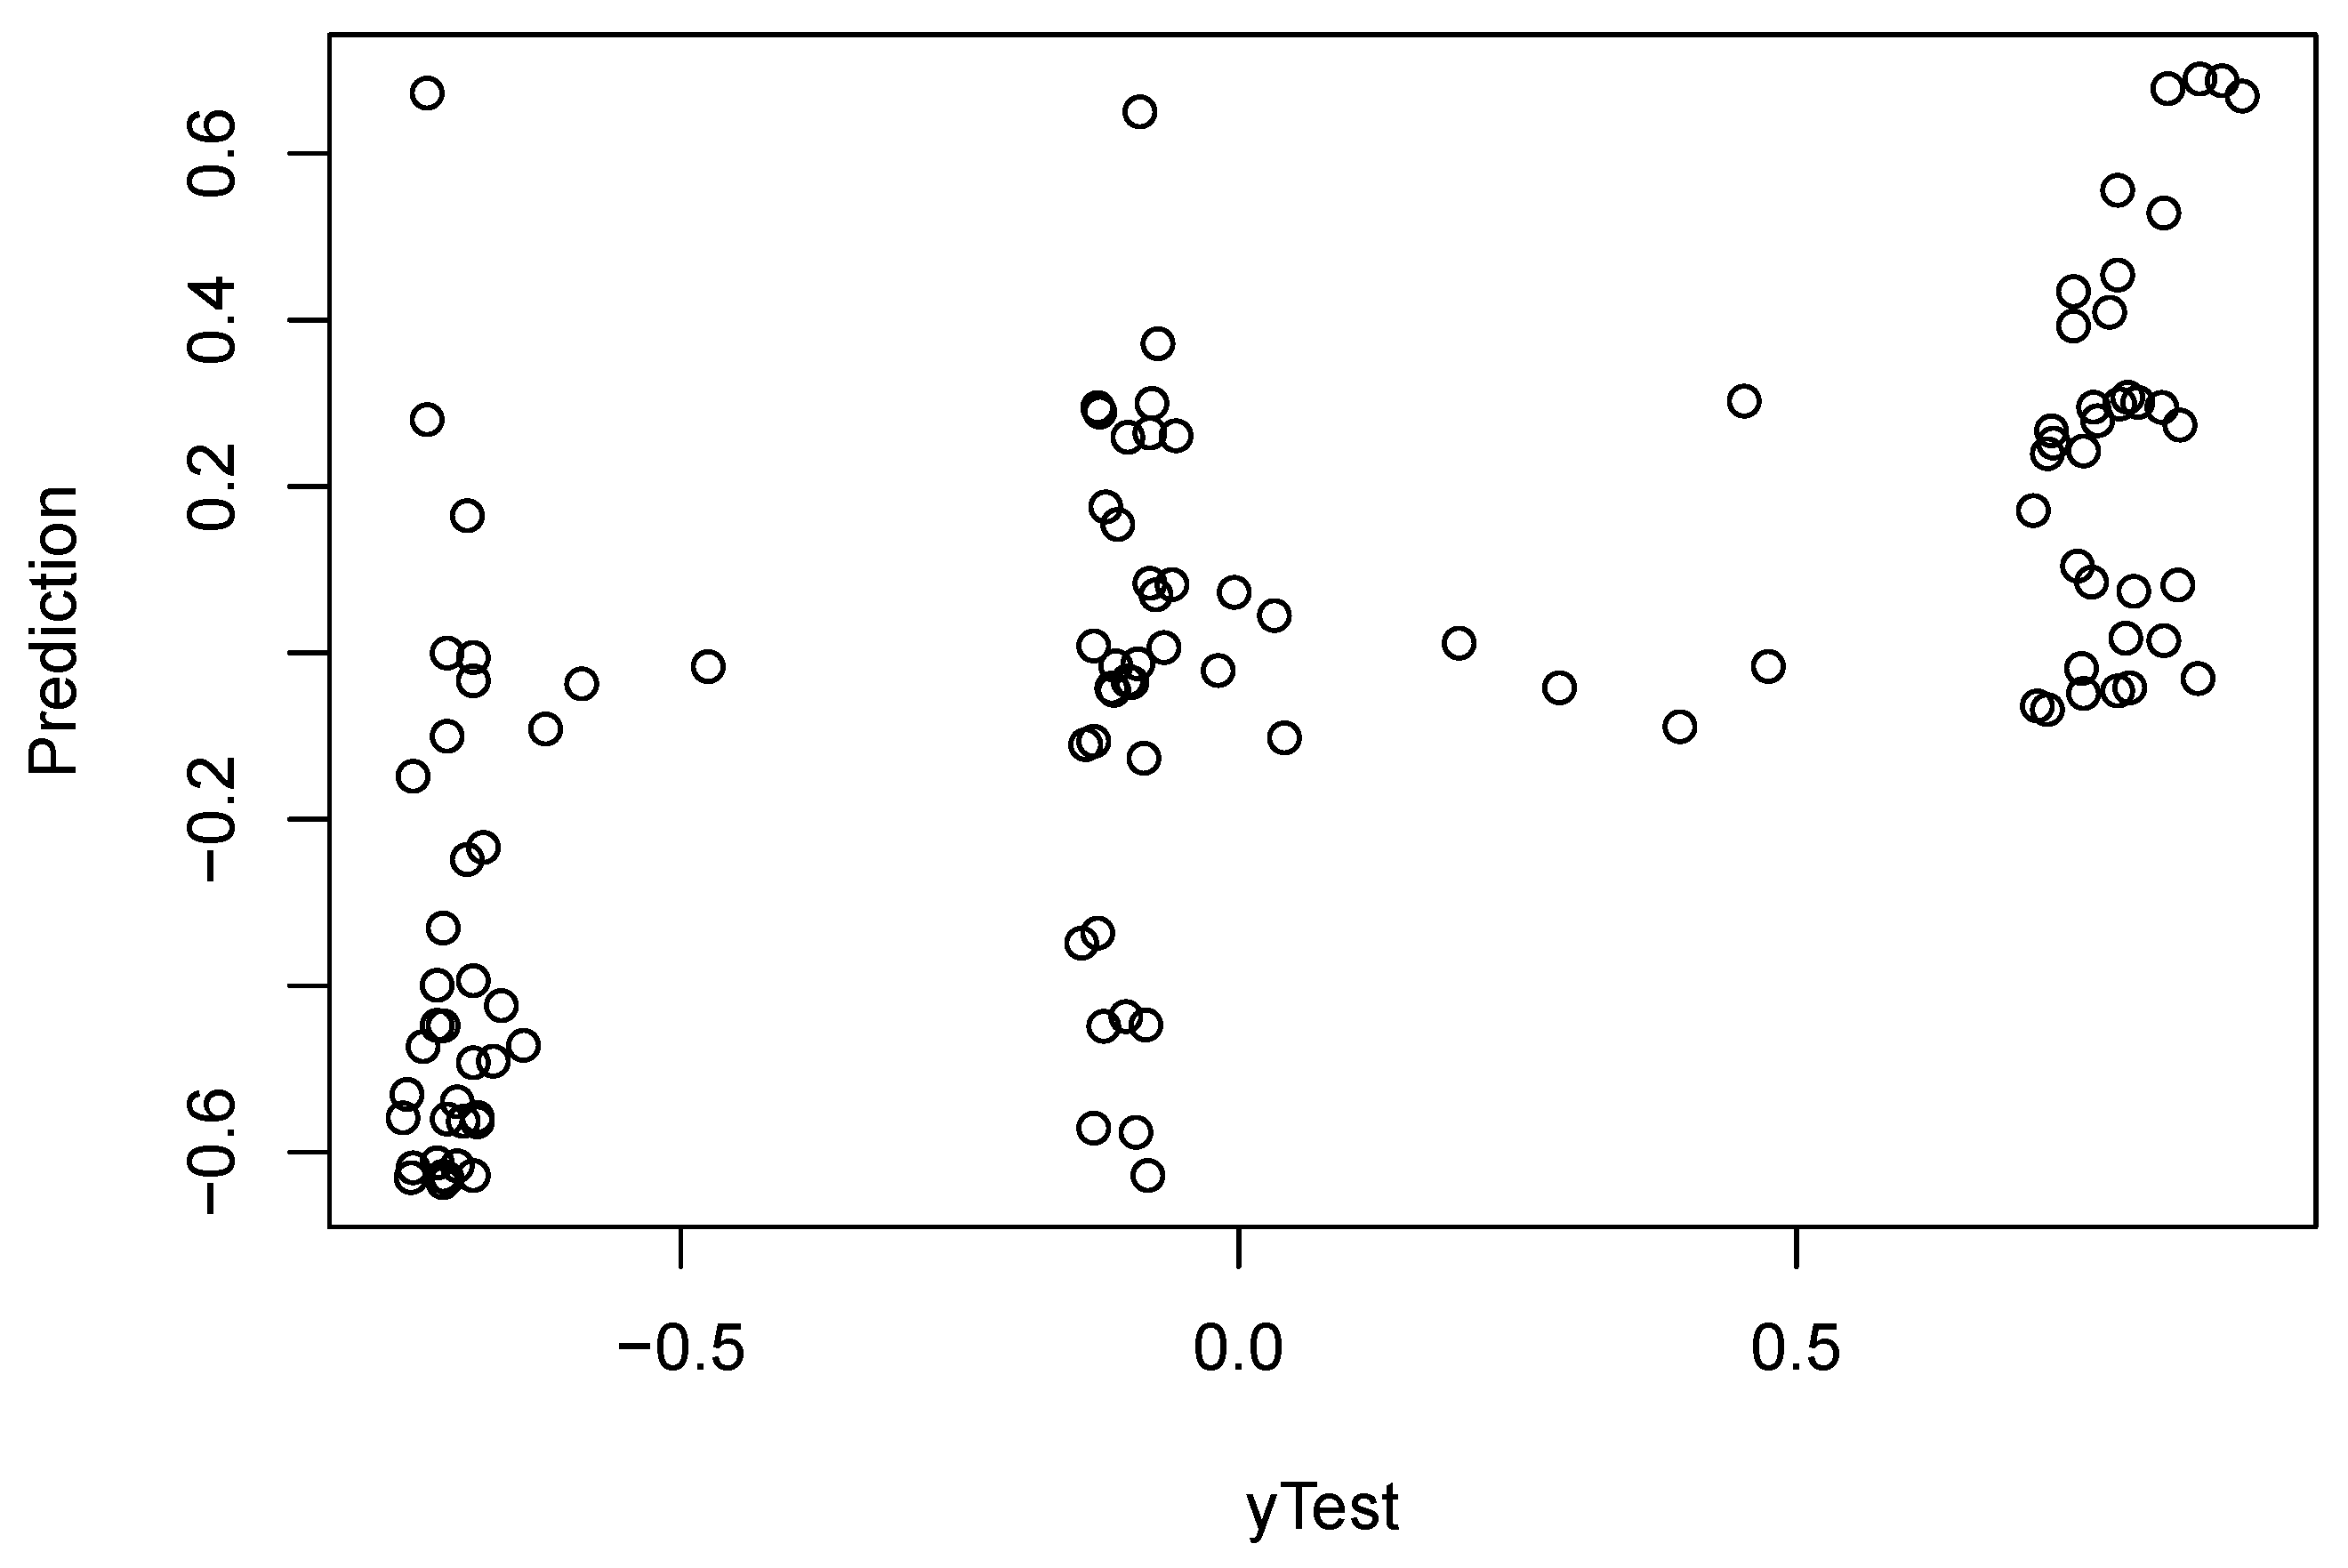
4.3. Body Fat Data Set
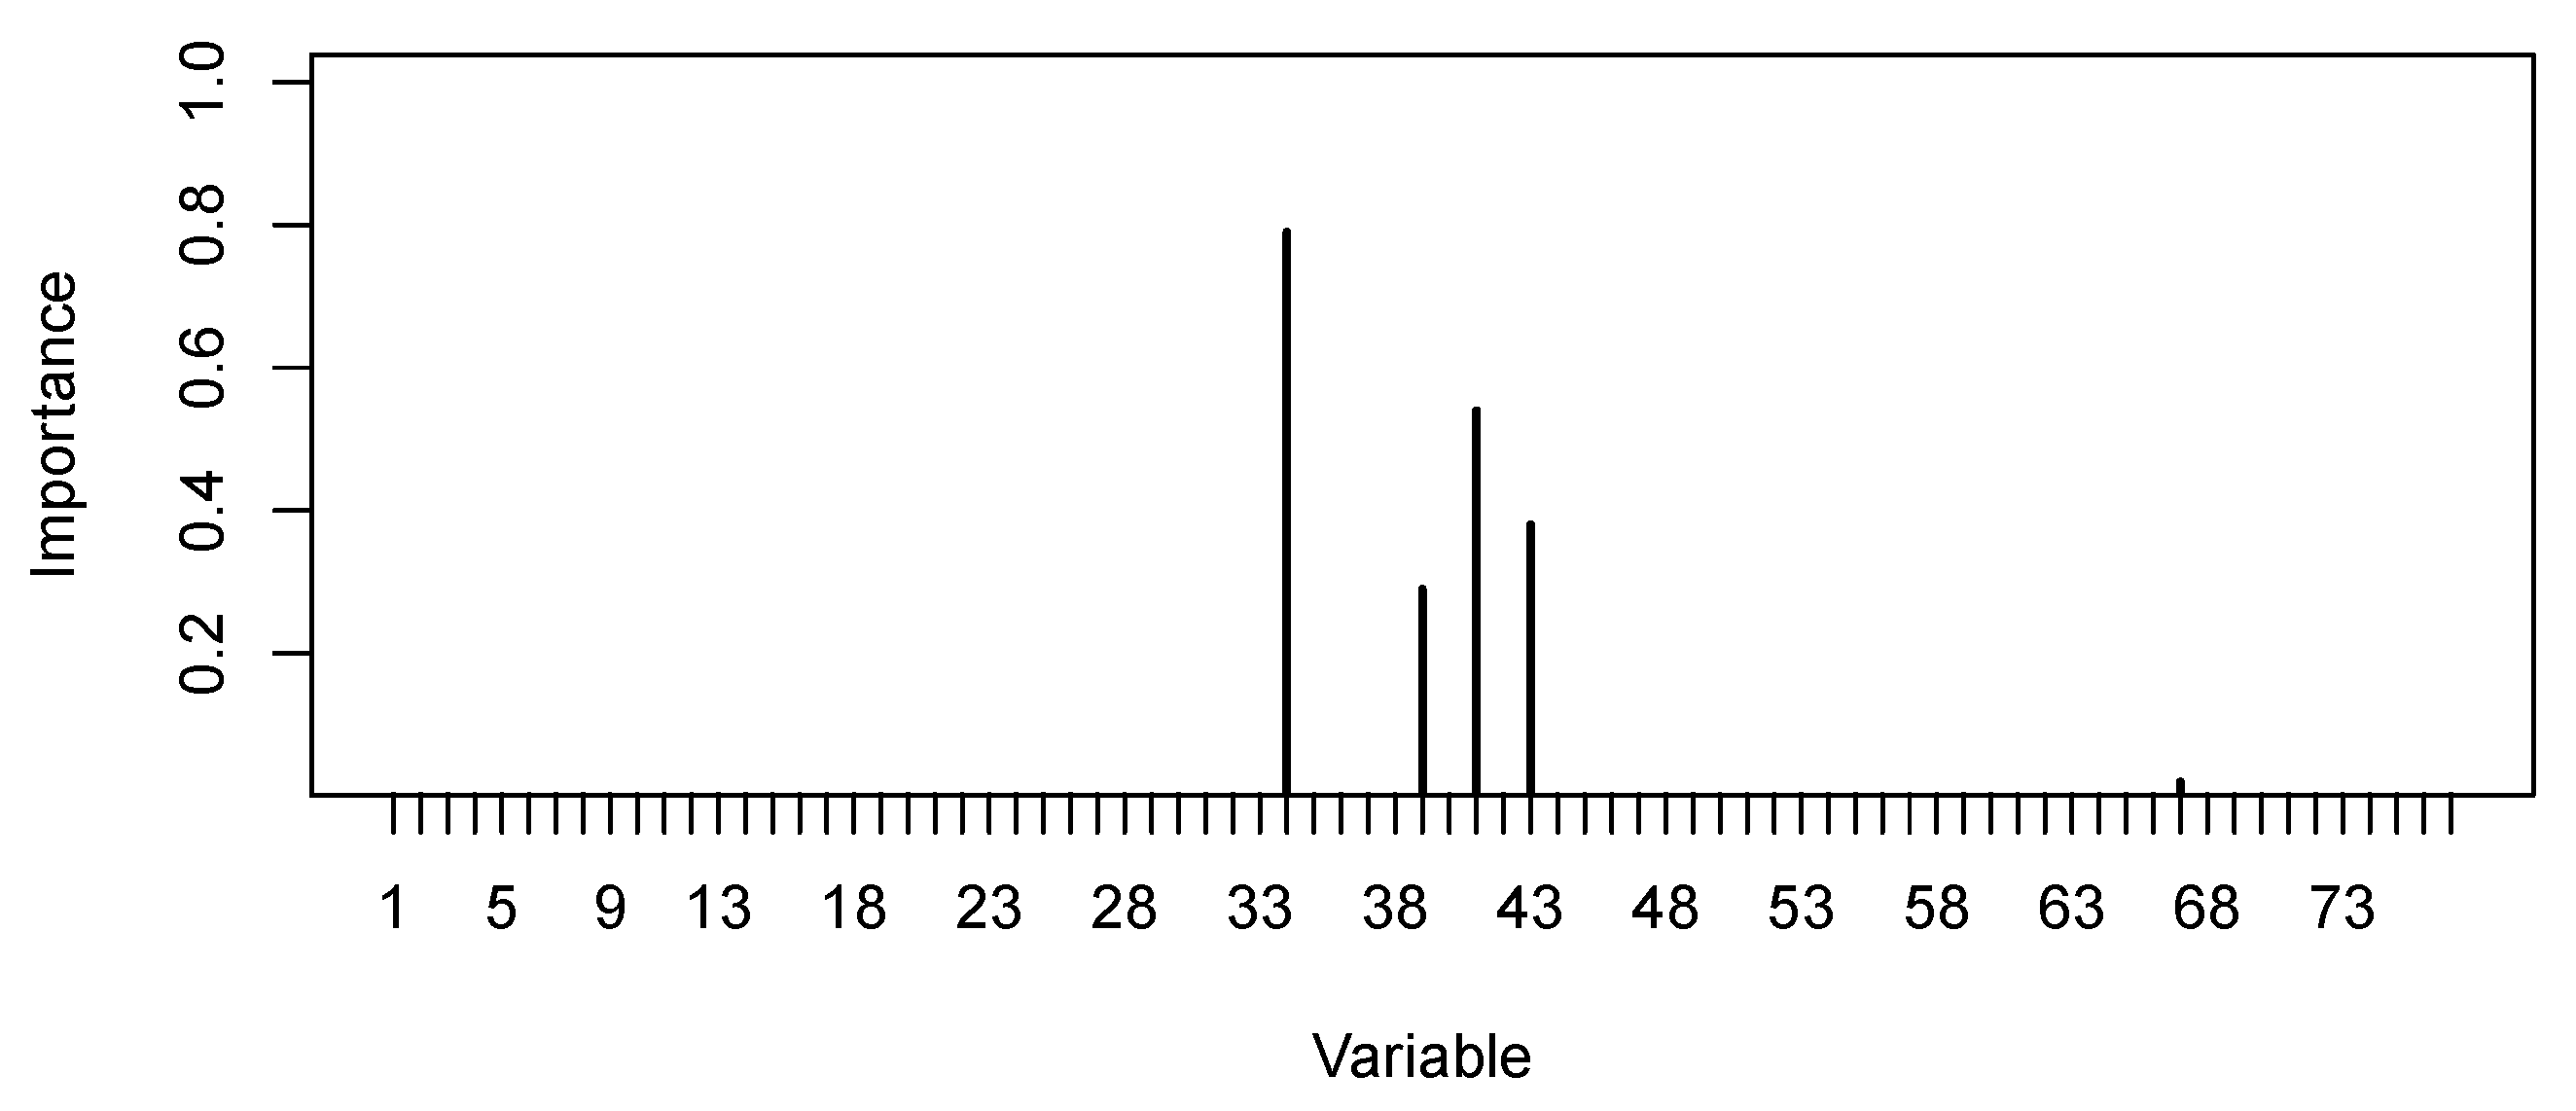
4.4. Semiconductor Frontend Manufacturing Data
5. Conclusions
Author Contributions
Funding
Data Availability Statement
Acknowledgments
Conflicts of Interest
Appendix A

| Symbol | Type | Description |
|---|---|---|
| n | scalar | Number of training observations. |
| d | scalar | Number of predictors (covariate dimension). |
| vector | Covariate vectors in . | |
| scalar | Response at location . | |
| vector | Training responses . | |
| S | set | Training input locations . |
| matrix | Design matrix . | |
| set | Random subset of active predictor indices, . | |
| k | scalar | Model size, . |
| matrix | Design matrix restricted to predictors in . | |
| vector | Linear regression coefficients. | |
| function | Latent nonlinear regression function. | |
| z | GP | Latent process . |
| function | Parent GP covariance function. | |
| function | NNGP covariance induced by neighbor factorization. | |
| function | Matérn- correlation using predictors in . | |
| scalar | Euclidean distance restricted to predictors in . | |
| scalar | Total process variance. | |
| scalar | Range (length-scale) parameter. | |
| scalar | Signal-to-noise ratio parameter. | |
| m | scalar | Maximum number of nearest neighbors in the NNGP. |
| set | Neighbor set of with . | |
| matrix | NNGP covariance matrix on S. | |
| matrix | Scaled NNGP correlation matrix with . | |
| function | Likelihood function. | |
| function | Integrated likelihood (with integrated out). | |
| density | Reference prior distribution. | |
| vector | Responses at test inputs . | |
| vector | Posterior mean prediction. |
Appendix B
References
- Buehlmann, P.; Drineas, P.; Kane, M.; van der Laan, M. Handbook of Big Data, 1st ed.; Chapman & Hall/CRC: Boca Raton, FL, USA, 2016. [Google Scholar]
- Lee, K.E.; Sha, N.; Dougherty, E.R.; Vannucci, M.; Mallick, B.K. Gene selection: A Bayesian variable selection approach. Bioinformatics 2003, 19, 90–97. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zheng, H.; Zhang, Y. Feature selection for high dimensional data in astronomy. Adv. Space Res. 2007, 41, 1960–1964. [Google Scholar] [CrossRef] [Scilit]
- Foster, D.P.; Stine, R.A. Variable Selection in Data Mining: Building a Predictive Model for Bankruptcy. J. Am. Stat. Assoc. 2004, 99, 303–313. [Google Scholar] [CrossRef] [Scilit]
- Duane, S.; Kennedy, A.; Pendleton, B.J.; Roweth, D. Hybrid Monte Carlo. Phys. Lett. B 1987, 195, 216–222. [Google Scholar] [CrossRef] [Scilit]
- Neal, R.M. Monte Carlo Implementation of Gaussian Process Models for Bayesian Regression and Classification. arXiv 1997, arXiv:physics/9701026. [Google Scholar] [CrossRef] [Scilit]
- Rasmussen, C.E.; Williams, C.K.I. Gaussian Processes for Machine Learning; MIT Press: Cambridge, MA, USA, 2005. [Google Scholar]
- Tibshirani, R. Regression Shrinkage and Selection via the Lasso. J. R. Stat. Soc. Ser. B (Methodol.) 1996, 58, 267–288. [Google Scholar] [CrossRef] [Scilit]
- Fan, J.; Li, R. Variable Selection via Nonconcave Penalized Likelihood and Its Oracle Properties. J. Am. Stat. Assoc. 2001, 96, 1348–1360. [Google Scholar] [CrossRef] [Scilit]
- Zou, H.; Hastie, T. Regularization and variable selection via the elastic net. J. R. Stat. Soc. Ser. B (Stat. Methodol.) 2005, 67, 301–320. [Google Scholar] [CrossRef] [Scilit]
- Zou, H. The Adaptive Lasso and Its Oracle Properties. J. Am. Stat. Assoc. 2006, 101, 1418–1429. [Google Scholar] [CrossRef] [Scilit]
- Park, T.; Casella, G. The Bayesian Lasso. J. Am. Stat. Assoc. 2008, 103, 681–686. [Google Scholar] [CrossRef] [Scilit]
- Ročková, V.; George, E.I. EMVS: The EM Approach to Bayesian Variable Selection. J. Am. Stat. Assoc. 2014, 109, 828–846. [Google Scholar] [CrossRef] [Scilit]
- Alhamzawi, R.; Taha Mohammad Ali, H. The Bayesian adaptive Lasso regression. Math. Biosci. 2018, 303, 75–82. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Posch, K.; Arbeiter, M.; Pilz, J. A novel Bayesian approach for variable selection in linear regression models. Comput. Stat. Data Anal. 2020, 144, 106881. [Google Scholar] [CrossRef] [Scilit]
- Bhattacharya, A.; Pati, D.; Pillai, N.S.; Dunson, D.B. Dirichlet–Laplace Priors for Optimal Shrinkage. J. Am. Stat. Assoc. 2015, 110, 1479–1490. [Google Scholar] [CrossRef] [Scilit]
- Bhadra, A.; Datta, J.; Polson, N.G.; Willard, B. The Horseshoe+ Estimator of Ultra-Sparse Signals. Bayesian Anal. 2017, 12, 1105–1131. [Google Scholar] [CrossRef] [Scilit]
- Chen, S.; Walker, S.G. Fast Bayesian variable selection for high dimensional linear models: Marginal solo spike and slab priors. Electron. J. Stat. 2019, 13, 284–309. [Google Scholar] [CrossRef] [Scilit]
- O’Hagan, A. Curve Fitting and Optimal Design for Prediction. J. R. Stat. Soc. Ser. B (Methodol.) 1978, 40, 1–42. [Google Scholar] [CrossRef] [Scilit]
- Neal, R.M. Bayesian Learning for Neural Networks; Springer: Berlin/Heidelberg, Germany, 1996. [Google Scholar]
- Chen, T.; Morris, J.; Martin, E. Gaussian process regression for multivariate spectroscopic calibration. Chemom. Intell. Lab. Syst. 2007, 87, 59–71. [Google Scholar] [CrossRef] [Scilit]
- Yuan, J.; Wang, K.; Yu, T.; Fang, M. Reliable multi-objective optimization of high-speed WEDM process based on Gaussian process regression. Int. J. Mach. Tools Manuf. 2008, 48, 47–60. [Google Scholar] [CrossRef] [Scilit]
- Santner, T.J.; Williams, B.J.; Notz, W.I. The Design and Analysis of Computer Experiments, 2nd ed.; Springer: New York, NY, USA, 2018. [Google Scholar]
- Gramacy, R.B. Surrogates: Gaussian Process Modeling, Design, and Optimization for the Applied Sciences, 1st ed.; Chapman and Hall/CRC: New York, NY, USA, 2020. [Google Scholar] [CrossRef] [Scilit]
- Binois, M.; Wycoff, N. A Survey on High-Dimensional Gaussian Process Modeling with Application to Bayesian Optimization. ACM Trans. Evol. Learn. Optim. 2022, 2, 1–26. [Google Scholar] [CrossRef] [Scilit]
- Sauer, A.; Cooper, A.; Gramacy, R.B. Non-stationary Gaussian Process Surrogates. arXiv 2023, arXiv:2305.19242. [Google Scholar] [CrossRef] [Scilit]
- Gramacy, R.B.; Lee, H.K.H. Bayesian Treed Gaussian Process Models with an Application to Computer Modeling. J. Am. Stat. Assoc. 2008, 103, 1119–1130. [Google Scholar] [CrossRef] [Scilit]
- Gramacy, R.B.; Apley, D.W. Local Gaussian Process Approximation for Large Computer Experiments. J. Comput. Graph. Stat. 2015, 24, 561–578. [Google Scholar] [CrossRef] [Scilit]
- Damianou, A.; Lawrence, N.D. Deep Gaussian Processes. In Proceedings of the Sixteenth International Conference on Artificial Intelligence and Statistics, Scottsdale, AZ, USA, 29 April–1 May 2013; Carvalho, C.M., Ravikumar, P., Eds.; Proceedings of Machine Learning Research: New York, NY, USA, 2013; Volume 31, pp. 207–215. [Google Scholar]
- Yi, G.; Shi, J.Q.; Choi, T. Penalized Gaussian Process Regression and Classification for High-Dimensional Nonlinear Data. Biometrics 2011, 67, 1285–1294. [Google Scholar] [CrossRef] [Scilit]
- Wu, X.; Chan, L.L.T.; Chen, J.; Xie, L. Application of Gaussian processes with variable shrinkage method and just-in-time modeling in the semiconductor industry. In Proceedings of the 2017 6th International Symposium on Advanced Control of Industrial Processes (AdCONIP), Taipei, Taiwan, 28–31 May 2017; pp. 78–83. [Google Scholar] [CrossRef] [Scilit]
- Linkletter, C.; Bingham, D.; Hengartner, N.; Higdon, D.; Ye, K.Q. Variable Selection for Gaussian Process Models in Computer Experiments. Technometrics 2006, 48, 478–490. [Google Scholar] [CrossRef] [Scilit]
- Chen, T.; Wang, B. Bayesian variable selection for Gaussian process regression: Application to chemometric calibration of spectrometers. Neurocomputing 2010, 73, 2718–2726. [Google Scholar] [CrossRef] [Scilit]
- Zhang, F.; Chen, R.B.; Hung, Y.; Deng, X. Indicator-based Bayesian variable selection for Gaussian process models in computer experiments. Comput. Stat. Data Anal. 2023, 185, 107757. [Google Scholar] [CrossRef] [Scilit]
- Gu, M.; Wang, X.; Berger, J.O. Robust Gaussian stochastic process emulation. Ann. Stat. 2018, 46, 3038–3066. [Google Scholar] [CrossRef] [Scilit]
- Berger, J.O.; de Oliveira, V.; Sanso, B. Objective Bayesian Analysis of Spatially Correlated Data. J. Am. Stat. Assoc. 2001, 96, 1361–1374. [Google Scholar] [CrossRef] [Scilit]
- Paulo, R. Default priors for Gaussian processes. Ann. Stat. 2005, 33, 556–582. [Google Scholar] [CrossRef] [Scilit]
- Kazianka, H.; Pilz, J. Objective Bayesian analysis of spatial data with uncertain nugget and range parameters. Can. J. Stat./Rev. Can. Stat. 2012, 40, 304–327. [Google Scholar] [CrossRef] [Scilit]
- Vollert, N.; Ortner, M.; Pilz, J. Robust additive Gaussian process models using reference priors and cut-off-designs. Appl. Math. Model. 2019, 65, 586–596. [Google Scholar] [CrossRef] [Scilit]
- Datta, A.; Banerjee, S.; Finley, A.O.; Gelfand, A.E. Hierarchical Nearest-Neighbor Gaussian Process Models for Large Geostatistical Datasets. J. Am. Stat. Assoc. 2016, 111, 800–812. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Vecchia, A.V. Estimation and Model Identification for Continuous Spatial Processes. J. R. Stat. Soc. Ser. B (Methodol.) 1988, 50, 297–312. [Google Scholar] [CrossRef] [Scilit]
- Robert, C.P.; Chopin, N.; Rousseau, J. Harold Jeffreys’s Theory of Probability Revisited. Stat. Sci. 2009, 24, 141–172. [Google Scholar] [CrossRef] [Scilit]
- Matérn, B. Spatial Variation; Stochastic Models and Their Application to Some Problems in Forest Surveys and Other Sampling Investigations; Statens Skogsforskningsinstitut. Band 49, Nr 5; University of Sweden: Stockholm, Sweden, 1966. [Google Scholar]
- Malsiner-Walli, G.; Wagner, H. Comparing Spike and Slab Priors for Bayesian Variable Selection. Austrian J. Stat. 2016, 40, 241–264. [Google Scholar] [CrossRef] [Scilit]
- Louzada, F.; Ferreira, P.H.; Nascimento, D.C. Spike-and-Slab Priors and Their Applications. In Wiley StatsRef: Statistics Reference Online; John Wiley & Sons, Ltd.: Hoboken, NJ, USA, 2023; pp. 1–8. [Google Scholar] [CrossRef] [Scilit]
- Neal, R.M. MCMC using Hamiltonian dynamics. In Handbook of Markov Chain Monte Carlo; Brooks, S., Gelman, A., Jones, G., Meng, X.L., Eds.; CRC Press: Boca Raton, FL, USA, 2011; pp. 113–162. [Google Scholar]
- Roberts, G.O.; Rosenthal, J.S. Examples of adaptive Markov chain Monte Carlo. J. Comput. Graph. Stat. 2009, 18, 349–367. [Google Scholar] [CrossRef] [Scilit]
- Friedman, J.; Hastie, T.; Tibshirani, R. Regularization Paths for Generalized Linear Models via Coordinate Descent. J. Stat. Softw. 2010, 33, 1–22. [Google Scholar] [CrossRef] [Scilit]
- Breiman, L. Random Forests. Mach. Learn. 2001, 45, 5–32. [Google Scholar] [CrossRef] [Scilit]
- Liaw, A.; Wiener, M. Classification and Regression by randomForest. R News 2002, 2, 18–22. [Google Scholar]
- Gu, M.; Palomo, J.; Berger, J. RobustGaSP: Robust Gaussian Stochastic Process Emulation, R Package Version 0.6.0; R Foundation: Vienna, Austria, 2020.
- Liang, F.; Paulo, R.; Molina, G.; Clyde, M.A.; Berger, J.O. Mixtures of g Priors for Bayesian Variable Selection. J. Am. Stat. Assoc. 2008, 103, 410–423. [Google Scholar] [CrossRef] [Scilit]
- Carbonetto, P.; Stephens, M. Scalable variational inference for Bayesian variable selection in regression, and its accuracy in genetic association studies. Bayesian Anal. 2012, 7, 73–108. [Google Scholar] [CrossRef] [Scilit]
- Sparapani, R.; Spanbauer, C.; McCulloch, R. Nonparametric Machine Learning and Efficient Computation with Bayesian Additive Regression Trees: The BART R Package. J. Stat. Softw. 2021, 97, 1–66. [Google Scholar] [CrossRef] [Scilit]
- Maia, M.; Murphy, K.; Parnell, A.C. GP-BART: A novel Bayesian additive regression trees approach using Gaussian processes. Comput. Stat. Data Anal. 2024, 190, 107858. [Google Scholar] [CrossRef] [Scilit]
- Dette, H.; Pepelyshev, A. Generalized Latin Hypercube Design for Computer Experiments. Technometrics 2010, 52, 421–429. [Google Scholar] [CrossRef] [Scilit]
- Carnell, R. lhs: Latin Hypercube Samples, R Package Version 1.1.1.; R Foundation: Vienna, Austria, 2020.
- Savitsky, T.; Vannucci, M.; Sha, N. Variable Selection for Nonparametric Gaussian Process Priors: Models and Computational Strategies. Stat. Sci. 2011, 26, 130–149. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Johnson, R.W. Fitting Percentage of Body Fat to Simple Body Measurements. J. Stat. Educ. 1996, 4, 1–8. [Google Scholar] [CrossRef] [Scilit]
- Tarr, G.; Müller, S.; Welsh, A.H. mplot: An R Package for Graphical Model Stability and Variable Selection Procedures. J. Stat. Softw. 2018, 83, 1–28. [Google Scholar] [CrossRef] [Scilit]
- Waschneck, B.; Brian, L.W.F.; Benny, K.C.W.; Rippler, C.; Schmid, G. Unified Frontend and Backend Industrie 4.0 Roadmap for Semiconductor Manufacturing. In Proceedings of the SamI40 Workshop at i-KNOW ’17, Graz, Austria, 11–12 October 2017. [Google Scholar]
- Lee, T.E.; Kim, H.J.; Yu, T.S. Semiconductor Manufacturing Automation. In Springer Handbook of Automation; Nof, S.Y., Ed.; Springer: Cham, Switzerland, 2023; pp. 841–863. [Google Scholar] [CrossRef] [Scilit]
- Pleschberger, M. Data Set of Extracted Summary Statistics from Equipment Sensor Data (Version 1) [Data Set]. Zenodo. 2021. Available online: https://zenodo.org/records/4462777 (accessed on 10 January 2026).






| Method | MSE | MAD |
|---|---|---|
| VRNNGP () | 0.3152 ± 0.2015 | 0.4163 ± 0.1498 |
| VRNNGP () | 0.1943 ± 0.0022 | 0.3152 ± 0.0006 |
| VRNNGP () | 0.1449 ± 0.0023 | 0.2775 ± 0.0019 |
| RGP | 1.4835 ± 0.0000 | 1.0195 ± 0.0000 |
| RF | 0.7656 ± 0.0217 | 0.7339 ± 0.0113 |
| Lasso | 1.1412 ± 0.1441 | 0.9066 ± 0.0494 |
| ALasso | 1.4273 ± 0.2009 | 0.9984 ± 0.0692 |
| BART | 1.4276 ± 0.0031 | 0.9812 ± 0.0011 |
| GPBART | 1.6171 ± 0.0031 | 1.0229 ± 0.0011 |
| BAS | 0.9985 ± 0.0000 | 0.8677 ± 0.0000 |
| VARBVS | 1.0196 ± 0.0000 | 0.8741 ± 0.0000 |
| Method | MSE | MAD |
|---|---|---|
| VRNNGP () | 0.2577 ± 0.0796 | 0.3371 ± 0.0554 |
| VRNNGP () | 0.2195 ± 0.0509 | 0.3371 ± 0.0396 |
| RGP | 0.6405 ± 0.1343 | 0.6690 ± 0.0913 |
| RF | 0.6891 ± 0.1976 | 0.6559 ± 0.1094 |
| Lasso | 0.7911 ± 0.1992 | 0.7262 ± 0.1226 |
| ALasso | 0.7867 ± 0.1898 | 0.7258 ± 0.1154 |
| BART | 1.5037 ± 0.0146 | 0.9699 ± 0.0037 |
| GP-BART | 1.4946 ± 0.0598 | 0.9782 ± 0.0213 |
| BAS | 0.8010 ± 0.0232 | 0.7399 ± 0.0131 |
| VARBVS | 0.7981 ± 0.0210 | 0.7386 ± 0.0122 |
| Method | MSE | MAD |
|---|---|---|
| VRNNGP () | 0.2849 ± 0.0359 | 0.4291 ± 0.0364 |
| RGP | 0.3408 ± 0.0180 | 0.4706 ± 0.0125 |
| RF | 0.3235 ± 0.0056 | 0.4671 ± 0.0024 |
| Lasso | 0.2933 ± 0.0143 | 0.4349 ± 0.0108 |
| ALasso | 0.2952 ± 0.0083 | 0.4406 ± 0.0069 |
| BART | 1.7193 ± 0.0290 | 1.0621 ± 0.0110 |
| GP-BART | 0.6139 ± 0.0092 | 0.6282 ± 0.0069 |
| BAS | 0.2889 ± 0.0056 | 0.4291 ± 0.0077 |
| VARBVS | 0.3081 ± 0.0053 | 0.4449 ± 0.0072 |
| Method | MSE | MAD |
|---|---|---|
| VRNNGP () | 0.2389 | 0.4198 |
| RGP | 0.3108 | 0.4684 |
| RF | 0.2672 | 0.4423 |
| Lasso | 0.2845 | 0.4575 |
| ALasso | 0.2898 | 0.4528 |
| BART | 0.4493 | 0.5712 |
| GP-BART | 0.4374 | 0.5451 |
| BAS | 0.2988 | 0.4622 |
| VARBVS | 0.3029 | 0.4602 |
| Method | MSE | MAD |
|---|---|---|
| RGP | 0.2053222 | 0.3692166 |
| RF | 0.2022327 | 0.3539577 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Share and Cite
Posch, K.; Arbeiter, M.; Truden, C.; Pleschberger, M.; Pilz, J. Feature Selection Using Nearest Neighbor Gaussian Processes. Mathematics 2026, 14, 476. https://doi.org/10.3390/math14030476
Posch K, Arbeiter M, Truden C, Pleschberger M, Pilz J. Feature Selection Using Nearest Neighbor Gaussian Processes. Mathematics. 2026; 14(3):476. https://doi.org/10.3390/math14030476
Chicago/Turabian StylePosch, Konstantin, Maximilian Arbeiter, Christian Truden, Martin Pleschberger, and Jürgen Pilz. 2026. "Feature Selection Using Nearest Neighbor Gaussian Processes" Mathematics 14, no. 3: 476. https://doi.org/10.3390/math14030476
APA StylePosch, K., Arbeiter, M., Truden, C., Pleschberger, M., & Pilz, J. (2026). Feature Selection Using Nearest Neighbor Gaussian Processes. Mathematics, 14(3), 476. https://doi.org/10.3390/math14030476