Article

Joint Modeling of Metocean Variables: A Comparative Study on Conditional Models and Copula Families Across Various Dependence Coefficient Levels

by
Mamadou Gning
*,
Marina Leivas Simão
and
Luis Volnei Sudati Sagrilo
Laboratory of Analysis and Reliability of Offshore Structures, Civil Engineering Program (PEC), Alberto Luiz Coimbra Institute for Graduate Studies and Research in Engineering, Federal University of Rio de Janeiro, Rio de Janeiro 21941-598, Brazil
*
Author to whom correspondence should be addressed.
Mathematics 2026, 14(11), 2014; https://doi.org/10.3390/math14112014
Submission received: 5 May 2026 / Revised: 1 June 2026 / Accepted: 2 June 2026 / Published: 5 June 2026
(This article belongs to the Special Issue Mathematical Modeling Applied to the Analysis of Marine Structures)

Abstract

The joint probabilistic modeling of environmental variables is essential for the design and analysis of offshore structures, as it enables the representation of dependence between parameters and the realistic estimation of combined events. This article presents a comparative evaluation between the Conditional Modeling Approach (CMA) and eight families of parametric copulas (Gaussian, Student’s t, Gumbel, Clayton, Frank, Joe, BB1, and Plackett) for the joint modeling of significant wave height ( H s ) and peak period ( T p ). Three datasets from the Brazilian coast were analyzed, encompassing a broad spectrum of dependence coefficient levels (Pearson’s coefficient, Kendall’s tau, and Spearman’s rho), ranging from high values to near-zero, including a scenario with domain-varying dependence across the T p domain. The results demonstrate that the CMA is the most robust model across all regimes, with some limitations only in the domain-varying scenario and in rank-domain residuals at low dependence coefficients. Parametric copulas perform satisfactorily solely in scenarios with high and moderate-high magnitude dependence coefficients, with the Gaussian copula standing out. At low dependence magnitudes, all copulas produce structures close to statistical independence, which shows that low dependence coefficients do not characterize the full dependence structure between H s and T p .

1. Introduction

Structural responses in offshore design are governed by the joint occurrence of multiple metoceanographic parameters, rather than by isolated environmental variables. Among the most relevant are significant wave height ( H s ), peak wave period ( T p ) or wave zero-up-crossing period ( T z ), wind speed ( V w ) and surface current speed ( V c ), as well as their respective incidence directions [1,2,3]. In more realistic scenarios, modeling may also consider the decomposition of waves into wind sea components (locally generated by wind) and swell components (propagated from distant regions), as discussed by Simão et al. [2], which increases the dimensionality and complexity of the problem. These two wave types exhibit different dependence structures between H s and T p . For wind sea, the local generation process couples wave height and period more tightly, resulting in high statistical correlation. For swell, long-distance propagation disperses wave energy by wave period. This dispersion weakens the coupling between wave height and period and often leads to low statistical dependence. Consequently, the dependence between H s and T p can vary widely across different ocean regions, depending on the dominant wave system.
The modeling of the joint probability distribution of these variables, therefore, represents a fundamental element for the design, reliability analysis, and fatigue assessment of offshore structures [2,3,4,5]. Its accuracy then has a direct impact on operational safety, cost optimization, and structural service life [6]. In literature, two main approaches are employed to model joint distributions of environmental variables: the Conditional Modeling Approach (CMA) and Copula Theory [1,2,3].
CMA, consolidated in offshore engineering practice and present in design standards and guidelines such as DNV GL [7], models the joint distribution through conditional probability distributions. CMA models for H s and T p (or T z ) were developed, for example, by Mathisen and Bitner-Gregersen [8], Simão et al. [9], Haver [10], and Ochi [11]. More recent developments have incorporated additional variables and the separate treatment of sea and swell wave components [2,12]. Despite its robustness, CMA has limitations: its extension to higher dimensions requires simplifications that may compromise statistical robustness [2], and its traditional structure may not capture complex dependence relationships [1,13].
In contrast, Copula Theory, founded on Sklar’s theorem [14], decouples the modeling of marginal distributions from the modeling of the dependence structure. Its application to offshore environmental modeling has grown in recent years. Antão and Guedes Soares [15] developed bivariate models for wave steepness and height using data from Denmark coast, Montes-Iturrizaga and Heredia-Zavoni [16] proposed formulations for environmental contours based on copulas with data from Gulf of Mexico, Manuel et al. [17] compared copula approaches and CMA for environmental data of the California coast, Zhang et al. [1] explored asymmetric copulas to capture nonlinear dependencies in offshore Alaskan data, while Wu et al. [18] extended the analysis to the trivariate case ( H s , T p , and V w ) using vine, elliptical, and Archimedean copulas with data from South China sea. In the Brazilian context, Sagrilo et al. [19] and Mosquera [3] made significant contributions using the Nataf transformation, a particular case of copula theory, for joint modeling of environmental parameters from Campos Basin and Gulf of Mexico, respectively.
Despite these advances, important gaps persist. First, most studies employing copulas focus on datasets with moderate to high dependence coefficients between variables, without testing the adequacy of different parametric families across the full range of situations encountered in practice, such as low or near-zero dependence coefficient scenarios and cases where the dependence between H s and T p is domain-varying. Second, prior works have not systematically diagnosed the consequences of low dependence coefficients and domain-varying dependence structures on copula performance. Third, applications focusing on the Brazilian offshore coastal environment, using local data and directly comparing multiple copulas with the CMA, remain scarce [3].
Given this scenario, this article aims to conduct a comparative evaluation between the CMA and eight families of parametric copulas for the probabilistic modeling of the joint probability distribution of H s and T p variables. The analyses use three metoceanographic datasets from the Brazilian coast that cover a wide spectrum of dependence coefficients between these variables, expressed by Pearson’s coefficient, Kendall’s tau, and Spearman’s rho, ranging from high to low values. The objectives are: (i) to evaluate the performance of different copula families in capturing the dependence between H s and T p under different dependence regimes; (ii) to verify the CMA’s capacity to represent bivariate dependence compared to the flexibility of copula models; and (iii) to identify the scenarios, in terms of dependence intensity, that recommend the adoption of each approach for practical offshore engineering applications.

2. Theoretical Foundations of Joint Environmental Modeling

2.1. Conditional Modeling Approach

The CMA is a consolidated method in offshore engineering for constructing joint probability models [7]. Its formulation is based on the decomposition of the joint probability density function (PDF) of a random vector into the product of a marginal distribution and one or more conditional distributions [2,7,8]. For the bivariate case, which is the focus of this work, the joint PDF of H s and T p variables is expressed as:
f H s , T p h s , t p = f H s h s f T p | H s t p | h s
The variable H s is modeled by a marginal probability distribution fitted to the observed data. The literature shows several univariate probability distribution candidates for this purpose [2,10,11,20]. An important aspect of modeling environmental variables is adherence to their physical domain, which is strictly positive. To address this without sacrificing model flexibility, the concept of a truncated distribution is employed. Let X be a random variable with PDF f X x and cumulative distribution function (CDF) F X x . For a given lower bound x T , the truncated PDF f X T x is obtained by normalizing the original distribution to the domain x x T as:
f X T x = f X x 1 F X x T
To capture more complex behaviors, piecewise distributions are used. A piecewise model combines two or more distributions, each defined over a different sub-domain of the variable’s range. Its PDF is defined as:
f X ( x ) = f 1 x ,       x x r f 2 x ,       x > x r
where f 1 x and f 2 x are the PDFs of the individual distributions, and x r denotes the transition point between them. A successful application of this approach in environmental variables modeling is the Lonowe model [10], which combines the Lognormal and 3-parameter Weibull distributions (Weibull 3P). Table 1 summarizes the main candidate marginal distributions considered in this study.
For the conditional distribution of T p given H s , the lognormal distribution (Equation (4)) is commonly used, as suggested in normative guidelines such as DNV GL [7]:
f T p | H s t p | h s = 1 2 π · ξ h s · t p e x p ln t p λ h s 2 2 ξ h s 2
The scale parameter λ h s and shape parameter ξ h s are functions dependent on H s . The following parametric expressions are commonly adopted to capture this dependence [8]:
λ h s = a 1 + a 2 H s a 3
ξ h s = b 1 e x p b 2 H s + b 3
The coefficients a i ,   b i ,   i = 1 ,   2 ,   3 , are estimated from observed data. The usual procedure involves dividing the domain of the variable H s into intervals, estimating the parameters λ h s and ξ h s of the lognormal distribution for each interval, and then fitting the curves defined by Equations (5) and (6) to these point values by means of a nonlinear optimization method, such as least squares.

2.2. Dependence Measures

Characterizing the statistical relationship between random variables is fundamental for joint probabilistic modeling. In the presence of dependence, probabilistic models must adequately represent this association structure. This work employs three classical measures to quantify the dependence between H s and T p and to assist in estimating copula parameters: Pearson’s linear correlation coefficient ( ρ ), Kendall’s tau coefficient ( τ ), and Spearman’s rho coefficient ( ρ S ) [21,22].
  • Pearson’s linear correlation coefficient ( ρ ) quantifies the degree of linear dependence between two random variables X and Y and is defined as:
ρ X , Y = C o v X , Y σ X σ Y
where C o v X , Y is the covariance between X and Y , and σ X , σ Y are their respective standard deviations. The value of ρ lies in the interval [ 1 , 1 ] . Values close to 1 or 1 indicate strong positive or negative linear correlation, while values close to zero suggest weak linear relationship. However, a close to zero ρ coefficient does not guarantee statistical independence. Its sample estimator ρ ^ , for N observed pairs x i , y i , is given by:
ρ ^ ( X , Y ) = i = 1 N x i μ ^ X y i μ ^ Y i = 1 N x i μ ^ X 2 i = 1 N y i μ ^ Y 2
where μ ^ X and μ ^ Y denote the sample means of X and Y , respectively.
  • Kendall’s tau coefficient ( τ ) is a nonparametric measure of association that evaluates monotonic dependence between two variables. It is based on the difference between the probabilities of concordance and discordance of observation pairs and is given by:
τ X , Y = P X 1 X 2 Y 1 Y 2 > 0 P X 1 X 2 Y 1 Y 2 < 0
where X 1 , Y 1 and X 2 , Y 2 represent two independent realizations of ( X , Y ) . τ also varies in [ 1 , 1 ] , with an interpretation analogous to Pearson’s for monotonicity, but it is invariant to increasing monotonic transformations of the variables. For a sample of N observed pairs x i , y i without tied values, the sample estimator τ ^ is calculated as:
τ ^ X , Y = 4 N N 1 1 i j N I x i x j y i y j 1
where the function I ( . ) returns + 1 for concordant pairs and 1 for discordant pairs.
  • Spearman’s rho coefficient ( ρ S ) is another nonparametric measure of monotonic dependence. ρ S is equivalent to Pearson’s correlation coefficient applied to the ranks of the observations, or equivalently, to the transformed variables U = F X x and V = F Y y , where F X x and F Y y are CDFs of X and Y , respectively. It is given by:
ρ s ( X , Y ) = ρ U , V = 12 E U V 3
Its interpretation is analogous to Kendall’s tau. For a sample of N observed pairs x i , y i without tied values, the sample estimator ρ s ^ is calculated as:
ρ s ^ X , Y = 1 6 i = 1 N d i 2 N N 2 1
where d i = r a n k x i r a n k y i , with r a n k x i being the position of the value in the ordered sample of variable X , and r a n k y i is defined analogously for variable Y .

2.3. Basic Concepts of Copula Theory

Copula theory offers a flexible approach for modeling multivariate probability distributions, as it allows decoupling the modeling of marginal distributions from the modeling of the dependence structure between variables [21,22].

2.3.1. Sklar’s Theorem

Sklar’s theorem [14] is the fundamental pillar of this theory. It establishes that any joint CDF F X ( x 1 , x 2 , , x n ) of a random vector X = ( X 1 , X 2 , , X n ) can be decomposed into its marginal CDFs F X i x i ,   i = 1 , 2 , , n and a copula C that describes the dependence structure between the variables:
F X x 1 , x 2 , , x n = C F X 1 x 1 , F X 2 x 2 , , F X n x n
The copula C : 0 , 1 n 0 , 1 is a multivariate distribution function with uniform marginals on 0 , 1 . If the marginals are continuous, the copula C is unique. The corresponding joint probability density function (PDF) is:
f X x 1 , x 2 , , x n = c F X 1 x 1 , F X 2 x 2 , ,   F X n x n i = 1 n f X i ( x i )
where f X i ( x i ) are the marginal PDFs and c · is the copula density. For the bivariate case with variables X and Y , the conditional distribution of one variable given the value of the other is defined as:
C 2 | 1 v | u = P V v | U = u = C u ,   v u
where u = F X x and v = F Y y .

2.3.2. Properties of Copulas

Copulas possess mathematical properties that derive from their definition [14,21,22]. For an n -dimensional copula C : 0 , 1 n 0 , 1 , the following properties hold:
  • Boundary conditions: for any u = u 1 , u 2 , , u n 0 , 1 n ,
C u 1 , , u i 1 , 0 , u i + 1 , u n = 0
If all coordinates except u i are equal to 1 , then:
C 1 , , 1 , u i , 1 , , 1 = u i
  • Invariance: if continuous random variables X = ( X 1 , X 2 , X n ) have copula C . , then the transformed vector α 1 X 1 , α 2 X 2 , , α n X n , where each α i is a strictly increasing function, shares the same copula C . .
  • Fréchet-Hoeffding Bounds: for any copula, the following relationship holds:
m a x i = 1 n u i n + 1 ,   0 C u min u 1 , u 2 , , u n
The upper bound, min u 1 , u 2 , , u n known as the comonotonicity copula, represents perfect positive dependence. The lower bound, m a x i = 1 n u i n + 1 ,   0 , corresponds to perfect negative dependence. In the bivariate case, both bounds are copulas.
  • Tail Dependence: an important property is the ability to quantify the association between extreme events. This dependence is quantified by the lower tail dependence coefficient λ L and the upper tail dependence coefficient λ U , defined as:
λ L = lim u 0 + C u ,   u u
  λ U = lim u 1 1 2 u + C u ,   u 1 u
A value of λ U or λ L in the interval ( 0 , 1 ] indicates a degree of upper or lower tail dependence, respectively, while values equal to zero correspond to absence of tail dependence. In practice, with sample data, these coefficients are estimated using empirical approximations. For a threshold q , which represents a quantile close to 0 (for the lower tail) or close to 1 (for the upper tail), the estimates are calculated as:
λ L ^ = 1 N i = 1 N I u i < q   a n d   v i < q q
λ U ^ = 1 N i = 1 N I u i > q   a n d   v i > q 1 q
where N is the total number of observations, I · is the indicator function (assumes value 1 if the condition is satisfied and 0 otherwise), q is the chosen threshold, and u i = F X x i , v i = F Y y i .

2.4. Families of Parametric Copulas

Several parametric families of copulas are available in the literature, each with specific dependence characteristics [21,22]. In this work, eight families are investigated to model the relationship between H s and T p , grouped into three categories according to their theoretical construction.
Elliptical copulas derive from multivariate elliptical distributions and are characterized by radial symmetry. The Gaussian copula is obtained from the bivariate normal distribution; its parameter ρ corresponds to the equivalent linear correlation coefficient after transforming the variables to the standard normal space, a construction directly related to the Nataf transformation [23]. The Student’s t copula derives from the multivariate t distribution, incorporating, in addition to the parameter ρ , a degree of freedom parameter ν that controls the probability of joint occurrence of extreme events, which enables tail dependence modeling.
Archimedean copulas are constructed from a generator function φ : 0 , 1 0 , , which is continuous, strictly decreasing, and convex, satisfying φ 1 = 0 . A bivariate Archimedean copula is expressed as C u , v = φ 1 φ u + φ v , where φ 1 ( · ) is the inverse of φ · . Different choices of φ · generate families with distinct dependence structures: Gumbel (asymmetric upper tail dependence), Clayton (asymmetric lower tail dependence), Frank (symmetric dependence, with no tail dependence), Joe (similar to Gumbel) and BB1 (two parameters θ and δ , which combines the structures of Clayton and Gumbel, allowing for modeling asymmetric dependence in both tails).
Plackett Copula belongs to a distinct, non-Archimedean class. It is constructed from the constant cross-ratio principle, resulting in a closed-form expression for C u , v that is symmetric and exhibits no tail dependence [22].
Table 2 summarizes the eight families described above, presenting their CDFs C u , v and the respective parameter spaces. Complete expressions for the density functions, conditional distributions, and the relationships between parameters and dependence measures ( ρ , τ , ρ s ), can be found in reference works [21,22].

2.5. Copula Fitting Techniques

The estimation of copula parameters is performed using two main methods: (a) method of moments and (b) maximum likelihood method. In the method of moments, which is based on the dependence measures discussed in Section 2.2, the copula parameters are obtained by equating the sample measures ( τ ^ ,   ρ s ^ or ρ ^ ) to their theoretical expressions as functions of the copula. For a copula C u , v ; θ , the coefficients τ and ρ s can be expressed, respectively, by the following integrals [21,22]:
τ = 4 0 1 0 1 C u , v ; θ d C u , v ; θ 1
ρ S = 12 0 1 0 1 C u , v ; θ d u d v 3
For many parametric families, these integrals simplify to closed-form analytical relationships, allowing one to write τ = g ( θ ) or ρ S = h θ , where g and h are known functions specific to each family [21,22]. Thus, in practice, for one-parameter copulas (e.g., Gumbel, Clayton, Frank, Joe), the relationship τ = g ( θ ) is used to estimate θ from the sample τ ^ . Alternatively, for some families, the relationship ρ S = h θ can be employed with the coefficient ρ s ^ . When closed-form expressions are not available, numerical approximation techniques can be employed to solve the integral equations relating the parameters to the dependence measures. For elliptical copulas, the natural parameter is the equivalent linear correlation coefficient, which relates to τ and ρ S by: τ = 2 π sin 1 ρ and ρ S = 6 π sin 1 ρ 2 [22]. For two-parameter copulas, such as BB1, a system of equations involving τ ^ and the sample upper tail dependence coefficient λ U ^ is employed [22].
In the maximum likelihood method, copula parameter estimation is performed using the joint PDF expressed via Sklar’s theorem. For an independent bivariate sample x i , y i i = 1 N , the log-likelihood function is given by:
ln L θ , α , β = i = 1 N ln c F X x i , α ,   F Y y i , β ; θ + i = 1 N ln f X x i , α + i = 1 N ln f Y ( y i , β )
where θ is the vector of copula parameters, and α and β are the vectors of marginal distribution parameters. Two common approaches are: full maximum likelihood (MLE), which jointly optimizes all parameters, and the inference functions for margins (IFM) method [24], adopted in this work. IFM is a sequential procedure: first, the parameters of the marginal distributions ( α , β ) are estimated by univariate maximum likelihood or the method of moments; then, with the marginals fixed, the copula likelihood is maximized with respect to its parameter vector θ . For two-parameter copulas (e.g., Student’s t and BB1), this step corresponds to the joint maximization of both parameters. The IFM method was adopted due to the large number of parameters involved in the joint estimation, particularly given the complexity of the marginal distributions considered in this study, which makes full MLE computationally demanding. It is worth noting, however, that the IFM estimator may lose efficiency relative to full MLE when the marginal distributions are not correctly specified.

3. Modelling Methodology

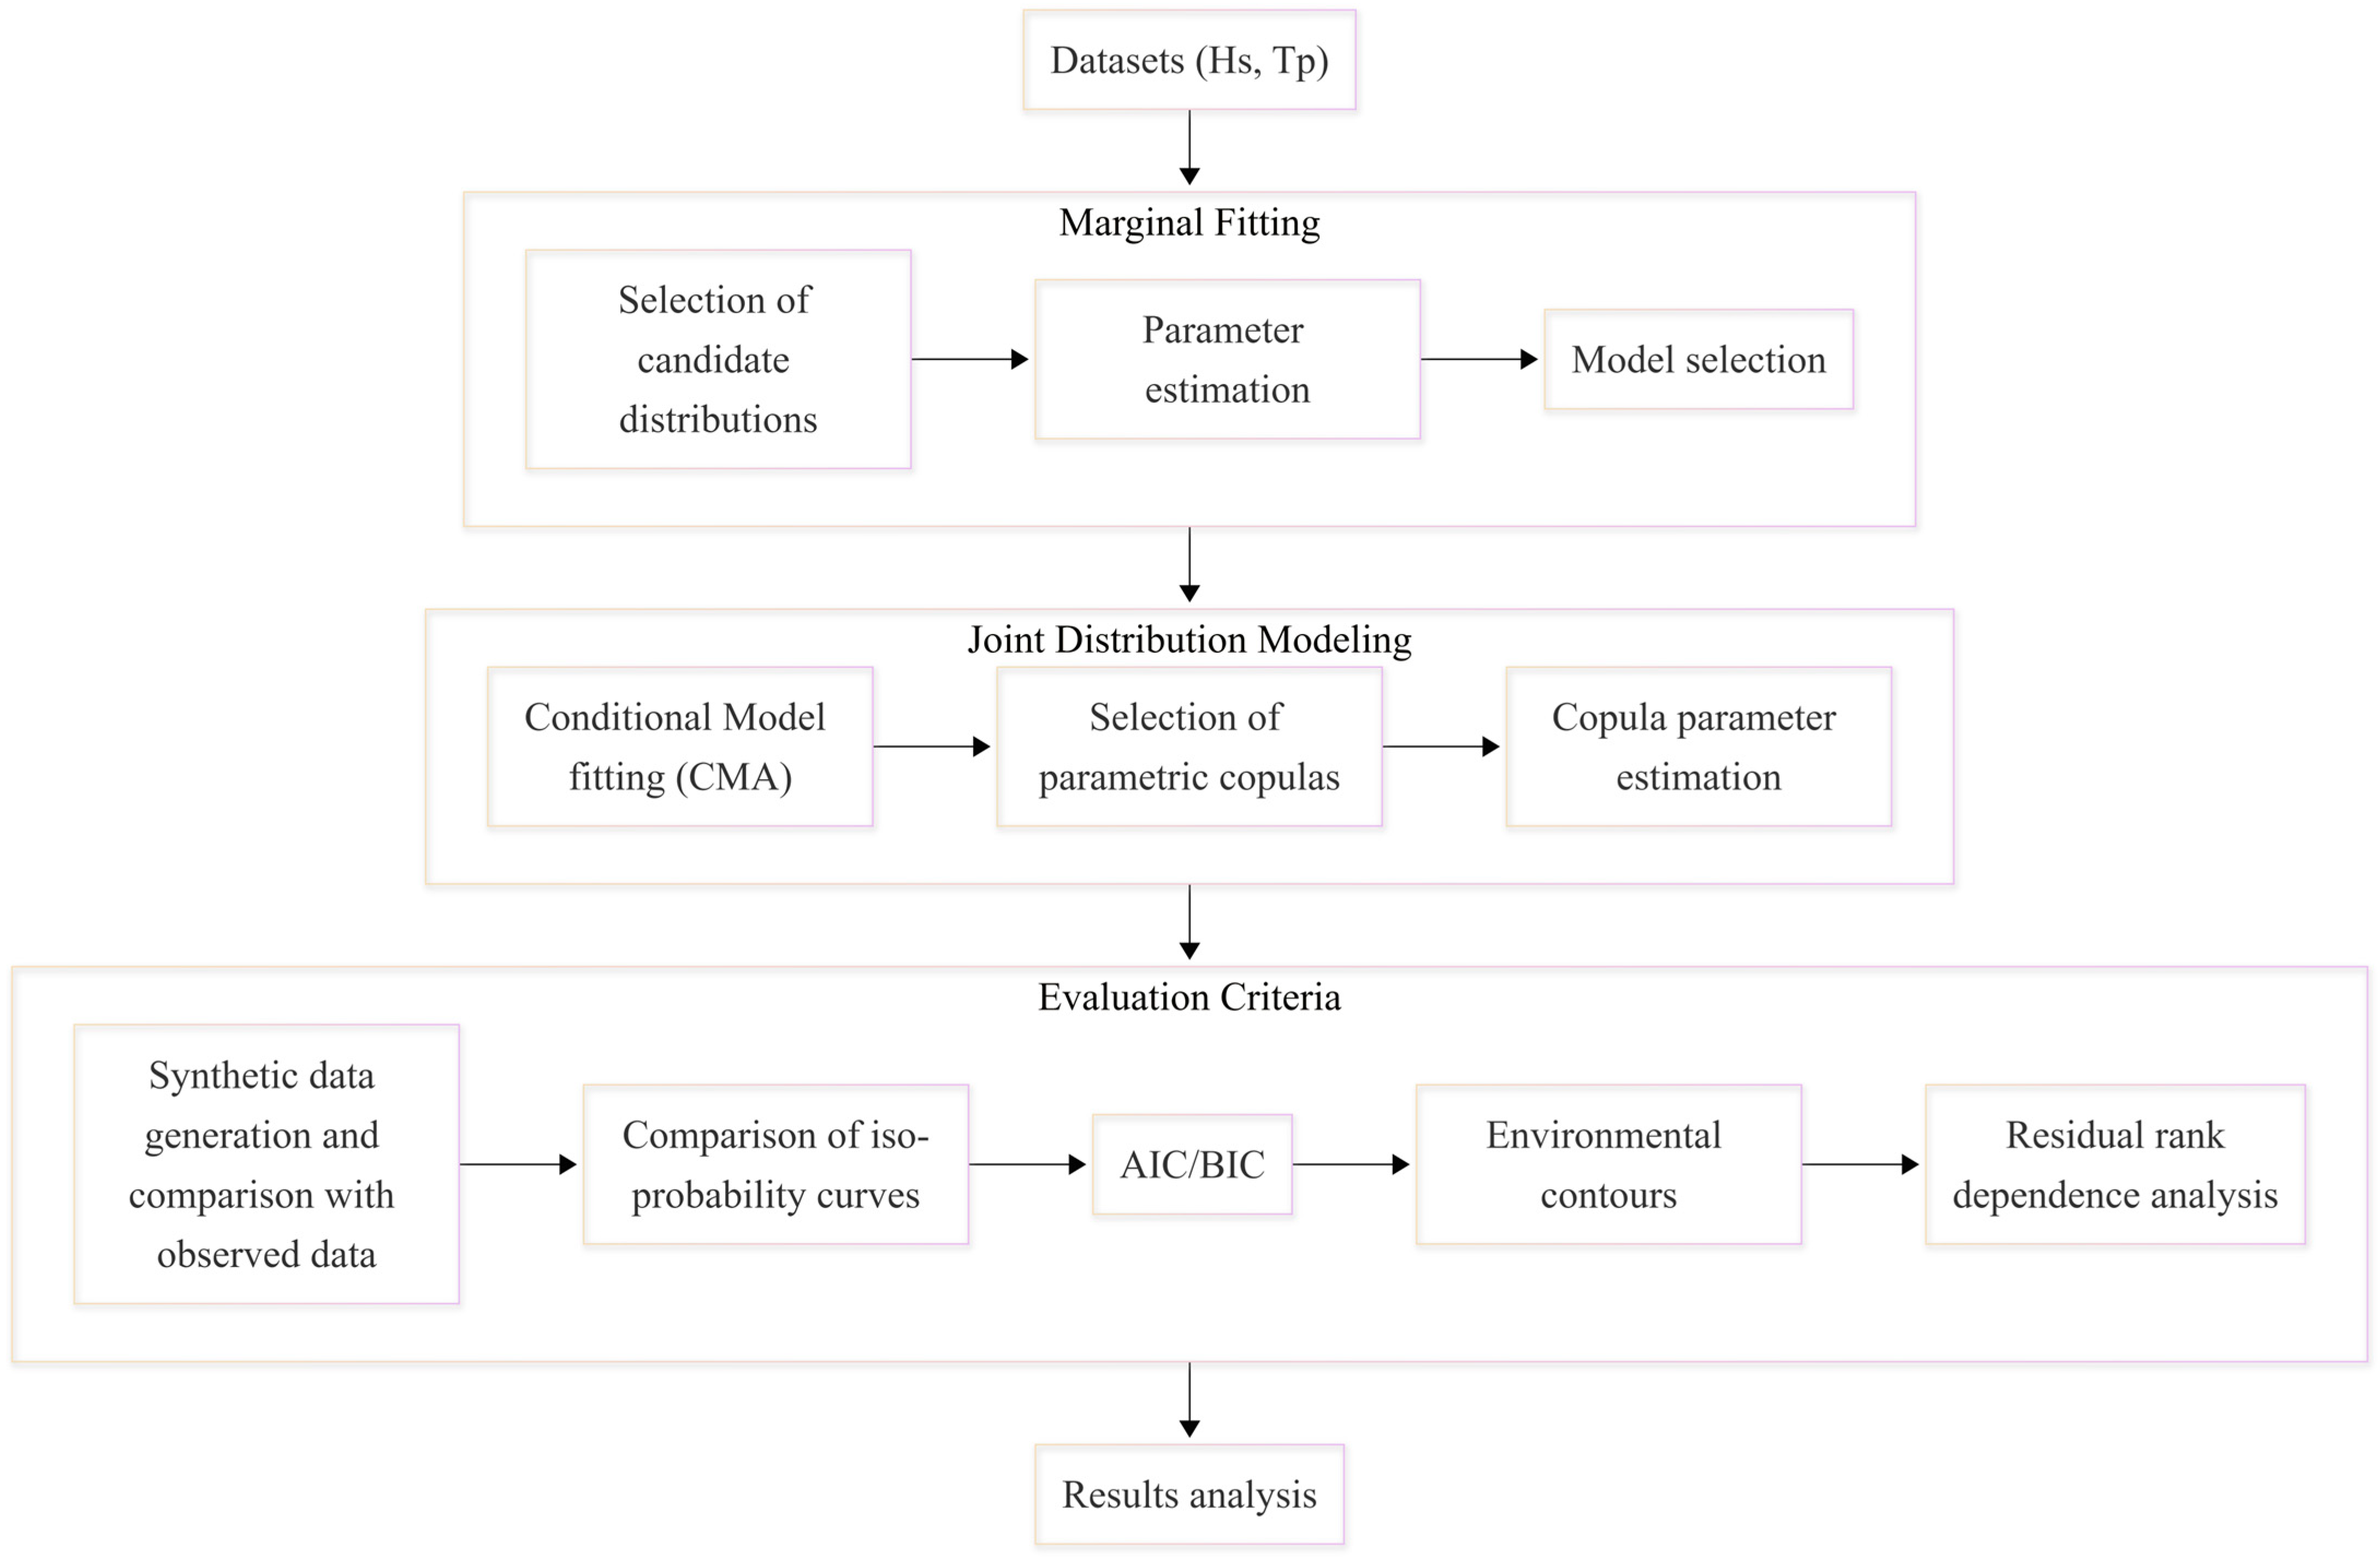
Figure 1 provides an overview of the modeling framework, summarizing the main steps from data input to model evaluation.

3.1. Description of Datasets

The data used in this study consist of historical wave hindcast series, with 3-h resolution, for the pairs ( H s , T p ) covering a continuous 20-year period. The series are derived from two numerical modeling sources:
  • Set 1 (C1): Data for the northern region of the Campos Basin, Brazil, generated from the MyOcean/Copernicus and ERA5 (ECMWF) databases, with validation via satellite data and GlobWave [25].
  • Sets 2 and 3 (C2, C3): Data obtained from the WAVEWATCH III (WW3) model for two locations: Santos Basin (C2) and Equatorial Margin (C3) [26].
For each location, the wave records are separated into their sea and swell components. This separation results in six distinct modeling scenarios. Table 3 summarizes the main sample dependence measures for each of the six scenarios. The wide variation observed in the dependence coefficients, ranging from very high values (C1-sea) to near-zero values (C2-swell, C3-swell), provides an ideal spectrum for evaluating model performance under different dependence regimes.
The near-zero dependence coefficients observed for the swell scenarios (C2-swell and C3-swell) in Table 3 are consistent with the wave energy dispersion mechanism described in the Introduction.
To complement the global dependence measures reported in Table 3, Table 4 presents the empirical lower and upper tail dependence coefficients ( λ L ^ and λ U ^ , Equations (21) and (22)) estimated for all six scenarios at thresholds q   =   0.10 (lower tail) and q   = 0.90 (upper tail). The results reveal that tail dependence is strongly correlated with the global dependence regime: C1-sea presents the highest values in both tails ( λ L ^ = 0.87 ; λ U ^ = 0.83 ), consistent with its near-perfect global correlation. Notably, even in scenarios with near-zero global coefficients, such as C3-swell, non-negligible tail dependence persists ( λ U ^ = 0.26 ).

3.2. Fitting of Marginal Distributions

For each of the six data series, a set of candidate distributions, listed in Table 1, was fitted to H s and T p data individually. Parameter estimation was performed using both the method of moments and maximum likelihood.
The empirical distribution was obtained by partitioning the domain of variable X into M intervals of equal width Δ x = x m a x x m i n / M , where M was determined by visual inspection for each dataset to ensure adequate resolution across the distribution domain and to maintain a sufficient number of observations per interval. For each interval i , centered at x i , the empirical PDF is estimated as:
f ^ X x i = n i n · Δ x
where n i denotes the number of observations falling within the i -th interval and n is the total sample size. The corresponding empirical CDF is given by:
F ^ X ( x ¯ j ) = j n + 1
where x ¯ j is the j -th element of the sampled values sorted in ascending order.
Model selection prioritized the quality of fit in the upper tail, as this region is critical for estimating extreme events in offshore engineering applications. For each candidate distribution, the mean relative error (MRE) was computed between the theoretical and empirical exceedance probabilities for four high quantiles: 95.0%, 99.0%, 99.5%, and 99.9%. The exceedance probability, also referred to as the survival function S ( x )   =   P ( X   >   x )   =   1     F X ( x ) , provides a direct measure of the probability of observing values above a given threshold. For a given quantile q , the corresponding threshold is defined as x q = F ^ X 1 q . The empirical exceedance probability is S e m p x q = 1 q , while the theoretical exceedance probability is S t e o x q = 1 F X x q . The relative error for each quantile is calculated as:
R E q = S t e o x q S e m p x q S e m p x q · 100 %
The MRE is then obtained as the arithmetic mean of the errors across the four selected quantiles:
M R E = 1 4 q Q R E q , Q = 0.950 ;   0.990 ; 0.995 ; 0.999
The distribution exhibiting the lowest MRE, combined with visual assessment of the fitted PDFs, CDFs and survival function, was selected for each variable.

3.3. Modeling of the Joint Distribution

The joint distribution of H s and T p was modeled using two approaches: the CMA and copula theory.
CMA: Following Equation (1), the joint PDF is given by the product of the marginal distribution of H s (Section 3.2) and the conditional distribution T p | H s , modeled as Lognormal with parameters λ h s and ξ h s (Equations (5) and (6)). The coefficients a i and b i were estimated using nonlinear least squares from the values of λ and ξ computed within H s intervals, where the number of intervals was determined by visual inspection for each scenario, with outlying point estimates removed before the fitting procedure. To ensure the positivity of ξ h s , the constraints b 1 ,   b 3   0 were imposed during the fitting procedure, with b 1 + b 3 >   0 as a sufficient condition for ξ h s >   0 across the entire H s domain.
Copulas: The data were transformed into uniform pseudo-observations u i = F H s h s i and v i = F T p t p i in the interval [ 0 , 1 ] . Eight families of copulas were fitted, as listed in Table 2: Gaussian, Student’s t, Gumbel, Clayton, Frank, Joe, BB1, and Plackett. Parameters were estimated using both the method of moments and maximum likelihood via the IFM (see Section 2.5). The eight families selected represent the most widely adopted parametric copulas in offshore and coastal engineering applications [1,15,16,17,18]. More flexible structures, such as non-parametric copulas and mixture copulas, are outside the scope of this baseline study but are identified as important directions for future research.
It should be noted that the CMA and the parametric copulas operate under structurally asymmetric parameterizations. The CMA employs six free parameters to describe the conditional distribution of T p given H s (Equations (5) and (6)), while most single-parameter copula families use one parameter to characterize the entire dependence structure. A strictly equivalent comparison would require either two-parameter copula families, such as the BB1 or Student’s t, already included in this study, or more flexible constructions such as mixture copulas with comparable degrees of freedom.

3.4. Evaluation Criteria

It is recognized that selecting the most appropriate joint distribution model is challenging, even for bivariate problems [13]. The performance of the models was evaluated using four complementary criteria:
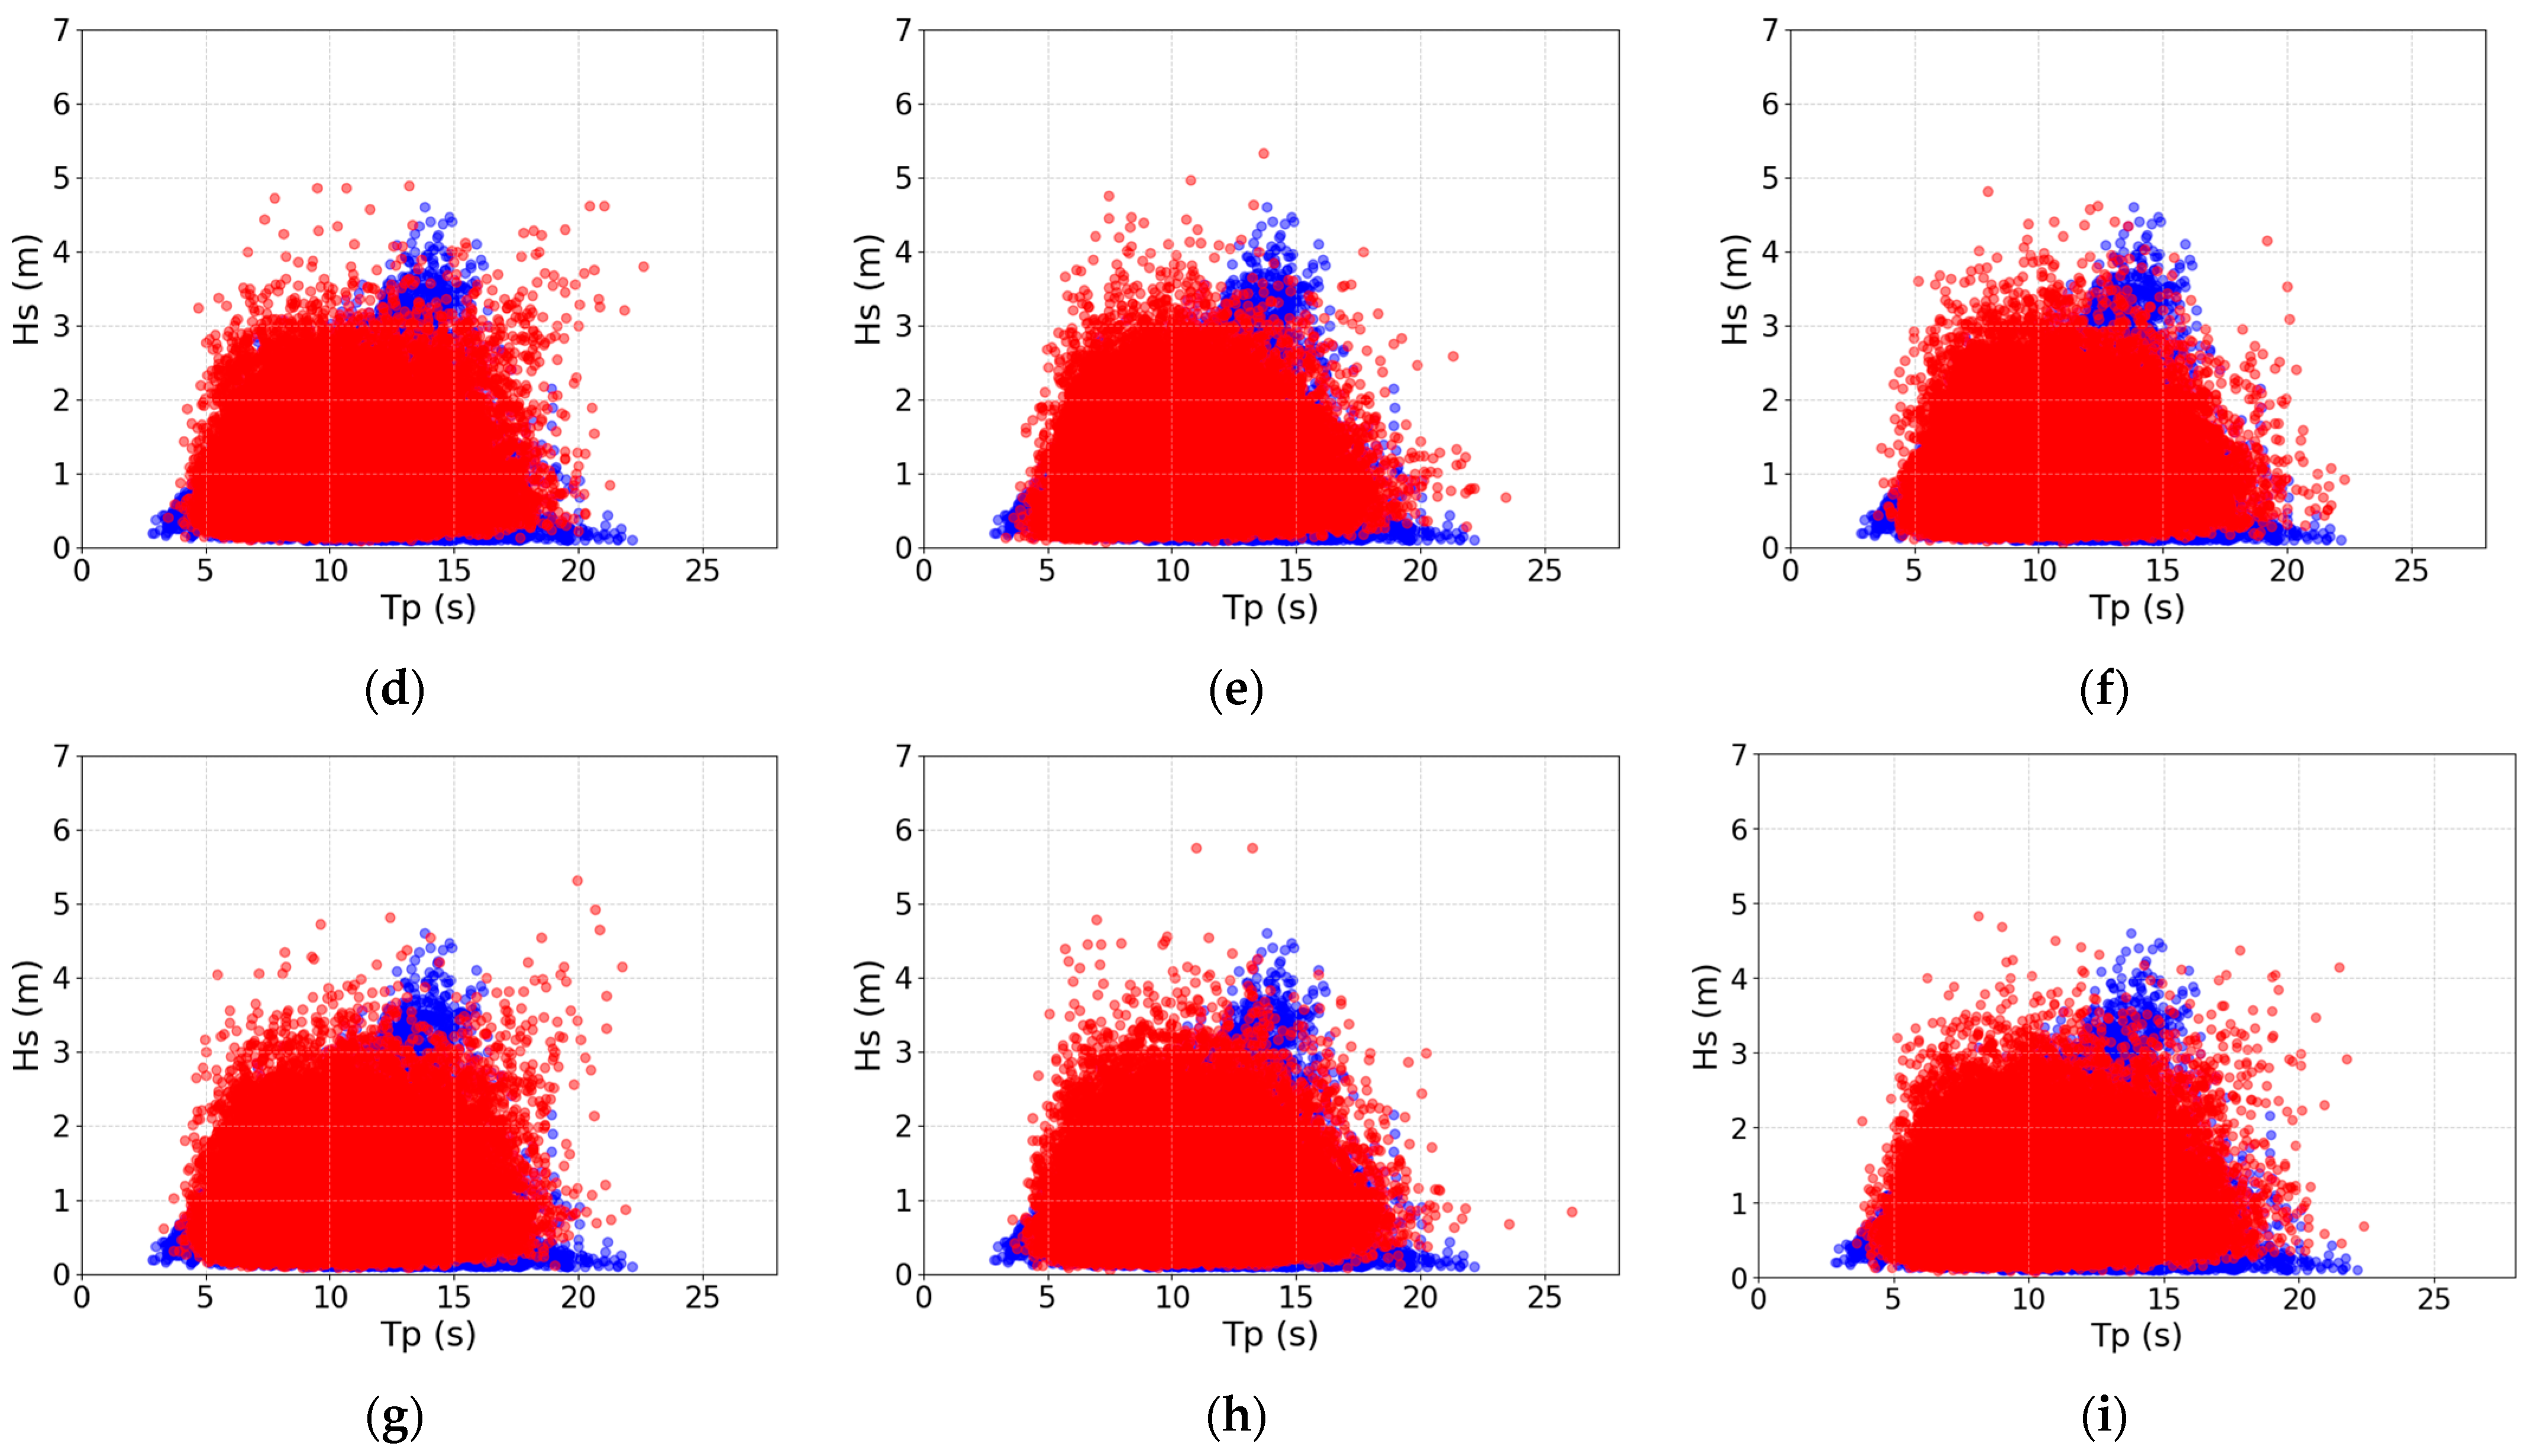
  • For each fitted model, a synthetic sample of the same size as the original dataset was generated via Monte Carlo Simulation. The synthetic scatter plots were visually compared to the observed data.
  • The empirical joint PDF of the observed data was estimated using two-dimensional histograms with the following formulation:
f H s T p h i , t j = n i , j n t o t a l · Δ h · Δ t
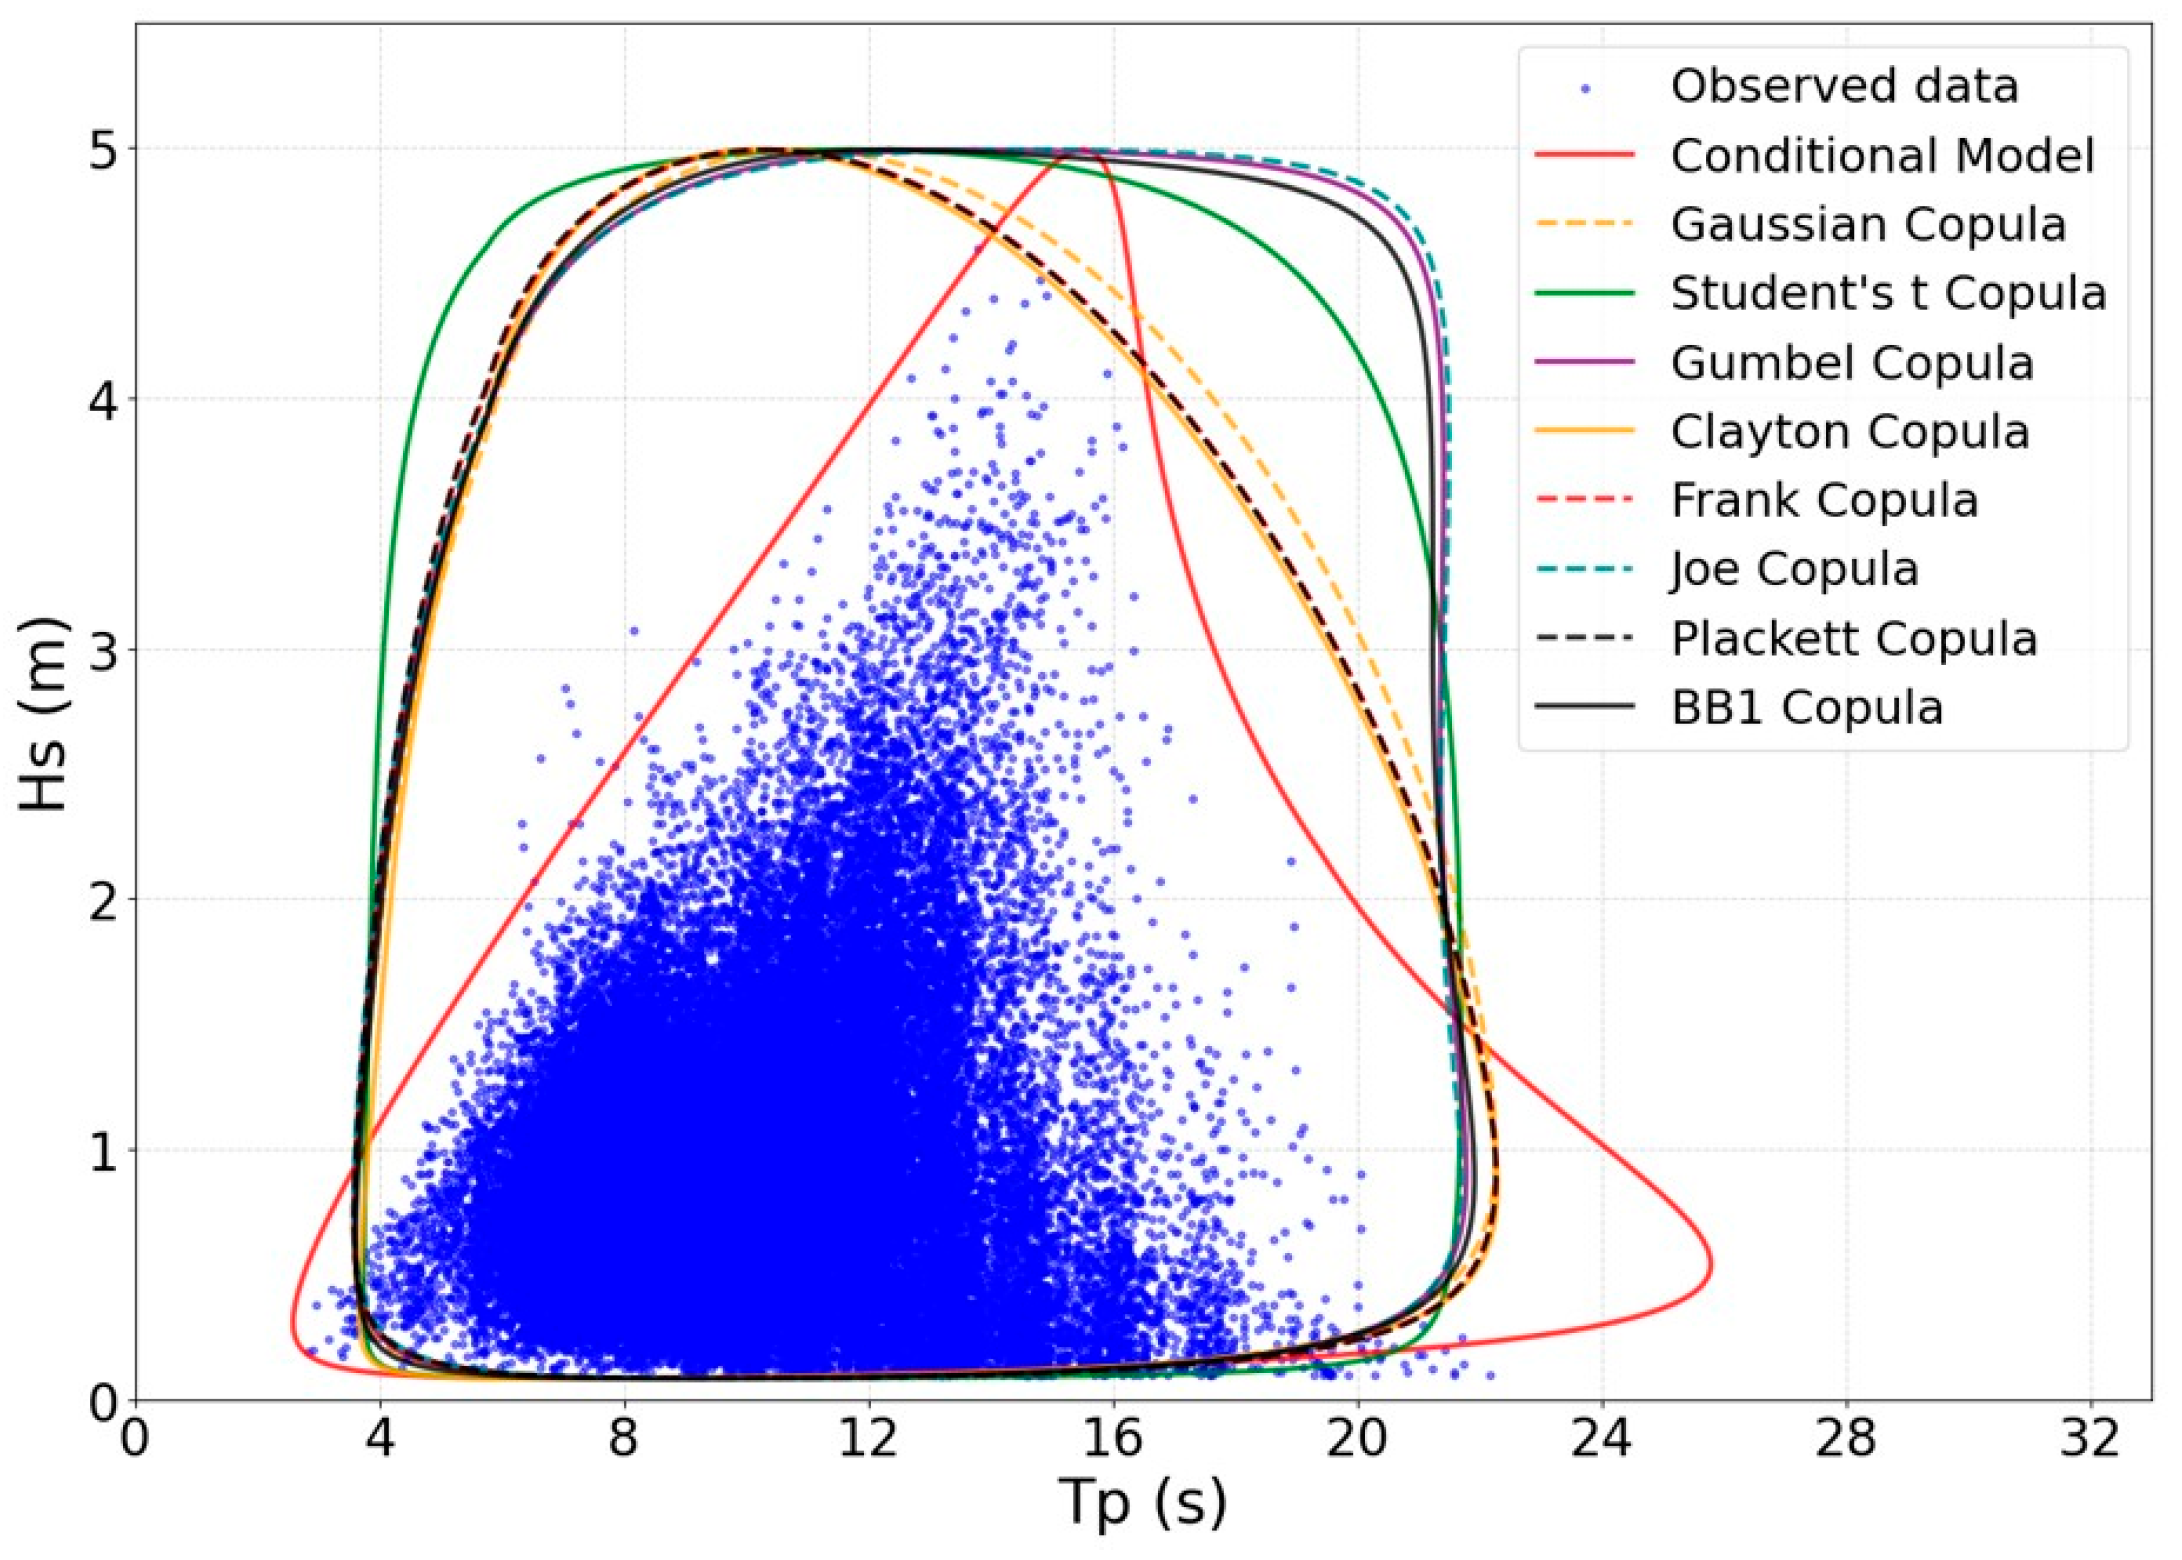
where n i , j is the number of observations contained in the cell i , j , n t o t a l is the total number of points, and Δ h and Δ t are the interval widths. For each fitted model, the theoretical joint PDF was obtained directly from Equation (1) for the CMA and from Equation (14) for the copula models. The theoretical and empirical PDFs were then visually compared through the iso-probability curves.
iii.
Akaike Information Criterion (AIC) [27] and Bayesian Information Criterion (BIC) [28]: these approaches were used as relative measures of goodness-of-fit, penalizing model complexity:
A I C = 2 k 2 i = 1 n ln f X , Y x i , y i ; θ , α , β
B I C = k ln n 2 i = 1 n ln f X , Y x i , y i ; θ , α , β
where k is the total number of parameters (marginal + copula parameters). Lower values indicate a better balance between fit and simplicity.
iv.
Environmental contours: these were constructed for a 20-year return period using the IFORM method [29], allowing validation of the models against the observed data. The reliability index β associated with the return period T r is given by:
β = Φ 1 1 1 N 1 y e a r · T r
where N 1 y e a r = 2920 is the expected number of short-term sea states in one year, considering a 3-h time discretization, and Φ 1 · denotes the inverse of the standard normal CDF, with Φ · representing the standard normal CDF itself. Standard Gaussian directions U 1 = β cos ϑ ,   U 2 = β sin ϑ ,   ϑ = 0 , 2 π , generate a circle of radius β in the bivariate standard normal space, which is mapped back to the physical space as follows:
  • CMA:
H s = F H S 1 Φ U 1 ,     T p = F T p | H s 1 Φ U 2 | H s ;
  • Copulas:
Z 1 = Φ U 1 ,     Z 2 = C 2 | 1 1 Φ U 2 | H s , w i t h   H s = F H S 1 Z 1 ,     T p = F T p 1 Z 2
It is worth noting that the IFORM construction relies on a Rosenblatt-like transformation [30] requiring a well-behaved inverse of the conditional copula CDF; alternative contour methods such as direct-sampling or ISORM approaches [6] are outside the scope of this study.
When the criteria do not fully agree, a hierarchical decision protocol is applied: physical plausibility of the synthetic scatter plot serves as a primary filter; structural adherence of iso-probability curves as a secondary filter; tail behavior in environmental contours as a tertiary criterion; and finally, AIC/BIC as an auxiliary discriminator among models that pass the preceding filters. When AIC/BIC contradicts the visual ranking, the visual criteria are prioritized due to their direct relevance to engineering design, particularly in applications such as the derivation of environmental contours for offshore structural design.
As a complementary criterion, a residual rank dependence analysis was conducted for selected scenarios based on the Rosenblatt probability integral transform, as detailed in Section 4.3.5. This analysis quantifies the dependence structure not captured by each fitted model in the rank domain and provides an additional perspective on model adequacy independent of the visual and likelihood-based criteria described above.
Regarding computational effort, the CMA and the parametric copula fitting procedures are computationally tractable for the dataset sizes considered. Computational efficiency was not a limiting factor in any scenario, and its influence on model selection is negligible compared to the differences in statistical robustness. All analyses were implemented in Python (version 3.12.13).

4. Results and Discussion

4.1. Fitting of Marginal Distributions

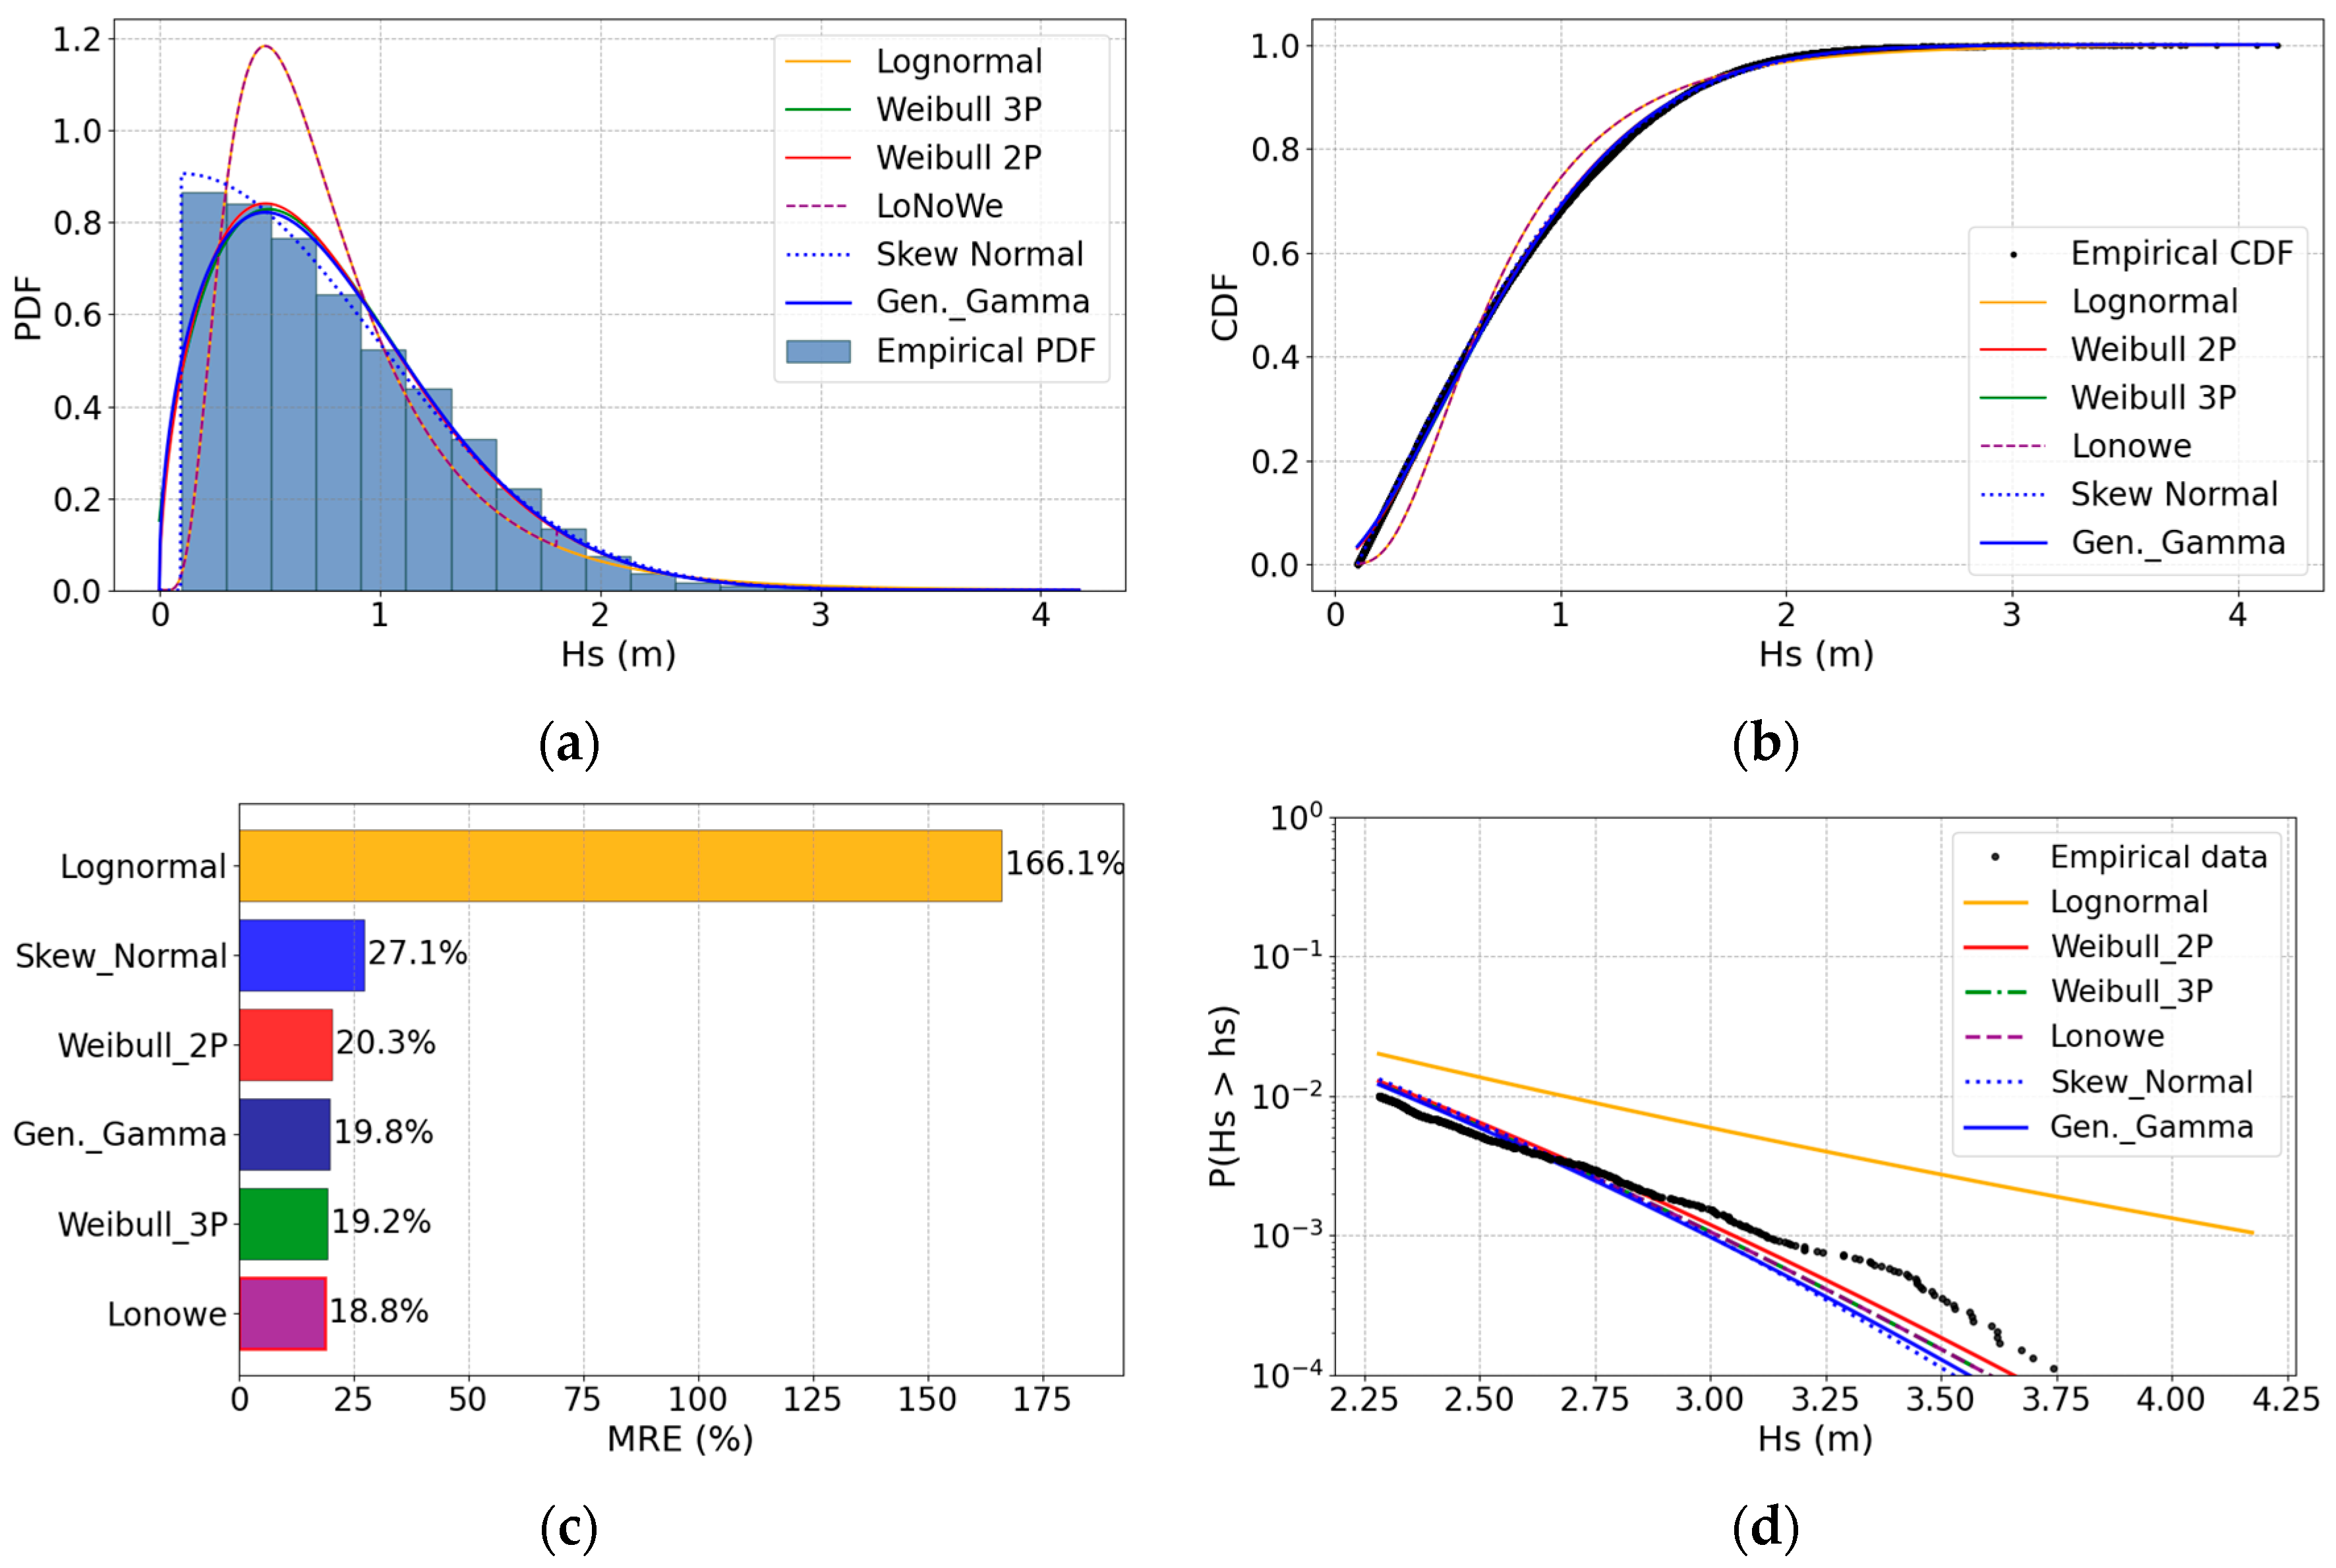
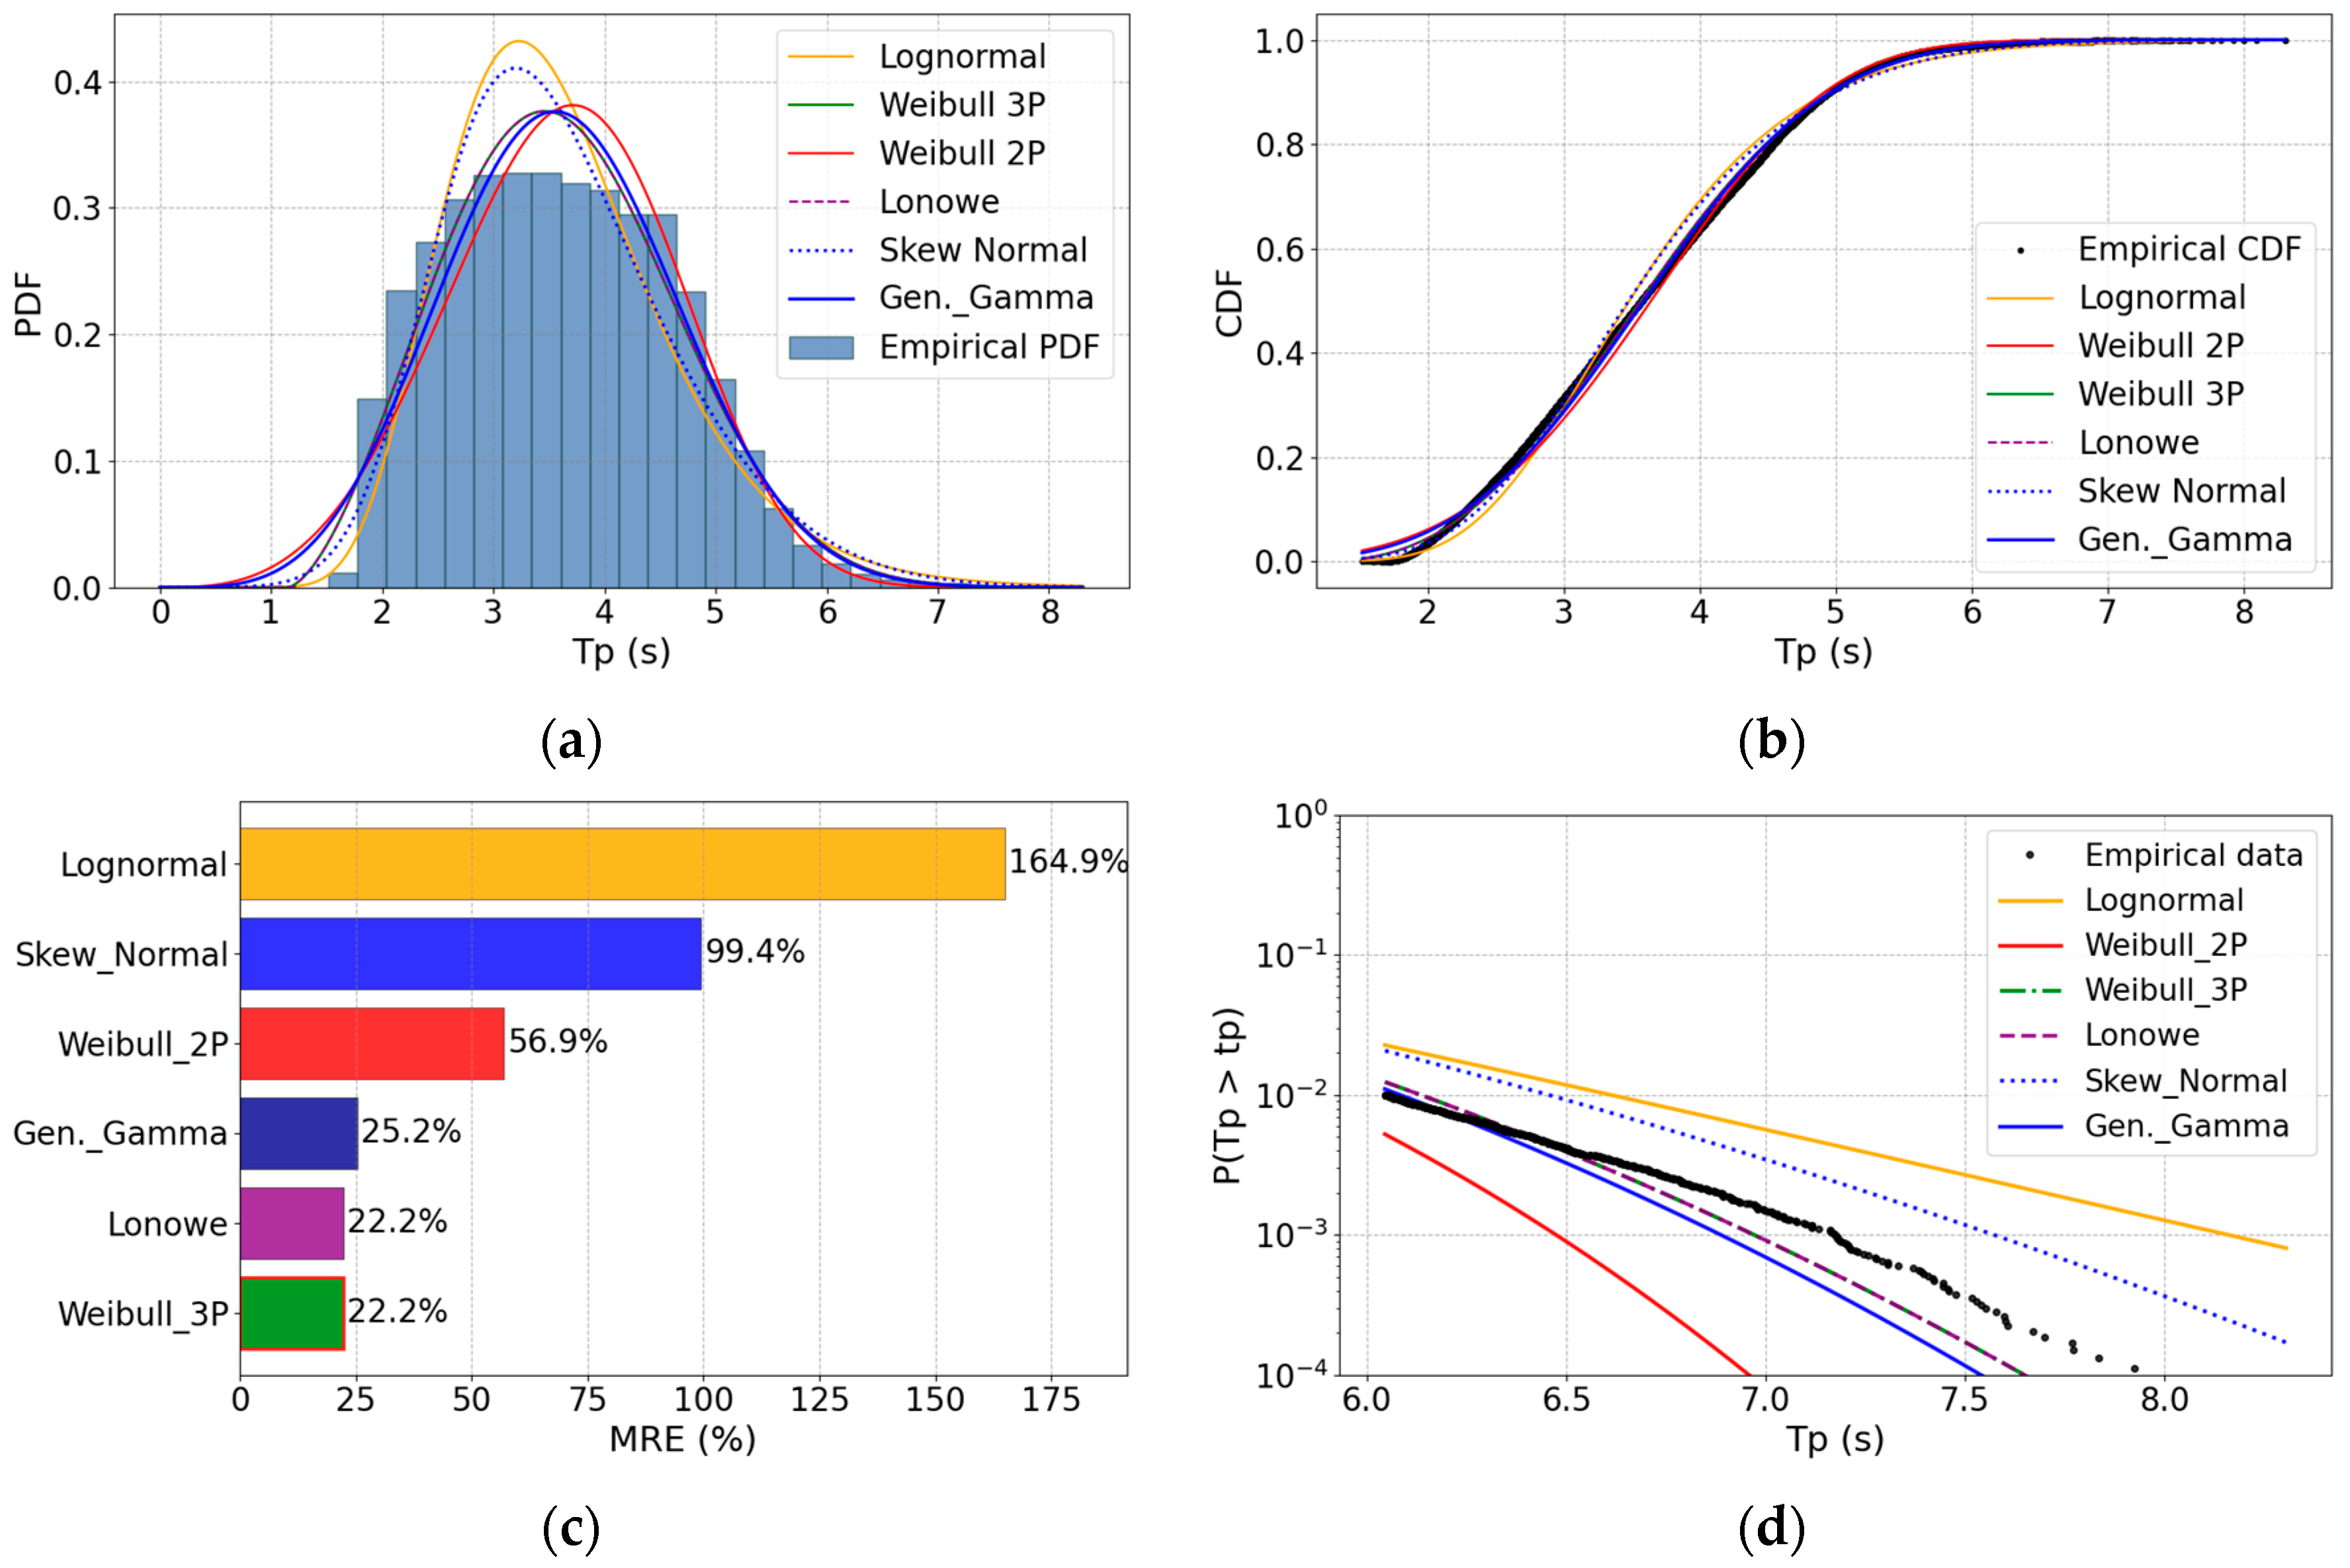
Figure 2 and Figure 3 illustrate, as an example, the selection process of marginal distributions for the variables H s and T p for sea component in Set 1 (C1-sea). For H s (Figure 2) the Weibull 2P distribution was selected based on the combined MRE and visual assessment. Although the MRE values of Weibull 2P (20.3%) and Lonowe (18.8%) are comparable, the Weibull 2P showed superior adherence to the observed data across both the body of the distribution and the upper tail region, as evidenced by the survival function plot in Figure 2d. For T p (Figure 3) the Lonowe distribution stood out with the lowest MRE (22.2%) and excellent fit in the upper tail.
Table 5 summarizes the selected marginal distributions for all scenarios. Lonowe was the most frequently selected distribution. The Generalized Gamma and Lognormal distributions were only selected for T p in C2-sea and C3-sea, respectively. For H s , Lonowe predominated, except for C1-sea (Weibull 2P).

4.2. Fitting of the Joint Distribution

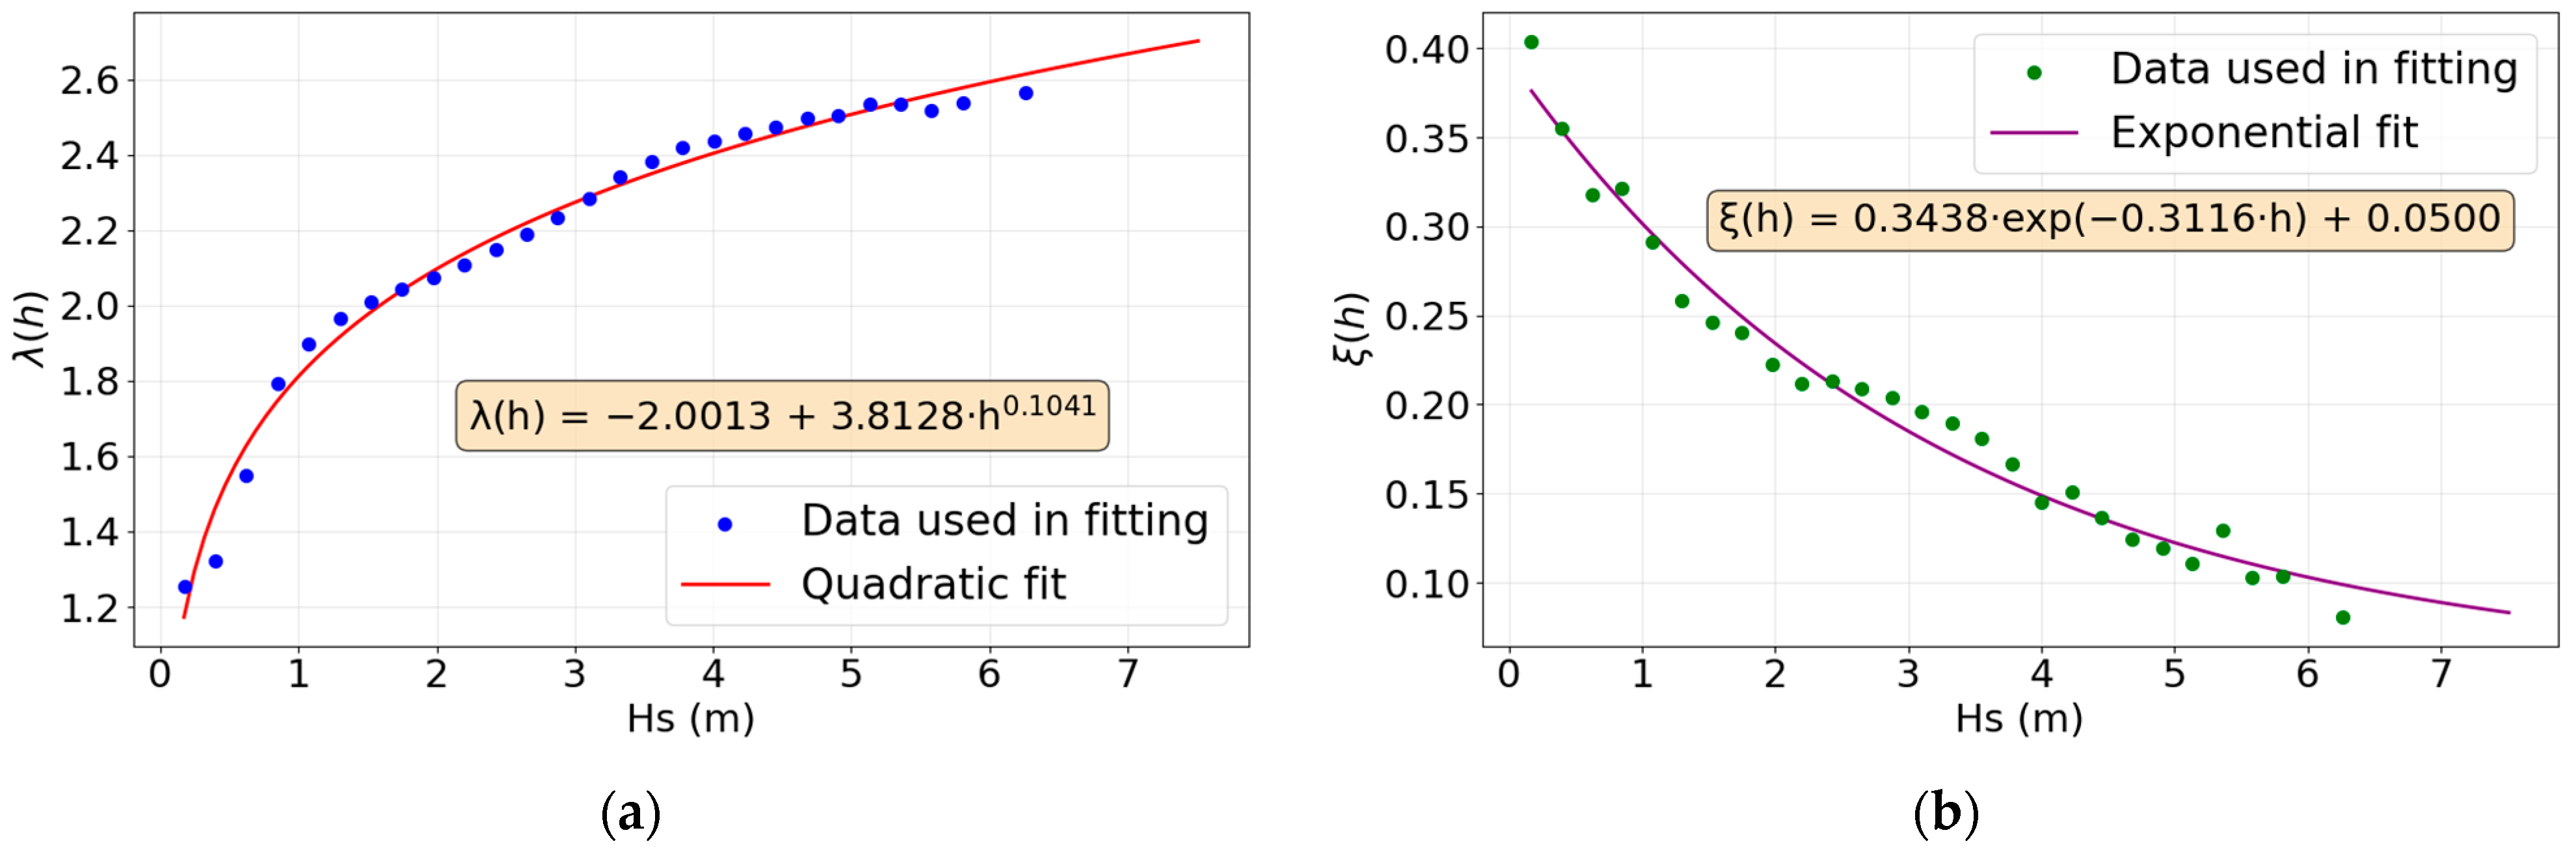
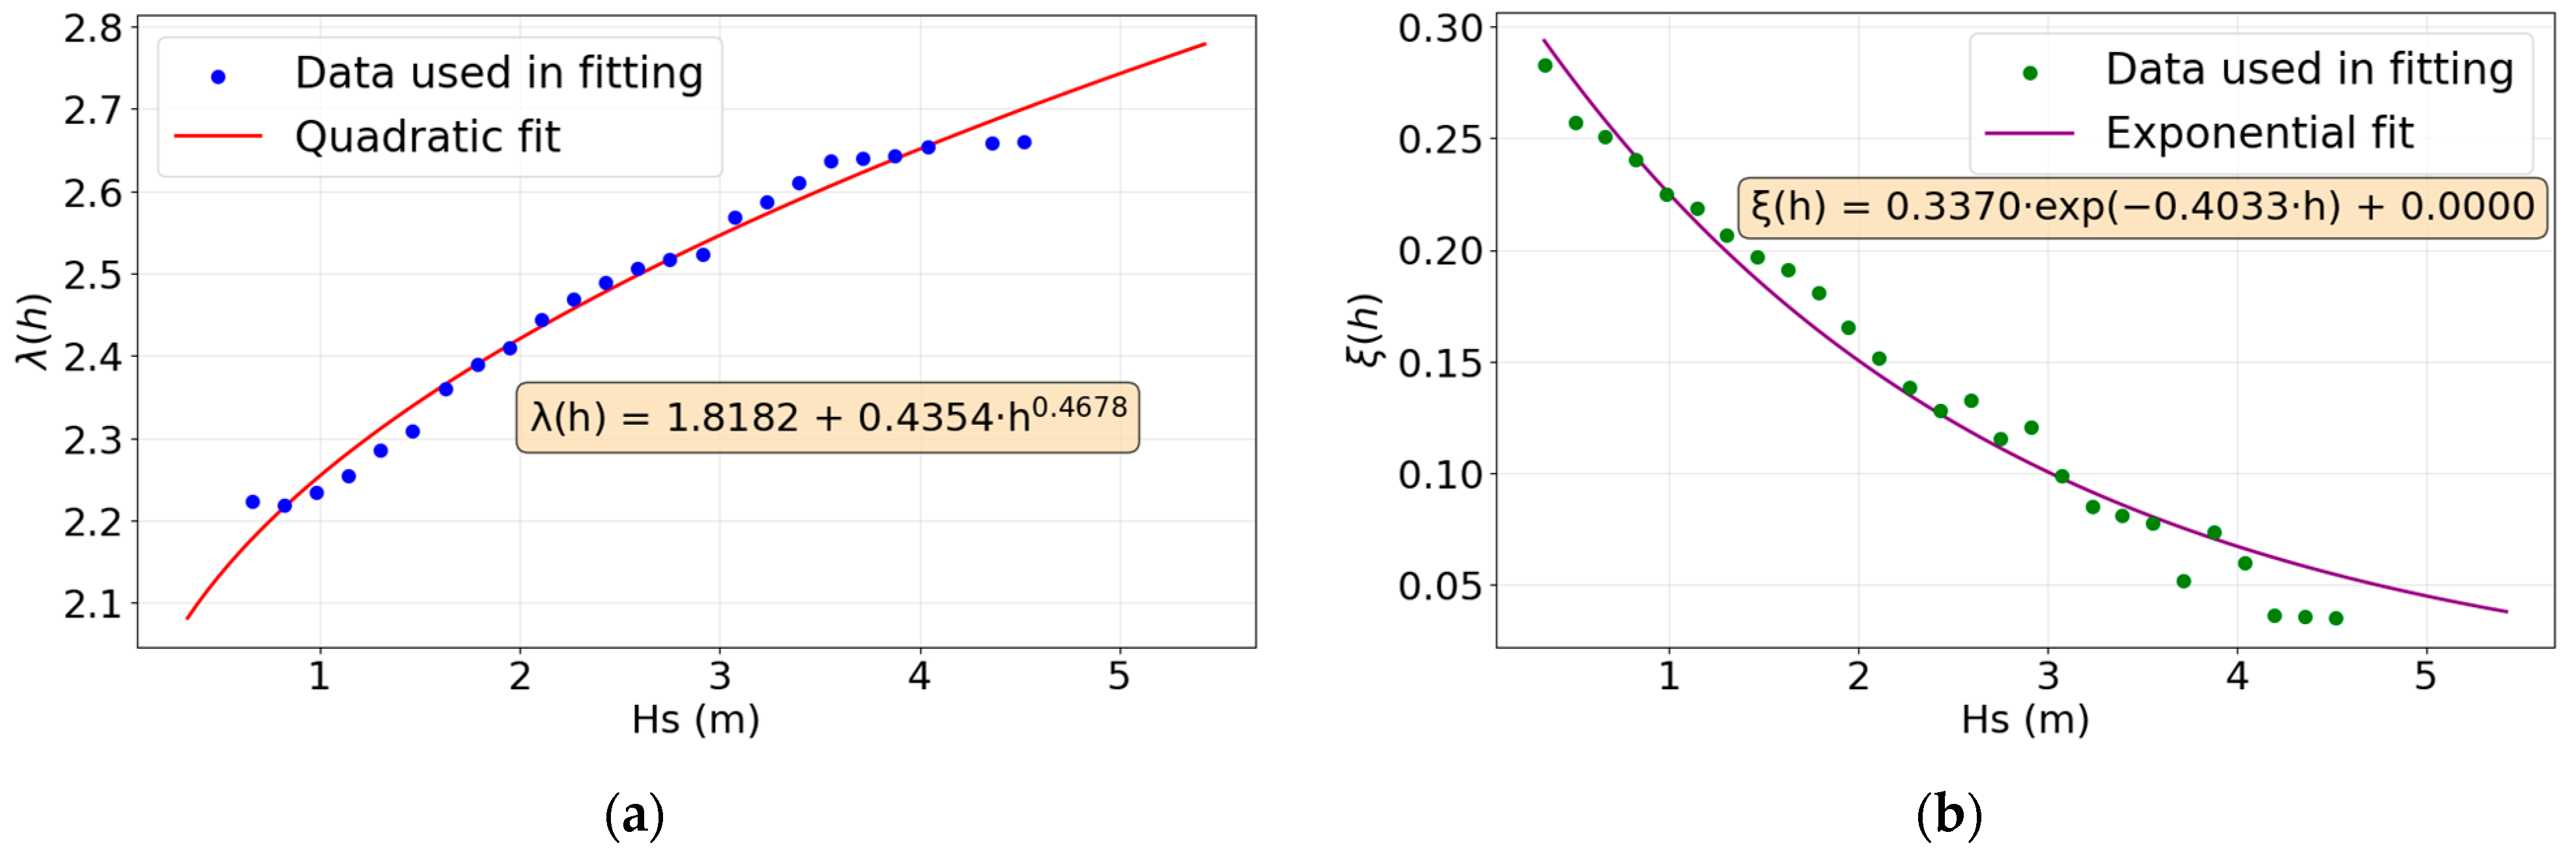
In the CMA, the coefficients of the parametric functions λ h s and ξ h s (Equations (5) and (6)) were estimated for each scenario. As an example, Figure 4 and Figure 5 illustrate the fitting for Set C2 for the sea and swell components. The fitted curves showed good agreement with the point estimates.
Table 6 summarizes the estimated parameters for the eight copula families in each scenario, obtained by the method of moments and maximum likelihood (IFM). In general, the estimated parameters by both methods were quite similar. In the few cases where the estimates diverged, the most appropriate set of parameters was selected based on visual inspection, prioritizing the model that best captured the observed statistical dependence structure. It can be observed that the parameters consistently reflect the intensity of the dependence coefficients: high values for C1-sea and values close to zero in the low dependence coefficient scenarios (C2-swell, C3-swell).

4.3. Analysis by Dependence Coefficient Levels

Based on the fitted models, a comparative performance analysis is presented for each regime of dependence coefficient magnitude (Table 3), integrating the four evaluation criteria described in Section 3.4.

4.3.1. High Dependence Coefficient Levels

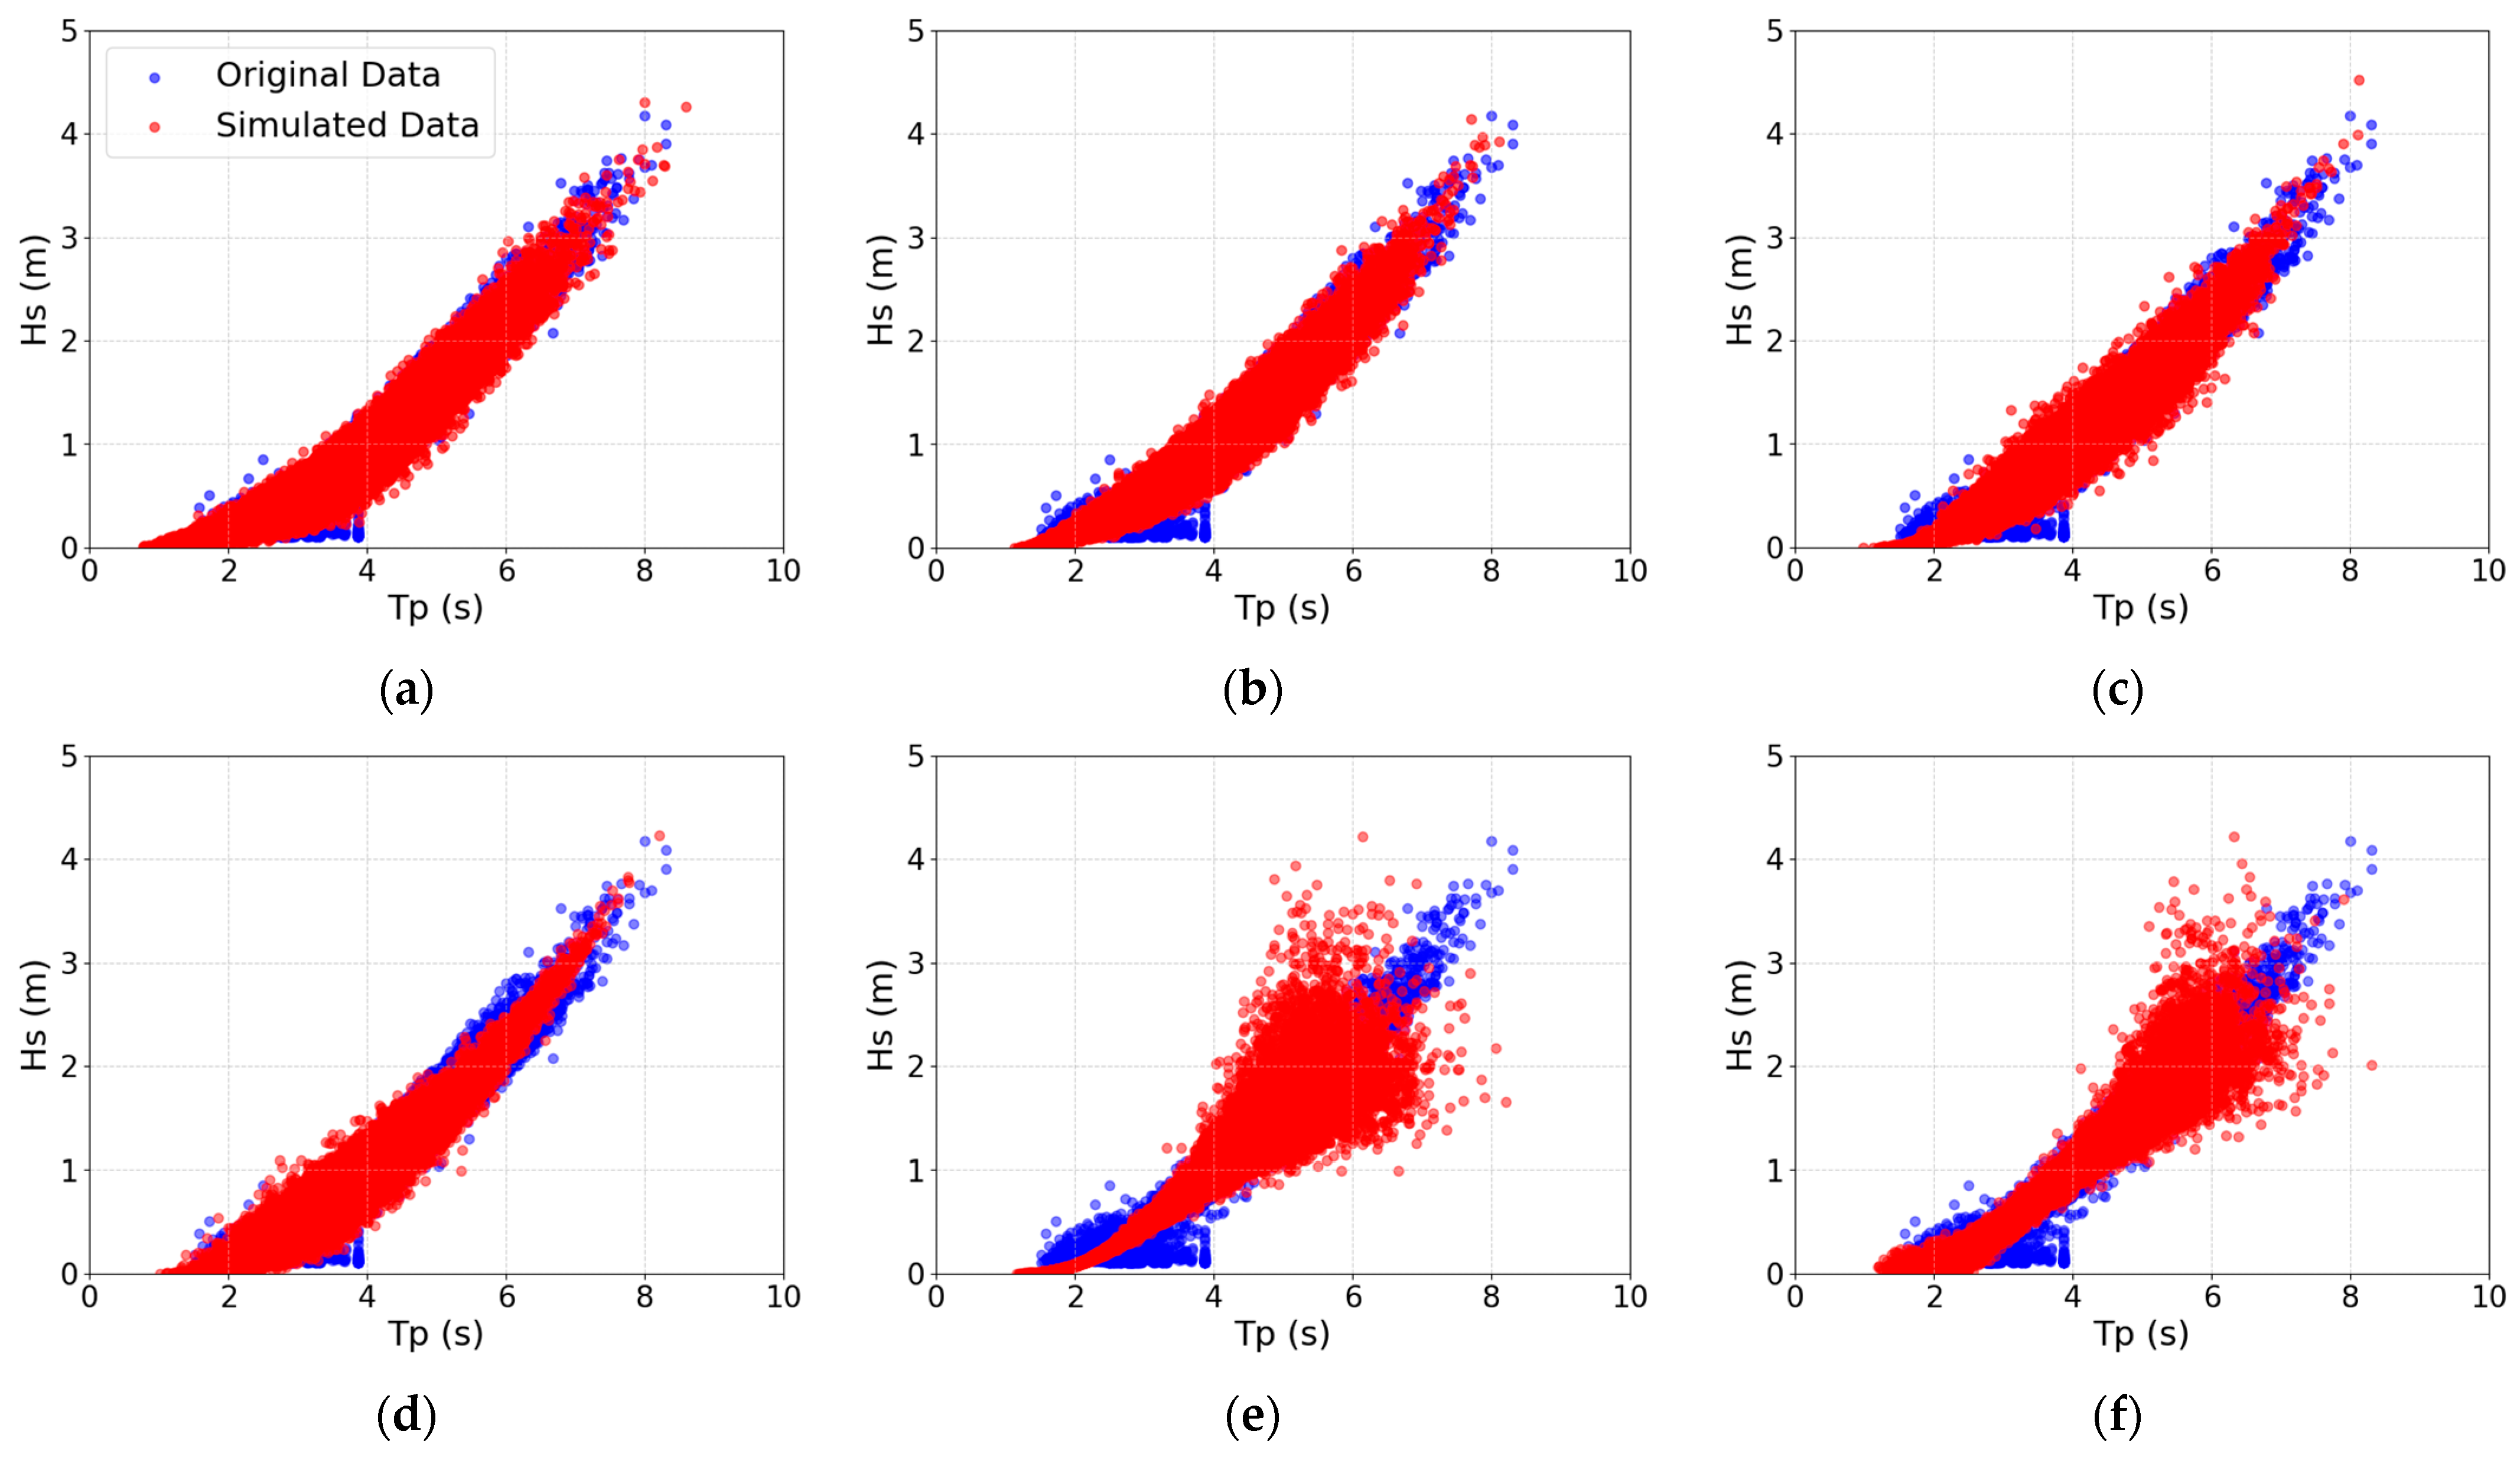
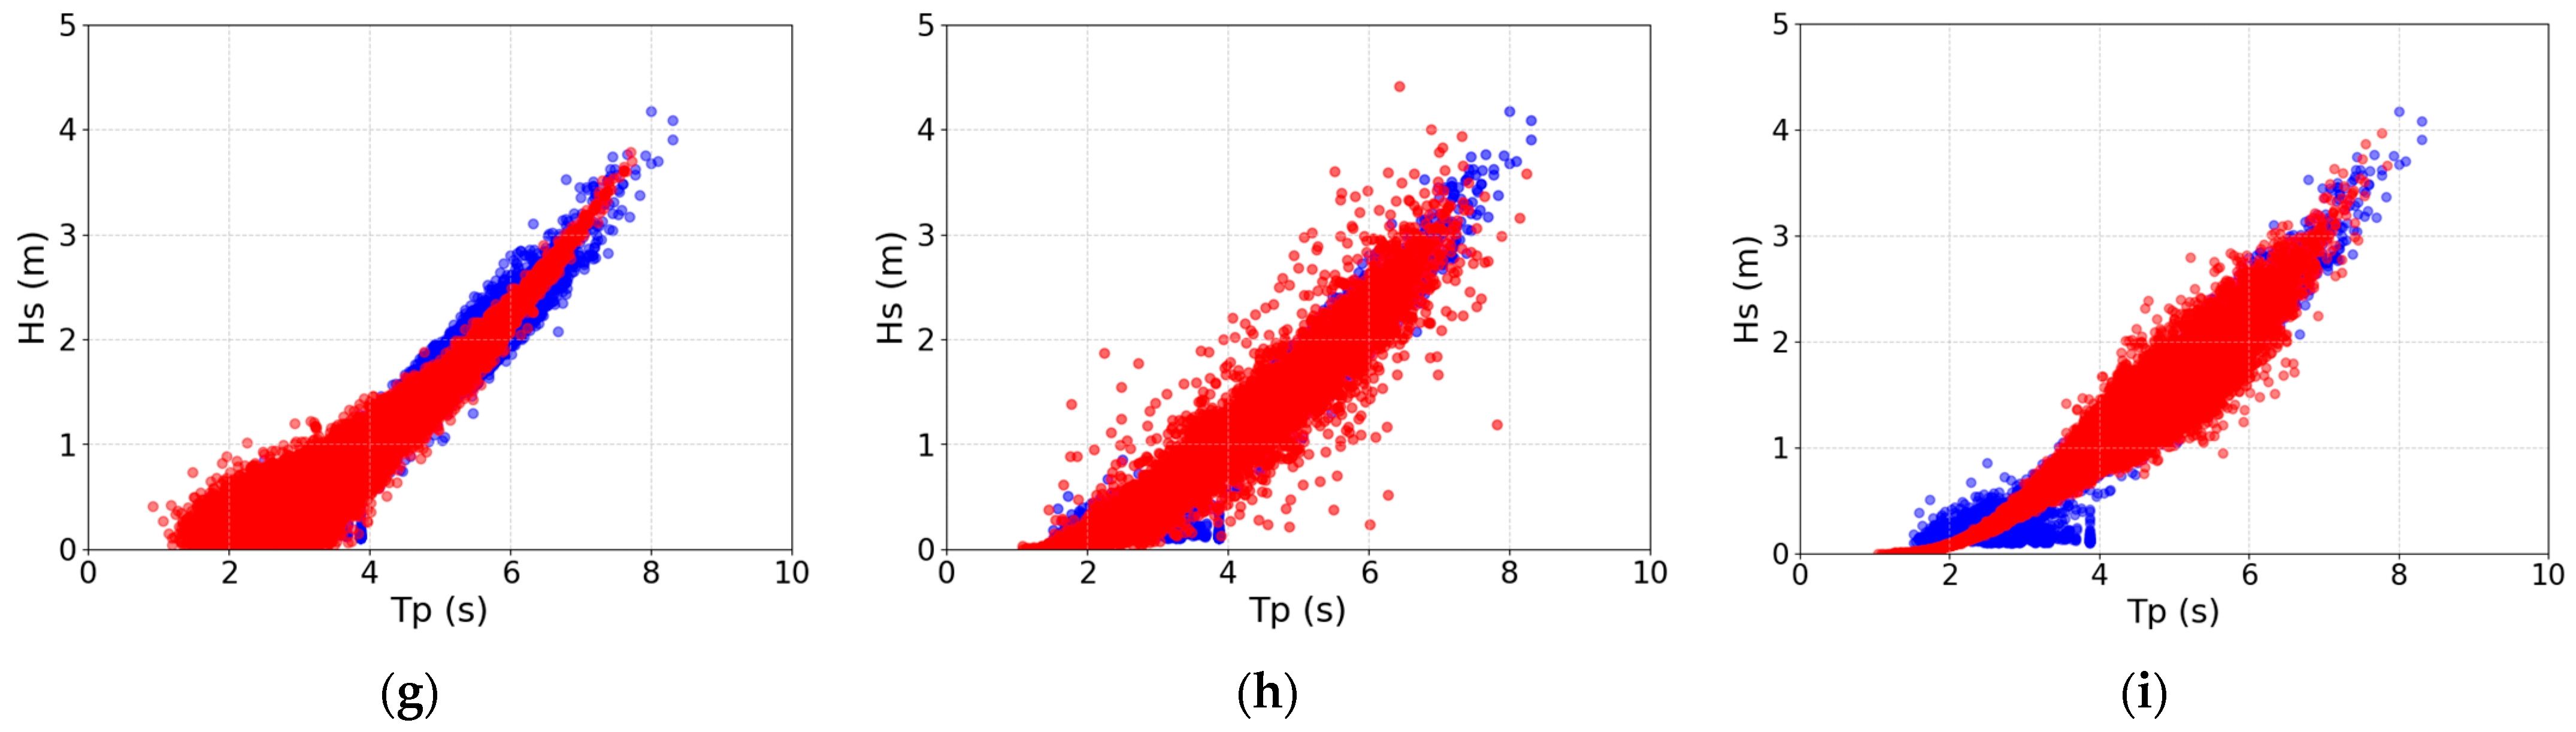
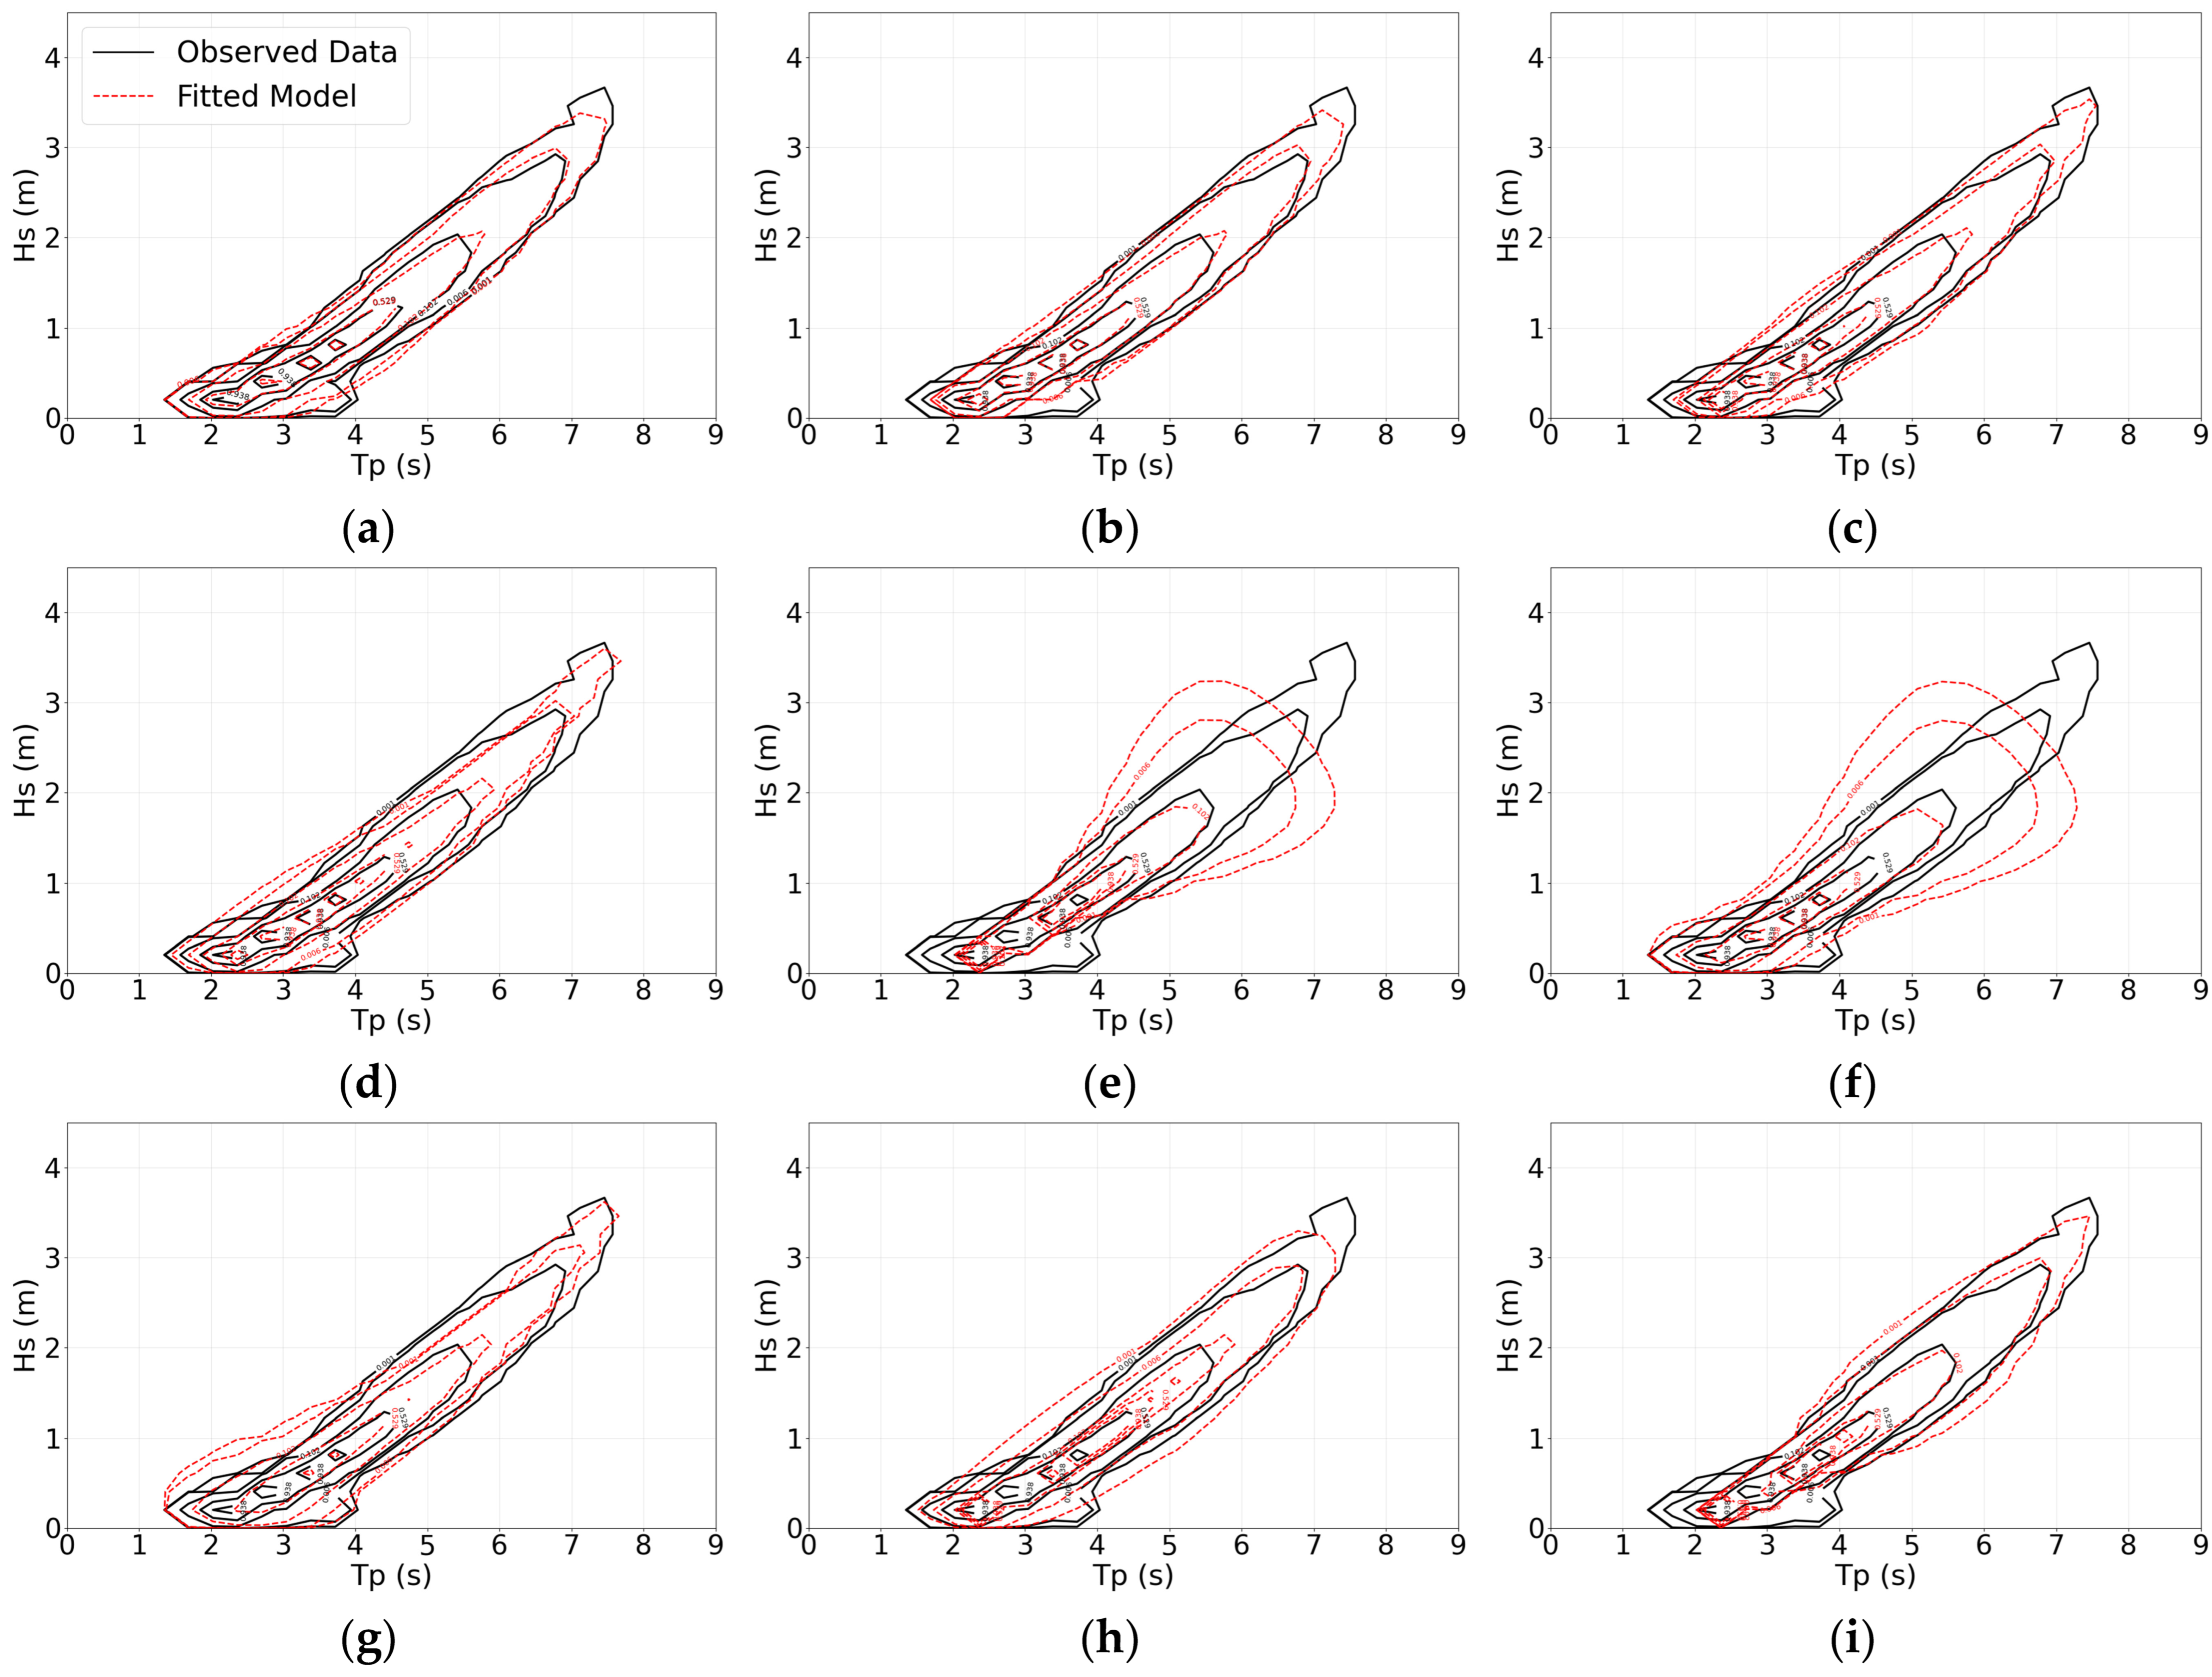
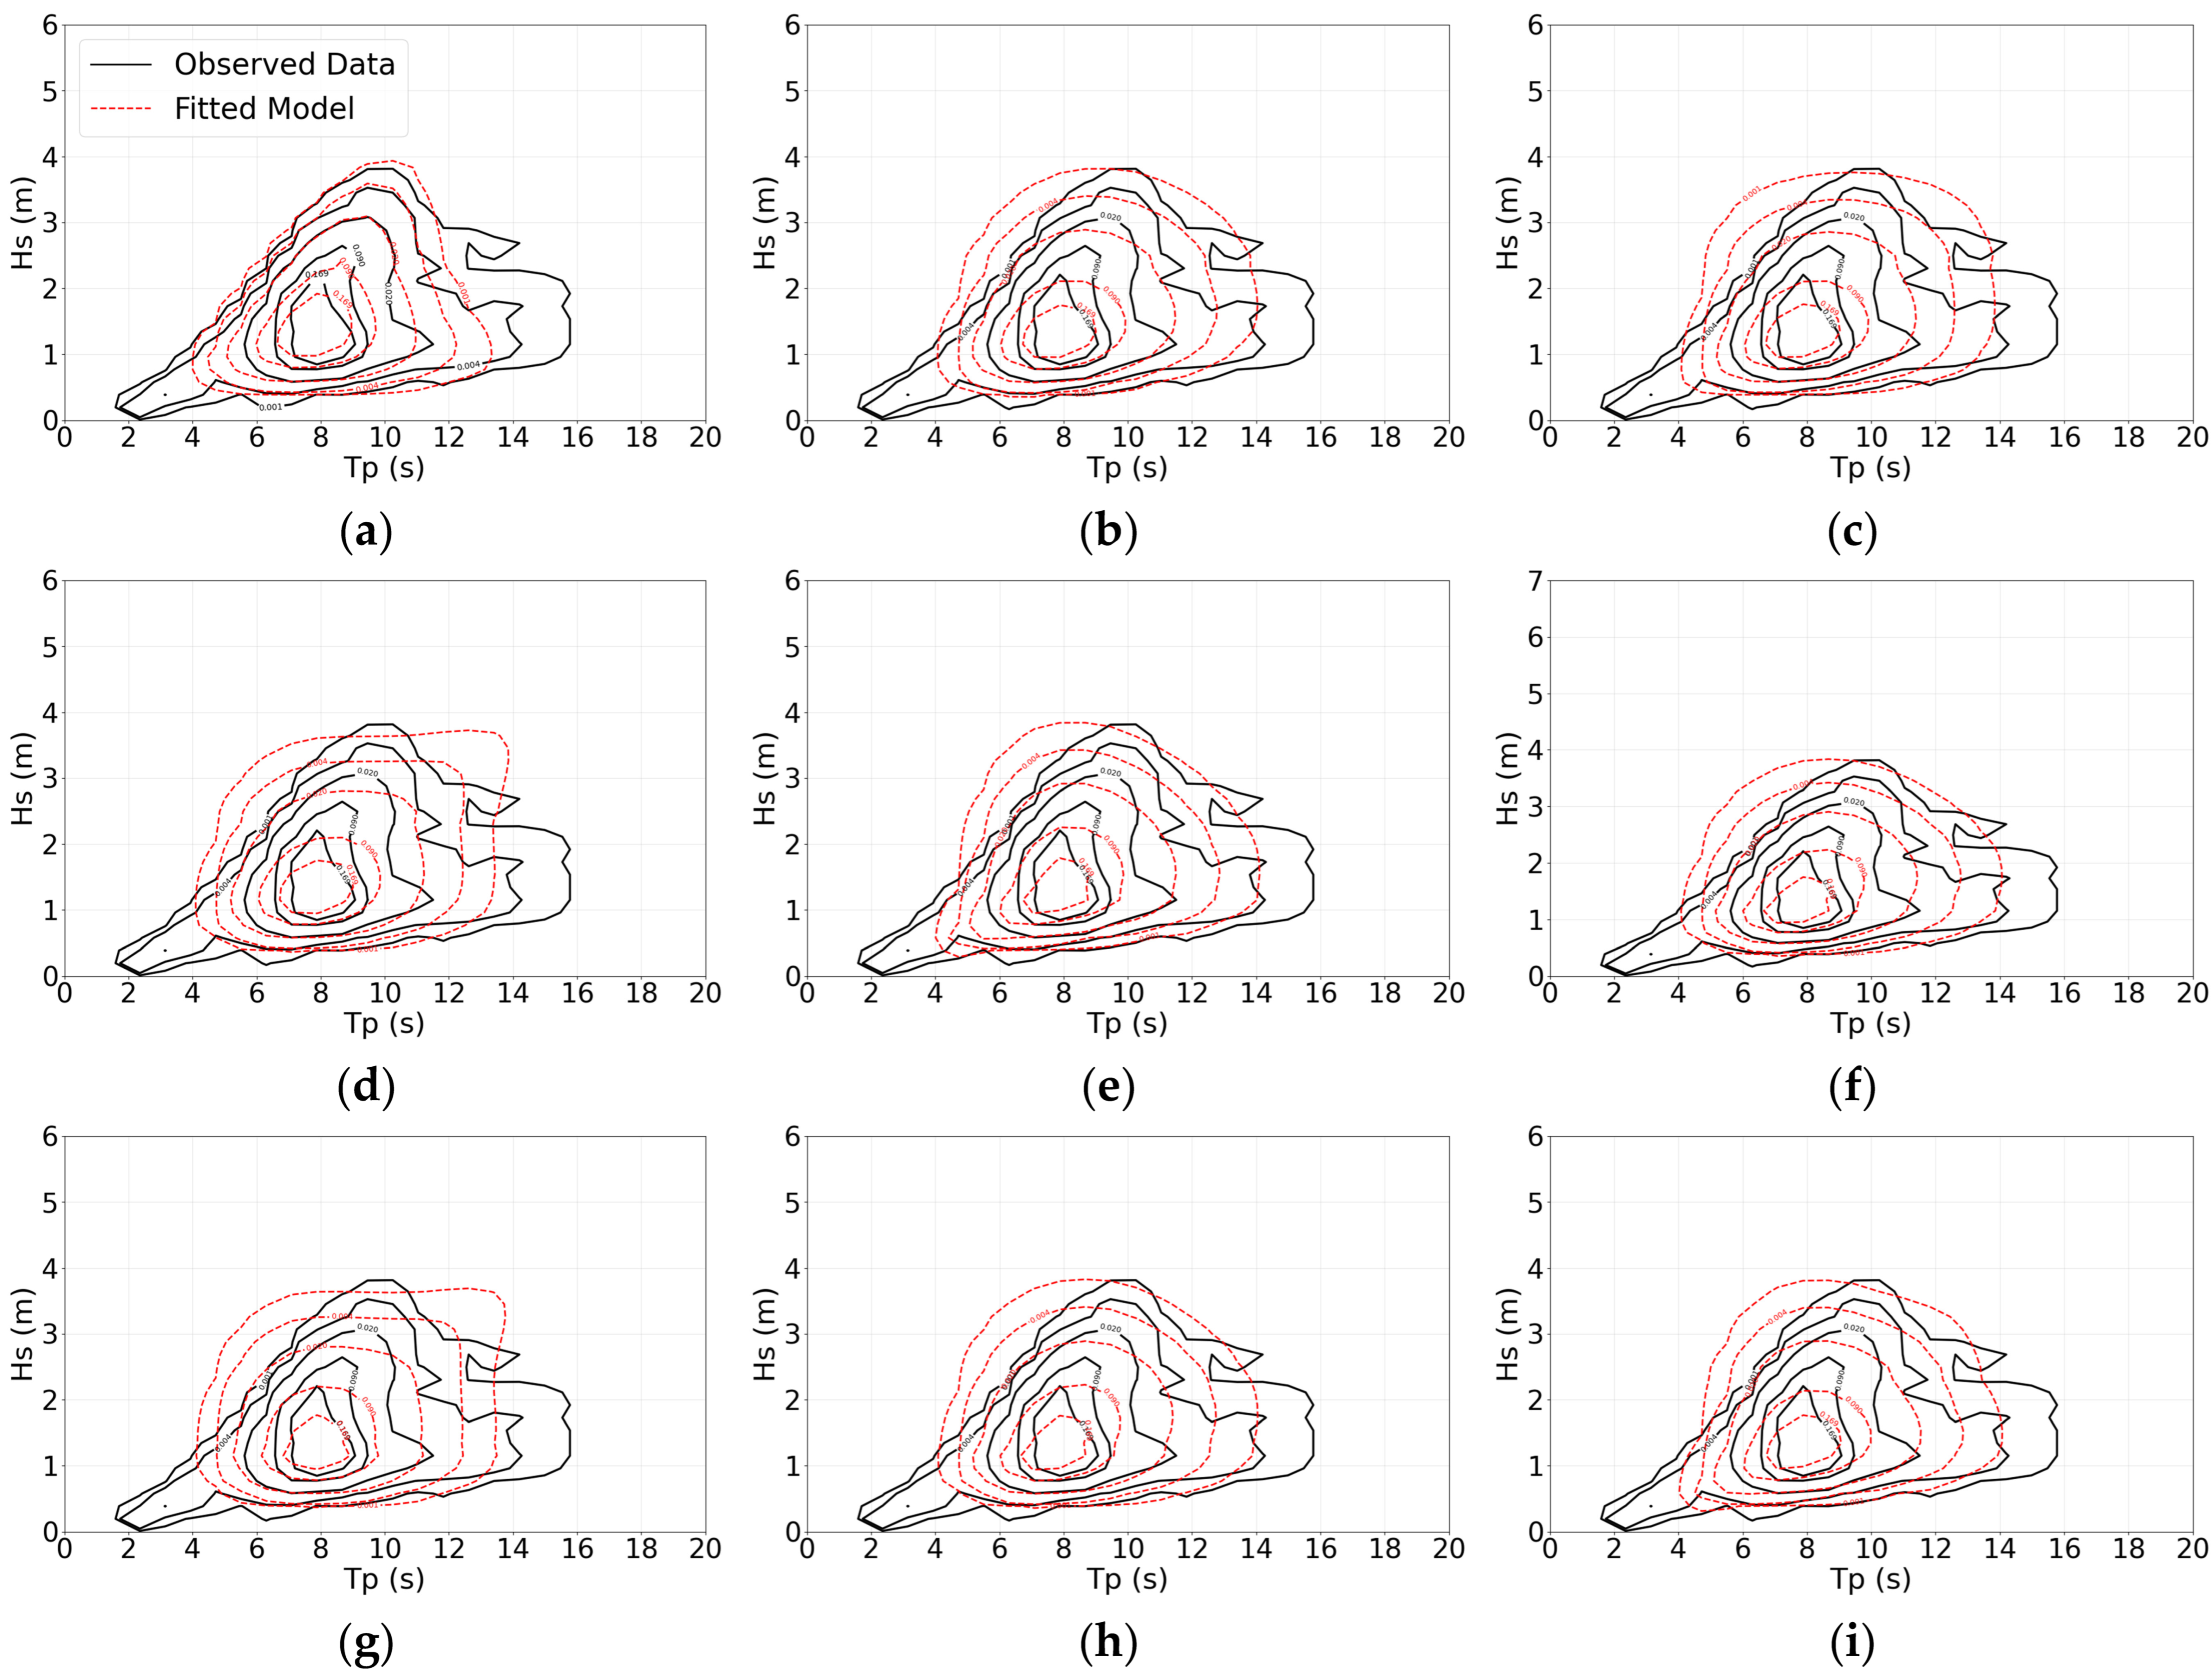
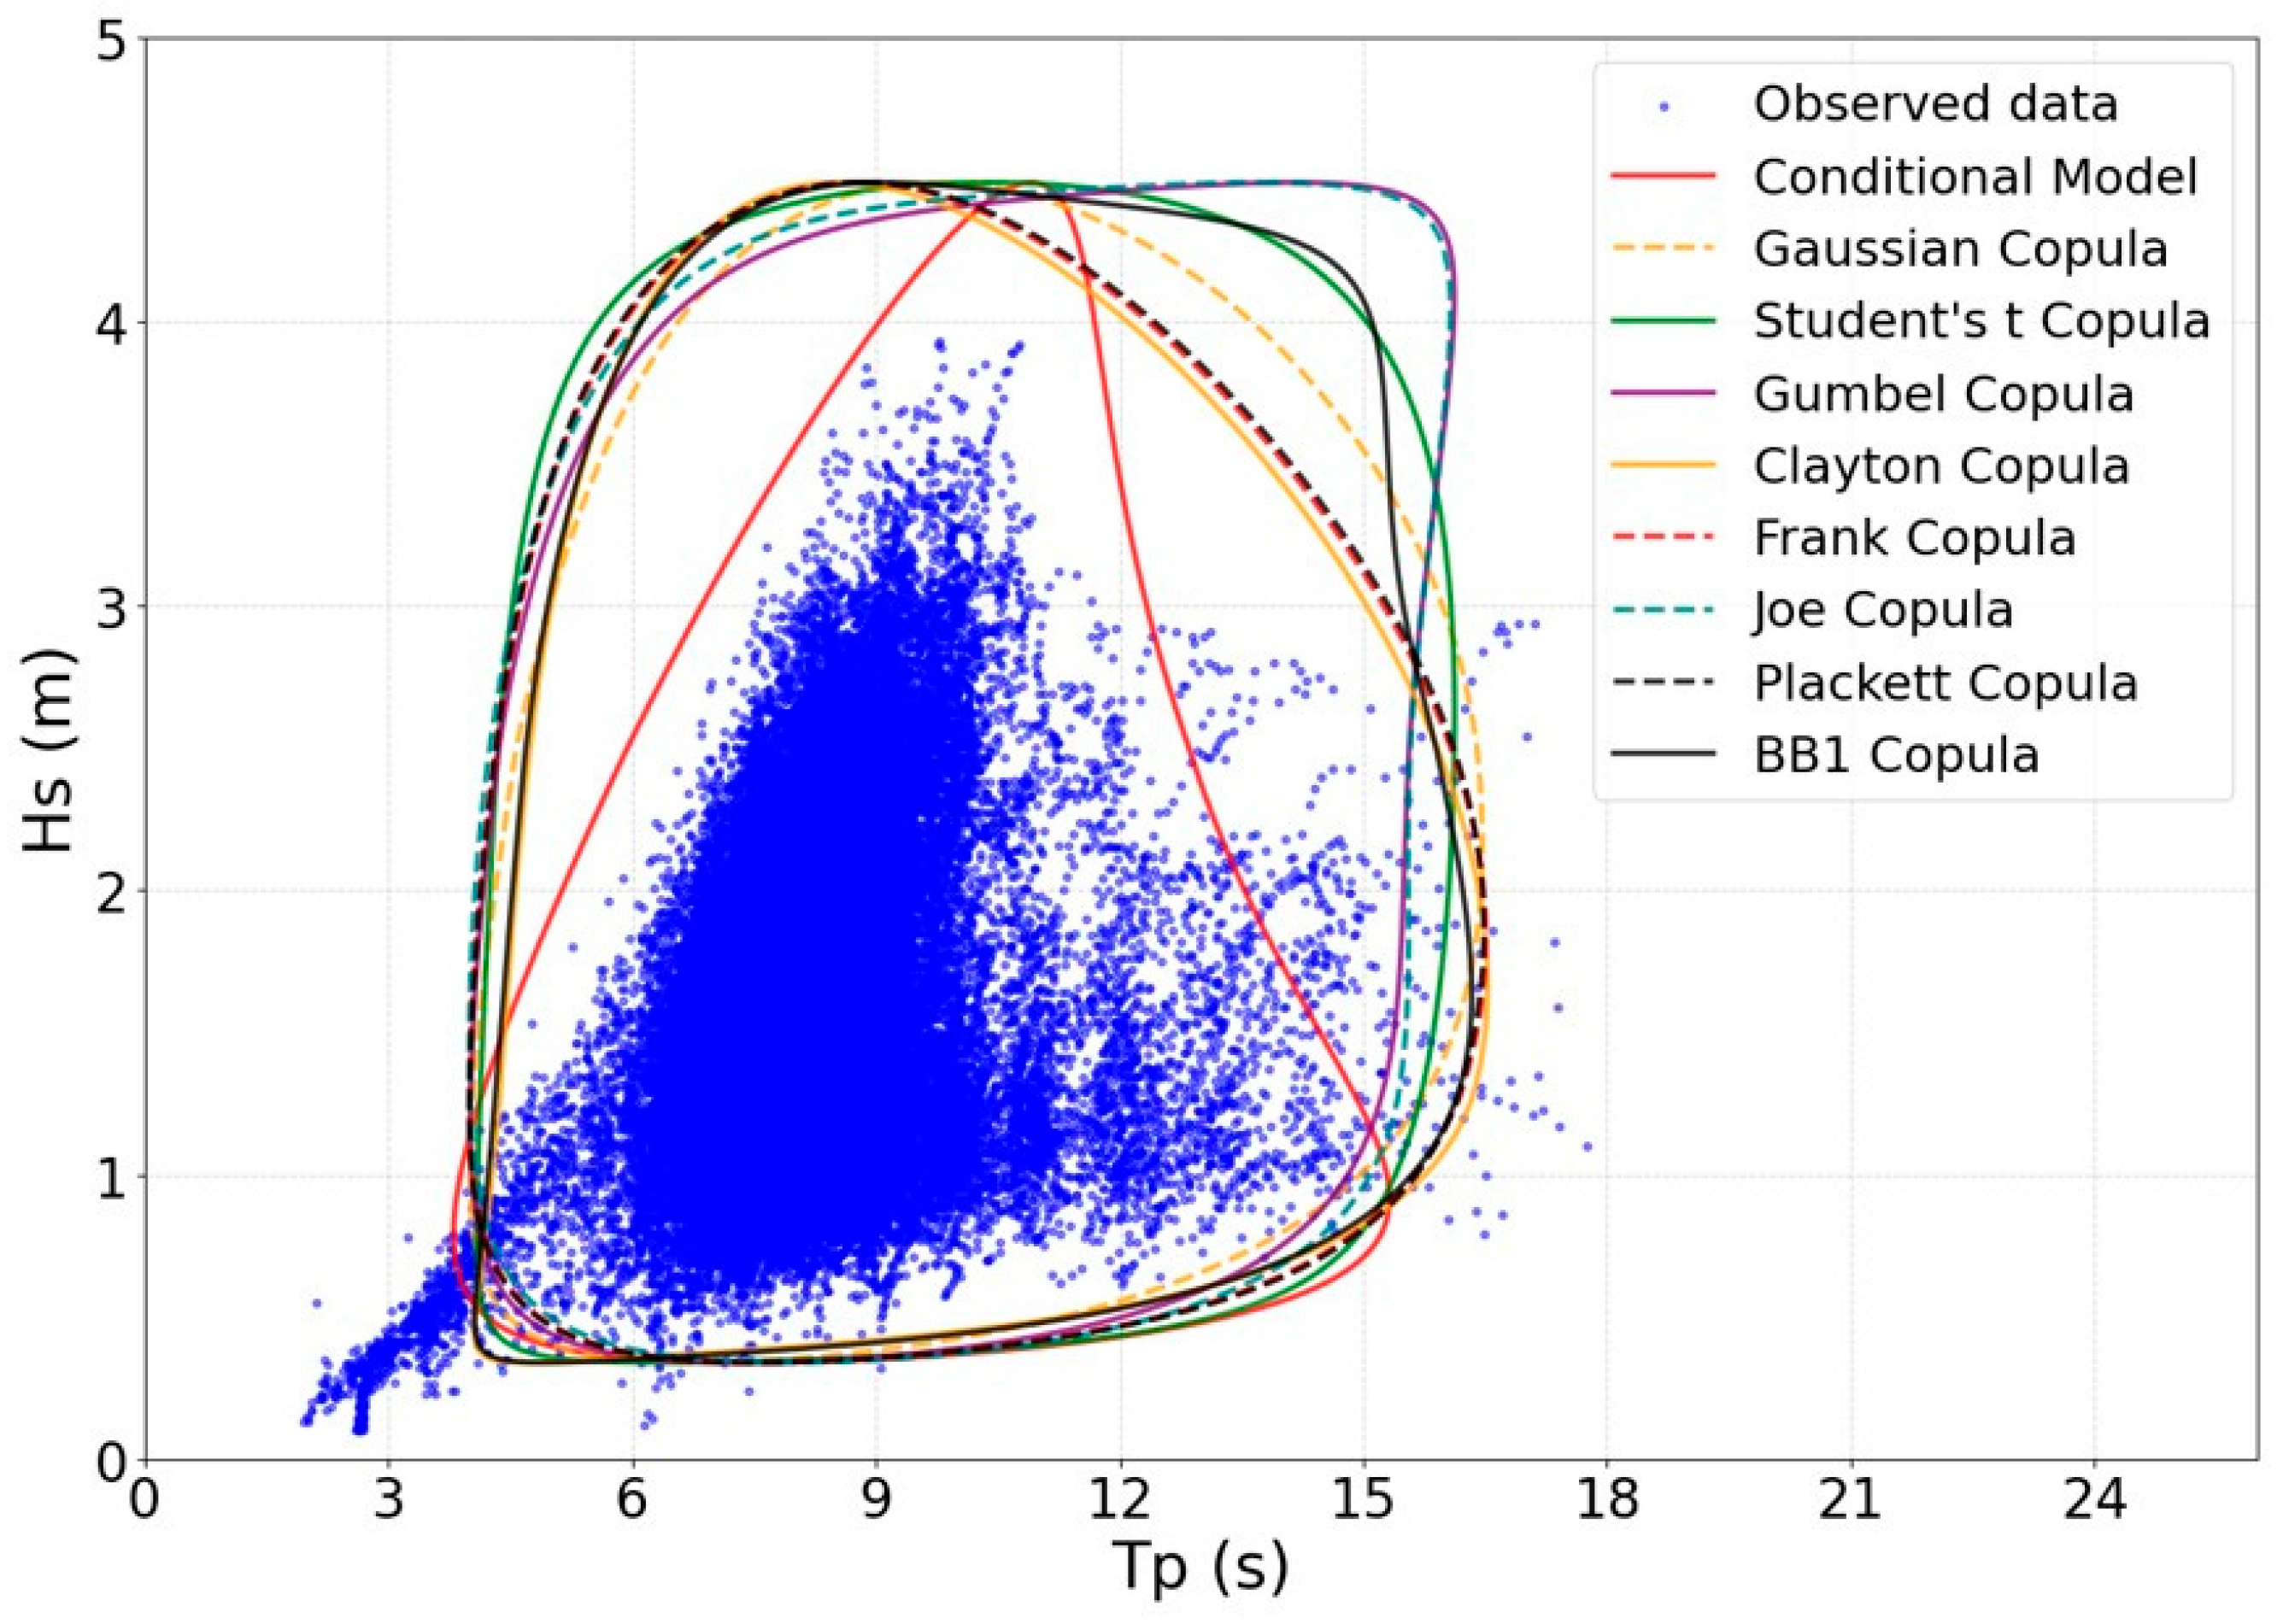
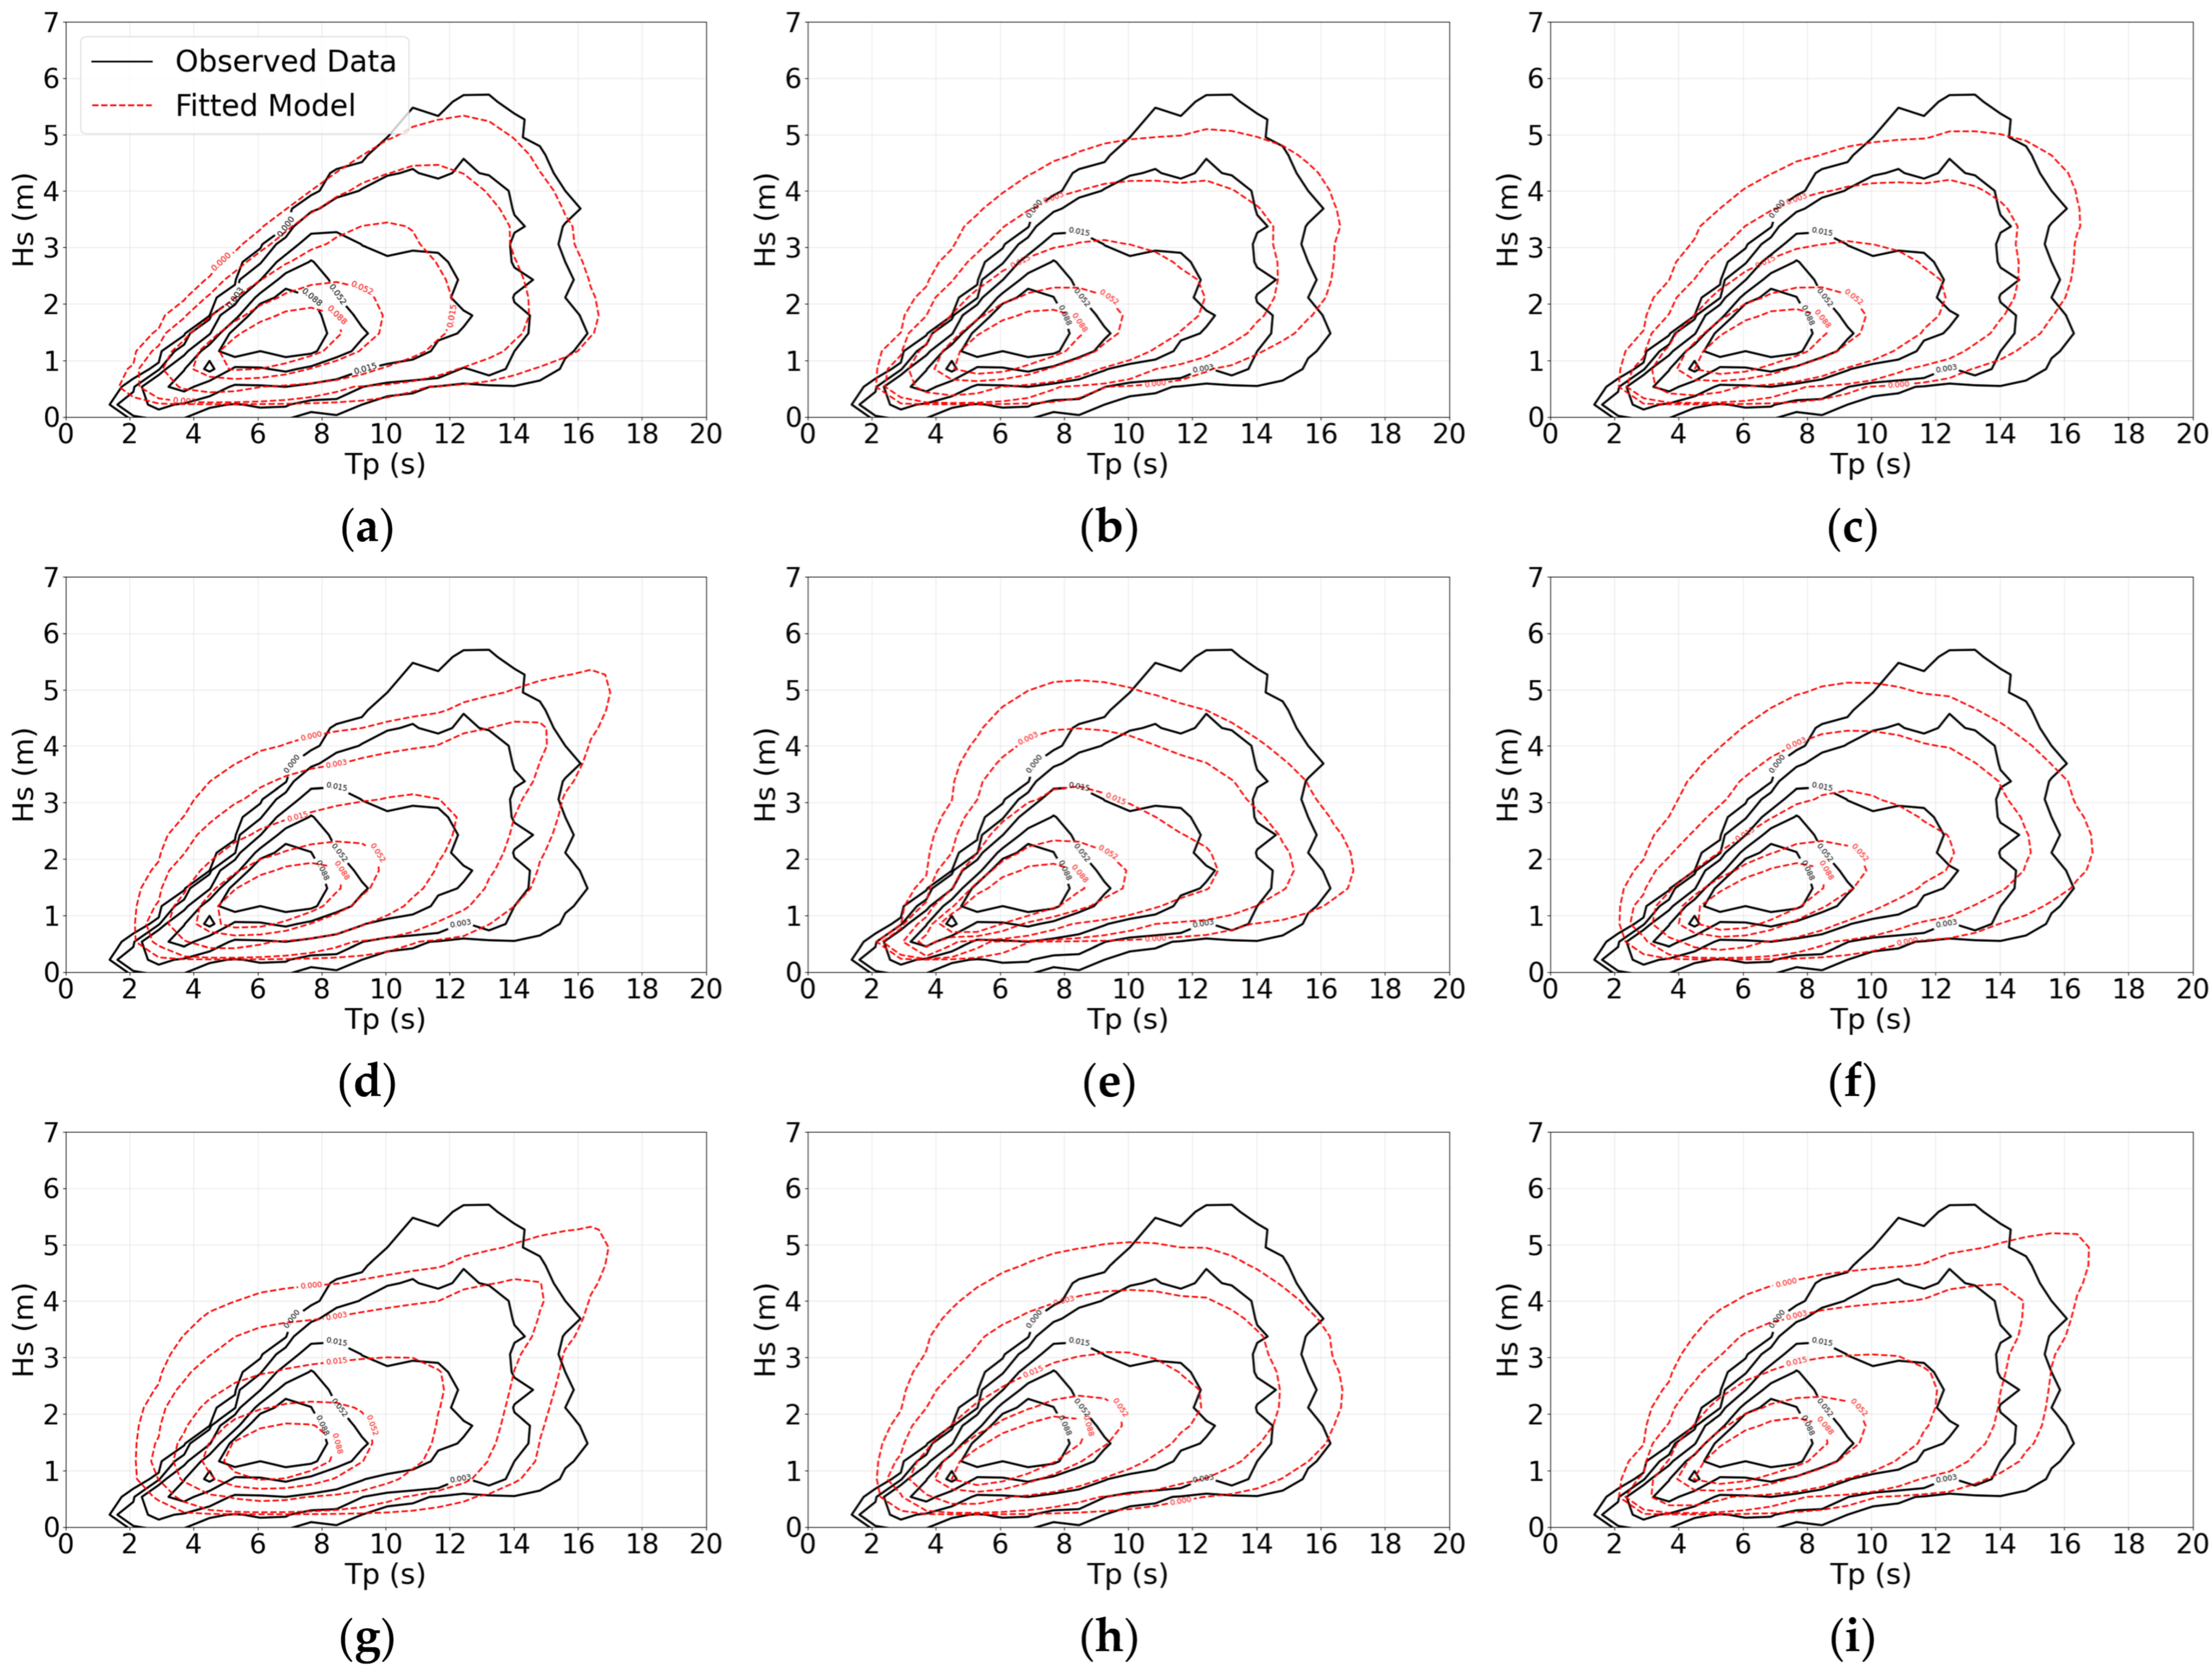
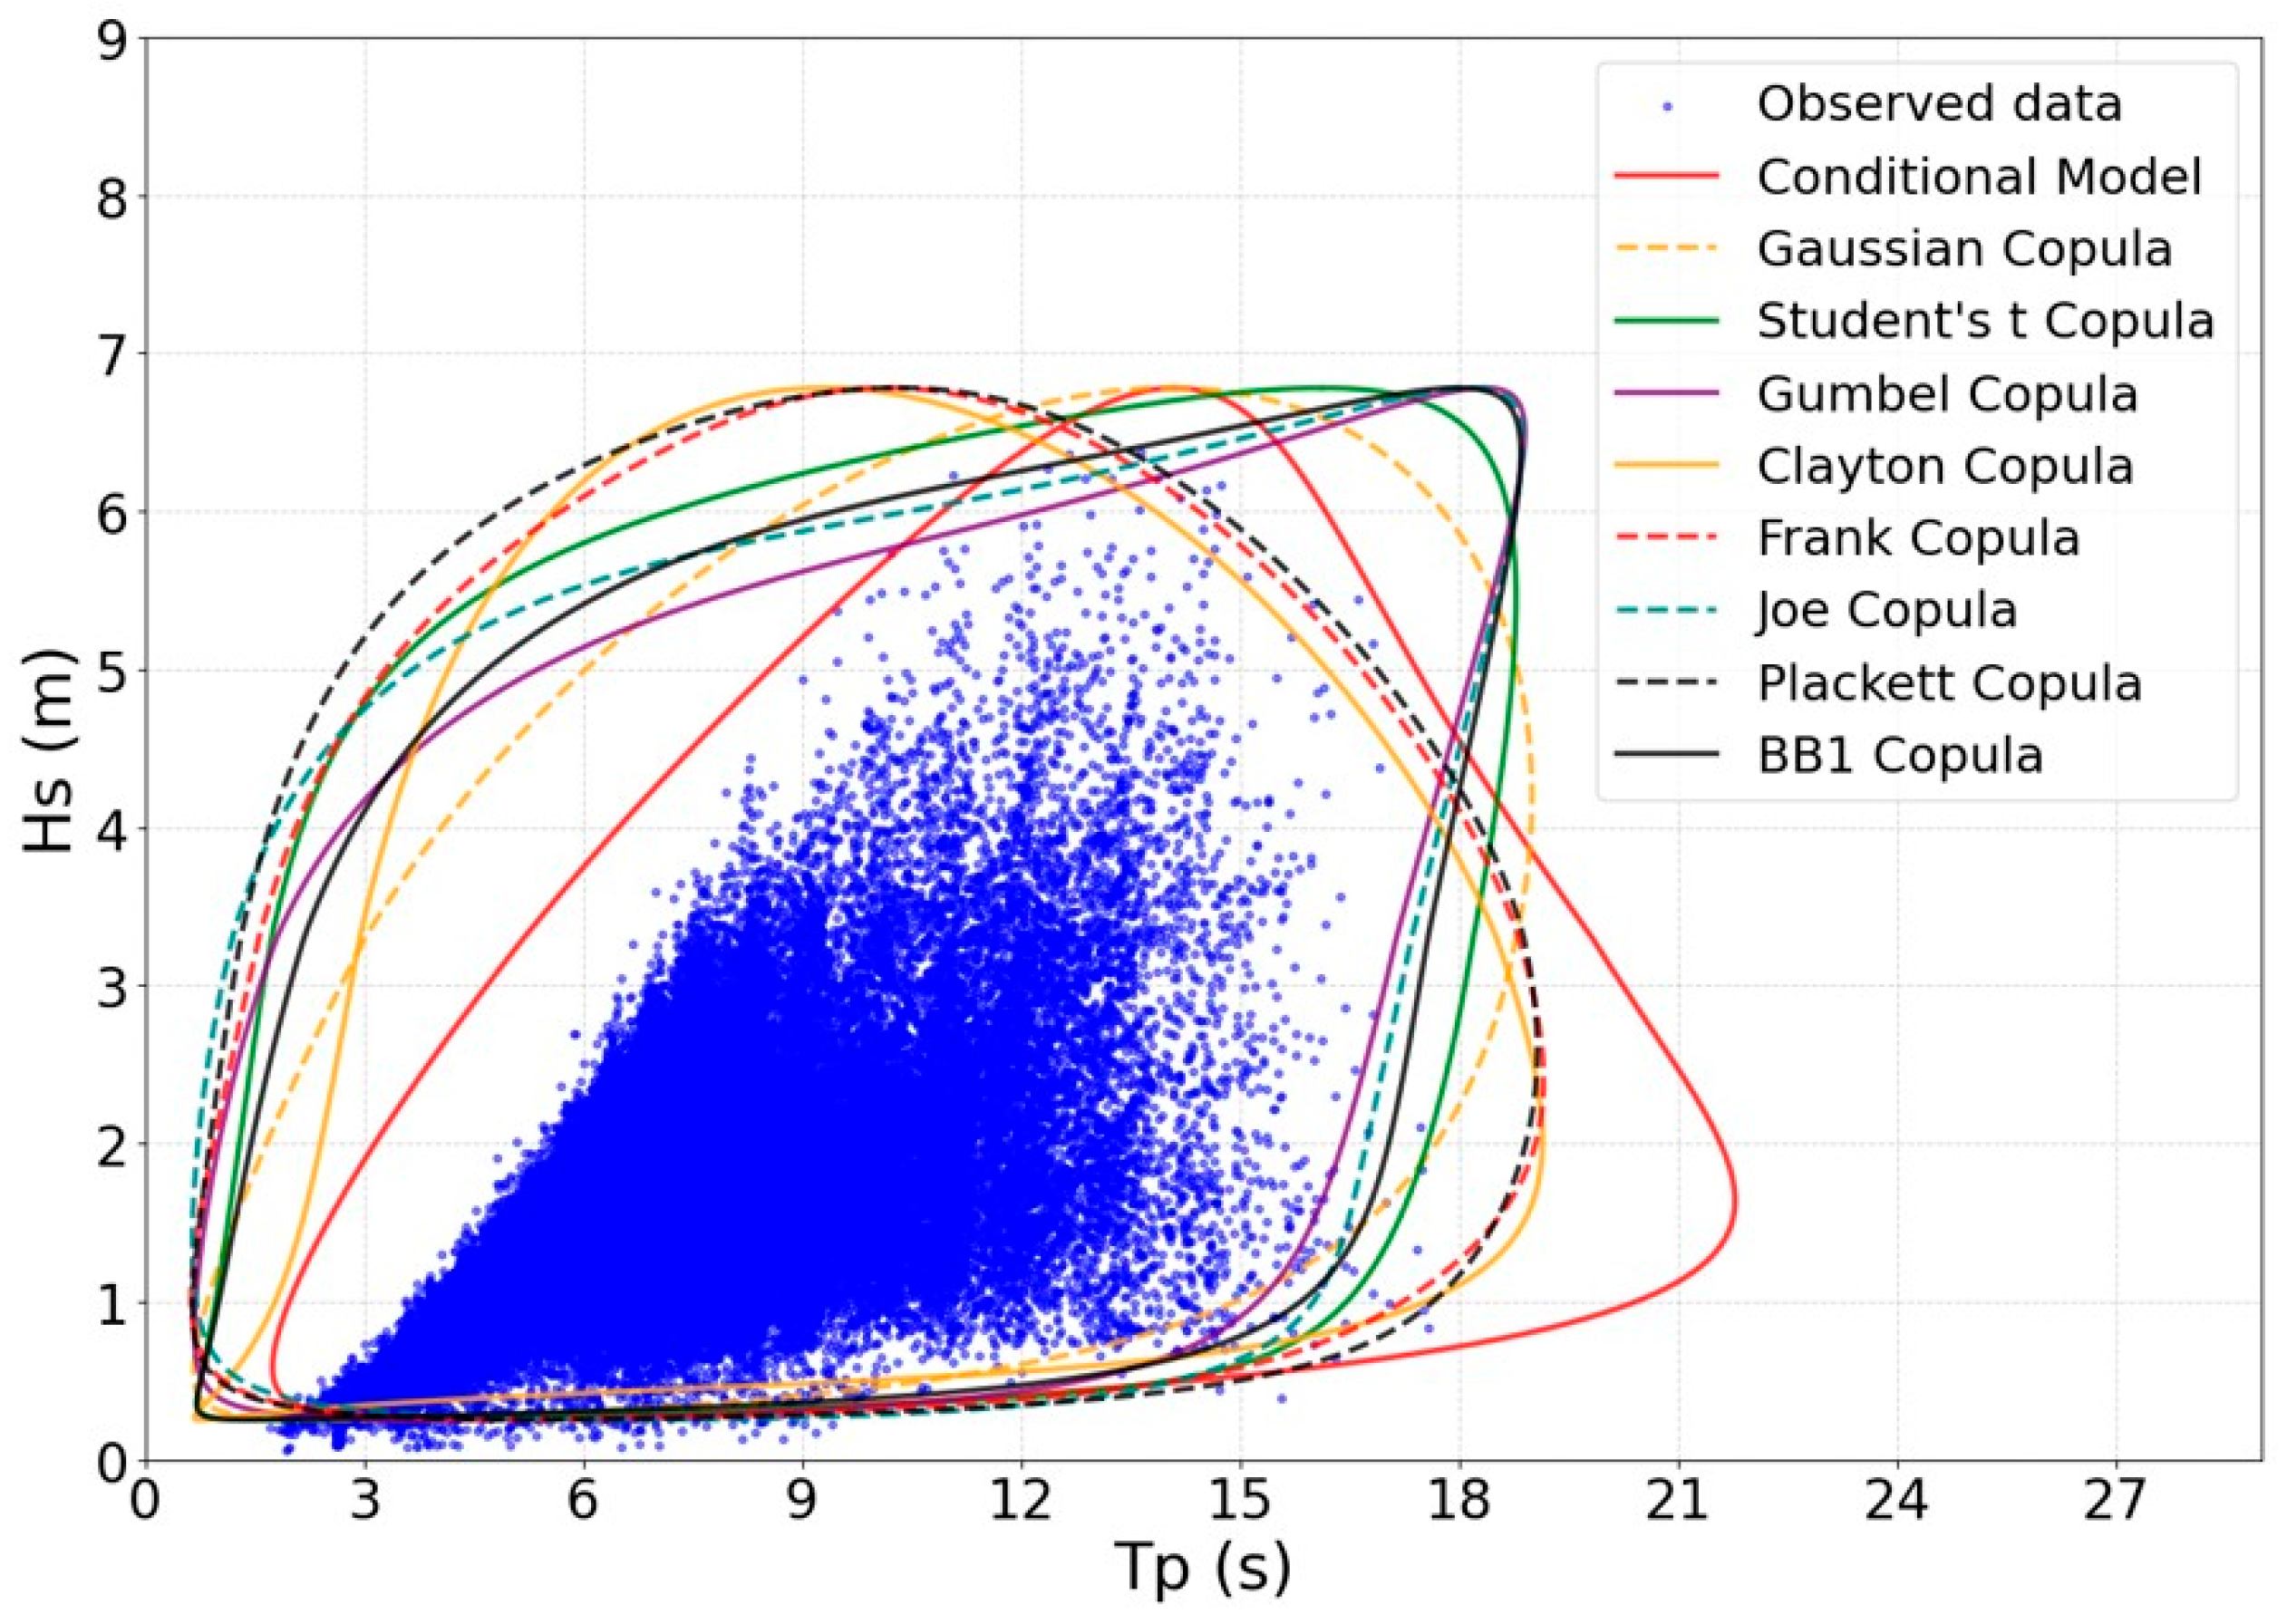
Set C1 in the sea wave component (C1-sea) presents the highest dependence coefficients among all scenarios (Table 3). In this context, the CMA and the elliptical copulas (Gaussian and Student’s t) showed superior and equivalent performance, reproducing with high fidelity the observed scatter plot and the iso-probability curves throughout the data domain, as illustrated in Figure 6 and Figure 7. The environmental contours generated for the 20-year return period (Figure 8) show that the CMA and the Gaussian copula almost perfectly coincide with the boundary of the observed data. The Student’s t copula, although visually close, presented small distortions in the environmental contour in the central region. The choice of the joint probability distribution model may consider the type of structural analysis to be performed and the structure’s dynamic behavior. In general terms, for fatigue analysis, for example, accuracy in the central region perhaps is most relevant; on the other hand, for extreme responses, accuracy in the distribution tails can be more critical [2,5]. In practice, however, a single model is often sought for all structural analyses. In this context, the CMA and the Gaussian and Student’s t copulas accurately represented both the central region and the upper tail, making them suitable for both purposes. The Gumbel, Joe, and BB1 copulas reasonably reproduced the central region of the distribution but underestimated the upper tail, resulting in non-conservative contours for long return periods. Thus, while they may be adequate for fatigue, their use for extreme responses requires caution. The Clayton, Frank, and Plackett copulas showed unsatisfactory performance, with synthetic scatter plots clearly distinct from the observed one, distorted iso-probability curves, and environmental contours encompassing physically improbable regions, limiting their applicability for both fatigue and extreme analyses.
The AIC and BIC criteria (Table 7) confirmed the performance of the Gaussian copula in this scenario, which presented the lowest index values, followed by the CMA. The remaining copulas exhibited significantly higher values, in agreement with the visual analyses. Among these, the Clayton copula stands out with notably higher AIC and BIC values (313,557.89 and 313,637.85, respectively), a reflection of its poor fit to the high dependence structure of C1-sea, consistent with the distorted scatter plots and physically improbable environmental contour observed.

4.3.2. Moderate Dependence Coefficient Levels

The moderate dependence coefficients scenarios encompass the swell wave component of Set C1 (C1-swell), which presents moderate-high dependence coefficients ( ρ ^ = 0.73 ;   τ ^ = 0.51 ;   ρ ^ S = 0.70 ), and the sea wave component of Set C2 (C2-sea), with typical moderate magnitude coefficients ( ρ ^ = 0.56 ;   τ ^ = 0.39 ;   ρ ^ S = 0.54 ), as per Table 3. For C1-swell, the CMA and elliptical copulas showed superior and equivalent performance across all evaluation criteria, following the same pattern observed for C1-sea (Section 4.3.1), with the Gumbel, Joe, and BB1 copulas underestimating the upper tail and the Clayton, Frank, and Plackett copulas proving inadequate.
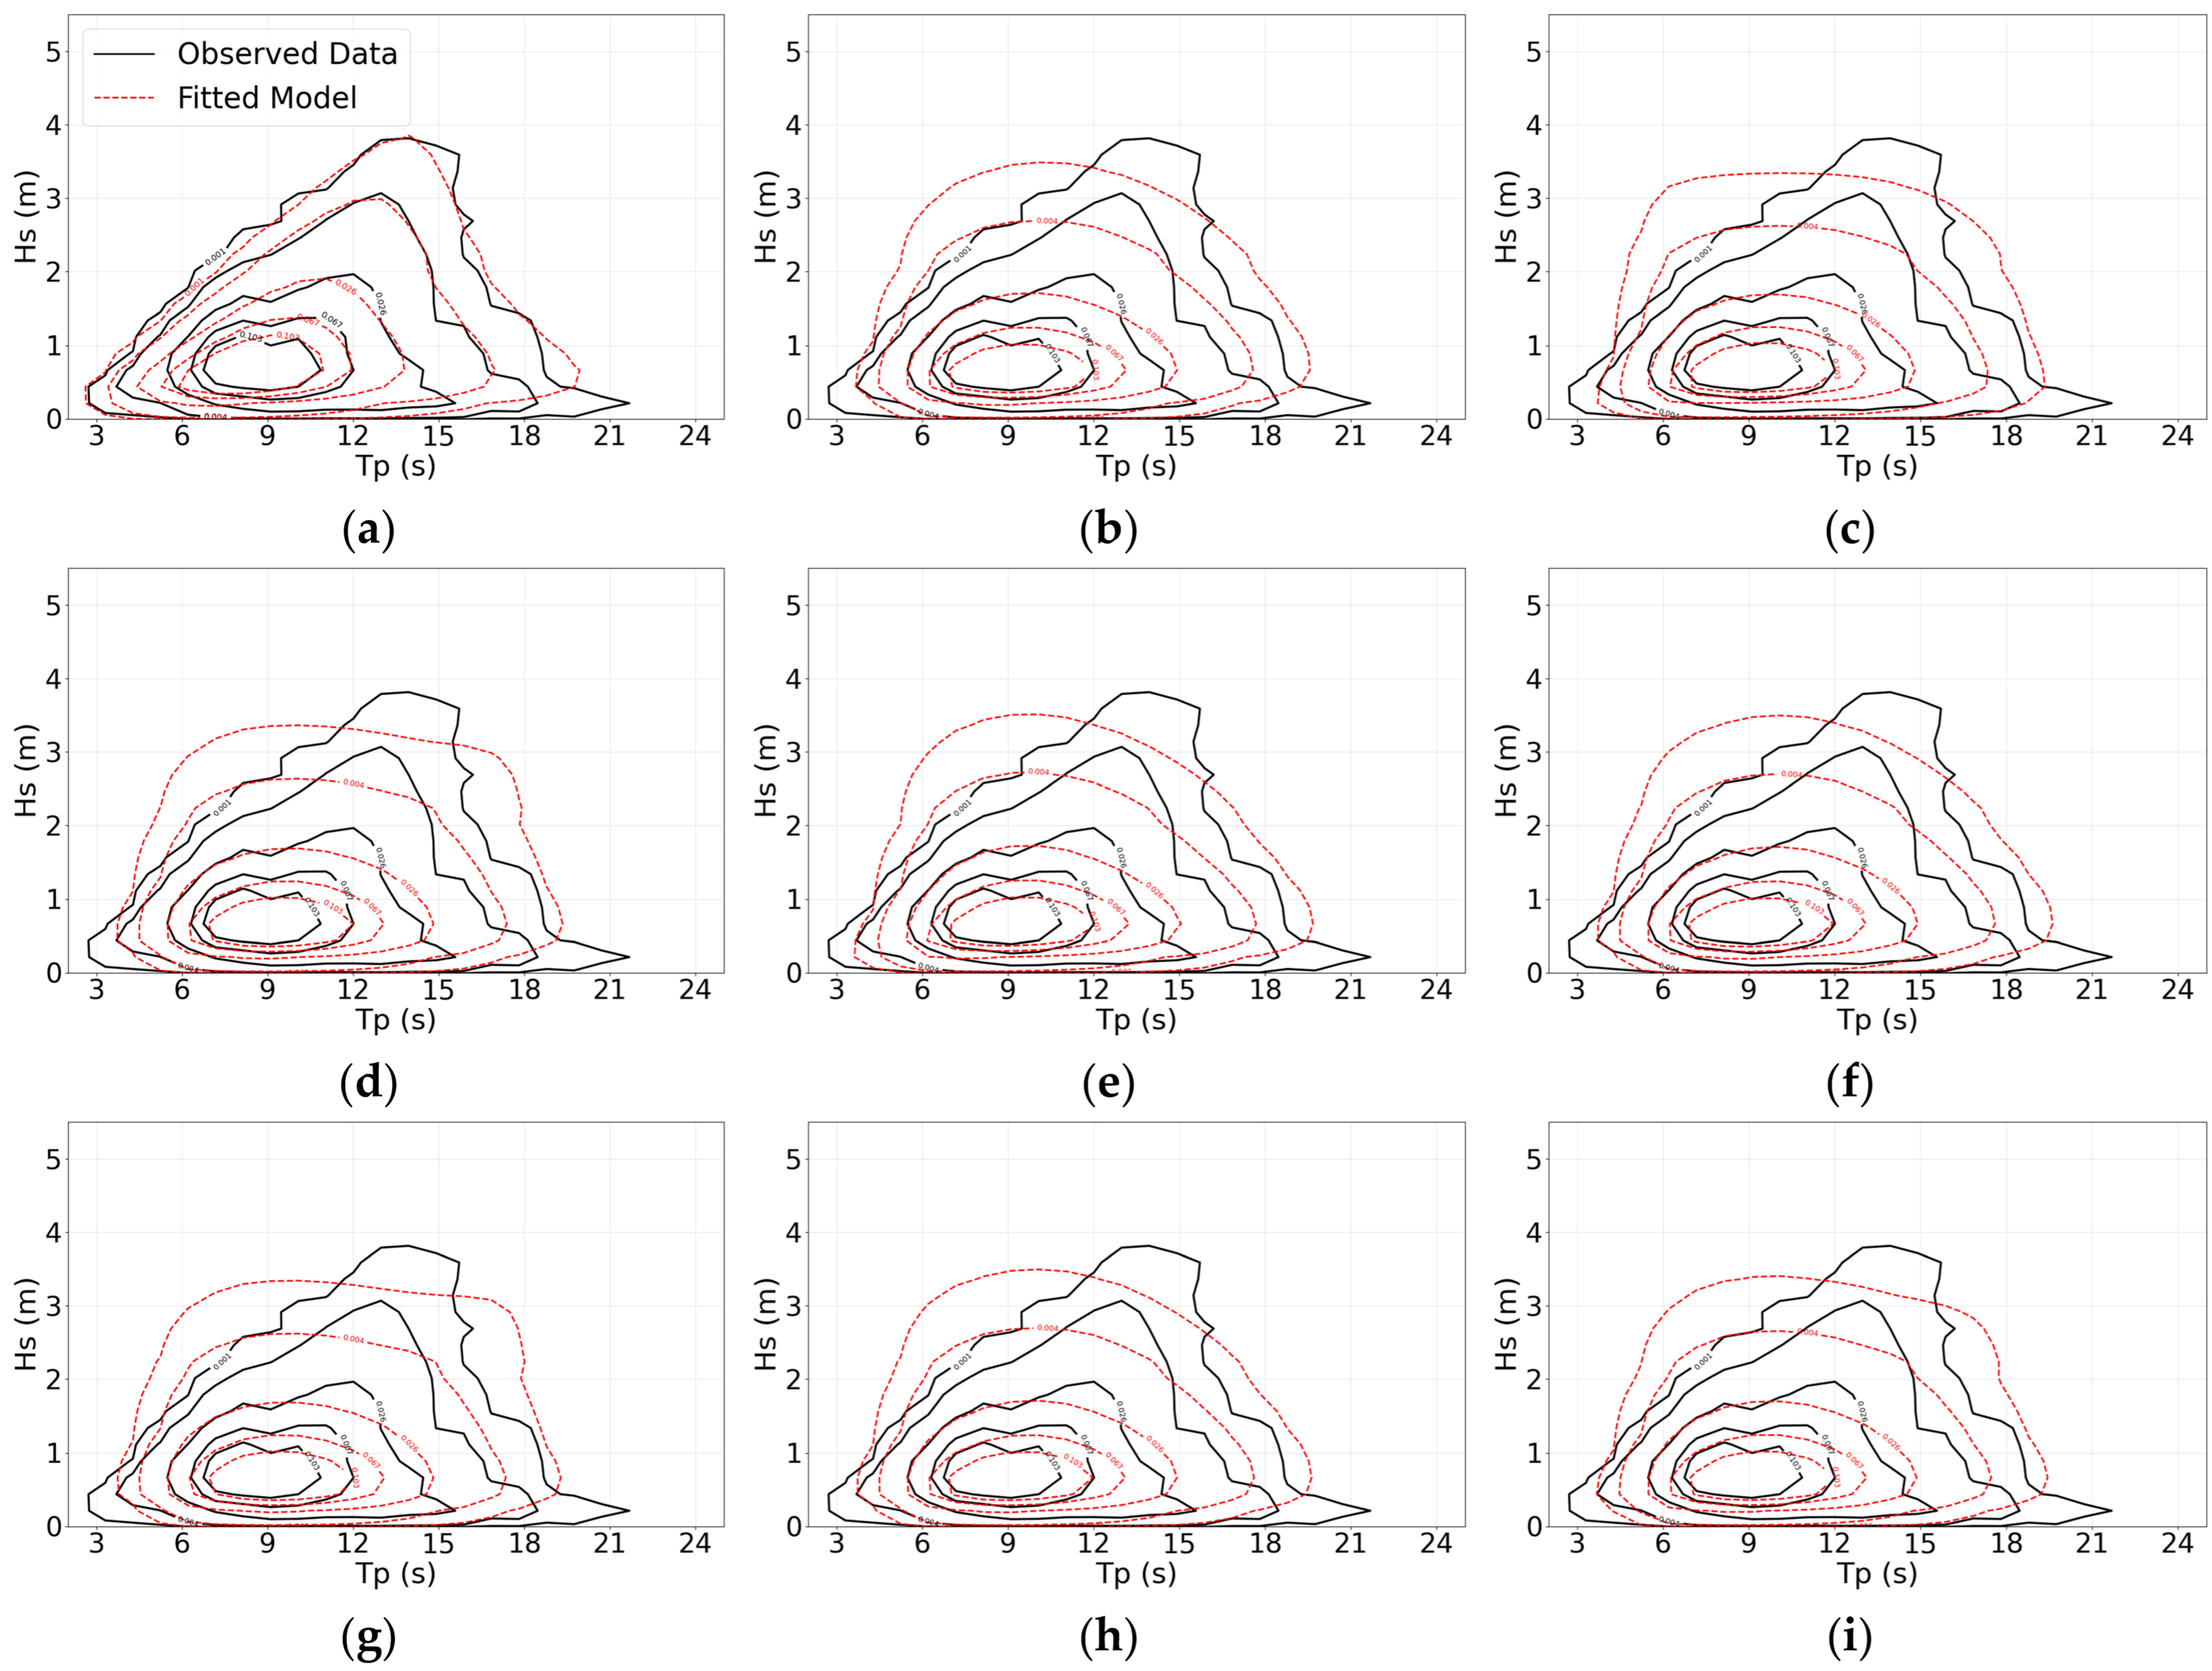
For C2-sea, the scatter plots and iso-probability curves (Figure 9 and Figure 10) show that the CMA remained the most robust, faithfully reproducing the observed statistical dependence structure throughout the data domain, making it suitable for both fatigue and extreme analyses. The elliptical copulas showed satisfactory performance in the scatter plots and iso-probability curves, with a slight limitation in the extreme regions, where the synthetic data either exceeded or underestimated the observed bounds, resulting in small distortions in the iso-probability curves. The remaining copulas showed unsatisfactory performance, limiting their applicability for structural design purposes. The environmental contours for the 20-year return period (Figure 11) show that the CMA and the Gaussian copula almost coincide with the boundary of the observed data. The Student’s t, Gumbel, Joe, and BB1 copulas exhibited a similar shape, with distortions in the central region and the upper tail, making them unsuitable for extreme response analyses. The remaining copulas presented contours that delimit regions encompassing unobserved parameter combinations, with shapes that do not correspond to the data structure.
The AIC and BIC criteria (Table 8) ratify the performance of the CMA in both scenarios, since this modelling approach presented the lowest index values. For C2-sea, the elliptical copulas rank next to the CMA, in agreement with the visual analyses, while the remaining copulas exhibit higher values. For C1-swell, it is observed that the Gumbel, Plackett, and Frank copulas present the lowest values after the CMA, differently from what is suggested by the visual analyses, where the elliptical copulas showed better performance. This apparent discrepancy reinforces that model selection remains a challenge, since different criteria may not agree on the ranking of candidate models [13]. This result highlights the importance of an integrated evaluation that combines multiple criteria.

4.3.3. Low Dependence Coefficient Levels

The swell wave component scenarios of Sets C2 and C3 (C2-swell and C3-swell) present low dependence coefficients, as per Table 3. Figure 12 illustrates, as an example, the scatter plot for C2-swell. The CMA was the only approach capable of reproducing the observed statistical dependence structure, which makes it suitable for both fatigue and extreme analyses. The iso-probability curves (Figure 13) and environmental contours (Figure 14) confirm its performance in these scenarios. All parametric copulas generated synthetic scatter plots close to statistical independence and distorted environmental contours that do not reflect the observed data, which limits their applicability for structural design purposes.
The AIC and BIC criteria (Table 9) reveal a behavior analogous to that observed in C1-swell (Section 4.3.2): the parametric copulas present slightly lower values than the CMA, in contrast with the clear visual superiority of the latter. This recurring discrepancy between quantitative metrics and visual assessments, manifested in distinct dependence regimes, highlights the need for an integrated approach to model selection, in which multiple criteria are considered in a complementary manner.

4.3.4. Varying Dependence Coefficient Levels

The sea component in dataset C3 (C3-sea) stands out among all scenarios due to its domain-varying dependence structure. To assess this behavior systematically across all scenarios, Table 10 presents Pearson, Kendall, and Spearman coefficients computed within three T p sub-intervals defined by the sample tertiles of each dataset. Tertile bands were adopted as they preserve approximately equal sample sizes per band while remaining sensitive enough to resolve dependence variation across the T p domain. For C1-sea, the coefficients remain consistently high across all three bands, which confirms a uniform and strongly dependent structure throughout the T p domain. A similar pattern of uniform dependence is observed for C1-swell, though with a moderate increase in dependence from T1 to T3. For C2-sea, a pronounced decay is observed from T1 to T2, with dependence remaining low in T3, revealing a domain-varying structure where dependence is concentrated in the lower T p band and essentially vanishes for higher periods. The low dependence scenarios C2-swell and C3-swell exhibit near-zero or slightly negative coefficients across all bands, which indicates statistical independence throughout the domain. C3-sea presents the most pronounced domain-varying behavior: dependence is moderate in the lower T p band (T1), decays sharply in the intermediate band (T2), and becomes slightly negative in the upper band (T3), confirming that global coefficients for this scenario mask a domain-varying dependence structure.
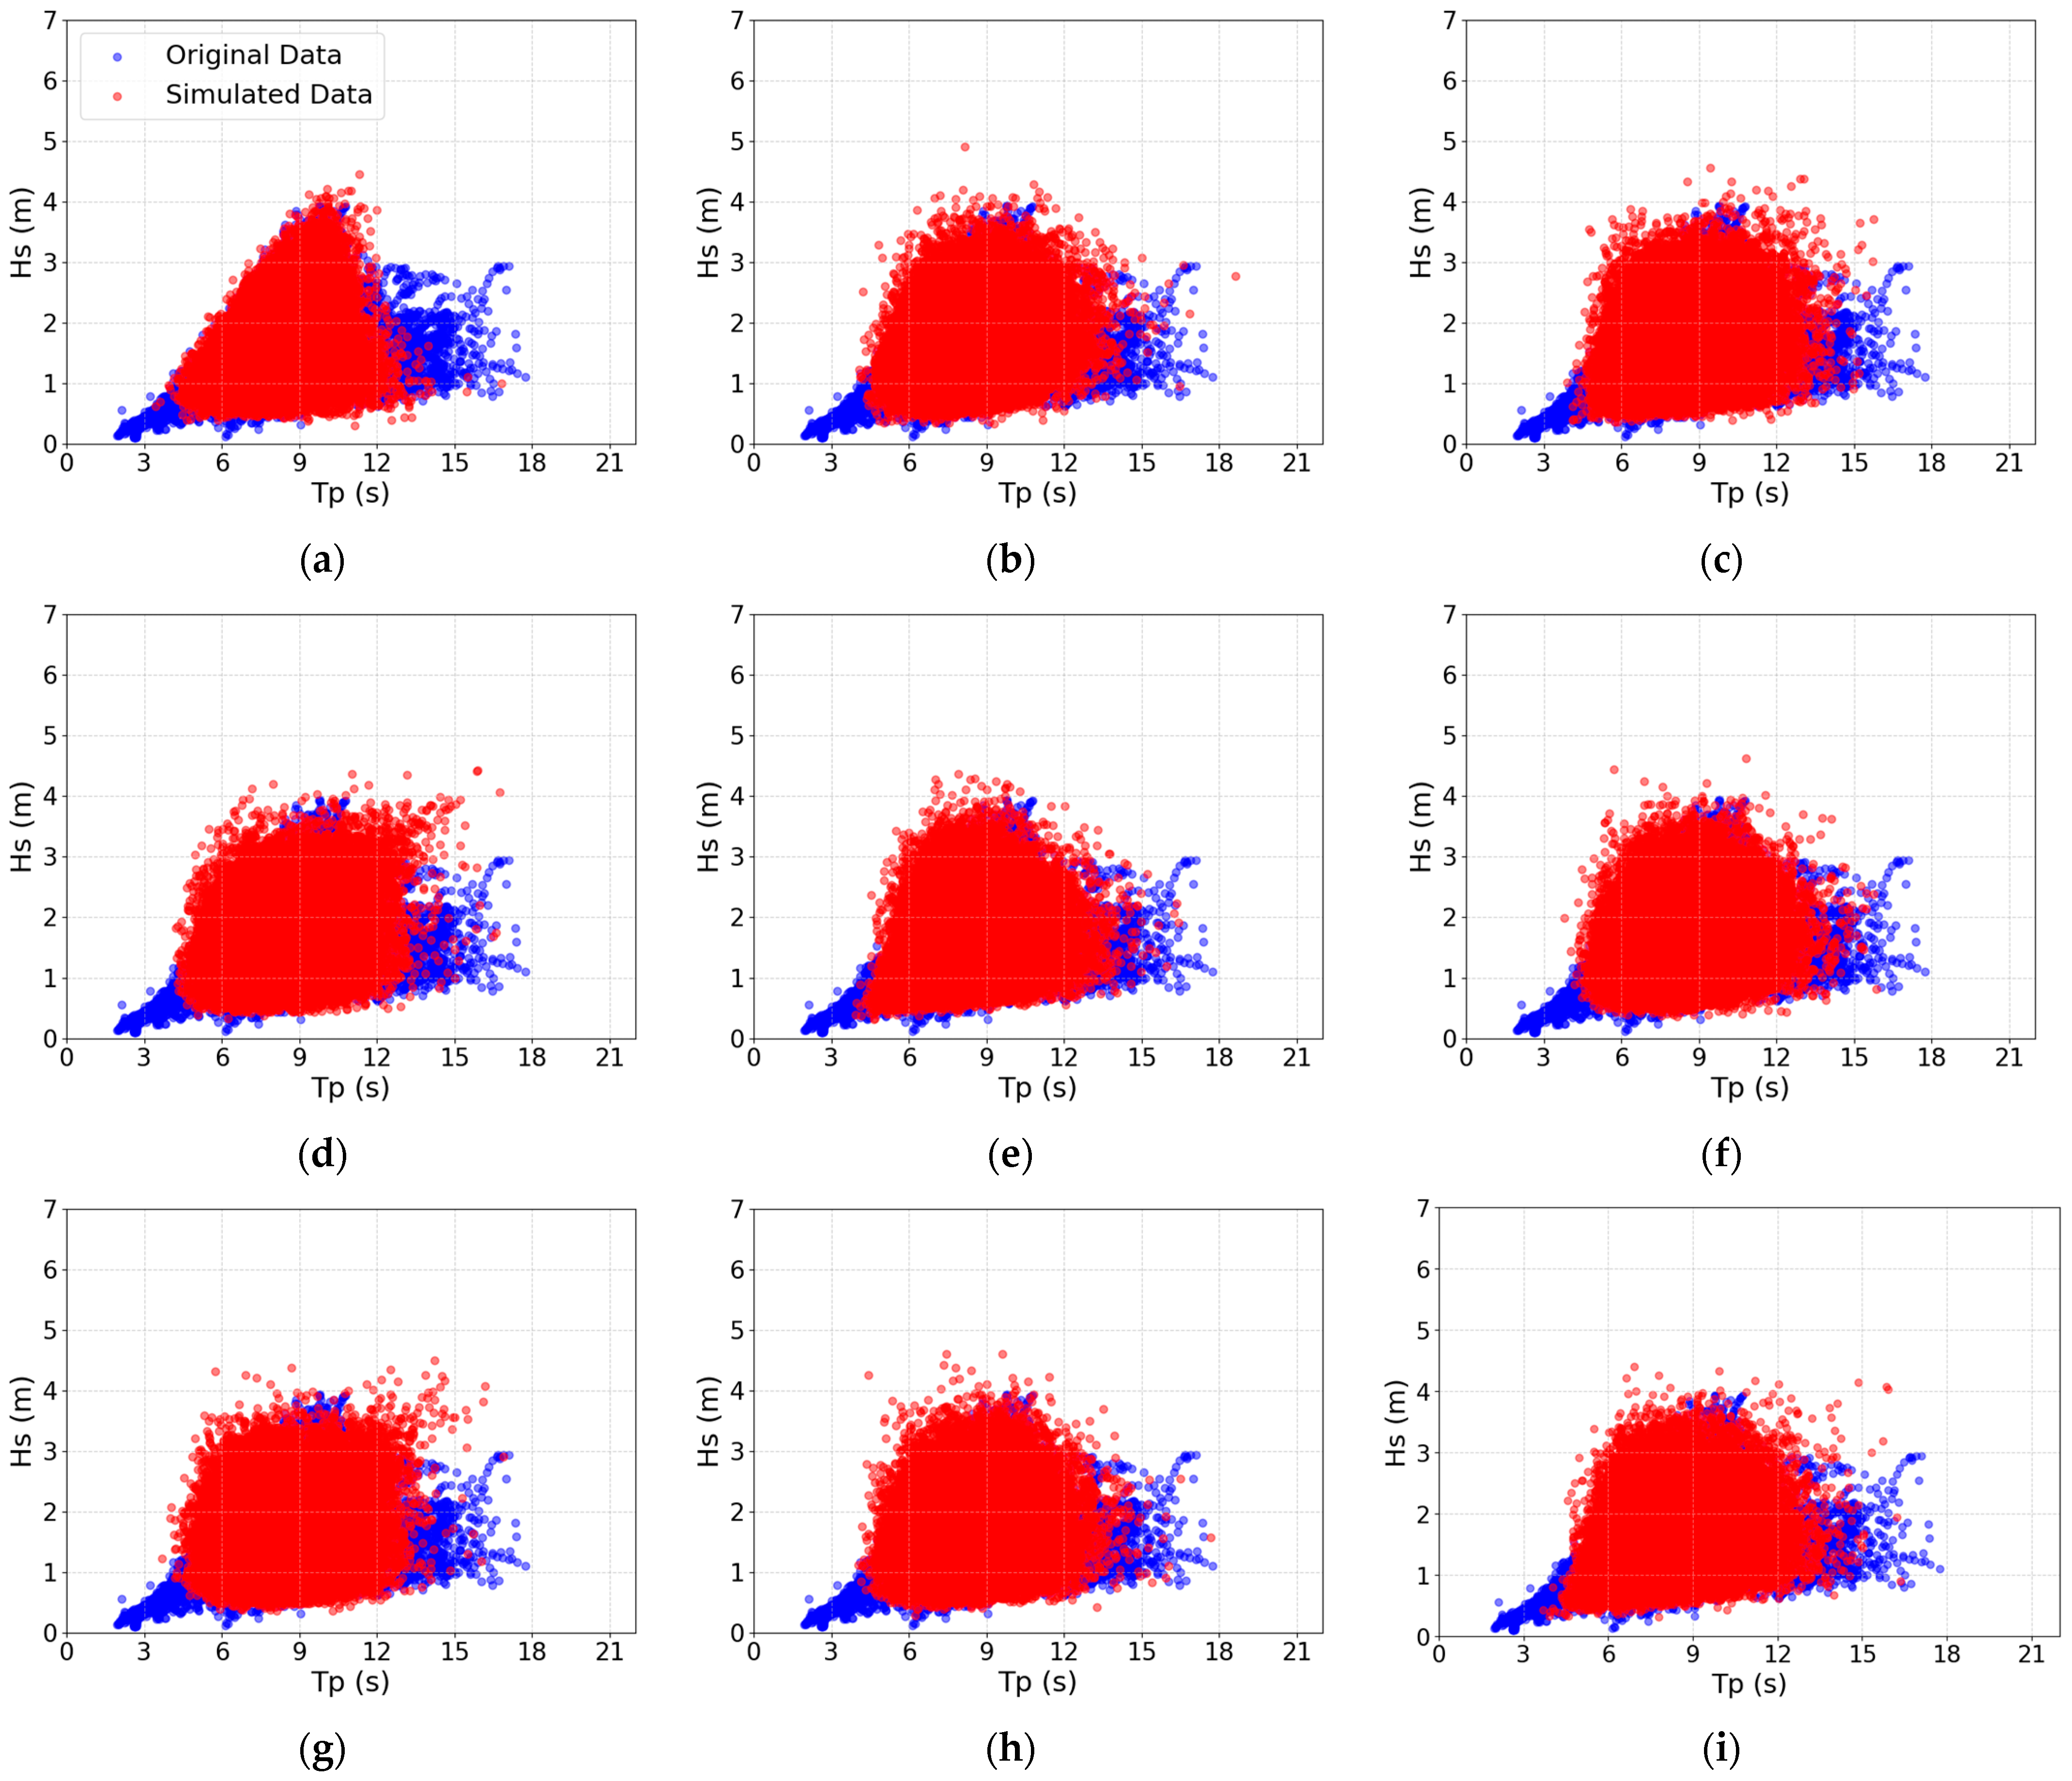
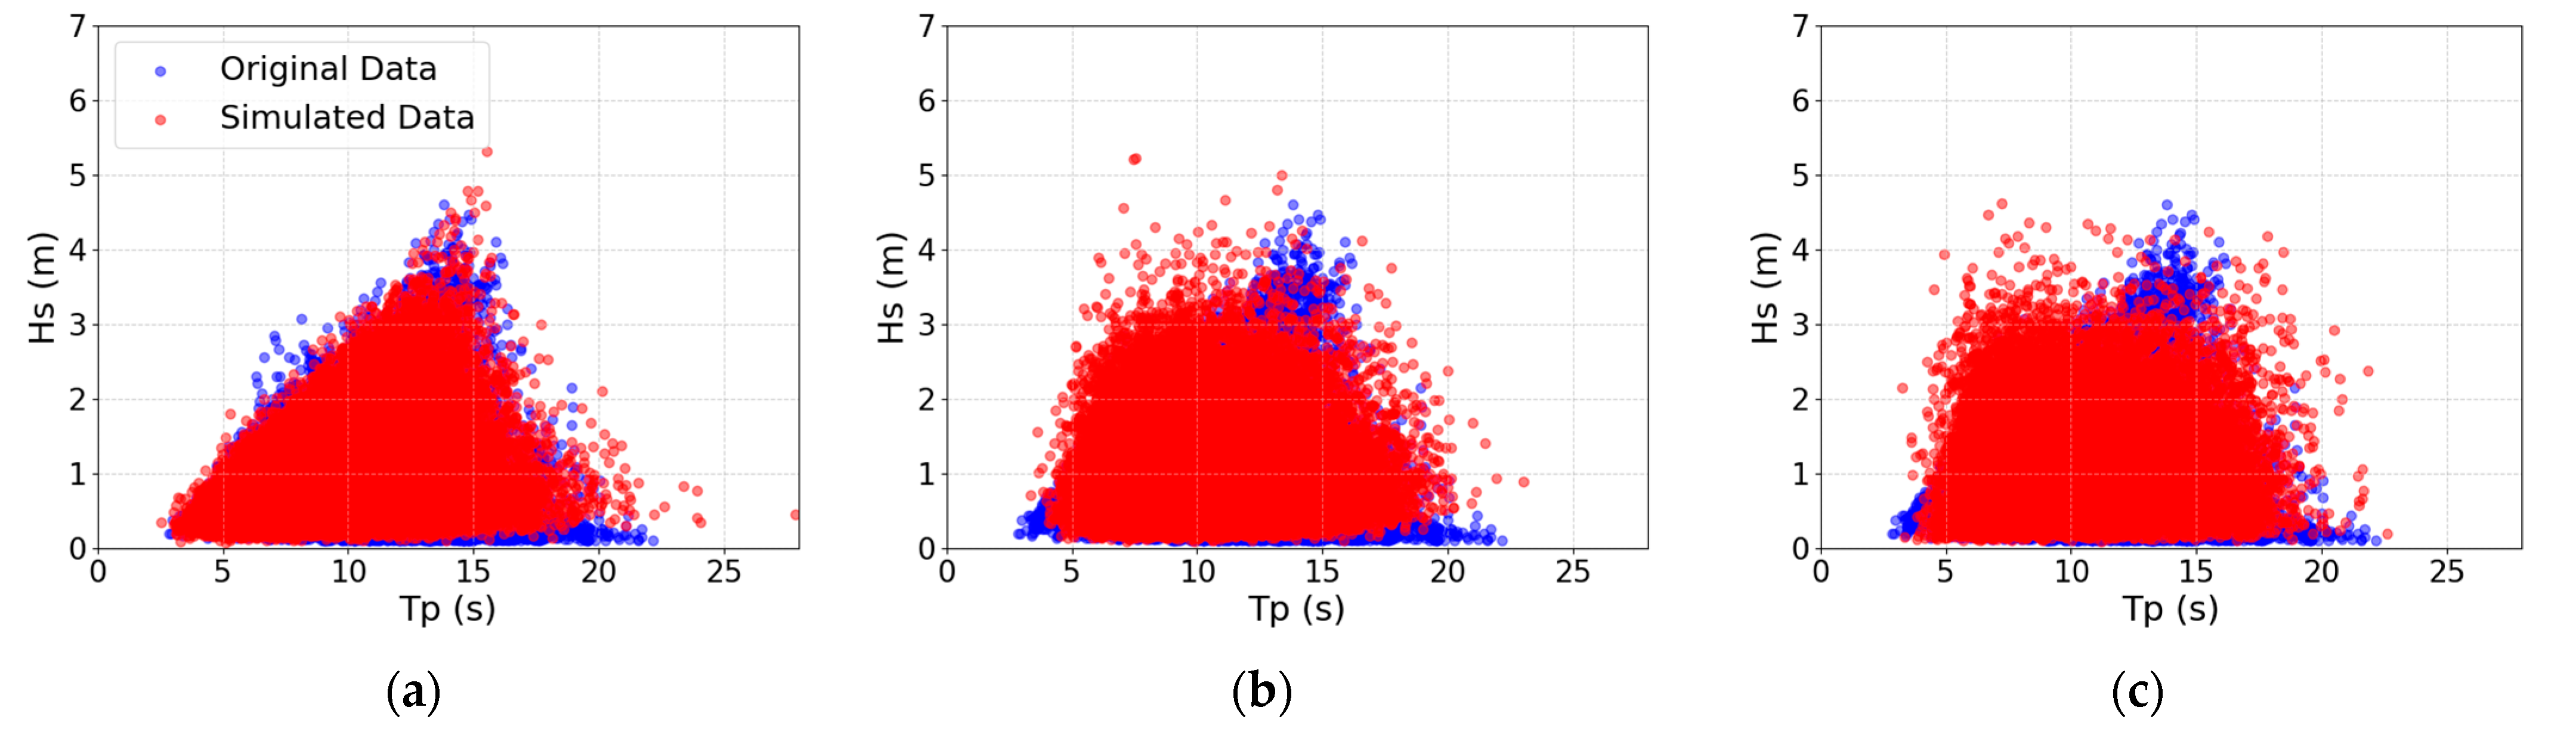
Figure 15 presents the scatter plot for this scenario. It is observed that the CMA partially captured this structure, reproducing well the central region and the extremes of H s , but with deviations in the extreme T p intervals (( T p < 5   s ) and ( T p > 11   s )). The parametric copulas proved incapable of representing this varying dependence. The iso-probability curves (Figure 16) confirm this behavior. While the CMA produces curves that reasonably follow the observed density, the copulas generate curves with a circular shape, typical of statistical independence, especially in the region of high T p values. Consequently, the CMA is suitable for both fatigue and extreme analyses in this scenario, though with some limitations in the tails, whereas the copulas are inadequate for either application.
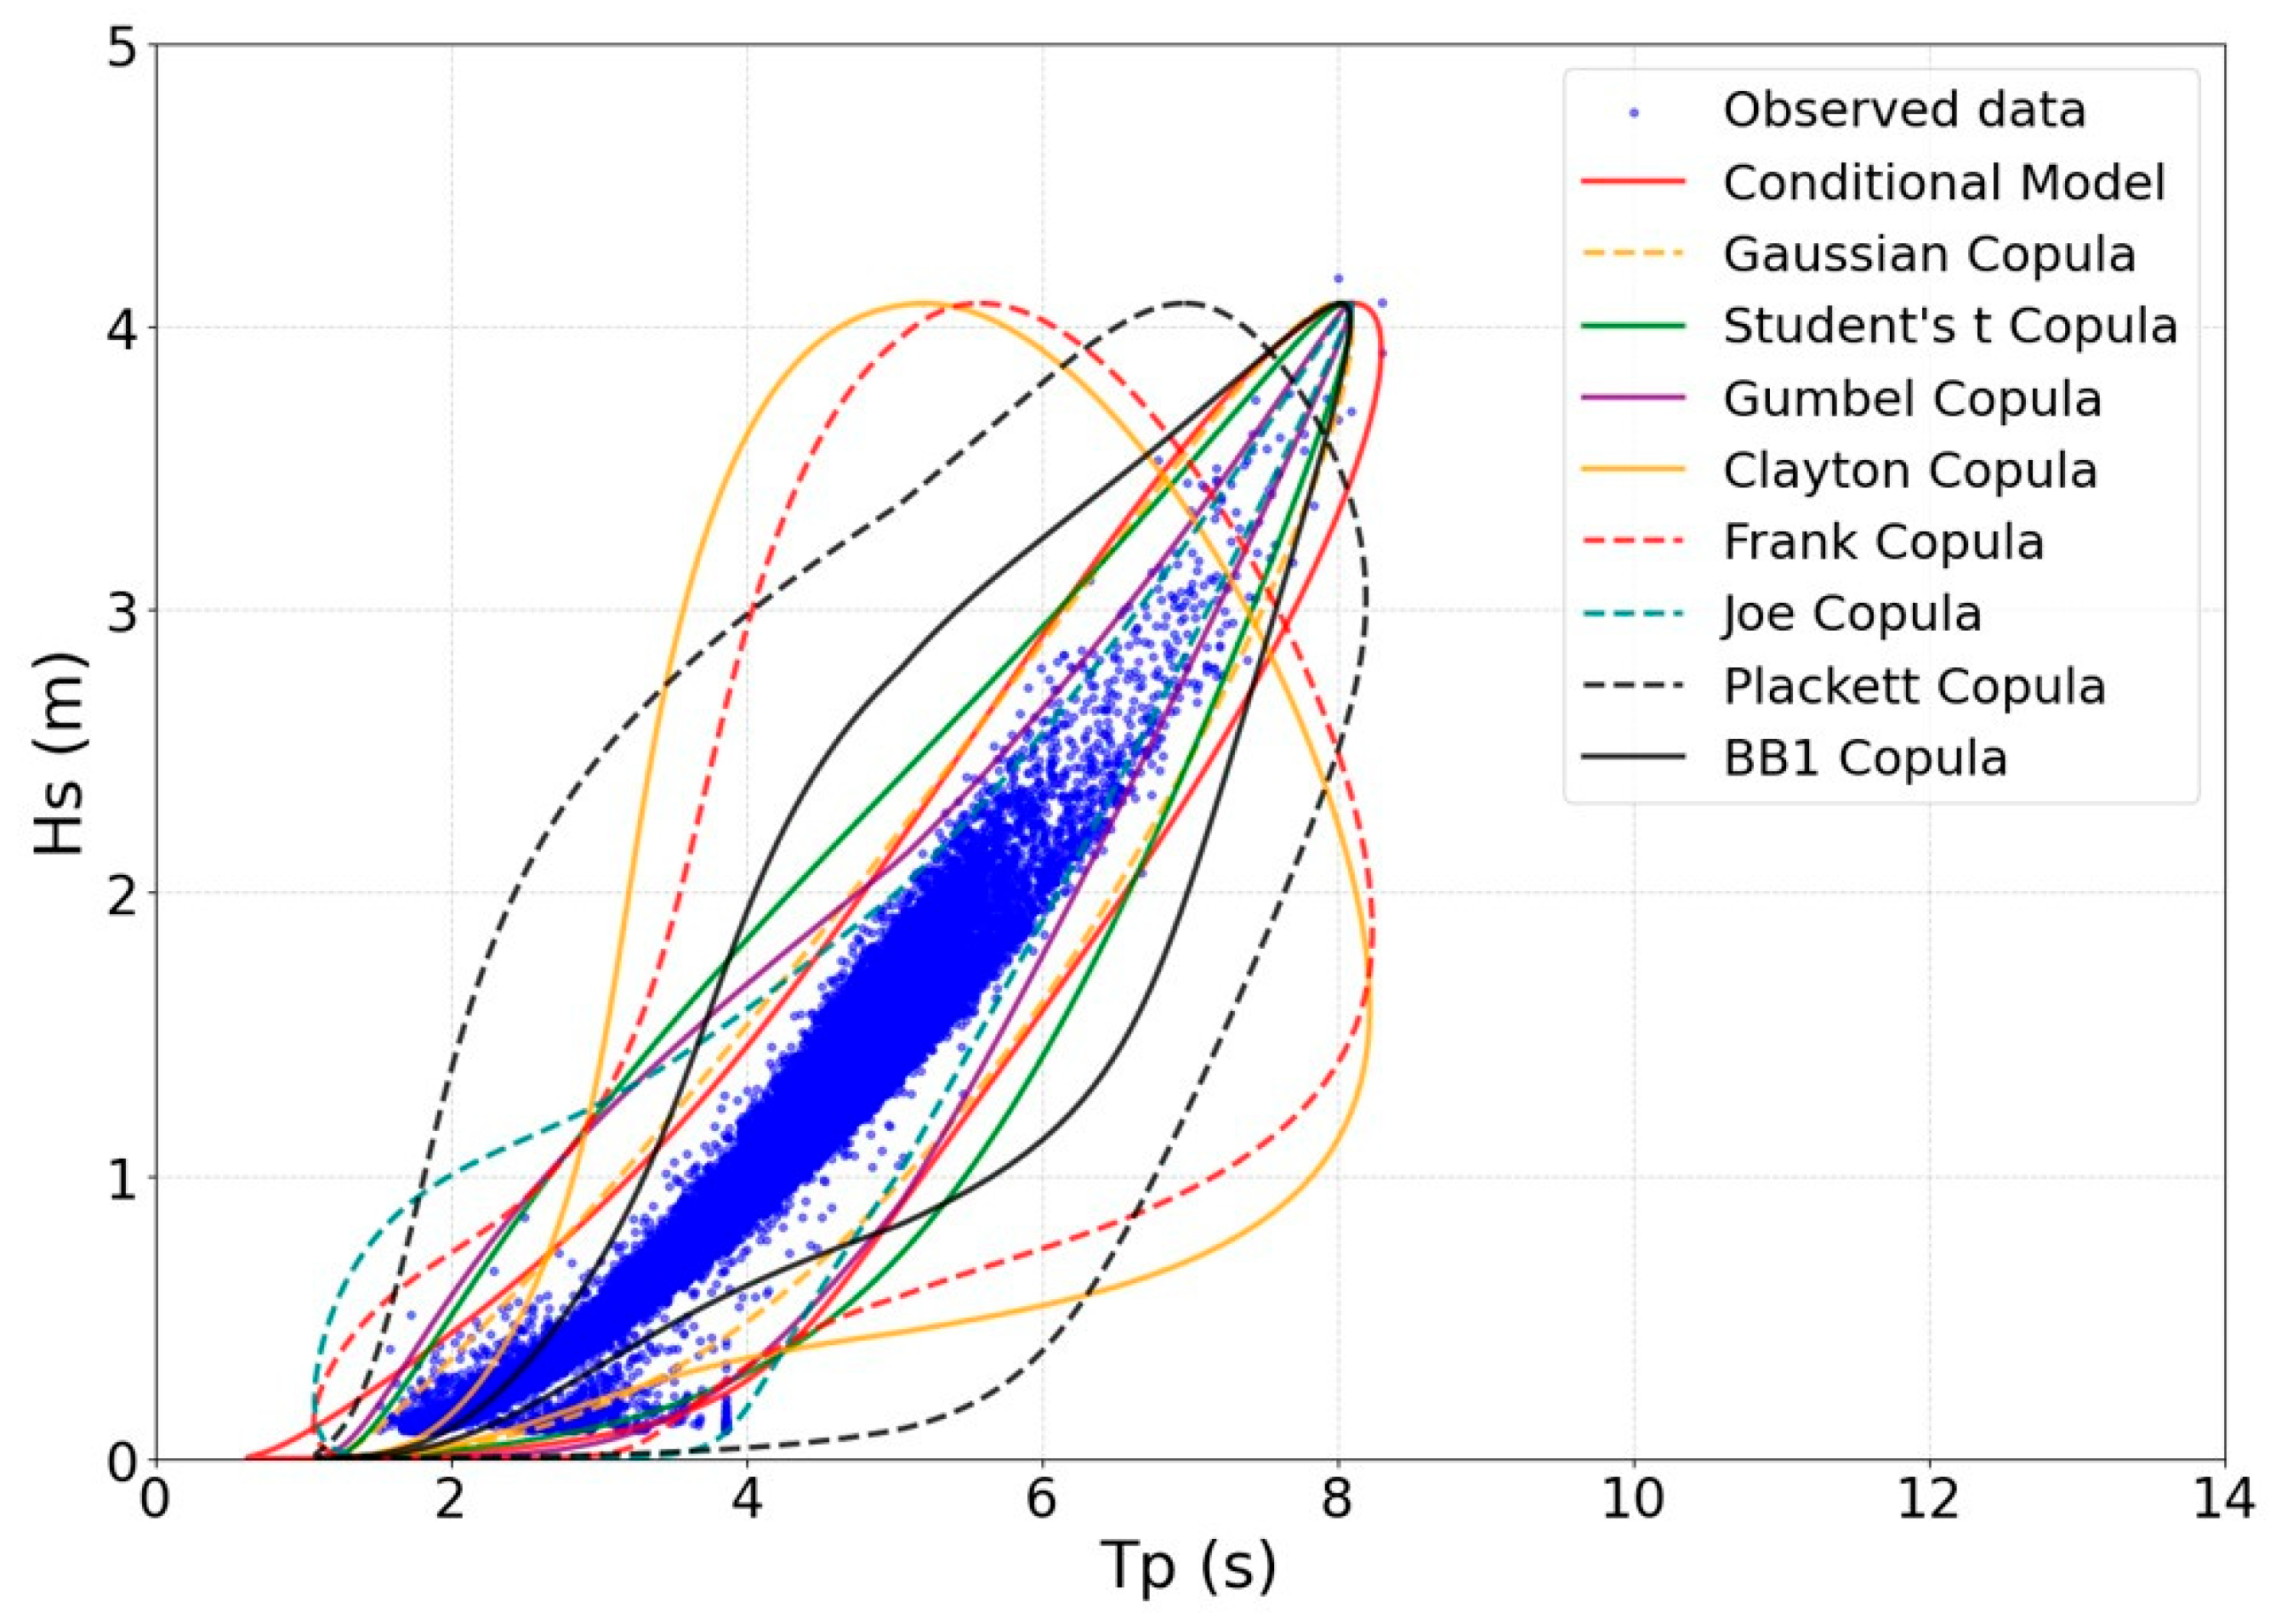
The environmental contours (Figure 17) illustrate the challenge imposed by this scenario. The CMA contour encompasses most of the observed data, although some extreme points in T p lie outside the delimited region. The copulas, in turn, produce contours that do not correspond to the observed boundary, underestimating or overestimating regions inconsistently. This scenario highlights the limitations of conventional models when faced with domain-varying dependence structures and reinforces the need for more flexible approaches capable of representing the variation of dependence across the variable domain.
The AIC and BIC criteria (Table 11) also point to the CMA as the best alternative, with lower index values than those of the copulas.

4.3.5. Residual Rank Dependence Analysis

To further investigate the adequacy of each fitted model beyond the visual and information-criterion assessments presented in Section 4.3.1, Section 4.3.2, Section 4.3.3 and Section 4.3.4, a residual rank dependence analysis was conducted following the Rosenblatt probability integral transform [30]. The analysis was applied to three representative scenarios selected to span the full dependence spectrum reported in Table 3: C1-sea, which represents the regime where the elliptical copulas and CMA showed their best visual performance; and C2-swell and C3-swell, which represent the regime where the visual superiority of the CMA over parametric copulas was most pronounced.
The procedure consists of transforming the observed bivariate data ( H s , T p ) into uniform pseudo-observations (U, E) using the fitted joint model. In both cases, U is obtained by applying the marginal CDF of H s to the observed data. For the CMA, E is obtained by applying the fitted conditional CDF of T p given H s , the lognormal distribution with parameters λ h s and ξ h s (Equations (5) and (6)), to the observed T p values. For the parametric copulas, E is obtained by evaluating the fitted conditional copula CDF C 2 | 1 v | u (Equation (15)) at the pseudo-observations ( u ,   v ), where v = F T p t p is the marginal CDF of T p . Under a correctly specified joint model, the transformed pair (U, E) should consist of independent uniform random variables on [ 0 , 1 ] . Any residual statistical dependence between U and E then indicates that the fitted model did not fully capture the dependence structure present in the original data ( H s , T p ). The residual dependence is quantified by Kendall’s tau (Equation (10)) applied to the pairs ( U i , E i ), i   =   1 , , N , where N is the total number of observed ( H s , T p ) pairs in each scenario.
Table 12 presents the residual τ ^ values for all nine models across the three selected scenarios.
In the high dependence coefficients scenario (C1-sea), all models exhibit non-negligible residual dependence, but the CMA presents the smallest residual τ ^ (0.16), followed by the Gaussian copula (0.24), confirming its superior capacity to absorb the dependence structure in the rank domain. In the low dependence coefficients scenario (C2-swell, C3-swell), the pattern reverses: most parametric copulas yield near-zero residual τ ^ values, with the Gaussian, Student’s, Frank, Joe, and Plackett copulas presenting magnitudes below 0.01 in both scenarios, which indicates adequate absorption of the rank-based dependence structure. The CMA, by contrast, produces large negative residual τ ^ values (C2-swell: τ ^ = 0.19 ; C3-swell: τ ^ = 0.16 ). This reveals that its conditional regression structure introduces an artificial negative dependence coefficient in the probability integral transformed residuals in near-independence coefficient regimes. This arises because the parametric lognormal conditional regression is overspecified relative to the strength of the conditional signal. When fitted to data where T p depends very weakly on H s , the fitted conditional CDF produces a probability integral transform that compresses the residuals in a way that yields mildly negative rank correlation. This is not a physical failure of the CMA, and does not undermine its engineering-relevant performance in the original ( H s , T p ) space.
These results reveal two complementary perspectives on model adequacy. In the rank domain, parametric copulas correctly identify near-independence in low dependence coefficient scenarios, consistent with their calibration on rank statistics, while the CMA misspecifies the copula-like dependence structure in these regimes. When evaluated in terms of the physical scatter structure of ( H s , T p ), however, the CMA’s conditional regression (Equations (5) and (6)) captures how the conditional distribution of T p varies with H s , a relationship that persists even when rank-based dependence is negligible, and that parametric copulas are structurally unable to represent. The two assessments therefore measure fundamentally different aspects of joint model adequacy, and neither alone is sufficient for model selection in offshore engineering applications.

5. Final Remarks

This work compared the CMA and eight families of parametric copulas for the joint probabilistic modeling of H s and T p wave variables. The analysis employed three datasets from the Brazilian coast (C1, C2, and C3), encompassing a wide spectrum of dependence coefficient magnitudes, from very high to near-zero values of Pearson’s correlation coefficient, Kendall’s tau, and Spearman’s rho, including a scenario with domain-varying dependence across the T p domain. Model performance was evaluated through four complementary criteria: synthetic scatter plots, iso-probability curves, AIC/BIC, and environmental contours. These assessments were supplemented by a residual rank dependence analysis based on the Rosenblatt probability integral transform.
The CMA proved to be the most robust across all analyzed regimes in terms of visual criteria: high magnitude dependence coefficients (C1-sea), moderate (C2-sea), moderate-high (C1-swell), low (C2-swell and C3-swell) and domain-varying (C3-sea). Its performance was consistent across synthetic data simulation, iso-probability curves, and environmental contours. The residual rank dependence analysis (Section 4.3.5) further confirmed this superiority in the high dependence coefficient regime (C1-sea), where the CMA presented the smallest residual τ ^ among all models. Two limitations, however, must be acknowledged. First, the AIC/BIC criteria showed disagreements with the visual assessments in the moderate-high (C1-swell) and low dependence coefficient regimes, where parametric copulas presented lower index values despite their clear visual inferiority. This discrepancy is rooted in the nature of these information criteria: AIC/BIC reward models with higher log-likelihood values, which tend to reflect goodness-of-fit in the central, data-dense region of the distribution where most observations concentrate, and may rank a copula above CMA even when the latter performs better in the tails and in physically meaningful regions of the ( H s , T p ) domain. The criteria are therefore not in conflict so much as they are measuring different aspects of model adequacy. This distinction is directly relevant for engineering-context-dependent model selection: AIC/BIC may be a reasonable discriminator for fatigue applications, where central distribution accuracy is most critical, but should be used with caution for extreme response applications, where tail accuracy is paramount. Second, the residual rank dependence analysis revealed that in low dependence coefficient regimes, the CMA introduces artificial negative dependence in the rank-transformed residuals, a limitation not captured by the visual criteria alone, and one that reinforces the importance of complementary assessment perspectives. The domain-varying scenario (C3-sea) further exposed the model’s difficulty in capturing complex dependence structures, with deviations observed in the extreme T p levels. It is important to note, however, that the robustness of CMA observed in this bivariate context may not extend directly to trivariate or higher-dimensional problems, where the conditional decomposition becomes increasingly complex and may require simplifying assumptions that compromise statistical robustness [2].
Regarding copula performance, the Gaussian, Student’s t, Gumbel, Joe, and BB1 copulas performed satisfactorily in scenarios with high magnitude of dependence coefficients (C1-sea) and moderate-high magnitude (C1-swell), with emphasis on the Gaussian copula, which presented lower AIC/BIC values than the CMA in the first regime; however, given the large sample size, this difference may not correspond to a meaningful distinction in practical fit, which is consistent with the visual indistinguishability of the two models observed in Figure 6, Figure 7 and Figure 8. Among the copula families, the Gaussian copula also presented the smallest residual τ ^ in the high dependence coefficient regime, further supporting its role as the most adequate copula for this scenario. In typical moderate dependence coefficient magnitudes (C2-sea), the elliptical copulas showed globally reasonable performance, albeit with limitations in the extreme regions. In scenarios with low dependence coefficient magnitudes (C2-swell and C3-swell), all copulas generated structures close to statistical independence in the physical scatter domain and proved incapable of capturing the conditional physical structure of T p given H s that persists even when global rank-based measures approach zero. The residual rank dependence analysis, however, showed that most parametric copulas yield near-zero residual τ ^ values in these regimes. This result indicates that they correctly identify near-independence in the rank domain, which is consistent with their calibration on rank statistics and highlights the complementary nature of rank-based and scatter-based model assessment. This suggests that the remaining dependence structure in low dependence coefficient scenarios may be of a tail-localized or conditional nature rather than a global rank-based one, as evidenced by the non-negligible empirical tail dependence coefficients reported in Table 4. Such a structure is better captured by the flexible conditional regression of the CMA than by rank-based copula calibration. The Clayton, Frank, and Plackett copulas proved inadequate across all studied scenarios for most evaluation criteria, consistently generating structures incompatible with the observed data. The domain-varying scenario (C3-sea) exposed the limitations of all tested approaches when faced with dependence structures that vary across the T p domain.
The choice of the joint probability model has direct implications for offshore structural design, and the most appropriate model may differ according to both the target application and the dependence regime. For the simulation of synthetic sea states, CMA consistently reproduced the observed scatter plot structure across all dependence regimes, except for the domain-varying scenario (C3-sea), where deviations were observed in the extreme T p intervals and no fully adequate model was identified. For fatigue analysis and extreme response, the Gaussian and Student’s t copulas represent viable alternatives to CMA in high and moderate-high dependence scenarios (C1-sea, C1-swell), where these models showed equivalent performance. The Gumbel, Joe, and BB1 copulas, while reasonably reproducing the central region of the distribution in high dependence scenarios, underestimated the upper tail and produced non-conservative contours, making them acceptable for fatigue but not for extreme response applications. In all remaining dependence regimes, CMA is the recommended choice for both purposes in terms of physical scatter structure reproduction and environmental contour construction, noting that its rank-domain limitation identified in Section 4.3.5 does not affect these engineering-relevant assessments.
Clayton, Frank, and Plackett copulas proved inadequate across all dependence regimes for most evaluation criteria considered: synthetic scatter plots, iso-probability curves, and environmental contours, consistently generating structures incompatible with the observed data, and are therefore not recommended for any offshore design application considered in this study.
Future research in this field may further explore several directions. More flexible dependence structures, including non-parametric copulas, mixture copulas, and other conditional dependence models, could provide additional insight, especially for low dependence coefficients and domain-varying scenarios such as C3-sea, where all standard parametric approaches showed limitations. The proposed modeling framework may also be extended to other relevant environmental variables (e.g., wind speed, current speed) and to higher-dimensional problems, where vine copulas may become useful. In addition, evaluating the impact of model selection on structural response analyses, including fatigue damage and extreme response estimation, may be quantified for real offshore structures. Formal goodness-of-fit tests for the fitted copulas, such as Cramér–von Mises or bootstrap-based statistics, would also strengthen future comparative studies. Furthermore, a simulation-based comparison of tail dependence coefficients between the CMA and parametric copulas would provide a more complete characterization of tail behavior across all models. Finally, future developments may include a more comprehensive quantitative framework for environmental contour generation, encompassing both contour validation procedures (return period consistency tests and structural design point comparisons), and uncertainty quantification associated with parameter estimation and its propagation into the joint probability distribution.


Author Contributions

Conceptualization, M.G., M.L.S. and L.V.S.S.; methodology, M.G., M.L.S. and L.V.S.S.; software, M.G. and M.L.S.; validation, M.G., M.L.S. and L.V.S.S.; formal analysis, M.G., M.L.S. and L.V.S.S.; investigation, M.G., M.L.S. and L.V.S.S.; resources, L.V.S.S.; data curation, M.G., M.L.S. and L.V.S.S.; writing—original draft preparation, M.G., M.L.S. and L.V.S.S.; writing—review and editing, M.G., M.L.S. and L.V.S.S.; visualization, M.G., M.L.S. and L.V.S.S.; supervision, M.L.S. and L.V.S.S.; project administration, L.V.S.S.; funding acquisition, L.V.S.S. All authors have read and agreed to the published version of the manuscript.

Funding

This research was partially funded by Coordenação de Aperfeiçoamento de Pessoal de Nível Superior (CAPES), grant number 88887.950594/2024-00; by Fundação Carlos Chagas Filho de Amparo à Pesquisa do Estado do Rio de Janeiro (FAPERJ), grant number E-26/201.782/2025 and by Conselho Nacional de Desenvolvimento Científico e Tecnológico (CNPq), grant number 306447/2021-5.

Data Availability Statement

The data presented in this study are available on request from the corresponding author due to confidentiality restrictions.

Acknowledgments

The authors thank the Laboratory of Analysis and Reliability of Offshore Structures (LACEO) at COPPE/UFRJ for the technical and administrative support.

Conflicts of Interest

The authors declare no conflicts of interest.

Abbreviations

The following abbreviations are used in this manuscript:
AICAkaike Information Criterion
BICBayesian Information Criterion
C1, C2, C3Dataset sets 1, 2, and 3
CDFCumulative distribution function
CMAConditional Modeling Approach
IFMInference functions for margins
IFORMInverse First-Order Reliability Method
MLEMaximum likelihood estimation
MREMean relative error
PDFProbability density function
H s Significant wave height
T p Peak wave period
T z Wave zero-up-crossing period
V c Surface current speed
V w Wind speed

References

  1. Zhang, Y.; Kim, C.-W.; Beer, M.; Dai, H.; Guedes Soares, C. Modeling multivariate ocean data using asymmetric copulas. Coast. Eng. 2018, 135, 91–111. [Google Scholar] [CrossRef] [Scilit]
  2. Simão, M.L.; Sagrilo, L.V.S.; Videiro, P.M. A multi-dimensional long-term joint probability model for environmental parameters. Ocean Eng. 2022, 255, 111470. [Google Scholar] [CrossRef] [Scilit]
  3. Mosquera, I.A.M.; Sagrilo, L.V.S.; Lima, E.C.P. A joint probabilistic model for wave, wind and current parameters using Nataf transform. In Proceedings of the XXXVI Iberian Latin American Congress on Computational Methods in Engineering (CILAMCE 2015), Rio de Janeiro, Brazil, 22–25 November 2015. [Google Scholar]
  4. Estrela, G.A.; Sousa, F.J.M.; Lopes, G.K.; Sagrilo, L.V.S.; Gonzaga e Silva, A.B.C.; Fairbairn, E.M.R.; Andrade, H.C.C.; Telles, J.C.F.; Siqueira, A.A.; Reales, O.A.M.; et al. Design of cement sheaths in offshore oil wells based on structural reliability. In Proceedings of the ASME 2024 43rd International Conference on Offshore Mechanics and Arctic Engineering (OMAE2024), Singapore, 9–14 June 2024. [Google Scholar] [CrossRef] [Scilit]
  5. Ibarra, M.A.C.; Simão, M.L.; Videiro, P.M.; Sagrilo, L.V.S. Long-term fatigue analysis of mooring lines considering wind-sea and swell waves using the univariate dimension-reduction method. Appl. Ocean Res. 2022, 118, 102997. [Google Scholar] [CrossRef] [Scilit]
  6. Ross, E.; Astrup, O.C.; Bitner-Gregersen, E.; Bunn, N.; Feld, G.; Gouldby, B.; Huseby, A.; Liu, Y.; Randell, D.; Vanem, E.; et al. On environmental contours for marine and coastal design. Ocean Eng. 2020, 195, 106194. [Google Scholar] [CrossRef] [Scilit]
  7. DNV Global. Environmental Conditions and Environmental Loads; RP-C205; Det Norske Veritas: Høvik, Norway, 2017. [Google Scholar]
  8. Mathisen, J.; Bitner-Gregersen, E. Joint distributions for significant wave height and wave zero-up-crossing period. Appl. Ocean Res. 1990, 12, 93–103. [Google Scholar] [CrossRef] [Scilit]
  9. Simão, M.L.; Videiro, P.M.; Silva, P.B.A.; Assad, L.P.F.; Sagrilo, L.V.S. Application of Taylor diagram in the evaluation of joint environmental distributions’ performances. Mar. Syst. Ocean Technol. 2020, 15, 151–159. [Google Scholar] [CrossRef] [Scilit]
  10. Haver, S. Wave climate of northern Norway. Appl. Ocean Res. 1985, 7, 85–92. [Google Scholar] [CrossRef] [Scilit]
  11. Ochi, M.K. Ocean Waves: The Stochastic Approach; Cambridge Ocean Technology Series, 6; Cambridge University Press: Cambridge, UK, 1998; pp. 1–331. [Google Scholar]
  12. Horn, J.T.; Bitner-Gregersen, E.; Krokstad, J.R.; Leira, B.J.; Amdahl, J. A new combination of conditional environmental distributions. Appl. Ocean Res. 2018, 73, 17–26. [Google Scholar] [CrossRef] [Scilit]
  13. Vanem, E. Joint statistical models for significant wave height and wave period in a changing climate. Mar. Struct. 2016, 49, 180–205. [Google Scholar] [CrossRef] [Scilit]
  14. Sklar, M. Fonctions de répartition à N dimensions et leurs marges. Ann. l’ISUP 1959, VIII, 229–231. [Google Scholar]
  15. Antão, E.M.; Guedes Soares, C. Approximation of bivariate probability density of individual wave steepness and height with copulas. Coast. Eng. 2014, 89, 45–52. [Google Scholar] [CrossRef] [Scilit]
  16. Montes-Iturrizaga, R.; Heredia-Zavoni, E. Environmental contours using copulas. Appl. Ocean Res. 2015, 52, 125–139. [Google Scholar] [CrossRef] [Scilit]
  17. Manuel, L.; Nguyen, P.T.T.; Canning, J.; Coe, R.G.; Eckert-Gallup, A.C.; Martin, N. Alternative approaches to develop environmental contours from metocean data. J. Ocean Eng. Mar. Energy 2018, 4, 293–310. [Google Scholar] [CrossRef] [Scilit]
  18. Wu, Y.; Feng, Y.; Zhao, Y.; Yu, S. Joint probability distribution of wind–wave actions based on vine copula function. J. Mar. Sci. Eng. 2025, 13, 396. [Google Scholar] [CrossRef] [Scilit]
  19. Sagrilo, L.V.S.; Lima, E.C.P.; Papaleo, A. A joint probability model for environmental parameters. J. Offshore Mech. Arct. Eng. 2011, 133, 031605. [Google Scholar] [CrossRef] [Scilit]
  20. Ang, A.H.-S.; Tang, W.H. Probability Concepts in Engineering: Emphasis on Applications in Civil & Environmental Engineering, 2nd ed.; John Wiley & Sons: Hoboken, NJ, USA, 2007; pp. 1–406. [Google Scholar]
  21. Nelsen, R.B. An Introduction to Copulas, 2nd ed.; Springer: New York, NY, USA, 2006; pp. 1–269. [Google Scholar] [CrossRef] [Scilit]
  22. Joe, H. Dependence Modeling with Copulas; CRC Press: Boca Raton, FL, USA, 2014; pp. 1–457. [Google Scholar] [CrossRef] [Scilit]
  23. Liu, P.; Der Kiureghian, A. Multivariate distribution models with prescribed marginals and covariances. Probabilistic Eng. Mech. 1986, 1, 105–112. [Google Scholar] [CrossRef] [Scilit]
  24. Joe, H.; Xu, J.J. The Estimation Method of Inference Functions for Margins for Multivariate Models; Report #166; Department of Statistics, University of British Columbia: Vancouver, BC, Canada, 1996; pp. 1–21. [Google Scholar] [CrossRef] [Scilit]
  25. ATMOSMARINE. Simultaneous Meteoceanographic Data; Report No. ATM-2019/001; ATMOSMARINE: Rio de Janeiro, Brazil, 2019; pp. 1–24. [Google Scholar]
  26. TETRA TECH. Caracterização Meteoceanográfica das Bacias de Campos, Santos e da Margem Equatorial; Report No. 24094-0000-MOG-RL001-A; TETRA TECH: Rio de Janeiro, Brazil, 2024; pp. 1–35. [Google Scholar]
  27. Akaike, H. Information theory and an extension of the maximum likelihood principle. In Proceedings of the Second International Symposium on Information Theory, Tsahkadsor, Armenia, 2–8 September 1971; Akadémiai Kiadó: Budapest, Hungary, 1973; pp. 267–281. [Google Scholar] [CrossRef] [Scilit]
  28. Schwarz, G. Estimating the dimension of a model. Ann. Stat. 1978, 6, 461–464. [Google Scholar] [CrossRef] [Scilit]
  29. Winterstein, S.R.; Ude, T.C.; Cornell, C.A.; Bjerager, P.; Haver, S. Environmental parameters for extreme response: Inverse form with omission factors. In Proceedings of the ICOSSAR-93, Innsbruck, Austria, 9–13 August 1993. [Google Scholar]
  30. Rosenblatt, M. Remarks on a multivariate transformation. Ann. Math. Stat. 1952, 23, 470–472. [Google Scholar] [CrossRef] [Scilit]
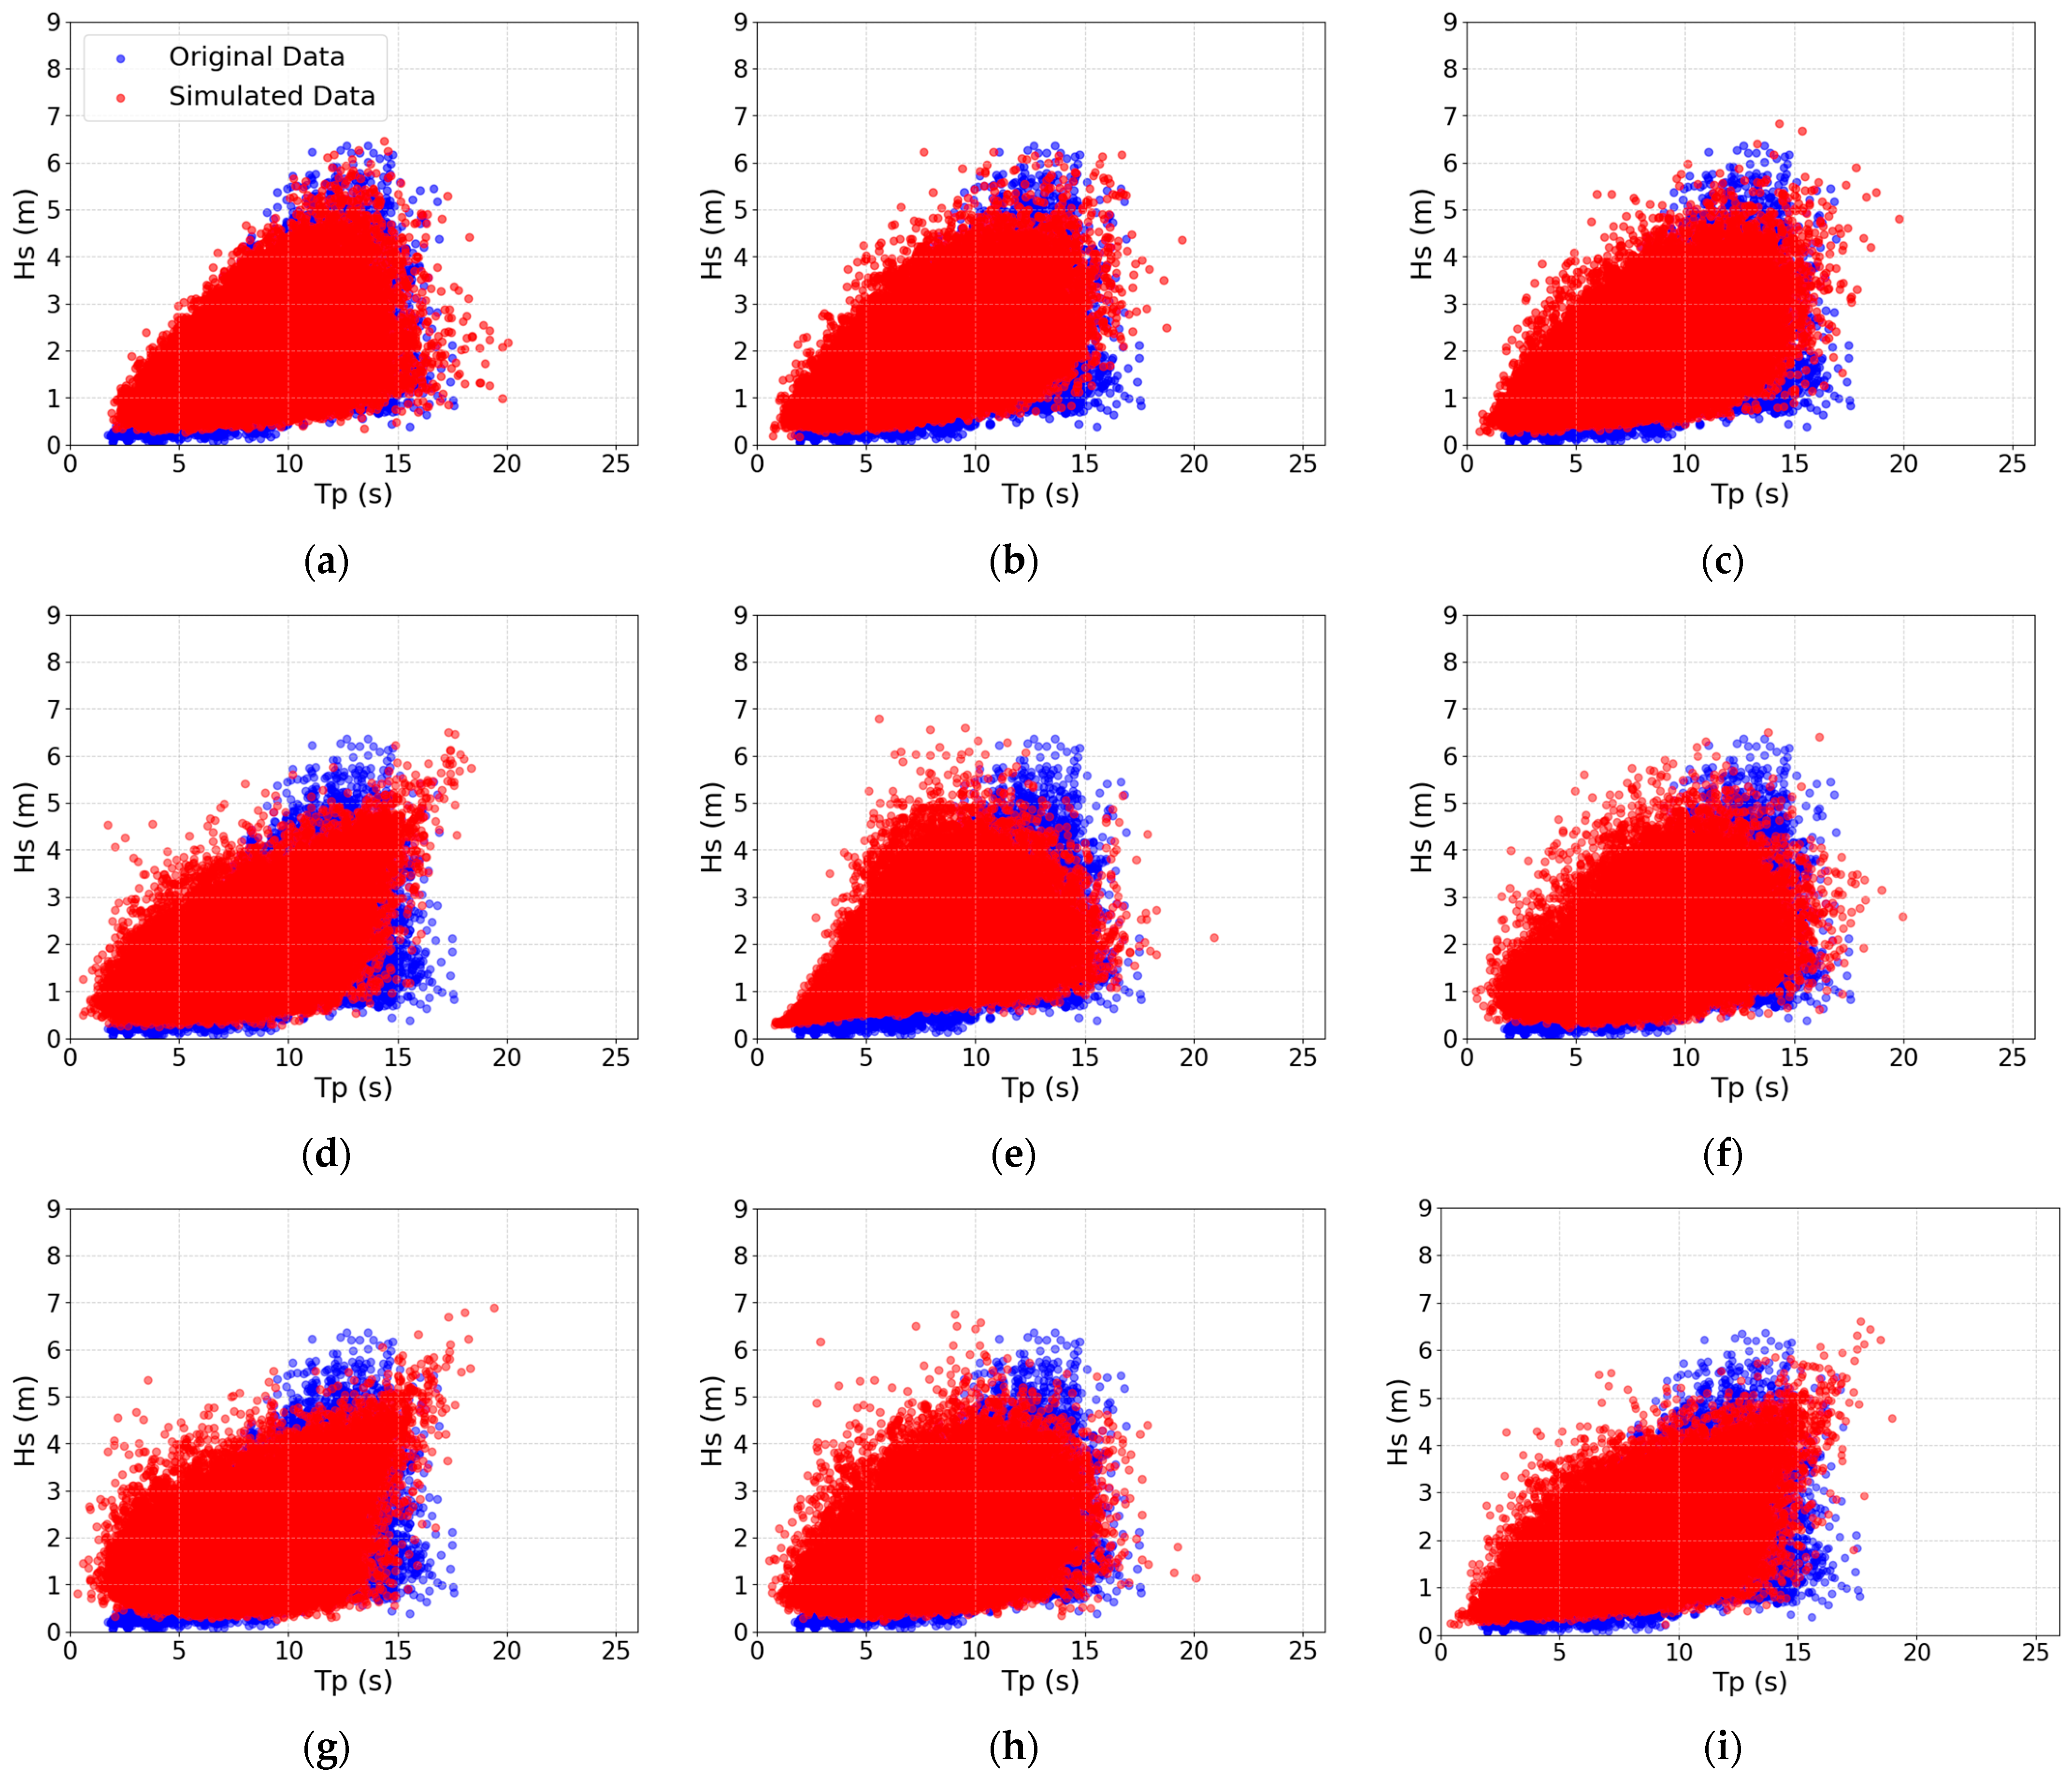
Figure 1. Overview of the modeling framework.
Mathematics 14 02014 g001
Figure 2. Marginal fitting for H s —C1-sea: (a) Fitted PDFs; (b) Fitted CDFs; (c) Ranking by upper tail MRE; (d) Survival function (1% tail).
Mathematics 14 02014 g002
Figure 3. Marginal fitting for T p —C1-sea: (a) Fitted PDFs; (b) Fitted CDFs; (c) Ranking by upper tail MRE; (d) Survival function (1% tail).
Mathematics 14 02014 g003
Figure 4. Fitting of λ h s and ξ h s for the Lognormal distribution–Set C2–Sea: (a) the conditional mean; (b) the conditional standard deviation.
Mathematics 14 02014 g004
Figure 5. Fitting of λ h s and ξ h s for the Lognormal distribution–Set C2–Swell: (a) the conditional mean; (b) the conditional standard deviation.
Mathematics 14 02014 g005
Figure 6. Scatter plot of original and simulated data for C1-sea—high dependence coefficients scenario: (a) Conditional Model; (b) Gaussian Copula; (c) Student’s t Copula; (d) Gumbel Copula; (e) Clayton Copula; (f) Frank Copula; (g) Joe Copula; (h) Plackett Copula; (i) BB1 Copula.
Mathematics 14 02014 g006aMathematics 14 02014 g006b
Figure 7. Iso-probability curves for observed data and fitted model for C1-sea—high dependence coefficients scenario: (a) Conditional Model; (b) Gaussian Copula; (c) Student’s t Copula; (d) Gumbel Copula; (e) Clayton Copula; (f) Frank Copula; (g) Joe Copula; (h) Plackett Copula; (i) BB1 Copula.
Mathematics 14 02014 g007
Figure 8. 20-year environmental contours for C1-sea—high dependence coefficients scenario.
Mathematics 14 02014 g008
Figure 9. Scatter plot of original and simulated data for C2-sea—moderate dependence coefficients scenario: (a) Conditional Model; (b) Gaussian Copula; (c) Student’s t Copula; (d) Gumbel Copula; (e) Clayton Copula; (f) Frank Copula; (g) Joe Copula; (h) Plackett Copula; (i) BB1 Copula.
Mathematics 14 02014 g009
Figure 10. Iso-probability curves for observed data and fitted model for C2-sea—moderate dependence coefficients scenario: (a) Conditional Model; (b) Gaussian Copula; (c) Student’s t Copula; (d) Gumbel Copula; (e) Clayton Copula; (f) Frank Copula; (g) Joe Copula; (h) Plackett Copula; (i) BB1 Copula.
Mathematics 14 02014 g010
Figure 11. 20-year environmental contours for C2-sea—moderate dependence coefficients scenario.
Mathematics 14 02014 g011
Figure 12. Scatter plot of original and simulated data for C2-swell—low dependence coefficients scenario: (a) Conditional Model; (b) Gaussian Copula; (c) Student’s t Copula; (d) Gumbel Copula; (e) Clayton Copula; (f) Frank Copula; (g) Joe Copula; (h) Plackett Copula; (i) BB1 Copula.
Mathematics 14 02014 g012aMathematics 14 02014 g012b
Figure 13. Iso-probability curves for observed data and fitted model for C2-swell—low dependence coefficients scenario: (a) Conditional Model; (b) Gaussian Copula; (c) Student’s t Copula; (d) Gumbel Copula; (e) Clayton Copula; (f) Frank Copula; (g) Joe Copula; (h) Plackett Copula; (i) BB1 Copula.
Mathematics 14 02014 g013
Figure 14. 20-year environmental contours for C2-swell—low dependence coefficients scenario.
Mathematics 14 02014 g014
Figure 15. Scatter plot of original and simulated data for C3-sea—varying dependence coefficients scenario: (a) Conditional Model; (b) Gaussian Copula; (c) Student’s t Copula; (d) Gumbel Copula; (e) Clayton Copula; (f) Frank Copula; (g) Joe Copula; (h) Plackett Copula; (i) BB1 Copula.
Mathematics 14 02014 g015
Figure 16. Iso-probability curves for observed data and fitted model for C3-sea—varying dependence coefficients scenario: (a) Conditional Model; (b) Gaussian Copula; (c) Student’s t Copula; (d) Gumbel Copula; (e) Clayton Copula; (f) Frank Copula; (g) Joe Copula; (h) Plackett Copula; (i) BB1 Copula.
Mathematics 14 02014 g016
Figure 17. 20-year environmental contours for C3-sea—varying dependence coefficients scenario.
Mathematics 14 02014 g017
Table 1. Candidate distributions for univariate probabilistic modeling.
Distribution f X ( x ) Parameters
Lognormal 1 2 π x σ e x p 1 2 l n ( x ) μ σ 2 μ (scale)
σ > 0 (shape)
Weibull 2P x λ 1 α λ λ e x p x α λ λ > 0 (shape)
α > 0 (scale)
Weibull 3P x ε λ 1 α λ λ e x p x ε α λ λ > 0 (shape)
α > 0 (scale)
ε (location)
Generalized Gamma c Γ m λ c m x c m 1 e x p ( λ x ) c m > 0 (shape 1)
c > 0 (shape 2)
λ (scale)
Skew-Normal 2 σ ϕ x μ σ Φ λ x μ σ μ (location)
σ > 0 (scale)
λ (skewness)
LonoweCombination of Lognormal and Weibull 3P with transition point, x r . μ (scale)
σ > 0 (shape)
x r
λ > 0 (shape)
α > 0 (scale)
ε (location)
Note: Γ · is the Gamma function; ϕ . and Φ ( . ) denotes the PDF and CDF of the Standard Normal distribution, respectively.
Table 2. Parametric copula families.
Family C ( u , v ) Parametric
Gaussian Φ 2 Φ 1 u , Φ 1 v ; ρ ρ 1 , 1
Student’s t T 2 , ν T ν 1 u , T ν 1 v ; ρ ; ν ρ 1 , 1 ,   ν > 0
Gumbel e x p log u θ + log v θ 1 θ θ [ 1 , )
Clayton u θ + v θ 1 1 θ θ ( 0 , )
Frank 1 θ log 1 + e θ u 1 e θ v 1 e θ 1 θ R \ 0
Joe 1 1 u θ + 1 v θ 1 u θ 1 v θ 1 θ θ [ 1 , )
BB1 1 + u θ 1 δ + v θ 1 1 δ 1 θ θ 0 , ,   δ [ 1 , )
Plackett 1 2 η 1 + η u + v 1 + η u + v 2 4 θ η u v η = θ 1 ,     θ [ 0 , )
Note: Φ 2 · , · , · and T 2 , ν · , · , · , · denote the CDFs of the bivariate normal and bivariate Student’s t distributions, respectively. Φ 1 · and T ν 1 · represent the inverse CDFs of the standard normal and univariate Student’s t distributions, respectively.
Table 3. Statistical characteristics of the datasets.
ComponentPeriod ρ ^ ρ ^ S τ ^
C1-sea1999–20180.970.990.92
C1-swell1999–20180.730.700.51
C2-sea2004–20240.560.540.39
C2-swell2004–20240.130.090.07
C3-sea2004–20240.260.240.17
C3-swell2004–20240.160.110.07
Table 4. Empirical tail dependence coefficients.
Component λ L ^ ( q   =   0.10 ) λ U ^ ( q   =   0.90 )
C1-sea0.870.83
C1-swell0.340.56
C2-sea0.620.38
C2-swell0.070.16
C3-sea0.320.20
C3-swell0.060.26
Table 5. Selected marginal distributions for the H s and T p variables.
ComponentVariableDistribution
C1-sea H s Weibull 2P
C1-sea T p Lonowe
C1-swell H s Lonowe
C1-swell T p Lonowe
C2-sea H s Lonowe
C2-sea T p Generalized Gamma
C2-swell H s Lonowe
C2-swell T p Lonowe
C3-sea H s Lonowe
C3-sea T p Lognormal
C3-swell H s Lonowe
C3-swell T p Lonowe
Table 6. Parameters of the fitted copulas.
ComponentGaussian ρ t-Student ( ρ ; ν ) Gumbel ( θ ) Clayton ( θ ) Frank ( θ ) Joe ( θ ) BB1 ( θ ; δ ) Plackett ( θ )
C1-sea 0.98   * 0.98 ;   9.42   * 6.45   * 24.30 50.91 8.88   * ( 8.75 ;   2.45 ) 1000.46
C1-swell 0.72 ( 0.72 ;   11.18 ) 2.05 2.11 5.98 2.33   * ( 0.26 ;   1.82 ) 13.05
C2-sea 0.57 ( 0.57 ;   24.62 ) 1.64 1.28 4.02 1.57   * ( 0.27 ;   1.44 ) 5.97
C2-swell 0.10 ( 0.10 ;   10.74 ) 1.07 0.14 0.60 1.08   * ( 0.04 ;   1.05 ) 1.30
C3-sea 0.26 ( 0.26 ;   14.02 ) 1.19 0.39 1.52 1.09   * ( 0.33 ;   1.03 ) 2.06
C3-swell 0.11 ( 0.11 ;   12.59 ) 1.08 0.16 0.66 1.18   * ( 0.01 ;   1.14 ) 1.37
* Indicates that the parameter was estimated via IFM. All other parameters were estimated via the method of moments.
Table 7. AIC and BIC information criteria for C1-sea—high dependence coefficients scenario.
ModelAICBIC
Conditional Model 44,875.32 44,946.39
Gaussian Copula 39,621.05 39,701.01
Student’s t Copula 58,457.36 58,546.20
Gumbel Copula 56,970.91 57,050.87
Clayton Copula 313,557.89 313,637.85
Frank Copula 60,565.97 60,645.93
Joe Copula 76,332.28 76,412.24
Plackett Copula 84,996.76 85,076.72
BB1 Copula 68,666.58 68,790.96
Table 8. AIC and BIC information criteria for moderate dependence coefficients scenarios.
ModelC1-SwellC2-Sea
AICBICAICBIC
Conditional Model 224,612.19 224,719.90 375,902.39 376,010.10
Gaussian Copula 230,095.64 230,212.32 383,843.05 383,959.74
Student’s t Copula 228,994.08 229,119.74 383,197.92 383,323.58
Gumbel Copula 225,035.34 225,152.02 388,699.06 388,815.74
Clayton Copula 274,878.19 274,994.87 395,498.50 395,615.18
Frank Copula 225,422.74 225,539.42 387,724.97 387,841.65
Joe Copula 228,228.30 228,344.98 395,651.88 395,768.57
Plackett Copula 226,388.55 226,505.24 387,162.63 387,279.31
BB1 Copula 235,005.91 235,131.57 390,060.95 390,186.61
Table 9. AIC and BIC information criteria for low dependence coefficients scenario.
ModelC2-SwellC3-Swell
AICBICAICBIC
Conditional Model 353,756.04 353,863.64 294,951.80 295,059.23
Gaussian Copula 351,668.72 351,785.29 290,405.37 290,521.74
Student’s t Copula 350,781.70 350,907.24 289,518.33 289,643.66
Gumbel Copula 351,271.33 351,387.90 289,021.74 289,138.12
Clayton Copula 353,672.76 353,789.32 293,060.22 293,176.60
Frank Copula 351,275.77 351,392.34 289,981.02 290,097.40
Joe Copula 351,079.91 351,196.48 288,385.52 288,501.90
Plackett Copula 351,231.45 351,348.02 289,948.67 290,065.04
BB1 Copula 351,753.62 351,879.16 289,831.44 289,956.77
Table 10. Local dependence by T p tertile bands.
ComponentBand ρ ^ τ ^ ρ ^ S
C1-sea T 1 :   T p   3.06   s 0.920.830.93
C1-sea T 2 :   3.06   s < T p   4.10   s 0.880.810.94
C1-sea T 3 :   T p > 4.10   s 0.940.750.92
C1-swell T 1 :   T p   8.15   s 0.310.220.33
C1-swell T 2 :   8.15   s < T p   9.13   s 0.250.170.25
C1-swell T 3 :   T p > 9.13   s 0.570.350.50
C2-sea T 1 :   T p   6.65   s 0.720.520.69
C2-sea T 2 :   6.65   s < T p   8.40   s 0.120.060.09
C2-sea T 3 :   T p > 8.40   s 0.280.180.26
C2-swell T 1 :   T p   8.73   s 0.170.080.12
C2-swell T 2 :   8.73   s < T p   11.02   s 0.130.080.11
C2-swell T 3 :   T p > 11.02   s −0.17−0.12−0.19
C3-sea T 1 :   T p   7.72   s 0.490.240.34
C3-sea T 2 :   7.72   s < T p   8.52   s 0.120.070.10
C3-sea T 3 :   T p > 8.52   s −0.070.010.01
C3-swell T 1 :   T p   8.34   s 0.150.090.13
C3-swell T 2 :   8.34   s < T p   10.75   s −0.07−0.07−0.10
C3-swell T 3 :   T p > 10.75   s 0.060.050.06
Table 11. AIC and BIC information criteria for C3-sea—varying dependence coefficients scenario.
ModelAICBIC
Conditional Model 295,180.38 295,288.08
Gaussian Copula 303,298.76 303,379.54
Student’s t Copula 300,425.78 300,515.53
Gumbel Copula 308,810.31 308,891.09
Clayton Copula 298,943.81 299,024.59
Frank Copula 308,368.90 308,449.68
Joe Copula 311,445.61 311,526.39
Plackett Copula 308,368.57 308,449.35
BB1 Copula 306,847.00 306,972.66
Table 12. Residual Kendall’s tau after Rosenblatt transformation.
ModelC1-SeaC2-SwellC3-Swell
Conditional Model0.16−0.19−0.16
Gaussian Copula0.24−0.006−0.003
Student’s t Copula0.40−0.008−0.002
Gumbel Copula0.38−0.010−0.004
Clayton Copula0.31−0.010−0.011
Frank Copula−0.11−0.0030.001
Joe Copula0.370.007−0.003
Plackett Copula0.340.0050.003
BB1 Copula0.32−0.010−0.062
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.