


Abstract
This paper investigates the latent block structure in the heterogeneous panel data model. It is assumed that the regression coefficients have group structures across individuals and structural breaks over time, where change points can cause changes to the group structures and structural breaks can vary between subgroups. To recover the latent block structure, we propose a robust biclustering approach that utilizes M-estimation and concave fused penalties. An algorithm based on local quadratic approximation is developed to optimize the objective function, which is more compact and efficient than the ADMM algorithm. Moreover, we establish the oracle property of the penalized M-estimators and prove that the proposed estimator recovers the latent block structure with a probability approaching one. Finally, simulation studies on multiple datasets demonstrate the good finite sample performance of the proposed estimators.
MSC:
62J07
1. Introduction
Panel data models can fully utilize both cross-sectional and time-series information, making them a popular tool in fields such as economics and finance. Traditional panel data models often assume that the regression coefficients are homogeneous across individuals and over periods, which is too rigid an assumption. In many real-world applications, heterogeneity in individual and/or time dimensions is often observed. For example, in precision medicine research, different subgroups of patients may respond differently to treatments, while in economics, events such as the 2009 European debt crisis led to varying debt-to-GDP ratios among European countries. Although these heterogeneous factors are unobserved and latent, modeling them will bring significant improvement to data analysis.
Numerous estimation methods have been developed for panel data models with heterogeneous coefficients, addressing two main sources of heterogeneity: individual and period. To account for heterogeneity across individuals, a commonly used assumption is that individuals can be classified into subgroups with identical coefficients within the same subgroup but different coefficients across subgroups. Penalty-based methods have been frequently used to cluster coefficients in the individual direction. Su et al. [1] propose C-Lasso, a modified version of Lasso, for subgroup identification and coefficient estimation. This method is based on a penalized objective function inspired by the fused Lasso method introduced by Tibshirani et al. [2]. Wang and Zhu [3] study high-dimensional panel data models using a concave fused penalty method for both subgroup identification and variable selection and proved the asymptotic properties of the proposed estimator under specific regularity conditions. To capture the heterogeneity that may exist over time, structural breaks are often assumed. Qian and Su [4] use a group fused Lasso method to estimate both the number of breaks and model parameters simultaneously. Furthermore, Qian and Su [5] employ an adaptive group fused Lasso approach that applies the shrinkage method to PLS and PGMM estimations. Their method can consistently determine the number of breaks and estimate the break dates with a probability approaching one.
However, these studies have two primary limitations. Firstly, they only account for heterogeneity in one dimension, which may be insufficient for modeling complex data prevalent in the era of big data. Secondly, their objective functions employ the least squares loss which can result in substantial estimation bias when the data distribution contains a heavy tail or outliers. Consequently, further research has been conducted to address these issues. Some researchers have focused on the two-dimensional heterogeneous panel data model, where the coefficients exhibit both subgroup structure and structural breaks. Okui and Wang [6] allow the number, timing, and size of structural breaks to vary across different subgroups and employ the K-means method and adaptive group fused Lasso method to identify the individual group structure and structural breaks, respectively. Lumsdaine et al. [7] study cases where the group structure of coefficients changes after the unknown structural break and develop a novel iterative algorithm to estimate the coefficients and recover the unknown structure. Additionally, some researchers have focused on robust estimation. For example, Zhang et al. [8] set the objective function as the sum of loss and concave pairwise fused penalty when studying the panel data model with an individual group structure and provide an easy-to-implement algorithm based on the idea of local linear approximation [9] to find local minima. Cheng et al. [10] further generalize the loss to a general loss function under the framework of M-estimation.
In this paper, we generalize the coefficient structure studied by [6,7] to a more general block structure. The regression coefficients with a block structure exhibit both an individual-group structure and temporal–structural breaks, where the individual-group structure can change at change points, and the temporal–structural breaks can vary across different groups. Furthermore, the regression coefficients are identical within the same sub-block, while they exhibit heterogeneity across different sub-blocks. This block structure is highly flexible and more general compared to the structures studied previously. Additionally, the homogeneous panel data model, the panel data model with a group structure, and the panel data model with structural breaks can all be viewed as special cases of the model being investigated in this study.
We propose a robust biclustering method based on M-estimation and double concave fused penalties for simultaneously recovering the unknown block structure and estimating the regression coefficients. The M-estimator exhibits robustness to heavy-tailed distributions and outliers, while the double concave fused penalty can automatically identify potential block structure. We develop an effective algorithm utilizing local quadratic approximation to optimize the objective function, which is computationally more efficient than the Alternating Direction Method of Multipliers (ADMM) [11] algorithm. Moreover, we establish the asymptotic convergence property of the oracle estimator and prove that the proposed estimator can recover the latent block structure with a probability approaching one. Simulation experiments on multiple datasets demonstrate that the estimator proposed in this paper has an excellent performance in finite sample situations. Additionally, models based on loss and loss functions can achieve more accurate results than those based on loss functions in the presence of heavy-tailed data distributions.
2. Materials and Methods
2.1. Model Setting
Given panel data observations , this paper explores a linear panel data model that accounts for the heterogeneity of intercept and slope coefficients across both the individual and time dimensions. The model is represented as follows,
where is the response variable, and is the explanatory variable. The intercept term and the slope coefficient can vary across both individual and time dimensions in the model. The random errors are assumed to be independent and identically distributed with a mean of 0 and a standard deviation of , and their distribution is denoted by f.
We assume that the observed data are collected from an unknown, different blocks, where the regression coefficients are homogeneous within the same block but heterogeneous across different blocks. It is worth noting that the group structure and structural breaks can be viewed as special cases of the block structure. Below, we provide the relevant notation to describe this block structure.
Let and . Then, Equation (1) can be expressed as follows,
We denote the block structure as , where represents the index set of samples belonging to the kth sub-block. If the ith individual’s observation at time t belongs to the kth sub-block, then . Let denote the real regression coefficients corresponding to the sub-blocks, and let be the real value of . Then, we have
In practical scenarios, the real block structure is often unknown. To recover the block structure described above, it is necessary to estimate the number of sub-blocks, the index sets of each block, and the block-specific coefficients.
2.2. Proposed Estimator
In this subsection, we propose a biclustering estimation method to automatically recover the block structure without specifying the number of blocks and provide robust estimates of regression coefficients via M-estimation and concave fused penalties. Let denote the coefficients to be estimated. To recover the block structure under the fused sparse assumption, a natural idea is to shrink the coefficient differences between two samples and that belong to the same block to zero. In the following, we present the objective function based on M-estimation and concave fused penalty as follows,
where the first term on the right-hand side is the regular loss function in the M-estimation literature. It satisfies several conditions, including being a continuous convex function on , almost everywhere differentiable except for a finite set of points, having a unique global minimum at 0, and . Commonly used loss functions such as least squares (), absolute deviation (), and Huber loss all satisfy these conditions. The second and third terms are two fused penalty terms designed to identify the individual-group structure and temporal–structure breaks.
Commonly used penalty terms include Lasso [12], Ridge [13], and Elastic net [14]. Ridge and Elastic net can shrink the fusion terms toward small values, but not exactly zero, which makes it challenging to cluster coefficients within the same block. Lasso, on the other hand, can shrink the fusion terms to exactly zero but has a tendency to introduce bias in the estimated coefficients. This bias can impact the accuracy of the parameter estimates and potentially lead to suboptimal results in recovering the latent block structure. To achieve both automatic recovery of the parameter structure and unbiased or nearly unbiased estimation of coefficients, concave fused penalty functions have been proposed, such as the smoothly clipped absolute deviation (SCAD) [15] and the minimax concave penalty (MCP) [16]. In this paper, following the approach of Wang and Zhu [3], Ma and Huang [17], Wang et al. [18], we use the SCAD penalty function with a tuning parameter ,
and the MCP penalty function with a tuning parameter ,
where the fixed parameter a controls the concavity of the penalty function, and k represents pairwise differences in regression coefficients between individuals or periods. and can compress some pairwise difference values and to zero, thereby recovering the block structure of the regression coefficients.
For a given and , we define the proposed estimator as
In the following, we abbreviate as when there is no ambiguity. Although the penalty term in Equation (4) is concave and global minimum points are difficult to obtain, local minimum points can be obtained through iterative algorithms. Ma and Huang [17] and Wang et al. [18] apply the ADMM algorithm to solve the penalized optimization problem by transforming it into a Lagrangian-constrained optimization problem. However, the algorithm is computationally intensive and involves cumbersome steps. In this paper, we develop a novel algorithm based on local quadratic approximation [15] to solve Equation (4). In the next section, we provide a detailed derivation.
2.3. Proposed Algorithm
We propose a local quadratic approximation-based algorithm to solve Equation (7). The local quadratic approximation algorithm was introduced by Fan and Li [15]. Specifically, given a non-zero value as the initial value for the penalty function , we can apply a first-order Taylor expansion on as follows,
Specifically, let denote the estimate of obtained after the th iteration. At the kth iteration, we locally approximate , , and around , which yields
where , , and are the derivatives of , , and , respectively. C depends on and can be treated as a constant when solving for the kth estimator. By minimizing , we obtain .
Equation (9) has an explicit solution. To simplify Equation (9), we first define some symbols as follows,
where the square root symbol , the function , the division symbol , and the absolute value function represent the corresponding operations performed on each element of the vector when they act on vectors.
Let be an N-dimensional vector with 1 in the i-th dimension and 0 in the other dimensions, and let be a T-dimensional vector with 1 in the tth dimension and 0 in the other dimensions. We define
where , , and are identity matrices, and ⊗ represents the Kronecker product. We concatenate for and for to obtain
Let and . and are both NTP-dimensional vectors that can be expressed as and , respectively, where and are P-dimensional vectors. Let and be the norms of and , respectively. Let ,
Thus, Equation (9) can be written as
where .
By minimizing the above equation, we obtain the iteration formula for the kth step,
We repeat this iteration process until the norm of the difference between and is smaller than a given threshold (set to 1e-5 in our experiments), at which point the algorithm terminates. As noted by Hunter and Li [19], this algorithm belongs to the class of MM algorithms, and its convergence is guaranteed.
To perform the iterative process, it is necessary to specify the initial value of the regression coefficients. An appropriate initial value can reduce the number of iterations and computation time. Following the approach of Wang et al. [18], we use ridge regression to obtain the initial values. The specific formula is as follows,
Here, and are tuning parameters, which are set to 1e-3 in all subsequent experiments.
To select the optimal tuning parameters in the objective function, we use the modified Bayesian information criterion (mBIC) [20], which has been widely utilized for hyperparameter selection in the field of heterogeneous structure recovery [8,10,21,22]. Notably, Cheng et al. [10] have demonstrate the selection consistency of mBIC within the context of subgroup identification tasks under the framework of M-estimation. In this paper, we denote the mBIC as follows,
where is an estimate of the number of sub-blocks, and c is a constant. In this paper, when is the loss, we follow the setting of Ma and Huang [17] and set ; when is the loss, we follow the setting of Zhang et al. [8] and set ; when is Huber, we also set . To search for the optimal values of the parameters , , and the controlling parameter a in the penalty functions, we use grid search to traverse the ranges of , , and , respectively, with a given step size. We calculate the mBIC value for each combination of , , and a. The combination that results in the minimum mBIC is selected as the optimal tuning parameters, which are then used to obtain the final estimation result.
2.4. Asymptotic Properties
We first investigate the property of oracle estimator. If the underlying block structure is known, the oracle estimator is defined by
where . The oracle estimator is unavailable in practice because it assumes the knowledge of the real block structure, but it plays a significant role in theoretical analysis.
First, we define some notations. Let denote the pth element of . and denote the minimum and maximum eigenvalues of a matrix, respectively. Let denote the derivative of , and denote the first and second derivatives of , respectively, and denotes the first derivative of the distribution function f of . denotes the unit sphere in .
Since may have nondifferentiable points, its derivative may have discontinuities. Therefore, we need to classify and discuss according to its properties. Following the method of He and Shao [23], we classify into two categories: smooth function and jump function. When is Lipschitz continuous on its domain, we call it a smooth function; when has a finite number of jump points but is Lipschitz continuous on the intervals between two adjacent jump points, we call it a jump function. It is clear that loss and Huber loss are smooth functions, while loss is a jump function.
We introduce the following assumptions.
(A1). There exists a constant such that
and there exist two positive constants and such that
(A2). , for some
(A3). When the loss function is a smooth function, and are bounded by ; when the loss function is a jump function, , f, and are bounded by .
(A4).
Remark 1.
Assumption (A1) is a regularization assumption on the design matrix, where the minimum and maximum eigenvalues of are bounded by constants, which is a common assumption in heterogeneity panel data analysis based on concave fused penalties; see Ma and Huang [17], Ma et al. [22], Wang and Zhu [3], etc. Assumption (A2) allows the real coefficients dimension to increase with the sample size but at a slower rate. Assumption (A3) provides bounds on the loss function and error term distribution for different types of ϕ. This assumption is used by He and Shao [23] to prove the asymptotic normality of the M-estimator in linear regression models. For commonly used loss functions in the M-estimation field (such as , , and Huber) and commonly used error term distributions (such as normal and t-distributions), it is easy to prove that assumption (A3) is satisfied. Assumption (A4) further imposes restrictions on the design matrix, where if is a random sample from a P-variate distribution and for any , that is uniformly bounded, then assumption (A4) holds, obviously.
Under these assumptions, we can obtain the consistency properties of the oracle estimator.
Theorem 1.
Under assumptions (A1)–(A4), we have
We can also provide the asymptotic normal theory for the oracle estimator (Proof of Theorem 1 in Appendix A.1).
Theorem 2.
Under assumptions (A1)–(A4), we have
where , and d is a vector such that (Proof of Theorem 2 in Appendix A.2).
Let b denote the minimum difference between coefficients of any two sub-blocks, i.e., . Let denote the sample size of the smallest sub-block. Let and denote the standardized penalty functions, where and are their derivatives. To derive the asymptotic properties of our proposed estimator, additional assumptions are required.
(A5). For any , there exists such that
where is defined in Assumption (A2).
(A6). There exist two positive constants and such that for any and , we have
(A7). The normalized penalty functions and are symmetric non-decreasing functions that are convex on . We have . There exist positive numbers and such that and are constant when and , respectively. The derivatives and are continuous except at a finite number of points, and
Remark 2.
Assumption (A5) provides the minimum difference in regression coefficients between different sub-blocks, which is essential for the separability of the coefficients. Assumption (A6) further restricts the error term, which is relatively mild for M-estimators. Specifically, when ρ is the loss, , and assumption (A6) is equivalent to requiring that the error term has sub-Gaussian tails, which is a common assumption in the field of high-dimensional statistics. When ρ is the or Huber loss, assumption (A6) obviously holds because ϕ is bounded by a constant. Assumption (A7) restricts concave penalty functions, which can be easily verified to be satisfied by SCAD and MCP, where positive a and control the concavity of the penalty function. It should be noted that when , is constant. This means that when and belong to different sub-blocks, the fused penalty term tends to be constant; i.e., it does not compress the coefficient differences of different sub-blocks.
Theorem 3.
Under assumptions (A1)–(A7) and , , the oracle estimator is a local minimizer of the objective function with probability tending to one, i.e., as both N and T , we have
Under the conditions of Theorems 2 and 3, we can obtain the following corollary (Proof of Theorem 3 in Appendix A.3).
Corollary 1.
where , and d is a vector such that .
In practice, the distribution of is unknown, and the estimate of can be taken as
When is a smooth function, the estimate of is denoted as
3. Simulation
3.1. Simulation Setting
This section presents two artificially constructed examples to investigate the finite-sample performance of the proposed estimator. The simulated data are independently generated from the following model,
We consider different combinations of the number of individuals N, the time range T, and the dimension of the regression coefficients P. For each combination of , we change the distribution of from normal to heavy-tailed and compared the estimation results under different loss functions, including L1, Huber, and L2 loss.
We use the MCP penalty function in the experiment, as SCAD yields similar results and is therefore not presented. The maximum number of iterations is set to 50, and the threshold is set to . The algorithm terminates when the number of iterations exceeds 50 or the update range of coefficients is less than . Each group of experiments is repeated times. In each experiment, we perform a grid search to select the optimal tuning parameters , , and a by comparing the mBIC values. The range of and is with a step size of 0.2, and the range of a is with a step size of 2. We utilize the following metrics to assess the systematic error of the regression coefficient estimation and the precision of the block structure recovery.
- RMSE: root mean square error between the estimated parameter and the real parameter .
- Bias: bias between the estimated parameter and the real parameter .
- Per: the percentage that the estimated number of blocks and the real number of blocks are equal.
- ERI: The Rand Index (RI) is used to evaluate the accuracy of clustering, which ranges between 0 and 1, with higher values indicating better performance. Motivated by the formation of , we can calculate individual or period-specific s, denoted as or , respectively. We define as the averages over all periods and individuals, as follows,
3.2. Simulation Examples
Example 1.
In this example, we generate simulated data from the following model,
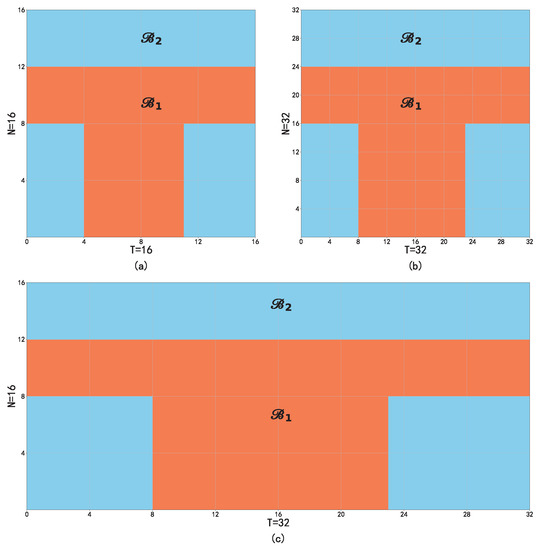
where and are independent and identically distributed standard normal random variables. The intercept term and slope coefficients have dimension 1 and exhibit the same block structure. As shown in Figure 1, we construct three sets of panel data by varying the combinations of N and T. Each set of data can be partitioned into two sub-blocks and , corresponding to coefficients and , respectively.
Figure 1.
Block structures corresponding to different combinations of N and T in Example 1. The orange regions correspond to block 1, and the blue regions correspond to block 2. (a) shows the block structure for . (b) shows the block structure for . (c) shows the block structure for and .
To verify the robustness of the proposed method, we consider three scenarios for generating . Scenario 1 (normal distribution): . Scenario 2 (heavy-tailed distribution): , where denotes the Student’s t-distribution with 3 degrees of freedom. Scenario 3 (mixture distribution): .
We obtain nine groups of panel data by varying the combinations of and the distribution of . For each group of data, we compare the performance of the oracle estimator, the -loss-based estimator, the -loss-based estimator, and the Huber-loss-based estimator. The oracle estimator is the estimator when the block structure is known, and for convenience, we use the loss as its loss function, so the oracle estimator has an explicit solution. The estimators under an unknown block structure are influenced by the tuning parameters , , and a. We use a grid search method to obtain the optimal hyperparameter combination following the setting in Section 2.3. Additionally, there is an extra parameter in the Huber loss function to control the shape of the loss function, and we use the default value of 1.345.
Example 2.
In this example, we adopt the block partitioning method under different combinations of as in Example 1 with the difference being an increase in the dimension of the regression coefficients from 2 to 4. The model is specified as follows,
where the real coefficients of the first block are , and those of the second block are . The explanatory variables are generated from a multivariate normal distribution with mean and covariance matrix
The error term is generated according to the same mixture distribution as in Example 1. We obtain three sets of panel data for different combinations of N and T.
For each set of data, we compute the oracle estimator and the estimator for the unknown block structure following the same procedure as in Example 1. Then, we analyze various result indicators to investigate the performance of the proposed method as the dimension of the regression coefficients increases.
Example 3.
To evaluate the effectiveness of a dual-penalty in handling two-dimensional heterogeneous panel data, we conduct an ablation experiment by removing either the individual dimension penalty or the time dimension penalty from the objective function (4) and comparing the results with the full objective function that includes both penalties.
We use a set of simulated data from Example 1, where the data have a dimension of , the error term follows a standard normal distribution, and the loss term in the objective function is the loss.
3.3. Simulation Results
Table 1, Table 2 and Table 3 display the simulation results for Example 1, corresponding to three different distributions of the error term. In each table, we consider three combinations of , reporting the results of the oracle estimator when the block structure is known, and the results based on three different loss functions when the block structure is unknown. The objective function for obtaining the oracle estimator is set to use the loss. Since obtaining the oracle estimator is difficult in practice, we use it only for comparison. We report the mean and standard deviation of 100 repeated experiments, with the standard deviation displayed in parentheses.
Table 1.
Experimental Indicators of Each Combination When the Error Term is Normally Distributed in Example 1.
Table 2.
Experimental Indicators of Each Combination When the Error Term is t-Distributed in Example 1.
Table 3.
Experimental Indicators of Each Combination When the Error Term Follows a Mixture Distribution in Example 1.
In Table 1, the error terms follow the standard normal distribution. Simulations based on loss and Huber loss perform similarly to those based on loss. In terms of coefficient estimation, when , the loss slightly outperforms and Huber losses, but as N and T increase, the differences among the three simulation results diminish, and they all approach the oracle estimator. In terms of structural recovery, the Per metric equals 1 in the second and third combinations of , indicating that the estimated number of blocks equals the actual number of blocks. The ERI metric approaches 1, indicating that the method accurately classifies the samples into the correct sub-blocks.
In Table 2, the error terms follow a heavy-tailed t distribution. It is evident that the results based on loss and Huber loss outperform those based on loss. When , we even observe that the RMSE metric based on loss is slightly lower than the oracle estimator based on loss. This is because the heavy-tailed distribution increases the probability of outliers in the simulated data, and loss is more sensitive to outliers than loss. As N and T increase, the results based on and Huber losses approach the oracle estimator, and the RMSE and Bias metrics for coefficient estimation become increasingly closer to those of the oracle estimator. The Per and ERI metrics reach or approach 1, indicating that the method accurately recovers the block structure.
In Table 3, the error terms follow a mixture of normal distributions with a stronger heavy-tailed effect. The simulation results are worse than those of the previous two cases, but those based on loss and Huber loss are still better than those based on loss. As N and T increase, the Per and ERI metrics gradually approach 1. This simulation experiment also confirms the robustness and block structure recovery ability of the proposed estimator.
Below, we analyze the performance of the proposed estimator as the dimension of the coefficient P increases. In Table 4, the error term follows a heavy-tailed mixture normal distribution. Increasing P makes coefficient estimation and block structure recovery more challenging, but the performance metrics corresponding to loss and Huber loss remain superior to those of loss. As N and T increase, all performance metrics of the estimator improve significantly, and the metric corresponding to loss approaches 0.9 when .
Table 4.
Experimental Indicators of Each Combination When the Error Term Follows a Mixture Distribution and P = 4 in Example 2.
Finally, we present the results of the ablation experiment with fused penalty terms. Since the simulated data have a block structure, setting penalty terms only in one dimension cannot effectively compress the coefficient differences in the other dimension and thus cannot recover the block structure. Hence, we report only the results of the RMSE and Bias metrics in Table 5. The performance of the double-penalty method exceed those of any single-dimensional penalty method by a large margin, indicating the necessity of biclustering analysis for block panel data. The double-penalty method not only recovers unknown structures but also greatly reduces the estimation error of the coefficients.
Table 5.
Ablation Experiment of Penalty Terms in Example 3.
4. Discussion
Panel data models with heterogeneous coefficients have gained a lot of attention in various fields due to their ability to capture complex data patterns. In this paper, we extend the existing literature by proposing a more general block structure that captures heterogeneity in individual and time dimensions in a flexible manner. Our proposed model exhibits both an individual-group structure that can change at change points and temporal–structural breaks that can vary across different groups. A robust biclustering method based on M-estimation and double concave fused penalties is developed to estimate the coefficients, which can handle heavy-tailed data and outliers. Under certain regularity conditions, we established the asymptotic normality of the oracle estimator and the proposed estimator. Numerical simulations have validated the excellent finite-sample performance of our proposed method by evaluating the recovery of unknown structures as well as the estimated bias of regression coefficients. Furthermore, in our numerical simulations, we specifically investigate the performance of our proposed model in the presence of heavy-tailed distributions, which highlights the superior performance of our proposed method in handling outliers. We believe that our method has potential applications in various fields where data exhibit complex heterogeneity.
Despite the progress made, there are still some limitations and further research topics that warrant further exploration. First among these is the lack of convergence proof for the Bayesian information criterion. To achieve this, more regularization assumptions would be required for the distribution of covariates and error terms. For relevant work in this area, researchers can consider the methodology proposed by Cheng et al. [10] for clustering individual group structures. A second challenge arises from the high-dimensional matrix calculations involved in the algorithm for solving the objective function. The computational requirements increase exponentially with N and T. To address this issue, the divide-and-conquer method can be used for parallel computation to improve the algorithm’s efficiency. Finally, variable selection through L1 penalty on covariates is another promising area for further research, particularly in situations with high-dimensional covariate dimensions P. These areas of investigation will be the topic of future studies.
Author Contributions
Methodology, W.C.; Software, W.C.; Formal analysis, W.C.; Investigation, W.C.; Resources, Y.L.; Data curation, W.C.; Writing—original draft, W.C.; Writing—review & editing, Y.L.; Supervision, Y.L.; Project administration, Y.L. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
All data generated or analyzed during this study are included in this article.
Conflicts of Interest
The authors declare no conflict of interest.
Appendix A
In the appendix, we provide the proofs of Theorems 1–3.
Appendix A.1. Proof of Theorem 1
Here, we present the proof of Theorem 1. The first conclusion of Theorem 1 follows directly from Example 1 in He and Shao [23].
Since , there exists a positive constant C such that . Using the relationship between and , we have
Thus, .
Finally, applying a simple inequality yields
This completes the proof of Theorem 1.
Appendix A.2. Proof of Theorem 2
By assumption (A2), there exists such that . Clearly,
Therefore, by Example 1 in He and Shao [23], the result of Theorem 2 follows directly.
Appendix A.3. Proof of Theorem 3
We partition the block structure of regression coefficients as follows: we first divide the samples into C groups according to the group structure in the dimension of individuals; then, we partition them into K time periods according to the structural breaks in the time dimension (if there exist structural breaks for any individuals at given time period, we perform segmentation on all individuals instead of splitting individuals under given groups). In this way, we obtain sub-blocks, which obviously exceeds the number of true sub-blocks. Let be the set of sample indexes that belong to both the cth individual group and the l-th true sub-block, and let be the set of sample indexes that belong to both the kth time group and the lth true sub-block. Denote
where the variable denotes the number of samples belonging to both the cth individual group and the lth true sub-block, while represents the number of samples belonging to both the kth time group and the lth true sub-block. To simplify the notation without creating confusion, we use to refer to the objective function in Equation (4), which is defined as
and let
Let denote the set of coefficients with a block structure. We define a mapping , which maps a block-structured -dimensional vector to an -dimensional vector . Here, is the concatenation of L P-dimensional vectors, with the lth vector representing the coefficients for the lth sub-block. Additionally, we define a mapping , which maps any -dimensional vector to an -dimensional vector based on the block structure of as follows. For any and , the mapping process is given by
From the properties of the mappings T and , it follows that for any , we have , . Let , then . Therefore, we conclude that,
We denote the true regression coefficients as and , and the oracle estimators as and . Then, we define the set
We now prove Theorem 2 in two steps.
(i) Let , and denote . For all , we have with a probability tending to 1.
(ii) Define the set , where s is a positive sequence. When s is small enough, we have with a probability tending to 1 for all .
Clearly, if (i) and (ii) are proved, then for any , we have , which means that the oracle estimator is a local minimum of , and this conclusion holds with probability tending to 1.
The proof for (i) is as follows. Let ; then,
therefore, all l and , the following inequation holds,
Using the inequality from assumption (A5), , and the condition , we can obtain
Therefore, assumption (A7) implies , where C is a constant, and . Since is the global minimum of , it follows that for any . Finally, using (A11), we have and , so for any . This completes the proof of conclusion (i).
Continuing with the proof for result (ii), we define two functions
By Taylor expanding around , we can decompose the difference of the objective function into three parts,
where each part takes the following form:
Here, , where is a scalar between 0 and 1.
First, let us handle the first part,
By Assumption (A6) and , we can deduce that,
which implies that as N and T approach infinity, holds with probability tending to one. Thus, we can bound as follows,
For and , using the results from Wang et al. [18] and Fang et al. [24], we have
Finally, by combining the above results, we can obtain
As , . Moreover, since , we have .
This completes the proof.
References
- Su, L.; Shi, Z.; Phillips, P.C. Identifying latent structures in panel data. Econometrica 2016, 84, 2215–2264. [Google Scholar] [CrossRef] [Scilit]
- Tibshirani, R.; Saunders, M.; Rosset, S.; Zhu, J.; Knight, K. Sparsity and smoothness via the fused LASSO. J. R. Stat. Soc. Ser. B 2005, 67, 91–108. [Google Scholar] [CrossRef] [Scilit]
- Wang, W.; Zhu, Z. Group structure detection for a high-dimensional panel data model. Can. J. Stat. 2022, 50, 852–866. [Google Scholar] [CrossRef] [Scilit]
- Qian, J.; Su, L. Shrinkage estimation of regression models with multiple structural changes. Econom. Theory 2016, 32, 1376–1433. [Google Scholar] [CrossRef] [Scilit]
- Qian, J.; Su, L. Shrinkage estimation of common breaks in panel data models via adaptive group fused Lasso. J. Econom. 2016, 191, 86–109. [Google Scholar] [CrossRef] [Scilit]
- Okui, R.; Wang, W. Heterogeneous structural breaks in panel data models. J. Econom. 2021, 220, 447–473. [Google Scholar] [CrossRef] [Scilit]
- Lumsdaine, R.L.; Okui, R.; Wang, W. Estimation of panel group structure models with structural breaks in group memberships and coefficients. J. Econom. 2023, 233, 45–65. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.; Wang, H.J.; Zhu, Z. Robust subgroup identification. Stat. Sin. 2019, 29, 1873–1889. [Google Scholar] [CrossRef] [Scilit]
- Zou, H.; Li, R. One-step sparse estimates in nonconcave penalized likelihood models. Ann. Stat. 2008, 36, 1509–1533. [Google Scholar]
- Cheng, C.; Feng, X.; Li, X.; Wu, M. Robust analysis of cancer heterogeneity for high-dimensional data. Stat. Med. 2022, 41, 5448–5462. [Google Scholar] [CrossRef] [Scilit]
- Boyd, S.; Parikh, N.; Chu, E.; Peleato, B.; Eckstein, J. Distributed optimization and statistical learning via the alternating direction method of multipliers. Found. Trends® Mach. Learn. 2011, 3, 1–122. [Google Scholar]
- Tibshirani, R. Regression shrinkage and selection via the lasso. J. R. Stat. Soc. Ser. B (Methodol.) 1996, 58, 267–288. [Google Scholar] [CrossRef] [Scilit]
- Hoerl, A.E.; Kennard, R.W. Ridge regression: Biased estimation for nonorthogonal problems. Technometrics 1970, 12, 55–67. [Google Scholar] [CrossRef]
- Zou, H.; Hastie, T. Regularization and variable selection via the elastic net. J. R. Stat. Soc. Ser. B (Stat. Methodol.) 2005, 67, 301–320. [Google Scholar] [CrossRef] [Scilit]
- Fan, J.; Li, R. Variable selection via nonconcave penalized likelihood and its oracle properties. J. Am. Stat. Assoc. 2001, 96, 1348–1360. [Google Scholar] [CrossRef] [Scilit]
- Zhang, C.H. Nearly unbiased variable selection under minimax concave penalty. Ann. Stat. 2010, 38, 894–942. [Google Scholar] [CrossRef] [Scilit]
- Ma, S.; Huang, J. A concave pairwise fusion approach to subgroup analysis. J. Am. Stat. Assoc. 2017, 112, 410–423. [Google Scholar] [CrossRef] [Scilit]
- Wang, W.; Yan, X.; Ren, Y.; Xiao, Z. Bi-Integrative Analysis of Two-Dimensional Heterogeneous Panel Data Model. arXiv 2021, arXiv:econ.EM/2110.10480. Available online: http://xxx.lanl.gov/abs/2110.10480 (accessed on 10 October 2021).
- Hunter, D.R.; Li, R. Variable selection using MM algorithms. Ann. Stat. 2005, 33, 1617. [Google Scholar] [CrossRef] [Scilit]
- Wang, H.; Li, R.; Tsai, C.L. Tuning Parameter Selectors for the Smoothly Clipped Absolute Deviation Method. Biometrika 2007, 94, 553–568. [Google Scholar] [CrossRef] [Scilit]
- Wang, H.; Li, B.; Leng, C. Shrinkage tuning parameter selection with a diverging number of parameters. J. R. Stat. Soc. Ser. B (Stat. Methodol.) 2009, 71, 671–683. [Google Scholar] [CrossRef] [Scilit]
- Ma, S.; Huang, J.; Zhang, Z.; Liu, M. Exploration of heterogeneous treatment effects via concave fusion. Int. J. Biostat. 2019, 16, 20180026. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- He, X.; Shao, Q.M. On parameters of increasing dimensions. J. Multivar. Anal. 2000, 73, 120–135. [Google Scholar] [CrossRef] [Scilit]
- Fang, K.; Chen, Y.; Ma, S.; Zhang, Q. Biclustering analysis of functionals via penalized fusion. J. Multivar. Anal. 2022, 189, 104874. [Google Scholar] [CrossRef] [Scilit] [PubMed]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2023 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).