


Abstract
Interferon-beta is one of the most widely prescribed disease-modifying therapies for multiple sclerosis patients. However, this treatment is only partially effective, and a significant proportion of patients do not respond to this drug. This paper proposes an alternative fuzzy logic system, based on the opinion of a neurology expert, to classify relapsing–remitting multiple sclerosis patients as high, medium, or low responders to interferon-beta. Also, a pipeline prediction model trained with biomarkers associated with interferon-beta responses is proposed, for predicting whether patients are potential candidates to be treated with this drug, in order to avoid ineffective therapies. The classification results showed that the fuzzy system presented 100% efficiency, compared to an unsupervised hierarchical clustering method (52%). So, the performance of the prediction model was evaluated, and 0.8 testing accuracy was achieved. Hence, a pipeline model, including data standardization, data compression, and a learning algorithm, could be a useful tool for getting reliable predictions about responses to interferon-beta.
1. Introduction
Multiple sclerosis (MS) is a chronic inflammatory disease of the central nervous system (CNS) [1]. Although MS can take several different forms, the most common type is relapsing–remitting MS (RRMS), characterized by alternating periods of remission and intensification of symptoms [2]. The etiology of MS can include several factors, such as genetic susceptibility and viral infections [3,4,5], which activate the immune system, generating immune dysregulation, and producing an immune attack against the myelin covering of the CNS [6]. Studies have shown that susceptibility to MS is genetically dependent, but the specific gene factors remain largely unknown. It is known that peripheral self-antigen-specific immune cells are activated during the antigen presentation process, and that they enter the CNS through the disrupted blood-–brain barrier (BBB) [7]. The route of entry depends on the phenotype and activation state of the T cells. T cells play important roles in cellular immunity [8]. T cells are divided into helper T cells (Th) and regulatory T cells (Treg).
The autoimmune etiology of MS has been the target of the therapeutic approach to patients. Treatment of MS can be divided into treatment of MS symptoms, treatment of MS relapse, and treatment modifying disease progression. The main target of MS treatment is delaying the disease progression [9]. Interferon-beta (IFN-) is one of the most widely prescribed disease-modifying therapies for RRMS patients. IFN- has multiple pathways of action on the immune system. IFN- inhibits the activated proliferation of T cells, and prevents the migration of activated immune cells through the BBB. Also, this drug inhibits the production of pro-inflammatory cytokines (e.g., IL-2, IL-12, IFN-), induces an increase in anti-inflammatory cytokines (e.g., IL-4, IL-5, IL-10 and TGF-), and promotes re-myelination in CNS [10,11]. IFN- can also prevent the differentiation of inflammatory Th1/Th17 cells, and it can change the phenotype of Th cells from inflammatory Th1 to anti-inflammatory Th2 cells. Studies have shown that IFN- can significantly improve the clinical symptoms of patients, reduce the annual recurrence rate, and delay the progress of the disease [12]. However, IFN- is only partially efficient, and a significant proportion of MS patients do not respond to this treatment, with the proportion of non-responders ranging from 20 to 50% [13]. Hence, in this paper, a pipeline model based on potential biomarkers associated with the response to IFN- is proposed, to predict whether MS patients are potential candidates to be treated with this drug. Studies have researched the effect of gene polymorphisms on therapeutic responses to IFN-, which can affect the efficacy of this therapy. Bustamante et al. [14] analyzed the relationship between single-nucleotide polymorphisms (SNPs) disposed in type I IFN-induced genes, genes becoming the toll-like receptor (TLR) pathway, and genes encoding neurotransmitter receptors, and the response to IFN- treatment in MS patients. Martinez et al. [15] evaluated the effect of polymorphisms in some genes (CD46, CD58, FHIT, IRF5, GAPVD1, GPC5, GRBRB3, MxA, PELI3, and ZNF697) on responses to IFN- treatment among RRMS patients. From seven selected SNPs, PELI3 and GABRR3 polymorphisms were exposed, to be related to IFN- responses.
Genome-wide research is generated in large numbers of data, and there is a need for soft computing methods (SCMs)—such as artificial neural networks, fuzzy systems, evolutionary algorithms, or metaheuristic and swarm intelligence algorithms—that can deal with this amount of data [16]. Studies of fuzzy systems have only focused on MS diagnosis. Ayangbekun & Jimoh [17] designed a fuzzy inference system for diagnosing five brain diseases: Alzheimer’s, Creutzfeldt–Jakob, Huntington’s, MS, and Parkinson’s. Hosseini et al. [18] developed a clinical decision support system (CDSS), to help specialists diagnose MS with a relapsing–remitting phenotype. Matinfar et al. [19] proposed an expert system for MS diagnosis, based on clinical symptoms and demographic characteristics. However, it is necessary to design new expert systems that can classify the possible responses to treatments in MS patients. Other studies have applied machine learning (ML) techniques to diagnose early MS. Goyal et al. [20] trained a random forest (RF) model with the serum level of eight cytokines (IL-1, IL-2, IL-4, IL-8, IL-10, IL-13, IFN-, and TNF-) in MS patients, to detect predictors for disease. Chen et al. [21] implemented a support vector machine (SVM) model, using gene expression profiles to identify potential biomarkers for MS diagnosis. CXCR4, ITGAM, ACTB, RHOA, RPS27A, UBA52, and RPL8 genes were detected. Among the studies that suggest genetics can predict the pharmacological response to a treatment, Fagone et al. [22] trained an uncorrelated reduced centroid (UCRC) algorithm to identify a subset of genes that could predict the responses to natalizumab in RRMS patients. A specific gene expression profile of CD4+ T cells could characterize the responsiveness.
Although the studies presented above have shown the efficiency of IFN- at improving the clinical symptoms of MS patients, a proportion of patients did not respond to this treatment. Genome-wide analytical studies have been conducted, in order to identify genetic factors associated with the responses to IFN- treatment. Gurevich et al. [23] identified a subgroup of secondary progressive MS (SPMS) patients presenting a gene expression signature similar to that of RRMS patients who are clinical responders to IFN- treatment. SPMS patients were classified using unsupervised hierarchical clustering, according to IFN-inducible gene expression profiling identified in RRMS clinical responders to treatment. Although, the hierarchical clustering method is easy to implement, it rarely provides the best solution, due to lots of arbitrary decisions. Clarelli et al. [24] detected genetic factors that affect the long-term response to IFN-. The found pathways associated with inflammatory processes and presynaptic membrane, i.e., the genes related to the glutamatergic system (GRM3 and GRIK2), play a potential role in the response to IFN-. Jin et al. [25] implemented a feature selection method based on differentially correlated edges (DCE), to identify the most relevant genes associated with the response to IFN- treatment in RRMS patients. Of the 23 identified genes, 7 had a confidence score > 2: CXCL9, IL2RA, CXCR3, AKT1, CSF2, IL2RB, and GCA. Because the analyzed data were unlabeled, the responder category was restricted to patients whose first relapse time was more than five years (60 months), resulting in nine responders and nine non-responders. So, seven patients were excluded from the analysis. Hence, we attempt to address some of the issues above in this research. The main contributions of this paper are as follows:
- An alternative fuzzy system based on expert knowledge, with linguistic rules to classify RRMS patients as high, medium, or low responders to IFN- treatment.
- A pipeline prediction model, including a data preprocessing technique, a transformation technique for data compression, and a learning algorithm for making predictions on new data. The prediction model is trained with biomarkers associated with the IFN- response for predicting whether MS patients are potential candidates to be treated with this drug, in order to avoid ineffective therapies.
2. Materials and Methods
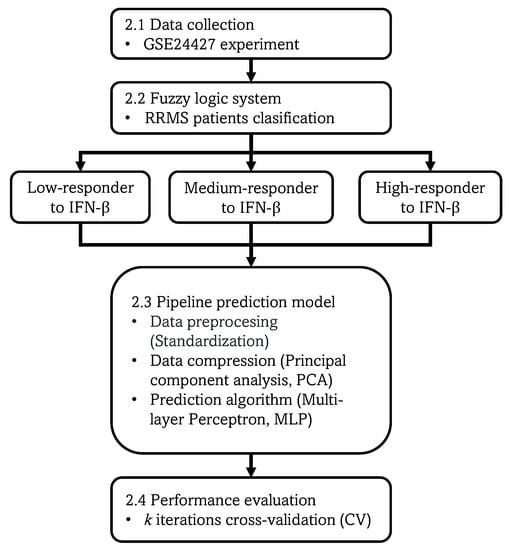
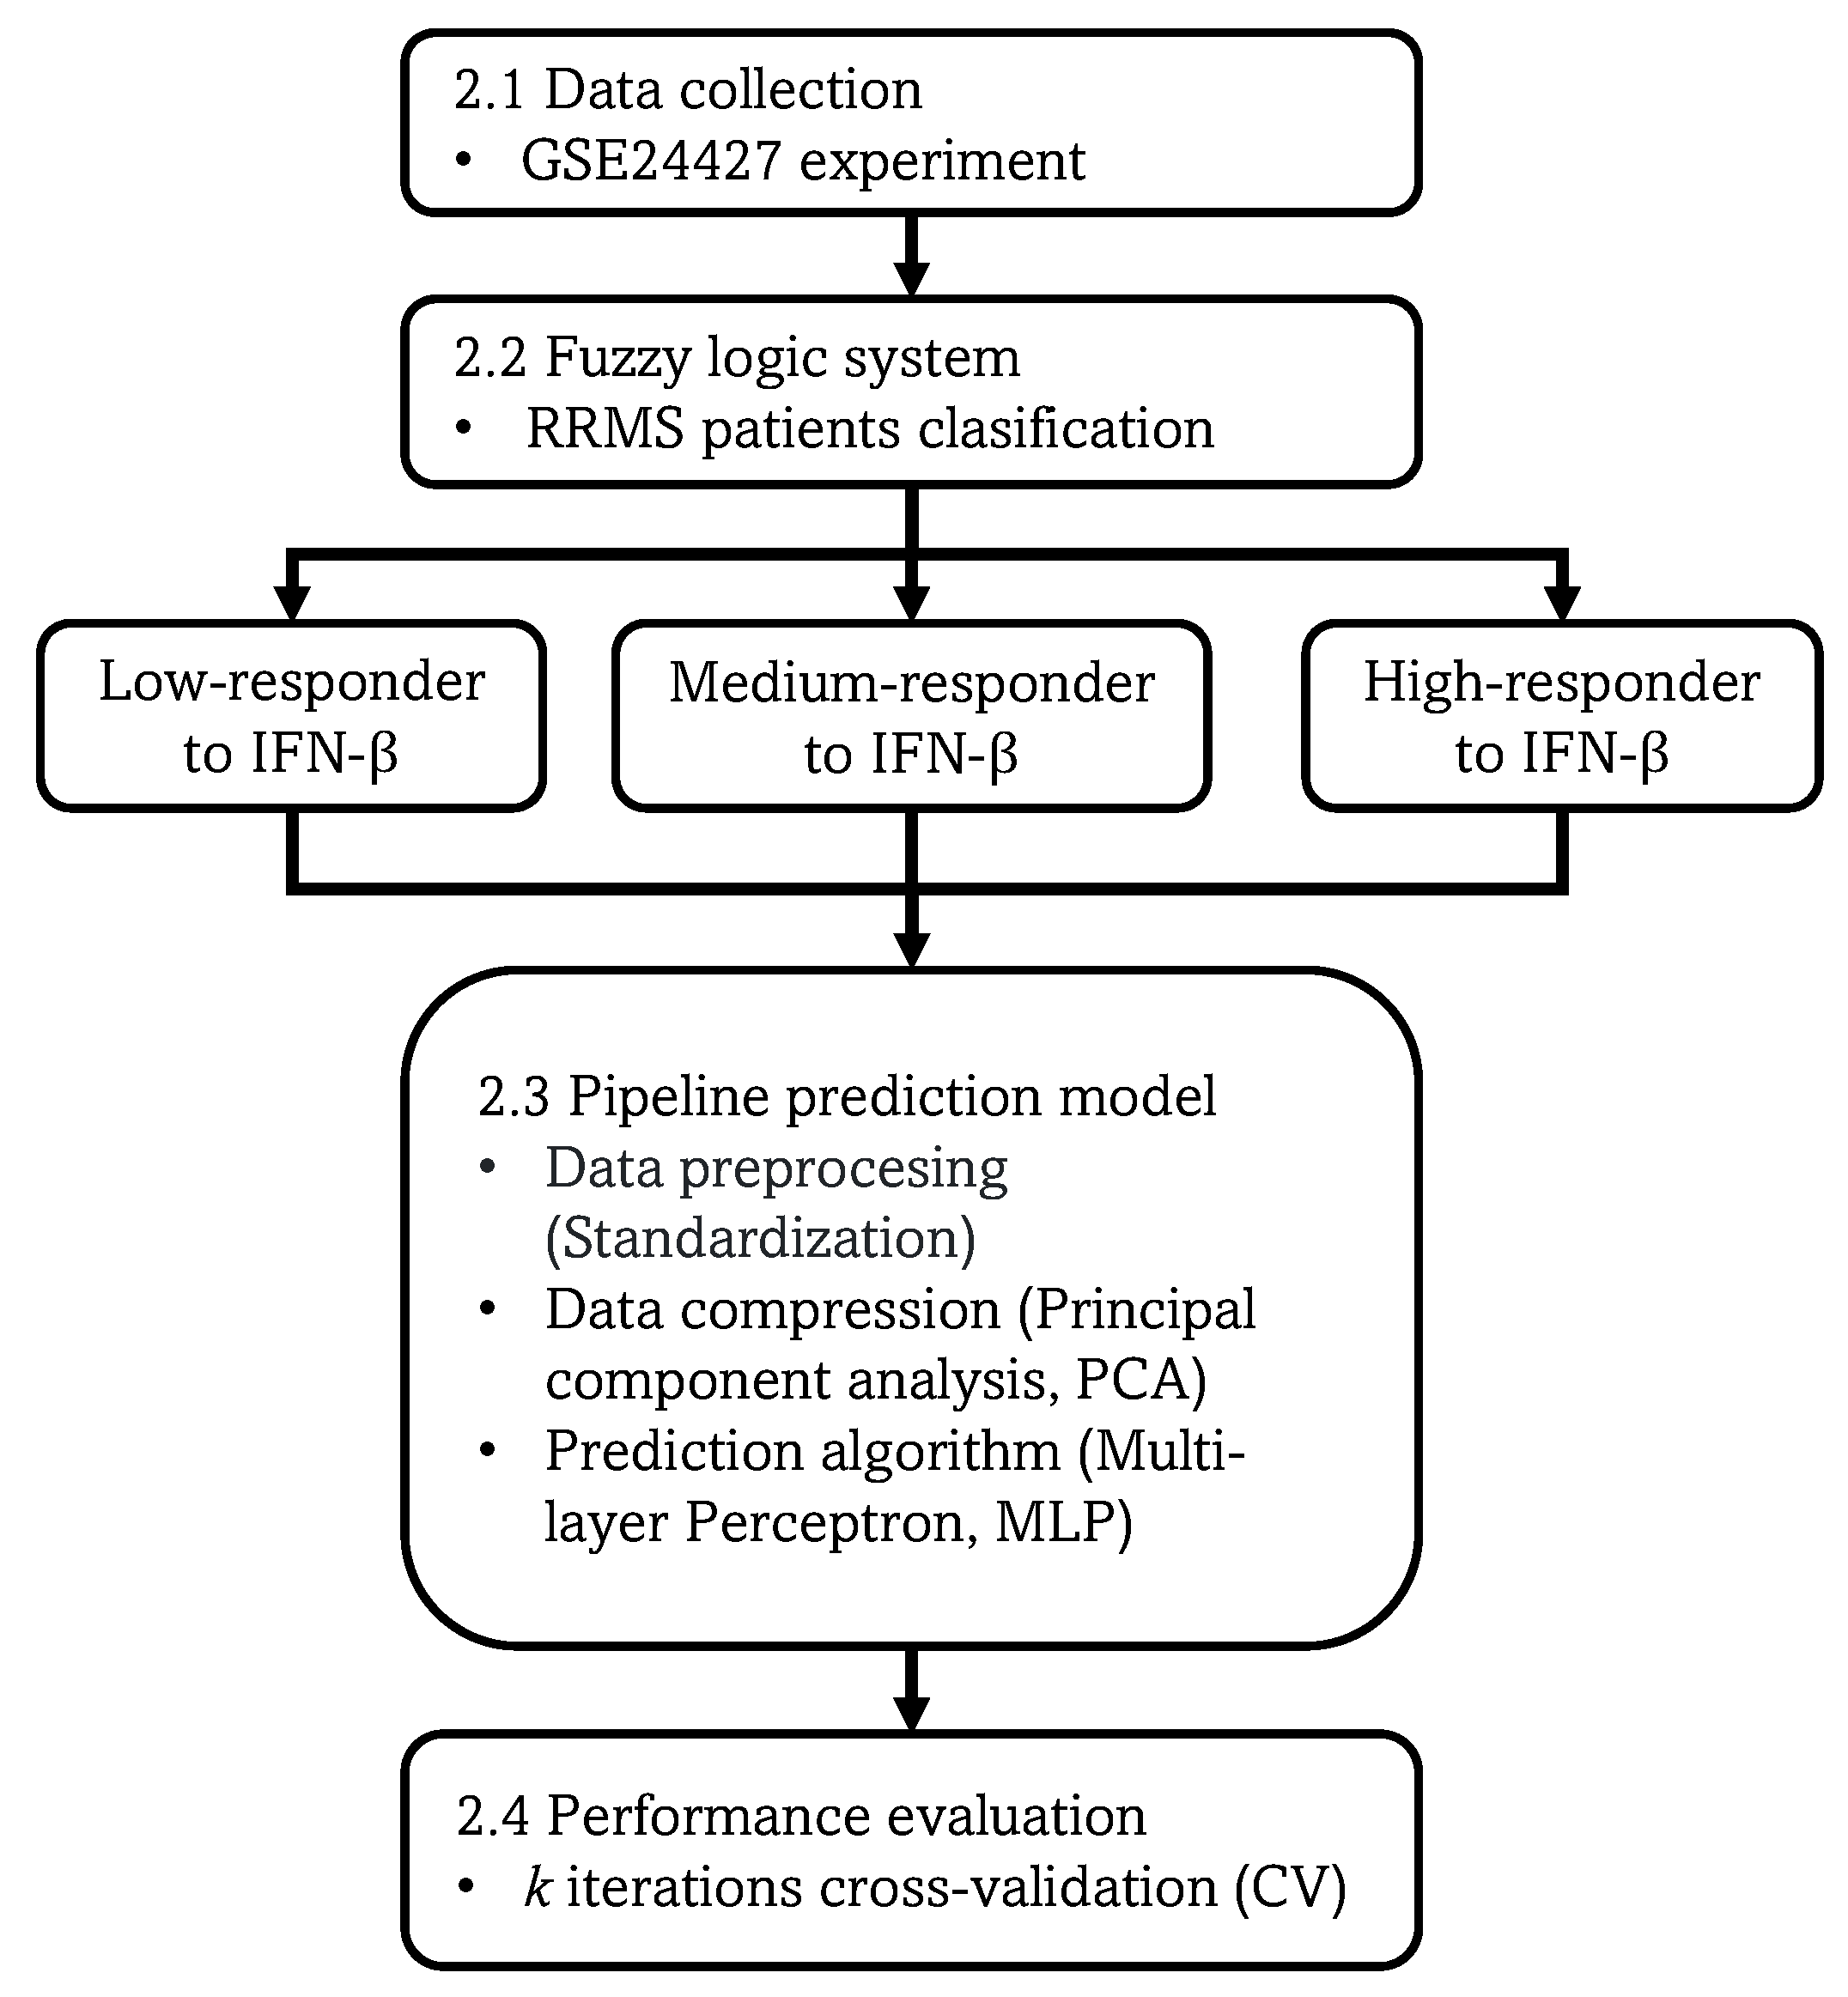
The strategy followed in this research is described in the flowchart of Figure 1, which divides the proposal into four stages.
Figure 1.
Proposed methodology. The gene data, demographic, and clinical characteristics are collected. Then, the RRMS patients are classified by the fuzzy logic system. A pipeline prediction model is implemented, including data standardization, PCA for data compression, and an MLP algorithm for making predictions. Finally, the k-iterations CV is implemented, for evaluating the model prediction performance.
2.1. Data Collection
The dataset was collected from the GSE24427 expression profiling by array experiment, available in the public repository of genomic data GEO [26]. Through the GPL96 [HG-U133A] platform (Affymetrix Human Genome U133A Array), the genome-wide expression profiles of peripheral blood mononuclear cells from 25 RRMS patients were obtained. Patients were treated with subcutaneous IFN-beta-1b (Betaferon, Bayer Healthcare) at the standard dose (250 µg every other day). Patient blood samples were drawn before first-dose, second-dose, 1st-month, 12th-month, and 24th-month IFN- injection. The expression summary values were analyzed by GEO2R, an interactive web tool that allows viewing of a specific gene expression through the profile graph tab. On the one hand, the GPL96 platform enabled us to see demographic and clinical characteristics of RRMS patients, which were used as input variables for the proposed fuzzy system, and these are presented in Table 1.
Table 1.
Demographic and clinical characteristics.
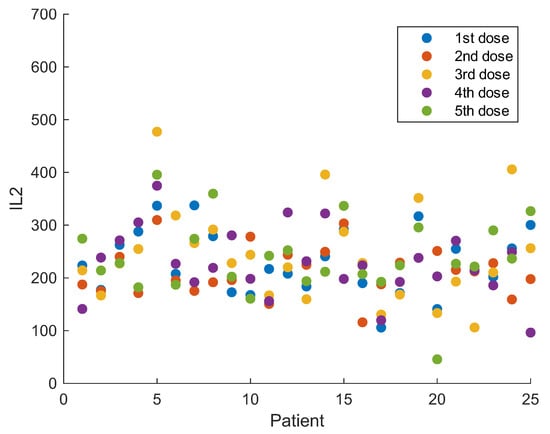
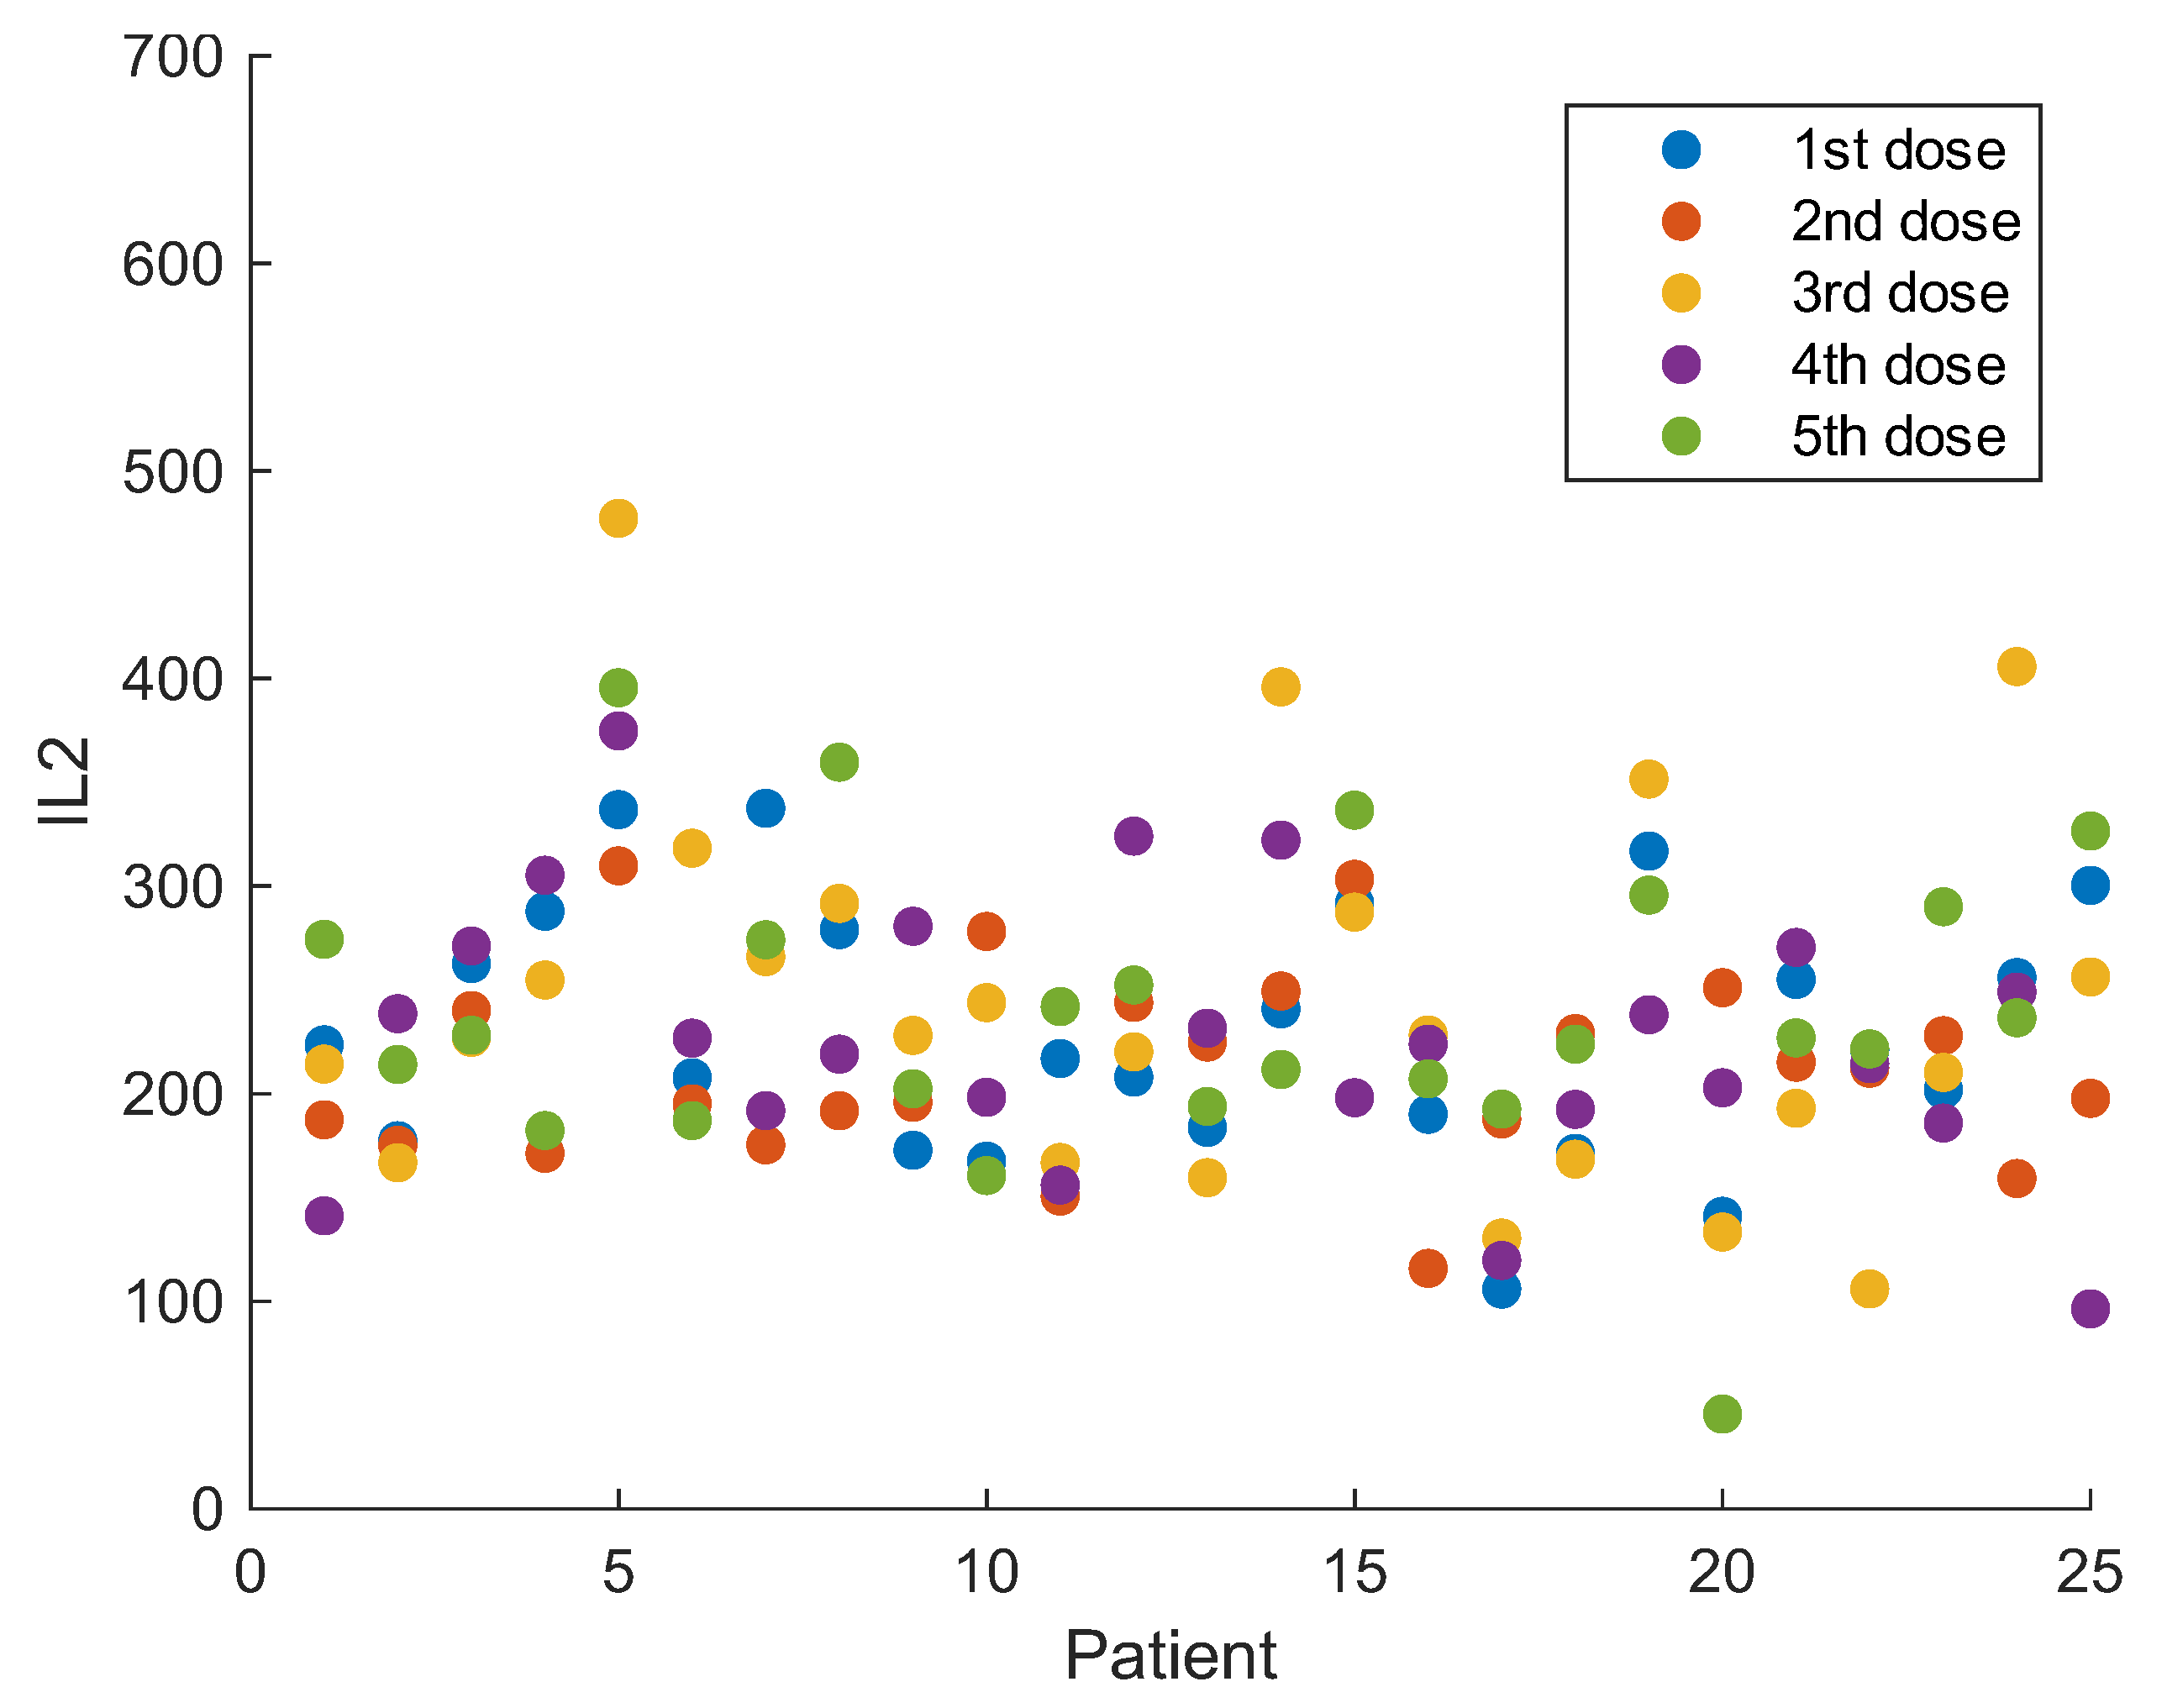
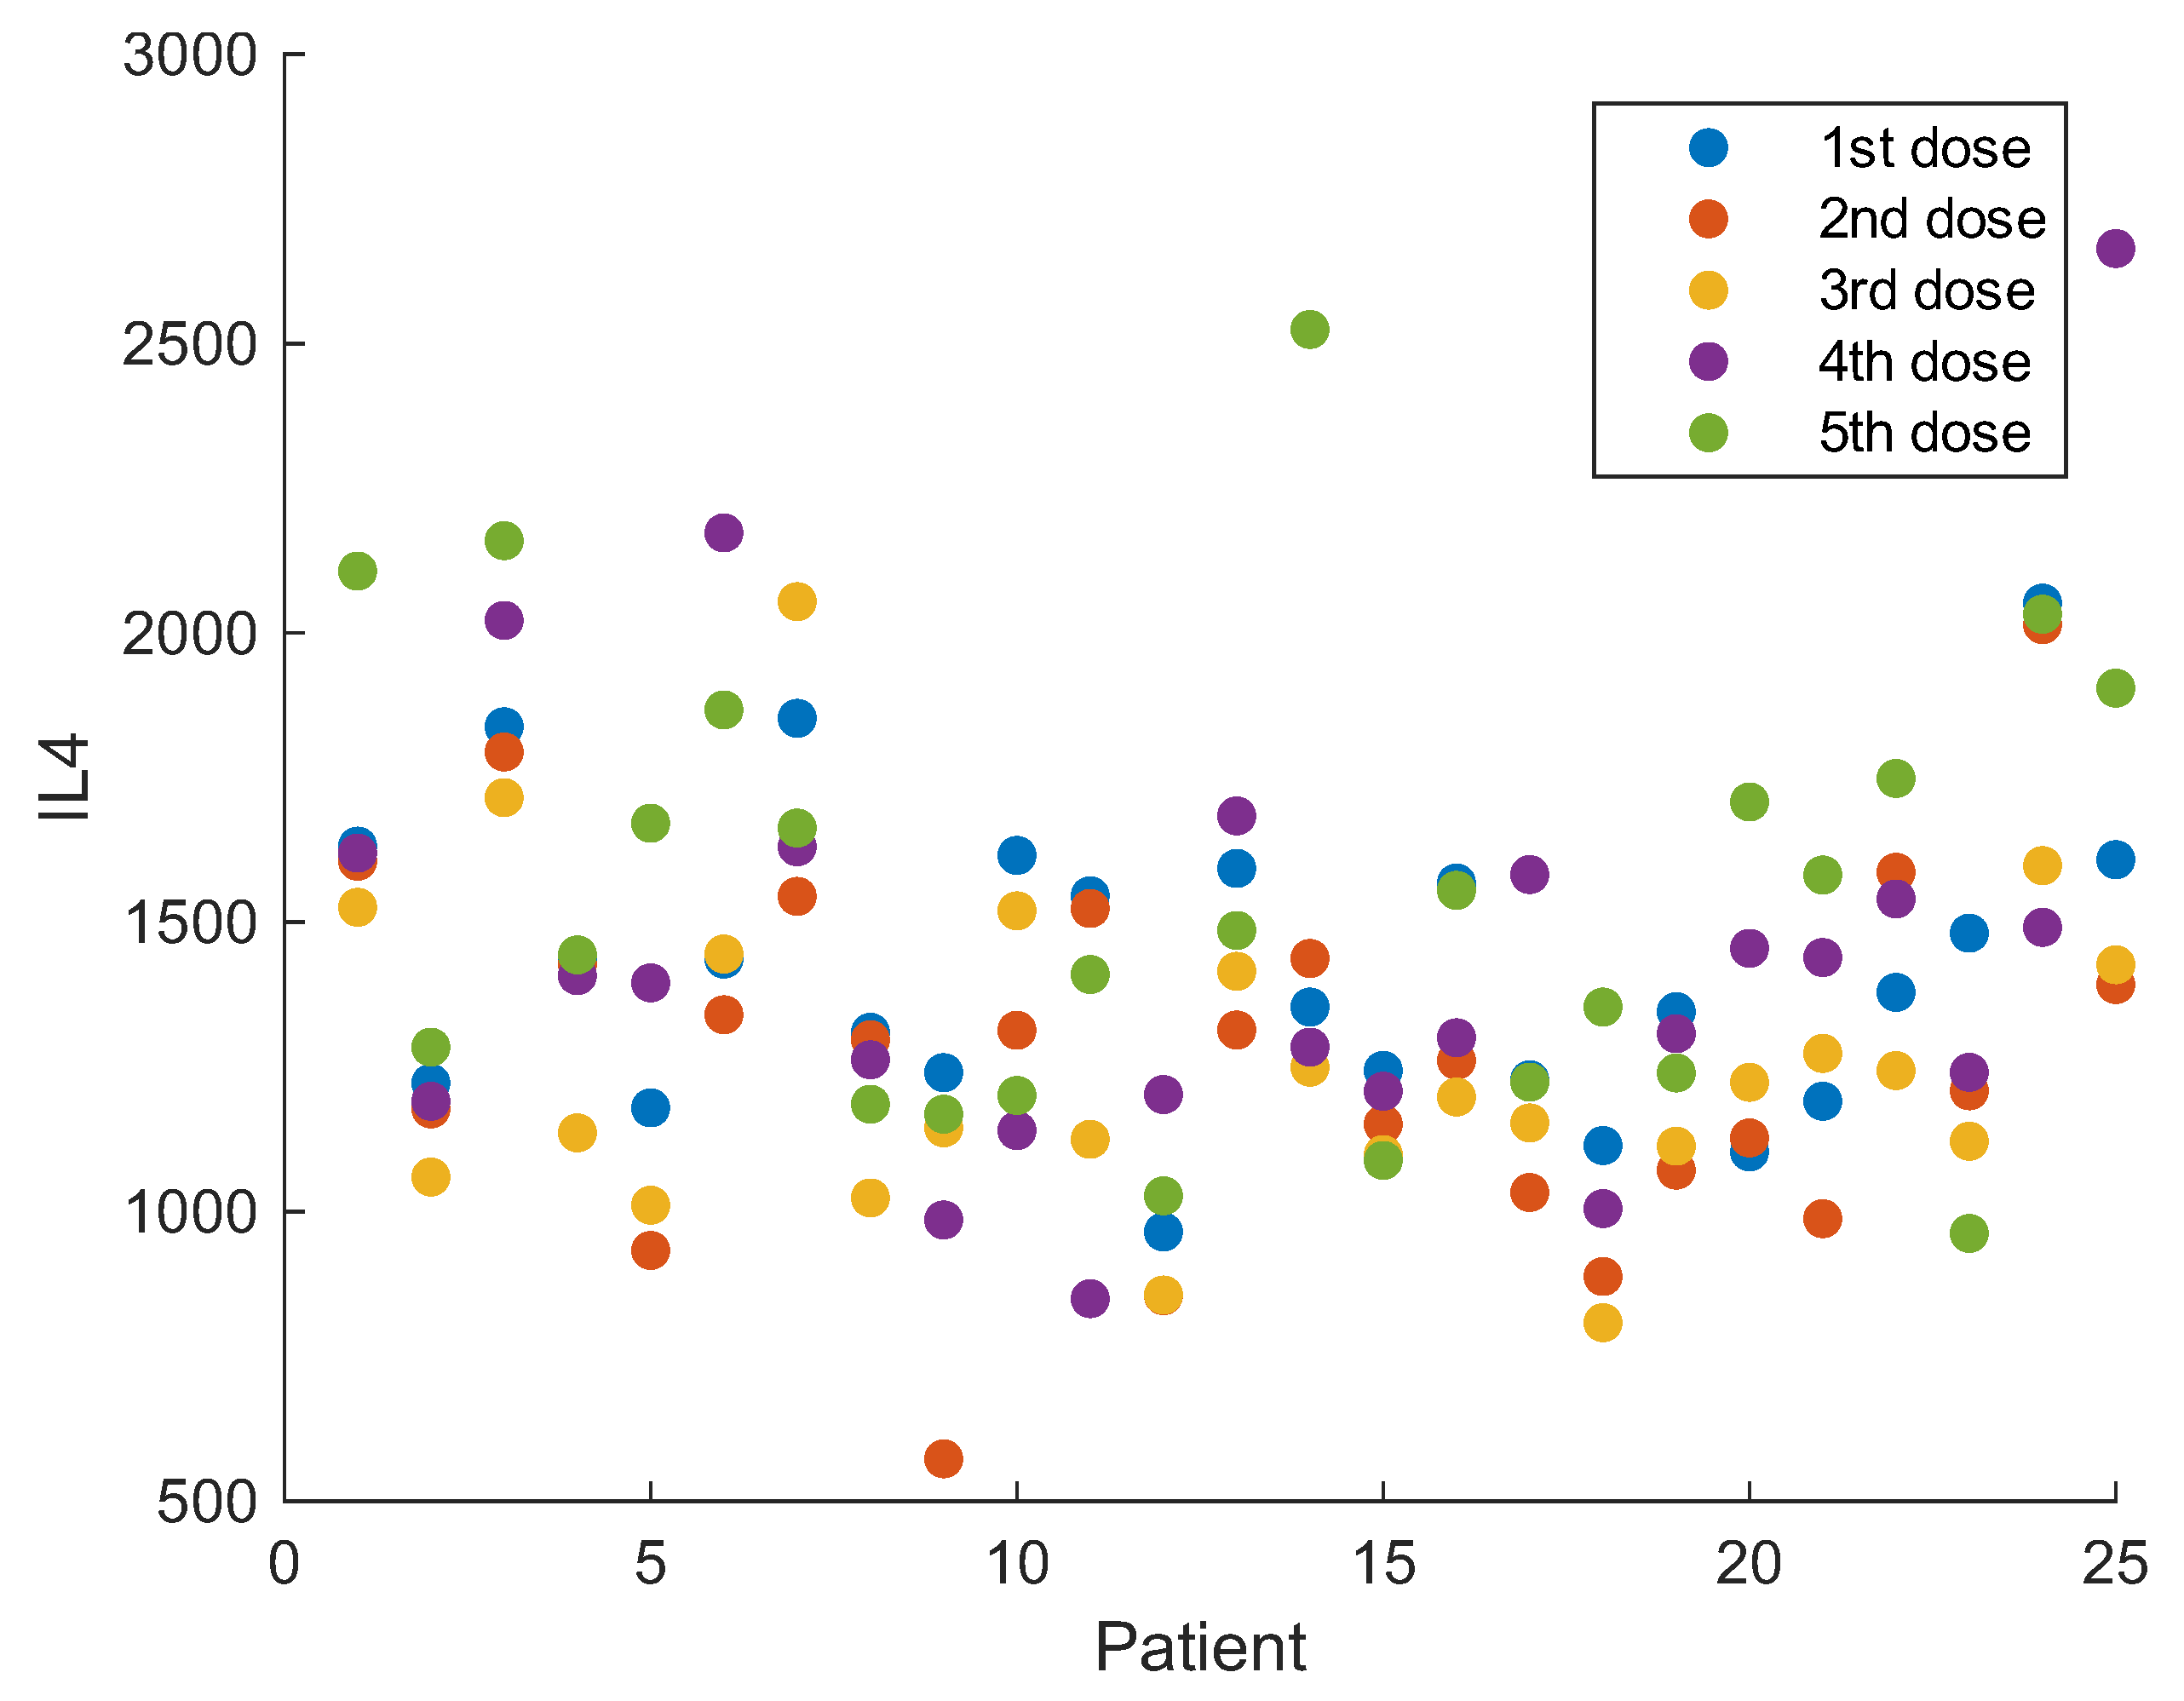
On the other hand, through the GPL96 platform, the expression values of 15 biomarkers associated with the response to IFN-—IL-2, IL-12, IFN-, TNF-, IL-4, IL-10, TGF-, CD46, CD58, FHIT, IRF5, GAPVD1, GPC5, GRM3, and GRIK2—were collected and integrated into an Excel spreadsheet, for training the proposed pipeline prediction model. For example, the IL-2 and IL-4 cytokines expression values are displayed in Figure 2 and Figure 3. The database is the same as the one used by Jin et al. [25]. However, the biomarkers are a little different.
Figure 2.
IL-2 cytokine. The expression values of 25 RRMS patients corresponding to five doses: before first-dose, second-dose, 1st-month, 12th-month, and 24th-month IFN- injection.
Figure 3.
IL-4 cytokine. The expression values seem more scattered than IL-2 cytokine.
2.2. Fuzzy Logic System
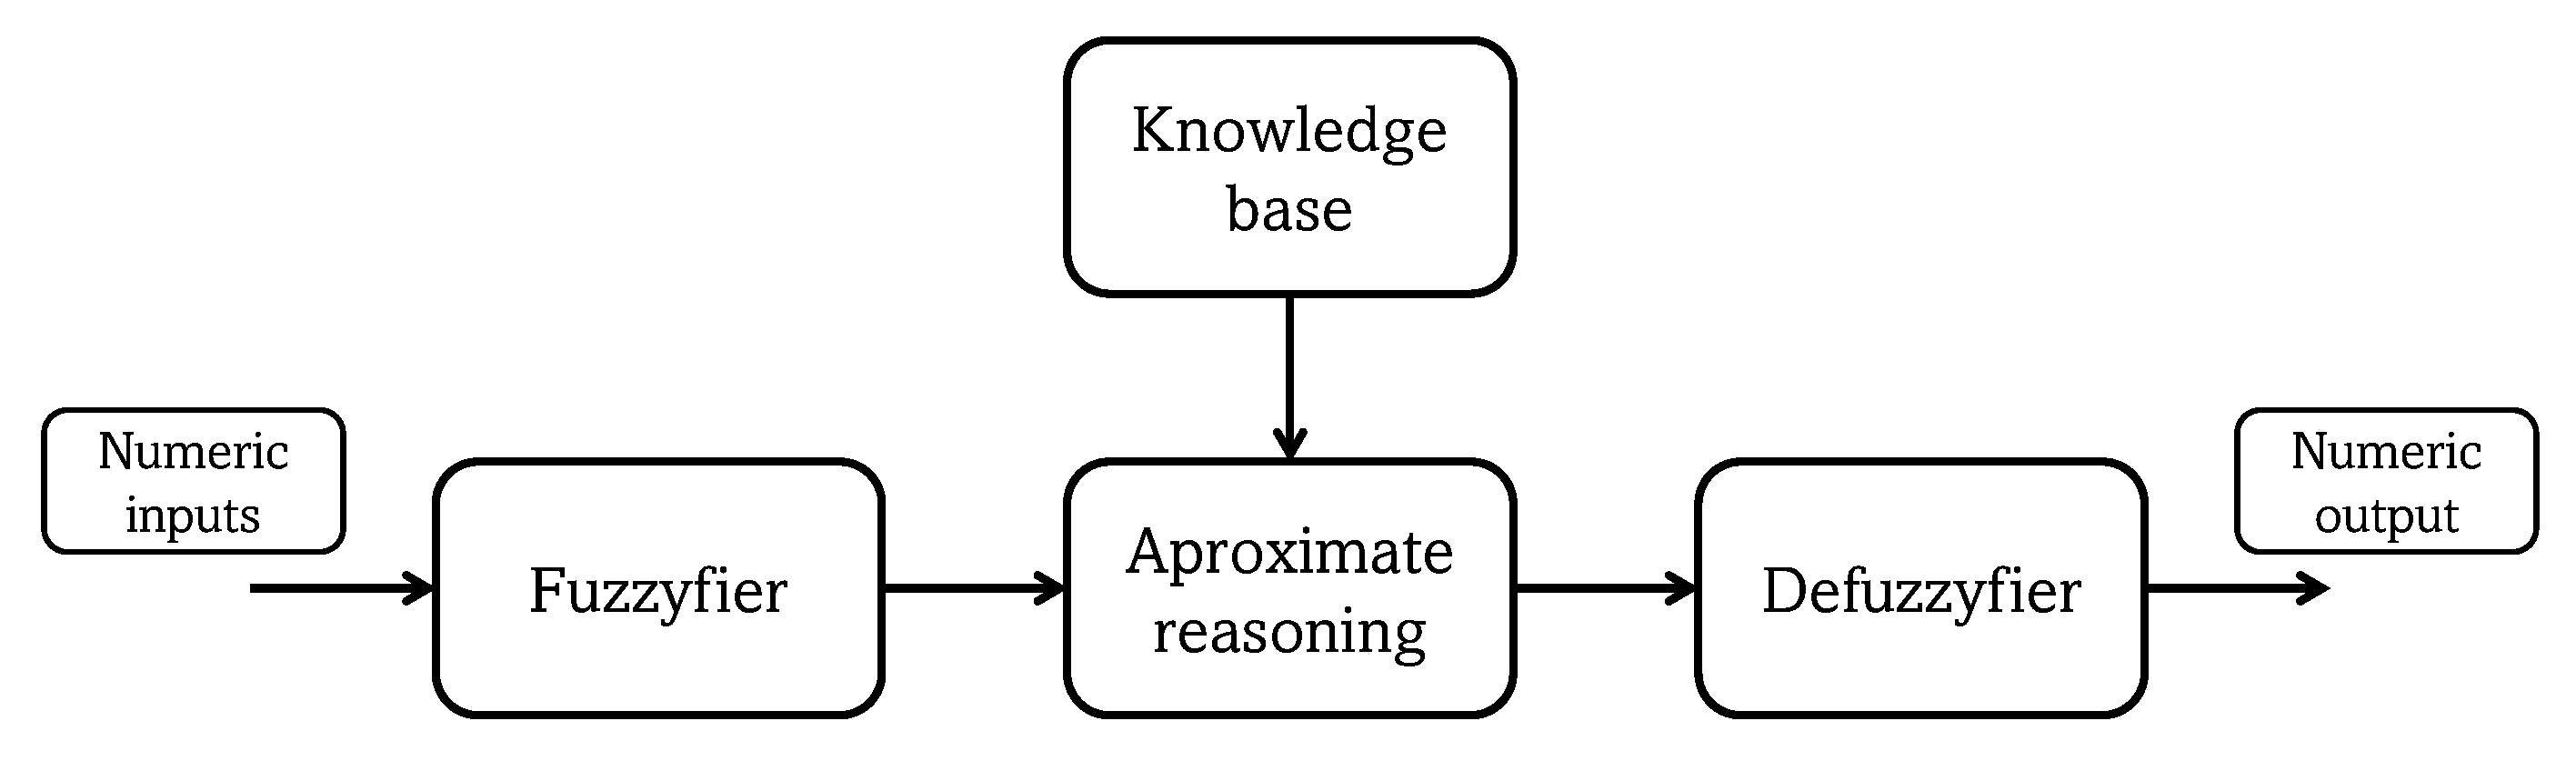
Fuzzy systems are structures based on fuzzy sets and fuzzy logic theories for processing inaccurate information [27]. Their main property includes symbolic knowledge representation in a form of fuzzy conditional (if-then) rules. The typical structure of a fuzzy system is described in Figure 4.
Figure 4.
Fuzzy system structure. The fuzzyfier transforms the values of input variables into an N-dimensional fuzzy set A (linguistic values of the output variable) defined on the universe , by means of approximate reasoning (inference engine) using expert knowledge, which is represented as a set of fuzzy conditional rules (knowledge base). The result of the approximate reasoning is a fuzzy set . The defuzzyfier computes a representative numerical output from the result of fuzzy set defined on the universe .
The fuzzyfier can be defined as the membership function of the fuzzy set A. Demographic and clinical characteristics of RRMS patients are used as input variables for the fuzzyfier. The numerical output is computed using the center of gravity (COG) method [28], as in Equation (1):
where represents the membership function of fuzzy set . The proposed fuzzy system is designed through the Fuzzy Logic Designer App of MATLAB R2023a software. The structure of the proposed fuzzy system is based on the Mamdani-–Assilan fuzzy system (MAFS) [29], which includes a set of conditional fuzzy rules, in the form of Equation (2), that can be determined by a human expert:
where I is the number of rules, represents the input linguistic variables, Y is the output linguistic variable, and and are the linguistic values, defined by fuzzy sets , and B on universes and , respectively. In this paper, the input linguistic variables describing the demographic characteristics—including gender and age—and the clinical characteristics—including expanded disability status scale (EDSS) 1st month and 24th month—are defined: “mean gender”; = “mean age”; = “mean EDSS 1st month”; = “mean EDSS 24th month”. The sets of possible linguistic values are collections of different labels describing the gender, age, EDSS 1st month, and EDSS 24th month: = {“female”, “male”}; = {“pediatric”, “adult”, “elderly”}; = {“low”, “medium”, “high”}; = {“low”, “medium”, “high”}, and response to IFN-: = {“low”, “medium”, “high”}. To each one of the labels, the fuzzy sets are assigned, defined on the universe , which represents the range of possible values. The whole description of the defined linguistic variables is presented in Table 2.
Table 2.
Linguistic variables description.
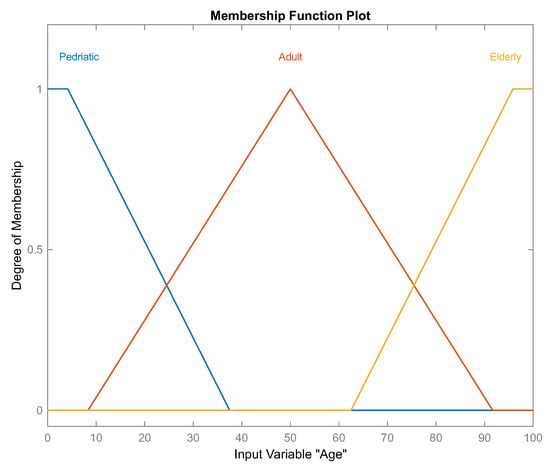
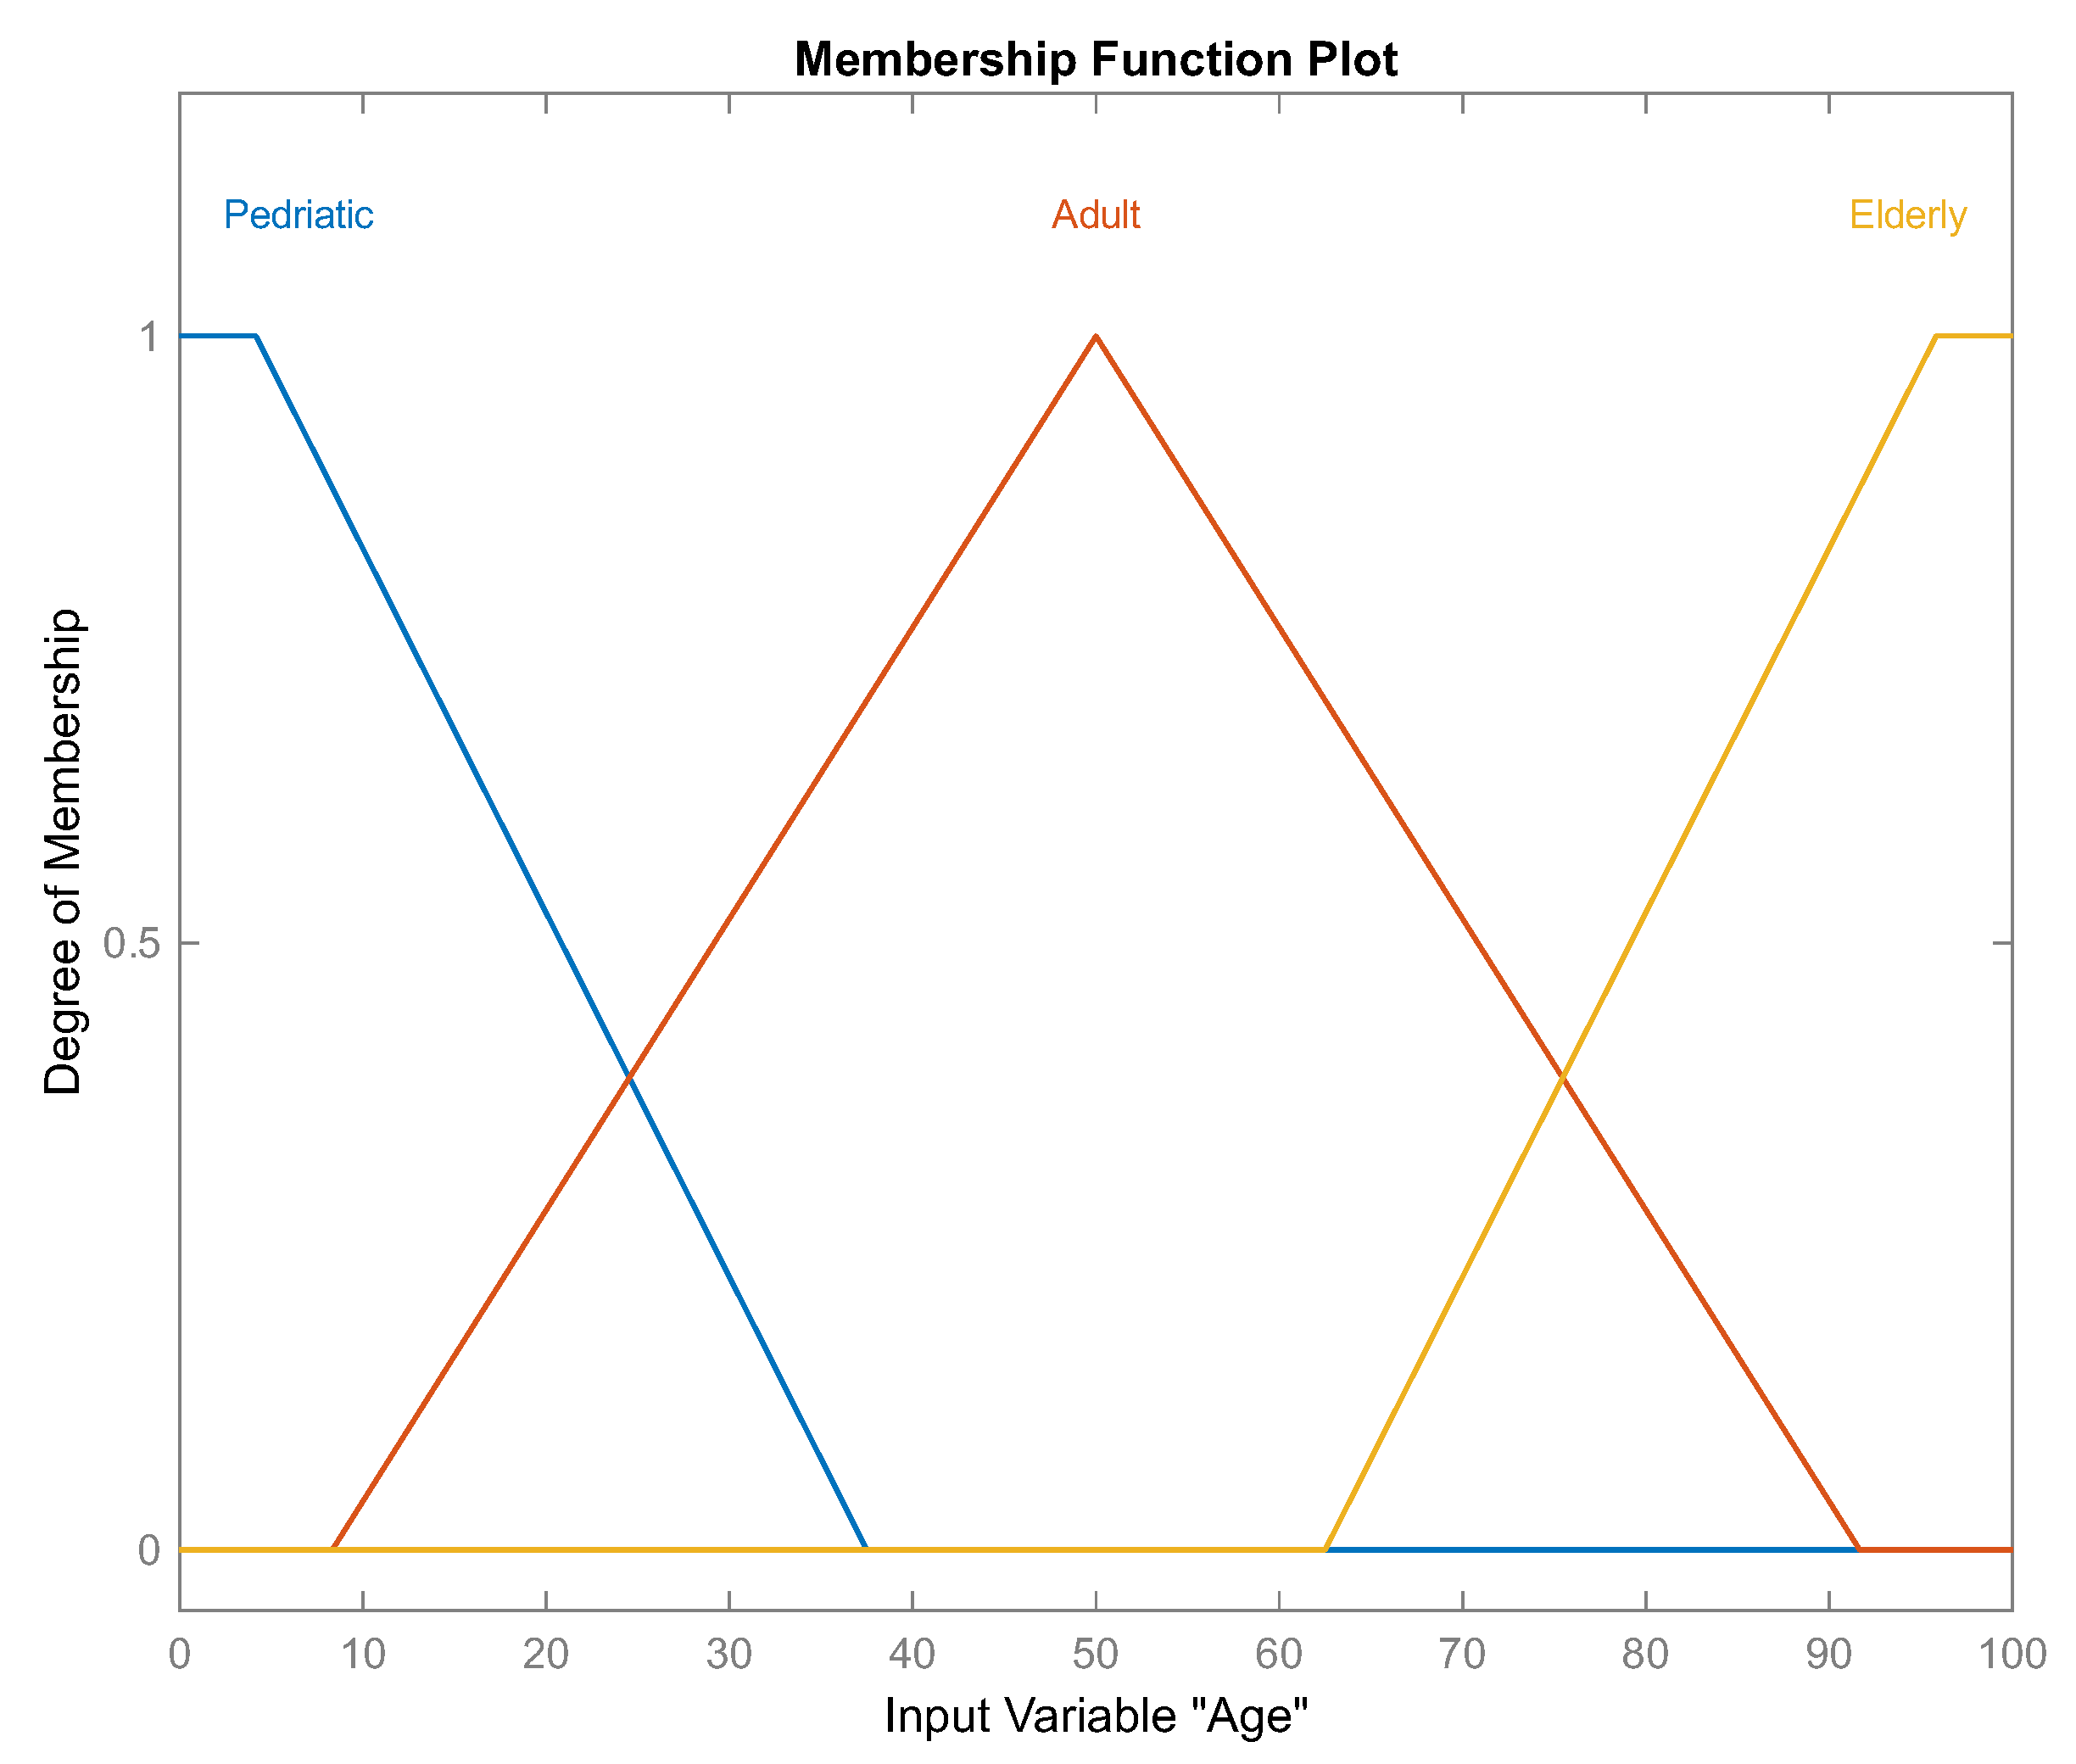
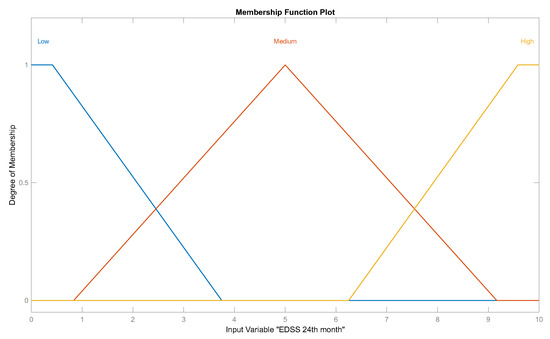
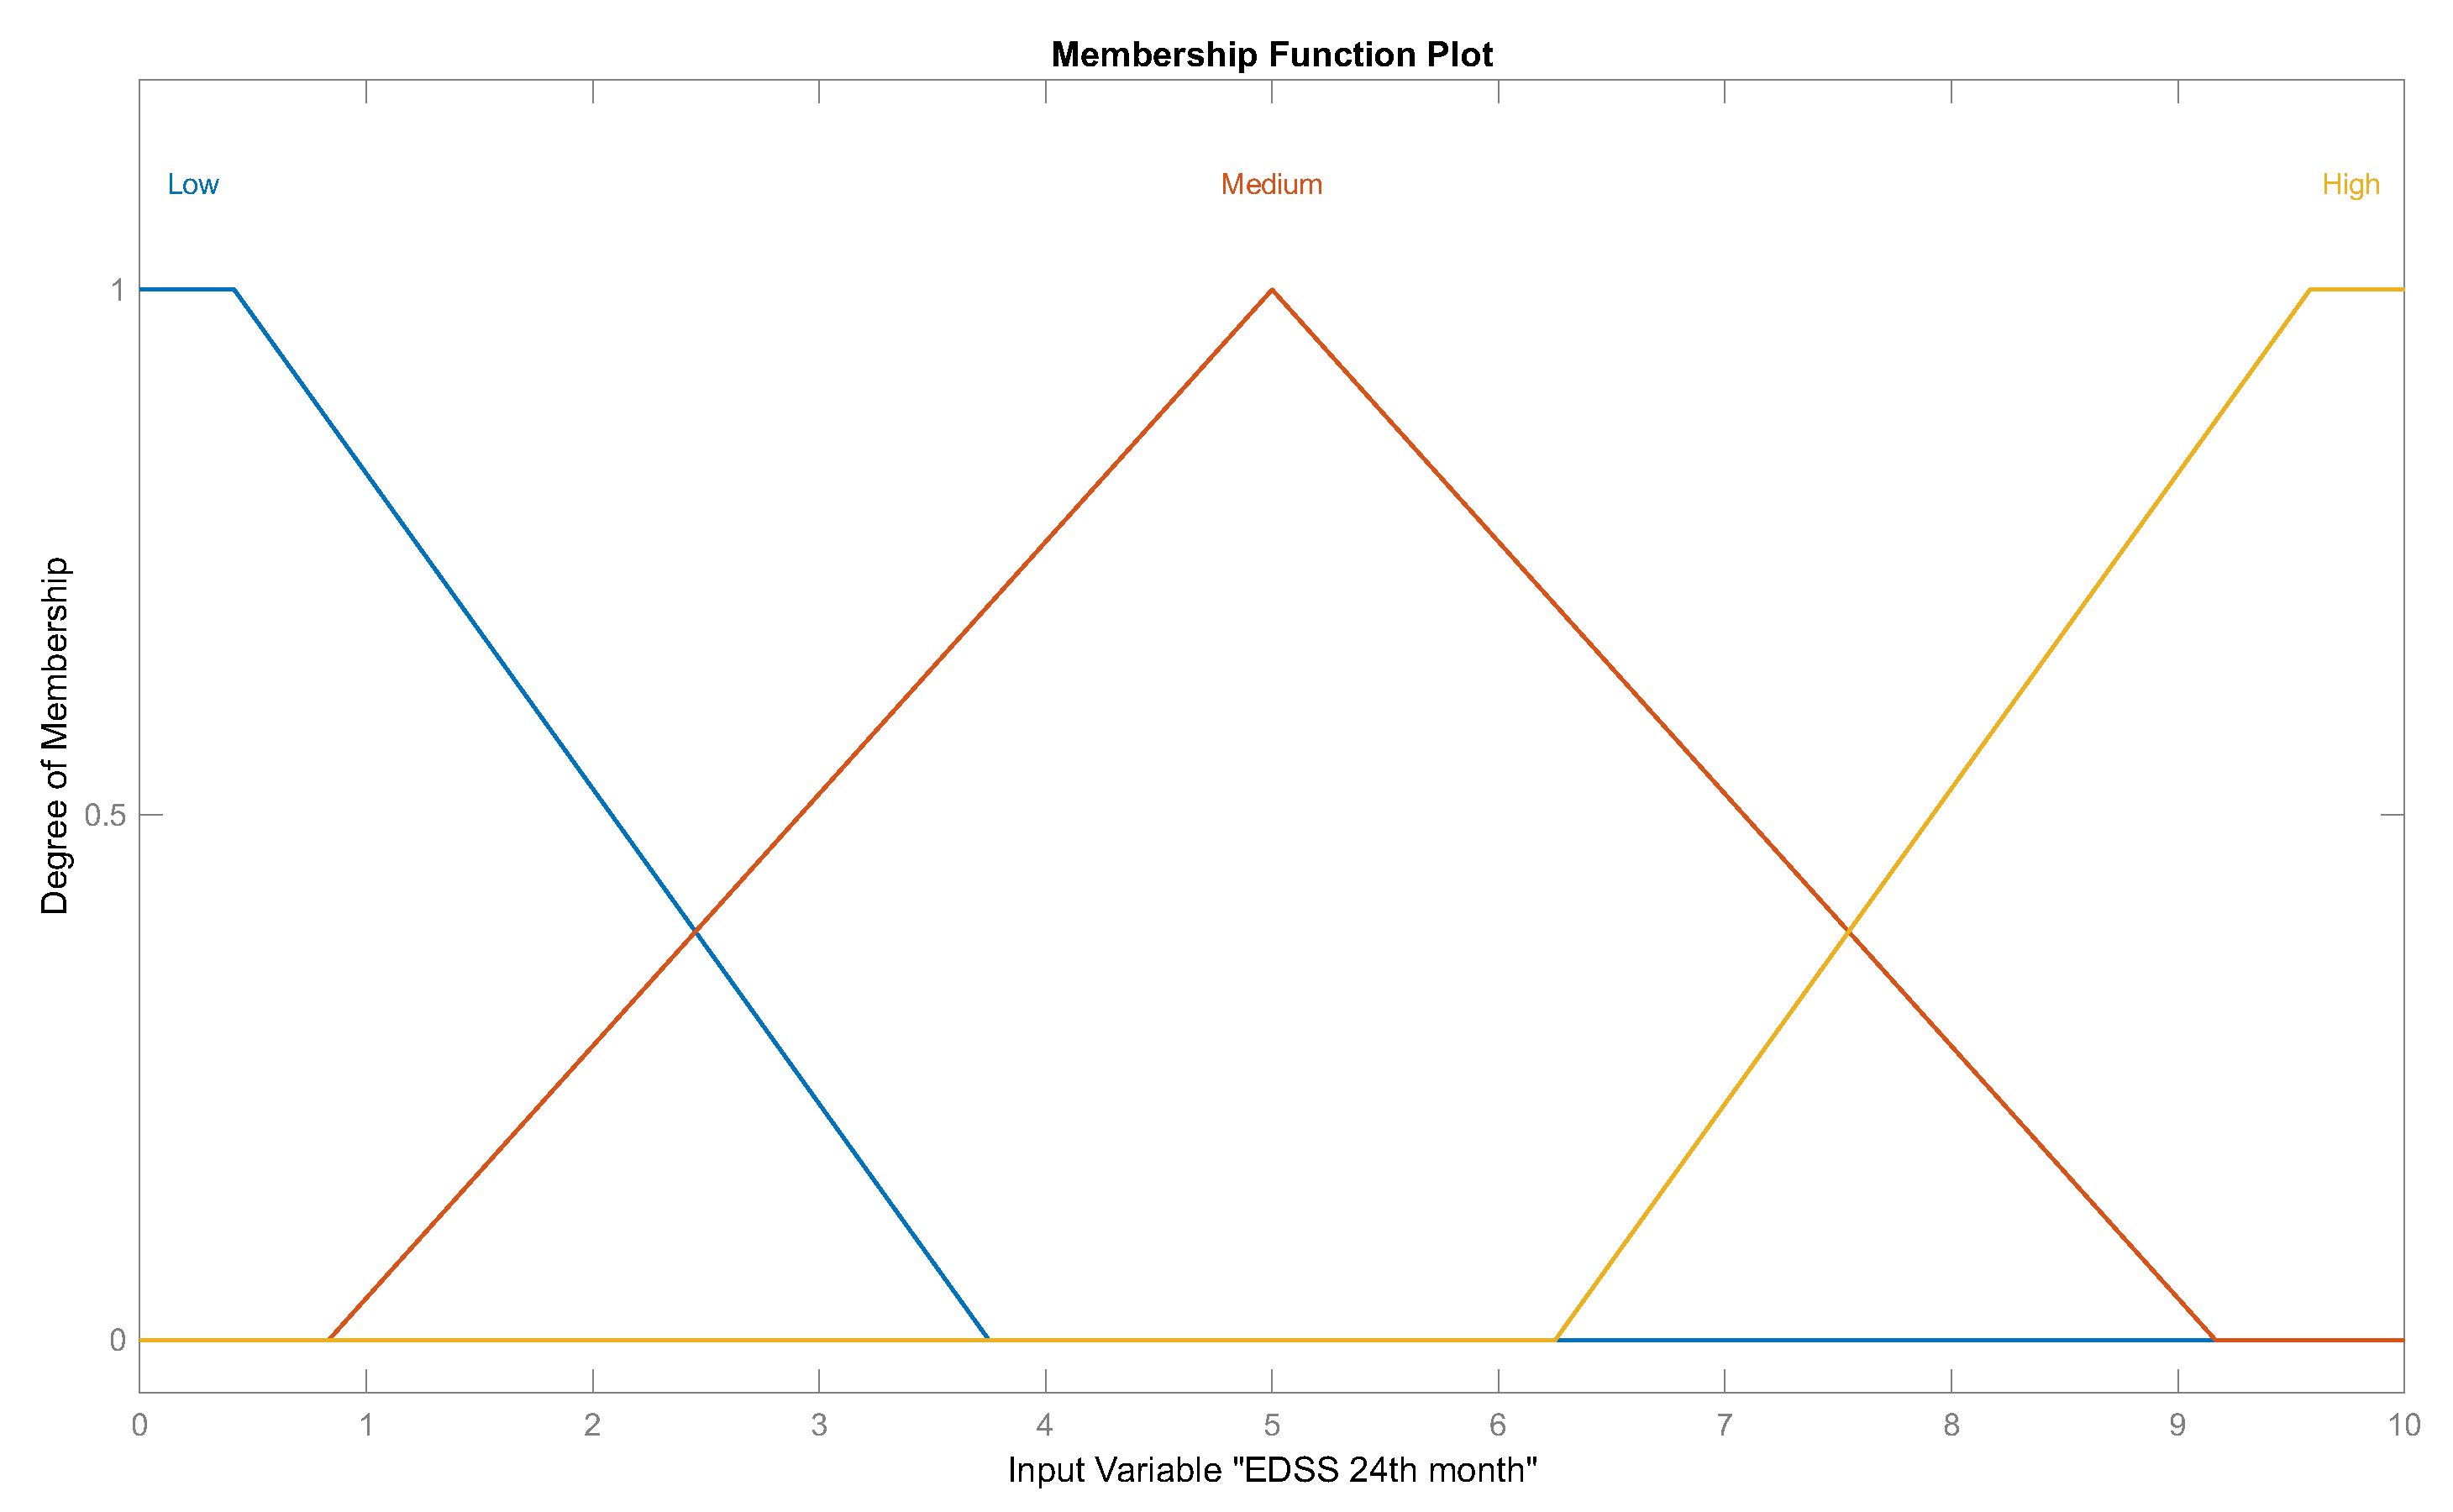
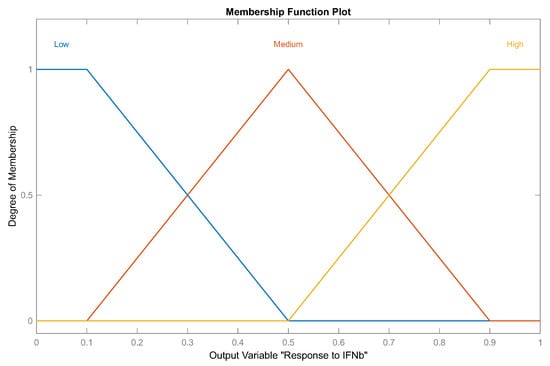
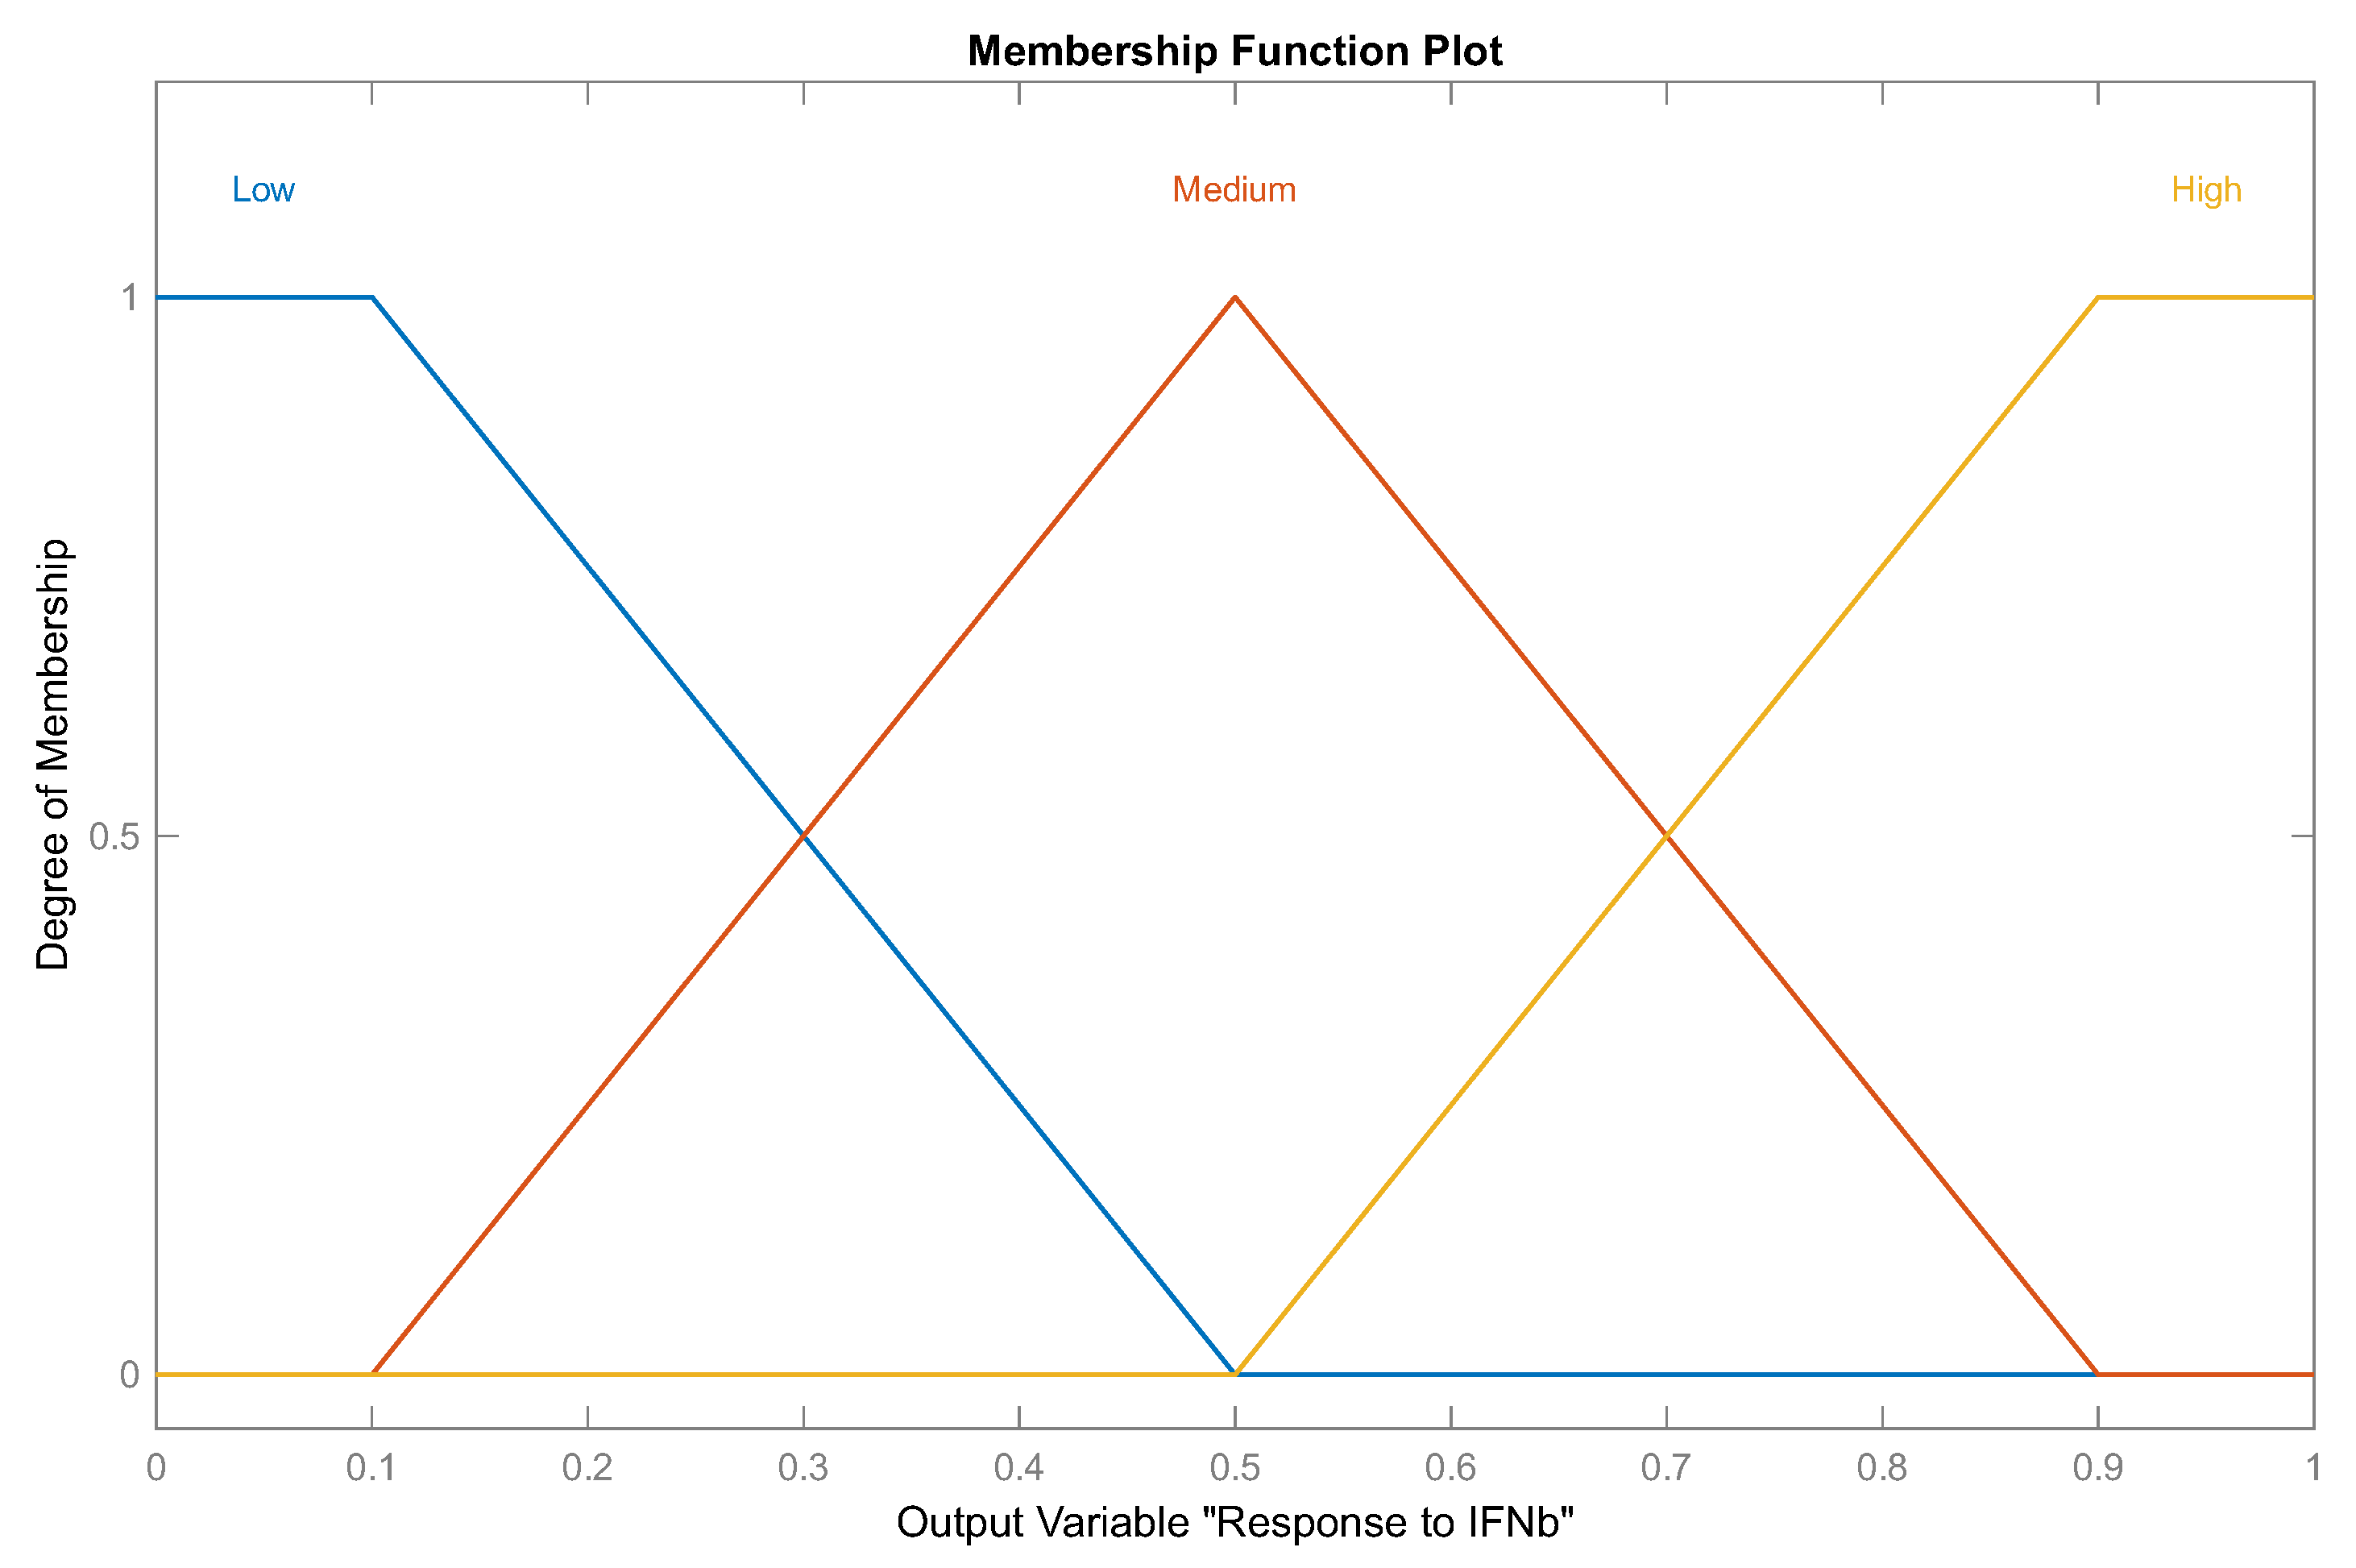
For example, the graphics of the membership functions , , and of the fuzzy sets , , and are displayed in Figure 5, Figure 6 and Figure 7, respectively.
Figure 5.
Set of linguistic values, which are three labels describing the “age” input variable, corresponding to fuzzy set .
Figure 6.
Set of linguistic values, which are three labels describing the “EDSS 24th month” input variable, corresponding to fuzzy set .
Figure 7.
Set of linguistic values, which are three labels describing the “Response to IFN-” output variable, corresponding to fuzzy set .
The fuzzy conditional rules (knowledge base) are meant to decide the influence of the input variables on responses to IFN- treatment. Table 3 and Table 4 display the 36 defined rules, according to the opinion of a neurology expert:
Table 3.
Fuzzy rules definition (first part).
Table 4.
Fuzzy rules definition (second part).
2.3. Pipeline Prediction Model
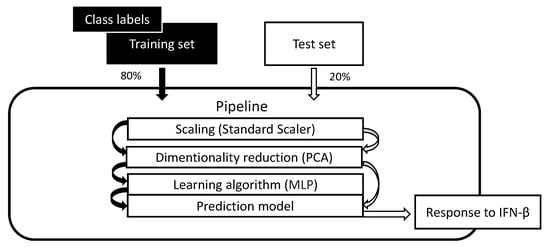
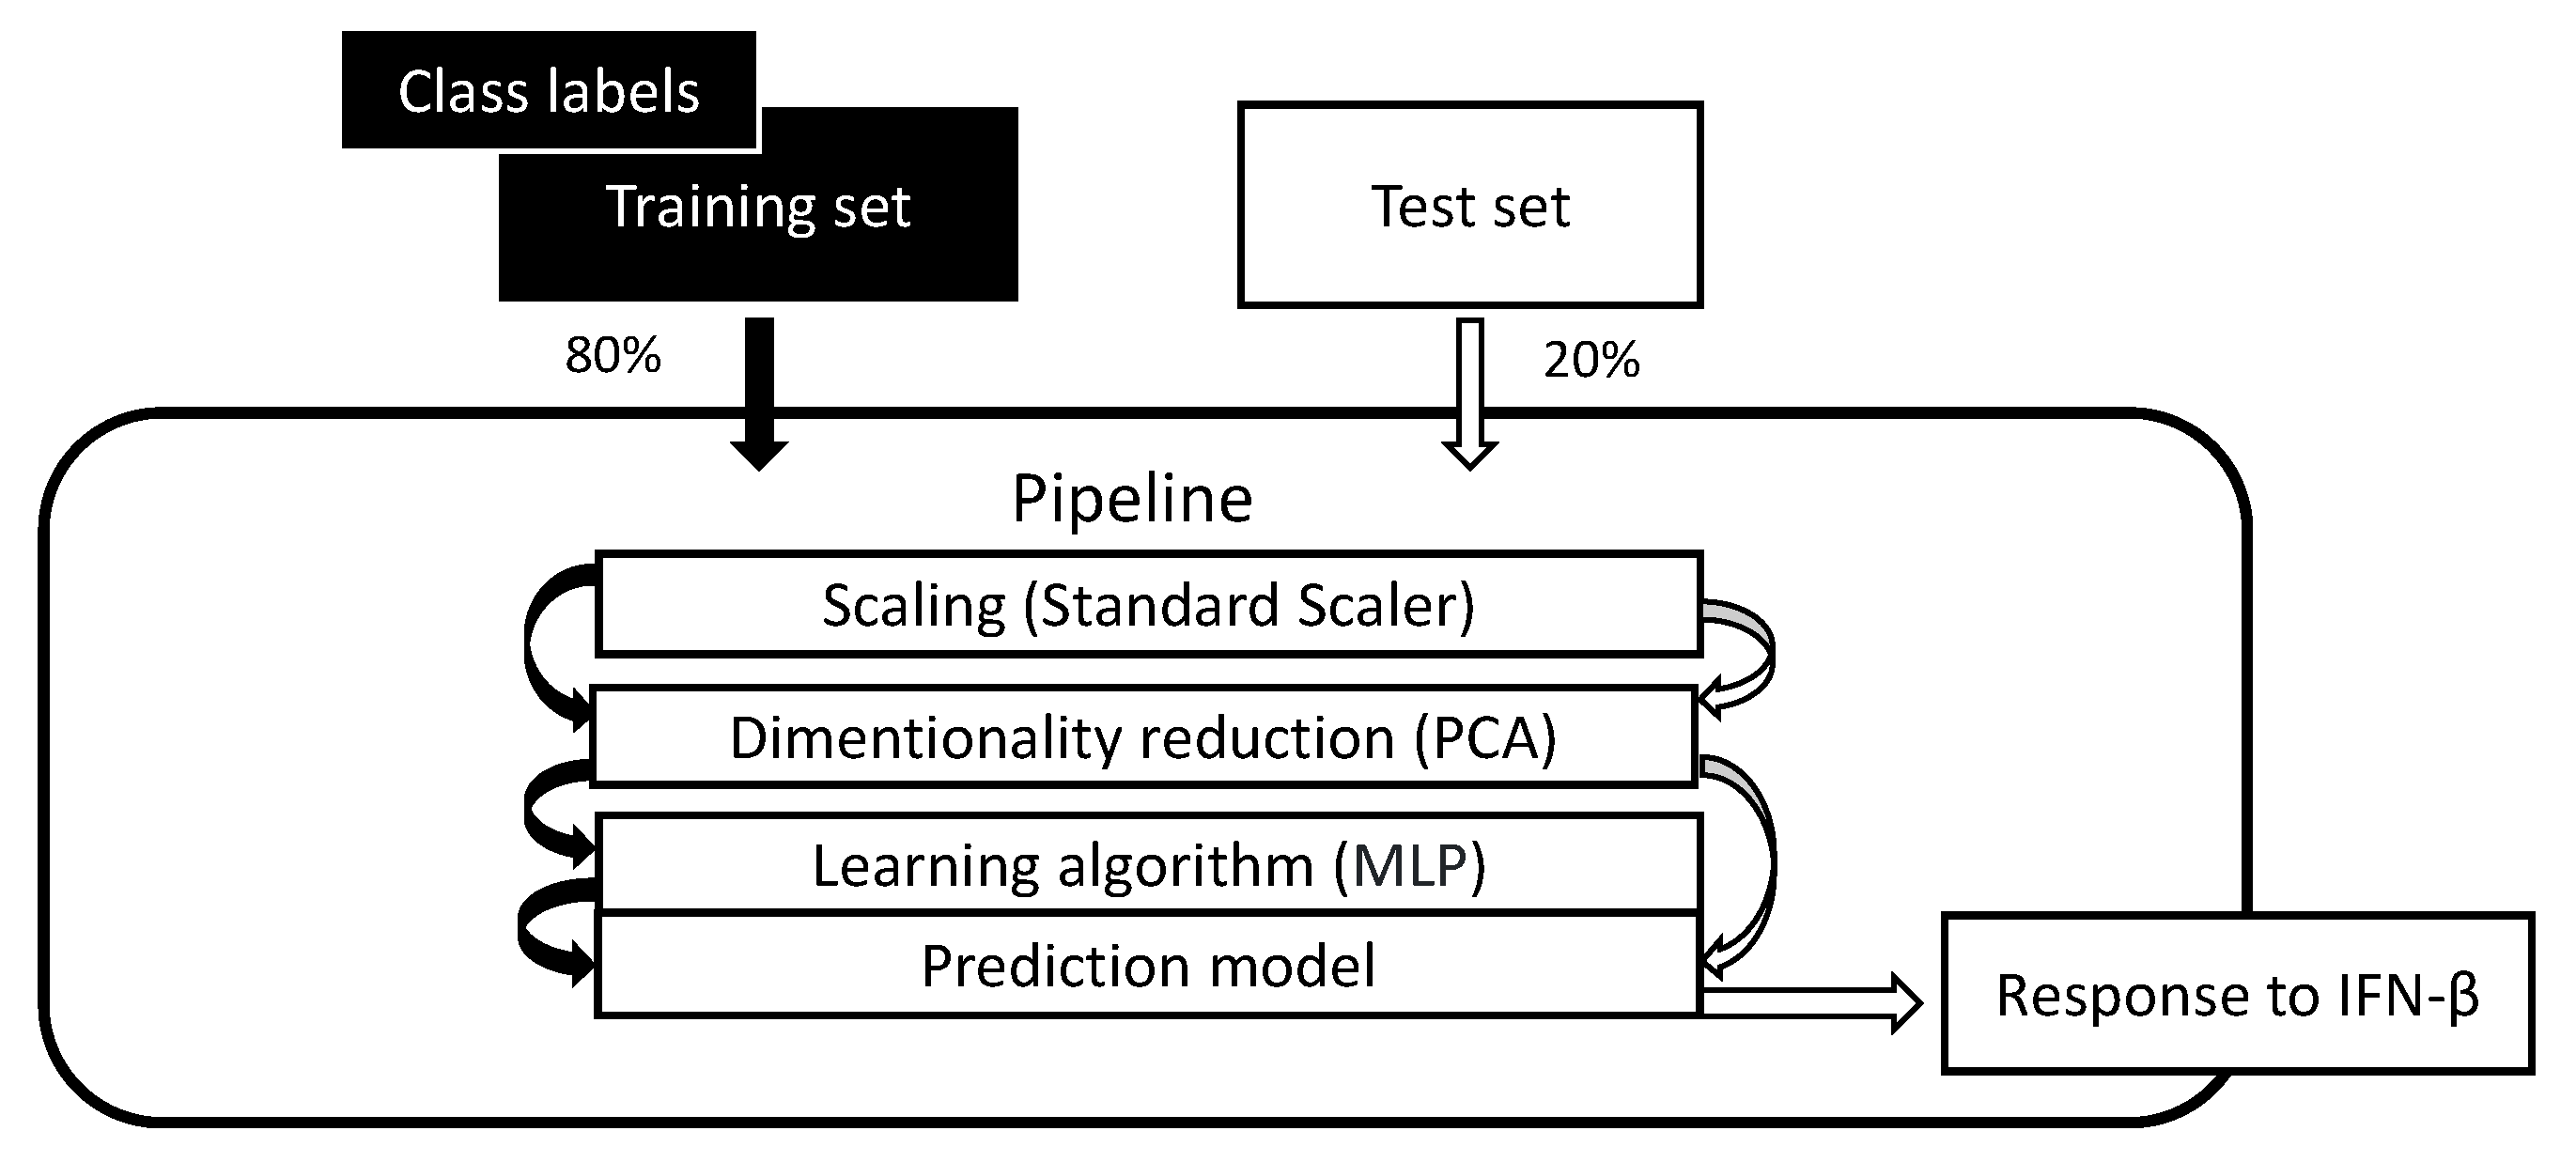
A pipeline is a tool for setting a learning model, including a data preprocessing technique (for instance standardization for feature scaling), a transformation technique (such as PCA for data compression), and a learning algorithm (like MLP) for making predictions on new data. The structure of the proposed pipeline is shown in Figure 8.
Figure 8.
Structure of proposed pipeline model, including feature scaling, data compression, and prediction algorithm.
PCA is a technique of dimensionality reduction, which transforms data from a high-dimensional space to a space of lower dimensions. The dimension reduction is achieved by selecting the principal components (directions of maximum variance) as a basis set for the new space [30]. Applications of PCA include analysis of genome data and gene expression levels. For extracting the principal components, the data are standardized; then, the covariance matrix is built, to store the pairwise covariances between features. For example, the covariance between two features and can be computed by Equation (3):
where and are the representative samples of the j and k features, respectively (, , because of the standardization). The eigenvectors of the covariance matrix represent the principal components, and the eigenvalues define the magnitude of the eigenvectors, so the eigenvalues have to be ordered by decreasing the magnitude [31]. The ratio of an explained variance of an eigenvalue is the fraction of the eigenvalue and the total sum of the eigenvalues, as shown by Equation (4):
MLP is a supervised learning algorithm that uses the backpropagation technique for learning. The structure of MLP consists of an input layer of neurons that receive the sample inputs, one or more hidden layers of neurons that convert the values from the previous layer to a weighted linear summation, , followed by a non-linear activation function that is used to learn the weights, and then the output layer that predicts the class label of the samples [32]. During the learning stage, MLP compares the true class labels to the continuous output values of the non-linear activation function, to compute the prediction error and update the weights. The hyperparameters of MLP are arbitrarily set as follows: solver = ’sgd’, activation = ’tanh’, and learning_rate_init = 0.01.
2.4. Performance Evaluation
One of the key steps in building an ML or deep learning (DL) model is estimating its performance with new data. A model can suffer underfitting (high bias) if the model is too simple, or can suffer overfitting (high variance) if the model is too complex for the subjacent training data [31]. In order to get an acceptable bias–variance rate, the k-iterations cross-validation (CV) technique is implemented, which can obtain reliable estimates of the model’s generalization performance.
In the k-iterations CV, the training dataset is randomly split into k iterations without replacement, where iterations are used for model training, and 1 iteration is used for performance evaluation. This process is repeated k times, to obtain k models and performance estimates. Then, the average performance of the models is computed by Equation (5), based on the independent iterations, to obtain a performance estimate:
Typically, the k-iterations CV is used for model fitting, to find the optimal values of the hyperparameters that produce satisfactory generalization performance. Also, the confusion matrix (CM) is computed, which reports the count of the predictions of a classifier [33]: true positives (TP), true negatives (TN), false positives (FP), and false negatives (FN).
3. Results
For this paper, a fuzzy logic system based on MAFS was implemented, to classify RRMS patients as high, medium, or low responders to IFN- treatment. Also, for comparison purposes, a hierarchical clustering technique was implemented, to classify the same patients. After the dataset outputs were labeled, the gene features were used as training inputs for the proposed pipeline prediction model.
3.1. Fuzzy Logic System
At fuzzification stage, the membership values were computed for each one of the input variables. Table 5 and Table 6 display the computed values of each membership function for all the samples.
Table 5.
Fuzzification results (gender and age).
Table 6.
Fuzzification results (EDSS 1st month and EDSS 24th month).
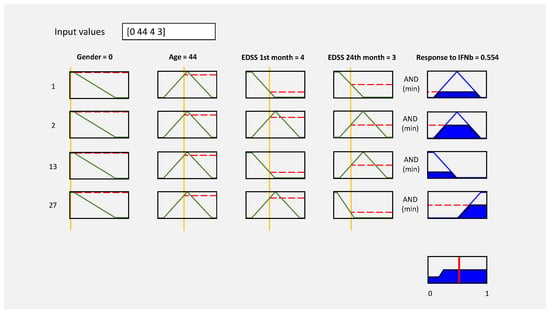
At the approximate reasoning stage, each one of the 36 inference rules from the knowledge base were evaluated with the obtained membership values from Table 5 and Table 6. For example, considering the input values of #7 sample (gender: “female”, age: “44”, EDSS 1st month: “4”, and EDSS 24th month: “3”), the inference engine results are shown in Table 7. In this case, only four rules—1, 2, 13, and 27—had an inference result different to zero. Figure 9 displays the evaluation graph of previous inference rules.
Table 7.
Inference results for #7 sample.
Figure 9.
Evaluation graph of the 1, 2, 13, and 27 inference rules. The result graph consists of the combination of the four rules’ inference values.
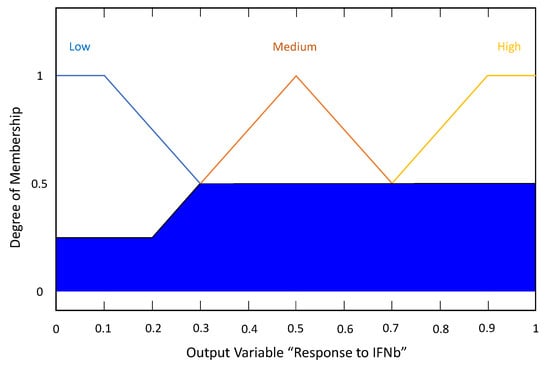
At defuzzification stage, the numerical outputs were computed, substituting the inference engine results into Equation (1), based on the inference result graphs. For example, for the inference results of #7 sample according to the result graph of Figure 10, the numerical output was computed as follows:
Figure 10.
Inference result graph of #7 sample, which includes the values of the “Low”, “Medium”, and “High” linguistic labels.
The small difference in calculation was due to the fuzzy system implementation in Matlab software providing more accurate results than by hand.
Finally, a classification of high, medium, and low responders to the IFN- drug was carried out, by three different methods: (1) opinion of a neurology expert, (2) proposed fuzzy system, and (3) agglomerative clustering model. The results are displayed in Table 8.
Table 8.
Classification of response to IFN-. The resulting numerical values of defuzzification less than 0.5 are considered as low responder (LR), those equal to 0.5 as medium responder (MR), and those greater than 0.5 as high responder (HR). For comparison purposes, the input data of Table 1 were preprocessed by the StandardScaler technique, and they were used to train a prediction model of agglomerative clustering (n_clusters = 3).
As Table 6 shows, 100% of the outputs were correctly labeled by the proposed fuzzy system, while 52% were correctly labeled by agglomerative clustering according to an expert opinion.
3.2. Pipeline Prediction Model
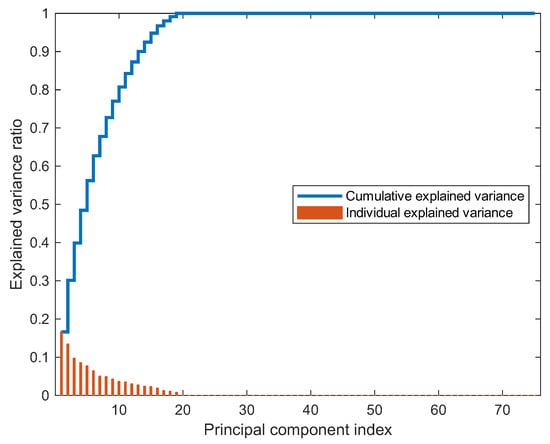
Once the dataset output labels had been classified, the pipeline prediction model was implemented, for making predictions on new data. First, the gene expression values were scaled by the StandardScaler technique. Then, the PCA technique was used, to reduce the dimensionality of the gene dataset by compressing it into a new subspace, so that only the subset of the eigenvectors (principal components) that contained more information (maximum variance) were selected. Figure 11 shows the results of the explained variance ratio of the eigenvalues.
Figure 11.
Explained variance ratio. The first principal component by itself accounts for almost 20% of the total variance. Furthermore, the first two combined principal components represent approximately 40% of the variance.
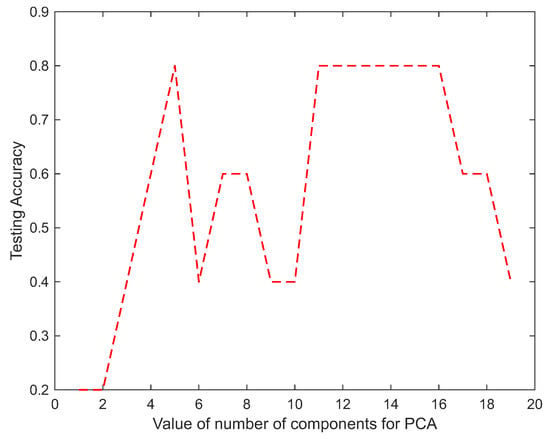
Figure 12 shows the graph used to determine the optimal value of the number of principal components (n_components) for the PCA technique to achieve the high testing accuracy of the MLP prediction algorithm.
Figure 12.
Optimal value of n_components. The value of the n_components is arbitrarily set to 13, for attaining a 0.8 average testing accuracy.
3.3. Performance Evaluation
In this paper, the -iterations CV technique was implemented for evaluating the prediction model performance. Table 9 presents the CV accuracy results for each fold. The maximun CV accuracy was achieved at the 7th and 8th folds, and the average estimate performance was 0.521 +/− 0.327.
Table 9.
K-iterations cross-validation results.
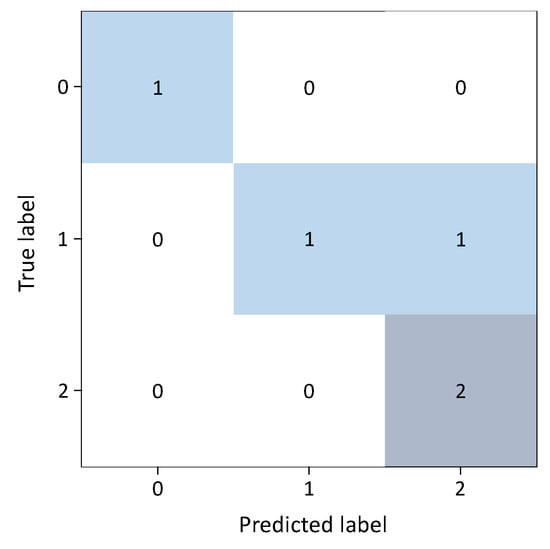
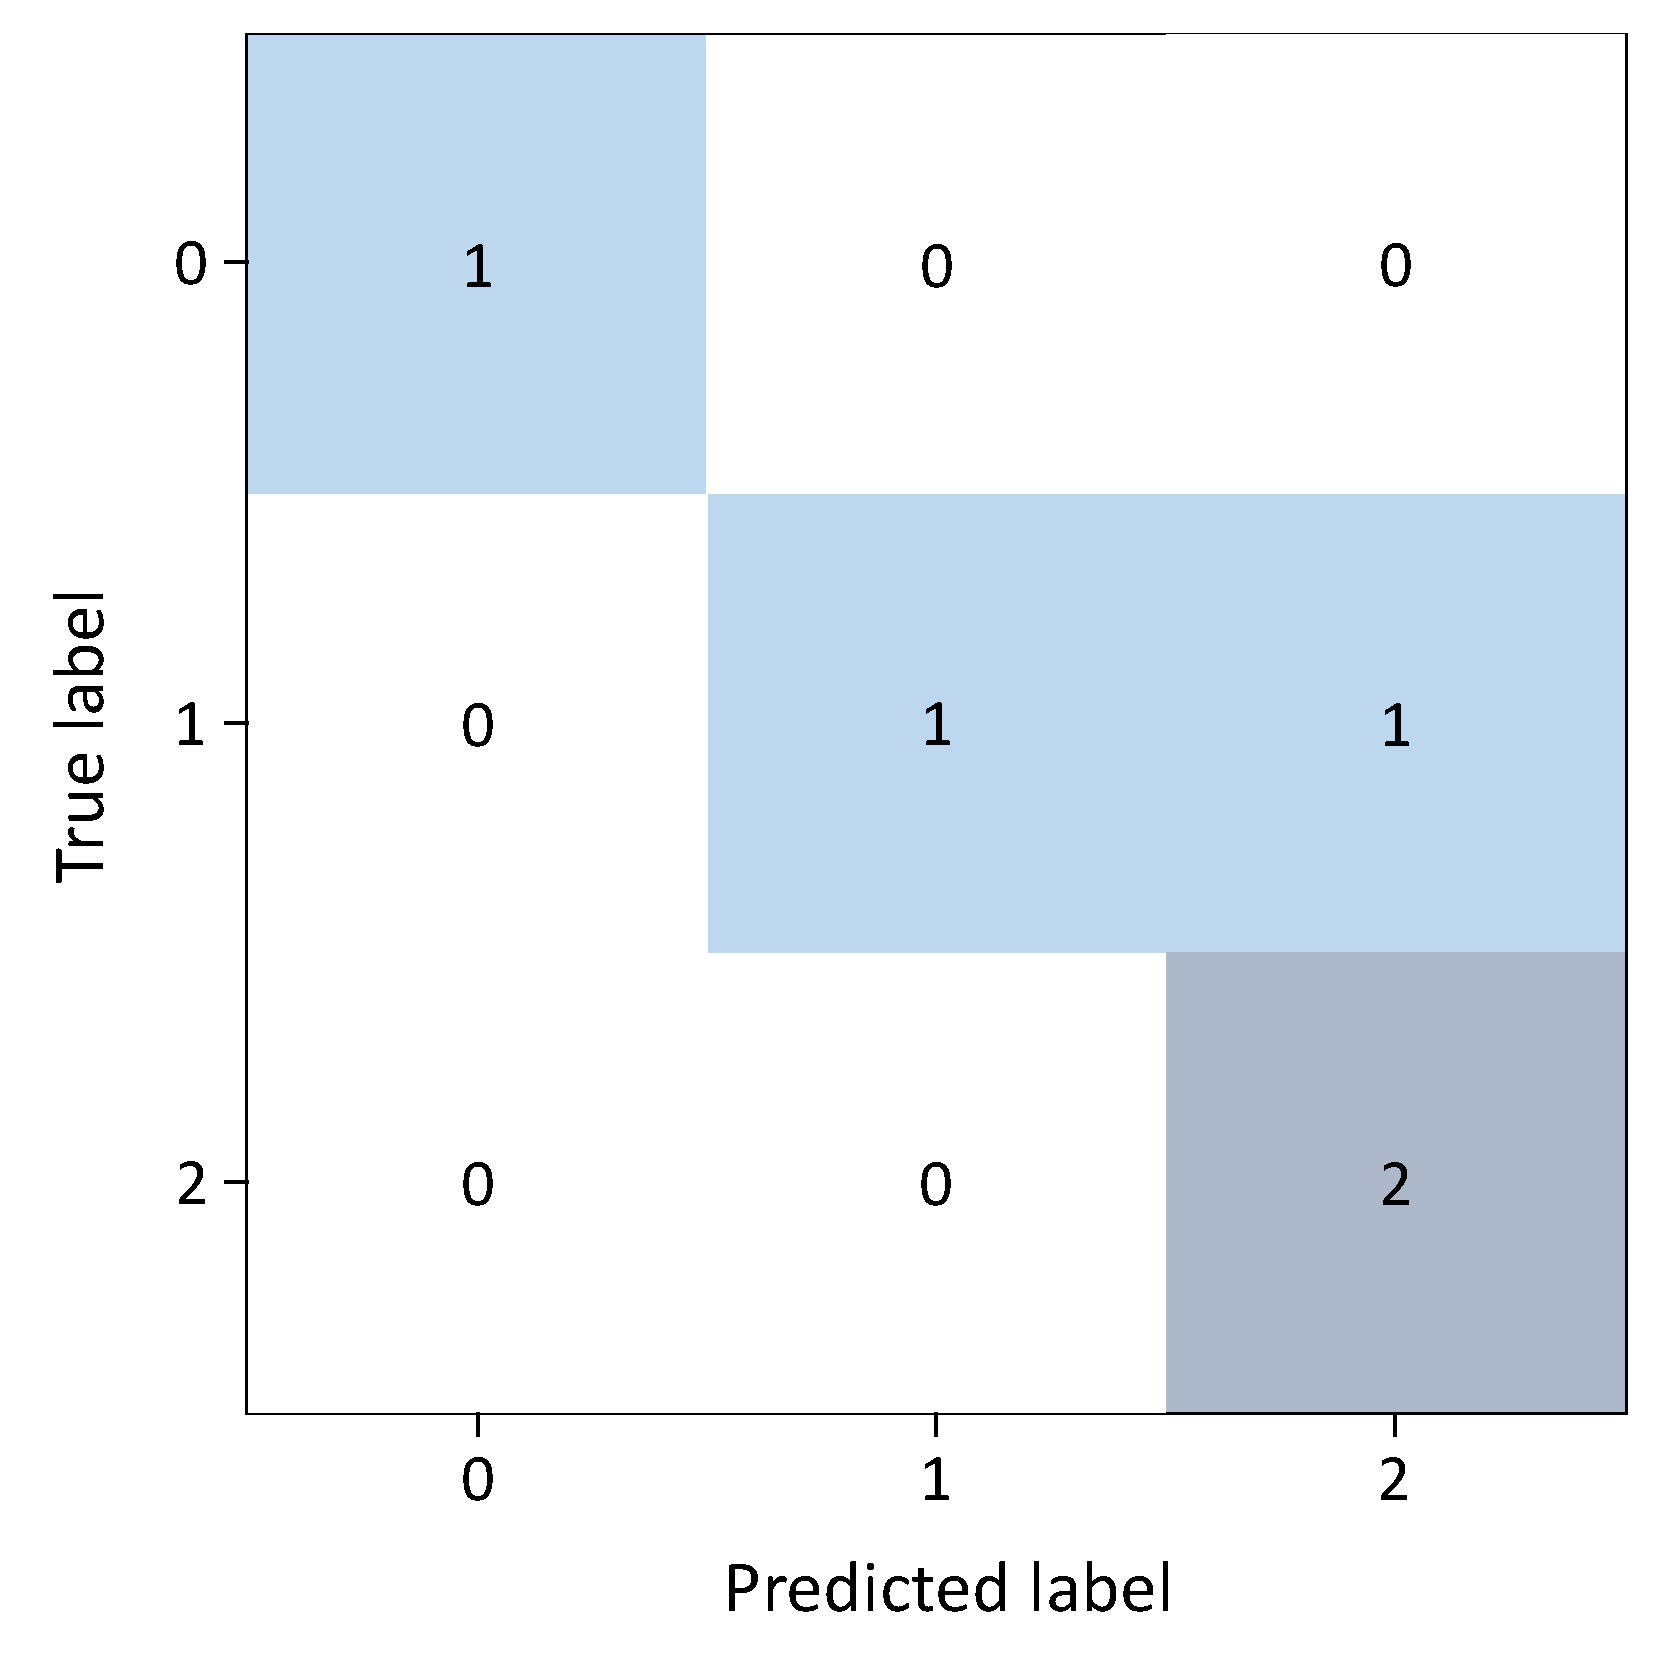
The input data (1875 samples) were divided into 80% (1500 samples) and 20% (375 samples), according to Pareto analysis [34], in order to avoid overfitting. In addition, the output labels (25 samples) were divided into 80% (20 samples) and 20% (5 samples), for validation. The CM was computed with test and predicted data, and the results are shown in Figure 13.
Figure 13.
Confusion matrix results: (0) high responder to IFN-, (1) low responder to IFN-, and (2) medium responder to IFN-.
The CM results represents one high-responder patient who was correctly predicted as a high responder, one low-responder patient who was correctly predicted as a low responder, one low-responder patient who was wrongly predicted as a medium responder, and two medium-responder patients who were correctly predicted as medium responders. Based on previous results, the prediction model achieved 0.8 testing accuracy.
4. Discussion
While binary logic generates only two output types—[0, 1]—fuzzy inference engines use approximate reasoning based on generalized rules of inference. Hence, fuzzy systems are convenient methods for decision support, due to their ability to process inaccurate information. For this paper, an alternative fuzzy system based on expert knowledge was implemented, for decision support in classification of the response to IFN- treatment of RRMS patients. Demographic and clinical characteristics were used as input variables to the fuzzy system. As shown in Table 8, the classification of the proposed fuzzy system achieved better results than the agglomerative clustering, because the latter did not consider the intrinsic properties of the data, it simply used the distance between the data points to group them into clusters. A software issue in the fuzzy system design was to set a small number of input variables: the greater the number of variables, the greater the data processing time.
It is important to mention that at the beginning of the fuzzy system design, a proposal of fuzzy rules definition was reviewed by the expert neurologist, who considered only two output linguistic labels: “low” and “high” responder to IFN-. Under these conditions, 88% efficiency was obtained in the results. After validating the results, the expert recommended adding an extra label—“medium”—to classify MS patients who had the same EDSS level at the beginning as at the end of treatment. After redefining the fuzzy rules, 100% efficiency was achieved.
Once the dataset output labels were classified by the fuzzy system, a pipeline prediction model was implemented, including data standardization, data compression through the PCA technique, and an MLP learning algorithm. The pipeline model was trained with 15 biomarkers associated with the response to IFN- for predicting whether RRMS patients were potential candidates to be treated with this drug. As shown in Figure 12, by setting 13 principal components for PCA, 0.8 testing accuracy was achieved. The use of the PCA technique for data compression provides some advantages: (1) the reduced dimension has the property of keeping most of the useful information, while reducing noise and other undesirable data, (2) the time and memory used in the data processing are smaller, (3) it provides a way to understand and visualize the structure of complex datasets. The use of the k-iterations CV technique helps to obtain a good bias–variance rate. The highest CV accuracy was achieved at the 7th and 8th folds, as shown in Table 9. One disadvantage in evaluating the prediction model performance was that the test samples size was too small. Therefore, the number of iterations for the CV technique was limited to eight.
ML algorithms can find natural patterns in the data, and they are a useful alternative in the field of bio-informatics. These algorithms have been implemented to improve the MS diagnosis [20,21] and to help specialists to predict the response to drug treatments in MS patients [22,25]. Table 10 presents a comparison of the performance results of some ML applications in MS study.
Table 10.
Performance results comparison of ML applications in MS study.
The results obtained in this paper could be a reference for future works, using other genes related to the response to IFN- treatment, as training data. Also, new prediction models, such as evolutionary or DL algorithms, could be designed, to improve model performance.
5. Conclusions
In general, IFN- treatment effectively reduces the rate of relapse and delays the progression of neurological disability in MS patients. However, a percentage of patients do not respond, or partially respond to this drug. In this paper, the proposed fuzzy system, based on the opinion of an expert, demonstrated high efficiency in decision support, and it could be a useful tool in labeling classes, such as classification of the response to IFN- therapy.
Although genome research is complex, there are ML methods—for instance, the proposed pipeline model—that can effectively deal the gene data for obtaining reliable predictions, to guide specialists in the selection of MS patients who may obtain the greatest benefit from IFN- treatment. Biomarkers—in particular IL-2, IL-12, IFN-, TNF-, IL-4, IL-10, TGF-, CD46, CD58, FHIT, IRF5, GAPVD1, GPC5, GRM3, and GRIK2—can be convenient predictive variables for improving the comprehension of the influence of IFN- therapy in MS patients.
Author Contributions
Conceptualization, E.R.P.d.L.-S. and A.M.H.-N.; methodology, E.R.P.d.L.-S. and A.M.H.-N.; software, E.R.P.d.L.-S.; validation, H.S.-M.; formal analysis, J.D.M.-S., O.A.D.-R., A.V.-C. and H.J.-H.; investigation, E.R.P.d.L.-S.; resources, J.D.M.-S., O.A.D.-R., A.M.H.-N., A.V.-C. and H.J.-H.; writing—original draft preparation, E.R.P.d.L.-S.; writing—review and editing, E.R.P.d.L.-S. and J.D.M.-S.; supervision, J.D.M.-S., O.A.D.-R., A.V.-C. and H.J.-H.; project administration, E.R.P.d.L.-S., J.D.M.-S. and O.A.D.-R. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
The implemented pseudo-codes and the collected dataset are available at https://github.com/ponceraf2020/Pipeline-model.git (accessed on 30 May 2023).
Conflicts of Interest
The authors declare no conflict of interest.
References
- Milo, R.; Miller, A. Revised diagnostic criteria of multiple sclerosis. Autoimmun. Rev. 2014, 13, 518–524. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Martynova, E.; Khaibullin, T.; Salafutdinov, I.; Markelova, M.; Laikov, A.; Lopukhov, L.; Liu, R.; Sahay, K.; Goyal, M.; Baranwal, M.; et al. Seasonal Changes in Serum Metabolites in Multiple Sclerosis Relapse. Int. J. Mol. Sci. 2023, 24, 3542. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Tarlinton, R.E.; Martynova, E.; Rizvanov, A.A.; Khaiboullina, S.; Verma, S. Role of viruses in the pathogenesis of multiple sclerosis. Viruses 2020, 12, 643. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zarghami, A.; Li, Y.; Claflin, S.B.; van der Mei, I.; Taylor, B.V. Role of environmental factors in multiple sclerosis. Expert Rev. Neurother. 2021, 21, 1389–1408. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Dominguez-Mozo, M.I.; Perez-Perez, S.; Villarrubia, N.; Costa-Frossard, L.; Fernandez-Velasco, J.I.; Ortega-Madueño, I.; Garcia-Martinez, M.A.; Garcia-Calvo, E.; Estevez, H.; Luque Garcia, J.L.; et al. Herpesvirus antibodies, vitamin d and short-chain fatty acids: Their correlation with cell subsets in multiple sclerosis patients and healthy controls. Cells 2021, 10, 119. [Google Scholar] [CrossRef] [Scilit]
- Rodríguez Murúa, S.; Farez, M.F.; Quintana, F.J. The immune response in multiple sclerosis. Annu. Rev. Pathol. Mech. Dis. 2022, 17, 121–139. [Google Scholar] [CrossRef] [Scilit]
- Pinheiro, M.A.L.; Kooij, G.; Mizee, M.R.; Kamermans, A.; Enzmann, G.; Lyck, R.; Schwaninger, M.; Engelhardt, B.; de Vries, H.E. Immune cell trafficking across the barriers of the central nervous system in multiple sclerosis and stroke. Biochim. Biophys. Acta (BBA)-Mol. Basis Dis. 2016, 1862, 461–471. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y.; Zheng, M.; Ma, Z.; Zhou, Y.; Huo, J.; Zhang, W.; Liu, Y.; Guo, Y.; Zhou, X.; Li, H.; et al. Design, synthesis, and evaluation of PD-L1 degraders to enhance T cell killing activity against melanoma. Chin. Chem. Lett. 2022, 34, 107762. [Google Scholar] [CrossRef] [Scilit]
- Szpakowski, P.; Ksiazek-Winiarek, D.; Glabinski, A. Targeting Antigen-Presenting Cells in Multiple Sclerosis Treatment. Appl. Sci. 2021, 11, 8557. [Google Scholar] [CrossRef] [Scilit]
- Mirandola, S.R.; Hallal, D.E.; Farias, A.S.; Oliveira, E.C.; Brandão, C.O.; Ruocco, H.H.; Damasceno, B.P.; Santos, L.M. Interferon-beta modifies the peripheral blood cell cytokine secretion in patients with multiple sclerosis. Int. Immunopharmacol. 2009, 9, 824–830. [Google Scholar] [CrossRef] [Scilit]
- Kay, M.; Hojati, Z.; Dehghanian, F. The molecular study of IFNβ pleiotropic roles in MS treatment. Iran. J. Neurol. 2013, 12, 149. [Google Scholar]
- Cohan, S.L.; Hendin, B.A.; Reder, A.T.; Smoot, K.; Avila, R.; Mendoza, J.P.; Weinstock-Guttman, B. Interferons and multiple sclerosis: Lessons from 25 years of clinical and real-world experience with intramuscular interferon beta-1a (Avonex). CNS Drugs 2021, 35, 743–767. [Google Scholar] [CrossRef] [Scilit]
- Río, J.; Nos, C.; Tintoré, M.; Borrás, C.; Galán, I.; Comabella, M.; Montalban, X. Assessment of different treatment failure criteria in a cohort of relapsing–remitting multiple sclerosis patients treated with interferon β: Implications for clinical trials. Ann. Neurol. Off. J. Am. Neurol. Assoc. Child Neurol. Soc. 2002, 52, 400–406. [Google Scholar] [CrossRef] [Scilit]
- Bustamante, M.F.; Morcillo-Suárez, C.; Malhotra, S.; Rio, J.; Leyva, L.; Fernández, O.; Zettl, U.K.; Killestein, J.; Brassat, D.; García-Merino, J.A.; et al. Pharmacogenomic study in patients with multiple sclerosis: Responders and nonresponders to IFN-β. Neurol. Neuroimmunol. Neuroinflamm. 2015, 2. [Google Scholar] [CrossRef] [Scilit]
- Martínez-Aguilar, L.; Pérez-Ramírez, C.; del Mar Maldonado-Montoro, M.; Carrasco-Campos, M.I.; Membrive-Jiménez, C.; Martínez-Martínez, F.; García-Collado, C.; Calleja-Hernández, M.Á.; Ramírez-Tortosa, M.C.; Jiménez-Morales, A. Effect of genetic polymorphisms on therapeutic response in multiple sclerosis relapsing-remitting patients treated with interferon-beta. Mutat. Res. Mutat. Res. 2020, 785, 108322. [Google Scholar] [CrossRef] [Scilit]
- KARLIK, B. Soft computing methods in bioinformatics: A comprehensive review. Math. Comput. Appl. 2013, 18, 176–197. [Google Scholar] [CrossRef] [Scilit]
- Ayangbekun, O.; Jimoh Ibrahim, A. Fuzzy logic application to brain diseases diagnosis. J. Emerg. Trends Comput. Inf. Sci. 2015, 6, 144–148. [Google Scholar]
- Hosseini, A.; Asadi, F.; Arani, L.A. Development of a knowledge-based clinical decision support system for multiple sclerosis diagnosis. J. Med. Life 2020, 13, 612. [Google Scholar] [CrossRef] [Scilit]
- Matinfar, F.; Golpaygani, A.T. A fuzzy expert system for early diagnosis of multiple sclerosis. J. Biomed. Phys. Eng. 2022, 12, 181. [Google Scholar] [CrossRef] [Scilit]
- Goyal, M.; Khanna, D.; Rana, P.S.; Khaibullin, T.; Martynova, E.; Rizvanov, A.A.; Khaiboullina, S.F.; Baranwal, M. Computational Intelligence Technique for Prediction of Multiple Sclerosis Based on Serum Cytokines. Front. Neurol. 2019, 10, 781. [Google Scholar] [CrossRef] [Scilit]
- Chen, X.; Hou, H.; Qiao, H.; Fan, H.; Zhao, T.; Dong, M. Identification of blood-derived candidate gene markers and a new 7-gene diagnostic model for multiple sclerosis. Biol. Res. 2021, 54, 1–12. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Fagone, P.; Mazzon, E.; Mammana, S.; Di Marco, R.; Spinasanta, F.; Basile, M.S.; Petralia, M.C.; Bramanti, P.; Nicoletti, F.; Mangano, K. Identification of CD4+ T cell biomarkers for predicting the response of patients with relapsing-remitting multiple sclerosis to natalizumab treatment. Mol. Med. Rep. 2019, 20, 678–684. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Gurevich, M.; Miron, G.; Falb, R.Z.; Magalashvili, D.; Dolev, M.; Stern, Y.; Achiron, A. Transcriptional response to interferon beta-1a treatment in patients with secondary progressive multiple sclerosis. BMC Neurol. 2015, 15, 1–8. [Google Scholar] [CrossRef] [Scilit]
- Clarelli, F.; Liberatore, G.; Sorosina, M.; Osiceanu, A.; Esposito, F.; Mascia, E.; Santoro, S.; Pavan, G.; Colombo, B.; Moiola, L.; et al. Pharmacogenetic study of long-term response to interferon-β treatment in multiple sclerosis. Pharmacogenom. J. 2017, 17, 84–91. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Jin, T.; Wang, C.; Tian, S. Feature selection based on differentially correlated gene pairs reveals the mechanism of IFN-therapy for multiple sclerosis. Bioinform. Genom. 2020, 8, 8812. [Google Scholar] [CrossRef] [Scilit]
- National Center for Biotechnology Information (NCBI)—Gene Expression Omnibus (GEO) Database 2010. Available online: https://www.ncbi.nlm.nih.gov/geo/geo2r (accessed on 15 January 2023).
- Rutkowska, D. Neuro-Fuzzy Architectures and Hybrid Learning; Springer Science & Business Media: Berlin/Heidelberg, Germany, 2001; Volume 85. [Google Scholar]
- Van Leekwijck, W.; Kerre, E.E. Defuzzification: Criteria and classification. Fuzzy Sets Syst. 1999, 108, 159–178. [Google Scholar] [CrossRef] [Scilit]
- Prokopowicz, P.; Czerniak, J.; Mikołajewski, D.; Apiecionek, Ł.; Ślezak, D. Theory and Applications of Ordered Fuzzy Numbers: A Tribute to Professor Witold Kosiński; Springer Open: Warsaw, Poland, 2017. [Google Scholar]
- Sanguansat, P. Principal Component Analysis: Engineering Applications; IntechOpen: Rijeka, Croatia, 2012. [Google Scholar]
- Mirjalili, V.; Raschka, S. Python Machine Learning: Machine Learning and Deep Learning with Python, Scikit-Learn and TensorFlow; Packt: Birmingham, UK, 2019. [Google Scholar]
- Casalino, G.; Castellano, G.; Consiglio, A.; Nuzziello, N.; Vessio, G. MicroRNA expression classification for pediatric multiple sclerosis identification. J. Ambient. Intell. Humaniz. Comput. 2021, 1–10. [Google Scholar] [CrossRef] [Scilit]
- Salamai, A.A.; El-kenawy, E.S.M.; Abdelhameed, I. Dynamic voting classifier for risk identification in supply chain 4.0. CMC Comput. Mater. Contin. 2021, 69, 3749–3766. [Google Scholar] [CrossRef] [Scilit]
- Roccetti, M.; Delnevo, G.; Casini, L.; Mirri, S. An alternative approach to dimension reduction for pareto distributed data: A case study. J. Big Data 2021, 8, 1–23. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2023 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).