


Abstract
To address the issues of fault tolerance and retrieval efficiency in cloud storage space data, we propose an efficient cloud storage solution based on erasure codes. A cloud storage system model is designed to use erasure codes to distribute the encoded original data files across various nodes of the cloud storage system in a decentralized manner. The files are decoded by the receiver to complete data recovery and ensure high availability of the data files while optimizing redundant computing overhead during data storage, thereby improving the stability of encoding and decoding and reducing the bit error rate. Additionally, the Kademlia protocol is utilized to improve the retrieval efficiency of distributed disaster recovery storage data blocks. The proposed solution is tested on the Hadoop cloud storage platform, and the experimental results demonstrate that it not only maintains high availability but also enhances the efficiency of retrieving data files.
1. Introduction
The swift advancement of cloud computing technology has led to cloud services becoming the predominant service model on the Internet [1,2,3,4]. As an efficient, flexible and scalable computing pattern, cloud services have been widely popularized worldwide, profoundly changing the computing and data management methods of enterprises and individuals. Among them, the cloud storage service, as an important part of cloud services, has become the preferred solution for enterprise and personal data storage because of its convenience, low cost and high scalability. Whether it is for backing up personal photos and videos or the storage and management of massive business data of enterprises, cloud storage provides strong support, greatly simplifying the complexity of data storage and access.
However, with the wide application of cloud storage services, data availability and security issues become increasingly prominent. In order to ensure the availability of cloud storage data, especially in the face of potential risks such as unexpected failures, natural disasters or human errors, data disaster tolerance backup has become a crucial means of protection. By saving multiple copies of data in different geographical locations or on different storage media, disaster recovery backup ensures that data can be quickly recovered in case of failure of the primary storage system, thus minimizing the risk of data loss and business interruption.
The implementation of data disaster recovery backup is a challenge that cannot be ignored. First, disaster recovery backup requires a large amount of redundant storage space to save data copies, which not only increases the storage cost but also puts forward higher requirements for the management of storage resources. Secondly, with the arrival of the era of big data, the amount of data is exploding, and the storage and management of massive data has become a huge challenge for cloud storage service providers. Traditional data backup methods, such as simple data replication or triple-backup strategies, can provide a certain degree of disaster tolerance but often lead to a large waste of storage space. For example, for a 1 TB data file, adopting a simple two-copy backup strategy would increase the total storage requirement to 3 TB, with 2 TB being redundant data. This results in a storage utilization rate of only 33.3%, meaning 66.7% of the allocated space is wasted. If a triple-backup strategy is used instead, then 4 TB of storage would be required, further reducing utilization to 25% and increasing the wasted space to 75%.
In recent years, network coding technology [5,6,7] has been widely applied in various fields to achieve redundant data storage, thereby significantly enhancing the reliability of data storage. Currently, common network coding techniques include random linear network coding (RLC) [8], locally repairable codes (LRCs) [9], regenerating codes [10], and RS erasure codes (RSECs) [11]. Each of these techniques has its own strengths and weaknesses. Random linear network coding has low repair efficiency and high redundancy computation overhead; locally repairable codes offer high repair efficiency but limited fault tolerance; and regenerating codes have strong fault tolerance but also high redundancy computation overhead. In contrast, RS erasure codes achieve a good balance between fault tolerance and redundancy computation overhead, which is why they are widely used [12]. Scholars can select the appropriate network coding technique based on the specific application scenario and requirements.
However, in complex cloud storage systems employing network coding redundancy techniques, further enhancing the fault tolerance of encoded data, optimizing the computational overhead of redundant storage and achieving rapid data recovery remain highly challenging issues due to resource heterogeneity and the massive scale of data.
In this work, we propose a highly available cloud storage solution called “EC-Kad” which is aimed at reducing storage redundant computing overhead and improving the reliability of data recovery. The main contributions of this work are as follows. First, we introduce an encoding-based approach for data file redundancy and fault tolerance, A Cauchy matrix with good numerical stability is used as the coefficient matrix to implement the encoding and decoding of data files in cloud storage systems, which ensures data integrity and availability even when storage nodes fail. Second, a Kademlia [13] algorithm is used to optimize the retrieval and recovery efficiency of data blocks during user read operations, thereby significantly enhancing the overall performance of the cloud storage system. Finally, we implement our proposed “EC-Kad” scheme on the Hadoop cloud storage platform. The experimental results demonstrate that by combining the two strategies mentioned above, our proposed “EC-Kad” solution not only minimizes redundant storage computational overhead but also maintains high data availability and reliability, making it well suited for modern cloud environments.
2. Related Work
In this era of information explosion, cloud storage has emerged as a powerful enabler for technological innovation. Beyond the initial web industry pioneers, an increasing number of enterprises, organizations and individuals are now turning to the cloud to store and manage their digital information. However, the growing diversity of user data and access patterns has introduced significant challenges for the management and maintenance of cloud storage systems. These challenges include balancing costs, ensuring reliability and availability and maintaining responsiveness. As cloud storage systems are designed to handle vast amounts of data, the relentless scale of growth makes it increasingly difficult to address these multifaceted issues effectively.
Well-known cloud storage systems like GFS, HDFS, Ceph and EMC Atoms all use replication to provide data redundancy. For example, HDFS, a widely used cloud file system today, adopts triplication (three-way replication) by default, and EMC Atoms allows reserving more replicas with additional payment.
Despite these advantages, replication does have some drawbacks. The huge amount of digital information (from exabytes to zettabytes) makes it undesirable to store several replicas for all of the data. Extra copies occupy a great deal of storage space (200% overhead for triplication), consume additional network bandwidth for replicating and updating the data and raise consistency issues that can affect the service performance of the whole system.
As a cloud storage solution, the traditional storage method, magnetic tape storage, has been widely used in institutions and research centers around the world. A tape library cloud storage system simulator called TALICS3 was introduced in [14], aiming to provide system administrators and reliability engineers with a design tool for evaluating the performance and reliability of tape libraries in distributed cloud environments through discrete event simulation technology. The core of the research is to help design and optimize large-scale data storage systems by simulating the behavior of tape libraries. Against the backdrop of rapid development in cloud computing and big data, Bhushan et al. [15] provided a detailed introduction to the technological progress of magnetic storage devices in improving recording density. It also comprehensively evaluates the current status and future of magnetic storage devices by combining market data and economic analysis. Ebermann et al. [16] analyzed the impact of the geometric characteristics of the TBS mode, such as the azimuth and subframe length, on the position estimation resolution, system delay and tracking performance. Four TBS modes were designed to significantly improve the tracking accuracy of magnetic tape storage systems.
While magnetic tape storage performs well in low-interference environments, in high-interference environments for practical applications, the data read and write speeds are relatively slow, making it suitable for storing cold data (infrequently accessed data). In addition, it requires complex management and incurs additional human resource costs, reducing its cost-effectiveness. This makes tape storage less suitable for the cloud era, where data mobility is crucial. Kim et al. [17] investigated the performance of a distributed file system (DFS) based on RAID storage in a tapeless storage scenario. The core of the research was to evaluate the performance characteristics of two distributed file systems—CERN EOS and GlusterFS—under different layouts and workloads and explore their feasibility as alternatives to traditional tape storage. A hybrid framework with a three-tier structure was proposed in [18], including a system monitoring layer, a hybrid storage management layer and a physical resource layer. Experiments were conducted using different configurations of RAID-1–6 to evaluate their performance in terms of fault tolerance, fault range and capacity. Liu et al. [19] proposed a hybrid high-reliability RAID architecture called H2-RAID, which was aimed at improving the reliability of SSD RAID systems by combining solid-state drives (SSDs) and hard disk drives (HDDs). The core of the research is to address the inherent write durability issue of SSDs and enhance system reliability by introducing an HDD as a backup while minimizing performance loss. The use of RAID storage technology for the reconstruction and recovery of file data in storage systems can reduce the data reconstruction time and optimize system performance in the event of file system failure, thereby improving data integrity and reliability [20,21,22].
On small-scale datasets, RAID can, to some extent, ensure redundant storage of data and reduce storage overhead, but it requires dedicated hardware support, which increases the complexity of the hardware and configuration, and when facing large-scale heterogeneous resource storage and reconstruction, data redundancy will increase. Moreover, if multiple hard drives fail simultaneously, then some RAID configurations may not be able to recover data. A global optimization model has been proposed [23] which allows different subsystems to adopt different redundancy strategies to optimize the reliability of the entire system. Muthumari et al. [24] proposed a high-security big data deduplication method based on dual encryption and an optimized SIMON cryptographic algorithm, aiming to improve the security and storage efficiency of big data in cloud computing environments. Jackowski et al. [25] proposed a distributed data structure and algorithm for processing object metadata in backup systems with block-level duplicate data deletion. Subsequently, they were implemented as object storage layers for the HYDRAstor backup system. A new cross-client cloud backup solution called Duplicacy was proposed in [26] based on the lock-free duplicate data elimination method. The lock-free method uses content hashing as a file name to store blocks in network or cloud storage for duplicate data removal.
Considering the advantages of coding redundancy, many scholars are committed to applying coding redundancy to data storage systems. In distributed storage systems, using network coding to encode and reconstruct data on storage nodes reduces storage redundancy to a certain extent but increases computational and traffic consumption [27,28,29]. This network encoding method is particularly suitable for file sharing in wireless networks, such as data transmission in multi-hop networks. Erasure codes have the advantages of high error tolerance, high storage efficiency, and low computational complexity. Academic workers are beginning to apply erasure code technology to cloud storage. Li et al. [30] proposed the Zebra framework, which dynamically encodes data into multiple levels based on data requirements, with each level using erasure codes of different parameters. Liu et al. [31] proposed an adaptive and scalable caching scheme using erasure codes in distributed cloud edge storage systems, aiming to reduce data access latency by caching data blocks on edge servers. Noor et al. [32] conducted benchmark testing on erasure code schemes in object systems, evaluating the time efficiency, I/O activity, and fault tolerance of erasure codes in cloud storage. Nachiappan et al. [33] proposed an optimized enhanced proactive recovery algorithm (EPRA) for improving data recovery efficiency in erasure-coded (EC) cloud storage systems. Zhang et al. [34] proposed an encoding construction based on the generalized matrix transposition method, which implements different security-level regeneration code schemes, and quantitatively analyzed the relationship between the security level and system performance parameters. Guefrachi A et al. [35] proposed a novel network coding scheme, NEC-CRC, which combined KK code and LRMC code with CRC error detection code, effectively preventing error propagation. A detailed comparison was made between the performance of the KK code and LRMC code under different network conditions, providing reference for practical applications.
3. Cloud Storage System Model Based on Erasure Code
3.1. Cloud Storage System Model
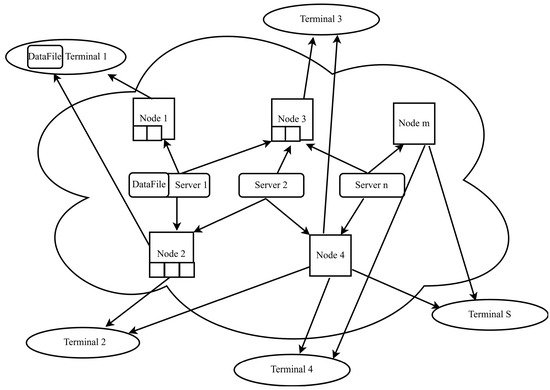
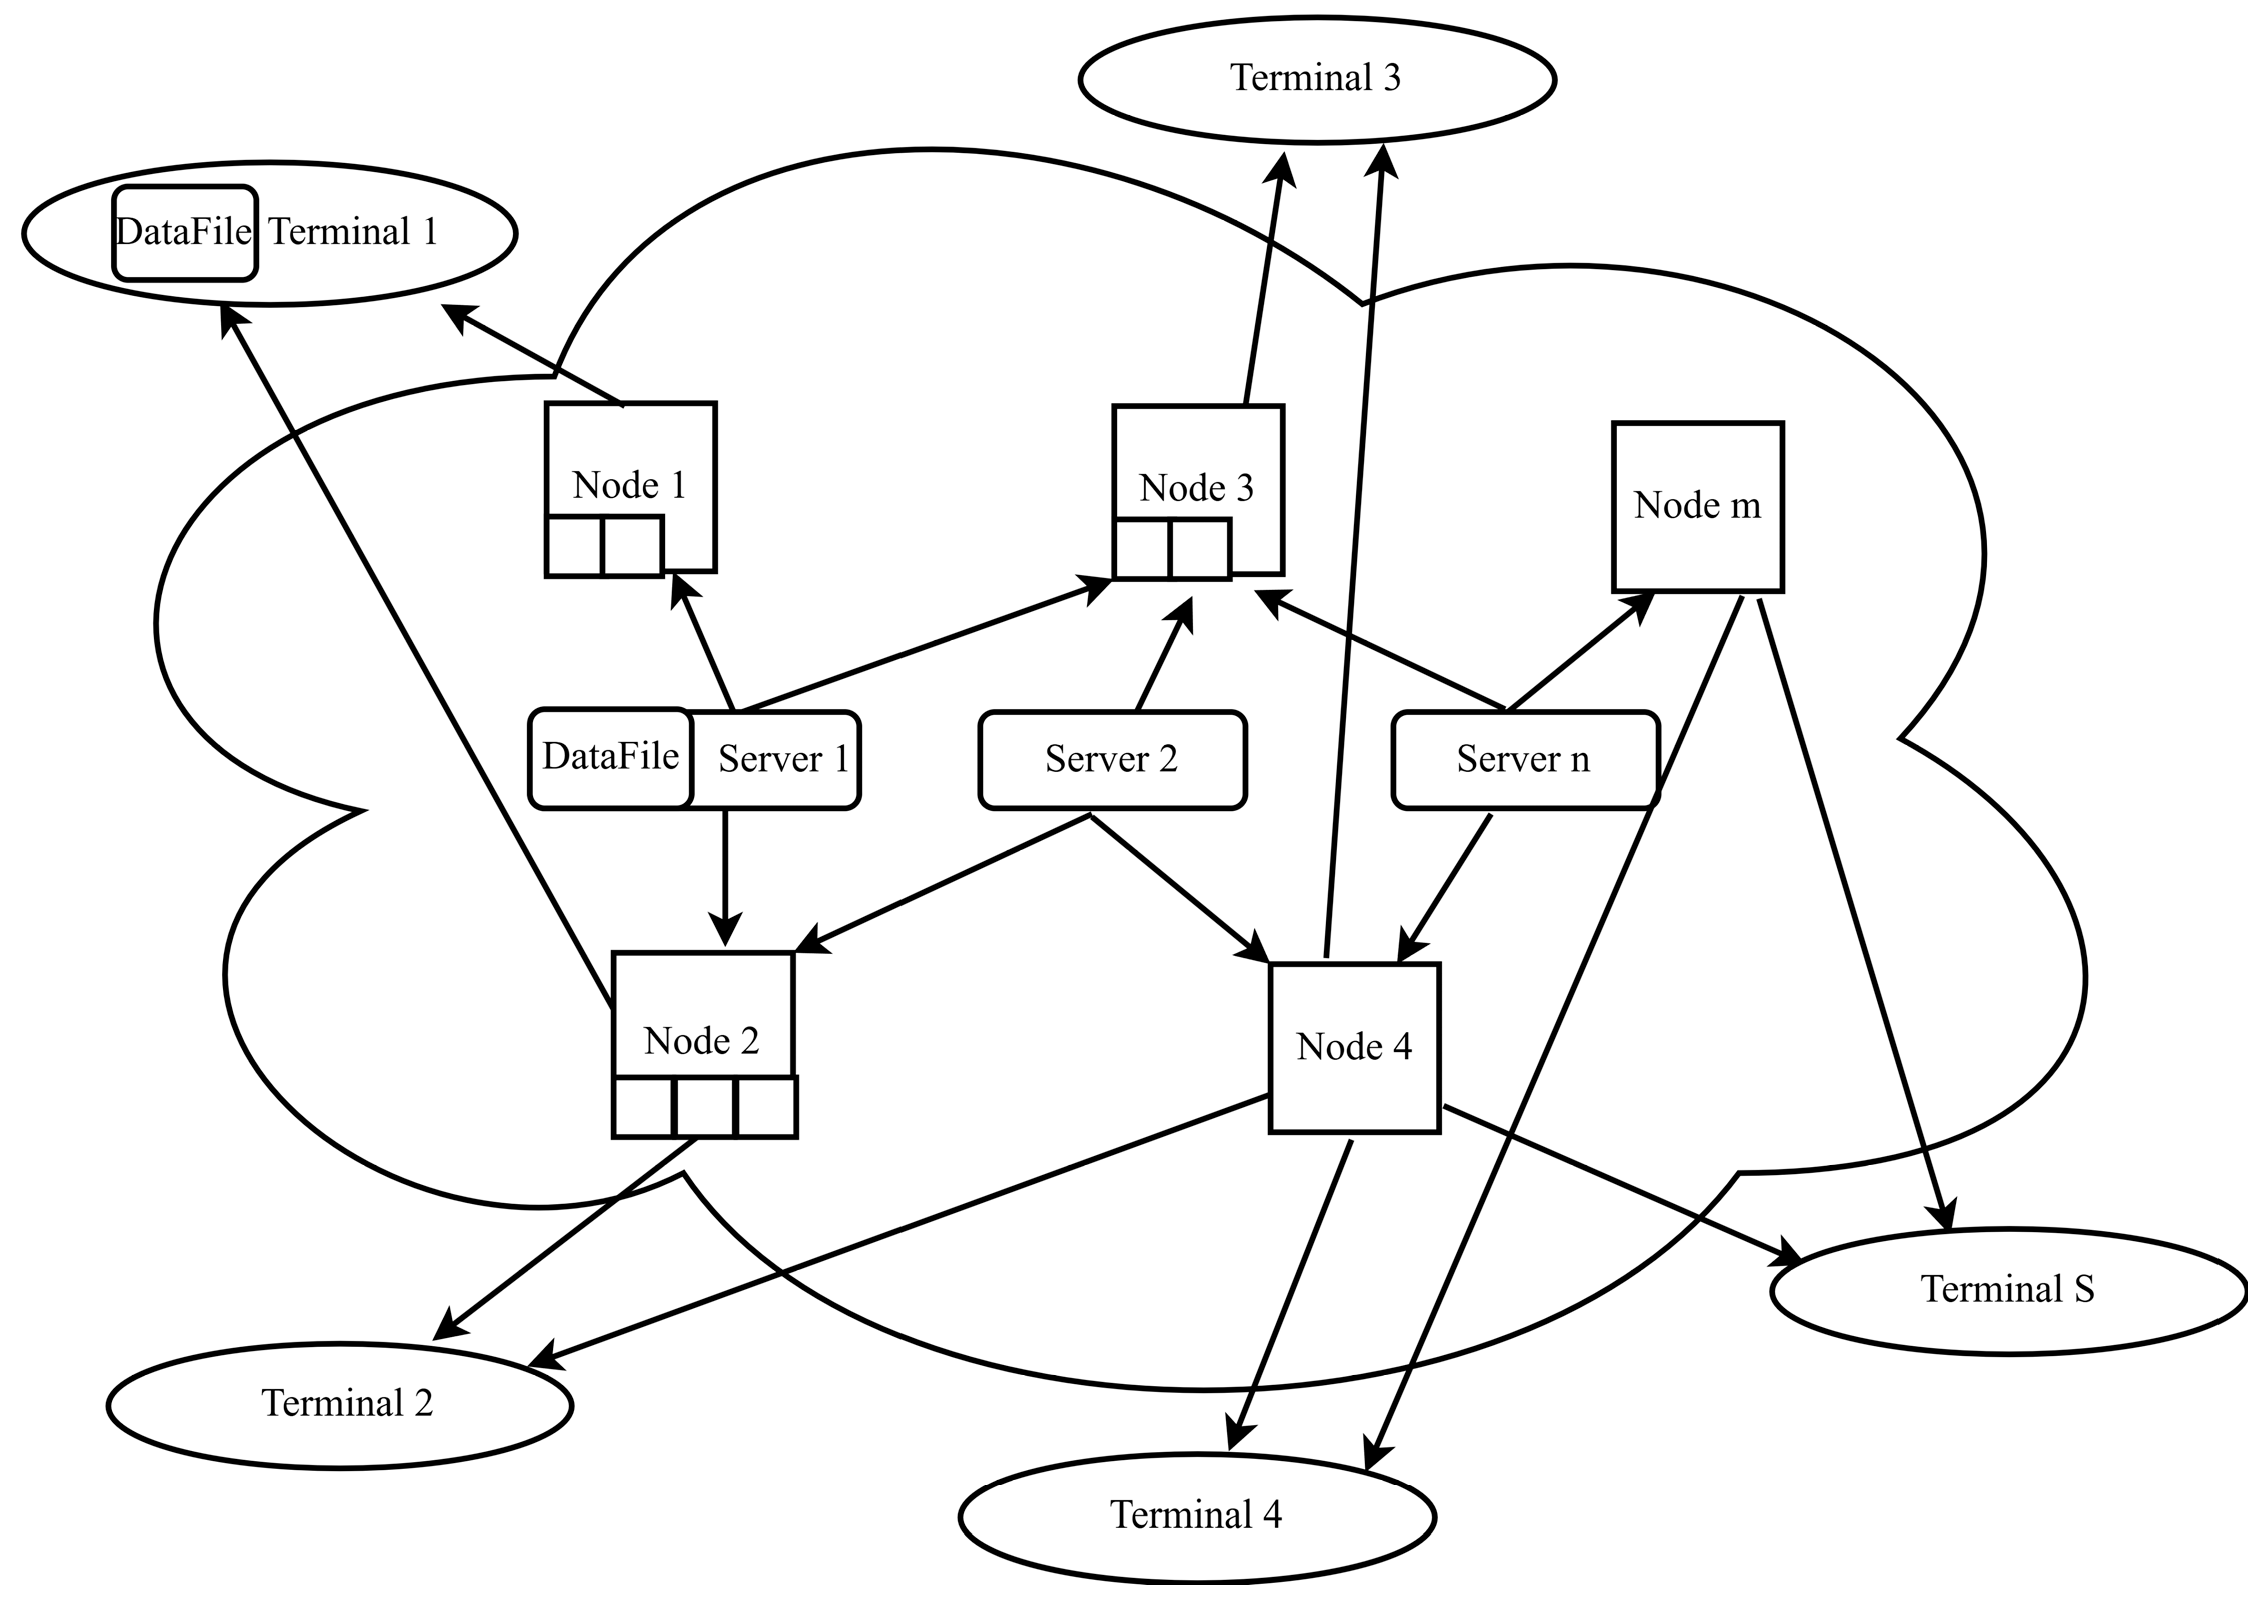
The cloud storage system can be represented by a directed graph G = (V, E), where V is the set of vertices and E is the set of edges connecting two points. All storage nodes and terminals in the cloud storage system are considered vertices, and the network connections between nodes are considered edges in the graph. As shown in Figure 1, the vertex set V is divided into three categories based on the different types of nodes. Server nodes (VS = {S1, S2, …, Sn}) possess the original copies of each file in the storage system; storage nodes (VN = {N1, N2, …, Nm}) receive and store R replicas generated for each file; and terminal nodes (VT = {T1, T2, …, Ts}) are the nodes or user ends that require access to data files. The edge set E can be divided into two major categories based on the type of data transmitted: ES, which transfers data from server nodes to storage nodes, and ET, which transfers data from storage nodes to terminal nodes. The direction of the directed graph edges represents the direction of data flow.
Figure 1.
A simple cloud storage system model.
The network composed of storage nodes and server nodes constitutes a simple cloud storage model, while the terminal nodes are the clients connected to the cloud. The server node stores n original data chunks of each data file F. In contrast, the storage nodes store data chunks that have been encoded with redundancy. Terminal nodes can retrieve a certain number of required data chunks from different storage nodes to reconstruct the data file. Therefore, the storage nodes need to be connected to the server that contains the original data chunks. Each terminal node must be connected to a set of storage nodes that collectively provide the necessary data chunks to recover the original file.
In order to simplify the cloud storage model without losing generality, we propose the following assumptions.
The original copy of each file exists only in one server node; that is, the intersection between the server nodes Si and Sj does not belong to the file Fn (i.e., ).
The type of node is single, and nodes of the same type do not communicate. In fact, a node can be used as the server node of file 1, the storage node of file 2, and the terminal node of file 3. Here, we divide the types and expand the multi-type nodes to multiple single-type nodes.
Assume that there are R copies of each file in the cloud storage system to provide data redundancy, where R is the backup factor.
The direction marked in Figure 1 is not the data link but the flow direction of the data flow in the cloud storage model. Therefore, the model does not involve the redistribution of the link. Because the target application is a storage system, the bandwidth of the link only affects the data transmission speed.
3.2. Data Encoding Storage and Recovery
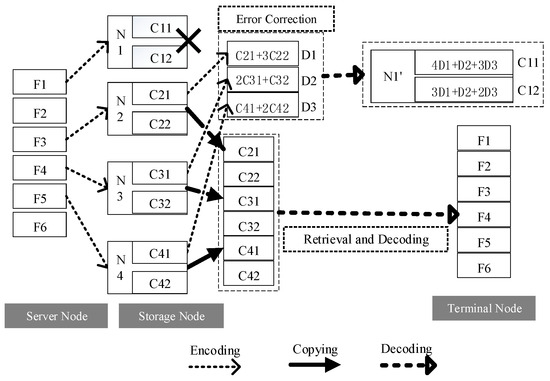
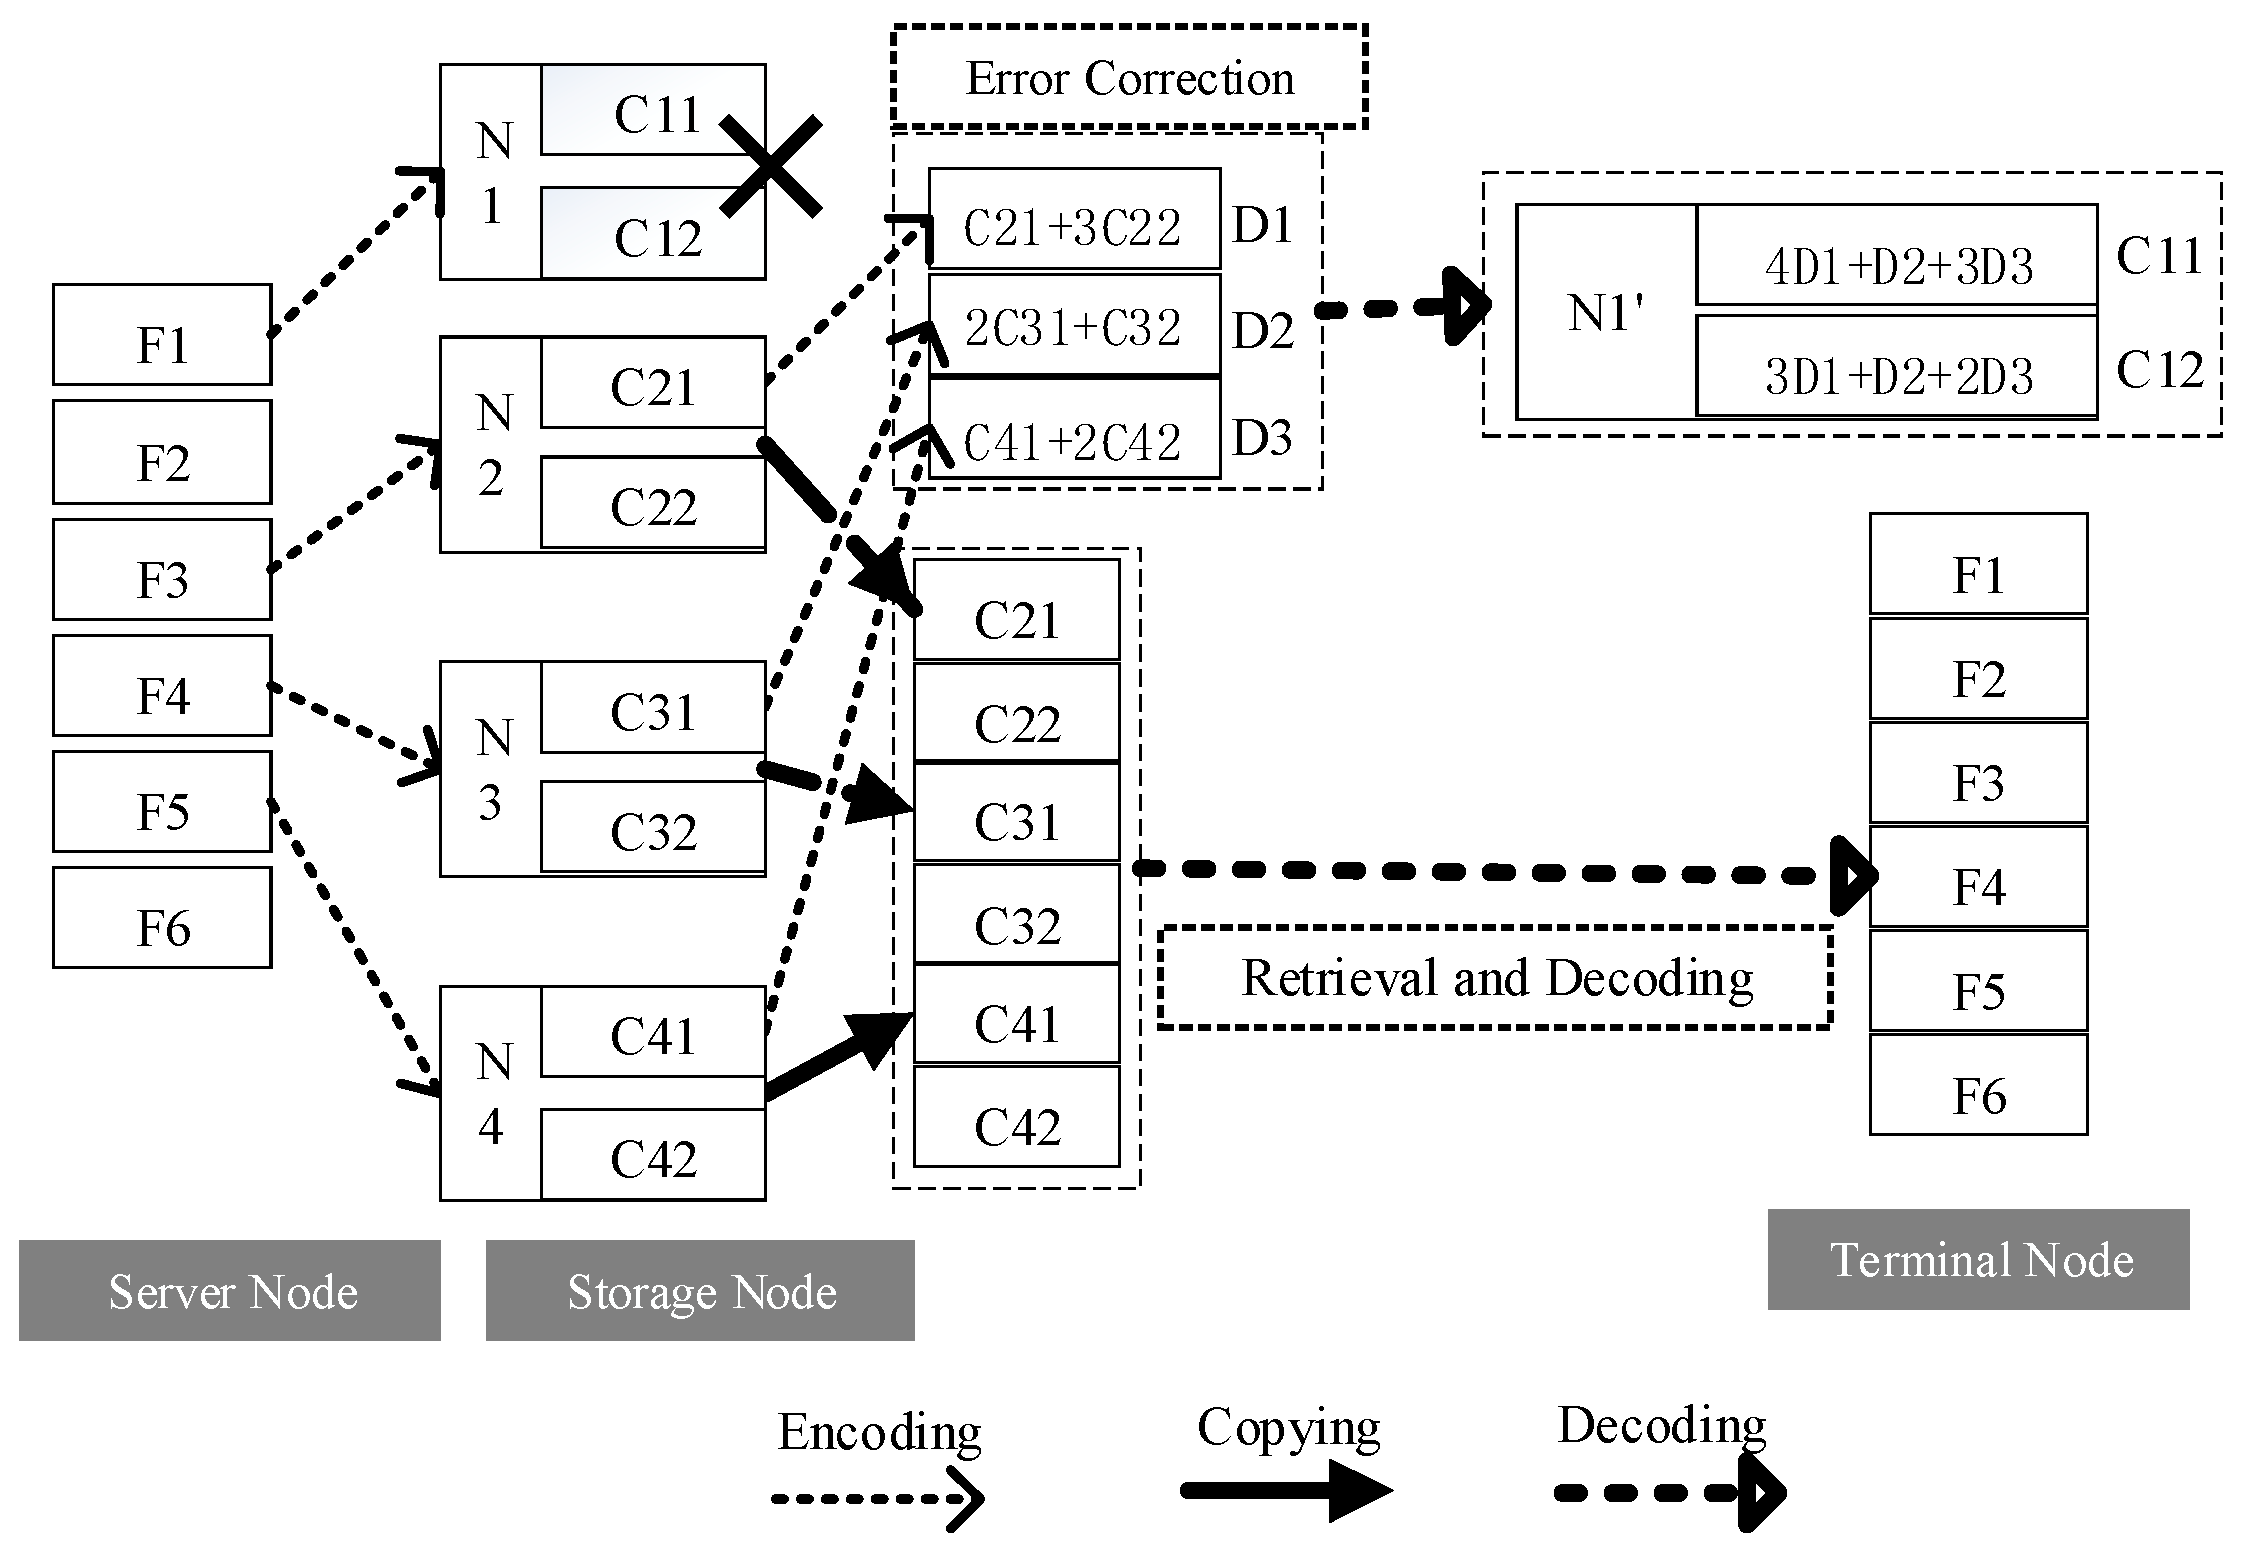
Erasure coding is for encoding the original data file into a data stream (including multiple coded data blocks), and the original data file is obtained after the receiver reconstructs the minimum required number of data blocks they obtained. The loss of encoded data blocks during transmission is independent of each of them. The cloud storage system based on erasure codes is shown in Figure 2 below.
Figure 2.
Cloud storage model based on erasure codes.
For the data file F, the erasure code is performed first, and then the encoded data blocks are distributed to each storage node n, as shown in Figure 2. If one of the four storage nodes fails and does not work, the minimum number of data blocks can be taken from the remaining storage nodes for decoding, thereby obtaining the data file f required by the terminal node. At the same time, the data block on the normal storage node can be encoded to recover the data block on the error node or transfer to other storage nodes.
In order to ensure high availability of data and low consumption of storage space, we need to adjust the redundancy factor when erasing the code. If the redundancy factor is too large, then the storage space will be consumed excessively, and if the redundancy factor is too small, then the availability will be reduced.
The k original data blocks are encoded to generate k + m data blocks, and then the k + m data blocks are stored on multiple storage nodes in the cloud storage system, where m of them are redundant data blocks but have fault tolerance capability and k data blocks have the function of restoring data; that is, for any data block no more than m that is lost, these k data blocks can restore them to the original data. The encoder is implemented through the multiplication operation of the generating matrix (C) and vector group (F). Here, C is a matrix of k + m rows and K columns, and F is a vector group composed of original data blocks of the same size.
The linear operation of the finite field is the core operation of the encoder, and thus constructing the finite field is the first step in the encoding process. Taking the finite field as an example, w is the word length, and the numerical value can be selected according to the size of the data block. Each element in the finite field can be represented as a w-bit binary number. For this, w = 8 is commonly used in storage systems, corresponding to 1 byte of data, and has 256 elements in all. Then, we can construct an irreducible polynomial of a degree w. For example, in , a commonly used polynomial is . Each element in the field is represented by a polynomial with a degree less than w (e.g., w = 8), and the coefficients are either zero or one. For instance, the element 0XFF corresponds to the polynomial , while the element 0X03 corresponds to the polynomial x + 1. When performing element operations, the rules are as follows. Addition is performed by adding the polynomial coefficients of bitwise modulo 2 (XOR operation). Multiplication involves polynomial multiplication followed by reduction modulo for an irreducible polynomial to simplify the result.
For construction of the encoder, a Cauchy matrix [36] is used as the source matrix of the generation matrix. The Cauchy matrix has good properties over the finite fields, ensuring that the generated encoding matrix has maximum reversibility and can efficiently recover the original data during decoding. The specific implementation process is as follows.
3.2.1. Source Matrix (Cauchy Matrix)
The definition of a Cauchy matrix is as follows.
Given two disjoint sets and , the role of and is to generate encoding coefficients in the encoding system, and the element of the Cauchy matrix can be described by Equation (1):
In Equation (1), and are elements in the finite field . During the encoding process, is the ID of storage nodes in the cloud system, and is the ID of the original data blocks, where . The constructed source matrix is shown in Equation (2):
An important property of the Cauchy matrix is that any submatrix is invertible, which makes it highly fault-tolerant in erasure codes.
3.2.2. The Construction of the Generative Matrix
The generative matrix used for encoding and decoding is a matrix constructed based on the Cauchy matrix . The first rows are extracted from the Cauchy matrix to form a identity matrix , which is used to represent the original data block. Then, the last rows of the Cauchy matrix are used as the generation part for redundant data blocks. Finally, the last rows of the identity matrix and the Cauchy matrix are combined to form the generative matrix . The representation of the generative matrix is as follows:
3.2.3. The Encoding Process of the Generative Matrix
Under the action of generative matrices, redundant terms are generated for the original data. Suppose that the file to be stored is , which consists of data blocks of the same size , with the last block being padded if it is not a complete block. After passing through the encoder’s generator matrix , redundant data blocks are generated. Thus, forms a new redundant storage vector group. The encoding process can be represented as matrix multiplication, satisfying Equation (4):
Specifically, each redundant data block can be calculated using Equation (5):
In Equation (5), is the element in row and column of .
When modifying data within a small range, we can take advantage of the properties of the Cauchy matrix to individually mark and calculate the modified data block. Eventually, we can distribute the generated corresponding redundant data blocks and the source data blocks separately to the storage nodes. There is no need to destroy all data blocks, recalculate them, and then redistribute and redeploy them to the storage nodes.
Suppose that we need to modify the data block . The redundant data blocks can be updated through the following steps: ① Calculate the modified data block . ② Calculate new redundant data blocks based on the generated matrix . ③ Finally, distribute and to storage nodes. Through this method, we can efficiently update data blocks in cloud storage without the need to re-encode the entire file.
3.2.4. Data Decoding
Data decoding is the inverse process of data encoding. It is necessary to decode multiple data blocks retrieved from the storage nodes and merge them into the data file that the user needs.
Suppose that some data blocks are lost during transmission. We need to recover the original data from the remaining data blocks. Since any submatrix of the Cauchy matrix is invertible, as long as we receive linearly independent data blocks, we can recover the original data through the decoding matrix (Equation (7)).
Assume that some data blocks are lost during transmission, but we still receive data blocks .These data blocks correspond to certain rows in the generator matrix . We need to extract the corresponding rows from the generator matrix to form a submatrix .
Let the row index corresponding to the received data block be and be the element of row and column of the generation m atrix . Then, submatrix can be expressed as shown in Equation (6):
Since any submatrix of the Cauchy matrix is invertible, submatrix is invertible. We can construct the decoding matrix by calculating the inverse matrix of :
The decoding matrix is a matrix, and its element satisfies Equation (8):
By decoding the matrix , we can recover the original data block from the received data block . The decoding process can be expressed as shown in Equation (9):
Here, is the element of row and column of the decoding matrix , and is the jth received data block. Each raw data block can be calculated using Equation (10):
3.2.5. Verify the Correctness of the Decoding Results
To verify the correctness of the decoding results, we can recompute the redundant data blocks and compare them with the received redundant data blocks to validate the decoding results. When any data in the redundant blocks stored in the cloud change, the relationship between the encoding matrix and the data blocks will no longer hold; that is, Equation (4) will not be valid. Therefore, this method can be used to verify the integrity of the data stored in the cloud. The purpose of verifying the integrity is to ensure that the received data block has not been tampered or lost during transmission, thereby enhancing the security of the storage.
During the data integrity verification process, we need to extract the rows corresponding to the redundant data blocks from the generator matrix to form a submatrix . This submatrix is used to recalculate the redundant data blocks and compare them with the received redundant data blocks to verify the integrity of the data.
For the above generator matrix, the first rows correspond to the original data blocks, while the last rows correspond to the redundant data blocks. The submatrix is represented as shown in Equation (11):
Using submatrix and the recovered original data block , we can recalculate the redundant data block :
When comparing the recalculated redundant data blocks with the received redundant data blocks, if they are consistent, then this indicates that the data are intact. Otherwise, it is suggested that the data have been tampered with or lost. This method ensures the reliability and integrity of the data in the cloud storage system.
3.3. Efficient Retrieval of Data Blocks
In cloud storage systems, after the original data file is encoded, divided into data blocks, and distributed across storage server nodes, retrieving the data file requires searching for the corresponding encoded data blocks among numerous storage service nodes. In traditional simple copy redundancy backup, the search process is relatively straightforward, as locating just one copy is sufficient to fulfill the request. However, under distributed storage redundancy backup using erasure codes, a predetermined number of data blocks must be retrieved to reconstruct the original data file. This imposes high demands on the data block retrieval process.
To efficiently retrieve these data blocks, we adopt the peer-to-peer lookup method of the Kademlia protocol and design a fast resource location method based on the same Kademlia process. In a cloud storage system, through the XOR distance metric and the distributed hash table (DHT) characteristics of the Kademlia method, each cloud storage node maintains a routing table (K-Bucket) to hierarchically manage neighboring nodes according to XOR distance. Data blocks processed by erasure coding are hashed to generate a key and are stored on the node closest to the key. The Kademlia lookup process is completed by iteratively querying the nodes closest to the key, which has high query efficiency and dynamic adaptability. Here are some relevant definitions.
Definition 1.
Data Block Key: Each data block resulting from the erasure coding of a file generates a unique key through the SHA-1 hash function. The generation method of the key is
, where
is the unique identifier of the data file and is the sequence number of the data block after file segmentation and encoding.
Definition 2.
NodeID: Each storage node generates a unique NodeID through a hash function, and the method for generating NodeIDs is
. Here, ”IP” and “port” are the IP address and port number of the node, respectively.
Definition 3.
XOR distance:
The data block is stored on the node closest to
, which is not a physical distance but a logical distance
calculated through the XOR distance. The smaller the XOR result, the shorter the distance.
In cloud storage systems, the network topology is divided into multiple buckets by nodes known as K-Buckets based on their own node IDs. Each K-Bucket contains a set of nodes that are similar to the current node. The criterion for these similar nodes is generally the Hamming distance of the node ID, which is the number of differing bits in the binary strings between the node IDs.
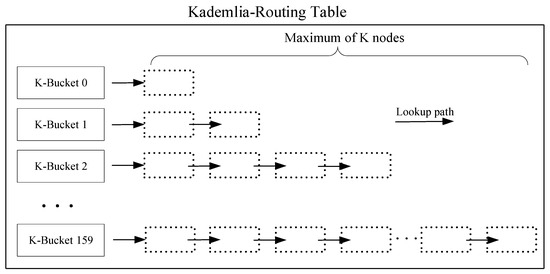
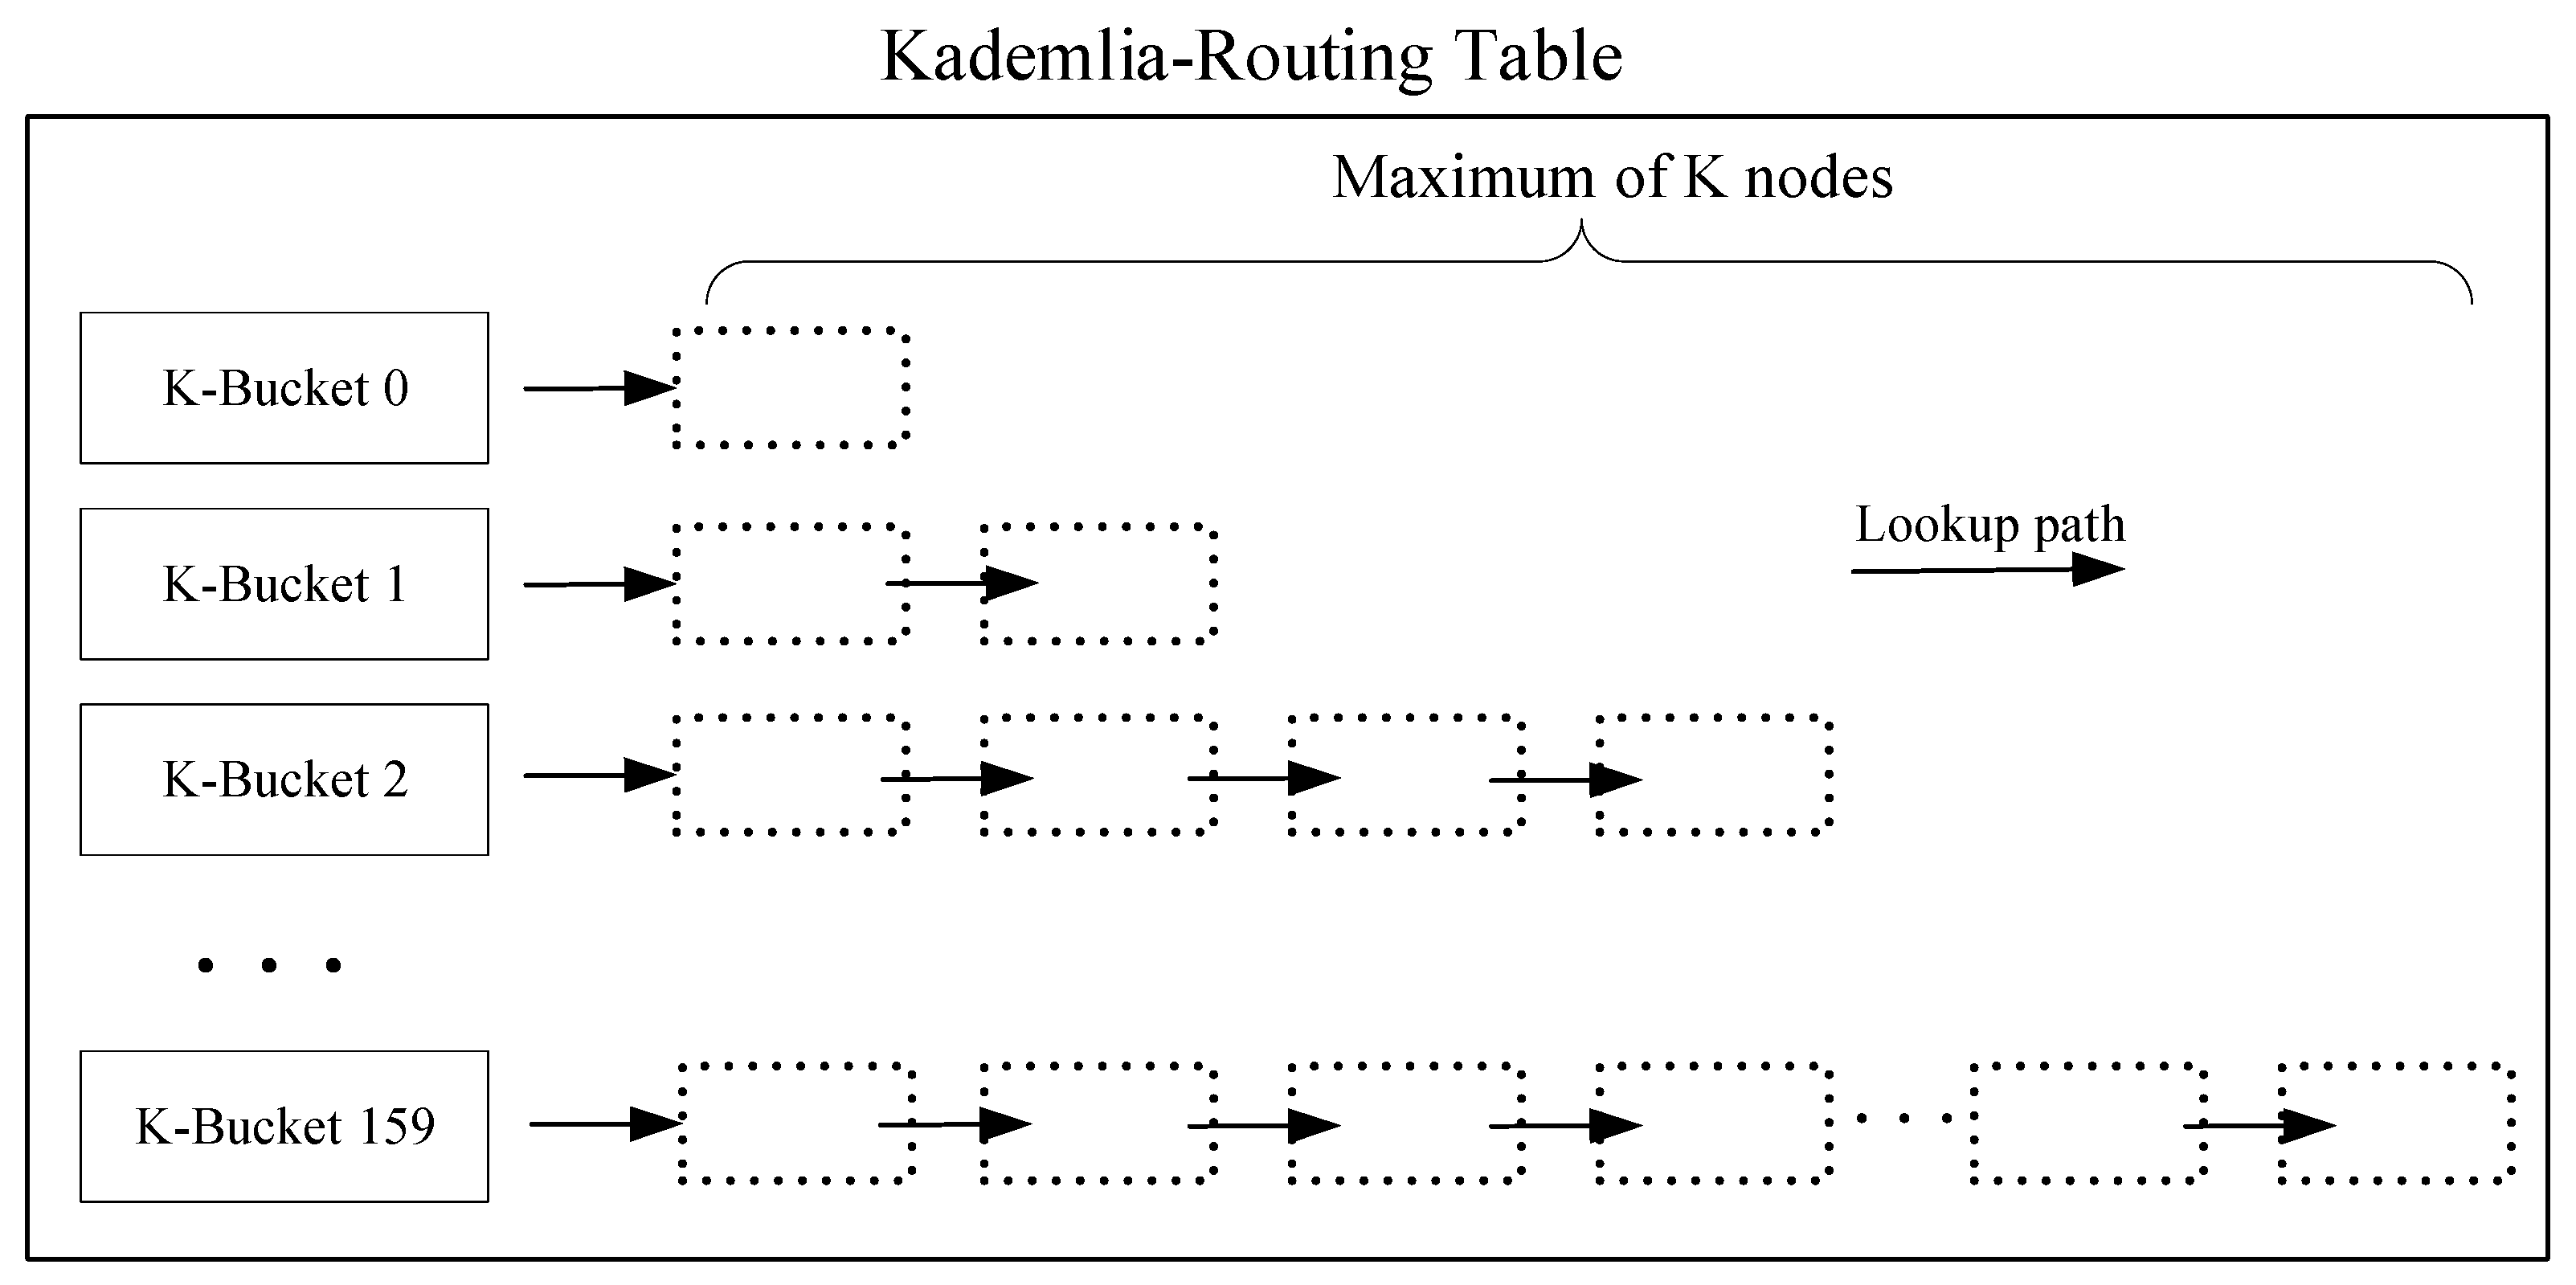
In the Kademlia protocol, the routing table maintained by nodes is hierarchically organized to manage neighboring nodes based on the XOR distance. The structure of the routing table in the Kademlia protocol consists of the number of K-Bucket layers and the number of nodes in each layer.
Regarding the number of K-Buckets, assuming that the node ID is a 160-bit hash space, the K-Buckets are divided into 160 layers, with each layer corresponding to one bit of the node ID.
For the number of nodes per layer in the K-Buckets, each layer maintains up to k nodes (typically k = 20) sorted by XOR distance.
The Kademlia routing table structure is shown in Figure 3. The table records all K-Buckets, with a maximum limit of k nodes per K-Bucket.
Figure 3.
Kademlia routing table structure diagram.
To locate the target node, we first identify the K-Bucket that is nearest or closest to the target node. If the target node is already within that K-Bucket, then it is directly returned. Otherwise, query requests are sent to the nodes within that K-Bucket, which continue to iteratively search for the target. The search process ultimately converges on the target node, from which the encoded data block is retrieved. Finally, the original data file is reconstructed by obtaining the minimum required number of data blocks from the same file.
If a new node is added during the search process, then the new node generates a new NodeID through the hash function. The new node contacts the known node, obtains its K-Bucket information, and updates its own K-Bucket. The new node takes over the data block closest to its NodeID. If a node failure is detected, then the data block responsible for the failed node is taken over by the node closest to its NodeID, and other nodes update their K-Buckets and remove the failed node. As the elasticity of nodes changes, when adding or reducing storage nodes, only nodes to the order of O (1/n) are required to change information.
The resource search and localization algorithm for storing a node’s encoded data blocks is provided in Algorithm 1. First the α (default value of three) nearest nodes from the local K-Bucket are selected, and FIND_NODE requests are sent to these nodes to obtain nodes closer to the target key. The above process is repeated until the target node is found or the maximum hop count is reached, and then the search is exited. From the K-Bucket routing structure and search algorithm, it can be seen that each time the nearest node was found, and the distance between the newly found node and the target data block node was usually reduced by half compared with the original. Usually, the nearest node can be searched up to logN times for successful location, which can accelerate the data block location of storage nodes.
| Algorithm 1. The Kademlia-based erasure code data block search algorithm. |
| Input: file_id, k (the number of raw data blocks), key Output: data_blocks set (at least k data blocks for subsequent decoding and recovery of a file) candidates [0] (the node closest to the key) 1. function find_data_blocks(file_id, k) 2. data_blocks ← empty set 3. for i from 1 to k + m do 4. key ← hash(file_id + i) // Generate data block key 5. node ← find_closest_node(key) // Find the node closest to the key 6. if there exists datablock key in the node then 7. data block← Retrieve data block from the node 8. data_blocks.add(data block) // Add the data block in data_blocks set 9. if data_blocks.size >= k then 10. break 11. end if 12. end for 13. return data_blocks // Used for subsequent merging of data blocks to decode and restore the original file operation 14. end function 15. function find_closest_node(key) 16. candidates ← Select α = 3 nearest nodes from the local K-Bucket 17. contacted ← empty set // Record the nodes that have been contacted to avoid duplicate search 18. while True do 19. selected_nodes ← Select β (β < =α) unconnected nodes from candidates 20. Send FIND_NODE (key) request in parallel to selected_nodes 21. new_nodes ← Collect a list of nodes in the response 22. new_nodes.sort_by_distance_to(key) // Sort new_nodes by XOR value with key 23. contacted.add(selected_nodes) // Mark the nodes that have been contacted 24. candidates ← Merge candidates and new_nodes 25. if all nodes have been contacted or the node storing the key has been found do 26. break 27. end while 28. return candidates [0] // Return the node closest to the key 29. end function |
4. Experiment Evaluation
4.1. Experimental Environment and Parameter Settings
To verify the effectiveness of the proposed cloud storage “EC-Kad” solution, we used three HP ProLiant DL380 Gen10 servers (manufacturer: Hewlett Packard Enterprise; Country: USA; primary production site: Houston, TX, USA), with the specifications including a Xeon 2.1 GHz Intel 16-core CPU, 64 GB DDR4 RAM, 2 TB HDD, and eight 1 Gbps Ethernet NICs, to build a cloud storage platform based on Hadoop. The three servers in the platform serve as three cloud data centers, and we virtualized the physical servers in each data center. One server had 6 virtual machines, while the other two servers had 7 virtual machines each. The cloud storage platform had a total of 20 virtual machines, and our experiment ran on the 64-bit Ubuntu operating system 20.04.2.0 LTS. In addition, the Hadoop version we used in the experiment was 3.3.2. Virtual machines from different data centers were interconnected through a VPN, and virtual machines from the same data center were directly connected to achieve collaborative computing among the virtual machines in the Hadoop clusters.
On the private cloud storage platform built with Hadoop, we implemented the storage solution “EC-Kad” proposed in this paper. The implementation was primarily carried out in the form of cloud tasks submitted to the cloud data center to conduct experiments on the data storage process of cloud storage services. During data storage, our erasure coding module was mainly responsible for encoding and splitting the submitted storage files. Assuming that the size of an original file is M, and the number of erasure-coded chunks for this file is k, then the size of each data chunk is M/k. If the last chunk is not a full block, then it is padded, and m represents the number of redundant data chunks.
The Kademlia data retrieval module first generates a corresponding key for the encoded data blocks using SHA-1. The data are then stored on the node whose ID has the closest XOR distance to the key. The module performs iterative searches to quickly retrieve and merge the data chunks from the virtual nodes and then decodes them. The specific operations are implemented by the virtual machine work nodes assigned by the data center hosts, with all operations scheduled by the master node.
We selected storage files of different sizes for the experiment. The file sizes were 100 MB, 200 MB, 300 MB, 400 MB, 500 MB, and 600 MB.
4.2. Benchmarks
- (1)
- Based on [34], a coding scheme based on the generalized matrix transposition method to construct regenerated codes for secure cloud storage, abbreviated to GMR-RC, was applied.
- (2)
- Based on [35], a coding scheme using KK code and LRMC code, combined with the error check code CRC, abbreviated to NEC-CRC, was applied to achieve reliable network coding.
4.3. Experimental Result Evaluation
Given the limited computational resources, to facilitate calculations and enable effective simulation, in the experiments, we divided all the original files equally into 10 data chunks. Under the condition of having the same number and size of original data chunks, we compared the performance of different network coding schemes. For the storage solution proposed in this paper, we chose the EC (10,3) strategy, which means that the number of original data chunks was 10, and the number of redundant data chunks was 3. The quantity of redundant data chunks here was determined based on empirical experience.
Regarding the performance indicators for comparison, we mainly focused on the encoding latency, decoding latency, recovery success rate under different failure probabilities, and redundancy calculation overhead. The experimental results were obtained through an average of 30 iterations of calculation.
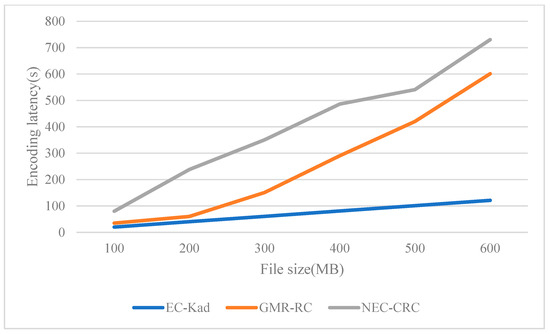
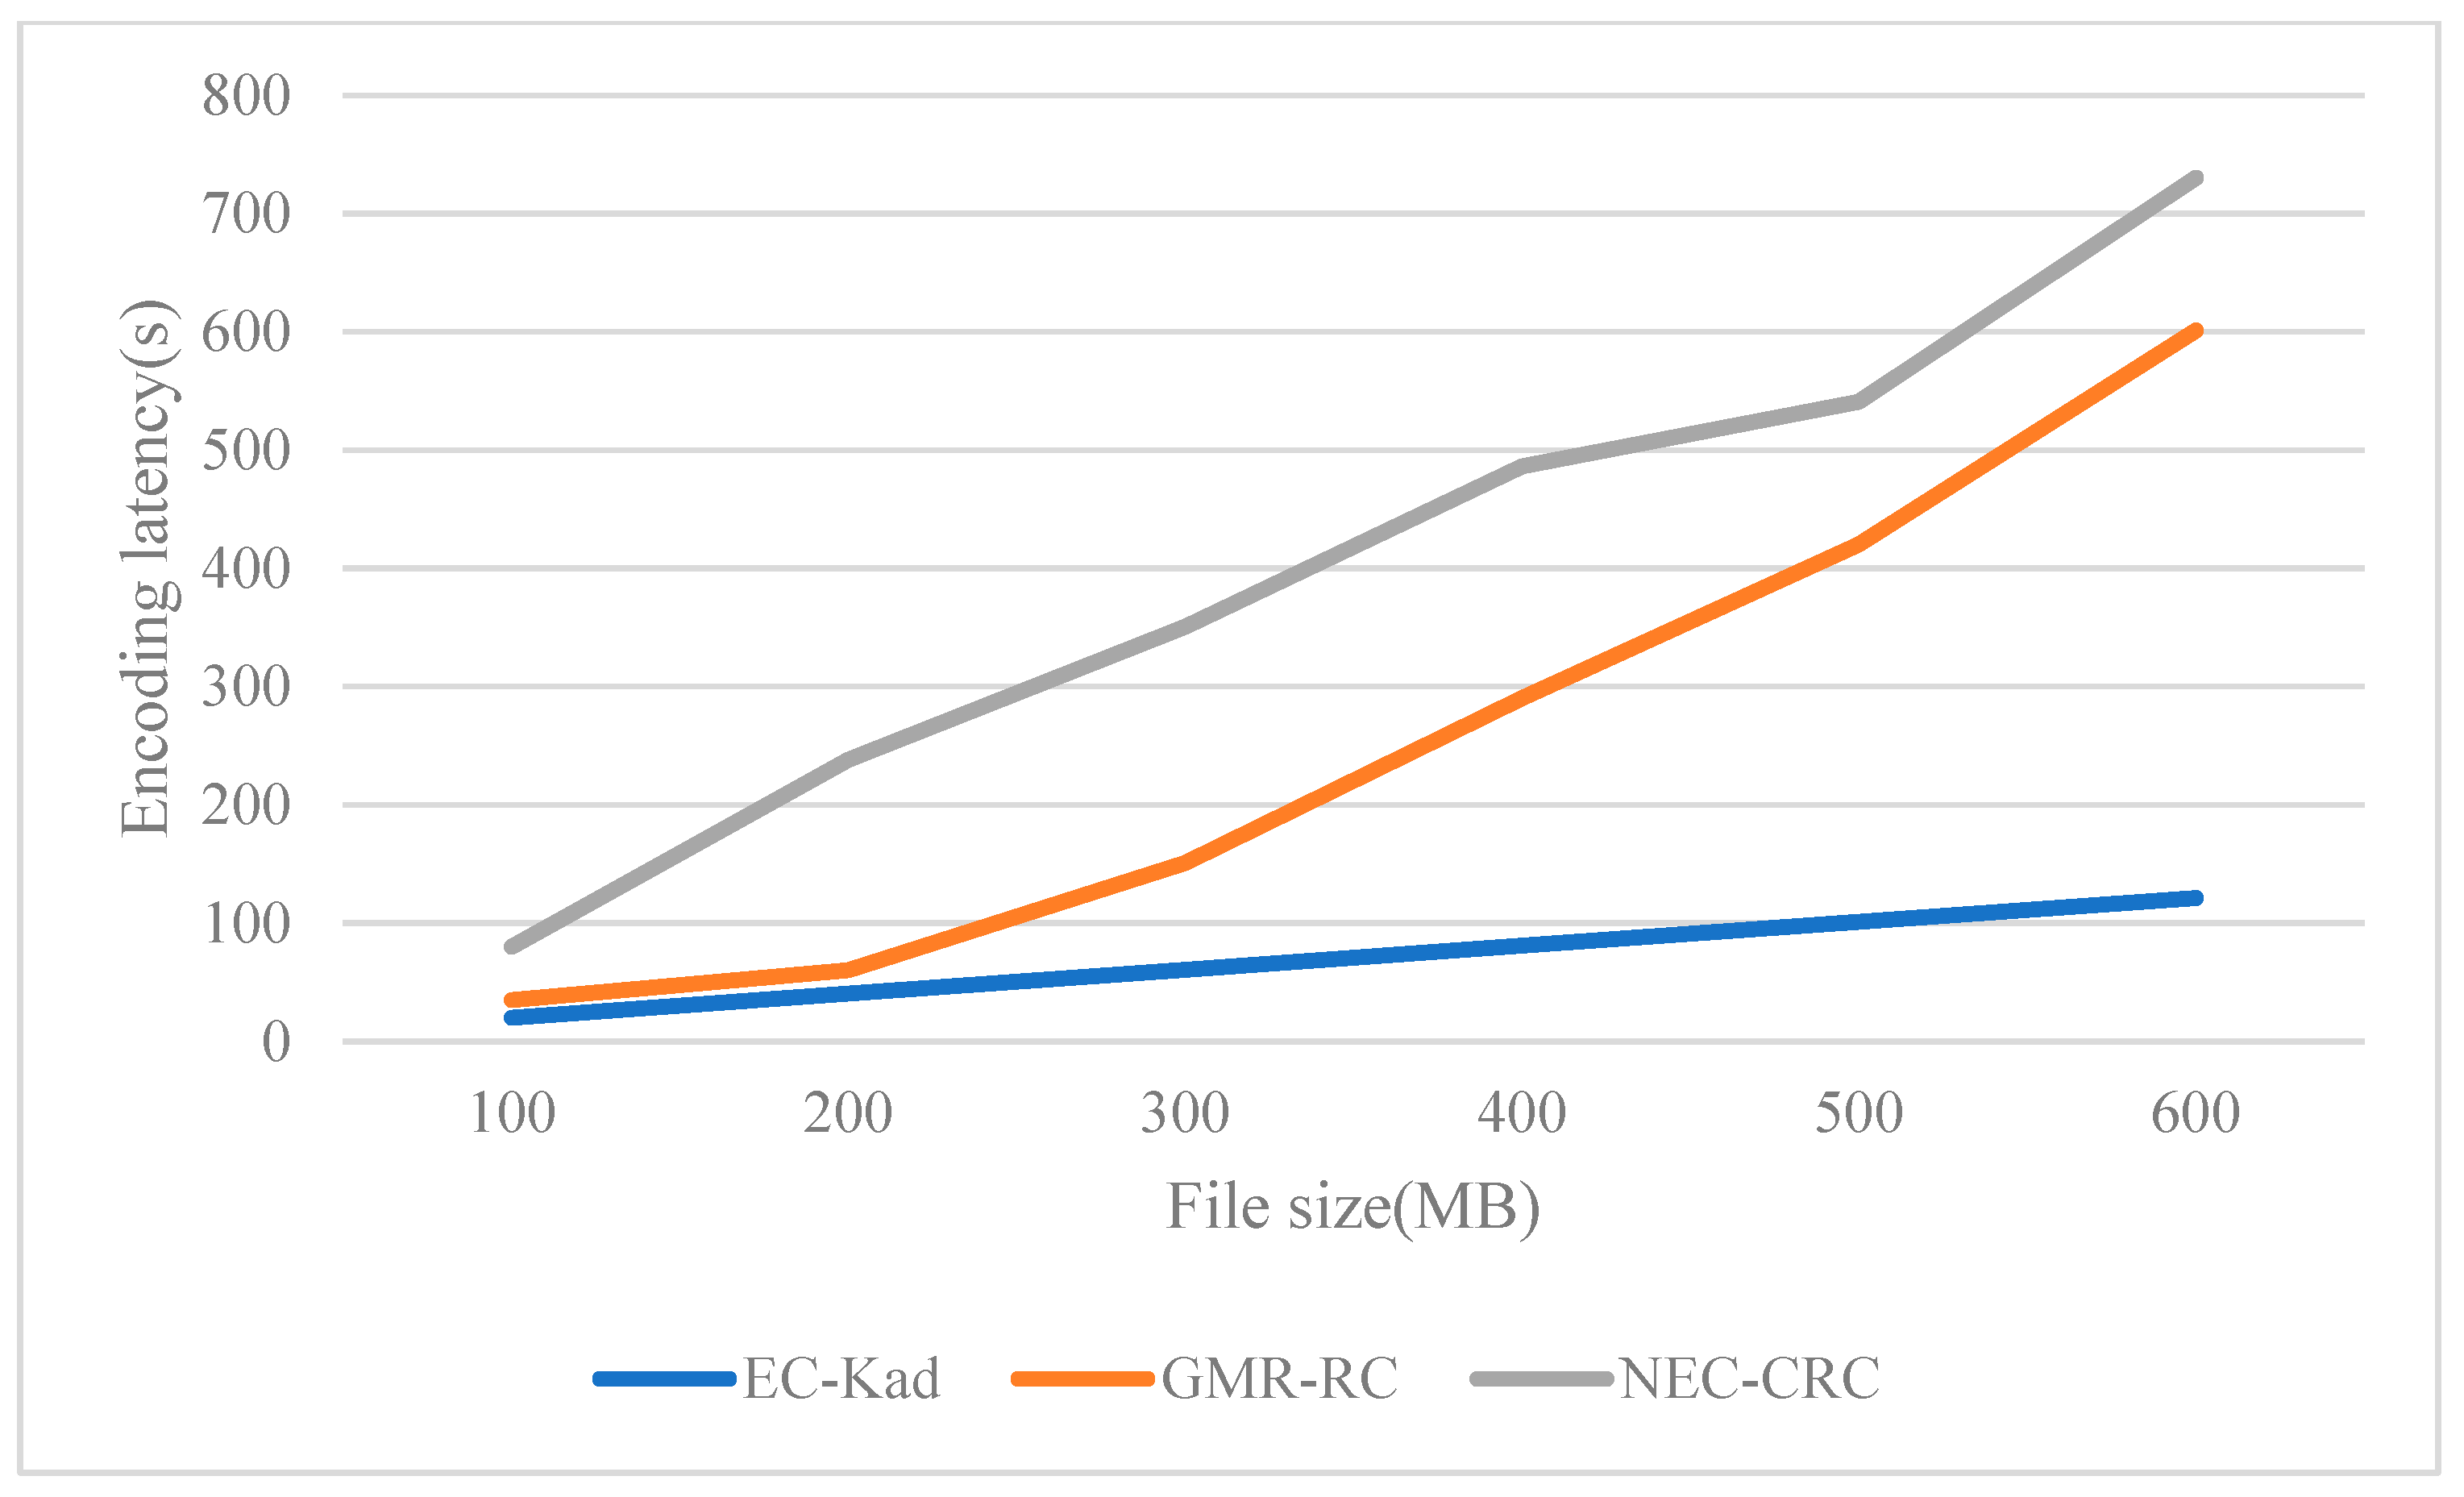
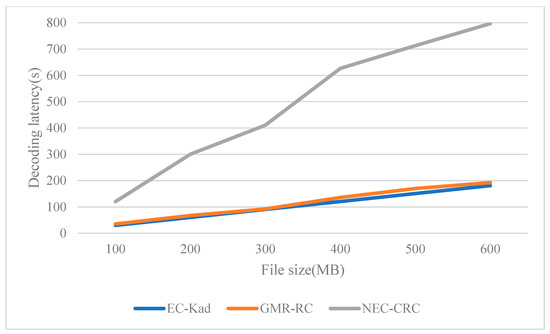
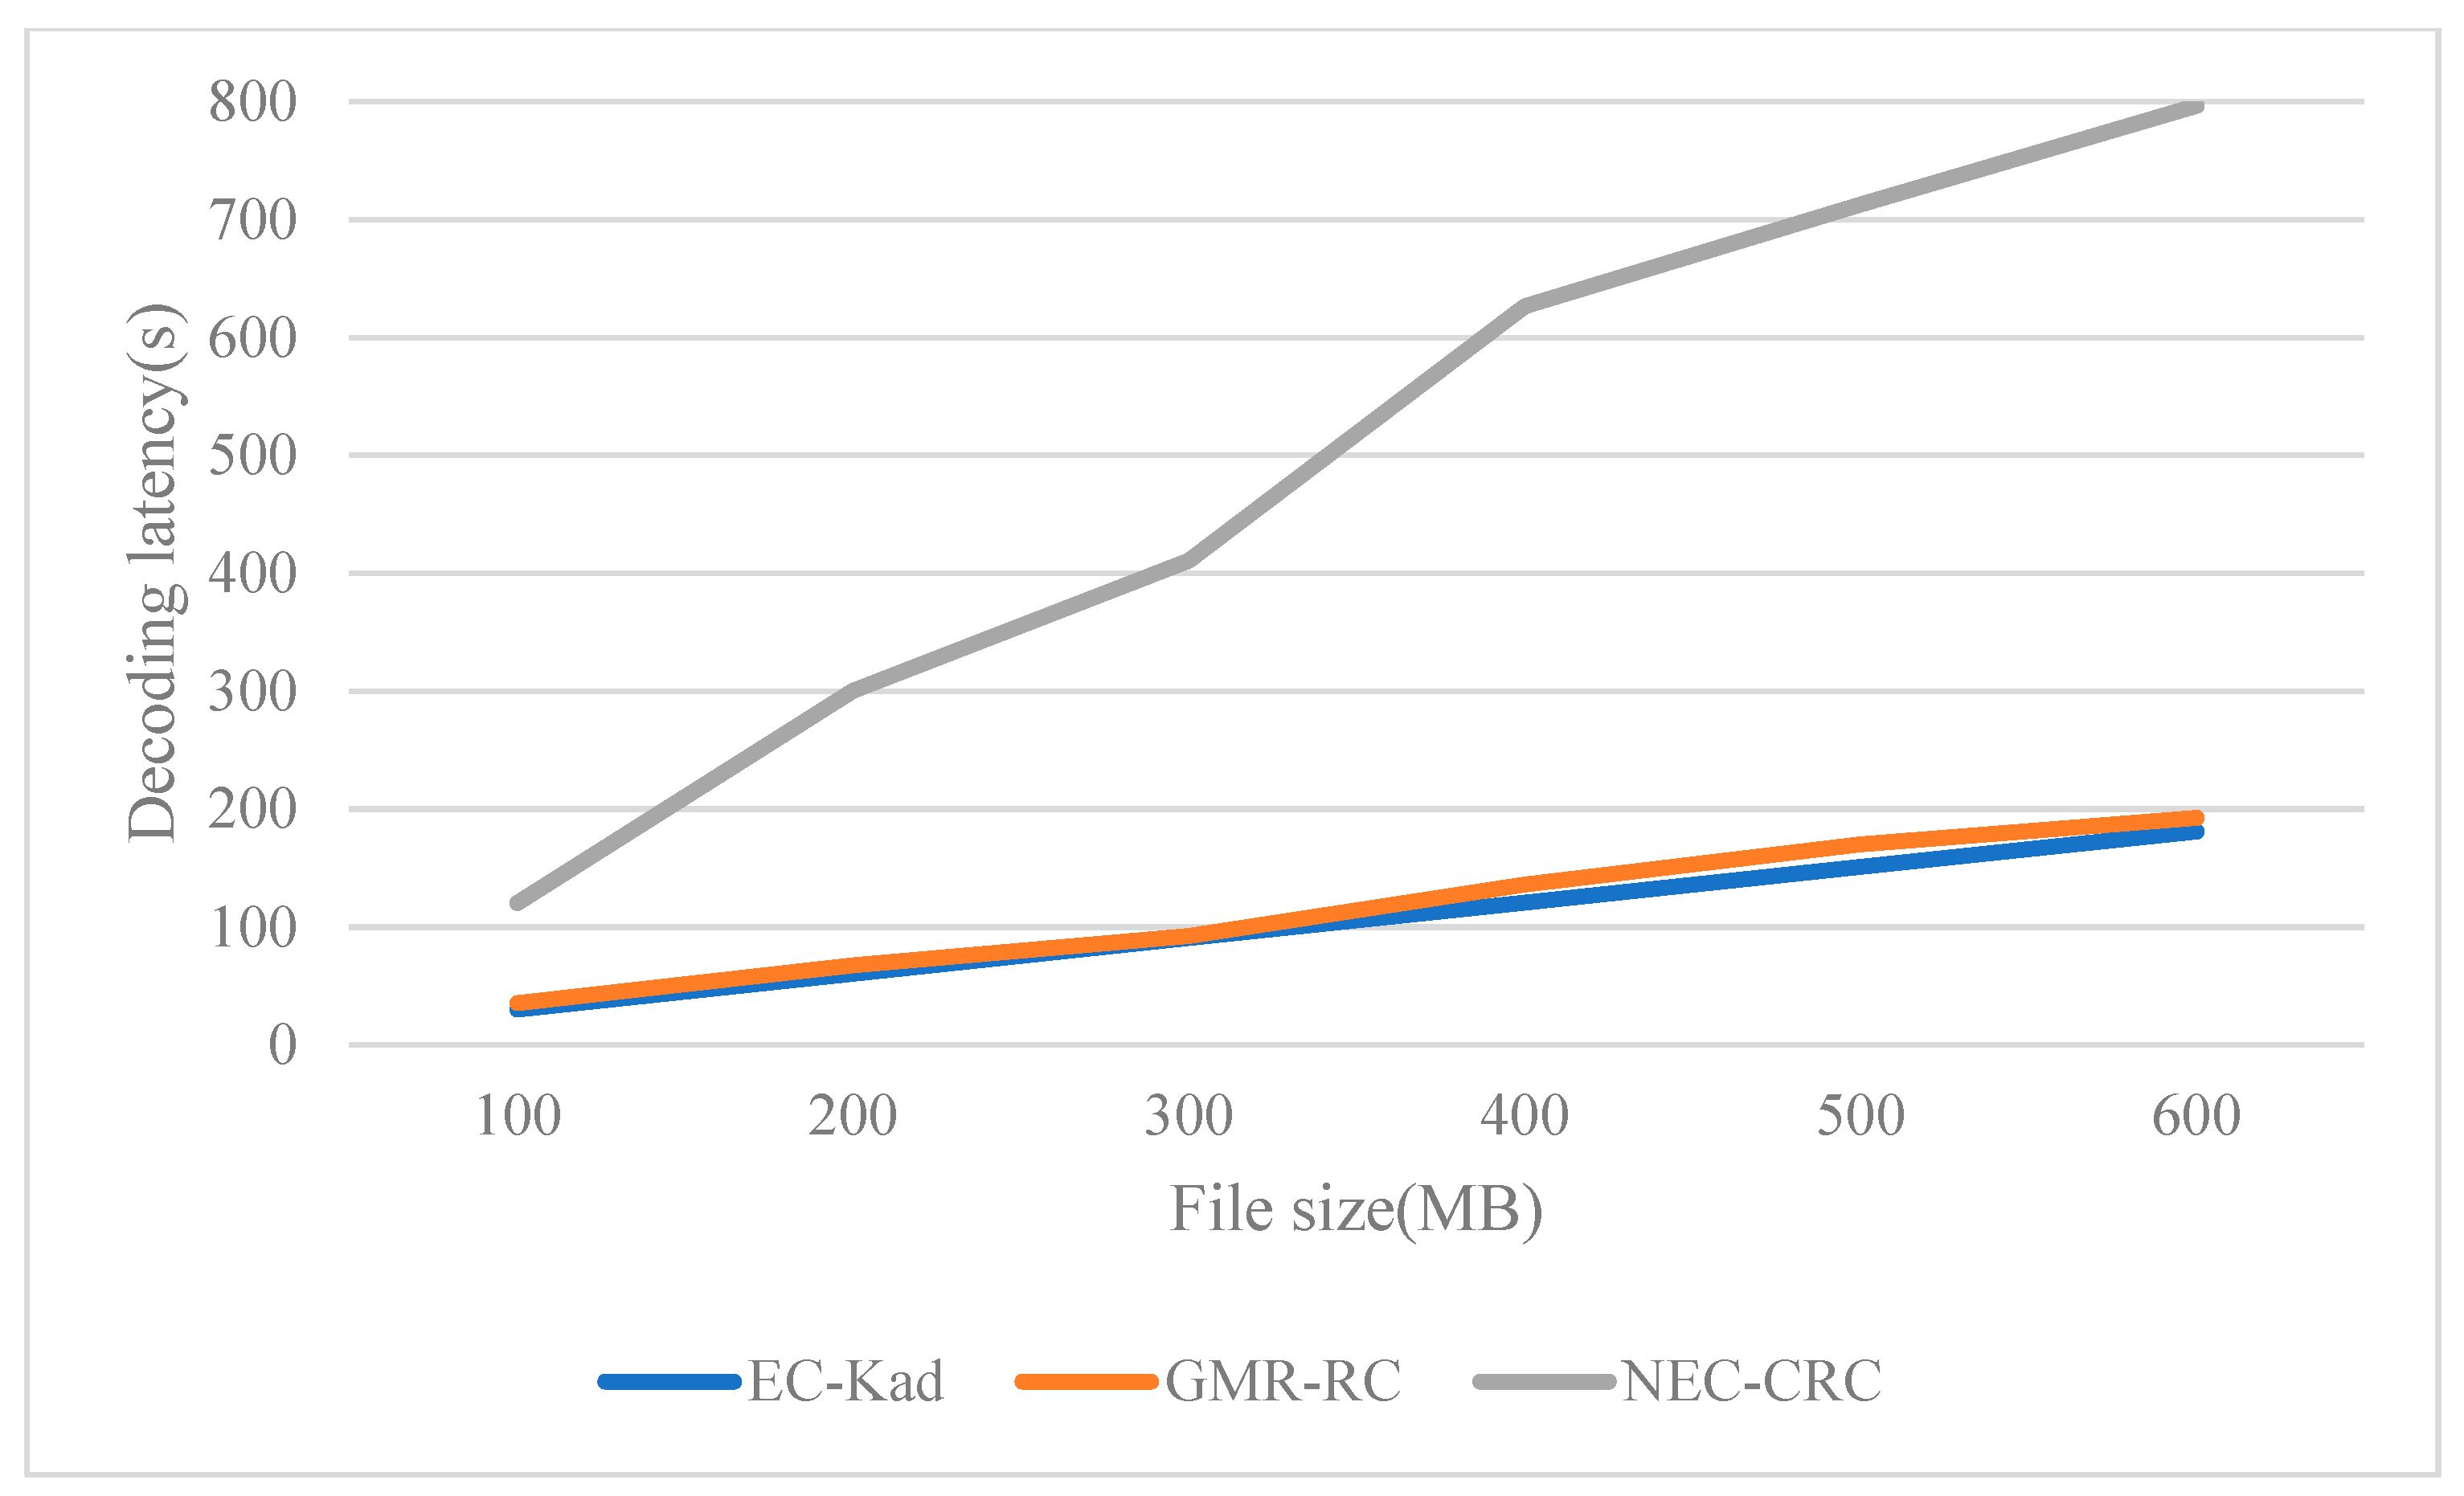
Figure 4 shows a comparison of the encoding and decoding latencies of the compared encoding schemes, with the X axis representing the different sizes of various files used in the experiment and the Y axis representing the encoding latency. Figure 5 shows the decoding latencies of the different encoding schemes being compared.
Figure 4.
Encoding latency.
Figure 5.
Decoding latency.
It can be seen from Figure 4 that the encoding latency of EC-Kad was shorter than those of the benchmarks and increased linearly with the file size. The encoding latency of the GMR-RC scheme was close to linear growth, and when processing small file encoding, there was not much of a difference between the EC-Kad and GMR-RC methods. As the file size increased, the difference widened. The NEC-CRC scheme had large time fluctuations due to the use of random coefficients in the encoding matrix. When encoding a 400 M file, the encoding latency of NEC-CRC was 486.25 s, and that of GMR-RC was 290.26 s. Then, as the file size gradually increased, the difference in the encoding latency between the GMR-RC and NEC-CRC methods decreased, and our solution (EC-Kad) still maintained its advantage.
As can be seen from Figure 5, the decoding latencies of EC-Kad and GMR-RC were comparable, while that of NEC-CRC fluctuated significantly. Decoding involves retrieving the data chunks of a file from the corresponding cloud data center nodes and then merging and decoding them. Our proposed EC-Kad solution employs the Kademlia algorithm to search for data chunks when retrieving them from the cloud, which enhances the efficiency of data chunk retrieval. Moreover, due to the redundancy of the encoding, only the minimum number of data chunks is required to merge and decode the original file, thereby speeding up the decoding process to a certain extent. In GMR-RC, the decoding process has been optimized, and thus its method achieved a decoding latency comparable to our solution. NEC-CRC, on the other hand, incurs random computational overhead. When retrieving data chunks for decoding, it randomly receives a sufficient number of data chunks, which leads to significant fluctuations in the decoding latency.
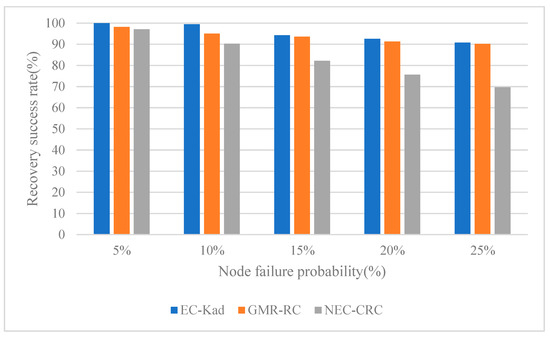
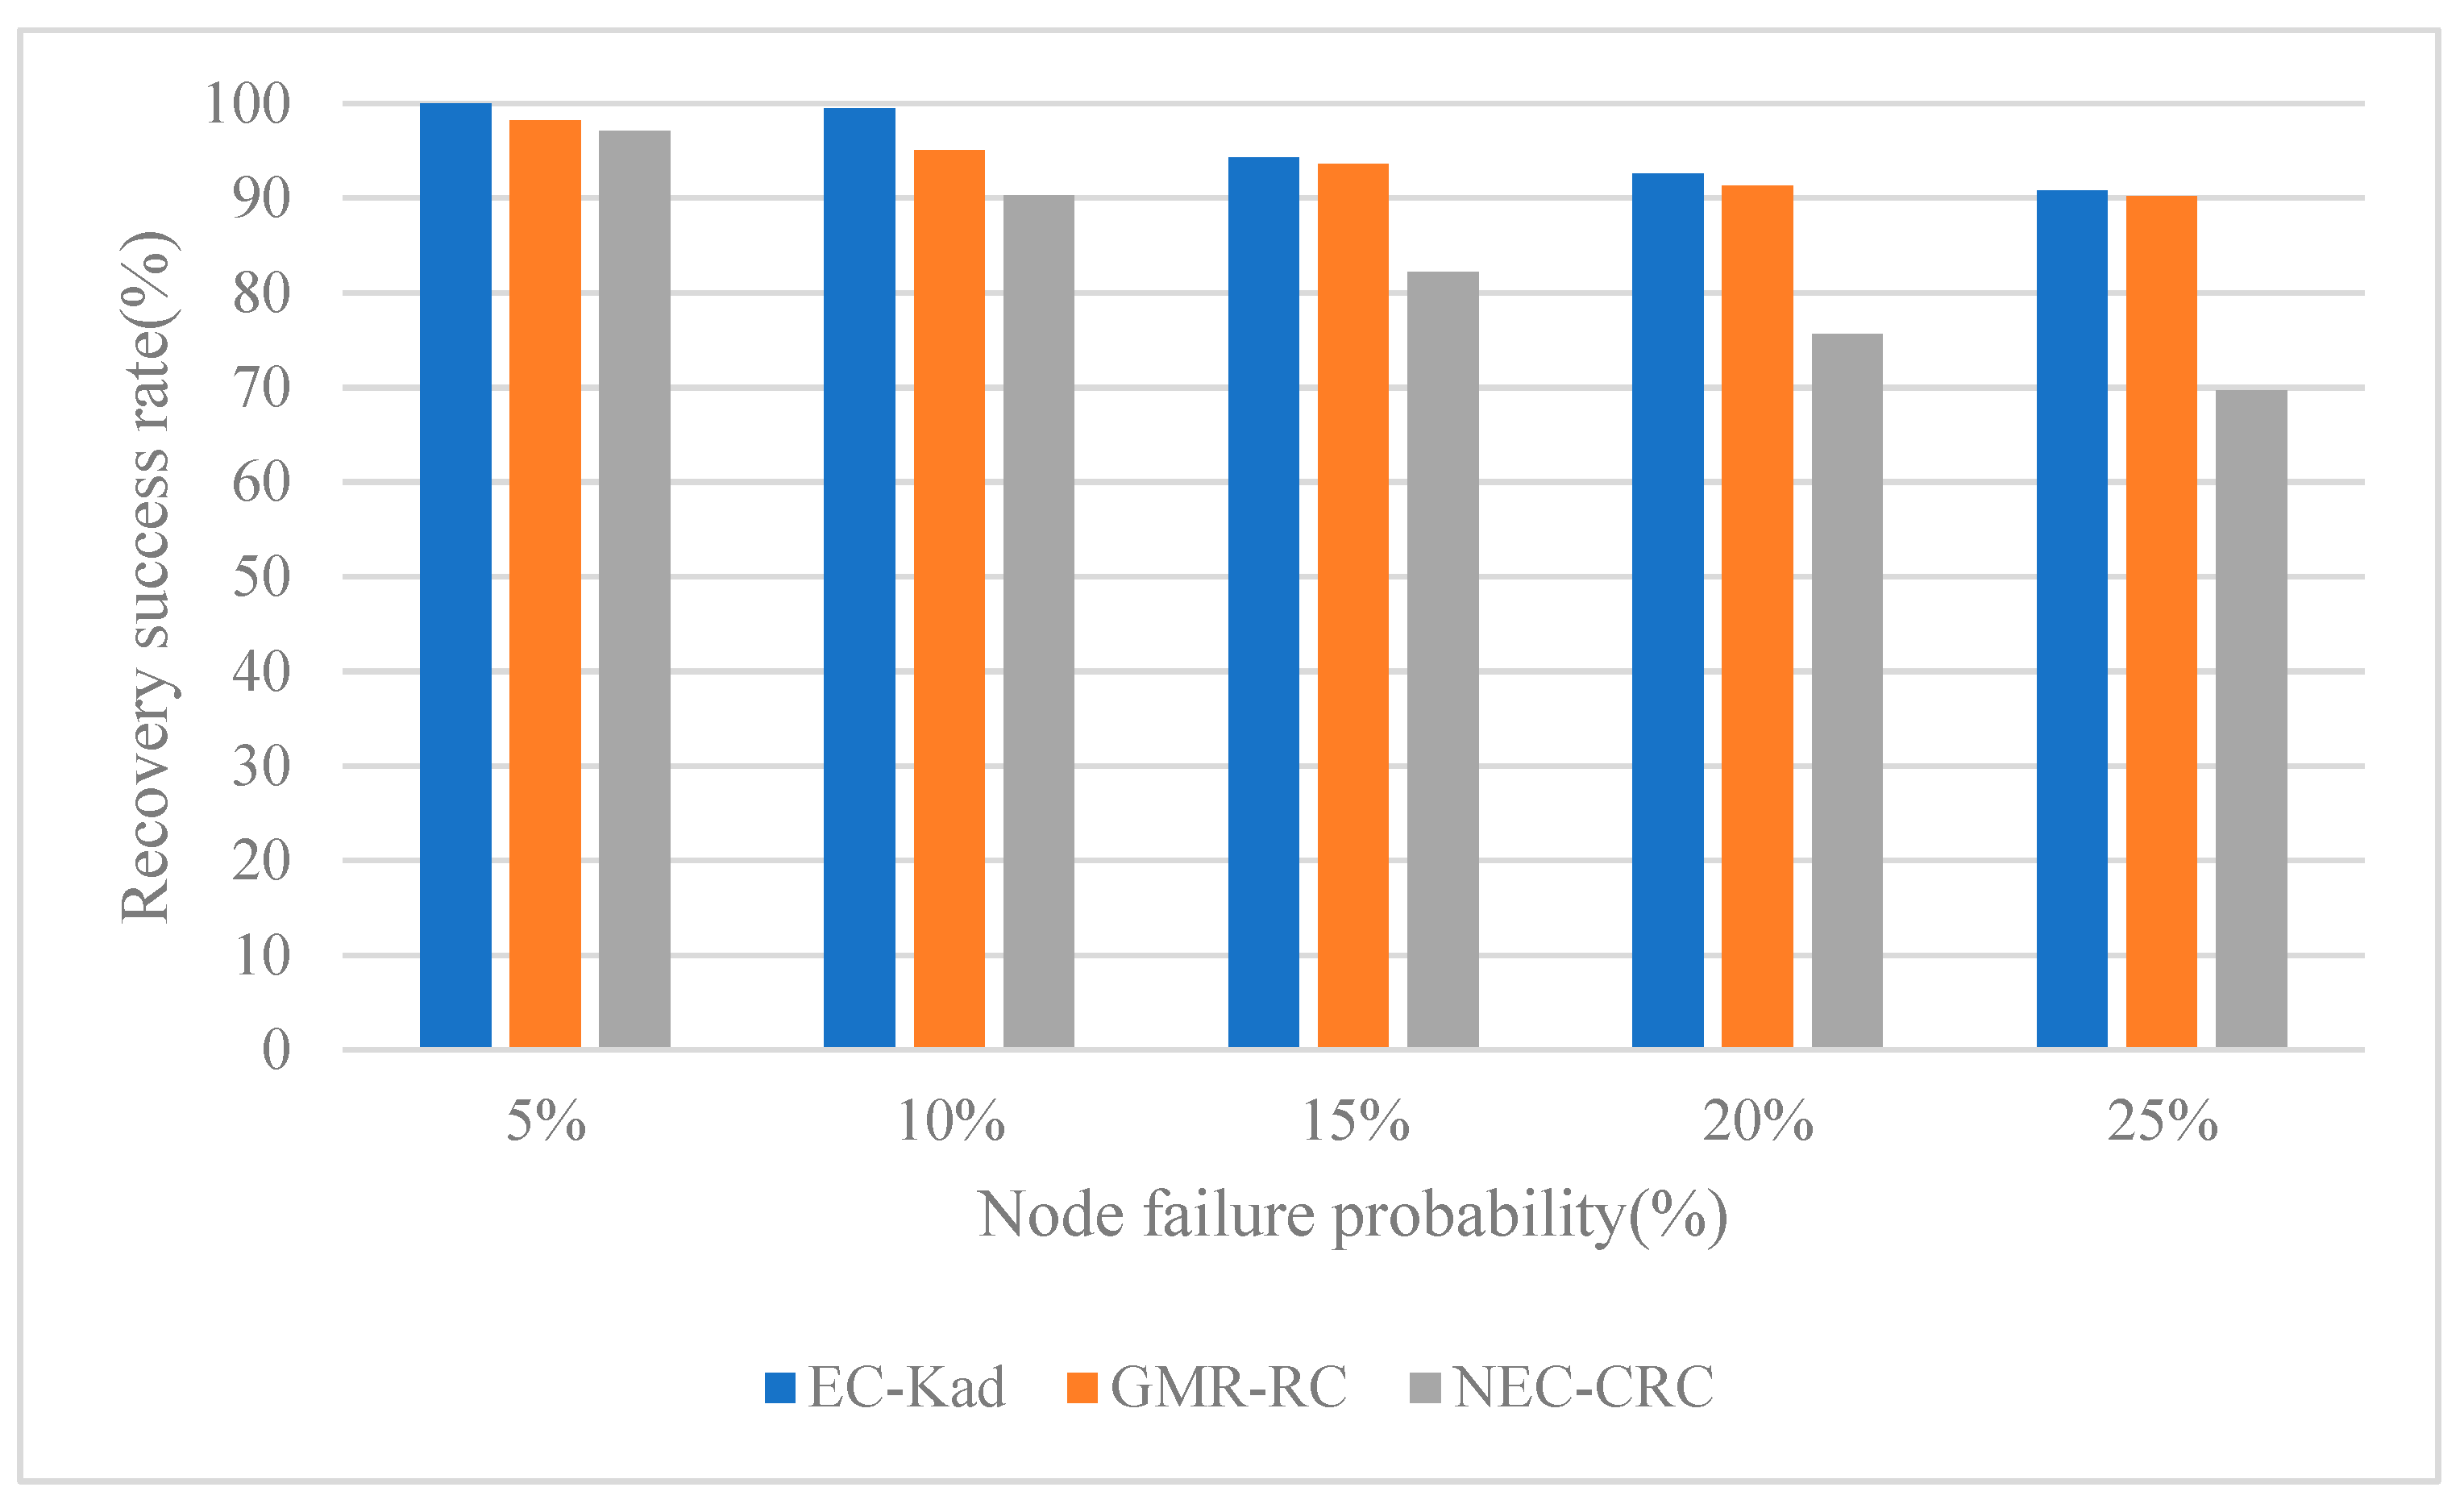
Figure 6 illustrates a comparison of the recovery success rates of the encoding schemes under different fault probabilities. In a Hadoop cluster, we could simulate node failures for virtual machines using a random fault injection method. We evaluated the recovery success rates of various comparative schemes under node failure probabilities of 5%, 10%, 15%, 20%, and 25%. As shown in Figure 6, EC-Kad and GMR-RC had comparable recovery success rates. However, the recovery success rate of NEC-CRC gradually decreased with increasing fault probability values. At a fault probability of 25%, the recovery success rate was only 69.7%. Our EC-Kad scheme demonstrated a higher level of fault tolerance. This is because we used a Cauchy matrix as the coefficient matrix for implementing erasure codes. The Cauchy matrix has good numerical stability, which ensures correctness in data recovery.
Figure 6.
Recovery success rate.
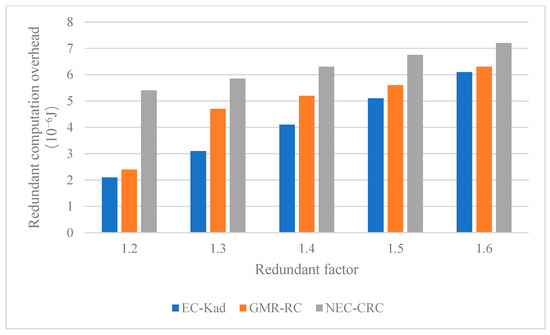
Figure 7 shows the comparison of the redundant computation overhead values for different redundancy encoding schemes when processing a 100 MB data file with 10 chunks under various redundant factors. When the redundant factor was 1.2, the redundant computation overhead values of our EC-Kad scheme and GMR-RC were 2.1 × 10⁻⁶ J and 2.4 × 10⁻⁶ J, respectively. As the redundant factor increased, the gap in redundant computation overhead between these two schemes gradually narrowed. When the redundant factor reached 1.6, the redundant computation overhead values of the two schemes were almost the same. Overall, our EC-Kad scheme outperformed the other comparative schemes. This is because our EC-Kad scheme uses a Cauchy matrix to implement erasure codes, which can reduce the computational complexity in the encoding and decoding processes, thereby significantly decreasing the redundant computation overhead. In contrast, NEC-CRC had the highest redundant computation overhead among all comparative schemes. This is because the NEC-CRC scheme needs to generate more encoding vectors during the encoding process, resulting in a higher redundant computation overhead.
Figure 7.
Redundant computation overhead.
5. Conclusions
This paper proposed an efficient cloud storage data redundancy scheme based on erasure codes and studied the data redundancy optimization of a cloud storage system composed of a cloud storage server, computing server and terminal node. The original data file was erased at the server node, and the encoded data block was distributed to each storage node and finally retrieved and decoded at the terminal node and restored to the data file required by the user. The distributed storage Kademlia algorithm was used to improve the efficiency of uploading and storage retrieval between the terminal nodes and cloud storage platform. This scheme ensures the reliability of users’ cloud data while reducing the redundant computation overhead of cloud storage data and improves the success rate of data recovery to a certain extent when the storage node fails and becomes unavailable. In future work, we will focus on the following aspects to improve our cloud storage solution. (1) Cross-data-center synchronization and load balancing in multi-tenant environments: We plan to introduce a dynamic load-balancing mechanism in the future to dynamically adjust data storage and access policies. We will also investigate optimization strategies for cross-data center data synchronization. (2) Applicability in edge computing scenarios: We plan to study the integration of our storage solution with edge computing architectures to achieve local data caching and preliminary processing. We will also explore how to leverage the computational capabilities of edge nodes to optimize the data encoding and decoding processes. (3) Adaptive redundancy factor adjustment strategy: Finally, we plan to design an adaptive redundancy factor adjustment algorithm based on data access frequency in the future to ensure the effectiveness of the solution in different scenarios.
Author Contributions
Methodology, M.C. and Y.W.; software, M.C.; validation and experiment, M.C. and Y.W.; writing, M.C.; writing—review and editing, M.C. and Y.W. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
The data used to support the research are available from the corresponding author upon request reasonably.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Agarwal, A.; Khari, M.; Singh, R. Detection of DDOS attack using deep learning model in cloud storage application. Wirel. Pers. Commun. 2022, 127, 419–439. [Google Scholar] [CrossRef] [Scilit]
- Ren, Y.; Leng, Y.; Qi, J.; Sharma, P.K.; Wang, J.; Almakhadmeh, Z.; Tolba, A. Multiple cloud storage mechanism based on blockchain in smart homes. Future Gener. Comput. Syst. 2021, 115, 304–313. [Google Scholar] [CrossRef] [Scilit]
- Mohiyuddin, A.; Javed, A.R.; Chakraborty, C.; Rizwan, M.; Shabbir, M.; Nebhen, J. Secure cloud storage for medical IoT data using adaptive neuro-fuzzy inference system. Int. J. Fuzzy Syst. 2022, 24, 1203–1215. [Google Scholar] [CrossRef] [Scilit]
- Prajapati, P.; Shah, P. A review on secure data deduplication: Cloud storage security issue. J. King Saud Univ.-Comput. Inf. Sci. 2022, 34, 3996–4007. [Google Scholar] [CrossRef] [Scilit]
- Parameswaran, M.; Savita; Kannagi, A.; Panwar, R. Evaluation of Different Network Coding Algorithm Strategies for Wireless Systems. In Proceedings of the 5th International Conference on Data Science, Machine Learning and Applications, Hyderabad, India, 15–16 December 2023; Springer Nature: Singapore, 2023; pp. 99–104. [Google Scholar]
- Ali, M.M.; Hashim, S.J.; Chaudhary, M.A.; Ferré, G.; Rokhani, F.Z.; Ahmad, Z. A reviewing approach to analyze the advancements of error detection and correction codes in channel coding with emphasis on LPWAN and IoT systems. IEEE Access 2023, 11, 127077–127097. [Google Scholar] [CrossRef] [Scilit]
- Rajan, V.A.; Marimuthu, T.; Londhe, G.V.; Logeshwaran, J. A Comprehensive analysis of Network Coding for Efficient Wireless Network Communication. In Proceedings of the 2023 IEEE 2nd International Conference on Industrial Electronics: Developments & Applications (ICIDeA), Imphal, India, 29–30 September 2023; IEEE: Piscataway, NJ, USA, 2023; pp. 204–210. [Google Scholar]
- Shi, L.; Cai, K.; Yang, T.; Li, J. Linear network coded wireless caching in cloud radio access network. IEEE Trans. Commun. 2020, 69, 701–715. [Google Scholar] [CrossRef] [Scilit]
- Fu, Q.; Wang, B.; Li, R.; Yang, P. Construction of Singleton-type optimal LRCs from existing LRCs and Near-MDS codes. IEICE Trans. Fundam. Electron. Commun. Comput. Sci. 2023, 106, 1051–1056. [Google Scholar] [CrossRef] [Scilit]
- Wang, J.; Luo, Y.; Shum, K.W. Storage and repair bandwidth tradeoff for heterogeneous cluster distributed storage systems. Sci. China Inf. Sci. 2020, 63, 1–15. [Google Scholar] [CrossRef] [Scilit]
- Kim, J.J. Erasure-coding-based storage and recovery for distributed exascale storage systems. Appl. Sci. 2021, 11, 3298. [Google Scholar] [CrossRef] [Scilit]
- Shen, Z.; Cai, Y.; Cheng, K.; Lee, P.P.; Li, X.; Hu, Y.; Shu, J. A Survey of the Past, Present, and Future of Erasure Coding for Storage Systems. ACM Trans. Storage 2025, 21, 1–39. [Google Scholar] [CrossRef] [Scilit]
- Monteiro, J.; Costa, P.A.; Leitao, J.; De la Rocha, A.; Psaras, Y. Enriching kademlia by partitioning. In Proceedings of the 2022 IEEE 42nd International Conference on Distributed Computing Systems Workshops (ICDCSW), Bologna, Italy, 10–13 July 2022; IEEE: Piscataway, NJ, USA, 2022; pp. 33–38. [Google Scholar]
- Arslan, S.S.; Peng, J.; Goker, T. TALICS3: Tape library cloud storage system simulator. Simul. Model. Pract. Theory 2024, 134, 102947. [Google Scholar] [CrossRef] [Scilit]
- Bhushan, B. Current status and outlook of magnetic data storage devices. Microsyst. Technol. 2023, 29, 1529–1546. [Google Scholar] [CrossRef] [Scilit]
- Ebermann, P.; Cherubini, G.; Furrer, S.; Lantz, M.A.; Pantazi, A. Track-following system optimization for future magnetic tape data storage. Mechatronics 2021, 80, 102662. [Google Scholar] [CrossRef] [Scilit]
- Kim, J.; Yu, H.-J.; Kang, H.; Shin, J.H.; Jeong, H.; Noh, S.Y. Performance Analysis of Distributed File System Based on RAID Storage for Tapeless Storage. IEEE Access 2023, 11, 116153–116168. [Google Scholar] [CrossRef] [Scilit]
- Alzahrani, A.; Alyas, T.; Alissa, K.; Abbas, Q.; Alsaawy, Y.; Tabassum, N. Hybrid Approach for Improving the Performance of Data Reliability in Cloud Storage Management. Sensors 2022, 22, 5966. [Google Scholar] [CrossRef] [Scilit]
- Liu, J.R.; Wang, T.Y.; Chen, X.W.; Li, C.; Shen, Z.; Zhang, Z. H2-RAID: Improving the reliability of SSD RAID with unified SSD and HDD hybrid architecture. Microprocess. Microsyst. 2024, 105, 104993. [Google Scholar] [CrossRef] [Scilit]
- Hong, D.; Ha, K.; Ko, M.; Chun, M.; Kim, Y.; Lee, S.; Kim, J. Reparo: A Fast RAID Recovery Scheme for Ultra-large SSDs. ACM Trans. Storage 2021, 17, 1–24. [Google Scholar] [CrossRef] [Scilit]
- Lin, H.D.; Luo, J.H.; Li, J.; Sha, Z.; Cai, Z.; Shi, Y.; Liao, J. Fast Online Reconstruction for SSD-Based RAID-5 Storage Systems. IEEE Trans. Comput.-Aided Des. Integr. Circuits Syst. 2024, 43, 1886–1899. [Google Scholar] [CrossRef] [Scilit]
- Li, Q.; Lyu, M.; Xu, L.; Xu, Y. Fast recovery for large disk enclosures based on RAID2. 0: Algorithms and evaluation. J. Parallel Distrib. Comput. 2024, 188, 104854. [Google Scholar] [CrossRef] [Scilit]
- Li, X.P.; Qin, S.; Liu, K.L.; Li, Y. Reliability modeling and optimization of K/N phased mission system with backup missions and global redundancy strategy. Qual. Reliab. Eng. Int. 2024, 40, 1061–1078. [Google Scholar] [CrossRef] [Scilit]
- Muthumari, A.; Banumathi, J.; Rajasekaran, S.; Vijayakarthik, P.; Shankar, K.; Pustokhina, I.V.; Pustokhin, D.A. High Security for De-Duplicated Big Data Using Optimal SIMON Cipher. CMC-Comput. Mater. Contin. 2021, 67, 1863–1879. [Google Scholar] [CrossRef] [Scilit]
- Jackowski, A.; Ślusarczyk, Ł.; Lichota, K.; Wełnicki, M.; Wijata, R.; Kielar, M.; Kopeć, T.; Dubnicki, C.; Iwanicki, K. ObjDedup: High-Throughput Object Storage Layer for Backup Systems With Block-Level Deduplication. IEEE Trans. Parallel Distrib. Syst. 2023, 34, 2180–2197. [Google Scholar] [CrossRef] [Scilit]
- Li, Z.H.; Chen, G.; Deng, Y.D. Duplicacy: A New Generation of Cloud Backup Tool Based on Lock-Free Deduplication. IEEE Trans. Cloud Comput. 2022, 10, 2508–2520. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.; Zhu, T.; Li, C. Efficient Communications in V2V Networks with Two-Way Lanes Based on Random Linear Network Coding. Entropy 2023, 25, 1454. [Google Scholar] [CrossRef] [Scilit]
- Zhu, F.M.; Zhang, C.; Zheng, Z.X.; Farouk, A. Practical Network Coding Technologies and Softwarization in Wireless Networks. IEEE Int. Things J. 2021, 8, 5211–5218. [Google Scholar] [CrossRef] [Scilit]
- Zhang, G.Z.; Zhang, D.Q.; Li, W.K. A Network Coding Scheme Transmitting Specific Data and Universal Data Based on Deep Learning. IEEE Syst. J. 2024, 18, 872–880. [Google Scholar] [CrossRef] [Scilit]
- Li, J.; Li, B.C. Demand-Aware Erasure Coding for Distributed Storage Systems. IEEE Trans. Cloud Comput. 2021, 9, 532–545. [Google Scholar] [CrossRef] [Scilit]
- Liu, K.; Peng, J.; Wang, J.; Huang, Z.; Pan, J. Adaptive and scalable caching with erasure codes in distributed cloud-edge storage systems. IEEE Trans. Cloud Comput. 2022, 11, 1840–1853. [Google Scholar] [CrossRef] [Scilit]
- Noor, J.; Upoma, R.I.; Sakif, M.S.I.; Al Islam, A.A. Towards benchmarking erasure coding schemes in object storage system: A systematic review. Future Gener. Comput. Syst. 2024, 163, 107522. [Google Scholar] [CrossRef] [Scilit]
- Nachiappan, R.; Calheiros, R.N.; Matawie, K.M.; Javadi, B. Optimized proactive recovery in erasure-coded cloud storage systems. IEEE Access 2023, 11, 38226–38239. [Google Scholar] [CrossRef] [Scilit]
- Zhang, F.; Xu, J.; Yang, G. Design of Regenerating Code Based on Security Level in Cloud Storage System. Electronics 2023, 12, 2423. [Google Scholar] [CrossRef] [Scilit]
- Guefrachi, A.; Nighaoui, S.; Zaibi, S.; Bouallegue, A. Performance Improvement of Kötter and Kschischang Codes and Lifted Rank Metric Codes in Random Linear Network Coding. Mob. Netw. Appl. 2023, 28, 168–177. [Google Scholar] [CrossRef] [Scilit]
- Mohsenifar, N.; Sajadieh, M. Introducing a new connection between the entries of MDS matrices constructed by generalized Cauchy matrices in GF (2 q). J. Appl. Math. Comput. 2023, 69, 3871–3891. [Google Scholar] [CrossRef] [Scilit]
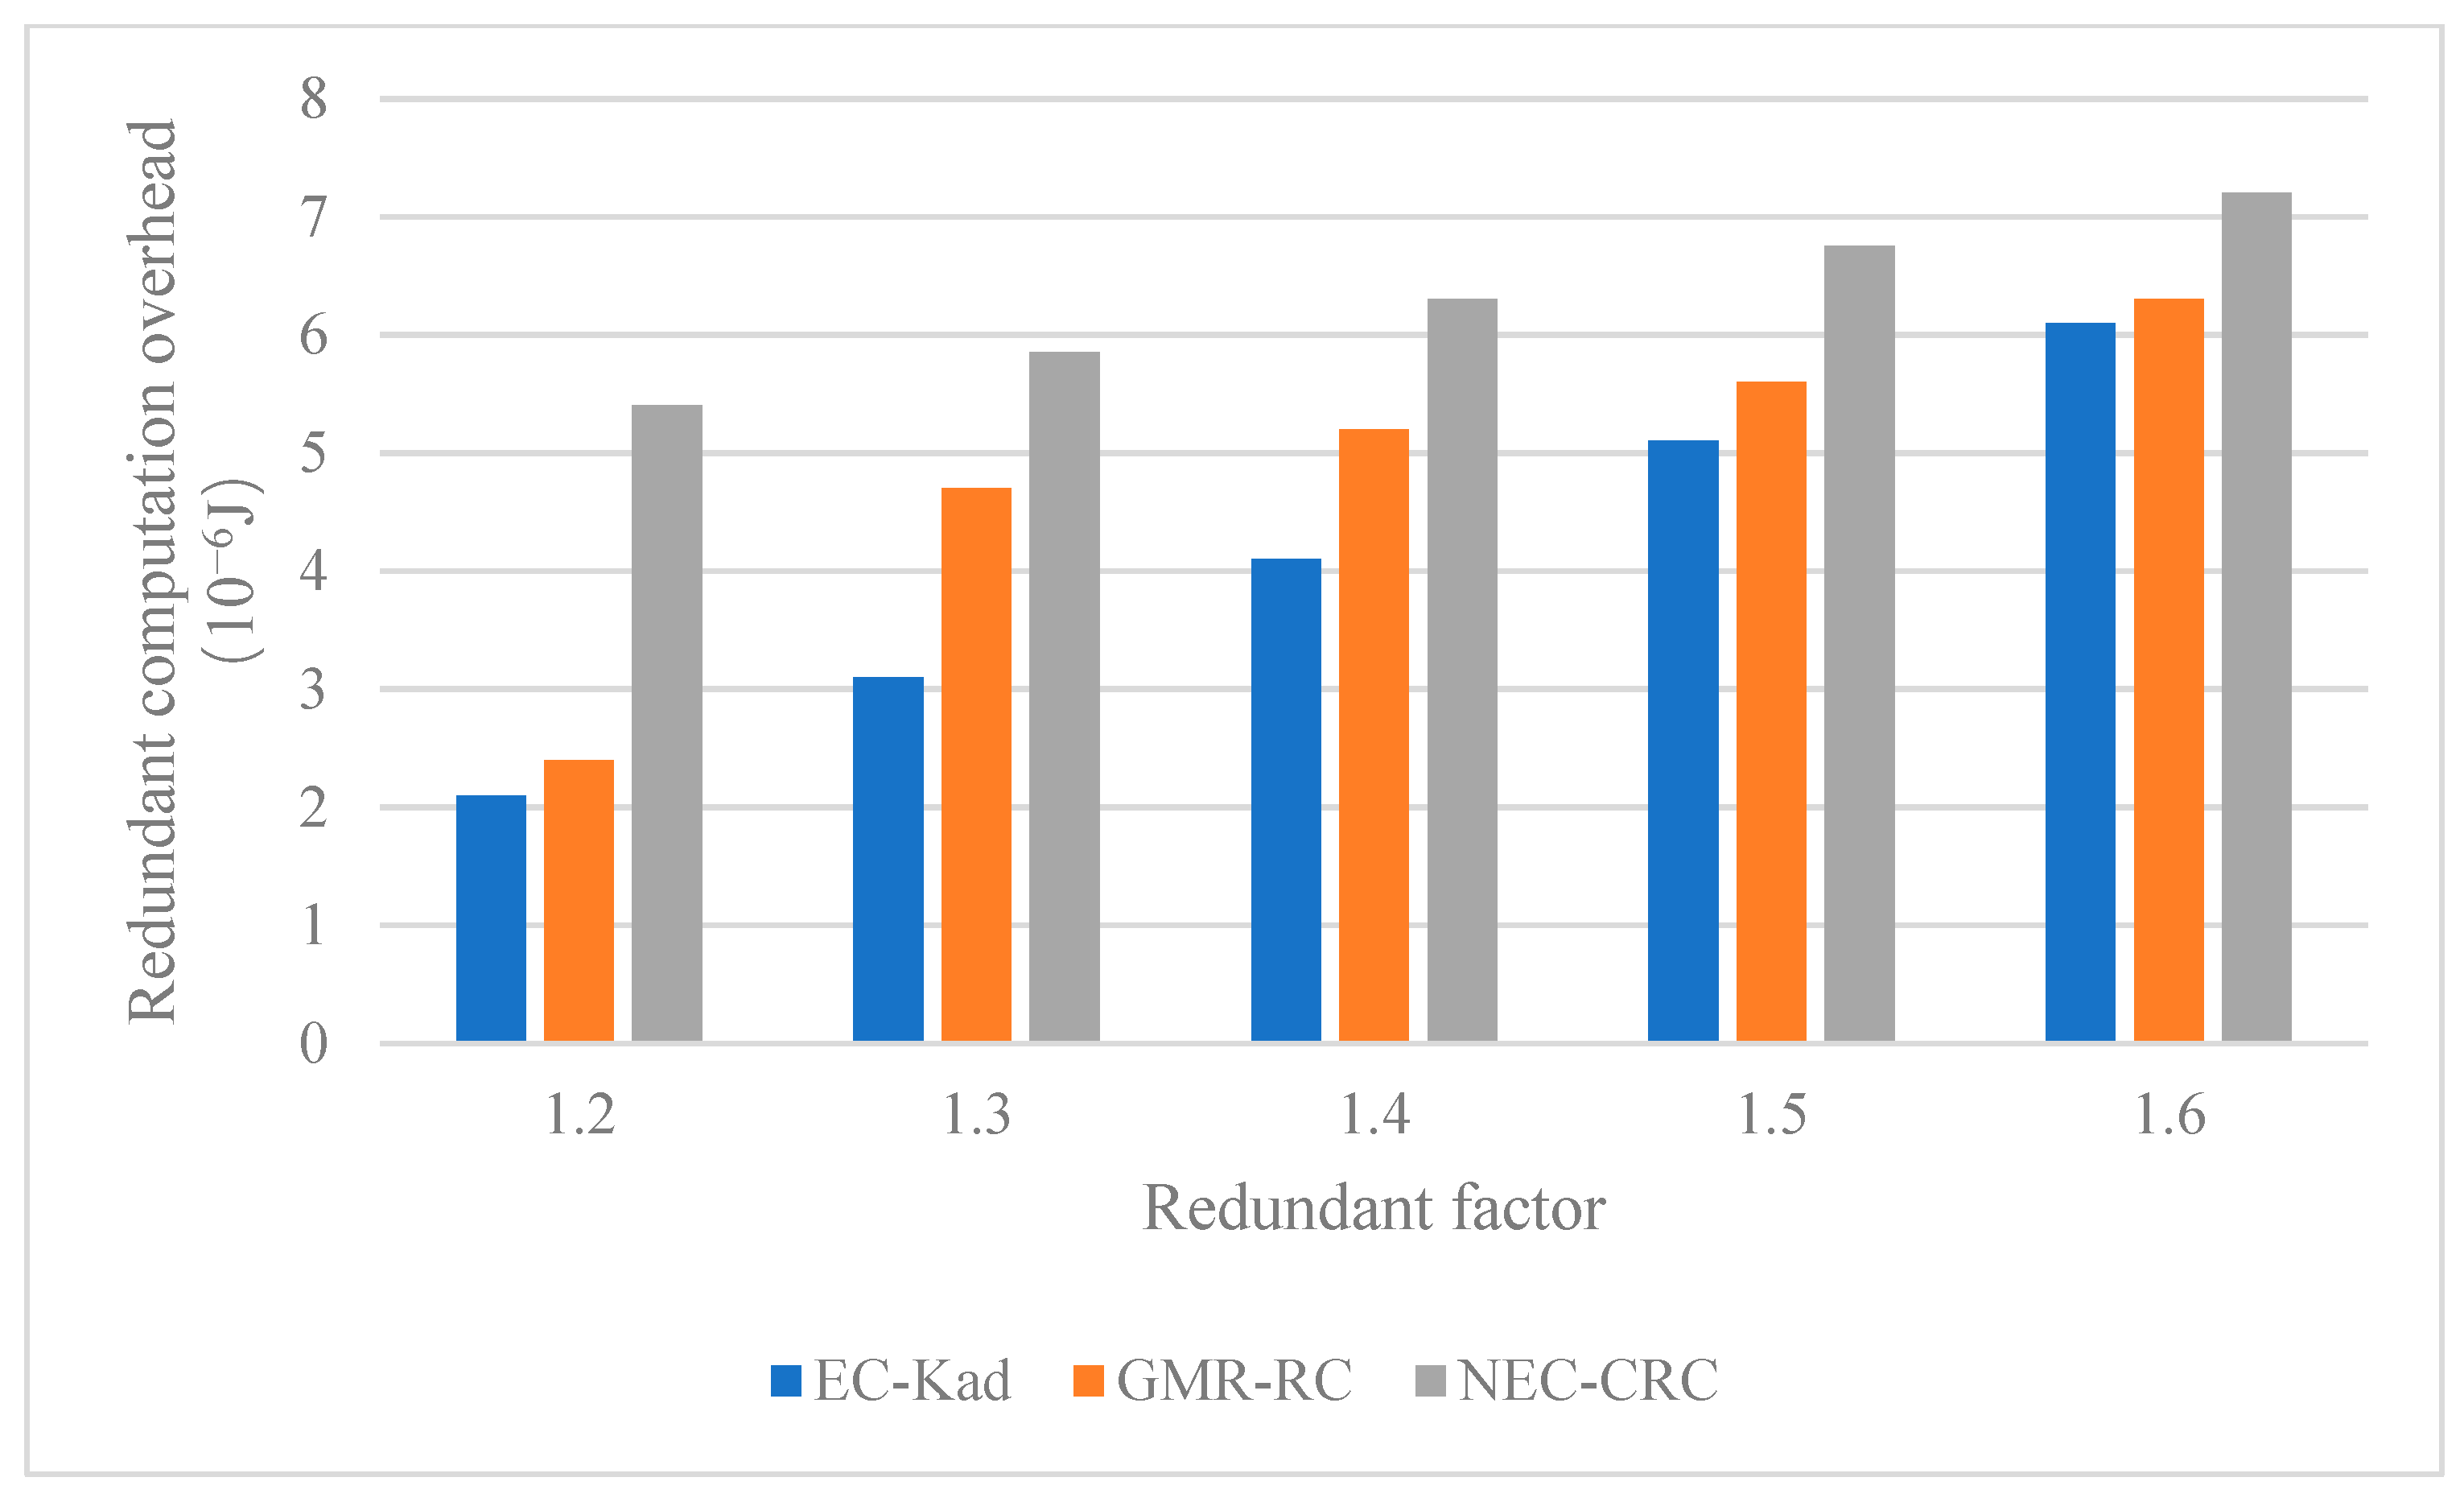
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).