1. Introduction
Everyday work in the humanities rarely turns on the confirmation of a single, self-contained fact. More often, scholars must read across heterogeneous sources in which one individual appears under multiple names or titles, the same event is narrated with shifting emphases, and key concepts acquire different semantic contours over time [
1]. Under such conditions, an answer alone is of limited scholarly value. What matters, rather, is the ability to account for that answer: from which document it is drawn; to which
juan (chapter or fascicle), page, and passage it can be traced; and, where relevant, to which edition it properly belongs. The interpretive work of comparative reading, relationship tracing, and contextual reconstruction depends on precisely this capacity to reconnect dispersed claims to citable evidence. Seen in this light, a knowledge management system (KMS) [
2] for humanities research cannot be judged by fluency alone. To be methodologically credible, it must secure at least two conditions: first, precise and citable provenance back to primary evidence; second, forms of interpretation and relational organization that remain bounded by verifiable sources.
That requirement for evidentiary accountability sits uneasily with the fluency of generative AI. Large models have undeniably reduced the cost of text processing and preliminary synthesis; they can summarize themes, cluster references, and assemble people and events into seemingly coherent accounts. Yet the very fluency that makes such systems attractive also introduces a distinctive scholarly risk. Citations may be omitted, editions conflated, inference presented as fact, and details supplied where the evidentiary record remains thin, thereby generating hallucinations that are often difficult to detect and potentially corrosive of research credibility [
3]. It follows that the scholarly usefulness of generative AI depends less on the production of polished prose than on the conditions under which model outputs are admitted into a verifiable knowledge process [
4]. Such a process, arguably, must preserve traceable locators at ingestion, bind each extracted assertion—whether concerning persons, places, events, or concepts—to resolvable evidence spans, privilege checkable source passages in retrieval and response generation, and expose uncertainty, conflict, and revision as auditable features of the workflow rather than as hidden residuals of model behavior.
Against this background, we develop an evidence-centric KMS framework for humanities scholarship. The framework is designed primarily around evidence governance: heterogeneous sources are converted into
evidence units furnished with stable identifiers and fine-grained locators, such as
juan–page–passage references and, where applicable, time-stamped media segments. Once established, this evidentiary substrate supports schema-governed extraction of entities, relations, and events, while organizing structured knowledge alongside retrievable source evidence to enable executable retrieval and graph-based querying through natural-language interaction [
5]. At the point of output, answers are generated only under explicit evidence constraints and are returned with provenance and supporting snippets. Admission checks, validation routines, quarantine and review procedures, and audit logging together constitute a traceable human-in-the-loop cycle [
6]. The broader aim is not to claim broad empirical validation across all modalities, but to show how humanities-oriented AI systems can make knowledge organization and scholarly argument more verifiable, shareable, and reproducible under a “find–verify–trace” principle [
7,
8,
9].
The empirical evaluation is intentionally limited in scope. The main quantitative evaluation is a document-modality study, while the oral history audio experiment is reported only as a transcript-mediated smoke test of timestamped EvidenceUnit portability. The paper makes four specific contributions. First, it formalizes an evidence-centric KMS architecture for humanities research, connecting knowledge acquisition, codification, storage, retrieval, verification, and revision within a single governed workflow. Second, it introduces EvidenceUnits and EvidencePointers as computable anchors that link structured records, retrieval results, visualizations, and generated answers back to citable source locations. Third, it evaluates the core governance mechanism on a controlled document-modality Shiji corpus, focusing not only on extraction accuracy but also on evidence-pointer resolvability, mis-citation, and overreach. Fourth, it reports a minimal transcript-mediated oral history audio smoke test to illustrate the portability of the evidence–unit abstraction without claiming full multimodal validation. To clarify the analytical scope of the study, we ask three research questions:
RQ1. Can an evidence-centric, schema-governed knowledge management system generate reliable, structured knowledge from historical humanities sources?
RQ2. To what extent do evidence–governance mechanisms—including schema validation, evidence-pointer checks, and claim-level verification—improve verifiability and reduce research-critical errors such as mis-citation and overreach?
RQ3. Can the proposed workflow support auditable, traceable question answering and knowledge access in the document pathway, and does a minimal oral history audio smoke test indicate preliminary portability of the evidence–unit abstraction?
3. Methods
3.1. Overall System Design
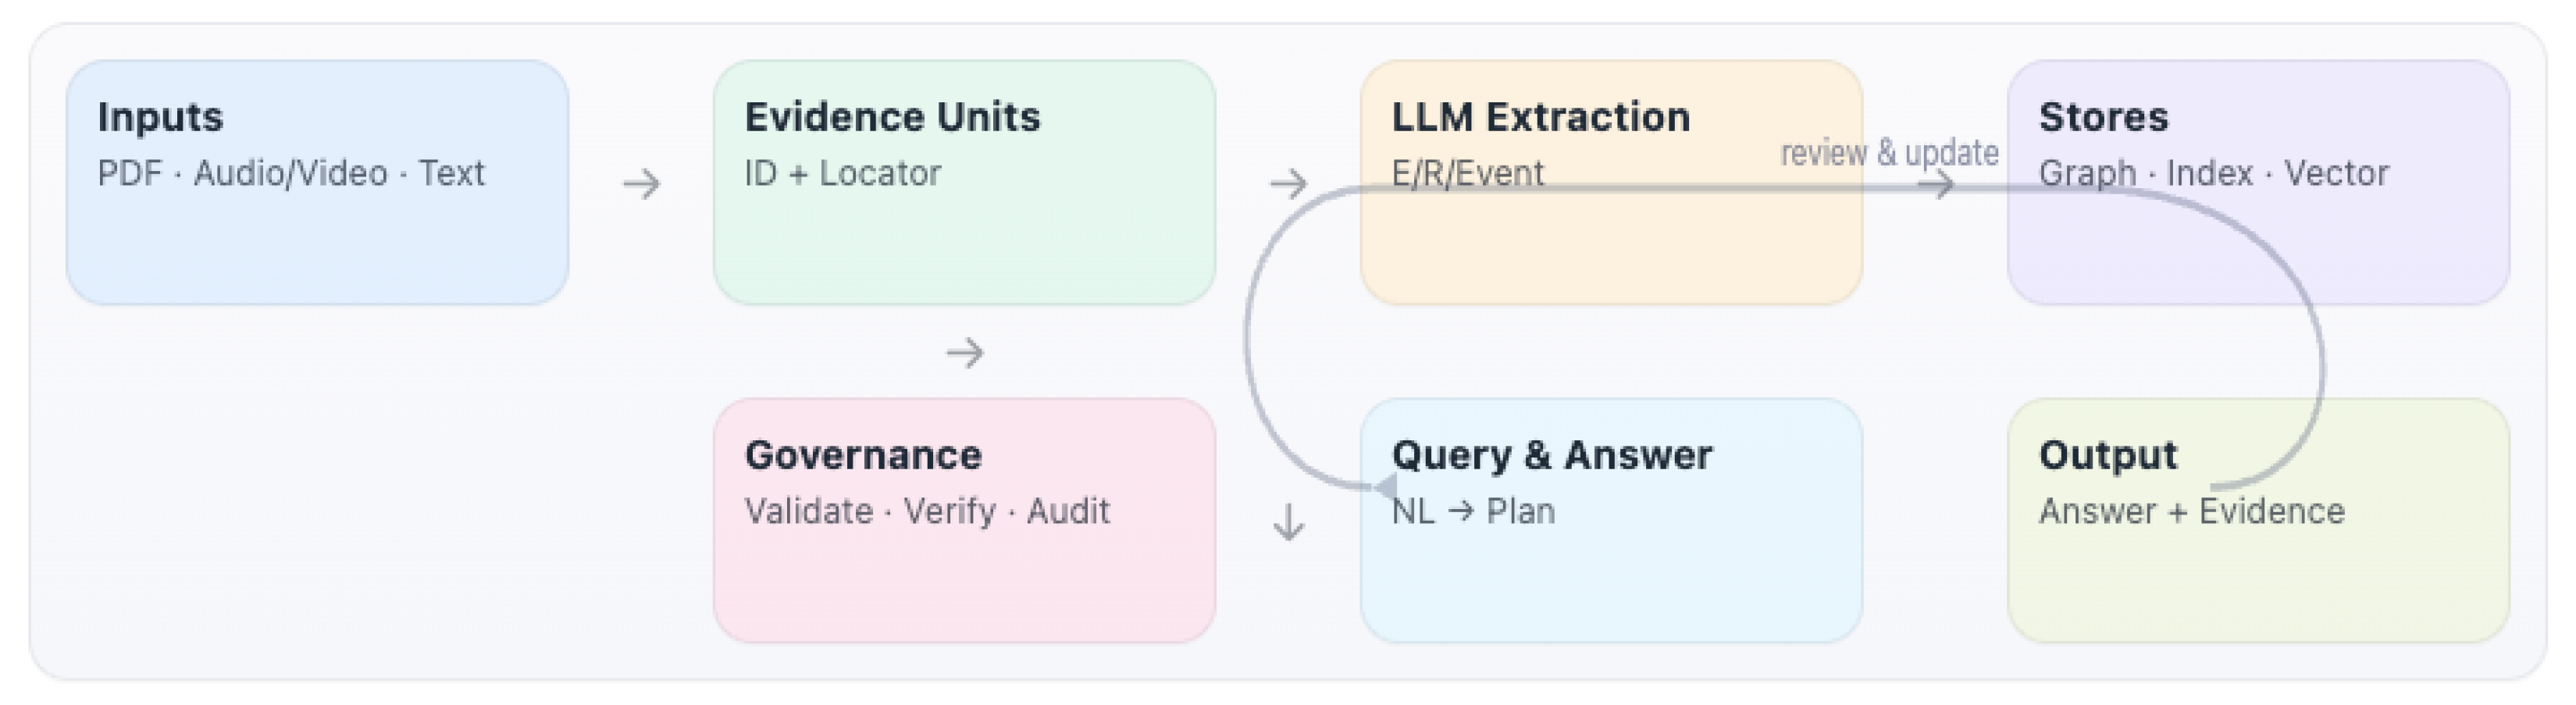
Our methodological contribution is instantiated in a running prototype of a modality-extensible, evidence-centric KMS, together with a reproducible construction and evaluation protocol. The system targets two core needs in humanities scholarship: (i) rapidly organizing dispersed materials into searchable and comparable evidence collections, and (ii) stabilizing representations of people, places, organizations, works, events, and concepts such that every substantive claim can be traced back to a concrete source location for verification and citation. Rather than treating an LLM as an “answer generator,” we position it as a
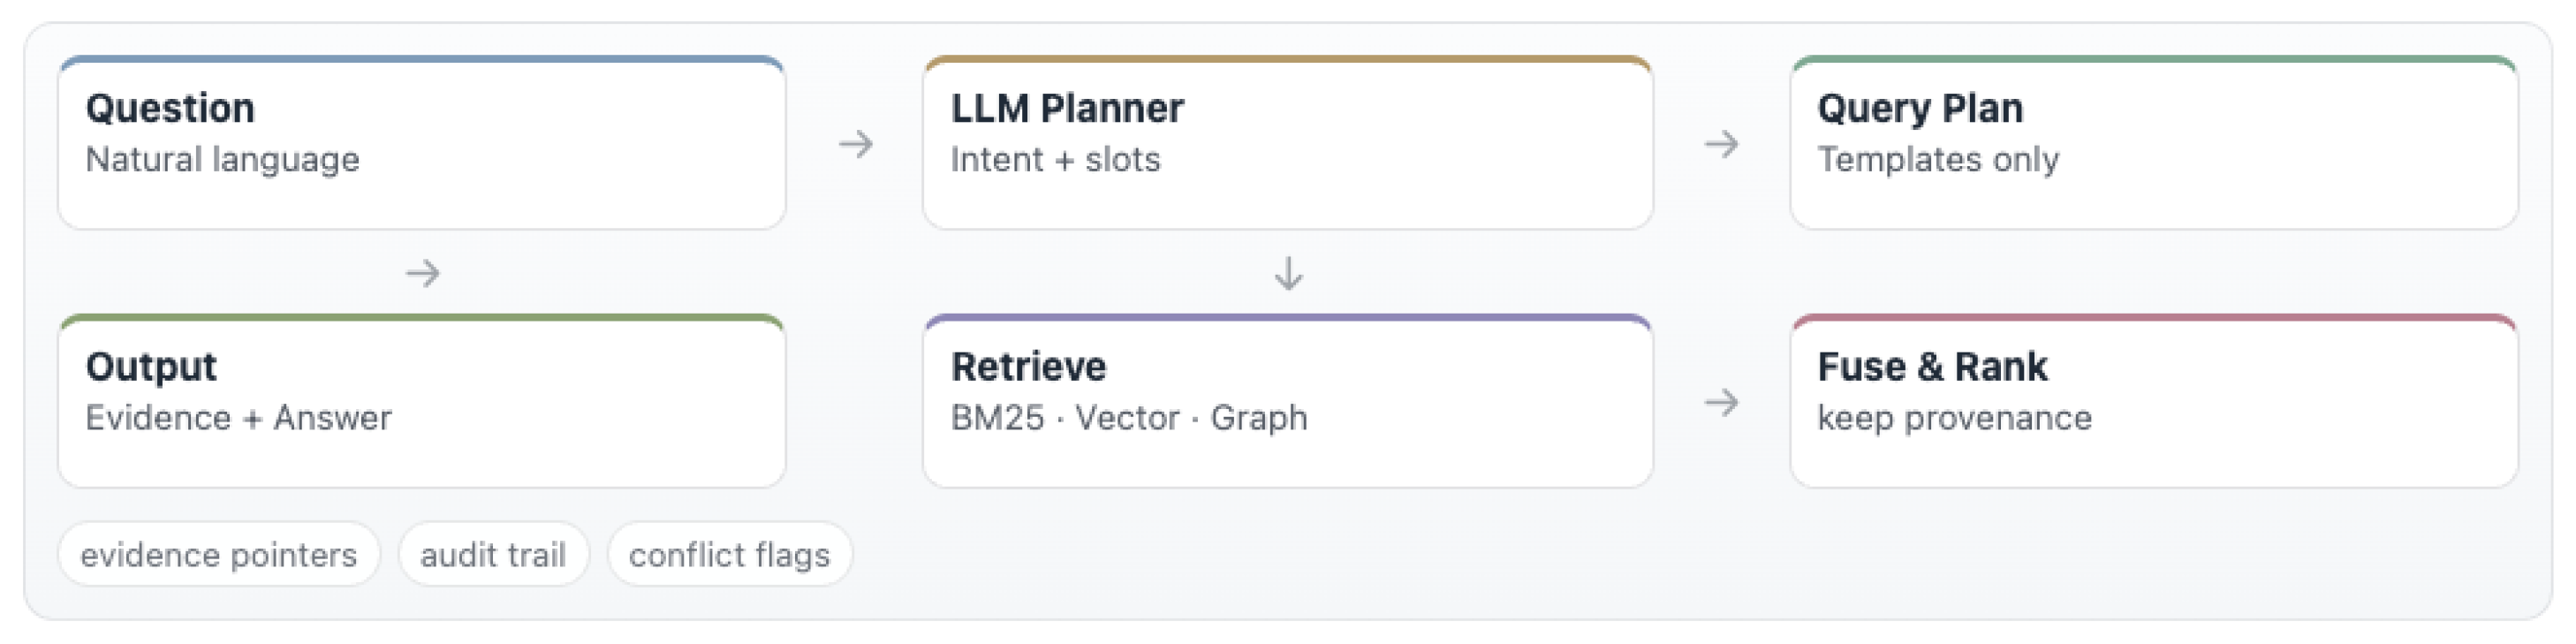
candidate proposer and retrieval orchestrator within a governed knowledge process. Outputs are constrained by evidence chains, schema rules, and audit logs, so that knowledge acquisition, codification, retrieval, sharing, and verification remain traceable. The main system modules and their corresponding knowledge-management functions are summarized in
Table 1. The overall workflow is illustrated in
Figure 1, highlighting the evidence–unit substrate, governed extraction, multi-store indexing, and auditable retrieval/answering.
3.1.1. Implementation Details
The prototype is deployed locally on an 8 × A100 GPU server. In the evaluated implementation, Qwen3-Omni-30B-A3B-Instruct serves as the main backbone for page recognition and document understanding, schema-governed extraction, query planning, and evidence-grounded verification. Unless otherwise specified, generation uses temperature , top_p , and top_k . For semantic retrieval, we use bge-m3 to encode evidence units and queries into a shared dense retrieval space. In the document pathway evaluated here, the Shiji corpus is segmented by pian-plus-paragraph, and this segmentation is used consistently for indexing, extraction, retrieval, and answer generation. For the oral history audio smoke test, recordings are transcribed with audio–text temporal alignment and converted into timestamped Audio EvidenceUnits before entering the same governance workflow. Prompts are organized into constrained templates for extraction, query planning, and verification. Outputs are subject to schema enforcement and programmatic validation, including checks on required fields, identifier syntax, and evidence-pointer resolvability. The storage layer combines a graph database for structured entities and relations, a full-text index for lexical retrieval, and a dense vector index for semantic retrieval, all linked through stable evidence–unit identifiers.
3.1.2. Reproducibility of Prompted Components
Constrained prompting is an important factor that can substantially affect system performance, especially in extraction, query planning, and verification tasks. For this reason, we report the prompt templates, output schemas, and verification rules used in the study rather than treating them as unspecified implementation details. The system uses three families of constrained prompts: extraction prompts, query-planning prompts, and claim-level verification prompts. These prompts are used to generate candidate entities, relations, events, executable query plans, and evidence–support judgments, respectively. In all cases, the model is required to return structured outputs following predefined schemas, and outputs that fail schema validation or evidence-pointer checks are not admitted to the main knowledge store.
Across the C0–C2 conditions, the same prompt templates and model settings are used; only the post-generation governance layers differ. This design isolates the effect of admission control rather than comparing alternative prompt designs.
The full prompt templates, JSON-style output schemas, and admission rules are reported in the appendices to support reproduction and scrutiny.
Appendix A provides the extraction, query planning, and claim–verification templates.
Appendix B provides the schemas for EvidenceUnits, Audio EvidenceUnits, entities, relations, events, query plans, and verification outputs.
Appendix C lists the deterministic validation rules and the evidence–support criteria used for admission, quarantine, or rejection. Together, these materials make the prompted components explicit and allow readers to assess both the role of prompt design and the added contribution of schema enforcement, evidence-pointer validation, and claim-level verification.
3.2. Digitization and Evidence–Unit Construction
3.2.1. Evidence Units and Locators
Traceability is enforced from ingestion. For document images and PDFs, we preserve document identifiers, page numbers, paragraph/line offsets, and (when available) layout coordinates; for audio/video, we preserve recording identifiers, segment indices, and start–end timestamps; for born-digital text and metadata, we preserve source paths, edition/version descriptors, and segmentation rules. We define the smallest citable object as an evidence unit (typically a paragraph, sentence, or time slice). Evidence units serve as the common anchor across extraction, retrieval, and answering, ensuring that any structured record and any answer-level assertion can be traced to the same evidence units and their locators. In this design, traceability is treated as a computable system property, not a citation format added manually at the writing stage.
3.2.2. Audio EvidenceUnits for Oral History Materials
For the oral history audio pathway, we construct timestamp-resolvable Audio EvidenceUnits from intangible cultural heritage recordings. The recordings are first transcribed by Qwen3-Omni-30B-A3B-Instruct while preserving audio–text temporal alignment. The aligned transcript is then segmented at the sentence level, and each sentence is linked to a corresponding audio clip with an audio_id, segment_id, start_time, and end_time. Each Audio EvidenceUnit, therefore, contains both the transcript used for downstream extraction and the original audio locator used for evidence verification. After this conversion, the downstream workflow is the same as the document pathway: schema-constrained extraction, evidence-pointer validation, claim-level verification, and knowledge-base admission. This design treats oral history audio not as ungrounded text, but as timestamp-resolvable evidence.
3.2.3. Input Modalities and Stable Identifiers
The architecture is designed to accommodate three common humanities data types: (1) scanned images or PDF pages (e.g., facsimiles of classical editions, manuscripts, rubbings, newspapers, catalogs), (2) audio/video speech (e.g., oral histories, interviews), and (3) born-digital text and metadata (e.g., transcripts, abstracts, tables of contents, colophons, edition notes, bibliographic records). For long-term maintenance and cross-collection linkage, we adopt stable identifier policies: a document or recording receives a top-level doc_id or audio_id, and subordinate objects are indexed by page_id, segment_id, or chunk_id. We version the processing pipeline and key parameters and, where needed, the outputs. This supports longitudinal governance: when review decisions, normalization policies, or model versions change, the system records these changes as traceable knowledge assets rather than silently overwriting prior states.
3.2.4. Data Partitioning for Reproducibility
To reduce leakage and better approximate real use, dataset partitioning is performed at the document/recording level rather than by randomly sampling sentences or paragraphs. This prevents adjacent segments from the same source from appearing in both development and test splits. In addition to a standard test set, we recommend holding out a cross-domain test set that simulates the continuous introduction of new materials common in humanities workflows (e.g., moving from printed to handwritten scripts, from clean layouts to dense marginalia, or from single-domain to interdisciplinary corpora). The goal is not to maximize average performance, but to evaluate whether the system still provides stable, verifiable evidence pointers and usable structure on unfamiliar inputs, and whether its failures are diagnosable.
3.2.5. Evaluation Design and Scope
The empirical scope is specified in
Section 4.1. Briefly, the quantitative evaluation focuses on the document pathway and the core evidence–governance mechanism, while the oral history audio pathway is reported only as a minimal timestamped EvidenceUnit portability check.
3.2.6. Model Choices and Governance Stance
For privacy, compliance, and portability, the system prioritizes locally deployable open-source models, while remaining compatible with commercial LLM APIs (e.g., OpenAI/Google/Alibaba). Text understanding and structured extraction can use instruction-tuned models from the Qwen or Llama families [
30], with strict output formats and admission checks to reduce uncontrolled generation. Speech transcription can use Qwen3-Omni-30B-A3B-Instruct or Whisper-class models [
31] augmented with domain lexicons and post-processing to improve named entity accuracy. Document recognition can combine mature OCR pipelines with controlled LLM-based correction and normalization. Importantly, the LLM is not treated as a final arbiter: it proposes candidates and explanations, while the system enforces evidence binding, validation rules, and retrieval constraints; uncertain or conflicting cases are routed to human review and recorded for iterative improvement.
Operationally, the digitization module converts images, audio, and born-digital text into citable, locatable evidence units that provide a unified substrate for downstream extraction and retrieval. For images and PDFs, the system performs layout analysis and region segmentation, applies line-level text recognition, and assembles recognized text into paragraph/line-group evidence units; each unit stores page_id and either a bounding box (bbox) or line-range locator. For audio/video, the system segments recordings, performs transcription, and stores start–end timestamps for each segment; optional speaker diarization can be applied to ensure stable alignment between transcript and timeline. For born-digital text, the system performs normalization and segmentation while preserving chapter boundaries and source metadata as locators.
LLMs are used in two controlled roles: constrained correction and constrained normalization. For OCR/ASR spans with low confidence, an LLM may propose edits, but only within the low-confidence region; it must output a structured diff (before/after text, edit location, and rationale) to support auditability and rollback. For common formatting differences (missing punctuation, inconsistent paragraphing, variant characters), the system can produce a normalized version while preserving the original; both are linked to the same evidence–unit identifier to prevent “clean” text from overwriting primary evidence. For proper name correction, domain lexicons (names, toponyms, titles, work names) constrain candidate substitutions: the model must choose from permitted candidates or provide evidence-based justification; otherwise, the substitution is rejected. This design leverages LLM language competence to reduce noise without crossing evidence boundaries.
3.3. Knowledge Extraction and Disambiguation
This module converts evidence units into computable entities and relations while ensuring that each record can be traced back to evidence. We adopt a compact, extensible type system covering common humanities objects (persons, places, organizations, works, events, time expressions, and topical concepts). Relation types prioritize high-value, verifiable relations such as aliases, authorship, citation/source links, participation in events, office holding with time spans, and edition/version links. Every entity and relation must store an evidence–unit identifier and an in-unit pointer (span or quoted excerpt) so that subsequent queries and answers can display supporting passages.
For LLM-based extraction, we enforce structured output rather than free-form summaries. The model is provided with the evidence unit, allowed entity/relation types, and required fields, and must return a fixed schema (e.g., entity name/type/evidence pointer/alias candidates; relation endpoints/type/time attributes/evidence pointer/quotation). Outputs that fail schema validation, type checks, or evidence-pointer requirements are not admitted to the main store and are routed to a review queue. For high-risk but high-value relations (e.g., citations and office holding), we use a two-stage procedure: the model first proposes candidates, then performs per-candidate verification under an “evidence-only” constraint, explicitly stating whether the evidence supports the claim, where it does so, and what ambiguities remain. This shifts model usage from “inventing details” to “checking and explaining”.
Name disambiguation is a pervasive challenge in historical corpora. We separate disambiguation into candidate generation and candidate ranking. Candidate generation relies on string similarity, alias tables, and existing entity inventories. Candidate ranking combines contextual similarity and relational coherence (e.g., temporal plausibility, associated offices, co-mentions, and location consistency). The LLM may provide explanatory features (why candidate A fits better than B), but final decisions are governed by checkable evidence and rules. When evidence is insufficient, or candidates are close, the system preserves uncertainty by marking low confidence and routing to human review, preventing premature consolidation and error propagation.
3.4. Knowledge Storage and Indexing
We organize structured relations and evidence fragments into a maintainable knowledge base that guarantees back-linking from any output to the original materials. Storage is layered: relational structure is stored in a graph database, while evidence fragments are stored in a full-text index and a vector index; stable identifiers link all three layers. The graph database stores nodes/edges with attributes such as time, source, and confidence; the full-text index supports precise lookup of quotations, names, and fixed expressions; the vector index supports semantic discovery of related evidence. Each evidence fragment stores doc_id, page_id or timestamps, bbox/span, raw/normalized text, and linked entity identifiers, enabling bidirectional navigation between retrieval results and structured relations.
LLMs do not replace databases in this design—they assist governance and alignment. First, when the same entity appears under different names across sources, the model can propose merge candidates with comparative evidence snippets and alias chains; admission is decided via review and rules. Second, when aligning external databases to the local ontology, the model may propose mapping rules, but final alignment is implemented as executable rules with sample-based verification. Third, embeddings for vector retrieval are generated by open embedding models and bound to evidence–unit identifiers so that semantic recall always resolves to explicit evidence locations rather than model memory.
3.5. Retrieval and Fusion
Humanities questions vary in intent, so the system provides an interpretable retrieval orchestration across complementary channels: exact retrieval for quotation lookup and named-entity search, relational retrieval for graph paths (e.g., person–office–event chains and version links), and semantic retrieval for topic exploration and paraphrase discovery. Users can express requests in natural language; the system selects and orchestrates retrieval pathways and returns checkable evidence.
LLMs play two controlled roles here: intent interpretation and query-plan generation. Intent interpretation classifies a request into executable intents (citation lookup, relationship tracing, comparison, or overview). Query plans are produced under strict templates: the model can only select from allowed query templates and fill slots (keywords, entity identifiers, time/version filters, path-length constraints). This preserves conversational convenience while ensuring execution is auditable and predictable.
Fusion prioritizes ranked results while retaining provenance: the system preserves each item’s channel, original rank, and fused rank. Outputs emphasize evidence-first presentation: results include supporting evidence–unit lists and explicit locators, and cross-version comparisons are grouped by source/time/edition to avoid conflating contexts.
3.6. Natural Language Interaction
The interaction layer translates researchers’ task-oriented natural-language requests (e.g., “aliases of a person across texts with citations,” “concept usage differences across periods,” “institutions associated with an event”) into executable queries over the full-text index, vector store, and graph database. Rather than allowing the model to generate arbitrary queries, the system provides the available fields, permitted templates, and return schemas; the model outputs a standardized query plan that the system executes and logs. After multi-store retrieval, results are aligned by stable identifiers (evidence–unit IDs and entity IDs) and fused. The model then produces an evidence-grounded organization of results (grouping, contrast, and short summaries), while each key claim in the response is linked to explicit evidence pointers. For complex questions, the system outputs (i) evidence lists, (ii) structured summaries, and (iii) constrained conclusions, preserving the verification path.
3.7. Visualization
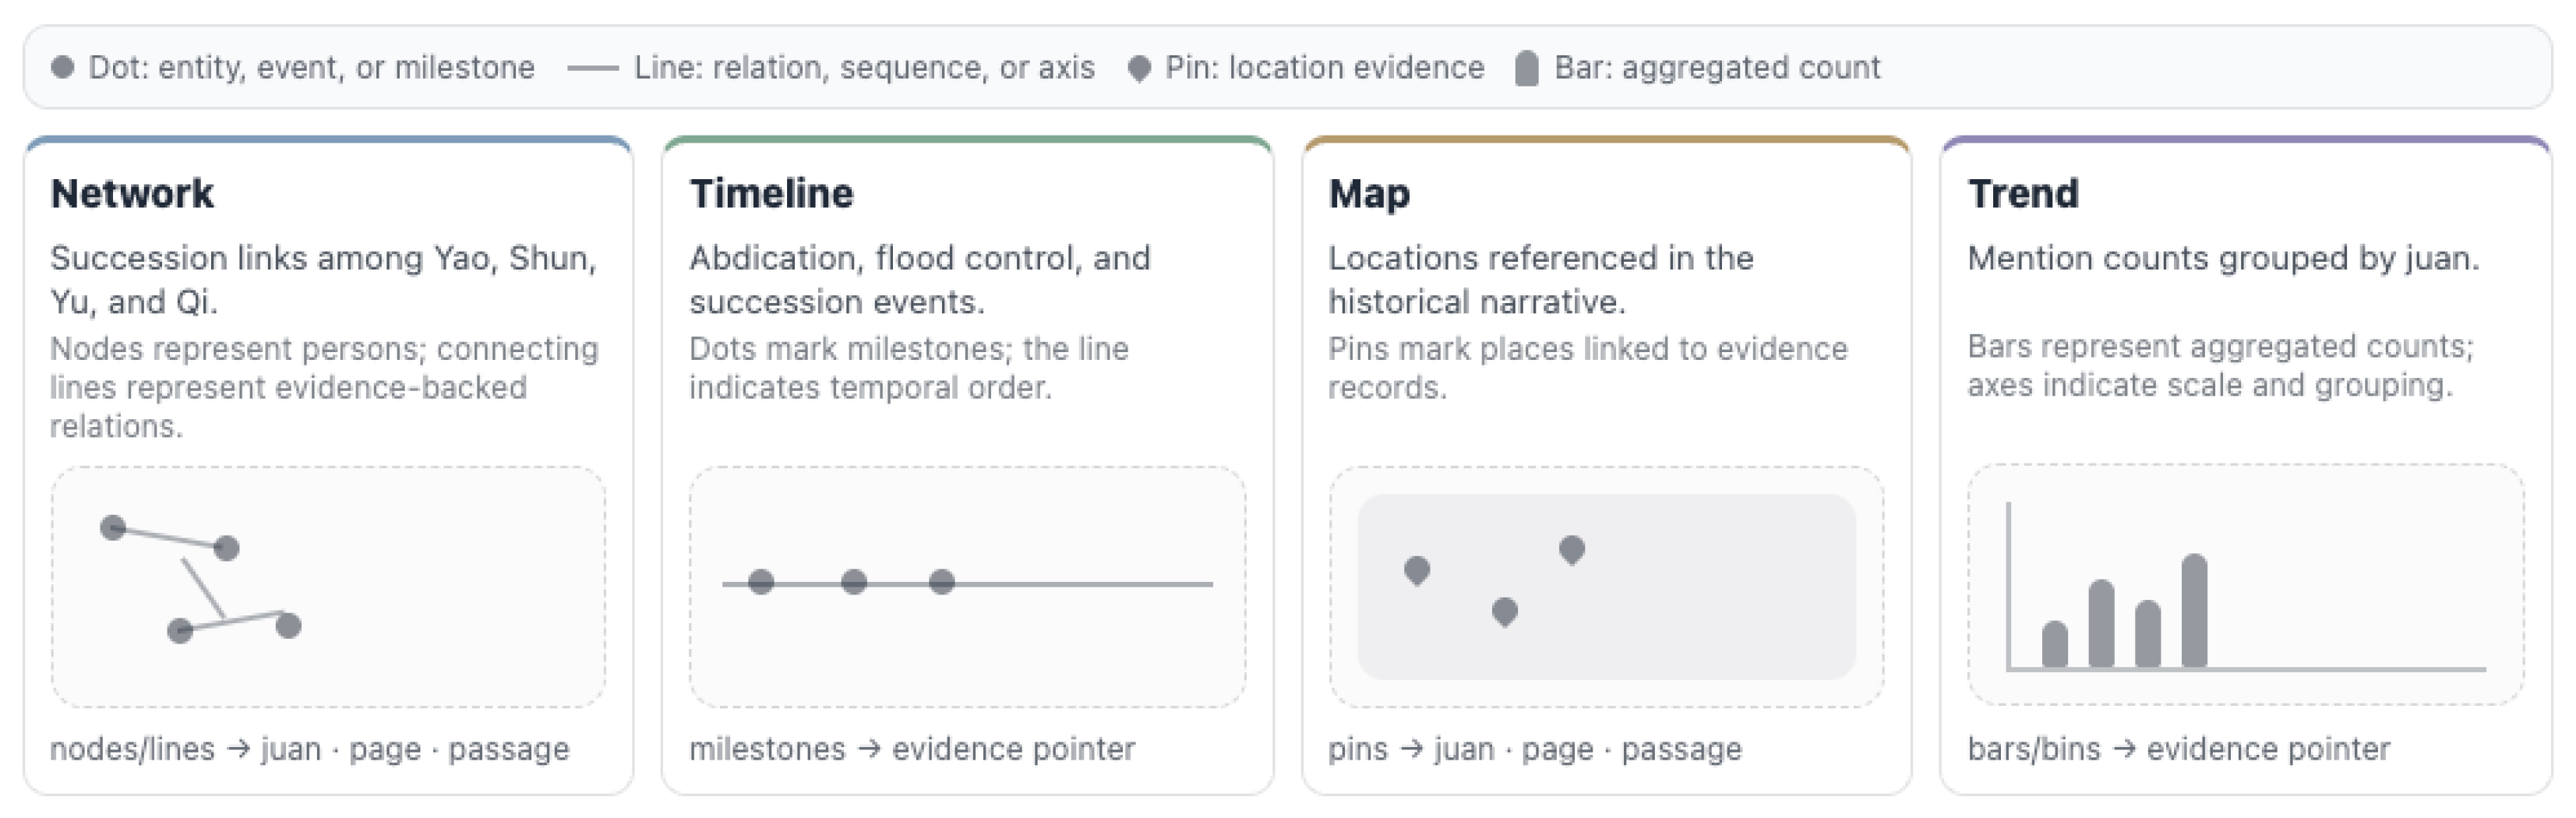
Visualization supports explanation and verification rather than esthetics. Common humanities visualizations include co-mention networks, timelines with cross-source contrasts, spatial distributions and migration paths, and periodized concept trends. Each visualization is bound to explicit data provenance: the evidence units, entities/relations, query conditions, aggregation rules, and parameters are stored together to enable reproduction and stable citation.
Implementation-wise, LLMs translate visualization intent into executable data-processing plans and code, under controlled execution (whitelisted libraries and fixed output paths). Outputs are packaged as shareable HTML pages that include the chart, parameter summaries, and downloadable data/scripts. Importantly, visual elements support back-linking: clicking a node/edge/peak navigates to the underlying evidence units with locators. Visualization also serves as an entry point for review workflows: low-quality evidence, conflicts, and low-confidence extractions are surfaced in review queues with side-by-side reading interfaces; review actions are logged as auditable diffs and written back to the knowledge base, enabling continuous improvement.
4. Experimental Results
4.1. Evaluation Scope and Corpus
The empirical evaluation in this section focuses on document-based materials in order to permit close expert verification and to assess the core evidence–governance mechanism under controlled conditions. The primary contribution of the proposed system lies in a knowledge–management workflow applicable across source modalities—
evidence units →
evidence pointers →
admission control →
auditable retrieval and answering.
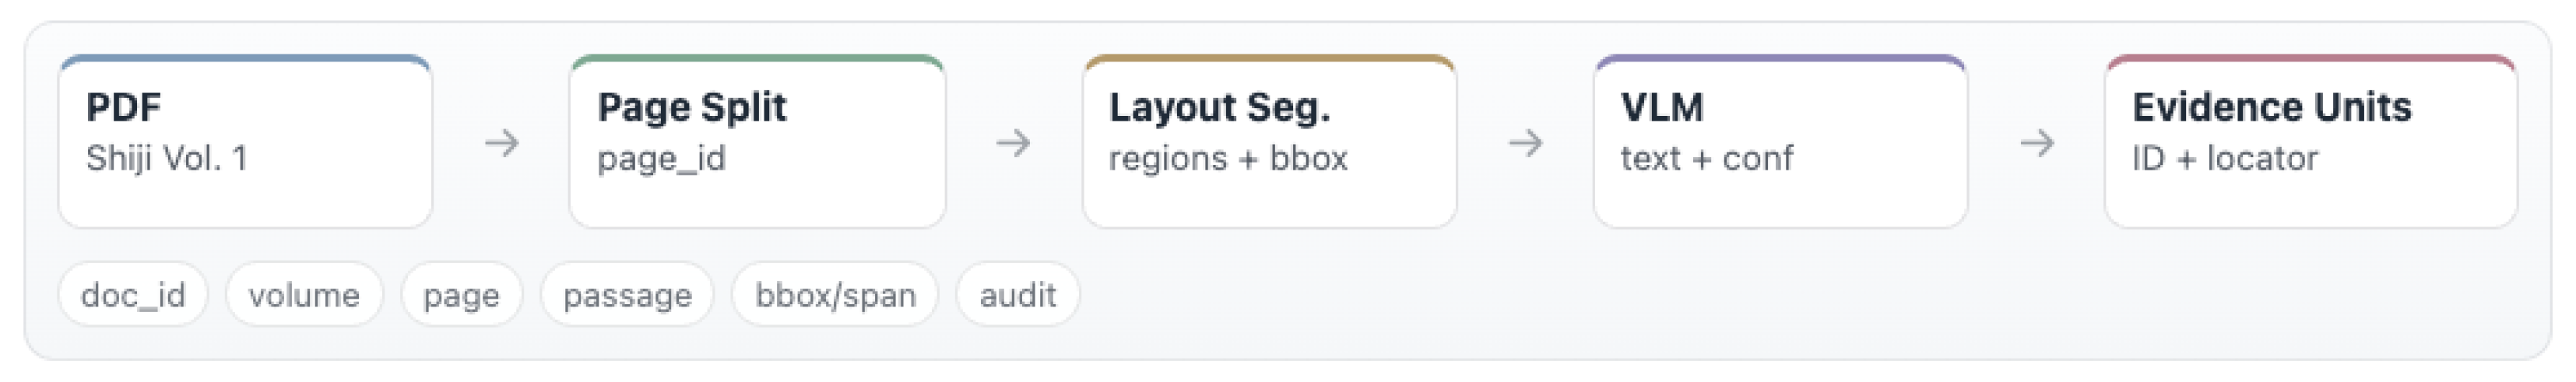
Figure 2 illustrates the page-level splitting pipeline and the construction of evidence units with resolvable juan–page–passage locators (and optional
bbox/span). Across source modalities, the main differences concern how evidence units are constructed and which perception models are required. For document inputs, evidence units are created via OCR and vision-language models with page and layout coordinates; for audio and video, evidence units can be created via ASR (optionally with speaker diarization) with timestamp locators; for born-digital text, evidence units are created via segmentation and edition metadata with paragraph-level locators. Once established, all evidence units are governed by the same schema constraints, evidence checks, and audit logging, and subsequent response generation remains constrained by evidence pointers. Thus, while this section reports quantitative results on document-based materials, the system’s support for audio and video and born-digital text is an extensible capability under the same governed workflow and can be evaluated through the same protocol in future work. Accordingly, the present experiments should be interpreted as a controlled validation of the core evidence–governance workflow on document inputs, rather than as a full comparative benchmark across all source modalities supported by the system.
We evaluate the system on a scanned subset of the Twenty-Four Histories from the Zhonghua Book Company Traditional Chinese edition, specifically Shiji (Records of the Grand Historian), Volume 1, Juan 1–7, comprising 339 PDF pages and approximately 200,000 characters. This corpus is used as a tractable, evidence-intensive test bed because it contains dense proper names, dispersed relational cues, narrative information distributed across paragraphs, and frequent ellipsis and referential ambiguity. These features make it suitable for evaluating citation quality, evidence-pointer resolvability, and interpretive overreach.
The evaluation consists of four parts. First, we validate evidence–unit construction and the establishment of stable document locators (
Section 4.2). Second, we assess the reliability of schema-governed extraction for entities, relations, and events using expert annotations, and report ablation analyses of governance mechanisms (
Section 4.3). Third, to clarify the multimodal scope of the framework, we report a minimal transcript-mediated oral history audio smoke test using intangible cultural heritage recordings (
Section 4.4). This smoke test examines whether timestamped Audio EvidenceUnits can be processed by the same schema-constrained extraction, evidence-pointer validation, claim-level verification, and admission workflow used in the document pathway. Fourth, we demonstrate auditable and traceable knowledge access through end-to-end question answering and evidence-centered presentation via executable query plans and direct links back to supporting evidence (
Section 4.5 and
Section 4.6); these latter parts are reported primarily as illustrative demonstrations, with broader quantitative extensions left for future work. Accordingly,
Section 4.2 and
Section 4.3 address RQ1,
Section 4.3.4 addresses RQ2, and
Section 4.4,
Section 4.5 and
Section 4.6 address RQ3.
4.2. Evidence–Unit Construction from Shiji
The ingestion stage is designed to maximize verifiability rather than the volume of extracted text. We construct a stable evidentiary foundation by (i) treating pages as discrete evidence objects and (ii) establishing stable locators so that any structured record and answer-level assertion can be traced back to juan–page–passage (and, when needed, to bbox/span). We assign a stable doc_id to Shiji Vol. 1 (Juan 1–7) and record juan/page indices, source files, and pipeline versions. The PDF is split into pages to generate page_id, preserving the page-to-juan mapping for auditability.
At the page-recognition stage, we use Qwen3-Omni-30B-A3B-Instruct to transcribe page images and retain layout cues, including vertical writing direction where present. To improve the stability of text-to-layout alignment, the default procedure performs layout region segmentation followed by region-level recognition while retaining bounding boxes. As a fallback, the system applies whole-page recognition followed by post hoc segmentation, thereby supporting robustness and rollback. Outputs are organized into evidence units at the paragraph or sentence level, including at minimum the following fields: doc_id, page_id, juan metadata, passage_id, bbox/span, raw transcription, optional normalized text, and quality flags. Normalization serves retrieval and aggregation, but never overwrites the raw text; all differences are preserved for auditing and rollback. Quality flags—for example, low confidence, missing glyphs, dense proper names, and segmentation anomalies—make ingestion uncertainty explicit and trigger more conservative downstream processing, such as reduced ranking priority, multi-evidence requirements, or review routing. In this way, potential errors remain visible at the level of evidence.
4.3. Ontology and Extraction Evaluation
We evaluate whether the system produces verifiable structured knowledge across entities, relations, and events, and whether evidence governance reduces research-critical errors. The evaluation uses an expert-annotated gold-standard set aligned with evidence units, comprising 500 annotated entities, 500 annotated relations, and 300 annotated events. Each annotation is linked to an evidence unit through an explicit juan–page–passage locator, thereby allowing the evaluation to capture not only correctness but also traceable provenance. Three graduate annotators with backgrounds in historical-document research and NLP independently annotated the data; inter-annotator agreement reached (
) for entities and (
) for relations and events, with all disagreements resolved through expert adjudication. The evaluation considers both strict and relaxed matching criteria; unless otherwise noted, the main tables report results under strict matching.
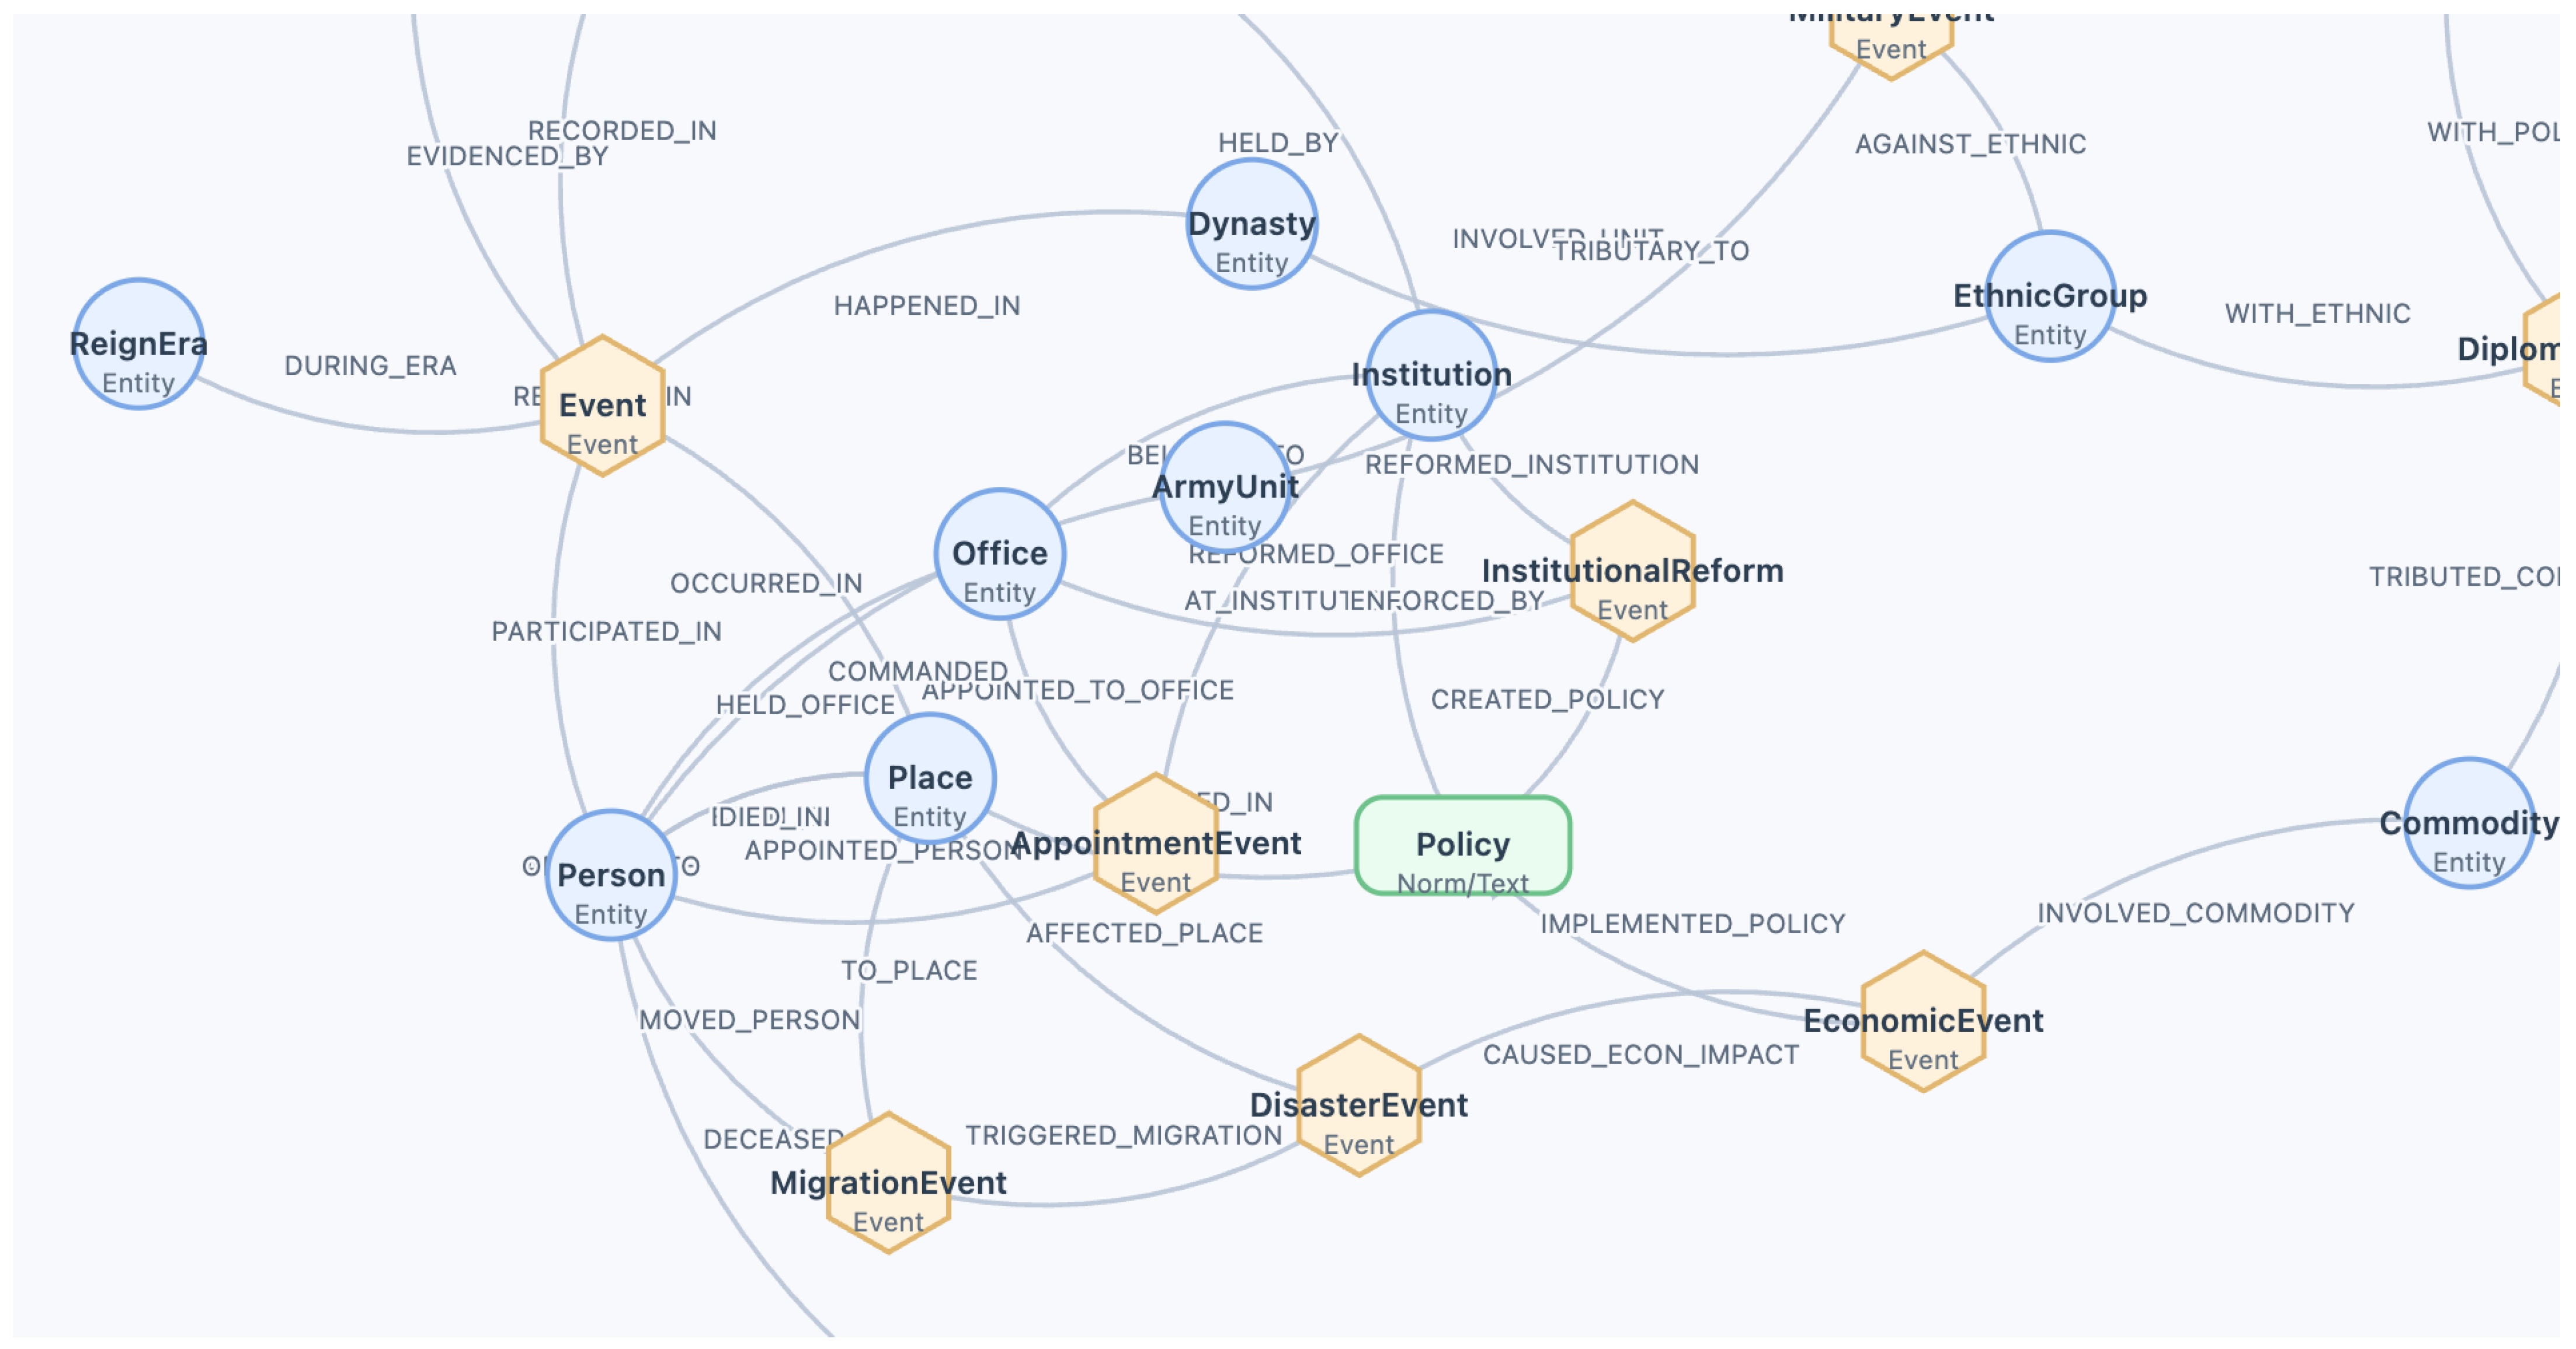
Figure 3 summarizes the ontology used in this study and defines the schema constraints governing extraction and admission checks.
4.3.1. Named Entity Recognition (NER)
Entities in Juan 1–7 exhibit early-state and clan/tribal characteristics, spanning persons (rulers and key figures), places (ancient toponyms and capitals, rivers and passes), polities/clans/ethnic groups, official titles, and artifacts/canons.
Table 2 reports per-type and micro-averaged results. Overall, micro-
is 0.84. Person and location entities perform best (
and
), while titles and artifacts are lower (
and
), consistent with the diversity of historical title expressions, alias ambiguity, and the boundary ambiguity between artifacts, book titles, and institutional terms.
4.3.2. Relation Extraction (RE)
Narratives in
Shiji commonly organize around kinship, power relations, succession, and territorial control.
Table 3 reports the relation extraction performance. Overall, micro-
is 0.78. Succession relations achieve the strongest performance (
), reflecting relatively explicit predicates and narrative structures; political relations are lower (
), which is consistent with implicit phrasing, cross-sentence composition, and subject–object confusion under multi-party mentions.
4.3.3. Event Extraction (EE): Triggers and Arguments
We evaluate event extraction at two layers: (i) trigger detection (trigger span + event type) and (ii) argument extraction (time, location, participants, outcome/impact).
Table 4 reports trigger results with micro-
. Natural phenomena perform best (
) due to more formulaic expressions; institutional change is more difficult (
), often requiring cross-sentence integration and stable recognition of institutional terms.
Table 5 reports argument extraction: time and location are relatively stable (
and
), participants are harder under ellipsis and co-reference (
), and outcome/impact is the most challenging (
), reflecting implicit consequence chains and subjective boundary decisions.
4.3.4. Governance-Layer Analysis
The C0–C2 comparison is not intended as an independent benchmark among competing extraction methods. Instead, it is a governance-layer analysis that measures how successive admission–control layers affect output admissibility, evidence traceability, and research-critical error rates under the same candidate–generation setting. In this sense, improvements in schema validity and evidence-pointer resolvability are partly expected by design. The analysis is therefore interpreted as evidence for the usefulness of explicit governance controls, rather than as independent validation of extraction competence.
Beyond extraction accuracy, we conduct a governance ablation to quantify the marginal value of
schema constraints, programmatic validation, and per-claim verification. We compare: C0 (LLM candidate output without enforced evidence checks), C1 (C0 + schema enforcement and programmatic validation), and C2 (C1 + multi-agent/per-claim verification).
Table 6 shows that under C0, schema validity and evidence-pointer resolvability are low (68.5% and 42.3%), accompanied by high mis-citation and overreach (27.8% and 31.5%). Under C1, schema validity reaches 100%, and resolvability improves to 76.5%, with risk rates reduced. Under C2, resolvability increases to 94.2%, and mis-citation/overreach drops to 4.1%/5.3%, reaching ranges appropriate for scholarly verification.
4.3.5. Operational Definitions of Metrics
Let be the set of generated candidate records and the set of evidence units. For any , let denote its evidence pointer and the resolved evidence unit (if not resolvable, ). Human verification provides binary labels: evidence support and overreach .
- (i)
Precision, Recall, and .
For a task (NER/RE/EE), let
be the predicted set and
the gold set. Define the strict matching indicator
(For RE,
can be replaced by the endpoint pair; for EE triggers/arguments, by the trigger/argument span.)
Relaxed matching replaces exact span equality with overlap:
- (ii)
Schema validity rate.
Let
, where
indicates required fields present, JSON parseable, schema-typed, and syntactically resolvable IDs.
- (iii)
Evidence-pointer resolvability.
Let
.
Measured on resolvable candidates:
Also measured on resolvable candidates:
Mis-citation and overreach are
not mutually exclusive; a single record may satisfy both conditions.
4.4. Minimal Oral History Audio Smoke Test
This subsection reports a bounded, transcript-mediated feasibility test using Yi intangible cultural heritage recordings. The test asks whether oral history audio can be converted into timestamp-resolvable Audio EvidenceUnits and incorporated into the same evidence–governance workflow used for the document pathway. It does not evaluate end-to-end acoustic reasoning, speaker diarization, gesture, video understanding, or comprehensive multimodal performance.
The audio recordings, totaling approximately 90 min, were first transcribed using Qwen3-Omni-30B-A3B-Instruct while preserving audio–text temporal alignment. Based on the recognized sentence boundaries, the recordings were segmented into 723 sentence-level audio clips, each paired with one transcript sentence and a timestamped audio locator. Each clip was then represented as an Audio EvidenceUnit containing an audio_id, segment_id, start_time, end_time, aligned transcript, and relevant metadata. After this conversion, the downstream procedure followed the same evidence–governance workflow as the Shiji document pathway: schema-constrained extraction, evidence-pointer validation, claim-level verification, and knowledge-base admission.
As shown in
Table 7, the smoke test produced 723 sentence-level Audio EvidenceUnits, with an average clip length of approximately 7.5 s. Manual inspection showed that sentence recognition and segmentation were correct in approximately 93% of cases, while the remaining cases required human adjustment, mainly due to boundary ambiguity, recognition noise, or speech disfluency. These results indicate that oral history audio can be transformed into timestamp-resolvable evidence objects suitable for the same downstream evidence–governance mechanism used in the document pathway.
4.5. End-to-End Traceable Question Answering
This section demonstrates an end-to-end, reproducible path: natural-language question → executable query plan → evidence retrieval → constrained answer with pointers. To contextualize the value of the proposed evidence-governed workflow, we additionally compare it with a conventional retrieval-augmented generation (RAG) baseline. Using the same
Shiji corpus and the same query set, the baseline retrieves the top-
k passages from the indexed text collection and prompts the LLM to answer directly from the retrieved context. Unlike the proposed system, this baseline does not enforce evidence-pointer admission, schema validation, per-claim verification, or review routing. The comparison is therefore intended to isolate the contribution of explicit evidence governance beyond standard retrieval-augmented generation. For comparability, the proposed workflow in
Table 8 corresponds to the fully governed setting (C2) reported in the ablation study, i.e., schema validation plus per-claim verification.
As shown in
Table 8, the comparison focuses not on fluency but on research-critical reliability. The conventional RAG baseline improves over unconstrained generation by grounding responses in retrieved passages, but it still falls short of the proposed governed workflow on all three metrics. In particular, pointer resolvability rises from 72.20% under conventional RAG to 94.20% under the proposed workflow, while mis-citation and overreach are reduced from 20.40% and 23.50% to 4.10% and 5.30%, respectively. These results indicate that the observed gains do not arise merely from combining retrieval with an LLM, but from explicit evidence governance, especially evidence-pointer admission and claim-level verification.
Beyond this baseline comparison, we validate traceability at the interface level: each key claim in the response must be bound to a resolvable evidence pointer, and the user interface provides one-click navigation back to the source location. For document inputs, links resolve to juan–page–passage (optionally highlighting bbox/span); for audio/video, links resolve to segment IDs and time ranges; for born-digital text, links resolve to chapter/paragraph boundaries. This makes citation a default system behavior rather than a post hoc writing convention, as illustrated in
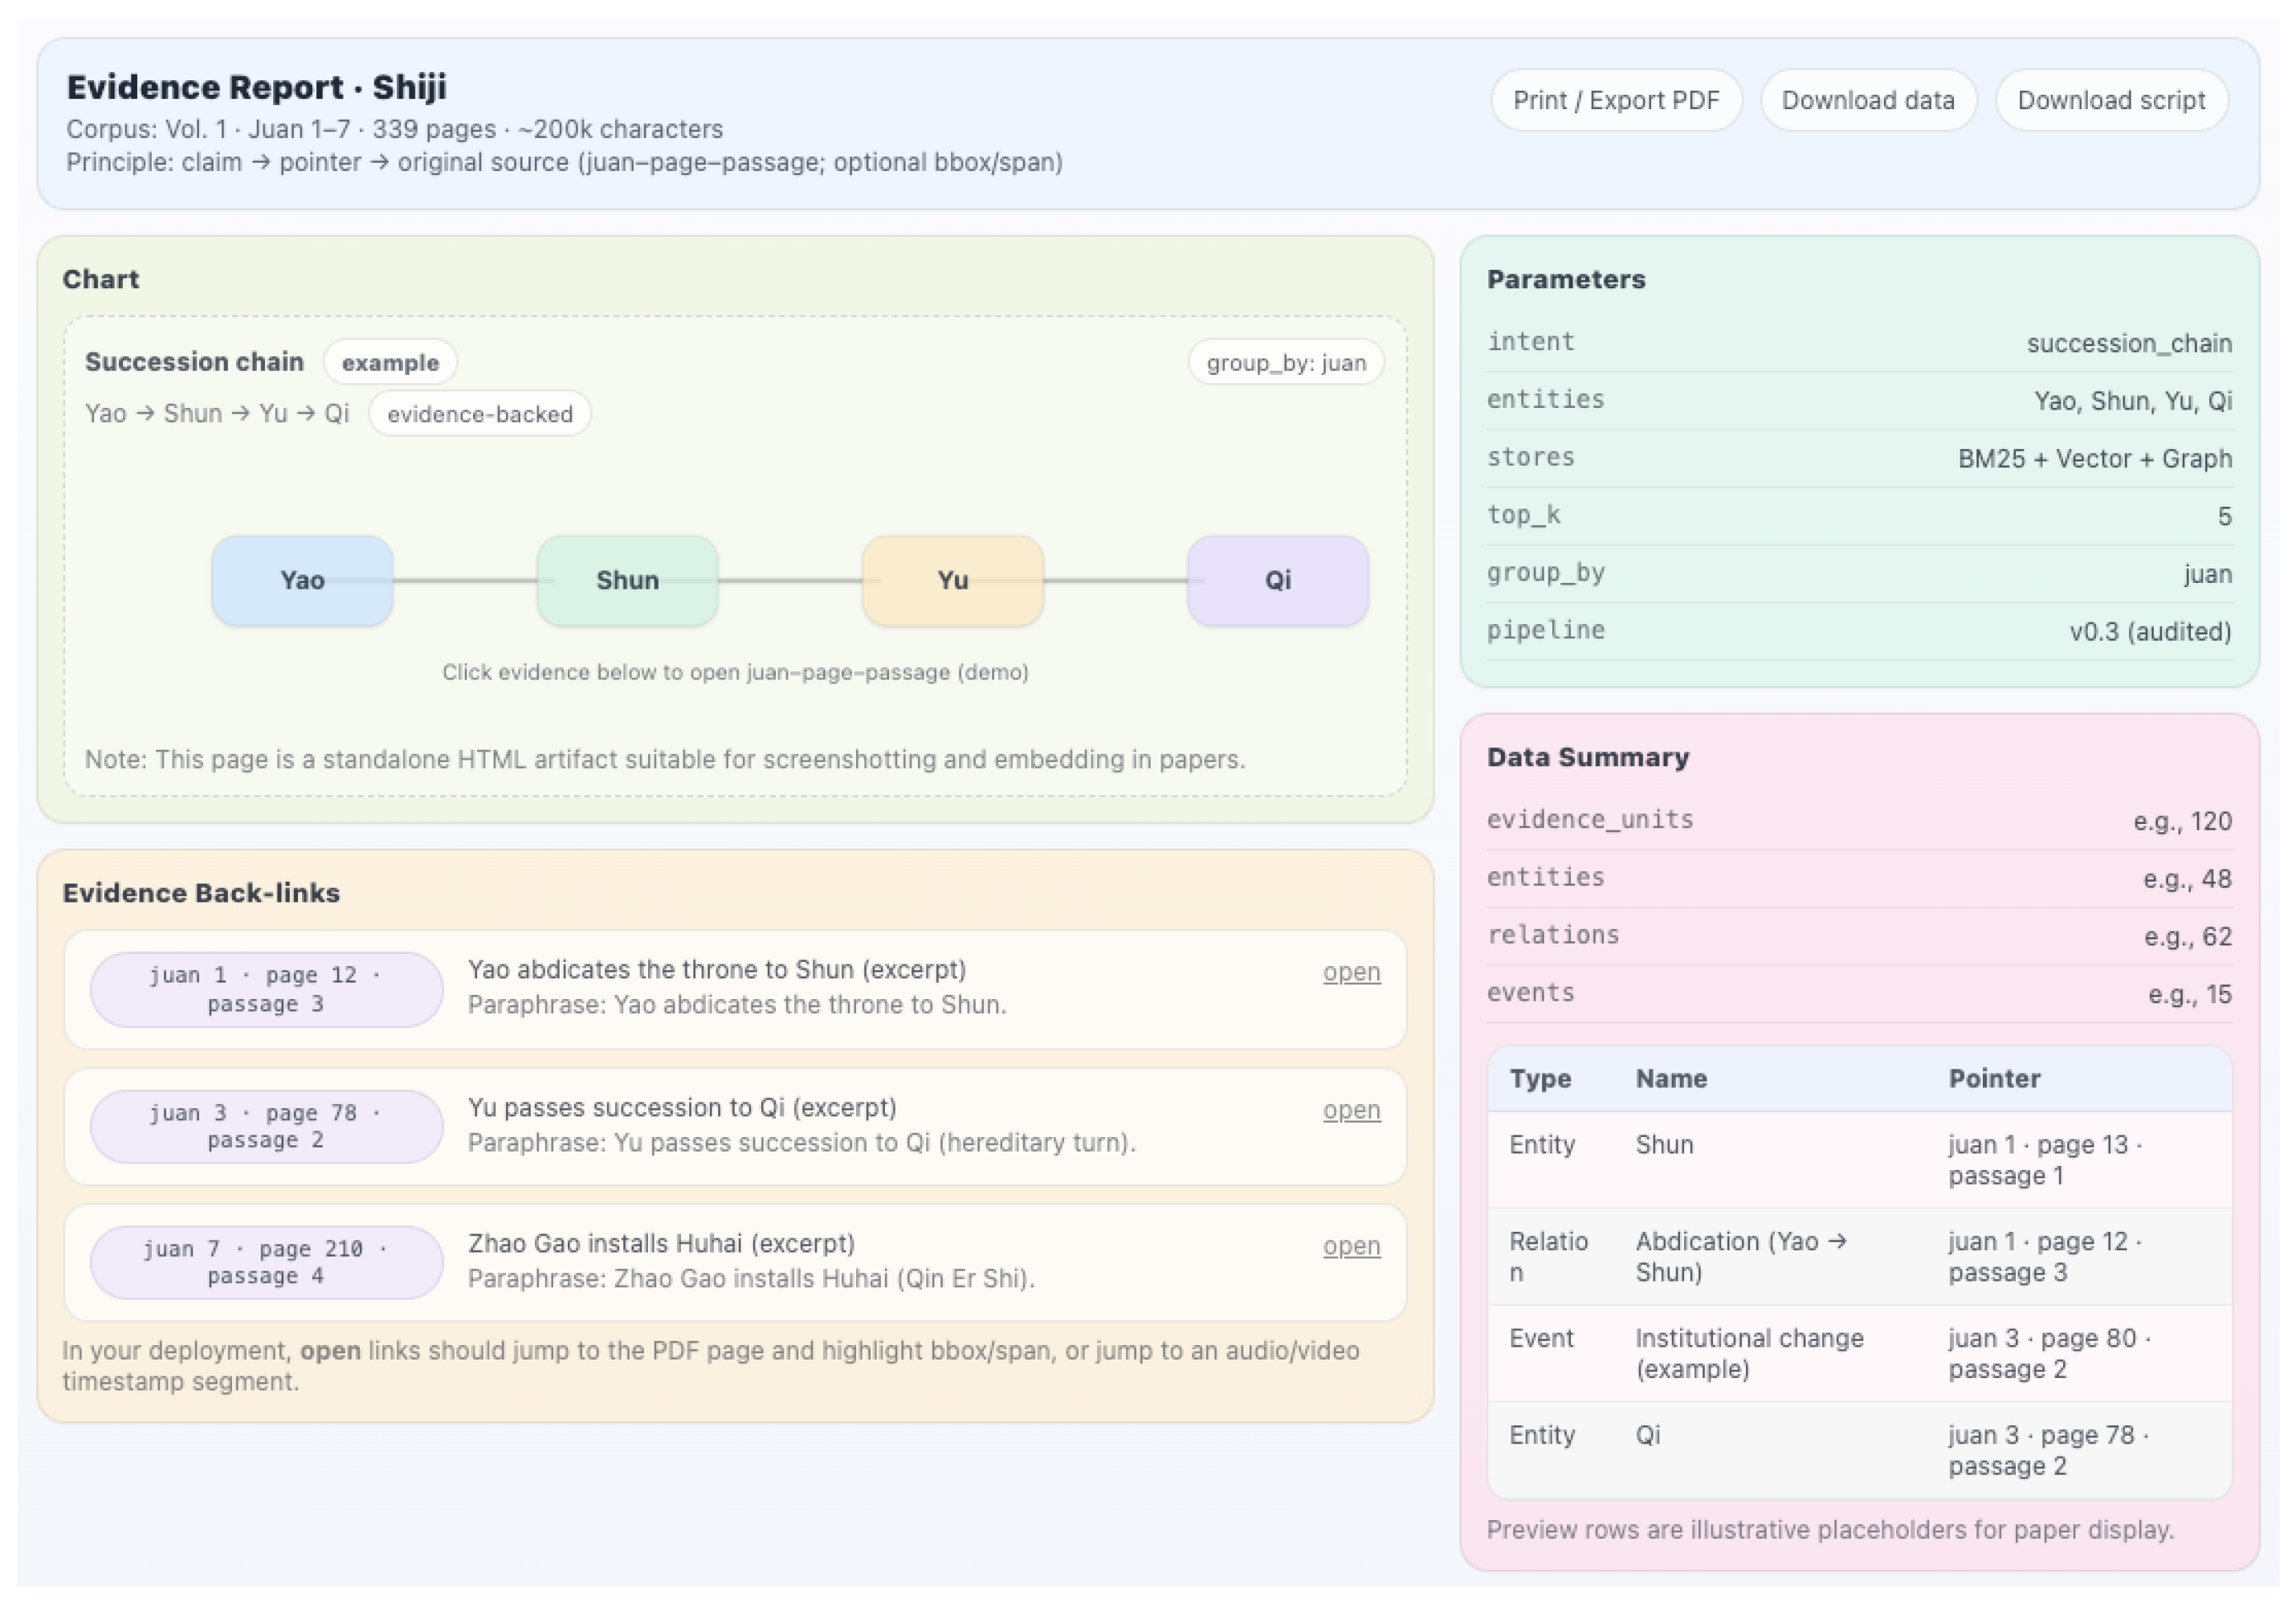
Figure 4.
We construct representative queries covering common scholarly tasks and log their query plans and evidence chains. Example tasks include citation lookup (phrase search with juan filters), alias tracing (graph relations back-linked to evidence units), office/role tracing (path queries with time-expression filters), and comparative reading (grouped evidence lists with explicit uncertainty flags). For reproducibility, the system records audit logs for each session, including the query plan, executed backend calls (full-text/vector/graph), the matched evidence–unit IDs, and the mapping from answer assertions to evidence pointers. Under the same data and pipeline versions, these logs enable re-running the same question to obtain consistent evidence sets and locators. As further illustrated in
Figure 5, the HTML report is designed as an evidence-first scholarly artifact rather than a presentation-only interface. The chart panel provides a compact summary of the current analytical result, while the parameter panel records the query intent, target entities, retrieval stores, and aggregation settings used to generate the output. Most importantly, the evidence back-links panel binds displayed claims to concrete supporting passages through resolvable juan–page–passage pointers, allowing users to inspect the underlying source context directly. The data-summary panel further reports the scope of the underlying evidence units, entities, relations, and events, making the output more transparent, auditable, and reproducible.
4.6. Visualization and Review Loop
We demonstrate that the system translates verifiable evidence structures into reproducible scholarly artifacts and that visualization serves as an argumentation interface rather than mere presentation. The platform supports common humanities visualizations (co-mention networks, timelines, maps, and concept trends), and binds each visualization to explicit provenance: the evidence units, query conditions, aggregation rules, and parameters are stored and displayed. Visual elements (nodes/edges/peaks/pins) provide back-links to juan–page–passage evidence spans, preventing charts from becoming decontextualized secondary narratives.
Implementation-wise, the system uses an LLM to translate visualization intent into controlled data-processing steps and code, and packages results as an HTML report, as shown in
Figure 6. The figure illustrates several typical output templates, including network, timeline, map, and trend views. In each case, the visualization is not treated as a standalone graphic; it remains linked to generation parameters, data summaries, and explicit evidence boundaries. This design allows visual elements to function as entry points for verification and review rather than as decontextualized secondary narratives. The same interface surfaces review queues for low-quality evidence, low-confidence extractions, and high-value relations; reviewers can accept/reject/edit/merge/split records, with all edits logged as auditable diffs and written back to the knowledge base to support continuous improvement.
5. Discussion
5.1. Answers to the Research Questions
The results answer the three research questions in a bounded way. For RQ1, the document-modality evaluation on the annotated Shiji subset shows that the proposed evidence-centric KMS can organize humanities sources into structured, evidence-linked knowledge. The system achieved micro-F1 scores of 0.84 for named entity recognition, 0.78 for relation extraction, and 0.82 for event trigger detection, suggesting that schema-constrained extraction over stable EvidenceUnits can support usable knowledge construction in this setting.
For RQ2, the governance-layer analysis shows that structural validation, evidence-pointer checking, and claim-level verification improve the traceability and admissibility of generated knowledge. Evidence-pointer resolvability increased from 42.3% to 94.2%, while mis-citation and overreach decreased to 4.1% and 5.3%, respectively. However, the C0–C2 comparison is not an independent benchmark among different extraction methods. It should be interpreted as an admission-control analysis showing the effect of successive governance layers.
For RQ3, the system supports auditable knowledge access in the document pathway by linking answers, graph records, and visual outputs back to source EvidenceUnits. The audio experiment provides only preliminary evidence of modality extensibility: timestamped Audio EvidenceUnits can be incorporated into the same governance workflow, but the test does not constitute a full validation of multimodal capability.
5.2. External Validity and Generalizability
The findings should be interpreted within the scope of the evaluation design. The main quantitative evaluation is a controlled document-modality study on an annotated subset of the Shiji. This setting is suitable for testing evidence pointers, schema-constrained extraction, and claim-level verification, but it does not establish that the same performance would hold across all humanities corpora. Materials with unstable pagination, variant editions, complex layouts, handwritten content, damaged scans, multilingual passages, or dense marginalia may pose additional challenges.
The audio component should also be understood narrowly. The oral history experiment is a minimal transcript-mediated smoke test showing that timestamped audio segments can be represented as Audio EvidenceUnits and processed through the same governance workflow. It does not test the full range of multimodal challenges, such as noisy recordings, overlapping speakers, dialectal variation, gesture, image-text relations, or video-based cultural practices.
Accordingly, the generalizable contribution of this study lies primarily in the evidence–governance mechanism rather than in the exact performance values. Stable EvidenceUnits, evidence pointers, schema validation, claim-level verification, review queues, and audit logs can be adapted to other humanities contexts, but their empirical performance should be re-evaluated for each target corpus and research setting.
5.3. Governance for Verifiable Knowledge Production
The point is not to deny the expressive power of generative models, but to argue that, in evidence-intensive historical scholarship, model capability must be embedded in system-level mechanisms that render outputs verifiable. As the results reported in
Section 4.3 indicate, reliance on unvalidated LLM-generated candidates creates instability both at the structural level and at the level of evidence: schema validity and evidence-pointer resolvability remain inadequate, while rates of mis-citation and overreach remain high. By contrast, schema-based constraints and programmatic validation stabilize structural validity, and the addition of claim-level verification further reduces mis-citation and overreach to levels compatible with scholarly verification. This point becomes clearer in comparison with a conventional RAG baseline. Although prompting grounded in retrieved evidence reduces some errors relative to unconstrained generation, it does not by itself guarantee resolvable evidence pointers or reduce mis-citation and overreach to levels appropriate for scholarly verification. The additional gains, therefore, arise from explicit governance mechanisms rather than from retrieval augmentation alone.
A broader implication for knowledge management systems follows from this finding. An LLM should be positioned as a component for candidate generation and orchestration, whose outputs become reusable knowledge resources only after being subjected to structural constraints, evidence alignment, and audit logging. Put differently, the main contribution of the system is not merely to make model outputs more fluent, but to render the conditions under which the system may produce an output, the permissible scope of its generalization, and the evidentiary basis on which its outputs rest computable, verifiable, and accountable properties of the workflow. In doing so, the system transforms generated responses into shareable and reviewable evidence chains.
5.4. Evidence Granularity and Reliability Controls
Evidence units function as a shared evidentiary anchor across ingestion, extraction, retrieval, and presentation, but the granularity of that anchor entails a practical trade-off between verifiability and computational and operational cost [
32]. Overly fine granularity, such as character- or line-level units, increases index size and extraction overhead, while also fragmenting the context needed for comparative reading. Overly coarse granularity, by contrast, reduces the precision of back-linking and increases the burden of verification. Our design adopts paragraph- and sentence-level evidence units with modality-specific locators, including
juan–page–passage locators for documents and start–end timestamps for oral history audio, optionally supplemented by
bbox/span information where available. This balances citational precision with practical scalability while allowing different source types to remain anchored to their original evidentiary objects.
Granularity, however, is best treated as a configurable parameter rather than a fixed design choice. Under noisy recognition or complex layouts, the system can begin with coarser units to preserve retrieval stability and then refine localization within matched pages in a second step. For fine-grained philological tasks, it can increase the granularity of evidence units locally and refer ambiguous cases to human review.
This perspective reflects a reliability-oriented approach to quality control that is particularly appropriate for historical materials: it is often methodologically safer to isolate uncertainty explicitly than to force uncertain materials into premature consolidation. The ablation results indicate that structural constraints can improve schema validity, but that evidence alignment and claim-level verification appear to be the mechanisms that matter most for reducing mis-citation and overreach. Consequently, the long-term reliability of the knowledge base is determined less by incremental improvements in single-pass performance than by evidence–governance mechanisms that prevent errors from being amplified through graph-based inference, statistical summaries, and visualization. As knowledge accumulates within the system, low levels of mis-citation and overreach, together with traceable revision histories, can prove more consequential than marginal performance gains, because the costs of correcting errors after they have propagated often exceed those associated with isolating and reviewing uncertainty earlier in the workflow. The oral history audio smoke test reinforces this point in a different modality: approximately 7% of sentence-level audio segments required manual adjustment, indicating that boundary ambiguity, recognition noise, and speech disfluency should be surfaced as reviewable evidence-quality issues rather than hidden during ingestion.
5.5. Controlled Orchestration for Auditable Knowledge Access
The integration of multiple storage layers and the translation of natural-language requests into executable queries lowers the threshold of access for humanities researchers, but usability must remain matched by procedural control. The unrestricted generation of queries by models introduces risks of non-executable queries, irreproducibility, and unintended access. The system, therefore, restricts query planning to a predefined set of templates with explicit field specifications and return schemas. This preserves the accessibility of natural-language interaction while ensuring that retrieval paths remain traceable, reproducible, and diagnosable. In scholarly research, diagnosable failure is methodologically valuable: when outputs are missing or skewed, researchers can trace the problem to entity linking, overly strict filters, keyword choice, or the limits of semantic retrieval, and can iteratively refine the query plan rather than accepting a single black-box answer.
Visualization is intended to function as an evidence-oriented interface for scholarly argument and verification rather than as a purely presentational device. Network graphs, timelines, maps, and trend plots must retain generation parameters, data summaries, and the boundaries of the underlying evidence set, while allowing visual elements, such as nodes, edges, peaks, and map pins, to link back to modality-specific evidence spans, including juan–page–passage locations for documents and timestamp ranges for oral history audio. This linkage enables rapid verification of questionable relations or notable peaks and positions visualization as a practical interface for quality control. Users can inspect whether a relation reflects recognition noise, extraction error, or disambiguation mistakes, so that corrections can be incorporated back into the governed workflow.
5.6. Limitations and Future Work
Despite the reductions in mis-citation and overreach achieved through evidence binding and audit mechanisms, several structural limitations remain. First, multimodal ingestion noise exhibits a “structural amplification” effect: systematic OCR and layout-segmentation biases can propagate into entity extraction and citation localization, thereby affecting retrieval, aggregation, and downstream interpretation; ingestion quality remains a primary upper bound. Second, editorial and versioning issues in historical studies are not purely technical: differences across editions and manuscripts, taboo characters, variant glyphs, and layered marginalia require richer edition metadata and citation standards. The system can store version metadata and support side-by-side evidence comparison, but the scholarly judgment of which version to privilege depends on research goals and community norms. Third, even with evidence pointers, a model can still exhibit evidence illusion: citing a relevant passage while attributing a stronger interpretation than the text warrants, or blending conditions across multiple passages into an overly specific conclusion. A practical mitigation is to decompose answering into an evidence list, a structured summary, and a constrained conclusion with explicit coverage checks at the claim level.
Regarding external validity, the reported quantitative values are specific to the controlled Shiji subset and should be re-estimated for other corpora, genres, scripts, layouts, and media conditions. The audio experiment remains a minimal transcript-mediated smoke test rather than a comprehensive multimodal evaluation. Future work will therefore pursue three directions: (i) extending the evaluation protocol to additional corpora and source modalities while retaining evidence traceability, mis-citation/overreach, conflict surfacing, and query-plan executability as system-level governance indicators; (ii) strengthening human-in-the-loop learning by converting review decisions into reusable lexicons, disambiguation rules, and domain constraints; and (iii) developing more standardized locator schemes for complex layouts, edition-critical materials, and time-based media under auditable governance and deployment constraints.
6. Conclusions
This paper presents an evidence-centric knowledge management system for historical humanities research. Instead of treating a large language model as a tool for producing free-form answers, the system places generation within a controlled workflow centered on evidence units, explicit locators, schema-constrained extraction, and auditable retrieval. In this design, the value of generation lies not in producing fluent summaries alone, but in supporting knowledge organization and access under conditions of traceability and verification.
The main empirical study reported here focuses on a controlled subset of Shiji. Within this document-modality setting, the results show that the proposed workflow can support stable extraction of entities, relations, and events from historical materials. More importantly, the ablation study shows that governance mechanisms make a substantial difference to reliability. Schema validation and programmatic checks improve structural compliance and evidence-pointer resolvability, while per-claim verification further reduces mis-citation and overreach. The comparison with a conventional RAG baseline points in the same direction: retrieval alone helps, but it does not provide the level of traceability and error control required for scholarly use. In addition, the minimal Yi oral history audio smoke test suggests that timestamp-resolvable Audio EvidenceUnits can be incorporated into the same evidence-governance workflow, providing preliminary evidence of audio-modality portability beyond the document pathway.
In evidence-intensive historical and humanities research, the main contribution of large language models does not lie in unconstrained generation, but in their integration into workflows that make claims inspectable, evidence links explicit, and errors easier to detect and correct. At the same time, the present study should be read primarily as a mechanism-oriented validation in a document-based setting, supplemented by a small transcript-mediated audio feasibility test, rather than as a full evaluation across all modalities supported by the architecture. Further work should therefore extend the analysis to additional corpora, modalities, and research contexts while preserving the same emphasis on evidence governance, provenance control, auditability, and human review.