


Abstract
Membrane computing, and more specifically P systems, has been a useful tool in the simulation of biological systems, both at the biomolecular and cellular levels, and also in microbial and ecological communities. The need for greater realism in the simulations of these systems has been growing in the recent years. Thus, it has become clear that the rules, objects and structures of P systems cannot always be useful to model some aspects of biological systems. Specifically, some aspects of population dynamics were not perfectly reflected in the P systems that supported these models. In this work we propose new types of rules that help to model some aspects of biological systems in a more realistic way. Fundamentally, our proposal focuses on the use of probabilistic parameters that help create probabilistic and stochastic models for biological systems. In addition, given the high complexity of some of these systems, in this work we describe two software tools that we have developed and that help in the validation and debugging of these systems.
1. Introduction
The intersection of computer science and biology has led to significant advancements in understanding complex biological systems, and the proposal of new ways of computing. Natural computing [1] has given rise to models inspired by biological phenomena, encompassing fields like evolutionary algorithms, artificial neural networks, and molecular computing. These models draw from natural selection, brain function, and molecular interactions, respectively, to solve complex problems in innovative ways. In particular, membrane computing, introduced by Gh. Păun [2,3], stands out as a groundbreaking approach inspired by the architecture of living cells. Membrane computing abstracts from the cell structure and its internal processes, envisioning each compartment as part of a computational unit. P systems formalize this concept, employing a membrane structure to represent the hierarchical organization of cells and using objects and evolution rules to simulate biochemical interactions. The computation within P systems unfolds through the nondeterministic and parallel application of these rules, demonstrating remarkable computational capabilities.
Membrane computing has evolved rapidly, leading to the development of P system models that offer a unique lens through which to view computational processes akin to those within eukaryotic cell membranes. These models, while powerful, continually adapt to capture the intricate dynamics of biological simulations more accurately. P systems are traditionally defined by a formal set of rules dictating the interactions and transformations within bio-inspired models. While potent, these rules frequently require evolution to match the growing complexity and nuanced needs of biological simulations.
In the realm of computational biology, membrane computing, particularly through P systems, has emerged as a very suitable tool for modeling and simulating complex biological processes [4,5,6,7,8]. Since its origins, membrane computing has led to the proposal of simulation models for biological systems. We can mention the works aimed at simulating photosynthesis processes [9], leukocyte recruitment [10], cell signalling networks [11], dynamics of HIV infections [12], gene regulatory networks [13], cell activation [14], thermoreceptor models [15], or plant development [16], among others. We must also highlight the work developed by the Seville team in the field of ecology, which has proposed new algorithms, membrane structures and stochastic and probabilistic P systems [17,18,19,20,21,22,23]. In the last years, some works have focused in the use of membrane computing and P systems for epidemics, such as those related to antibiotic resistance [24], COVID-19 [25] or, recently, to sexually transmitted infections [26]. Some works on the ecological environment of sensitive species has also been recently shown [27,28,29]. The Mitogen-Activated Protein Kinases (MAPK) cascade modeling [30], a hypergraph cell membrane computing network model for soybean disease identification [31], a membrane computing model for the diel vertical migration [32] or a prediction model for esophageal cancer survivor [33] can be referred as recent works on membrane computing related to systems biology, among others.
In our works on systems biology, we have found limitations within the existing P system rules framework, underscoring the necessity for innovation. Let us take, as an example, the modeling and simulation of the immune system in the face of vaccination processes. While P systems lay a solid foundation, the intricacies of the immune system modeling demand a more customized approach. In the human immune system’s response to vaccines and viral infections modeling, organs and cells can be modeled as membranes within the P system, while key entities like interleukins and immunoglobulins can be portrayed as objects, in an effort to accurately represent biological processes [34,35,36]. P system rules must represent the interactions between membranes and objects, allowing for movements such as object migration, duplication, and replication, thus mimicking biological processes. For instance, in the central nervous system, the interleukins before and after vaccination or infection are simulated as objects in the P system. These interleukins, are originated from various organs or they are generated in response to other object interactions. They reflect biological activities occurring in the body.
This realization drives the development of new rules within the P system paradigm, seeking to close the gap between theoretical models and the practical requirements of biological simulations. We propose in this work a new kind of rules to manage empty membranes. That is a critical aspect in some biological systems modeling that has been overlooked in membrane computing. We also propose new parameters in the probabilistic rules, to enable a more nuanced simulation of biological interactions that are stochastics.
In addition, we show new computational tools for visualizing membrane structures and the dependencies of P system rules that are of great help when modeling extremely complex systems. These tools are useful to the designers during the debugging and validation of computer simulators using membrane computing.
By advancing the P system rule set and introducing new tools to visualize these computational models, this work seeks to narrow the gap between theoretical constructs and their practical application in simulating biological systems. Our objectives are threefold: to innovate new rules and definitions for modeling cellular dynamics in biological systems, to enhance the computational capabilities of P systems for complex biological simulations, and to develop visualization tools for membrane computing, thereby providing a comprehensive platform for the exploration and understanding of biological processes through membrane computing.
The structure of this work is as follows: Section 2 provides the basic P system definition. Section 3 introduces extended rule syntax including empty membrane rules, catalysts, time semantics, conditional gating, and probabilistic parameters. Section 4 demonstrates these extensions through an RSV infection illustrative example. Section 5 presents visualization tools for rule networks and membrane structures. Finally, Section 6 discusses implications and future directions.
2. A Basic Definition
In what we will show below, we assume that the reader is familiar with the basic concepts of membrane computing. The only basic definition that we need in the rest of this work to describe new rules and behaviors comes from [37] as follows.
Definition 1.
A P system with active membranes of degree is defined by the tuple where
- 1.
- O is the alphabet of objects
- 2.
- H is the alphabet of labels for membranes
- 3.
- μ is the initial membrane structure, of degree m, with all membranes labeled with elements of H and no polarizations. A membrane with label h is represented as []h
- 4.
- are strings over O specifying the multiset of objects present in the compartment of μ
- 5.
- R is a finite set of rules of the following types
- (a)
- with (evolution rules)
- (b)
- with (‘in’ communication rules)
- (c)
- with (‘out’ communication rules)
- (d)
- with (membrane creation with object evolution)
For any alphabet of objects O, the multisets of those objects are denoted by strings of the set that include the empty string, which can be considered the empty multiset. - 6.
- indicates the region where the result of a computation is obtained (0 represents the environment).
The rules of the P system are applied in a non-deterministic maximally parallel manner, and the computation of the system ends whenever no rule can be applied. A configuration of the system at an instant t during a computation is defined by the membrane structure and the multiset of objects at every compartment in .
The use of P systems for modelling and simulating real-life processes limits the concept of computation to a maximum number of steps that reflect the time scale of the real phenomenon to be simulated. Thus, in the rest of this work, when we talk about a computation in a P system, we will not necessarily consider halting conditions but rather a maximum number of computation steps necessary to obtain a simulation of a real phenomenon.
3. New Membrane Computing Rules for Systems Biology Modeling
This section introduces our extended rule framework for modeling complex biological systems. We present: (1) general rule syntax and descriptive annotations, (2) time semantics and conditional gating, (3) catalyst notation (pooled and distributed), (4) four probabilistic parameters (IPP, RPI, RP, EPP) and their interaction algorithm, and (5) empty membrane rules ().
3.1. Formal Syntax of Extended Rules
We first define the general syntax for rules with properties.
Definition 2
(Extended Rule Format). Let be a P system. An extended rule has the form:
where:
- α (the left-hand side or input) specifies the preconditions for rule application, typically involving objects and/or membranes;
- β (the right-hand side or output) specifies the result of applying the rule;
- are property keys;
- are the corresponding property values, whose domains are defined below;
- C (optional conditional gating) is a boolean expression controlling rule applicability based on system state (object counts, global time, etc.); if omitted, the rule has no conditional constraint. Formal semantics are provided in Section 3.4.
The property specification is optional. A rule without properties or conditions follows the standard P system semantics.
For example, in the rule two objects a inside the membrane produce a new object b. Hence, the input establishes the required conditions to apply the rule while the output defines the expected result from applying the rule.
3.2. Descriptive Annotations
In complex biological models, documenting the purpose and biological interpretation of rules becomes essential for model validation, debugging, and collaboration. We introduce three descriptive annotation properties that provide human-readable metadata without affecting rule execution semantics.
Definition 3
(Descriptive Annotation Properties). The following properties assign descriptive metadata to rules for documentation, visualization, and debugging purposes:
- name: A unique identifier for the ruleThis property distinguishes between rules that have similar or identical left-hand sides but represent different biological processes or produce different outputs.
- process: A biological process category or pathway identifierThis property classifies rules into functional groups (e.g., “viral_replication”, “cytokine_ signaling”, “cell_death”) to facilitate analysis and visualization of pathway-specific dynamics.
- desc: A free-text description of the biological meaningThis property provides a human-readable explanation of what the rule represents biologically, including relevant literature references, assumptions, or modeling decisions.
These annotations are optional and do not affect rule applicability, priority, or execution. They are primarily used by visualization tools (see Section 5) and for model documentation.
Example 1.
A viral protein synthesis rule with descriptive annotations:
These annotations help identify the rule in debugging output, group it with other viral replication rules in pathway visualizations, and document its biological interpretation for model validation.
3.3. Time Semantics
It is expected that every rule requires some time to produce the output. Time property can be specified with time units (e.g., seconds, minutes, hours, …). According to the time units, universal and local clocks should be introduced in the P system to trigger the different events for producing the outputs.
Definition 4
(Time Property and Timed Rule Semantics). The time property specifies the duration required for a rule to produce its output:
All rules must specify a positive time value that respects the minimum clock resolution unit. The semantics of timed rules are as follows:
- 1.
- At time t, if rule r is applicable and selected for execution, the input objects/membranes specified in the left-hand side are consumed immediately and marked as reserved.
- 2.
- The output specified in the right-hand side becomes available at time .
- 3.
- During the interval , the consumed objects are not available for other rules.
- 4.
- At time , the output objects/membranes are added to the system and become available for subsequent rules.
A global or local clock mechanism is introduced in the system to track elapsed time and trigger delayed outputs. The time unit of a computation step should be at most the minimum time value among all timed rules: .
For example, the following rule models viral protein synthesis taking two hours to complete:
The viral mRNA molecules are consumed at time t, and 5 viral proteins appear in the cell membrane at time .
3.4. Conditional Gating
Biological systems exhibit complex regulatory logic where reactions occur only under specific conditions. Temporal predicates model processes with activation windows or delays (i.e. circadian rhythms, or infection phase transitions), and time-based events such as scheduled drug administration. Object count thresholds capture gating phenomena like quorum sensing and concentration-dependent activation. Boolean connectives express regulatory logic while remaining read-only to preserve multiset dynamics. Conditional gating controls rule applicability through boolean predicates over system configuration (object counts and/or global time).
Definition 5
(Conditional Expression). A conditional expression C for a rule r is a boolean predicate evaluated in the current configuration σ:
where Σ is the set of all possible system configurations. A rule r with condition C is applicable only if , in addition to satisfying its left-hand side requirements.
Syntax and Scope
Let denote the multiplicity of object in membrane labeled . Nested references use dot-notation, e.g., denotes object a in membrane z inside membrane x. Let t denote the global simulation time expressed in the base time unit. Time literals in conditions may specify explicit units ; if omitted, the value is interpreted in the configured base unit.
Boolean expressions are built from atomic predicates using logical connectives:
- Atomic numeric constraints: , ,
- Temporal constraints: , , , ,
- Connectives: , , with parentheses for grouping
Definition 6
(Condition Evaluation Semantics). Given rule r with condition C, a configuration satisfies C iff under the standard interpretation:
- Object counts: is the multiplicity of o in the multiset of membrane m
- Time: t is the current global time
- Read-only: condition evaluation does not consume objects nor change t
Example 2
(Scheduled drug administration).
Drug dose administered exactly at 6 h post-treatment.
Example 3
(Delayed adaptive response).
Th1 differentiation occurs only after day 5, representing delayed adaptive immunity onset.
Example 4
(Object count threshold).
Cytokine redistribution occurs only when concentration thresholds are met.
3.5. Catalysts
In biological systems, catalysts (such as enzymes) facilitate reactions without being consumed in the process. To accurately model such phenomena, we introduce catalytic behavior notation that specifies when objects act as catalysts in specific rules. Similar to the approach described by [2,8], we define:
Definition 7
(Pooled Catalyst Notation). A pooled catalyst is indicated by a single backtick (‘) appended to an object in a rule’s left-hand side. Given an object appearing as in a rule’s left-hand side:
- The rule requires at least n copies of object c to be present in the membrane for the rule to be applicable.
- These n catalyst objects are not consumed by this specific rule application.
- The same n catalyst objects can support all parallel applicatio of this rule in a single computation step.
- Formally, for a rule r with pooled catalyst , the rule is applicable in membrane h with configuration if and only if , where denotes the multiplicity of object c in multiset .
- After applying rule r: if and r contains catalyst , then (the count of c is unchanged by r).
Example 5.
Consider ATP acting as a catalyst in a phosphorylation reaction, while also being consumed in other cellular processes:
Rule 1 (ATP as pooled catalyst):
Rule 2 (ATP consumed for energy):
If membrane contains 10 ATP, 6 glucose, and 2 ADP molecules:
- Rule 1 can be applied 3 times in parallel (), sharing the same 4 ATP molecules (pooled catalyst). After execution: 10 ATP remain, 0 glucose remain, 6 G6P produced.
- Rule 2 can be applied 1 time (limited by 2 ADP). After execution: 8 ATP remain, 4 ADP total, 1 energy produced.
The same object (ATP) acts as a catalyst in Rule 1 but is consumed in Rule 2.
Definition 8
(Distributed Catalyst Notation). A distributed catalyst is indicated by a double backtick (“) appended to an object in a rule’s left-hand side. Given an object appearing as in a rule’s left-hand side:
- Each parallel application of this rule requires its own n copies of object c.
- The catalyst objects are not consumed by this specific rule application.
- If the rule is applied k times in parallel, then catalyst objects must be present.
- Formally, for a rule r with distributed catalyst applied k times in parallel in membrane h, the rule is applicable in membrane h with configuration if and only if , where denotes the multiplicity of object c in multiset .
- After applying rule r: if and r contains catalyst , then (all catalyst objects remain).
Example 6.
Consider ribosomes acting as distributed catalysts for translation, while being produced by ribosome biogenesis:
Rule 1 (Ribosome as distributed catalyst):
Rule 2 (Ribosome production):
If membrane contains 3 ribosomes and 8 mRNA molecules:
- Rule 1 can be applied only 3 times in parallel (limited by 3 ribosomes, since each parallel application requires its own dedicated ribosome). After execution: 3 ribosomes remain (not consumed), 5 mRNA remain, 3 proteins produced.
- New ribosomes can be added to the system via Rule 2.
If we had used pooled catalyst notation then with 1 ribosome and 8 mRNA molecules, all 8 mRNA would be translated in one step (all sharing the same ribosome), which is biologically unrealistic since each ribosome can only process one mRNA at a time.
Catalyst notation provides an explicit and formal mechanism to indicate that certain objects are required for a rule to be applicable, yet are not consumed during its execution. While the resulting computational behavior may resemble that of promoters as introduced in [8], the underlying biological interpretation can differ: catalysts typically represent reusable entities such as enzymes, whereas promoters/inhibitors often correspond to regulatory signals that enable or block reactions. Notably, the effects of promoters and inhibitors can be modeled directly and flexibly using the conditional gating framework described in Section 3.4, allowing for complex regulatory logic based on object counts, temporal conditions, or combinations thereof.
3.6. Probabilistic Parameters
The use of P systems to model biological phenomena involves giving them a probabilistic or stochastic flavor. Therefore, the rules must establish a probability that determines whether they will be executed under the appropriate conditions. If the input conditions are met (that is, the objects or membranes specified in the left-hand side of the rules are present), the rule is applied as long as there is no other competing rule. However, in the simulation of real phenomena, it is not a fact that the rule will be executed every time those conditions are met. This is where probability comes into play, adding a layer of realism to simulations by recognizing that biological processes do not always follow a simple, deterministic path.
In the following section, we discuss how the system can define the probabilities so that any simulator based on membrane computing obtains realistic results of biological phenomena.
3.6.1. Input Population Percentage (IPP)
This is a crucial aspect of the rule enhancements for P systems to model biological systems. IPP specifically addresses the variability in the number of objects and membranes contained within a single membrane, which can range from a few to millions. The rules in P systems apply uniformly to the objects or membranes defined in their left-hand side. This universal application may not always align with the desired simulation outcomes, particularly in complex biological processes where interactions often occur on a probabilistic rather than a deterministic basis.
Definition 9
(Input Population Percentage (IPP)). The Input Population Percentage parameter controls what fraction of eligible objects participate in a rule application:
Given a rule r with and a multiset M of eligible objects in membrane h where :
- 1.
- The number of selected objects is .
- 2.
- The k objects are selected uniformly at random without replacement from M.
- 3.
- The rule r is applied only to the selected subset of k objects.
- 4.
- The remaining objects in M are unaffected by this rule application.
Formally, if and , then a random subset with is selected, and the rule operates on rather than M.
IPP models scenarios where not all molecules or cells in a population respond to a stimulus. For example, only a fraction of T cells may be activated by an antigen, or only some enzyme molecules may be in the correct conformational state to catalyze a reaction.
Example 7.
The following rule models the apoptosis of a subset of activated T cells during immune contraction. It is applied to only 20% of the activated T cell objects in the lymph node membrane. Hence, 20% of the T cells undergo programmed cell death and are removed from the lymph node, while 80% survive and maintain the memory T cell pool.
3.6.2. Rule Priority Index (RPI)
Definition 10
(Rule Priority Index (RPI)). The Rule Priority Index resolves conflicts when multiple rules are simultaneously applicable to the same objects:
Given a set of rules all applicable to the same multiset of objects in membrane h at time t:
- 1.
- Randomly shuffle the rule set to achieve non-deterministic execution order and break any systematic ordering bias.
- 2.
- Sort the shuffled rules by their RPI values in ascending order (lower RPI = higher priority), using a stable sort to preserve the random order for rules with equal RPI.
- 3.
- Apply rules in the sorted order, with highest-priority rules (lowest RPI values) considered first.
- 4.
- Rules with the same RPI value are considered in random order (due to the initial shuffle and stable sort).
RPI addresses scenarios where multiple rules compete for the same resources, requiring controlled execution order. This is essential when rules simulate transport of objects to different locations or when object concentrations indicate different biological states requiring distinct responses. By assigning priority levels, RPI ensures critical actions execute first, preventing unintended resource distribution or misinterpretation of system state. In our proposal, the lowest RPI value means the highest priority. RPI can be used to models biological pathway priorities, such as T cell differentiation preferences (Th1 over Th2 under specific cytokine conditions) or DNA repair pathway hierarchies based on damage severity.
Example 8.
Let us consider a rule designed for a biological process: In the rule , the presence of specific quantities of interleukins ( objects) and tumor necrosis factors ( objects) within the membrane triggers the addition of the object , denoting a sharp pain response. The assigned RPI of 1 indicates that this rule takes precedence over the rest of the rules, ensuring that it is applied first to accurately represent severe biological conditions.
The rule produces an object that means a normal response based on the object concentrations of interleukins and tumor necrosis factors. The rule has a RPI value equals to 2, and it will be applied only if there is no other competing rule with higher priority, that is RPI = 1.
3.6.3. Rule Probability (RP)
Definition 11
(Rule Probability (RP)). The Rule Probability parameter determines whether an applicable rule actually fires:
Given a rule r that is applicable (all input conditions satisfied and priority constraints met) with :
- 1.
- Generate a random number .
- 2.
- If , the rule r fires (is applied).
- 3.
- If , the rule r does not fire (is skipped in this computation step).
This is equivalent to a Bernoulli trial with success probability p.
This parameter associates a probability to the rule application whenever it meets the input conditions. RP models stochastic reactions that occur with certain probabilities even when substrates are present. Examples include probabilistic binding events, spontaneous membrane fusion, or stochastic gene expression where transcription factors are present but transcription is not guaranteed.
Example 9.
The following rule models dendritic cell maturation triggered by pathogen detection. The rule will be applied 90% of times whenever it can be applied (RP = 0.9),
3.6.4. Entity Population Percentage (EPP)
Definition 12
(Entity Population Percentage (EPP)). The Entity Population Percentage is a pre-computation parameter that selects which rules are available before the P system computation begins:
Given a set of mutually exclusive rules (or rules with the same left-hand side but different behaviors) where each has :
- 1.
- Before computation starts, compute the total EPP: .
- 2.
- For each rule , its selection probability is .
- 3.
- Select rule with probability , or select none with probability (if ).
- 4.
- Only the selected rule is included in the rule set for this computation.
- 5.
- The other rules in are excluded entirely from this computation.
- 6.
- This selection happens once per computation (simulation run), not per computation step.
EPP models inter-individual genetic or phenotypic variation in population dynamics by enabling different rule sets across computations. This pre-computation parameter allows simulations of identical scenarios to produce distinct outcomes based on rule availability, where each rule’s EPP value determines its selection probability for an entire computation. EPP captures biological heterogeneity such as metabolic enzyme polymorphisms (e.g., lactase persistence), immune receptor repertoire diversity, or drug response variation due to genetic differences. When simulating populations, each individual (computation) has rules selected according to EPP probabilities, creating realistic population-level heterogeneity.
Notation convention: Rules with EPP parameters that form mutually exclusive sets use the naming convention XX.1, XX.2, etc., where the common prefix (XX) identifies the set and the numeric suffix distinguishes individual variants.
Example 10.
The following example shows how EPP is applied in the system modeling and simulation. Let us consider the following two rules representing genetic variation in cytokine response:
Rules RIV.1 and RIV.2 represent alternative immune response phenotypes with identical left-hand sides. Rule RIV.1 () models a low-responder phenotype producing anti-inflammatory IL-10, selected in 10% of individual simulations. Rule RIV.2 () models a high-responder phenotype producing pro-inflammatory IL-12, selected in 80% of simulations. The remaining 10% of individuals have neither rule available, representing intermediate or mixed response patterns.
The previous example demonstrates the utility of , that is getting the unique profiles or scenarios over the population and flexibility of the P system rules to accommodate the diversity of biological responses among different entities or individuals.
3.7. Parameter Interaction and Execution Order
The four probabilistic parameters operate at different stages and must be applied in a specific order to ensure correct semantics. In addition, rule condition gating (Section 3.4) precedes probabilistic and priority handling:
- EPP (Entity Population Percentage): Applied before computation starts (pre-computation phase). Selects which rules from mutually exclusive groups are available for this entire computation.
- RPI (Rule Priority Index): Applied at the beginning of each computation step. The active rule set is randomly shuffled to achieve non-deterministic execution order, then sorted by RPI in ascending order using stable sort.
- Conditions and Input Requirements: Applied for each rule in sorted order during the main simulation loop. Each rule is checked for applicability based on input objects/membranes and condition evaluation.
- RP (Rule Probability): Applied for each applicable rule to determine if the rule actually fires.
- IPP (Input Population Percentage): Applied if the rule fires to select what fraction of eligible objects participate in the reaction.
The execution order described above is formalized by using the Algorithm 1, which is detailed below.
| Algorithm 1 Probabilistic Rule Execution Algorithm |
|
This ordered execution ensures that:
- EPP creates population-level diversity (different individuals have different rule sets)
- RPI establishes execution priority
- Conditions and input requirements gate applicability for each rule in the main loop
- RP introduces stochasticity in rule firing (probabilistic reactions)
- IPP models partial population responses (not all molecules/cells react)
3.8. Empty Membrane Rules
Considering a scenario of an empty cell, where a membrane devoid of objects which, in biological terms, would typically die (if it is a living cell), or it should be dissolved (if it is an organelle or a vesicle). In the standard P systems, a membrane can be dissolved if the objects in the left-hand side of a dissolution rule are in the region. Then, the objects in the region of the dissolved membrane move to the parent region. However, our approach is focused on what happens if a membrane is empty, representing a cell with no functional components that would not be viable. To address this, we introduced the phi symbol (), representing the absence of objects in the referred region.
For example, an empty membrane that dissolves can be represented as
Observe that the symbol ∂ is used to preserve the criterion that every rule has a left part and a right part, and it has no object meaning. This rule not only aligns with biological understandings of cellular behavior but also significantly enhances the P system capacity to simulate these processes more accurately.
The symbol can also be used in conjunction with other objects, in those cases it represents an only if condition, for example the following rule:
This rule only dissolves membrane X if it only contains the objects defined by v. This kind of rules is very useful in systems biology, for example when modeling the cellular destruction caused by viruses once they have replicated within a cell.
Example 11.
Consider a P system modeling viral infection where membrane represents an infected cell. After viral replication, the cell contains only viral particles and is no longer viable. The rule:
models cell lysis: the cell (membrane) dissolves when it contains exactly 100 viral particles and nothing else, releasing the viruses to the extracellular environment (parent membrane).
4. Illustrative Example: RSV Infection and Immune Response
This section demonstrates how the proposed P system extensions work together to model biological systems. We present a simplified model of Respiratory Syncytial Virus (RSV) infection and the subsequent immune response, prioritizing feature demonstration over biological completeness.
4.1. Biological Background
RSV infection triggers a multiphasic immune response characterized by distinct temporal dynamics [34,36]. Through our simplified model, we capture the key phases of this response and model infection progression through three phases:
Early Innate Response (0–24 h): Upon viral entry into epithelial cells, infected cells rapidly produce type I interferons (IFN- and IFN-) as the first line of defense. This innate response establishes an early antiviral state in surrounding tissues [36].
Intermediate Replication Phase (1–5 days): During this period, the virus replicates within infected cells, eventually causing cell lysis and release of viral particles. Antigen-presenting cells (APCs) process viral antigens and migrate to lymphoid tissues, initiating adaptive immunity [35].
Adaptive Response (>5 days): The adaptive immune system becomes fully engaged. Naive T helper cells (Th0) differentiate into Th1 or Th2 subsets depending on the cytokine environment, with IL-12 promoting Th1 and IL-4 promoting Th2 polarization. CD8+ cytotoxic T cells eliminate infected cells, while B cells produce neutralizing antibodies [35,36].
This example models these processes to demonstrate:
- Empty membranes (): Cell lysis when only viral particles remain
- Pooled catalysts (‵): ATP-dependent metabolic reactions
- Distributed catalysts (‵‵): Ribosome-mediated translation (one mRNA per ribosome)
- Time conditions: Phase transitions (innate < 24 h, adaptive > 5 days)
- Count conditions: Threshold-based activation (T cell activation requires APC ≥ 3)
- Combined conditions: Scheduled therapeutic interventions (drug at h if viral load ≥ 100)
- IPP: Partial T cell migration to infection sites
- RPI: Th1 vs. Th2 differentiation priority based on cytokine signals
- RP: Stochastic cytokine secretion by activated cells
- EPP: Individual immune response variation (high/low responder phenotypes)
4.2. P System Definition
The RSV infection model is formally defined as:
where , , and .
Objects:
Membrane structure:
with hierarchy:
Initial configuration:
The environment (Env) serves as the output region (), representing the extracellular space. Simulation clock resolution is 1 min and base time unit is minutes.
4.3. Rule Descriptions
The model employs 21 main rules organized into 10 groups, each demonstrating specific framework features. Table 1 summarizes all rules with their biological interpretations.
Table 1.
Summary of RSV infection model rules with biological interpretations.
4.3.1. Empty Membrane Dissolution
R01: Infected cell lysis
When an epithelial cell contains only viral particles (50 or more) with no functional cellular components remaining, the membrane dissolves, releasing viruses to the environment in 1 min. This demonstrates the predicate for representing cell death.
4.3.2. Pooled Catalyst Reactions
R02: ATP-dependent interferon production
Five ATP molecules catalyze the production of 3 IFN- molecules in response to viral presence. The pooled catalyst ‵ allows the same ATP pool to support multiple simultaneous reactions. Execution time is 120 min (2 h).
R03: ATP-dependent viral replication
Viral protein synthesis from mRNA requires ATP as an energy source. The vmRNA template is preserved for multiple rounds of translation, modeling the biological reality that mRNA templates are reused rather than consumed. The reaction takes 180 min (3 h) and demonstrates pooled catalysis where ATP availability rate-limits production.
4.3.3. Distributed Catalyst Translation
R04: Ribosome-mediated viral protein translation
Each ribosome translates one viral mRNA molecule to produce 3 viral proteins. The distributed catalyst enforces 1:1 stoichiometry between ribosomes and mRNA substrates. Takes 60 min (1 h).
R05: IL-12 cytokine translation
IL-12 protein synthesis occurs in the lymph node via ribosome-dependent translation of IL-12 mRNA. Each ribosome produces 2 IL-12 protein molecules from one mRNA template over 30 min. This demonstrates translation in a different compartment (lymph node vs. epithelial cell).
4.3.4. Time-Based Conditions
R06: Early viral infection and innate response
Viral infection produces viral mRNA (vmRNA) for replication along with interferon- as an innate immune response. This occurs only during the first 1440 min (24 h) post-infection. Each infected virus particle generates 2 vmRNA molecules and triggers 1 IFNb molecule production. Takes 60 min with 80% probability.
R07: APC maturation triggered by viral infection
APCs mature and migrate from epithelial infection sites to lymph nodes when viral load is ≥10 particles AND IFN- levels are ≥5. The process consumes viral antigens and inflammatory signals and takes 2880 min (2 days) representing antigen processing and migration time. This demonstrates combined count conditions triggering a biologically realistic adaptive immune response.
R08: Scheduled therapeutic intervention
Antiviral drug is administered precisely at min (48 h), demonstrating scheduled interventions using exact time conditions. Administration takes 1 min.
4.3.5. Object-Count Conditions
R9: T cell activation threshold
T cell activation requires at least 3 antigen-presenting cells in the lymph node, modeling the need for sufficient antigenic stimulation. Only 60% of Th0 cells respond (IPP). The count condition ensures threshold-based activation. Takes 360 min (6 h) for activation and differentiation.
4.3.6. Combined Conditions
R10: Conditional antiviral action
Drug kills virus only within the 2880–5760 min (48–96 h) therapeutic window AND if viral reservoir ≥100 particles. Takes 30 min for drug action. This demonstrates combined time range and count conditions.
R11: Emergency interferon response
Emergency interferon production triggered by high viral load OR strong Th1 response, modeling emergency response using disjunction. Takes 120 min (2 h) with 90% probability.
4.3.7. Rule Priority Index (RPI)
R12: Th1 differentiation (high priority)
R13: Th2 differentiation (low priority)
When both IL-12 and IL-4 are present with sufficient APCs (≥3), Th1 differentiation takes priority (RPI = 1) over Th2 (RPI = 2), modeling the dominant Th1 response in RSV infection. Both take 480 min (8 h).
4.3.8. Rule Probability (RP)
R14: Stochastic IL-2 secretion
Th1 cells secrete IL-2 with 60% probability. The Th1 cell remains in the TC membrane while IL23 is produced in the parent LN membrane. Secretion takes 60 min (1 h) for cytokine synthesis and export.
R15: Probabilistic viral assembly
Viral assembly from proteins succeeds with 75% probability, taking 240 min (4 h) when successful.
4.3.9. Input Population Percentage (IPP)
R16: Partial CD8 T cell migration
IPP models partial response: only 30% of available CD8+ T cells migrate from lymph nodes to infection sites after 7200 min (5 days). This dynamic approach adapts to the actual CD8 population size, unlike static object counts. Migration takes 180 min (3 h).
R17: Partial antibody neutralization
Antibodies neutralize virus with 40% efficiency per individual, accounting for antibody affinity variation. Neutralization takes 6 min (rapid binding kinetics).
4.3.10. Entity Population Percentage (EPP)
R18.1: Strong Th1 response (70% of population)
R18.2: Weak Th1 response (30% of population)
70% of individuals mount strong Th1 responses (3 cells per Th0) while 30% show weaker responses (1 cell per Th0), reflecting IL-12 receptor polymorphisms.
R19.1: High antibody producer (60% of population)
R19.2: Low antibody producer (40% of population)
60% of individuals produce high antibody levels (10 Ab per B cell) while 40% produce low levels (3 Ab per B cell), modeling genetic variation in B cell receptor affinity. B cells produce antibodies only when sufficient Th2 helper signals (≥5 Th2 cells in lymph node) are present. Production requires 1440 min (24 h) with 80% success probability.
4.3.11. Additional Supporting Rules and Object Measurements
To create a fully functional illustrative model, the system requires additional supporting rules beyond the previous mentioned rules. These rules handle essential biological processes for example:
- APC migration: Transportation rules to migrate matured APCs from epithelial infection sites to lymph nodes for T cell activation.
- Viral particle distribution: Send-in communication rules to transport viral particles from the environment to epithelial cell membranes, initiating infection.
- Drug administration: Send-in rules to deliver therapeutic agents from the environment to target epithelial membranes.
- Antibody secretion: Communication rules for antibody movement from B cells to lymph nodes and subsequently to infection sites for viral neutralization.
- Cell recruitment: Rules for recruiting naive T helper cells (Th0) to lymph nodes and generating new epithelial cell membranes to replace lysed infected cells, maintaining tissue homeostasis.
This illustrative model is designed to demonstrate the extended P system framework’s capabilities rather than to provide quantitative clinical predictions. Object counts, initial conditions, and parameter values (e.g., 50 ATP molecules, 10 ribosomes, viral load thresholds) are chosen for demonstration clarity and computational tractability, not fitted to experimental data. For validated quantitative models, each object type must be mapped to real biological units with precise scaling factors: for example, one viral object might represent virions (plaque-forming unit assays), one immune cell object could correspond to cells/mL (flow cytometry), or one cytokine object might represent 1 pg/mL (ELISA). Similarly, rule parameters (RP, IPP, time delays) would require calibration through parameter estimation techniques (e.g., approximate Bayesian computation, maximum likelihood fitting) using experimental time-series data. Such quantitative mapping is essential for translating simulations into clinically actionable predictions and enabling applications in personalized medicine, treatment optimization, or vaccine design.
4.4. Simulation Results and Variations Modeling
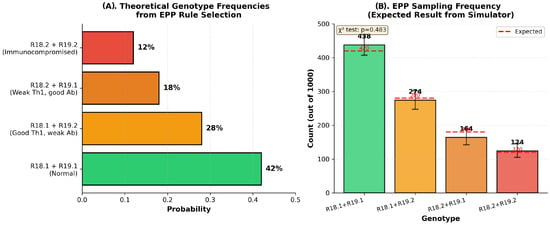
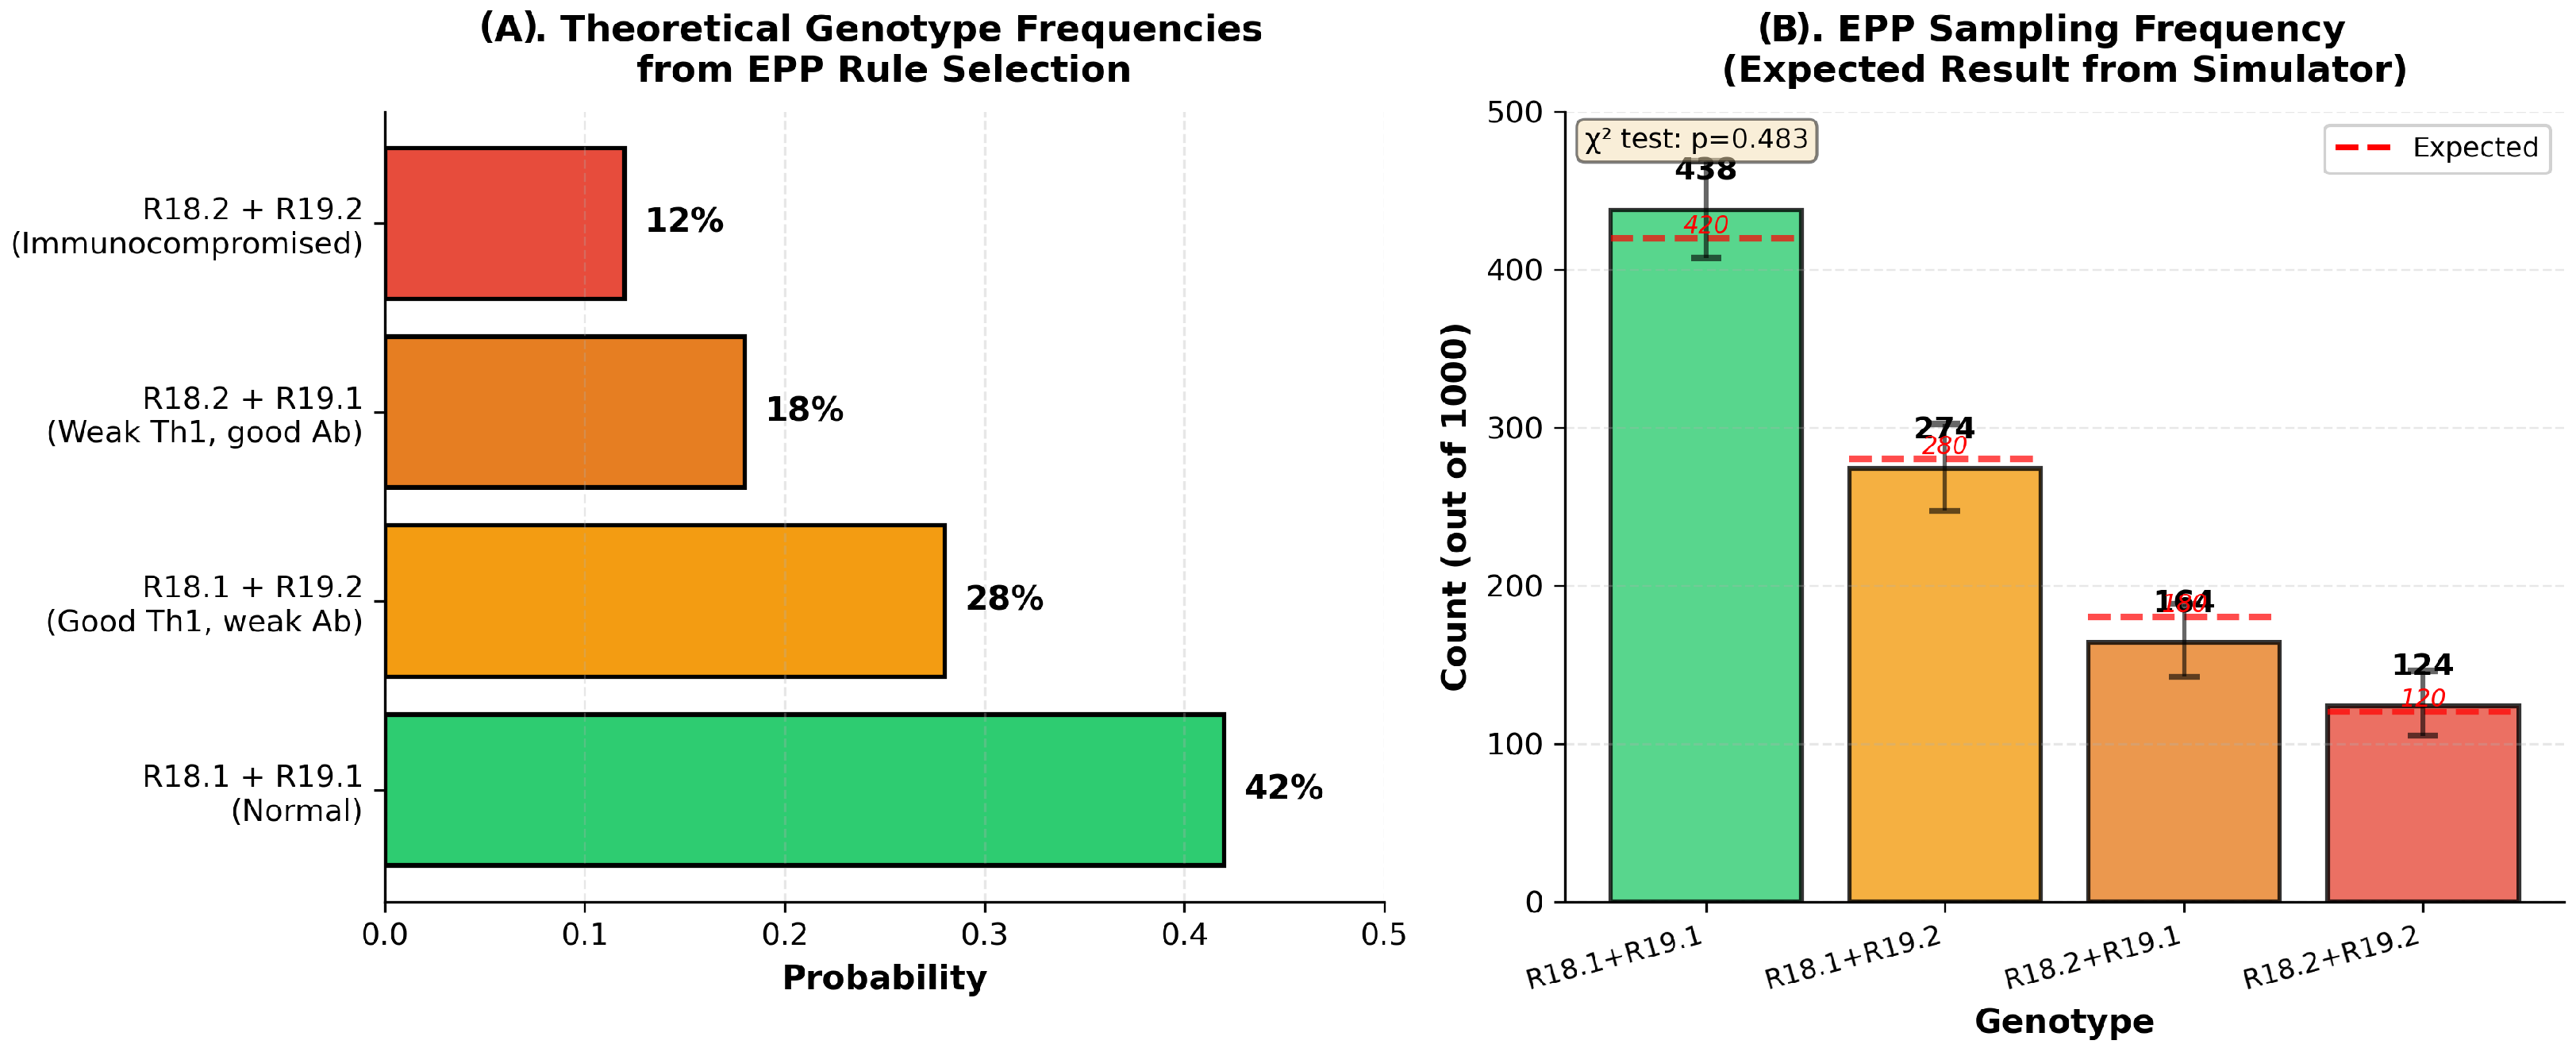
We demonstrate the EPP feature’s capability to model population genetic heterogeneity. The RSV case study includes two EPP-controlled genetic variations: Th1 response intensity (process = Th1_responder with R18.1 desc = ‘Th1 high responder’ vs. R18.2 desc = ‘Th1 low responder’) and B cell antibody production (process = Ab_producer with R19.1 desc = ‘Ab high producer’ vs. R19.2 desc = ‘Ab low producer’). EPP’s rule selection mechanism generates four distinct genotype groups with expected frequencies matching theoretical population genetics predictions (Figure 1).
Figure 1.
EPP Population Distribution and Validation. (A) Theoretical genotype frequencies from EPP scenario generation. Each individual inherits one rule variant from (R18.1: 70% or R18.2: 30%) and one from (R19.1: 60% or R19.2: 40%). Joint probabilities determine population stratification into four phenotype groups (42%, 28%, 18%, 12%). (B) EPP sampling frequency showing observed distribution when simulator generates N = 1000 individual profile configurations. Observed counts (bars) match theoretical expectations (red dashed lines) with test p > 0.05, confirming EPP’s rule selection mechanism produces the intended genotype frequencies. Error bars show binomial 95% confidence intervals.
EPP addresses a fundamental challenge in computational modeling: systematically exploring scenario combinations without creating multiple model files. Traditional approaches require manually editing model specifications for each scenario (error-prone, not scalable). EPP solves this through rule selection during initialization: one model specification with alternative rule pairs generates all combinations automatically with controlled probabilities.
To demonstrate EPP’s versatility, we map rule selection to genetic polymorphisms. EPP rule pairs encode genetic variants. The four scenarios represent genotype combinations (R18.1 + R19.1: 42%, R18.2 + R19.2: 12%, etc.). This same EPP mechanism applies equally to treatment arms, environmental conditions, parameter variations, etc.—any context requiring multi-scenario exploration with controlled frequencies.
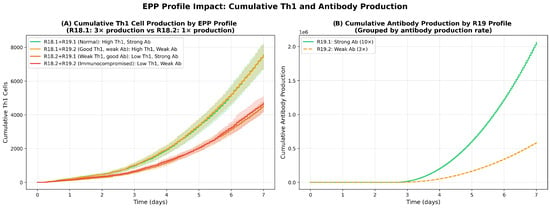
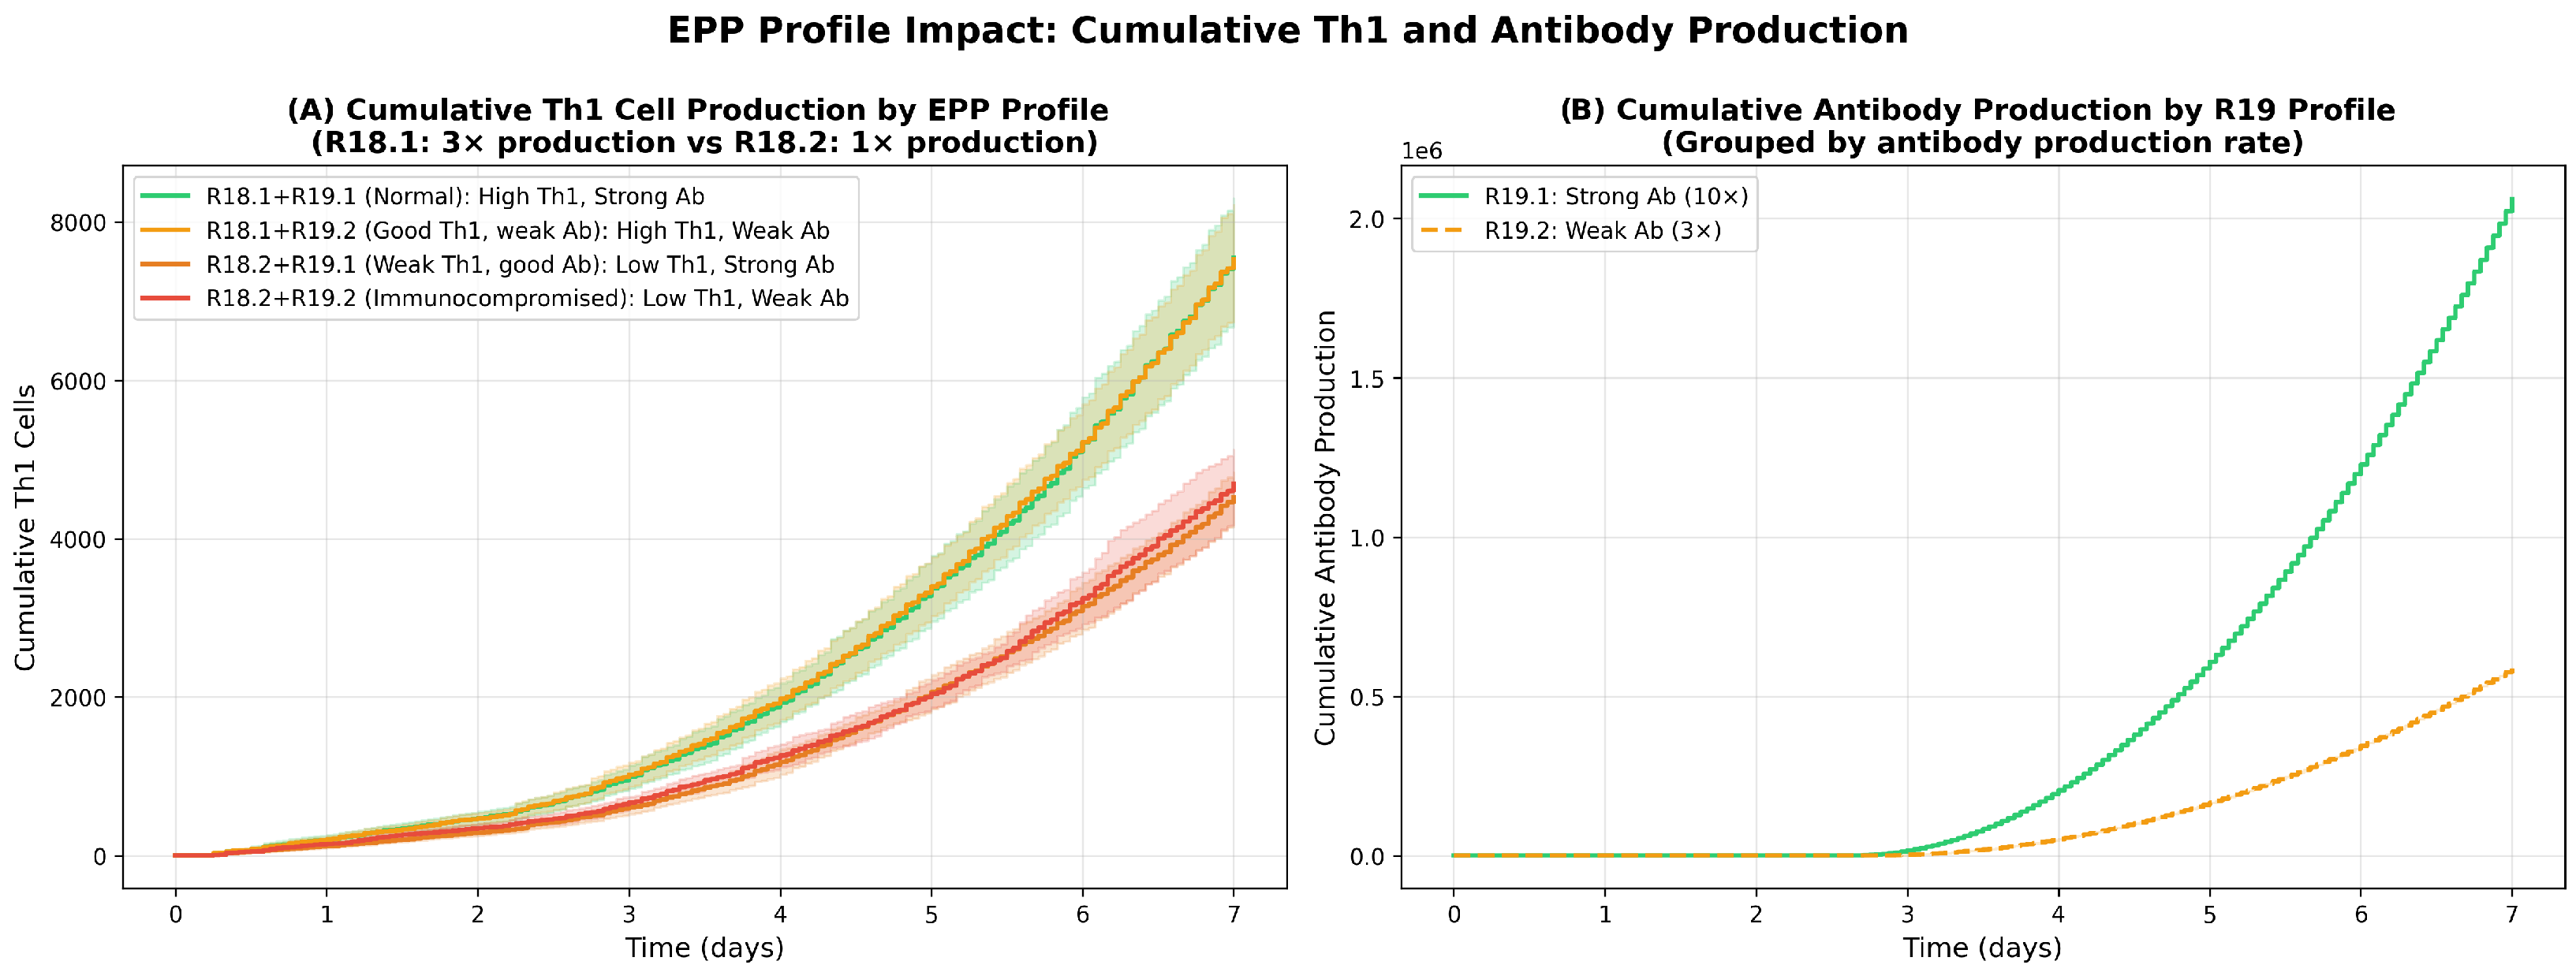
Figure 2 demonstrates the biological impact of EPP-selected rule variants on immune response dynamics. The four genotype profiles produce markedly different Th1 and antibody responses, validating EPP’s ability to capture both inter-individual variation (differences between genotype groups, shown by the separation of mean trajectories) and intra-individual variation (stochastic fluctuations within each group, shown by ±1 standard deviation shaded regions). The intra-individual variation is prominently visible in Th1 dynamics (Panel A), where the shaded regions indicate substantial stochastic fluctuations due to the interplay of RP (stochastic rule firing) and IPP (partial population responses). In contrast, antibody production (Panel B) exhibits more limited intra-individual variation, as the rule design specifies a 24-h production time (R19.1 and R19.2, time = 1440 min), which constrains the temporal dynamics and results in more synchronized responses within the 7-day simulation window. Nevertheless, small but measurable intra-individual variation is still present in antibody kinetics, reflecting the stochastic nature of B cell activation (RP = 0.8) combined with the Th2-dependent conditional gating (requiring Th2 ≥ 5).
Figure 2.
EPP Profile Impact on Cumulative Th1 and Antibody Production. (A) Cumulative Th1 cell production over 7 days grouped by R18 genotype. R18.1 profiles (Normal and Good Th1, weak Ab) show 3× Th1 production rate compared to R18.2 profiles (Weak Th1, good Ab and Immunocompromised) with 1× rate. Lines show mean values with shaded regions indicating ±1 standard deviation across samples. (B) Cumulative antibody production grouped by R19 genotype. R19.1 profiles (strong Ab: 10× production) achieve substantially higher antibody levels compared to R19.2 profiles (weak Ab: 3× production). The clear separation between genotypes demonstrates EPP’s capability to generate distinct immune response phenotypes from a single model specification. Cumulative metrics reveal total immune response capacity, with the immunocompromised group (R18.2 + R19.2) showing reduced capacity in both Th1 and antibody production arms.
The extended framework’s power emerges from the synergistic combination of all probabilistic parameters and conditional rules working together. Even in this simplified illustrative model, the interplay of EPP (population-level genetic variation), IPP (partial population responses), RP (stochastic reaction probabilities), RPI (priority-based pathway selection), time semantics, and conditional gating produces substantial variation in simulation outcomes that mirrors the heterogeneity observed in real biological systems. Each parameter contributes a distinct layer of stochasticity: EPP establishes baseline individual capabilities (determining whether individuals belong to Normal, Good Th1/weak Ab, Weak Th1/good Ab, or Immunocompromised profiles), RP and IPP introduce within-individual variability in immune cell activation and response magnitudes, while RPI and conditional rules enforce biologically realistic constraints on when and how immune processes unfold.
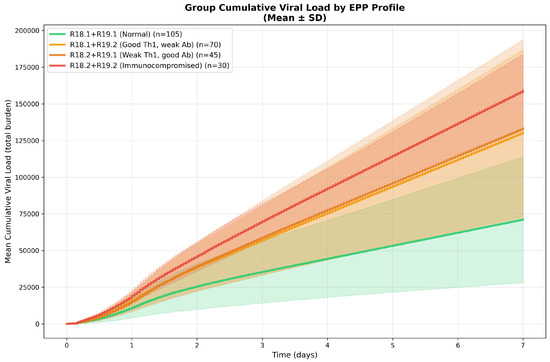
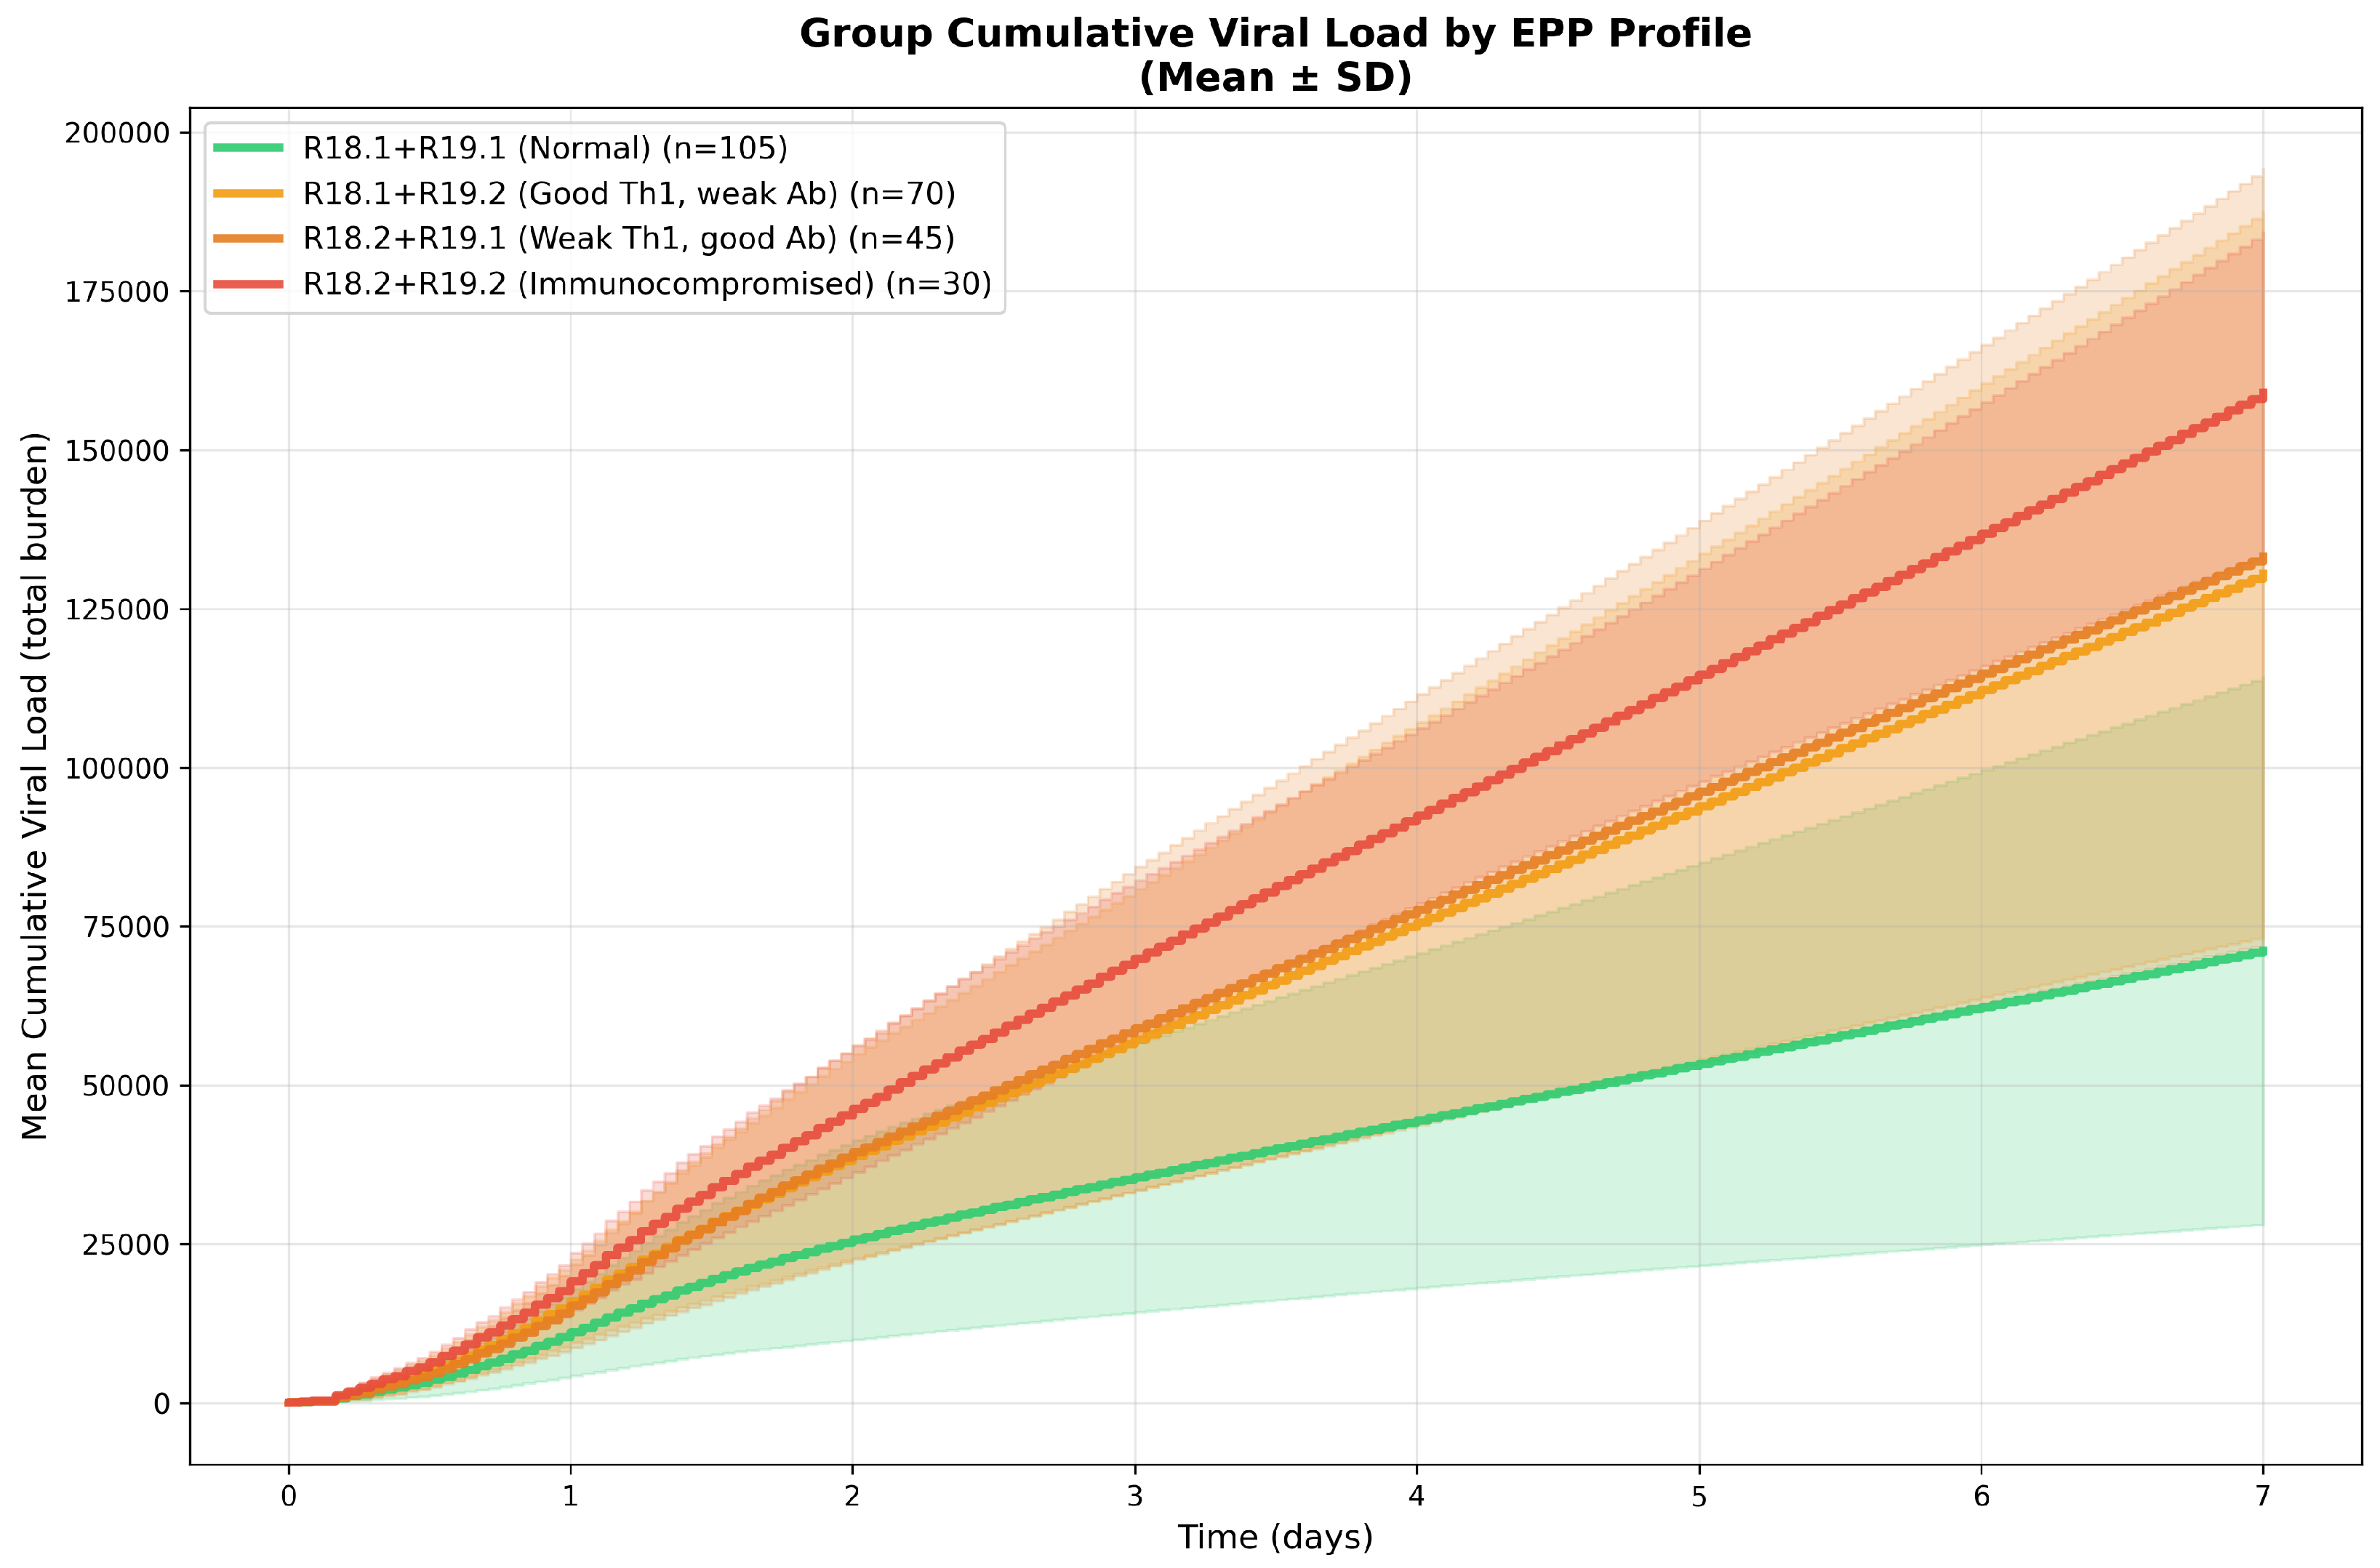
The viral load analysis (Figure 3) reveals the downstream consequence of this integrated parameter framework on infection dynamics. The clear stratification of viral burden across genotypes demonstrates that the extended framework captures not merely mathematical variation but biologically meaningful phenotypic differences that align with clinical observations of RSV severity.
Figure 3.
Cumulative Viral Load Variation Across EPP Profiles. Mean cumulative viral burden (total viral particles, vmRNA, and vProteins) over 7 days for each EPP genotype profile. Lines represent mean trajectories with shaded regions showing ±1 standard deviation. Normal profile (R18.1 + R19.1, green, n = 105) exhibits the strongest immune control with lowest viral burden due to combined high Th1 differentiation and strong antibody production. Good Th1/weak Ab profile (R18.1 + R19.2, yellow, n = 70) maintains intermediate viral control through cellular immunity despite reduced antibody response. Weak Th1/good Ab profile (R18.2 + R19.1, orange, n = 45) also shows intermediate viral burden with antibody-mediated control compensating for reduced Th1 response. Immunocompromised profile (R18.2 + R19.2, red, n = 30) demonstrates highest viral burden with deficiencies in both immune arms. The diverging trajectories illustrate how the extended framework produces clinically relevant variation in infection outcomes, with the immunocompromised group showing 2–3× higher cumulative viral exposure compared to the normal population within 7 days period.
5. Visualization Tools
In order to debug and validate the P systems for their use in simulations of real processes, we have developed computational tools that help the developer in the debugging of rules and membrane structures. The tools discussed in this section can be downloaded from a public repository (The visualization tools can be accessed at https://github.com/biotechvana/membranes accessed on 30 December 2025).
5.1. Rules Visualization
Complex rule-based P system interactions can be really difficult to diagnose. Visualization tools can facilitate designing such complex systems. We have developed network diagrams that can be used for diagnostics, identifying orphan rules, detecting unreachable simulation paths inside the system, and enhancing our understanding and analysis of P system behaviors. Our software tool obtains a graphical version of such network diagrams.
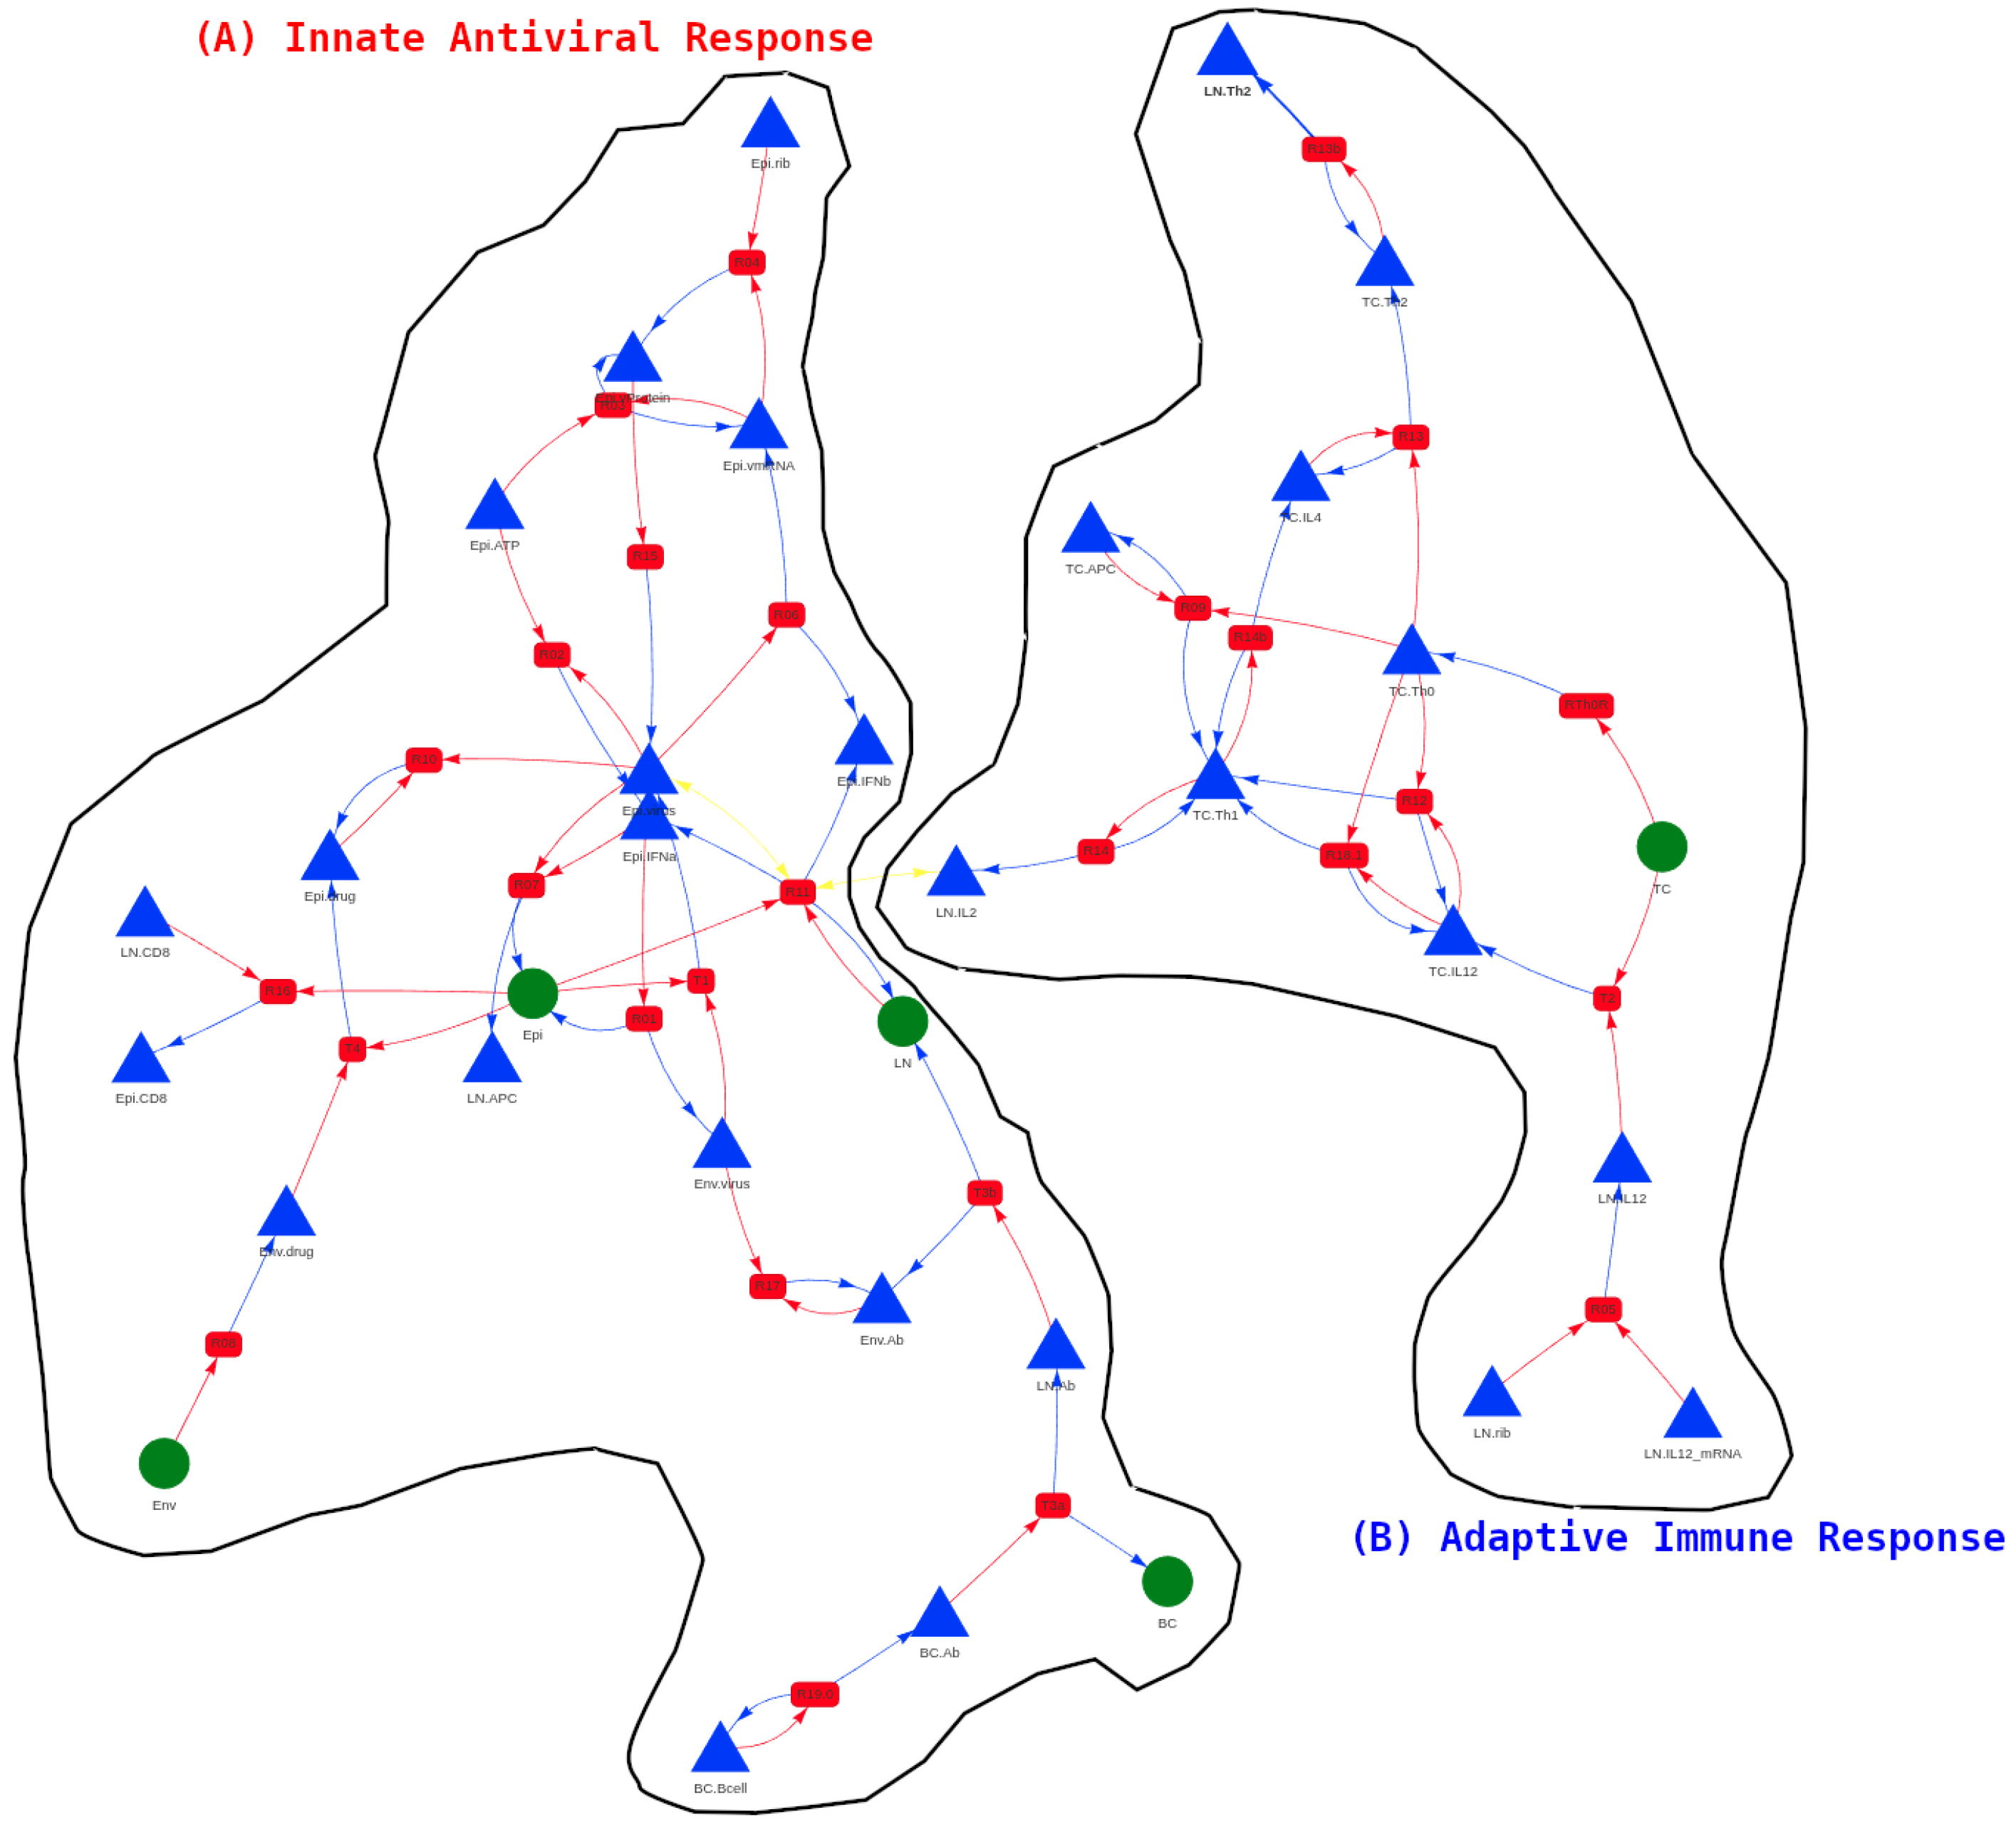
In Figure 4, we show a network diagram obtained by our visualization tool that translates the rules and object dependencies into nodes and edges for the RSV infection model described in Section 4. In such network diagrams, blue triangle nodes represent objects, green dots represent required input membranes for a given rule (i.e., rules that require the presence of some membranes but do not require the inclusion of any objects in such membranes), and red square nodes represent rules. Directed edges represent inputs and outputs of the rules. Object names use a full name convention in the form to distinguish them, as there might be identical objects in different membranes. For example, Epi.virus is the object that belongs to the epithelial membrane Epi, while Env.virus is the object that belongs to the environment membrane Env. The rules are represented in red square nodes, red arrows represent the rule input (left-hand side), blue arrows represent the output (right-hand side), and yellow edges represent conditions required by conditional gating (e.g., object count thresholds, or combined conditions as introduced in Section 3). The network visualization reveals two functionally independent modules that are connected only through conditional gating: Module A (Innate Antiviral Response) encompasses viral infection dynamics, innate immunity, and antiviral therapeutics, while Module B (Adaptive Immune Response) encompasses T cell differentiation pathways and antibody production. This also demonstrates how conditional gating can be used to enable cross-module coordination.
Figure 4.
A network diagram showing P system objects, membranes and rule dependencies from the model described in Section 4. The network illustrates two independent functional modules only connected with conditional gating: Module (B) (Adaptive Immune Response) encompasses T cell activation, differentiation, and regulation, including T cell homeostasis, Th1/Th2 polarization pathways, and adaptive-innate cross-talk. Module (A) (Innate Antiviral Response) covers viral replication dynamics, innate immunity, antigen presentation, and effector responses, integrating viral infection mechanisms with therapeutic interventions and antibody-mediated neutralization.
5.2. Membranes Structure Visualization
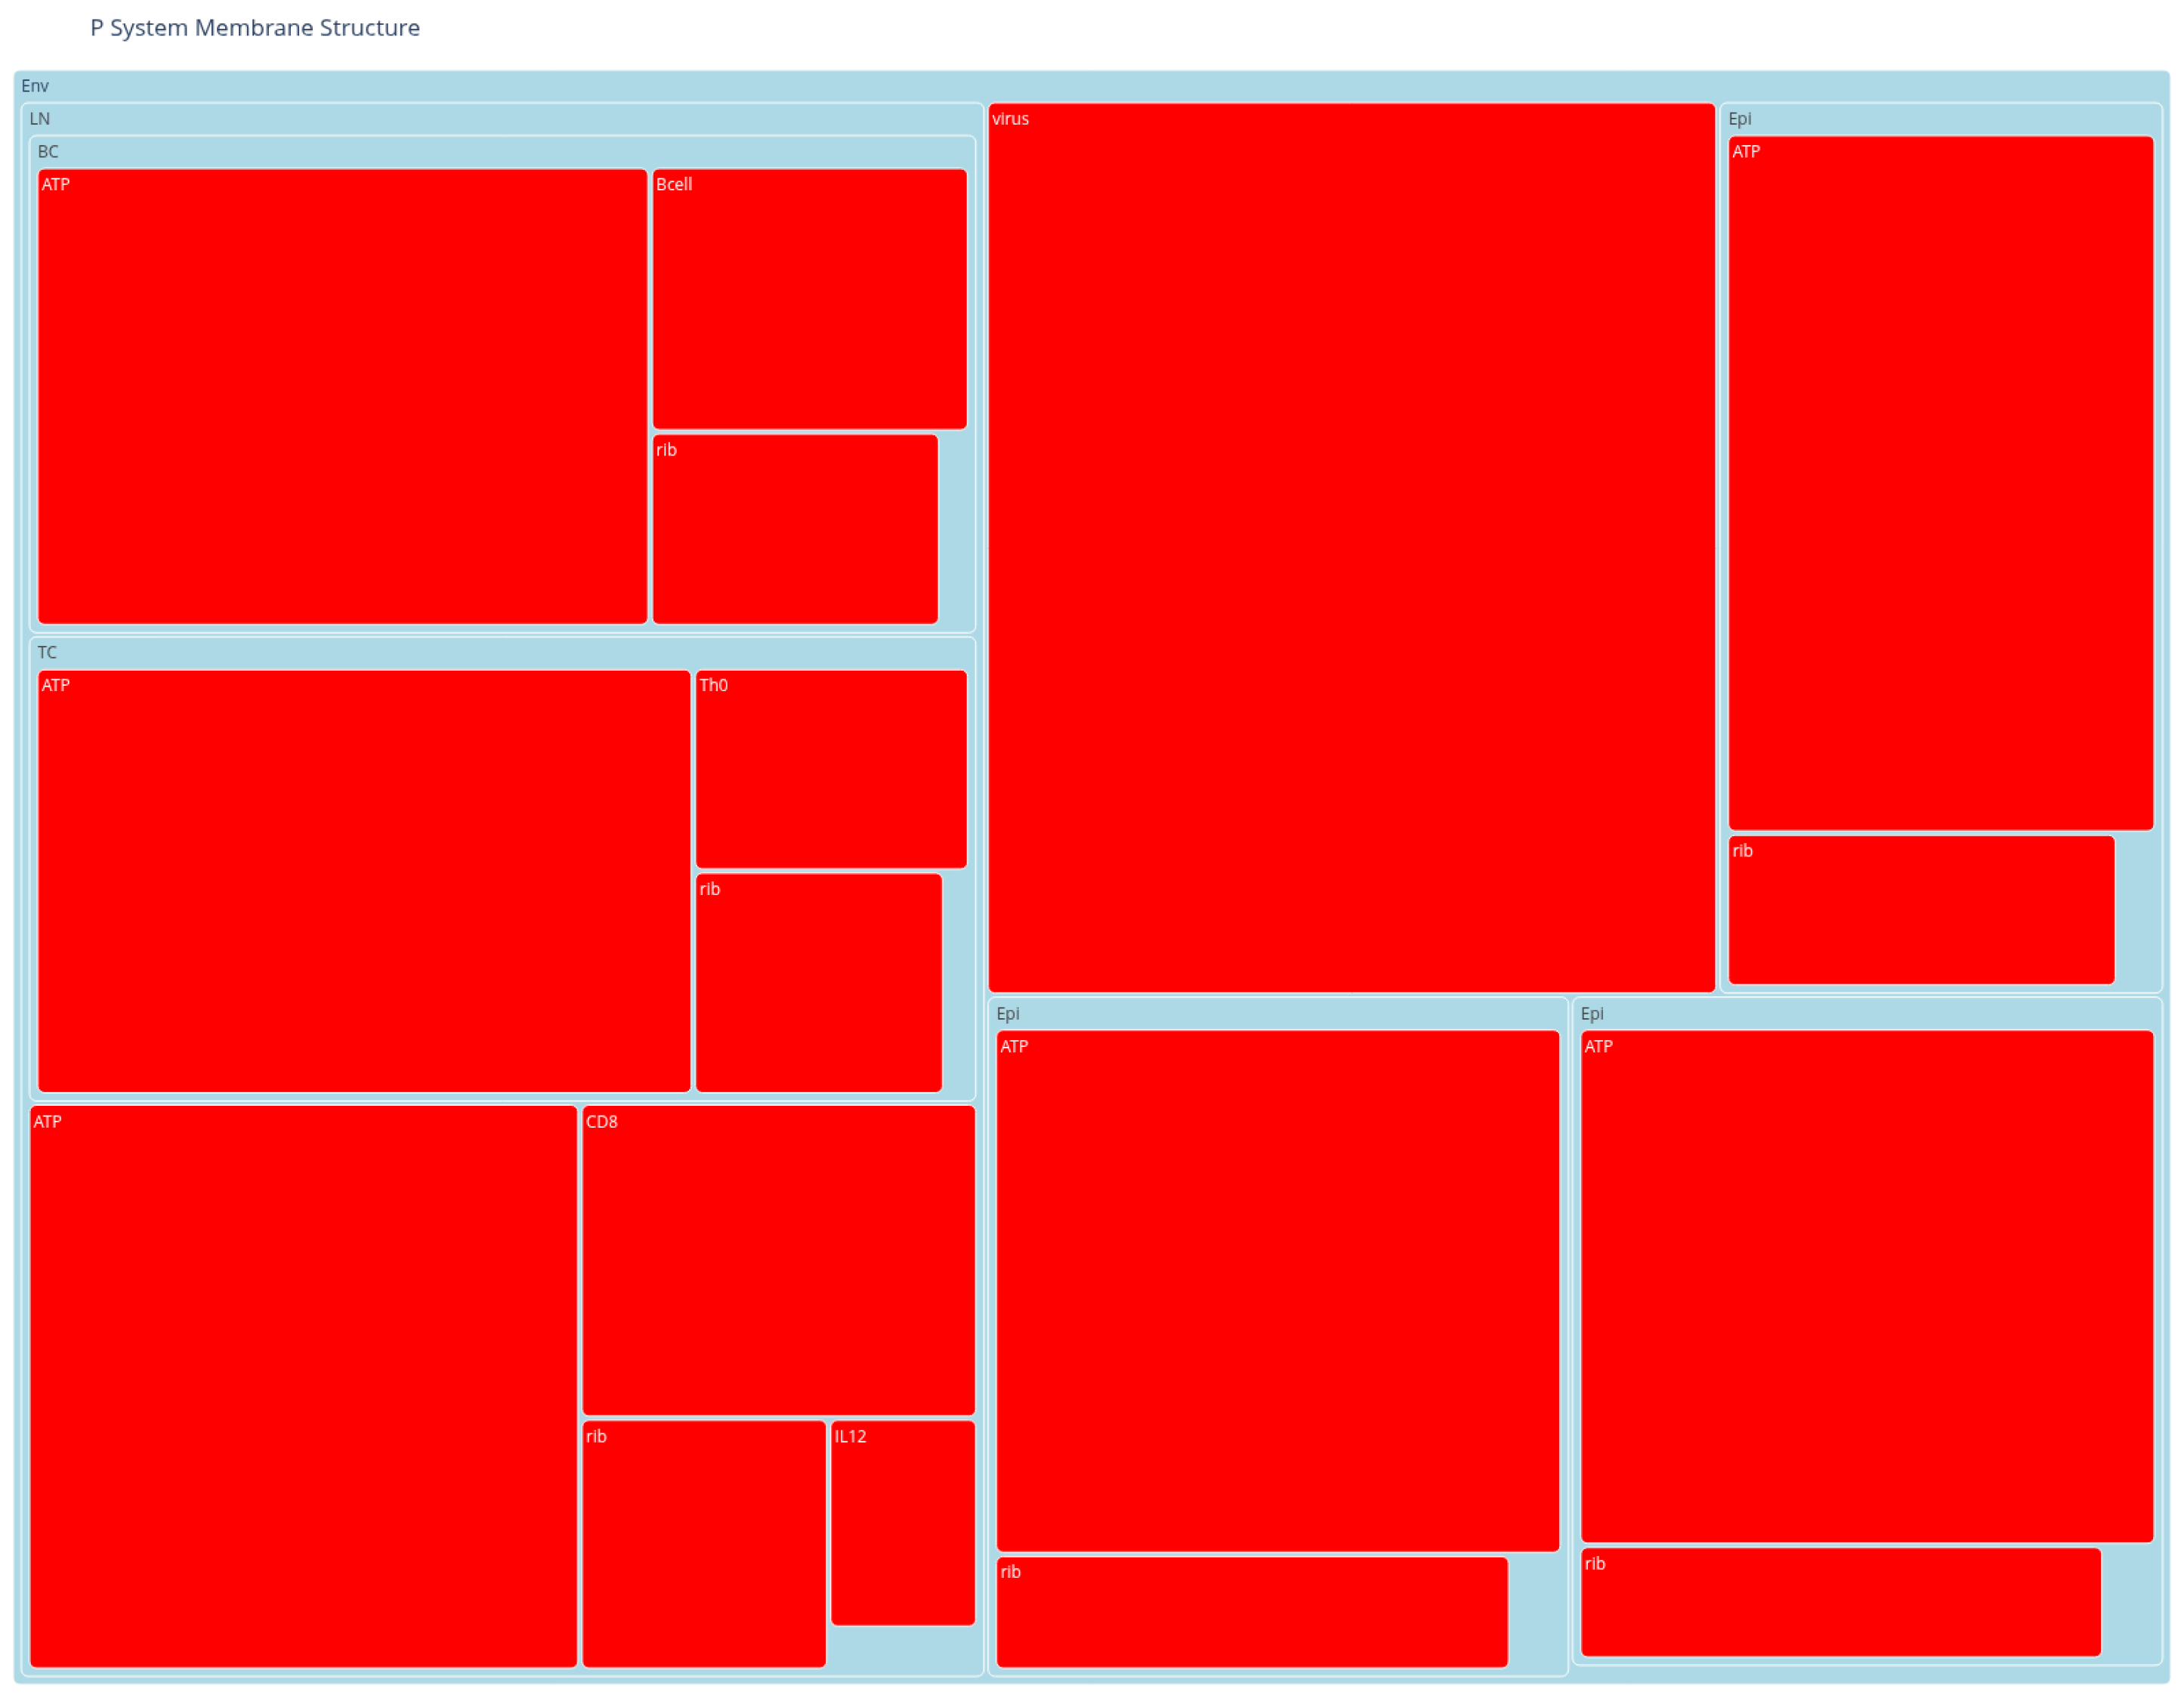
Visualizing the membrane structure during the P system computation can be a useful diagnostic tool of any simulator behaviour. We have developed a computer tool that shows the membrane structure of the P system at a given time during a computation. In Figure 5, we show a diagram obtained by our computer tool that contains a hierarchical and nested visualization of the membranes. Figure 5 depicts at each membrane level all its nested objects and membranes. This type of visualization can also be obtained by the software tool at each iteration, as diagnostic and tracking the behaviour of the membranes during the computation.
Figure 5.
A diagram obtained by the visualization tool for the membranes structure during a computation.
6. Discussion
This work introduces significant enhancements to P systems, addressing the challenges of simulating empty membranes and developing a comprehensive probabilistic framework to mirror complex biological interactions more closely.
- Extended Rule Syntax, Catalyst Semantics, and Empty Membrane Rules
Our framework extends P system rule syntax to incorporate critical biological mechanisms, including formal catalyst semantics and empty membrane detection. The catalyst notation distinguishes between pooled and distributed catalysts, enabling accurate modeling of enzymatic reactions and regulatory molecules. This distinction is essential for biological accuracy, allowing the representation of both multi-use and one-to-one regulatory interactions. The RSV case study employs both mechanisms: pooled catalysts for ATP-dependent reactions (interferon production and viral protein synthesis) and distributed catalysts for ribosome-mediated translation processes.
The formalization of empty membrane detection through the predicate represents a fundamental advancement in P system semantics. Unlike previous approaches that treated membrane emptiness implicitly or through ad-hoc mechanisms, our framework provides formal definitions that accommodate different modeling scenarios. The dissolution rule for empty membranes, represented by , aligns with biological realities where non-viable cells, lacking functional components, naturally deteriorate. This conceptual advancement not only enriches the P system’s biological fidelity but also enables the simulation of critical biological processes such as apoptosis, viral lysis, and cellular clearance that were difficult to represent accurately in traditional P system frameworks.
- Comprehensive Probabilistic Framework
The elaboration of four distinct probabilistic rule properties—Input Population Percentage (IPP), Rule Priority Index (RPI), Rule Probability (RP), and Entity Population Percentage (EPP)—substantially enhances P system simulation capabilities. Each parameter addresses a specific aspect of biological stochasticity:
- IPP controls the fraction of available input objects consumed by a rule, modeling partial population responses and resource competition.
- RPI determines execution priority, addressing the biological reality that cellular processes occur in stochastic yet constrained sequences.
- RP governs whether a rule executes when conditions are met, capturing the probabilistic nature of molecular interactions and pathway activations.
- EPP enables population heterogeneity by specifying variant rule sets with distinct parameter values, allowing the simulation of genetic diversity, phenotypic variation, and individual differences in immune responses.
The parameter interaction order—EPP pre-computation, followed by RPI-based rule ordering, applicability checking (conditions and input requirements), RP-based execution decisions, and finally IPP-based input selection—ensures that biological constraints are enforced hierarchically. This layered approach mirrors the natural organization of biological systems where genetic factors (EPP) establish baseline capabilities, regulatory priorities (RPI) determine process ordering, pathway activations (RP) gate specific reactions, and resource availability (IPP) modulates response magnitudes.
- Validation Through Illustrative RSV Infection Model
The RSV infection model demonstrates the practical utility of these enhancements. The EPP mechanism successfully models four distinct immune response genotypes through variant rule sets (R18.1/R18.2 for Th1 production, R19.1/R19.2 for antibody production). As shown in Figure 1, Figure 2 and Figure 3, this population heterogeneity produces biologically realistic variation in immune kinetics and viral clearance outcomes, stratifying individuals into distinct phenotypic groups (Normal, Good Th1/weak Ab, Weak Th1/good Ab, and Immunocompromised profiles). The integration of EPP with IPP and RP parameters generates cumulative viral load distributions demonstrating variable infection severity that capture both inter-individual variability and intra-individual stochasticity.
- Comparison with Existing Approaches
Comparatively, while existing models in membrane computing offer robust frameworks for simulating biological processes, our approach introduces a level of specificity and adaptability previously unattained. Traditional P systems with stochastic features typically implement a single probabilistic mechanism (e.g., rule probability alone), whereas our framework provides four orthogonal parameters that can be composed to model different biological phenomena. Previous work on timed P systems introduced temporal dynamics but lacked the probabilistic sophistication needed to capture biological variability. Our integration of time semantics () with the probabilistic framework allows for simulations that incorporate both temporal constraints and stochastic variation, thereby enhancing model accuracy and realism in reflecting biological processes.
The RPI mechanism represents a methodological advancement over traditional priority-based approaches. Unlike deterministic priority systems that always execute rules in the same order, or purely random systems that ignore biological constraints, our approach achieves non-deterministic execution within priority constraints—mirroring the biological reality that cellular processes have preferred orderings but exhibit stochastic variation in timing.
The EPP mechanism addresses a limitation in conventional P system approaches to population modeling. While previous work often simulated heterogeneous populations by running multiple homogeneous models, our approach integrates population diversity directly into the rule structure. This enables more efficient simulation of population-level phenomena and provides a natural framework for modeling genetic polymorphisms, phenotypic variation, and personalized medicine scenarios.
The visualization of membrane computing through P systems with network diagrams makes the complex interactions governed by our newly introduced rules clearer. This visual representation helps simplify the understanding of the rules, providing clear insights into the simulation processes. Additionally, the active visualization of membranes and objects, along with the visible changes after applying the rules, gives a concrete view into how the simulated biological system changes over time.
In conclusion, our work introduces necessary extensions and innovations to P systems for simulating biological systems complexities. The formalization of empty membrane rules through the predicate, conditional gating for threshold-based and temporal rule activation, the comprehensive four-parameter probabilistic framework (IPP, RPI, RP, EPP), and the integration of time semantics collectively establish a foundational framework for biological simulations. The RSV infection model validates these enhancements, demonstrating that the framework can capture both population-level heterogeneity and individual-level stochasticity in immune responses. These advancements position P systems as a powerful computational tool for modeling complex biological phenomena where variability, timing, and population diversity are critical factors.
- Potential implications and future directions
The innovations presented in this study hold significant implications for the field of computational biology and beyond. By enhancing the P systems ability to simulate biological processes with higher fidelity, our work supports more accurate modeling of complex systems, such as immune responses to pathogens or vaccines. This could, in turn, inform more precise predictive models for disease progression and treatment outcomes.
Our future research will explore the integration of our enhanced P system model with machine learning algorithms to predict outcomes of biological processes under varying conditions. Additionally, expanding the model to incorporate more diverse biological rules and interactions could further its applicability across different domains of biology and medicine. Ultimately, the continued development of membrane computing models, grounded in biological accuracy and computational efficiency, will pave the way for breakthroughs in understanding and manipulating complex biological systems.
Author Contributions
Conceptualization, A.A.E., R.C., C.L. and J.M.S.; methodology, A.A.E., R.C., C.L. and J.M.S.; software, A.A.E. and A.I.H.; validation, A.A.E., R.C., A.I.H. and C.L.; formal analysis, A.A.E., R.C. and J.M.S.; investigation, A.A.E., R.C., C.L. and J.M.S.; resources, A.I.H. and C.L.; writing—original draft preparation, A.A.E. and J.M.S.; writing—review and editing, A.A.E., C.L. and J.M.S.; visualization, A.A.E. and J.M.S.; supervision, A.I.H., C.L. and J.M.S.; project administration, C.L.; funding acquisition, C.L. All authors have read and agreed to the published version of the manuscript.
Funding
This work has received funding from CDTI within the framework of the Misiones CDTI 2021 program in the project “Investigation of a new vaccine for human respiratory disease” EXP—00162016/MIG-20211034 and from the Generalitat Valenciana within the Prometeo program in the project “A disruptive way to ameliorate the diagnosis and treatment of sensorineural diseases” CIPROM/2023/026.
Data Availability Statement
No new data were created or analyzed in this study. Data sharing is not applicable to this article.
Conflicts of Interest
The authors declare no conflict of interest.The funders had no role in the design of the study; in the collection, analyses, or interpretation of data; in the writing of the manuscript; or in the decision to publish the results.
References
- Kari, L.; Rozenberg, G. The Many Facets of Natural Computing. Commun. ACM 2008, 51, 72–83. [Google Scholar] [CrossRef] [Scilit]
- Păun, G. Computing with membranes. J. Comput. Syst. Sci. 2000, 61, 108–143. [Google Scholar] [CrossRef] [Scilit]
- Păun, G.; Rozenberg, G. A guide to membrane computing. Theor. Comput. Sci. 2002, 287, 73–100. [Google Scholar] [CrossRef] [Scilit]
- Frisco, P.; Gheorghe, M.; Pérez-Jiménez, M.J. (Eds.) Applications of Membrane Computing in Systems and Synthetic Biology; Springer: Berlin/Heidelberg, Germany, 2014. [Google Scholar]
- Besozzi, D. Computational and Modelling Power of P Systems. Ph.D. Thesis, Universitá degli Studi di Milano, Milan, Italy, 2004. [Google Scholar]
- Bianco, L.; Fontana, F.; Franco, G.; Manca, V. P systems for biological dynamics. In Applications of Membrane Computing; Springer: Berlin/Heidelberg, Germany, 2006; pp. 83–128. [Google Scholar]
- Sempere, J.M. Membrane computing: A wonderful framework for systems and computational biology. In Proceedings of the Twenty-Fourth International Conference on Membrane Computing (CMC2023); Slezká Univerzita: Opava, Czech Republic, 2023; p. 4. [Google Scholar]
- Bottoni, P.; Martín-Vide, C.; Păun, G.; Rozenberg, G. Membrane systems with promoters/inhibitors. Acta Inform. 2002, 38, 695–720. [Google Scholar] [CrossRef] [Scilit]
- Nishida, T.Y. Simulations of Photosynthesis by a K-Subset Transforming System with Membrane. Fundam. Inform. 2002, 49, 249–259. [Google Scholar]
- Franco, G.; Manca, V. A Membrane Systems for the Leukocyte Selective Recruitment. In Proceedings of the International Workshop WMC 2003; LNCS 2933; Springer: Berlin/Heidelberg, Germany, 2004; pp. 181–190. [Google Scholar]
- Hinze, T.; Lenser, T.; Dittrich, P. A Protein Substructure Based P Systems for Description and Analysis of Cell Signalling Networks. In Proceedings of the 7th International Workshop, WMC 2006; LNCS 4362; Springer: Berlin/Heidelberg, Germany, 2006; pp. 409–423. [Google Scholar]
- Frisco, P.; Wolfe, D. Modeling the dynamics of HIV Infection with Conformon-P Systems and Cellular Automata. In Proceedings of the 8th International Workshop WMC 2007; LNCS 4860; Springer: Berlin/Heidelberg, Germany, 2007; pp. 21–23. [Google Scholar]
- Hinze, T.; Hayat, S.; Lenser, T.; Matusmaru, N.; Dittrich, P. Hill Kinetics Meets P Systems: A Case Study on Gene Regulatory Networks as Computing Agents in silico and in vivo. In Proceedings of the 8th International Workshopm WMC 2007; LNCS 4860; Springer: Berlin/Heidelberg, Germany, 2007; pp. 320–335. [Google Scholar]
- Jack, J.; Paun, A.; Rodríguez-Patón, A. Effects of HIV-1 Proteins on the Fas-Mediated Apoptotic Signaling Cascade: A Computational Study of Latent CD4+ T Cell Activation. In Proceedings of the 9th International Workshop, WMC 2008; LNCS 5391; Springer: Berlin/Heidelberg, Germany, 2009; pp. 246–259. [Google Scholar]
- Hinze, T.; Kirkici, K.; Sauer, P.; Sauer, P.; Behre, J. Membrane Computing Meets Temperature: A Thermoreceptor Model as Molecular Slide Rule with Evolutionary Potential. In Proceedings of the 16th International Conference, CMC 2015; LNCS 9504; Springer: Berlin/Heidelberg, Germany, 2015; pp. 215–235. [Google Scholar]
- Sosík, P.; Smolka, V.; Bradík, J.; Garzon, M. Modeling Plant Development with M Systems. In Proceedings of the 19th International Conference, CMC 2018; LNCS 11399; Springer: Berlin/Heidelberg, Germany, 2019; pp. 246–257. [Google Scholar]
- Cardona, M.; Colomer, M.A.; Margalida, A.; Pérez-Hurtado, I.; Pérez-Jiménez, M.J.; Sanuy, D. A P System Based Model of an Ecosystem of Some Scavenger Birds. In Proceedings of the 10th International Workshop WMC 2009; LNCS 5957; Springer: Berlin/Heidelberg, Germany, 2010; pp. 182–195. [Google Scholar]
- Colomer, M.A.; Lavín, S.; Marco, I.; Margalida, A.; Pérez-Hurtado, I.; Pérez-Jiménez, M.J.; Sanuy, D.; Serrano, E.; Valencia-Cabrera, L. Modeling Population Growth of Pyrenean Chamois (Rupicapra p. pyrenaica) by Using P-Systems. In Proceedings of the 10th International Conference, CMC 2010; LNCS 6501; Springer: Berlin/Heidelberg, Germany, 2010; pp. 144–159. [Google Scholar]
- Colomer, M.A.; Pérez-Hurtado, I.; Pérez-Hurtado, M.J.; Pérez-Jiménez, M.J.; Riscos-Núñez, A. Simulating Tritrophic Interactions by Means of P Systems. In Proceedings of the 2010 IEEE Fifth International Conference on Bio-inpired Computing: Theories and Applications, BIC-TA 2010, Changsha, China, 23–26 September 2010; IEEE Press: Piscataway, NJ, USA, 2010; Volume 2, pp. 637–643. [Google Scholar]
- Cardona, M.; Colomer, M.A.; Margalida, A.; Palau, A.; Pérez-Hurtado, I.; Pérez-Jiménez, M.J. A computational modeling for real ecosystems based on P systems. Nat. Comput. 2010, 10, 39–53. [Google Scholar] [CrossRef] [Scilit]
- Colomer, M.A.; Margalida, A.; Sanuy, D.; Pérez-Jiménez, M.J. A bio-inspired computing model as a new tool for modeling ecosystems: The avian scavengers as a case study. Ecol. Model. 2011, 222, 33–47. [Google Scholar] [CrossRef] [Scilit]
- Colomer, M.A.; Pérez-Hurtado, I.; Riscos-Núñez, A.; Pérez-Jiménez, M.J. Comparing simulation algorithms for multienvironment probabilistic P system over a standard virtual ecosystem. Nat. Comput. 2011, 11, 369–379. [Google Scholar] [CrossRef] [Scilit]
- Colomer, M.A.; Margalida, A.; Valencia, L.; Palau, A. Application of a computational model for complex fluvial ecosystems: The population dynamics of zebra mussel Dreissena polymorpha as a case study. Ecol. Complex. 2014, 20, 116–126. [Google Scholar] [CrossRef] [Scilit]
- Campos, M.; Capilla, R.; Naya, F.; Futami, R.; Coque, T.; Moya, A.; Fernández-Lanza, V.; Cantón, R.; Sempere, J.M.; Llorens, C.; et al. Simulating Multilevel Dynamics of Antimicrobial Resistance in a Membrane Computing Model. mBio 2019, 10, e02460-18. [Google Scholar] [CrossRef] [Scilit]
- Baquero, F.; Campos, M.; Llorens, C.; Sempere, J.M. P systems in the time of COVID-19. J. Membr. Comput. 2021, 3, 246–257. [Google Scholar] [CrossRef] [Scilit]
- Campos, M.; Galán, J.C.; Rodríguez-Domínguez, M.; Sempere, J.M.; Llorens, C.; Baquero, F. Membrane computing simulation of sexually transmitted bacterial infections in hotspots of individuals with various risk behaviors. Microbiol. Spectr. 2024, 12, e02728-23. [Google Scholar] [CrossRef] [Scilit]
- Duan, Y.; Rong, H.; Qi, D.; Valencia-Cabrera, L.; Zhang, G.; Pérez-Jiménez, M.J. A Review of Membrane Computing Models for Complex Ecosystems and a Case Study on a Complex Giant Panda System. Complexity 2020, 2020, 1312824. [Google Scholar] [CrossRef] [Scilit]
- Duan, Y.; Rong, H.; Zhang, G.; Qi, D.; Valencia-Cabrera, L.; Pérez-Jiménez, M.J. Estimation of minimum viable population for giant panda ecosystems with membrane computing models. Nat. Comput. 2023, 22, 69–93. [Google Scholar] [CrossRef] [Scilit]
- Duan, Y.; Rong, H.; Zhang, G.; Gorbachev, S.; Qi, D.; Valencia-Cabrera, L.; Pérez-Jiménez, M.J. A review of computing models for studying population dynamics of giant panda ecosystems. Ecol. Model. 2024, 487, 110543. [Google Scholar] [CrossRef] [Scilit]
- Mohan, B.S.; Mahmood, A.A.; Mohammed, M.Q.; Dheyaa Zaki, N. Replicating the MAP Kinase Cascade in Membrane Computing. J. Phys. Conf. Ser. 2021, 1963, 012156. [Google Scholar] [CrossRef] [Scilit]
- Huang, Y.; Song, H.; Han, T.; Xu, S.; Wang, Z.; Liu, Q.; Wang, X. A hypergraph cell membrane computing network model for soybean disease identification. Sci. Rep. 2024, 14, 29637. [Google Scholar] [CrossRef] [Scilit]
- García-Quismondo, M.; Hintz, W.D.; Schuler, M.S.; Relyea, R.A. Modeling diel vertical migration with membrane computing. J. Memr. Comput. 2021, 3, 35–50. [Google Scholar] [CrossRef] [Scilit]
- Jiang, S.; Li, H.; Wang, Y.; Sun, J.; Liu, H. Study on the prognostic model for esophageal cancer survival based on blood indicators and probabilistic membrane system. J. Membr. Comput. 2024, 6, 278–296. [Google Scholar] [CrossRef] [Scilit]
- Shang, Z.; Tan, S.; Ma, D. Respiratory syncytial virus: From pathogenesis to potential therapeutic strategies. Int. J. Biol. Sci. 2021, 17, 4073–4091. [Google Scholar] [CrossRef] [Scilit]
- Marshall, J.; Warrington, R.; Watson, W.; Kim, H.L. An introduction to immunology and immunopathology. Allergy Asthma Clin. Immunol. 2018, 14, 49. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Russell, C.D.; Unger, S.; Walton, M.; Schwarze, J. The human immune response to respiratory syncytial virus infection. Clin. Microbiol. Rev. 2017, 30, 481–502. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Păun, G.; Rozenberg, G.; Salomaa, A. (Eds.) The Oxford Handbook of Membrane Computing; Oxford University Press: Oxford, UK, 2010. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.