


Abstract
In this study, we developed a similar text retrieval system using Sentence-BERT (SBERT) for our database of closed medical malpractice claims and investigated its retrieval accuracy. We assigned each case in the database a short Japanese summary of the accident as well as two labels: the category was classified as a hospital department mainly, and the process indicated a failed medical procedure. We evaluated the accuracies of a similar text retrieval system with the two labels using three different multilabel evaluation metrics. For the encoders of SBERT, we employed two pretrained BERT models, UTH-BERT and NICT-BERT, that were trained on huge Japanese corpora, and we performed iterative optimization to train the SBERTs. The accuracies of the similar text retrieval systems using the trained SBERTs were more than 15 points higher than those of the Okapi BM25 system and the pretrained SBERT system.
1. Introduction
To prevent the recurrence of medical accidents, it is important to learn from past accidents. In Japan, the Project to Collect Medical Near-Miss/Adverse Event Information operated by the Japan Council for Quality Health Care [1] and the Medical Accident Investigation System operated by the Japan Medical Safety Research Organization (Medsafe Japan) [2] collect and analyze data on medical accidents that meet certain requirements and conduct educational activities to prevent the recurrence of similar medical accidents. The Japan Council for Quality Health Care created a database of information on medical accidents for their near-miss and adverse event project and made a part of the information publicly available, and medical institutions use this database for risk management by searching for similar medical accidents using keywords. However, because medical terminology is not uniform, it is not yet possible to fully derive similar medical accident cases through keyword searches.
One source of medical accident case studies is insurance companies’ closed claims. A representative example is the Data Sharing Project of the MPL Association, in which ~70% of MPL (medical professional liability) insurers in the United States participate. The closed claims collected through this project are analyzed from various aspects and used for medical institutions’ risk management [3].
In Japan, Sompo Japan Insurance Inc. (SJ) holds ~70% of the MPL insurance market. We have analyzed the SJ closed claims and reported on their usefulness as a source of information on medical accidents and medical disputes [4,5,6]. Currently, we are creating a database of closed SJ claims including textual information for more efficient analysis. Furthermore, we are also developing not only a keyword search system but also a similar case search system with higher accuracy for this database. In the future, we hope to return these results to medical institutions so they can utilize them in their risk management.
To effectively utilize our closed-claims database, it is essential to have a system to extract past medical accidents that are similar to the one being investigated. Because our database contains textual information, we considered that a similar document retrieval system would be useful. There are two main types of similar document retrieval systems: lexical similarity and semantic similarity. A lexical similarity system matches keywords or phrases in a search query to text content; it focuses on exact word matching without considering the context or the meanings of words. A representative system based on lexical similarity is Okapi BM25 [7], whose implementation began in the 1990s; it is based on term frequency–inverse document frequency (TF-IDF) and is still widely used today.
In contrast, a semantic similarity system focuses on the meaning and context of the words in a query, considering synonyms, related concepts, and the context of a word’s usage. This type of search produces more relevant results by understanding the intent behind an input query. Retrieval systems based on semantic similarity are built using machine learning models that output word-embedding vectors. Representative models are Word2Vec [8], Doc2Vec [9], Glove [10], fastText [11], BERT [12], and GPT-3 [13] in the order of publication. Among these models, we chose to employ BERT (bidirectional encode representations from transformers) because of the large numbers of research publications in the fields of medicine and Japanese natural language processing, as well as available frameworks and libraries.
BERT is a pretrained language model that can be fine-tuned for a variety of natural language processing (NLP) tasks. The algorithm uses an encoder–decoder architecture with a transformer-based encoder. The first key feature of the BERT algorithm is bidirectional training. BERT models are trained on a large corpus using a bidirectional approach where the model can consider left-to-right as well as right-to-left context. This allows the model to understand the meaning of words based on the surrounding context. The second key feature is the Masked Language Model. During pretraining, a certain percentage of input tokens are randomly masked, and the model is trained to predict the original tokens based on the surrounding context. This forces the model to learn a deeper understanding of the context. Then, the pretrained BERT model can be fine-tuned on a specific NLP task, such as sentiment analysis, question answering, or named entity recognition, by adding an additional output layer and training the model on a smaller dataset. The feature of only requiring a small dataset is suitable for this study without a large dataset.
Among the various derivatives of BERT, Sentence-BERT (SBERT) [14] is highly regarded for its search accuracy and speed. Therefore, we decided to develop a similar accident retrieval system for our closed-claims database using SBERT and to investigate its retrieval accuracy.
2. Materials and Methods
2.1. BERT
In this study, we adopted SBERT as a semantic search system to find similar medical accident summaries for our Japanese database of closed medical accident claims. To implement SBERT, we used Sentence-Transformers [15], a library in the Python language. This library is based on PyTorch, a deep learning framework, and the Transformers repository of Hugging Face, Inc.
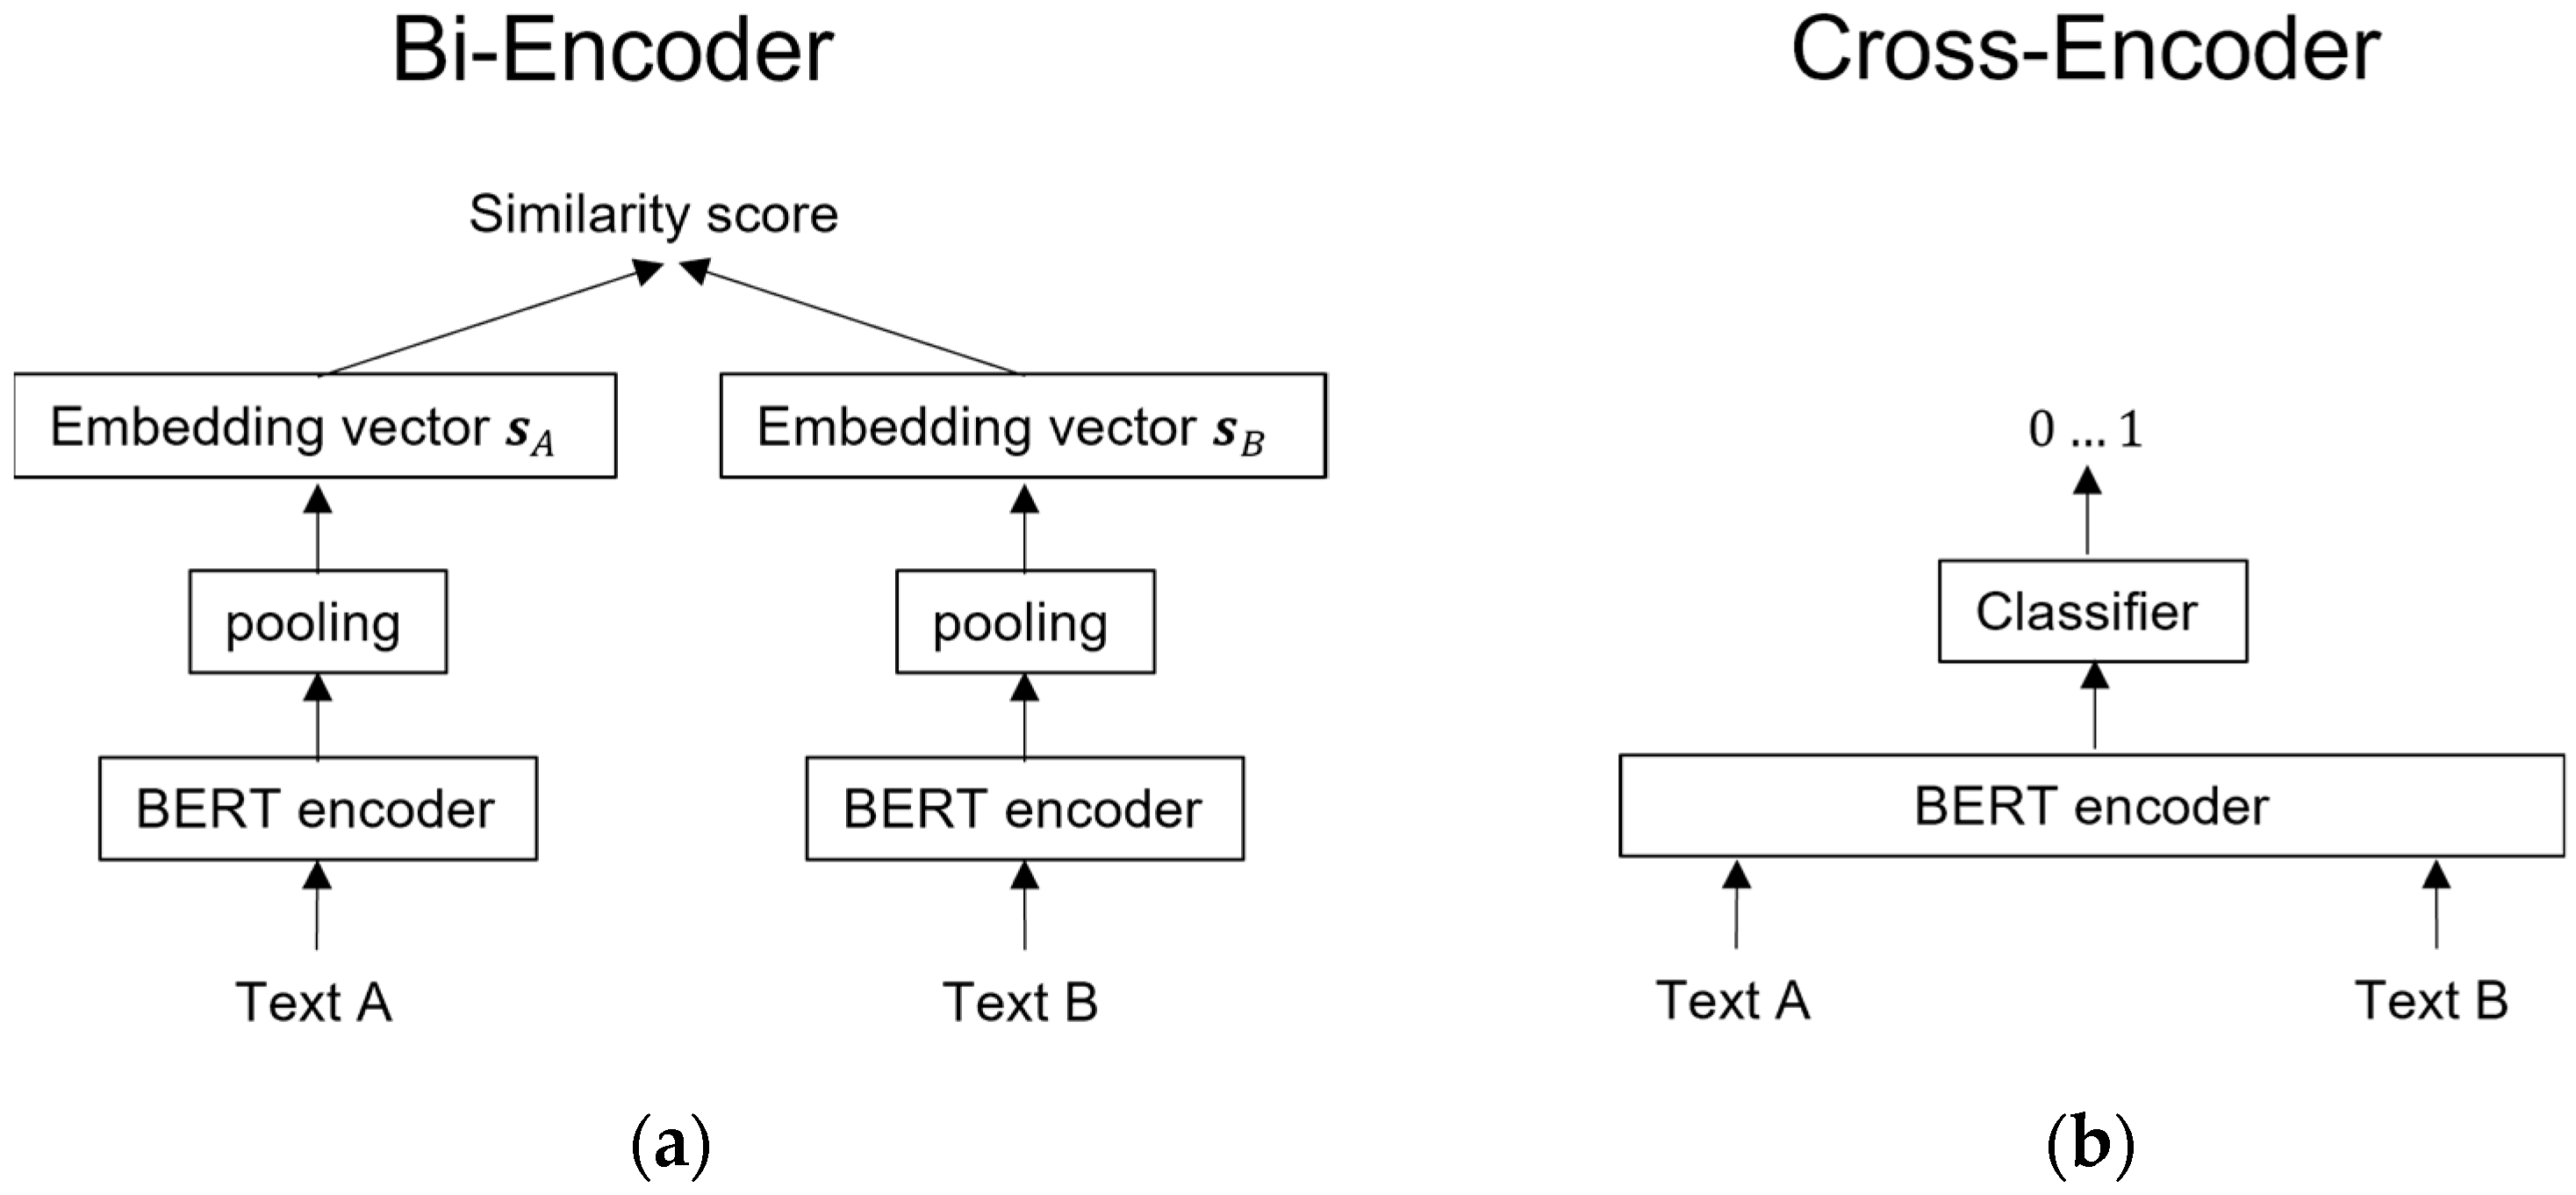
As shown in Figure 1, there are two types of SBERT: the bi-encoder model, which uses two BERT encoders to compare two texts, and the cross-encoder model, which uses only one BERT encoder. The bi-encoder model has the advantage of operating at high speed, but the cross-encoder model is more accurate and is suitable for re-ranking small numbers of documents [15]. Because our final goal was to eventually be able to find similar texts from more than 30,000 texts in the future, we chose the bi-encoder model, which is suitable for this application.
Figure 1.
SBERT architectures: (a) the bi-encoder model and (b) the cross-encoder model.
We employed the two Japanese pretrained BERT models shown in Table 1 for the SBERT encoders. UTH-BERT [16] was trained with ~120 million lines of clinical texts stored in the electronic health record system of the University of Tokyo Hospital (UTH). Although UTH-BERT does not have a large vocabulary (25,000 tokens), it is rich in medical terms. Therefore, we considered UTH-BERT to be suitable for this study of medical accidents.
Table 1.
The specifications of the pretrained BERT models.
In contrast, NICT-BERT [17] is a generic BERT model created by the National Institute of Information and Communications Technology (NICT) and trained on all articles in Japanese Wikipedia. Because it has a rich vocabulary of 100,000 tokens, we chose it for comparison with UTH-BERT. For both the UTH-BERT and NICT-BERT tokenizers, we used the morphological analysis engine MeCab [18] implemented in Hugging Face Transformers with the external dictionaries specified for each BERT model.
2.2. Datasets of Medical Accidents
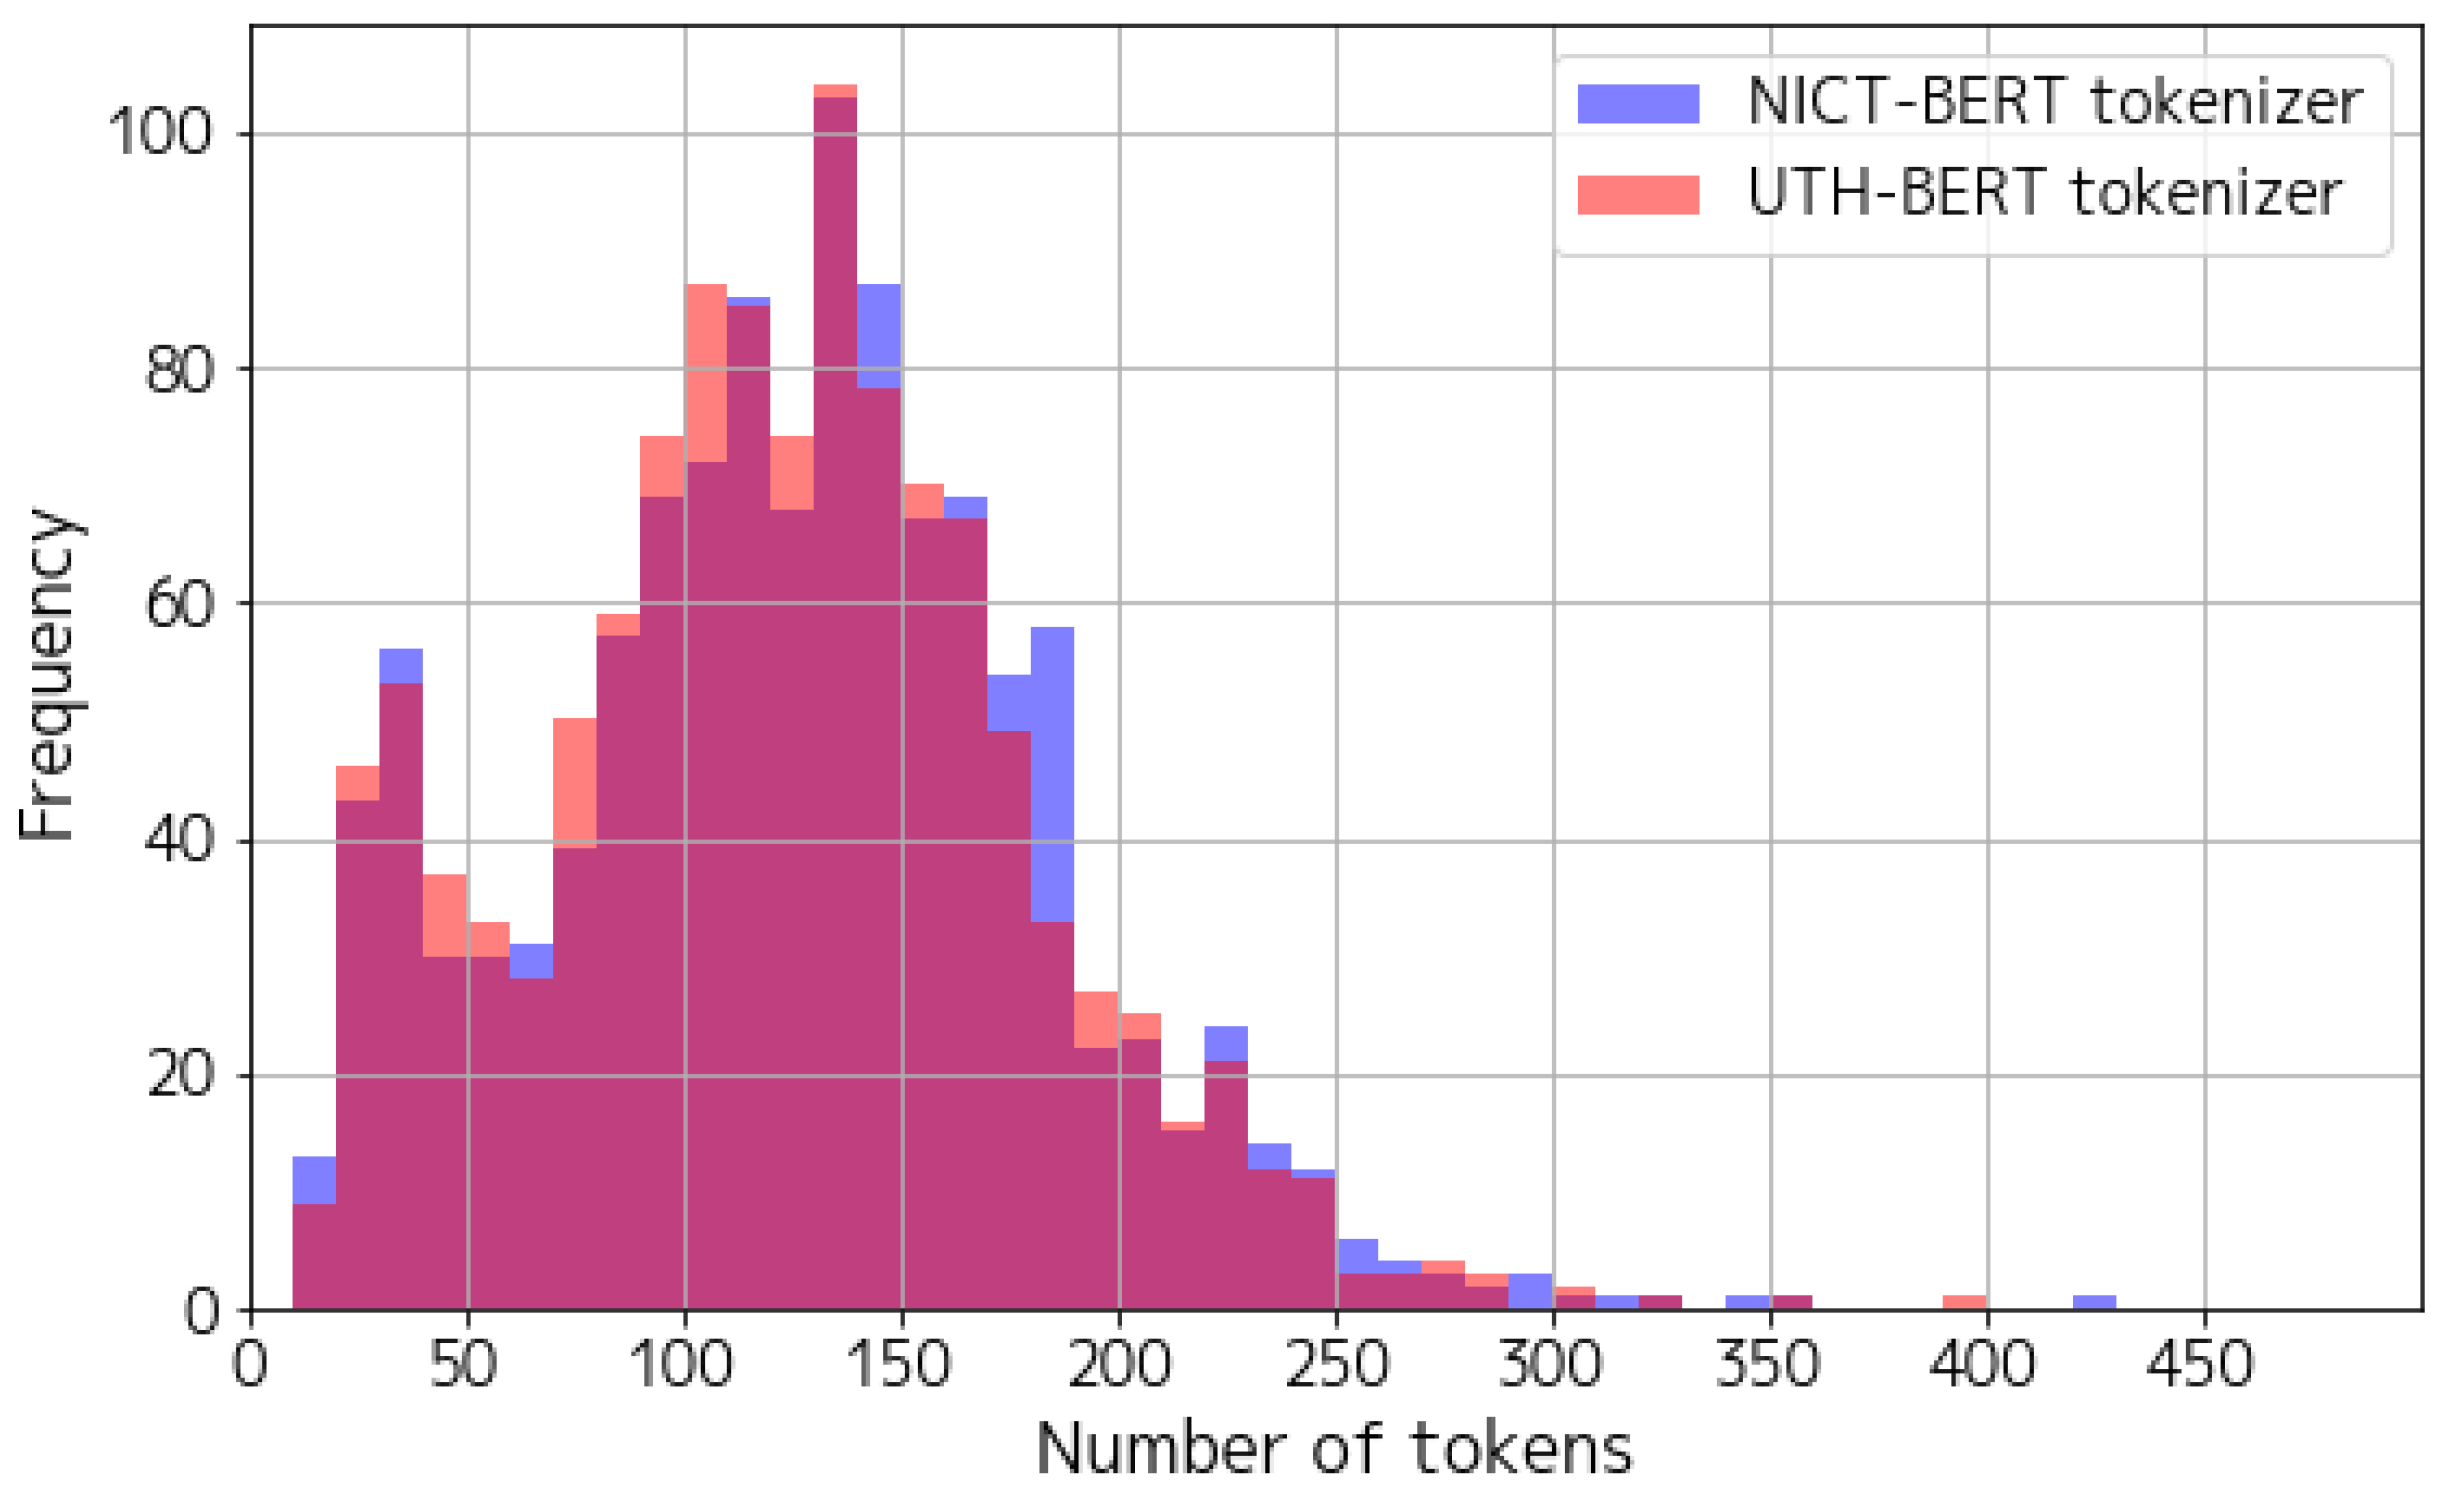
We used 1165 closed claims handled by SJ’s Tokyo office from April 2018 to March 2019 as the dataset for medical accidents. For each case, we manually created a short text summarizing the medical process, patient outcome, and legal liability outcome based on paper documents stored in the SJ office. Figure 2 shows a histogram of the number of tokens in the short texts; there is little difference between the histograms for the UTH-BERT and NICT-BERT tokenizers. The mean and maximum numbers of tokens were 123 and 399 for the UTH-BERT tokenizer and 126 and 425 for the NICT-BERT tokenizer, respectively. The maximum numbers of tokens were smaller than the maximum sequence length of 512 in both UTH-BERT and NICT-BERT, and no sentence truncation occurred.
Figure 2.
A histogram of the numbers of tokens in the short summary texts of medical accidents. The purple area is where the NICT-BERT tokenizer area shown in blue overlaps the UTH-BERT tokenizer area shown in red.
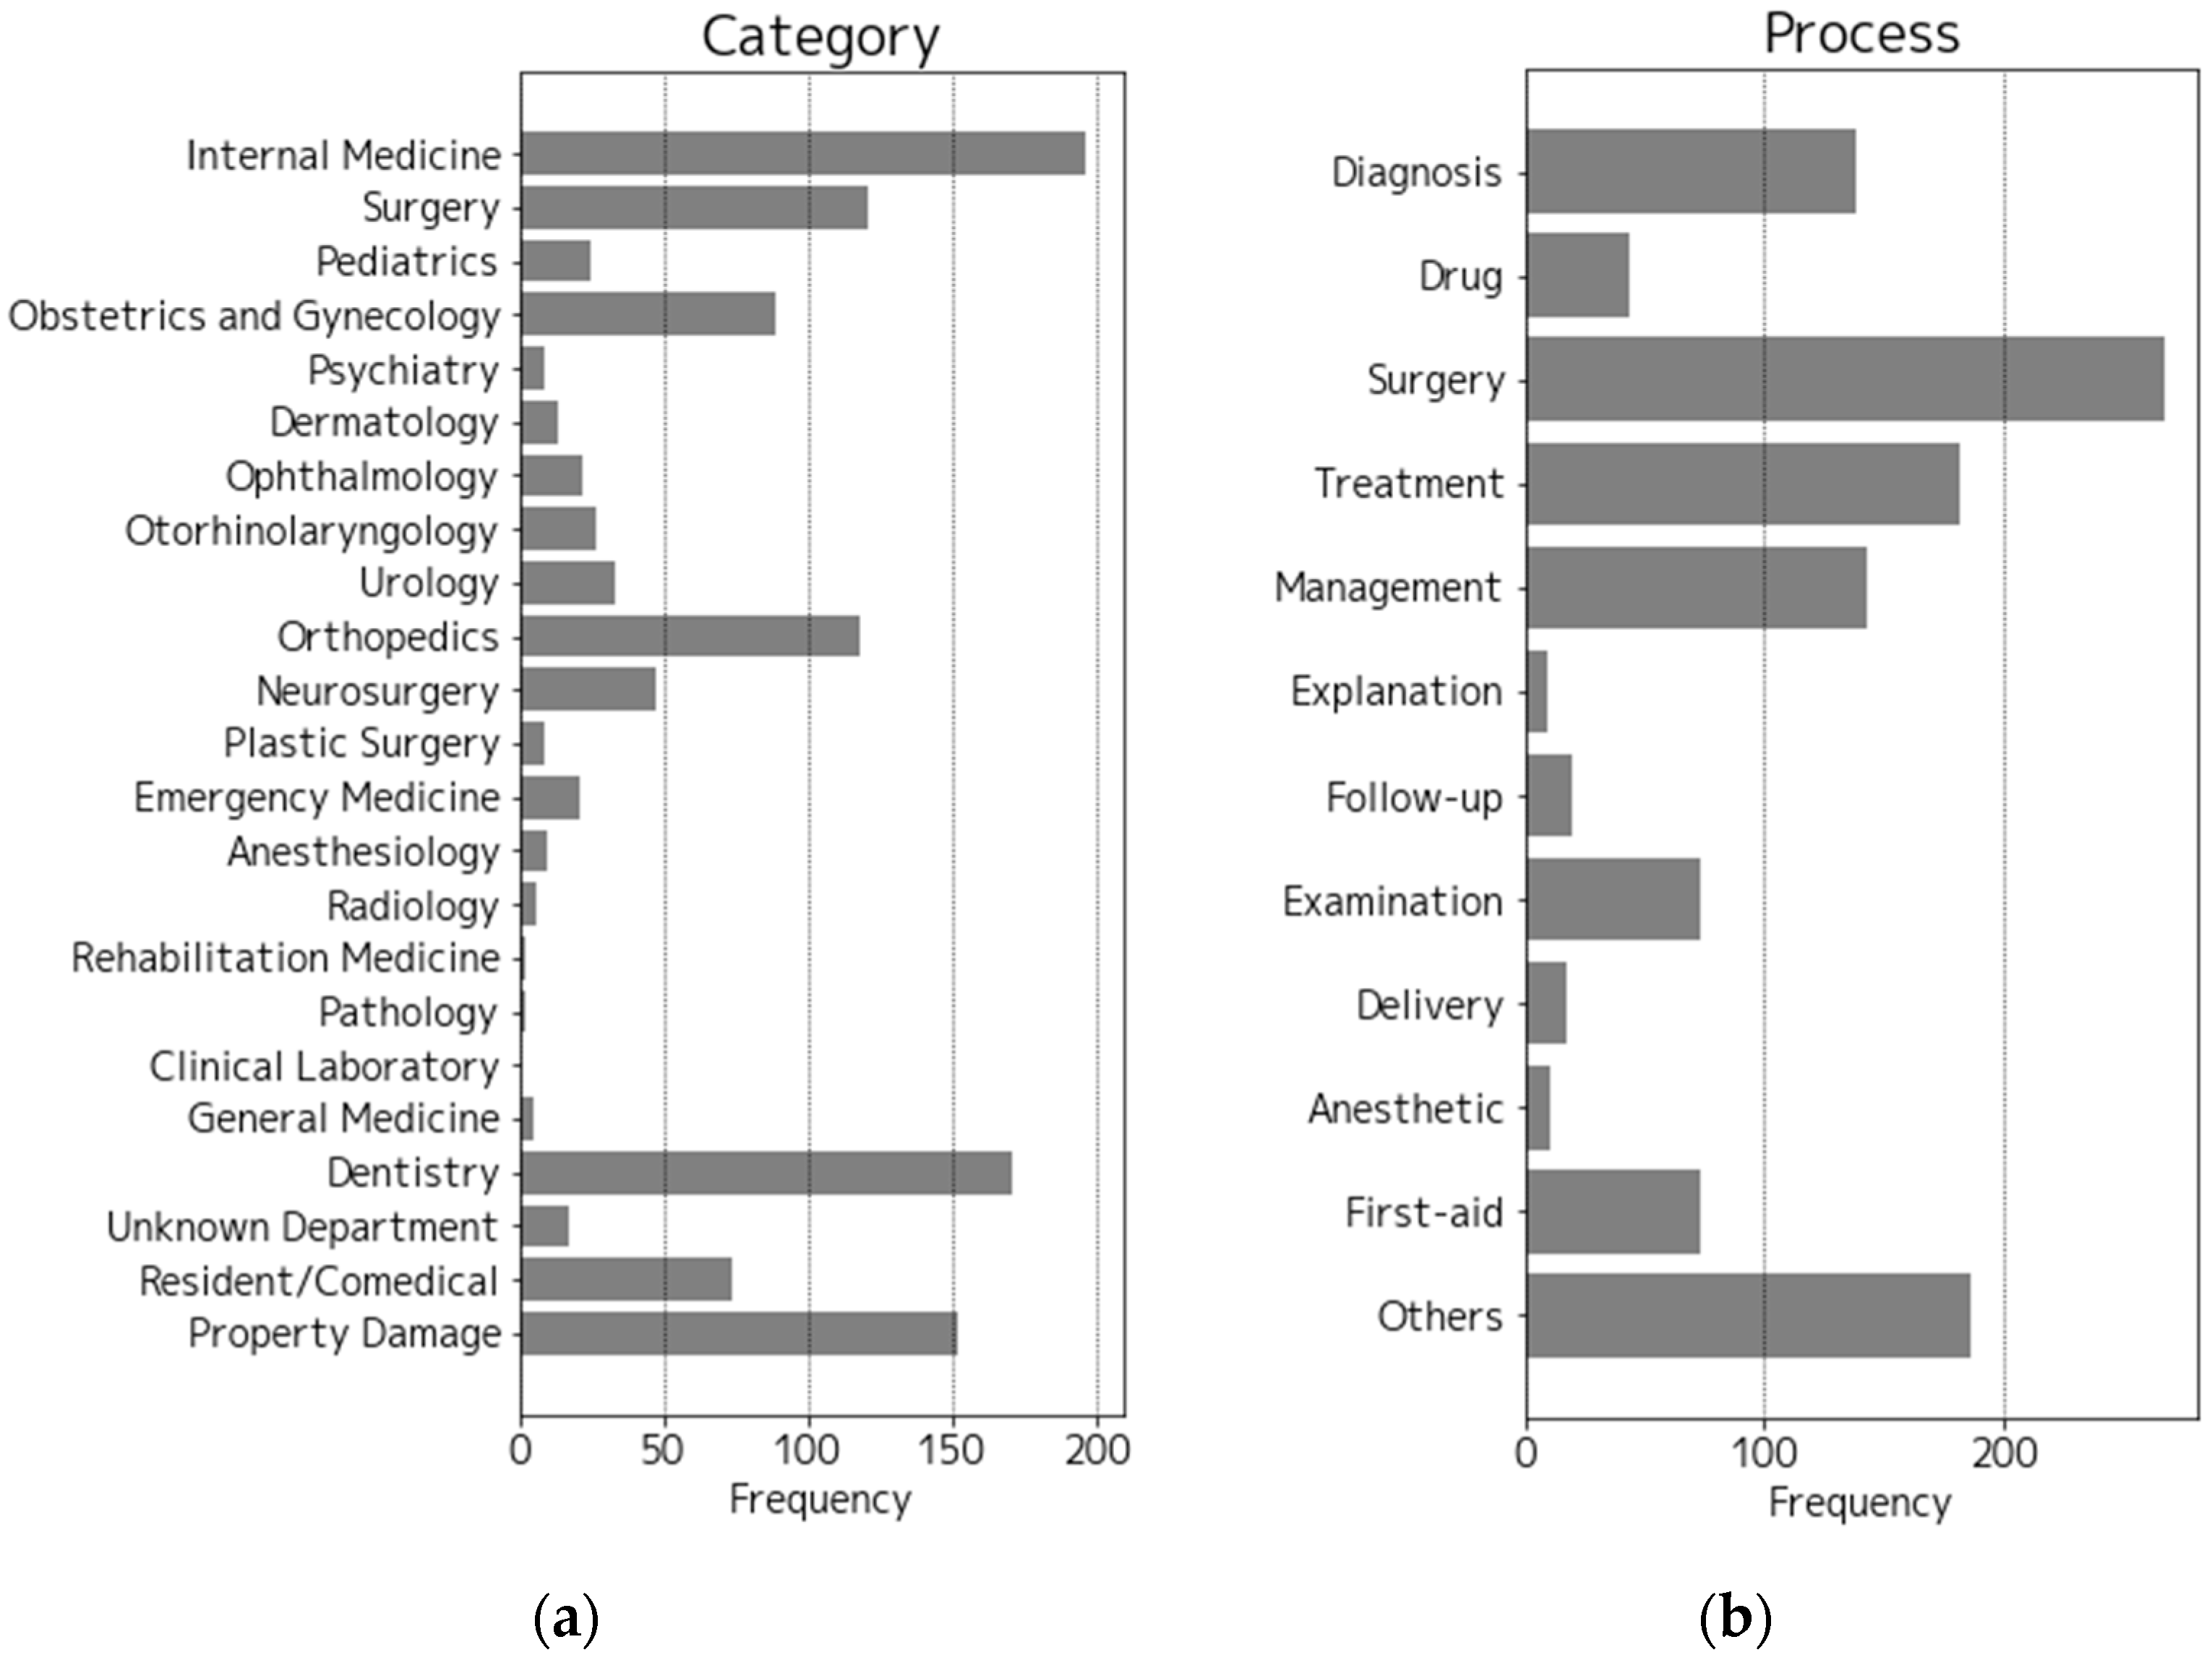
We also manually annotated each accident case with its category and process; the category identified the hospital department, medical profession, and property damage (e.g., patient’s spectacles dropped and broken), and the process indicated a failed medical procedure. Figure 3 shows the different categories and processes and the frequencies of appearance of each in the dataset. The most frequent categories were internal medicine, surgery, obstetrics and gynecology, orthopedics, and dentistry, and the most frequent processes were diagnosis, surgery, treatment, and management. There was no intentional bias in the data collection.
Figure 3.
The (a) categories and (b) processes that occurred most often in the dataset according to their frequency of appearance.
Y. Otaki, a physician and lawyer, and an assistant on the project performed the documentation and annotation through trial and error from March 2019 to August 2022. Specific examples of the short texts and the labels are listed in Tables 4 and 5 in Section 3.2.
2.3. Similarity Scores
The similar text search engines we developed extracted the top-K texts with good similarity scores for a given query. Here let be a multilabel dataset consisting of multilabel instances . The short text contains keywords . In creating the keywords, we performed word segmentation using the UTH-BERT tokenizer or the NICT-BERT tokenizer and stop word removal using the dictionary of Japanese stop words from SlothLib [19]. The multilabel is defined as a one-hot vector of
In similar text retrieval by SBERT, we measured the similarity between two texts with the Euclidean distance in the following formula:
where is the embedding of the text derived by the BERT encoder. The smaller the Euclidean distance, the more similar the two texts.
We also built a similar text retrieval system using Okapi BM25 to compare with the SBERT system. For the Okapi BM25 system [7,20], we measured the similarity given by
where is the number of times that occurs in the text , avgdl is the average text length in the dataset , and and are free parameters. is the inverse document frequency weight of the query keyword . This is given by
where is the number of texts that contained . A higher BM25 indicates greater similarity between the two texts.
2.4. Evaluation Metrics
In this study, we employed the degrees of agreement between labels of a query and labels of similar texts as measures of similar text retrieval accuracy. We focused not on ranking the extracted similar texts but rather on how many of the top-K similar instances had labels that matched the query. In multilabel machine learning [21], there are three possible states of label agreement: complete match, partial match, and complete mismatch. First, we defined the exact match ratio as a measure of complete match. Here the top-K instances similar to a query instance found by search engines in dataset are . The multilabel is given by a one-hot vector of . Then, the exact match ratio is given by
where is the indicator function:
In some of the extracted similar texts, one label matches that of the query, but the other label is different (e.g., surgical vs. dental anesthesia accidents). Therefore, we defined the Hamming score in the following equation as a measure of partial match:
The Hamming score is sometimes referred to simply as accuracy in multilabel classification tasks; we also defined the Hamming loss as a measure of mismatch:
Finally, we averaged the above evaluation measures defined for individual queries for all queries. Let be a training dataset and be a testing dataset, and we defined the averaged metrics with the following equations:
Larger averaged exact match ratios and Hamming scores and smaller averaged Hamming losses are better. In the results discussed below, , the number of extracted similar instances, was fixed at 10.
2.5. Optimization Method
Table 2 lists the hyperparameters used when training SBERT. We used the loss function of multiple negatives ranking (MNR) loss [22] to train the SBERT used in the search engine. MNR loss has the advantage of only requiring a pair of original text and similar text, whereas the loss function of triplet loss used in the first SBERT paper [14] required a set of original text (anchor), similar text (positive), and dissimilar text (negative). For optimizer, batch size, learning rate, pooling strategy, and warmup rate, we followed the parameters used in the first SBERT paper. We adopted 15 as the optimal number of epochs based on preliminary experiments with other parameters fixed. The maximum sequence length was given by the maximum number of tokens in the dataset plus 3, the number of special tokens ([CLS] and [SEP]), and a trailing blank. We split the dataset into training, evaluation, and testing sets and allocated 80% to training, 10% to evaluation, and 10% to testing. We used random numbers for the data splitting and for the initial value setting during training. We calculated the evaluation metrics based on the means of the results with 10 different random seeds.
Table 2.
Specific hyperparameters for SBERT training.
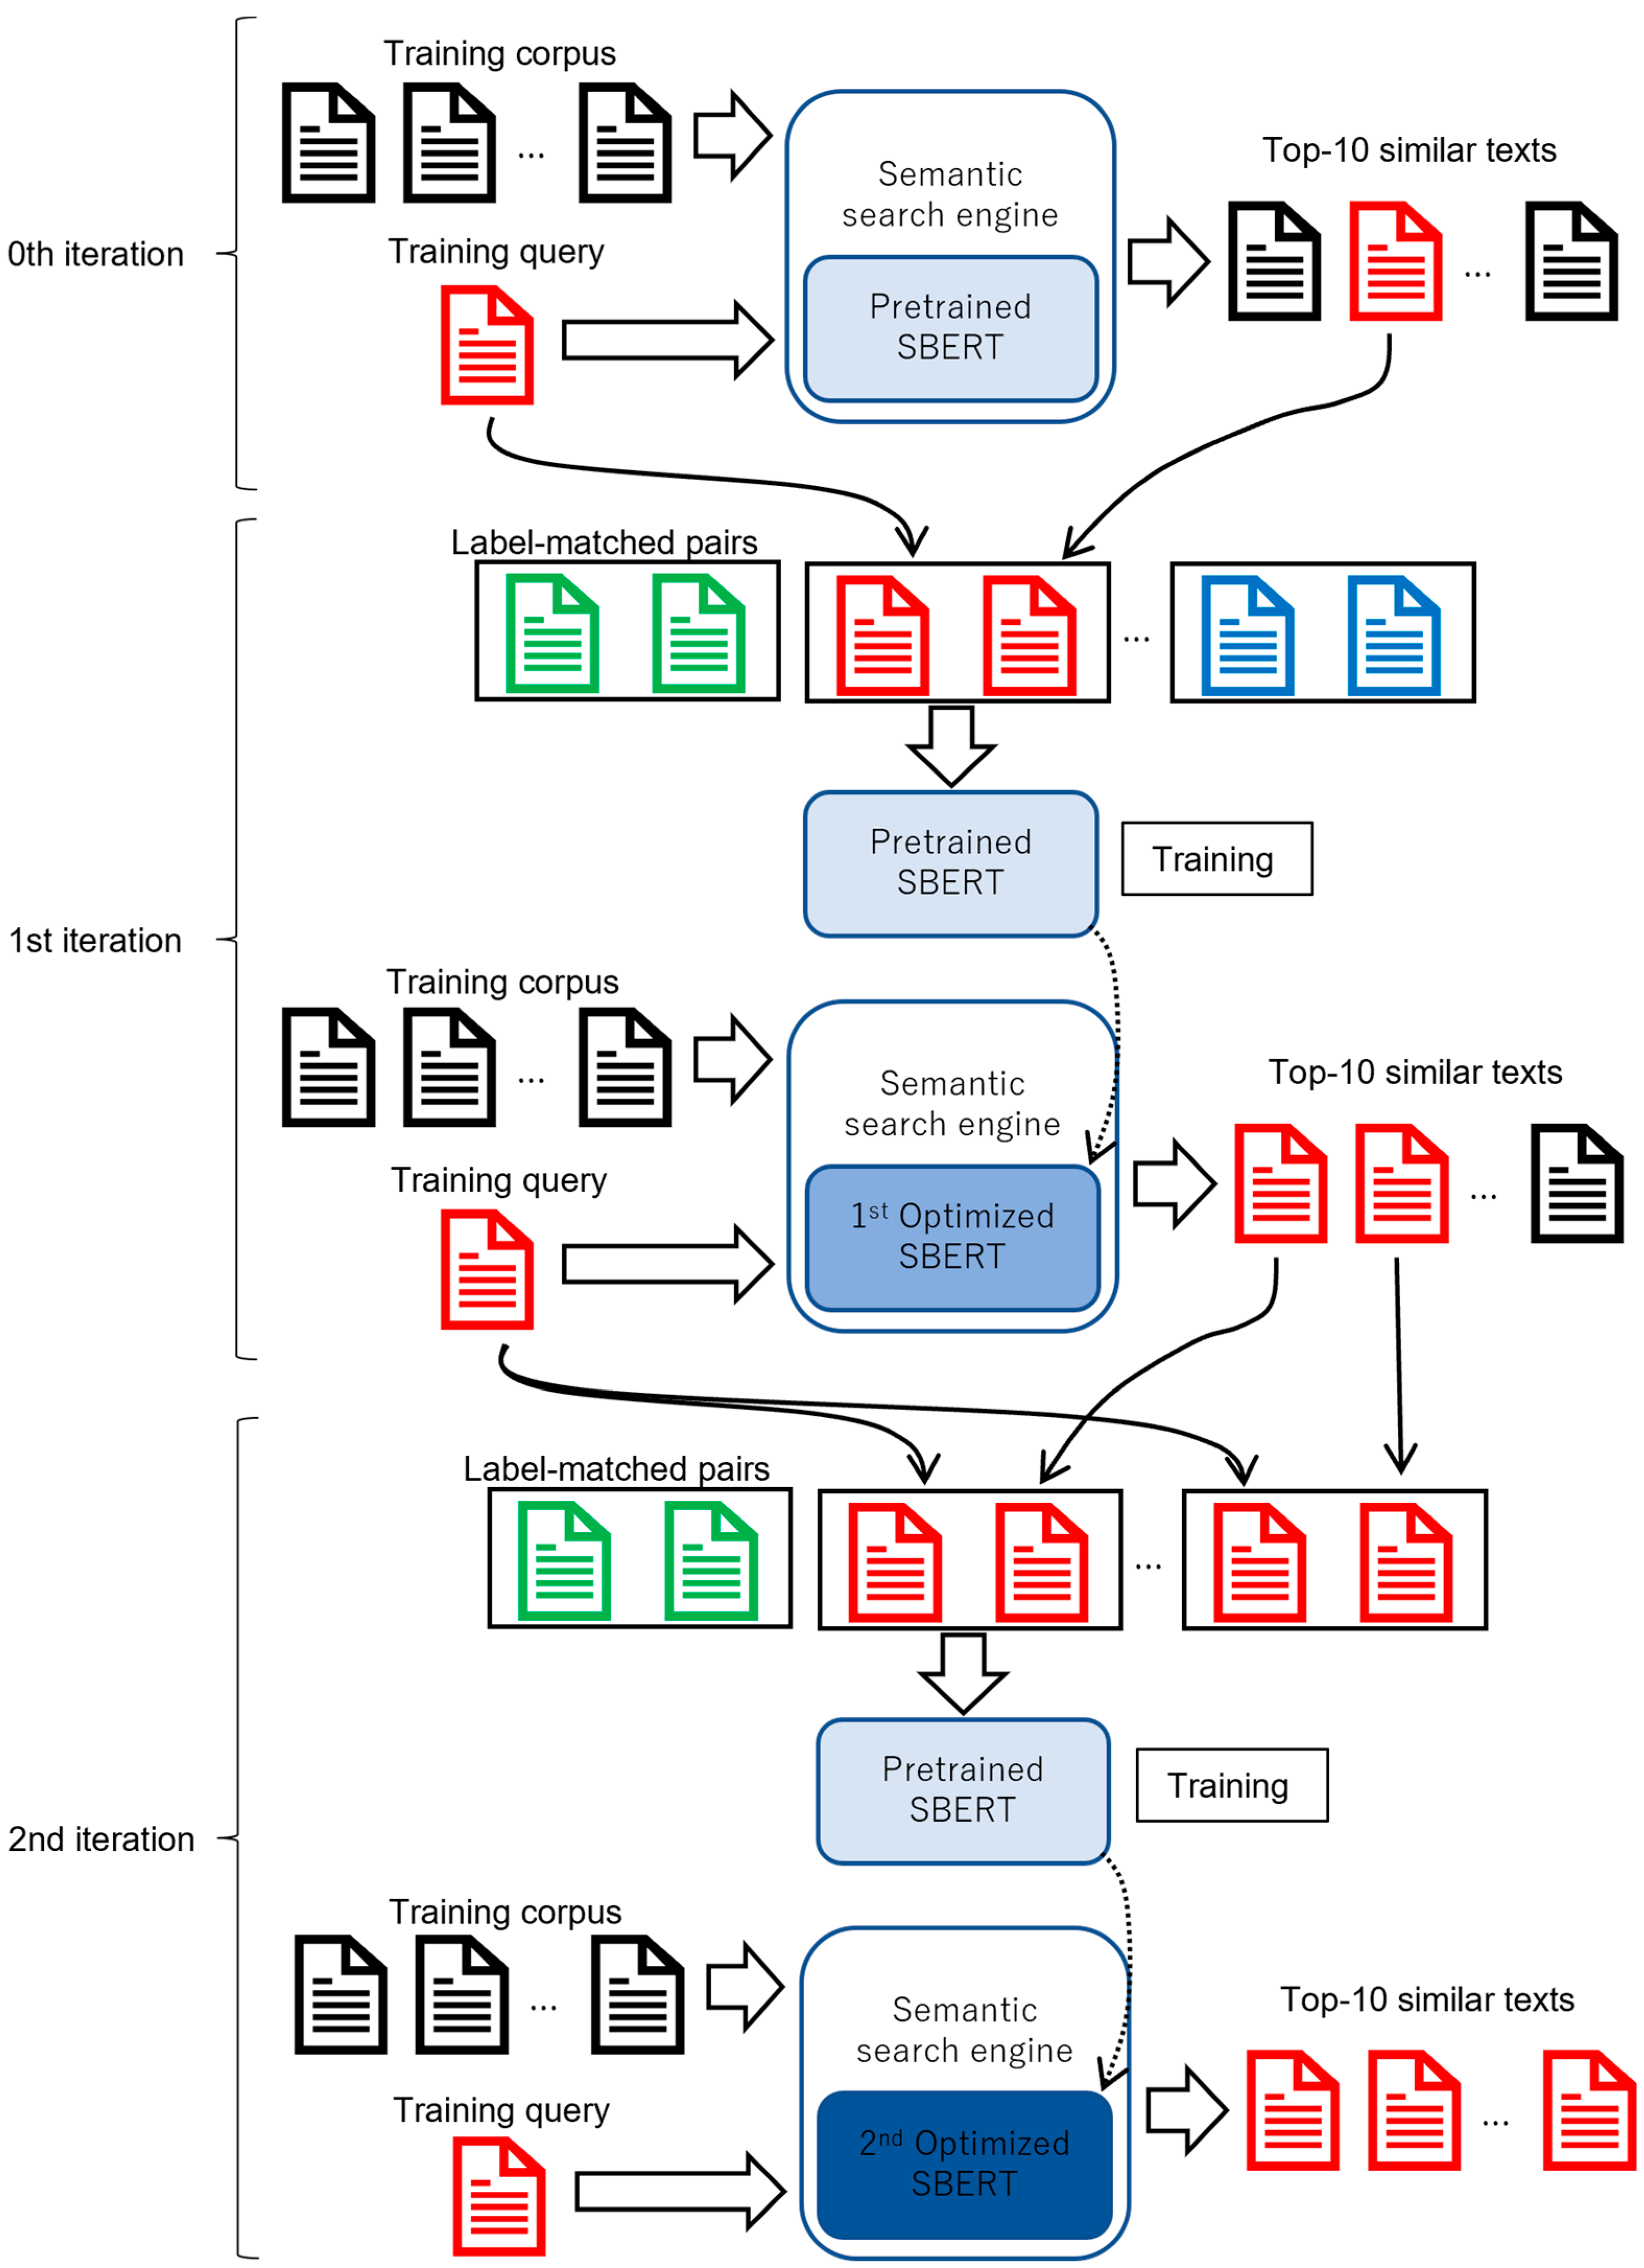
We note here that it is very labor intensive to manually create the text pairs needed to train SBERT with MNR loss; therefore, we developed the iterative method shown in Figure 4. First, as the zeroth iteration, a search engine using a pretrained SBERT and given the entire training dataset as a database corpus would find 10 similar texts for one query selected from the training dataset in order of best similarity score defined as Euclidean distance; here the same text as the query was excluded. If any of the 10 similar texts had labels that exactly matched those of the query, we created label-matched pairs with the query and the similar texts, and we repeated this with all texts in the training dataset as queries to build a dataset of label-matched pairs. Next, as the first iteration, we trained SBERT using the dataset of label-matched pairs with MNR loss. Then, we created a renewed dataset of label-matched pairs for the second iteration using a search engine with the trained SBERT (first optimized SBERT in Figure 4). We performed these iterations 10 times. We expected that this iterative process would efficiently expand the dataset of label-matched pairs and gradually improve the accuracy of the search. Finally, we chose the SBERT model that yielded the best retrieval accuracy among the 10 iterations.
Figure 4.
The SBERT iterative optimization method. Documents of the same color indicate that the labels are an exact match.
3. Results
3.1. Effectiveness of the Iterative Optimization Method
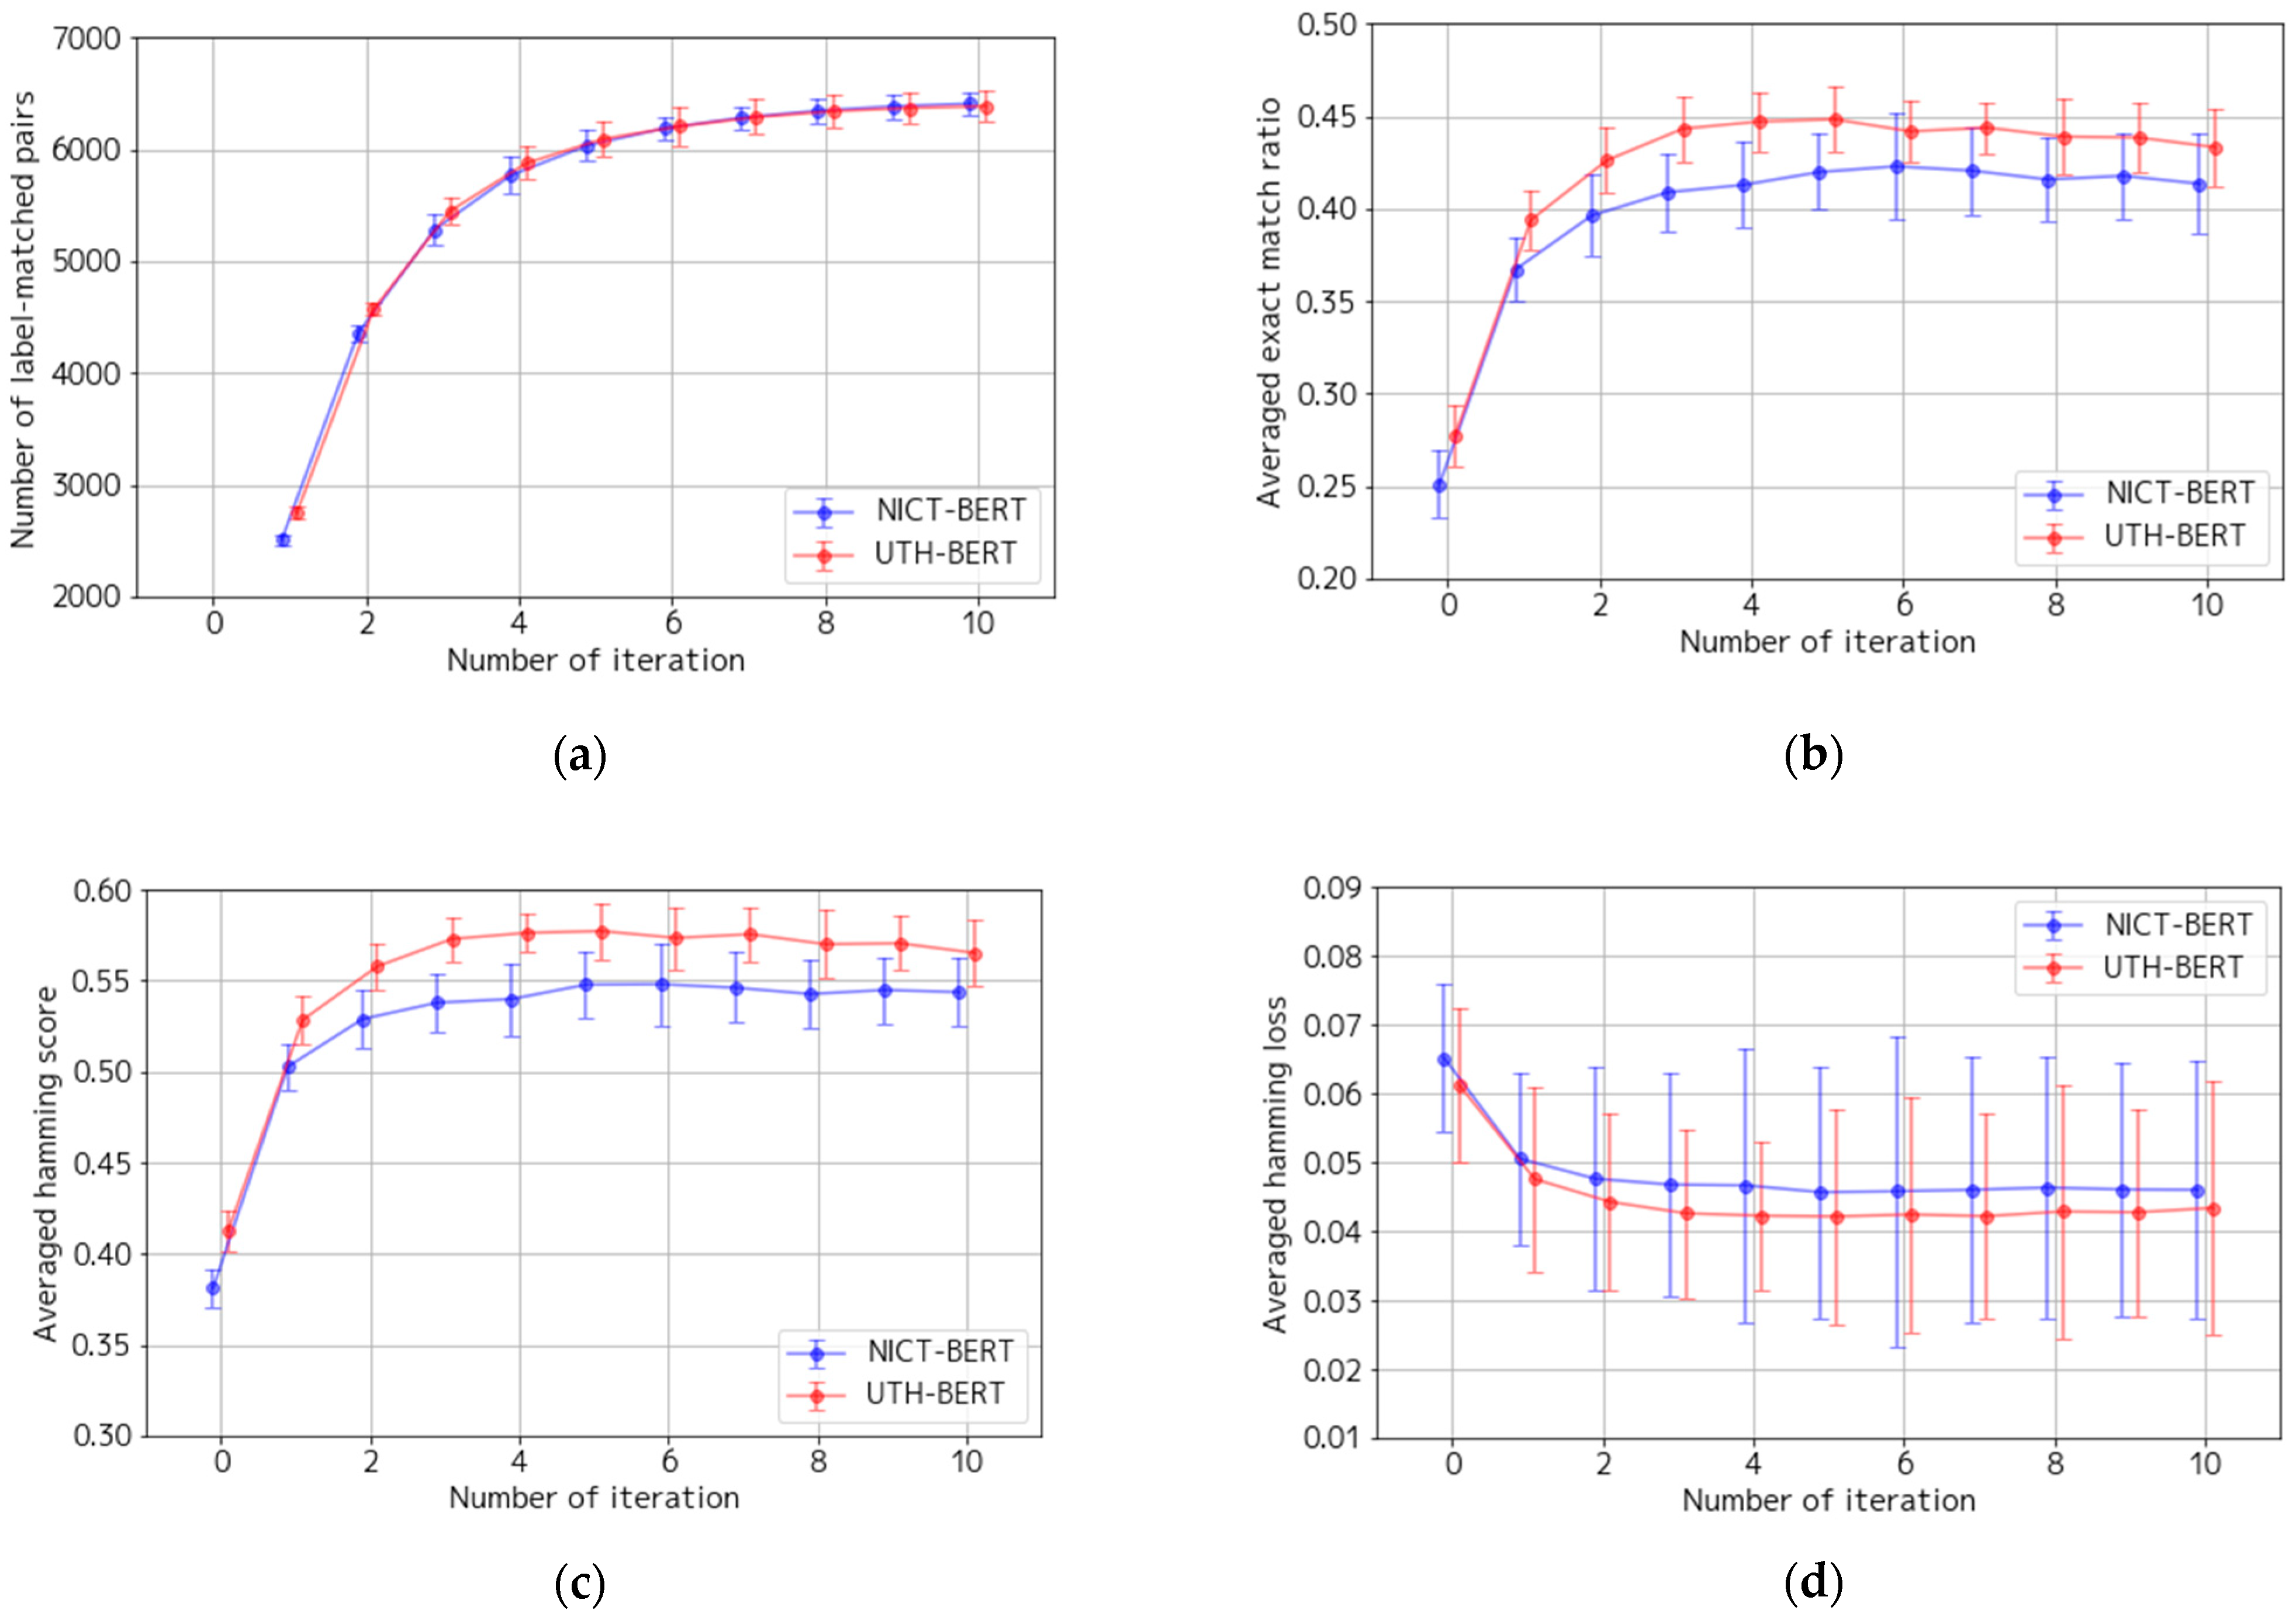
In this section, we present the results of training SBERT with the iterative optimization method described in Section 2.5. Figure 5a shows the number of label-matched pairs versus the number of iterations; as expected, the number of pairs showed a monotonic increase with the number of iterations and almost saturated at the eighth iteration. Figure 5b shows the averaged exact match ratio, a measure of complete match, versus the number of iterations; overall, UTH-BERT performed better than NICT-BERT. For UTH-BERT, the averaged exact match ratio was 27% with the pretrained model (zeroth iteration in the graph), but it improved to 45% at the fifth iteration, after which it declined. Figure 5c shows the averaged Hamming score, a measure of partial match, against the number of iterations, which showed the same characteristics as the change in the averaged exact match ratio. Figure 5d shows the averaged Hamming loss, a measure of mismatch, versus the number of iterations; a smaller averaged Hamming loss means fewer mismatches. Both UTH-BERT and NICT-BERT improved until the fourth iteration, after which we observed almost no change.
Figure 5.
Changes in the numbers of label-matched pairs and evaluation metrics with the optimization iterations: (a) number of label-matched pairs, (b) averaged exact match ratio, (c) averaged Hamming score, and (d) averaged Hamming loss. The dots and the error bars indicate the mean and the standard deviation of the results from 10 different random seeds, respectively. To distinguish between UTH-BERT and NICT-BERT symbols, the UTH-BERT iteration number is offset by +0.1, and the NICT-BERT iteration number is offset by −0.1. The zeroth iteration shows the results from the pretrained SBERT systems.
3.2. Comparison between Search Engines
In this section, we compare the search accuracies of the search engine using the optimized SBERT with those of the search engines using the pretrained SBERT and Okapi BM25 as shown in Table 3; we found that the pretrained SBERT and Okapi BM25 were equally accurate. Using the trained SBERT system optimized by the iterative method described in the previous section, both the averaged exact match ratio and averaged Hamming score improved by more than 15 points. In addition, UTH-BERT performed two to three points better than NICT-BERT. Table 4 and Table 5 show specific examples of search results for a specific query by search engines using the pretrained SBERT and the trained SBERT with UTH-BERT, respectively. Comparing the results in Table 4 and Table 5, it is clear that the trained SBERT is more accurate.
Table 3.
Comparison between search engines; bold type indicates the best results. The value of each evaluation metric is the mean and the standard deviation (SD) of the results from 10 different random seeds. The UTH-BERT and NICT-BERT results are derived from the fifth and sixth iterations in the iterative optimization, respectively.
Table 4.
An example results of a similar text search by the PRETRAINED SBERT with the UTH-BERT model. The labels in red are those that match the labels in the query.
Table 5.
An example results of a similar text search by the TRAINED SBERT with the UTH BERT model. The query is the same as in Table 4. The labels in red are those that match the labels in the query.
4. Discussion
The purpose of this study was to develop an information retrieval system to find similar accidents to a specific medical accident with high accuracy and high speed for a Japanese database of 1165 closed medical malpractice claims. In the database, we manually created a short text summarizing each accident and assigned each a category and a process (e.g., orthopedics and surgery or plastic surgery and follow-up). We developed the semantic search engines based on SBERT, which was reported to have excellent speed and accuracy in extracting similar texts [14]. The search engines extracted 10 similar summary texts that were close to a given query in the Euclidean distance of the embedding. To train SBERT, we conducted iterative optimization to efficiently expand the training dataset and gradually increase the retrieval accuracy. We defined three evaluation metrics that indicated how well the labels of the 10 extracted similar instances matched the labels of the query: averaged exact match ratio, averaged Hamming score, and averaged Hamming loss. For the SBERT encoder, we employed UTH-BERT, the medical BERT model pretrained on clinical records, and NICT-BERT, a generic BERT model pretrained on Japanese Wikipedia articles, and we compared the results from these models. We also built search engines based on lexical similarity using Okapi BM25 for comparison.
In the early stages of the iterative optimization, the number of label-matched pairs increased with the number of iterations, and the search accuracy improved as expected. This could mean that the SBERT model gradually adapted to the style of texts in our database through the iterative optimization while updating the dataset. The evaluation metrics were highest around the middle five of the ten iterations, after which there was a gradual decline. The reason the search accuracy did not monotonically increase with the number of iterations could have been duplicated label-matched pairs in the dataset and/or over-training on the training dataset. The current implementation allowed for duplicating the pairs created when the query was ‘A’ and its similar text was ‘B’ and pairs created when the query was ‘B’ and its similar text was ‘A’ . Duplications increased with each optimization iteration, which might have prevented accuracy from improving. In the future, the iterative optimization algorithm should be modified to prevent this duplication.
The search engine using the best SBERT obtained via iterative optimization showed higher search accuracy than the search engine using Okapi BM25 using both UTH-BERT and NICT-BERT as encoders. In both the study on detecting COVID-19 misinformation on social media [23] and the study on unsupervised FAQ retrieval with question generation [24], the information retrieval systems using BERT are 15 to 20 points more accurate for mean reciprocal rank (MRR) than those using BM25. Our results are consistent with these previous studies in that BERT performs better than BM25.
In the search engine using trained SBERT, the system using UTH-BERT as the encoder showed a higher search accuracy than the one using NICT-BERT as the encoder. In a study on extracting pain expression from medical records using UTH-BERT [25], UTH-BERT showed ~10 points higher accuracy in the F1-score evaluation than Kyoto University BERT, which was pretrained on Japanese Wikipedia articles. Our result is consistent with the previous study’s finding in that UTH-BERT performed better than the general BERT models for medical texts. We consider that the higher retrieval accuracy of UTH-BERT than of NICT-BERT is largely owing to the accuracy of morphological analysis. To give an example, 犬吠様咳嗽 (the Japanese expression kennel cough) became a single token with the UTH-BERT tokenizer, where the vocabulary was created from the corpus of clinical records. In contrast, the NICT-BERT tokenizer split 犬吠様咳嗽into four tokens, 犬 (dog), 吠様 (barking-like), 咳 (cough), and 嗽 (gargling), which have somewhat different meanings.
As described above, a similar document retrieval system using the trained SBERT demonstrated high retrieval accuracy in our closed-claims database. Currently, we are working on expanding our database, which we expect to eventually have more than 30,000 cases. By applying the search system we established in this study, we expect to be able to utilize the expanded closed-claims database more effectively when extracting similar medical accidents.
Author Contributions
Conceptualization, N.F., Y.O. and S.K.; methodology, N.F.; software, N.F.; validation, N.F., Y.O. and S.K.; formal analysis: N.F. and Y.O.; data curation, N.F. and Y.O.; writing—original draft preparation, N.F.; writing—review and editing, N.F., Y.O. and S.K.; visualization, N.F.; supervision, S.K.; project administration, Y.O.; funding acquisition, N.F. and Y.O. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported by JSPS KAKENHI Grant Numbers JP18KT0099, JP19K10542, and JP21K10359.
Institutional Review Board Statement
This study complied with the Japanese epidemiologic study guidelines and was approved by the ethics committee of our university: Teikyo University Ethical Review Board for Medical and Health Research Involving Human Subjects (authorized number Teirin19-059). To preserve anonymity, no short texts or labels created in this study contained information that could identify specific individuals or organizations. Therefore, the ethics committee waived the requirement for informed consent in this retrospective study.
Informed Consent Statement
Not applicable.
Data Availability Statement
All relevant data are within the paper. Researchers need to contact the author, Yasuhiro Otaki, for access to the original summary text and the labels of each medical accident.
Acknowledgments
We would like to thank Hanaoka, the assistant, for her help in writing the short text summaries and annotating. We would like to thank Tatsuji Katsuki for his help in data curation.
Conflicts of Interest
The authors declare no conflict of interest.
References
- The Project to Collect Medical Near-Miss/Adverse Event Information. Available online: https://www.med-safe.jp/ (accessed on 31 January 2023).
- Japan Medical Safety Research Organization. To Secure Medical Safety “Medical Accident Investigation System” in Japan. Available online: https://www.medsafe.or.jp/uploads/uploads/files/leaflet_english.pdf (accessed on 31 January 2023).
- Medical Professional Liability Association. Available online: https://www.mplassociation.org/ (accessed on 31 January 2023).
- Otaki, Y.; Ishida, M.D.; Saito, Y.; Oyama, Y.; Oiso, G.; Moriyama, M. Analysis of closed claims in the clinical management of rheumatoid arthritis in Japan. Chin. Med. J. 2017, 130, 1454–1458. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Otaki, Y.; DaSilva, M.I.; Saito, Y.; Oyama, Y.; Oiso, G.; Yoshida, T.; Fukuhara, M.; Moriyama, M. Characteristics of claims in the management of septic arthritis in Japan: Retrospective analyses of judicial precedents and closed claims. J. Chin. Med. Assoc. 2018, 81, 236–241. [Google Scholar] [CrossRef] [Scilit]
- Otaki, Y.; Fujishiro, N.; Oyama, Y.; Hata, N.; Kato, D.; Kawachi, S. The risk of fatal bleeding complications in jugular catheterization in patients with coagulopathy: A retrospective analysis of death cases in closed claims and the Medical Accident Investigating System in Japan. PLoS ONE 2022, 17, e0261636. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Robertson, S.E.; Walker, S. Some simple effective approximations to the 2-poisson model for probabilistic weighted retrieval. In Proceedings of the 17th Annual International ACM-SIGIR Conference on Research and Development in Information Retrieval, Dublin, Ireland, 3–6 July 1994; pp. 232–241. [Google Scholar]
- Mikolov, T.; Chen, K.; Corrado, G.; Dean, J. Efficient estimation of word representations in vector space. In Proceedings of the Workshop at the International Conference on Learning Representations, Scottsdale, AZ, USA, 2–4 May 2013. [Google Scholar]
- Le, Q.; Mikolov, T. Distributed representations of sentences and documents. In Proceedings of the 31st International Conference on Machine Learning (ICML 2014), Beijing, China, 21–26 June 2014; pp. 1188–1196. [Google Scholar]
- Pennington, J.; Socher, R.; Manning, C.D. Glove: Global vectors for word representation. In Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP 2014), Doha, Qatar, 25–29 October 2014; pp. 1532–1543. [Google Scholar]
- Bojanowski, P.; Grave, E.; Joulin, A.; Mikolov, T. Enriching word vectors with subword information. arXiv 2016, arXiv:1607.04606. [Google Scholar] [CrossRef] [Scilit]
- Devlin, J.; Chang, M.W.; Lee, K.; Toutanova, K. BERT: Pre-training of deep bidirectional transformers for language understanding. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers), Minneapolis, MN, USA, 2–7 June 2019; pp. 4171–4186. [Google Scholar] [CrossRef] [Scilit]
- Brown, T.B.; Mann, B.; Ryder, N.; Subbiah, M.; Kaplan, J.; Dhariwal, P.; Neelakantan, A.; Shyam, P.; Sastry, G.; Askell, A.; et al. Language models are few-shot learners. In Proceedings of the 34th International Conference on Neural Information Processing Systems, Vancouver, BC, Canada, 6–12 December 2020; pp. 1877–1901. [Google Scholar]
- Reimers, N.; Gurevych, I. Sentence-BERT: Sentence embeddings using Siamese BERT-networks. arXiv 2019, arXiv:1908.10084. [Google Scholar]
- Sentence-Transformers. Available online: https://www.sbert.net/ (accessed on 15 February 2023).
- Kawazoe, Y.; Shibata, D.; Shinohara, E.; Aramaki, E.; Ohe, K. A clinical specific BERT developed using a huge Japanese clinical text corpus. PLoS ONE 2021, 16, e0259763. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- NICT BERT: A Japanese Pre-Trained Model. Available online: https://alaginrc.nict.go.jp/nict-bert/index.html (accessed on 31 January 2023).
- MeCab: Yet Another Part-of-Speech and Morphological Analyzer. Available online: https://taku910.github.io/mecab/ (accessed on 31 January 2023).
- Ohshima, H.; Nakamura, S.; Tanaka, K. SlothLib: A programming library for research on web search. DBSJ Lett. 2007, 6, 113–116. [Google Scholar]
- Whissell, J.S.; Clarke, C.L. Improving document clustering using Okapi BM25 feature weighting. Inf. Retr. 2011, 14, 466–487. [Google Scholar] [CrossRef] [Scilit]
- Sorower, M.S. A Literature Survey on Algorithms for Multi-Label Learning. Ph.D. Thesis, Computer Science, Oregon State University, Corvallis, OR, USA, 2010. [Google Scholar]
- Henderson, M.; Al-Rfou, R.; Strope, B.; Sung, Y.H.; Lukács, L.; Guo, R.; Kumar, S.; Miklos, B.; Kurzweil, R. Efficient natural language response suggestion for smart reply. arXiv 2017, arXiv:1705.00652. [Google Scholar]
- Hossain, T.; Logan IV, R.L.; Ugarte, A.; Matsubara, Y.; Young, S.; Singh, S. COVIDLIES: Detecting COVID-19 misinformation on social media. In Proceedings of the Workshop on NLP for COVID-19 (Part 2), EMNLP, Virtual, 16–20 November 2020. [Google Scholar]
- Mass, Y.; Carmeli, B.; Roitman, H.; Konopnicki, D. Unsupervised FAQ retrieval with question generation and BERT. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, Virtual, 5–10 July 2020; pp. 807–812. [Google Scholar]
- Shibata, D.; Kawazoe, Y.; Shimamoto, K.; Shinohara, E.; Aramaki, E. Pain expressions extraction with pre-training BERT based on clinical note. In Proceedings of the Spring Meeting on Medical Informatics, Mito, Japan, 16–19 March 2020; Volume 40, pp. 73–82. [Google Scholar] [CrossRef]






Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2023 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).