


Abstract
In recent years, copyright infringement has been one of the most serious problems that hamper the development of the culture and arts industry. Due to the limitations of existing image search services, these infringements have not been properly identified and the number of infringements has been increasing continuously. To uncover these infringements and handle big data extracted from copyright photos, we propose a photo copyright identification framework to accurately handle manipulations of stolen photos. From a collage of cropped photos, regions of interest (RoIs) are detected to reduce the influence of cropping and identify each photo by Image RoI Detection. Binary descriptors for quick database search are generated from the RoIs by Image Hashing robustly to geometric and color manipulations. The matching results of Image Hashing are verified by measuring their similarity using the proposed Image Verification to reduce false positives. Experimental results demonstrate that the proposed framework outperforms other image retrieval methods in identification accuracy and significantly reduces the false positive rate by 2.8%. This framework is expected to identify copyright infringements in practical situations and have a positive effect on the copyright market.
1. Introduction
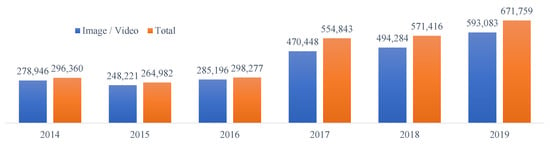
Copyright is one of the legal protections used to encourage creative activities as the creator’s exclusive right to use or allow others to use their content. Despite the legal protections, numerous copyright violations still occur worldwide by pirates. According to Copytrack [1], approximately 65M images in 115 countries suffer from copyright infringement and the damage from the stolen image is estimated at approximately USD 63M. If an illegal use is detected, corrective recommendations can be taken to compensate copyright holders by public institutions such as the Copyright Commission. In particular, as shown in Figure 1, the number of corrective recommendations for copyright infringement in South Korea is increasing. In 2019, more than 670,000 corrective recommendations were made and the total amount of compensation is approximately USD 28M [2].
Figure 1.
The number of corrective recommendations for copyright infringements reported by the Korea Copyright Commission from 2014 to 2019 in Korea [2].
More than 90% of the violations are images and videos, and it takes a lot of cost to manually identify and uncover hundreds of thousands of infringements. Considering the large number of photos and videos that have not yet been detected on the web, it is very inefficient to capture all of the infringements with human labor. An automated copyright photo identification method is required to efficiently capture these copyright infringements [3,4,5,6] by finding a perfectly identical original photo the same as an query image. When a subject is photographed at different angle at the same time, the photos are not identical but very similar, and it is a very challenging task to distinguish these photos considering the trade-off between speed and accuracy.
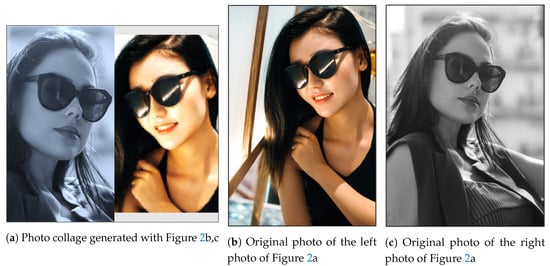
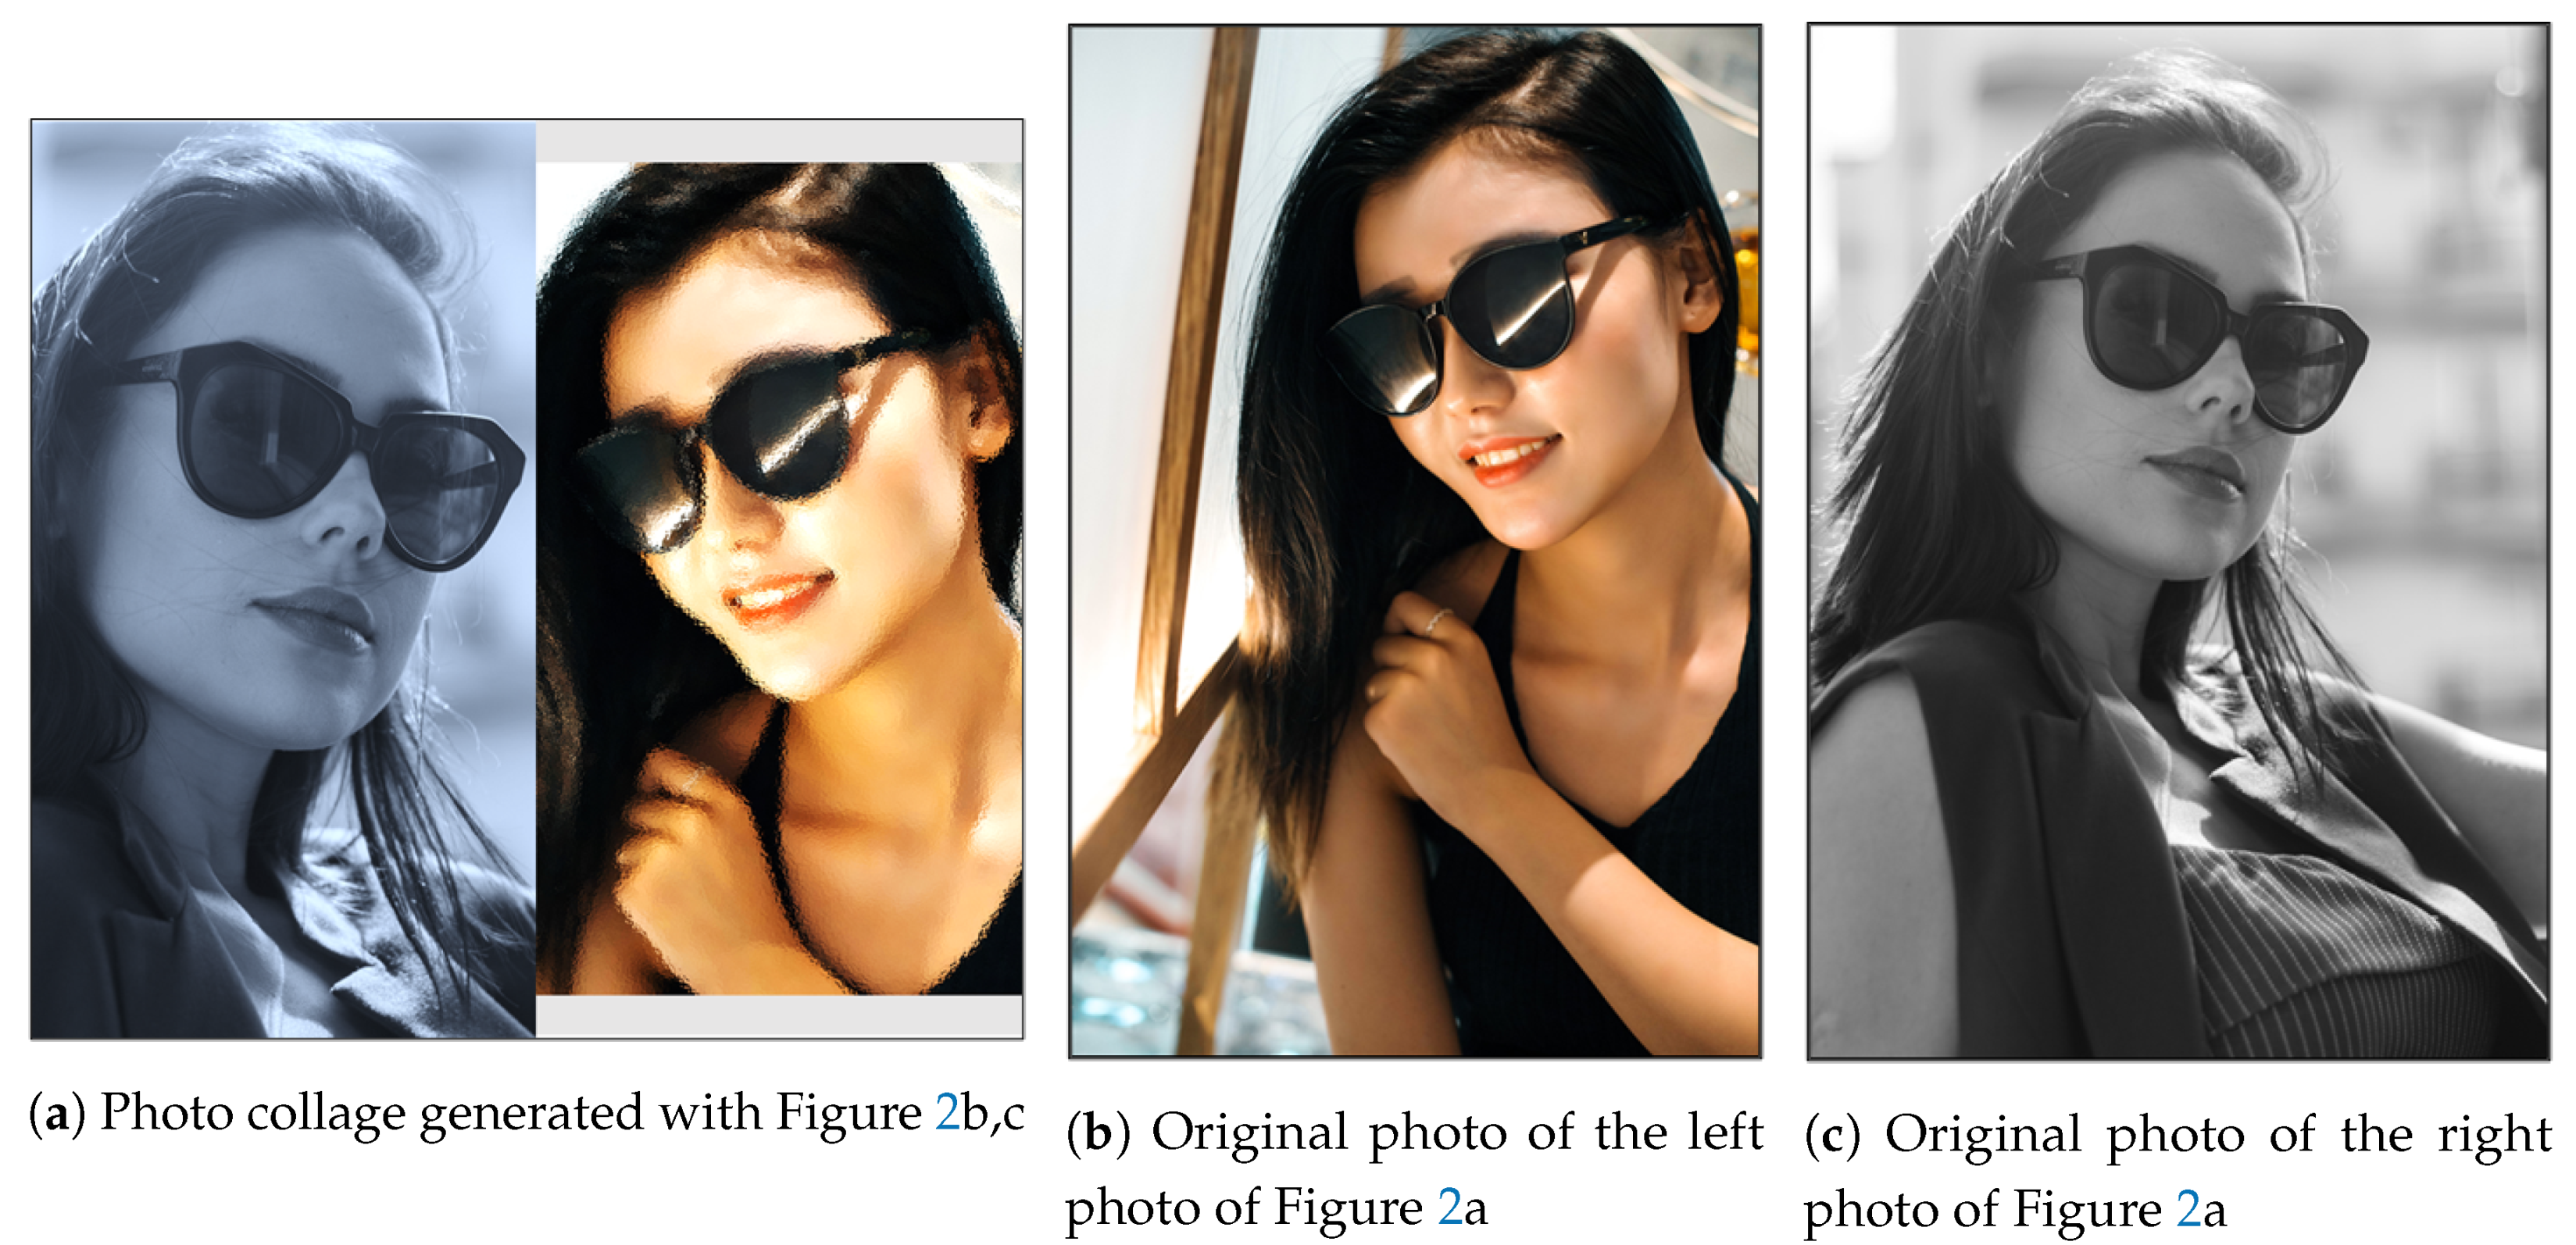
Web image search services [7,8,9] correspond to automated solutions that can perform the aforementioned functions. They provide results of not only visually similar images but also identical images for image queries. However, existing web image search services such as Google, TinEye, Yandex, and Bing do not accurately find the original photo from manipulations such as image cropping or image collage, which frequently occurs when photos are stolen. For example, as shown in Figure 2, if a shopping website steals photos to promote sunglasses, it only crops the person wearing sunglasses from the background (image cropping) and combines several images of sunglasses (image collage). In addition, image manipulations such as resizing, color distortion, flipping, and compression can occur during image editing, and these can also lead to degradation in identification performance. Image cropping and image collages have problems, loss of information from original photos and misidentification of multiple photo copyrights, respectively. These problems are difficult to solve with existing web image search services.
Figure 2.
Example of a photo collage with two cropped photos. In these photos, the sunglasses are the target object for
unauthorized use. The source of these photos is https://unsplash.com (accessed on 27 September 2021), which provides
copyright-free images.
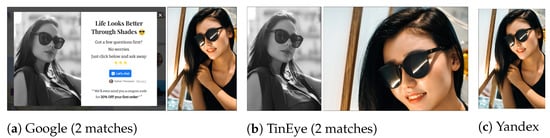
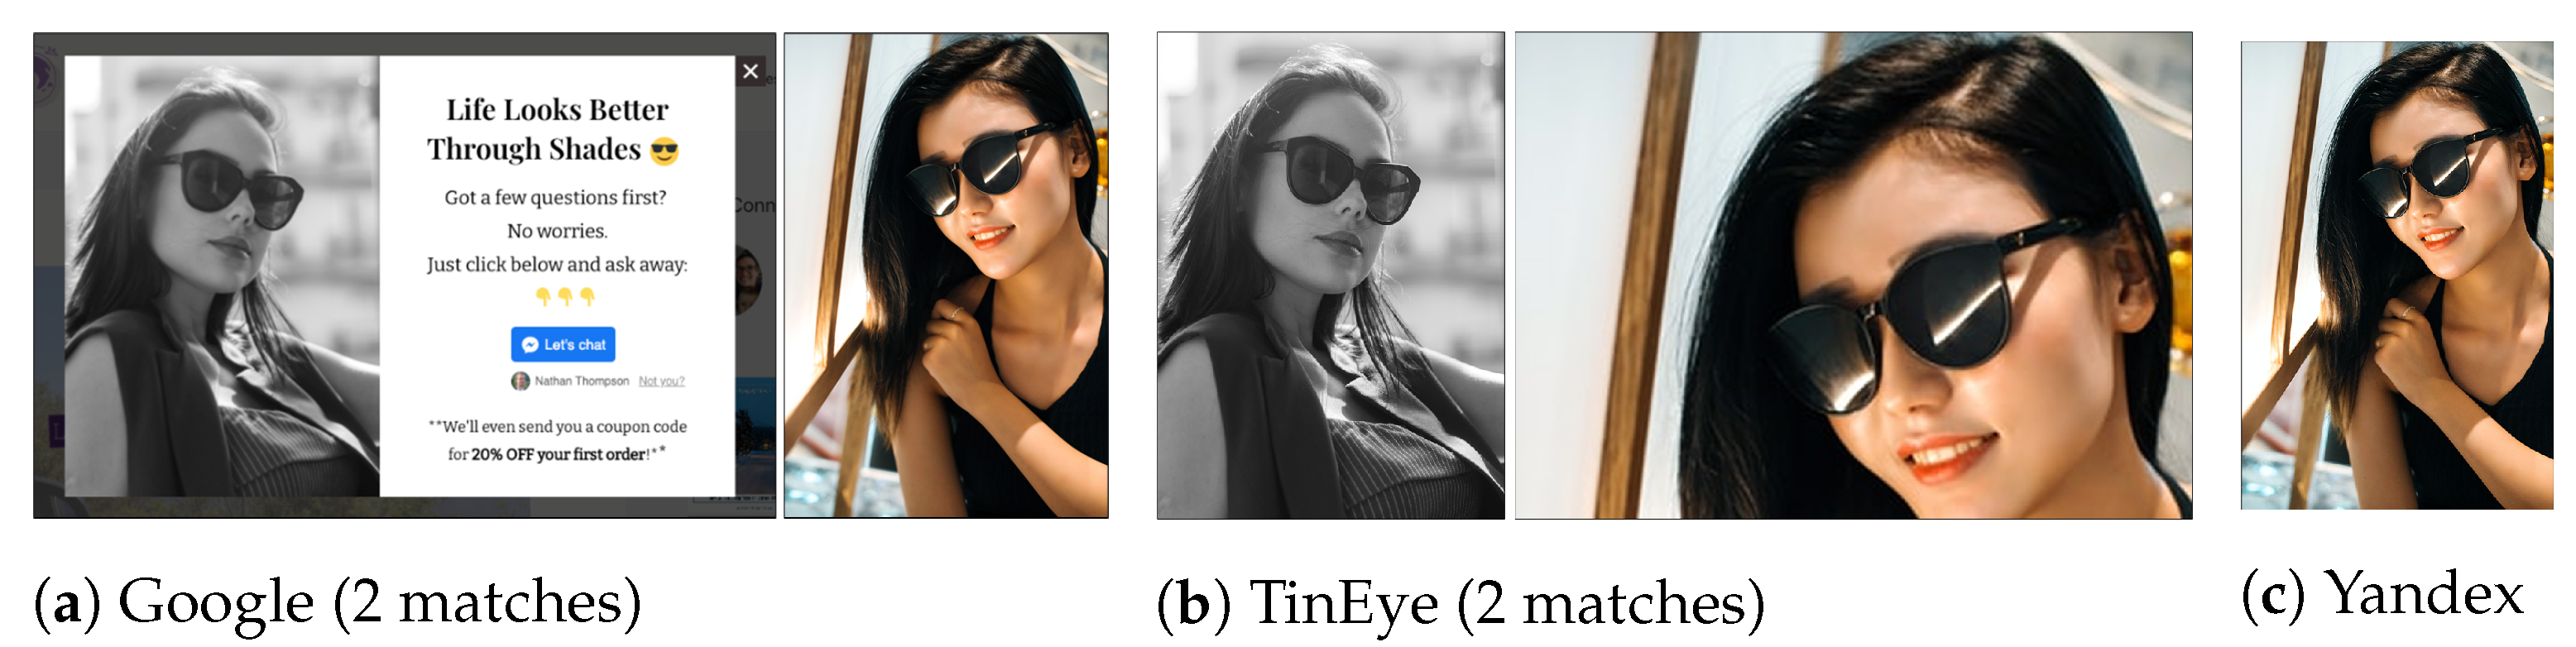
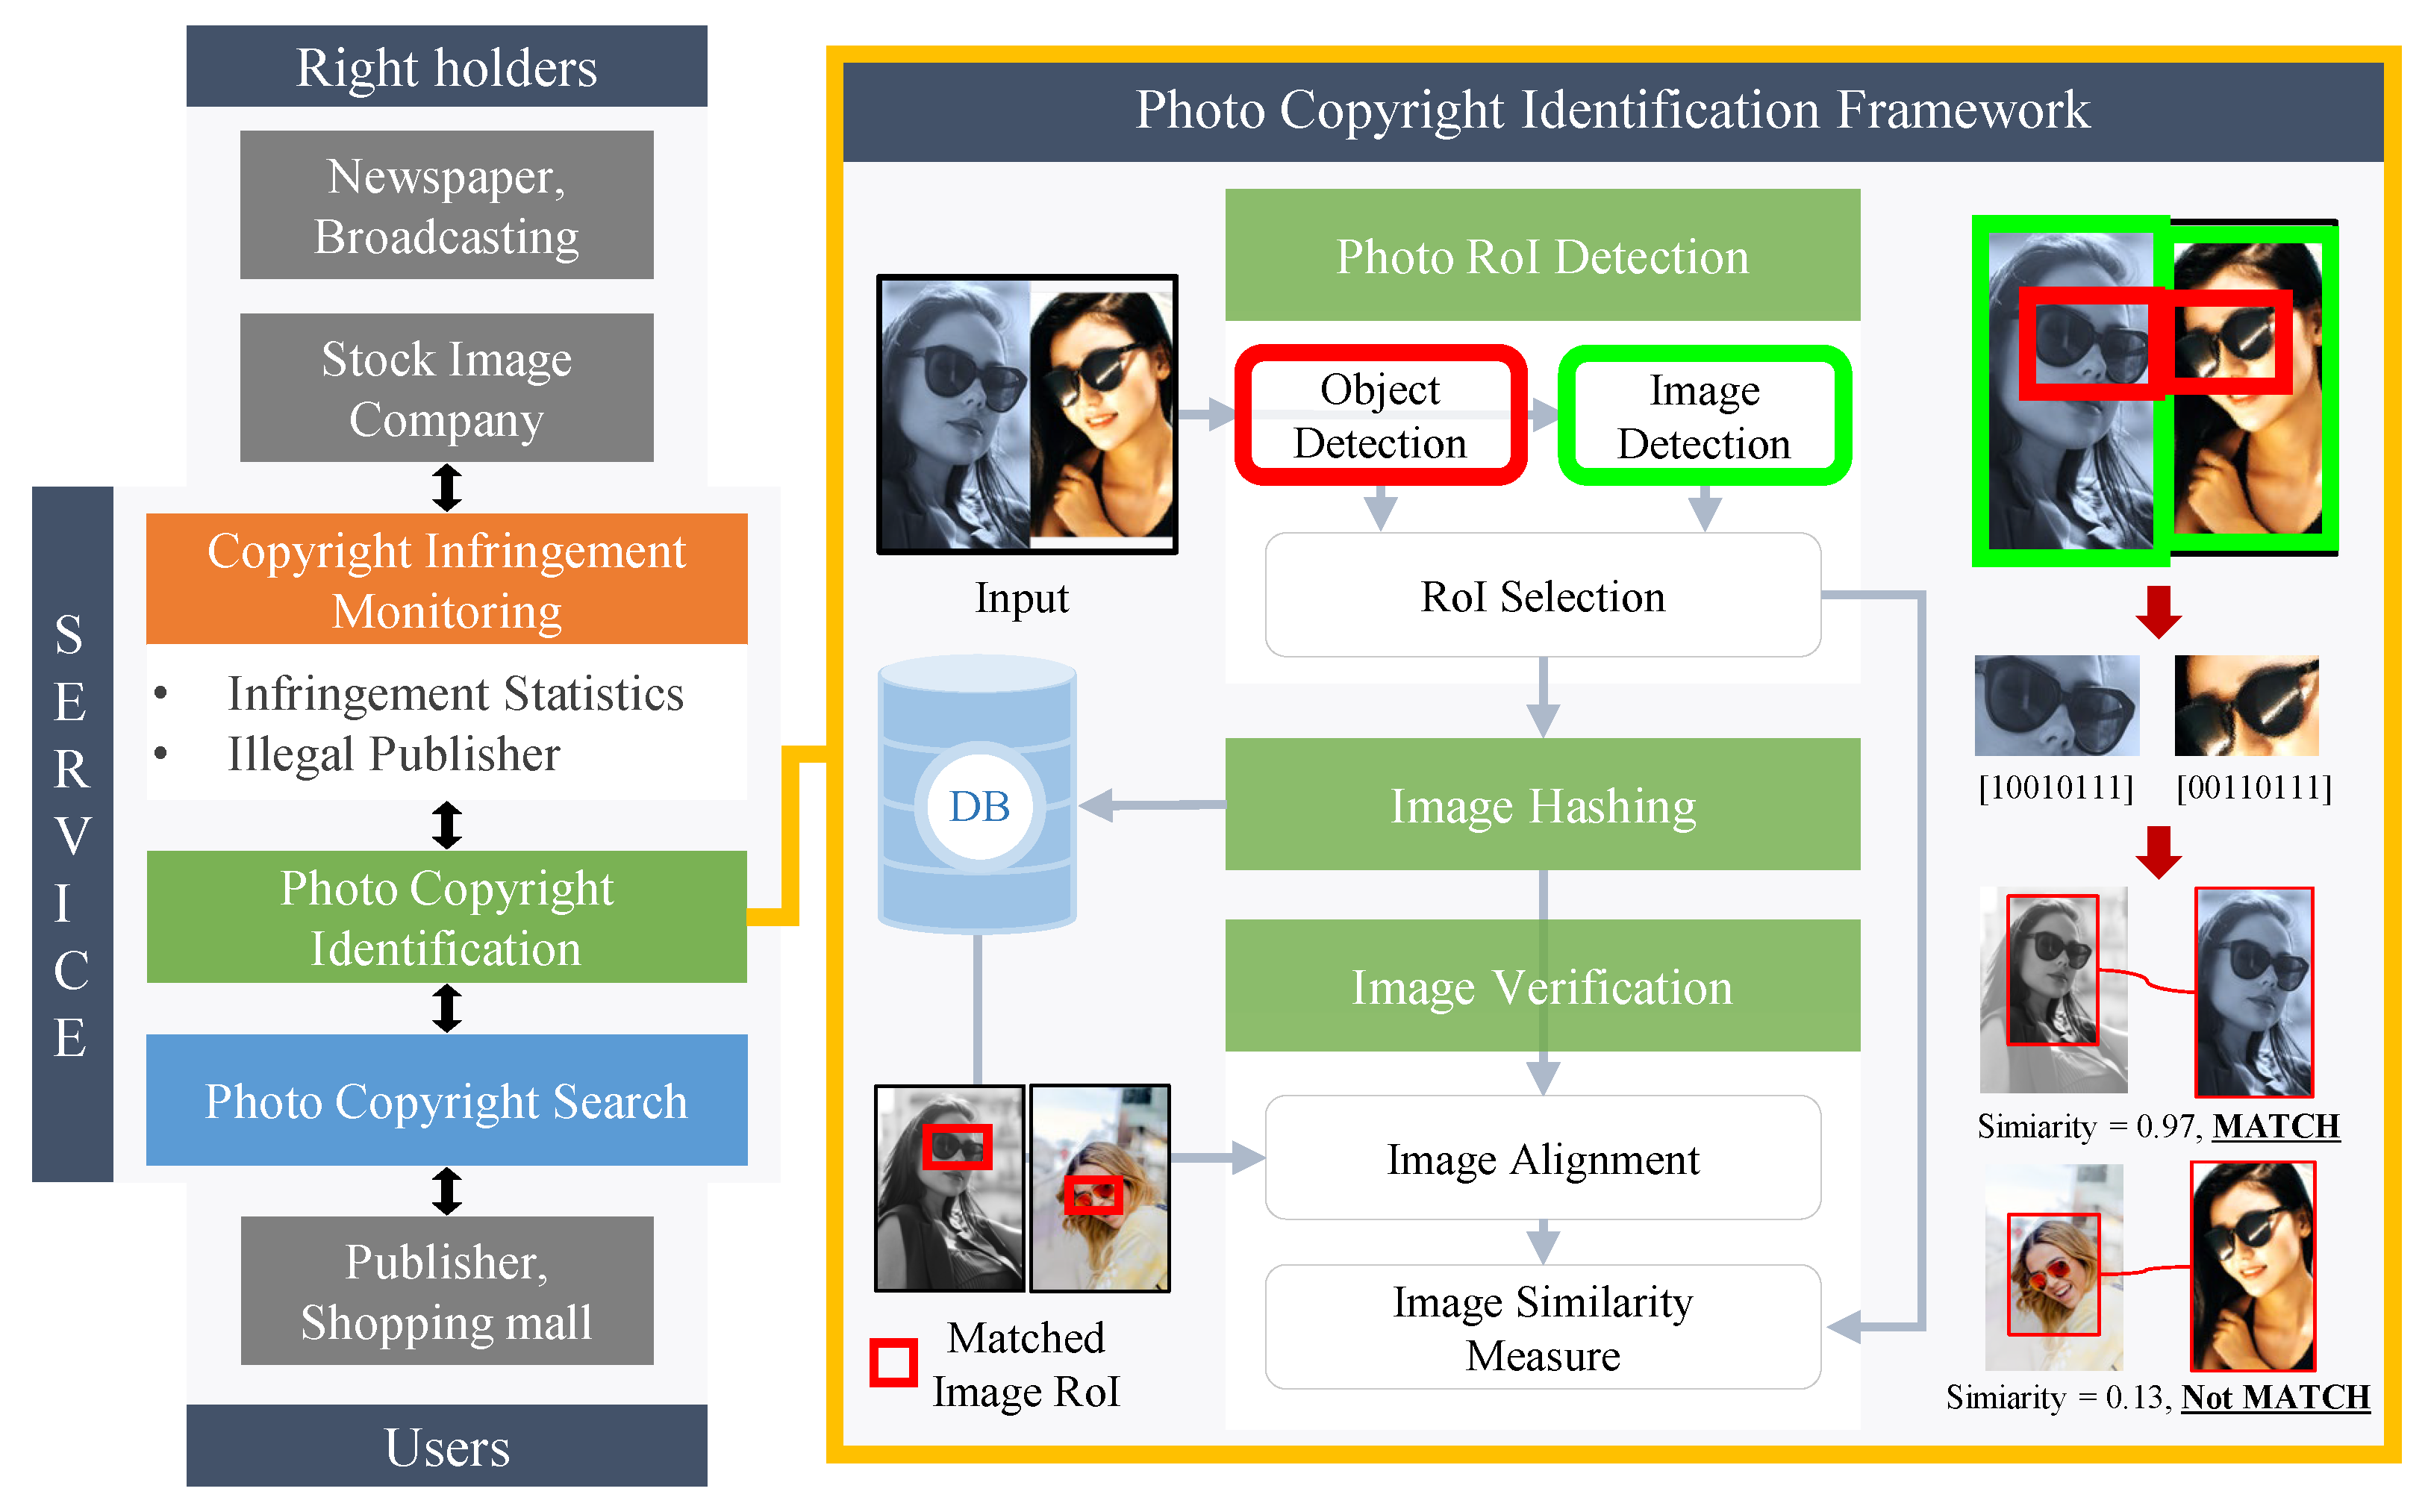
As shown in Figure 3, since existing image search services do not consider the characteristics of copyright infringements, existing web image search services show the poor responses to the aforementioned manipulations. Figure 3a,b show that Google image search and TinEye matched only one of the match results correctly, and Yandex matched only one photo as shown in Figure 3c. The limitations of existing image search services emphasize the need for a new photo copyright identification and database. In addition to technical limitations, the absence of a service capable of providing copyright information also makes it difficult to handle infringements. The service in Figure 4 can facilitate the legal use of copyrighted photos by connecting users and copyright holders, and helps to find copyright infringements based on the photo copyright identification framework.
Figure 3.
Image search results of Figure 2a by Google [7], TinEye [9], and Yandex [8]. We additionally
tried with Bing, but did not obtain any results.
Figure 4.
Service block diagram for the photo copyright search. The yellow box on the right side is the proposed photo copyright identification framework in this paper.
In this paper, we propose a photo copyright identification framework that can handle the manipulations that appear in Figure 2a. The proposed framework in Figure 4 is composed of three modules, Image RoI Detection, Image Hashing, and Image Verification, where the original photo and the manipulated photo are matched accurately. Image RoI Detection divides a collage of cropped images into RoIs, which represent the characteristics of each image well. This module reduces the influence of geometric manipulations to detect RoIs consistently from original photos and manipulated photos. The image collage dataset is constructed to train optimized detectors for Image RoI Detection. The most efficient detector is applied through benchmarking the state-of-art object detectors for this dataset.
Image Hashing generates a binary descriptor from each detected RoI to search the photo copyright DB. By training the image hashing network through image augmentation with diverse manipulations, the generated binary descriptor is robust to manipulations such as color transformation, blurring, and cropping that ImageRoI Detection did not handle. However, severe manipulations make it very difficult to identify photos correctly with their binary descriptors, leading to occurrences of false positives. Since it is not easy to check whether identification results are correct in the field test, lots of false positives can be identified as incorrect copyrights.
To tackle this problem, we propose Image Verification to confirm whether the identification results of Image Hashing are correct. This module geometrically aligns a query image and its matched photo, and obtains the overlapping region between them for pixel-to-pixel comparison. The image similarity Siamese network calculates the similarity of the overlapping region and verifies whether the images are identical.
This stable framework composed of the series of three modules improves the identification accuracy and minimizes the false positive rate for manipulated photos. Through exhaustive evaluations in experimental results, we verify the benefits of each module in the proposed framework for photo copyright identification. Furthermore, it is demonstrated that the proposed framework significantly improves identification accuracy and decreases false positive rate, outperforming conventional and state-of-the-art retrieval methods [10,11].
Contributions
The contributions of this paper is summarized as follows.
- We propose Image RoI Detection, a preprocessing technique that can effectively handle geometric manipulations such as image collage and image cropping, which cannot be solved by existing image search services. To train the image detector used in Image RoI Detection, image collage datasets with 300,000 image collages are introduced.
- We propose Image Hashing that can generate similar binary descriptors from manipulated photos and original photos. This module is designed to handle color manipulations such as color distortion and blur as well as geometric manipulations.
- To accomplish Image Verification, we introduce an geometric alignment method to accurately align an query image with the matched one in the database obtained by Image Hashing method and propose a similarity measurement network to distinguish whether the aligned image infringes copyright robustly to manipulations.
- By applying the aforementioned three steps, we improve the identification accuracy and significantly reduce the false positive rate for manipulated photos. The experimental results demonstrate advantages of each module in the proposed framework and show notable performance improvements of the proposed framework over the state-of-the-art image retrieval method [10].
2. Related Works
2.1. Efficient Object Detection
Object detectors [12,13,14,15,16,17] have become more accurate and precise with the development of deep learning techniques such as backbone networks, multi-scale methods, and prediction heads. However, the state-of-the-art detector [18] requires huge network size and expensive computational cost, making it difficult to apply to real-world applications such as mobile, robotics, and self-driving cars. As demands for real-time detectors increase, the scheme of one-stage detectors [12,16,17] achieved sufficient performance for real-time applications. Compared to two-stage detectors [13,14,15] with two separated steps, localization and classification, the one-stage detectors perform very fast due to them having single tensor output for these multi-tasks [16,17]. However, the localization precision of one-stage detectors is lower than that of two-stage detectors due to information abstraction caused by pooling operations of convolutional neural networks. The feature pyramid network (FPN) [19] aggregates multi-scale features and uses them as the final output tensor computation. This method leverages different sizes of receptive fields to effectively reflect multi-scale object information to improve performance. In recent years, the state-of-art one-stage detector, EfficientDet [12], has utilized bi-directional FPN to share information between low-level and high-level layers. In addition, compound scaling, which considers various aspects of CNN architectures, was proposed to design efficient object detectors, EffcientDet-D0 to D7. We deploy this model as it is suitable for object and image detection through the benchmark of object detectors.
2.2. Image Hashing
To generate a binary descriptor reflecting image semantics, supervised hashing methods [20,21] utilized label information, but most collected images do not have label since the labeling is expensive. On the other hand, unsupervised hashing methods [10,22,23] use image contents only to generate binary descriptors. Although it is difficult to extract highly refined semantics from images without label information, unsupervised hashing has been studied due to its utility. BinGAN [22] applied regularization to GAN (Generative Adversarial Network) [24] for image hashing, and binaryGAN [10] also utilized adversarial loss along with autoencoder architecture to learn image distribution. However, since existing image hashing methods have not considered image manipulation such as cropping, color distortion, and blur, it is highly likely that these manipulations degrade their accuracies. We propose image hashing scheme to handle various manipulations that degrade the performance of photo copyright identification.
2.3. Image Classification
Image classification has been developed with fundamental techniques for deep learning. The backbone networks such as AlexNet [25], VGGNet [26], GoogleNet [27], and ResNet [28] have been studied and improved performances of image classification, object detection, and image segmentation. Moreover, many image datasets [29,30,31,32] have been introduced. ImageNet [25] is a large-scale dataset containing more than 1.2 million images, which have greatly influenced many image classification tasks in the ImageNet Large Scale Visual Recognition Challenge (ILSVRC). The aforementioned image classification networks also utilized ImageNet, providing the most generalized feature representation due to its overwhelming scale. This feature representation power of ImageNet pretraining shows better performance on a variety of tasks, networks, and other datasets. We utilize ImageNet pretraining for the image hashing network to generate binary descriptors.
2.4. Self-Supervised Learning
Many researchers have proposed self-supervised learning methods [33,34,35,36] to learn semantics of images without labels. Self-supervised learning methods have been developed to a level comparable to supervised learning methods, and received more attention due to their transferability to other tasks. SimClr [34] learned a large number of negative samples with NT-Xent loss, and SimSiam [35] learned common features of an image pair through stop-gradient operation without a negative sample. We employ a self-supervised learning scheme to train the image hashing network.
2.5. Siamese Network
In recent years, one-shot learning, which learns to generate discriminative features for subjective task, has been successfully used for image similarity assessment. This is applicable not only to wide variation [37] but also to sensitive variation [38]. The core network of one-shot learning is Siamese structure [39]. When the number of training data is very small or additional learning such as online system is difficult, Siamese network can learn discriminative features and perform k-nearest neighbor classification. In addition, applying multimodal data to Siamese network allows learning of similar feature presentation from different domains. Koch et al. [39] performed one-shot learning on the Omniglot dataset [38] with a small number of data, achieving near-human-level accuracy. We propose a variant of the Siamese network to predict similarities of image pairs for image verification.
2.6. Image Verification Metric
The image verification metric helps to determine whether two images match exactly. Naive approaches such as mean squared error (MSE), mean absolute error (MAE), and peak signal-to-noise ratio (PSNR) do not reflect structural difference and correlation of images due to their simple arithmetical operations for local pixel dissimilarity. To complement this, Wang et al. [40] proposed Structural Similarity Index (SSIM) based on the Human Visual System (HVS). However, although SSIM capture local structural dissimilarities of each patch, the local differences tend to be ignored by averaging local similarities. Moreover, because the luminance and contrast term of SSIM are vulnerable to color distortion such as tone variation and JPEG compression, SSIM is not suitable with image verification metric. To overcome these limitations, DeepQA [41], DeepVQA [42], and DRF-IQA [43] has been proposed in a data-driven scheme using deep neural networks. For image similarity measure, we propose the image verification metric to capture both global and local dissimilarities.
3. Copyright Photo Identification Framework
3.1. Overall Framework
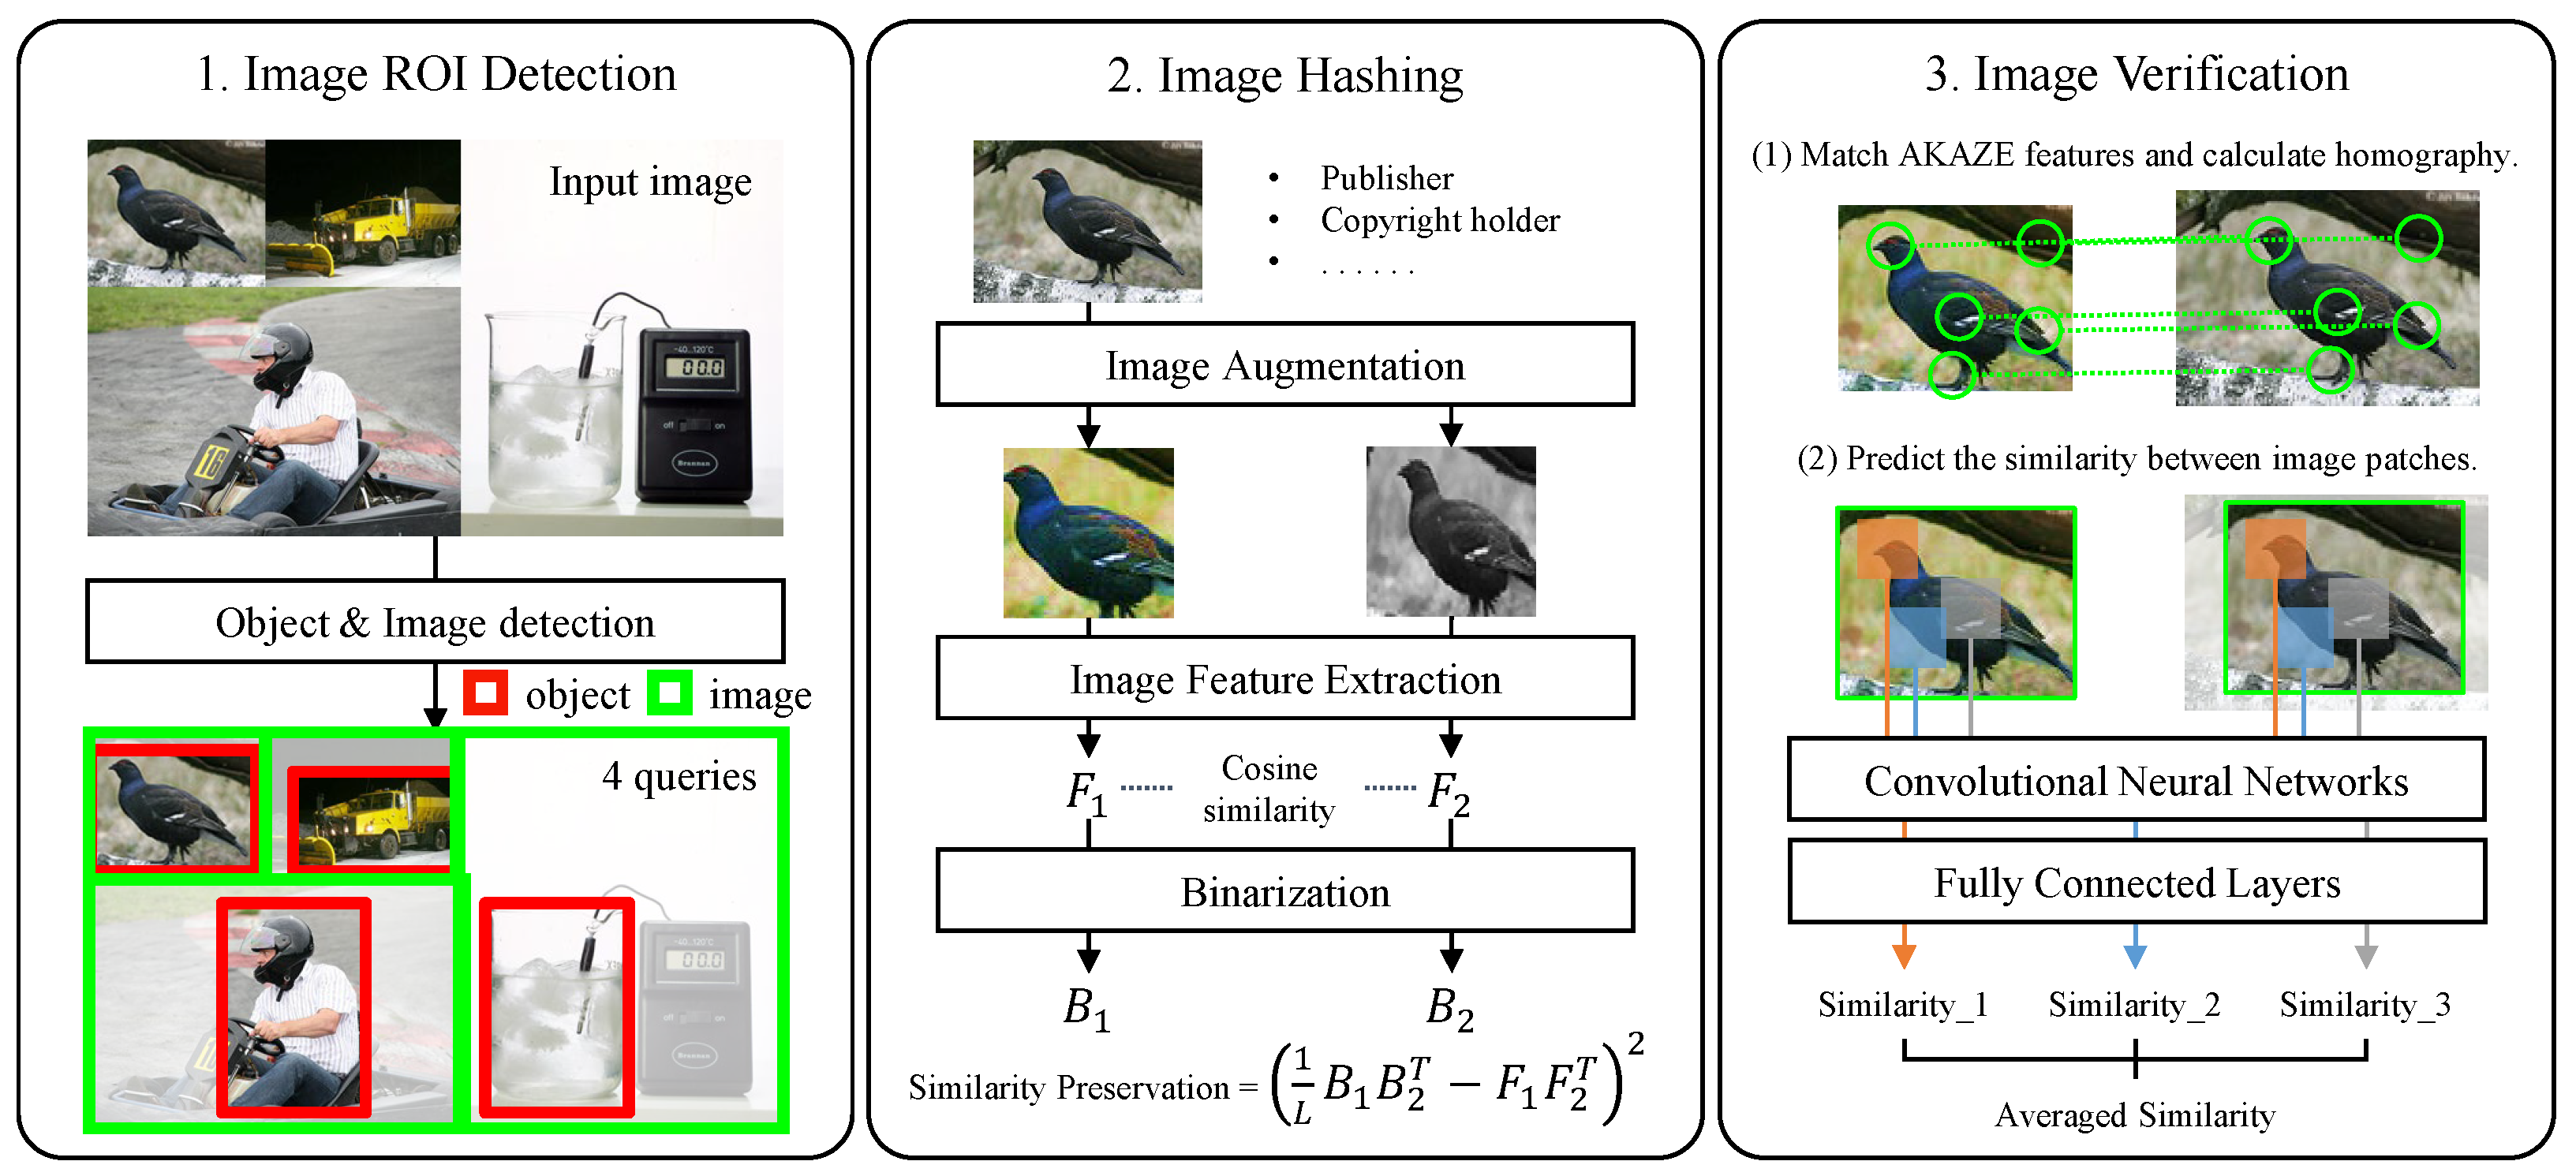
As shown as Figure 5, the copyright photo identification framework and searches photo assets in the database with an image query through three steps: Image RoI Detection, Image Hashing, and Image Verification. The first step, Image RoI Detection, detects image regions and object regions from an input image. The image detector separates an image collage into individual images, and the object detector recognizes object regions to reduce the effect of image cropping in backgrounds. The largest object is selected as an RoI to represent each separated image. If the object size is less than a certain percentage of the separated image or any object is not detected, the whole separated image is selected as an RoI. Through this module, a query image is refined to be similar to the RoI of the original photo.
Figure 5.
Overall framework for copyright photo identification. The source of these photos is ImageNet [29].
In Image Hashing, binary descriptors are generated from the RoIs selected in the previous step. The backbone network of Image Hashing is pretrained by ImageNet to utilize its representation power, and the SimSiam [35] is employed as the head network to fine-tune on copyright photos. The output vector of the head network is utilized as a binary descriptor, which constructs the photo copyright database with the information of an input photo. The binary descriptor helps to search quickly the most similar photo with Hamming distance.
The matched photo with the binary descriptor is verified with the query image by measuring their similarity in Image Verification. The query image and the matched photo are aligned geometrically by the affine matrix, and the overlapping region is derived according to their geometric relationship as shown in 3-(2) of Figure 5. The similarities of patch pairs sampled from the overlapping region are calculated by the proposed Siamese similarity measure network, and aggregated into the image similarity by multi-layer perceptron (MLP). This image similarity determines whether two photos are identical based on the threshold value. Details of each step is described in following Sections.
3.2. Image RoI Detection
In this step, the image collage is divided into a set of single images and then the corresponding image RoI representing a salient object in an image is determined for every single image. To detect the single image in an image collage and objects, we adopt two separate deep detector networks. The network architecture is determined by benchmarking three state-of-the-art object detection network: Faster R-CNN [14], Yolo v3 [17], and EfficientDet [12]. Based on the benchmark presented in Table 1, our framework uses EfficientDet (D1) architecture for each detector, which outperforms the other detectors in predicting the RoIs from geometrically manipulated images. We trained these two networks with classification and localization losses. For a class t and corresponding network prediction with ground truth , the classification loss is defined by the alpha balanced focal loss [44] which is defined as weighted binary cross-entropy,
where and are the focusing weight for modulating easy/hard examples and balancing weight for positive/negative examples, respectively. The localization loss is smooth L1 loss [14] with predicted bounding box and ground truth bounding box ,
where is defined as
Table 1.
Image detection performance with image collage inputs applied to object detectors.
The total loss function is expressed as a weighted summation of the classification loss and localization loss. Since the image detection is less dependent on the detection label, we put a larger weight on localization loss for the image detector while the key object detector is trained on evenly weighted losses.
Since there are many publicly available datasets for object detection such as MS-COCO [45], the object detector can be trained by using a public dataset. However, for the best of our knowledge, there is no dataset for detecting the image collage. Thus, we develop a data generation method to create collage images by using pristine image data from public image dataset. For a rectangular frame with a predefined resolution, the proposed method recursively partitions the frame and inserts the pristine images into each subframe. To avoid an unnatural image resizing, an image to be inserted into the subframe is selected based on the similarity of aspect ratio between them. Before insertion, the selected image is center-cropped to make it fit the subframe. From an empty frame with a predefined resolution, the recursive partitioning is performed on horizontal or vertical axes.
| Algorithm 1: Generating the template by the partitioning frame. |
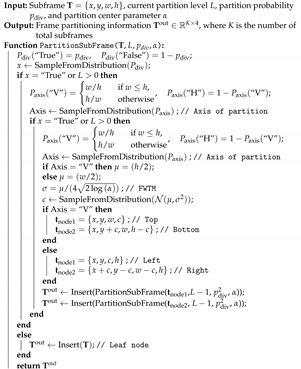 |
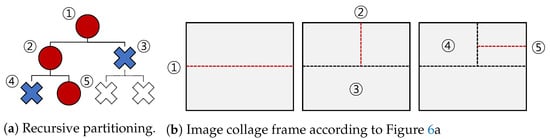
For each partitioning step, the occurrence of partition, partitioning axis, and its center are randomly determined with appropriate probability distributions. Specifically, we sample the partition center from a Gaussian distribution centered on the mid-location of the partition axis to make the size of the subframe variable. Furthermore, to prevent the partition center set too far from the mid-location, the variance of the Gaussian distribution is computed based on full width tenth maximum (FWTM) with . Details of the recursive frame partitioning algorithm are shown in Algorithm 1. In Figure 6, an example of recursive frame partitioning is described. For an image collage produced from the proposed method, the bounding box information and its label named as ’image’ for each image in the image collage are marked as the ground-truth label.
Figure 6.
Example of generating an image collage frame with recursive partitioning with L = 2. In
this example, the partitioning occurs in the node notated in the red circle (①, ②, and ⑤ ) while
the others do not. In this example, the partition axis for ①, ②, and ⑤ are horizontal, vertical, and
horizontal, respectively. For each partition level, the partitioning would not occur when it is in the
maximum level of partition (after ⑤) or the decision of partition occurrence is false (in ③).
In our framework, by using the trained detectors, the image RoIs of the query image are determined based on detected images in an image collage and its objects. Note that the number of RoIs is the number of images used for image collage. Since the main purpose of copyrighted photos is to use a salient object, the image RoI is chosen to be a bounding box of the conspicuous object. If there is an object in a single image, a bounding box of the object which has a larger IoU (Intersection over Union) than the predefined IoU threshold is determined to the image RoI while the whole image is used as image RoI otherwise. By using image RoI instead of general objects or whole image regions, our framework is robust to the geometric manipulations.
3.3. Image Hashing
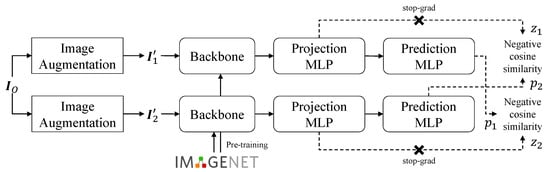
SimSiam [35], a self-supervised scheme for Siamese networks, is employed for Image Hashing. The image hashing network is composed of Backbone, Projection MLP, and Prediction MLP as shown in Figure 7. The original photo is augmented randomly and sampled into and . This augmentation includes geometric manipulations such as random aspect ratio and random cropping and color manipulations such as color distortion, grayscale, and Gaussian blur. This augmentation helps to learn common feature representation between the augmented image inputs by generating diverse pixel distributions for the same image. Without this augmentation, similar pixel distributions can cause overfitting and degrade the performance of the network. The backbone network is pretrained to utilize generalized features by ImageNet, which can help to prevent overfitting with fewer dataset images. The weights of the Projection MLP and the Prediction MLP are initialized randomly, and trained to minimize negative cosine similarity loss by fitting the copyright photos. The negative cosine similarity D is defined as:
where p and z are the outputs of the Prediction MLP and the Projection MLP, respectively. Since there is no negative sample, the image hashing network collapses with D and all the outputs have same value. To prevent the collapse, the stopGrad operation is applied to z and D is defined again as:
Figure 7.
Image hashing network, where MLP is a Multi-Layer Perceptron.
The stopGrad operation prevents the gradients of network weights from being updated and the network is trained to be closer to the constant tensor stopGrad(z). For symmetry, negative cosine similarity loss is defined as:
To generate a binary descriptor, sign function is applied to the output of the Prediction MLP and the binary descriptor b is defined as:
The binary descriptor can search the database very quickly by using bit operations. The index of the closest photo to the query is defined as:
where , , and ⊕ are the binary descriptor of the query, binary descriptor of the database, and XOR operation, respectively. In order to minimize information loss due to the dimension reduction in output features from the backbone network and the binarization, the similarity preservation loss is defined as:
where , , , and are the output features from the backbone network and the binary descriptors, respectively. The final loss L is defined as:
The image hashing network is trained to minimize the final loss L.
3.4. Image Verification
3.4.1. Image Alignment
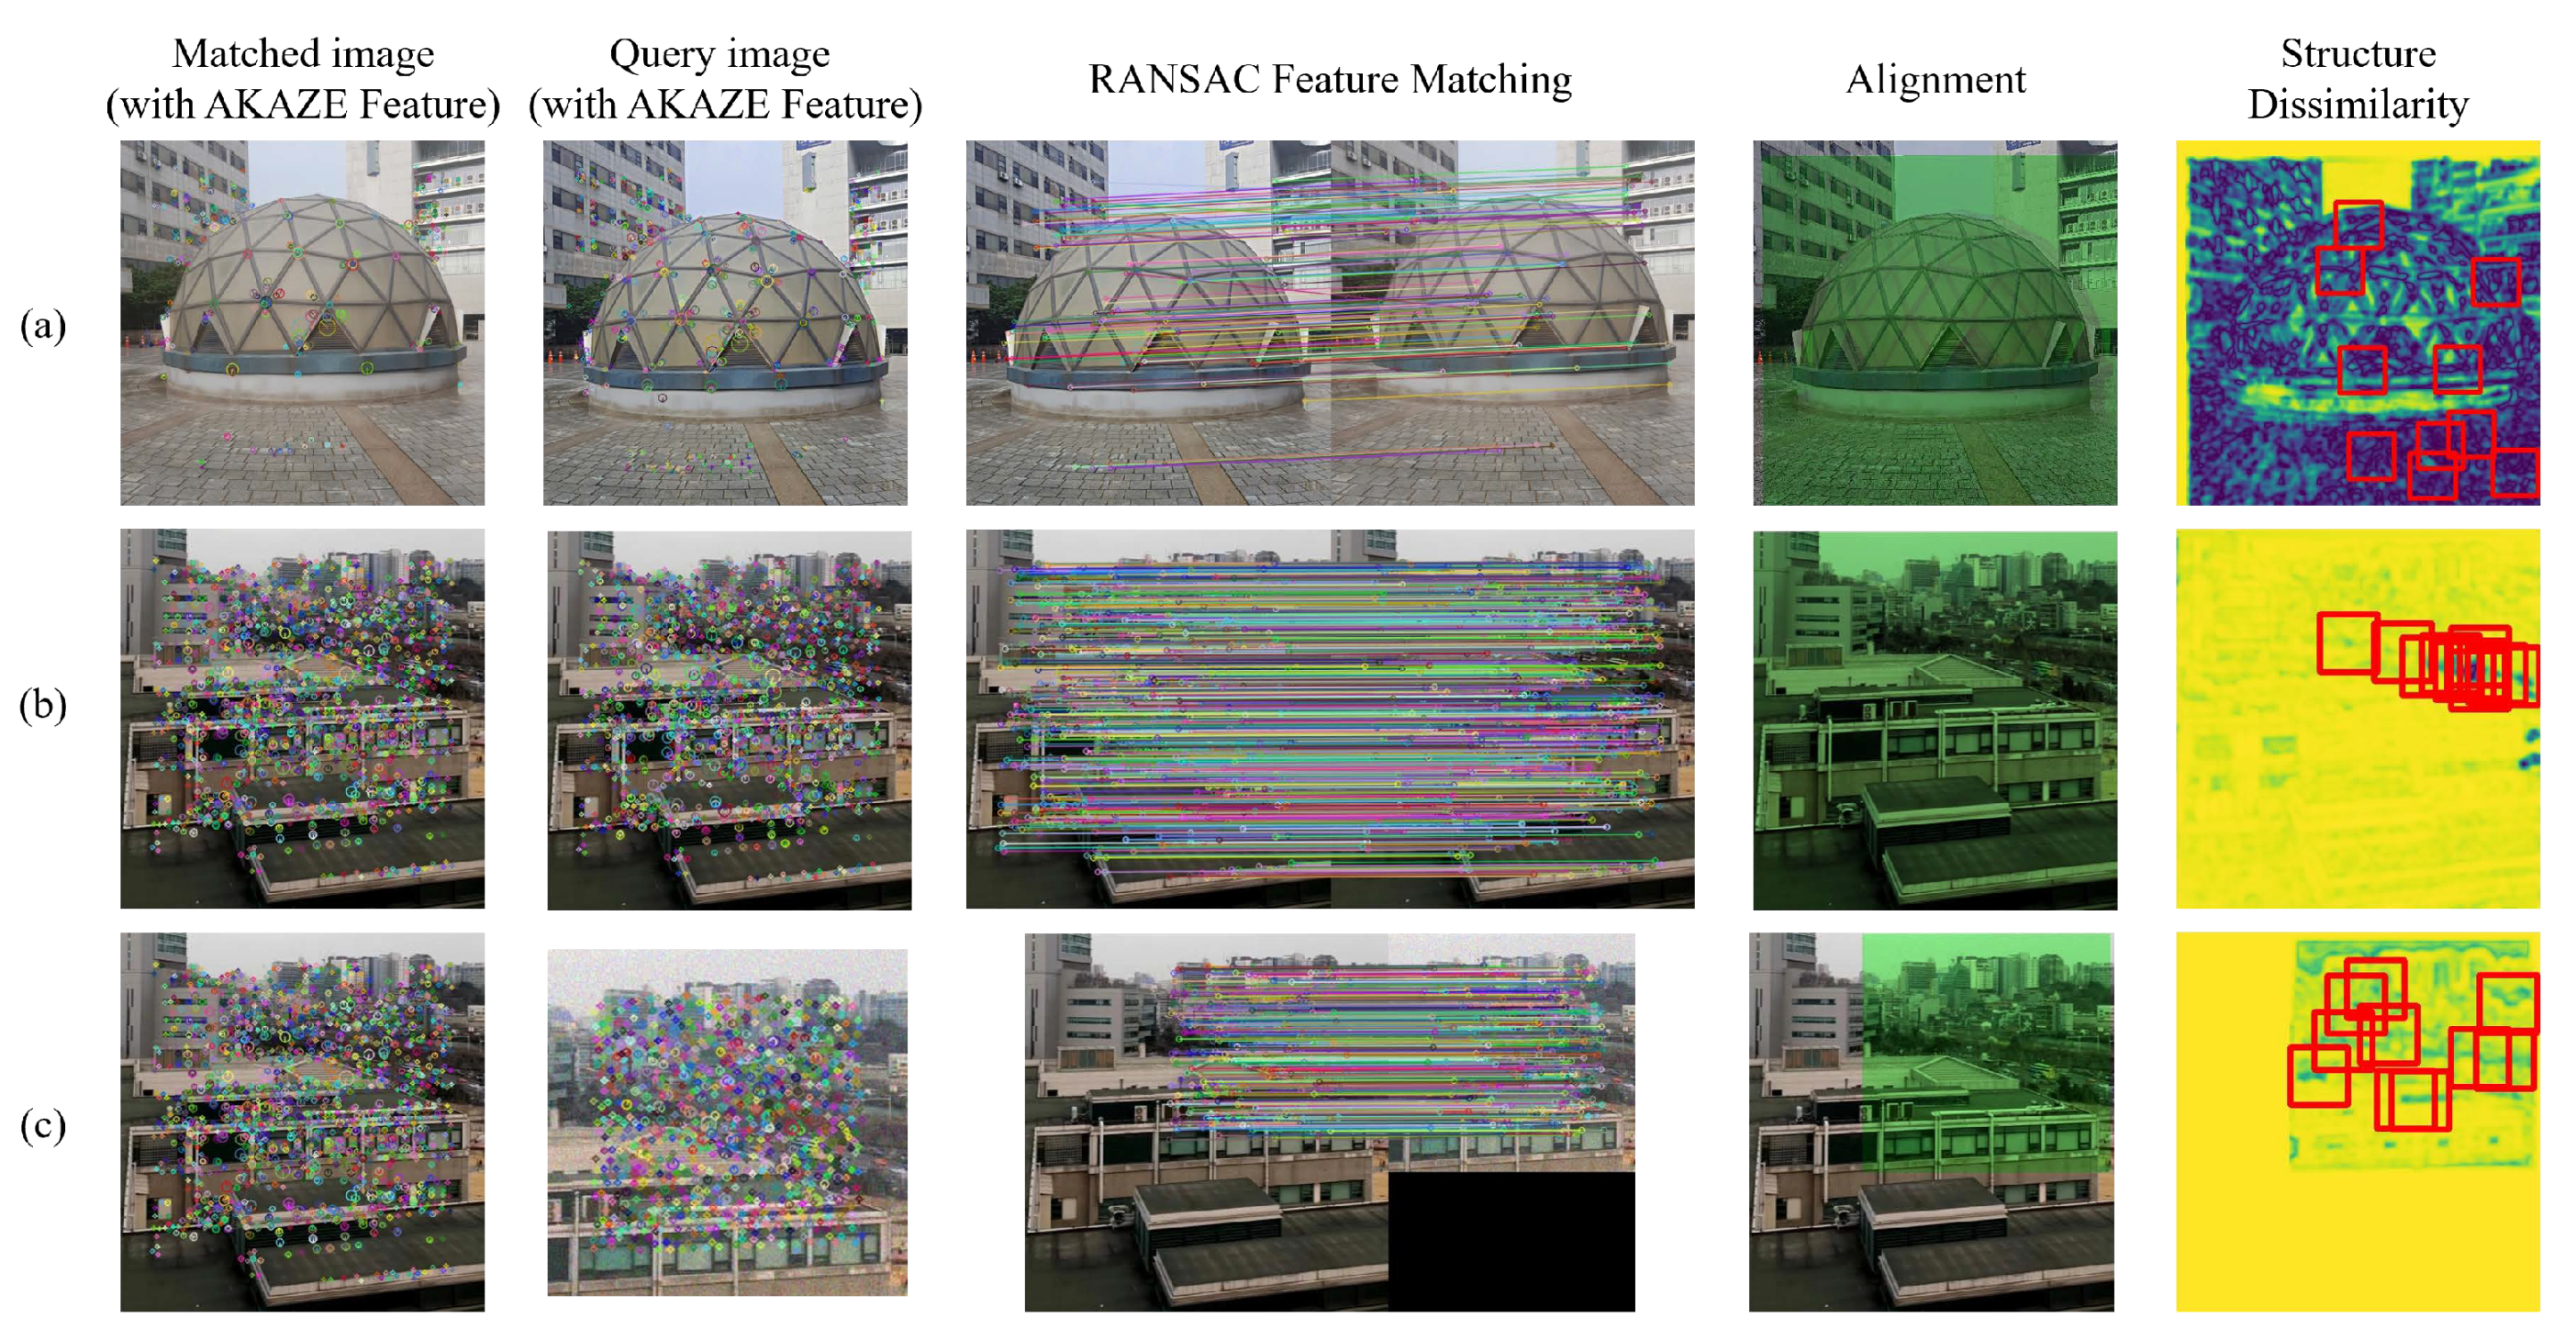
In the image verification step, a matched image pair from the image hashing step in Section 3.3 is verified based on the measured similarity between them. Because the query image possibly has geometric manipulation such as cropping or resizing, it is necessary to geometrically align the query and its matched image. In our framework, since the photos taken in different views should be predicted as different, the transform between the query and matched image is assumed to be in the affine space rather than projective space. By using matched image features, the alignment process computes an transform matrix and then extract an overlapping region based on it. Consequently, the image structure including edge contrast between two images is deemed to be similar which is necessary for image similarity measurement in the next subsection.
As shown in Figure 8, we use image features by using Accelerated KAZE (AKAZE) [46] for image feature matching. The AKAZE is a more computationally efficient method than KAZE. It can computes robust features within milliseconds while having comparable feature matching accuracy with well-known feature extractors such as SIFT [47] and SURF [48]. From the feature descriptors computed on each image, the affine transform matrix is estimated by using RANSAC (RANdom SAmple Consensus) [49] that computes the robust solution to the outlier matches. The detailed procedure of estimating the affine transform matrix by using AKAZE feature matches is described in the Algorithm 2.
| Algorithm 2: Pseudo-code for calculating the optimal transform matrix by RANSAC. |
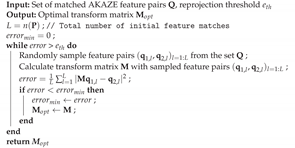 |
Figure 8.
Image alignment between the matched image from the database and its corresponding query image. Images may be taken in slightly different viewpoints (a) or pose differences of some objects in the image (b). These are considered as different images. On the other hand, the image processed from matched image (c) needs to be recognized as the same image. The overlapped region is marked in green. We additionally plot the structure similarity and boxes centered at a local minimum. Note that mean value for (a–c) are 0.33, 0.96, and 0.96, respectively.
3.4.2. Image Similarity Siamese Network
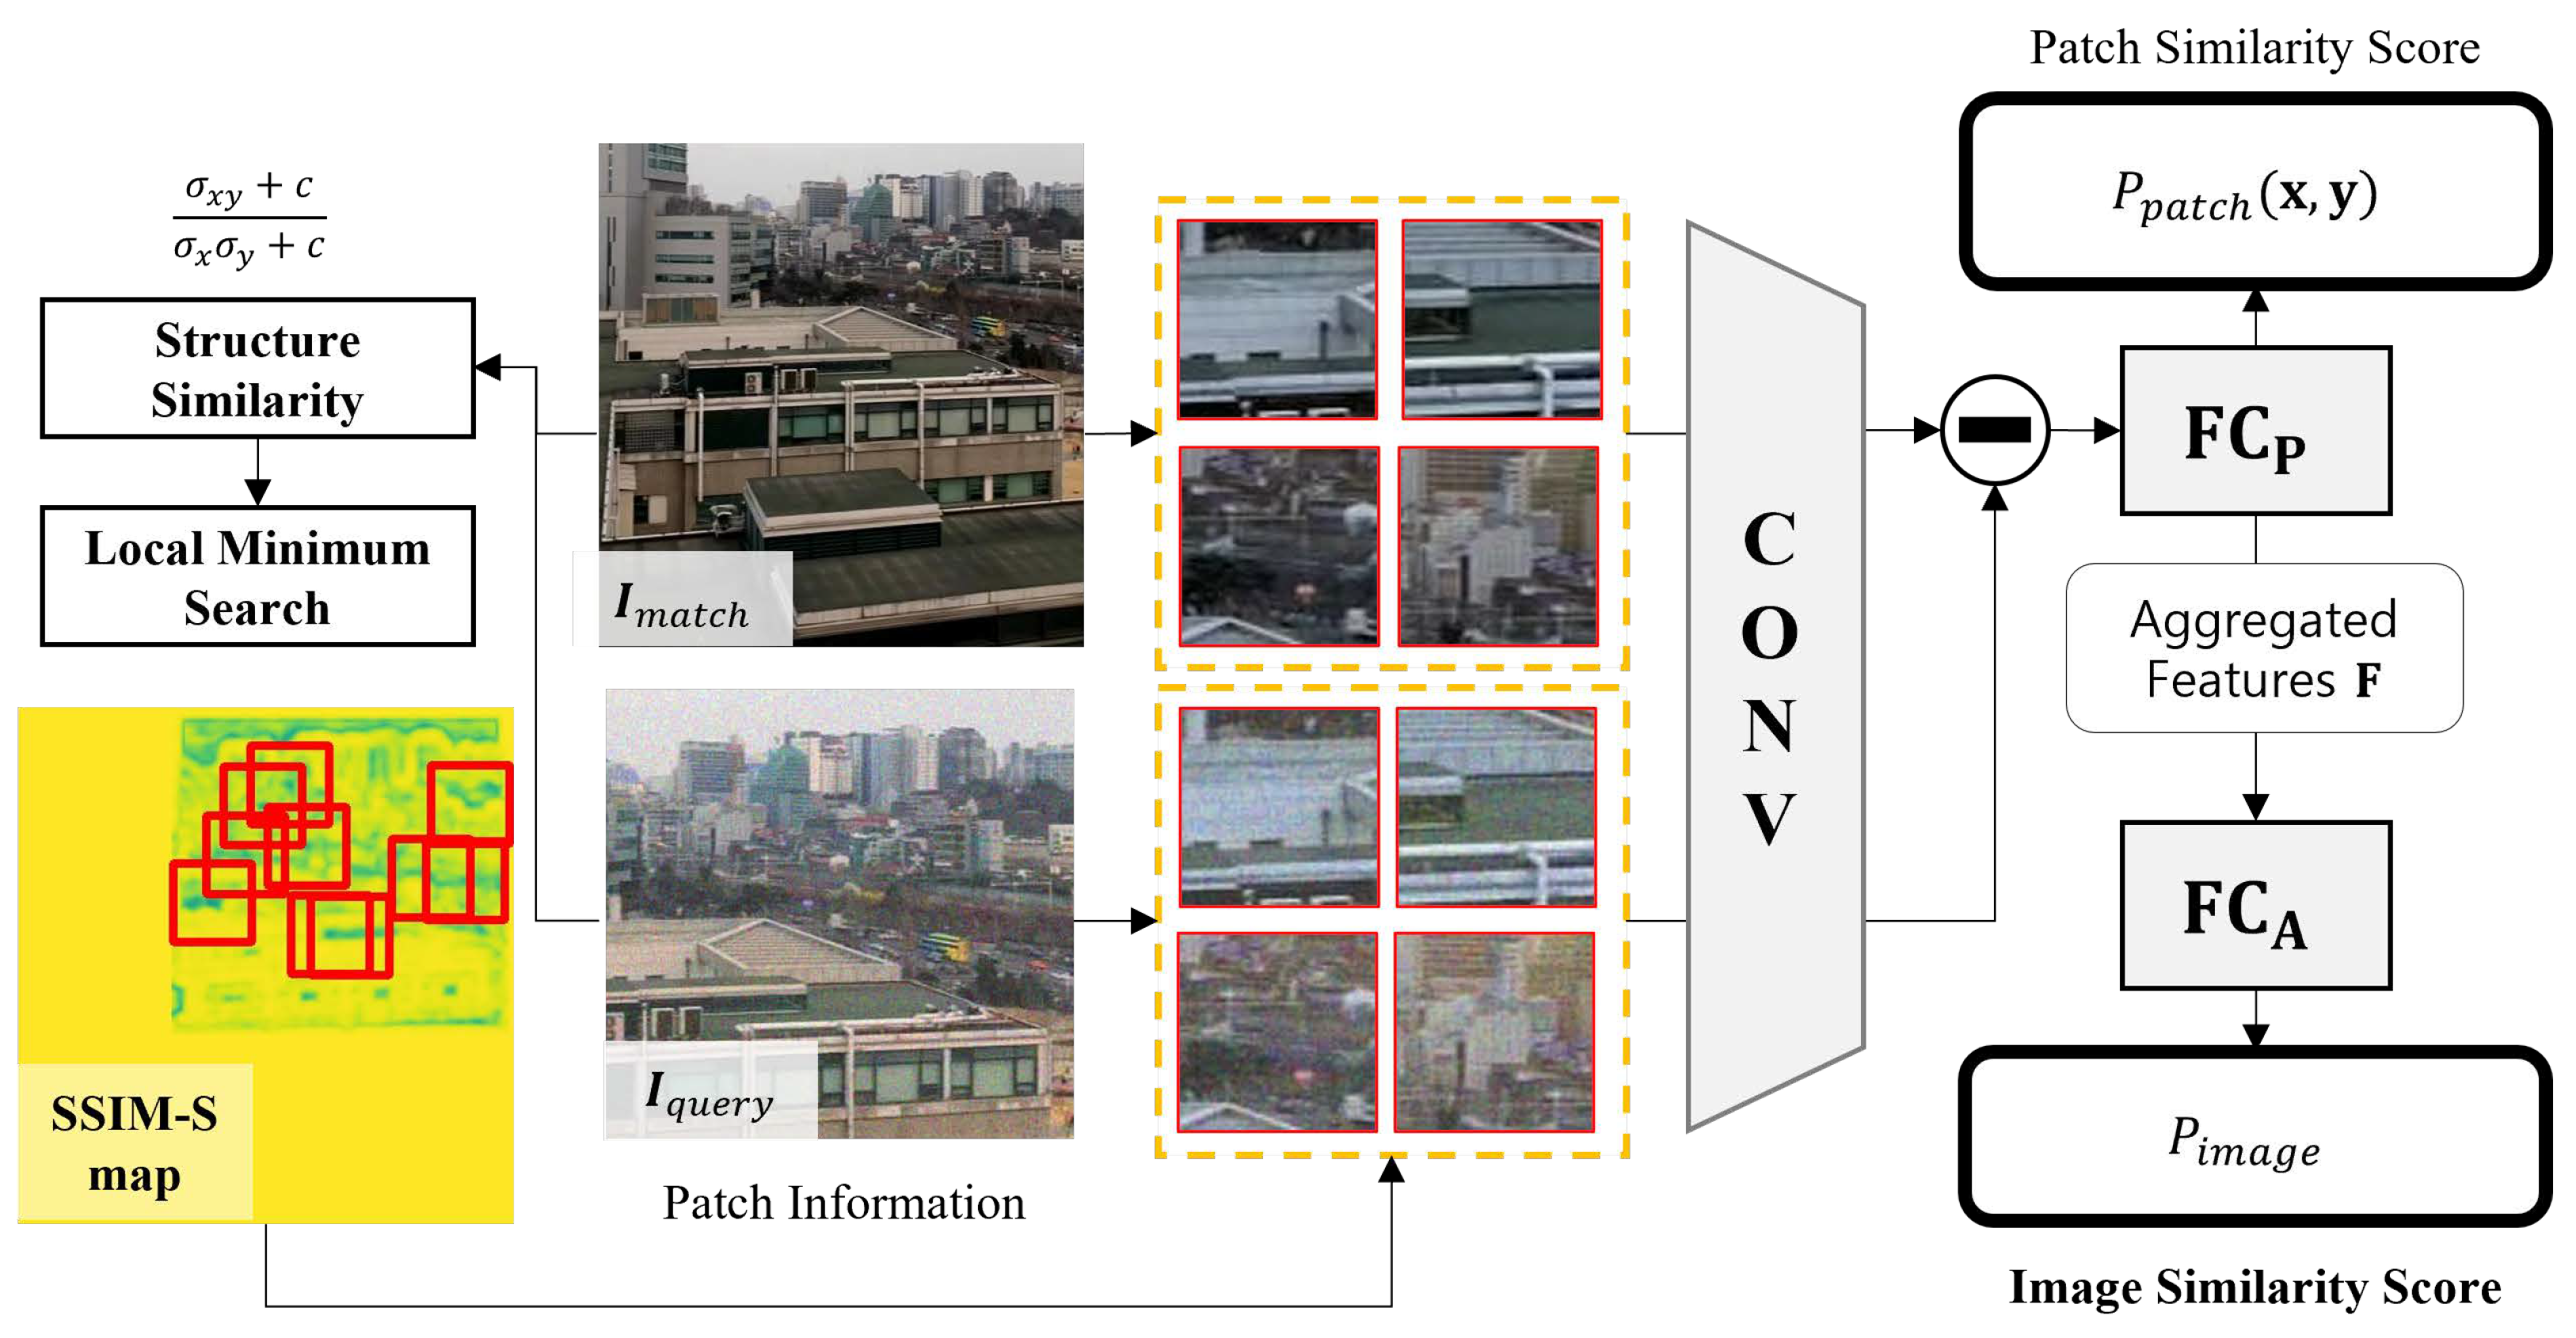
As mentioned in the previous section, the input image pair is assumed to have a similar geometric structure. Though the images have a similar structure, directly computing the image similarity by using a general pixel-wise metric would result in an inappropriate similarity score due to differences in color or other noise factors. Furthermore, because of the possible noise from misalignment, measuring similarity between images is not accurate. For instance in Figure 8, both the mean structure similarity (SSIM-S) which is structure term of SSIM of different images as in (b) and the same images as in (c) have the same high value (=0.96). To address this problem, we propose a robust image similarity metric based on a deep Siamese CNN model. In addition, to make the proposed model catch the small structural difference between images, we design the input to our CNN model as not simply using image pair but the patches that are sampled around the local minimum of the SSIM-S. The process outline of the proposed patch-based Siamese CNN model is shown in Figure 9.
Figure 9.
Image similarity siamese network between the matched database image and the query image . The architecture of [38] is employed for this . In the figure, the SSIM-S map corresponds to structure term of SSIM.
From the geometrically aligned image pair, the image similarity Siamese network predicts their image similarity score . If is less than the pre-defined threshold , it returns a decision that the two input images are different to the framework. Let the patch pair extracted from two images be . Each patch pair is extracted on the local minimum of the SSIM-S map, which is defined as structure part of SSIM [40]. The loss function is defined as sum of patch similarity loss on patch pairs and image similarity loss on aggregated features (i.e., ). The patch similarity loss is expressed as:
where , , and are the ground truth label, which is 1 for patches extracted from identical images and 0 otherwise, convolutional neural network for computing patch-wise features, and patch similarity network composed of fully-connected layers, respectively. The last layer of the patch similarity network is sigmoid to make output value in . This loss term is introduced for the network to capture significant local dissimilarity within patch pairs. Meanwhile, the image similarity loss measures the loss in terms of entire image with aggregated feature from intermediate feature vectors of :
where and are the ground truth label, which is 1 for same images, and image similarity patch aggregated similarity network with fully-connected layers, respectively. To make the image similarity score have value in , the patch aggregated similarity network has a sigmoid layer as an output. In Figure 8a,b, the measured similarity scores using the proposed model are and . These values are more desirable compared to the mean structure similarity . Training the network solely using different images with simple augmentations may cause the proposed model to be less sensitive to the fine structure difference between images. Therefore, we sample image pairs which have barely visible differences from the Youtube 8M dataset [50]. For each video, the frame data whose SSIM-S values are larger than the specific value for adjacent frames are extracted and labeled as hard negative examples. From 150 pristine videos among the Youtube 8M dataset, we extract 200,000 frames based on SIMM-S difference. To simulate various image manipulations except for cropping, these frames are augmented by using color clipping, JPEG compression, and chromaticity adjustment. In training, we use both totally distinctive image pairs and the frame pairs extracted by using the above procedure.
4. Implementation Details
4.1. Photo Copyright Dataset
To develop the photo copyright identification method, we used 35,824 copyrighted photos provided by copyright holders for purpose of research only. To leverage diverse images, images from ImageNet and MS-COCO were also randomly sampled to compose the dataset. In total, the dataset was composed of 289,111 images. We used this dataset in Image RoI Detection and Image Hashing. On the other hand, as mentioned in Section 3.4.2, 200,000 frames were sampled from the Youtube 8M dataset [50] to train the image similarity Siamese network of Image Verfication.
4.2. Image RoI Detection
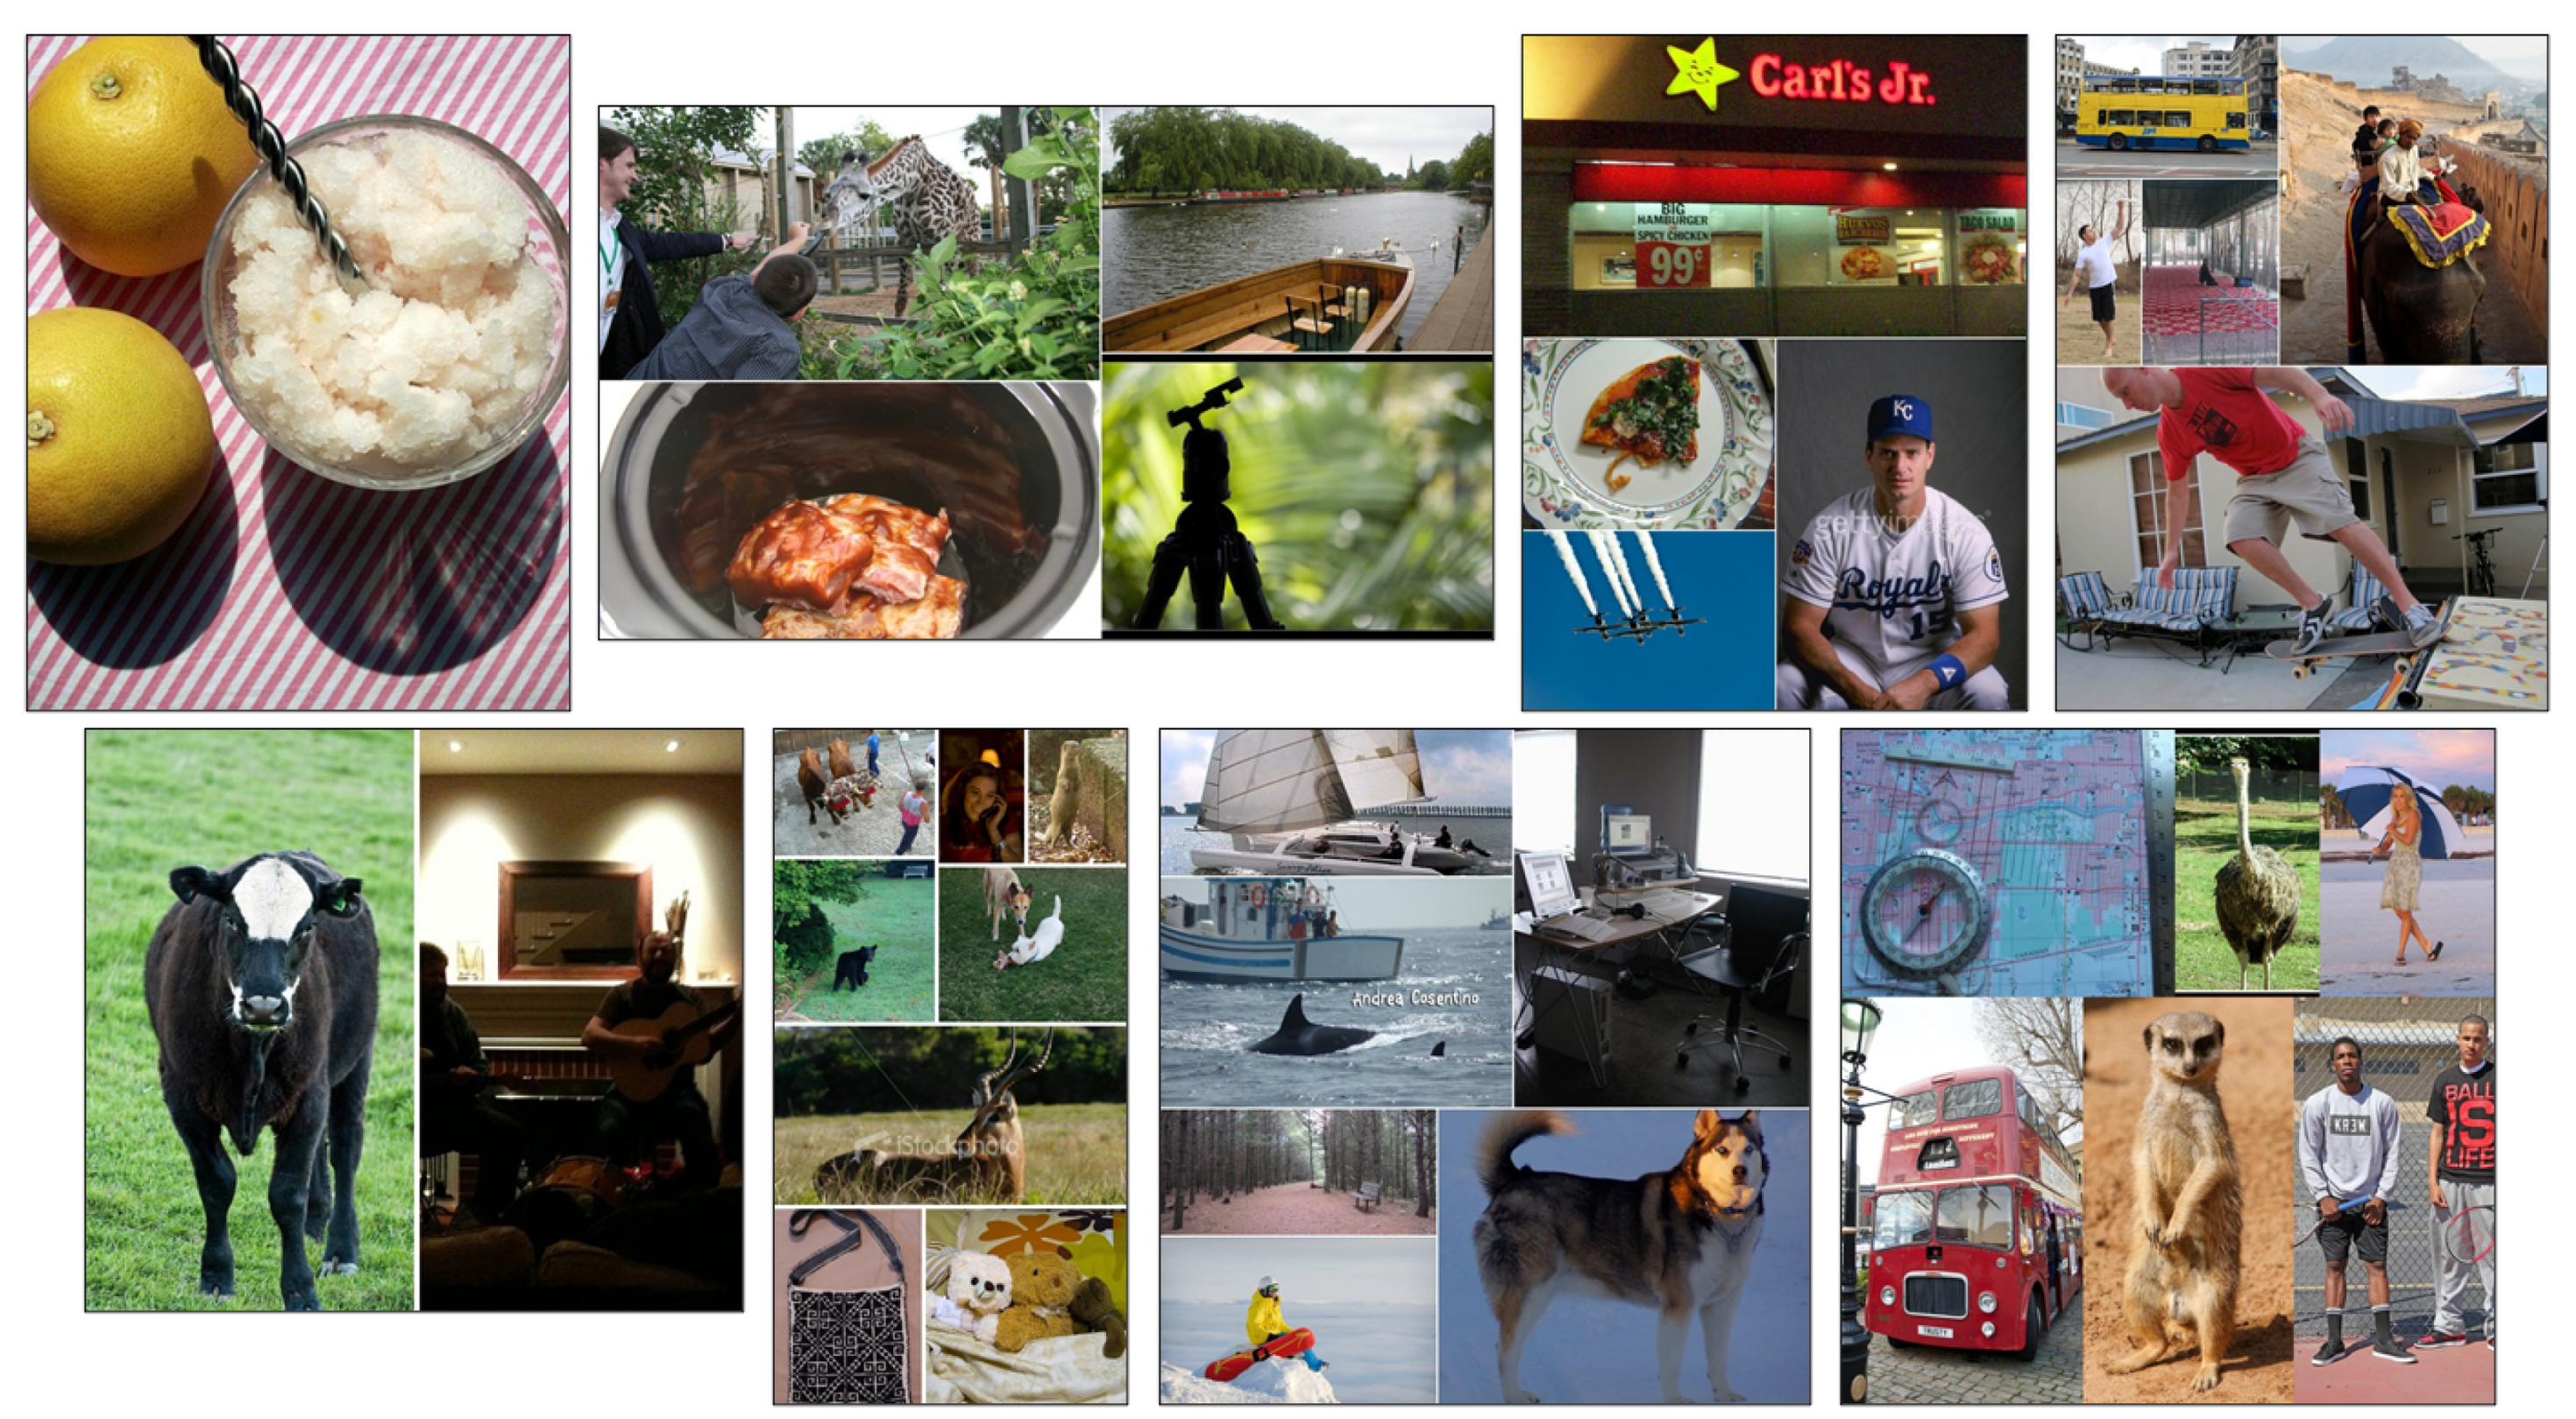
EfficientDet-D1 [12] was deployed to train the object detector and the image detector with MS-COCO [45] and image collage dataset, respectively. We generated 300,000 image collages by using the image collage generation method in Section 3.2 from the photo copyright dataset as shown in Figure 10. 270,000 and 30,000 image collages were used for training and testing, respectively. In object detection, the objectness score was used to select reliable objects among object predictions. We set the thresholds to and for the object detector and the image detector. Note that the larger yields tighter bounding box for the image detector. Furthermore, to filter out small objects, we set the threshold for IoU (Intersection over Union) to between an image region and an object region.
Figure 10.
Samples from the image collage dataset. The collages are generated according to random partition graphs.
4.3. Image Hashing
The SimSiam [35] was employed for the image hashing network to generate binary descriptors. The ResNet-50 [28] pretrained by ImageNet [29] was used as the backbone network. The hidden unit size of Projection MLP and Prediction MLP was set as the same as the binary descriptor size, i.e., 128, 256, and 512.
4.4. Image Verification
For AKAZE [46] feature extraction, the threshold and number of octaves were empirically set to and 3, respectively, and the reprojection threshold in Algorithm 2 was set to 0.2.
5. Experimental Results
5.1. Image Detector with Image Collage Dataset
For image detection from image collages, we benchmark Yolo v3 [17], Faster R-CNN [14], and EfficientDet [12]. Yolo v3 and EfficientDet are one-stage detectors whereas Faster R-CNN is a two-stage detector.
Table 1 shows the results of image detection by using three detectors, which are trained on the image collage dataset. Avg. IoU and Avg. time indicate an averaged IoU between prediction and ground truth boxes and an average measure of time spent on a box prediction. The results of Yolo v3 and Faster R-CNN show the difference of one-stage and two-stage detectors. Faster R-CNN shows better average IoUs with ResNet-101 without Feature Pyramid Network (FPN) [19] than Yolo v3 while the average time of Faster R-CNN is more than ten times that of Yolo v3. EfficientDet shows much better average IoUs than those of Yolo v3 and Faster R-CNN and its inference speed is fast due to the characteristics of one-stage detectors. EfficientDet-D1 with the saturated average IoU is employed in this framework.
5.2. Image Hashing
To verify the performance of the image hashing network, identification accuracies are measured for geometric manipulation and color manipulation. To construct the photo copyright database, binary descriptors are generated from RoIs of original photos. For testing, random cropping is applied for the geometric manipulation and color distortion in HSV space; brightness change, and Gaussian blur are applied for the color manipulation. A Histogram of Gradients (HoG) [11] and BinaryGAN [10] are used for comparison with various binary descriptor sizes.
5.2.1. Geometric Manipulation
As shown in Table 2, the identification accuracies are measured according to IoUs between the original photos and randomly cropped images with various aspect ratios and sizes. The accuracies of all methods increase as an IoU and a descriptor size increase. The proposed image hashing achieves better accuracies than those of HoG and binaryGAN. These results show that the proposed image hashing network that learns various geometric manipulation is effective. HoG, a low-level handcrafted feature, shows a rapid decrease in accuracy as an IoU decreased, and BinaryGAN based on autoencoder network seems difficult to handle the geometric manipulation compared to the proposed image hashing.
Table 2.
Identification results on the copyright image dataset by applying the HoG, the BinaryGAN and the proposed method with geometric manipulation and binary descriptor sizes.
5.2.2. Color Manipulation
Table 3 shows the identification accuracies of three methods. All methods show similar accuracies for color manipulations. HoG which is vulnerable to the geometric manipulations, shows slightly higher accuracies than BinaryGAN and the proposed image hashing for color distortion. Since HoG describes the input image with its graidents in detail, HoG obtains good accuracies if there is no geometric manipulation. BinaryGAN has the lowest accuracies for all color manipulations, and the proposed image hashing shows the highest accuracies for brightness change and Gaussian blur. These results show that the proposed method can handle color manipulations effectively by learning manipulated photos.
Table 3.
Identification results on the copyright image dataset by applying the HoG, the BinaryGAN and the proposed method with various color manipulations and descriptor sizes.
5.3. Image Verification
In Image Verification, the performance of the image alignment and the image similarity Siamese network is measured after applying random clipping (10–30%).
5.3.1. Image Alignment
We verify whether AKAZE [46] is precise enough to perform the image alignment, and the results are shown in Table 4. After the image alignment, the significantly high accuracies are shown with small deviations. These average IoUs are not visually distinctive, and AKAZE is sufficient to utilize for Image Verification.
Table 4.
Image alignment results according to clipping proportions.
5.3.2. Image Similarity Siamese Network
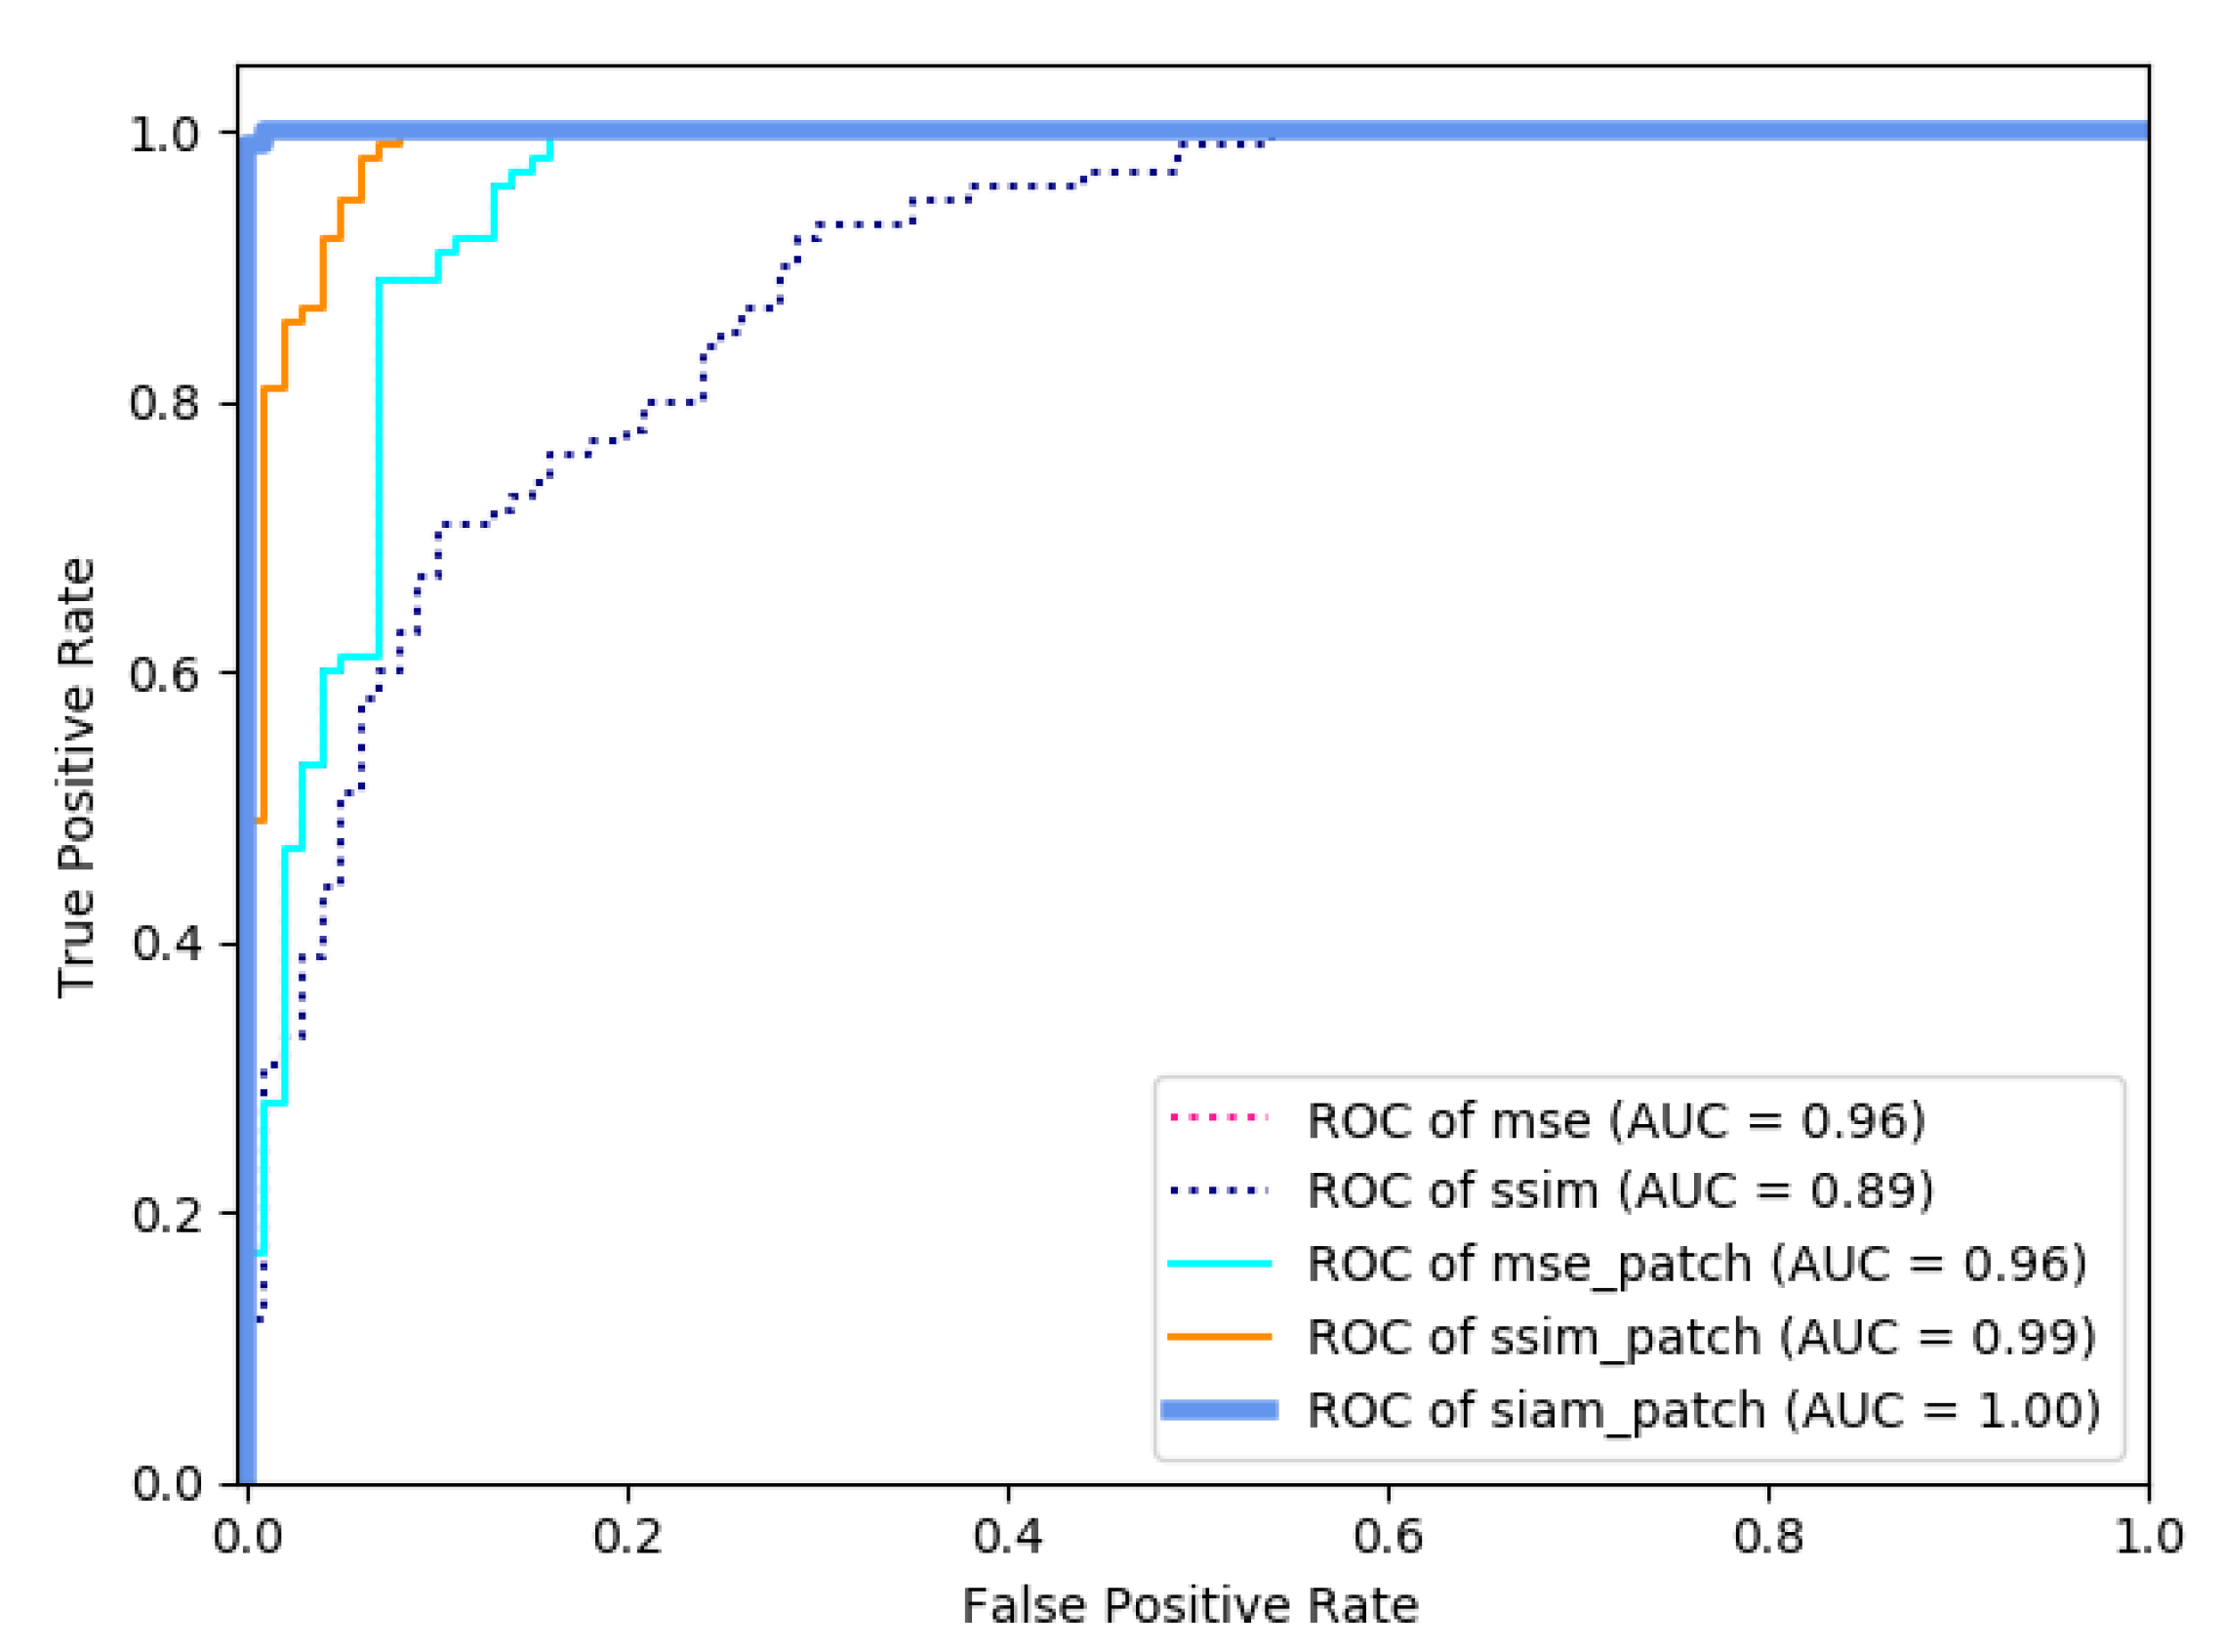
Figure 11 shows the receiver operating characteristic (ROC) curve of the image similarity measure results. The proposed similarity measure shows better performance than that of MSE and SSIM. Since handcrafted image quality metrics such as MSE and SSIM take an average of local similarities for their final similarity scores, it is insensitive to capture local differences. Specifically, SSIM is robust to linear transforms such as contrast enhancement and mean shift, but its similarity score is greatly reduced when nonlinear transforms are such as JPEG compression or blurring occur. On the other hand, since the proposed network is designed from a cognitive perspective on geometric structures, it is able to handle color manipulations better than the other similarity metrics. Table 5 also provides F1-scores and AUC (Area Under the Curve) of Figure 11, showing the great performance of the proposed similarity measure.
Figure 11.
Receiver operating characteristic curves of similarity metrics with geometric coincident image pair or patch pairs. Patch means a similarity metric uses multiple patches sampled from an image as inputs. The pink curve (ROC of mse) is same as the cyan curve (ROC of mse_patch).
Table 5.
Similarity metric performance with geometric coincident image pair or patch pairs. Patch means a similarity metric which uses multiple patches sampled from an image as inputs. FN and FP are False Negative and False Positive, respectively.
In addition, to show efficiency of similarity measure based on significantly different patches, the results of patch-based MSE and SSIM are also provided. MSE of sampled patches is measured as the same as MSE of an image due to its consistent similarity statistics. The patch-based SSIM reflects only local patches with large structural differences and seems very sensitive to subtle differences. However, due to the sensitivity to nonlinear transforms, the results of SSIM are worse than those of the proposed similarity measure.
5.4. Overall Framework Test for Photo Copyright Identification
To demonstrate the effectiveness of each module in the proposed framework, as shown in Table 6, Image RoI Detection and Image Verification are progressively applied to Image hashing. There are three identification results, identified, unidentified, and misidentified. unidentified is only decided by Image Verification.
Table 6.
Ablation tests of photo copyright identification framework by using HoG [11], BinaryGAN [10], and the proposed image hashing with the binary descriptor size 512. The identification results are divided into identified, unidentified, and misidentified. Identified means the correct identification, and unidentified defers the image identification. Misidentified is the identification error (false positive rate), which should be reduced.
(1) Image hashing only shows the identification results without Image RoI Detection. Due to randomness, most image collages with one image are correctly identified, whereas image collages with more than two images are prone to be misidentified. In (2) Image RoI detection + Image hashing, images are separated well from images collages and this method achieves identified of more than 80%, but there still remains a misidentified rate of 11% at least. The last one, (3) Image RoI detection + Image hashing + Image verification, can distinguish unidentified from misidentified. By applying Image Verification, the proposed framework reduces the number of misidentified collages significantly and the number of misidentified collages which can be categorized as the false positive rate is reduced to as a consequence.
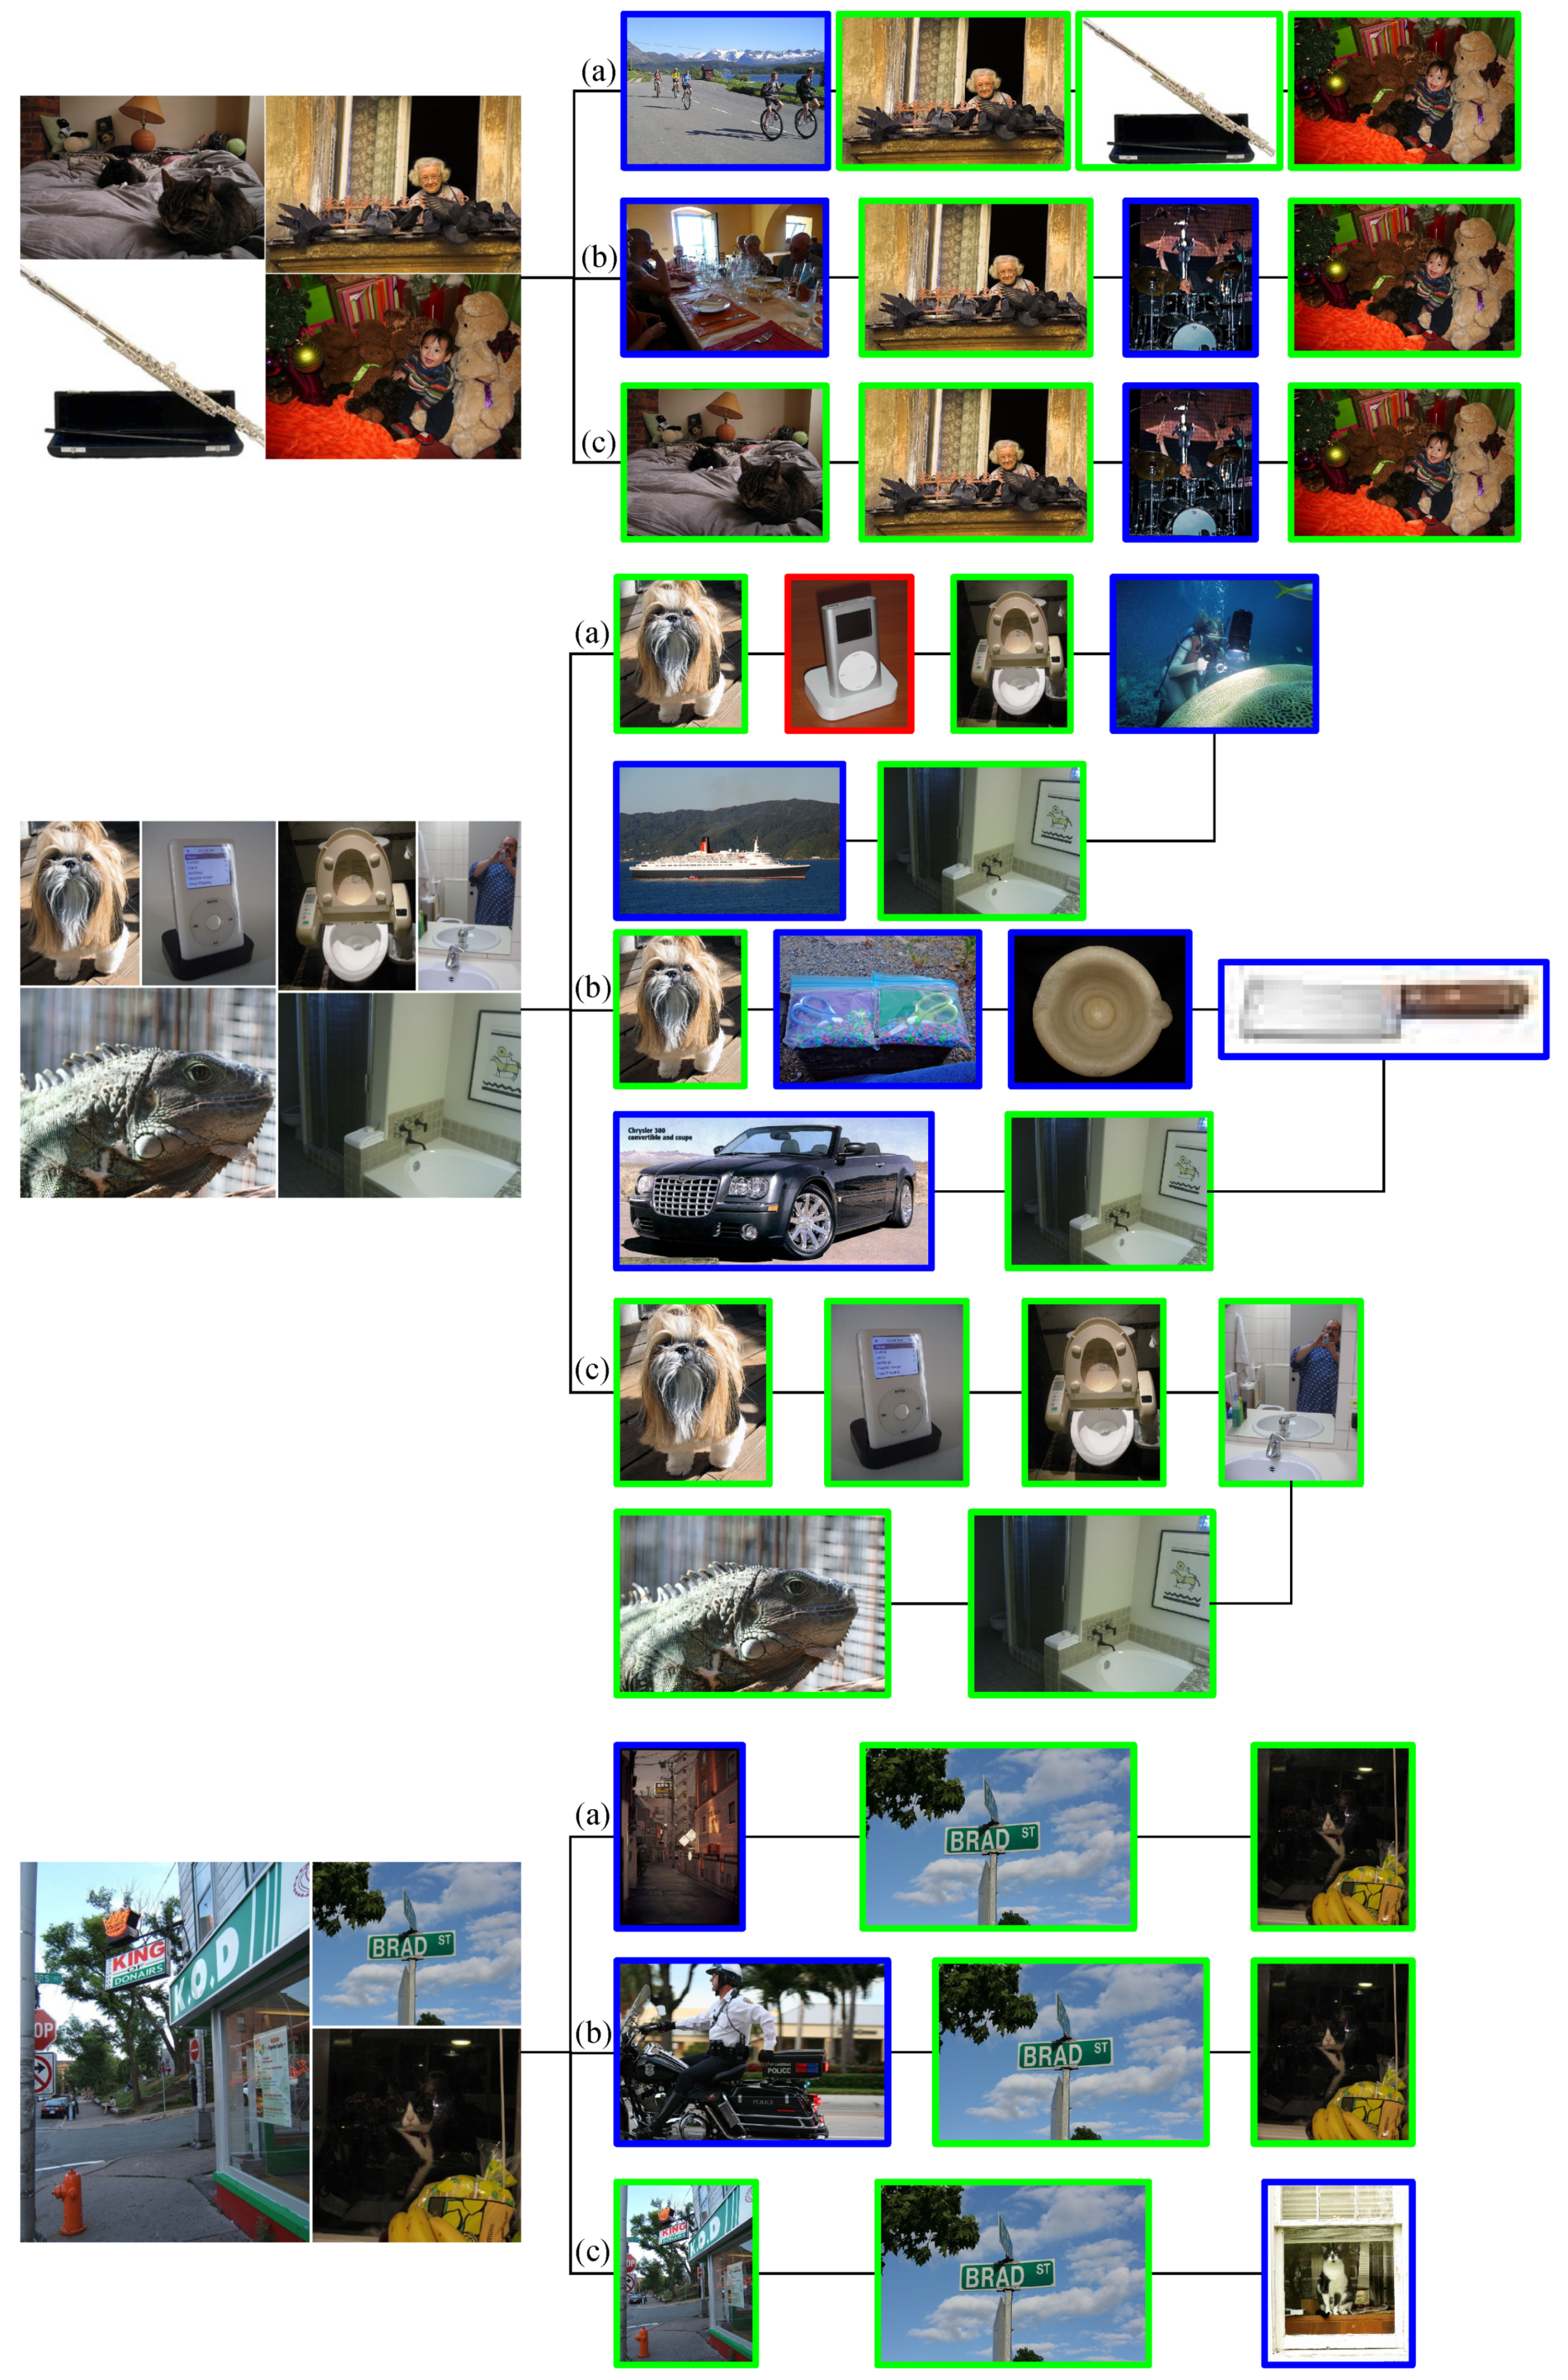
Figure 12 shows identification results of HoG, BinaryGAN, and the proposed framework. The number of results is the same as the number of images in a collage, meaning that the image detector works well to separate images from an image collage. The performance of the proposed framework is especially remarkable in comparison with the other methods in the second results of Figure 12. While the other methods give incorrect images similar to original images in terms of shape or color, the proposed framework correctly matches images by distinguishing image details. Lastly, only one image is determined as misidentified by reducing false positives.
Figure 12.
Copyright identification results of image collage queries. (a–c) indicate the results of HoG [11], BinaryGAN [10], and the proposed hashing method, respectively. Green, Red, and blue boxes mean identified, misidentified, and unidentified results, respectively.
6. Conclusions
We proposed the photo identification framework to prevent copyright infringements. To handle manipulations by pirates, we developed preprocessing steps to identify all photo copyrights in images. First, we detected image RoIs from an image collage to distinguish multiple copyright photos. To train the image RoI detector, we collected the dataset for image collage and proposed the recursive partitioning method to build an image collage frame. Subsequently, we identified each RoI by using the proposed image hashing method that handles image manipulations. By augmenting images, we generated similar binary descriptors from an original image and a manipulated image. Consequently, we have verified identification results by measuring image similarities. This process reduced false positives and left them unidentified while reducing false positives. We experimentally showed the effectiveness of each step in the proposed photo copyright identification framework in comparison with the other methods.
The development of the identification framework is expected to automatically monitor the copyrights of infringed photos from websites, vitalize the photo copyright search service, and prevent copyright holders from copyright infringements. In addition to identification, an image descriptor can be developed for image retrieval, which is utilized in various web image search services. Users also will use legally copyrighted photos by paying royalty and be able to access a lot of available copyright photos. This virtuous cycle, creation of copyrighted works → use of creations and payment of royalties→ recreation copyrighted works, will make it possible to build a ecosystem for copyrights.
Author Contributions
Conceptualization, methodology, software, validation, formal analysis, investigation, resources, data curation, and writing—original draft preparation, D.K. and S.H.; writing—review and editing, D.K., S.H., J.K. and H.K.; supervision and funding acquisition, S.L. All authors have read and agreed to the published version of the manuscript.
Funding
This research project was supported by Ministry of Culture, Sports and Tourism (MCST) and from Korea Copyright Commission in 2021.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
Not applicable.
Conflicts of Interest
The authors declare no conflict of interest. The funders had no role in the design of the study; in the collection, analyses, or interpretation of data; in the writing of the manuscript, or in the decision to publish the results.
References
- Copytrack. Available online: https://www.copytrack.com/ (accessed on 27 September 2021).
- Korea Copyright Commission. Available online: https://www.copyright.or.kr/eng/main.do (accessed on 27 September 2021).
- Oh, T.; Choi, N.; Kim, D.; Lee, S. Low-complexity and robust comic fingerprint method for comic identification. Signal Process. Image Commun. 2015, 39, 1–16. [Google Scholar] [CrossRef] [Scilit]
- Lee, S.-H.; Kim, D.; Jadhav, S.; Lee, S. A restoration method for distorted comics to improve comic contents identification. Int. J. Doc. Anal. Recognit. 2017, 20, 223–240. [Google Scholar] [CrossRef] [Scilit]
- Lee, S.-H.; Kim, J.; Lee, S. An identification framework for print-scan books in a large database. Inf. Sci. 2017, 396, 33–54. [Google Scholar] [CrossRef] [Scilit]
- Kim, D.; Lee, S.-H.; Jadhav, S.; Kwon, H.; Lee, S. Robust fingerprinting method for webtoon identification in large-scale databases. IEEE Access 2018, 6, 37932–37946. [Google Scholar] [CrossRef] [Scilit]
- Google Image Search. Available online: https://www.google.co.kr/imghp (accessed on 27 September 2021).
- Yandex Images. Available online: https://yandex.com/images/ (accessed on 27 September 2021).
- TinEye Reverse Image Search. Available online: https://tineye.com/ (accessed on 27 September 2021).
- Song, J.; He, T.; Gao, L.; Xu, X.; Hanjalic, A.; Shen, H.T. Binary generative adversarial networks for image retrieval. In Proceedings of the AAAI Conference on Artificial Intelligence, New Orleans, LA, USA, 2–7 February 2018; Volume 32.1. [Google Scholar]
- Mcconnell, R.K. Method of and Apparatus for Pattern Recognition. U.S. Patent 4,567,610, 28 January 1986. [Google Scholar]
- Tan, M.; Pang, R.; Le, Q.V. Efficientdet: Scalable and efficient object detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 14–19 June 2020; pp. 10781–10790. Available online: https://openaccess.thecvf.com/content_CVPR_2020/html/Tan_EfficientDet_Scalable_and_Efficient_Object_Detection_CVPR_2020_paper.html (accessed on 20 August 2021).
- Girshick, R. Fast r-cnn. In Proceedings of the IEEE International Conference on Computer Vision, Santiago, Chile, 7–13 December 2015; pp. 1440–1448. [Google Scholar]
- Ren, S.; He, K.; Girshick, R.; Sun, J. Faster R-CNN: Towards real-time object detection with region proposal networks. IEEE Trans. Pattern Anal. Mach. Intell. 2016, 39, 1137–1149. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- He, K.; Gkioxari, G.; Dollar, P.; Girshick, R. Mask r-cnn. In Proceedings of the IEEE International Conference on Computer Vision, Venice, Italy, 22–29 October 2017; pp. 2961–2969. [Google Scholar]
- Redmon, J.; Divvala, S.; Girshick, R.; Farhadi, A. You only look once: Unified, real-time object detection. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Las Vegas, NV, USA, 27–30 June 2016; pp. 779–788. [Google Scholar]
- Redmon, J.; Farhadi, A. YOLO9000: Better, faster, stronger. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Honolulu, HI, USA, 21–26 July 2017; pp. 7263–7271. [Google Scholar]
- Zoph, B.; Cubuk, E.D.; Ghiasi, G.; Lin, T.-Y.; Shlens, J.; Le, Q.V. Learning data augmentation strategies for object detection. In Proceedings of the European Conference on Computer Vision, Glasgow, UK, 23–28 August 2020; pp. 566–583. [Google Scholar]
- Lin, T.-Y.; Dollar, P.; Girshick, R.; He, K.; Hariharan, B.; Belongie, S. Feature pyramid networks for object detection. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Honolulu, HI, USA, 21–26 July 2017; pp. 2117–2125. [Google Scholar]
- Cao, Y.; Long, M.; Liu, B.; Wang, J. Deep cauchy hashing for hamming space retrieval. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Salt Lake City, UT, USA, 18–23 June 2018; pp. 1229–1237. [Google Scholar]
- Cakir, F.; He, K.; Bargal, S.A.; Sclaroff, S. Hashing with mutual information. IEEE Trans. Pattern Anal. Mach. Intell. 2019, 41, 2424–2437. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zieba, M.; Semberecki, P.; El-Gaaly, T.; Trzcinski, T. BinGAN: Learning compact binary descriptors with a regularized GAN. In Proceedings of the 32nd International Conference on Neural Information Processing Systems, Montreal, QC, Canada, 3–8 December 2018; pp. 3612–3622. [Google Scholar]
- Deng, C.; Yang, E.; Liu, T.; Li, J.; Liu, W.; Tao, D. Unsupervised semantic-preserving adversarial hashing for image search. IEEE Trans. Image Process. 2019, 28, 4032–4044. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Goodfellow, I.; Pouget-Abadie, J.; Mirza, M.; Xu, B.; Warde-Farley, D.; Ozair, S.; Courville, A.; Bengio, Y. Generative adversarial nets. In Proceedings of the Advances in Neural Information Processing Systems, Montreal, QC, Canada, 8–13 December 2014; pp. 2672–2680. [Google Scholar]
- Krizehevsky, A.; Sutskever, I.; Hinton, G.E. Imagenet classification with deep convolutional neural networks. Adv. Neural Inf. Process. Syst. 2012, 25, 1097–1105. [Google Scholar]
- Simonyan, K.; Zisserman, A. Very deep convolutional networks for large-scale image recognition. In Proceedings of the International Conference on Learning Representations (ICLR), San Diego, CA, USA, 7–9 May 2015. [Google Scholar]
- Szegedy, C.; Liu, W.; Jia, Y.; Sermanet, P.; Reed, S.; Anguelov, D.; Erhan, D.; Vanhoucke, V.; Rabinovich, A. Going deeper with convolutions. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Boston, MA, USA, 7–12 June 2015; pp. 1–9. [Google Scholar]
- He, K.; Zhang, X.; Ren, S.; Sun, J. Deep residual learning for image recognition. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Las Vegas, NV, USA, 27–30 June 2016; pp. 770–778. [Google Scholar]
- Russakovsky, O.; Deng, J.; Su, H.; Krause, J.; Satheesh, S.; Ma, S.; Huang, Z.; Karpathy, A.; Khosla, A.; Bernstein, M.; et al. ImageNet Large Scale Visual Recognition Challenge. Int. J. Comput. Vis. 2015, 115, 211–252. [Google Scholar] [CrossRef] [Scilit]
- Krizhevsky, A.; Hinton, G. Learning Multiple Layers of Features from Tiny Images. 2009. Available online: https://citeseerx.ist.psu.edu/ (accessed on 27 September 2021).
- Lecun, Y.; Bottou, L.; Bengio, Y.; Haffner, P. Gradient-based learning applied to document recognition. Proc. IEEE 1998, 86, 2278–2324. [Google Scholar] [CrossRef] [Scilit]
- Netzer, Y.; Wang, T.; Coates, A.; Bissacco, A.; Wu, B.; Ng, A.Y. Reading digits in natural images with unsupervised feature learning. In Proceedings of the NIPS Workshop on Deep Learning and Unsupervised Feature Learning, Granada, Spain, 10–13 December 2011. [Google Scholar]
- He, K.; Fan, H.; Wu, Y.; Xie, S.; Girshick, R. Momentum contrast for unsupervised visual representation learning. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, WA, USA, 16–18 June 2020; pp. 9729–9738. [Google Scholar]
- Chen, T.; Kornblith, S.; Norouzi, M.; Hinton, G. A simple framework for contrastive learning of visual representations. In Proceedings of the International Conference on Machine Learning (PMLR), Montréal, QC, Canada, 6–8 July 2020; pp. 1597–1607. [Google Scholar]
- Chen, X.; He, K. Exploring Simple Siamese Representation Learning. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Nashville, TN, USA, 19–25 June 2021; pp. 15750–15758. [Google Scholar]
- Richemond, P.H.; Gril, J.-B.; Altche, F.; Tallec, C.; Strub, F.; Brock, A.; Smith, S.; De, S.; Pascanu, R. BYOL works even without batch statistics. arXiv 2020, arXiv:2010.10241. [Google Scholar]
- Florian, S.; Dmitry, K.; James, P. Facenet: A unified embedding for face recognition and clustering. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Boston, MA, USA, 7–12 June 2015; pp. 815–823. [Google Scholar]
- Lake, B.M.; Salakhutdinov, R.; Tenenbaum, J.B. Human-level concept learning through probabilistic program induction. Science 2015, 350, 1332–1338. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Koch, G.; Zemel, R.; Salakhutdinov, R. Siamese neural networks for one-shot image recognition. In Proceedings of the ICML Deep Learning Workshop, Lille, France, 10–11 July 2015. [Google Scholar]
- Wang, Z.; Bovik, A.C.; Sheikh, H.R.; Simoncelli, E.P. Image quality assessment: From error visibility to structural similarity. IEEE Trans. Image Process. 2004, 13, 600–612. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Kim, J.; Lee, S. Deep learning of human visual sensitivity in image quality assessment framework. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Honolulu, HI, USA, 21–26 July 2017; pp. 1676–1684. [Google Scholar]
- Kim, W.; Kim, J.; Ahn, S.; Kim, J.; Lee, S. Deep video quality assessor: From spatio-temporal visual sensitivity to a convolutional neural aggregation network. In Proceedings of the European Conference on Computer Vision, Munich, Germany, 8–14 September 2018; pp. 219–234. [Google Scholar]
- Kim, W.; Nguyen, A.-D.; Lee, S.; Bovik, A.C. Dynamic receptive field generation for full-reference image quality assessment. IEEE Trans. Image Process. 2020, 29, 4219–4231. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Lin, T.Y.; Goyal, P.; Girshick, R.; He, K.; Dollár, P. Focal loss for dense object detection. In Proceedings of the IEEE International Conference on Computer Vision, Venice, Italy, 22–29 October 2017; pp. 2980–2988. [Google Scholar]
- Lin, T.-Y.; Maire, M.; Belongie, S.; Hays, J.; Perona, P.; Ramanan, D.; Dollar, P.; Zitnick, C.L. Microsoft coco: Common objects in context. In European Conference on Computer Vision; Springer: Cham, Switzerlnad, 2014; pp. 740–755. [Google Scholar]
- Alcantarilla, P.F. Solutions, T. Fast explicit diffusion for accelerated features in nonlinear scale spaces. IEEE Trans. Patten Anal. Mach. Intell. 2011, 34, 1281–1298. [Google Scholar]
- Lowe, D.G. Distinctive image features from scale-invariant keypoints. Int. J. Comput. Vis. 2004, 60, 91–110. [Google Scholar] [CrossRef] [Scilit]
- Bay, H.; Tuytelaars, T.; Van, G.L. Surf: Speeded up robust features. In Proceedings of the European Conference on Computer Vision, Graz, Austria, 7–13 May 2006; pp. 404–417. [Google Scholar]
- Huber, P.J. Robust Statistics; Wiley: Hoboken, NJ, USA, 1981; p. 1. [Google Scholar]
- Abu-El-Haija, S.; Kothari, N.; Lee, J.; Natsev, P.; Toderici, G.; Varadarajan, B.; Vijayanarasimhan, S. Youtube-8m: A large-scale video classification benchmark. arXiv 2016, arXiv:1609.08675. [Google Scholar]

Publisher’s Note: MDPI stays neutral with regard to jurisdictional claims in published maps and institutional affiliations. |
© 2021 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).