1. Introduction
Collaborative robots are increasingly being adopted for assembly tasks within the operator-centered manufacturing paradigm promoted by Industry 5.0 [
1,
2], but their interaction with the operator still relies heavily on rigid interfaces such as teach pendants, as well as offline programming, both of which require technical knowledge and increase the operator’s cognitive load [
3].
Using voice and vision offers a more natural alternative to this human–robot communication interface, but both channels can fail in different ways in a real manufacturing environment, where machinery noise degrades speech recognition, and occlusions or poor lighting reduce the reliability of visual detection. In the experiments conducted for this research, a signal-to-noise ratio of 0 dB was sufficient for Whisper to produce incoherent transcriptions for most commands (
Section 6). A system that relies on a single perceptual channel has no alternative evidence to detect when that channel has deteriorated; it acts—or fails—based on the only available source of information [
4].
This research addresses this vulnerability using a Confidence-Weighted Late Fusion engine, which continuously evaluates the quality of each perceptual channel and dynamically distributes the weight between the speech and visual channels based on that quality; the system’s behavior in the presence of acoustic noise, visual occlusion, and simultaneous degradation of both channels is detailed in
Section 3.
As a second contribution, the framework incorporates an LLM-assisted Reference Resolver that maps natural language commands to the current state of the workspace. Instead of relying on keyword matching or template-based analysis, the resolver constructs a prompt that feeds the visible scene, fusion weights, and the transcribed command into a locally hosted LLM model, thereby enabling the disambiguation of referential expressions such as color terms, spatial descriptors, and implicit references to objects. Deploying the model locally via Ollama prevents the operator’s audio, transcripts, or images of the workspace from leaving the system.
The rest of the manuscript is organized as follows.
Section 2 provides a review of the state of the art regarding digital twins in Industry 5.0, natural human–robot interaction, and multimodal perception for assembly tasks.
Section 3 describes the proposed architecture for the system. The ROS 2 implementation, confidence-weighted fusion pipeline, and LLM-based Reference Resolver are described in
Section 4.
Section 5 describes the simulation environment, degradation protocols and experimental conditions.
Section 6 presents quantitative and qualitative results. We discuss the interpretation of the results, the limitations and future work in
Section 7. Finally, the main contributions and conclusions are presented in
Section 8.
3. Proposed Framework
The DT encompasses a spectrum ranging from a digital model, through a digital shadow—which is characterized by unidirectional synchronization between the physical asset and the digital model—to a complete DT characterized by real-time bidirectional synchronization between the physical asset and its digital counterpart. In this research, the CoppeliaSim environment implements the virtual layer and the execution layer of this architecture, but the physical counterpart has not yet been instantiated: the operator, the ABB YuMi cobot, and the workspace all reside entirely within this simulated environment. Therefore, the proposed system should be understood precisely as a high-fidelity simulation framework that implements the perceptual, fusion, and reasoning logic of an operator-centered DT, and not as a fully deployed DT.
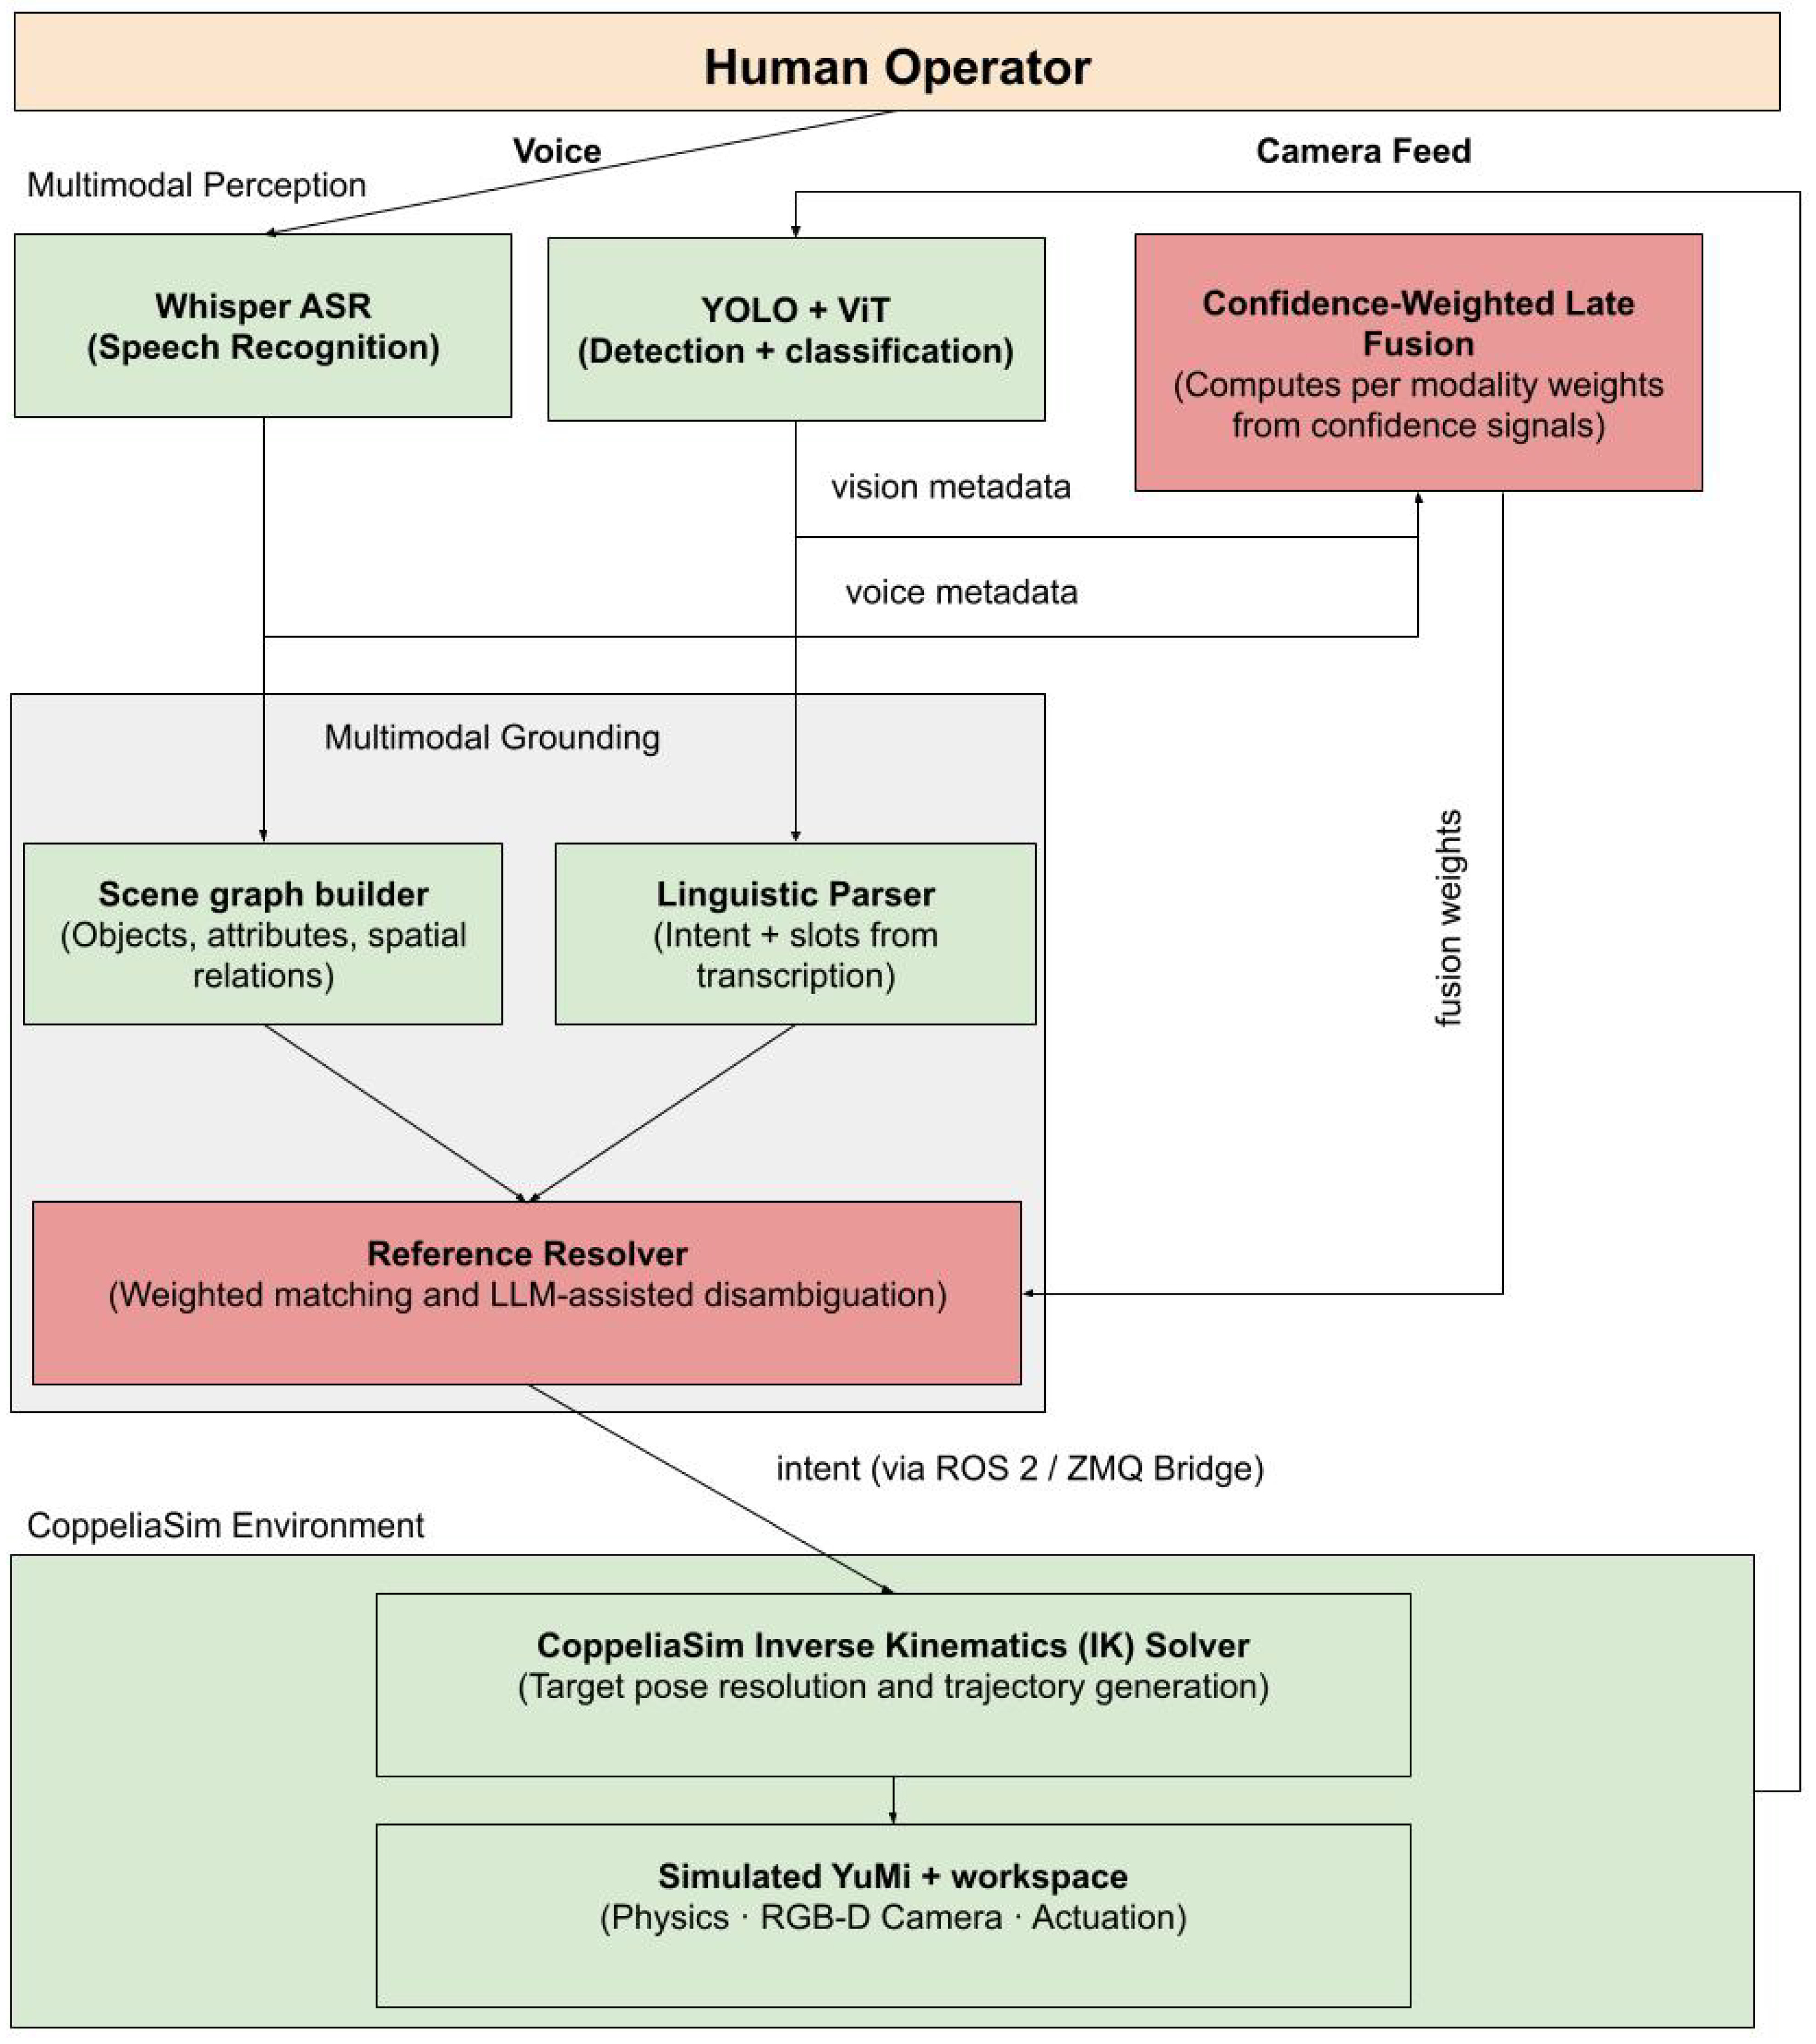
The architecture proposed in this work, shown in
Figure 1 integrates a Confidence-Weighted Late Fusion engine with a Reference Resolver based on a Large Language Model (LLM), implemented in this work using Llama 3.1 8B and served locally via Ollama. Instead of treating all sensor inputs equally, it performs a mathematical evaluation of the reliability of the audio and visual signals before making any grounding decisions.
When one modality is degraded—for instance, by high ambient noise affecting speech recognition, or occlusions that may affect the vision channel—the system automatically compensates by increasing the weight of the unaffected modality. This dynamic compensation allows the robotic system to maintain a safe space, and accurate and seamless operations, effectively absorbing the ambiguity of human communication within chaotic industrial settings.
3.1. Multimodal Perception Layer
The operational cycle begins with the operator; the instructions this operator provides in natural language and within the physical workspace are captured by the multimodal perception layer. To ensure deterministic latency and data sovereignty, all processing is performed locally. This layer comprises two parallel pipelines responsible for extracting both the semantic content and the associated trust metadata.
Audio processing is performed through the integration of Whisper ASR, which, in addition to transcribing the linguistic intent, extracts signal quality metadata—such as the normalized mean logarithmic probability of the generated tokens, the signal-to-noise ratio (SNR) estimated and normalized using a sigmoid function, and the proportion of tokens decoded with low probability, which penalizes critical words decoded with hesitation.
At the same time, visual signal processing is performed using a hybrid YOLO + ViT pipeline on the data stream from an RGB-D camera; in this context, YOLO detects the geometry of objects while ViT classifies complex attributes. This pipeline generates metadata that includes the average and minimum confidence scores of YOLO’s bounding boxes, ViT’s normalized classification entropy—where high entropy indicates uncertainty in the classification—and the total number of detected objects, which serve as a proxy for the scene’s visual complexity.
3.2. Confidence-Weighted Late Fusion Engine
The fusion process proposed in this research consists of three steps. In the first step, for each modality, a quality score is calculated using a linear combination of its positive confidence signals and its uncertainty penalties. In the second step, a softmax function with a temperature parameter converts these scores into normalized weights whose sum equals one. The temperature controls how this weight is distributed among the modalities; so, for example, a low temperature concentrates the weight almost entirely on the modality with the highest quality score, while a moderate temperature distributes the weight more gradually, thereby preserving the contribution of the weaker modality in proportion to the difference in scores. Finally, in the third step, clipping is performed to restrict the weights to the interval [0.15, 0.85], thereby ensuring that
and that no modality is suppressed. The complete mathematical formulation and hyperparameters are detailed in
Section 4.
3.3. Multimodal Grounding and LLM-Assisted Disambiguation
The computed fusion weights are forwarded to the Reference Resolver, the cognitive core of the system powered by a local LLM.
When an operator gives an ambiguous command (for example, “pick up the screwdriver” from among three screwdrivers of different colours), the solver must select the correct object from the 3D scene graph.
The Reference Resolver computes a final candidate score (
) for each object in the scene by combining linguistic matching (
) and visual saliency/confidence (
), modulated by the dynamically calculated weights:
This architecture ensures reliable operation in a variety of industrial environments.
Clean Conditions: In both modalities, the data quality is high; however, because Whisper produces consistently higher confidence scores on undegraded speech than the visual pipeline does on detection, the weights favor the audio channel (), while the vision channel retains the minimum contribution guaranteed by the safety clipping.
Acoustic Degradation: In the presence of intense noise such as that from machinery, which would be typical of an industrial plant, the SNR and decrease, and the fusion engine shifts the weight toward the vision channel in proportion to the drop; under severe degradation, the weights converge to equilibrium (). Even with a partially corrupted transcript, the resolver relies on visual context and spatial reasoning to recover the correct intent.
Visual Occlusion: When the camera is partially obstructed or it is poorly lit, the ViT entropy increases sharply and drops; therefore, the weights shift toward the audio (), and the resolver decides to prioritize the audio signal over the visual signal.
Double Degradation: In the event of simultaneous failure of both modalities, the overall combined confidence metric remains critically low. Rather than executing an unsafe action, the resolver detects this threshold and safely triggers a request for verbal confirmation from the operator.
3.4. Simulation and Execution Environment
Once the Reference Resolver identifies the highest-scoring candidate and deduces the precise spatial intent, the command is transmitted via a ROS 2/ZMQ middleware bridge.
This ensures asynchronous, reliable and low-latency data transfer to the physical execution layer.
The execution domain is materialized within a high-fidelity CoppeliaSim environment. To optimize computational efficiency, trajectory generation is delegated to the native CoppeliaSim Inverse Kinematics (IK) solver. The IK solver converts the target Cartesian coordinates to the exact joint configuration for the simulated ABB YuMi collaborative robot.
As the cobot executes the task, the physical state of the workspace changes. This action is immediately captured by the simulated RGB-D camera that continuously updates the multimodal perception layer, thus closing the loop of the system operation.
4. System Implementation
The proposed framework is fully implemented as a distributed system of ROS 2 Jazzy Jalisco nodes written in Python 3.12.3, deployed on a workstation running Ubuntu 24.04 LTS under the Windows Subsystem for Linux (WSL2). The simulation environment is hosted in CoppeliaSim Edu, interfaced to the ROS 2 graph via the official ZMQ Remote API. All inferences (including speech recognition and reasoning based on Large Language Models) are carried out locally, ensuring deterministic latency and full data sovereignty; neither the operators’ audio, nor the transcriptions, nor the images of the workspace are transmitted to external services.
4.1. ROS 2 Communication Architecture and Custom Message Interfaces
The framework is structured as two ROS 2 Jazzy packages with separate and non-overlapping roles: an edge perception package containing the nodes for acquiring and characterizing the quality of the auditory and visual signals, and a cognition and execution package containing the fusion engine, the LLM-based interpreter, and the motion executor. This separation guarantees perception components are robot-agnostic and reusable across platforms, with robot-specific logic fully contained within a single package boundary.
To integrate task execution workflow and digital twin technology [
16,
35], the communication architecture is built on the basis of ROS’s publish–subscribe model. The bridge to the CoppeliaSim simulator is based on segregated channels, where a high-bandwidth pathway is used for depth camera data and a low-latency channel is used for poses and execution feedback [
16,
35].
Such an arrangement does not overwhelm the control pathway with visual data, which is a necessary measure to satisfy the real-time processing and safety requirements of collaborative manufacturing environments [
16]. The framework introduces four ROS 2 topics that do not exist in the baseline pipeline and that represent the backbone of the communication in the contribution.
Table 2 shows their message types and the nodes that publish and subscribe to them.
To enable strongly typed and self-documenting communication, a dedicated interface package defines three custom message types. The VoiceMetadata message encapsulates four float32 fields that characterize the quality of each utterance: whisper_confidence, defined as the exponentiated mean log-probability of the decoded tokens, normalized to the interval ; snr_estimate, an estimated signal-to-noise ratio that is normalized via a sigmoid function centered at a reference SNR of 15 dB; low_confidence_token_ratio, the proportion of decoded tokens whose individual log-probability falls below a fixed threshold, thereby serving as a penalty for locally uncertain or hesitant decoding; and duration_seconds, the utterance duration in seconds, used exclusively as a diagnostic sanity-check signal.
The VisionMetadata message carries four fields derived from each processed camera frame: yolo_confidence_mean and yolo_confidence_min, the mean and minimum detection confidence scores across all bounding boxes; ViT_classification_entropy, the normalized Shannon entropy of the ViT classification distribution on the predicted top labels k, calculated as to bound the value to ; and num_objects_detected, the total count of objects, which serves as a proxy for the complexity of the visual scene.
The FusionWeights message carries three float32 fields:
w_audio and w_vision, the per-modality fusion weights bounded within , and confidence_combined, a scalar in reflecting the overall reliability of the current fusion decision.
A low confidence value _combined signals that both modalities are simultaneously degraded; downstream components use this field to decide whether to proceed autonomously or to request verbal confirmation from the operator.
All quality signals are normalized to at the publishing node. The fusion node applies a secondary defensive clipping upon reception to guard against upstream normalization failures, decoupling the correctness of the fusion arithmetic from the correctness of the upstream perception nodes and improving fault isolation across the distributed system.
4.2. Confidence-Weighted Late Fusion: Internal Pipeline and Hyperparameter Configuration
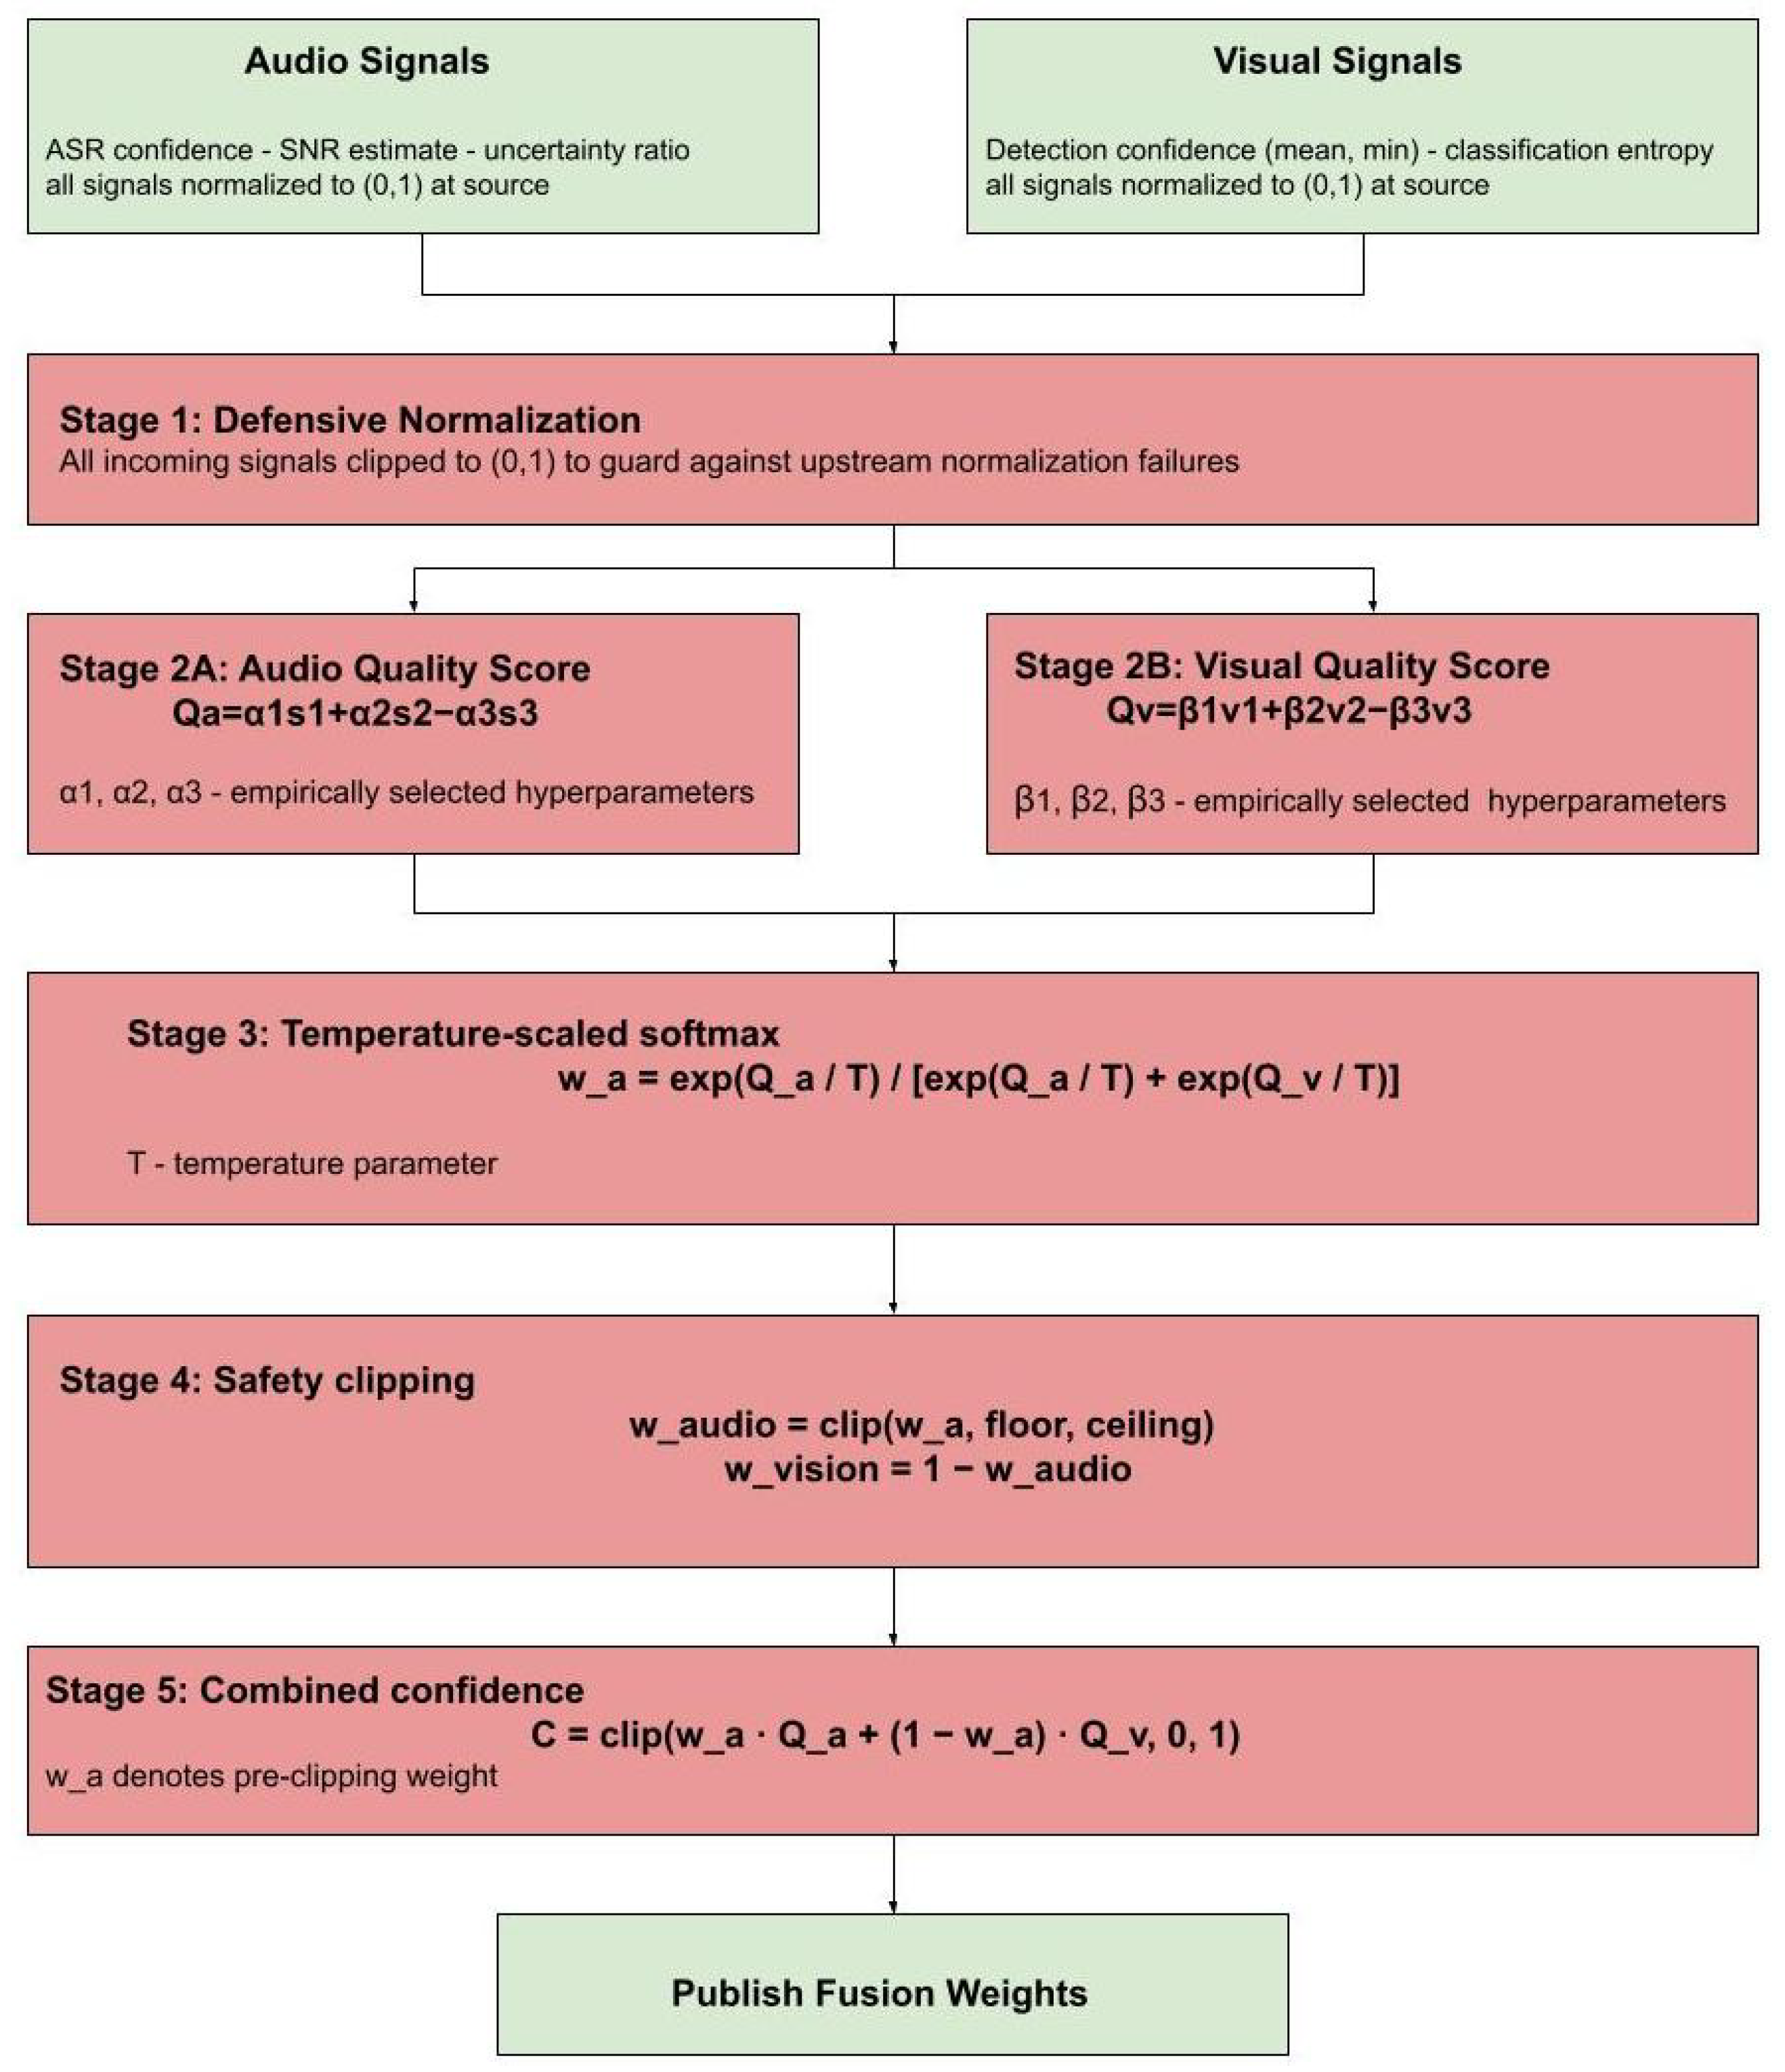
The main scientific contribution of the proposed framework is the Confidence-Weighted Late Fusion module. This module continuously assesses the quality of each incoming stream of perceptual input and dynamically adjusts its relative contribution to the downstream grounding decision. The module runs as a dedicated ROS 2 node at a fixed rate of 5 Hz, consuming quality metadata from both perception pipelines and publishing per-modality fusion weights to the Reference Resolver. Its internal processing is structured into five successive stages, each with a well-defined mathematical responsibility, as depicted in
Figure 2.
Within the broader architecture shown in
Figure 1, the fusion module occupies a parallel pathway with respect to the main perception-to-action pipeline. It operates asynchronously on the quality metadata exposed by both perception nodes and publishes fusion weights that the Reference Resolver consumes at decision time. This architectural choice ensures that the computational cost of the fusion pipeline does not compound with the latency of the LLM-based grounding stage. All quality signals arrive pre-normalized to
from their respective publishing nodes, establishing a consistent numerical domain for the fusion arithmetic.
4.2.1. Stage 1: Defensive Normalization
Although all quality values are pre-normalized to the interval [0, 1] prior to being emitted by their respective publishing nodes, the fusion engine applies an additional clipping operation upon receipt of each metadata message. This clipping procedure is a defensive measure designed to mitigate errors arising from faulty upstream normalization—for example, when a publishing node outputs an invalid value due to sensor malfunction or software defects—and to decouple the correctness of the fusion algorithm employed in Stages 2–5 from potential inaccuracies introduced by upstream perception nodes.
4.2.2. Stage 2: Per-Modality Quality Scores
The normalized signals are combined into a single scalar quality score per modality, as a linear combination of positive evidence terms and negative uncertainty penalties. The audio modality quality score is as follows:
where
is the confidence of ASR transcription,
is the normalized signal-to-noise ratio estimate, and
is the token ratio decoded individually with low probability. The coefficients
,
,
are empirically chosen hyperparameters that weight the relative contribution of each signal component.
For the visual modality, the analogous quality score is as follows:
where
and
are the mean and minimum object detection confidence scores across all bounding boxes in the current frame, and
is the normalized Shannon entropy of the visual classification distribution, computed as
over the labels predicted above
k, where high entropy represents classification uncertainty. The coefficients
,
and
are structurally similar to their auditory counterparts.
The additive structure of both quality scores is the same: a positive contribution for signals increasing with perceptual reliability and a negative contribution for signals increasing with uncertainty. This design ensures that and monotonically decrease as their respective modalities degrade, which is the property needed for the softmax stage to produce the desired weight shift.
The values of the coefficients reported in
Table 3 were fixed after an ad hoc calibration process, guided during the testing phase before the formal evaluation; their fixed values were maintained for all the experimental conditions, for the sake of comparability. Instead of a black box optimization, the selection relies on three interpretable principles.
First, within each modality, positive evidence weights were sorted according to the informational reliability of each signal. For the auditory modality, we give more weight to the ASR confidence () than to the SNR estimate (), which directly reflects the decoder’s confidence regarding the linguistic content; the penalty for low-probability tokens () is a second-order correction term.
Similarly, the average detection confidence () dominates the minimum confidence () and the classification entropy penalty () in the visual modality.
The softmax temperature () was chosen to maintain sensitivity to quality differences without degenerating into a near-binary assignment; pilot tests suggested that lower values caused abrupt, unstable transitions, while higher values obscured the distinction between modalities.
Third, the limits for the clipping (
,
) were selected so that no modality is ever fully suppressed, thus leaving residual information and avoiding discontinuities in the decision surface of the Reference Resolver. The combined confidence threshold
was chosen empirically based on the observed distribution of
C, described in detail in
Section 5.4.
4.2.3. Stage 3: Temperature-Scaled Softmax
The two scalar quality scores are converted into normalized fusion weights through a softmax function parameterized by a temperature scalar
T:
The temperature parameter modulates the decisiveness of the mapping: a low value of T produces a near-binary assignment, whereas a higher value preserves a more balanced distribution even when quality scores differ substantially. The value selected maintains the sensitivity to quality differences while keeping complementary information from the lower modality. For numerical stability, the calculation is using a max-shift before the exponentiation, minus from either argument, which prevents floating point overflow but does not change the distribution of the output.
4.2.4. Stage 4: Safety Clipping
The raw softmax output is hard-clipped so that no modality ever gets fully suppressed, even in the face of severe degradation:
and
. This constraint ensures that both modalities always have a minimum 15% contribution to the grounding decision.
This reasoning is based on two aspects: on one hand, a completely suppressed modality could still carry some residual information that would marginally improve robustness, while on the other hand, abrupt transitions between unimodal and bimodal operations would produce instabilities in the decision surface of the Reference Resolver.
When the limits of safety are reached, a warning is sent to the diagnostic stream of the system to audit offline.
4.2.5. Stage 5: Combined Confidence
The combined confidence metric
is a weighted sum of the per-modality quality scores:
One important implementation detail is that
in Equation (
7) is the raw softmax output before clipping, not
after clipping. This difference makes
C a faithful representation of the perceptual confidence of the system irrespective of the safety correction introduced in Stage 4. When both modalities are degraded at the same time,
and
are both low, and
C is below the downstream threshold
, which triggers the operator confirmation request discussed in
Section 3. This mechanism directly provides the dual degradation safety behaviour as a function of signal quality, without the need of explicit state machines or manual thresholds per modality.
4.2.6. Output and Downstream Consumption
This pipeline outputs three quantities,
,
, and
C, which are packaged into a
FusionWeights message and published on
/fusion/weights at 5 Hz. The Reference Resolver subscribes to this topic and uses the weights to modulate the relative contribution of linguistic and visual evidence in the computation of candidate object scores defined in Equation (
1). The LLM-based interpreter also further uses the combined confidence
C to gate command execution: commands with
are rejected before reaching the language model, avoiding the cost of an inference cycle on a signal that is unlikely to yield a reliable grounding decision.
4.2.7. Design Rationale: Interpretability over
Expressiveness
Inspired by the operational needs of collaborative industrial settings, we consider an explicit linear aggregation followed by a closed-form softmax function and hard clipping instead of a learned flow control network.
Each fusion decision can be completely traced to its input signals and hyperparameter values: with the published , , and C, an auditor can reconstruct the quality scores and discover which signals shifted the weights. This feature aligns with the traceability requirements of the European AI Act and the Industry 5.0 agenda on human-auditable automation.
As discussed in
Section 7, an immediate future direction is to learn a gating variant trained on synthetic degradation data, with the current heuristic formulation providing a transparent and reproducible baseline to benchmark learned approaches against.
4.3. Reference Resolver Implementation: LLM-Grounded Strategist and Motion Executor
The Reference Resolver, presented in
Section 3, is implemented as a cooperative two-node pipeline, as shown in
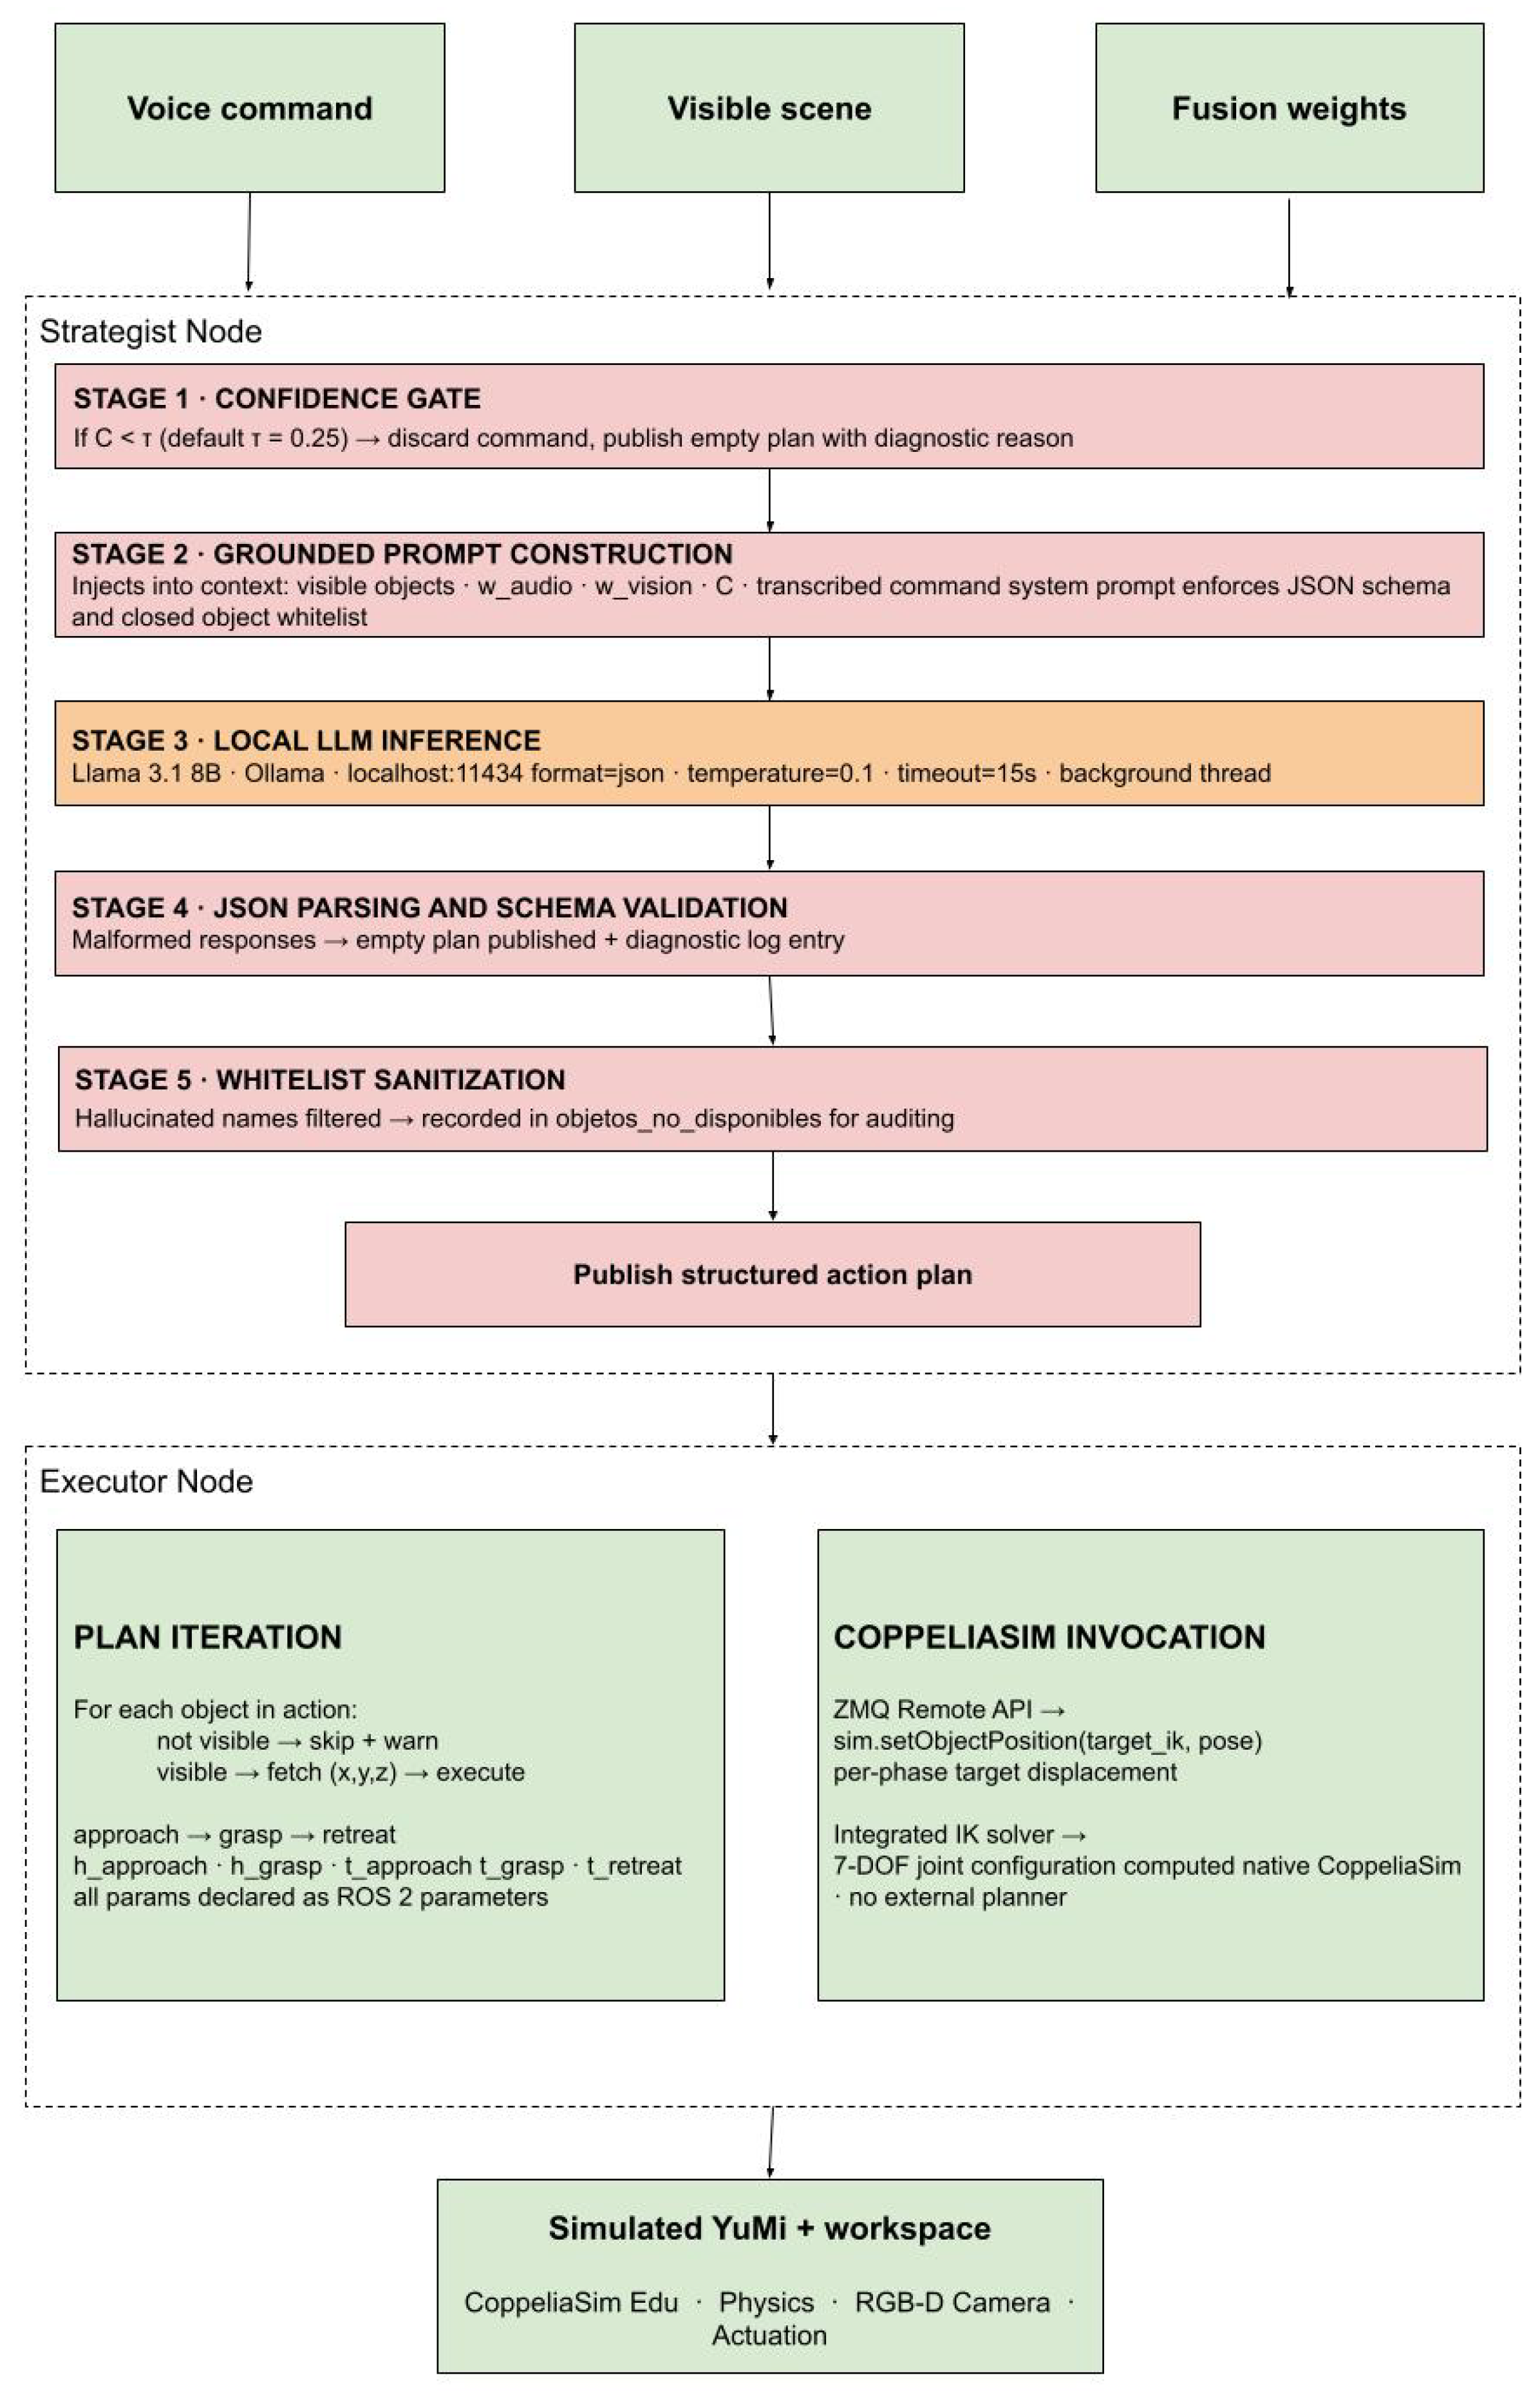
Figure 3. The separation of functions is deliberate: the strategist node is responsible for all natural language understanding and linking, whilst the executor node is responsible for all motion control. Neither node encroaches on the other’s responsibilities, allowing each to evolve independently.
The system receives three simultaneous inputs—the transcribed voice command from /voz/comando, the currently detected objects and their 3D coordinates from /vision/detecciones, and the real-time fusion weights from /fusion/weights—and processes them through five sequential stages.
First, a confidence gate filters out any command with a combined confidence
C that is below a configurable threshold
, implementing the dual degradation safety behavior described in
Section 3 without calling the language model.
Commands that clear this gate are used to construct a grounded prompt that injects the visible scene, the fusion weights and the transcribed utterance into the reasoning context of the model.
This prompt is given to a locally hosted instance of Llama 3.1 8B served through Ollama [
36], with the structured JSON output enforcement set and a low sampling temperature of
to constrain variability in the output.
The response is analyzed and validated with respect to the expected format. Incorrectly formatted outputs are detected and an empty plan is returned.
During validation, a whitelist is used to reject any object names not in the workspace inventory logging the fictitious references for offline auditing before publishing the validated plan to /yumi/plan.
The executor node subscribes to “/yumi/plan” and iterates through the ordered list of actions. It checks whether the object is visible in the current scene for each target object. If no object is detected then the action is skipped and a warning is issued. For visible targets, the executor sends successive target pose displacements to CoppeliaSim via the ZMQ Remote API to perform a three-phase approach–grasp–retreat trajectory, delegating joint configuration to the simulator’s internal Inverse Kinematics solver. All timing and height parameters are declared as ROS 2 parameters so they can be tuned between experimental conditions without recompilation.
The perception-to-action loop is closed by this pipeline, together with the fusion module in
Section 4.2: the fusion weights control the confidence gate in Stage 1 and the grounded context in Stage 2, such that the reasoning of the language model is always conditioned on the current confidence of each perceptual channel.
5. Experimental Setup
This section details the experimental setup, encompassing the simulation environment, the degradation protocols, and the experimental conditions employed to evaluate the framework under controlled sensory conditions.
5.1. Simulation Environment
The framework is fully validated in CoppeliaSim Edu, a high-fidelity robot simulator developed by Coppelia robotics (Zurich, Switzerland). CoppeliaSim was chosen for three reasons that directly satisfy the requirements of this work. It first provides a native Inverse Kinematics solver that computes 7-DOF joint configurations in real time, without the need for an external motion planning library, thus keeping the system architecture self-contained. Second, it exposes a ZMQ Remote API that enables low-latency bidirectional communication with the ROS 2 Jazzy graph, supporting the asynchronous control architecture described in
Section 3. Third, its physics engine (Bullet 2.78) and integrated RGB-D camera sensor provide a sufficiently realistic visual feed for evaluating the YOLO + ViT perception pipeline under the degradation conditions introduced in this study.
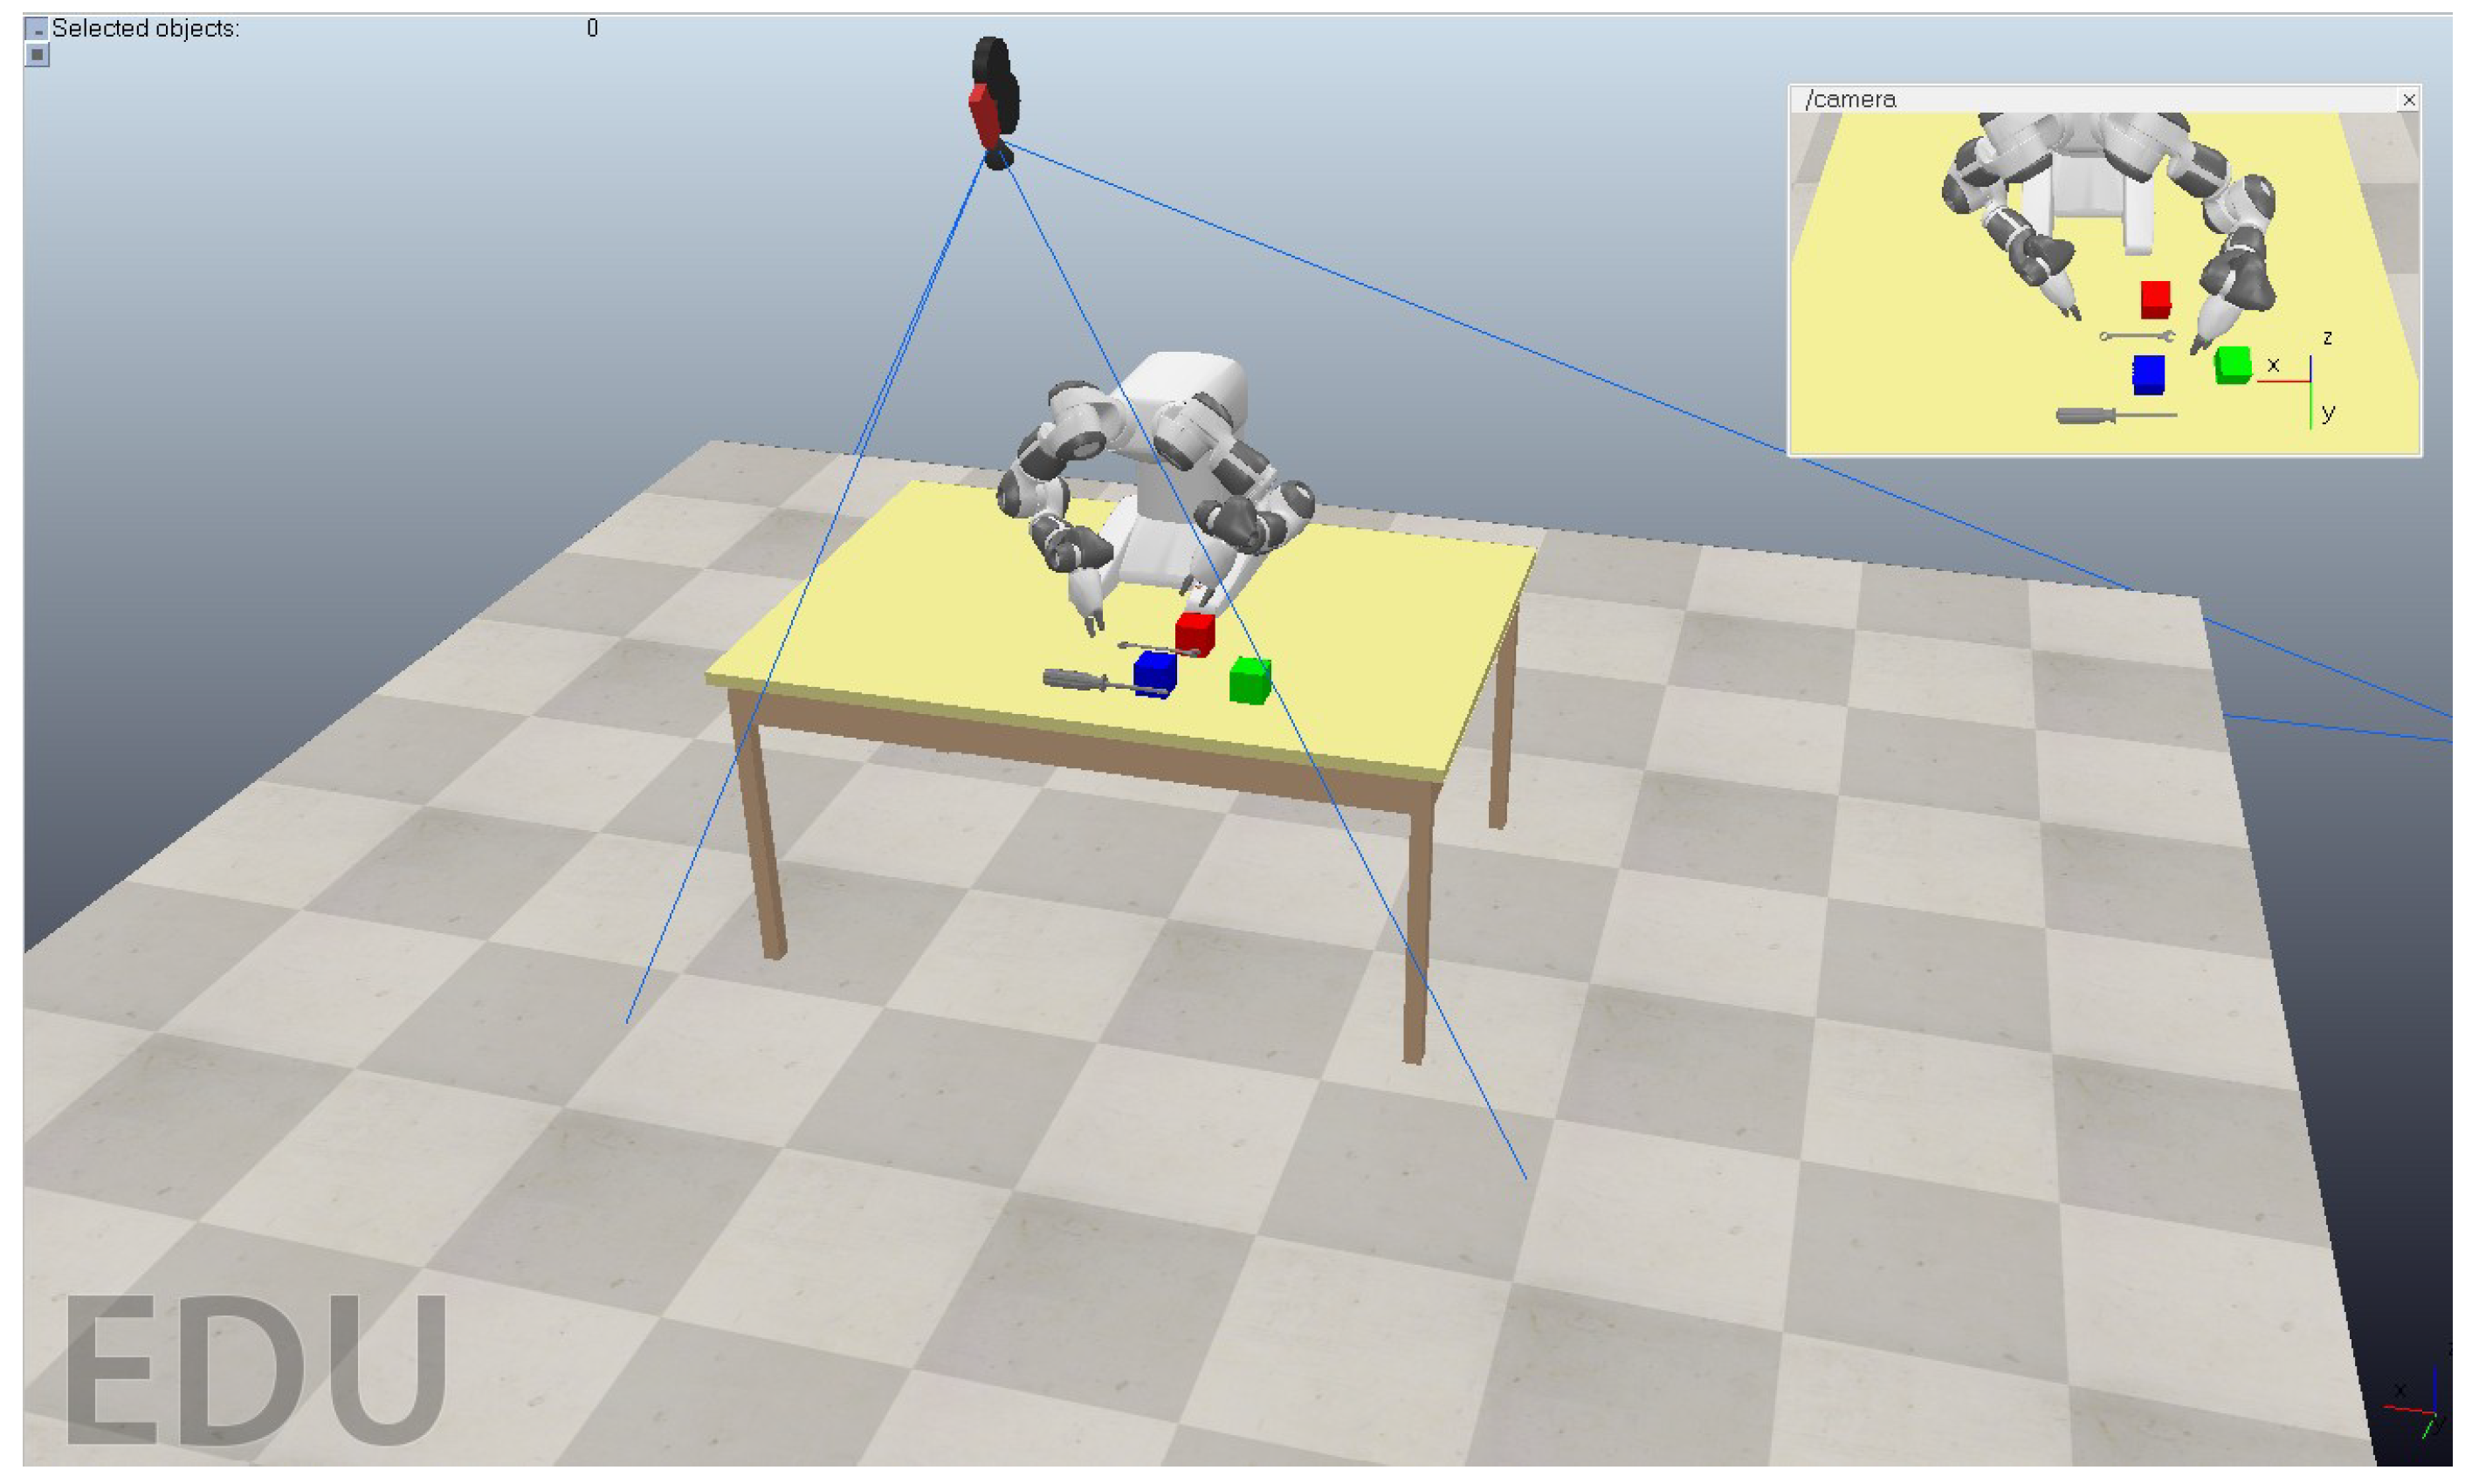
Figure 4 shows the simulated workspace, which consists of a workbench where three colored target objects are placed: a red cube (
cubo_rojo), a green cube (
cubo_verde) and a blue cube (
cubo_azul). Also present is a screwdriver as a distractor object not present in the command set. An overhead RGB-D camera observes the workspace from a fixed bird’s eye view. The camera feed is streamed to the ROS 2 graph through the high-bandwidth ZMQ channel at a rate of up to 30 Hz. The dual-arm ABB YuMi collaborative robot is positioned at the edge of the workbench and all manipulation tasks are performed with its right arm driven by the CoppeliaSim IK solver. The inset in
Figure 4 shows the field of view of the camera used by the visual detection pipeline in action.
All experiments are performed only in this simulated environment. There is no physical robot hardware. The fully simulated implementation provides a reproducible benchmark where the scene, object positions, audio recordings, and degradation parameters are all fixed and version controlled such that every experimental condition can be exactly reproduced.
5.2. Hardware and Software Configuration
The framework runs on a workstation equipped with an Intel Core i7-12700 processor, 16 GB of RAM, and an NVIDIA RTX 4070 GPU, under Ubuntu 24.04 LTS via WSL2. Llama 3.1 8B is served locally via Ollama. All inferences are executed on-premise with no external service dependencies.
5.3. Command Set and Voice Recordings
The single operator recorded a total of 15 voice commands in a controlled acoustic environment with a directional microphone at a fixed distance of about 30 cm, sampled at 16 kHz mono PCM, the native input format of the Whisper ASR model. Five different linguistic command variants were recorded for each target object, varying verb forms and referential expressions. This lexical variation ensures that the evaluation is not biased towards a single command template. A JSON mapping file defines the ground truth object for each of the recordings. The logging system uses this to automatically determine the success of the execution.
5.4. Confidence Threshold Selection
The confidence gate in Stage 1 of the strategist node discards any command with combined confidence C below a threshold . Its value was chosen empirically in pilot experiments, prior to the formal evaluation. In the pilot, we observed the distribution of values C in all conditions. In clean and mildly degraded conditions, C was always above 0.40, whereas under simultaneous severe degradation of both modalities, C fell under 0.20 in the majority of frames. We thus identified the value as a natural operating boundary between reliable fusion decisions and those for which no modality is providing sufficient signal quality to enable safe autonomous execution. At this threshold, the system requests verbal confirmation from the operator instead of attempting a possibly wrong manipulation. A more systematic sensitivity analysis of over a wider range of values is identified as an avenue for future work; the present study treats it as a fixed design parameter.
5.5. Audio Degradation Protocol
Auditory degradation was simulated by adding white Gaussian noise (AWGN), at three different SNR levels, 20, 10 and 0 dB, under controlled conditions. The noise power for each clean recording was calculated from the desired SNR and the RMS power of the clean speech signal as Gaussian noise was generated using
numpy with a fixed random seed (seed = 42), to ensure full reproducibility.
The degraded signal was clipped to before conversion to 16-bit PCM. The output SNR was empirically verified for all 45 degraded recordings (15 records × 3 levels) and was found to agree with the target values within ±0.06 dB under all conditions. The speech remains intelligible at 20 dB, comparable to a noisy industrial environment at 10 dB, and at 0 dB, the noise power is equal to the signal power, corresponding to a severe degradation scenario where the ASR model produces incoherent transcriptions. In experiment mode, the degraded audio files are fed directly into the Whisper ASR node, skipping the microphone capture phase to ensure perfect reproducibility between runs.
5.6. Visual Degradation Protocol
Visual degradation was programmatically introduced at two levels applied to each camera frame before YOLO and ViT processing, selected to result in a measurable and progressive decrease in YOLO detection confidence and an increase in ViT classification entropy. During piloting, we tested a mild blur-only level (Gaussian kernel ), but it was not included in the formal protocol as it produced no statistically distinguishable change in either visual quality signal relative to the clean baseline and therefore did not stress the fusion module.
For medium level, we add Gaussian blur (kernel ) and reduce the brightness to 60% of the original luminance, simulating poor lighting conditions with partial occlusion. At the severe level, the medium-level transformations are augmented by a grey rectangle covering 40% of the central image area, simulating a physical obstacle partially obstructing the workspace.
5.7. Experimental Conditions and Evaluation Metric
Table 4 summarizes the seven experimental conditions evaluated in this work. Each condition is evaluated under two system configurations:
Fusion ON, in which the Confidence-Weighted Late Fusion module operates as described in
Section 3.2, and
Fusion OFF, in which the interpreter node uses fixed weights
regardless of signal quality. This ablation study isolates the contribution of the adaptive fusion module from the rest of the pipeline.
The main evaluation metric is the command execution accuracy, which is defined as the percentage of commands where the system selected and attempted manipulation of the correct target object.
A command is considered correct if the first element of the actions field in the published action plan matches the ground truth object for that recording. Commands discarded by the confidence gate are counted as failures, since, from the operator’s perspective, the robot did not execute the intended action. We also track a secondary qualitative measure of grounding errors, defined as executions where the system chooses and tries to manipulate an incorrect object instead of simply abstaining. Grounding errors are particularly relevant for safety assessment, since they are active errors, not conservative abstentions.
6. Results
In this section, we report the quantitative and qualitative results obtained over the 210 experimental executions described in
Section 5. The results are ordered according to the degradation axis: auditory degradation, visual degradation, and dual degradation.
We compare the Fusion ON and Fusion OFF configurations for each condition in order to remove the contribution of the adaptive fusion module.
6.1. Baseline Performance
In clean acoustic and visual conditions (C1), both system configurations achieved a perfect command execution accuracy of 100% for all 15 commands and all three target objects. The mean fusion weights for this condition were
and
, which indicates the dominance of the auditory channel in the case of a clear speech signal with Whisper ASR providing high-confidence transcriptions. The overall confidence
C was always above 0.50, well above the safety threshold
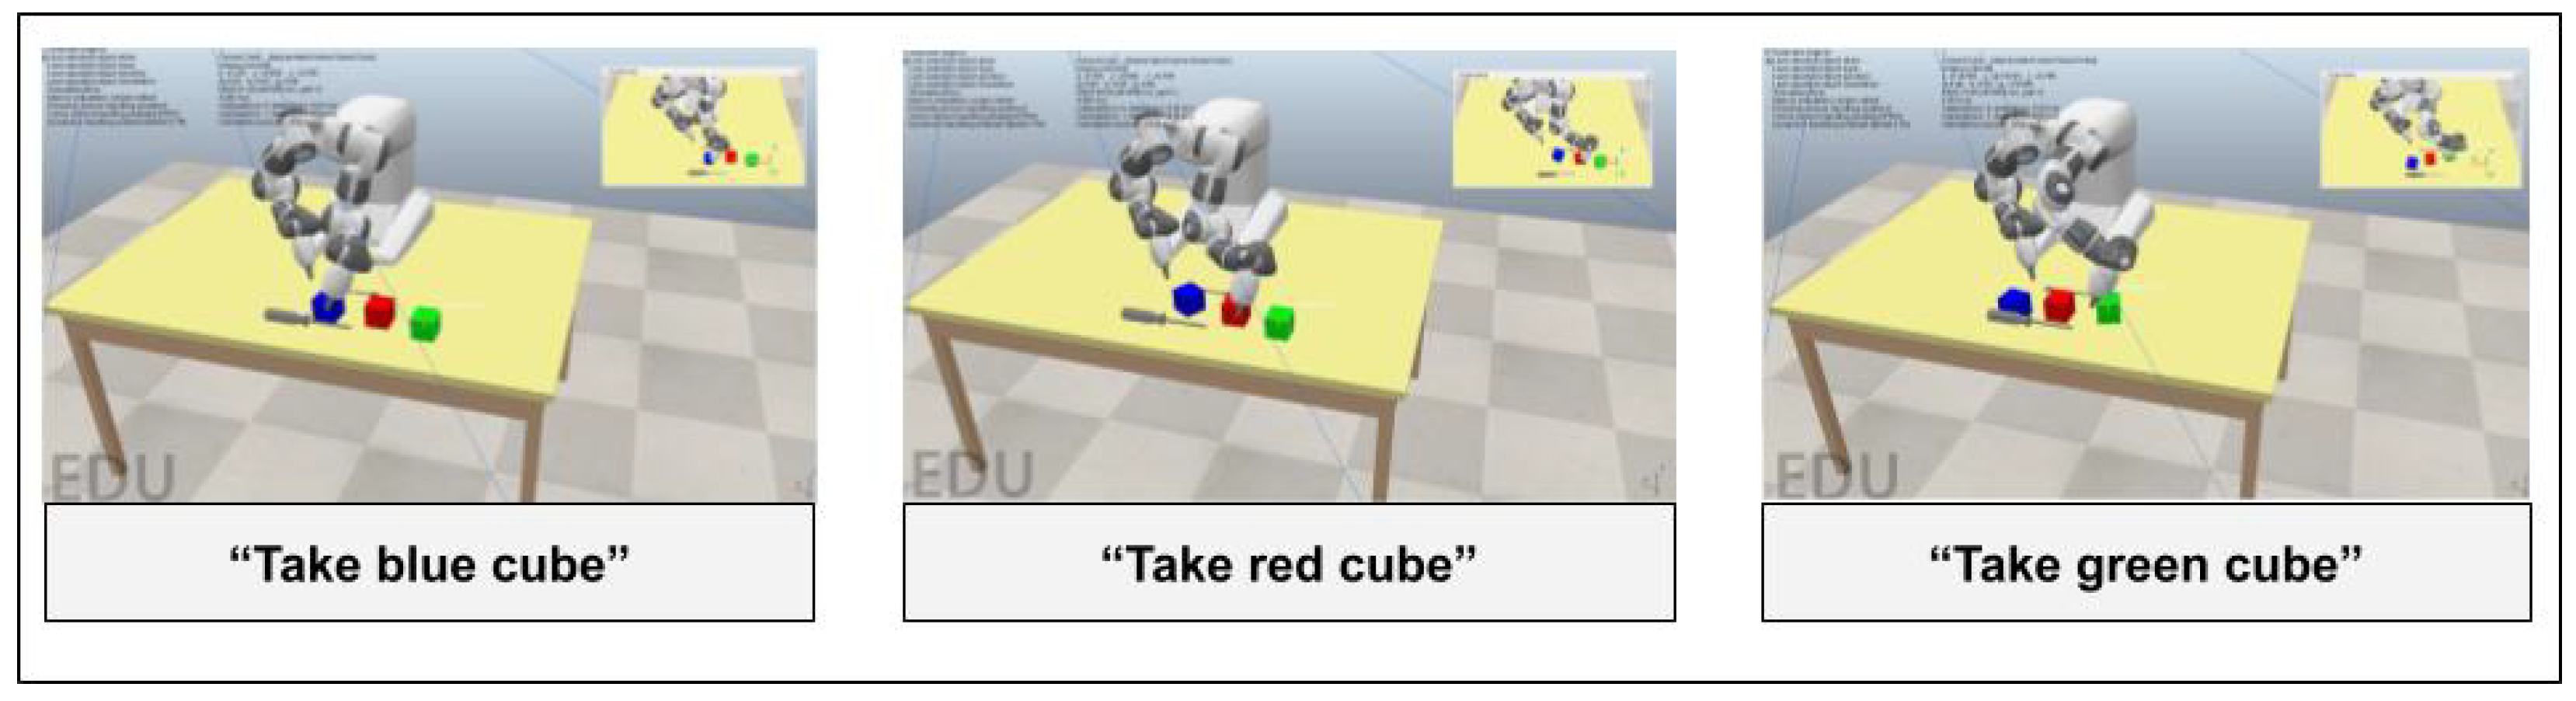
, and no commands were rejected by the confidence gate. Representative execution snapshots under baseline conditions for each of the three target objects are shown in
Figure 5.
6.2. Effect of Auditory Degradation
The full accuracy results over all the experimental conditions and system configurations are presented in
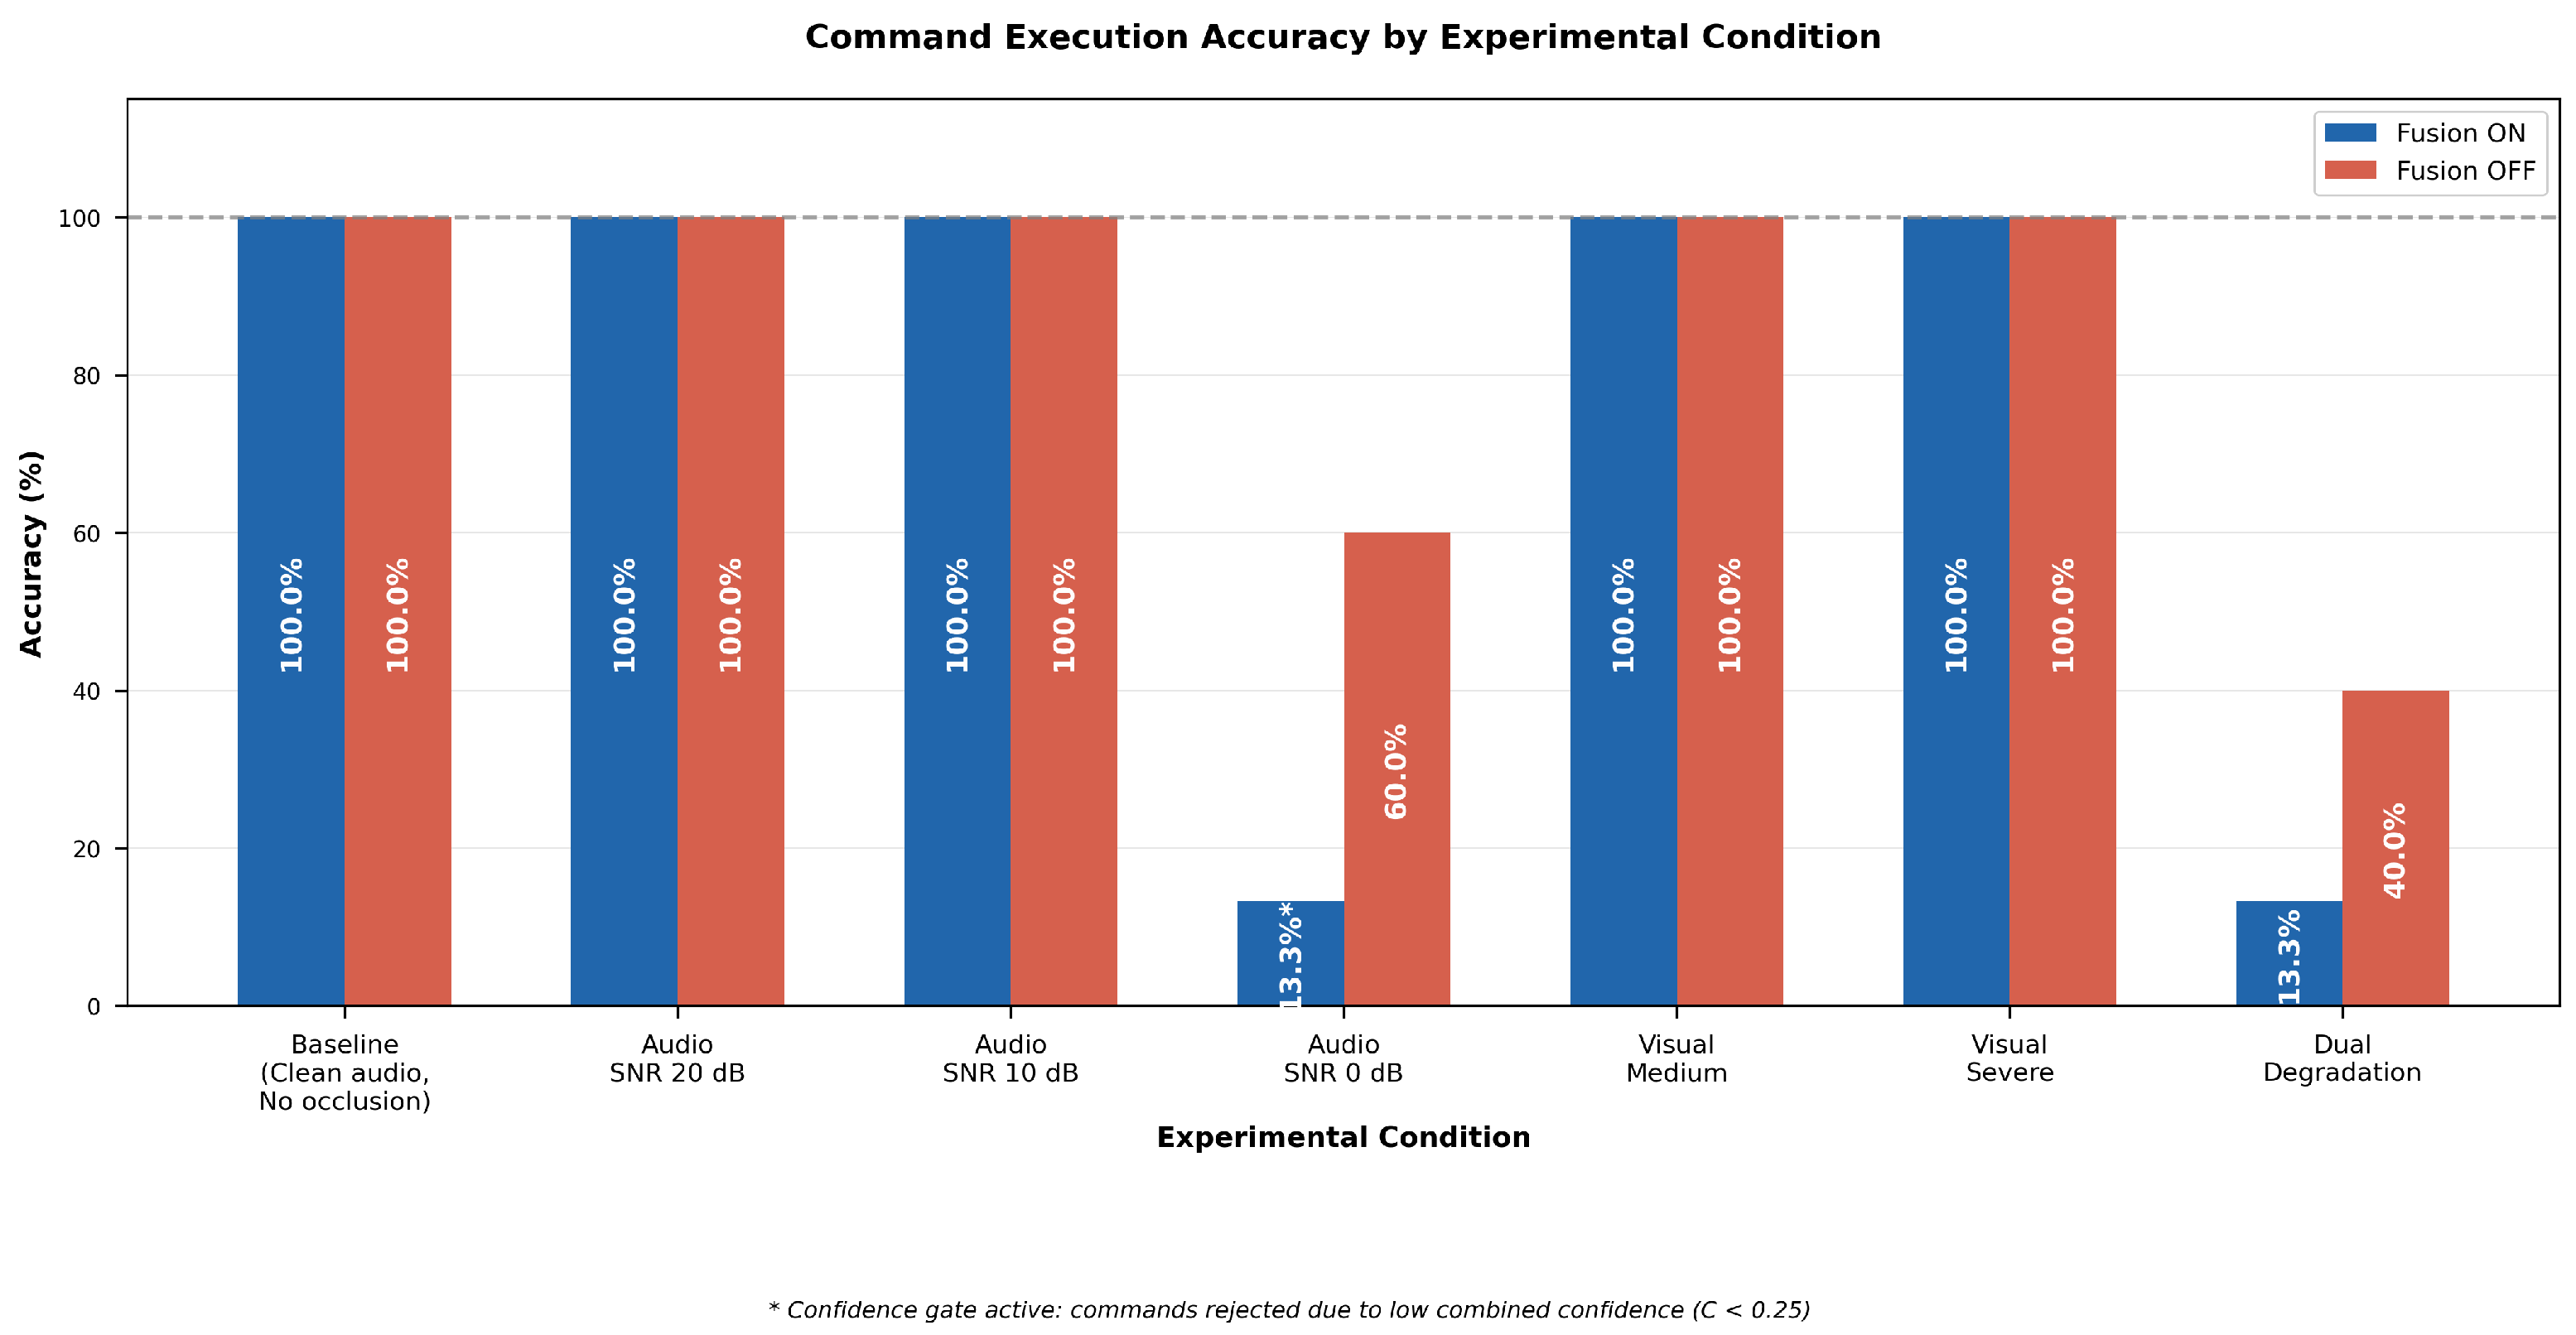
Table 5. The results are presented as grouped bar charts in
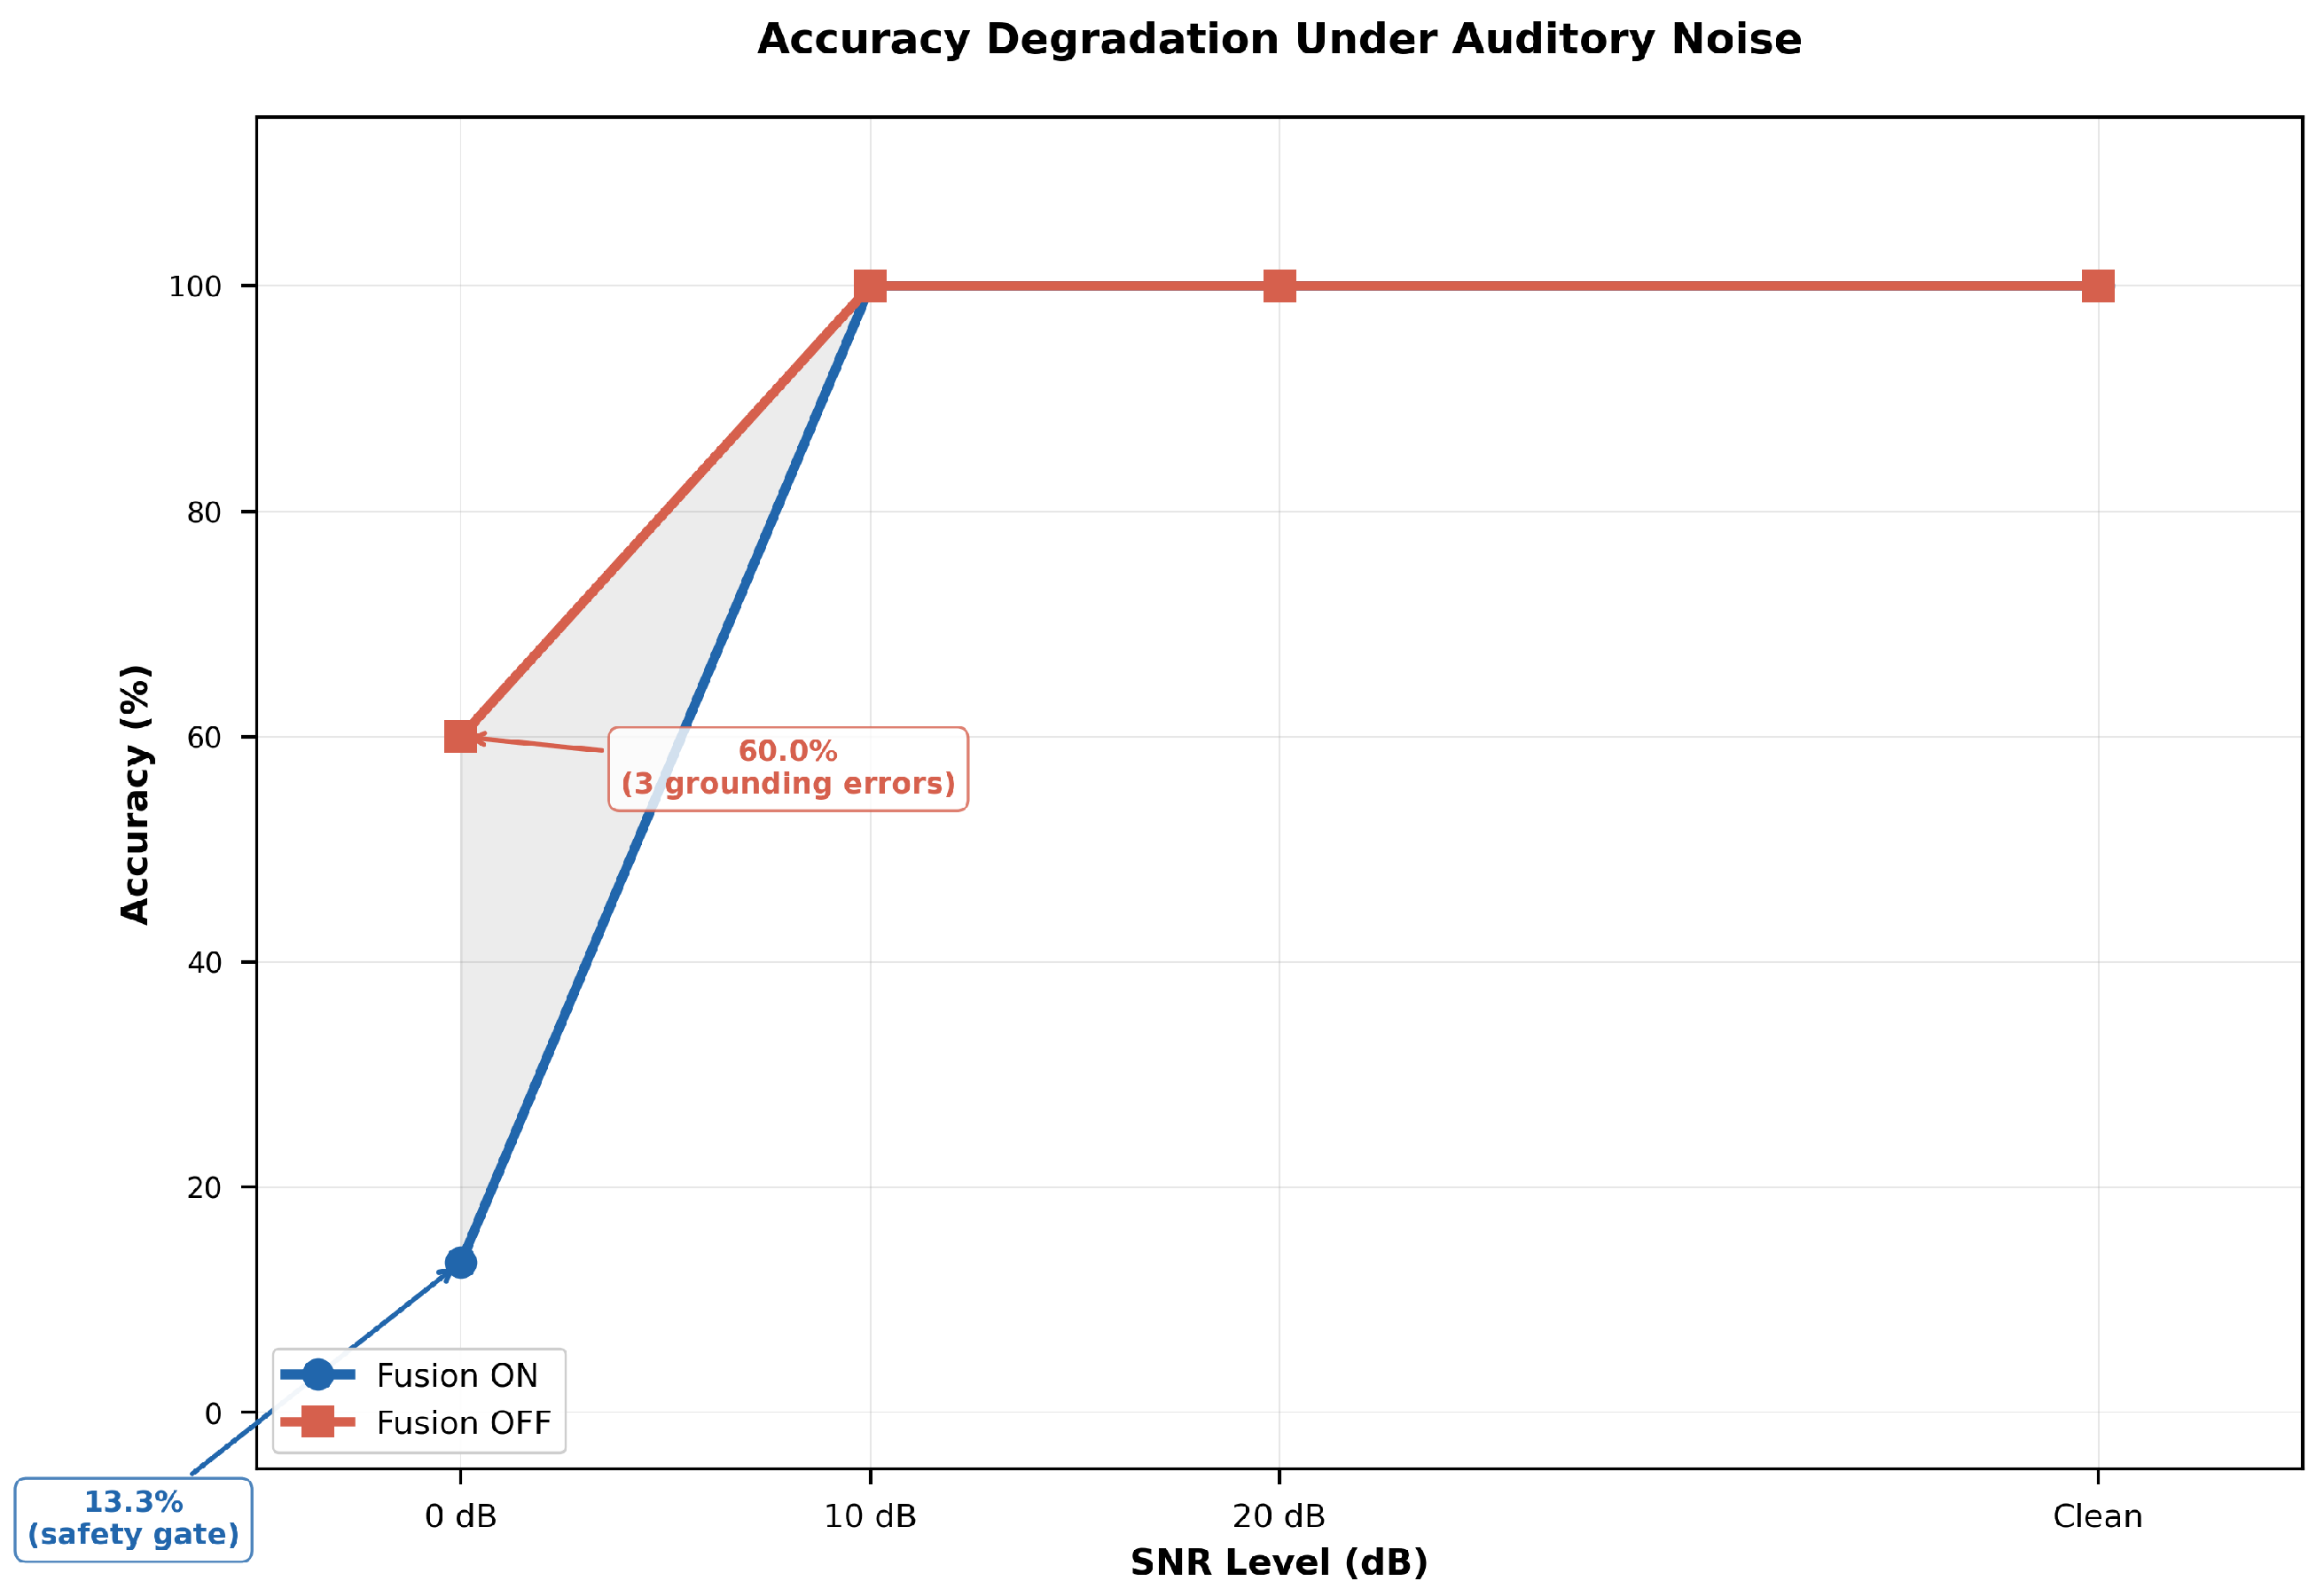
Figure 6 and the accuracy degradation curve for the auditory channel only is shown in
Figure 7.
Under mild auditory degradation (C2, SNR 20 dB), both Fusion ON and Fusion OFF maintained 100% accuracy. At moderate degradation (C3, SNR 10 dB), this finding suggests that, at these noise levels, Whisper ASR produces reliable enough transcriptions to allow the LLM to resolve the correct target object, regardless of whether the fusion weights are adaptive or fixed. The mean values decreased progressively from 0.796 at SNR 20 dB to 0.753 at SNR 10 dB, indicating that the fusion module detected the progressive degradation and adjusted the weights accordingly even when the downstream accuracy was not affected yet.
In the case of severe auditory degradation (C4, SNR 0 dB), the two configurations differ significantly. Fusion ON achieved 13.3% accuracy (2/15 commands), whereas Fusion OFF achieved 60.0% accuracy (9/15 commands). This counter-intuitive result is worthy of careful interpretation. With Fusion ON, the combined confidence C was below for 13 of 15 commands, which were rejected by the confidence gate before reaching the language model. These rejections are considered as failures in the accuracy metric. For Fusion OFF, the fixed weights resulted in higher C in some frames and thus more commands passing the gate. However, three of the commands that Fusion OFF attempted to run returned grounding errors, in which the system chose the wrong object to play with and played with it. Fusion ON, on the other hand, had no grounding errors in all 210 executions. This distinction is crucial for safety assessment in an industrial environment: conservative abstention is preferable to active incorrect manipulation.
6.3. Effect of Visual Degradation
Under isolated visual degradation with clean audio (C5 and C6), Fusion ON and Fusion OFF achieved 100% accuracy regardless of the severity of the degradation. Under these conditions, the fusion module assigned to 0.850 for both visual degradation levels, effectively routing the grounding decision through the clean audio channel.
The result shows that our framework can degrade gracefully when only one modality is corrupted; the fusion engine correctly recognizes the reliable channel and puts the weight on it, while the executor can retrieve the object coordinates from visual detections even with lower confidence.
6.4. Effect of Dual Degradation
Meanwhile, with both channels severely degraded (C7, SNR 0 dB + visual severe), Fusion ON obtains 13.3% accuracy and zero grounding errors, versus 40.0% and five grounding errors with Fusion OFF. The mean fusion weights under C7 were and , indicative of a forced equilibrium where neither modality is of high enough quality to take over.
In 13 out of 15 commands, the combined confidence C fell below under Fusion ON, and in all cases, this triggered the safety gate. This behavior implements the dual degradation safety scenario: the system does not take an action that has uncertain grounding and implicitly asks the operator for confirmation.
6.5. Adaptive Fusion Weight Behaviour
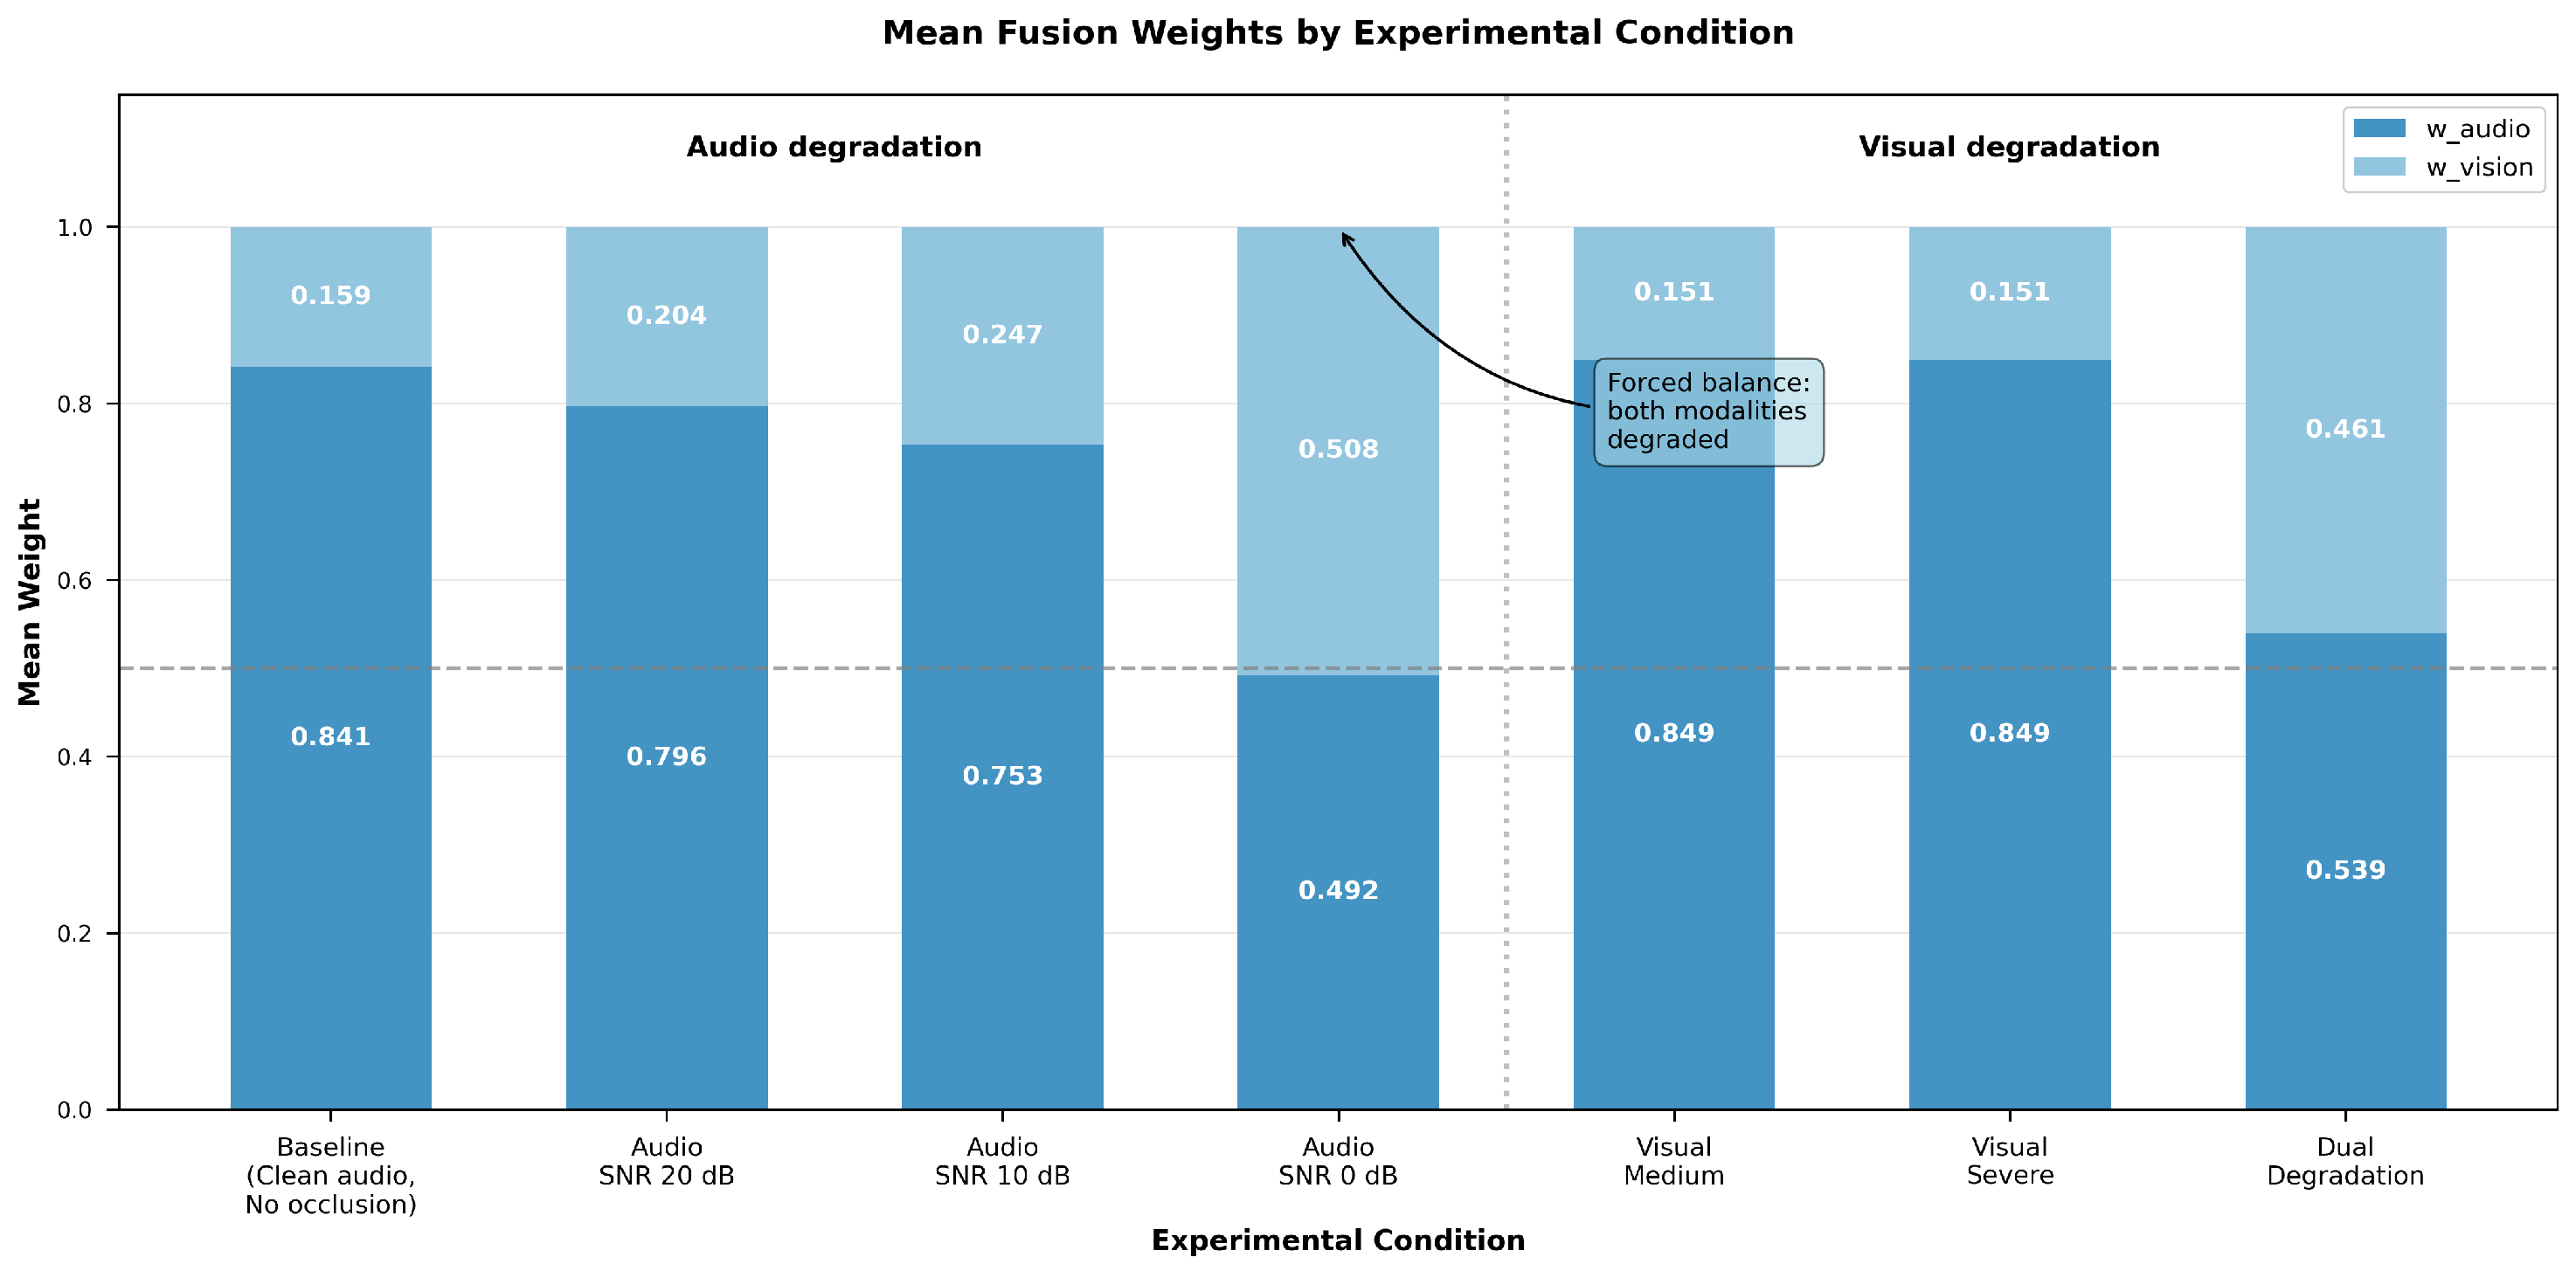
Figure 8 shows the mean fusion weights
and
per condition under the Fusion ON configuration.The figure shows three regions, with different behavior in each. For clean conditions and mild or moderate auditory degradation (C1, C2, C3), and for visual degradation of any severity (C5, C6), the audio channel dominates with
. This is consistent with the high confidence of the ASR and the low token uncertainty when the audio is not severely degraded.
For the case of severe audio degradation in isolation (C4), the weights converge to equilibrium (, ) which indicates that the fusion engine correctly detects the degraded audio and shifts reliance to the visual channel.
In dual degradation (C7), the weights settle around , in line with the forced balance when neither modality is reliable. This progressive and bidirectional adaptation proves that the confidence-weighted fusion module responds correctly to each degradation scenario without manual intervention.
6.6. Summary
Table 5 and
Figure 6,
Figure 7 and
Figure 8 jointly show three important results. First, the adaptive fusion module does not cause any performance loss in favorable conditions: both configurations reach the same accuracy from C1 to C3 and from C5 to C6. Second, under severe unimodal or dual degradation, the key differentiator between the two configurations is not raw accuracy but error type: Fusion ON produces exclusively conservative abstentions (zero grounding errors across 210 executions), while Fusion OFF produces active incorrect manipulations (eight grounding errors total across C4 and C7).
Third, in
Figure 8, the weight trajectories for the fusion demonstrate that the adaptive behavior is continuous and proportional to the signal quality and not a binary switch, which confirms the design rationale presented in
Section 4.
7. Discussion
The experimental results in
Section 6 raise three questions that need to be properly interpreted within the framework of human–cobot cooperation in Industry 5.0: the safety–accuracy dilemma that is seen in case of high degradation, the asymmetric robustness of the auditory and visual modality channels, and the relevance of an interpretable fusion method in industry.
The results should be interpreted within the context of the current study, which involved a fully simulated station, a single operator, and three differently colored target objects. The implications for generalizability are discussed in the following sections.
7.1. Safety–Accuracy Trade-Off Under Severe Degradation
The most interesting result is the apparent accuracy inversion at SNR 0 dB, where Fusion ON achieves 13.3% and Fusion OFF achieves 60.0%. At first blush, one might be tempted to conclude that the fixed-weight baseline is better than the adaptive system. But this interpretation conflates two very different modes of failure.
Fusion ON results in only conservative abstentions—the confidence gate blocks commands before reaching the language model, and the robot stays in place. Fusion OFF generates active erroneous manipulations—three grounding failures in C4 and five in C7—in which the robot selects and attempts to manipulate the wrong object with high reported confidence. In an industrial assembly environment, an incorrect manipulation can damage components, disrupt production sequences or compromise the operator safety.
Considering only the subset of commands that each configuration was able to execute during the simulation (i.e., not including commands that were rejected by the confidence gate), the error rate for Fusion OFF among the attempted executions was 25% (3/12) under C4 and 45.5% (5/11) under C7, compared to a 0% error rate for Fusion ON under both conditions. These results demonstrate that, although Fusion OFF has a higher nominal accuracy, almost one in two of the active decisions under dual degradation was wrong.
We found the confidence gate threshold to be an effective separator of reliable from unreliable fusion decisions. Under clean and mildly degraded conditions, C was always greater than 0.40 and no valid commands were rejected. Under severe degradation, C fell below 0.20 in most frames and the gate fired appropriately.
We empirically show that, at , the separation is robust for the three-object workspace considered here. However, whether it can be extended to larger or more complex workspaces with a larger number of object classes and more perceptual ambiguity remains an open question. A systematic sensitivity analysis of over workspace configurations of increasing complexity is identified as a direct direction for future work.
7.2. Asymmetric Robustness Between Modalities
An interesting result is the asymmetry of degradation between audio and visual. Both setups kept 100% accuracy for any degree of isolated visual degradation (C5, C6) because the clean audio channel alone provided sufficient grounding information. In the case of isolated severe audio degradation (C4), neither configuration was able to maintain high accuracy, albeit for different reasons discussed above.
This asymmetry reflects the relative amount of information offered by each modality with respect to the current task: in a three-object workspace with color-distinct targets, a single transcribed color word (“red”, “green”, “blue”) is sufficient to uniquely identify the target object, while visual grounding alone is less discriminative under the noise levels induced in C4 as YOLO’s detection confidence degraded significantly. This suggests that the auditory channel contains a disproportionate amount of disambiguating information for color-based object selection tasks, and future work should investigate workspaces where visual context is more important for disambiguation, for example, environments with objects that are similar in color but different in geometry or spatial arrangement.
7.3. Interpretability as a Design Principle
We chose the heuristic formulation of the fusion module: linear quality scores, temperature-scaled softmax and hard clipping, in a deliberate fashion over a learned gating network. The experimental results justify this choice from an operational point of view: all the fusion decisions taken in the 210 executions are fully traceable to their contributing quality signals and hyperparameters. With a given command, an operator or a safety auditor can look at the published , and C that produced the decision, and can reconstruct exactly why the system preferred one modality or rejected the command entirely.
This interpretability is visually confirmed in
Figure 8: the progressive transition from audio dominance to equilibrium as the SNR goes from clean to 0 dB is smooth, proportional, and physically interpretable without reference to internal model states. Here the gating behavior is transparent, whereas a multi-layer perceptron fusion network would present an opaque gating behavior under the same conditions.
7.4. Limitations
Some limitations of the present study should be noted. The evaluation was first performed in a fully simulated environment with a fixed three-object workspace. While the feed provided by CoppeliaSim is visually realistic enough to test the perception and fusion pipeline, the sim-to-real gap is not quantified. Further validation of the performance of the framework outside the simulation is needed with physical robot experiments with real-world acoustic noise and natural lighting variation.
In addition, the command set consisted of 15 utterances by one operator. Speaker variability, such as different accent, speech rate, and microphone placement, can affect the confidence of the Whisper transcription and the audio quality signals used by the fusion module. A multi-speaker evaluation is needed to assess generalizability to diverse operator populations.
However, the visual degradation protocol used synthetic transformations (blur, brightness reduction, central occlusion) rather than physically realistic occlusions such as moving obstacles or changing lighting conditions. These degradations are methodologically controlled and reproducible, but may not reflect the complexity of real industrial visual interference.
Finally, the hyperparameters of the fusion module (, , T, , , ) were chosen empirically for the current workspace. Their sensitivity to changes in workspace complexity, number of objects, and perceptual difficulty has not been systematically characterized.
7.5. Future Work
The fusion module and task complexity are the most immediate extensions. We will replace the heuristic weight formulation presented here with a learned multimodal fusion model trained on a robust degradation dataset representative of real industrial environments, moving beyond fixed hyperparameters toward a fusion policy that adapts to the statistical structure of each deployment context. At the same time, the command vocabulary will be extended from simple object selection to structured assembly instructions that involve sequential manipulation and spatial relations between components, thus stress-testing the LLM grounding stage under referential ambiguity conditions that the current three-object workspace cannot induce.
Two further extensions concern the discriminatory requirement imposed by each modality. For future evaluations, the colored objects used here will be replaced by sets of perceptually similar colors (e.g., red, purple, pink) that require the system to rely on finer visual cues and spatial reasoning rather than a single dominant color cue, as well as tools rather than objects such as cubes. The influence of the microphone type, voice timbre, and recording distance on the transcription confidence will also be systematically analyzed at the acoustic level as a complement to the assessment of multiple speakers, and will characterize how these acoustic factors propagate within the fusion module.
The longer-term roadmap addresses physical deployment and operator health. The transfer of the framework to the real YuMi platform will quantify the sim-to-real gap in the perception pipeline and the ZMQ control architecture under real-world acoustic and lighting conditions. Future work will also incorporate cognitive load and fatigue monitoring within the control loop, enabling the system to adjust its interaction modality and confirmation thresholds based on the operator’s physiological state, thus closing the loop between the digital twin and the human operator that this work places at the center of the architecture, in line with the human-centric mandate of Industry 5.0.
8. Conclusions
In this paper, a multimodal digital twin approach to operator-centered collaboration between humans and cobots in virtual assembly was proposed by taking two significant steps into account, namely, a Confidence-Weighted Late Fusion module that dynamically adjusts modality dependence based on the quality of perception signal and an LLM-powered Reference Resolver module that contextualizes the ambiguous commands of natural language in the current scene and fusion scores.
The experimental evaluation on 210 executions and seven degradation conditions established three main conclusions. The adaptive fusion module does not introduce performance overhead under favorable or mildly degraded conditions: both adaptive and fixed-weight configurations achieved 100% accuracy from baseline through SNR 10 dB and across all isolated visual degradation levels. Under severe sensory degradation, the critical differentiator is not accuracy but error type: the adaptive system produced zero grounding errors across all 210 executions by activating a confidence gate that abstains from unsafe actions, while the fixed-weight baseline produced eight active incorrect manipulations. Fusion weight dynamics have verified that the adaptability of the module exhibits continuous, proportional, and physically plausible characteristics. In all 210 trials, the LLM-enhanced Reference Resolver was successful in resolving referential instructions every time it passed through the confidence gate, thus proving that grounding of natural language both visually and in terms of fusion weights works well for selecting objects in cases of uncertainty.
These results demonstrate that Confidence-Weighted Late Fusion is an effective strategy for building resilient human–cobot interfaces that degrade gracefully rather than failing catastrophically under adverse industrial conditions. The fully simulated and version-controlled implementation provides a reproducible benchmark against which future multimodal fusion approaches—including learned gating networks and cross-modal attention mechanisms—can be directly evaluated.




 ,


 tables. The authors have reviewed and edited the output and take full responsibility for the content of this publication.