


Abstract
The main focus of this paper is to introduce an algorithm that enhances the outcomes of multiple-attribute decision making by harnessing the adaptability of interval-valued intuitionistic fuzzy () sets (s). This algorithm utilizes numbers (s) to represent attribute values and attribute weights, enabling the decision maker to account for the intricate nuances and uncertainties that are inherent in the decision-making process. We introduce a novel generalized score function () designed to overcome the limitations of previous functions. This function incorporates two parameters, denoted as with . The core concept of this algorithm centers around the computation of the p-distance for each alternative relative to the positive ideal alternative. The p-distance is derived from the p-norm associated with each alternative’s score matrix, providing the decision maker () with a tool to rank the available alternatives. Various examples are given to demonstrate the practicality and effectiveness of the proposed algorithm. Additionally, we apply the algorithm to a real event-based multiple-attribute decision-making () problem—the investment company problem—to identify the optimal alternatives through a comparative analysis.
1. Introduction
With the continuous advancement of science and technology and the development of society, fuzzy set theory [1] and its various extensions in managing complexity and uncertainty in research problems have become increasingly apparent. Nevertheless, s often encounter difficulties when attempting to express their opinions solely through membership degrees. This challenge arises due to the presence of positive indeterminacy in some decision-related information, and thus requires a more comprehensive means of accurately conveying their perspectives. To address this hardship, Atanassov [2] introduced “intuitionistic fuzzy sets” (s), which offer a more flexible and robust framework for computing such information. This framework was further developed by Atanassov and Gargov [3] into an “” theory. In this theory, an element’s representation incorporates interval numbers for three different degrees—membership, non-membership, and indeterminacy—rather than relying on crisp numbers. Consequently, this theory has found extensive practical applications in the development of decision-making techniques for solving “” problems, as indicated in references [4,5,6,7] and the literature cited therein. This underscores the notion that the theory provides a more nuanced and advanced framework for handling decision-making scenarios characterized by high levels of uncertainty and imprecision.
1.1. Review of Existing Studies
The initial section of the literature review is dedicated to the examination of commonly employed score functions (s) and accuracy functions (s) [4,7,8,9,10,11,12,13,14,15] utilized for assessing the performance of interval-valued intuitionistic fuzzy numbers. Subsequently, the review delves into various modern approaches for multiple-attribute group decision making () within the context of s. Garg [4] developed an entropy-based algorithm by introducing a generalized, improved score function for s. Kumar and Kumar [6] designed an algorithm by using a game model and a new order function for s. Kumar and Chen [16] presented a new procedure in the present framework with the help of set pair analysis (). Chen and Tsai [7] constructed a novel of values. Thereafter, they developed solution steps for problems by using the mean and the variance of the computed score matrix. Wang et al. [17] offered a new Jenson–Shannon divergence measure operator for constructing a novel algorithm. Ohlan [18] built up a new in the domain by utilizing the entropy measure. Senapati et al. [19] proposed Aczel–Alsina operations based , in which they created various Aczel–Alsina geometric operators. Shen et al. [20] used the concept of the partial connection number of for decision making with s. Patra [21] introduced a new technique, which is based on the probability density function of . This technique defeats many delusions in the existing method [22]. Shi et al. [23] extended the power aggregation operators with Aczel–Alsina t-norm and t-conorm for “interval-valued Atanassov–intuitionistic fuzzy sets” in order to propose the method. Zhong et al. [24] developed various operators for s in the context of Dempster–Shafer theory to introduce a new decision-making method. Chen and Hsu [25] developed a weight- determining algorithm in five steps for handling problems based on a new and a nonlinear optimization model.
1.2. Motivation and a Brief Overview of the Present Research
After carefully reviewing the above literature, we have identified the following as the main issues in the theory:
- (1)
- Numerous methods ([7,16,26,27]; see Section 5 for more details) discussed in the existing literature exhibit several notable shortcomings. The shortcomings, presented in the methods [7,16,26,27], include (i) division by zero and (ii) avoiding Definition 4. As a result, these methodologies fall short in delivering an equitable and rational ranking order for the diverse array of alternatives under consideration.
- (2)
- There is an unequivocal necessity for an efficient and appropriate score function tailored to s, which can consistently and reliably manage comparable and incomparable decision data.
This makes it difficult to accurately order and prioritize these types of data. So, the present study has two main objectives. Firstly, we contrive a new for s and its constructive properties. This new function has several advantages over previous ones, as it not only allows for reasonable comparisons of two or more s, but also conquers the limitations of past s. This function involves an unknown portion of the s and two regulator parameters, and (), with . Furthermore, we demonstrate the preference of this function through various numerical examples. Secondly, an algorithm was developed for using s. The essence of this algorithm is to determine the p-distance corresponding to each alternative from the positive ideal alternative. To identify the finest alternative(s) based on p-distance, the p-distances are calculated for each alternative score matrix (a row matrix that corresponds to an alternative in which entries are score values of attribute values). The p-distances are then provided a preference order () of alternatives. The Python code for this algorithm is also given. Several examples are provided to illustrate the practicality and advantage of the proposed work. Finally, by applying the proposed algorithm, we find the most suitable investment company from a given set of companies.
1.3. Key Contributions and Organizing Structure
This paper presents the following noteworthy contributions:
- (1)
- We introduce a for s with robust properties. This function incorporates the concept of the unknown portion of an and two flexible parameters, and , where and . The advantage of these parameters is that varying their values can aid in ordering alternatives.
- (2)
- Several numerical examples are provided to demonstrate the usefulness, effectiveness, and credibility of the that was formulated.
- (3)
- We develop an algorithm to provide a comprehensive solution to decision-making problems by incorporating the p-distance and the proposed .
- (4)
- We showcase the effectiveness of the proposed algorithm by presenting multiple numerical examples. Additionally, our algorithm is used to identify the best investment company.
The remaining format of this paper is as follows:
2. Preliminaries
In this section, we delve into the intricacies of s and s together with their associated operations. Furthermore, we discuss the various s and s that have been developed in this context. A list of abbreviations used throughout the paper is listed in Table 1.
Table 1.
List of Abbreviations.
Definition 1
([2]). An I on a fixed set X is given as
where are, respectively, the functions of membership and non-membership with . For each , the degree of hesitation is defined by
Definition 2
([3]). An on a fixed set X is stated as
where are, respectively, the functions of membership and non-membership with . The set is the set of all closed and bounded subintervals of . Thus, and are represented by interval numbers for each .
The elements of set are called s. For ease of use, here, an is denoted by where and .
The interval of hesitation () relative to an is given as
Remark 1.
The following cases are obtained from the Definition 2.
- (i)
- If and in , then reduces to an intuitionistic fuzzy number ().
- (ii)
- If and , then reduces to a fuzzy number ().
- (iii)
- If and in , then reduces to an interval value fuzzy number ().
Definition 3
([3]). For and , the following arithmetic operations are given as
- (i)
- ,
- (ii)
- ,
- (iii)
- ,
- (iv)
- ,
- (v)
- ;
Definition 4
([8]). For and , if the relations , and , hold. Here, the symbol “≻” represents the relation ”.
Definition 5
([28]). Let be the n-dimensional Euclidean space. Then, for any , the p-norm of x, denoted by , is defined as
By using p-norm, the p- distance between x and y, denoted by , is obtained as
where .
Definition 6.
For an , the mathematical expressions for certain existing score and accuracy functions are given as follows:
- The score and accuracy functions, proposed by Xu [8], areand
- The accuracy function, proposed by Ye [9], is
- The accuracy function, proposed by Nayagam et al. [10], is
- The score function, proposed by Bai [11], is
- The score function, proposed by Garg [4], iswhere
- The score function, proposed by Nayagam et al. [12], is
- The score function, proposed by Selvaraj and Majumdar [13], is
- The score function proposed by Chen and Tsai [14] is
- The score function, proposed by Chen and Yu [15], is
After reviewing the existing ranking functions, s require a new score function for s that not only ranks two or more considered fuzzy numbers effectively but also overcomes the limitations of the existing ones. The formulation of this new score function is presented in the next section.
3. A Novel for s with Robust Properties: A Generalized Approach
This section is partitioned into three subsections, each focusing on a different aspect related to comparing s. In the first subsection, we highlight some of the limitations of existing s and s commonly used for this purpose. Moving on to the second subsection, we introduce a novel that overcomes these limitations and provides an effective method for comparing two or more s. This function possesses certain properties that make it most desirable for this type of analysis. In the third subsection, we demonstrate the primacy of the new by showcasing its many advantages over the existing ones.
3.1. Shortcomings of Many Existing Score and Accuracy Functions
The aim of this subsection is to present the limitations of the existing score and accuracy functions, as defined in Definition 6, through the following numerical examples. These examples show that they often fail to effectively distinguish or compare two or more s. This underscores the necessity of developing more reliable measures to enhance decision-making accuracy under environment.
Example 1.
Consider two s and . The resultant values are given as
- The functions and give the values and .
- The function produces .
Example 2.
Consider the information in terms of two s, and .
- The function gives the values .
- The computed values are .
Example 3.
Suppose that two decision information sets are given as and .
- The function gives .
- The function presents .
- The function provides .
Example 4.
Consider two s and . For and , the computed values of function are .
Example 5.
Consider the s and . Different s and s are applied to these numbers to obtain various values.
- The and functions result in and , respectively.
- The function produces .
- The function yields .
- The function gives . The function yields .
- The function produces .
Example 6.
Consider two alternatives under the domain— and . The function values are .
Example 7.
Let and be two numbers in the context. The function values are .
Example 8.
Consider two s and . The function values are .
Example 9.
In a decision process, two alternatives are given as and .
- The functions and yield and , respectively.
- The function yields .
- The function gives .
- The function produces .
Hence, from the above-explained examples, it indicates that the existing s are sometimes quite unable to provide a ranking order between and .
3.2. Novel for s
Keeping the above irregularities presented in score functions in view, the requires a robust score function to measure s, which works smoothly and effectively.
Definition 7.
Suppose is an . Then, by using the unknown degree, a new is defined by
where and .
Definition 8.
For s and , if for all .
Proposition 1.
If an reduces to an , i.e., and then .
Proposition 2.
If an reduces to a , i.e., and then .
Proposition 3.
If an reduces to an , i.e., and then .
Proposition 4.
If is the largest , then .
Proposition 5.
For the smallest , the value of the .
Theorem 1.
Let and be two s. If , i.e., , and , then
Proof.
For the given and , Formula (1) takes the following form:
and
respectively. Now, we calculate the following difference:
The given inequalities and yield the results and . Again, the inequalities and yield the results and . Thus we get
Adding (3) and (4), we have
Similarly, we can derive the following inequalities
These inequalities give
Utilizing (5) and (6), the difference (2) becomes
□
Theorem 2.
For an arbitrary , the proposed increases monotonically with ε and ϑ, and decreases monotonically with ϱ and φ.
Proof.
Let and be two s where
Assuming that
and
The inequalities and with yield the following results
Using (7) and (8), we get , whenever and . It proves that the is a monotonically increasing function with respect to and .
In a similar manner, it can be proved that the is a monotonically decreasing function with respect to and . □
Theorem 3.
Let be an arbitrary , then
Proof.
From the expression (1),
By Theorem 2, for a given value of and , is a monotonically increasing function with respect to and .
Consequently, for , we get
By Theorem 2, for a given value of and , is a monotonically decreasing function with respect to and .
Theorem 4.
Let , and be three s. If then .
Proof.
Using Definition 3, the following results are found as
It is given that . By using Definition 4, we get
The relations in (13), give the following:
This gives
Also, we have
Suppose that
Using Theorem 1 and (16), the results (14) and (15), lead to the following inequality:
Using (1) and (12), the inequality (17) becomes . □
Theorem 5.
Let , and be three s. If then .
Proof.
The proof follows a similar logic presented in Theorem 4. □
3.3. Championing the Significance of the Novel
To describe the advantages of the proposed function, we recalculate the examples mentioned in Section 3.1 and discuss their results in Table 2.
Table 2.
The computed s for Examples 1–9.
After a thorough examination of the results in Table 2, it becomes clear that the suggested offers a valuable means of appraising the effectiveness of decision-making information.
4. Algorithm for Based on Proposed and -Distance
For a better presentation, we split this section into three subsections—(i) formulation of the problem and some auxiliary results for developing a novel algorithm, (ii) novel algorithm steps, (iii) numerical examples.
The details are given below.
4.1. Formulation and Auxiliary Results
This section aims to introduce an algorithm to tackle the current problem, where attribute values are given by s for distinct attributes. The decision-making problem involves sets of alternatives and attributes , and the alternative–attribute matrix is presented in Table 3. Each entry in the matrix, denoted as , represents the rating of the jth attribute in the ith alternative as an .
Table 3.
The alternative–attribute matrix.
The attribute values for ith alternative corresponding to attributes are represented in the following form:
Here, indicates the degree of satisfaction with attribute by alternative , while represents the degree of dissatisfaction with attribute by alternative . It is worth noting that with and , for , . For alternative , the alternative matrix is a row matrix, denoted by of size . It is defined by . The score matrix of this matrix is given by , where . Thus, we can find a row vector from for each i.
If each rating of an alternative is given in terms of an , it is called the positive ideal alternative (). Similarly, if each rating of an alternative is of the form , it is called the negative ideal alternative (). Then, we get the vectors and associated with and , respectively.
Definition 9.
Using Definition 5, the p-distance of relative to , denoted by , is given by
Definition 10.
Let and be the p-distances of the alternatives and relative to , respectively. Then, if .
4.2. A Novel Algorithm for the Current
In the face of complex and uncertain situations, s often grapple with the task of assigning precise numerical weights to available information. To tackle this challenge, a viable approach involves the utilization of s to represent these weights. The following algorithm outlines the steps for implementing this approach:
- Step 1.
- The aim of this step is to build up a normalized decision matrix from the matrix , where
- Step 2.
- This step computes the weighted decision matrix from the matrix and the assigned weight vector , where each is represented by an . The th entry of is given bywhich is obtained by using property (ii) (Definition 3).
- Step 3.
- By utilizing the proposed and the matrix , the score alternative matrix is calculated for each i, where with and .
- Step 4.
- For each , we find a row vector . Then, based on Definition 9 and obtained vectors , we calculate p-distance corresponding to each as follows:
- Step 5.
- Based on Definition 10 and the calculated s, we determine a of alternatives. The smaller the p-distance , the better the of alternative , where .
The step-by-step procedure of the proposed algorithm can be outlined as follows: First, the normalized decision matrix is obtained from the given decision matrix. Next, the weighted normalized decision matrix is constructed, where the attribute weights are expressed in terms of s. In the third step, the alternative score matrix for each alternative is calculated using the proposed together with the weighted normalized decision matrix. Subsequently, a row vector is extracted from each alternative score matrix, and the p-distance between this row vector and the is determined. Finally, the of the alternatives is established based on the computed p-distances. A smaller p-distance indicates a higher preference, meaning that alternative (for ) is ranked higher.
- Benefits and Limitations
Here, some benefits and limitations of the developed algorithm are presented. The benefits are as follows:
- This algorithm provides the solution steps to solve an problem in the context. In such decision-making problems, the expert focuses not only on the behavior of the fuzzy decision matrix (a matrix in which each entry is shown by an ) but also provides attribute weight information in terms of s.
- We calculate a row vector for each alternative score matrix. The advantage of these vectors is that we define a p-distance to check the overall performance of each alternative. Definition 10 states that a small value of the p-distance represents better performance of an alternative in a set of feasible alternatives.
- The proposed is utilized in this algorithm to obtain reasonable decision results. The use of this function permits a sensitivity analysis with respect to the parameter in order to find an effective measure of s.
Some limitations of this approach are given as follows:
- This research avoids group perceptions to provide more realistic decision opinions.
- The used in this algorithm has some limitations for parameter . For , this function does not work effectively. For example, if and and , then . This shows that the function does not provide a for and , even though the two numbers are different from each other.
- The present algorithm can be strengthened by including the concept of the negative ideal alternative ().
- A method will be proposed to determine attribute weights precisely, which will ensure a smoother decision-making process.
4.3. Numerical Examples
The objectives of this subsection are to present-(i) the applicability of the developed algorithm; and (ii) the impact of the p-distance.
Example 10.
This example addresses an problem that involves decision information. The decision matrix for this problem [7] is presented in Table 4.
Table 4.
The decision matrix ().
The steps involved in the algorithm are outlined below.
- Step 1.
- This step is not applicable because each attribute is of the benefit type. Consequently, .
- Step 2.
- According to , the weights for the attributes are given asThen, we calculate the weighted decision matrix , presented in Table 5.Table 5. The weighted decision matrix ().
- Step 3.
- By utilizing the proposed , we construct the score matrix for , presented in Table 6.Table 6. The score matrix ().
- Step 4.
- Utilizing (18), the value for is calculated for , where . The calculated values are
- Step 5.
- Step 4 produces the following sequence:This yields the following:Thus, is the most preferable.
Example 11.
This example addresses an problem that involves decision information. The decision matrix for this problem [7] is presented in Table 7.
Table 7.
The decision matrix ().
The steps involved in the algorithm are outlined below.
- Step 1.
- This step is not applicable because each attribute is of the benefit type. Consequently, .
- Step 2.
- According to , the weights for attributes are given asThen, we calculate the weighted decision matrix , presented in Table 8.Table 8. The weighted decision matrix ().
- Step 3.
- By utilizing the proposed , we construct the score matrix for , presented in Table 9.Table 9. The score matrix ().
- Step 4.
- Utilizing (18), the value for is calculated for where . The calculated values are
- Step 5.
- Step 4 produces the following sequence:This yields the following:Thus, is the most preferable.
Example 12.
This example addresses an problem that involves decision information. The decision matrix for this problem [7] is presented in Table 10.
Table 10.
The decision matrix ().
The steps involved in the algorithm are outlined below.
- Step 1.
- This step is not applicable because each attribute is of the benefit type. Consequently, .
- Step 2.
- According to , the weights for attributes are given asThen, we calculate the weighted decision matrix , presented in Table 11.Table 11. The weighted decision matrix ().
- Step 3.
- By utilizing the proposed , we construct the score matrix for , presented in Table 12.Table 12. The score matrix ().
- Step 4.
- Utilizing (18), the value for is calculated for , where . The calculated values are
- Step 5.
- Step 4 produces the following sequence:This yields the following:Thus, is the most preferable.
Example 13.
This example addresses an problem that involves decision information. The decision matrix for this problem [7] is presented in Table 13.
Table 13.
The decision matrix ().
The steps involved in the algorithm are outlined below.
- Step 1.
- This step is not applicable because each attribute is of the benefit type. Consequently, .
- Step 2.
- According to , the weights for attributes are given asThen, we calculate the weighted decision matrix , as presented in Table 14.Table 14. The weighted decision matrix ().
- Step 3.
- By utilizing the proposed , we construct the score matrix for , as presented in Table 15.Table 15. The score matrix ().
- Step 4.
- Utilizing (18), the value for is calculated for where . The calculated values are
- Step 5.
- Step 4 produces the following sequence:This yields the following:Thus, is the most preferable.
Example 14.
This example addresses an problem that involves decision information. The decision matrix for this problem [7] is presented in Table 16.
Table 16.
The decision matrix ().
The steps involved in the algorithm are outlined below.
- Step 1.
- This step is not applicable because each attribute is of the benefit type. Consequently, .
- Step 2.
- According to , the weights for attributes are given asThen, we calculate the weighted decision matrix , as presented in Table 17.Table 17. The weighted decision matrix ().
- Step 3.
- By utilizing the proposed , we construct the score matrix for , presented in Table 18.Table 18. The score matrix ().
- Step 4.
- Utilizing (18), the value for is calculated for , where . The calculated values are
- Step 5.
- Step 4 produces the following sequence:This yields the following:Hence, each alternative has an equal ranking.
Example 15.
This example addresses an problem that involves decision information. The decision matrix for this problem [21] is presented in Table 19.
Table 19.
The decision matrix ().
The steps involved in the algorithm are outlined below.
- Step 1.
- This step is not applicable because each attribute is of the benefit type. Consequently, .
- Step 2.
- According to , the weights for attributes are given asThen, we calculate the weighted decision matrix , as presented in Table 20.Table 20. The weighted decision matrix ().
- Step 3.
- By utilizing the proposed , we construct the score matrix for , presented in Table 21.Table 21. The score matrix ().
- Step 4.
- Utilizing (18), the value for is calculated for , where . The calculated values are
- Step 5.
- Step 4 produces the following sequence:This yields the following:Thus, is the most preferable.
Example 16.
This example addresses an problem that involves decision information. The decision matrix for this problem [25] is presented in Table 22.
Table 22.
The decision matrix ().
The steps involved in the algorithm are outlined below.
- Step 1.
- This step is not applicable because each attribute is of the benefit type. Consequently, .
- Step 2.
- According to , the weights for attributes are given asThen, we calculate the weighted decision matrix , as presented in Table 23.Table 23. The weighted decision matrix ().
- Step 3.
- By utilizing the proposed , we construct the score matrix for , presented in Table 24.Table 24. The score matrix ().
- Step 4.
- Utilizing (18), the value for is associated with where . The calculated values are
- Step 5.
- Step 4 produces the following sequence:This yields the following:Thus, is the most preferable.
5. Comparisons and Advantages
A comprehensive analysis is conducted to compare the performance of the current approach against existing approaches. The ranking results in Examples 10–16 are obtained from both the existing approaches and the proposed approach, and the results are summarized in the following subsections.
5.1. Comparisons and Advantages with Example 10
- Kumar and Chen [16] presented a connection number-based approach to address an problem. However, their method produced an unreasonable of () for the given data, as the attribute values of and are distinct. To address this issue, Definition 4 is applied, revealing the s of () and () in the pairs and , respectively. These results differed from the calculated ones, rendering the Kumar and Chen method unreliable. In contrast, our proposed method yielded a of () that not only addressed the limitations of the Kumar and Chen method but also justified Definition 4.
- The method in [7] is based on the mean and variance of score matrices for values, while the approach in [25] employs a score function along with a non-linear programming model. The existing methods in [7,25], establish a of (). In harmony with our proposed approach, both s not only adhere to the criteria defined in Definition 4 but also converge on the same top-ranked alternative.
5.2. Comparisons and Advantages with Example 11
- Kumar and Chen [16] developed a connection number-based method for addressing an problem. Kumar and Chen’s approach [16] yielded the () for the given decision problem. However, upon employing Definition 4, it became evident that this method is incapable of providing a consistent . Our proposed algorithm, on the other hand, produced a of (), which satisfies both relationships () and ().
- The ranking ordering yielded by the methods [7,25] corresponds exactly to the ordering produced by our proposed algorithm.
5.3. Comparisons and Advantages with Example 12
- The obtained from Kumar and Chen’s method [16] for the given data is (), which appears unreasonable since the attribute values for these alternatives are distinct. In contrast, our proposed algorithm ranks the alternatives as (), thereby addressing the limitation of Kumar and Chen’s method.
- Chen and Tsai [7] proposed a methodology for solving problems that utilizes the score function of s, along with the mean and variance of the resulting score matrices. The proposed algorithm yields a of (), whereas the existing method [7] produces a of (). Despite the differences, both methods successfully differentiate between the rankings of , and .
5.4. Comparisons and Advantages with Example 13
- Li [26] proposed a nonlinear programming methodology based on the framework to solve problems, where both the ratings of alternatives and the weights of attributes are represented using sets. The method given in [26] suffers from the issue of “division by zero,” rendering it incapable of generating a reliable ranking. However, our proposed algorithm effectively overcomes this shortcoming.
- The methodologies presented in [7,16,25,29,30,31,32,33] are considered for comparison to demonstrate the credibility of our proposed approach. These methods are designed to address problems within the context and are based on various concepts, including the mean and variance, non-linear programming models, probability density functions, U-quadratic distribution, Beta distribution, etc. The proposed algorithm gives the best alternative that is consistent with the alternative obtained from existing methods in [7,16,25,29,30,31,32,33].
5.5. Comparisons and Advantages with Example 14
- To address problems, Li [26] proposed a nonlinear programming methodology based on the framework, while Zhao and Zhang [27] developed a method utilizing an accuracy function and the weighted averaging operator. The existing methods [26,27] are unable to solve this problem due to issue with “division by zero”. However, our proposed algorithm effectively addresses this shortcoming.
- Our proposed algorithm produces the same as that generated by the existing methods outlined in [7,16,25,29,30,31,32,33].
5.6. Comparisons and Advantages with Example 15
- The novel approaches presented in [7,21,22,25,27] are developed within the context, with some methods based on concepts such as probability density functions and z-score decision matrix. Our proposed algorithm yields the same as that produced by the existing methods outlined in [7,21,22,25,27]. While the method suggested by Li [26] is unable to generate the for this problem.
- The above comparisons show the reliability of the proposed algorithm.
5.7. Comparisons and Advantages with Example 16
- Chen and Tsai’s method, as outlined in [7], initially established a of () for the given decision making problem. However, upon a thorough examination of matrix , it became apparent that the attribute values associated with , , and for alternatives and exhibited notable differences. This discrepancy indicated that and should not be considered equal in their ranking. In contrast, our proposed algorithm produced a of (), effectively rectifying the limitation identified in [7].
- Chen and Hsu [25] proposed a method in which attribute weights are determined using a non-linear programming model, and combined with a score function to derive the . The proposed algorithm yields a of (), whereas the existing method [25] produces a of (). Despite the differences, both methods successfully differentiate between the rankings of and .
6. Applicability of Proposed Algorithm
The following example (investment company problem) is considered for showing the applicability of the proposed work in the real world scenarios. The aims to invest money in one of the following alternatives—a car company (), a food company (), a medicine company (), or an arm company (). These alternatives are evaluated based on three attributes—risk analysis (), growth analysis (), and environment impact analysis (). The decision must be made under environment. The decision matrix [4] is given in Table 25.
Table 25.
The decision matrix ().
To make the best investment decision, the must select the optimal alternative(s) based on the given attributes. The following steps can be taken to arrive at the following solution:
- Step 1.
- This step is not applicable because each attribute is of the benefit type. Consequently, .
- Step 2.
- According to , the weights for attributes are given asThen, we calculate the weighted decision matrix , as presented in Table 26.Table 26. The weighted decision matrix ().
- Step 3.
- By utilizing the proposed , we construct the score matrix for , as presented in Table 27.Table 27. The score matrix ().
- Step 4.
- Utilizing (18), the value for is calculated for where . The calculated values are
- Step 5.
- Step 4 produces the following sequence:This yields the following:Thus, is the most preferable.
Comparisons and advantages
In order to test the performance of the developed result over the existing results, we conducted an experiment. From this, the results are summarized in Table 28.
Table 28.
Comparisons with existing approaches.
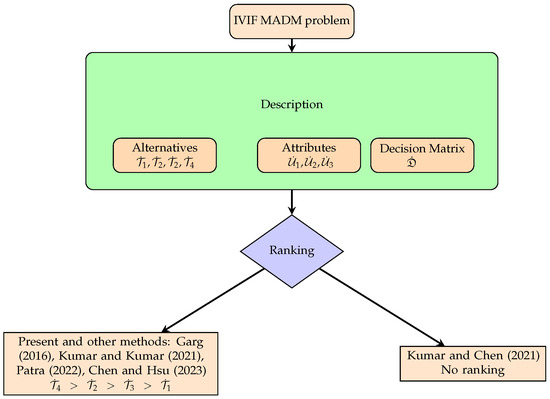
Figure 1.
Comparison of Methods in alternative ranking with other methods: (See Garg (2016) [4], Kumar and Kumar (2021) [6], Patra (2022) [21], Chen and Hsu (2023) [25], Kumar and Chen(2021) [22]).
From Table 28, the important comparison points are listed as follows:
- (i)
- Both kinds (subjective [21,22] and objective [4,6,25]) for describing attribute weight information are used in the approaches given in Table 28 in order to create an effective comparative analysis. However, in the present algorithm, the attribute weight information is subjectively given. But the proposed solution steps are completely different from the steps given in the existing approaches.
- (ii)
- In contrast to Kumar and Chen’s [22] inability to discern a within the given numerical data, the remaining approaches consistently mirror the elucidated by our suggested algorithm. These findings lend credence to the robustness and reliability of the proposed algorithm.
7. Conclusions
7.1. Main Outcomes of the Present Research
The main results of this research are given below:
- (i)
- A was constructed with its robust properties to measure s for solving decision-making problems. The main features of this function are as follows: (a) This function incorporates the degree of uncertainty presented in an ; (b) it contains two flexible parameters, and , with the relation and ; (c) the efficacy of this function was demonstrated through various numerical examples that indicate its preference over the past s.
- (ii)
- An algorithm was contrived for the using the decision framework. This algorithm utilizes the concept of the p-distance of each alternative score matrix relative to the to effectively accomplish the ’s task. The novelties of the algorithm are as follows: (a) it is simple to implement, i.e., the algorithm running time is very short; (b) a program for this algorithm is given in Python to handle the numerical problems smoothly; (c) the p-distance is computed for each alternative, which plays a crucial role in ranking the alternatives.
- (iii)
- The implementation and advantages of the suggested algorithm are demonstrated through numerous comparative examples.
7.2. Management Insights and Computer Software
Some management insights for real event-based problem of the proposed algorithm are given below:
- (i)
- It is effective and flexible to include the p-distance of alternatives to the problems. The use of the values of p-distances cooperates for prioritizing alternatives accurately.
- (ii)
- faces many challenges in assigning precise numerical weights to different attributes due to the complex and uncertain nature of the information. Therefore, in this work, the attribute weights are represented by s.
- (iii)
- A practical problem was successfully modeled and solved by using the proposed algorithm. A comprehensive comparative analysis is also provided to show the advantages of the algorithm.
- (iv)
- To calculate the numerical results accurately, Python software (version 3.12.3) was used throughout this paper. The results are presented in Appendix A.
7.3. Future Scope and Limitations
- (i)
- In future studies, the present algorithm can be used for solving problems in other fuzzy and uncertain environments, such as picture fuzzy and linguistic interval-valued intuitionistic fuzzy contexts.
- (ii)
- To expand its range of applications, the developed algorithm is anticipated to be employed in addressing various other real-world problems, such as the selection of healthcare waste disposal alternatives [34] and the connected autonomous vehicles in real-time traffic management [35].
- (iii)
- The present algorithm can be strengthened by including the concept of the negative ideal alternative ().
- (iv)
- The present algorithm ranks the alternatives in problems only; it can be expanded to solve group decision-making problems.
- (v)
- A method will be proposed to determine attribute weights precisely, ensuring a smoother decision-making process.
Author Contributions
Conceptualization, S.K., S.R.M. and R.T.; methodology, S.K., S.R.M. and R.T.; software, S.K. and R.T.; validation, S.K., S.R.M. and R.T.; formal analysis, S.K., S.R.M. and R.T.; writing—original draft preparation, R.T.; writing—review and editing, S.K., S.R.M. and R.T.; supervision, S.K.; funding acquisition, S.R.M. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported by the Deanship of Scientific Research, Vice Presidency for Graduate Studies and Scientific Research, King Faisal University, Saudi Arabia [Grant No. KFU253312].
Data Availability Statement
Data are contained within the article.
Conflicts of Interest
The authors declare no conflicts of interest.
Appendix A. Python Code
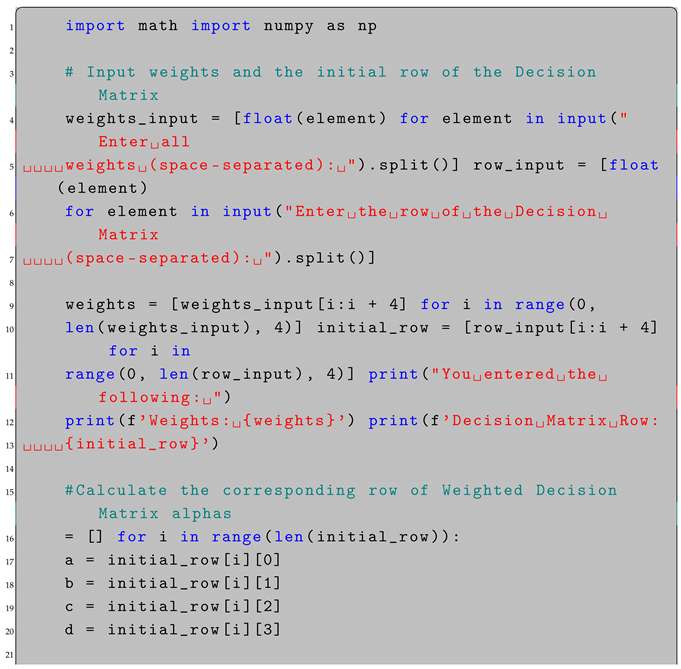
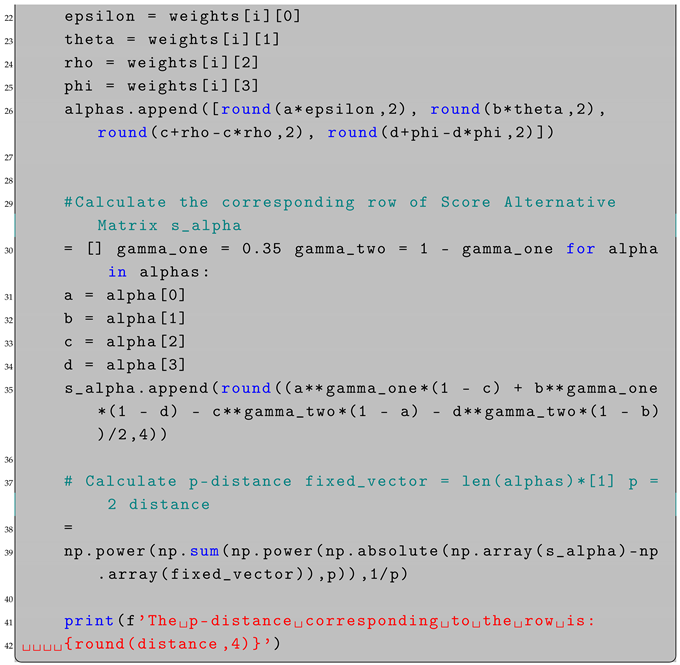
The Python code for calculating rankings from the normalized decision matrix is given as follows:
| Listing A1. Python code. |
  |
References
- Zadeh, L.A. Fuzzy sets. Inf. Control 1965, 8, 338–353. [Google Scholar] [CrossRef] [Scilit]
- Atanassov, K.T. lntuitionistic fuzzy sets. Fuzzy Sets Syst. 1986, 20, 87–96. [Google Scholar] [CrossRef] [Scilit]
- Atanassov, K.; Gargov, G. Interval-valued intuitionistic fuzzy sets. Fuzzy Sets Syst. 1989, 31, 343–349. [Google Scholar] [CrossRef] [Scilit]
- Garg, H. A new generalized improved score function of interval-valued intuitionistic fuzzy sets and applications in expert systems. Appl. Soft Comput. 2016, 38, 988–999. [Google Scholar] [CrossRef] [Scilit]
- Wan, S.; Dong, J. Decision Making Theories and Methods Based on Interval-Valued Intuitionistic Fuzzy Sets; Springer Nature: Singapore, 2020. [Google Scholar]
- Kumar, S.; Kumar, M. A game theoretic approach to solve multiple group decision making problems with interval-valued intuitionistic fuzzy decision matrices. Int. J. Manag. Sci. Eng. Manag. 2021, 16, 34–42. [Google Scholar] [CrossRef] [Scilit]
- Chen, S.-M.; Tsai, C.-A. Multiattribute decision making using novel score function of interval-valued intuitionistic fuzzy values and the means and the variances of score matrices. Inf. Sci. 2021, 577, 748–768. [Google Scholar] [CrossRef] [Scilit]
- Xu, Z.S. Methods for aggregating interval-valued intuitionistic fuzzy information and their application to decision making. Control Decis. 2007, 22, 215–219. [Google Scholar]
- Ye, J. Multicriteria fuzzy decision-making method based on a novel accuracy function under interval-valued intuitionistic fuzzy environment. Expert Syst. Appl. 2009, 36, 6899–6902. [Google Scholar] [CrossRef] [Scilit]
- Nayagam, V.L.G.; Muralikrishnan, S.; Sivaraman, G. Multi-criteria decision-making method based on interval-valued intuitionistic fuzzy sets. Expert Syst. Appl. 2011, 38, 1464–1467. [Google Scholar] [CrossRef] [Scilit]
- Bai, Z.-Y. An interval-valued intuitionistic fuzzy TOPSIS method based on an improved score function. Sci. World J. 2013, 2013, 879089. [Google Scholar] [CrossRef] [Scilit]
- Nayagam, V.L.G.; Jeevaraj, S.; Dhanasekaran, P. An intuitionistic fuzzy multi-criteria decision-making method based on nonhesitance score for interval-valued intuitionistic fuzzy sets. Soft Comput. 2018, 21, 7077–7082. [Google Scholar] [CrossRef] [Scilit]
- Selvaraj, J.; Majumdar, A. A new ranking method for interval-valued intuitionistic fuzzy numbers and its application in multi-criteria decision-making. Mathematics 2021, 9, 2647. [Google Scholar] [CrossRef] [Scilit]
- Chen, S.-M.; Tsai, K.-Y. Multiattribute decision making based on new score function of interval-valued intuitionistic fuzzy values and normalized score matrices. Inf. Sci. 2021, 575, 714–731. [Google Scholar] [CrossRef] [Scilit]
- Chen, S.-M.; Yu, S.-H. Multiattribute decision making based on novel score function and the power operator of interval-valued intuitionistic fuzzy values. Inf. Sci. 2022, 606, 763–785. [Google Scholar] [CrossRef] [Scilit]
- Kumar, K.; Chen, S.M. Multiattribute decision making based on interval-valued intuitionistic fuzzy values, score function of connection numbers, and the set pair analysis theory. Inf. Sci. 2021, 551, 100–112. [Google Scholar] [CrossRef] [Scilit]
- Wang, Z.; Xiao, F.; Ding, W. Interval-valued intuitionistic fuzzy Jenson-Shannon divergence and its application in multi-attribute decision making. Appl. Intell. 2022, 52, 16168–16184. [Google Scholar] [CrossRef] [Scilit]
- Ohlan, A. Novel entropy and distance measures for interval-valued intuitionistic fuzzy sets with application in multi-criteria group decision-making. Int. J. Gen. Syst. 2022, 51, 413–440. [Google Scholar] [CrossRef] [Scilit]
- Senapati, T.; Mesiar, R.; Simic, V.; Iampan, A.; Chinram, R.; Ali, R. Analysis of interval-valued intuitionistic fuzzy Aczel-Alsina geometric aggregation operators and their aplication to multiple attribute decision-making. Axioms 2022, 11, 258. [Google Scholar] [CrossRef] [Scilit]
- Shen, Q.; Zhang, X.; Lou, J.; Liu, Y.; Jiang, Y. Interval-valued intuitionistic fuzzy multi-attribute second-order decision making based on partial connection numbers of set pair analysis. Soft Comput. 2022, 26, 10389–10400. [Google Scholar] [CrossRef] [Scilit]
- Patra, K. An improved ranking method for multi attributes decision making problem based on interval valued intuitionistic fuzzy values. Cybern. Syst. 2022, 54, 648–672. [Google Scholar] [CrossRef] [Scilit]
- Kumar, K.; Chen, S.M. Multiattribute decision making based on converted decision matrices, probability density functions, and interval-valued intuitionistic fuzzy values. Inf. Sci. 2021, 554, 313–324. [Google Scholar] [CrossRef] [Scilit]
- Shi, X.; Ali, Z.; Mahmood, T.; Liu, P. Power aggregation operators of interval-valued Atanassov-intuitionistic fuzzy sets based on Aczel-Alsina t-norm and t-conorm and their applications in decision making. Int. J. Comput. Intell. Syst. 2023, 16, 43. [Google Scholar] [CrossRef] [Scilit]
- Zhong, Y.; Zhang, H.; Cao, L.; Li, Y.; Qin, Y.; Luo, X. Power Muirhead mean operators of interval-valued intuitionistic fuzzy values in the framework of Dempster-Shafer theory for multiple criteria decision-making. Soft Comput. 2023, 27, 763–782. [Google Scholar] [CrossRef] [Scilit]
- Chen, S.M.; Hsu, M.H. Multiple attribute decision making based on novel score function of interval-valued intuitionistic fuzzy values, score matrix, and nonlinear programming model. Inf. Sci. 2023, 645, 119332. [Google Scholar] [CrossRef] [Scilit]
- Li, D.F. TOPSIS-based nonlinear-programming methodology for multiattribute decision making with interval-valued intuitionistic fuzzy sets. IEEE Trans. Fuzzy Syst. 2010, 18, 299–311. [Google Scholar] [CrossRef] [Scilit]
- Zhao, Z.; Zhang, Y. Multiple attribute decision making method in the frame of interval-valued intuitionistic fuzzy sets. In Proceedings of the Eighth International Conference on Fuzzy Systems and Knowledge Discovery, Shanghai, China, 26–28 July 2011; pp. 192–196. [Google Scholar]
- Balakrishnan, A.V. Applied Functional Analysis; Springer: Berlin/Heidelberg, Germany, 1980. [Google Scholar]
- Chen, S.M.; Huang, Z.C. Multiattribute decision making based on interval-valued intuitionistic fuzzy values and linear programming methodology. Inf. Sci. 2017, 381, 341–351. [Google Scholar] [CrossRef] [Scilit]
- Chen, S.M.; Han, W.H. An improved MADM method using interval-valued intuitionistic fuzzy values. Inf. Sci. 2018, 467, 489–505. [Google Scholar] [CrossRef] [Scilit]
- Chen, S.M.; Fan, K.Y. Multiattribute decision making based on probability density functions and the variances and standard deviations of largest ranges of evaluating interval-valued intuitionistic fuzzy values. Inf. Sci. 2019, 490, 329–343. [Google Scholar] [CrossRef] [Scilit]
- Chen, S.M.; Chu, Y.C. Multiattribute decision making based on U-quadratic distribution of intervals and the transformed matrix in interval-valued intuitionistic fuzzy environments. Inf. Sci. 2020, 537, 30–45. [Google Scholar] [CrossRef] [Scilit]
- Chen, S.M.; Liao, W.T. Multiple attribute decision making using Beta distribution of intervals, expected values of intervals, and new score function of interval-valued intuitionistic fuzzy values. Inf. Sci. 2021, 579, 863–887. [Google Scholar] [CrossRef] [Scilit]
- Komal. Archimedean t-norm and t-conorm based intuitionistic fuzzy WASPAS method to evaluate health-care waste disposal alternatives with unknown weight information. Appl. Soft Comput. 2023, 146, 110751. [Google Scholar]
- Gokasar, I.; Pamucar, D.; Deveci, M.; Ding, W. A novel rough numbers based extended MACBETH method for the prioritization of the connected autonomous vehicles in real-time traffic management. Expert Syst. Appl. 2023, 211, 118445. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).