1. Introduction
In recent years, the brewing sector has undergone a profound transformation, characterized not only by an increasing diversification of products but also by a redefinition of quality paradigms driven by emerging consumption patterns. Within this framework, low- and non-alcoholic beers represent one of the fastest-growing segments, supported by rising health awareness, changing lifestyles, and increasingly stringent regulatory constraints [
1]. However, alongside this transition, maintaining high sensory quality—particularly in terms of aromatic complexity and product identity—has emerged as a critical challenge for the industry [
2].
The aroma profile of beer results from a complex network of volatile organic compounds (VOCs), generated and modulated throughout the different stages of the production process [
3]. Dealcoholization technologies, while essential for the development of alcohol-free products, introduce significant perturbations to the volatilome, altering delicate chemical equilibria and often compromising organoleptic properties [
4]. The ability to monitor and interpret these variations in a rapid, accurate, and non-destructive manner therefore represents a key technological challenge.
Advanced chromatographic techniques, such as gas chromatography coupled with mass spectrometry (GC–MS), are considered the gold standard for VOC analysis due to their high sensitivity and molecular identification capabilities [
5]. However, their applicability in dynamic industrial environments is limited by high instrumentation costs, lengthy analysis times, and the requirement for highly skilled personnel, particularly in contexts where rapid and in-line solutions are needed.
In this scenario, gas sensing technologies based on metal oxide (MOX) sensors are emerging as promising alternative tools with applications spanning diverse domains, from food quality monitoring to medical diagnostics and healthcare gas sensing [
6,
7,
8]. Unlike traditional analytical approaches, these systems do not aim at the selective identification of individual compounds but rather at capturing complex patterns of the volatilome, translating them into multidimensional olfactory fingerprints. This paradigm, based on the global analysis of sensor responses, has proven particularly effective in classification, authentication, and quality control applications, including raw material and product quality assessment across the food and beverage sector [
9]. Within the beer sector specifically, recent studies have applied electronic nose and sensor-based systems to product quality assessment, such as shelf-life prediction of beer through volatile profile monitoring [
10], as well as deep learning-based approaches, including convolutional neural networks, for beer identification via portable electronic nose systems [
11].
Despite the growing interest in sensor-based technologies within the agri-food sector, a fundamental issue remains unresolved: the correlation between sensor responses and the actual chemical composition of the sample. In this context, the integration of GC–MS and MOX-based systems represents a strategic approach, combining analytical accuracy with operational speed, providing a more comprehensive interpretation of the volatilome, and facilitating the translation of chemical data into actionable real-time information.
In the brewing field, such integration is particularly relevant for discriminating beers with different alcohol contents, as well as different brands and production types. This capability is not only essential for quality control but is also increasingly important for traceability, authenticity assessment, and fraud prevention in a highly competitive global market [
12].
At the same time, the use of rapid sensing systems opens new perspectives across the entire production chain, from fermentation monitoring to shelf-life evaluation. In this context, MOX sensors stand out due to their low cost, portability, and ease of integration into embedded platforms, making them well-suited for in-line and distributed monitoring applications.
In light of these considerations, the present study aims to investigate an integrated GC–MS and MOX-based sensing approach for the discrimination of commercial beers differing in alcohol content (alcoholic vs. alcohol-free) and brand. HS-SPME-GC–MS was first employed to characterize the volatile organic compound profiles of the selected samples, providing a chemical reference against which the discriminative capability of a six-element MOX sensor array was then evaluated through a dedicated feature-based machine-learning framework. Particular attention was further devoted to assessing the feasibility of rapid, short-exposure discrimination, as a step toward embedded, in-line quality-screening applications in the brewing sector. All investigated samples belonged to the same beer category, i.e., lager, produced using comparable raw materials and fermentation processes and thus sharing broadly similar volatile organic compound profiles [
13,
14]. This intrinsic similarity increases the complexity of the classification task, as it reduces pronounced compositional differences and challenges the discriminative capability of the sensing system, thereby allowing the assessment to focus on subtle variations in aroma profiles rather than on macroscopic differences between distinct beer types [
15].
2. Materials and Methods
2.1. Sample Preparation
Beer samples were selected from four widely recognized commercial brands available on the Italian market. Samples were purchased weekly from a local store over the entire five-month sampling period and analyzed within the following days of each corresponding week. Samples were stored at room temperature between purchase and analysis without any further treatment, consistent with routine product acquisition practices, thereby capturing the natural batch turnover of commercially available stock rather than relying on a single production lot. For each brand, one alcoholic beer and its corresponding alcohol-free commercial variant were analyzed: Heineken Original (HNK) and Heineken 0.0 (HNK_0), Peroni Nastro Azzurro Originale (NA) and Peroni Nastro Azzurro 0.0% (NA_0), Birra Moretti Ricetta Originale (MRT) and Birra Moretti La Zero (MRT_0), Forst Premium (FRST) and Forst 0.0% (FRST_0). The sample codes reported in parentheses were adopted consistently throughout the study. All samples were selected within the same beer category, i.e., lager [
16].
2.2. Determination of Volatile Compound by GC-MS
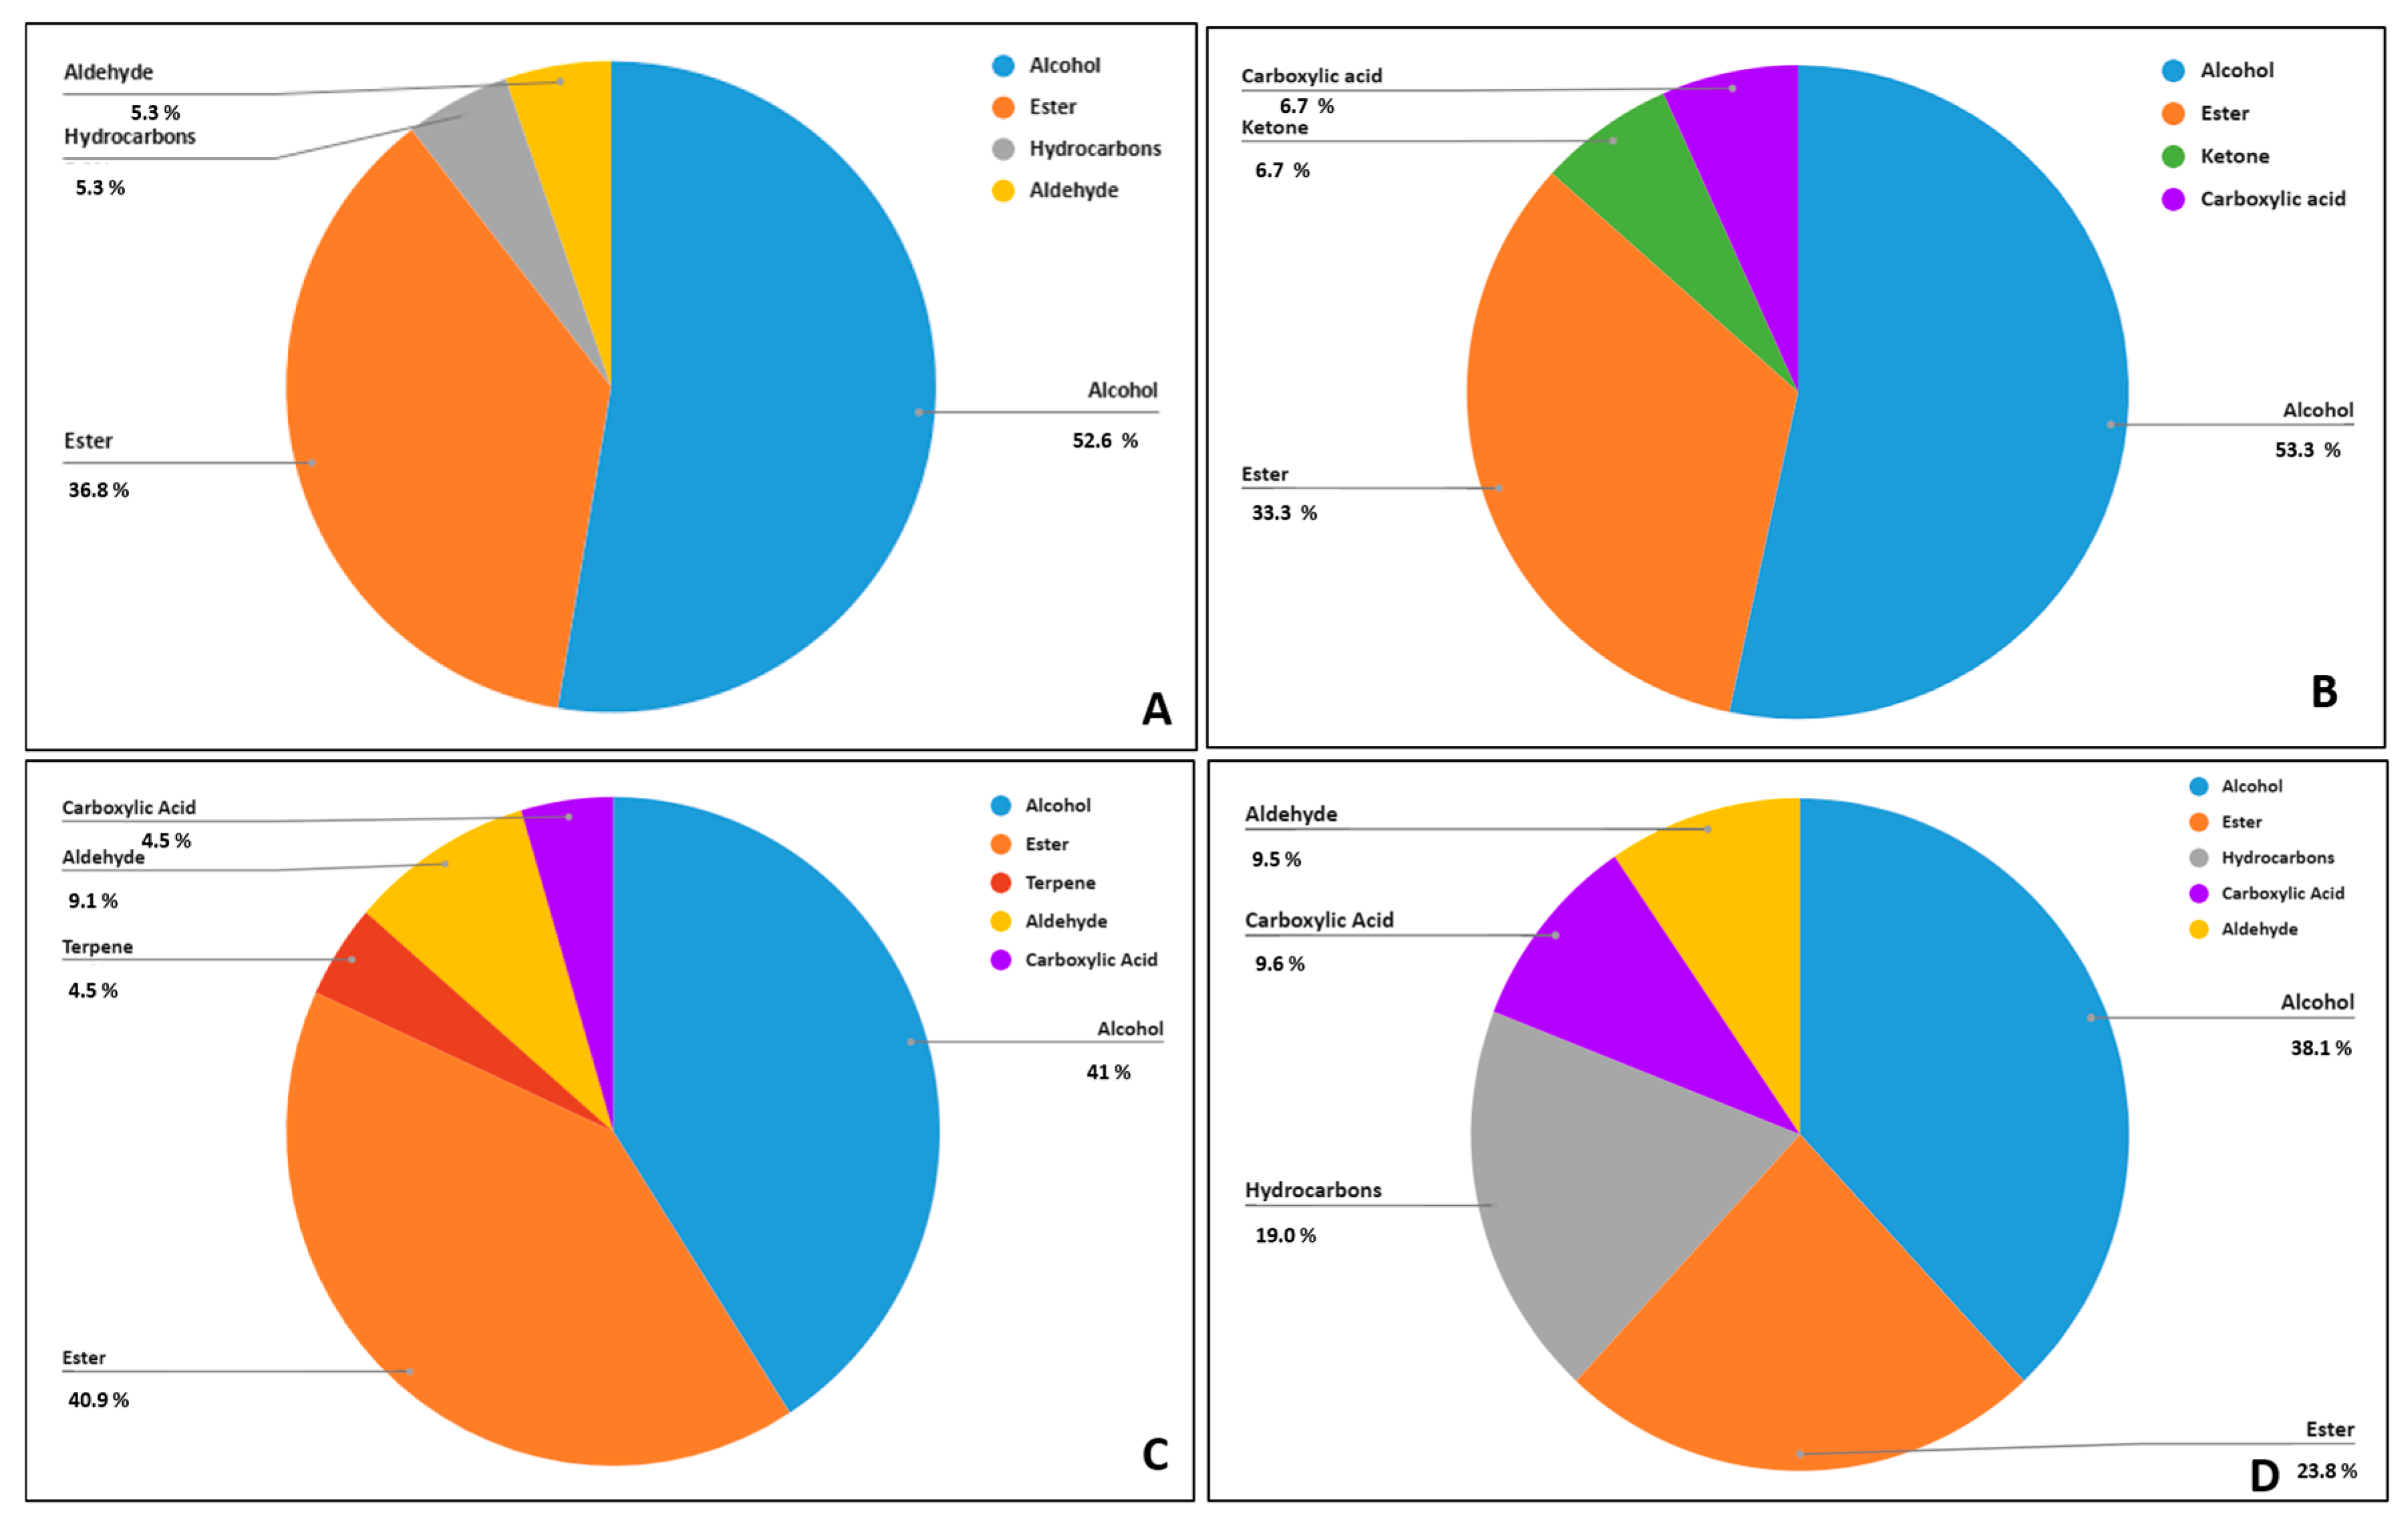
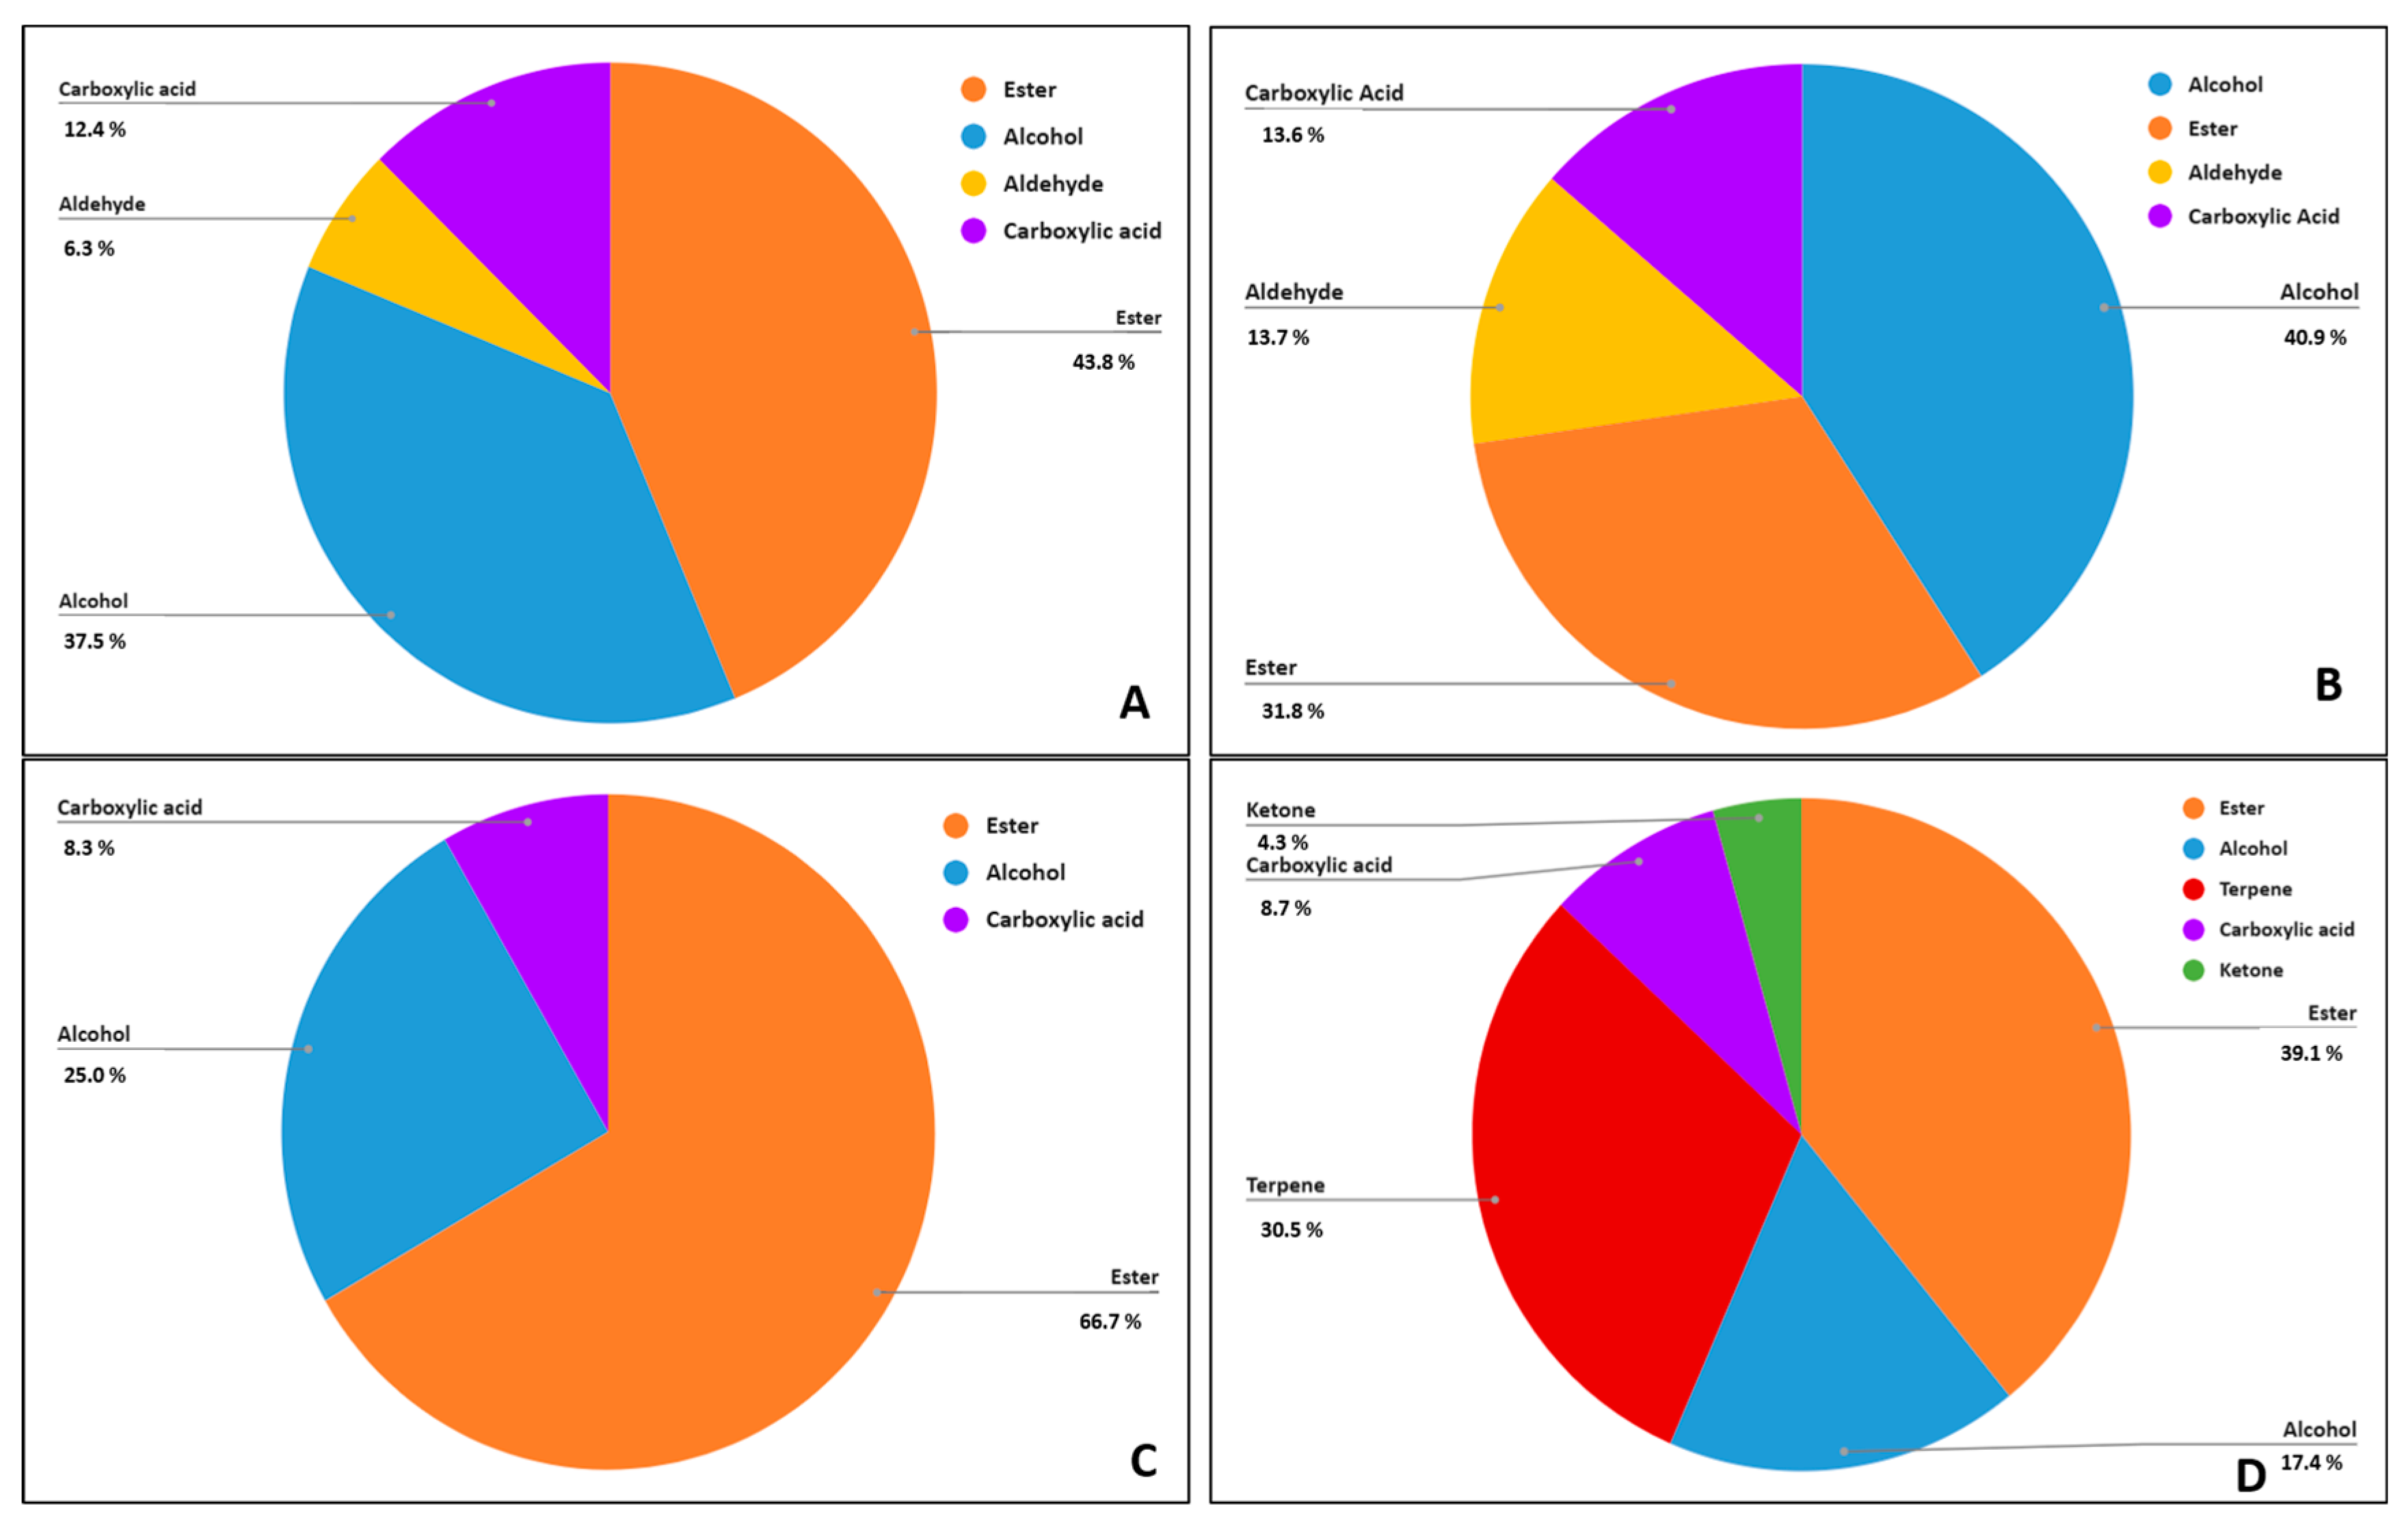
To provide chemical context for the interpretation of the MOX sensor array responses, the volatile profiles of the beer samples were independently characterized using headspace solid-phase microextraction (HS-SPME) coupled with gas chromatography–mass spectrometry (GC–MS).
For each analysis, 5 mL of sample were transferred into a sterile glass vial and equilibrated at 50 °C for 16 min using an ICF 120 incubator (ARGO LAB, Giorgio Bormac S.r.l., Carpi, Italy). Headspace extraction was then performed using a divinylbenzene/carboxen/polydimethylsiloxane (DVB/CAR/PDMS, 50/30 μm) fiber (Supelco, Bellefonte, PA, USA), the extraction step was conducted at 50 °C for 30 min.
Following extraction, the analytes were analyzed using a GC-2020 gas chromatograph coupled with an MS-QP2020 mass spectrometer (Shimadzu, Kyoto, Japan). The fiber was placed in the GC injector port for 6 min at 240 °C in direct mode leading to the thermal desorption of the volatile compounds. Gas chromatographic separation was achieved using a low-polarity stationary phase MEGA-5MS column (25 m × 0.25 mm internal diameter × 0.25 μm film thickness) from Agilent Technologies (Santa Clara, CA, USA). Hydrogen gas with 99.99% purity, supplied by the GENius PF500 system (FullTech Instruments Srl, Rome, Italy), was employed as the carrier gas, at 35.7 kPa, 2.2 mL/min flow, 87.4 cm/s linear velocity, and 4.0 mL/min purge flow. The column oven temperature program consisted of an initial temperature of 40 °C for 3 min, a gradient of 5 °C/min to 150 °C, followed by a gradient of 15 °C/min to 200 °C, and a final hold at 200 °C for 2 min. The total chromatographic run time was 30 min. Mass spectrometric detection was conducted under electron impact (EI) ionization at 70 eV, using the full-scan acquisition mode within the 40–350
m/
z range. The transfer line and ion source were both held at a constant temperature of 200 °C. Data acquisition was performed in the total ion current (TIC) mode at interval of 0.3 s. The detector temperature was set at 240 °C. Compound identification was performed by comparison of acquired mass spectra with three reference libraries (Nist11, Nist 11b, and FFNSC2) with automatic peak integration was carried out using peak area as the quantification parameter, a minimum of 70 peaks with area values ≥ 500 AMU were considered for analysis. Integration parameters included a slope of 100/min, peak width of 2 s, drift of 0/min, and doubling time (T.DBL) of 1000 min. No signal smoothing was applied. Volatile compounds were quantified in terms of relative abundance, expressed as a percentage of the total GC peak area [
17].
2.3. MOX Sensor Array Platform
All measurements were performed using an S3+ device (Nano Sensor Systems Srl, Reggio Emilia, Italy), equipped with an array of six metal oxide semiconductor (MOX) gas sensors. The system consists of a sample container, a sensor chamber, a diaphragm pump, three solenoid valves, and a carbon filter. The sensing elements were based on tin dioxide (SnO
2) as the active semiconducting material, used either in its pristine form or modified with selected noble-metal additives to diversify the surface reactivity of the array [
18]. Specifically, the sensor array included SnO
2-based elements with different surface functionalization involving palladium (Pd), platinum (Pt), and gold (Au) as shown in
Table 1. This controlled variation in surface composition is designed to expand the chemical response space of the array, thereby improving its capability to generate distinctive and informative responses in the presence of complex VOC mixtures [
19]. The sensors were operated at a constant working temperature of 500 °C, maintained by integrated platinum-based micro-heaters.
The sensor chamber (11 × 6.5 × 1.3 cm) was designed to promote uniform airflow over the sensing surfaces while limiting the influence of external environmental fluctuations. The MOX sensors were linearly arranged within the chamber to ensure comparable exposure to the sample headspace, thereby providing controlled measurement conditions and improving the reproducibility of sensor–analyte interactions [
20].
Gas handling is achieved through a dynamic fluidic circuit composed of a diaphragm pump (model NMP05B, KNF, Milan, Italy), polyurethane tubing, a solenoid valve (model K000-303-K11M, Camozzi Group S.p.A., Brescia, Italy), and an activated carbon filter placed along the inlet line to provide purified reference air and reduce the contribution of background contaminants. The solenoid valve, installed upstream of the sensing chamber, regulates the airflow delivered by the pump, with a maximum flow rate of 250 sccm, thus enabling controlled and repeatable exposure conditions. The valve was responsible for switching the inlet line between two sources: the activated carbon filter, delivering purified reference air to the sensing chamber, and the sample container, directing the beer headspace into the sensing chamber for analysis. To account for environmental variability, the system is equipped with a temperature and humidity sensor (AM2320, Guangzhou Aosong Electronics Co., Ltd., Guangzhou, China), which continuously monitors ambient temperature (T, °C) and relative humidity (RH, %). These parameters are used to ensure that all measurements are performed under comparable environmental conditions, thereby minimizing potential biases in the sensor responses.
2.4. Operational Configuration and Data Acquisition
For each measurement, 100 mL of beer were transferred into a 250 mL glass vessel, which was closed during the conditioning step to allow headspace accumulation. Before analysis, the samples were conditioned at 50 °C for 16 min to standardize headspace generation and improve the reproducibility of sensor exposure. The conditioning time was selected based on preliminary tests, as it provided stable and repeatable sensor responses while maintaining the protocol compatible with a controlled laboratory screening workflow. After conditioning, the accumulated headspace was dynamically sampled by the MOX device through its fluidic circuit and delivered to the sensor chamber by the integrated pump.
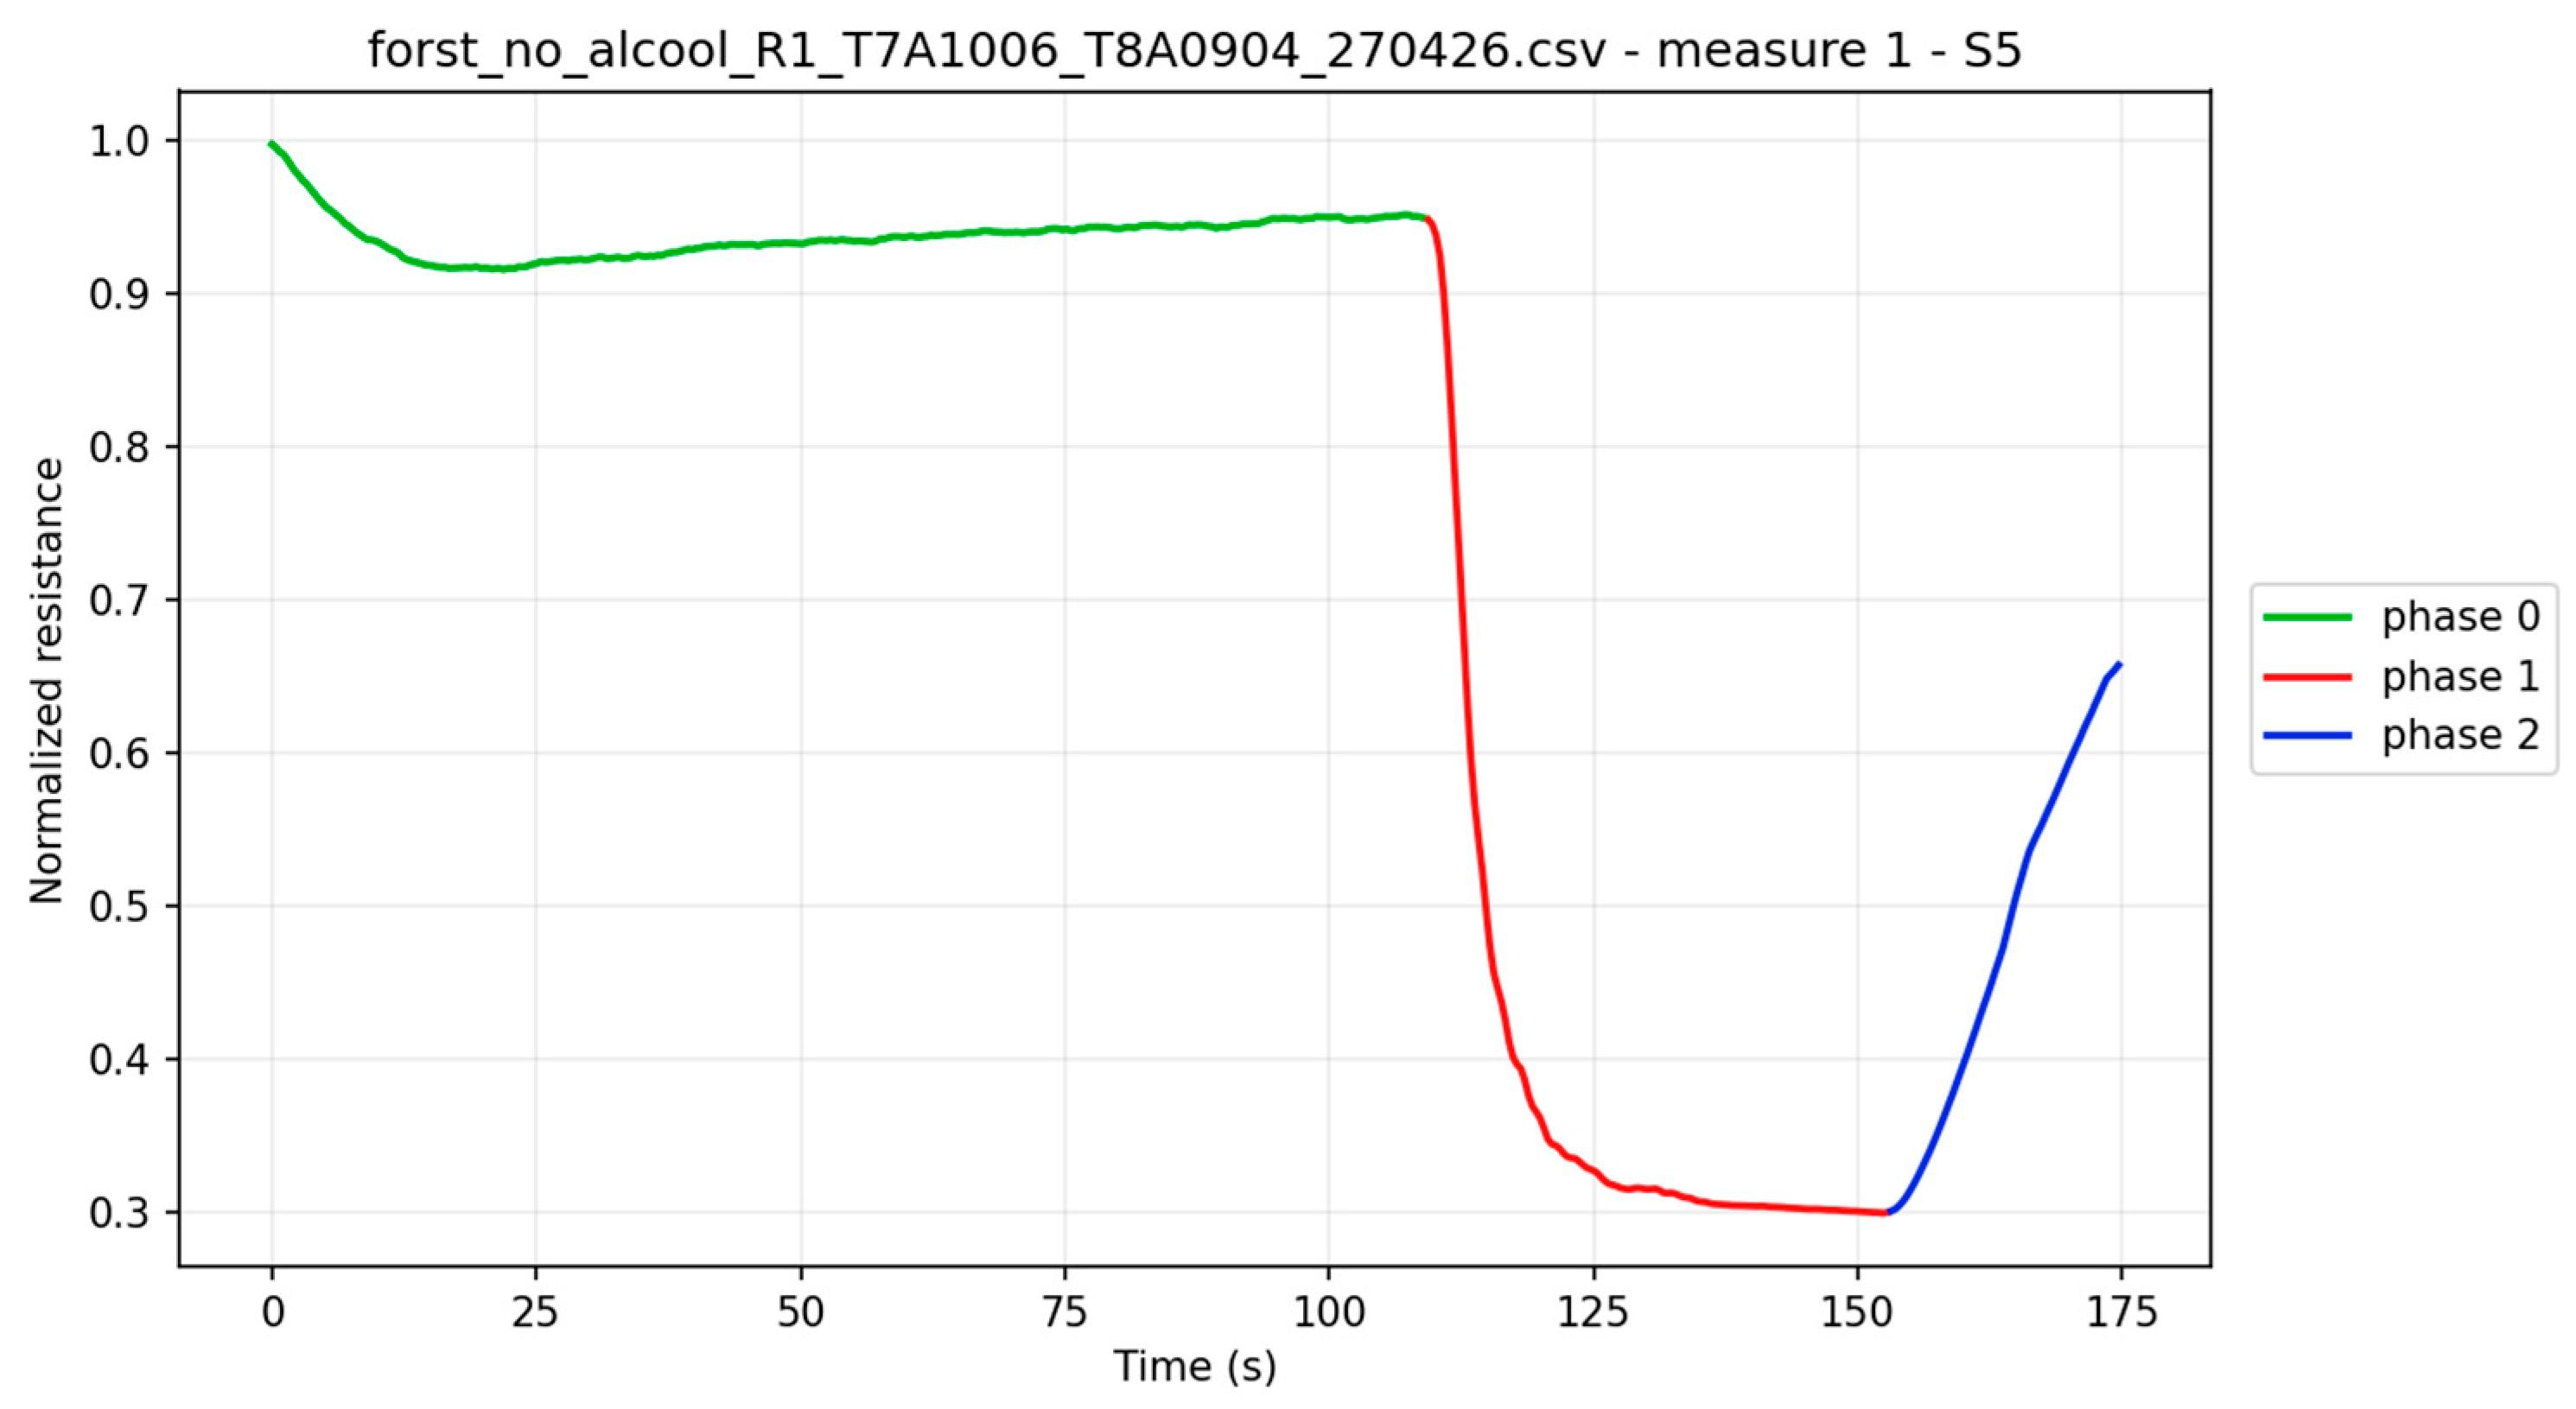
Each measurement cycle consisted of three sequential phases. In the initial phase (Phase A), filtered air was continuously flushed over the sensor array to establish and record a stable baseline. This was followed by the sampling phase (Phase B), during which the sample headspace was introduced into the sensing chamber for analysis. In the final phase (Phase C), the sensors were again exposed to filtered air to promote signal recovery. Raw response profiles of all six sensors across representative samples of each brand are reported in
Figures S1 and S2, for alcohol-free and alcoholic beers, respectively. As a representative example,
Figure 1 shows the normalized resistance response of a single sensor (S5) during one measurement cycle.
To improve dataset robustness and account for experimental variability, beer samples were analyzed over multiple days, with multiple measurement cycles acquired for each sample, each comprising the full sequence of Phases A, B, and C.
Different acquisition times were used according to the beer category to account for the different response dynamics observed during preliminary measurements. Alcoholic beers were analyzed using 110 s of baseline stabilization, 10 s of headspace exposure, and 21 s of recovery; whereas, alcohol-free beers were measured using 110 s, 43 s, and 21 s for the same phases, respectively. Each measure lasted 2 min and 21 s for the alcoholic beer samples and 2 min and 54 s for the alcohol-free sample. This choice reflected the faster headspace-induced response observed for alcoholic beers, likely related to the higher contribution of ethanol and other volatile constituents [
21].
For each classification scenario, all samples were compared using sensor signals extracted over an equivalent sampling duration. In brand-matched alcoholic versus alcohol-free comparisons, only the portion of the alcohol-free signal corresponding to the sampling window used for the respective alcoholic beer was retained, ensuring that both classes were evaluated over the same temporal response interval. This choice reflects the distinct headspace-induced response dynamics observed for alcoholic beers, and was also exploited to assess the feasibility of rapid discrimination, by evaluating whether the early sensor response contained sufficient information for sample classification. Restricting the alcohol-free signal to this shorter window may exclude potentially discriminative information present in its later response phase; however, this information was not excluded from the study overall, as the multiclass brand-discrimination analysis for alcohol-free beers was performed using the full native sampling window, allowing later-phase response dynamics to be exploited in that context.
2.5. Data Processing
Raw sensor data were organized as individual CSV files, each corresponding to a single experimental acquisition. Each file contained multiple measurement cycles, recorded as time-series signals from the six MOX sensors and structured according to the experimental sequence described above. For machine-learning analysis, the sampling phase was selected as the most informative region, as it corresponds to the direct exposure of the sensor array to the sample headspace [
22]. This phase was therefore used to extract the response patterns associated with the volatile fraction of each sample. Prior to feature extraction, sensor responses were preprocessed to reduce acquisition-dependent variability and improve comparability across measurements, specifically, each sensor signal was normalized with respect to its corresponding baseline within the same measurement cycle. This transformation converted raw resistance values into relative response profiles, reducing the influence of baseline offsets and intrinsic differences among sensing elements [
23]. After preprocessing, each normalized sensor response was converted into a set of descriptive features extracted from the sampling phase. The feature set included internally defined statistical, temporal, derivative-based, integral, variability, entropy, energy-related, and signal-shape descriptors, hereafter referred to as standard features. These custom descriptors were complemented by additional features generated using established time-series feature extraction libraries, including catch22, tsfresh, and tsfel [
24,
25,
26]. This combined feature space was designed to retain both interpretable response characteristics and more complex temporal patterns encoded in the sensor signals. Such an approach is important because classification tasks may involve samples sharing a largely similar volatile backbone, in which case classification may depend on subtle differences in sensor response dynamics [
27].
Feature selection was then applied to reduce the dimensionality of the high-dimensional candidate feature space generated from the MOX time-series responses. The procedure combined low-variance filtering with mutual-information-based ranking of feature relevance with respect to the class labels. Multiple combinations of variance and percentile thresholds were evaluated, ranging from 0.1 to 0.9 with increments of 0.1. For each combination, the most informative descriptors were retained while enforcing a minimum number of selected features. Among the candidate feature subsets, the pipeline prioritized those showing better preliminary classification performance, while also accounting for the presence of highly correlated features, before proceeding to full classifier training.
2.6. Supervised Model Development and Evaluation
Before model training, the dataset was partitioned at the acquisition-file level into a training set (70%) and a validation set (30%) using stratified sampling to preserve the class distribution of each classification task. Feature selection was performed using only the training set. The same training set was then further divided into an internal training subset (70%) and an internal test subset (30%) using a group-based split. The internal training subset was used for classifier fitting and hyperparameter optimization; whereas, the internal test subset was used for model assessment during development. The validation set was kept separate from feature selection, hyperparameter optimization, and model fitting, and was used after model development to evaluate candidate models and generate the final model ranking [
28].
A broad panel of supervised classification algorithms was evaluated to compare different modeling strategies. The candidate model pool included logistic regression (LgRg), support vector machines (SVC), polynomial-kernel support vector machines (PSVM), radial-basis-function support vector machines (RSVM), k-nearest neighbors (KNN), decision trees (DT), random forests (RF), Extra Trees (ExTr), gradient boosting (GB), AdaBoost (Ada), XGBoost (XGB), naive Bayes (NB), quadratic discriminant analysis (QDA), multilayer perceptron classifiers (MLP), a KMeans-based logistic regression pipeline (KMLR), a linear-discriminant-analysis/SVC pipeline (LSVC), and voting-based ensemble models. For each feature subset generated during the feature-selection stage, the classifiers were trained and evaluated using the same data partitioning strategy, enabling systematic comparison across feature configurations and algorithm families. Feature standardization was included within the machine-learning pipeline as a preprocessing step before classifier training. The scaler was fitted only on the internal training subset and subsequently applied to the internal test subset and to the validation set, preventing statistical information from the evaluation data from being transferred into the model-fitting process. Model performance was assessed separately on the internal test subset and on the validation set. The final model ranking was primarily based on balanced accuracy on the validation set, with macro-F1 and internal test balanced accuracy used as secondary criteria. Balanced accuracy was selected as the main ranking metric because it accounts for class-wise performance and is more informative than overall accuracy when the number of observations per class is not perfectly balanced [
29,
30]. Additional metrics, including accuracy, macro-precision, macro-recall, macro-F1, and ROC AUC when available, were used to provide a more comprehensive evaluation of classifier performance.
2.7. Experimental Classification Scenarios
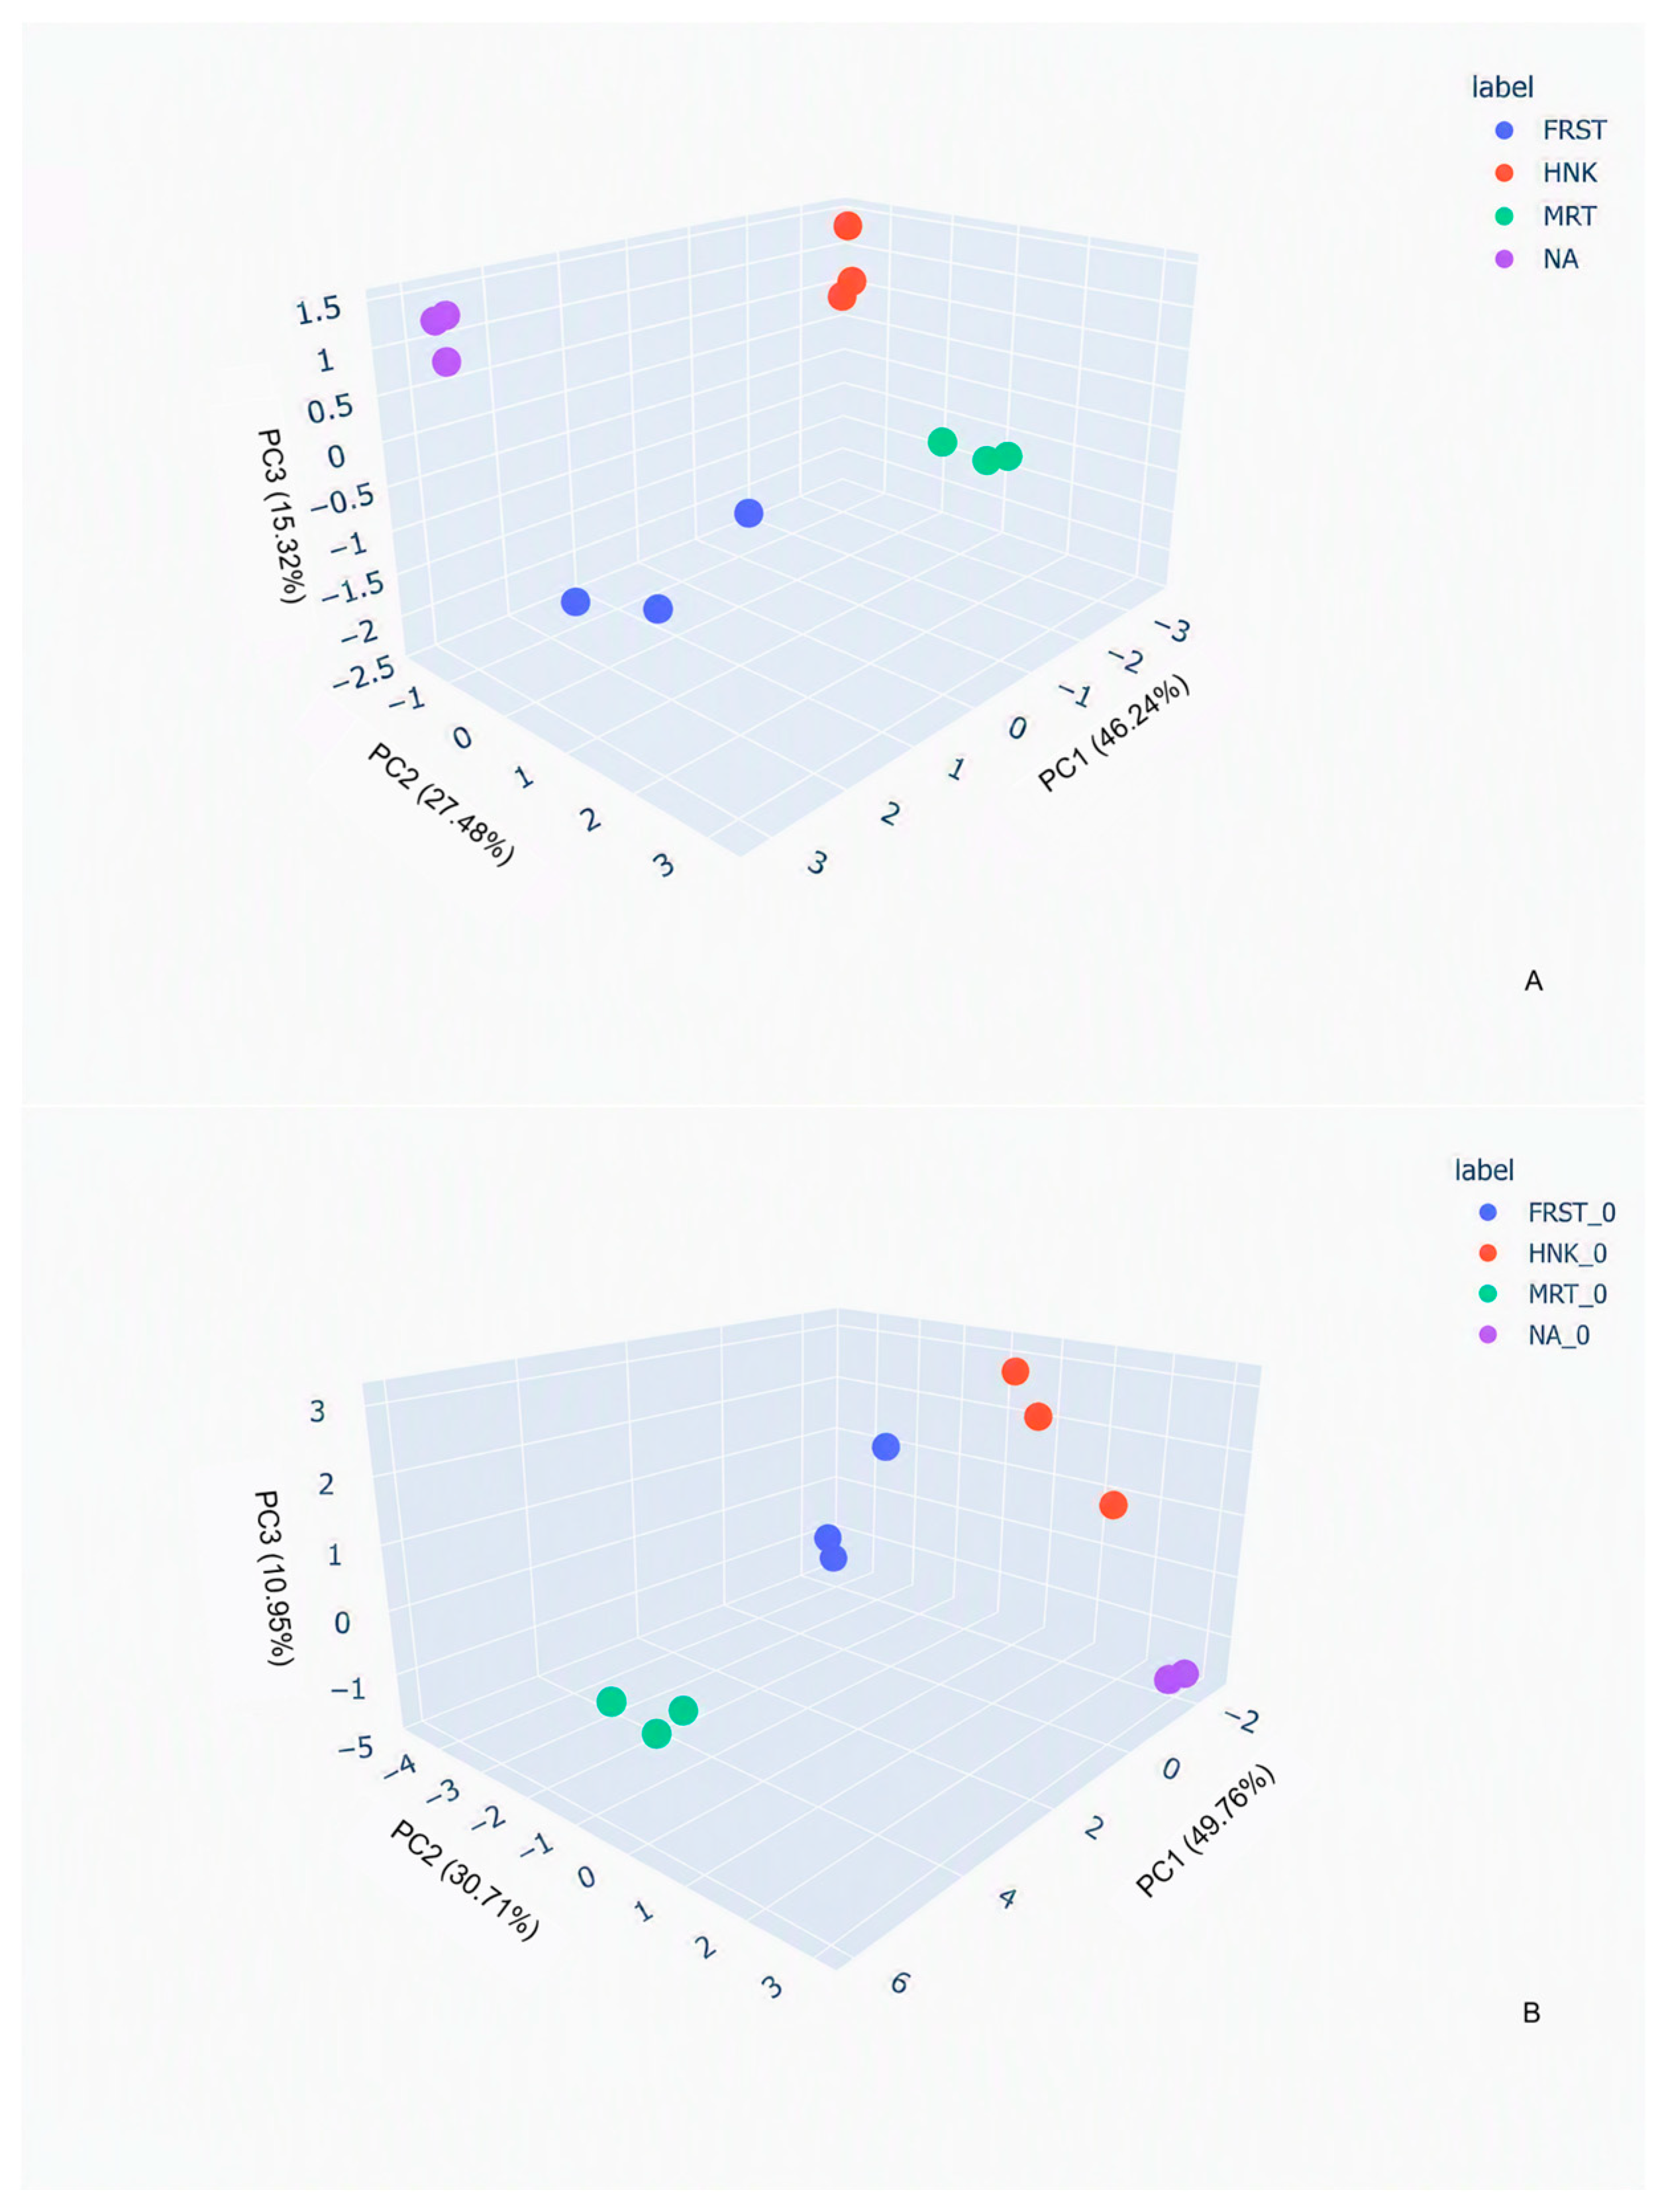
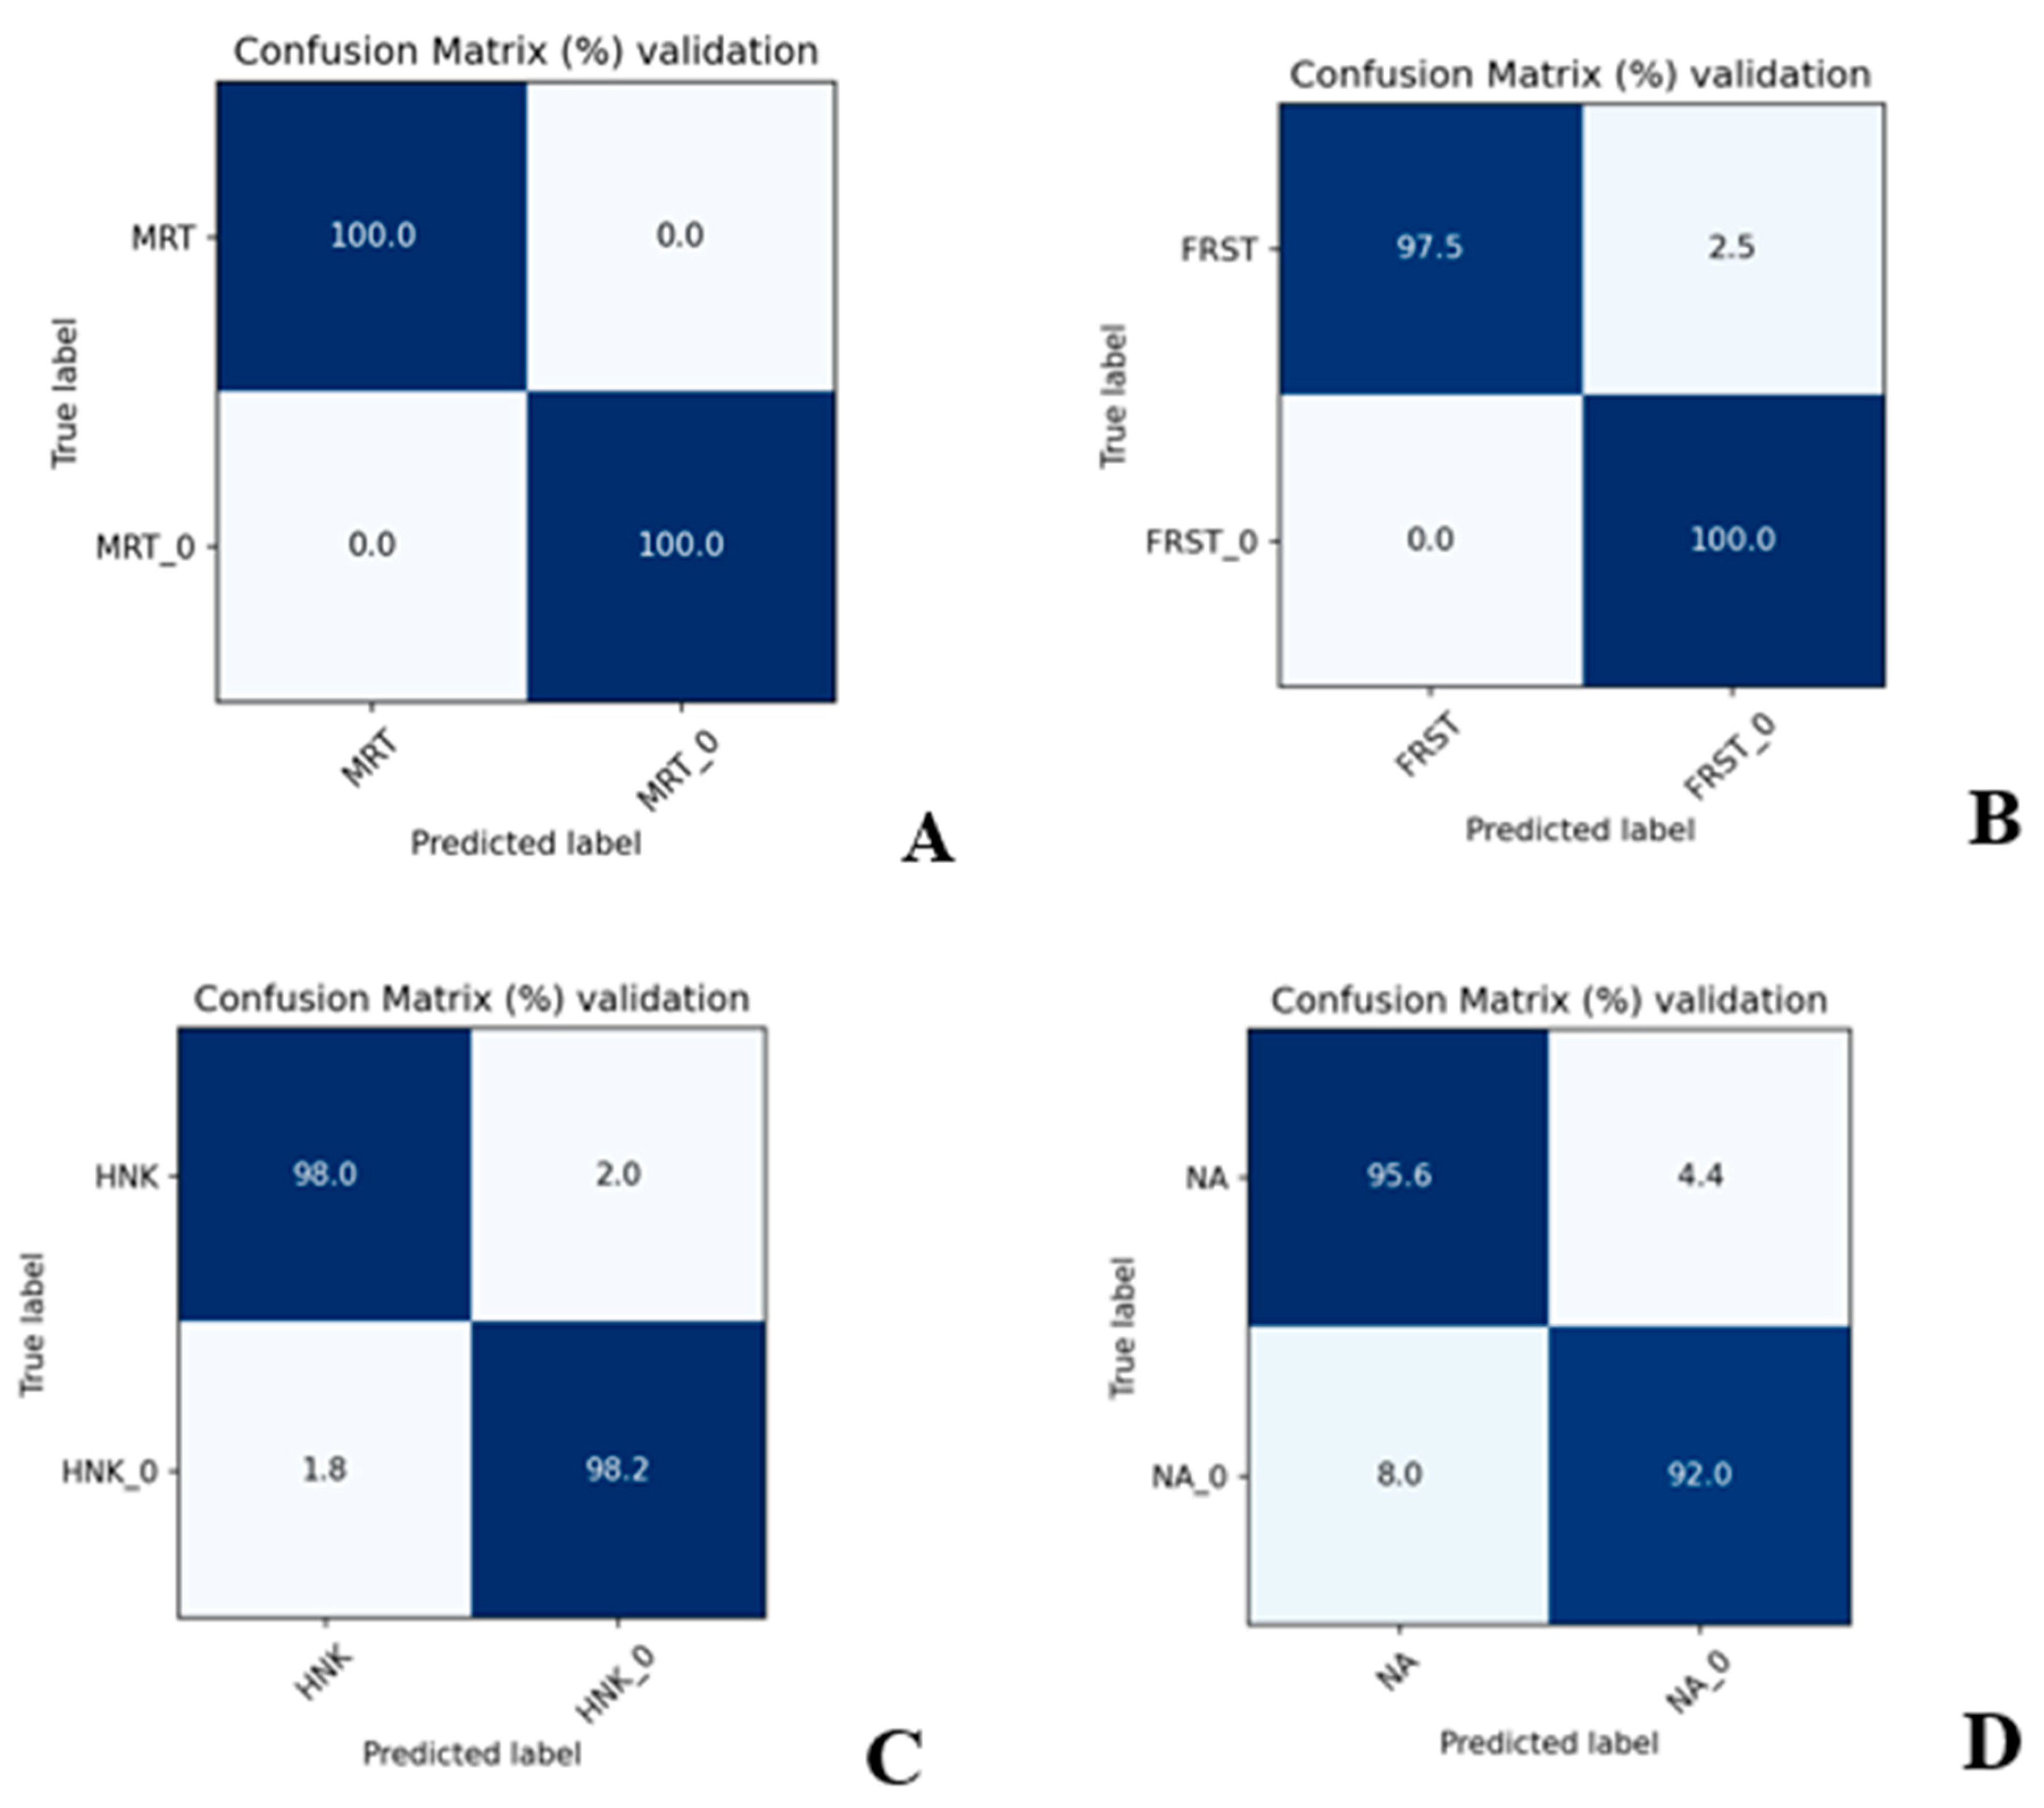
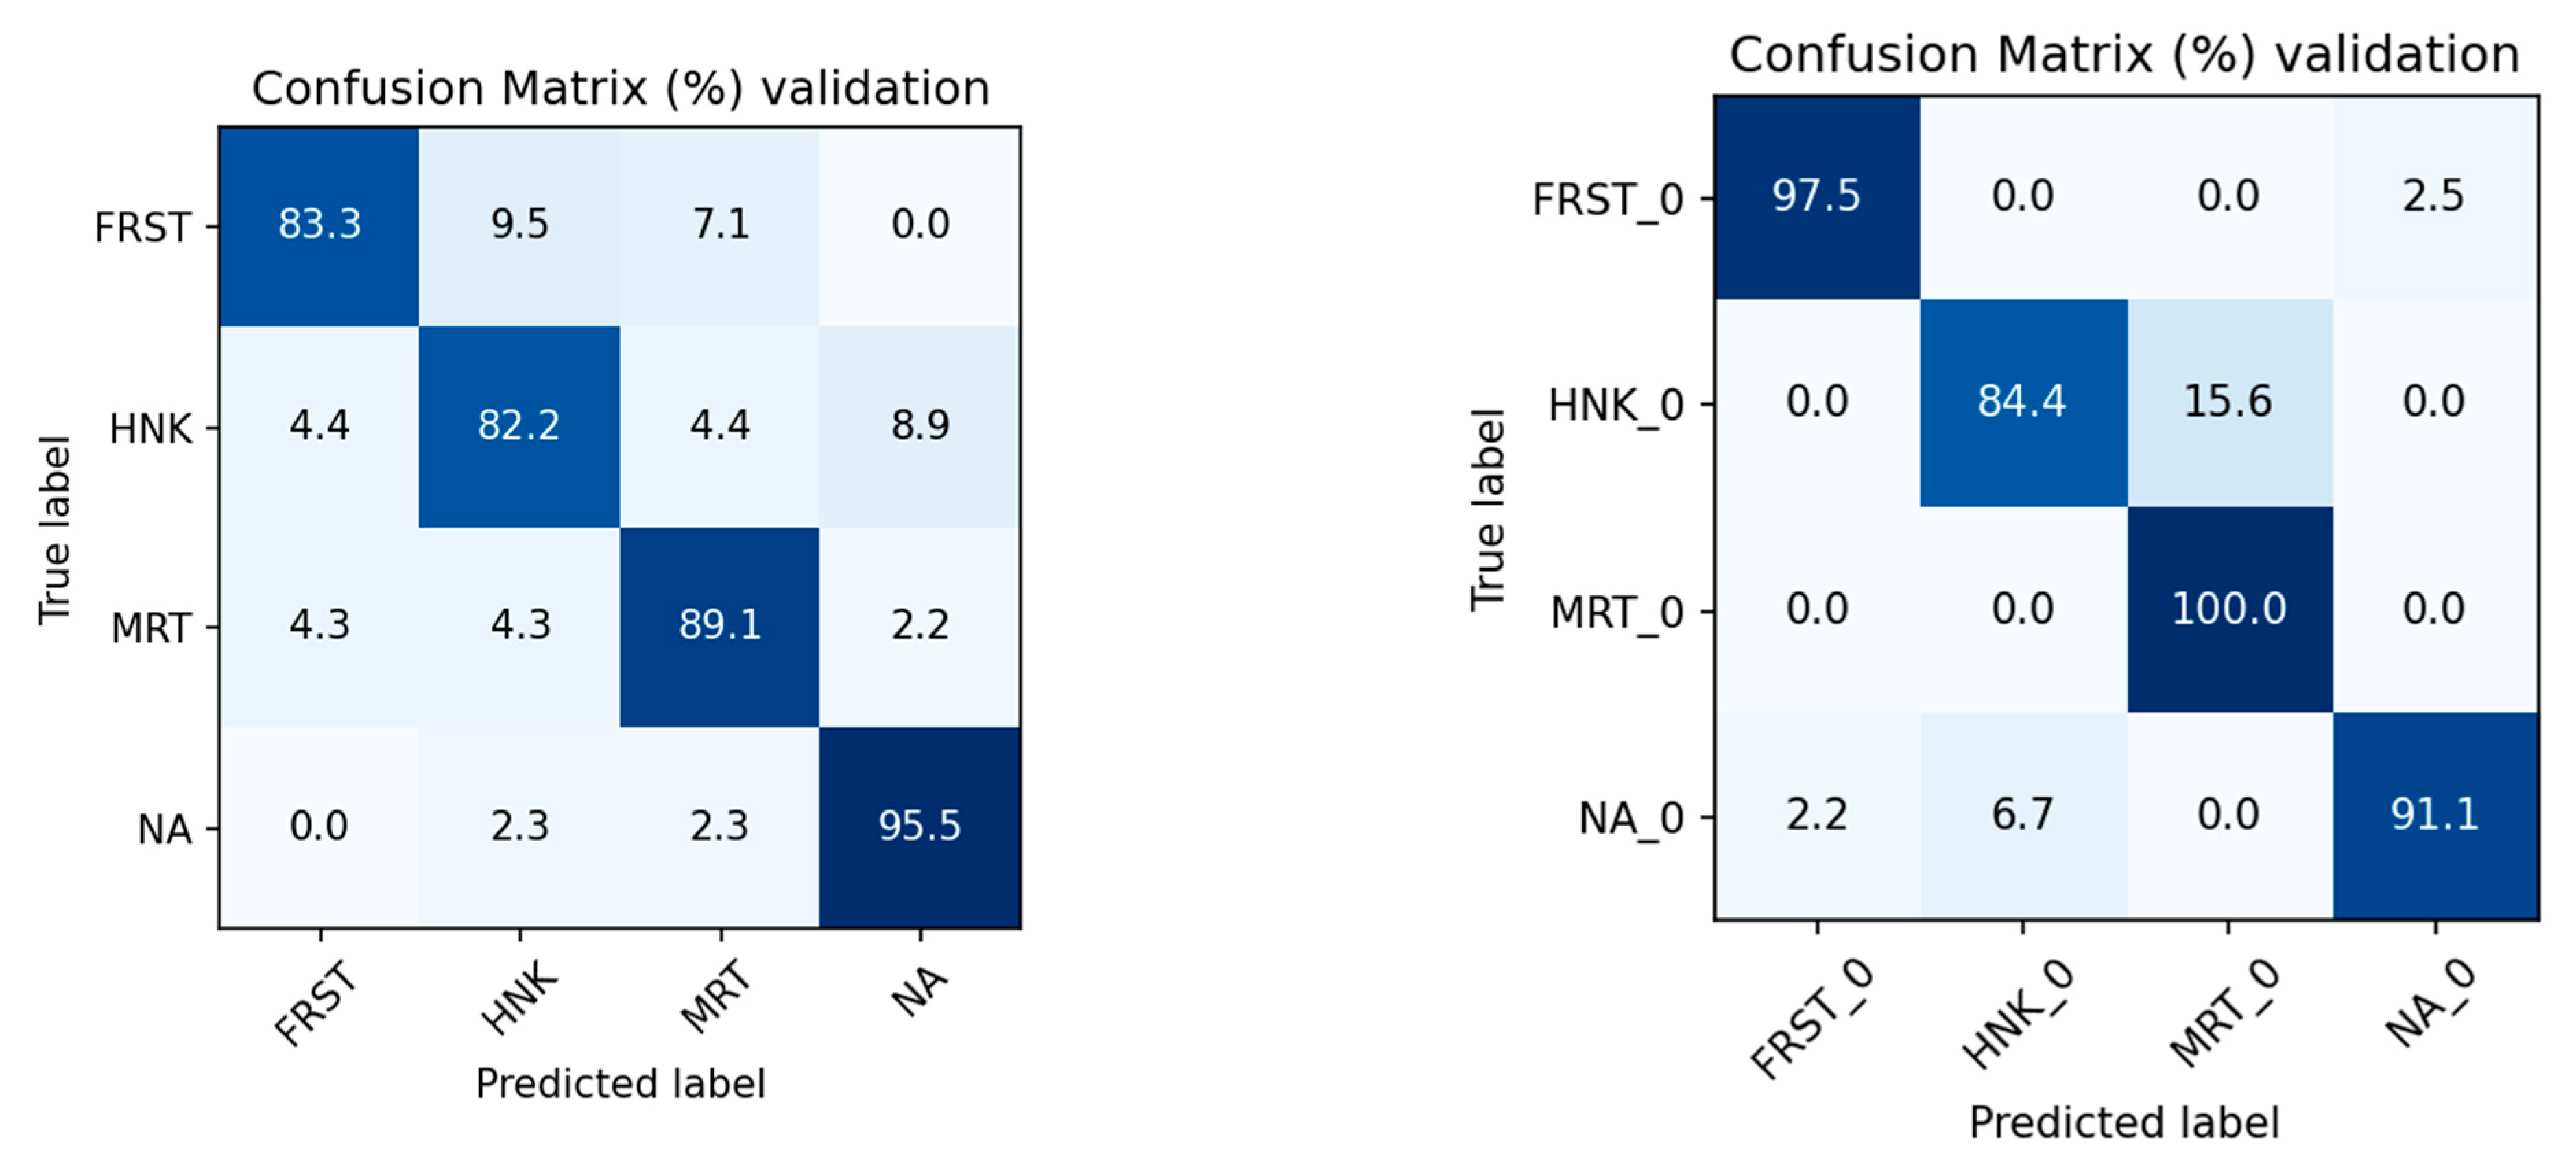
The workflow was applied to complementary classification tasks addressing both alcohol-status recognition and brand-level discrimination. Binary classification was first performed to distinguish alcoholic and alcohol-free variants within the same brand, with each brand-matched comparison treated as an independent case study. Specifically, four binary comparisons were considered: HNK vs. HNK_0; NA vs. NA_0; MRT vs. MRT_0 and FRST vs. FRST_0. In addition, two multiclass classification tasks were performed separately on alcoholic beers (HNK, NA, MRT, and FRST) and alcohol-free beers (HNK_0, NA_0, MRT_0, and FRST_0), in order to assess whether MOX sensor response patterns could discriminate among brands within the same alcohol category. For each task, data partitioning, feature selection, model development, validation, and final ranking were carried out independently, ensuring that each classification scenario was evaluated under task-specific conditions.
4. Conclusions
This study demonstrates the potential of MOX sensor technology combined with machine learning as a rapid, non-destructive, and data-driven strategy for discriminating commercial lager beers according to alcohol content and brand. The integration with HS-SPME-GC–MS supported the chemical interpretation of sensor-derived fingerprints, revealing a common volatile backbone dominated by fermentation-related compounds, while also highlighting brand- and category-dependent differences in VOC distribution. The MOX sensor array effectively captured these variations through multidimensional response patterns. Notably, the discrimination between alcoholic and alcohol-free beers of the same brand was achieved using only a 10 s exposure window, confirming the extremely rapid nature of the proposed approach. Despite this short acquisition time, supervised models achieved high classification performance, with balanced accuracy values ranging from 0.937 to 1.000 in binary comparisons. Brand-level classification within the same alcohol category also yielded promising results, indicating that MOX signals retain information related not only to alcohol content but also to product-specific volatile identity. These findings are consistent with the growing body of research investigating sensor-based and machine-learning methodologies for beverage quality assessment and discrimination. The present work contributes to this direction by concurrently addressing alcohol-content and brand-level discrimination within a rapid, short-exposure acquisition framework, corroborated by HS-SPME-GC–MS reference data. Some limitations should nonetheless be acknowledged. The present study was based on a limited number of commercial brands and was carried out within a single-platform, single-laboratory setting. These conditions, while ensuring controlled and consistent acquisition, inevitably constrain the generalizability of the developed models, which may not directly transfer to other product types or measurement systems without further validation. Overall, these findings suggest that the MOX platform could serve as a fast, portable, and scalable screening tool for beer quality assessment, supporting product discrimination, authenticity control, process monitoring, and conformity evaluation. Future work should move toward validating the approach under more realistic industrial conditions, including different production batches, beer styles, storage times, and dealcoholization processes. Further efforts should focus on improving model transferability, reducing the dependence on laboratory-controlled conditions, and developing interpretable correlations between sensor responses, VOC profiles, and sensory attributes. These steps will be essential to support the implementation of MOX-based systems as at-line or in-line tools for real-time quality control in breweries.






 ,