Article

Imbalance-Aware Cross-Modal Focal Modulation for Cross-Dataset Audio-Visual Deepfake Detection

by
Shahad Mohammad Bn Dokiey
1,
Tariq M. Khan
1,2,* and
Qazi Emad Ul Haq
1,2
1
Department of Cybersecurity and Digital Forensics, College of Forensic & Investigative Sciences, Naif Arab University for Security Sciences, Riyadh 14812, Saudi Arabia
2
Center of Artificial Intelligence for Security, Naif Arab University for Security Sciences, Riyadh 14812, Saudi Arabia
*
Author to whom correspondence should be addressed.
Future Internet 2026, 18(7), 379; https://doi.org/10.3390/fi18070379
Submission received: 4 June 2026 / Revised: 15 July 2026 / Accepted: 17 July 2026 / Published: 20 July 2026

Abstract

Audio-visual deepfake detection remains challenging under cross-dataset distribution shift, especially when the source-domain training data are severely imbalanced. Existing middle-fusion detectors often rely on softmax-based cross-attention, which can learn sharp source-domain token interactions and may transfer poorly to unseen datasets. This study proposes FocalNet, an audio-visual detector that replaces the cross-attention block of the 2D3MF framework with cross-modal focal modulation. The proposed module aggregates multi-scale temporal context before audio-visual interaction, enabling softmax-free contextual modulation between visual MARLIN features and audio EAT features. We evaluate the method under a strict FakeAVCeleb-to-DFDC protocol, where all training and validation is performed on FakeAVCeleb and the DFDC is used only as an unseen target-domain test set. Compared with the reproduced 2D3MF baseline, which collapses to a single-class prediction pattern on the DFDC, FocalNet achieves substantially stronger zero-shot score separation, with a DFDC ROC-AUC of 0.9324. Thresholded analysis further shows an improved balanced accuracy, macro F1 score, and MCC when the frozen source-domain operating point is applied. The model also preserves practical efficiency, requiring comparable FLOPs and lower per-sample inference time than the reproduced baseline. These findings suggest that cross-modal focal modulation is a promising alternative to attention-based middle fusion for audio-visual deepfake detection under dataset shifts, while broader validation across additional unseen datasets, multi-seed training, and deployment-oriented calibration remain important for future work.
Keywords: audio-visual deepfake detection; cross-dataset generalization; focal modulation; multimodal fusion; class imbalance; confusion matrix; explainable artificial intelligence; FakeAVCeleb; DFDC audio-visual deepfake detection; cross-dataset generalization; focal modulation; multimodal fusion; class imbalance; confusion matrix; explainable artificial intelligence; FakeAVCeleb; DFDC
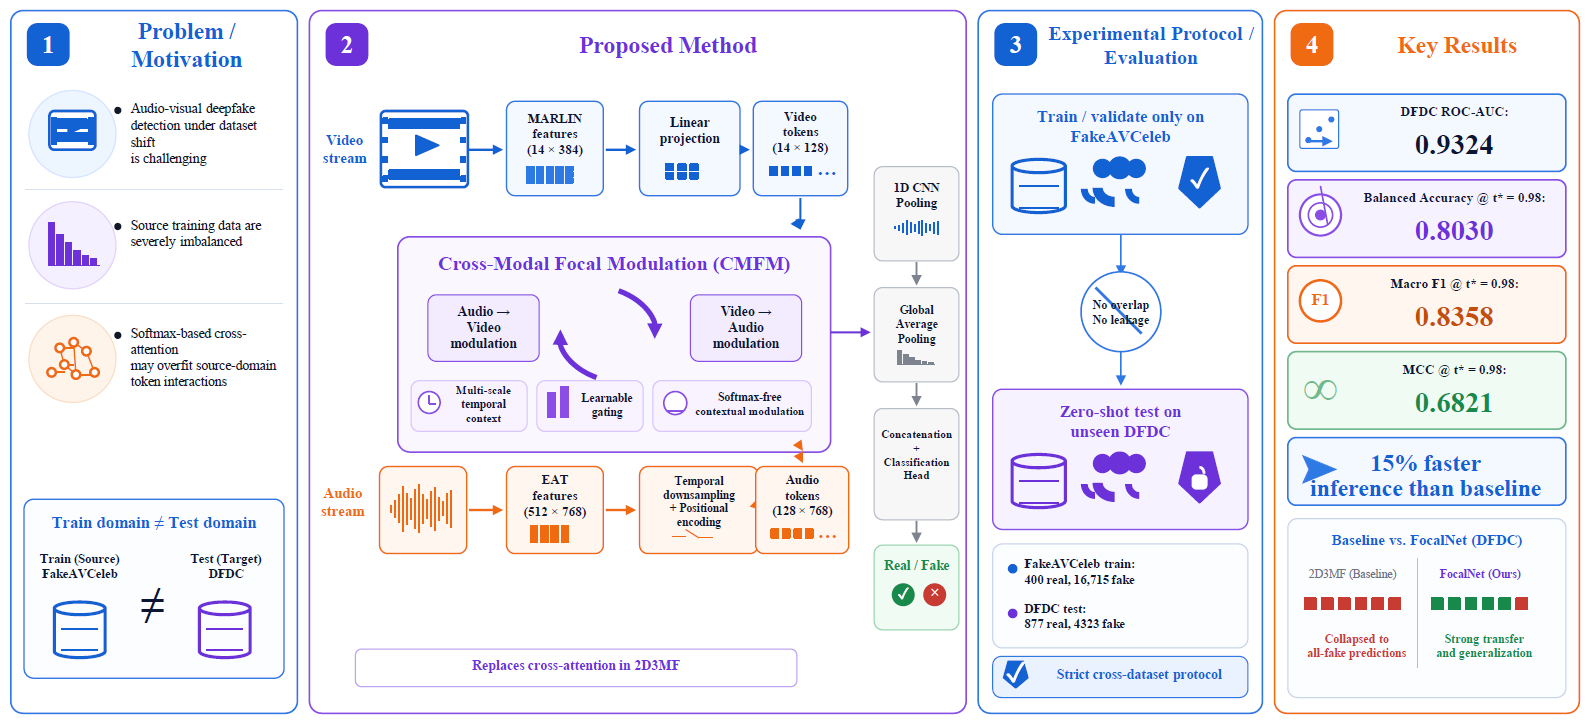
Graphical Abstract