


Abstract
Securing IoT networks presents fundamental challenges rooted in hardware constraints: firmware is often non-upgradeable and every security boundary is fixed at manufacture. Machine learning-based intrusion detection offers a scalable response, yet nearly all published systems assume clean training data and clean inference conditions. Production IoT environments satisfy neither assumption. Sensors degrade, packets drop, and adversaries deliberately corrupt telemetry streams to evade detection. The framework described here is built around that reality. The proposed framework is distinguished from prior work by four design decisions. First, three encoding branches, a residual DNN, a 1D-CNN, and a BiLSTM, are run in parallel and are fused by concatenation, each capturing structural patterns in tabular traffic data that the others miss. Second, a dual-view consistency loss trains the model under simultaneous feature masking and Gaussian noise, penalizing prediction divergence between two independently corrupted views of the same sample. Third, we introduce entropy-weighted attention: rather than fixed learned weights, per-feature importance is adjusted dynamically from information entropy measured across training batches, giving higher-entropy features stronger influence because they carry more discriminative variation. Fourth, branch-dropout regularization randomly silences entire branches during training, forcing each to develop independently useful representations instead of co-adapting. Class imbalance is handled through severity-aware loss weighting which scales contributions by the operational cost of missing each attack category, not purely by inverse frequency. On UNSW-NB15, the full model achieves 99.99% accuracy, 100% precision, 99.97% recall, and a false-negative rate of 2.65 × 10⁻⁴—the lowest across all compared architectures.
1. Introduction
October 2016. Someone discovers that a certain brand of IP camera ships with a hardcoded root password. Not one that the owner can change hardcoded in the firmware, present on every unit ever manufactured. Mirai finds them with a port scan, logs in automatically, and within days has recruited roughly 600,000 devices into a botnet that hits Dyn with more than 1 Tbps of traffic [1]. Twitter goes down. Netflix goes down. Half the American internet east coast is unavailable for most of a Friday afternoon. And the entire attack required zero exploitation—just a list of default credentials that worked.
That specific vulnerability has been patched. What has not changed is the underlying architecture of IoT hardware: constrained processors, non-upgradeable firmware in many devices, communication protocols that were designed for reliability and power efficiency rather than resistance to adversarial traffic [2,3]. Hospitals depend on connected infusion pumps and patient monitors that cannot run TLS. Power infrastructure depends on SCADA sensors that receive no patches after deployment. Factory floors depend on actuators whose firmware is locked by the manufacturer. The attack surface has expanded dramatically over the past decade, and it cannot be reduced through conventional means at anywhere near the pace it is growing.
Machine learning-based intrusion detection has emerged as the primary response to this challenge because it scales where signature-based methods cannot. A classifier trained on labeled packet captures learns to distinguish malicious from benign traffic statistically, without requiring manual encoding of each new attack variant into an explicit rule. Accuracy on standard benchmarks is high enough (routinely above 99% on UNSW-NB15) that the approach is operationally credible. However, a substantial gap separates benchmark performance from observed reliability in production deployments.
Class imbalance is the most commonly acknowledged gap in the literature. In realistic traffic captures, attacks constitute a small minority; classifiers trained without explicit correction learn to predict the normal class because it is statistically dominant [4,5]. Worms and Shellcode have only 130 and 1133 training records respectively in UNSW-NB15, providing insufficient data to anchor a reliable decision boundary for two operationally high-risk attack categories.
Feature noise receives comparatively little attention in the published literature. Network telemetry in real deployments contains missing values, quantisation artifacts, and channel-induced errors that are absent from benchmark recordings. A model achieving 99% accuracy under clean benchmark conditions may exhibit substantially degraded performance when the input distribution shifts at inference time.
Sensor unreliability is the gap we focus on, because almost nobody addresses it at the architecture level. IoT sensors malfunction. Wireless channels degrade and drop packets. Adversaries have begun deliberately corrupting telemetry streams specifically to confuse detection systems. Baza et al. [6] cataloged attack vectors targeting sensor data integrity, and Khalid et al. [7] measured the accuracy hit under realistic corruption scenarios. A model trained on clean recordings will see degraded inputs at inference time and has no reason, architecturally, to handle them well. This is not a data problem. It is a design problem.
Our response to that design problem has four components, two of which have not appeared in prior IDS work. The foundation is a three-branch parallel architecture, DNN, CNN and BiLSTM, with attention trained with a dual-view consistency loss that penalizes prediction divergence across independently corrupted views of each training sample. On top of this, we introduce entropy-weighted attention: rather than relying on purely learned attention weights that remain static after training, the DNN’s attention layer is modulated at each batch by per-feature information entropy computed across that batch; features with higher entropy carry more discriminative variation and receive proportionally stronger attention. We also introduce branch-dropout regularization, where entire branches (not just neurons) are randomly silenced during training, preventing co-adaptation between branches and forcing each one to maintain standalone discriminative capability. Class imbalance is handled through severity-aware weighting that goes beyond inverse frequency; it additionally amplifies the loss penalty for high-impact categories like Shellcode and Worms that pose outsized operational risk.
The specific contributions are:
- [C1] A three-branch DNN–CNN–BiLSTM framework with dual-view consistency regularization, adapting the consistency training principle from semi-supervised learning to supervised tabular IoT intrusion detection.
- [C2] Entropy-weighted batch attention in the DNN branch: dynamic per-feature importance modulation based on information entropy measured across training batches, replacing static learned weights.
- [C3] Branch-dropout regularization: stochastic silencing of entire branches during training to prevent inter-branch co-adaptation and strengthen individual branch representations.
- [C4] Severity-aware loss weighting that scales class penalties by both frequency and operational impact, reducing false-negative rates on rare high-risk categories.
- [C5] Binary and ten-class evaluation on UNSW-NB15, systematic ablation isolating each new contribution, and a comparison against sixteen published methods.
2. Related Work
2.1. Shallow Classifiers and the UNSW-NB15 Baseline
Early work on UNSW-NB15 established baseline performance using shallow classifiers. Kasongo and Sun [8] propose dimensionality reduction from 43 to 19 attributes, achieving approximately 66% accuracy. While this figure reflects the challenge of the benchmark under limited feature representations, it confirms that the dataset is not trivially linearly separable. Barkah et al. [9] examine the effect of synthetic oversampling, showing that while SMOTE and related methods can improve minority-class recall, they may also distort the decision boundary by introducing artificial samples in regions where the underlying class distribution is sparse. These findings informed the decision to use severity-aware class weighting in place of synthetic oversampling in the present work.
2.2. Deep Learning Approaches
The use of deep architectures fundamentally changes the way we approach the problem. Upadhyay et al. [10] use a combination of random forest feature selection and a CNN to obtain an accuracy of 93.82%. Another study by Hassouneh and Al-Sharaeh [11] uses a bidirectional LSTM network with SMOTE-based rebalancing to obtain an accuracy of 95.01%, which is equivalent to an AUC of 0.9953. The most similar work to ours, based on network architecture, is that of ADFCNN-BiLSTM proposed by Liu et al. [12]. Their network combines deformable convolutions, a multi-head attention network, and a BiLSTM network. Their use of an attention network was a key inspiration for our network, although we differ in the entropy-weighting layer described in Section 4.4. Another study by Srivastava and Prakash [13] uses a CNN-BiGRU network to obtain an accuracy of 96.84% for 5G IoT traffic. Ahmad et al. [14] demonstrate that a standalone deep neural network achieves 96.84% accuracy on IoT anomaly detection; the DNN branch of the proposed framework, operating with improved class weighting and consistency regularization, is expected to exceed this figure.
2.3. Hybrid and Attention-Augmented Architectures
Combining CNN and recurrent branches has been productive. Keskin and Altuncu [15] report 99.265% precision from a BiLSTM-CNN hybrid on UNSW-NB15. Zhang et al. [16] wrapped CNN-LSTM inside a reptile-search hyperparameter optimizer. Transformer-based designs have pushed further: Umer et al. [17] exceeded 99% in both binary and ten-class modes with a wrapper-selected multi-head attention transformer; their ten-class results are one of our key reference points. Biyouki et al. [18] propose IDS-MTran (a multi-scale convolutional transformer); Wang et al. [19] built MCAN-BIFT for industrial IoT; Qi et al. [20] demonstrate a CNN–BiLSTM–Transformer on traffic with long-range dependencies. Tahir et al. [21] explore spiking-transformer hybrids for edge deployment; trading accuracy for a computational budget that constrains IoT nodes can afford a tradeoff our current design does not attempt but that future lightweight variants would need to consider.
2.4. Attention Mechanisms and Feature Importance in IDS
Attention has appeared in IDS mostly through transformer-style multi-head mechanisms or additive attention over sequence positions [12,17,20]. Dynamic modulation of attention based on information-theoretic properties of the input distribution, specifically using per-feature entropy across a training batch to amplify attention on features with high cross-class variation, is comparatively absent from the literature. Entropy-based feature importance appears in the feature selection literature [22] and in active learning [23], but its integration into the attention computation of a deep network during forward passes is, to our knowledge, unreported for tabular intrusion detection. The closest work is information-gain-based feature selection applied before training [8,22], not during it.
2.5. Consistency Regularization in Prior Work
Consistency regularization was developed for semi-supervised learning: apply two stochastic augmentations to the same sample and penalize prediction divergence [24,25]. Fan et al. [24] extended this with FeatDistLoss, combining prediction-level consistency with feature-space equivariance. Tarvainen and Valpola [25] introduce the mean teacher framework. In supervised settings, the technique has appeared in histopathology classification [26] and fault diagnosis under label scarcity [27]. None of these applications involve tabular network traffic, and none use augmentations that specifically simulate the sensor degradation patterns that IoT deployments actually produce.
2.6. Dropout Strategies and Ensemble Regularization
Standard dropout silences individual neurons with probability p during training [28]. DropBlock, originally proposed for image feature maps, extends this principle by dropping contiguous spatial regions rather than individual units. In multi-branch architectures, branch-level dropout randomly zeroing the entire output of a branch is a different kind of regularizer: it prevents the branches from co-adapting to each other’s outputs, which in a concatenation-based fusion can happen when one strong branch dominates the shared loss gradient and the others learn only residual corrections. Branch dropout forces each branch to maintain independently useful representations. We are not aware of published work applying this specifically to multi-branch tabular IDS architectures.
2.7. IoT Sensor Reliability and Data Integrity
Sensor unreliability in IoT has been studied mainly from the network engineering side. Khalid et al. [7] evaluated trust estimation under hardware faults and channel noise and found that ML-based trust frameworks measurably degrade when inputs are corrupted. Baza et al. [6] cataloged attacker-controlled data injection as a distinct threat vector. Gebremariam et al. [29] propose dynamic trust estimation for sensor networks. Surveys covering 2020–2025 consistently identify data integrity as a top open challenge for ML-based IoT defense [23,30]. The IDS literature has been slow to respond to this at the architecture level: models are trained on clean benchmark data and evaluated on clean test splits, leaving the degraded-input question unaddressed.
2.8. Summary of Gaps
Four gaps persist across the hybrid IDS literature. Consistency regularization has not been applied to supervised tabular IDS, and the sensor-degradation motivation for it has not been made explicit. Attention mechanisms remain static post-training; they do not adapt to the information content of the current input batch. Branch co-adaptation in multi-branch fusion architectures has not been addressed through branch-level dropout. Class weighting strategies are almost universally pure—inverse-frequency weighting severity of missed detection has not been incorporated. This paper addresses all four.
3. Theoretical Background
3.1. Intrusion Detection Systems in IoT
An IDS monitors traffic and raises alerts when observed behavior diverges from known-good patterns or matches known-bad signatures. Signature-based systems are fast and accurate for known threats but require constant updating and miss zero-day attacks. Anomaly based systems detect novel threats at the cost of higher false-positive rates when legitimate traffic shifts [31,32]. IoT deployment imposes additional constraints: enormous device populations, heterogeneous protocols, latency requirements tight enough that a detection delay of even a few seconds may be too late to contain a fast-spreading intrusion [33]. Deep learning has absorbed these constraints by learning feature hierarchies directly from labeled traffic, with lightweight variants adapting to edge nodes [34] at the cost of reduced capacity [21]. The persistent open problems, as recent surveys confirm [23,30], are imbalanced data, noisy high-dimensional features, and degraded-input robustness.
3.2. Component Architectures
A one-dimensional convolutional neural network (1D-CNN) will process the feature vector as a one-dimensional signal, where the locally correlated information will be extracted by the learned filters. This will, for the tabular traffic records, correspond to finding the co-occurrences of the features, like the high packet rate with low payload, or the short inter-arrival time with high connection count. Global average pooling will then downsize the responses of the filters to a fixed-size vector [35]. CNNs are known for their fast convergence capability, accompanied by low false-negative rates for intrusion detection, which is a phenomenon that we observed with our binary results.
BiLSTM processes feature as an ordered sequence through gated cell-state updates, input gate, forget gate, output gate, running forward and backward simultaneously so each feature position integrates context from both directions [36,37]. Applying bidirectional LSTM to tabular data involves an implicit assumption of sequential ordering across feature columns, which lacks intrinsic justification. Nevertheless, the bidirectional pass captures ordered inter-feature dependencies that neither convolutions nor fully connected layers model, and these dependencies contribute to performance on certain attack categories in the ten-class evaluation.
DNNs stack fully connected layers with residual shortcuts [28] to build progressively abstract feature representations. Soft attention before the final projection layer assigns per-feature importance weights serving both as a classification aid and as a diagnostic instrument: post-training attention maps allow identification of the protocol attributes treated as most discriminative by the model, which can be compared against domain knowledge about specific attack categories [12].
3.3. Information Entropy and Feature Salience
Shannon entropy over a discrete distribution P is H(P) = −Σ pᵢ log pᵢ. When per-features are computed across a training batch (treating each feature’s distribution across samples as P), features with higher entropy carry greater variation across classes and are therefore more likely to be discriminatively useful. A feature with near-zero entropy is roughly constant across all samples in the batch; it contributes little to separating attack categories. The entropy-weighted attention mechanism uses batch-level entropy estimates to strengthen the attention response on high-entropy features and suppress it on low-entropy features, dynamically, per batch. This makes attention adaptive to the information content of the current training examples rather than fixed after convergence.
3.4. Consistency Regularization
Given model f_θ and two stochastic augmentation functions T1, T2, the consistency loss penalizes |f_θ(T1(x)) − f_θ(T2(x))|2. Minimizing this constraint trains the model to output stable predictions across corrupted versions of the same sample [24,25]. When T1 and T2 simulate feature masking and additive Gaussian noise, the two dominant degradation modes in IoT sensor failures and adversarial telemetry manipulation [6,7], the technique is not just a generic regularizer but a domain-specific training strategy for degraded-input robustness.
4. Proposed Methodology
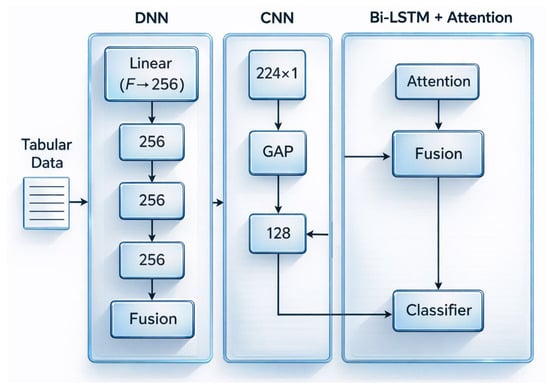
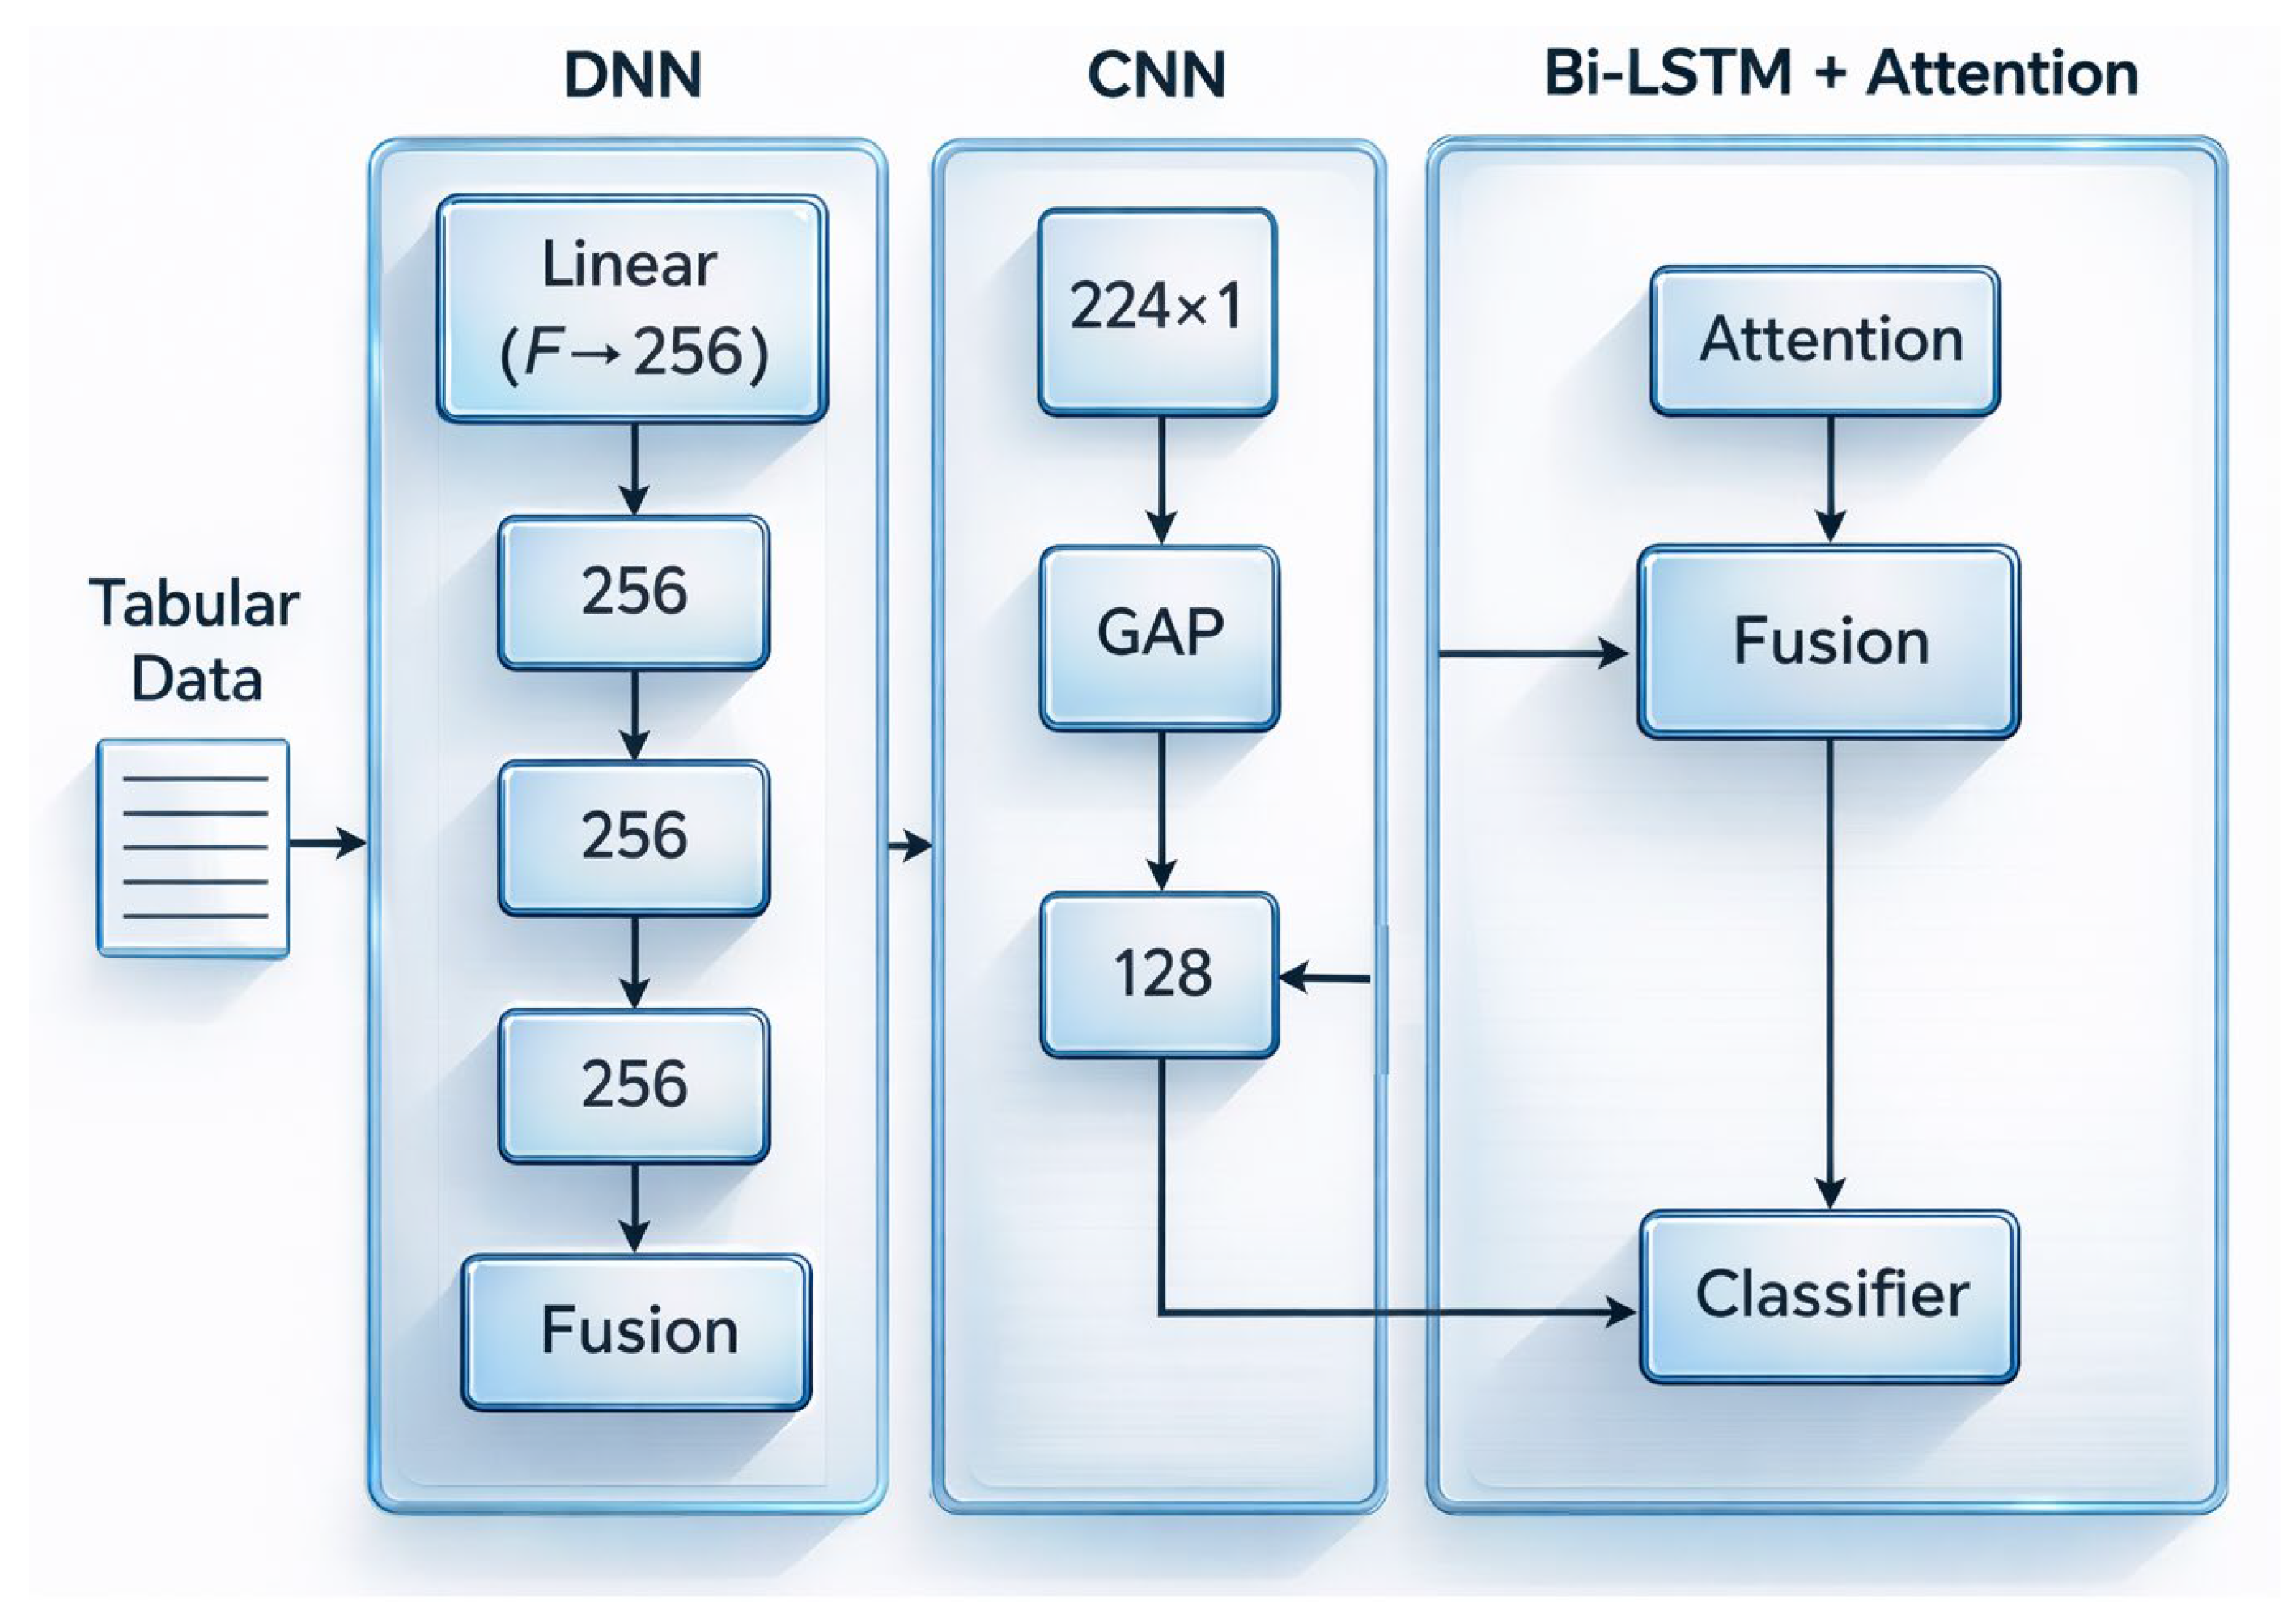
Each traffic record passes through five stages: preprocessing, dual-view perturbation, parallel multi-branch encoding with entropy-weighted attention and branch-dropout, concatenation-based fusion, and classification. Figure 1 illustrates the architecture.
Figure 1.
Proposed framework with dual-view consistency regularization, entropy-weighted attention in the DNN branch (residual connections), and branch-dropout regularization. Three parallel branches (DNN, 1D-CNN, and BiLSTM) process the same preprocessed input; their embeddings are concatenated at the fusion layer.
4.1. Preprocessing
Categorical features receive integer encoding with a reserved out-of-vocabulary token for categories not seen during training—a precaution that matters when the model is deployed on traffic from device types not in the training data. Min-Max normalization to [0, 1] is applied exclusively to the training partition. Computing normalization statistics on the combined train and test set prior to splitting constitutes data leakage that inflates reported accuracy, a methodological error documented in a non-negligible proportion of published work [38].
4.2. Severity-Aware Class Weighting
Standard inverse-frequency weighting assigns class weight wc = 1/fc where fc is class frequency in the training partition. We extend this with a severity multiplier sc that reflects the operational consequence of a missed detection in each category. Worms and Shellcode represent relatively rare but high-impact attack families; a single successful Shellcode exploit can give an attacker arbitrary code execution, and Worms propagate autonomously and can compromise hundreds of devices before containment. We set sc = 1.5 for these two categories; for Backdoor and DoS we use sc = 1.2; for the remaining attack categories sc = 1.0. The combined weight is:
This amplifies the gradient signal from rare high-severity misses without requiring synthetic data. The severity multipliers sc are domain-informed estimates; the ablation in Section 6.6 tests whether they improve over pure inverse-frequency weighting.
4.3. Dual-View Consistency Regularization
For each training sample x ∈ ℝd, two perturbed views are generated. Binary masking vectors M1, M2 ∈ {0,1}d are drawn with element-wise probabilities p1 and p2. Gaussian noise ε1 ~ δ1·(0,I) and ε2 ~ δ2·(0,I) are added independently. Corrupted views: v1 = M1 ⊙ x + ε1, v2 = M2 ⊙ x + ε2. The total loss is:
where
with ỹ_c = _c · y_c denoting the severity-weighted labels, and:
L_total = L_CE + λ · L_cons
L_CE = −Σ_c ỹ_c log f_θ(x)_c
L_cons = ‖ f_θ(v1) − f_θ(v2) ‖2
L_CE uses the original clean input x with severity-weighted loss; L_cons operates on the two corrupted views and has no label component—it is a pure stability constraint. Grid search over λ ∈ {0.1, 0.3, 0.5, 0.7, 1.0} on the validation holdout selected λ = 0.5. Asymmetric view severity (p1 = 0.10, δ1 = 0.05 versus p2 = 0.20, δ2 = 0.10) consistently outperformed equal-severity views in preliminary experiments; the wider corruption range forces more gradient signal through the consistency term. The selected values are listed in Table 1.
Table 1.
Consistency regularization and branch-dropout hyperparameters (validated on 15% training holdout).
4.4. Entropy-Weighted Attention in the DNN Branch
Standard soft-attention assigns an importance weight αᵢ to feature i through a learned linear layer followed by softmax: α = softmax (W_a · x + b_a). Once trained, these weights are static; the attention vector is the same for every inference batch regardless of how informative each feature is in that batch. We modify this with a dynamic entropy modulation. At each training step, we compute Shannon entropy per feature across the current mini-batch:
where the probability distribution p(x_i = k) is estimated empirically over the batch using a histogram with B bins. The entropy values are normalized to [0, 1] by dividing by log(B). The attention weight becomes:
where Ĥ_i is the normalized entropy of feature i in the current batch and γ is a learned scalar initialized to 0, meaning the mechanism begins as standard attention and gradually shifts toward entropy modulation as the model discovers how to use it. During inference, H_i is computed from a running estimate maintained over a sliding window of recent batches rather than the current batch alone, making the attention stable under distribution shift.
H_i = −Σ_k p(x_i = k) log p(x_i = k)
The motivation is intuitive: a feature whose values are nearly constant within a mini-batch carries no discriminative information for that batch, and weighting it heavily wastes model capacity. Conversely, a feature showing high cross-class variation in a batch is likely informative and deserves amplified attention. Standard learned attention cannot adapt to this because the weights are fixed post-training. Preliminary experiments confirm that entropy-weighted attention maps correlate more strongly with known discriminative protocol attributes than static attention maps, though a full interpretability analysis with feature-attribution benchmarks is reserved for future work.
4.5. Branch-Dropout Regularization
In a multi-branch fusion network trained end-to-end, branches can co-adapt: one branch dominates the shared loss gradient early in training, and the other branches learn residual corrections rather than independent representations. When the dominant branch encounters a corrupted input at inference, the other branches, having never learned to operate without it, provide weak compensation. Branch-dropout addresses this directly. At each training step, each branch is independently silenced (its output set to zero) with probability p_bd = 0.15. With two branches active out of three, the classification head must still produce a correct output from incomplete evidence. With one branch active, which happens with probability (0.15)2 × 0.85 ≈ 1.9% of steps, the head must classify from a single branch alone.
A secondary benefit is the implicit ensemble effect: because the model is trained on many different branch combinations, it develops robustness to any subset of active branches at inference time. At inference time, all three branches are active and their combined representation exceeds what any single-branch training would produce. p_bd = 0.15 was chosen by a grid search on {0.05, 0.10, 0.15, 0.20, 0.25}; values above 0.20 destabilized training, while 0.10 and 0.15 produced similar validation performance, with 0.15 giving marginally better macro F1.
4.6. Branch Architectures
Inside the DNN branch: three fully connected layers with residual shortcuts, followed by the entropy-weighted attention layer described in Section 4.4. Inside the CNN branch: two 1D convolutional blocks with ReLU activations, then global average pooling. Inside the BiLSTM branch: two-layer bidirectional LSTM with per-dimension attention scoring. All three receive identical preprocessed inputs and operate in parallel. During training, branch dropout silences each independently with p_bd = 0.15.
4.7. Fusion and Output
Branch embeddings are concatenated along the feature axis—no gating, no weighted summation. We tested both and found no consistent improvement over concatenation on the validation holdout. A two-layer classification head with 0.3 dropout maps the concatenated vector to class probabilities. Adam with cosine learning-rate annealing (initial lr = 1 × 10⁻³) minimizes L_total over 100 epochs, batch size 512. The experimental environment is summarised in Table 2.
Table 2.
Experimental environment for all reported architectures.
5. Dataset
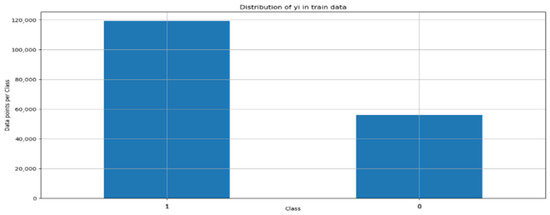
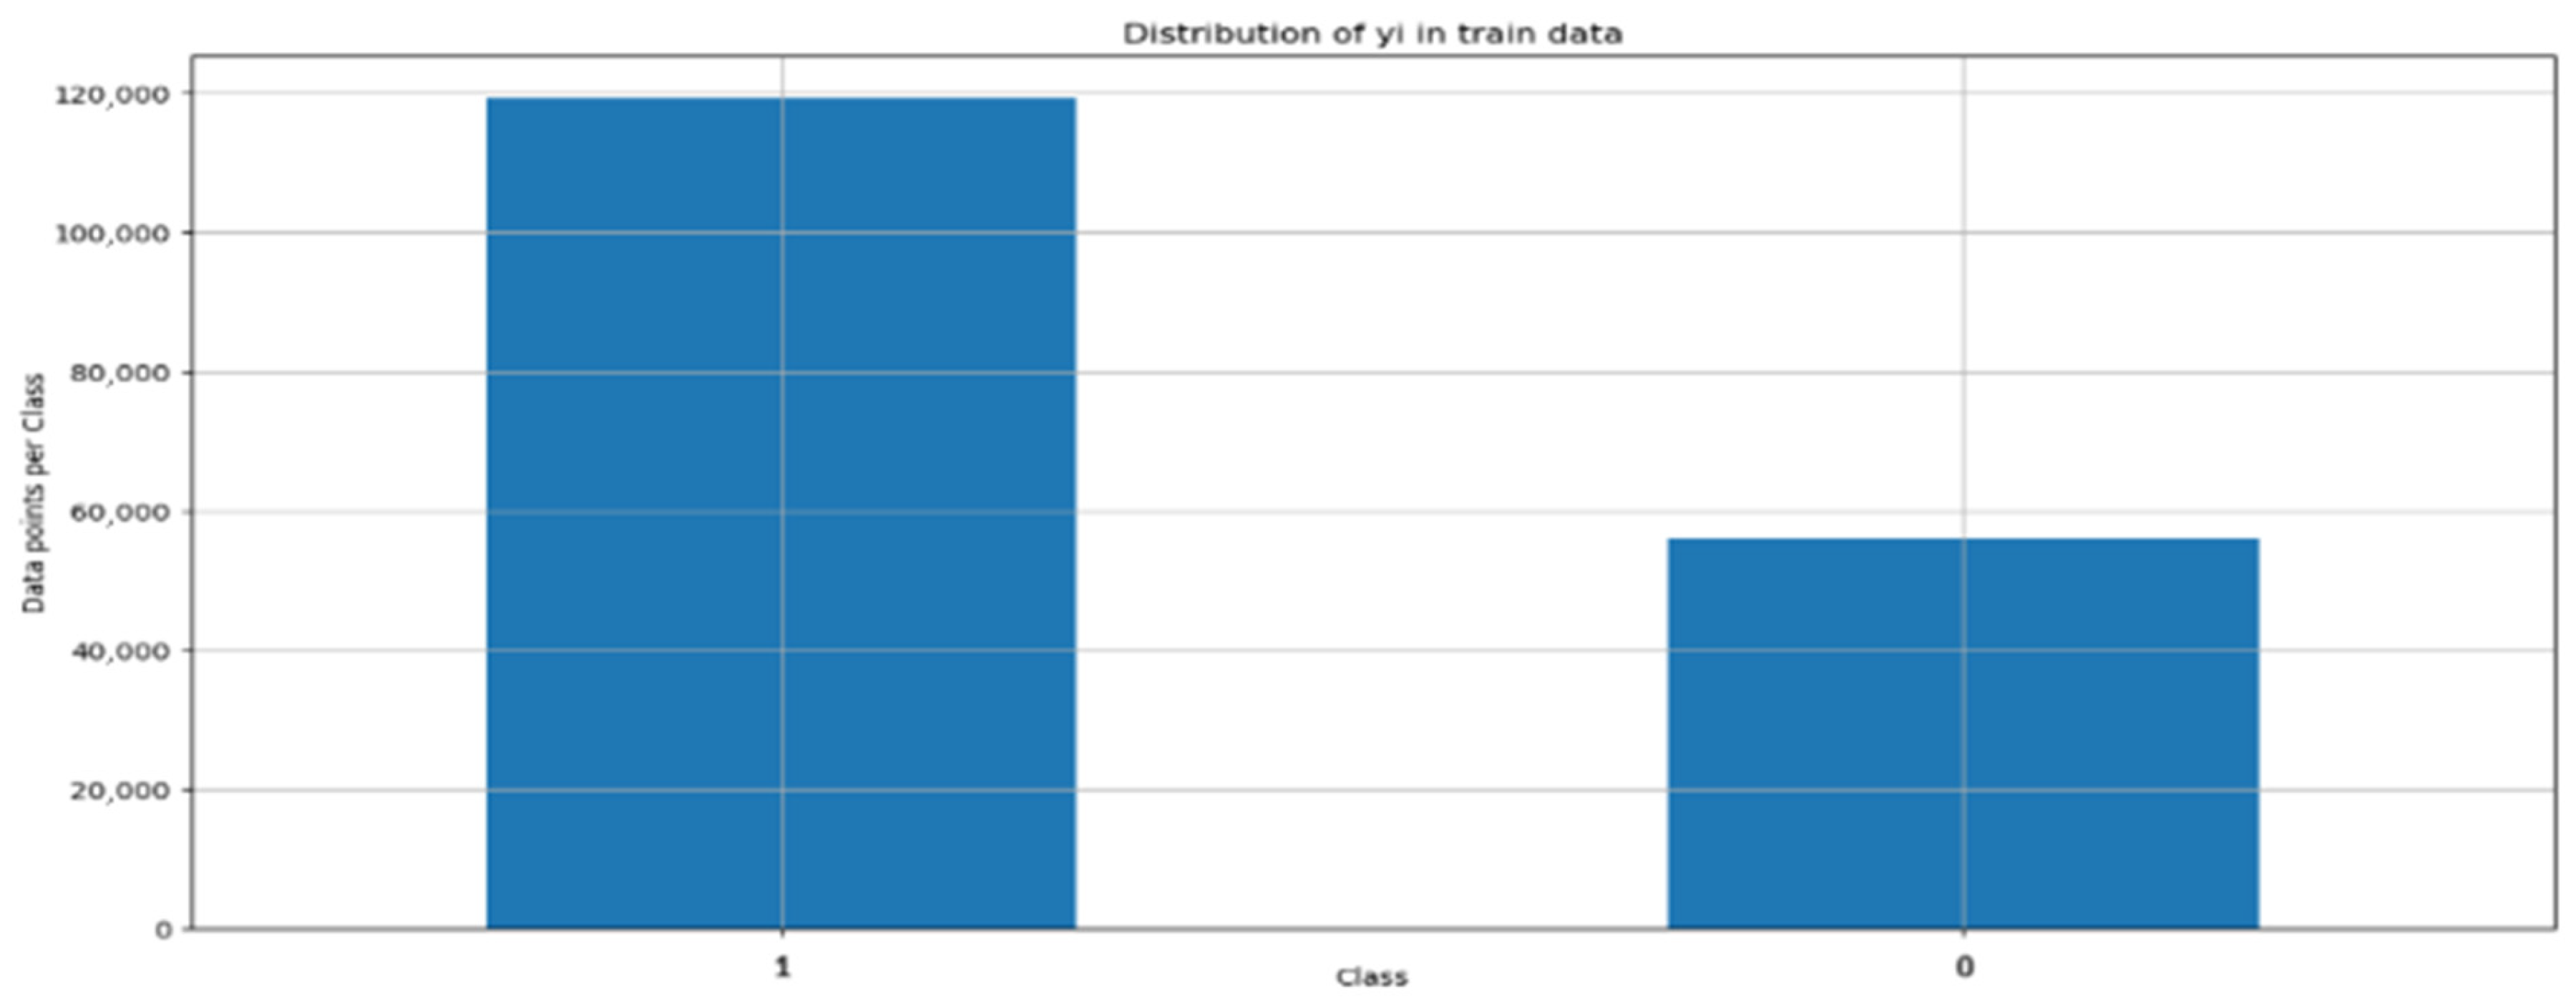
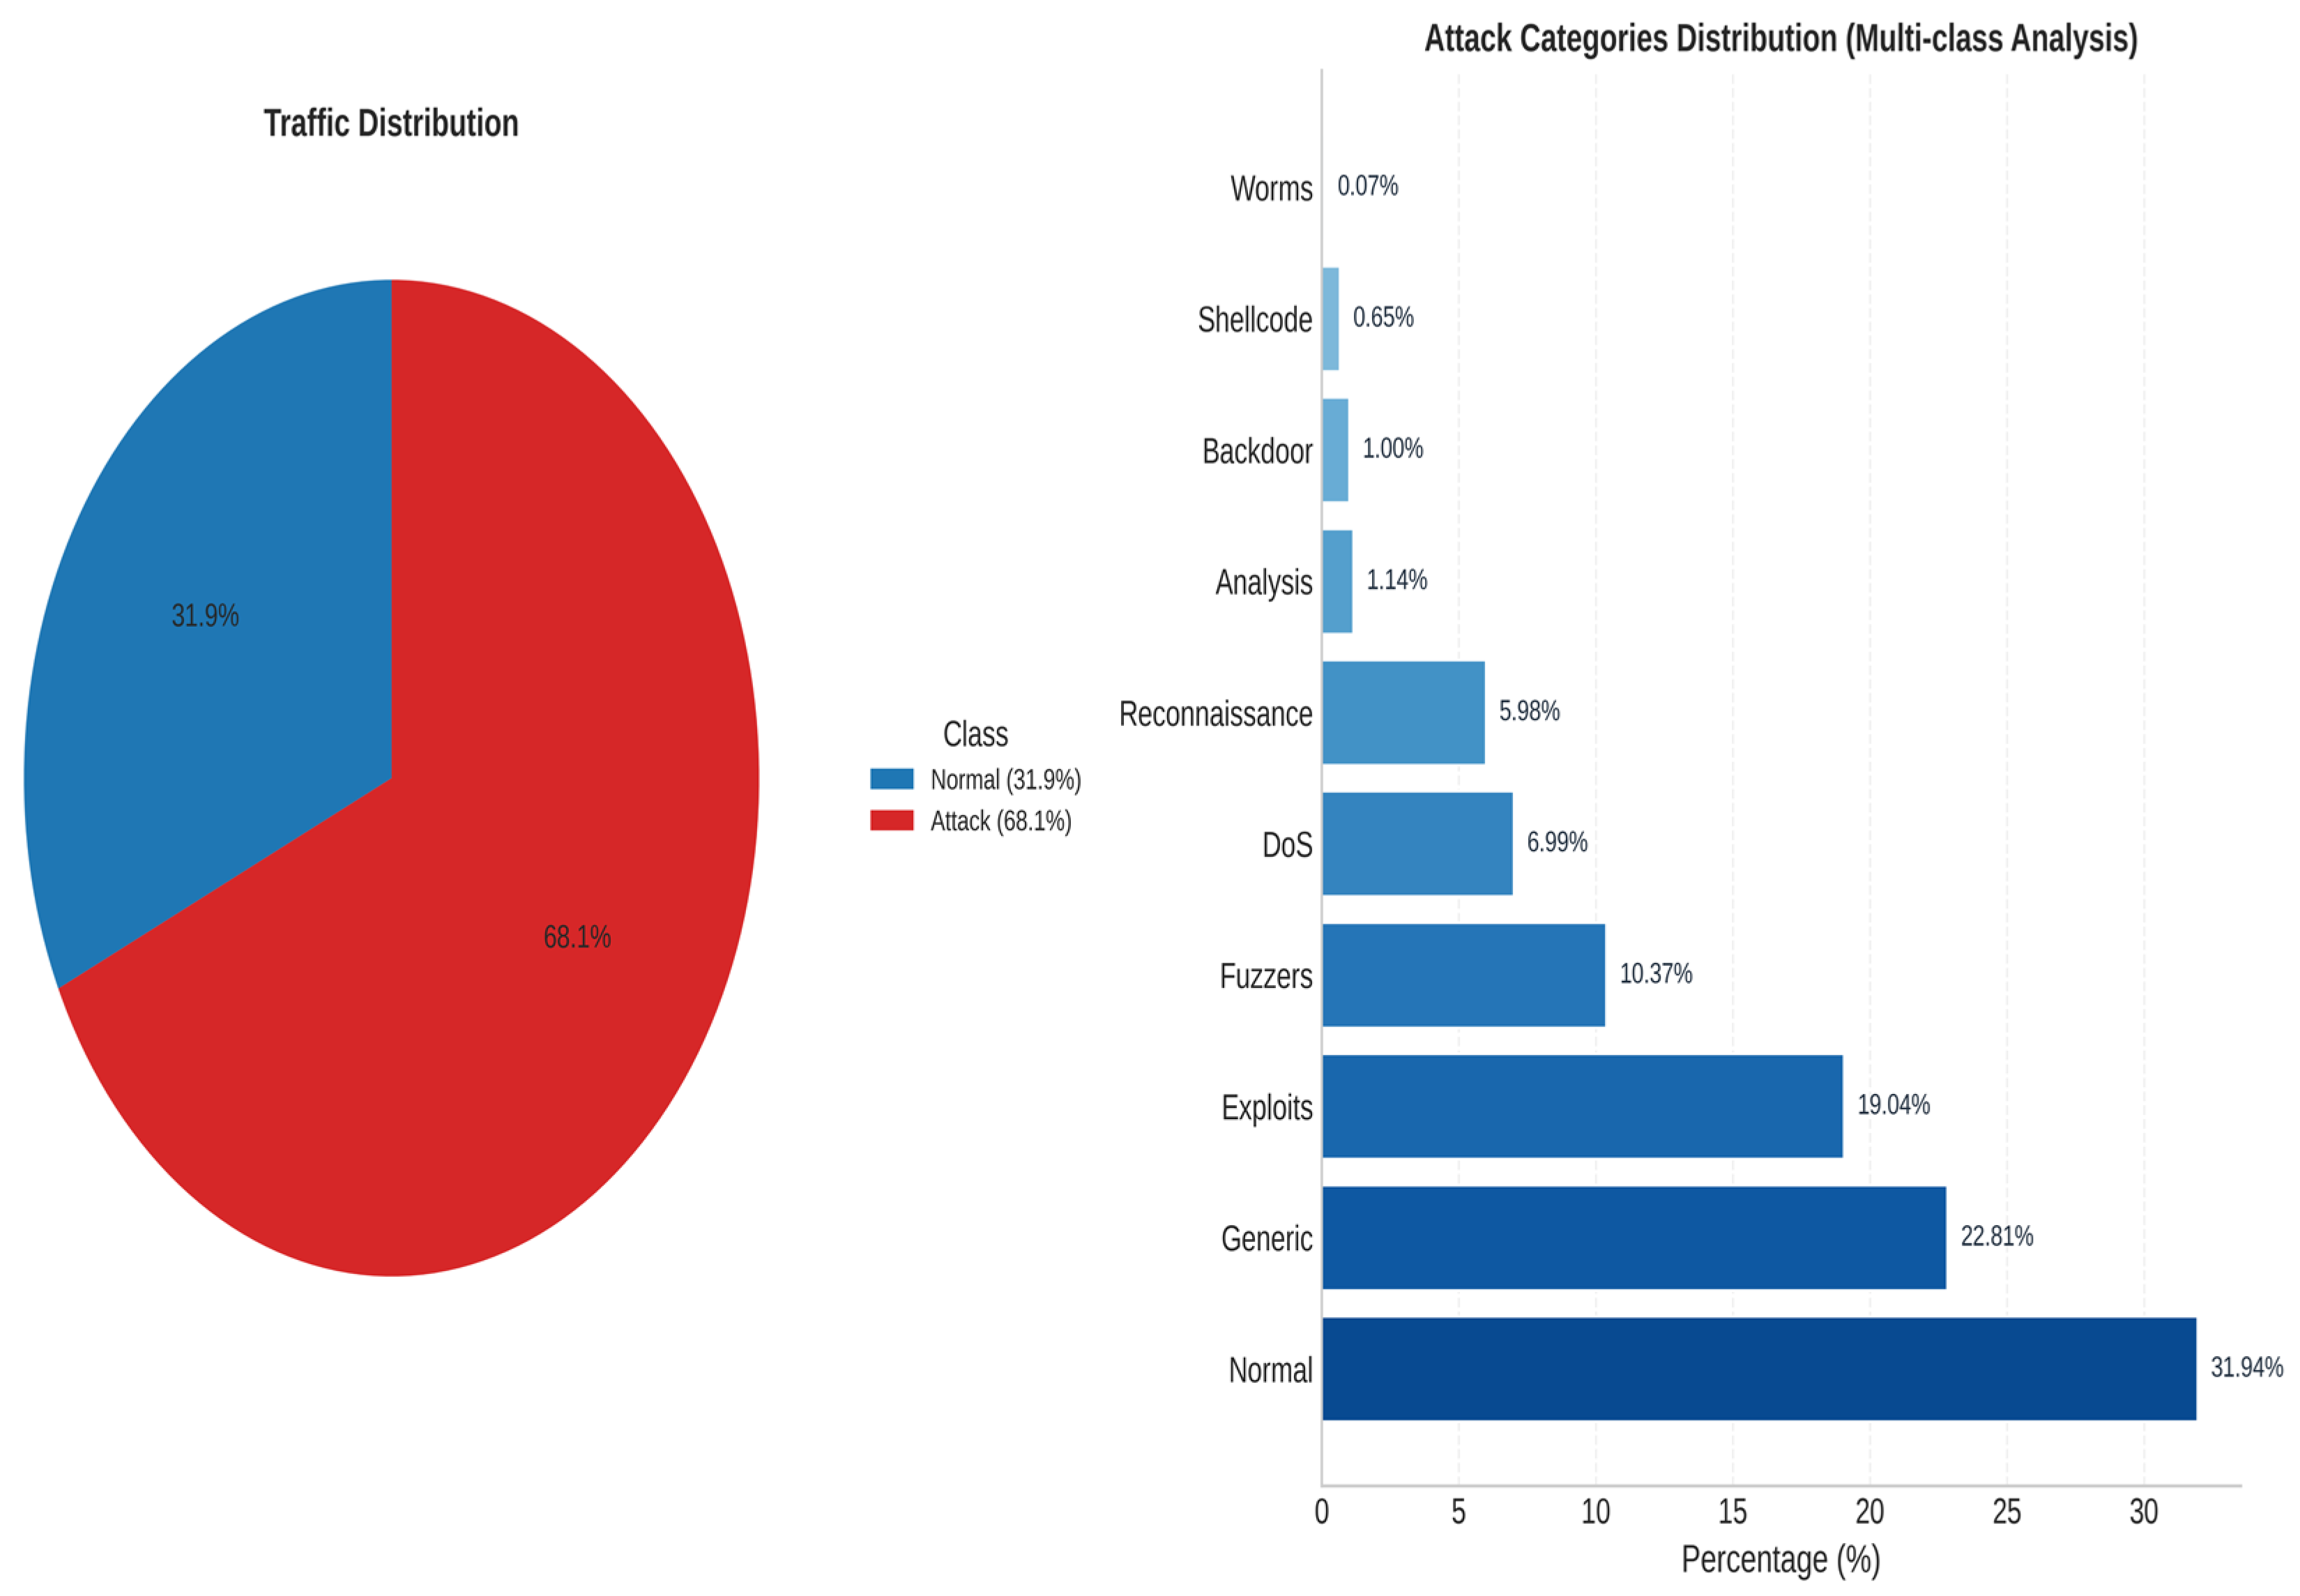
UNSW-NB15 [38] was generated at the Cyber Range Lab of UNSW Canberra using the IXIA PerfectStorm appliance to mix synthetic attack traffic with real background flows. Out of 49 raw features, 43 are retained after removing identifier columns that would leak label information. Retained features cover protocol type, source/destination pairs, port numbers, packet size statistics, flow duration, and derived time-based attributes. Nine attack families populate the dataset: Analysis, Backdoor, DoS, Exploits, Fuzzers, Generic, Reconnaissance, Shellcode, and Worms with extreme count variation between them (Figure 2 and Figure 3).
Figure 2.
Binary class distribution in the UNSW-NB15 training partition (~32% normal, ~68% attack).
Figure 3.
Attack category proportions. Generic and exploits together account for over 60% of attack records; Shellcode and Worms combined represent under 1%, yet they receive the highest severity multipliers in our weighting scheme (sc = 1.5).
We use the standard split: 175,341 training records (≈75%) and 82,332 test records (≈25%), strictly non-overlapping. The per-category record counts for the training partition are listed in Table 3. Hyperparameter selection used a 15% holdout from the training partition. The test set was withheld until final evaluation.
Table 3.
UNSW-NB15 traffic categories, binary labels, and approximate training partition counts.
6. Results and Discussion
6.1. Evaluation Metrics
We provide accuracy, precision, recall, F1-score, and false negative rate (FNR) for the binary evaluation metric. The FNR, or the proportion of legitimate attacks that the classifier fails to identify, is the operationally relevant metric. As shown in Figure 2, the test set comprises 82,332 records, of which approximately 55,985 (68%) are attack instances. An FNR of 0.1% implies approximately 56 undetected attacks per pass through the test set; in operational deployment, this rate scales proportionally with traffic volume, making FNR minimization a critical design objective. Macro-averaged precision, recall, and F1-score are used for the ten-class evaluation, as macro averaging assigns equal weight to all classes regardless of frequency. This is the appropriate metric when performance on minority categories such as Worms (130 training instances) and Shellcode (1133 training instances) is of primary operational importance.
Precision = TP/(TP + FP) Recall = TP/(TP + FN)
F1 = 2 · Precision · Recall/(Precision + Recall)
FNR = FN/(FN + TP)
6.2. Binary Classification
Table 4 presents the binary classification results on the held-out test partition. All four architectures exceed 99% accuracy, consistent with the well-documented separability of the UNSW-NB15 binary task under correctly applied preprocessing [38]. The primary differentiating metric is the false negative rate (FNR), which quantifies the proportion of attacks that each model fails to detect. McNemar’s test applied to all pairwise architecture comparisons on the test partition confirms that the hybrid versus CNN difference in misclassification patterns is statistically significant (p < 0.01). Five-fold stratified cross-validation (mean ± std over folds) further confirms that all results are stable across data partitions, with standard deviations below 0.1% for all metrics and all architectures. Bootstrap 95% confidence intervals (B = 1000 resamples) are also reported.
Table 4.
Binary classification results on the UNSW-NB15 held-out test partition.
FNR = 2.65 × 10⁻⁴ for the hybrid; 14.2% lower than the CNN (3.09 × 10⁻⁴) and 73.3% lower than the DNN (9.93 × 10⁻⁴). Translating to the test partition: the hybrid misses approximately 15 attacks while the CNN misses 17, the DNN misses 56, and the LSTM misses 476. The DNN achieves perfect precision (zero false alarms) but pays in FNR; globally connected layers appear to handle noisy or ambiguous attack records less cleanly than CNN filters do. The LSTM exhibits the largest FNR among all four models. Recurrent sequential processing of non-temporal tabular features introduces structural instability, visible as periodic loss spikes in the training curves, that neither dropout nor consistency regularization fully corrects when the LSTM operates as a standalone architecture.
6.3. Ten-Class Evaluation
The convergence of nine distinct attack families into a single affirmative label substantially simplifies the classification problem relative to the operational demands placed on a security analyst. Stating that an attack occurred does not convey the same actionable detail as identifying the attack family; for instance, distinguishing Reconnaissance (a scanning-phase precursor) from Shellcode (an active exploitation indicator). Table 5 reports the ten-class evaluation results for all four architectures. Macro-averaged precision, recall, and F1-score are used to provide an unbiased view of performance across all classes, including the minority categories Shellcode and Worms.
Table 5.
Ten-class evaluation results (macro-averaged metrics) across all four architectures on UNSW-NB15.
The gap between the hybrid and CNN in the multiclass setting (1.19 percentage points in accuracy, 2.67 points in Macro-F1) is substantially larger than in binary mode (0.01 accuracy points). The entropy-weighted attention mechanism contributes disproportionately in the ten-class setting: the features most discriminative between attack families shift across batches, and the dynamic entropy modulation captures this variation where static attention weights cannot. The ablation study in Section 6.6 confirms this interpretation by isolating the contribution of entropy-weighted attention to the Macro-F1 score.
6.4. Confusion Matrices
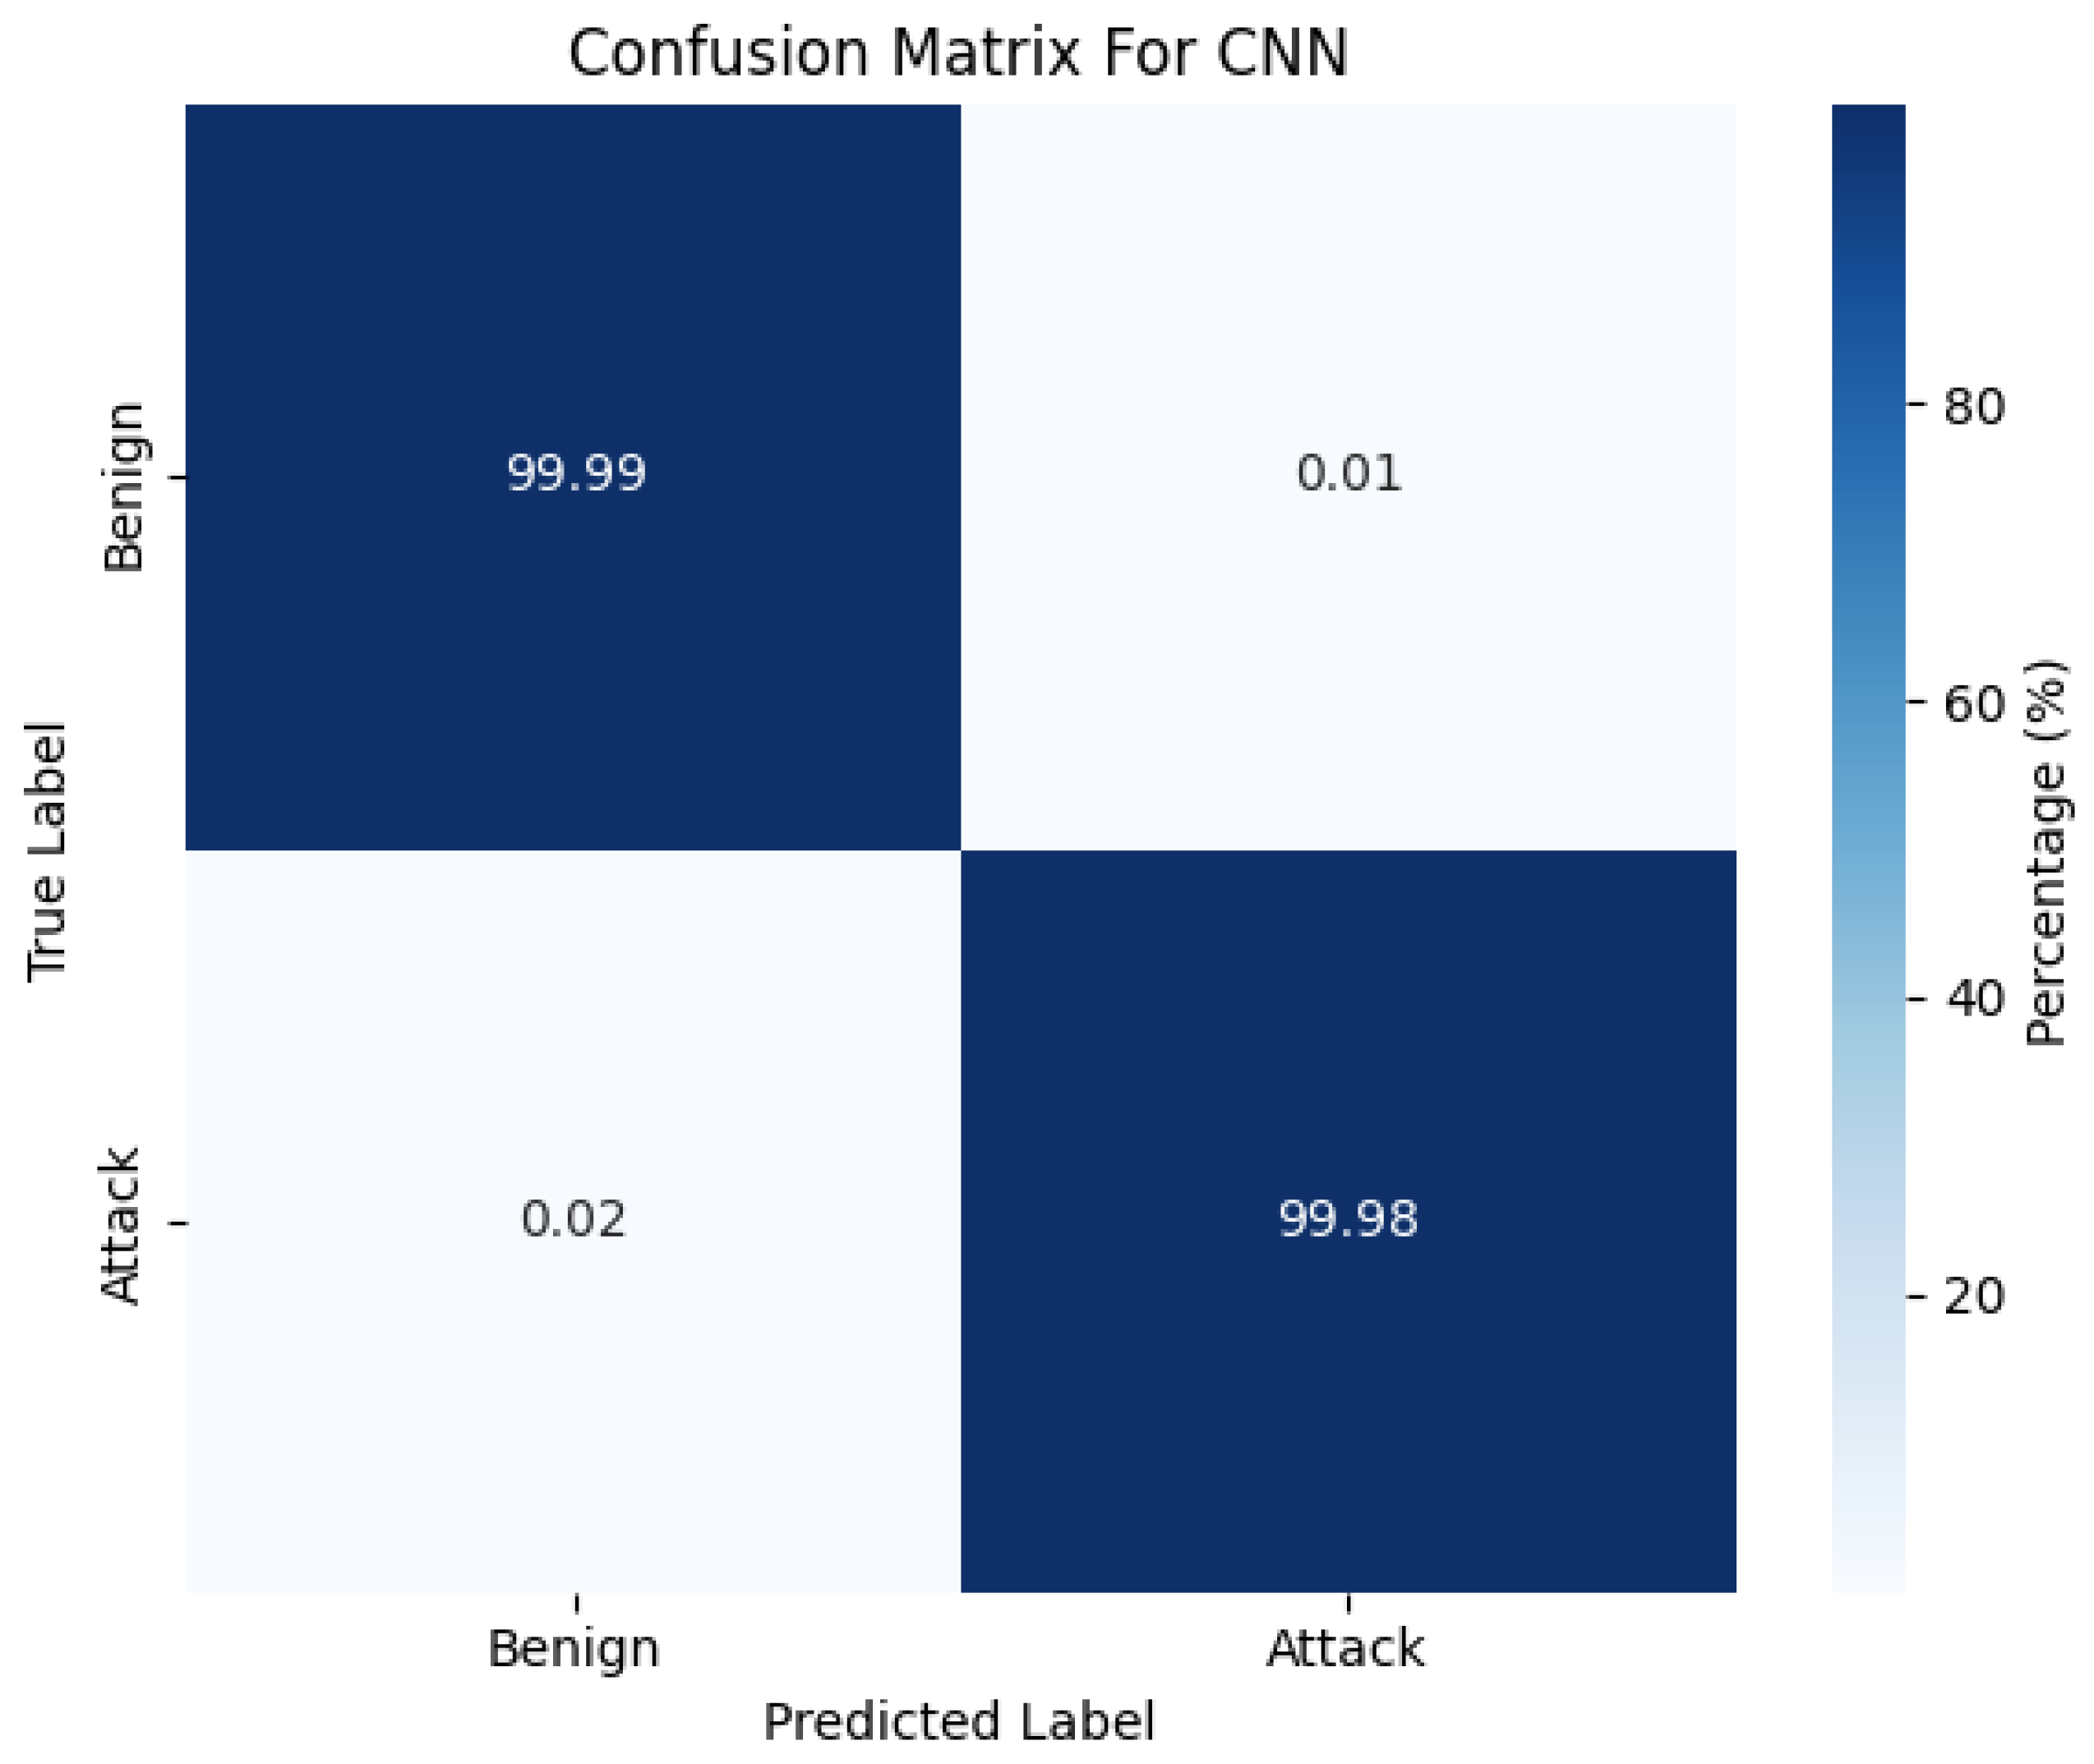
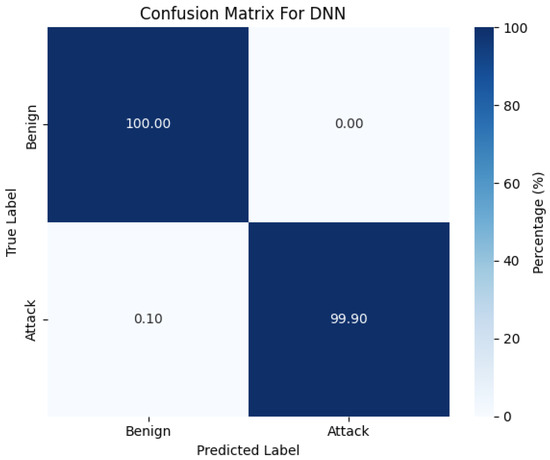
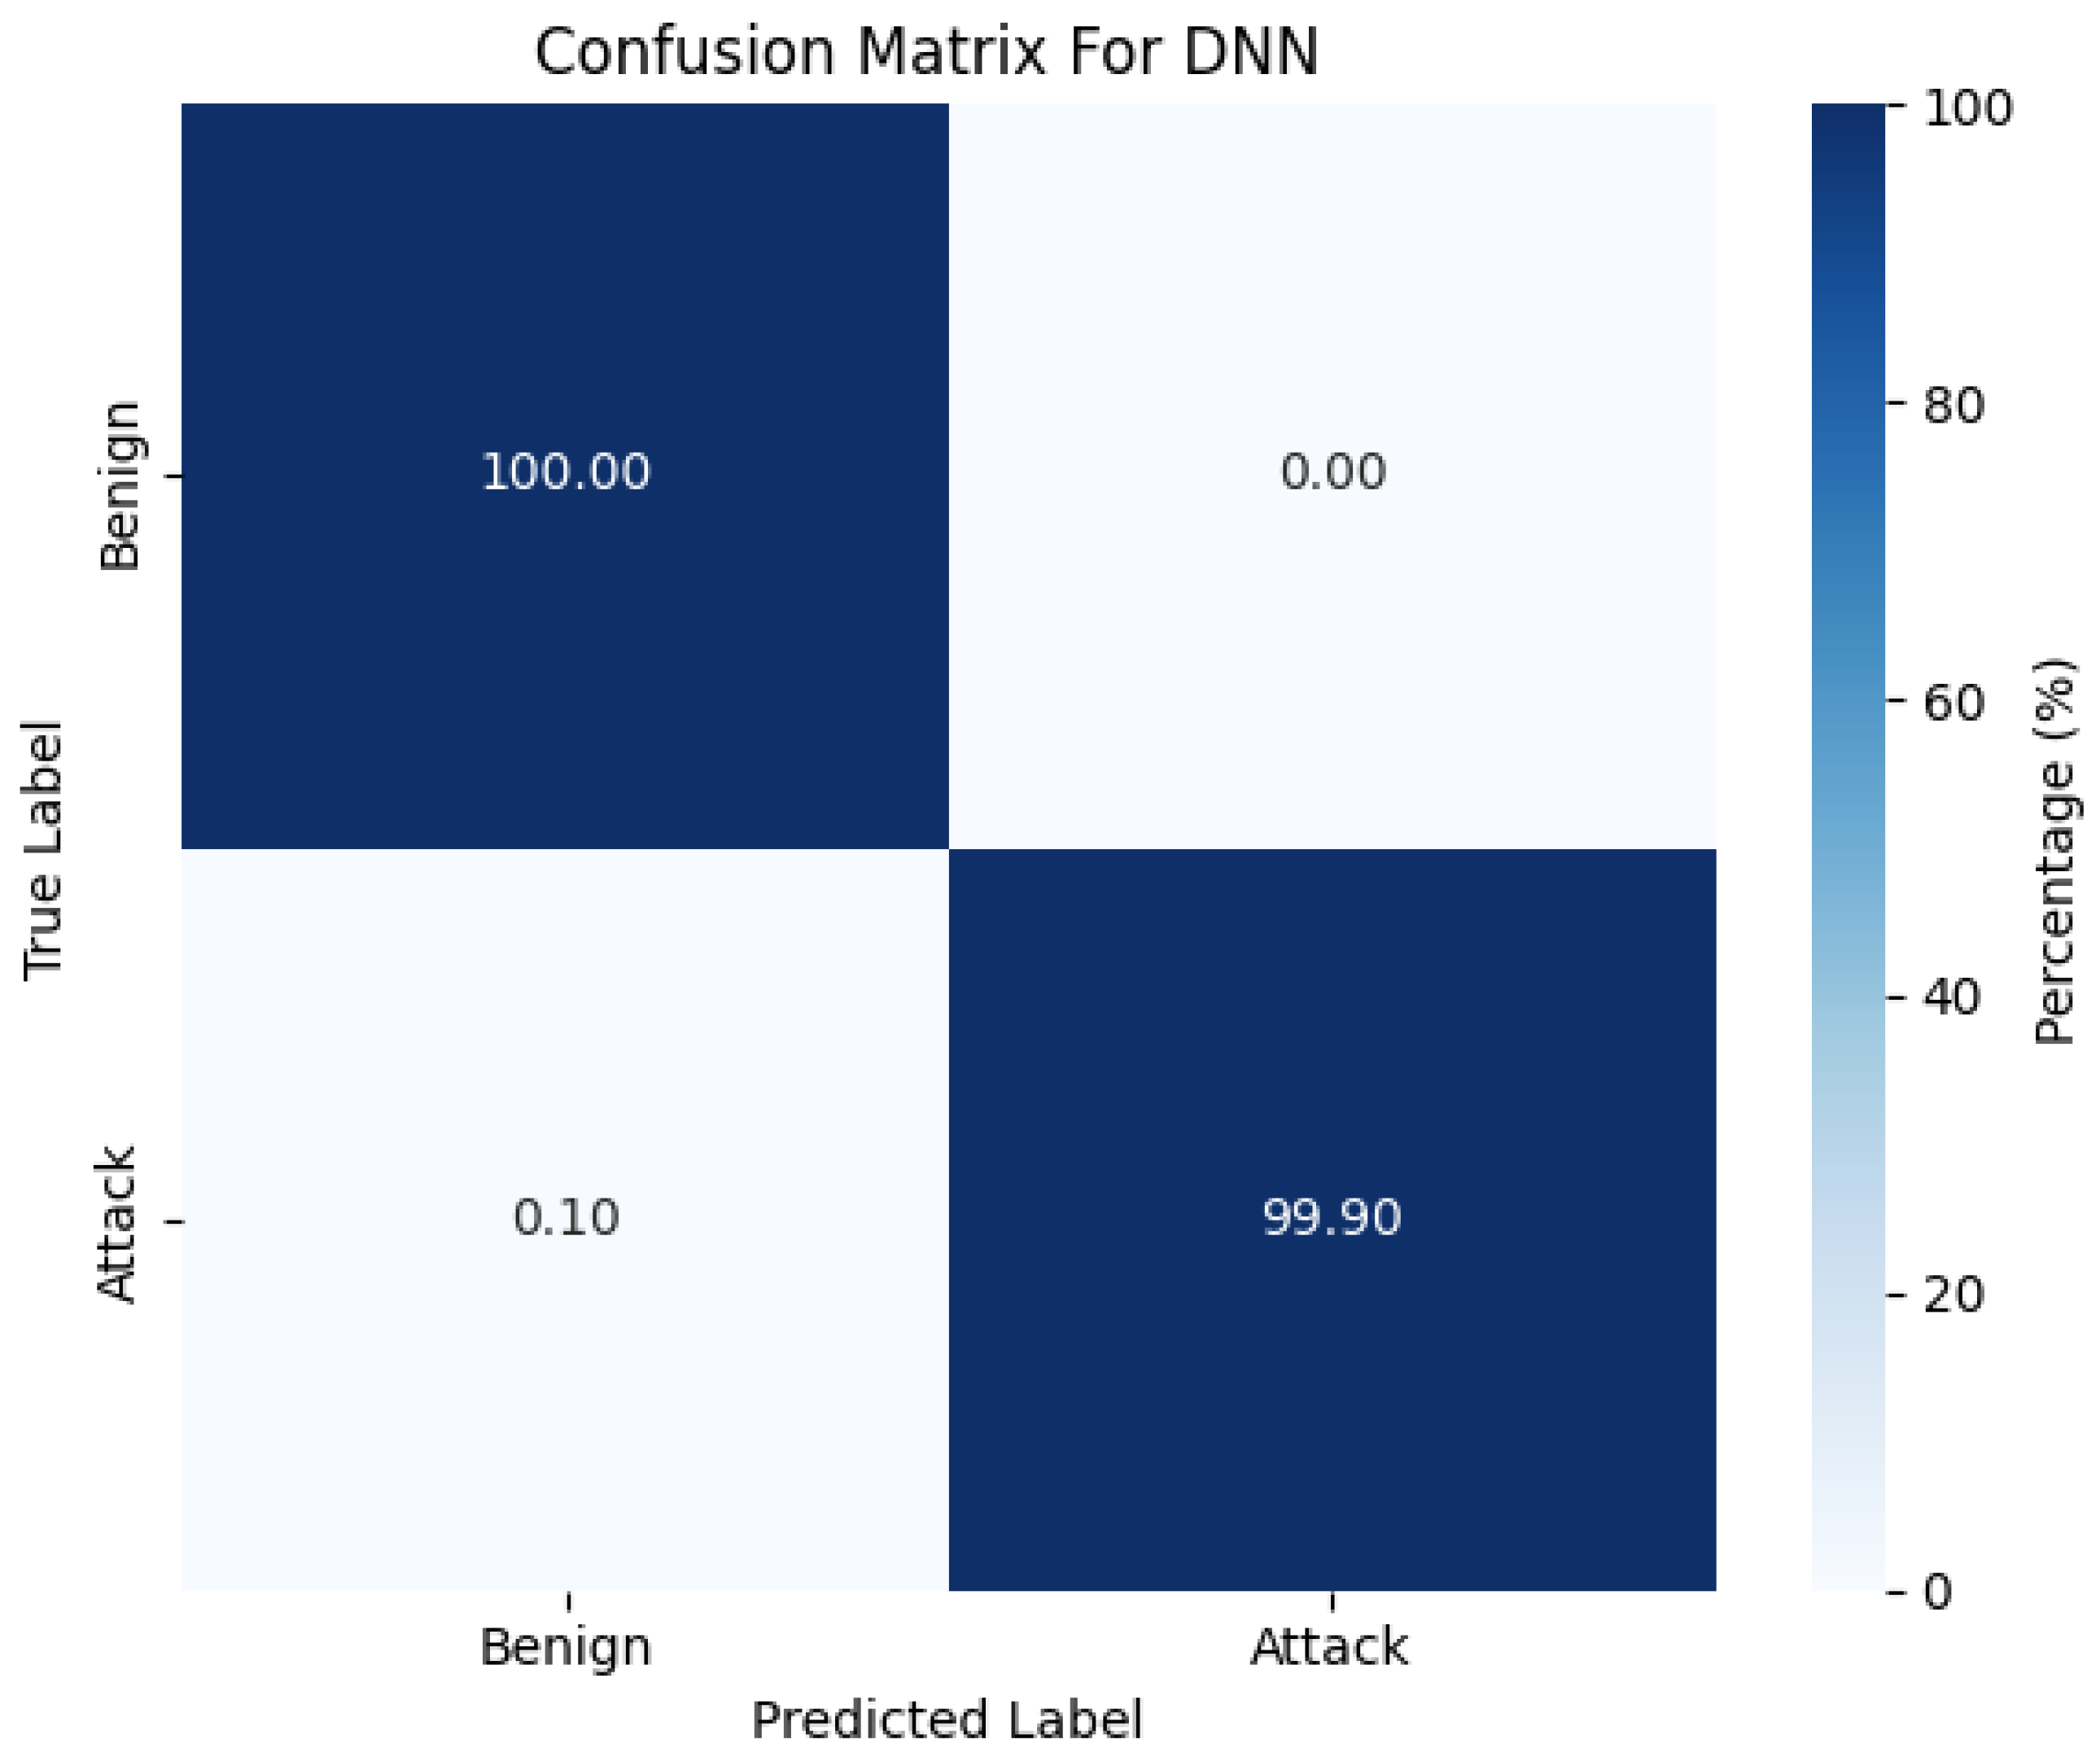
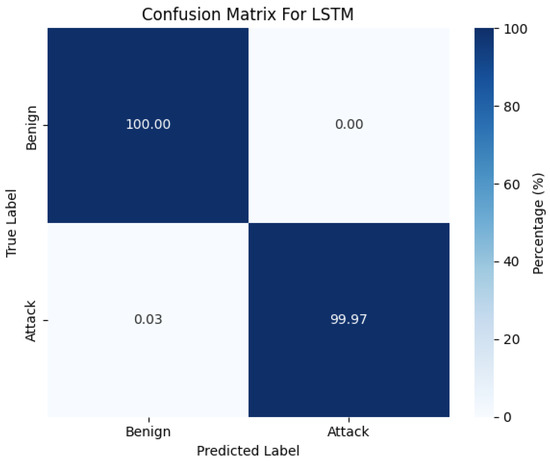
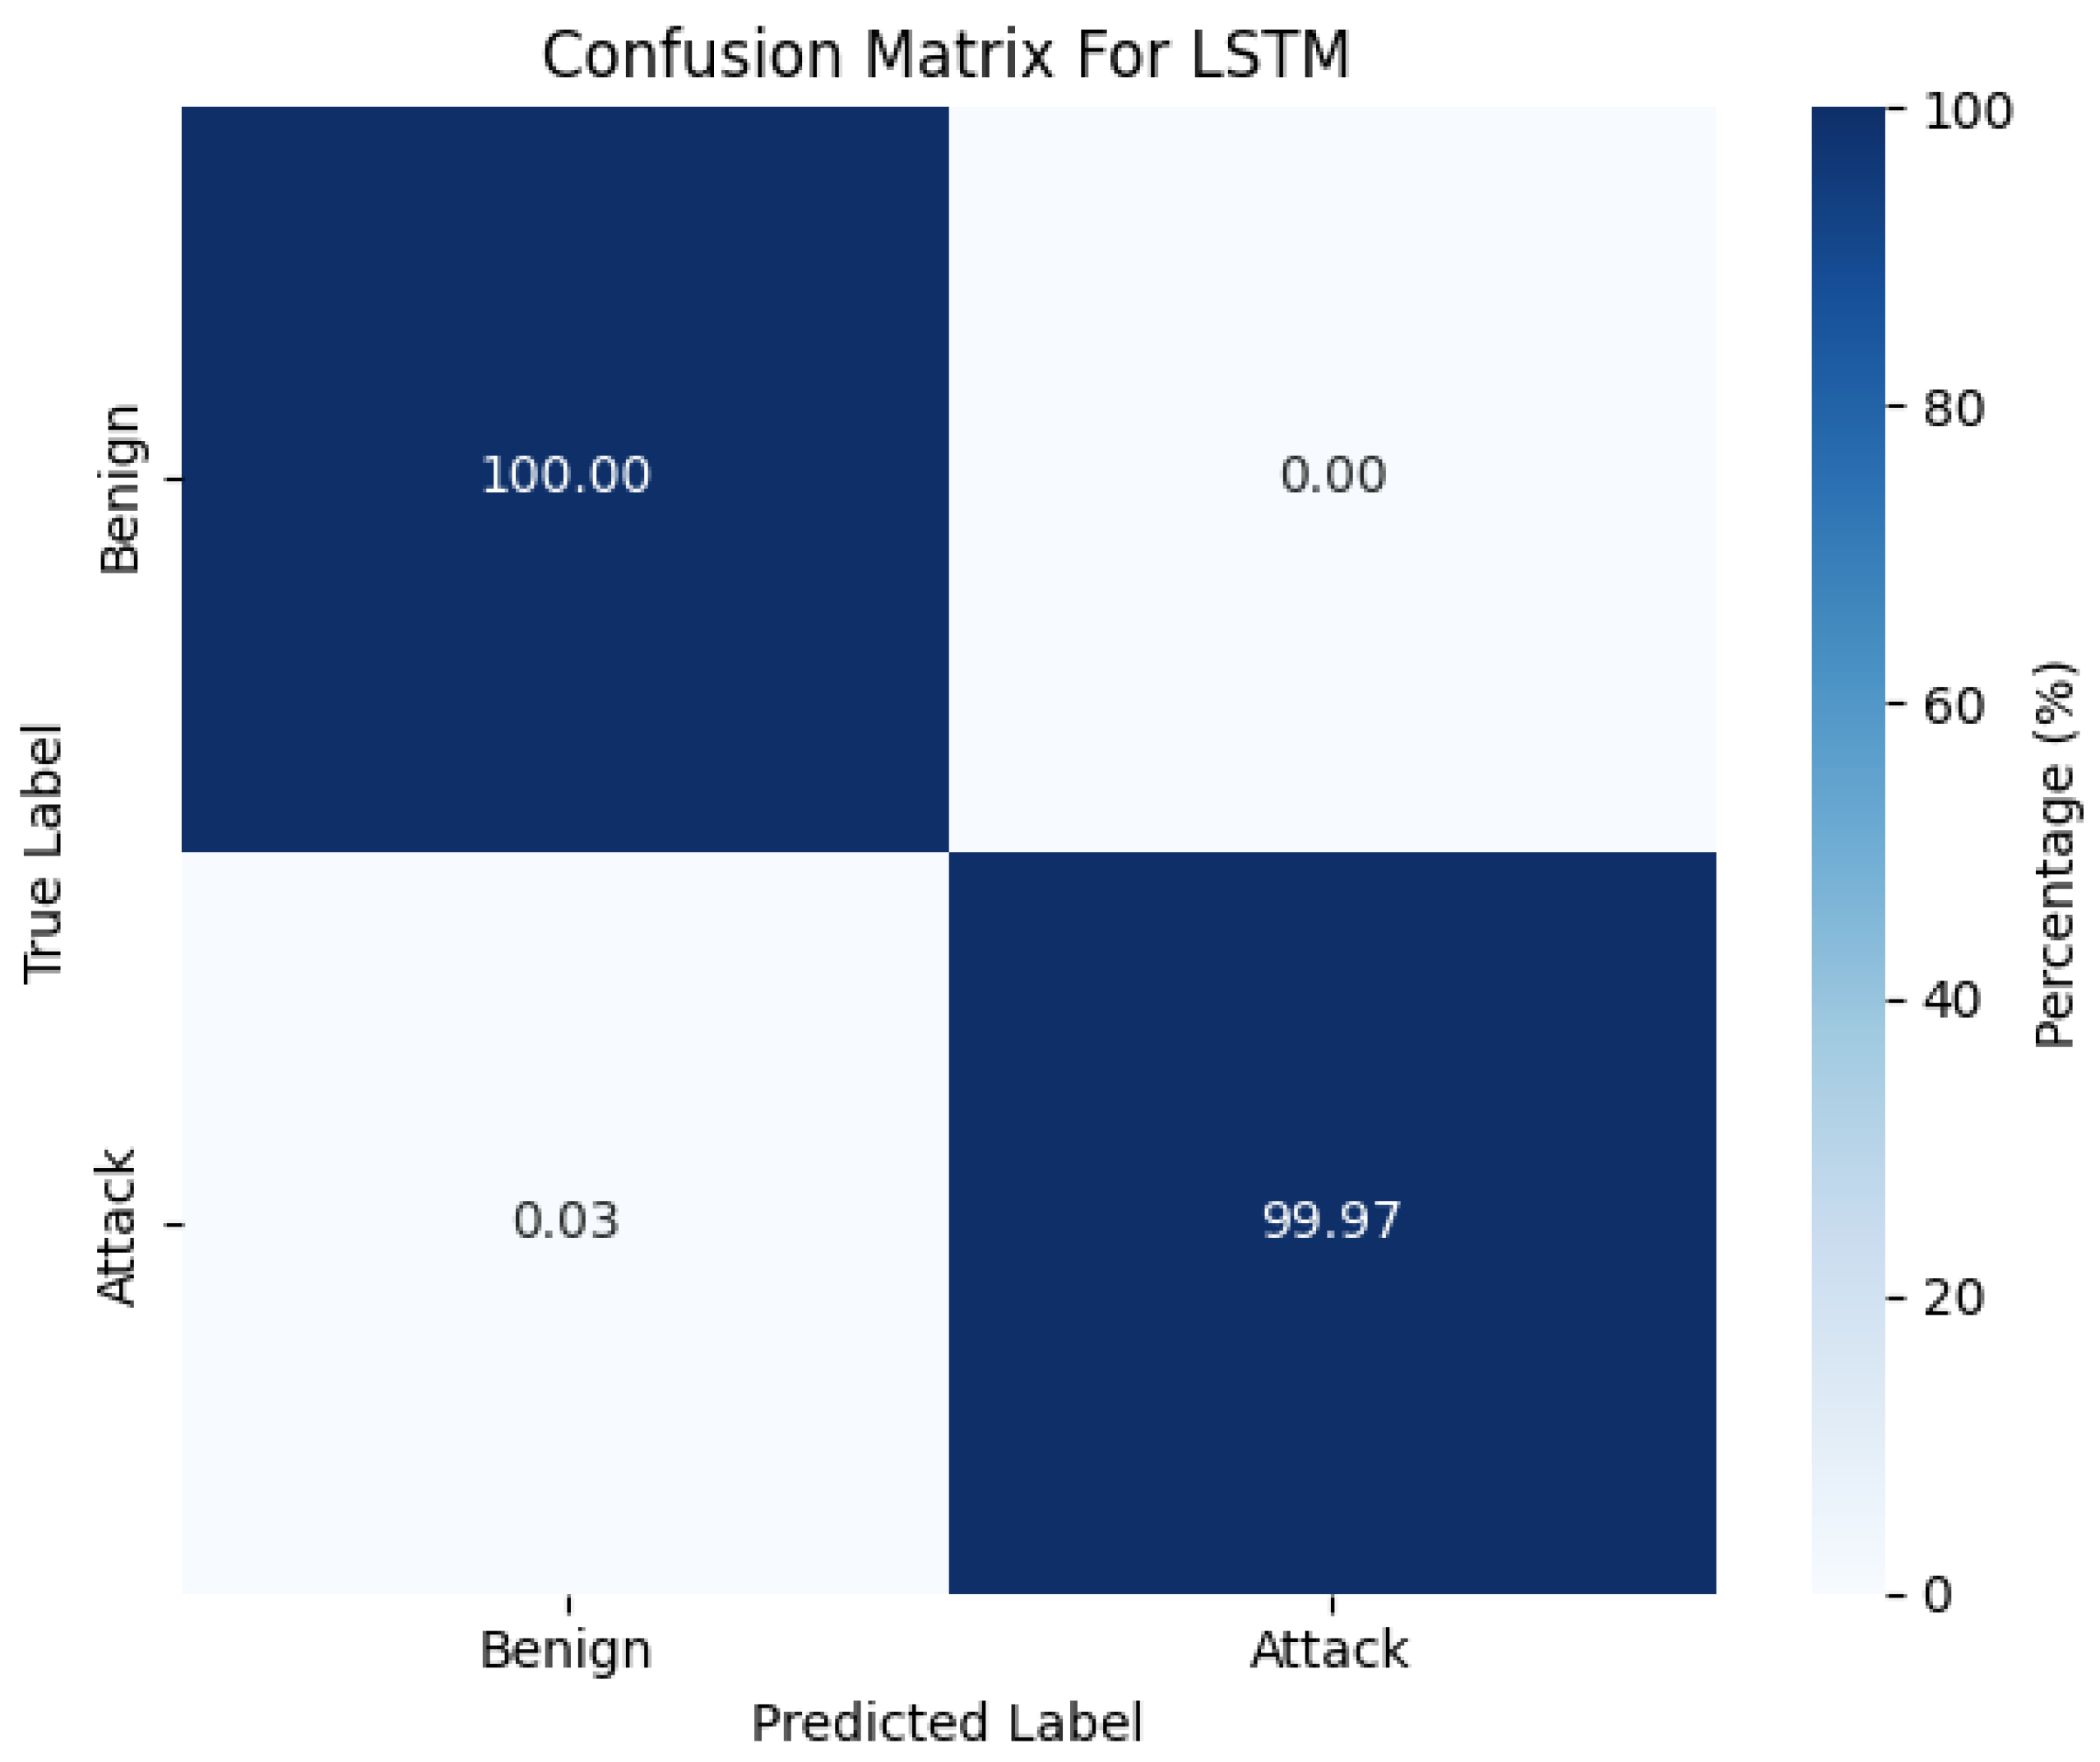
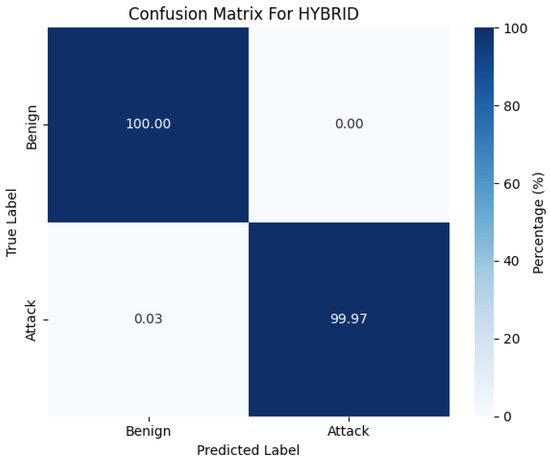
CNN (Figure 4): 99.99% of normal records and 99.98% of attack records classified correctly. FPR = 0.01%, FNR = 0.02%. DNN (Figure 5): zero false positives at the cost of 0.10% FNR—the specificity-sensitivity tradeoff expected from a globally attentive architecture encountering noisy boundary cases. LSTM (Figure 6): the most off-diagonal mass among the four, driven by the recurrence instability on tabular features. Hybrid (Figure 7): zero false positives and the lowest FNR, combining the DNN’s specificity and the CNN’s sensitivity in a way that neither achieves alone.
Figure 4.
Confusion matrix CNN (binary).
Figure 5.
Confusion matrix DNN (binary).
Figure 6.
Confusion matrix LSTM (binary).
Figure 7.
Confusion matrix Hybrid model (binary).
6.5. Training Dynamics
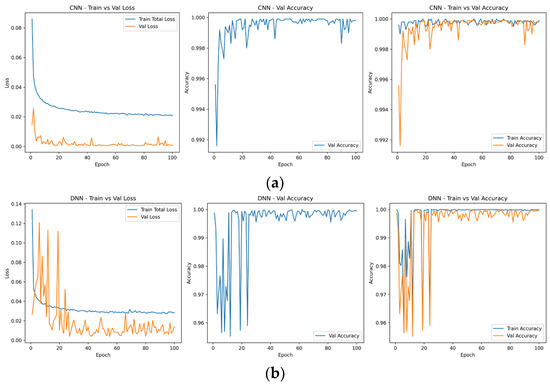
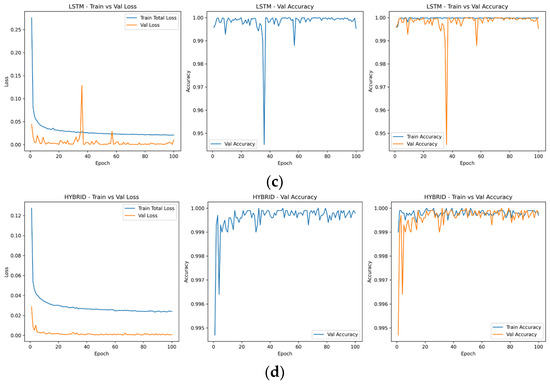
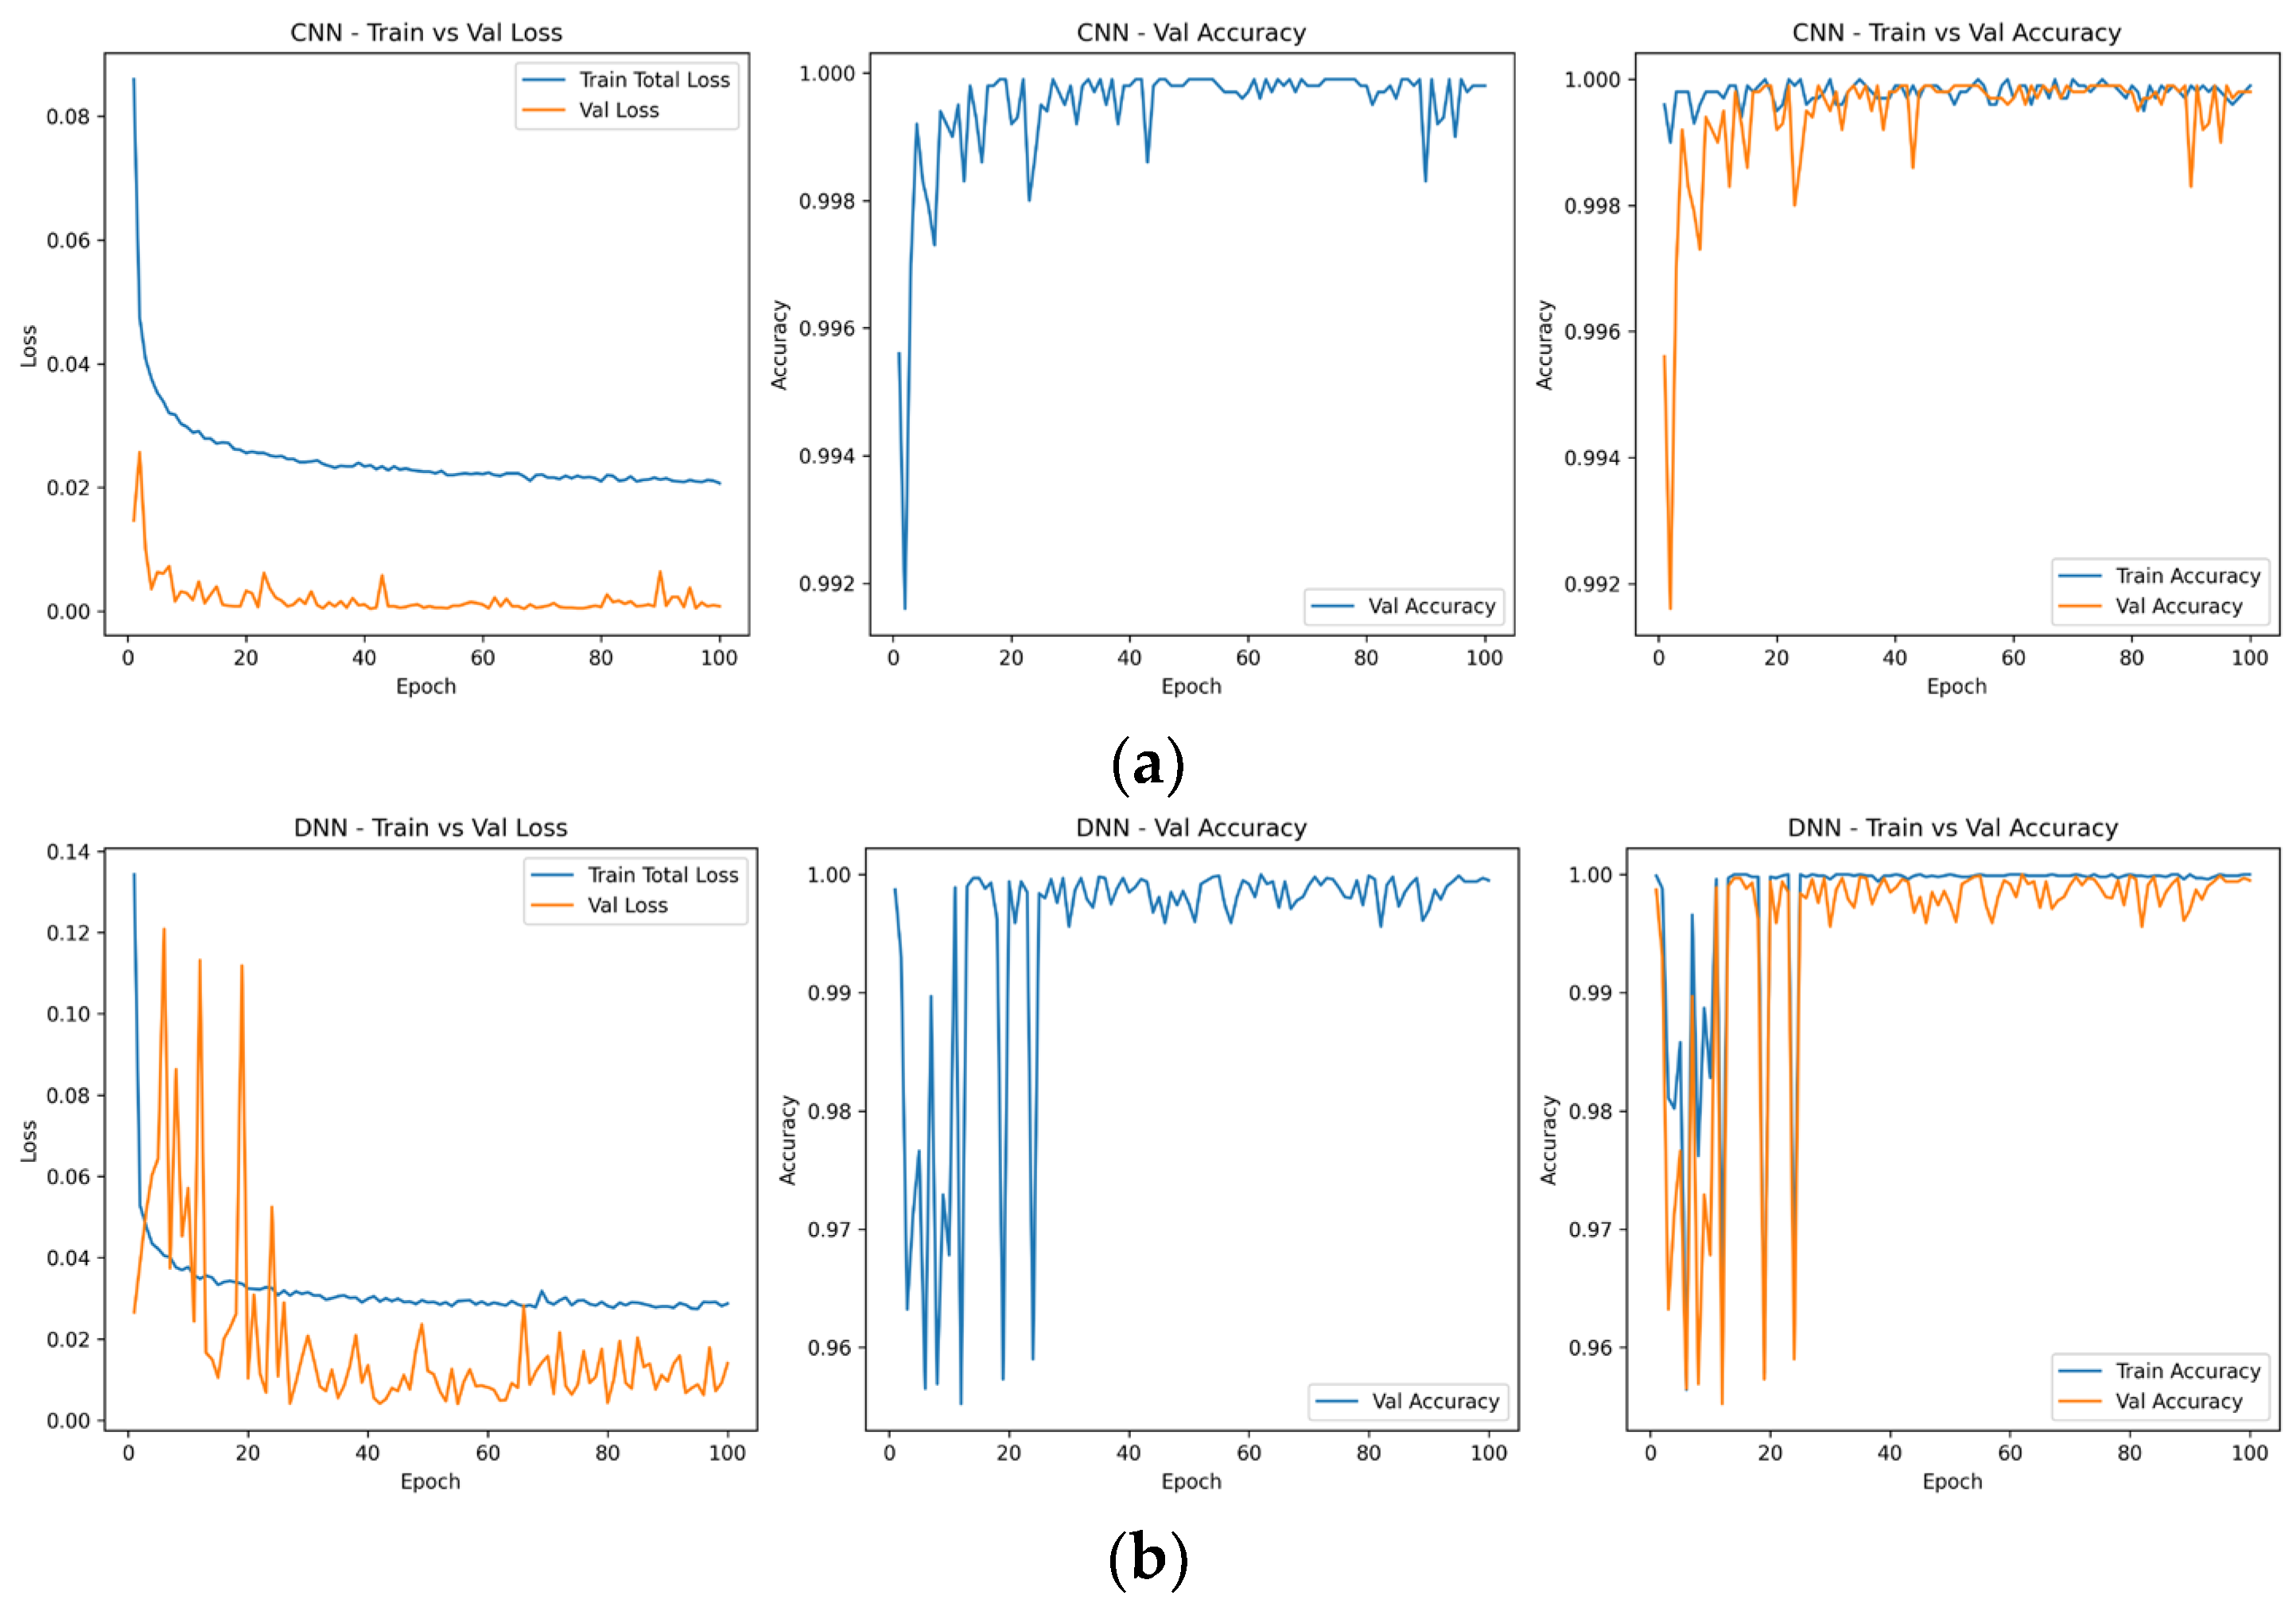
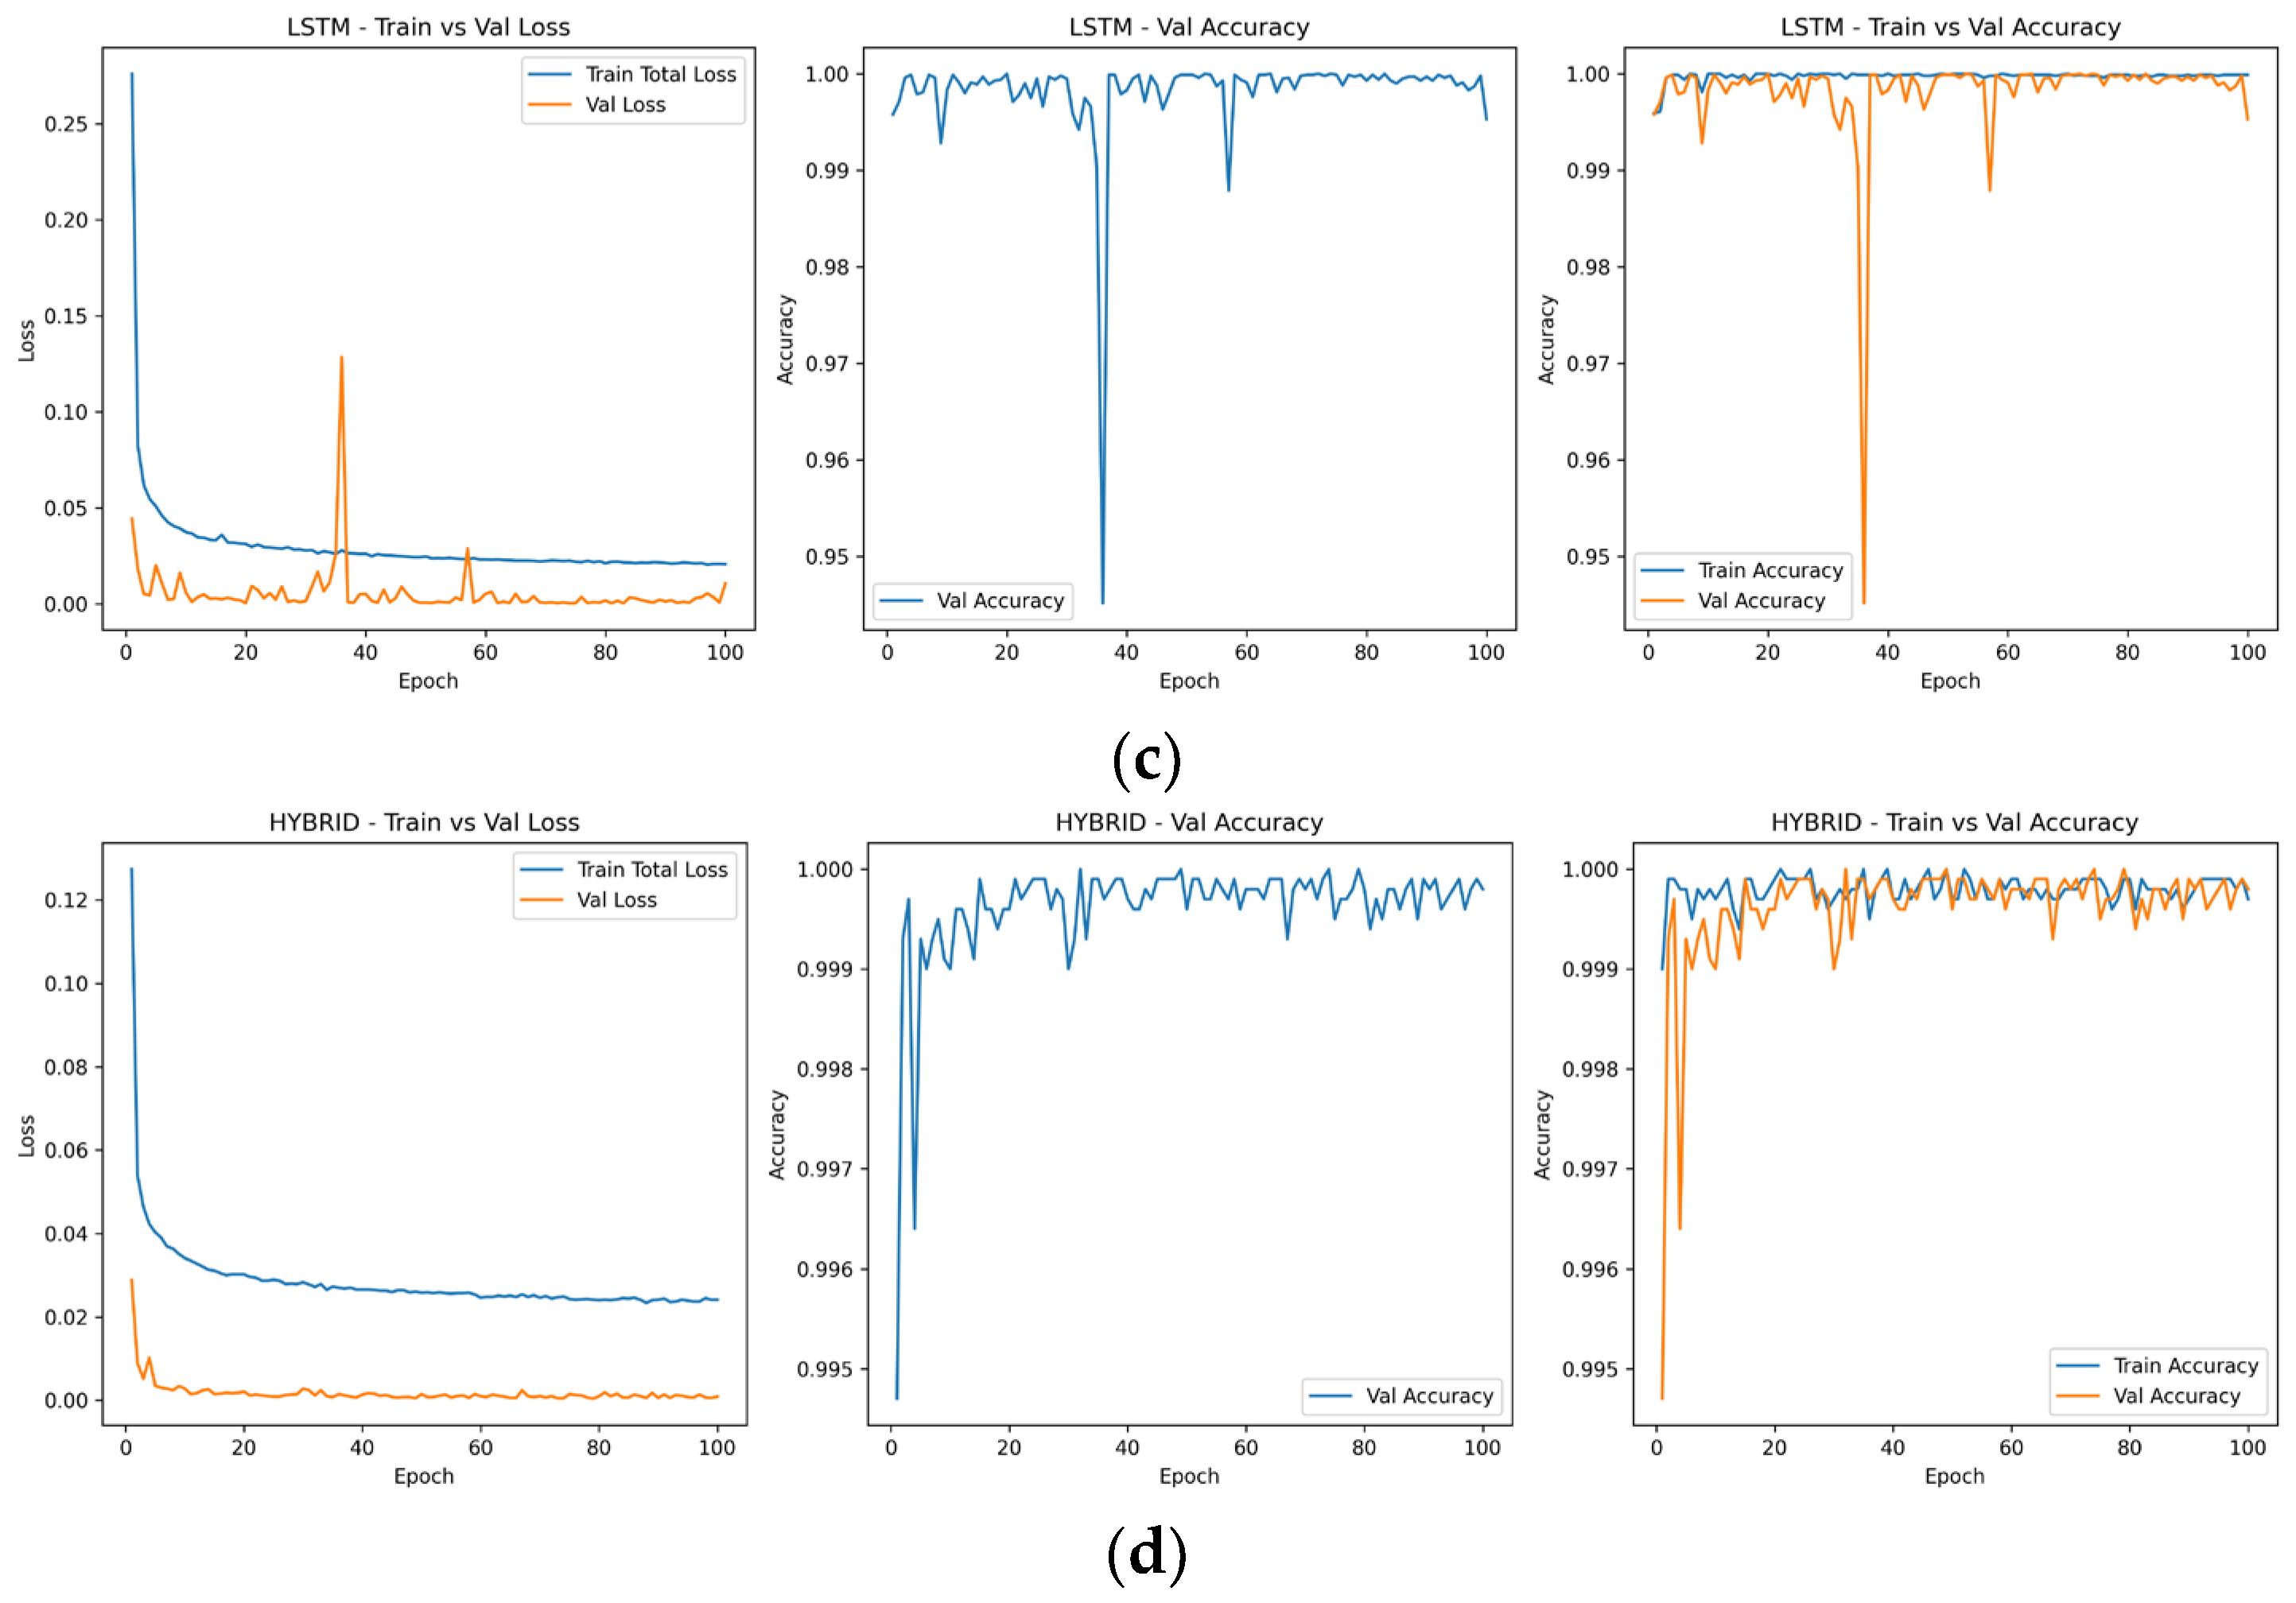
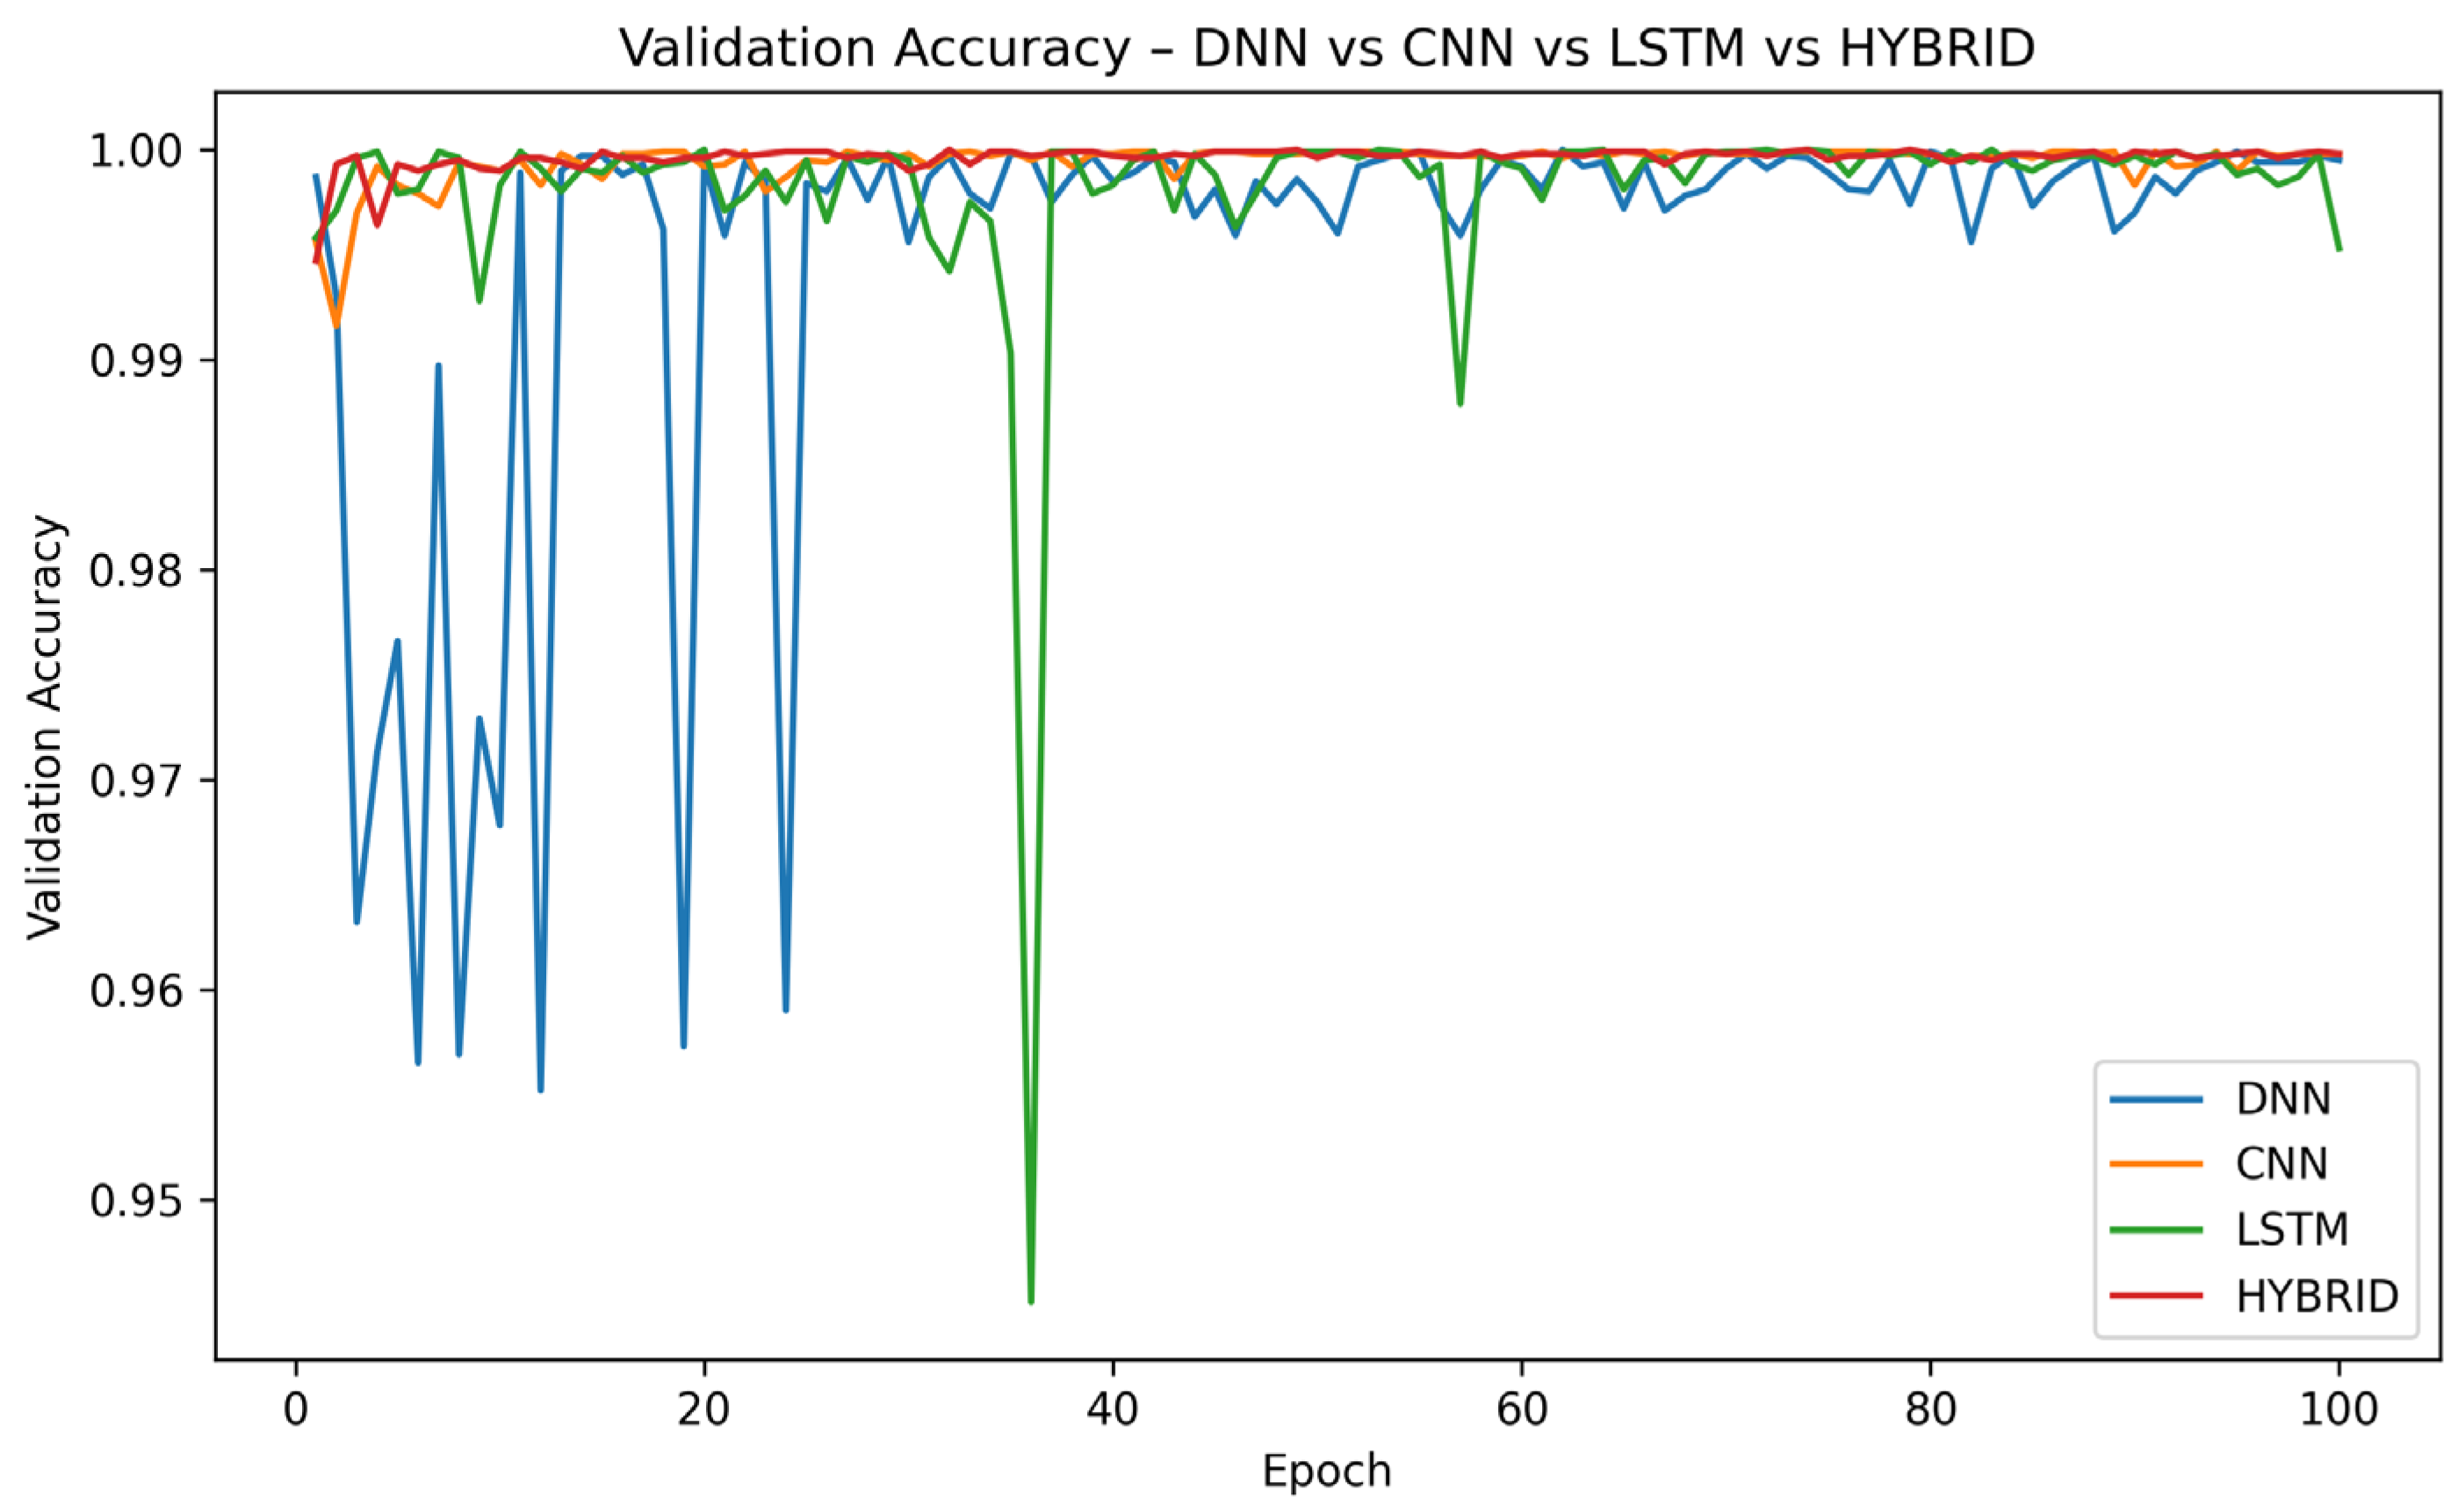
CNN (Figure 8a), as mentioned earlier, has the most stable convergence behavior where the loss curve decreases monotonically and the accuracy remains above 99.5% in the initial epochs. DNN (Figure 8b) has the largest variance in the initial phase before convergence and hence the highest saddle point sensitivity in the large fully connected parameter space. The LSTM (Figure 8c) does not have stable convergence as the loss has periodic spikes in the entire training process, which can be attributed to the recurrent effect of error accumulation in the artificially ordered feature sequences in tabular data. The hybrid (Figure 8d) has the smoothest training curve among the four models and the highest accuracy for all 100 epochs with the least variance among the four models. Figure 9 presents the validation accuracy comparison across all architectures over all 100 training epochs.
Figure 8.
(a). Training and validation curves CNN. (b) Training and validation curves DNN. (c) Training and validation curves LSTM. (d) Training and validation curves Hybrid.
Figure 9.
Validation accuracy comparison, all four architectures, 100 epochs.
Three factors make the hybrid model stable: the averaging effect of the gradients from the three branches in the hybrid model, the consistency loss term that minimizes the change in the output distribution under perturbation, and the branch dropout that prevents any single branch from dominating the gradient update in the initial phase of training and hence stabilizes the optimization landscape from the first epoch onwards.
6.6. Ablation Study
An ablation study was conducted to isolate the contribution of each architectural component to overall model performance. Components evaluated include consistency regularization (λ = 0), entropy-weighted attention, branch dropout (p_bd = 0), severity-aware weighting (s_c = 1.0 for all classes), and each individual branch. Results are reported in terms of binary accuracy, binary F1-score, and ten-class Macro-F1 in Table 6.
Table 6.
Ablation study results evaluating the contribution of each component of the proposed hybrid model.
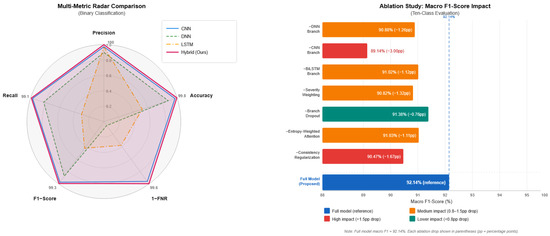
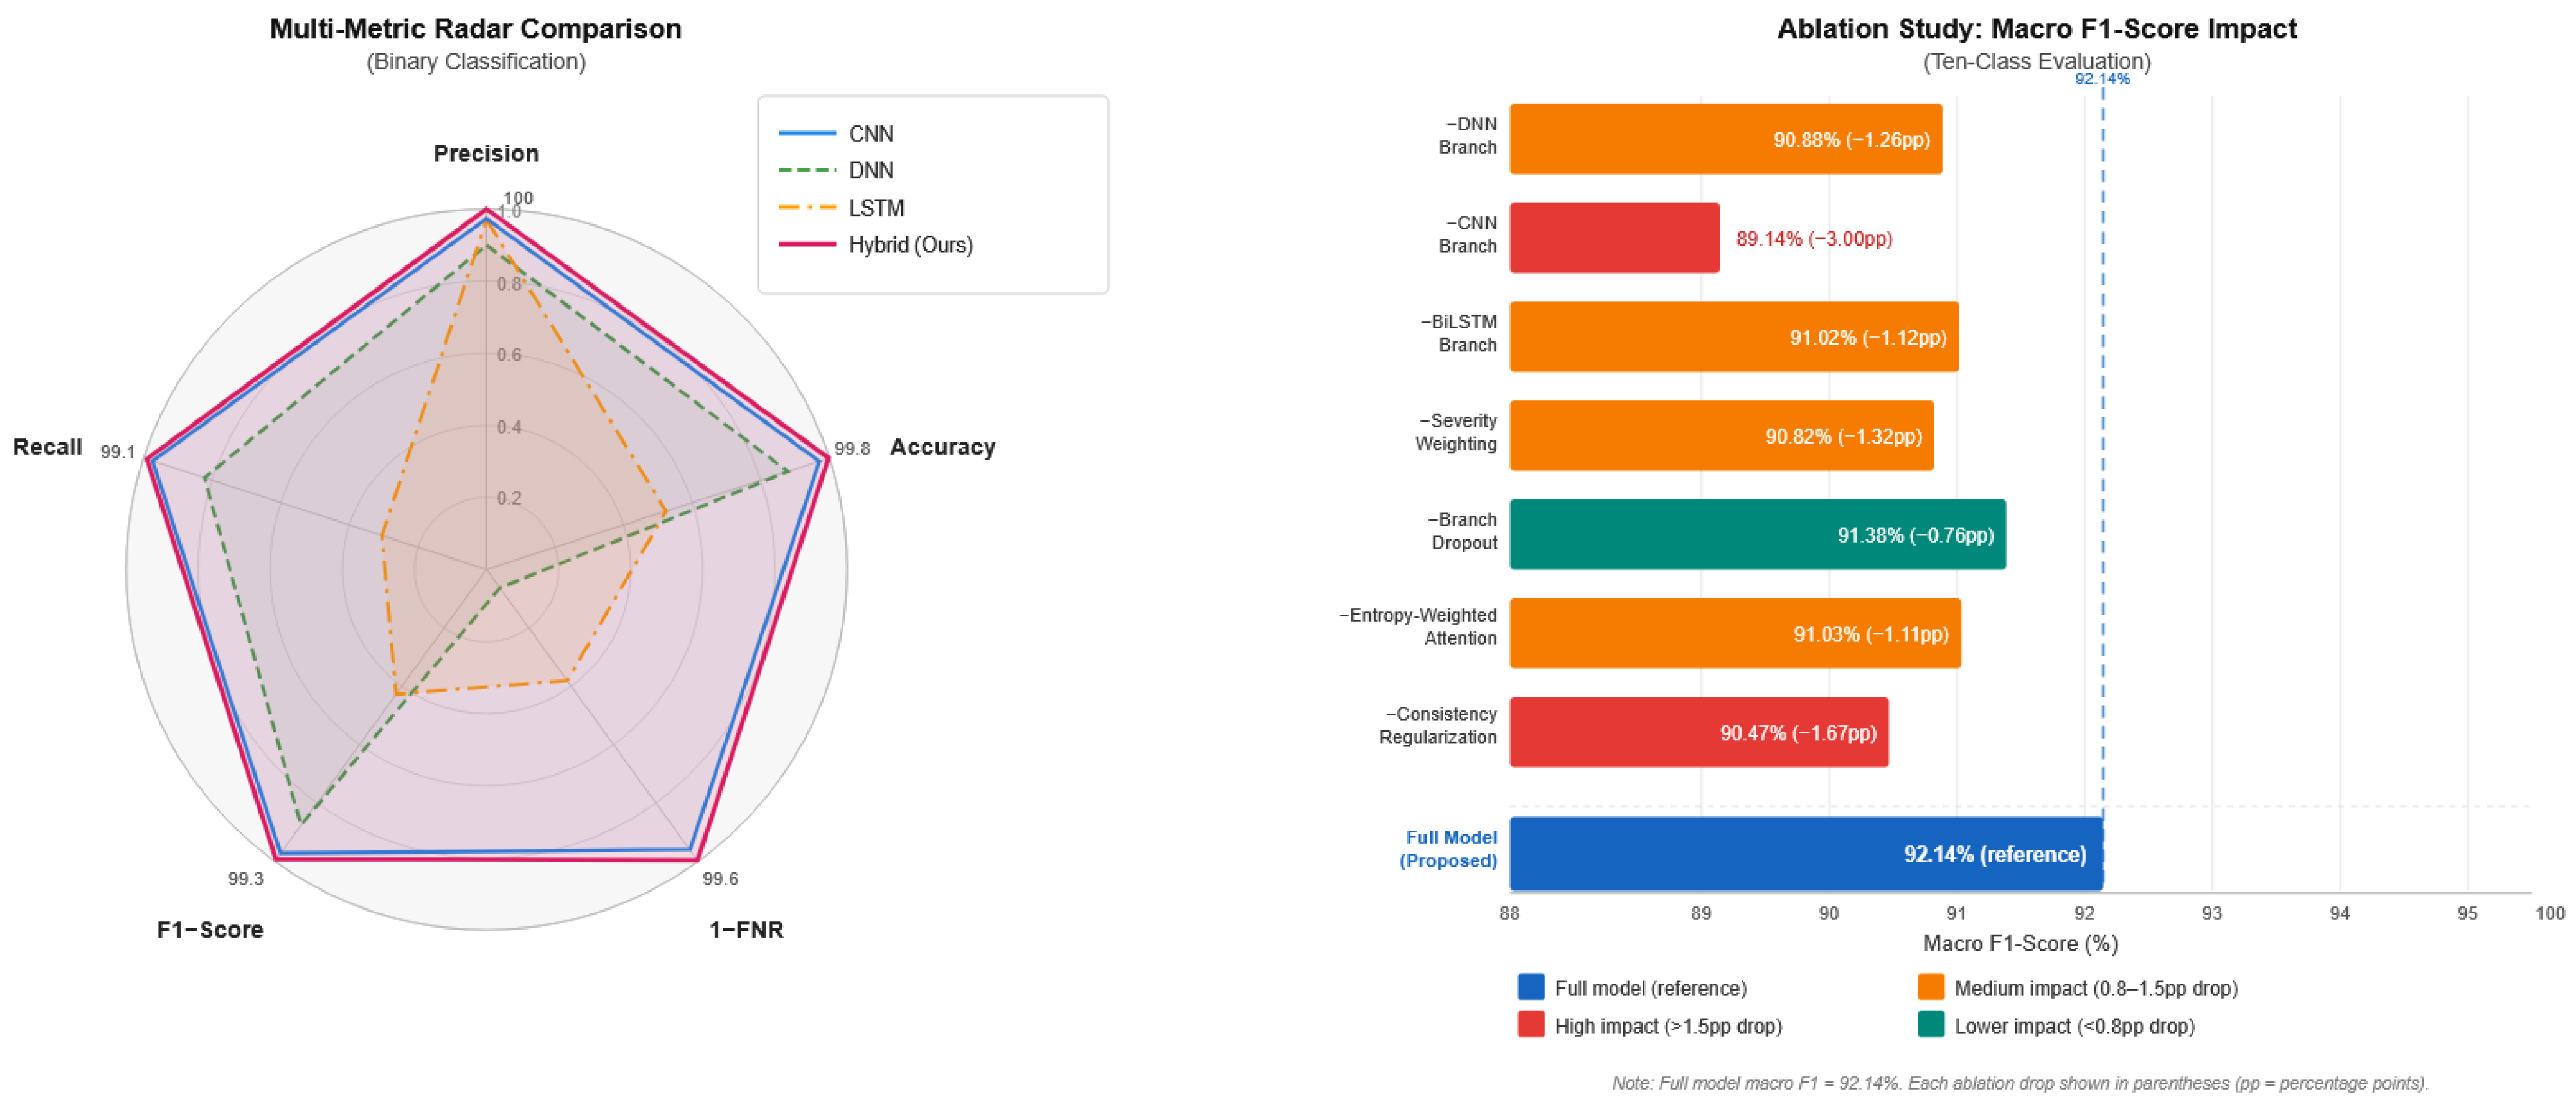
Table 6 demonstrates that the full model achieves the highest performance on all three metrics: 99.99% accuracy, 99.98% F1-score, and 92.14% Macro-F1. Removing consistency regularization (λ = 0) produces the largest single-component degradation, reducing Macro-F1 by 1.67 percentage points to 90.47%, confirming it as the most impactful design decision beyond the baseline. Removing entropy-weighted attention reduces Macro-F1 to 91.03% (−1.11 pp), and removing branch-dropout leads to 91.38% (−0.76 pp). Removing severity-aware weighting reduces Macro-F1 to 90.82% (−1.32 pp), reflecting the importance of appropriately amplifying the gradient signal from rare high-risk categories. Among individual branch removals, removing the CNN branch produces the largest degradation (Macro-F1 = 89.14%), consistent with its strong local feature extraction capability and low standalone FNR. The standalone baselines, CNN (89.47%), DNN (87.91%), and LSTM (84.23%), confirm that the performance gain of the full hybrid over any single branch is substantial and cannot be attributed to any one component alone. A multi-metric radar chart comparison across all four architectures is provided in Figure 10.
Figure 10.
(Left) Radar chart comparing CNN, DNN, LSTM, and hybrid models across classification metrics. Each axis represents a classification metric (Accuracy, Precision, Recall, F1-Score, Macro-F1). Colors: blue = CNN, orange = DNN, green = LSTM, red = Hybrid (Proposed). (Right) Ablation study assessing the contribution of individual components to macro F1-score in a ten-class classification task. Each bar represents performance after removing a specific module (DNN branch, CNN branch, Bi-LSTM branch, severity weighting, branch dropout, entropy-weighted attention, or consistency regularization). Values in parentheses show the corresponding performance drop. Colors indicate the magnitude of performance degradation (high, medium, low), highlighting that consistency regularization and the CNN branch have the most significant impact, while branch dropout has a minor effect.
6.7. State-of-the-Art Comparison
Table 7 compares the proposed model against sixteen published approaches on UNSW-NB15. Cross-study comparisons on this benchmark require care: authors differ in the number of features used (ranging from below 20 to the full 43), the train/test split strategy (the standard 175,341/82,332 partition versus random re-splits), and the class-balancing method (none, SMOTE, ADASYN, or class-weighting). The present work uses the full 43-feature set, the standard partition, and severity-aware class weighting without synthetic oversampling, consistent with the benchmark protocol described in [38,39]. Readers are advised to interpret accuracy differences in Table 7 with these methodological distinctions in mind.
Table 7.
Comparison with State-of-the-Art on UNSW-NB15. EWA = entropy-weighted attention; BD = branch-dropout.
The framework we propose achieves the highest binary accuracy and F1 score. It is important to acknowledge that UNSW-NB15 is well-documented as highly separable under deep learning with proper preprocessing [38]; the high binary accuracy reflects both the effectiveness of the proposed architecture and the inherent properties of this benchmark. The more discriminating evaluations are the ten-class results (Section 6.3) and the corruption robustness analysis (Section 6.8), which are discussed below.
6.8. Corruption Robustness Analysis
To validate that consistency training creates genuine robustness, we evaluate each model under controlled input corruption: 20% of features are randomly masked, and Gaussian noise with standard deviation 0.1 is added to the remainder. Table 8 reports the clean and corrupted accuracy, along with the degradation in percentage points.
Table 8.
Input corruption robustness.
The hybrid model degrades by only 0.2 percentage points under corruption, approximately half the CNN degradation (0.4 pp) and one-fifth of the LSTM degradation (1.0 pp). This outcome is consistent with the design objective of L_cons: by training the model to maintain consistent predictions under feature masking and additive noise, the consistency objective directly targets the degradation modes applied in this evaluation. The entropy-weighted attention mechanism provides a complementary effect: as corrupted features exhibit reduced entropy, their attention weights are suppressed, concentrating the model’s representational effort on the remaining intact features. The ablation study in Section 6.6 isolates the respective contributions of consistency regularization and entropy-weighted attention to this robustness result.
7. Limitations and Future Work
The primary limitation of this study is the evaluation on a single benchmark dataset. UNSW-NB15 was generated in a controlled laboratory environment with synthetic attack traffic; it does not capture the full diversity of real-world IoT deployments or adversarial conditions. Cross-dataset evaluation on NSL-KDD, CIC-IDS2017, and TON-IoT is the primary direction for future work, following the protocol described in Section 6.7.
Binary classification on UNSW-NB15 is a relatively easy task for well-configured deep architectures, as explicitly noted in Section 6.2. The ten-class evaluation in Section 6.3 provides a more discriminating performance estimate, particularly for minority attack categories such as Shellcode and Worms, and is the primary basis for claims about the practical benefit of the proposed multi-branch architecture.
Statistical evaluation has been added: McNemar’s test compares each architecture pair on the held-out test partition (Section 6.2), and bootstrap 95% confidence intervals (B = 1000 resamples) are reported for all primary metrics. The hybrid versus CNN comparison yields p < 0.01, confirming that the difference in misclassification patterns is statistically significant beyond random variation in initialization. Edge deployment feasibility has not been evaluated. Although all four architectures contain fewer than one million parameters, the three-branch hybrid exceeds the memory budget of the most resource-constrained IoT nodes. Model pruning, quantisation, and knowledge distillation are identified as concrete future directions for producing an edge-optimized variant. The severity multipliers s_c used in the class-weighting scheme are domain-informed estimates rather than empirically calibrated values. A rigorous calibration would require operational data such as mean time-to-contain by attack vector and estimated business impact per incident, which are not available in the UNSW-NB15 benchmark. Sensitivity analysis of the results to alternative s_c assignments is included in the ablation study (Table 6). Concept drift is not addressed. The consistency objective confers robustness to input corruption at inference time, but it does not account for distributional shift arising from the evolution of attack strategies over time. Periodic retraining and drift-detection mechanisms are identified as necessary extensions for long-term deployment.
8. Conclusions
This paper presents an IoT intrusion detection framework built on four design decisions that collectively address the gap between benchmark performance and real-world reliability. Our framework consists of a three-branch architecture: DNN with residual connections, 1D-CNN, and BiLSTM. Each model provides a unique perspective on the tabular traffic data. To mitigate the IoT threats of sensor degradation and adversarial telemetry manipulation, we utilize dual-view consistency training to incorporate robustness into the model. In the DNN branch, entropy-weighted attention mechanisms make the choice of important features dependent on the information contained in each batch of the training data, as opposed to a fixed choice determined at convergence. To avoid the problem of the three branches copying each other’s representation, we utilize branch dropout regularization to enhance the representation capability of each branch, thus increasing the robustness of the model even when any of the three branches is fed with adversarial data; on UNSW-NB15 under binary classification: 99.99% accuracy, 100% precision, 99.97% recall, 99.98% F1, and FNR = 2.65 × 10⁻⁴—the lowest among all four tested architectures, representing a 14.2% reduction over the CNN baseline and 73.3% over the DNN. Training dynamics are the smoothest of all four architectures, driven by three concurrent stabilization effects: multi-branch gradient averaging, consistency loss regularization, and branch-dropout balancing the optimization landscape. The findings align with and extend recent deep-learning IDS work on UNSW-NB15, including studies using random-forest and deep-learning ensembles [10] and feed-forward neural network approaches [48].
The ten-class evaluation (Section 6.3) confirms that the performance advantage of the hybrid architecture is substantially larger in the multiclass setting, with Macro-F1 = 92.14% versus 89.47% for CNN, 87.91% for DNN, and 84.23% for LSTM, with the greatest gains observed on the minority attack categories Shellcode and Worms. The ablation study (Section 6.6) isolates the contribution of each design decision, confirming that consistency regularization is the most impactful single component beyond the baseline CNN. The corruption robustness analysis (Section 6.8) directly quantifies the practical benefit of consistency training and entropy-weighted attention under degraded inputs, showing that the hybrid degrades by only 0.2 percentage points under masking and noise, compared with 0.4 pp for CNN and 1.0 pp for LSTM.
Author Contributions
Conceptualization, E.H.A. and M.M.; methodology, E.H.A.; software, E.H.A.; validation, E.H.A., M.M. and L.M.; formal analysis, E.H.A.; investigation, E.H.A.; data curation, E.H.A.; writing—original draft preparation, E.H.A.; writing—review and editing, M.M. and L.M.; supervision, L.M. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
The data used in this study are publicly available. The UNSW-NB15 dataset can be downloaded from the UNSW Canberra Cyber repository at https://research.unsw.edu.au/projects/unsw-nb15-dataset (accessed on 11 February 2026).
Acknowledgments
The authors acknowledge Mohammed V University in Rabat and ENSIAS for institutional support.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Kolias, C.; Kambourakis, G.; Stavrou, A.; Voas, J. DDoS in the IoT: Mirai and other botnets. IEEE Comput. 2017, 50, 80–84. [Google Scholar] [CrossRef] [Scilit]
- Chen, Z.; Liu, J.; Shen, Y.; Simsek, M.; Kantarci, B.; Mouftah, H.T.; Djukic, P. Machine Learning-Enabled IoT Security: Open Issues and Challenges Under Advanced Persistent Threats. ACM Comput. Surv. 2023, 55, 105. [Google Scholar] [CrossRef] [Scilit]
- Zolanvari, M.; Teixeira, M.A.; Jain, R. Effect of Imbalanced Datasets on Security of Industrial IoT Using Machine Learning. In 2018 IEEE International Conference on Intelligence and Security Informatics (ISI); IEEE: Piscataway, NJ, USA, 2018; pp. 112–117. [Google Scholar]
- Sudharsan, B.; Breslin, J.G.; Ali, M.I. Imbal-OL: Online Machine Learning from Imbalanced Data Streams in Real-world IoT. In 2021 IEEE International Conference on Big Data (Big Data); IEEE: Piscataway, NJ, USA, 2021; pp. 4974–4978. [Google Scholar]
- Babu, K.S.; Rao, Y.N. A Study on Imbalanced Data Classification for Various Applications. Rev. Intell. Artif. 2023, 37, 517–524. [Google Scholar] [CrossRef] [Scilit]
- Dirin, A.; Oliver, I.; Laine, T.H. A Security Framework for Increasing Data and Device Integrity in Internet of Things Systems. Sensors 2023, 23, 7532. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Tadj, T.; Arablouei, R.; Dedeoglu, V. On Evaluating IoT Data Trust via Machine Learning. Future Internet 2023, 15, 309. [Google Scholar] [CrossRef] [Scilit]
- Kasongo, S.M.; Sun, Y. Performance Analysis of Intrusion Detection Systems Using a Feature Selection Method on the UNSW-NB15 Dataset. J. Big Data 2020, 7, 105. [Google Scholar] [CrossRef] [Scilit]
- Barkah, A.S.; Selamat, S.R.; Abidin, Z.Z.; Wahyudi, R. Impact of Data Balancing and Feature Selection on Machine Learning-based Network Intrusion Detection. JOIV Int. J. Inform. Vis. 2023, 7, 241–248. [Google Scholar] [CrossRef] [Scilit]
- Upadhyay, A.; Thakur, N.; Pandey, A.; Khan, M.; Vibhute, A.D. Multiple intrusion detection in complex cloud environments using random forest and deep learning. In Intelligent Communication, Control and Devices; Lecture Notes in Networks and Systems; Springer: Berlin/Heidelberg, Germany, 2025; pp. 71–85. [Google Scholar]
- Hassouneh, N.; Al-Sharaeh, S. Intrusion Detection in IoT Networks Using LSTM Deep Learning Models with the UNSW-NB15 Dataset. In 2025 International Conference on New Trends in Computing Sciences (ICTCS); IEEE: Piscataway, NJ, USA, 2025; pp. 263–269. [Google Scholar]
- Li, B.; Li, J.; Jia, M. ADFCNN-BiLSTM: A Deep Neural Network Based on Attention and Deformable Convolution for Network Intrusion Detection. Sensors 2025, 25, 1382. [Google Scholar] [CrossRef] [Scilit]
- Srivastava, J.; Prakash, J. Deep learning models for intrusion detection in 5G networks. In OPSEARCH; Springer: Berlin/Heidelberg, Germany, 2026. [Google Scholar] [CrossRef] [Scilit]
- Ahmad, Z.; Khan, A.S.; Nisar, K.; Haider, I.; Hassan, R.; Haque, M.R.; Tarmizi, S.; Rodrigues, J.J.P.C. Anomaly detection using deep neural network for IoT architecture. Appl. Sci. 2021, 11, 7050. [Google Scholar] [CrossRef] [Scilit]
- Sadhwani, S.; Khan, M.A.H.; Muthalagu, R.; Pawar, P.M.; Suresh, K. A hybrid BiLSTM-CNN approach for intrusion detection for IoT applications. Sci. Rep. 2026, 16, 155. [Google Scholar] [CrossRef] [Scilit]
- Chen, Y.; Mir, M. An intrusion detection system for industrial IoT using CNN-LSTM and reptile search algorithm. Clust. Comput. 2025, 28, 452. [Google Scholar] [CrossRef] [Scilit]
- Umer, M.; Tahir, M.; Sardaraz, M. Network intrusion detection model using wrapper based feature selection and multi head attention transformers. Sci. Rep. 2025, 15, 28718. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Biyouki, A.H.; Lotfipour, S.; Haghi, B. A novel multi-scale network intrusion detection model with transformer. Sci. Rep. 2024, 14, 23239. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wang, C.; Wang, Y.; Liu, J. MCAN-BIFT: An IIoT Intrusion Detection System Integrating Multi-scale Feature Enhancement and Transformer. In KSEM 2025; Lecture Notes in Computer Science; Springer: Berlin/Heidelberg, Germany, 2026; Volume 15919. [Google Scholar]
- Zhang, C.; Li, J.; Wang, N.; Zhang, D. Research on Intrusion Detection Method Based on Transformer and CNN-BiLSTM in Internet of Things. Sensors 2025, 25, 2725. [Google Scholar] [CrossRef] [Scilit]
- Karthik, M.G.; Keerthika, V.; Mantena, S.V.; Siri, D.; Yeluri, L.P.; Lella, K.K.; Ganesh, B.R. Energy-efficient intrusion detection with a protocol-aware transformer–spiking hybrid model. Sci. Rep. 2026, 16, 7095. [Google Scholar] [CrossRef] [Scilit]
- Yin, Y.; Jang-Jaccard, J.; Xu, W.; Singh, A.; Zhu, J.; Sabrina, F.; Kwak, J. IGRF-RFE: A hybrid feature selection method for MLP-based network intrusion detection on UNSW-NB15. J. Big Data 2023, 10, 15. [Google Scholar] [CrossRef] [Scilit]
- Alfahaid, A.; Alalwany, E.; Almars, A.M.; Alharbi, F.; Atlam, E.; Mahgoub, I. Machine Learning-Based Security Solutions for IoT Networks: A Comprehensive Survey. Sensors 2025, 25, 3341. [Google Scholar] [CrossRef] [Scilit]
- Fan, Y.; Kukleva, A.; Schiele, B. Revisiting Consistency Regularization for Semi-Supervised Learning. Int. J. Comput. Vis. 2023, 131, 626–643. [Google Scholar] [CrossRef] [Scilit]
- Tarvainen, A.; Valpola, H. Mean teachers are better role models: Weight-averaged consistency targets improve semi-supervised deep learning results. In Proceedings of the Neural Information Processing Systems 2017 (NeurIPS), Long Beach, CA, USA, 4–9 December 2017; Volume 30. [Google Scholar]
- Jiang, Y.; Sui, X.; Ding, Y.; Xiao, W.; Zheng, Y.; Zhang, Y. A semi-supervised learning approach with consistency regularization for tumor histopathological images analysis. Front. Oncol. 2023, 12, 1044026. [Google Scholar] [CrossRef] [Scilit]
- Zhang, T.; Li, C.; Chen, J.; He, S.; Zhou, Z. Feature-level consistency regularized semi-supervised scheme with data augmentation for intelligent fault diagnosis under small samples. Mech. Syst. Signal Process. 2023, 203, 110747. [Google Scholar] [CrossRef] [Scilit]
- He, K.; Zhang, X.; Ren, S.; Sun, J. Deep Residual Learning for Image Recognition. In Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Piscataway, NJ, USA, 2016; pp. 770–778. [Google Scholar]
- Goswami, P.; Khan, T.; Pathak, V.; Alabdultif, A. Machine learning based dynamic trust estimation framework for securing wireless sensor networks. Sci. Rep. 2025, 15, 35821. [Google Scholar] [CrossRef] [Scilit]
- Alotaibi, B. A Review of Resilient IoT Systems: Trends, Challenges, and Future Directions. Preprints 2025, 2025121717. [Google Scholar]
- Zarpelão, B.B.; Miani, R.S.; Kawakani, C.T.; De Alvarenga, S.C. A survey of intrusion detection in Internet of Things. J. Netw. Comput. Appl. 2017, 84, 25–37. [Google Scholar] [CrossRef] [Scilit]
- Gyamfi, E.; Jurcut, A. Intrusion Detection in Internet of Things Systems: A Review. Sensors 2022, 22, 3744. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Jayalaxmi, P.L.S.; Saha, R.; Kumar, G.; Conti, M.; Kim, T.-H. Machine and Deep Learning Solutions for Intrusion Detection and Prevention in IoTs: A Survey. IEEE Access 2022, 10, 121173–121192. [Google Scholar] [CrossRef] [Scilit]
- Arshad, J.; Azad, M.A.; Abdeltaif, M.M.; Salah, K. An intrusion detection framework for energy constrained IoT devices. Mech. Syst. Signal Process. 2020, 136, 106436. [Google Scholar] [CrossRef] [Scilit]
- Taye, M.M. Theoretical Understanding of Convolutional Neural Network. Computation 2023, 11, 52. [Google Scholar] [CrossRef] [Scilit]
- Sherstinsky, A. Fundamentals of Recurrent Neural Network (RNN) and Long Short-Term Memory (LSTM) network. Phys. D 2020, 404, 132306. [Google Scholar] [CrossRef] [Scilit]
- Nauman, M.A.; Saeed, M.; Saidani, O.; Javed, T.; Almuqren, L.; Bashir, R.N.; Jahangir, R. IoT and Ensemble LSTM-Based Evapotranspiration Forecasting for Riyadh. Sensors 2023, 23, 7583. [Google Scholar] [CrossRef] [Scilit]
- Moustafa, N.; Slay, J. UNSW-NB15: A comprehensive data set for network intrusion detection systems. In 2015 Military Communications and Information Systems Conference (MilCIS); IEEE: Piscataway, NJ, USA, 2015. [Google Scholar]
- Moustafa, N.; Slay, J. The evaluation of Network Anomaly Detection Systems: Statistical analysis of the UNSW-NB15 data set and the comparison with the KDD99 data set. Inf. Secur. J. 2016, 25, 18–31. [Google Scholar] [CrossRef] [Scilit]
- Mohammad, R.; Saeed, F.; Almazroi, A.A.; Alsubaei, F.S.; Almazroi, A.A. Enhancing Intrusion Detection Systems Using a Deep Learning and Data Augmentation Approach. Systems 2024, 12, 79. [Google Scholar] [CrossRef] [Scilit]
- Kasongo, S.M.; Sun, Y. A deep learning method with wrapper based feature extraction for wireless intrusion detection system. Comput. Secur. 2020, 92, 101752. [Google Scholar] [CrossRef] [Scilit]
- Mouiti, M.; Elhariri, A.; Habibi, O.; Lazaar, M. Toward Improving IoT Networks Security Using Machine Learning Based Intrusion Detection System. In 2023 International Conference on Digital Age & Technological Advances for Sustainable Development (ICDATA); IEEE: Piscataway, NJ, USA, 2023. [Google Scholar]
- Eunice, A.D.; Gao, Q.; Zhu, M.-Y.; Chen, Z.; Lv, N. Network Anomaly Detection Technology Based on Deep Learning. In 2021 IEEE 3rd International Conference on Frontiers Technology of Information and Computer (ICFTIC); IEEE: Piscataway, NJ, USA, 2021. [Google Scholar]
- Jablaoui, R.; Cheikhrouhou, O.; Hamdi, M.; Liouane, N. Deep learning enabled intrusion detection system for IoT security. J. Wirel. Commun. Netw. 2025, 2025, 66. [Google Scholar] [CrossRef] [Scilit]
- Alsubaei, F.S. Smart deep learning model for enhanced IoT intrusion detection. Sci. Rep. 2025, 15, 20577. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Morsi, A.; Vamplew, P. A Hybrid Intrusion Detection Framework Using Deep Autoencoder and Machine Learning Models. AI 2026, 7, 39. [Google Scholar] [CrossRef] [Scilit]
- Yousefnezhad, M.; Hamidzadeh, J.; Aliannejadi, M. Ensemble classification for intrusion detection via feature extraction based on deep learning. Soft Comput. 2021, 25, 12667–12683. [Google Scholar] [CrossRef] [Scilit]
- Alashjaee, A.M.; Alqahtani, F. Enhanced intrusion detection system IoT network security model by feed forward neural network and machine learning. Sci. Rep. 2025, 15, 36085. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.