Article

MonoPrior-Fusion: Monocular-Prior-Guided Multi-Frame Depth Estimation with Multi-Scale Geometric Fusion

by
Zhiwei Lin
1,2,
Bohan Sun
2,
Zhan Zhang
2,
Linrui Qian
1,2,* and
Nianyu Yi
1
1
School of Mathematics and Computational Science, Xiangtan University, Xiangtan 411105, China
2
CogLeap.AI Space Intelligence (Wuxi) Technology Co., Ltd., Beijing 100080, China
*
Author to whom correspondence should be addressed.
Sensors 2026, 26(2), 712; https://doi.org/10.3390/s26020712
Submission received: 16 December 2025 / Revised: 19 January 2026 / Accepted: 19 January 2026 / Published: 21 January 2026
(This article belongs to the Section Sensing and Imaging)

Abstract

Precise 3D perception is critical for indoor robotics, augmented reality, and autonomous navigation. However, existing multi-frame depth estimation methods often suffer from significant performance degradation in challenging indoor scenarios characterized by weak textures, non-Lambertian surfaces, and complex layouts. To address these limitations, we propose MonoPrior-Fusion (MPF), a novel framework that integrates pixel-wise monocular priors directly into the multi-view matching process. Specifically, MPF modulates cost-volume hypotheses to disambiguate matches and employs a hierarchical fusion architecture across multiple scales to propagate global and local geometric information. Additionally, a geometric consistency loss based on virtual planes is introduced to enhance global 3D coherence. Extensive experiments on ScanNetV2, 7Scenes, TUM RGB-D, and GMU Kitchens demonstrate that MPF achieves significant improvements over state-of-the-art multi-frame baselines and generalizes well across unseen domains. Furthermore, MPF yields more accurate and complete 3D reconstructions when integrated into a volumetric fusion pipeline, proving its effectiveness for dense mapping tasks. The source code will be made publicly available to support reproducibility and future research.

1. Introduction

Depth estimation plays a central role in visual perception systems, enabling downstream tasks such as autonomous navigation, robotic interaction, and augmented reality. Recent advances in monocular depth estimation have achieved remarkable progress by leveraging large-scale datasets and powerful neural architectures [1,2,3,4,5]. However, monocular predictions inherently suffer from scale ambiguity and often become unreliable in low-texture or low-parallax regions where appearance cues provide insufficient geometric constraints [6].
Multi-view or multi-frame depth estimation, in contrast, grounds reconstruction on calibrated geometric relationships across views [7,8]. While this paradigm naturally alleviates scale ambiguity, its performance is strongly tied to photometric consistency. When the baseline is small, textures are weak, or repetitive patterns dominate the scene, feature correspondence becomes unstable, degrading the reliability of traditional cost-volume or plane-sweep matching. As a result, existing multi-frame pipelines struggle to maintain accurate and consistent depth in challenging real-world environments.
Despite recent efforts, three fundamental limitations persist in current multi-frame approaches. First, feature matching remains sensitive to the quality of photometric cues; small baselines or weak textures often cause ambiguous cost distributions even with multi-view aggregation [9,10]. Second, geometric consistency is typically enforced through local warping or single-plane evaluations, providing only limited global regularization and making predictions susceptible to noise. Third, although monocular depth priors contain rich structural information, prior works [11,12] generally incorporate them only as pseudo-labels or coarse regularizers, preventing these priors from influencing the core multi-view correspondence generation process.
To overcome these limitations, we propose MonoPrior-Fusion (MPF), a new multi-frame depth estimation framework that integrates pixel-wise monocular priors directly into multi-view matching. Unlike previous strategies that rely on monocular predictions only as auxiliary supervision or low-resolution initialization, MPF injects dense prior cues—depth, surface normals, and confidence—into the hypothesis space of the cost volume itself. This design enriches the matching evidence at a fine-grained level, enabling the network to disambiguate weak photometric cues and preserve structural details in low-texture or small-baseline scenarios.
Beyond prior-guided correspondence, MPF introduces a geometric consistency loss based on virtual planes that regularizes depth by enforcing agreement across a set of randomly sampled planes in 3D. This plane-level supervision complements local photometric and normal-based cues, providing stronger global geometric coherence than traditional warping-based constraints. To further enhance robustness across large depth ranges and complex indoor layouts, MPF employs a hierarchical fusion architecture across multiple scales that propagates geometric information from coarse global structure to fine spatial detail. Throughout the pipeline, MPF operates under known camera intrinsics and poses, following established practice in calibrated multi-view estimation.
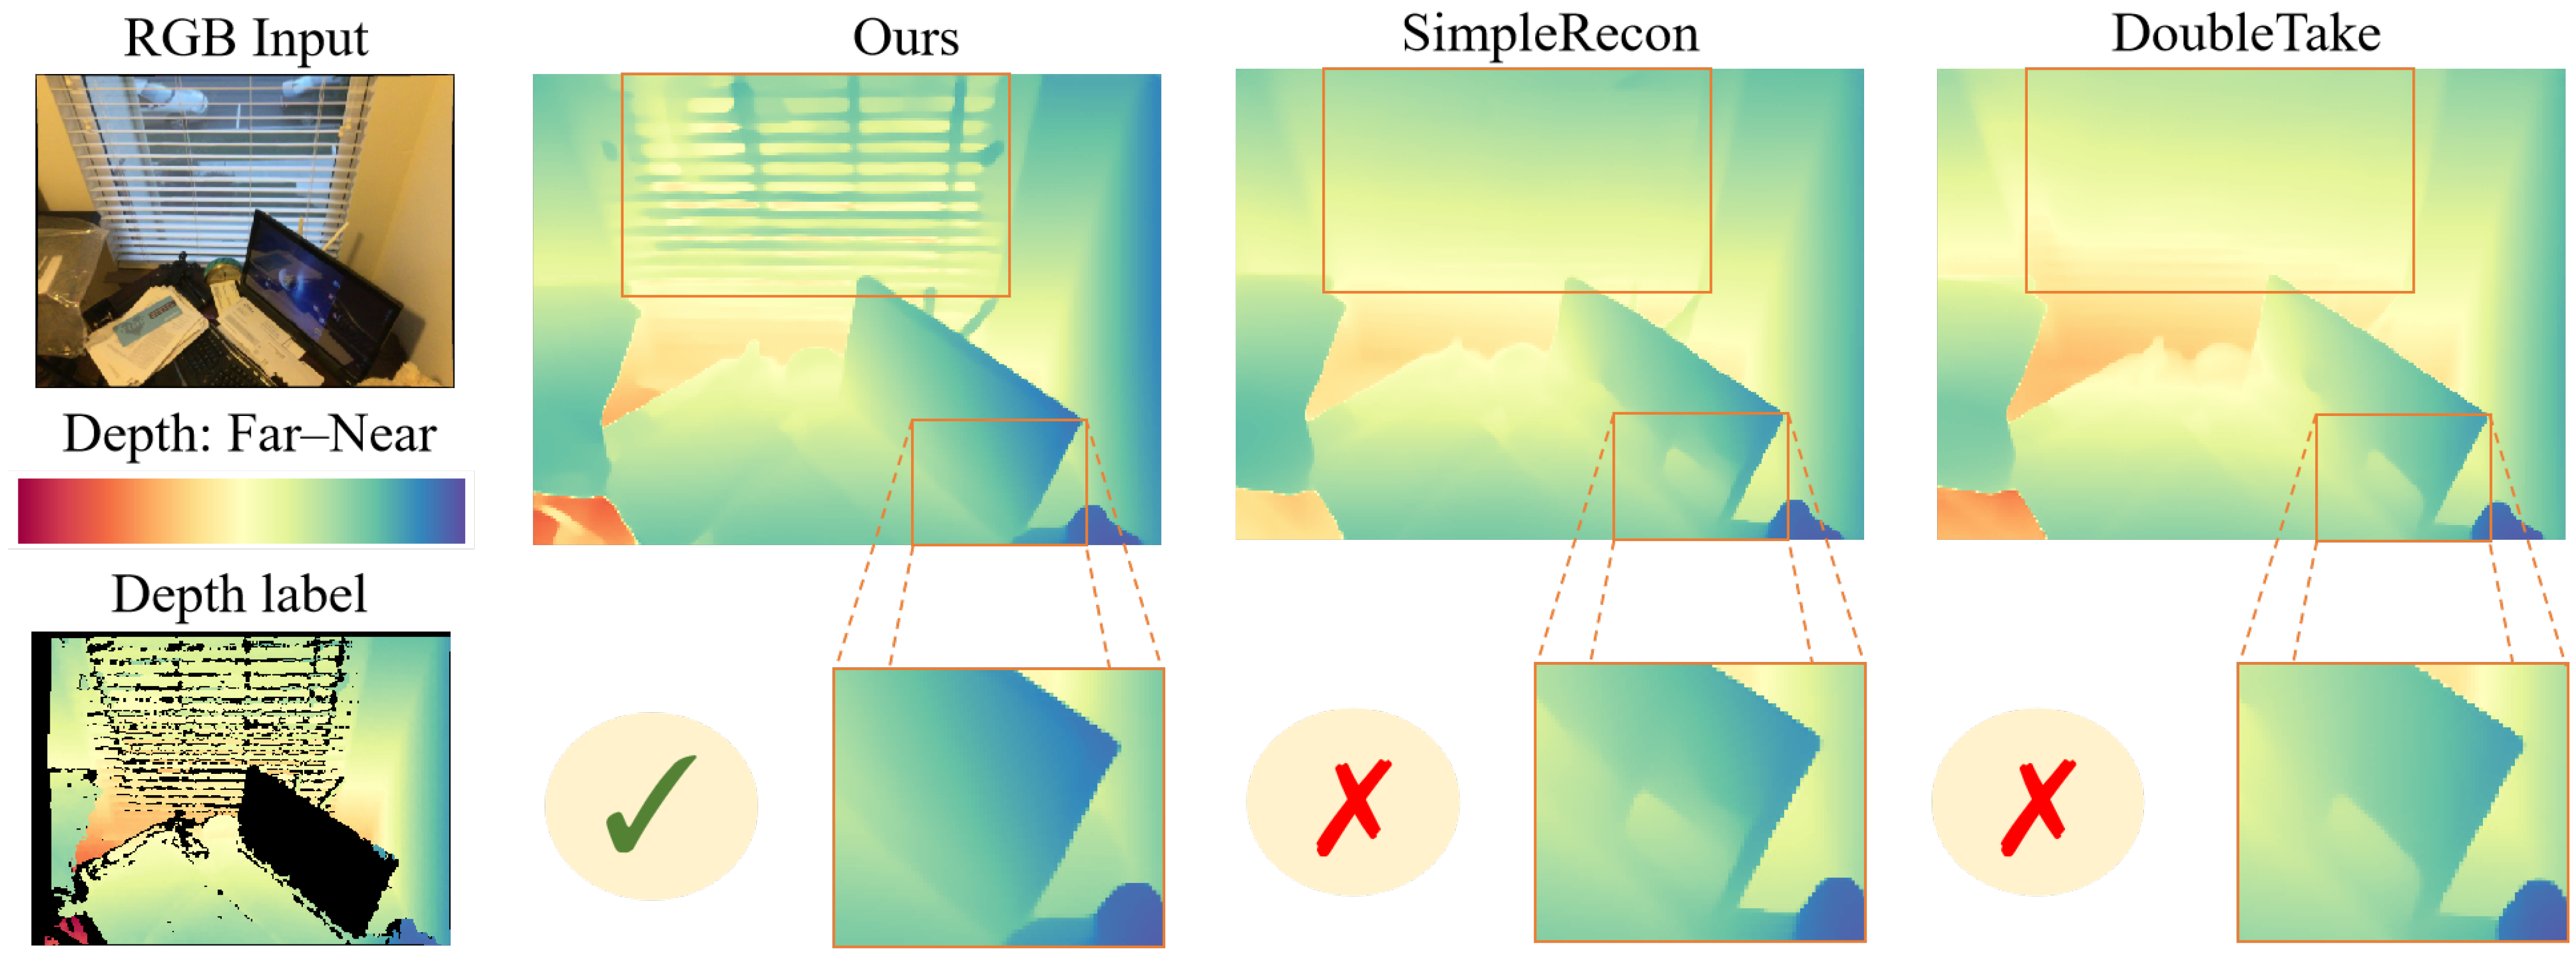
Figure 1 illustrates the advantage of our approach: MPF preserves sharper geometry and cleaner depth boundaries compared to purely photometric methods. To summarize, the main contributions of this work are as follows:
  • We propose MonoPrior-Fusion (MPF), a novel framework that integrates pixel-wise monocular priors directly into the multi-view matching process to address ambiguities in low-texture scenarios.
  • We design a hierarchical fusion architecture across multiple scales that propagates geometric cues from coarse to fine resolutions, improving structural coherence.
  • We introduce a geometric consistency loss based on virtual planes that enforces plane-level alignment in 3D space, providing stronger global regularization.
  • Extensive experiments on ScanNetV2, 7Scenes, TUM RGB-D, and GMU Kitchens demonstrate that MPF outperforms state-of-the-art methods and exhibits superior zero-shot generalization.
The remainder of this paper is organized as follows: Section 2 reviews related work. Section 3 details the MPF framework. Section 4 presents experimental results and ablation studies. Finally, Section 5 concludes this paper.

2. Related Work

2.1. Monocular Depth Estimation and Prior-Based Guidance

Monocular depth estimation has advanced significantly with the emergence of deep CNN- and transformer-based architectures. Early supervised methods [15,16] introduced multi-scale prediction pipelines that progressively refined feature representations, leading to consistent improvements in metric depth accuracy. Self-supervised approaches, such as Monodepth2 [17] and view-synthesis-based frameworks [18,19], further demonstrated that enforcing photometric consistency across adjacent frames provides a powerful supervisory signal, enabling depth learning without reliance on ground-truth depth annotations. More recently, large-scale pretrained models—including MiDaS [20], Depth Anything V2 [21], ZoeDepth [22], UniDepth [23], and Metric3Dv2 [24]—have shown strong generalization across diverse imaging conditions and camera settings, alongside architectural refinements that improve multi-scale feature utilization [25].
Monocular priors have also been incorporated into multi-view or multi-frame systems. Existing methods typically use monocular predictions to initialize cost volumes [11], refine sparse depth [26], or serve as auxiliary supervision [12,27]. However, these priors are usually injected only at late stages—as pseudo-labels, global regularizers, or coarse initialization—and therefore do not participate in early correspondence formation [28]. Consequently, the matching process remains largely photometric and often fails in textureless or low-parallax regions. To address this limitation, MPF integrates pixel-level monocular cues directly into the depth-hypothesis space, enabling finer structural discrimination during matching.

2.2. Learning-Based Multi-View Stereo and Geometric Consistency

Classical learning-based multi-view stereo (MVS) methods reconstruct metric depth by enforcing geometric consistency across calibrated views. MVSNet [7] introduced differentiable plane sweeping and learned cost-volume regularization, inspiring subsequent works such as CasMVSNet [10], DPSNet [29], and hybrid PatchMatch-based pipelines. Video-based extensions, including DeepVideoMVS [9] and SimpleRecon [8], adapt MVS principles to sequential frames, improving efficiency through temporally aligned features and lightweight correlation modules. More recently, MVSAnywhere [30] has demonstrated the potential of zero-shot MVS by leveraging large-scale pretraining, though often at a higher computational cost.
Despite these advances, cost-volume aggregation still relies heavily on local photometric consistency, making MVS vulnerable to small baselines, motion blur, low-texture regions, and repetitive patterns. Moreover, most methods enforce geometric consistency through local warping or single-plane evaluation, limiting their ability to incorporate global geometric constraints. In contrast, MPF stabilizes correspondence by augmenting the hypothesis space with monocular structural cues and introduces a geometric consistency loss based on virtual planes to enhance global regularization beyond local photometric signals.

2.3. Feed-Forward Multi-View Reconstruction

Recent feed-forward 3D reconstruction models aim to recover geometry without explicit triangulation or depth sweeping. DUSt3R [31] and MASt3R [32] estimate dense point maps or 3D correspondences directly from image pairs, while transformer-based architectures such as VGGT [33] jointly infer depth, camera parameters, and feature tracks through large-scale pretraining. These methods demonstrate impressive generalization and robustness to unconstrained viewpoints.
However, feed-forward models typically recover geometry only up to an unknown global scale, depend strongly on learned priors rather than explicit geometric reasoning, and often require joint processing of multiple images, which can be computationally demanding. Such properties limit their applicability in robotics or SLAM pipelines where metric, calibrated, and lightweight inference is required. MPF operates in a complementary setting: by leveraging calibrated camera geometry while injecting pixel-level monocular priors, it achieves metric depth estimation with improved robustness in challenging visual conditions.
Table 1 provides a comprehensive taxonomy of current paradigms. While pure monocular methods offer dense priors, they lack metric grounding, and feed-forward models often recover geometry only up to an unknown scale. Conversely, traditional MVS relies heavily on photometric consistency, making it vulnerable to textureless regions. Unlike existing prior-based MVS frameworks such as MVSAnywhere [30] that incorporate monocular cues as late-stage initialization or postprocessing, MPF implements a pixel-wise early fusion. By directly modulating the cost-volume hypothesis space with monocular priors (Equations (2)–(4)), MPF disambiguates matches at the source, effectively unifying the complementary strengths of both geometric and monocular paradigms.

3. Method

This section presents MPF, a framework for geometric fusion from multiple sources that integrates multi-frame matching, pixel-level monocular priors, multi-scale geometric reasoning, and consistency checks based on virtual planes. Traditional learning-based MVS systems rely heavily on photometric consistency and therefore degrade on weak textures and repetitive patterns or in small-baseline scenarios. Conversely, monocular depth models provide sharp structural priors but lack geometric grounding and metric scale.
As summarized in the taxonomy of Table 1, MPF unifies the complementary strengths of these two paradigms by implementing a pixel-wise early-fusion strategy. This is achieved through the following: (i) A multi-frame backbone that preserves camera geometry; (ii) A prior-guided modulation of depth hypotheses at the earliest stage of matching; (iii) Fusion volumes across multiple scales that propagate geometric cues across resolutions; (iv) Global 3D regularization via virtual planes.
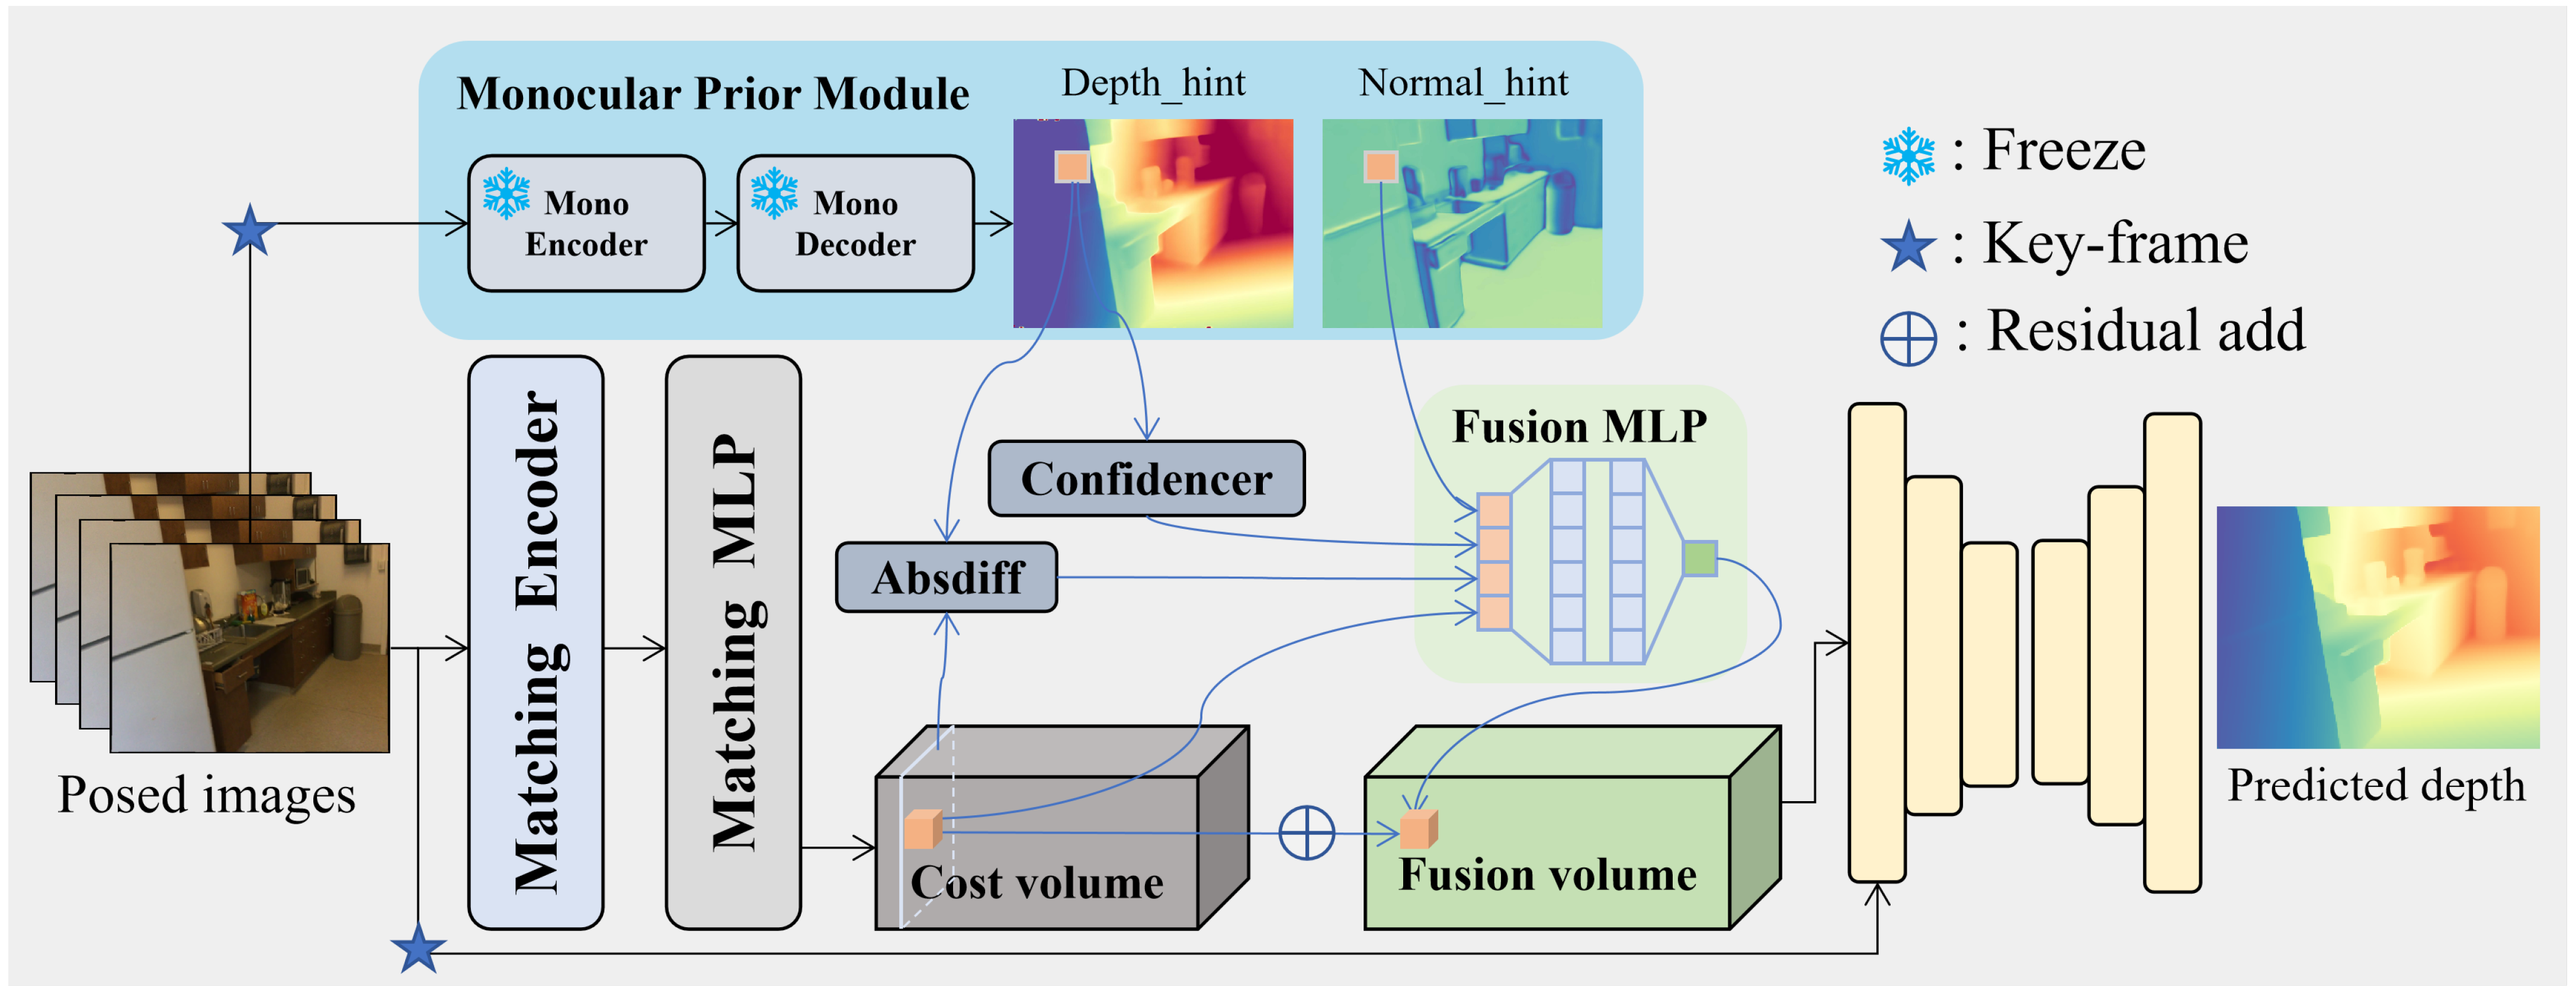
Together, these components enhance depth accuracy, robustness, and cross-domain generalization. Finally, the high-quality depth predictions produced by MPF serve as input to a volumetric fusion pipeline to enable dense 3D reconstruction. An overview of the entire MPF architecture is shown in Figure 2.

3.1. Multi-Frame Backbone

We adopt SimpleRecon (SR) [8] as the multi-frame matching backbone. SR aligns reference-frame features into the keyframe coordinate frame using known camera intrinsics and poses. For each depth hypothesis d i , the warped reference features are correlated with keyframe features to form a 4D cost volume:
C R C × D × H × W ,
where C denotes the feature channels, D the number of depth hypotheses, and ( H , W ) the spatial resolution.
A shared lightweight per-pixel MLP aggregates depth-dependent matching evidence for each pixel ( x , y ) and each hypothesis d i , producing a scalar matching score f d i ( x , y ) R . MPF preserves the cost-volume construction of SR, including the geometric warping and the D discretized depth planes, while following a causal-view protocol to maintain geometric consistency.

3.2. Pixel-Wise Monocular Prior Fusion

Multi-view photometric matching becomes unreliable when texture or parallax is weak. To address this, MPF distinguishes itself from traditional late-fusion methods by incorporating pixel-wise monocular priors directly into the matching hypothesis space.
A pretrained Metric3Dv2 model [24] is applied to generate a monocular depth hint d ̂ and a surface-normal map n ^ . Additionally, a lightweight “Confidencer” module produces a reliability score c ^ to downweight ambiguous monocular predictions. To achieve direct integration at the source of matching, we construct a 4-D hypothesis cue h ( 0 ) ( i , x , y ) for each depth hypothesis d i by concatenating the matching score with monocular geometric features:
h ( 0 ) ( i , x , y ) = f d i ( x , y ) , | d ^ ( x , y ) d i | , n ( x , y ) , c ^ ( x , y ) ,
where | d ^ d i | measures the discrepancy between the prior and the hypothesis. A four-layer Fusion MLP M then maps this 4-D cue to a scalar:
f ˜ d i ( x , y ) = M h ( 0 ) ( i , x , y ) ,
The final hypothesis response H ( i , x , y ) is obtained by a residual combination:
H ( i , x , y ) = f ˜ d i ( x , y ) + f d i ( x , y ) .
Mechanistically, this formulation enables the network to leverage monocular structure to disambiguate matching. The prior discrepancy term acts as a soft geometric gate, suppressing hypothesis peaks that contradict the monocular hint. By modulating the hypothesis space directly, MPF ensures a geometry-aware representation that filters out photometric noise in challenging environments.

3.3. Multi-Scale Fusion Volume

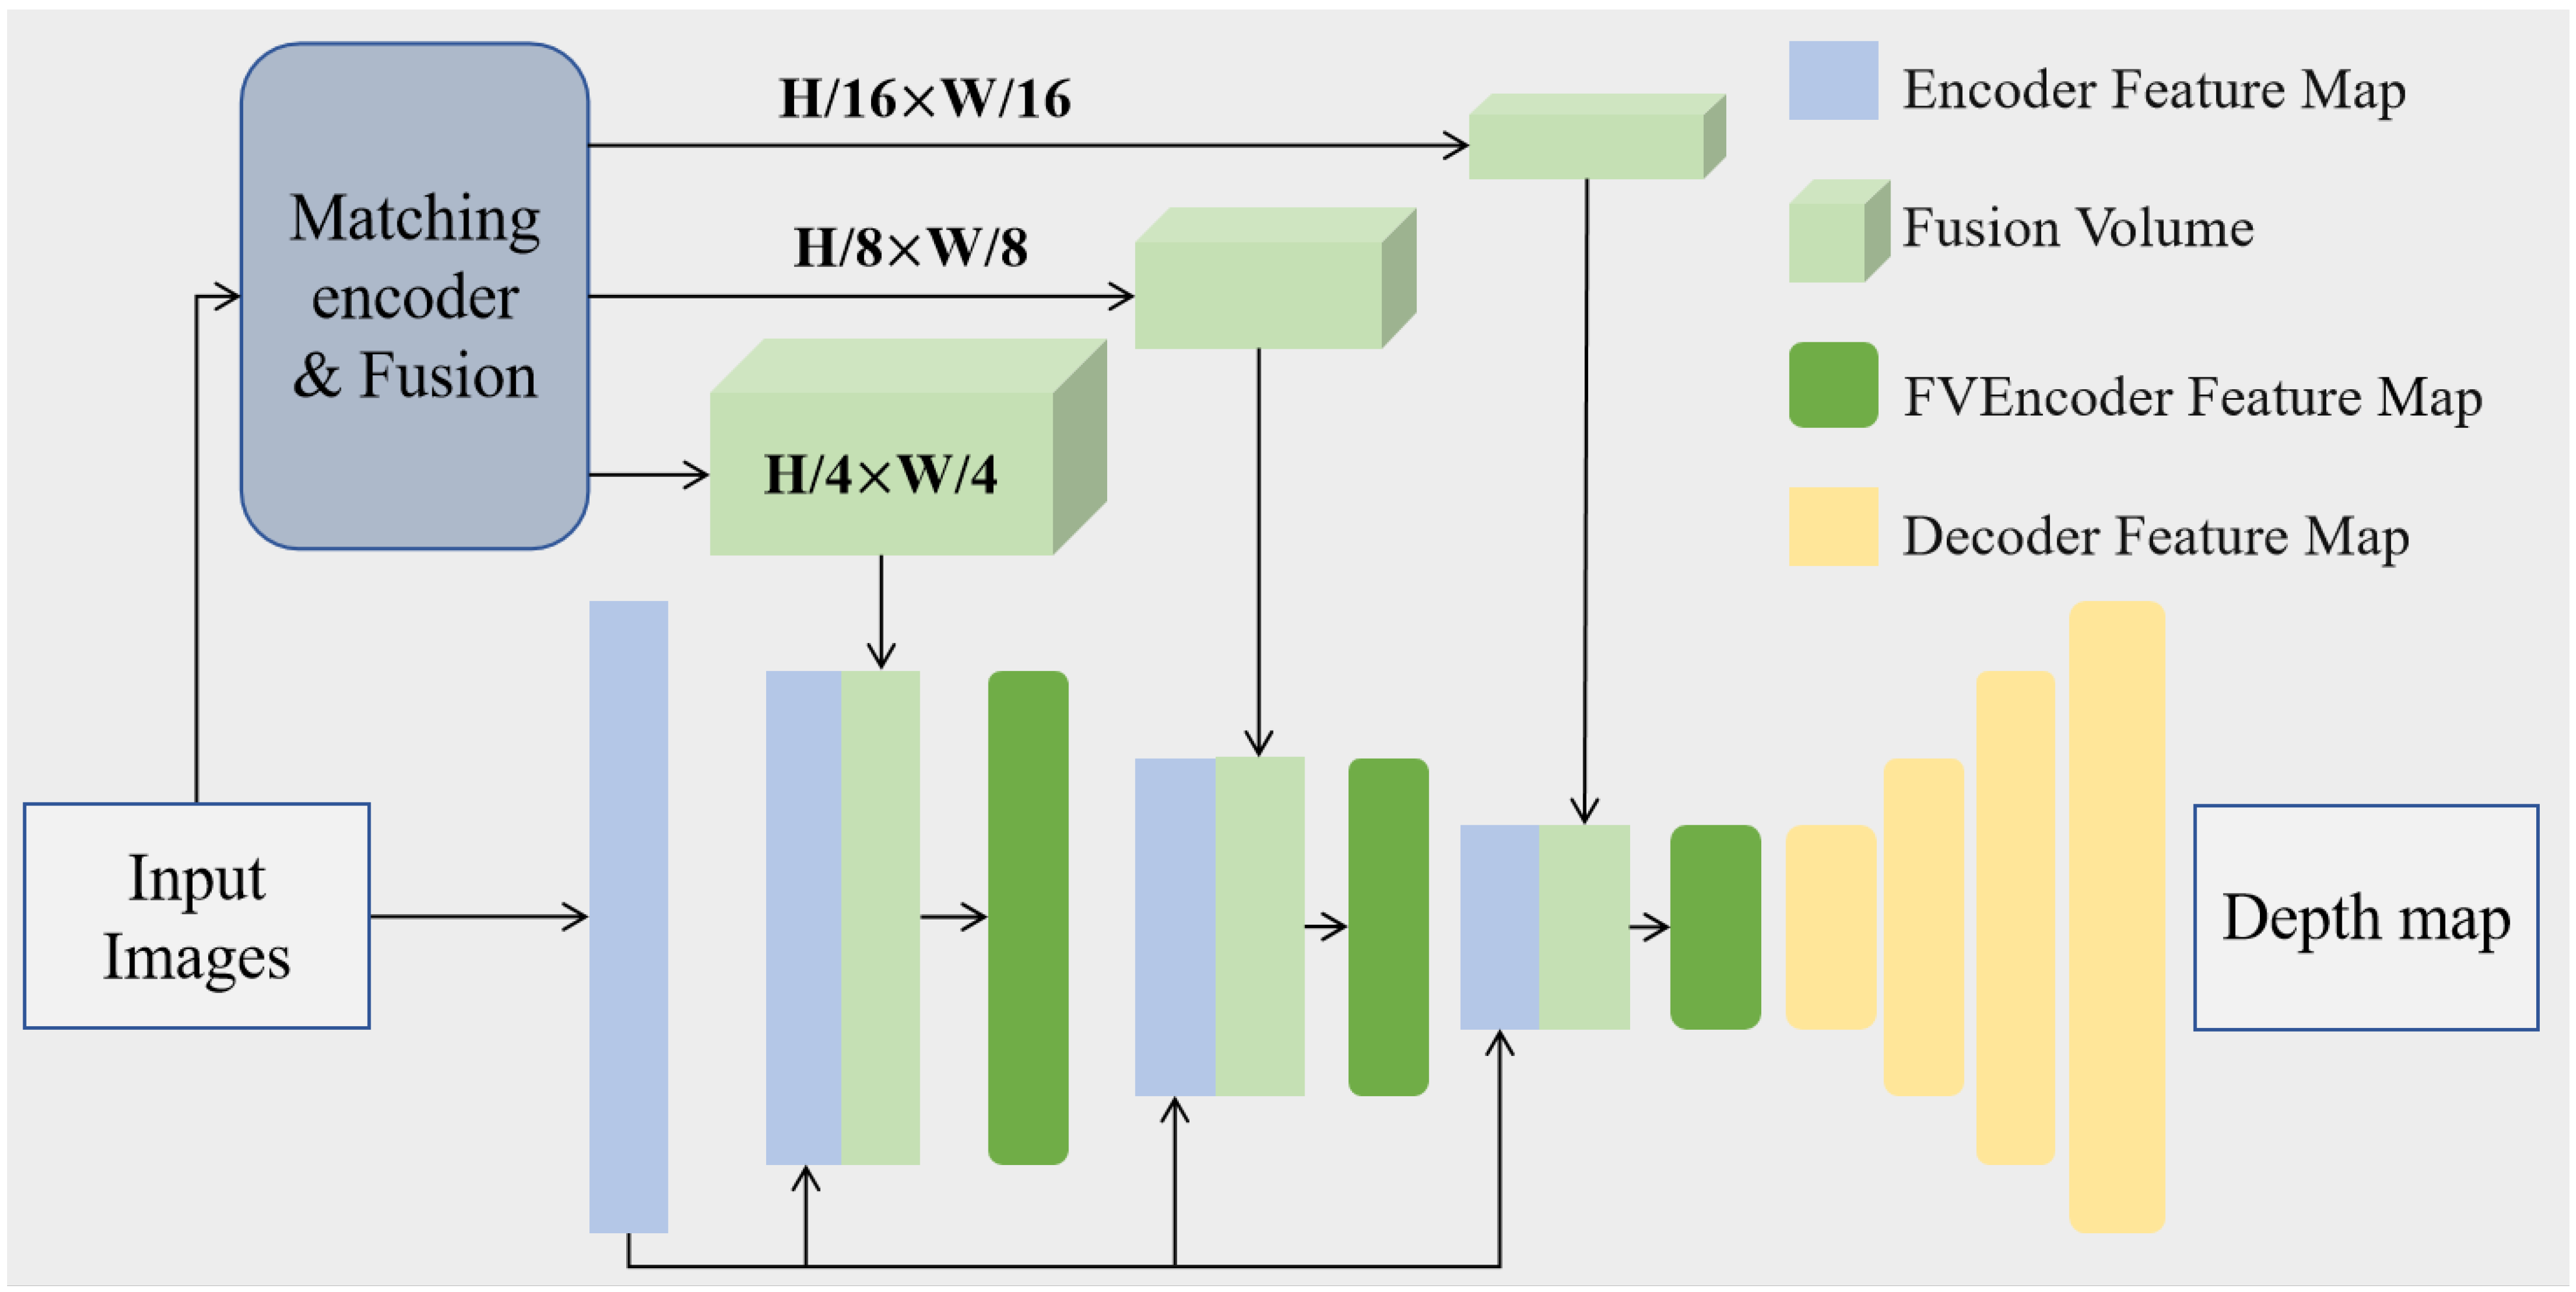
Indoor scenes often exhibit large depth variations, yet SR constructs its cost volume only at H 4 × W 4 spatial resolution, limiting the available global context. MPF introduces a hierarchical architecture for fusion volumes (FVs) that aggregates geometric cues across three resolutions, as illustrated in Figure 3.
The high-resolution FV is initialized by combining the backbone matching features (Section 3.1) with the prior-fused hypothesis responses from Section 3.2. This FV is then downsampled to generate mid- and low-resolution FVs, while maintaining a consistent depth discretization ( D = 64 hypotheses) across all scales. The three spatial resolutions,
H 4 × W 4 , H 8 × W 8 , H 16 × W 16 ,
capture fine-grained details, mid-level structural layout, and coarse global geometry.
At each scale, the FV is refined by a residual BasicBlock [34]. Let X fv ( i ) denote the FV at scale i and let F ( i ) be the corresponding encoder feature map at the same spatial resolution. Following the coarse-to-fine structure shown in Figure 3, the FV from the previous coarser scale is first upsampled and fused with the current FV and its encoder features:
S ( i ) = B × 2 B X fv ( i ) US ( S ( i 1 ) ) F ( i ) , i > 1 ,
where B denotes a single BasicBlock, B × 2 applies two consecutive BasicBlocks, ⊕ denotes channel-wise concatenation, and error denotes bilinear upsampling. At the finest scale, the coarse feature does not exist and the refinement reduces to
S ( 1 ) = B × 2 B ( X fv ( 1 ) ) F ( 1 ) .
This hierarchical fusion allows coarse-scale structure to guide finer refinements while preserving sharp depth boundaries. By propagating geometric cues across resolutions, MPF improves both global consistency and fine-grained structural accuracy.

3.4. Geometric Regularization

MPF enhances geometric fidelity through two complementary constraints, which operate at different spatial scales to improve depth consistency.

3.4.1. Regularization Based on Surface Normals

Given a predicted depth map z ( u , v ) , we estimate local geometric slopes using Sobel filters ( 3 × 3 ). The resulting depth gradients ( d x , d y ) are mapped to a 3D vector under the pinhole model:
n x ( u , v ) = d x f x z ( u , v ) , n y ( u , v ) = d y f y z ( u , v ) , n z ( u , v ) = 1 ,
where setting n z = 1 follows the small-angle approximation [35]. This vector is then normalized to obtain the predicted unit surface normal:
n ^ ( u , v ) = ( n x ( u , v ) , n y ( u , v ) , n z ( u , v ) ) ( n x ( u , v ) , n y ( u , v ) , n z ( u , v ) ) 2 .
Ground-truth normals n ( u , v ) are either provided by the dataset or computed from ground-truth depth using the same procedure. The surface-normal loss penalizes angular deviation via
L sn = 1 | V | ( u , v ) V 1 | n ^ ( u , v ) · n ( u , v ) | ,
where V denotes the set of valid pixels.

3.4.2. Consistency Based on Virtual Planes

While L sn enforces local smoothness, it remains sensitive to noise. To introduce a more global geometric constraint, we adapt virtual-normal supervision [35] to the multi-view depth setting by enforcing consistency over randomly sampled 3D planes.
For a pixel ( u k , v k ) with depth d k , back-projection into 3D yields
a k = d k ( u k u c ) f x , b k = d k ( v k v c ) f y , c k = d k ,
where ( u c , v c ) denotes the principal point. We sample non-degenerate triplets T = { ( Q A , Q B , Q C ) k } k = 1 M within the keyframe only to avoid pose-induced noise. Each triplet satisfies
δ ( Q A Q B , Q A Q C ) γ , | Q A Q B | , | Q A Q C | > ϵ .
Using ground-truth depth, each triplet defines a plane normal:
N k = ( Q B Q A ) × ( Q B Q C ) ( Q B Q A ) × ( Q B Q C ) 2 .
Applying the same construction to the predicted depth yields the estimated normal N ^ k . The geometric consistency loss based on virtual planes is defined as follows:
L vn = 1 | T | k T 1 | N ^ k · N k | .
Compared with purely local normal supervision, L vn enforces geometric alignment over larger spatial regions by constraining entire planar surfaces in 3D. Crucially, this global constraint helps rectify scale ambiguities often present in monocular priors, ensuring that the fused depth map respects the structural layout of the scene while preserving sharp discontinuities.

3.5. Training Objective

MPF is trained using a combination of depth, gradient, multi-frame consistency, and geometric regularization losses. The overall objective follows the training protocol of SimpleRecon (SR) [8], while incorporating our proposed constraints derived from surface normals and virtual planes.

3.5.1. Baseline Losses

Following SR, we supervise the predicted depth map using three standard losses:
  • Depth regression loss L depth , implemented as an 1 loss on inverse depth, identical to SR.
  • Gradient loss L grad , computed using first-order finite differences on depth to encourage edge alignment.
  • Multi-view consistency loss L mv , following SR’s formulation based on reprojection depth consistency between the reference views and the predicted keyframe depth.
These baseline terms encourage photometric and geometric agreement across the multi-frame backbone.

3.5.2. Proposed Geometric Losses

The surface-normal loss L sn (Section 3.4) provides local geometric refinement and improves high-frequency details. The consistency loss based on virtual planes L vn enforces global geometric alignment by encouraging predicted 3D points to agree with ground-truth planar structures.
Together, L sn and L vn provide complementary local and global geometric constraints.

3.5.3. Total Loss

The full training objective is
L = L depth + L sn + α grad L grad + α mv L mv + α vn L vn ,
where we follow SR and set α grad = 1.0 and α mv = 0.2 . The weight for the loss based on virtual planes is α vn = 0.2 . All losses are computed only at the final output resolution and normalized by the number of valid pixels.
This combination jointly supervises fine-scale local geometry, cross-view photometric reasoning, and global structural consistency, consistent with the design for geometric fusion from multiple sources of MPF.

3.6. Implementation Details

We follow the causal-view training protocol of SR [8], where each keyframe aggregates seven preceding reference frames sampled with stride 1. MPF is trained for 20 epochs using AdamW with an initial learning rate of 1 × 10 4 . All remaining optimization and hardware configurations—including batch sizes, learning rate scheduling, and memory management strategies—are provided in Appendix A. A detailed analysis of computational efficiency (runtime and memory) is presented in Section 4.5.

4. Experiments

This section evaluates MPF on large-scale indoor RGB-D datasets, examining depth accuracy, cross-domain generalization, ablation behaviors, 3D reconstruction quality, and computational efficiency. To maintain clarity, complete metric definitions, extended qualitative comparisons, and additional tables are provided in the Appendix B.

4.1. Datasets and Evaluation Protocol

MPF is trained exclusively on ScanNetV2 [13] and evaluated in a strictly zero-shot manner on 7Scenes [36], TUM RGB-D [37], and GMU Kitchens [38]. These datasets exhibit diverse challenges, including low texture, repetitive indoor patterns, motion blur, strong lighting variation, and high-resolution imagery. Dataset statistics are summarized in Table 2.
We report the standard depth metrics AbsRel, AbsDiff, SqRel, and δ -accuracy thresholds. Full definitions are available in Appendix B. Invalid or missing ground-truth depth pixels are masked out following common RGB-D evaluation protocols.
We compare MPF against representative multi-view and multi-frame methods: DPN [29], DELTAS [39], GPMVS [40], DVMS [9], SimpleRecon (SR) [8], DoubleTake (DT) [14], and MVSA [30]. This selection covers both established baselines and the most recent state-of-the-art approaches.

4.2. Results on ScanNetV2 (Seen Domain)

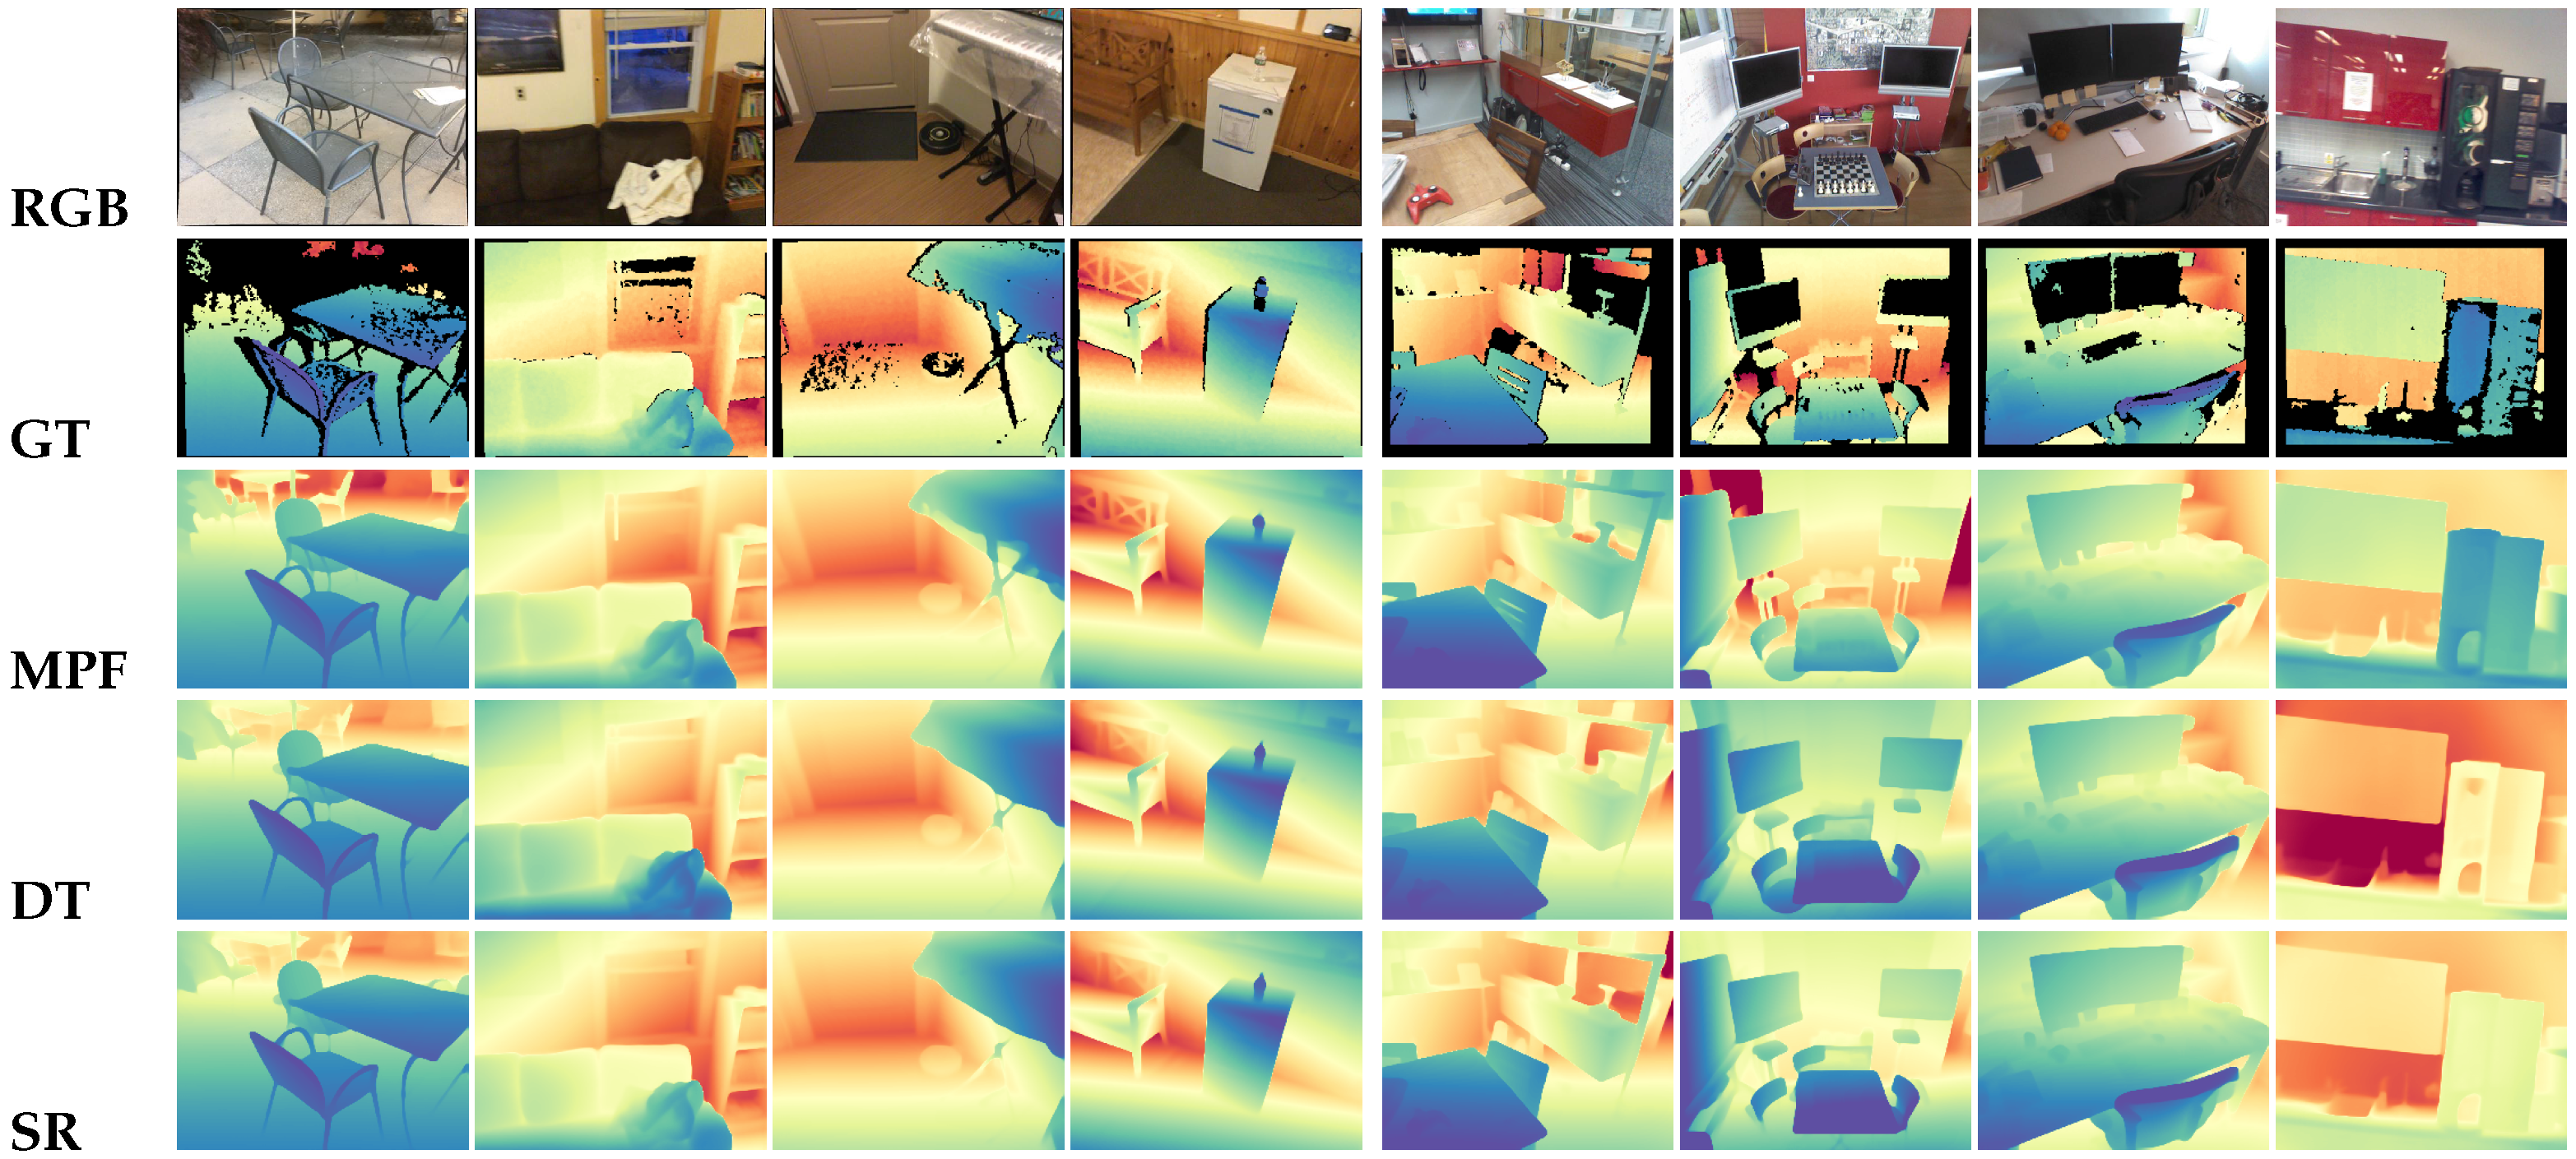
Table 3 summarizes the quantitative evaluation on the ScanNetV2 test set. MPF achieves state-of-the-art performance, outperforming both the strong baseline SimpleRecon (ECCV 2022) and the recent DoubleTake (ECCV 2024). Specifically, compared to SimpleRecon, MPF reduces AbsRel by 11% and SqRel by approximately 35%. This significant improvement validates that our proposed prior-guided modulation effectively disambiguates cost volumes in regions where photometric consistency alone fails (e.g., white walls and reflective floors), preventing the “oversmoothing” artifacts common in traditional multi-frame methods. Qualitative comparisons in Figure 4 further confirm that MPF recovers sharper object contours and thinner structures.

4.3. Zero-Shot Generalization to 7Scenes, TUM, and GMU

To evaluate robustness, we test models trained on ScanNetV2 directly on unseen datasets without fine-tuning.
7Scenes. As shown in Table 4 (left), MPF achieves the best performance across all metrics on 7Scenes. Since 7Scenes contains extremely low texture and repetitive patterns (e.g., stairs and cabinets), purely photometric methods like SR and DT struggle to find reliable correspondence. By leveraging monocular structural priors, MPF effectively rectifies these ambiguities, preserving planar structures and depth discontinuities even in textureless regions.
TUM RGB-D. Results on the large-scale TUM dataset are shown in Table 4 (right). It is worth noting that MVSA [30] achieves high δ -accuracy ( a 10 ) due to its large-scale pretraining, which learns robust relative depth. However, MVSA suffers from scale ambiguity in zero-shot transfer, resulting in higher absolute errors (AbsDiff). In contrast, MPF delivers superior metric accuracy (lowest AbsDiff and AbsRel), demonstrating that our framework successfully grounds monocular cues with multi-view geometry to maintain precise metric scale.
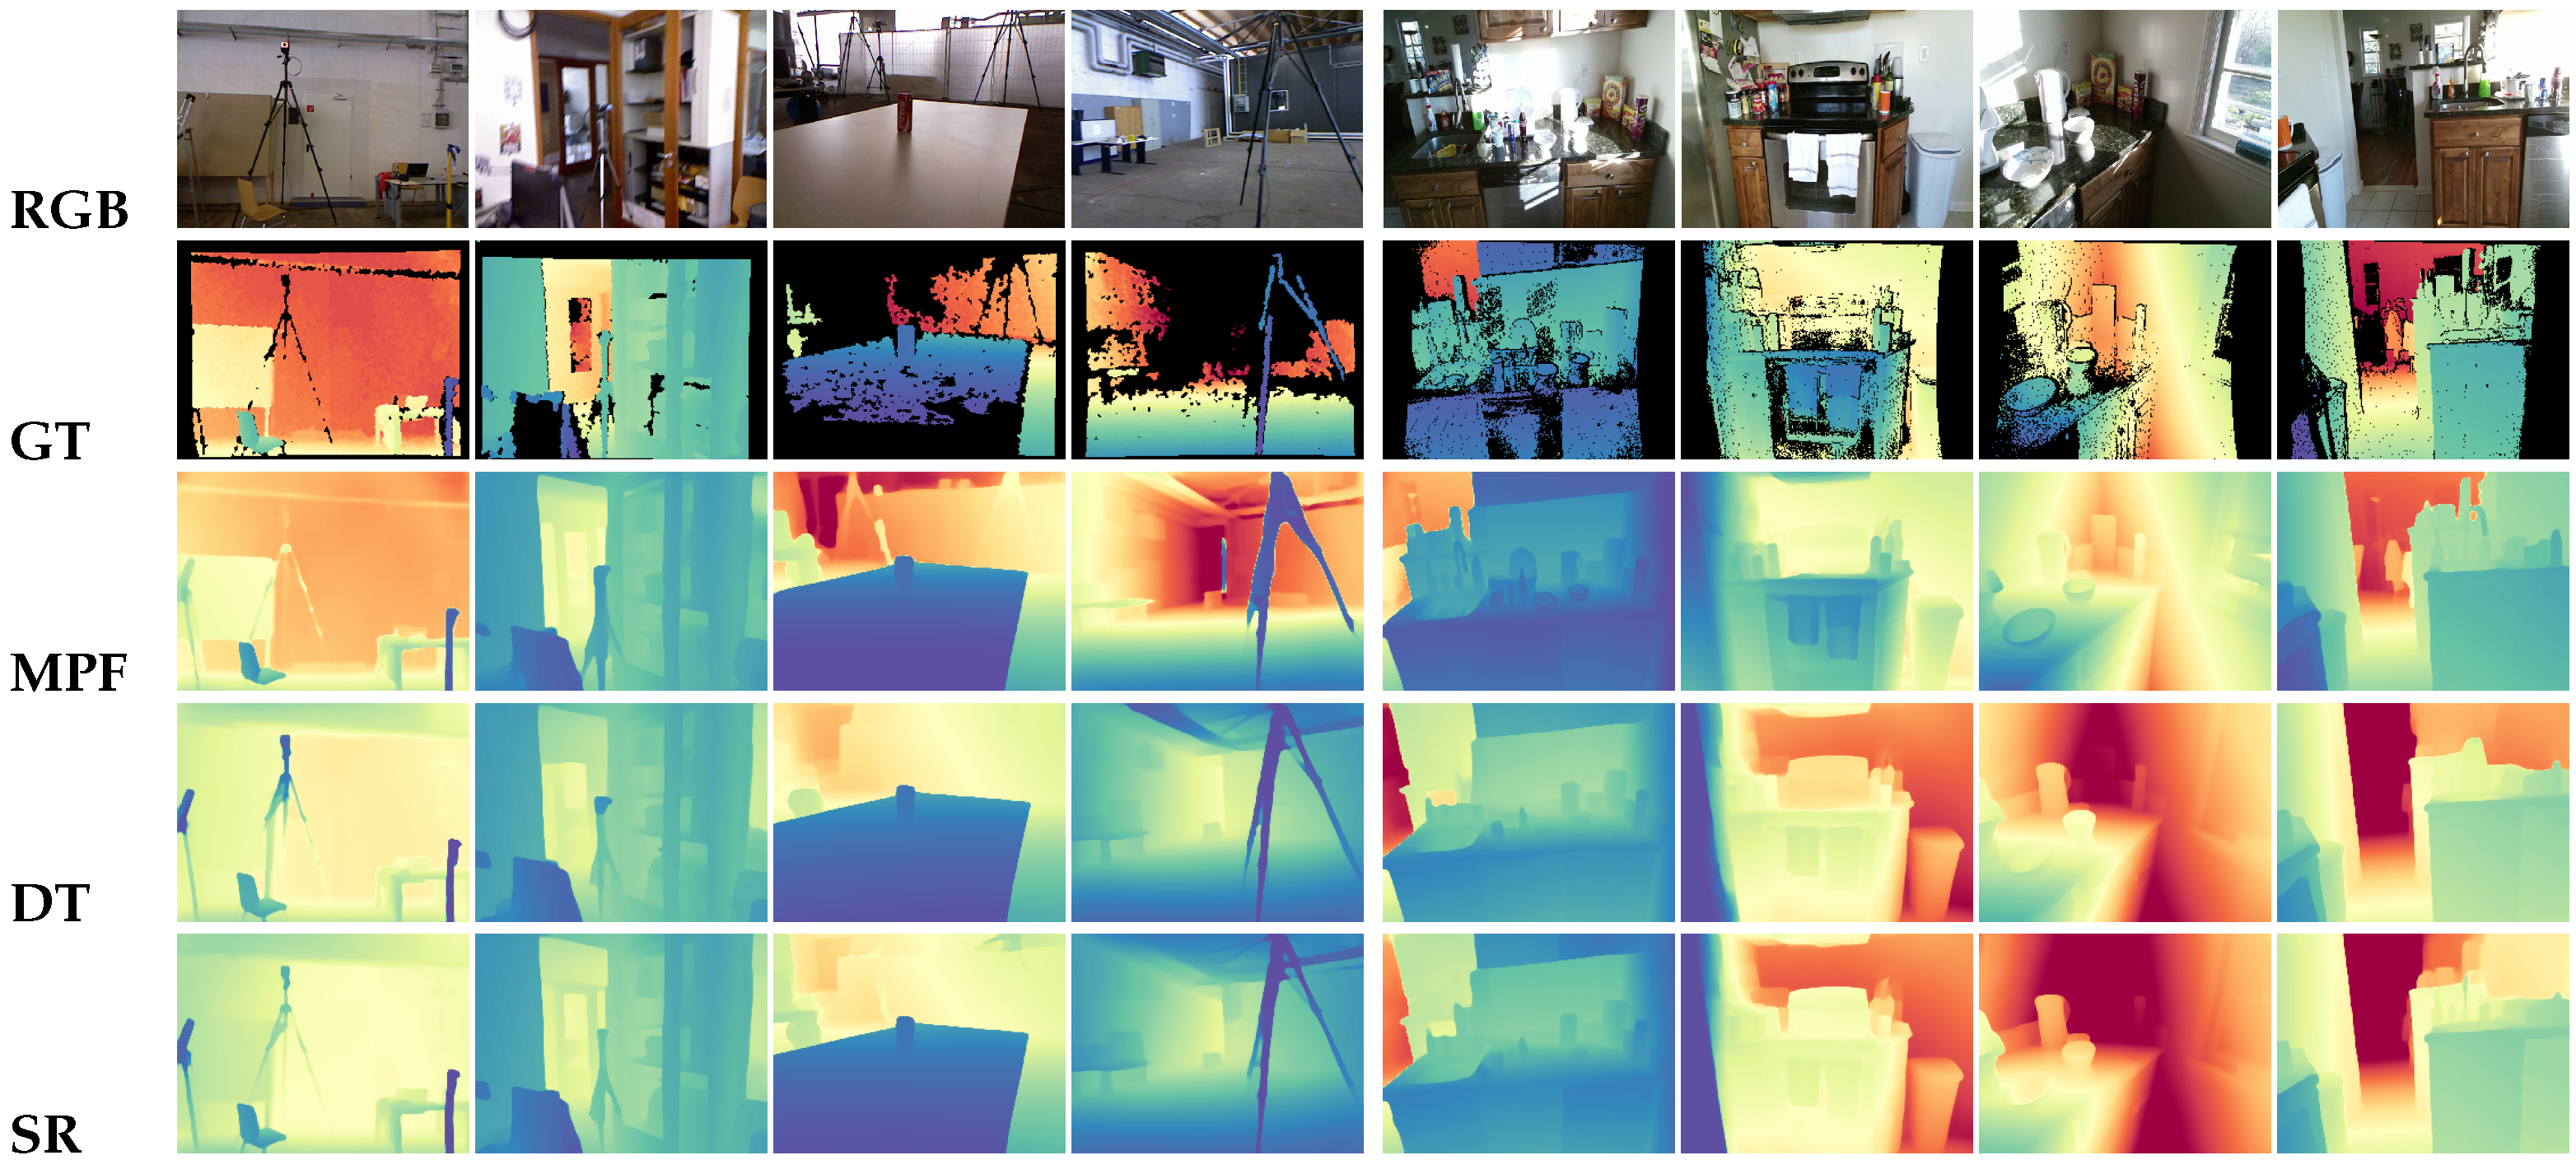
GMU Kitchens. GMU presents extreme challenges with dramatic lighting variation and reflective surfaces. As shown in Table 5, classical baselines exhibit catastrophic failure modes (high AbsDiff > 0.27) due to unreliable photometric cues. In contrast, MPF maintains stable performance (AbsDiff ≈ 0.09), substantially outperforming all baselines. Note that we report only stable multi-frame results; MVSA produced unstable predictions on this dataset due to the severe domain shift and sensor noise and is thus excluded from this specific comparison (raw outputs provided in Appendix B). Qualitative visualizations in Figure 5 show that MPF produces clean depth on strongly lit surfaces where other methods exhibit noisy or fragmented geometry.

4.4. Ablation and Component Analysis

Ablation experiments are performed on the 7Scenes dataset using a 40% randomly sampled subset of the ScanNetV2 training data. This reduced subset accelerates experimentation while maintaining a representative distribution of indoor scenes.

4.4.1. Component Effectiveness

Table 6 summarizes the effect of progressively adding each MPF component. The baseline configuration (MPF-base w/o F,M,V) preserves only the multi-frame matching backbone. Given that the baseline is architecturally equivalent to SR, the qualitative comparisons in Figure 4 and Figure 5 serve as a direct visual ablation, demonstrating the cumulative geometric gains achieved by our proposed prior-guided fusion and consistency constraints over the pure photometric baseline.
As shown in Table 6, the baseline exhibits the lowest accuracy (AbsRel 0.0630), reflecting the inherent limitations of purely photometric correspondence. Incorporating the fusion module (w/F) integrates monocular priors directly into the cost volume, which noticeably improves depth hypothesis discrimination. Adding the hierarchical fusion volume (w/F,M) further strengthens geometric reasoning by enabling coarse-to-fine feature aggregation. Finally, the full model (w/F,M,V) achieves the highest accuracy, demonstrating that the geometric consistency loss based on virtual planes provides complementary global geometric constraints. Visually, this corresponds to the recovery of sharp planar structures and fine edges in MPF compared to the oversmoothed baseline results (SR) in Figure 4.

4.4.2. Cost-Volume Discriminability

To verify that our method improves the quality of the matching distribution itself (and not just the final regression), Table 7 evaluates Rank Percentile (RP), Depth Margin (DM), and Quadfit MAE (Q-MAE) before and after applying the Fusion Network. Remarkably, the fusion module reduces the Rank Percentile error by over 5 × at the 1 / 4 resolution (0.354 → 0.051). This provides direct quantitative evidence of how our pixel-wise early fusion manifests in practice: by modulating the hypothesis space at the source (as described in Section 3.2), MPF effectively “sharpens” the probability distribution around the true depth. This structural improvement enables the network to recover correct geometry even when photometric signals are ambiguous, which is a direct consequence of our proposed direct integration strategy.

4.5. Depth Reconstruction and Runtime Analysis

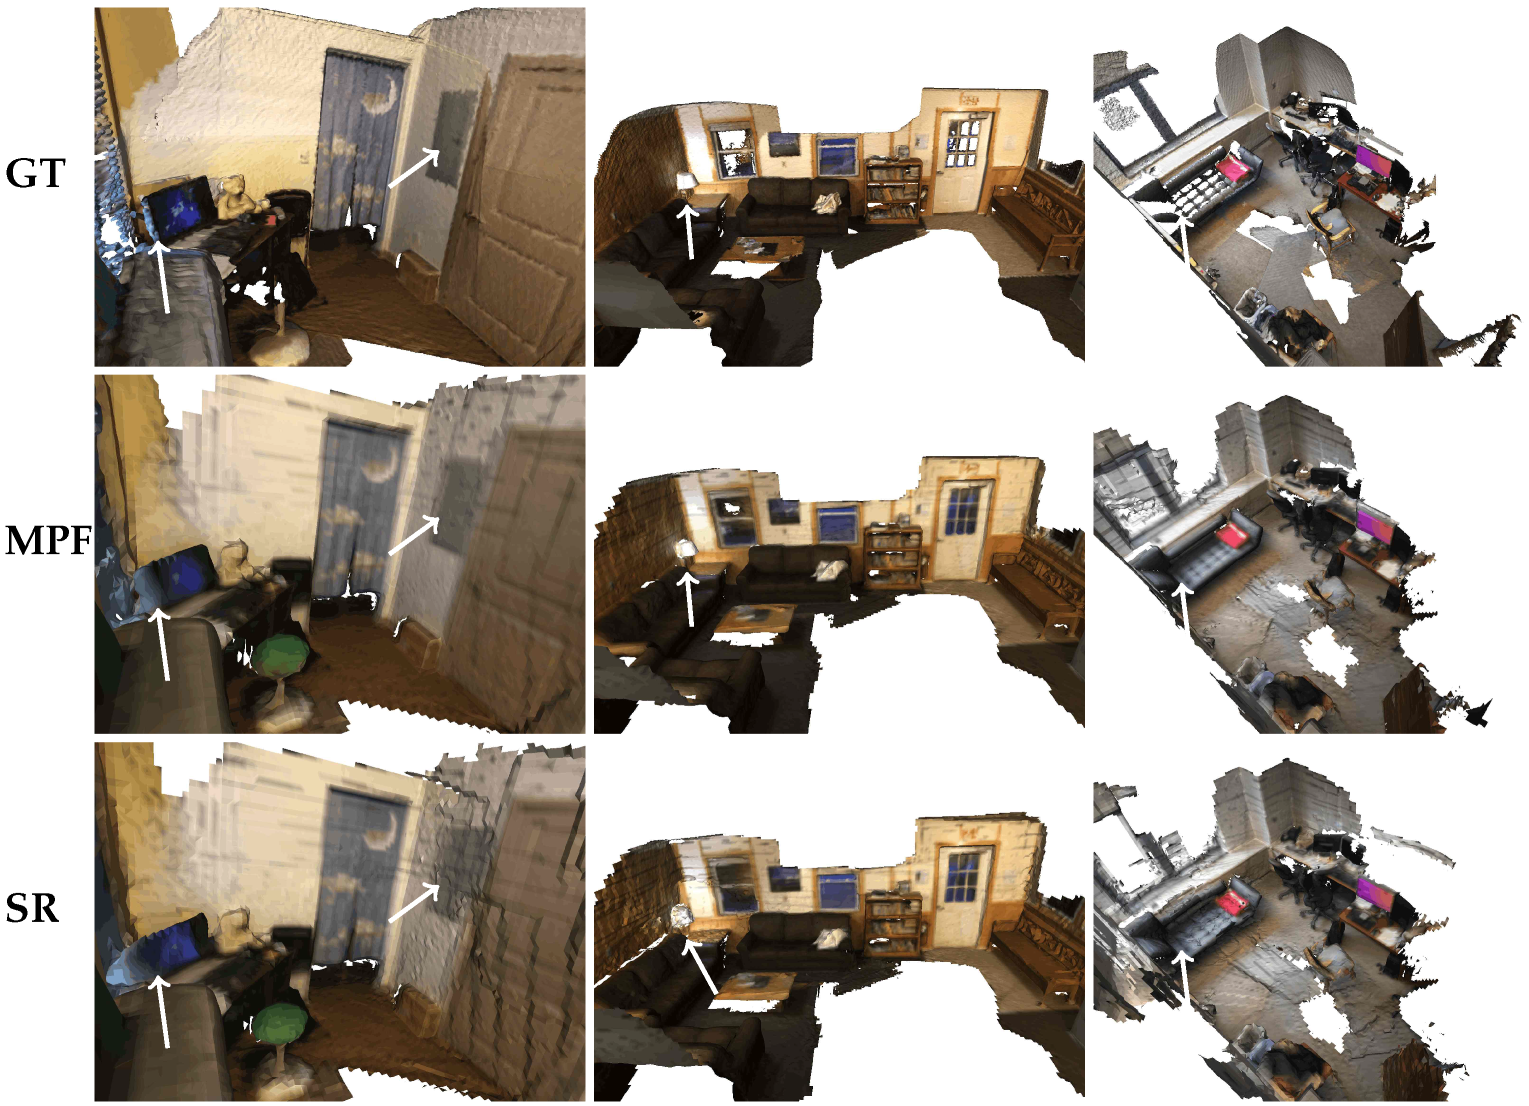
We integrate predicted depths into a volumetric fusion pipeline following TransformerFusion [41]. As shown in Table 8, MPF achieves the lowest geometric error and highest precision. Figure 6 illustrates that MPF reconstructs smoother planar surfaces, cleaner object boundaries, and finer geometric structures than SR, confirming the benefit of more accurate depth inputs for downstream 3D reconstruction.

Computational Efficiency

MPF processes each keyframe in 0.172 s on NVIDIA GeForce RTX 4090 GPU (NVIDIA Corporation, Santa Clara, CA, USA), of which 0.047 s is spent on the frozen monocular prior and 0.114 s on cost-volume construction and fusion. Peak memory consumption is 6.4 GB. With a 10:1 keyframe compression ratio, MPF achieves throughput compatible with real-time multi-frame pipelines.

4.6. Limitations and Discussion

While monocular priors significantly improve geometric detail, they introduce additional inference cost (approx. 47 ms) and may be sensitive to strong domain shifts where the pretrained prior fails. MPF also assumes known intrinsics and poses. Recent pose-free frameworks [32,33] suggest promising directions for removing this requirement. Future work will explore more efficient prior integration and pose-free multi-view depth estimation.

5. Conclusions

We presented MonoPrior-Fusion (MPF), a multi-frame depth estimation framework that combines monocular priors with multi-view geometric reasoning. A fusion module across multiple scales and a geometric consistency loss based on virtual planes were introduced to address textureless regions, small baselines, and challenging indoor conditions. Extensive experiments demonstrate that MPF achieves strong accuracy, robustness, and practical runtime efficiency across multiple benchmarks. These results highlight MPF’s potential for deployment in real-world 3D perception, reconstruction, and embodied AI systems. Future work will extend MPF to outdoor and dynamic environments and investigate integration with large-scale pretrained vision models.


Author Contributions

Conceptualization, Z.L. and L.Q.; methodology, Z.L.; software, Z.L.; validation, Z.L., B.S. and Z.Z.; formal analysis, Z.L.; investigation, Z.L. and B.S.; resources, L.Q.; data curation, Z.L.; writing—original draft preparation, Z.L.; writing—review and editing, L.Q., N.Y. and Z.Z.; visualization, Z.L.; supervision, L.Q. and N.Y.; project administration, L.Q.; All authors have read and agreed to the published version of the manuscript.

Funding

This work was supported by the Research Fund of Xiangtan University under Grant No. XDCX2025Y210 and in part by the National Natural Science Foundation of China (NSFC) under Grant No. 12431014.

Institutional Review Board Statement

Not applicable.

Informed Consent Statement

Not applicable.

Data Availability Statement

All data supporting the findings of this study are obtained from publicly available RGB-D datasets. The complete data preparation pipeline, experimental code, and evaluation scripts are publicly available at https://github.com/2k-lin/MPF-DepthEstimation (accessed on 18 January 2026), ensuring full reproducibility of the reported results.

Acknowledgments

The authors would like to thank all contributors who supported this research.

Conflicts of Interest

Authors Zhiwei Lin, Bohan Sun and Zhan Zhang and Linrui Qian were employed by the company CogLeap.AI Space Intelligence (Wuxi) Technology Co., Ltd. The remaining authors declare that the research was conducted in the absence of any commercial or financial relationships that could be construed as a potential conflict of interest.

Abbreviations

The following abbreviations are used in this manuscript:
AbsDiffAbsolute Difference
AbsRelAbsolute Relative error
CNNConvolutional Neural Network
DTDoubleTake
FVFusion Volume
GMUGeorge Mason University (Dataset)
GTGround Truth
M3vMetric3Dv2
MLPMulti-Layer Perceptron
MPFMonoPrior-Fusion
MVSMulti-View Stereo
RGB-DRed–Green–Blue and Depth
RMSERoot Mean Square Error
SLAMSimultaneous Localization and Mapping
SqRelSquared Relative error
SRSimpleRecon
TUMTechnical University of Munich (Dataset)

Appendix A. Full Implementation Details

Appendix A.1. Training Setup

All experiments follow the causal-view protocol of SimpleRecon (SR) [8], in which each keyframe is paired with seven temporally preceding reference frames. We train MPF for 20 epochs using AdamW with an initial learning rate of 1 × 10 4 , decayed linearly. Two hardware configurations are used: (i) 40% of ScanNetV2 [13] with batch size 16 on two NVIDIA A100 GPUs (NVIDIA Corporation, Santa Clara, CA, USA) for ablation studies and (ii) full ScanNetV2 with batch size 8 on two NVIDIA GeForce RTX 4090 GPU (NVIDIA Corporation, Santa Clara, CA, USA) for final benchmarking.

Appendix A.2. Depth Hypotheses and Multi-Scale Volumes

We adopt D = 64 depth planes uniformly sampled in inverse depth over [ 0.001 , 10 ] meters. The same D hypotheses are used at all three spatial resolutions ( H 4 , H 8 , and H 16 ), ensuring consistent geometric discretization. To control memory usage, feature channel dimensions decrease with spatial resolution, and coarse levels use proportionally fewer channels.

Appendix A.3. Network Architecture

EfficientNetV2-S [42] is used as the keyframe encoder, and a UNet++ decoder [43] regresses the final depth map. For multi-scale fusion volumes, features from the first four residual blocks of ResNet18 [34] are extracted at H 4 , H 8 , and H 16 resolutions. The fusion MLP consists of four fully connected layers with 16 hidden units, expanding the 4-D prior cue to the cost-volume channel dimension C.

Appendix A.4. Monocular Prior Extraction

The monocular model Metric3Dv2 (M3v) [24] is kept frozen during training. For each keyframe, M3v provides two pixel-wise priors: (1) a monocular depth estimate d ^ and (2) an RGB-encoded surface-normal map n ^ . Since M3v does not provide confidence estimates, we compute a confidence prior c ^ from the predicted depth by measuring its deviation from the valid inverse-depth range used during multi-frame matching. Pixels with d ^ near or outside the predefined range [ 0 , 10 ] m receive lower confidence, while in-range predictions receive higher reliability scores. All monocular priors are computed once per keyframe and cached for subsequent iterations, introducing negligible runtime overhead.

Appendix A.5. Normal-to-Scalar Projection

The surface-normal prior produced by the pretrained monocular model is provided in an RGB-encoded format n ^ ( u , v ) R 3 . To integrate this prior efficiently into the hypothesis fusion pipeline, we convert the three-channel normal map into a scalar orientation cue using a luminance-based projection:
n ( u , v ) = 0.299 r + 0.587 g + 0.114 b .
This mapping preserves relative orientation variations while preventing over-parameterization in the fusion MLP.

Appendix A.6. Sampling of Virtual Planes

For the loss based on virtual planes (Section 3.4), 15% of valid keyframe pixels are sampled per iteration. Triplets ( Q A , Q B , Q C ) are sampled from the keyframe only to avoid pose-induced noise. We set the maximum angular deviation to γ = 120 , the minimum deviation to δ = 30 , and the minimum distance to ϵ = 0.6 m.

Appendix A.7. Dataset and Evaluation Protocol

To emulate realistic online mapping, reference frames are drawn only from preceding timestamps. All competing methods are evaluated under identical causal-view constraints.

Appendix B. Additional Results

Appendix B.1. Evaluation Metrics

We report five standard depth estimation metrics: AbsDiff, AbsRel, SqRel, a 10 , and a 25 . Let Ω denote the set of valid pixels ( | Ω | = N ), d ( p ) the predicted depth, and d ( p ) the ground truth at pixel p Ω . The metrics are defined as follows:
AbsDiff = 1 N p Ω | d ( p ) d ( p ) | ,
AbsRel = 1 N p Ω | d ( p ) d ( p ) | d ( p ) ,
SqRel = 1 N p Ω ( d ( p ) d ( p ) ) 2 d ( p ) ,
a x = 100 N | p Ω : max d ( p ) d ( p ) , d ( p ) d ( p ) < 1 + x 100 | , x { 10 , 25 } .
Here, a 10 and a 25 denote the percentage of pixels within 10 % and 25 % relative error bounds. Lower is better for AbsDiff/AbsRel/SqRel; higher is better for a x .

Appendix B.2. MVSA on GMU

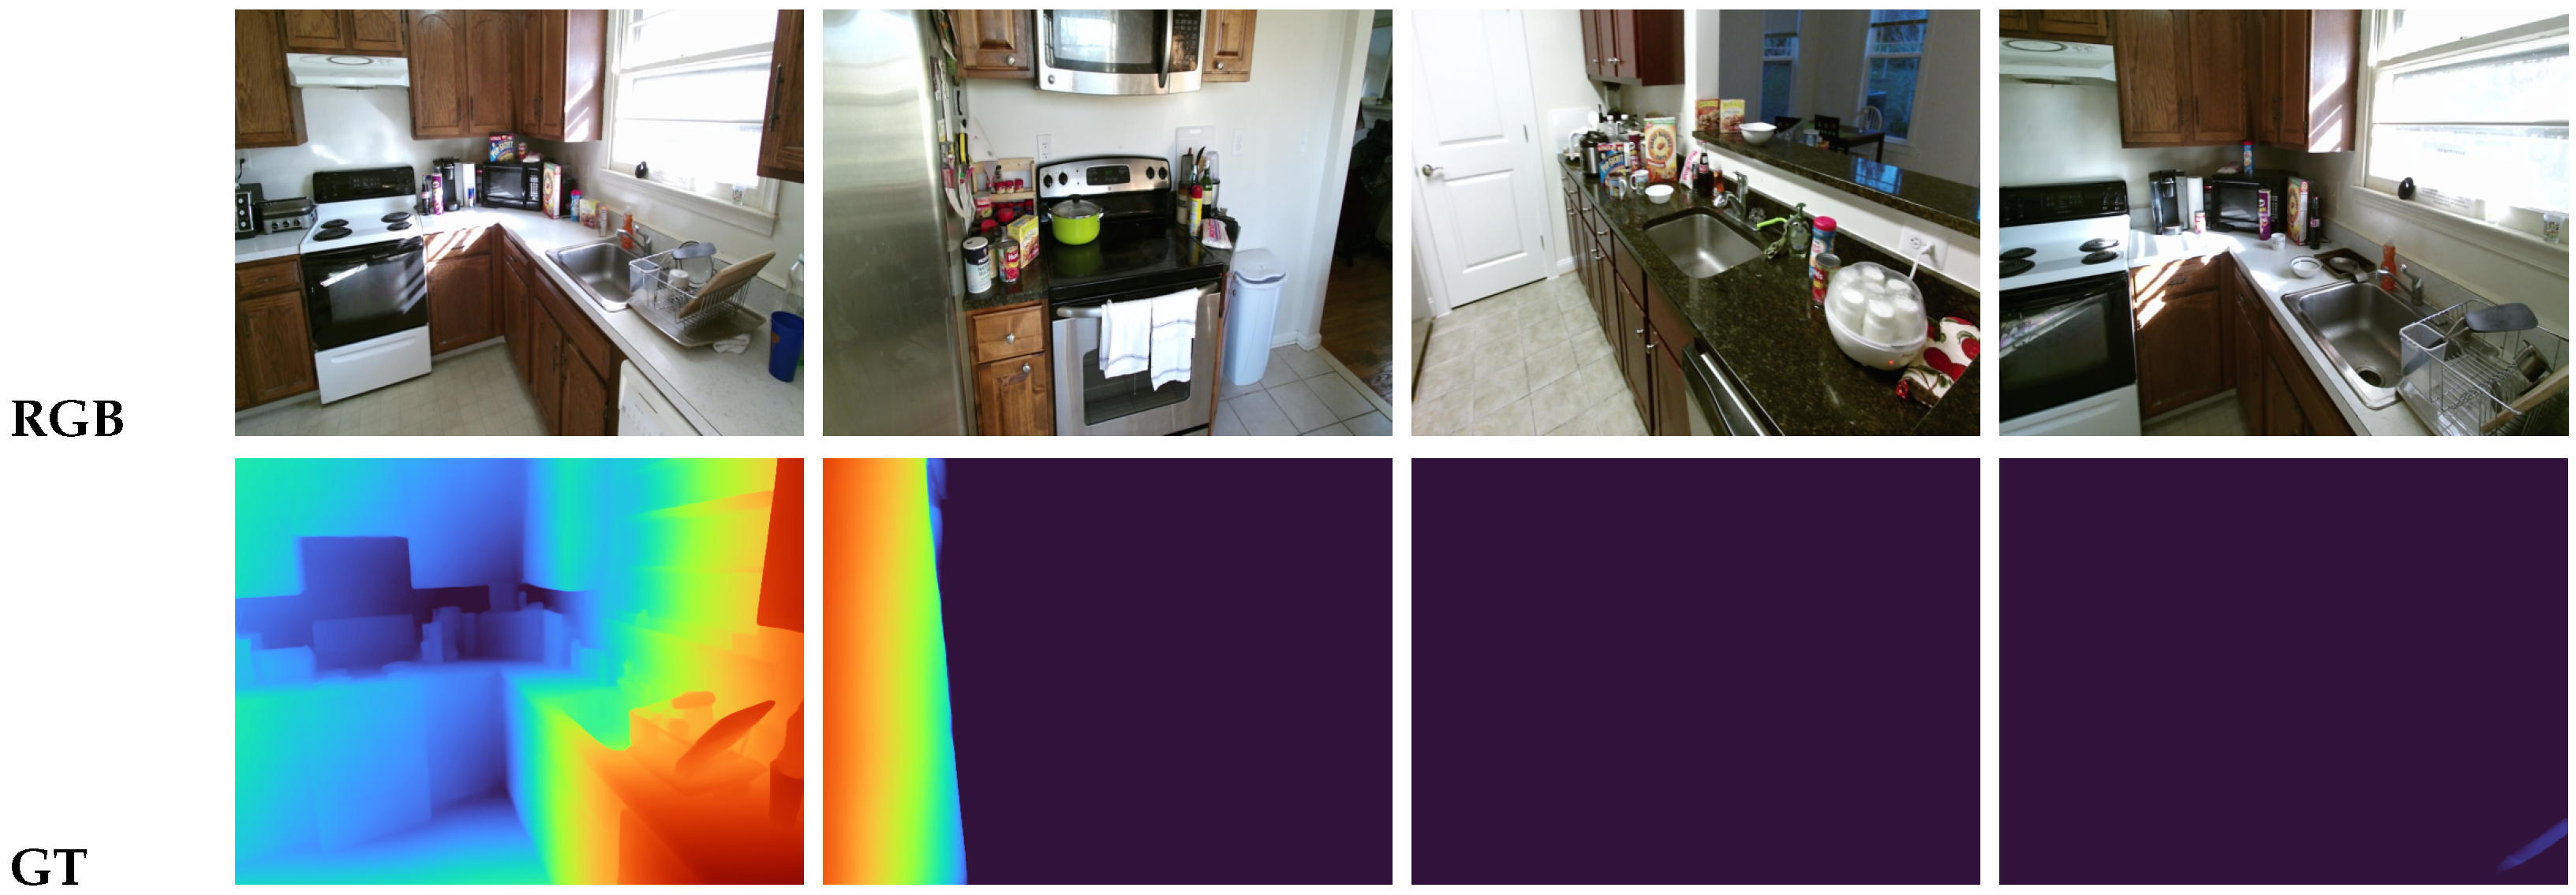
Table A1 reports the raw evaluation metrics of MVSA on the GMU dataset. Although data preprocessing was verified to be correct, the majority of predictions degenerated into nearly uniform outputs with no meaningful depth variation. As a result, the reported numbers are abnormally poor. Figure A1 further illustrates this issue: while some frames show valid depth structure, most collapse into a single-color map, highlighting the instability of MVSA under the GMU sensor configuration. For transparency, we include these results here but omit them from the main comparison tables.
Figure A1. Qualitative MVSA results on GMU. Warm colors (e.g., red) indicate closer distances, while cool colors (e.g., blue) indicate further distances. In a few cases, MVSA predicts reasonable depth, but in most scenes the outputs collapse to uniform single-color maps, providing no useful geometric information. This confirms that MVSA is not suitable for GMU despite correct preprocessing.
Sensors 26 00712 g0a1
Table A1. MVSA results on GMU. Bold indicates the best performance, and arrows (↑/↓) indicate that higher/lower values are better. The metrics collapse due to degenerate uniform predictions, demonstrating that MVSA is unsuitable for GMU. Reported here only for completeness.
MethodAbsDiff ↓AbsRel ↓SqRel ↓ a 10 a 25
MVSA6.14575.631674.04621.12092.6884

References

  1. Laina, I.; Rupprecht, C.; Belagiannis, V.; Tombari, F.; Navab, N. Deeper Depth Prediction with Fully Convolutional Residual Networks. In Proceedings of the International Conference on 3D Vision (3DV), Stanford, CA, USA, 25–28 October 2016. [Google Scholar]
  2. Fu, H.; Gong, M.; Wang, C.; Batmanghelich, K.; Tao, D. Deep Ordinal Regression Network for Monocular Depth Estimation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Salt Lake City, UT, USA, 18–23 June 2018. [Google Scholar]
  3. Yang, L.; Kang, B.; Huang, Z.; Xu, X.; Feng, J.; Zhao, H. Depth Anything: Unleashing the Power of Large-Scale Unlabeled Data. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 17–21 June 2024. [Google Scholar]
  4. Bochkovskii, A.; Delaunoy, A.; Germain, H.; Santos, M.; Zhou, Y.; Richter, S.R.; Koltun, V. Depth Pro: Sharp Monocular Metric Depth in Less Than a Second. In Proceedings of the International Conference on Learning Representations (ICLR), Singapore, 24–28 April 2025. [Google Scholar]
  5. Hemmati, E.; Jarahizadeh, S.; Aghabalaei, A.; Asadollah, S.B.H.S. Enhanced Monocular Depth Estimation Using Novel Scale-Invariant Error Structure Similarity Index Measure Optimization in Convolutional Neural Network Architecture. J. Vis. Commun. Image Represent. 2025, 98, 104052. [Google Scholar] [CrossRef] [Scilit]
  6. Chen, S.; Guo, H.; Zhu, S.; Zhang, F.; Huang, Z.; Feng, J.; Kang, B. Video Depth Anything: Consistent Depth Estimation for Super-Long Videos. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Nashville, TN, USA, 11–15 June 2025. [Google Scholar]
  7. Yao, Y.; Luo, Z.; Li, S.; Fang, T.; Quan, L. MVSNet: Depth Inference for Unstructured Multi-View Stereo. In Proceedings of the European Conference on Computer Vision (ECCV), Munich, Germany, 8–14 September 2018. [Google Scholar]
  8. Sayed, M.; Gibson, J.; Watson, J.; Prisacariu, V.; Firman, M.; Godard, C. SimpleRecon: 3D Reconstruction without 3D Convolutions. In Proceedings of the European Conference on Computer Vision (ECCV), Tel Aviv, Israel, 23–27 October 2022. [Google Scholar]
  9. Duzceker, A.; Galliani, S.; Vogel, C.; Speciale, P.; Dusmanu, M.; Pollefeys, M. DeepVideoMVS: Multi-View Stereo on Video with Recurrent Spatio-Temporal Fusion. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Nashville, TN, USA, 20–25 June 2021. [Google Scholar]
  10. Gu, X.; Fan, Z.; Zhu, S.; Dai, Z.; Tan, F.; Tan, P. Cascade Cost Volume for High-Resolution Multi-View Stereo and Stereo Matching. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 13–19 June 2020. [Google Scholar]
  11. Wang, K.; Shen, S. MVDepthNet: Real-Time Multiview Depth Estimation Neural Network. In Proceedings of the International Conference on 3D Vision (3DV), Verona, Italy, 5–8 September 2018. [Google Scholar]
  12. Huang, Z.; Liu, J.; Xu, S.; Chen, Y.; Liu, Y. FusionDepth: Complement Self-Supervised Monocular Depth Estimation with Cost Volume. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Vancouver, BC, Canada, 18–22 June 2023. [Google Scholar]
  13. Dai, A.; Chang, A.X.; Savva, M.; Halber, M.; Funkhouser, T.; Nießner, M. ScanNet: Richly-Annotated 3D Reconstructions of Indoor Scenes. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Honolulu, HI, USA, 21–26 July 2017. [Google Scholar]
  14. Sayed, M.; Aleotti, F.; Watson, J.; Qureshi, Z.; Garcia-Hernando, G.; Brostow, G.; Vicente, S.; Firman, M. DoubleTake: Geometry-Guided Depth Estimation. In Proceedings of the European Conference on Computer Vision (ECCV), Milan, Italy, 29 September–4 October 2024. [Google Scholar]
  15. Eigen, D.; Puhrsch, C.; Fergus, R. Depth Map Prediction from a Single Image Using a Multi-Scale Deep Network. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), Montreal, QC, Canada, 8–13 December 2014. [Google Scholar]
  16. Li, B.; Shen, C.; Dai, Y.; Van Den Hengel, A.; He, M. Depth and Surface Normal Estimation from Monocular Images Using Regression on Deep Features and Hierarchical CRFs. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Boston, MA, USA, 7–12 June 2015. [Google Scholar]
  17. Godard, C.; Mac Aodha, O.; Firman, M.; Brostow, G.J. Digging into Self-Supervised Monocular Depth Prediction. In Proceedings of the IEEE International Conference on Computer Vision (ICCV), Seoul, Republic of Korea, 27 October–2 November 2019. [Google Scholar]
  18. Zhou, T.; Brown, M.; Snavely, N.; Lowe, D.G. Unsupervised Learning of Depth and Ego-Motion from Video. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Honolulu, HI, USA, 21–26 July 2017. [Google Scholar]
  19. Lin, X.; Li, N. Self-Supervised Learning Monocular Depth Estimation from Internet Photos. J. Vis. Commun. Image Represent. 2024, 98, 104033. [Google Scholar] [CrossRef] [Scilit]
  20. Ranftl, R.; Lasinger, K.; Hafner, D.; Schindler, K.; Koltun, V. Towards Robust Monocular Depth Estimation: Mixing Datasets for Zero-Shot Cross-Dataset Transfer. IEEE Trans. Pattern Anal. Mach. Intell. 2022, 44, 1623–1637. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  21. Yang, L.; Kang, B.; Huang, Z.; Zhao, Z.; Xu, X.; Feng, J.; Zhao, H. Depth Anything v2. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), Vancouver, BC, Canada, 10–15 December 2024. [Google Scholar]
  22. Bhat, S.F.; Birkl, R.; Wofk, D.; Wonka, P.; Müller, M. ZoeDepth: Zero-Shot Transfer by Combining Relative and Metric Depth. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Vancouver, BC, Canada, 18–22 June 2023. [Google Scholar]
  23. Piccinelli, L.; Yang, Y.-H.; Sakaridis, C.; Segu, M.; Li, S.; Van Gool, L.; Yu, F. UniDepth: Universal Monocular Metric Depth Estimation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 17–21 June 2024. [Google Scholar]
  24. Hu, M.; Yin, W.; Zhang, C.; Cai, Z.; Long, X.; Chen, H.; Wang, K.; Yu, G.; Shen, C.; Shen, S. Metric3D v2: A Versatile Monocular Geometric Foundation Model for Zero-Shot Metric Depth and Surface Normal Estimation. IEEE Trans. Pattern Anal. Mach. Intell. 2024, 46, 10579–10596. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  25. Liu, F.; Shao, X.; Zhang, C.; Wang, L.; Liu, L.; Ren, J. EFDepth: A Monocular Depth Estimation Model for Multi-Scale Feature Optimization. Sensors 2025, 25, 7379. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  26. Ma, F.; Karaman, S. Sparse-to-Dense: Depth Prediction from Sparse Depth Samples and a Single Image. In Proceedings of the IEEE International Conference on Robotics and Automation (ICRA), Brisbane, Australia, 21–25 May 2018. [Google Scholar]
  27. Li, R.; Gong, D.; Yin, W.; Chen, H.; Zhu, Y.; Wang, K.; Chen, X.; Sun, J.; Zhang, Y. Learning to Fuse Monocular and Multi-View Cues for Multi-Frame Depth Estimation in Dynamic Scenes. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Vancouver, BC, Canada, 18–22 June 2023. [Google Scholar]
  28. Zhou, J.; Hu, Y.; Rao, Y.; Fan, H. Joint Dual-Branch Denoising for Underwater Stereo Depth Estimation. Sensors 2025, 25, 7094. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  29. Im, S.; Jeon, H.-G.; Lin, S.; Kweon, I.S. DPSNet: End-to-End Deep Plane Sweep Stereo. In Proceedings of the International Conference on Learning Representations (ICLR), New Orleans, LA, USA, 6–9 May 2019. [Google Scholar]
  30. Izquierdo, S.; Sayed, M.; Firman, M.; Garcia-Hernando, G.; Turmukhambetov, D.; Civera, J.; Mac Aodha, O.; Brostow, G.J.; Watson, J. MVSAnywhere: Zero-Shot Multi-View Stereo. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Nashville, TN, USA, 11–15 June 2025. [Google Scholar]
  31. Wang, S.; Leroy, V.; Cabon, Y.; Chidlovskii, B.; Revaud, J. Dust3R: Geometric 3D Vision Made Easy. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 17–21 June 2024. [Google Scholar]
  32. Leroy, V.; Cabon, Y.; Revaud, J. Grounding Image Matching in 3D with MASt3R. In Proceedings of the European Conference on Computer Vision (ECCV), Milan, Italy, 29 September–4 October 2024. [Google Scholar]
  33. Wang, J.; Chen, M.; Karaev, N.; Vedaldi, A.; Rupprecht, C.; Novotny, D. VGGT: Visual Geometry Grounded Transformer. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Nashville, TN, USA, 11–15 June 2025. [Google Scholar]
  34. He, K.; Zhang, X.; Ren, S.; Sun, J. Deep Residual Learning for Image Recognition. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Las Vegas, NV, USA, 27–30 June 2016. [Google Scholar]
  35. Yin, W.; Liu, Y.; Shen, C.; Yan, Y. Enforcing Geometric Constraints of Virtual Normal for Depth Prediction. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Long Beach, CA, USA, 16–20 June 2019. [Google Scholar]
  36. Shotton, J.; Glocker, B.; Zach, C.; Izadi, S.; Criminisi, A.; Fitzgibbon, A. Scene Coordinate Regression Forests for Camera Relocalization in RGB-D Images. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Portland, OR, USA, 23–28 June 2013. [Google Scholar]
  37. Sturm, J.; Engelhard, N.; Endres, F.; Burgard, W.; Cremers, D. A Benchmark for the Evaluation of RGB-D SLAM Systems. In Proceedings of the IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), Vilamoura, Portugal, 7–12 October 2012. [Google Scholar]
  38. Georgakis, G.; Reza, M.A.; Mousavian, A.; Le, P.-H.; Košecká, J. Multiview RGB-D Dataset for Object Instance Detection. In Proceedings of the International Conference on 3D Vision (3DV), Stanford, CA, USA, 25–28 October 2016. [Google Scholar]
  39. Sinha, A.; Murez, Z.; Bartolozzi, J.; Badrinarayanan, V.; Rabinovich, A. DELTAS: Depth Estimation by Learning Triangulation and Densification of Sparse Points. In Proceedings of the European Conference on Computer Vision (ECCV), Glasgow, UK, 23–28 August 2020. [Google Scholar]
  40. Hou, Y.; Kannala, J.; Solin, A. Multi-View Stereo by Temporal Nonparametric Fusion. In Proceedings of the IEEE International Conference on Computer Vision (ICCV), Seoul, Republic of Korea, 27 October–2 November 2019. [Google Scholar]
  41. Božić, A.; Palafox, P.; Thies, J.; Dai, A.; Nießner, M. TransformerFusion: Monocular RGB Scene Reconstruction Using Transformers. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), Virtual, 6–14 December 2021. [Google Scholar]
  42. Tan, M.; Le, Q. EfficientNetV2: Smaller Models and Faster Training. In Proceedings of the International Conference on Machine Learning (ICML), Virtual, 18–24 July 2021. [Google Scholar]
  43. Zhou, Z.; Rahman Siddiquee, M.M.; Tajbakhsh, N.; Liang, J. UNet++: A Nested U-Net Architecture for Medical Image Segmentation. In Proceedings of the International Conference on Medical Image Computing and Computer-Assisted Intervention (MICCAI), Granada, Spain, 16–20 September 2018. [Google Scholar]
Figure 1. Qualitative comparison on ScanNetV2 [13]. Compared to SimpleRecon [8] and DoubleTake [14], MPF preserves sharper geometry in repetitive patterns (e.g., window blinds) and clearer depth boundaries at object edges (e.g., monitor). Note how baselines suffer from oversmoothing in these low-texture regions.
Sensors 26 00712 g001
Figure 2. Overview of the proposed MPF framework. The Monocular Prior Module extracts pixel-wise cues—depth, confidence, and normal—from the input keyframe. These priors are fused with multi-frame matching features through a Fusion MLP, forming a hypothesis representation guided by priors that is further processed by the fusion volume and decoder to predict depth.
Sensors 26 00712 g002
Figure 3. Architecture of the multi-scale fusion volume used in MPF. Fusion volumes at three spatial resolutions propagate geometric cues from coarse to fine scales, combining them with encoder features to produce a depth representation with improved structural consistency.
Sensors 26 00712 g003
Figure 4. Qualitative depth comparisons on samples from ScanNetV2 and 7Scenes [13,36]. Cool colors (e.g., blue) indicate closer distances, while Warm colors (e.g., red) indicate further distances. MPF produces clearer geometric boundaries and more consistent depth than SR and DT, especially in low-texture regions.
Sensors 26 00712 g004
Figure 5. Qualitative depth comparisons on TUM and GMU datasets [37,38]. Cool colors (e.g., blue) indicate closer distances, while Warm colors (e.g., red) indicate further distances. MPF produces more stable and complete depth maps than SR and DT, recovering clearer scene geometry under challenging conditions such as motion blur (TUM) and strong lighting variation (GMU).
Sensors 26 00712 g005
Figure 6. Qualitative 3D reconstruction results on ScanNetV2 [13]. The highlighted regions (white arrows) show that MPF reconstructs smoother wall surfaces, preserves fine geometric details, and recovers large indoor structures more completely than SR.
Sensors 26 00712 g006
Table 1. Taxonomy and comparison of MPF with representative depth estimation paradigms. We explicitly distinguish our early-fusion mechanism, which modulates the hypothesis space at a pixel-wise level, from traditional late-fusion or pure photometric MVS methods.
Method CategoryRepresentative MethodsMechanism (Implementation Details)Key Properties
Integration Stage Fusion Granularity Matching Guidance Metric Scale Texture Sensitivity
Pure MonocularMetric3Dv2 [24], DepthAnything [21]Direct PredictionPixel-wiseLearned PriorRelativeLow
Feed-forward Recon.DUSt3R [31], VGGT [33]Implicit/LearnedFeature-levelGlobal ContextUnknown/Rel.Low
Traditional MVSSimpleRecon [8]NoneN/APhotometric OnlyMetricHigh
Prior-based MVSMVSAnywhere [30]Late/AuxiliaryImage-levelFeature RefinementMetricMedium
Ours (MPF)Proposed FrameworkEarly (Cost Vol.)Pixel-wisePrior-modulatedMetricLow
Table 2. Overview of the datasets used in our experiments. Each dataset exhibits distinct challenges that influence multi-frame depth estimation performance.
DatasetScenesCharacteristics
ScanNetV21513General indoor environments
7Scenes13Low texture, Repetitive patterns
TUM13Large-scale areas, Motion blur
GMU9Lighting variation, High resolution
Table 3. Depth evaluation on ScanNetV2 [13]. We compare against representative multi-frame MVS models and recent SOTA methods. Best and second-best results are shown in bold and underline. Arrows (↑/↓) indicate that higher/lower values are better.
MethodAbsDiff ↓AbsRel ↓SqRel ↓ a 10 a 25
DPN0.15500.07940.029973.5593.27
DELTAS0.14980.07870.027673.6593.77
GPMVS0.16190.08230.034673.0492.62
DVMS0.11810.05790.018983.8296.78
SR0.08690.04290.012790.8598.06
DT0.07660.03720.011593.1698.31
MPF0.07210.03800.008293.1798.89
Table 4. Zero-shot depth evaluation on 7Scenes [36] and TUM [37] using models trained only on ScanNetV2. Best and second-best results are shown in bold and underline. Arrows (↑/↓) indicate that higher/lower values are better.
7Scenes (Zero-Shot)TUM (Zero-Shot)
Method AbsDiff ↓ AbsRel ↓ SqRel ↓ a 10 a 25 AbsDiff ↓ AbsRel ↓ SqRel ↓ a 10 a 25
DPN0.17930.09850.040665.5189.950.79500.18320.345046.3267.71
DELTAS0.18470.10370.040662.1989.940.99640.22920.477836.8457.48
GPMVS0.17490.09420.042868.1991.000.78690.18660.332843.3266.96
DVMS0.12800.06840.021178.7395.790.86890.18820.401847.4666.66
SR0.10480.05750.015784.6097.300.93010.19810.435046.2463.41
DT0.09930.05360.016187.3896.770.96720.20370.489048.3663.34
MVSA0.12140.06610.027481.8595.060.56730.14610.364963.9783.14
MPF0.09150.05110.010887.9498.370.53760.14110.156746.6577.37
Table 5. Depth evaluation on GMU Kitchens [38]. Baseline methods (SR and DT) degrade significantly under strong lighting variations, whereas MPF maintains robustness. Unstable predictions from MVSA are excluded. Best and second-best results are shown in bold and underline. Arrows (↑/↓) indicate that higher/lower values are better.
MethodAbsDiff ↓AbsRel ↓SqRel ↓ a 10 a 25
DELTAS0.55850.58530.571314.4433.43
DVMS0.59660.59610.626213.7131.77
SR0.32610.33320.178221.4349.81
DT0.27350.25490.119527.9759.48
MPF0.09050.07110.015675.7395.47
Table 6. Ablation study on 7Scenes [36]. “F”, “M”, and “V” correspond to the fusion module, multi-scale fusion, and virtual-plane loss. Each component contributes to the progressive improvement in depth accuracy. Best results are shown in bold. Arrows (↑/↓) indicate that higher/lower values are better.
MethodAbsRel ↓SqRel ↓RMSE ↓ a 10 a 25
MPF-base (w/o F,M,V)0.06300.01810.173782.1596.69
MPF-base (w/F)0.06150.01440.156382.2397.86
MPF-base (w/F,M)0.05830.01310.150983.5498.08
MPF (w/F,M,V)0.05730.01290.149884.1798.20
Table 7. Cost-volume quality on 7Scenes before and after applying the Fusion Network. Lower values indicate sharper and more accurate matching distributions.
ResolutionStatusRP ↓DM ↓Q-MAE ↓
1/4Before0.3542.912.72
After0.0510.140.14
1/8Before0.1390.400.39
After0.1140.330.32
1/16Before0.3812.662.46
After0.0670.190.19
OverallBefore0.3132.412.25
After0.0640.180.18
Table 8. Mesh reconstruction evaluation on ScanNetV2 [13]. Best and second-best results are shown in bold and underline. Arrows (↑/↓) indicate that higher/lower values are better.
MethodAcc ↓Chamfer ↓Prec ↑Recall ↑
DELTAS11.959.710.4780.533
ESTDepth12.7110.120.4560.542
DVMS10.688.790.5410.592
NeuralRecon5.097.110.6300.612
SR5.535.810.6860.658
DT4.705.090.7300.701
MVSA4.935.660.6160.696
MPF4.234.900.7520.650
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.