


Abstract
The increasing connectivity of Internet of Things (IoT)-oriented environments has made them more vulnerable to cyberattacks, requiring intrusion-detection systems (IDSs) to ensure their secure and reliable operation. The feature selection (FS) process of an IDS affects its performance, as effective FS can enhance detection accuracy and reduce the computational cost and model complexity. This paper presents Adaptive Hybrid Genetic Algorithm-Simulated Annealing (AHGA-SA) as an FS framework that integrates the global search ability of a genetic algorithm and the local exploitation ability of simulated annealing. AHGA-SA aims to find compact, informative feature subsets in high-dimensional intrusion-detection datasets at an acceptable computational cost while maintaining detection performance. The experimental results on three recent benchmarks demonstrate feature-space reduction, with classification accuracies of 99.04% on IoTID20 (using 12 features), 98.25% on WUSTL-EHMS (using seven features), and 99.18% on Edge-IIoTset (using nine features). The results also demonstrate reduced training and testing times, central processing unit usage, resident set size overhead, and subset size compared to the baseline. Furthermore, Shapley additive explanations, as an explainable artificial intelligence technique, are applied to explain the model’s predictions and to show the contribution of the selected features to the IDS decision-making process.
1. Introduction
The Internet of Things (IoT) has increased connectivity between devices and systems in many areas, such as healthcare, manufacturing, agriculture, and smart cities [1]. In the medical field, the Internet of Medical Things (IoMT) connects medical devices and healthcare systems to enable patient monitoring and care delivery [2]. In industrial environments, this growth has led to the emergence of the Industrial Internet of Things (IIoT), which enables automation, monitoring, and machine-to-machine communication [3]. While these environments provide valuable operational advantages, their high connectivity and heterogeneity also make them vulnerable to cyberattacks. Attacks such as replay attacks, unauthorized access, and data tampering can affect confidentiality, integrity, and reliability. As a result, effective intrusion-detection systems (IDSs) are critical for ensuring secure and reliable operation in these environments [4,5].
An IDS is a system that identifies malicious activities or potential threats in a network and raises alerts to facilitate timely response. An IDS should be able to detect a variety of attacks with low false positive rate (FPR) and false negative rate (FNR). However, the efficient handling of high-dimensional and diverse intrusion-detection data remains a challenge in IoT-oriented systems [6]. A potential solution to enhance IDS efficiency is feature selection (FS), which selects the most informative features from a set of variables. FS can reduce data dimensionality, leading to better model performance, reduced computational cost, and improved interpretability [7]. Related concerns regarding effective feature representation and vulnerability-aware analysis have also been discussed in adjacent intelligent-system domains [8,9].
FS approaches are typically classified into four categories: filter, wrapper, embedded, and hybrid [10]. Filter methods assess feature relevance using statistical measures. While they are fast and straightforward, they may include redundant or noisy features and may fail to capture feature interactions. Wrapper methods assess feature subsets using learning algorithms and often achieve better detection performance, but they are generally more computationally intensive and prone to overfitting. Embedded methods conduct FS while training models, offering a balance between efficiency and performance, but they are model-dependent. Hybrid methods leverage the strengths of the above methods to perform more effective FS, but they may be harder to design and maintain in large-scale systems. Despite the strengths of these approaches, current FS methods still struggle to simultaneously achieve subset compactness, detection performance, efficiency, and interpretability in diverse IoT-oriented intrusion-detection environments [10,11,12]. Additionally, the balance between exploration and exploitation in high-dimensional search spaces is difficult to achieve in metaheuristic FS, which may increase the risk of convergence to local optima [12,13].
To address these challenges, we present an Adaptive Hybrid Genetic Algorithm-Simulated Annealing (AHGA-SA) method, an FS framework for IDSs in IoT-oriented settings. AHGA-SA integrates the global search ability of a genetic algorithm (GA) and the local exploitation ability of simulated annealing (SA) in a hybrid design that incorporates complementary processes for the discovery of effective feature subsets. In summary, AHGA-SA aims to discover compact and informative feature subsets, maintain or improve detection performance, and enable effective and computationally efficient IDS operation in resource-limited IoT-oriented environments. Finally, explainable artificial intelligence (XAI) is used in the form of Shapley additive explanations (SHAP) to aid in the interpretation of feature contributions and the IDS decision process.
The following are the main contributions of this study:
- We propose AHGA-SA, a novel adaptive hybrid FS framework for IDSs in IoT-oriented environments. The framework integrates GA-based exploration, SA-based exploitation, and Extreme Gradient Boosting (XGBoost)-based feature preselection within a structured two-stage search design for identifying compact and effective feature subsets.
- We evaluate the proposed framework on three recent benchmark datasets representing important IoT-oriented environments, including IoMT and IIoT IDS settings.
- We conduct a comprehensive evaluation using detection performance, computational efficiency, and subset compactness metrics.
- We employ SHAP as an XAI method to interpret the contribution of selected features to the IDS decision process.
The remainder of this paper is organized as follows: Section 2 provides the background and methodological context for this study. Related work is reviewed in Section 3. Section 4 presents the methodology. Section 5 reports the results. Section 6 presents the XAI-based interpretations. Section 7 discusses the findings. Finally, Section 8 concludes this paper and outlines future work.
2. Background
This section offers background and context to help understand the proposed framework by introducing the key concepts and methodologies relevant to this study.
2.1. FS
FS is a critical step in contemporary machine learning (ML), particularly for high-dimensional data. Such data may lead to redundancy, irrelevant information, and overfitting, which can reduce model performance due to the curse of dimensionality. FS helps overcome these challenges by selecting the most informative subset of features, which can lead to better model performance, lower computational cost, and increased interpretability [7,10].
FS techniques can be classified into supervised, unsupervised, and semi-supervised methods, depending on the availability of labels. Supervised FS is often used in classification problems because it uses labels to enhance classification performance. The FS process typically consists of four components: subset generation, subset evaluation, the stopping criterion, and the resulting selected feature set [12,14,15]. The general FS process for classification is illustrated in Figure 1.
Figure 1.
General FS workflow for classification.
In supervised classification, FS techniques are typically classified into four broad categories: filter, wrapper, embedded, and hybrid methods. Figure 2 illustrates these categories and some of their representative techniques. Hybrid approaches combine several FS techniques, such as a filtering step followed by subset refinement [12,13].
Figure 2.
Categorization of supervised FS methods and typical techniques.
Of these, wrapper-based methods are particularly relevant to optimization-focused FS, as they assess feature subsets based on classification performance, taking into account feature interactions. As illustrated in Figure 3, the wrapper approach iteratively generates and evaluates feature subsets using a classification algorithm to identify the best-performing subset. Wrapper-based methods can employ various search strategies to explore the search space, such as exponential, randomized, and sequential search [16,17]. These strategies can be summarized as follows:
Figure 3.
General Framework of wrapper-based FS.
- Exponential search: Searches subsets whose number grows exponentially with the number of features. Therefore, it is often not feasible for high-dimensional data due to its high computational complexity.
- Randomized search: Uses randomness to reduce the risk of converging to local optima and is often population-based, as in many metaheuristic algorithms (MAs).
- Sequential search: Adds or removes features one at a time, as in greedy search, which is fast but may converge to local optima.
2.2. MAs
MAs are commonly used to solve complex optimization problems and find optimal or near-optimal solutions. They are typically stochastic and may avoid local optima. MAs do not rely on gradient information and, instead, explore the search space heuristically. MAs can be classified in several ways. They are often divided into two broad categories: trajectory-based and population-based algorithms [18,19].
- Trajectory-based (single-solution) methods: They iteratively improve a single candidate solution, as seen in SA, tabu search, and hill climbing.
- Population-based methods: They work with a population of candidate solutions that are iteratively updated, as in GAs, ant colony optimization, and particle swarm optimization (PSO).
Besides this classification based on the search structure, MAs can also be classified according to their source of inspiration. These include evolution-based (such as GAs), physics-based (such as SA), and swarm-intelligence-based (such as PSO) algorithms. Other classes include chemistry-based, human-inspired, and miscellaneous algorithms [19,20]. Population-based methods are often preferred because their search for multiple solutions can improve exploration and help achieve exploration–exploitation balance [21]. In this study, GAs and SA are of particular interest because the proposed approach uses them as two complementary search components.
2.3. Hybrid MAs
Hybrid metaheuristics have attracted considerable attention in optimization research. They can be broadly grouped in three ways: hybridization level, execution model, and control strategy. In terms of the level of hybridization, hybrid approaches can be classified into high-level (weak coupling) and low-level (strong coupling) hybrids. In high-level hybrids, the integrated algorithms interact with each other through clearly defined interfaces but are otherwise independent. Low-level hybrids share internal components or operators in a more tightly integrated manner [22].
In terms of execution, hybrid metaheuristics can adopt batch, interleaved, or parallel approaches, where the hybridized algorithms are executed in a serial, alternate, or parallel fashion. Finally, depending on the control strategy, they may be classified as integrative (coercive), where one algorithm is embedded within another, or cooperative (collaborative), where the algorithms exchange information without direct embedding [23]. Hybridization becomes particularly useful when the strengths of one metaheuristic can compensate for the limitations of another.
2.4. GA
The GA was first introduced by Holland in 1975 as an evolutionary metaheuristic [24]. The key elements of a GA are solution representation (chromosomes), fitness function, selection, and genetic operators (crossover and mutation). The fitness function is used to assess the quality of individuals, and the fitter individuals are given a greater chance of reproduction, according to the principle of natural selection. This process repeats until the termination criteria are met [25]. The relationship between genes, chromosomes, and the population is shown in Figure 4.
Figure 4.
Genes, chromosomes, and population in a GA.
Common representation schemes in a GA include the following [26]:
- Binary GA: Represents genes as binary strings (zero or one).
- Real-coded GA: Uses real numbers within bounded ranges and is more appropriate for continuous optimization problems.
For discrete problems, the number of bits needed to encode n values is [25]. For FS problems, a binary GA is particularly suitable, as each gene can represent the presence or absence of a feature. The flowchart of a typical GA is shown in Figure 5, and the pseudocode is shown in Algorithm 1.
| Algorithm 1 Typical GA. |
|
Figure 5.
Flowchart of a typical GA.
2.4.1. Initial Population
Initialization of the population is an important phase in a GA, as the quality and diversity of the initial population affect the exploration ability and convergence properties of the algorithm. The key features of initialization methods are as follows [27]:
- Randomness: Indicates how initial solutions are generated, ranging from stochastic approaches to more deterministic or low-discrepancy strategies.
- Compositionality: Indicates the way the initial population is formed, which can be noncomposite or composite (e.g., hybrid or multistep).
- Generality: Refers to whether the initialization method is general or problem-specific.
These characteristics impact the diversity and quality of the initial population, which in turn affects the search process.
2.4.2. Selection
Selection is a core GA process in which individuals are selected for reproduction based on their fitness. Selection is biased toward better solutions, so fitter individuals are more likely to survive and reproduce, which enhances exploitation. At the same time, selection should maintain diversity by giving less-fit individuals a small chance to reproduce, which helps reduce the risk of premature convergence [28]. Common selection strategies include:
- Proportionate roulette wheel selection: Individuals are selected with a probability proportional to their fitness.
- Linear ranking selection: Individuals are selected based on their rank, rather than absolute fitness, which helps reduce the dominance of high-fitness individuals.
- Tournament selection: A random sample of individuals is selected, and the fittest individual is chosen.
Other selection methods, such as exponential ranking, stochastic universal sampling, and truncation, can also be applied depending on the application [29].
2.4.3. Crossover
Crossover creates new offspring by recombining genetic material from parents. This process promotes diversity and enables the search to explore new areas of the search space. It is governed by the crossover rate (). Higher values promote exploration, while lower values help maintain useful schemata and promote exploitation [30]. The following are some common crossover techniques:
- Single-point crossover: One split point is chosen, and the segments are swapped.
- Two-point crossover: Two split points are selected, and the middle chromosome segment is exchanged.
These are illustrated in Figure 6. Other crossover variants include multipoint, partially matched, uniform, and half-uniform [31].
Figure 6.
Single-point crossover and two-point crossover in the GA.
2.4.4. Mutation
Crossover only exchanges genetic material and does not directly modify gene values, which may result in a loss of diversity and increased risk of premature convergence. To address this problem, the mutation operator randomly alters genes according to the mutation rate (). In practice, for each gene, if a random number is less than , the gene is mutated (e.g., by flipping its bit value in binary GA or assigning a new random value in a real-coded GA) [32]. Figure 7 shows this effect. Other mutation variants include uniform, exchange, and boundary [33].
Figure 7.
Effect of mutation in the GA.
2.5. SA
SA was introduced in 1983 by Kirkpatrick et al. as a metaheuristic to solve complex optimization problems [34]. The technique is inspired by metallurgy, where a material is heated and then cooled to achieve a minimum energy state. In optimization, this translates to beginning with a high “temperature” to enable substantial random changes (exploration) and then cooling to reach a stable solution (exploitation). SA uses a probabilistic acceptance rule known as the Metropolis criterion [35], which allows the algorithm to occasionally accept a worse solution, which may help it escape local minima and keep exploring promising regions of the search space [36].
The cooling schedule and acceptance probability [] are the main features of SA. The acceptance probability is determined by the temperature T, and the cooling rate () determines how T is reduced over iterations. As such, the acceptance probability of a new solution, even if it is worse than the current solution, is given by Equation (1) [36].
The difference in cost between the new candidate solution and the current solution x is . The new candidate solution is obtained by applying a perturbation to the current solution, such that . As T is lowered, the search becomes more exploitative. The flow diagram of SA is given in Figure 8, and the pseudocode is given in Algorithm 2.
| Algorithm 2 Typical SA (minimization). |
|
Figure 8.
Flowchart of typical SA (minimization).
3. Related Work
This section surveys related work from two complementary perspectives. First, it reviews algorithm-based hybrid FS methods, focusing on GA- and SA-based hybrids that are methodologically related to the proposed framework. Second, it reviews dataset-based studies that have been evaluated on IoTID20, Washington University in St. Louis Enhanced Healthcare Monitoring System (WUSTL-EHMS), and Edge-IIoTset (ML).
3.1. Algorithm-Based Related Work
Recent studies have increasingly explored hybrid metaheuristics to address the high dimensionality and redundancy of network features in IDS-oriented FS tasks. Therefore, this subsection highlights representative GA- and SA-driven hybrid FS designs.
Hybrid GA-based FS has been increasingly used to explore large combinatorial feature spaces and enhance IDS performance. Vijayanand and Devaraj [37] combined GA operators with a complementary optimizer for wrapper-based IDS FS. Halim et al. [38] used improved GA-based approaches with customized fitness functions and multiple datasets. Kunhare et al. [39] applied GA to obtain reduced feature sets for traditional ML and hybrid classifier setups, such as logistic regression with a decision tree (DT), for IDS. More recently, Hosseini et al. [40] combined GA with the slime mold algorithm in a hybrid FS approach for IDS.
Likewise, recent hybrid SA-based approaches for IDS FS include Prakash et al. [41], who combined SA with improved salp swarm optimization for FS in IoT-based network IDS. Liu et al. [42] combined SA with adaptive differential evolution for IoT-IDS FS. Huang et al. [43] enhanced binary pigeon-inspired optimization with SA and a population decay factor for feature-subset search in network IDS. Lastly, Han et al. [44] integrated SA into binary PSO to enhance feature-subset search for reflective denial-of-service detection.
These studies show that GA- and SA-based hybrid FS approaches can improve the search process by combining broader exploration with local refinement, which may enhance detection performance and reduce feature redundancy. More importantly, the aforementioned studies did not directly investigate a unified GA–SA hybrid FS approach for recent IoT-oriented intrusion-detection scenarios. Moreover, the studies are not directly comparable because of the lack of consistent reporting of selected feature subsets, validation settings, and computational cost; some studies explicitly report runtime or complexity analysis, whereas others focus mainly on detection performance, and some hybrid enhancements may introduce additional computational overhead.
3.2. Dataset-Based Related Work
This subsection provides an overview of recent IDS studies that evaluated FS on the three datasets of interest. The aim is to offer a brief, dataset-based summary of the reported FS approaches, subset sizes, and binary-classification accuracy. Table 1 lists the studies considered for each dataset.
Table 1.
Dataset-based summary of IDS studies on IoTID20, WUSTL-EHMS, and Edge-IIoTset (ML).
For the IoTID20 dataset, the related studies reported different FS strategies with varying classification accuracies. Alkahtani and Aldhyani [45] used PSO to select 20 features and reported 98.20% accuracy with a long short-term memory (LSTM) model. Bhavsar et al. [46] applied Pearson’s correlation coefficient (PCC)-based FS to select 15 features and achieved 99.00% accuracy with a PCC-based convolutional neural network (PCC-CNN) model. Boubertakh et al. [47] used a binary butterfly optimization algorithm (BBOA) wrapper to select 40 features and reported 98.87% accuracy using LSTM. Lastly, Zayed et al. [48] used firefly algorithm (FA)-based FS in a hybrid deep-learning IDS model combining an FA, a convolutional neural network (CNN), and a recurrent neural network (RNN) to select 47 features and achieved 98.20% accuracy.
For WUSTL-EHMS, previous research has reported various FS techniques with varying performance for the selected feature subsets and classifiers. Chaganti et al. [49] used PSO-based FS and obtained eight optimal features, with 96.00% accuracy using a deep neural network (DNN) classifier. Alalhareth and Hong [50] reported results using logistic redundancy coefficient gradual upweighting and mutual information feature selection (LRGU-MIFS), where the highest accuracy was 96.70% with 25 features and fuzzy-based self-tuning LSTM (FST-LSTM). Lazrek et al. [51] used the recursive feature elimination with DT (RFE-DT), where features were removed until eight features were left; this configuration achieved 97.85% accuracy. Lastly, Pinar et al. [52] introduced a random subset FS with correlation feature selection (RSFS + CFS) approach, where 18 features were selected and 96.37% accuracy was achieved using a DNN classifier.
Research on Edge-IIoTset (ML) has also shown variation in FS design and performance. Thiyam and Dey [53] used the Synthetic Minority Oversampling Technique (SMOTE) and PCC filtering with a variance threshold to select 15 features and reported 98.43% accuracy with DT. Rajput et al. [54] used Fisher-score ranking to select 45 features and achieved 94.54% accuracy with a hyperparameter-tuned random forest (RF) model. Thiyam and Dey [55] applied receiver operating characteristic (ROC)-value feature importance with RF to select 15 features, reporting 99.16% accuracy in the study’s comparison with other works. Lastly, Keshavamurthy et al. [56] applied an ensemble FS approach with seven algorithms and demonstrated that XGBoost achieved 97.64% accuracy with 34 features.
The studies reviewed for these three datasets show substantial differences in how FS is defined and reported, from explicit subset selection (wrapper-style) to ranking-, filter-, and preprocessing-based FS. They also vary in the consistency of reporting subset sizes, runtime/resource indicators, and evaluation settings. While some studies report runtime or memory, such reporting is not consistent across the datasets and evaluation settings. Therefore, to facilitate better dataset-level benchmarking and reproducibility, the current experiments adopted a standardized evaluation protocol; we consistently report subset sizes, selected feature lists, experimental settings, and operational-cost measures.
4. Methodology
This section outlines the methodology adopted to design the proposed FS framework for intrusion detection across IoT-oriented datasets. The methodology workflow and the research framework are shown in Figure 9 and Figure 10, respectively.
Figure 9.
Comprehensive methodology workflow.
Figure 10.
Phase-based research framework.
4.1. Data Preprocessing and Benchmark Datasets
The datasets used in this study were preprocessed to enhance data consistency and facilitate the FS and intrusion-detection processes. The preprocessing steps were applied across the datasets and included:
- Infinite-value handling: Positive and negative infinite values were replaced with missing values.
- Data splitting: The data were first split into training and test sets using an 80%/20% split with shuffling and stratification. The training set was then further split into internal training and validation sets via an 80%/20% split with shuffling and stratification for the AHGA-SA search process.
- Feature removal: Potentially leakage-prone features were first examined through internal training/validation diagnostic behavior, with the diagnostic results later discussed in Section 7. The held-out test set was not used to decide feature removal. Before reporting the final test results, the final removal decision was also supported by feature semantics to exclude dataset-specific fields that could encode non-generalizable artifacts, including identifiers, addressing fields, temporal or ordering fields, payload- or content-bearing fields, and protocol-specific or derived flow/session fields. The complete removed-feature lists are reported in the corresponding dataset descriptions.
- Missing-value imputation: Missing numerical values were replaced with the median; the imputer was fitted on the training portion of each split and then applied to the corresponding validation or test portion.
- Categorical encoding: Categorical features were encoded numerically using a label encoder fitted on the training portion of each split and then applied to the corresponding validation or test portion.
- Standardization: Numerical features were standardized using StandardScaler, which was fitted on the training portion of each split and then applied to the corresponding validation or test portion.
4.1.1. IoTID20 Dataset
The IoTID20 dataset [57] was introduced in 2020 by Imtiaz Ullah and Mahmoud [58] to offer a comprehensive IoT botnet benchmark with network- and flow-based features for developing and evaluating flow-based intrusion detection in IoT networks. This dataset contains labeled normal and attack traffic and can be used to detect anomalies in IoT networks.
- Class distribution: 625,783 samples.
- –
- Label 0 (Normal): 40,073
- –
- Label 1 (Attack): 585,710
- Feature summary: 83 features + 3 label columns.
- –
- Total features (Initial): 83
- –
- Features after removal (Final): 65
- Removed features: 18 features.
- –
- “Timestamp,” “Active_Max,” “Bwd_IAT_Max,”“Src_Port,” “Dst_Port,” “Src_IP,” “Dst_IP,”“Subflow_Bwd_Byts,” “Subflow_Bwd_Pkts,”“Subflow_Fwd_Byts,” “Subflow_Fwd_Pkts,”“Bwd_Seg_Size_Avg,” “Fwd_IAT_Max,”“PSH_Flag_Cnt,” “Pkt_Size_Avg,”“Fwd_Seg_Size_Avg,” “Idle_Max,”“Flow_ID”
- Data splitting: 80% for training and 20% for testing.
- –
- Training set (500,626 samples):32,168 for Normal, 468,458 for Attack.
- –
- Test set (125,157 samples):7905 for Normal, 117,252 for Attack.
4.1.2. WUSTL-EHMS Dataset
In 2020, Hady et al. [59] created the WUSTL-EHMS dataset [60] to enhance intrusion detection in IoT-based healthcare systems. Generated using man-in-the-middle attacks, it includes network-flow features and patient biometric data. The dataset was cleaned and labeled with attack types and binary labels for ML applications.
- Class distribution: 16,318 samples.
- –
- Label 0 (Normal): 14,272
- –
- Label 1 (Attack): 2046
- Feature summary: 43 features + 2 label columns.
- –
- Total features (Initial): 43
- –
- Features after removal (Final): 36
- Removed features: 7 features.
- –
- “Dir,” “Flgs,” “SrcAddr,” “DstAddr,” “SrcMac,”“DstMac,” “Packet_num”
- Data splitting: 80% for training and 20% for testing.
- –
- Training set (13,054 samples):11,372 for Normal, 1682 for Attack.
- –
- Test set (3264 samples):2900 for Normal, 364 for Attack.
4.1.3. Edge-IIoTset (ML) Dataset
The Edge-IIoTset (ML) dataset [61], proposed by Ferrag et al. [62] in 2022, is a realistic cybersecurity benchmark for IoT and IIoT applications that can be used in both centralized and federated learning scenarios. It was created using a multilayer IoT/IIoT testbed with a variety of device types and contains labeled traffic with 14 attacks in five major threat categories, allowing for the development and evaluation of ML-based IDSs. The ML version was used in this study.
- Class distribution: 157,800 samples.
- –
- Label 0 (Normal): 24,301
- –
- Label 1 (Attack): 133,499
- Feature summary: 61 features + 2 label columns.
- –
- Total features (Initial): 61
- –
- Features after removal (Final): 42
- Removed features: 19 features.
- –
- “dns.qry.name.len,” “tcp.payload,” “tcp.srcport,”“mqtt.protoname,” “icmp.transmit_timestamp,”“http.request.full_uri,” “arp.dst.proto_ipv4,”“http.file_data,” “mqtt.topic,” “mqtt.msg,”“frame.time,” “ip.src_host,” “tcp.options,”“mqtt.conack.flags,” “arp.src.proto_ipv4,”“http.request.uri.query,” “ip.dst_host,”“udp.port,” “tcp.dstport”
- Data splitting: 80% for training and 20% for testing.
- –
- Training set (126,240 samples):19,471 for Normal, 106,769 for Attack.
- –
- Test set (31,560 samples):4830 for Normal, 26,730 for Attack.
Table 2 summarizes the initial, removed, and final feature counts for each dataset.
Table 2.
Summary of feature statistics for each dataset.
4.2. AHGA-SA
The proposed approach uses AHGA-SA for FS, which integrates the global search ability of GA and the local exploitation ability of SA. To prevent selection leakage, the data are first split into training and test sets, represented as (, ) and (, ), respectively. In the AHGA-SA search process, the training set is further split into an internal training subset (, ) and a validation subset (, ). The internal training subset is used to train candidate feature subsets, and the validation subset is used to evaluate them, while the test set is only used for final testing.
A GA begins with a binary population, with “1” and “0” representing selected and unselected features, respectively. A GA searches the solution space through repeated selection, crossover, and mutation but can still become trapped in local optima. To overcome this issue, SA is used after crossover and mutation to generate neighboring solutions. Better solutions are always accepted, while worse solutions are accepted with a certain probability based on the Metropolis criterion, enabling the search to escape local optima. The temperature is gradually reduced to shift the search from exploration to exploitation.
Prior to the hybrid optimization, XGBoost is first trained with only two estimators to obtain a quick initial importance ranking, and only features with importance scores greater than zero are retained to reduce the search space for the subsequent AHGA-SA search. After this preselection step, AHGA-SA is executed in two search stages: the first search stage explores the reduced feature space and keeps track of the feature counts associated with the retained best solutions, and the second search stage restricts the search to these selected feature counts. This makes the second search stage more targeted by focusing on subset sizes that are found to be promising in the first search stage. The best solution is replaced if a new candidate has a higher validation accuracy or the same validation accuracy but fewer features.
Adaptive tournament selection also controls the balance between exploration and exploitation based on the SA temperature: higher temperatures encourage diversity, while lower temperatures encourage fitter individuals and convergence. This adaptive approach allows the complementary roles of GA exploration and SA exploitation to navigate the search space and generate small, informative feature subsets. The following are the main steps and key design considerations of the AHGA-SA framework:
- Initial setup:
- –
- Input variables: The framework uses an internal training subset and a validation subset derived from the training data. The held-out test set is exclusively reserved for final evaluation.
- –
- Parameters: These include population size (N), fixed two-stage AHGA-SA search design , crossover rate (), mutation rate (), tournament size (S), initial temperature (T), and cooling rate (). Together, they regulate the genetic and annealing operations and help strike a balance between exploration and exploitation.
- Core functional steps:
- –
- XGBoost feature preselection: As a lightweight preselection step to obtain a rapid initial feature ranking, XGBoost is trained on the internal training subset using two estimators. Features with importance scores greater than zero are retained, thereby reducing the search space.
- –
- Population initialization: The population is initialized by generating random binary vectors, where 1 and 0 denote selected and unselected features, respectively, from the subset preselected by XGBoost.
- –
- Duplicate-removal strategy: To maximize diversity and reduce redundant computation, duplicates are checked and removed after population initialization and after hybridization.
- –
- Fitness evaluation: In each search stage, the fitness of each individual is evaluated on the internal training and validation subsets at three evaluation points—after duplicate removal, after offspring generation, and after SA execution—to capture any improvement achieved at each stage.
- –
- Adaptive tournament selection: To support adaptive exploration and exploitation, tournament selection pressure is adjusted according to the current SA temperature.
- –
- Hybrid SA: SA generates neighboring solutions through further refinement; new solutions are accepted if they improve fitness or, if they are worse, probabilistically based on the temperature-dependent acceptance criterion.
- –
- Temperature cooling: Gradual temperature reduction shifts the search from broader exploration toward exploitation and convergence.
- Best-solution update and stage-based refinement:
- –
- Best-solution update: The first evaluated solution is stored as the initial entry in the best-solution list. Thereafter, the list is updated whenever a new candidate achieves a higher validation accuracy or the same validation accuracy but fewer features. Each retained entry stores the corresponding feature subset and validation accuracy.
- –
- First search stage: Broadly explores the preselected feature space to identify promising subsets.
- –
- Second search stage: Refines the search by exploring subsets with the same feature counts as the retained best solutions from the first search stage.
- Termination and output:
- –
- Termination: The search process stops after completing the predefined AHGA-SA search stages.
- –
- Output: The best feature subset obtained during the search process is returned as the final solution.
Algorithm 3 presents the pseudocode of the proposed AHGA-SA, summarizing its main steps.
| Algorithm 3 AHGA-SA algorithm for feature selection. |
|
4.3. Detection Model
We employed an XGBoost classifier in the detection models. XGBoost is a scalable gradient boosting algorithm introduced by Chen and Guestrin in 2016, with competitive predictive performance, computational efficiency, and a regularized learning objective to reduce overfitting [63]. Based on these characteristics, it was selected for the classification tasks.
4.4. Model Evaluation
The classifiers were evaluated based on their ability to distinguish attack traffic from normal traffic using a comprehensive set of metrics. Additionally, operational metrics were considered to assess computational efficiency and resource usage [64,65,66].
- Confusion matrix (CM): The CM is a table that compares the actual and predicted classes and summarizes classification outcomes. As shown in Figure 11, the matrix layout depends on the definition of the positive class; “Attack” was defined as the positive class. The CM consists of four components:
- –
- True positives (TP): Attack instances correctly classified as attacks.
- –
- True negatives (TN): Normal instances correctly classified as normal.
- –
- False positives (FP): Normal instances incorrectly classified as attacks.
- –
- False negatives (FN): Attack instances incorrectly classified as normal.
- Performance metrics:
- –
- Accuracy (Acc): The proportion of correctly classified samples among all samples.
- –
- Matthews correlation coefficient (MCC): A correlation-based measure computed from TP, TN, FP, and FN. It ranges from to and is particularly suitable for imbalanced datasets.
- –
- Precision or positive predictive value (PPV): The proportion of predicted attacks that are truly attacks.
- –
- Recall or sensitivity or true positive rate (TPR): The proportion of actual attacks that are correctly detected.
- –
- Specificity or true negative rate (TNR): The proportion of normal traffic that is correctly identified.
- –
- F1 score: The harmonic mean of precision and recall.
- –
- FPR or Type I error: The proportion of normal traffic incorrectly classified as attacks.
- –
- FNR or Type II error: The proportion of attacks incorrectly classified as normal. This metric is particularly important, as it indicates missed attacks.
These metrics, computed using the formulas in Table 3, provide an overall assessment of model performance [67]. - Threshold-independent evaluation:
- –
- Area under the ROC curve (AUC-ROC): This metric measures the model’s ability to distinguish between the positive class, “Attack,” and the negative class, “Normal,” across all possible threshold values. Unlike CM-based metrics at a fixed threshold, AUC-ROC was computed from prediction probabilities across different classification thresholds. Higher AUC-ROC values indicate better overall discriminative performance.
- –
- ROC curve: It is constructed from prediction probabilities by plotting the TPR against the FPR across different classification thresholds. It visually represents the trade-off between detection sensitivity and false alarm rate.
- Operational metrics:
- –
- FS process time: The total end-to-end time required to complete the FS process for the baseline FS method and AHGA-SA.
- –
- Number of features: The number of features selected and used for model training and testing.
- –
- Training time: The time required to fit the model on the training set.
- –
- Testing time: The time required for the model to generate predictions on the test set.
- –
- Central processing unit (CPU) usage: CPU utilization was separately recorded during model training and testing via Windows Performance Recorder, with the traces analyzed using Windows Performance Analyzer.
- –
- Resident set size (RSS) overhead: The increase in process memory consumption, measured as the difference between the peak process RSS recorded using the psutil library during each phase and the baseline RSS immediately before that phase.
For operational measurements, one warm-up run was performed and excluded from reporting, followed by five consecutive measured runs within the same measurement session under the same data split, selected feature subset, random states, and classifier configuration. Non-essential background applications were closed during measurement. The training/testing time, CPU-usage, and RSS-overhead values reported in the main result tables represent the mean of the five measured runs, while the corresponding standard deviations are provided in Appendix A.
Figure 11.
CM layouts in binary intrusion detection.
Table 3.
Common performance metrics and their formulas.
4.5. Experimental Setup
To ensure reproducibility, all experiments were performed in a controlled computational environment. The hardware and software specifications are listed in Table 4, while Table 5 presents the algorithm parameters and programming settings.
Table 4.
Hardware and software setup.
Table 5.
Algorithm parameters and programming settings.
Considering the dataset diversity and available computational resources, these configurations were selected to support effective FS and classification in a consistent experimental setting; the algorithm parameter choices are further discussed in Section 7. RF was used as the baseline FS method, as it provides feature-importance estimates, is robust to noise and overfitting, and can perform well in high-dimensional settings, thereby making it a practical baseline for comparison [68,69]. XGBoost was employed for feature preselection and for model training and testing. As shown in Table 5, the number of estimators was set on a dataset-specific basis, as the datasets differed in their characteristics and computational burden. Moreover, SHAP was used to support the interpretation of the resulting XGBoost model.
5. Results
The next subsections show the RF-based FS baseline results and corresponding model results, followed by the AHGA-SA FS results and final model results across the three datasets.
5.1. IoTID20 Experimental Results
The IoTID20 results are presented first.
5.1.1. Baseline RF-Based FS—IoTID20
For the IoTID20 dataset, the RF classifier was used to calculate feature-importance scores for the 65 features. A total of 55 features were retained after removing features with zero importance. The scores are shown in Table 6, and the top features are shown in Figure 12. The FS processing time was 34,702 milliseconds (ms).
Table 6.
Feature importance computed using RF—IoTID20.
Figure 12.
Top RF feature-importance scores—IoTID20.
5.1.2. Baseline Model Performance—IoTID20
The baseline model was evaluated with the XGBoost classifier using the 55 features selected in the previous step. The performance metrics are presented in Table 7, and the CM is illustrated in Figure 13.
Table 7.
Performance metrics for the baseline model—IoTID20.
Figure 13.
CM for the baseline model—IoTID20.
5.1.3. Proposed FS Method (AHGA-SA)—IoTID20
The XGBoost preselection process was a lightweight filtering stage that retained 31 of the 65 features with importance scores greater than zero in 137 ms, as listed in Table 8.
Table 8.
Feature importance from XGBoost preselection—IoTID20.
AHGA-SA then searched for effective feature combinations from that subset. With a population size of four, two search stages, and three evaluation points per search stage, the search produced 24 solutions, resulting in 23 unique solutions after one duplicate was removed by the framework’s duplicate-removal strategy. The retained best solutions are shown in Figure 14, with the solution ranks calculated among these 23 unique solutions. The orange bars show the validation accuracy of the displayed solutions, and the blue bars show the number of features. The solutions are shown in the order in which they were retained. Since the list of best solutions is initially empty, the first solution is retained as the initial best solution. Subsequently, a solution is retained only if it is better than the previously retained solution according to the framework criterion, which favors solutions with higher validation accuracy and, in the case of ties, with fewer features. For each solution shown, the figure also lists its solution number and rank out of the 23 unique solutions, its fitness time, cumulative time from the beginning of the AHGA-SA search, and the search stage in which it was found. Therefore, the last solution retained, No. 7, is the final best solution, which is found in the second search stage, where the search focuses on subsets with the same feature counts as the retained best solutions in the first search stage. The subsets of selected features are given in Table 9. Figure 15 and Figure 16 report the fitness time and cumulative time of the best solutions, respectively.
Figure 14.
Best AHGA-SA solutions for the IoTID20 dataset.
Table 9.
Selected feature subsets of the best solutions—IoTID20.
Figure 15.
Fitness time for the best solutions—IoTID20.
Figure 16.
Cumulative time for the best solutions—IoTID20.
5.1.4. Final Model Performance—IoTID20
The final model was evaluated with the XGBoost classifier on the 12-feature subset selected by AHGA-SA. The results are shown in Table 10. The CM is shown in Figure 17, and the ROC curve is shown in Figure 18.
Table 10.
Performance Metrics for the Final Model—IoTID20.
Figure 17.
CM for the final model—IoTID20.
Figure 18.
ROC curve of the final model—IoTID20.
5.2. WUSTL-EHMS Experimental Results
Next, the results for the WUSTL-EHMS dataset are shown.
5.2.1. Baseline RF-Based FS—WUSTL-EHMS
For the WUSTL-EHMS dataset, the RF classifier was used to calculate feature-importance scores for the 36 features. After removing features with zero importance, 30 features were retained in 1254 ms. The scores are shown in Figure 19.
Figure 19.
Top RF feature-importance scores—WUSTL-EHMS.
5.2.2. Baseline Model Performance—WUSTL-EHMS
The baseline model was evaluated with the XGBoost classifier using the 30-feature subset. Table 11 shows the performance metrics, and Figure 20 shows the CM.
Table 11.
Performance metrics for the baseline model—WUSTL-EHMS.
Figure 20.
CM for the baseline model—WUSTL-EHMS.
5.2.3. Proposed FS Method (AHGA-SA)—WUSTL-EHMS
The XGBoost preselection step retained 13 features out of the 36 features with importance scores greater than zero in 10 ms, as listed in Table 12. AHGA-SA was then applied to the preselected features, and the best solution selected seven features: “DIntPkt,” “Pulse_Rate,” “Resp_Rate,” “SYS,” “Heart_rate,” “Sport,” and “Temp.” The results for AHGA-SA are shown in Figure 21.
Table 12.
XGBoost preselection feature importance—WUSTL-EHMS.
Figure 21.
Best AHGA-SA solutions for the WUSTL-EHMS dataset.
5.2.4. Final Model Performance—WUSTL-EHMS
The final model was evaluated with the XGBoost classifier using the seven features selected by AHGA-SA. The performance metrics are shown in Table 13, and the CM is shown in Figure 22.
Table 13.
Performance metrics for the final model—WUSTL-EHMS.
Figure 22.
CM for the final model—WUSTL-EHMS.
5.3. Edge-IIoTset (ML) Experimental Results
Finally, we report the results for Edge-IIoTset (ML).
5.3.1. Baseline RF-Based FS—Edge-IIoTset (ML)
For the Edge-IIoTset (ML) dataset, we used the RF classifier to calculate the feature-importance scores for the 42 features. A total of 33 features were retained in 3091 ms after removing features with zero importance. The scores are shown in Figure 23.
Figure 23.
Top RF feature-importance scores—Edge-IIoTset (ML).
5.3.2. Baseline Model Performance—Edge-IIoTset (ML)
The baseline model was evaluated on the 33-feature set using the XGBoost classifier. The performance metrics are shown in Table 14, and the CM is shown in Figure 24.
Table 14.
Performance metrics for the baseline model—Edge-IIoTset (ML).
Figure 24.
CM for the baseline model—Edge-IIoTset (ML).
5.3.3. Proposed FS Method (AHGA-SA)—Edge-IIoTset (ML)
The XGBoost preselection step reduced the feature space from 42 to 11 in 29 ms, as listed in Table 15. AHGA-SA was then used to select the best features from that subset, and the best solution contained seven features: “tcp.checksum,” “http.request.version,” “udp.time_delta,” “tcp.seq,” “tcp.flags,” “tcp.ack,” and “tcp.ack_raw.” The AHGA-SA results are presented in Figure 25.
Table 15.
XGBoost preselection feature importance—Edge-IIoTset (ML).
Figure 25.
Best AHGA-SA solutions for the Edge-IIoTset (ML) dataset.
5.3.4. Final Model Performance—Edge-IIoTset (ML)
The final model was evaluated using the XGBoost classifier with the seven features selected by AHGA-SA. The performance metrics are shown in Table 16, while the CM is shown in Figure 26.
Table 16.
Performance metrics for the final model—Edge-IIoTset (ML).
Figure 26.
CM for the final model—Edge-IIoTset (ML).
6. XAI
SHAP is derived from the Shapley value, a game theory concept proposed by Lloyd Shapley in 1953 [70] and later adapted into a practical unified explanation framework by Lundberg and Lee [71]. It provides a contribution value for each feature, which can be used to explain how features contribute to model predictions and thus enhance the interpretability of black-box models [72,73].
SHAP was applied to explain how the final XGBoost model made predictions using the seven-feature subset identified by AHGA-SA; the WUSTL-EHMS dataset was chosen for this illustrative example. This dataset was selected because the small subset size enabled easier visualization, and the results showed the greatest improvement over the baseline among the three datasets. For clarity in the binary setting, the SHAP visualizations are shown for the positive class, “Attack.”
6.1. SHAP Beeswarm Plot
The SHAP beeswarm plot offers a compact global view of how the most important features affect the model output for the test set. In Figure 27, features are ranked by the mean absolute SHAP value; each dot corresponds to a test instance, and the dot’s color indicates the original feature value (blue is low, red is high). Positive SHAP values increase the prediction for the class shown, while negative values decrease it. We used Tree SHAP with XGBoost to explain all 3264 test instances of the WUSTL-EHMS dataset. The beeswarm plot for the “Attack” class is shown in Figure 27. The most important feature is “DIntPkt,” with higher values tending to push the prediction toward attack and lower values shifting it away.
Figure 27.
SHAP beeswarm plot—WUSTL-EHMS.
6.2. SHAP Violin Plot
The violin plot in Figure 28 complements the beeswarm plot, as it displays the density of the SHAP values for each feature across the test set. This can help identify the spread and concentration of feature contributions to the prediction of the “Attack” class.
Figure 28.
SHAP violin plot—WUSTL-EHMS.
6.3. SHAP Waterfall Plot
The SHAP waterfall plot shows how the selected features contribute to the prediction of a single instance. It begins with the expected value , which is the model’s output, before taking into account the feature values of the selected instance, and then it displays the way in which positive and negative SHAP contributions move the prediction toward the final model output . The number before each feature name is the actual value of the feature in the selected instance. As shown in Figure 29, the largest SHAP contributions were from the features “DIntPkt,” “Temp,” and “Sport,” which all contributed to moving the model output away from the “Attack” class, while “Pulse_Rate” contributed a smaller positive value. These contributions led to a model output of , which is a very low probability of attack.
Figure 29.
SHAP waterfall plot—WUSTL-EHMS.
6.4. SHAP Force Plot
The SHAP force plot also provides an explanation for the prediction of one instance by visualizing the influence of the selected features on the model output. It begins with the baseline, which is the model output without taking into account the feature values of the instance. The features then push the model output up or down for the class shown (red features push up, blue features push down). These effects add up to the model output . In Figure 30, the features “DIntPkt,” “Pulse_Rate,” “SYS,” and “Resp_Rate” pushed the prediction toward the “Attack” class, resulting in , which indicated weak support for the “Normal” class.
Figure 30.
SHAP force plot—WUSTL-EHMS.
6.5. SHAP Decision Plot
The SHAP decision plot illustrates how the model output varies from the expected value as the feature contributions are added from the bottom up. With the identity link option, the horizontal axis is the model output. In Figure 31, the fixed gray vertical line represents the base value, and movement to the right or left indicates increasing or decreasing support for the class shown. The colored path illustrates how the selected features contribute to shift the output toward the “Attack” class. The overall effect of these contributions led to an output of , which supports the “Attack” class for this instance.
Figure 31.
SHAP decision plot for single instance—WUSTL-EHMS.
Compared with Figure 31, which shows a single instance, Figure 32 shows the cumulative decision paths for 100 instances. Each colored path represents one observation and gives a more comprehensive picture of how cumulative feature contributions differ across multiple instances for the “Attack” class.
Figure 32.
SHAP decision plot for 100 instances—WUSTL-EHMS.
7. Discussion
This section discusses the main findings of the study by comparing the baseline and proposed methods across the three datasets. It also examines the effect of leakage-prone features, computational efficiency, parameter sensitivity and robustness, representative FS baselines, and comparisons with related studies.
On the IoTID20 dataset, AHGA-SA maintained the baseline’s high detection performance while substantially enhancing the model’s compactness and efficiency. As shown in Table 17, reducing the feature set from 55 to 12 corresponds to a 78.18% relative reduction, with slight improvements in accuracy, precision, specificity, and AUC-ROC. At the same time, MCC, recall, F1 score, and FNR were preserved while FPR was reduced, indicating a slight decrease in false alarms. In addition, the proposed approach enhanced computational efficiency, with a 67.52% reduction in training time, a 49.49% reduction in testing time, a 3.92% reduction in training CPU usage, a 3.30% reduction in testing CPU usage, a 69.22% reduction in training RSS overhead, and a 99.58% reduction in testing RSS overhead.
Table 17.
Comparison of baseline and proposed methods—IoTID20.
On the WUSTL-EHMS dataset, AHGA-SA improved the detection performance while substantially reducing the model complexity, as shown in Table 18. The number of features decreased by 76.67%. At the same time, accuracy, MCC, recall, F1 score, and AUC-ROC improved, but precision and specificity slightly decreased and FPR slightly increased. Notably, FNR decreased by 30.91%, which is important for reducing missed attacks. Computational efficiency also improved, with training time reduced by 49.30%, testing time by 51.26%, training CPU usage by 4.24%, testing CPU usage by 4.14%, training RSS overhead by 98.99%, and testing RSS overhead by 80.00%.
Table 18.
Comparison of baseline and proposed methods—WUSTL-EHMS.
For the Edge-IIoTset (ML) dataset, AHGA-SA substantially improved model compactness while maintaining high detection performance, as shown in Table 19. The number of features decreased by 72.73%. At the same time, accuracy, precision, recall, specificity, and F1 score slightly increased, while MCC remained the same. Moreover, both FPR and FNR were reduced, indicating small reductions in false alarms and missed attacks. While AUC-ROC slightly decreased, the proposed method improved computational efficiency, with a 61.53% reduction in training time, a 38.07% reduction in testing time, a 5.64% reduction in training CPU usage, a 3.12% reduction in testing CPU usage, an 83.15% reduction in training RSS overhead, and a 98.91% reduction in testing RSS overhead.
Table 19.
Comparison of baseline and proposed methods—Edge-IIoTset (ML).
To assess the effect of retaining leakage-prone fields, a diagnostic analysis was conducted before finalizing feature removal. As shown in Table 20, AHGA-SA selected extremely small subsets with perfect accuracy when such fields were retained, suggesting inflated FS behavior rather than reliable generalization. Figure 33 further illustrates this behavior for the representative IoTID20 case.
Table 20.
Diagnostic effect of retaining leakage-prone features across datasets.
Figure 33.
Diagnostic AHGA-SA solutions before feature removal—IoTID20.
In terms of computational cost, the population size is a key factor in population-based optimization algorithms, such as GAs. A larger population may increase search diversity and potentially improve the chance of finding high-quality feature subsets, but it also increases the number of evaluated candidate solutions and the overall FS runtime [74]. Since AHGA-SA uses a fixed two-stage search design, the effect of population size was further examined on the representative IoTID20 dataset while keeping the remaining settings unchanged. To isolate the effect of population size on the number of evaluated candidate solutions and runtime, this comparison was conducted without duplicate removal only for this sensitivity check. As shown in Table 21, increasing the population size from four to eight doubled the evaluated candidate solutions from 24 to 48 and increased the FS time from ∼3319 ms to ∼7104 ms. However, the classification accuracy did not improve, decreasing slightly from 99.04% to 99.03%, although the selected subset size was reduced from 12 to 10 features. Therefore, the adopted population size of four provides a more practical accuracy–compactness–cost trade-off for the lightweight AHGA-SA setting.
Table 21.
Population-size sensitivity analysis for AHGA-SA on IoTID20.
To further examine whether the compact AHGA-SA configuration produced stable outcomes under stochastic search behavior, a repeated-seed robustness check was conducted using the full adopted AHGA-SA setting on IoTID20, including the duplicate-removal strategy. In this check, the data split and all AHGA-SA parameters were kept fixed, while only the random seed controlling the stochastic search operations was changed across five runs. As shown in Table 22, AHGA-SA maintained highly consistent classification accuracy, compact feature subsets, and comparable FS runtime across different random seeds. The accuracy ranged from 98.99% to 99.04%, while the number of selected features ranged from 11 to 14. This indicates that the observed performance and compactness were not dependent on a single favorable random run.
Table 22.
Repeated-seed robustness check for AHGA-SA on IoTID20.
The XGBoost preselection depth was also examined on the same representative IoTID20 dataset because this step determines the initial reduced feature space passed to AHGA-SA. As shown in Table 23, increasing the number of XGBoost estimators from two to five and ten increased the number of retained preselected features from 31 to 39 and 41, respectively, and also increased the preselection time from 137 ms to 166 ms and 194 ms. Since the purpose of this step is to provide a lightweight initial feature ranking rather than a final classifier, two estimators were retained as a practical setting that reduces the search space and preselection cost before the AHGA-SA search.
Table 23.
XGBoost preselection-depth check on IoTID20.
A representative FS baseline comparison was conducted on IoTID20 to contextualize the proposed AHGA-SA framework against commonly used standalone FS alternatives. All methods were evaluated using the same data split, the same final XGBoost classifier, and the same hardware/software setup. The baseline FS methods were used independently, and each method selected features according to its own selection mechanism. RF importance used RandomForestClassifier with random_state=42 and retained features with importance scores greater than zero. MI used mutual_info_classif with random_state=42 and retained features with MI scores above the mean MI score. L1-based selection used L1-regularized logistic regression and retained features with non-zero coefficients. GA-based FS used the same GA-related parameters as AHGA-SA, namely , , , and tournament size , with an initial population followed by five generations, resulting in 24 evaluated candidate solutions. PSO-based FS used four particles, six iterations, inertia weight , cognitive coefficient , and social coefficient , resulting in 24 evaluated candidate solutions. SA-based FS used the same annealing-related parameters as AHGA-SA, namely, initial temperature and cooling rate , with one initial solution followed by 23 neighbor evaluations, resulting in 24 evaluated candidate solutions. This setup allowed the comparison to reflect the quality of the selected feature subsets in terms of detection accuracy, subset compactness, and FS cost. Table 24 summarizes the results.
Table 24.
Representative FS baseline comparison on IoTID20.
The results show that MI achieved the highest accuracy, with a marginal gain of 0.01% over AHGA-SA. However, this required 32 selected features and substantially higher FS time. In contrast, AHGA-SA achieved 99.04% accuracy using only 12 features and the lowest FS time among the compared methods. Compared with GA-based, PSO-based, and SA-based FS, AHGA-SA selected fewer features while maintaining higher detection accuracy and lower FS time. These results show that AHGA-SA provides a favorable accuracy–compactness–cost trade-off rather than only optimizing detection accuracy. It is worth noting that the additional representative analyses reported above were conducted on IoTID20 because it is the largest dataset in this study and represents the most computationally demanding setting.
In the adopted configuration, a tournament size of two was chosen to preserve search diversity and maintain sufficient selection pressure toward fitter individuals. Notably, a low crossover rate may reduce the creation of new candidate solutions and lead to premature convergence, while a high mutation rate may disrupt high-quality solutions and impede convergence. Therefore, a crossover rate of 70% and a mutation rate of 20% were chosen to maintain diversity and support convergence stability. For SA, the initial temperature was set to 95 and the cooling rate to 90% to support broader exploration in the early part of the annealing process, followed by greater exploitation as the temperature decreases.
To further examine the stability of the GA and SA parameter settings, a targeted representative fixed-seed parameter-robustness analysis was conducted on IoTID20, as reported in Appendix B. In that analysis, one GA/SA parameter was varied at a time, while the data split, XGBoost settings, hardware/software setup, and evaluation protocol were kept unchanged. FS time is reported as the mean and standard deviation over five consecutive measured runs. The selected subset size and accuracy showed no observed variation across the measured runs for each configuration.
Beyond parameter-setting robustness, the stochastic nature of the GA-based search process remains a relevant methodological consideration. In particular, population initialization introduces randomness that helps maintain search diversity, but it may also influence population coverage, convergence behavior, and the quality of the final selected feature subset [75]. This issue can be mitigated through more structured initialization strategies, such as low-discrepancy sequences, Latin Hypercube sampling, probability-distribution-based initialization, chaotic initialization, and hybrid initialization schemes, which have been investigated to improve search-space coverage, population diversity, and optimization performance [76,77].
To better contextualize the proposed framework, Table 25 compares AHGA-SA with other studies on the three datasets. AHGA-SA achieved the highest reported accuracy among the compared studies on the three datasets while using the smallest feature subsets. These results suggest the effectiveness of AHGA-SA in obtaining a competitive accuracy–compactness trade-off across datasets with different characteristics.
Table 25.
Comparison of the proposed method with related work across the three datasets.
8. Conclusions and Future Work
This paper presented AHGA-SA, an adaptive hybrid approach to FS for intrusion detection in IoT-oriented environments. The framework used GA-based exploration, SA-based exploitation, and XGBoost-based feature preselection, along with a duplicate-removal strategy, multi-point fitness evaluation, and a two-stage AHGA-SA search design, to discover compact, informative feature subsets while maintaining or enhancing detection performance at an acceptable computational cost.
AHGA-SA was tested on three recent benchmark datasets from key IoT-oriented environments, including IoT, IoMT, and IIoT. The findings showed that detection performance was maintained or improved while the number of selected features was reduced, with accuracies of 99.04% on IoTID20 (using 12 features), 98.25% on WUSTL-EHMS (using seven features), and 99.18% on Edge-IIoTset (ML) (using nine features). The results also showed lower training and testing times, CPU usage, and RSS overhead compared to the baseline. The selected feature subsets and the FS process were reported, and SHAP-based XAI was used to explain the contribution of the selected features to the IDS decision-making process.
One limitation is the stochastic nature of the GA-based search process, particularly population initialization, which may lead to variability in the selected feature subsets. Future research may investigate more controlled population-generation mechanisms to better balance population diversity and solution quality, reduce reliance on purely random initialization, and improve the consistency of AHGA-SA across multiple experiments. Another future direction is to apply AHGA-SA to additional datasets from different IoT-oriented domains to further evaluate its robustness and generalizability.
Author Contributions
Conceptualization, S.A.A. and I.A.; Methodology, S.A.A. and I.A.; Software, S.A.A.; Validation, S.A.A., I.A. and M.A.; Formal analysis, S.A.A. and I.A.; Investigation, S.A.A. and I.A.; Resources, S.A.A.; Writing—original draft, S.A.A. and I.A.; Writing—review & editing, S.A.A., I.A. and M.A.; Visualization, S.A.A.; Supervision, I.A. and M.A. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by KAU Endowment (WAQF) at King Abdulaziz University, Jeddah, Saudi Arabia. The authors gratefully acknowledge WAQF and the Deanship of Scientific Research (DSR) for their technical and financial support.
Data Availability Statement
The datasets used in this study are publicly available from their original sources: IoTID20 [57], WUSTL-EHMS [60], and Edge-IIoTset [61]. No new datasets were generated.
Conflicts of Interest
The authors declare no conflicts of interest.
Appendix A. Repeated Operational-Measurement Variability
Table A1.
Repeated operational-measurement variability across datasets.
Appendix B. Targeted Parameter-Robustness Analysis
Table A2.
Targeted AHGA-SA parameter-robustness analysis on IoTID20.
References
- Vermesan, O.; Friess, P.; Guillemin, P.; Sundmaeker, H.; Eisenhauer, M.; Moessner, K.; Le Gall, F.; Cousin, P. Internet of things strategic research and innovation agenda. In Internet of Things; River Publishers: Aalborg, Denmark, 2022; pp. 7–151. [Google Scholar] [CrossRef] [Scilit]
- Zachos, G.; Essop, I.; Mantas, G.; Porfyrakis, K.; Ribeiro, J.C.; Rodriguez, J. An anomaly-based intrusion detection system for internet of medical things networks. Electronics 2021, 10, 2562. [Google Scholar] [CrossRef] [Scilit]
- Soliman, S.; Oudah, W.; Aljuhani, A. Deep learning-based intrusion detection approach for securing industrial Internet of Things. Alex. Eng. J. 2023, 81, 371–383. [Google Scholar] [CrossRef] [Scilit]
- Kasongo, S.M. An advanced intrusion detection system for IIoT based on GA and tree based algorithms. IEEE Access 2021, 9, 113199–113212. [Google Scholar] [CrossRef] [Scilit]
- Bhushan, B.; Kumar, A.; Agarwal, A.K.; Kumar, A.; Bhattacharya, P.; Kumar, A. Towards a secure and sustainable internet of medical things (iomt): Requirements, design challenges, security techniques, and future trends. Sustainability 2023, 15, 6177. [Google Scholar] [CrossRef] [Scilit]
- Thamilarasu, G.; Odesile, A.; Hoang, A. An intrusion detection system for internet of medical things. IEEE Access 2020, 8, 181560–181576. [Google Scholar] [CrossRef] [Scilit]
- Miao, J.; Niu, L. A survey on feature selection. Procedia Comput. Sci. 2016, 91, 919–926. [Google Scholar] [CrossRef] [Scilit]
- Sheng, H.; Wang, X.; Zhang, C.; Wang, J.; Duan, P.; Wang, Y. AIGC Video Detection Based on the Fusion of Spatial-Frequency-Optical Flow Multimodal Features. J. Syst. Eng. Electron. 2026, 1–15. [Google Scholar] [CrossRef] [Scilit]
- Wang, P.; Wu, X.; He, X. Vibration-Theoretic Approach to Vulnerability Analysis of Nonlinear Vehicle Platoons. IEEE Trans. Intell. Transp. Syst. 2023, 24, 11334–11344. [Google Scholar] [CrossRef] [Scilit]
- Pudjihartono, N.; Fadason, T.; Kempa-Liehr, A.W.; O’Sullivan, J.M. A review of feature selection methods for machine learning-based disease risk prediction. Front. Bioinform. 2022, 2, 927312. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Thakkar, A.; Lohiya, R. A survey on intrusion detection system: Feature selection, model, performance measures, application perspective, challenges, and future research directions. Artif. Intell. Rev. 2022, 55, 453–563. [Google Scholar] [CrossRef] [Scilit]
- Akinola, O.O.; Ezugwu, A.E.; Agushaka, J.O.; Zitar, R.A.; Abualigah, L. Multiclass feature selection with metaheuristic optimization algorithms: A review. Neural Comput. Appl. 2022, 34, 19751–19790. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Ghosh, P.; Kiran, S.; Mahalakshmi, J.; Basha, S.A.H. Understanding Machine Learning; AG PUBLISHING HOUSE (AGPH Books): Bhopal, India, 2023. [Google Scholar]
- Li, J.; Cheng, K.; Wang, S.; Morstatter, F.; Trevino, R.P.; Tang, J.; Liu, H. Feature selection: A data perspective. ACM Comput. Surv. (CSUR) 2017, 50, 1–45. [Google Scholar] [CrossRef] [Scilit]
- Nguyen, B.H.; Xue, B.; Zhang, M. A survey on swarm intelligence approaches to feature selection in data mining. Swarm Evol. Comput. 2020, 54, 100663. [Google Scholar] [CrossRef] [Scilit]
- Gad, A.G.; Sallam, K.M.; Chakrabortty, R.K.; Ryan, M.J.; Abohany, A.A. An improved binary sparrow search algorithm for feature selection in data classification. Neural Comput. Appl. 2022, 34, 15705–15752. [Google Scholar] [CrossRef] [Scilit]
- Brezočnik, L.; Fister, I., Jr.; Podgorelec, V. Swarm intelligence algorithms for feature selection: A review. Appl. Sci. 2018, 8, 1521. [Google Scholar] [CrossRef] [Scilit]
- Rezk, H.; Olabi, A.G.; Wilberforce, T.; Sayed, E.T. Metaheuristic optimization algorithms for real-world electrical and civil engineering application: A review. Results Eng. 2024, 23, 102437. [Google Scholar] [CrossRef] [Scilit]
- Rajwar, K.; Deep, K.; Das, S. An exhaustive review of the metaheuristic algorithms for search and optimization: Taxonomy, applications, and open challenges. Artif. Intell. Rev. 2023, 56, 13187–13257. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Singh, P.; Kottath, R. A step-size follow-the-leader optimization algorithm with an improved step parameters. Decis. Anal. J. 2023, 9, 100360. [Google Scholar] [CrossRef] [Scilit]
- Jain, S.; Jain, A.; Jangid, M. Review of metaheuristic techniques for feature selection. In Soft Computing: Theories and Applications: Proceedings of SoCTA 2022; Springer: Berlin/Heidelberg, Germany, 2023; pp. 397–410. [Google Scholar] [CrossRef] [Scilit]
- Raidl, G.R. A unified view on hybrid metaheuristics. In Proceedings of the International Workshop on Hybrid Metaheuristics; Springer: Berlin/Heidelberg, Germany, 2006; pp. 1–12. [Google Scholar] [CrossRef] [Scilit]
- Alba, E. Parallel Metaheuristics: A New Class of Algorithms; John Wiley & Sons: Hoboken, NJ, USA, 2005. [Google Scholar] [CrossRef] [Scilit]
- Holland, J.H. Adaptation in Natural and Artificial Systems: An Introductory Analysis with Applications to Biology, Control, and Artificial Intelligence; First MIT Press Edition 1992; Originally Published 1975 by The University of Michigan; MIT Press: Cambridge, MA, USA, 1992. [Google Scholar]
- Curry, D.M.; Dagli, C.H. A computational intelligence approach to system-of-systems architecting incorporating multi-objective optimization. Procedia Comput. Sci. 2015, 44, 86–94. [Google Scholar] [CrossRef] [Scilit]
- Achiche, S.; Baron, L.; Balazinski, M. Real/binary-like coded versus binary coded genetic algorithms to automatically generate fuzzy knowledge bases: A comparative study. Eng. Appl. Artif. Intell. 2004, 17, 313–325. [Google Scholar] [CrossRef] [Scilit]
- Kazimipour, B.; Li, X.; Qin, A.K. A review of population initialization techniques for evolutionary algorithms. In Proceedings of the 2014 IEEE Congress on Evolutionary Computation (CEC); IEEE: New York, NY, USA, 2014; pp. 2585–2592. [Google Scholar] [CrossRef] [Scilit]
- Shukla, A.; Pandey, H.M.; Mehrotra, D. Comparative review of selection techniques in genetic algorithm. In Proceedings of the 2015 International Conference on Futuristic Trends on Computational Analysis and Knowledge Management (ABLAZE); IEEE: New York, NY, USA, 2015; pp. 515–519. [Google Scholar] [CrossRef] [Scilit]
- Jannoud, I.; Jaradat, Y.; Masoud, M.Z.; Manasrah, A.; Alia, M. The role of genetic algorithm selection operators in extending WSN stability period: A comparative study. Electronics 2021, 11, 28. [Google Scholar] [CrossRef] [Scilit]
- Hassanat, A.; Almohammadi, K.; Alkafaween, E.; Abunawas, E.; Hammouri, A.; Prasath, V.S. Choosing mutation and crossover ratios for genetic algorithms—A review with a new dynamic approach. Information 2019, 10, 390. [Google Scholar] [CrossRef] [Scilit]
- Aladdin, A.M.; Rashid, T.A. A new Lagrangian problem crossover—A systematic review and meta-analysis of crossover standards. Systems 2023, 11, 144. [Google Scholar] [CrossRef] [Scilit]
- Mirjalili, S.; Song Dong, J.; Sadiq, A.S.; Faris, H. Genetic algorithm: Theory, literature review, and application in image reconstruction. In Nature-Inspired Optimizers: Theories, Literature Reviews and Applications; Springer: Cham, Switzerland, 2020; pp. 69–85. [Google Scholar] [CrossRef] [Scilit]
- Katoch, S.; Chauhan, S.S.; Kumar, V. A review on genetic algorithm: Past, present, and future. Multimed. Tools Appl. 2021, 80, 8091–8126. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Kirkpatrick, S.; Gelatt, C.D., Jr.; Vecchi, M.P. Optimization by simulated annealing. Science 1983, 220, 671–680. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Metropolis, N.; Rosenbluth, A.W.; Rosenbluth, M.N.; Teller, A.H.; Teller, E. Equation of state calculations by fast computing machines. J. Chem. Phys. 1953, 21, 1087–1092. [Google Scholar] [CrossRef] [Scilit]
- Delahaye, D.; Chaimatanan, S.; Mongeau, M. Simulated annealing: From basics to applications. In Handbook of Metaheuristics; Springer: Cham, Switzerland, 2019; pp. 1–35. [Google Scholar] [CrossRef] [Scilit]
- Vijayanand, R.; Devaraj, D. A novel feature selection method using whale optimization algorithm and genetic operators for intrusion detection system in wireless mesh network. IEEE Access 2020, 8, 56847–56854. [Google Scholar] [CrossRef] [Scilit]
- Halim, Z.; Yousaf, M.N.; Waqas, M.; Sulaiman, M.; Abbas, G.; Hussain, M.; Ahmad, I.; Hanif, M. An effective genetic algorithm-based feature selection method for intrusion detection systems. Comput. Secur. 2021, 110, 102448. [Google Scholar] [CrossRef] [Scilit]
- Kunhare, N.; Tiwari, R.; Dhar, J. Intrusion detection system using hybrid classifiers with meta-heuristic algorithms for the optimization and feature selection by genetic algorithm. Comput. Electr. Eng. 2022, 103, 108383. [Google Scholar] [CrossRef] [Scilit]
- Hosseini, S.; Khorashadizade, M.; Jouyban, M. A hybrid method using slime mold algorithm and genetic algorithm for feature selection problems in intrusion detection systems. Eng. Rep. 2025, 7, e70254. [Google Scholar] [CrossRef] [Scilit]
- Prakash, P.J.; Lalitha, B. Optimized ensemble classifier based network intrusion detection system for RPL based internet of things. Wirel. Pers. Commun. 2022, 125, 3603–3626. [Google Scholar] [CrossRef] [Scilit]
- Liu, Q.; Zhang, X.; Hua, Q.; Wen, Z.; Li, H. Adaptive differential evolution algorithm with simulated annealing for security of IoT ecosystems. Wirel. Commun. Mob. Comput. 2022, 2022, 6951849. [Google Scholar] [CrossRef] [Scilit]
- Huang, W.; Tian, H.; Wang, S.; Zhang, C.; Zhang, X. Integration of simulated annealing into pigeon inspired optimizer algorithm for feature selection in network intrusion detection systems. PeerJ Comput. Sci. 2024, 10, e2176. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Han, D.; Li, H.; Fu, X. Reflective distributed denial of service detection: A novel model utilizing binary particle swarm Optimization—Simulated annealing for feature selection and Gray Wolf Optimization-Optimized LightGBM algorithm. Sensors 2024, 24, 6179. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Alkahtani, H.; Aldhyani, T.H. Intrusion detection system to advance Internet of Things infrastructure-based deep learning algorithms. Complexity 2021, 2021, 5579851. [Google Scholar] [CrossRef] [Scilit]
- Bhavsar, M.; Roy, K.; Kelly, J.; Olusola, O. Anomaly-based intrusion detection system for IoT application. Discov. Internet Things 2023, 3, 5. [Google Scholar] [CrossRef] [Scilit]
- Boubertakh, O.; Sahnoun, A.; Zitouni, A.; Harous, S. HyMD2I: Hybrid metaheuristic-deep learning approach for intrusion detection in IoT. J. Netw. Syst. Manag. 2025, 33, 74. [Google Scholar] [CrossRef] [Scilit]
- Zayed, S.M.; Alshathri, S.; El-Shafai, W. Firefly Algorithm Optimized Hybrid Deep Learning Framework for Intrusion Detection in IoT Environments. Int. J. Comput. Intell. Syst. 2026, 19, 158. [Google Scholar] [CrossRef] [Scilit]
- Chaganti, R.; Mourade, A.; Ravi, V.; Vemprala, N.; Dua, A.; Bhushan, B. A particle swarm optimization and deep learning approach for intrusion detection system in internet of medical things. Sustainability 2022, 14, 12828. [Google Scholar] [CrossRef] [Scilit]
- Alalhareth, M.; Hong, S.C. An Adaptive Intrusion Detection System in the Internet of Medical Things Using Fuzzy-Based Learning. Sensors 2023, 23, 9247. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Lazrek, G.; Chetioui, K.; Balboul, Y.; Mazer, S.; El bekkali, M. An RFE/Ridge-ML/DL based anomaly intrusion detection approach for securing IoMT system. Results Eng. 2024, 23, 102659. [Google Scholar] [CrossRef] [Scilit]
- Pinar, M.; Aktas, A.; Ulku, E.E. Feature efficiency in IoMT security: A comprehensive framework for threat detection with DNN and ML. Comput. Biol. Med. 2025, 186, 109603. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Thiyam, B.; Dey, S. Hyperparameter Tuning for Edge-IIoT Intrusion Detection Using SMOTE. In Proceedings of the International Conference on Communication and Intelligent Systems; Springer: Berlin/Heidelberg, Germany, 2022; pp. 407–419. [Google Scholar] [CrossRef] [Scilit]
- Rajput, D.; Sharma, D.K.; Gupta, M. Intrusion detection in IoT devices using ML and DL models with Fisher score feature selection. In Proceedings of the International Conference on Cryptology & Network Security with Machine Learning; Springer: Berlin/Heidelberg, Germany, 2023; pp. 115–134. [Google Scholar] [CrossRef] [Scilit]
- Thiyam, B.; Dey, S. Efficient feature evaluation approach for a class-imbalanced dataset using machine learning. Procedia Comput. Sci. 2023, 218, 2520–2532. [Google Scholar] [CrossRef] [Scilit]
- Keshavamurthy, P.; Smith, E.C.; Majeed, A.; Kulkarni, S. Performance Impact of Feature-Selection and Hyperparameter Tuning in IIoT Attack Detection. In Proceedings of the 2025 IEEE World AI IoT Congress (AIIoT); IEEE: New York, NY, USA, 2025; pp. 352–358. [Google Scholar] [CrossRef] [Scilit]
- Ullah, I.; Mahmoud, Q.H. IoT Network Intrusion Dataset (IoTID20). 2020. Available online: https://sites.google.com/view/iot-network-intrusion-dataset/home (accessed on 22 June 2026).
- Ullah, I.; Mahmoud, Q.H. A scheme for generating a dataset for anomalous activity detection in iot networks. In Proceedings of the Canadian Conference on Artificial Intelligence; Springer: Berlin/Heidelberg, Germany, 2020; pp. 508–520. [Google Scholar] [CrossRef] [Scilit]
- Hady, A.A.; Ghubaish, A.; Salman, T.; Unal, D.; Jain, R. Intrusion detection system for healthcare systems using medical and network data: A comparison study. IEEE Access 2020, 8, 106576–106584. [Google Scholar] [CrossRef] [Scilit]
- Hady, A.A.; Ghubaish, A.; Salman, T.; Unal, D.; Jain, R. WUSTL EHMS Dataset. 2020. Available online: https://www.cse.wustl.edu/~jain/ehms/index.html (accessed on 22 June 2026).
- Ferrag, M.A. Edge-IIoTset Cyber Security Dataset of IoT & IIoT. Kaggle. 2022. Available online: https://www.kaggle.com/datasets/mohamedamineferrag/edgeiiotset-cyber-security-dataset-of-iot-iiot (accessed on 22 June 2026).
- Ferrag, M.A.; Friha, O.; Hamouda, D.; Maglaras, L.; Janicke, H. Edge-IIoTset: A new comprehensive realistic cyber security dataset of IoT and IIoT applications for centralized and federated learning. IEEE Access 2022, 10, 40281–40306. [Google Scholar] [CrossRef] [Scilit]
- Chen, T.; Guestrin, C. Xgboost: A scalable tree boosting system. In Proceedings of the 22nd ACM Sigkdd International Conference on Knowledge Discovery and Data Mining; ACM: New York, NY, USA, 2016; pp. 785–794. [Google Scholar] [CrossRef] [Scilit]
- Cuadros-Rodríguez, L.; Pérez-Castaño, E.; Ruiz-Samblás, C. Quality performance metrics in multivariate classification methods for qualitative analysis. TrAC Trends Anal. Chem. 2016, 80, 612–624. [Google Scholar] [CrossRef] [Scilit]
- Cano, J.R.; Gutiérrez, P.A.; Krawczyk, B.; Woźniak, M.; García, S. Monotonic classification: An overview on algorithms, performance measures and data sets. Neurocomputing 2019, 341, 168–182. [Google Scholar] [CrossRef] [Scilit]
- Jiao, Y.; Du, P. Performance measures in evaluating machine learning based bioinformatics predictors for classifications. Quant. Biol. 2016, 4, 320–330. [Google Scholar] [CrossRef] [Scilit]
- Alzughaibi, S.; El Khediri, S. A cloud intrusion detection systems based on dnn using backpropagation and pso on the cse-cic-ids2018 dataset. Appl. Sci. 2023, 13, 2276. [Google Scholar] [CrossRef] [Scilit]
- Fawagreh, K.; Gaber, M.M.; Elyan, E. Random forests: From early developments to recent advancements. Syst. Sci. Control Eng. Open Access J. 2014, 2, 602–609. [Google Scholar] [CrossRef] [Scilit]
- Nguyen, T.T.; Huang, J.Z.; Nguyen, T.T. Unbiased feature selection in learning random forests for high-dimensional data. Sci. World J. 2015, 2015, 471371. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Shapley, L.S. A Value for n-Person Games. In Contributions to the Theory of Games; Kuhn, H.W., Tucker, A.W., Eds.; Annals of Mathematics Studies; Princeton University Press: Princeton, NJ, USA, 1953; Volume II, pp. 307–317. [Google Scholar]
- Lundberg, S.M.; Lee, S.I. A Unified Approach to Interpreting Model Predictions. In Proceedings of the Advances in Neural Information Processing Systems; Curran Associates, Inc.: Red Hook, NY, USA, 2017; Volume 30. [Google Scholar]
- Wang, M.; Zheng, K.; Yang, Y.; Wang, X. An explainable machine learning framework for intrusion detection systems. IEEE Access 2020, 8, 73127–73141. [Google Scholar] [CrossRef] [Scilit]
- Gaspar, D.; Silva, P.; Silva, C. Explainable AI for Intrusion Detection Systems: LIME and SHAP Applicability on Multi-Layer Perceptron. IEEE Access 2024, 12, 30164–30175. [Google Scholar] [CrossRef] [Scilit]
- Elhoseny, M.; Tharwat, A.; Hassanien, A.E. Bezier curve based path planning in a dynamic field using modified genetic algorithm. J. Comput. Sci. 2018, 25, 339–350. [Google Scholar] [CrossRef] [Scilit]
- Li, Q.; Liu, S.Y.; Yang, X.S. Influence of initialization on the performance of metaheuristic optimizers. Appl. Soft Comput. 2020, 91, 106193. [Google Scholar] [CrossRef] [Scilit]
- Tharwat, A.; Schenck, W. Population initialization techniques for evolutionary algorithms for single-objective constrained optimization problems: Deterministic vs. stochastic techniques. Swarm Evol. Comput. 2021, 67, 100952. [Google Scholar] [CrossRef] [Scilit]
- Agushaka, J.O.; Ezugwu, A.E. Initialisation Approaches for Population-Based Metaheuristic Algorithms: A Comprehensive Review. Appl. Sci. 2022, 12, 896. [Google Scholar] [CrossRef] [Scilit]
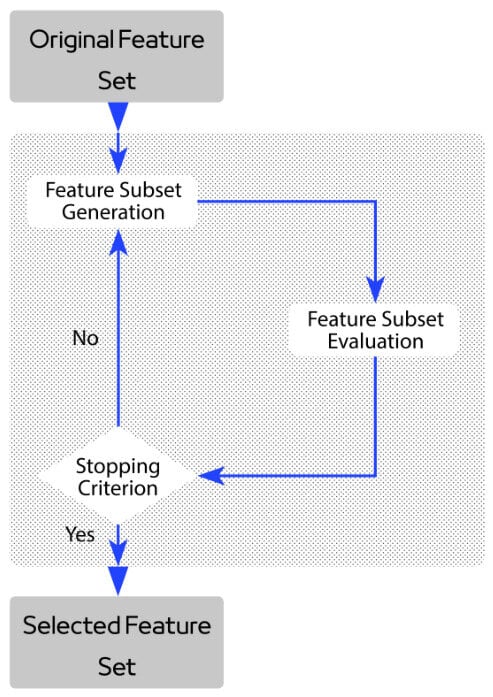
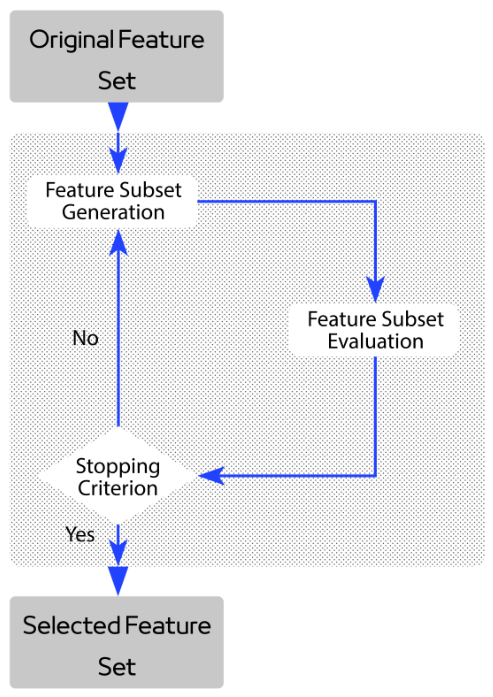
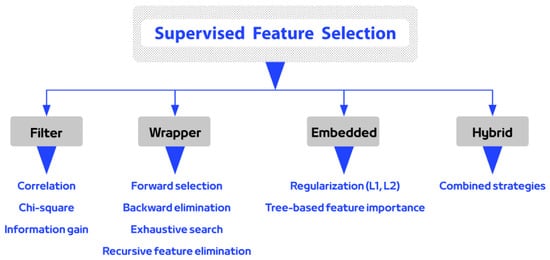
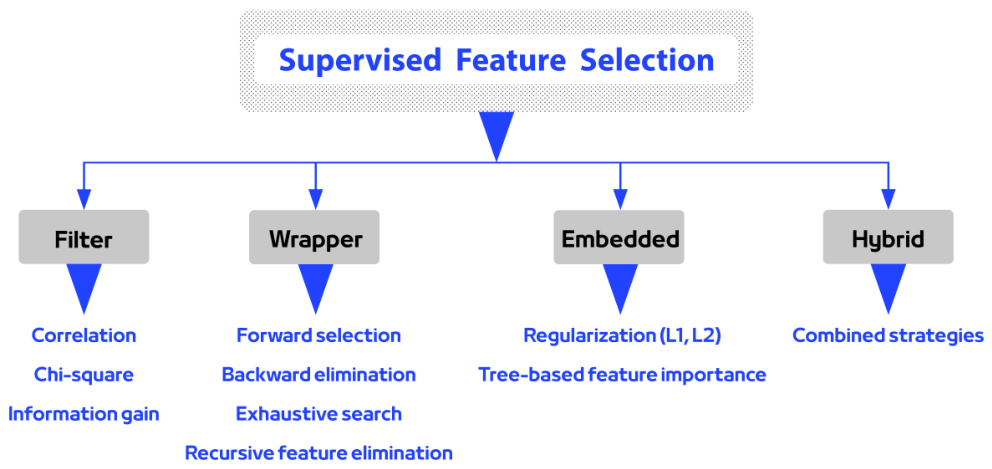
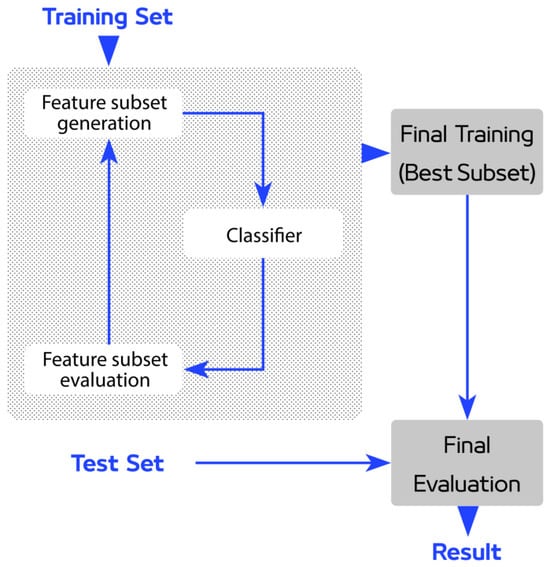
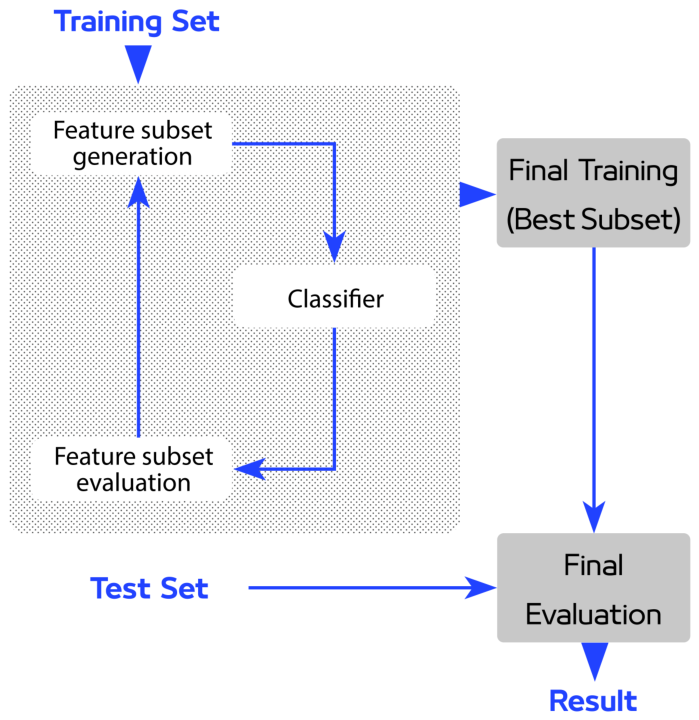
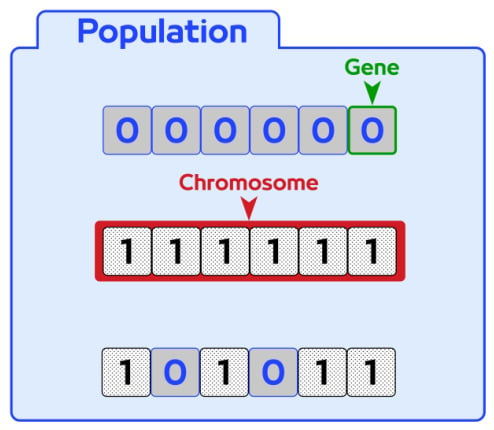
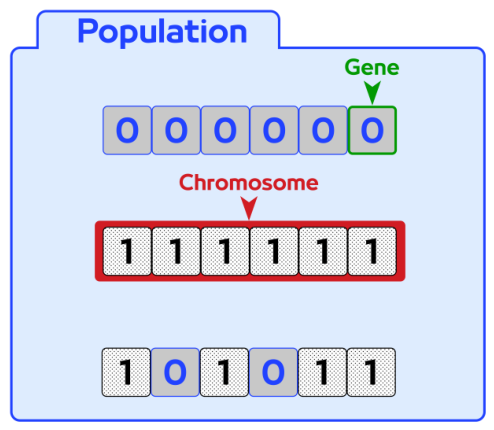
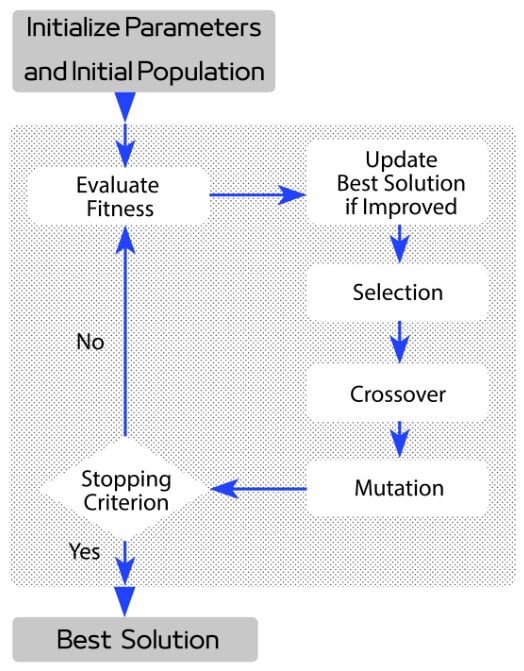
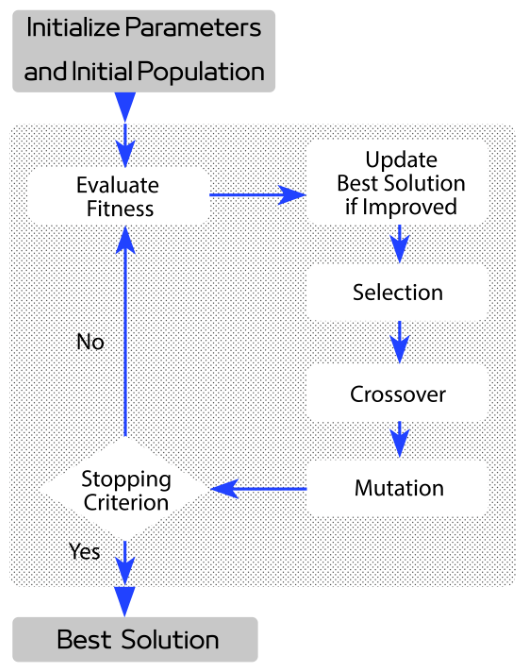
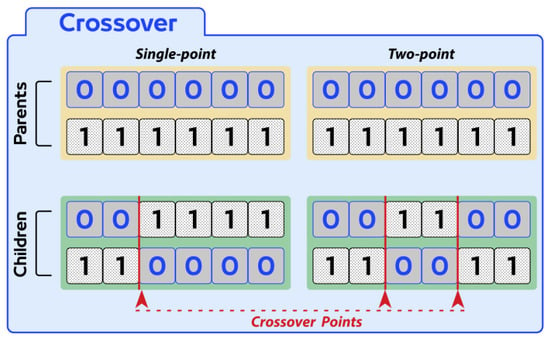
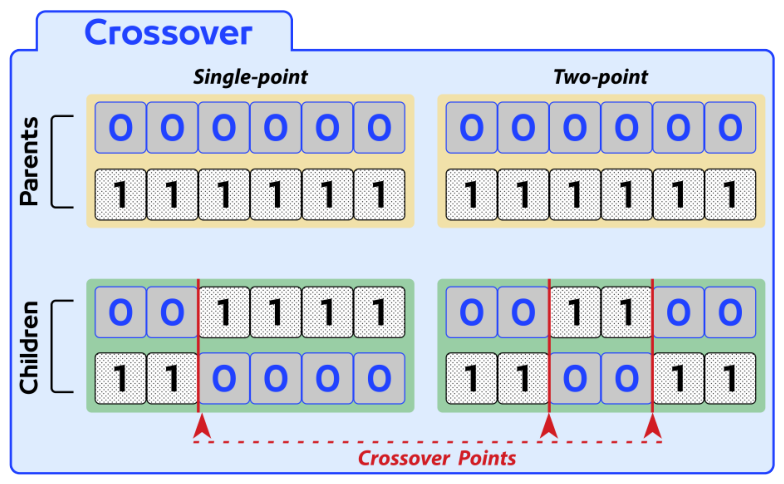
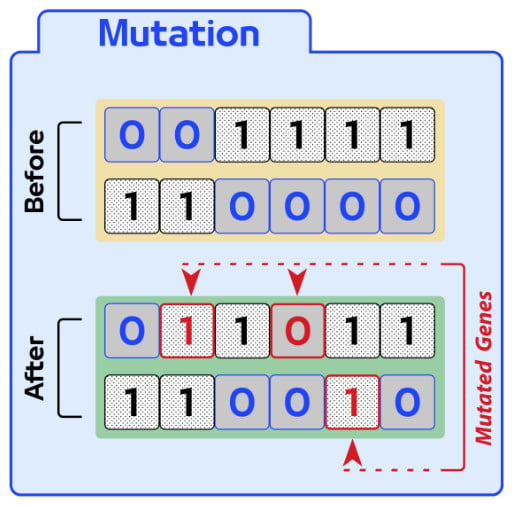
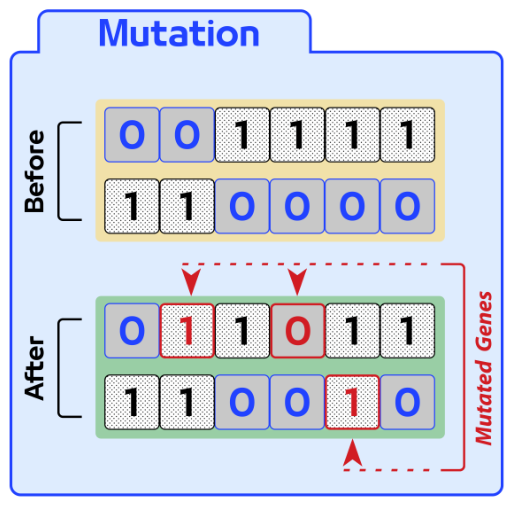
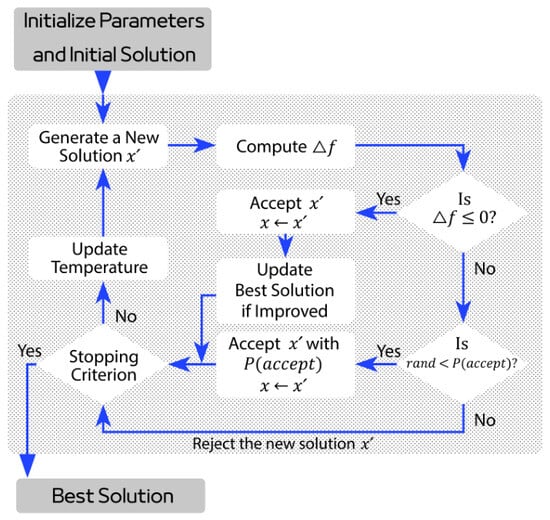
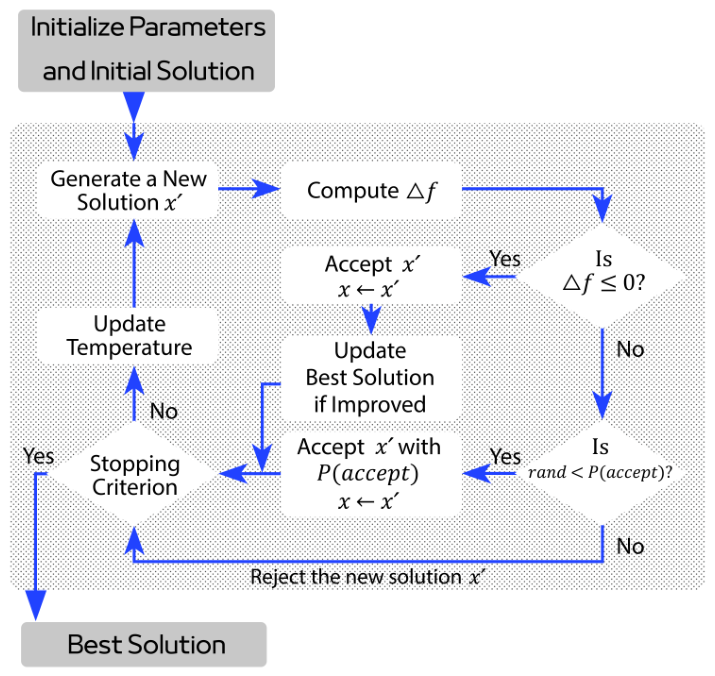
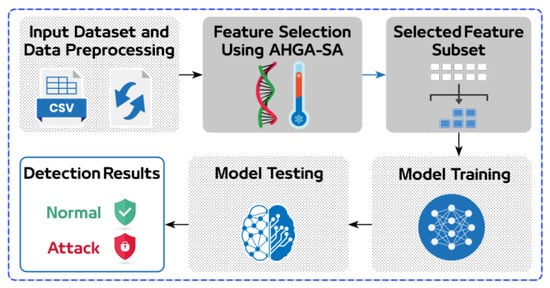
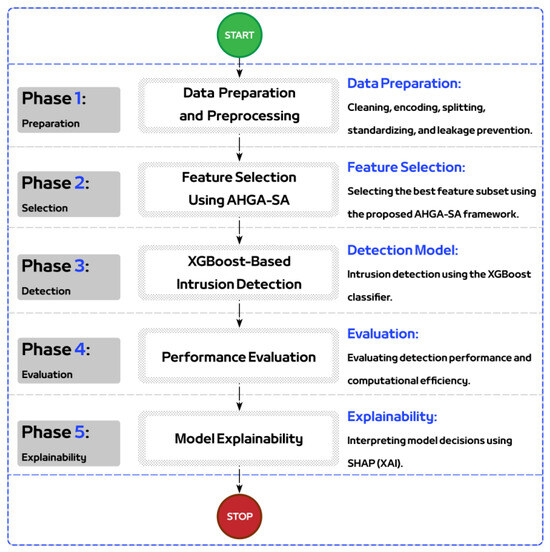
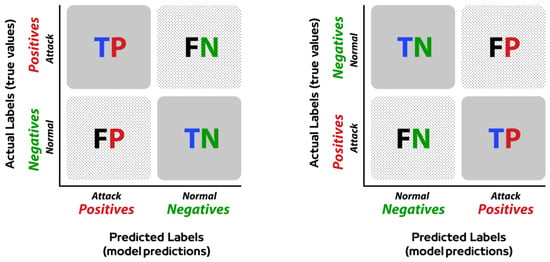
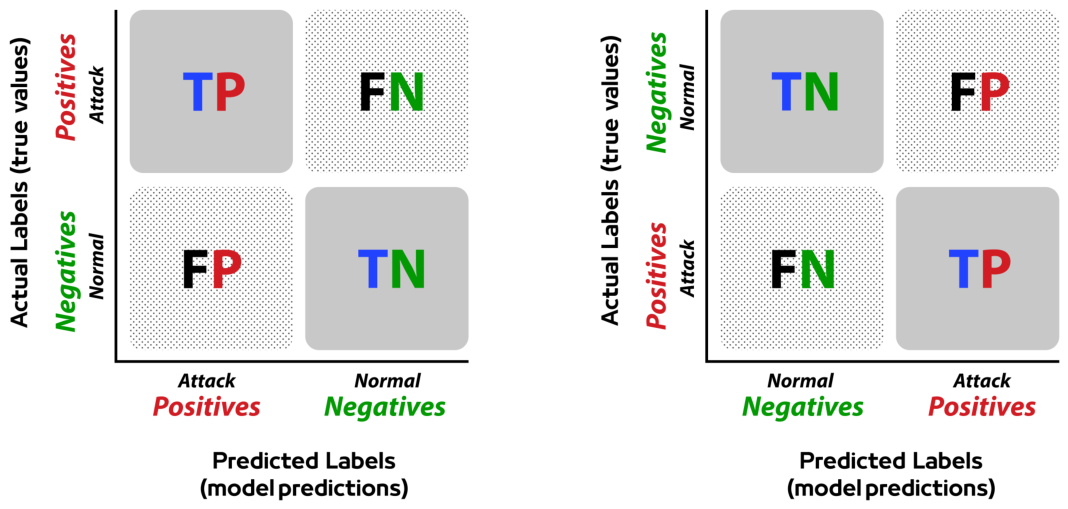
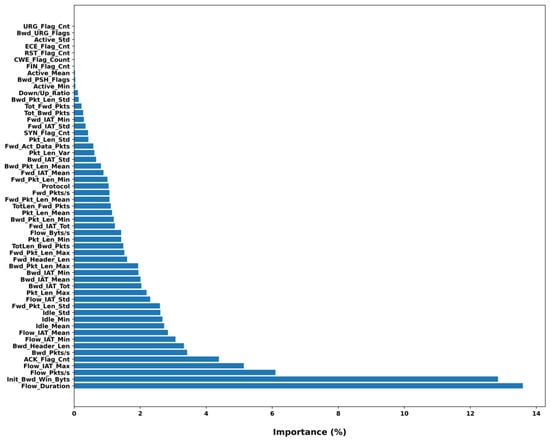
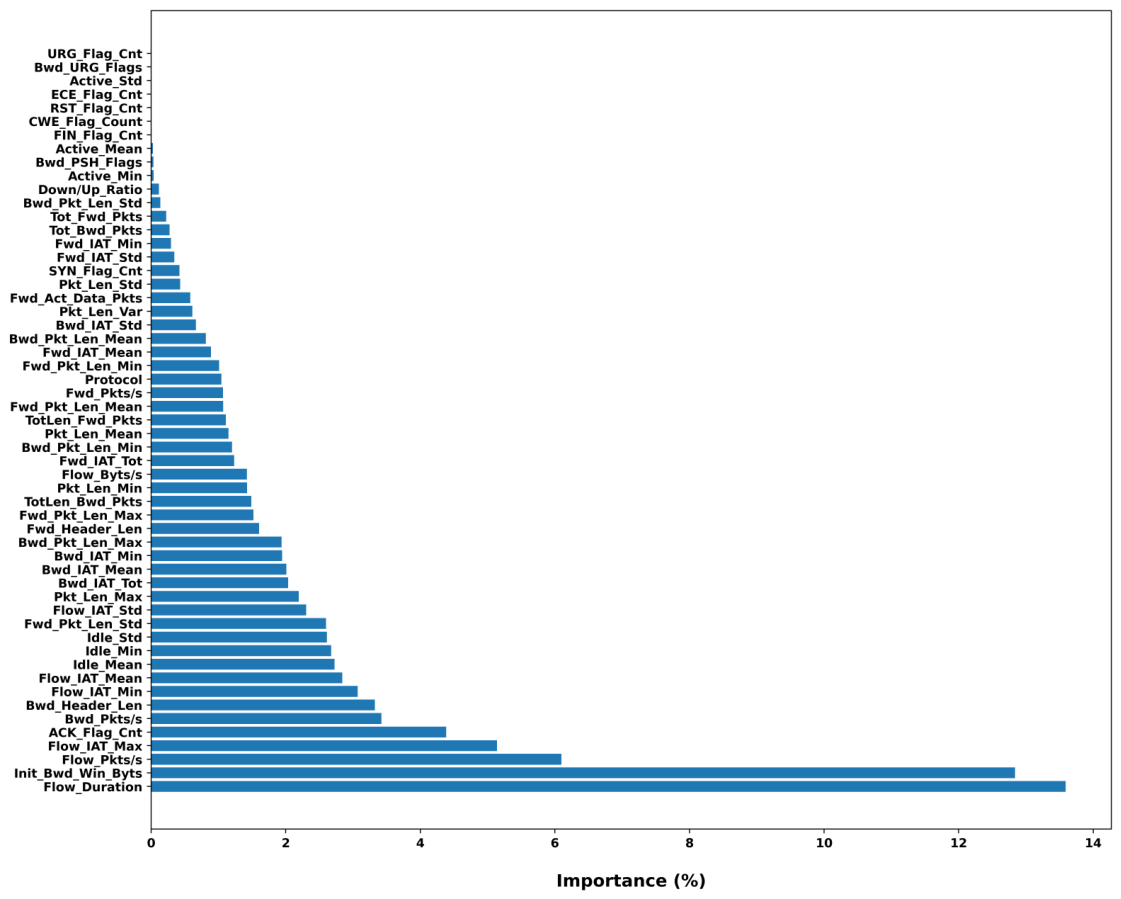
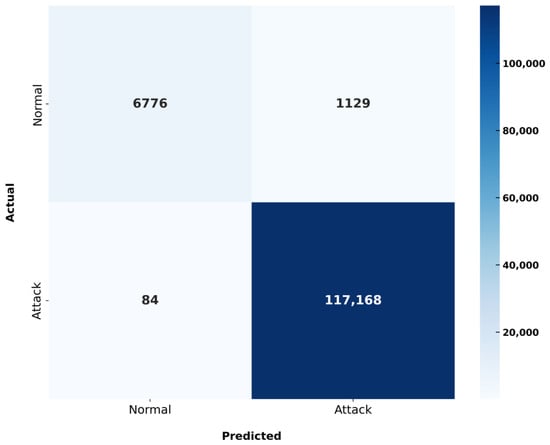
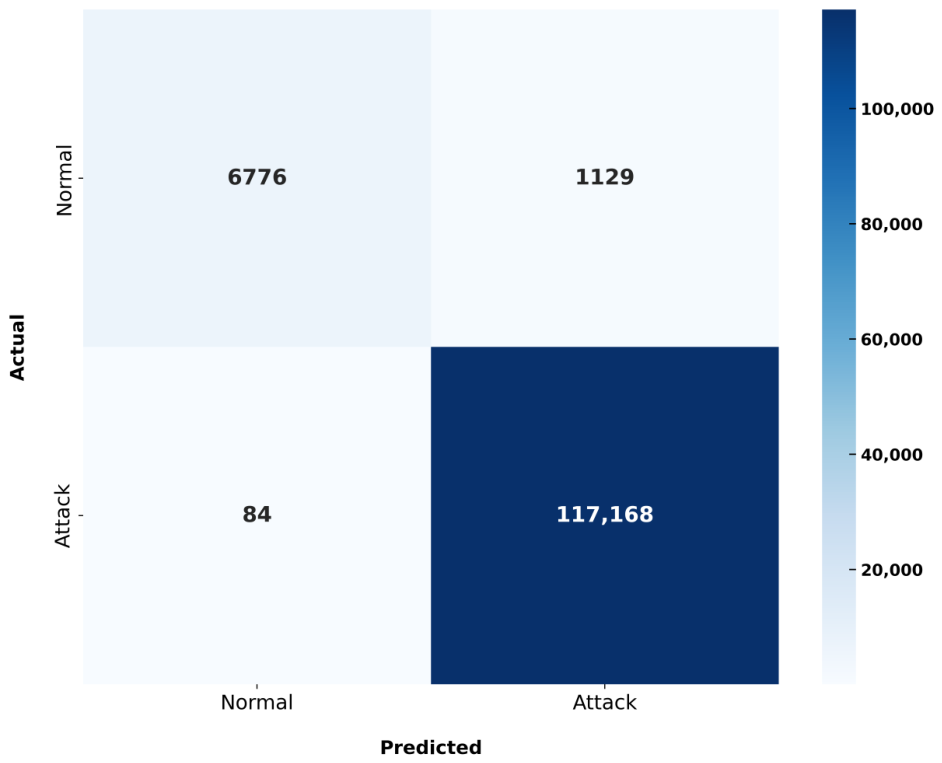
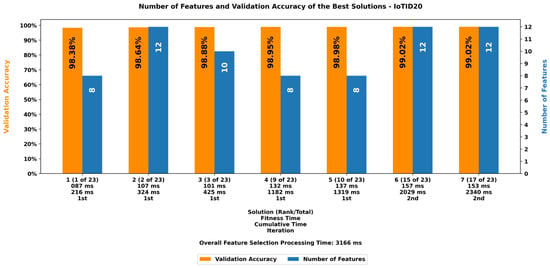
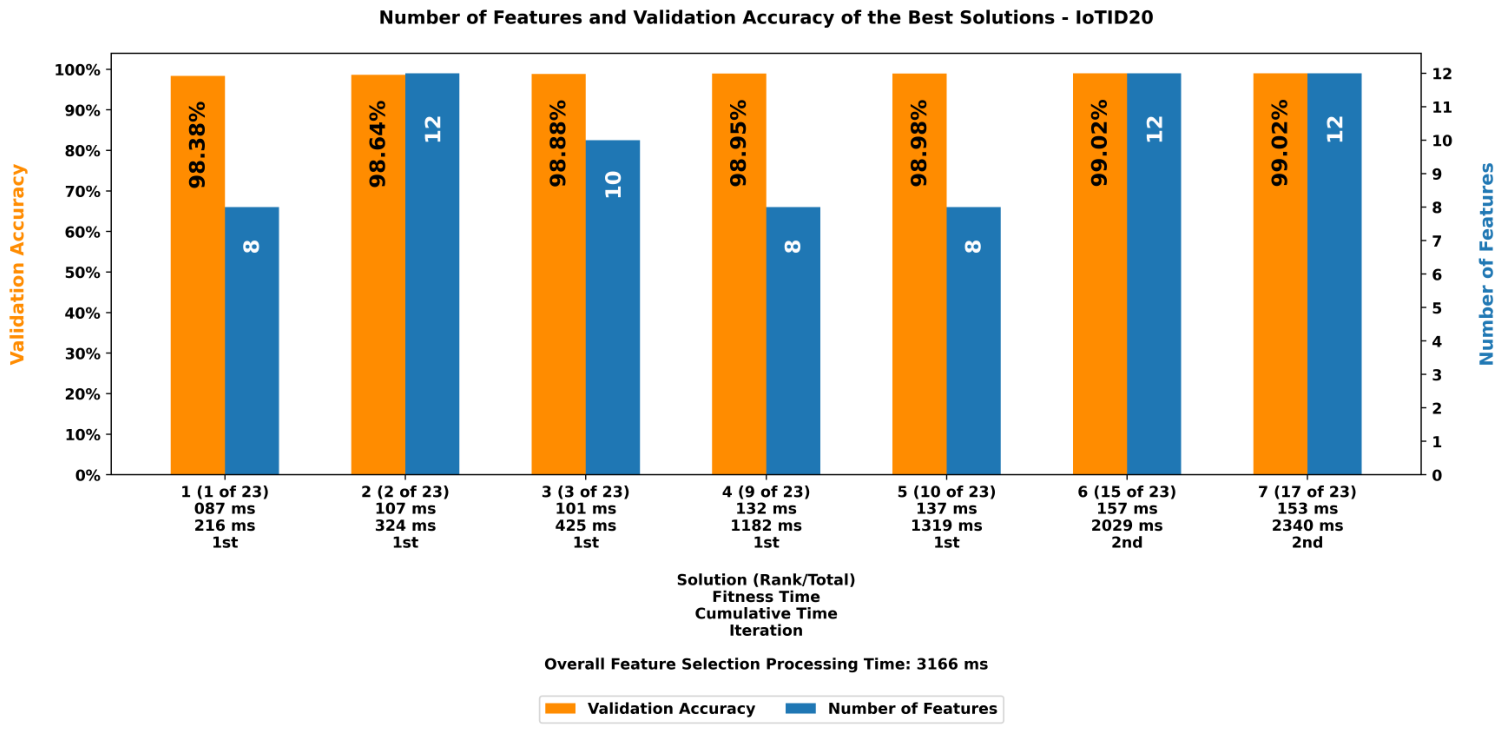
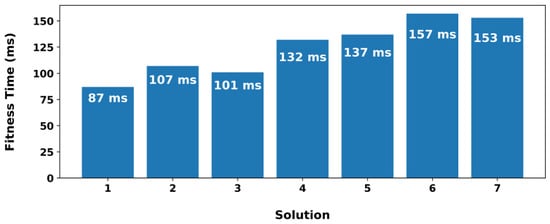
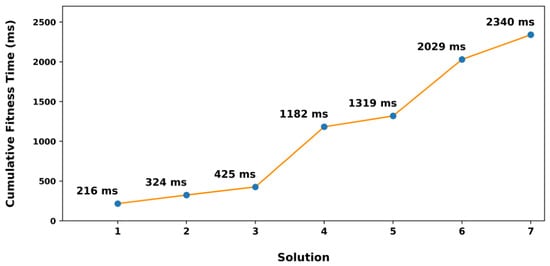
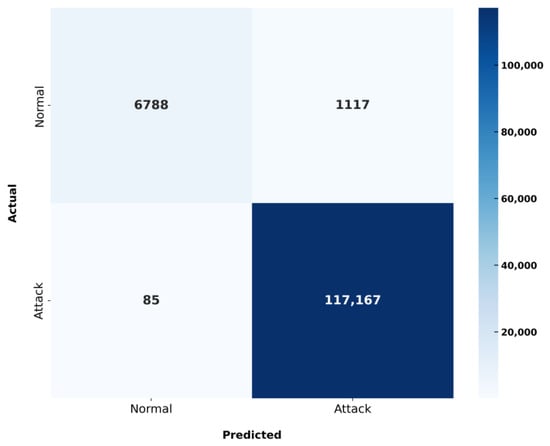
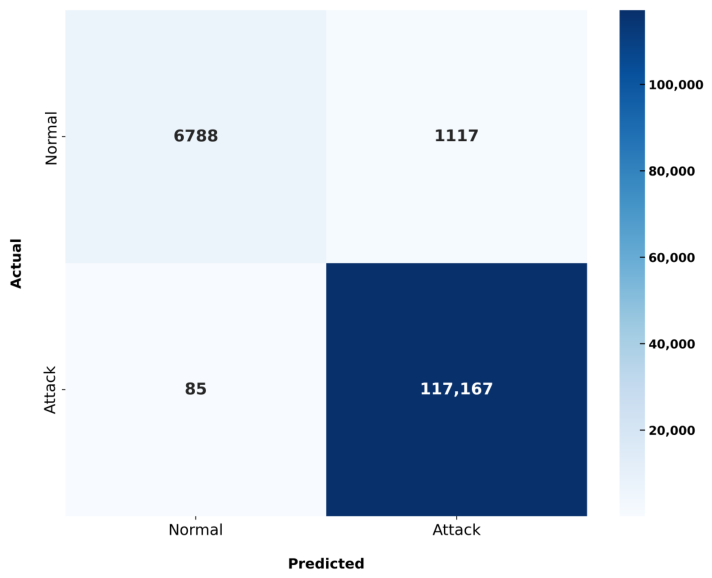
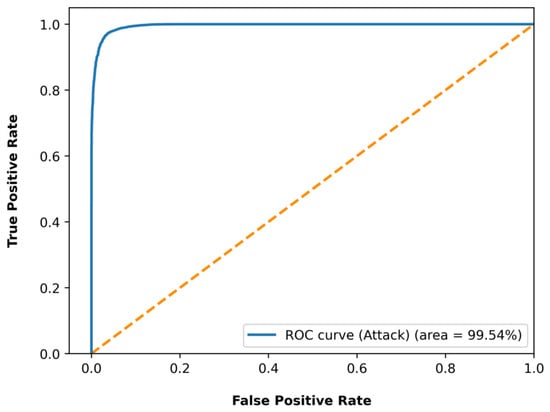
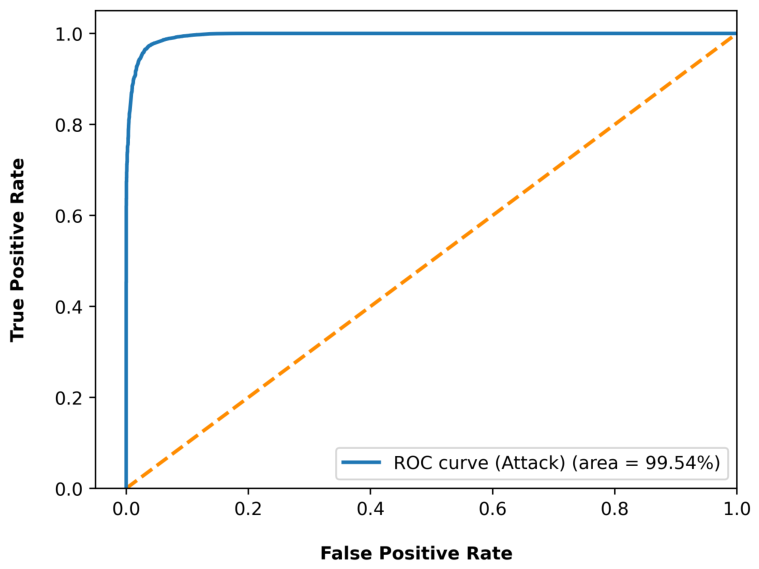
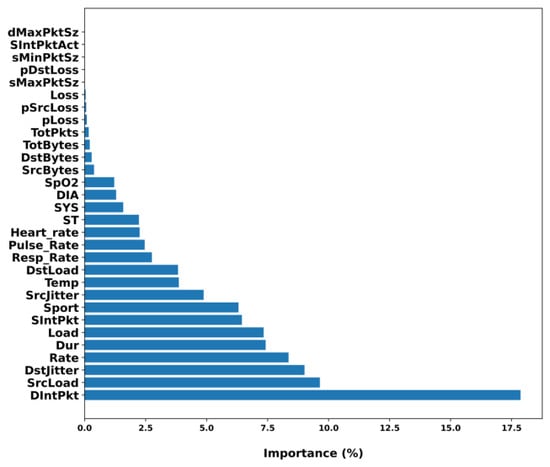
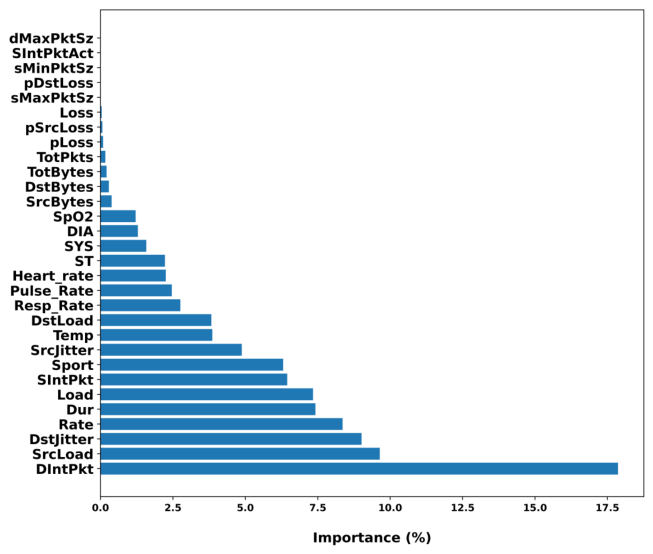
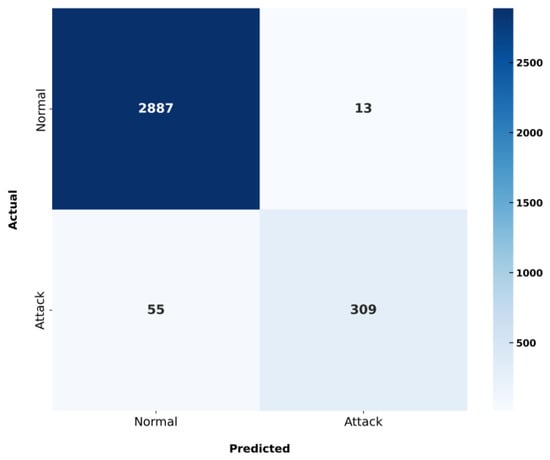
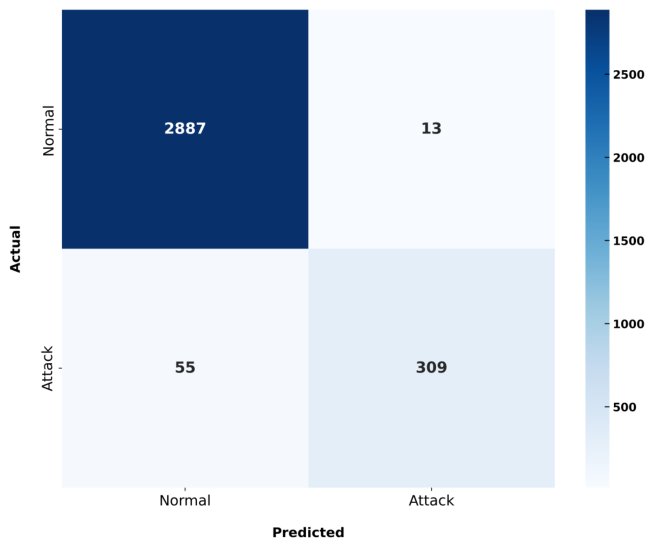
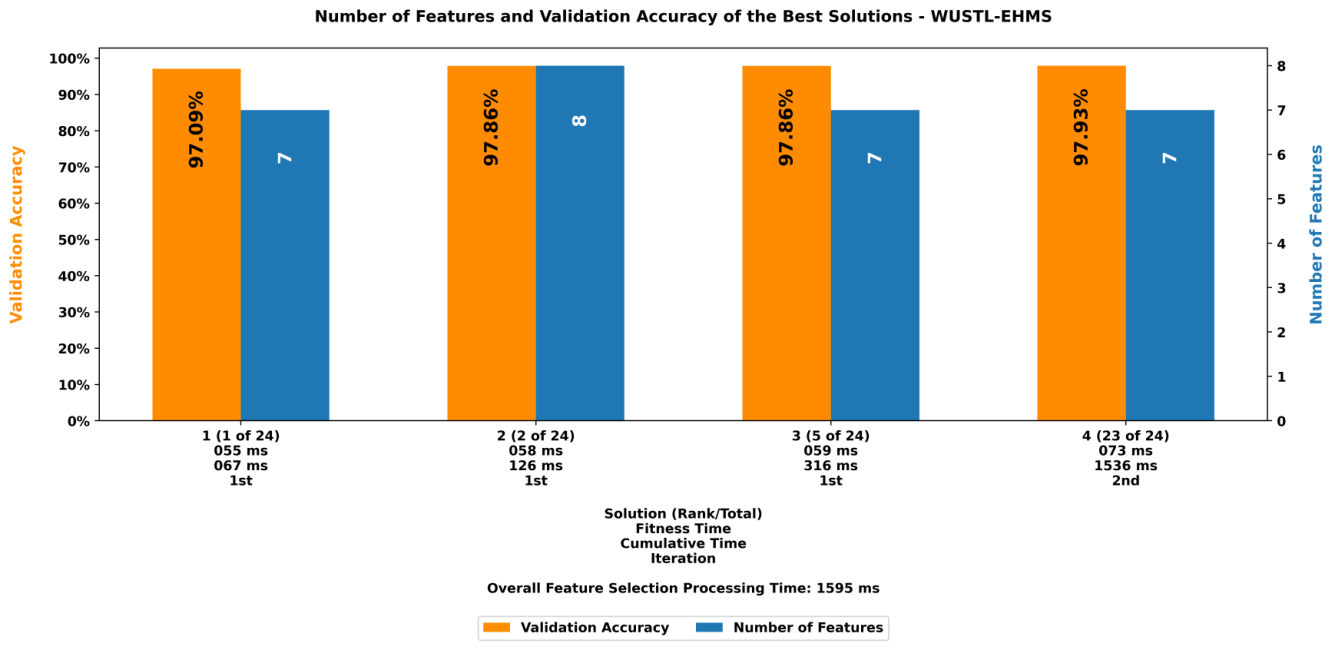
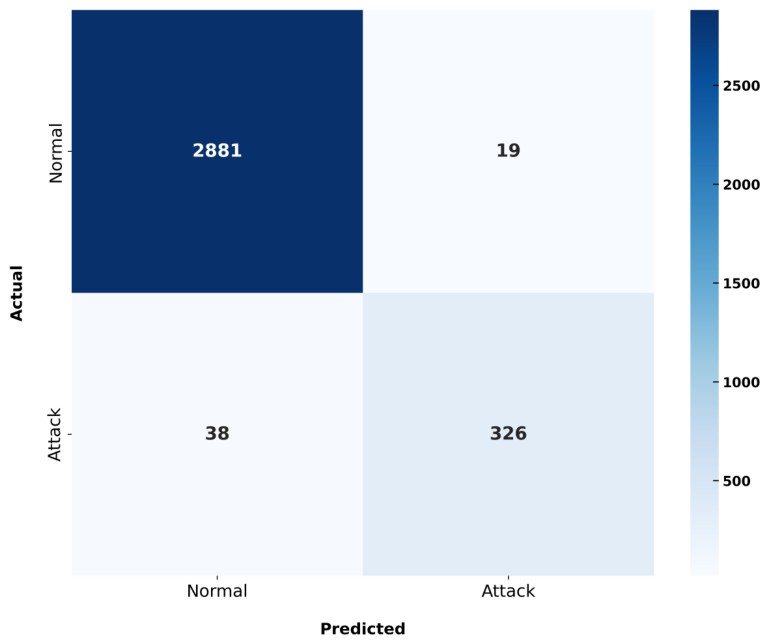
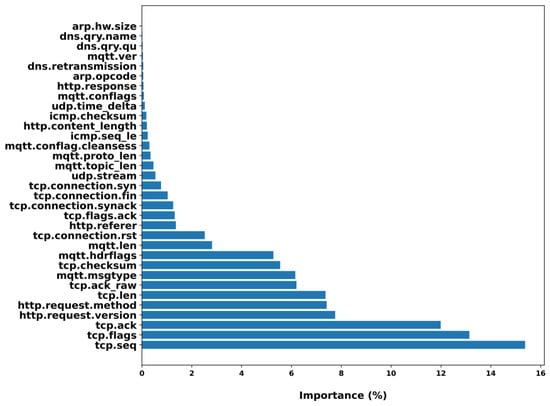
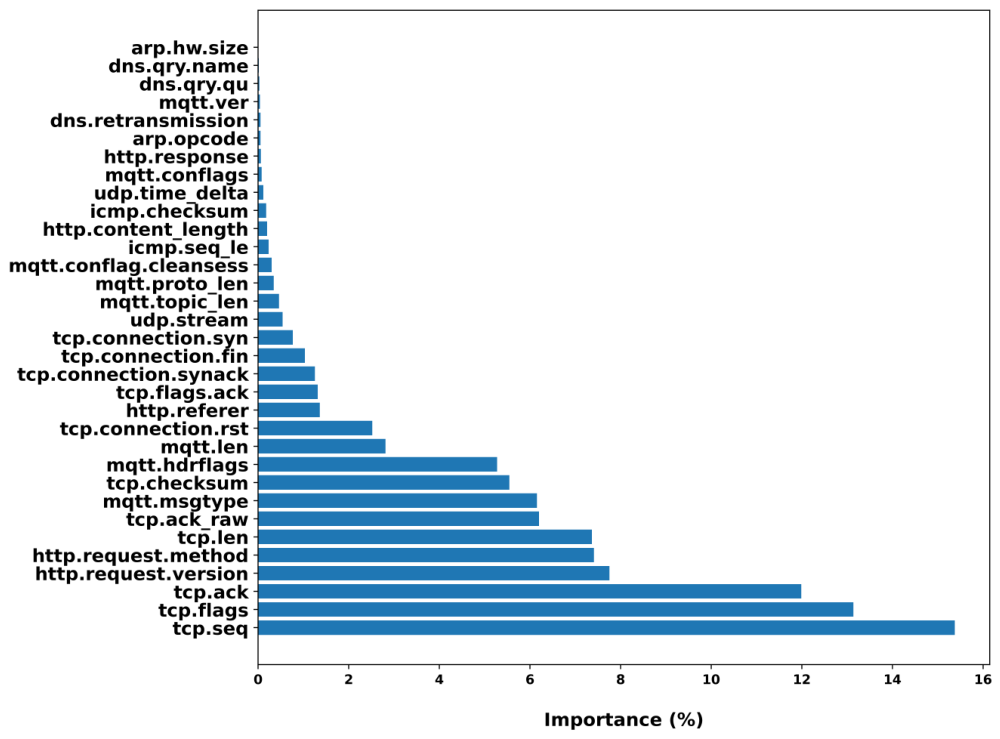
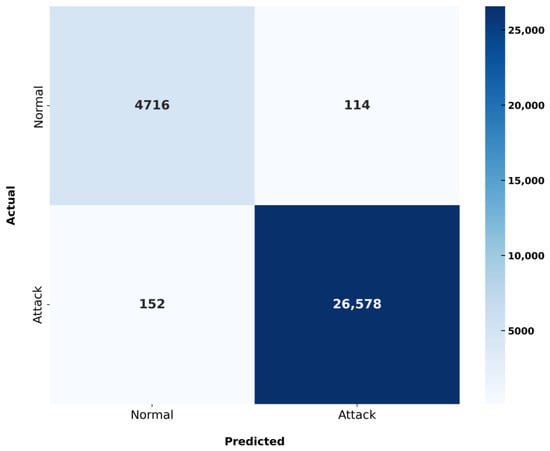
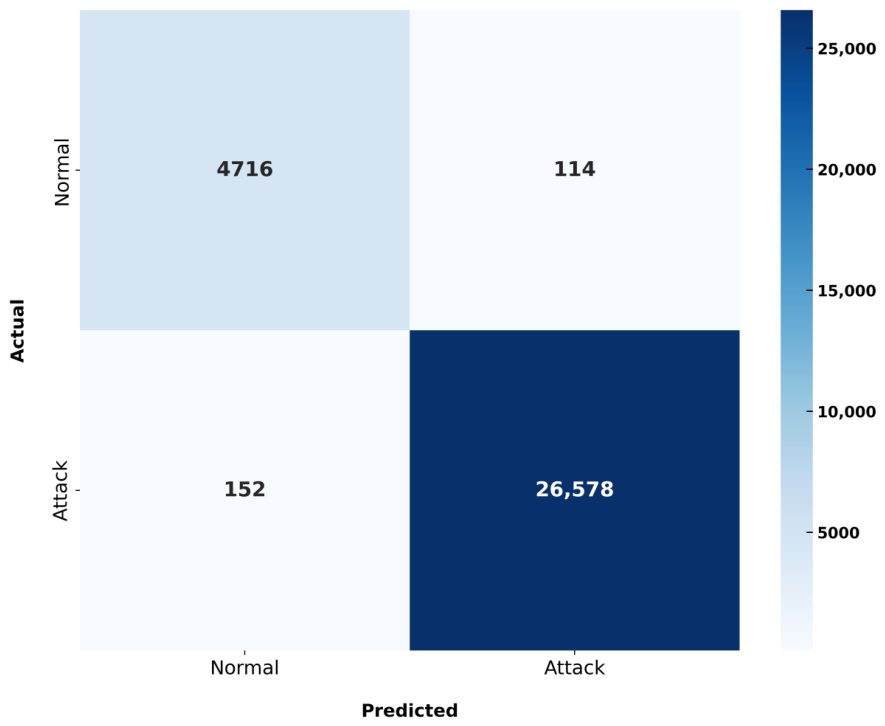
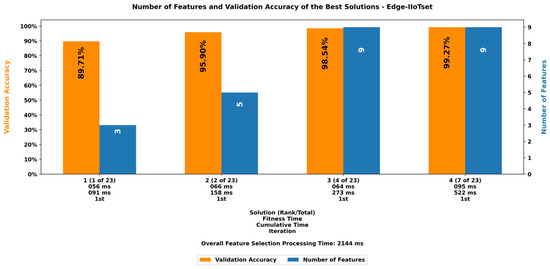
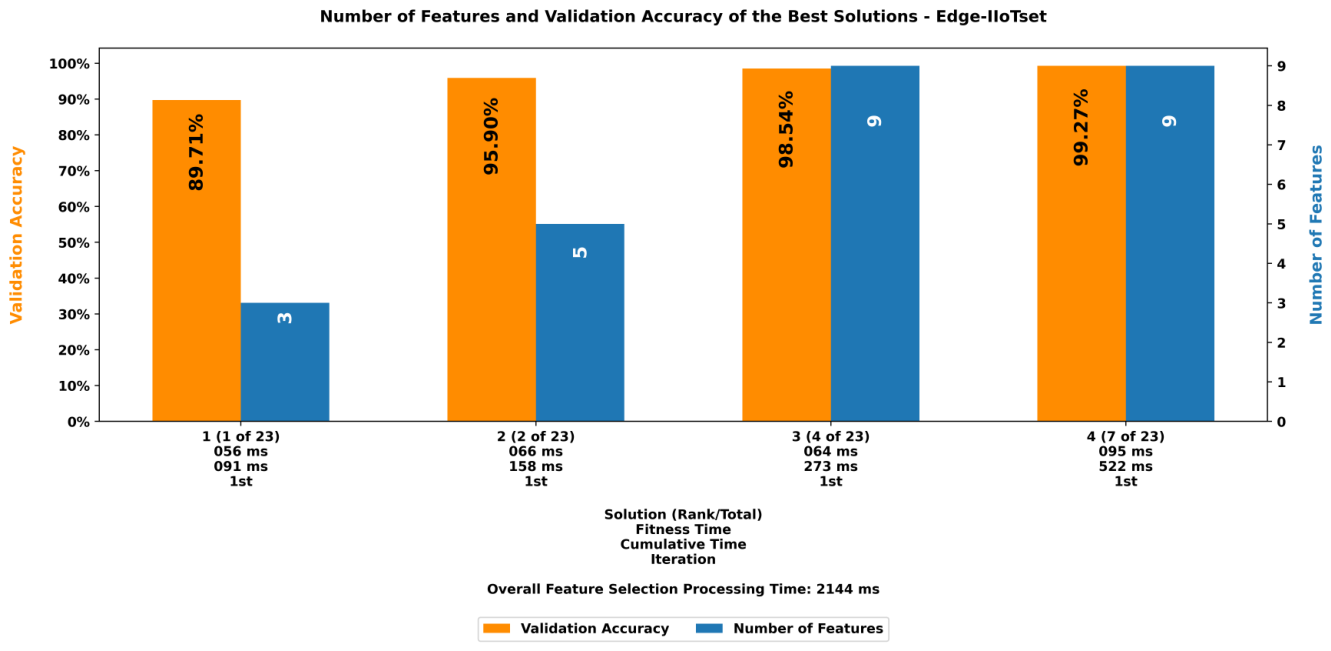
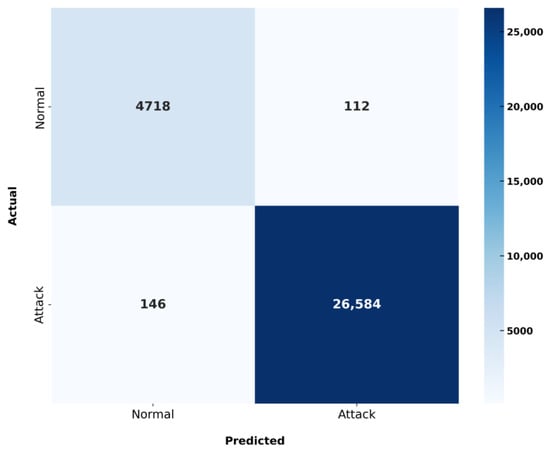
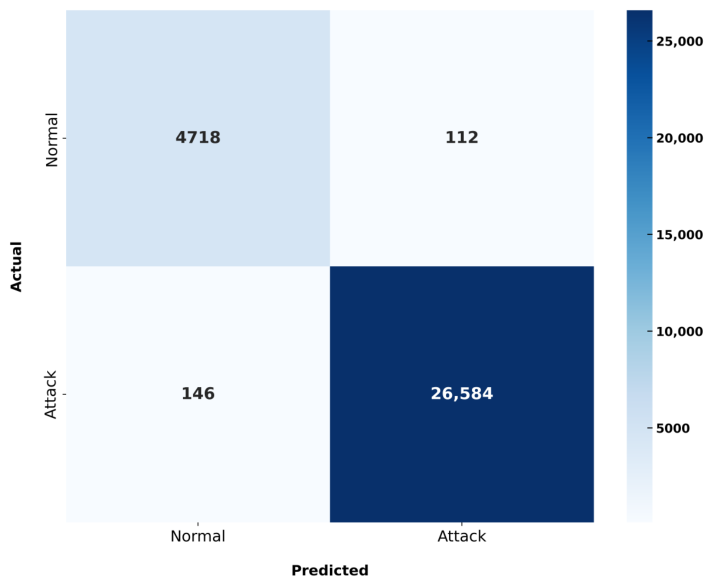
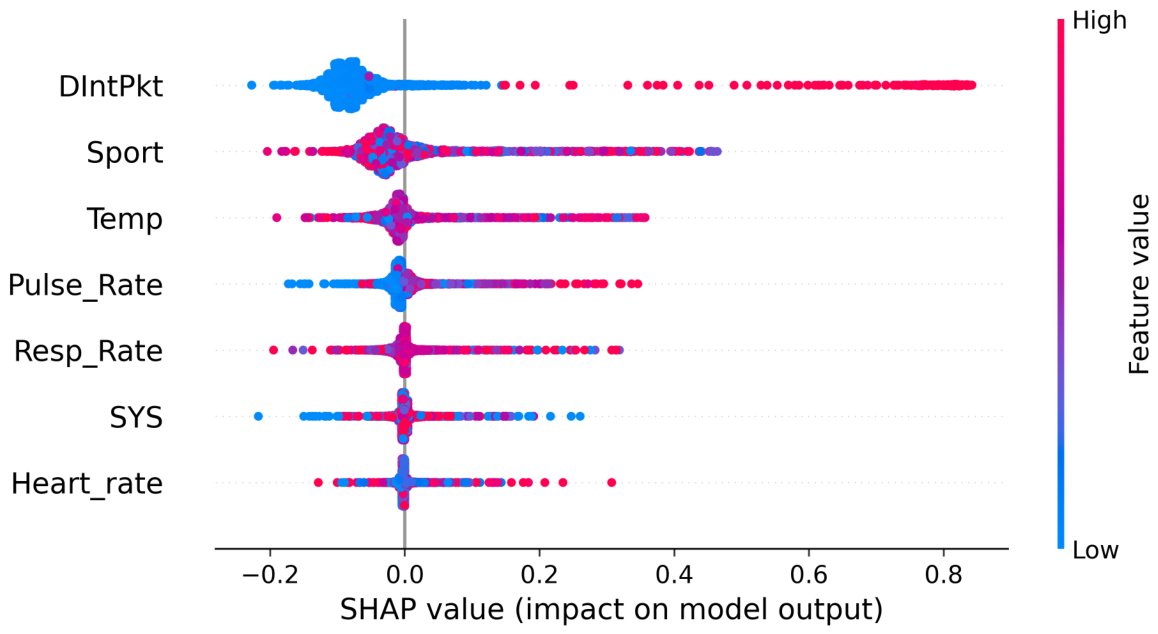
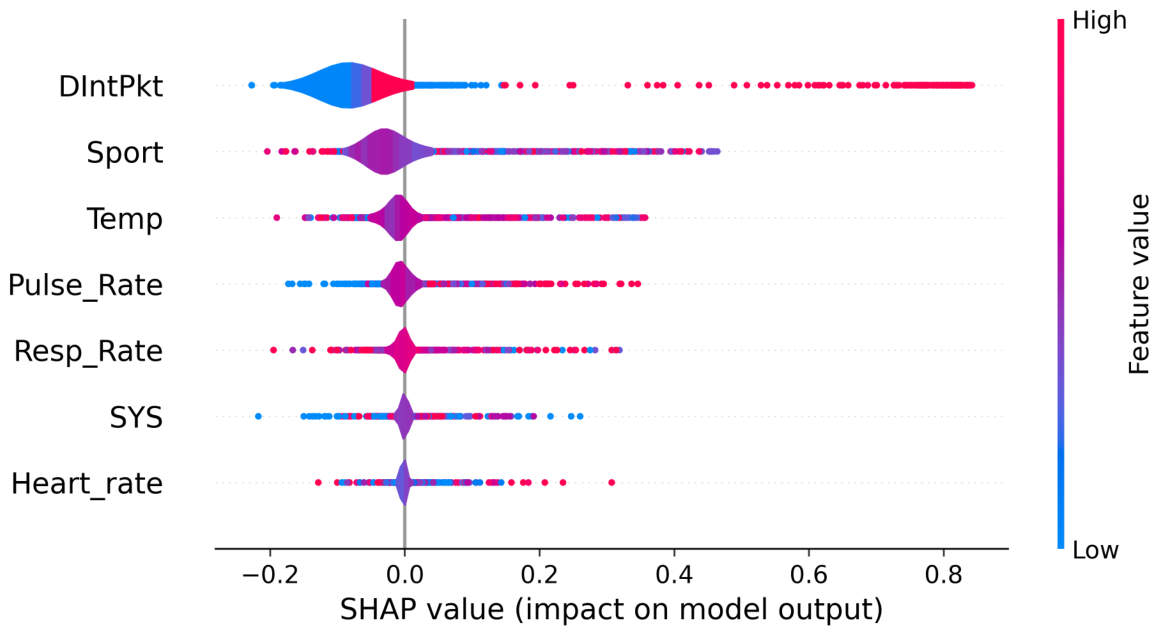
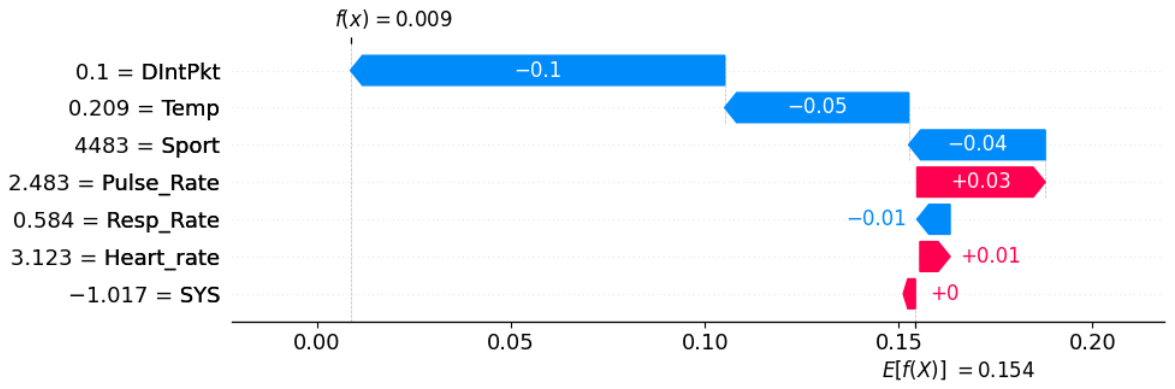
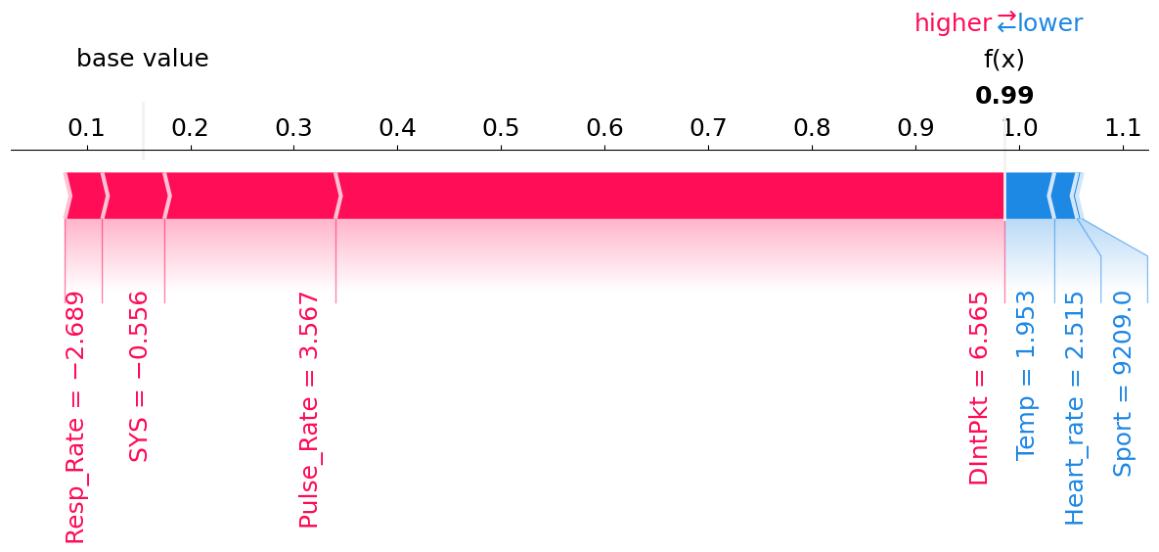
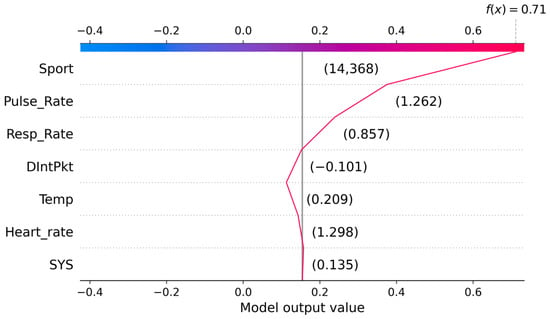
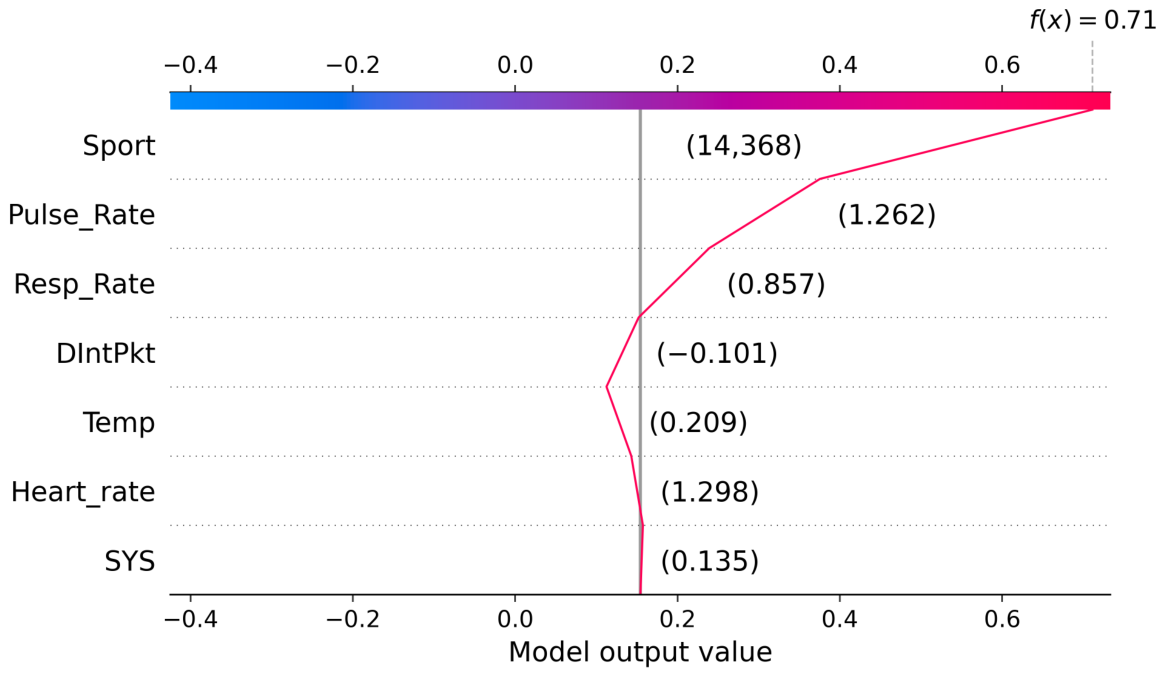
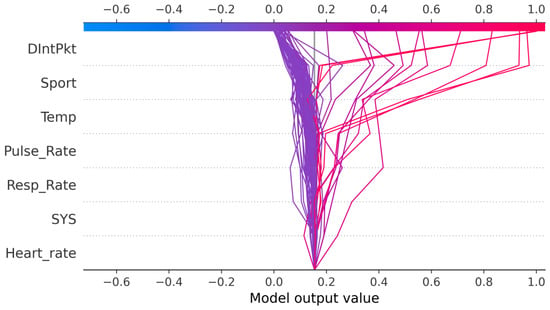
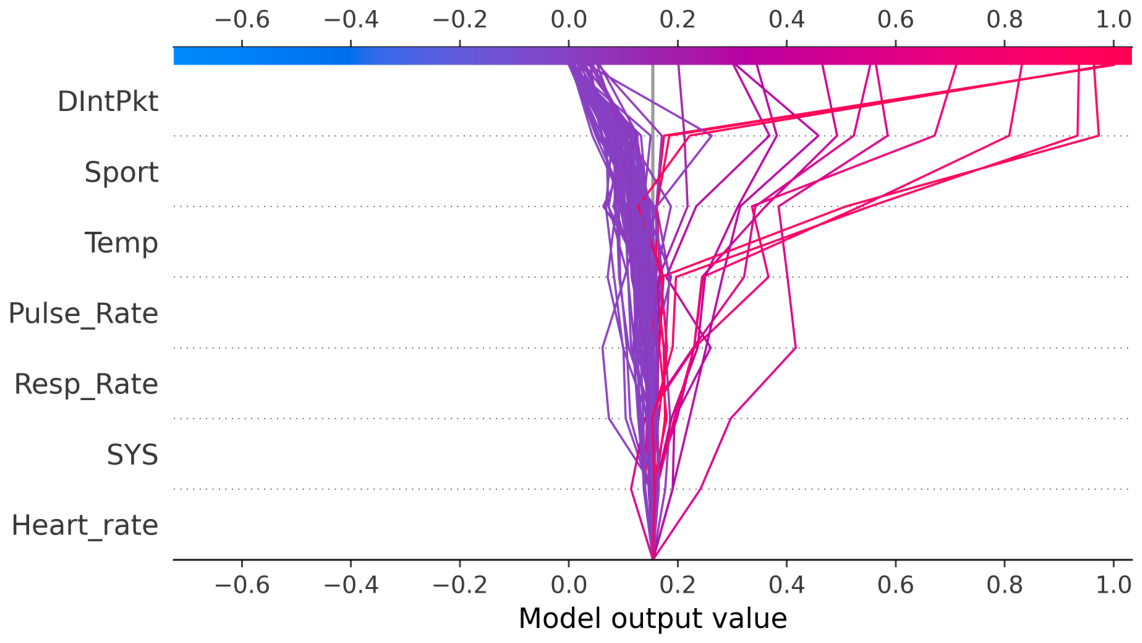
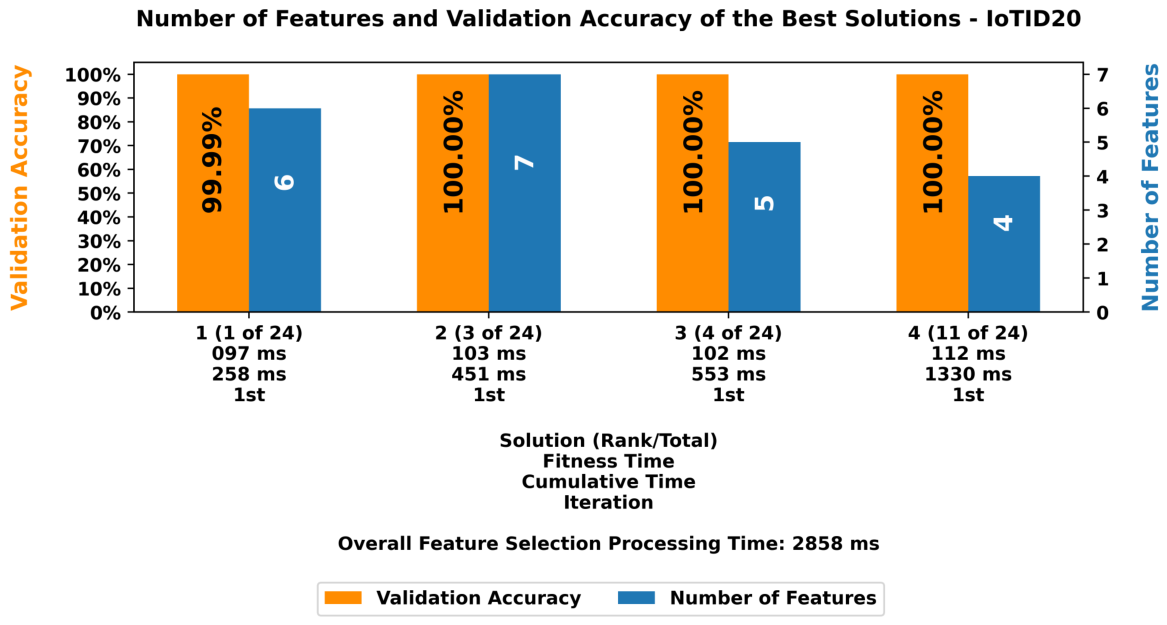

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.