1. Introduction
Entropy is a fundamental measure of uncertainty in probability distributions, reflecting the average information content of a sample. Shannon entropy, introduced by Shannon [
1], is the most widely used formulation of this concept, later generalized by Rényi through an additional parameter
that provides flexibility in tuning the measure’s sensitivity. Entropy is particularly valuable in reliability and lifetime data analysis, outperforming traditional measures such as the mean and variance in characterizing skewed and heavy-tailed distributions. Shannon entropy is defined as:
Rényi [
2] extended this measure through an order parameter
, defined as:
Entropy has been applied in diverse fields, including password security [
3], agricultural economics [
4], seismology [
5], and software reliability [
6]. Shannon entropy serves disciplines ranging from ecology to economics, while Rényi entropy has become essential in reliability engineering, life testing, and information theory.
Life-tests typically involve constraints on overall testing duration, necessitating censoring schemes to reduce time and cost. In such schemes, the experiment terminates before all units fail. This study employs progressive Type-II censoring, where the stopping rule depends on a pre-specified number of observed failures. In this scheme, n units are placed on test at time 0, with m failures to be observed. At the first failure , surviving units are randomly withdrawn; at the second failure , units are withdrawn, and so on. At the failure, all remaining units are removed. The observed data consist of the pairs with pre-specified removal values. Although more complex to design and analyze than traditional censoring, this scheme offers greater cost and experimental efficiency while maintaining the desired estimation accuracy.
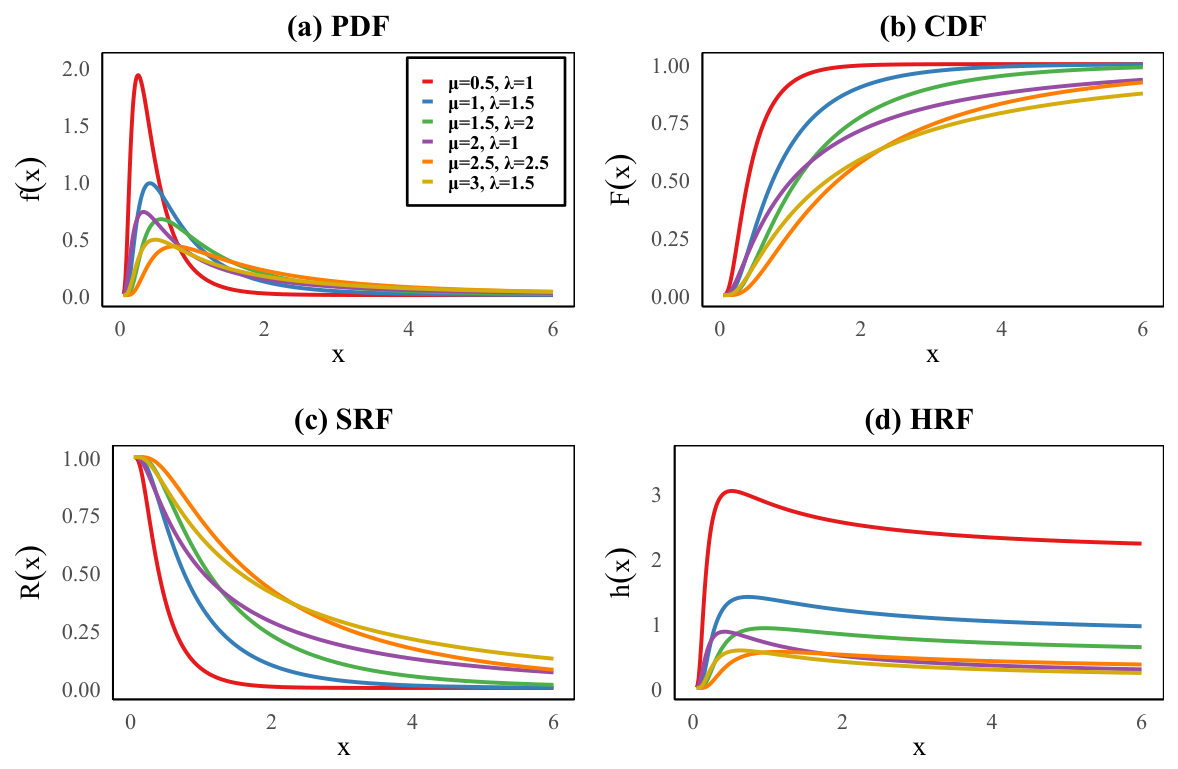
The inverse Gaussian distribution (IG) has attracted considerable attention due to its usefulness in statistical analysis, see
Figure 1. The origin of the IG dates back to Tweedie [
7] and Wald [
8] through studies on Brownian motion. Later, Tweedie [
9,
10,
11] provided a more detailed development of this distribution; with scale parameter
and location parameter (mean)
, the following probability density function (PDF), cumulative density function (CDF), survival function
and hazard rate function
are defined, respectively, as follows:
where
denotes the CDF of a standard normal distribution and can be expressed using the error function
. The HRF of IG decreases in
x for
.
Due to the extensive use of the IG distribution, numerous authors have examined the estimation of its parameters and related properties under various censoring schemes. Nath [
12] introduced generalized censored samples and obtained maximum likelihood estimates. Whitmore [
13] employed the EM algorithm for progressively right-censored data. Anaya and O’Reilly [
14] assessed goodness-of-fit under censoring. Ismail and Auda [
15] proposed kernel estimation under Type-II censoring. Jia et al. [
16] developed progressive hybrid Type-I censoring and derived MLE and Bayesian estimators. Rostamian and Nematollahi [
17] assessed stress-strength reliability under progressive Type-II censoring. Jayalath and Chhikara [
18] performed Bayesian and fiducial survival analysis using Gibbs sampling for various censoring types. Roy et al. [
19] considered progressive Type-I interval censoring. Bera and Jana [
20] examined stress-strength reliability with bootstrap and Bayes estimators. Xavier et al. [
21] formulated goodness-of-fit tests based on a fixed-point characterization for complete and right-censored data.
This section reviews entropy estimation under various censoring schemes. Kang et al. [
22] and Cho et al. [
23,
24] estimated Shannon entropy for double exponential, Rayleigh, and Weibull distributions under different censoring types. Anis and De [
25] studied Shannon and Rényi entropies for the Unit-Gompertz distribution. Hashem and Alyami [
26] analyzed entropies for the exponential doubly Poisson distribution. Okasha and Nassar [
27] and Shrahili et al. [
28] estimated entropy for inverse Weibull and log-logistic distributions under progressive Type-II censoring. Maiti et al. [
29] compared MLE and Bayesian estimates for generalized exponential distributions. Patra et al. [
30] proposed improved entropy estimators for exponential distributions. Ahmed et al. [
31] studied gamma distributions under progressive Type-I censoring, while Gong et al. [
32] considered generalized inverse exponential distributions under Stepwise Type-II truncated samples.
Despite the numerous studies addressing entropy estimation for lifetime distributions under various censoring schemes, these efforts have primarily focused on distributions such as the Weibull, exponential, generalized exponential, and log-logistic models. To the best of our knowledge, no previous study has investigated the estimation of Shannon and Rényi entropies for the IG distribution under progressive Type-II censoring, despite the importance of this distribution in reliability analysis and degradation modeling, and the flexibility of this censoring scheme in life-testing experiments. This gap is particularly consequential given that the IG distribution poses well-documented estimation challenges. Folks and Chhikara [
33] reported instability of maximum likelihood estimators for its parameters, particularly under small sample sizes or extreme parameter values, while Giner and Smyth [
34] highlighted numerical difficulties in handling the IG likelihood within the
statmod package in R, including issues related to flatness and numerical optimization. How these challenges may propagate or become amplified when estimating functions of parameters such as entropy measures has remained unexplored, and constitutes the starting point of the present study. To address this gap, this paper presents a comprehensive computational Bayesian framework that combines maximum likelihood estimation with Bayesian inference under multiple loss functions, employing Lindley’s approximation, importance sampling, and Markov chain Monte Carlo techniques. The primary contributions of this work can be summarized as follows:
Deriving closed-form Shannon and Rényi entropy expressions for the IG distribution, and developing a unified Bayesian computational framework under progressive Type-II censoring.
Documenting the breakdown of maximum likelihood estimation for Shannon entropy under certain parameter configurations, and providing practical, validated guidance for reliable entropy inference using Monte Carlo Markov Chain and importance sampling.
In this paper, we address the estimation of Shannon and Rényi entropies for the IG distribution under progressive Type-II censoring. We begin by deriving the Shannon entropy and the Rényi entropy of the IG distribution by substituting in Equation (
1) and Equation (
2), respectively, using Equation (
3) as the basis for substitution (detailed in
Supplementary Materials Section S1):
and
where
is the Bessel function and
is the exponential integral.
The remainder of this paper is organized as follows. In
Section 2, we obtain maximum likelihood estimators for the Shannon and Rényi entropies and the confidence interval (CIs).
Section 3 presents Bayesian estimates using different loss functions: the squared error loss function (SE), the general entropy loss function (GE), and the LINEX loss function. Due to the absence of clear formulas for the Bayes estimates, we employ Lindley’s approximation method in
Section 4, while in
Section 5, we use importance sampling (IS) to derive credible intervals. In
Section 6, the Monte Carlo Markov Chain (MCMC) is used to determine credible intervals and the highest posterior density (HPD). The simulation study is analyzed in
Section 7 with the attachment of its resulting tables and figures and commentary on the tables. As for
Section 8, it presents the real data and attaches the resulting tables and figures along with their interpretation. Finally, we review the recommendations based on the simulation results and real data, as they are linked to a previous study, to illustrate the advantages.
2. Maximum Likelihood Estimation
Let
denote the progressive Type-II censored sample, with
representing the
failure time. Although the MLEs for the parameters of the IG distribution under progressive Type-II censoring have been derived previously, we briefly restate the derivation here because the subsequent entropy estimators depend directly on these MLEs through the invariance property. The likelihood function is given by:
By using Equations (
3) and (
4) and substituting them into Equation (
9), we obtain:
where
,
.
The log-likelihood function is expressed as:
We obtain the MLEs of the unknown parameters
and
by maximizing the log-likelihood function given in Equation (
11) with respect to
and
, respectively. Differentiating Equation (
11) with respect to
, and then equating the result to 0, we obtain the normal equation for
, which is given by:
Similarly, the normal equation of
is as follows:
where
,
. We simultaneously solve Equations (
12) and (
13) for
and
to determine their maximum likelihood estimates (MLEs). Nevertheless, explicit solutions for these equations are nonexistent, indicating that the maximum likelihood estimators cannot be articulated in a closed form. We employ numerical methods to ascertain solutions to Equations (
12) and (
13). Let
denote the joint maximum likelihood estimators (MLEs) of
and
. The Shannon and Rényi entropy measures are nonlinear functions of
. By substituting the joint MLEs
into these functions, we obtain the corresponding profile maximum likelihood estimators (Pr. MLEs) of the entropies as follows:
and
It is important to emphasize that these are profile MLEs (plug-in estimates) of the entropy measures, not true MLEs. This distinction is critical because profile MLEs of nonlinear functions may not inherit the optimal properties of MLEs and can exhibit bias and instability, particularly under censoring and for complex entropy measures such as Shannon entropy.
To compute the CIs for unknown parameters
and
, we utilize the asymptotic characteristics of the MLEs. In numerous real scenarios, precisely estimating these predicted values can prove challenging. We typically adopt a more straightforward method: we eliminate the expectation and compute the second derivatives directly, subsequently substituting the estimated values of
and
. This provides us with an estimated representation of the Fisher information matrix:
which we used to get an approximate variance-covariance matrix for the estimators. That helps us to understand how much uncertainty there is in each estimate and how the two parameters might be statistically related. The variance-covariance matrix of IG estimators is calculated as follows:
The inverse of the matrix:
The second derivatives with respect to the parameters
and
are computed (
Section S2),
where
. Subsequently, we substitute in Matrix (
16). Furthermore, we utilize the delta approach to obtain estimated confidence intervals for the Shannon and Rényi entropy metrics. For a comprehensive elucidation of this strategy, we direct the reader to Greene [
35]. Assume that
Moreover, the approximate estimated variances in
and
were given by
Therefore,
and
asymptotically followed the standard normal distribution. Thus, the asymptotic CIs (Wald interval)
for the Shannon and Rényi entropies were given, respectively, by
where
denoted the upper
percentile of the standard normal distribution. The final result is obtained numerically because the equations involved are complex to solve analytically. It is important to note that the Wald-CIs constructed via the delta method are asymptotic in nature, and their finite sample performance depends on the shape of the likelihood function, the nonlinearity of the entropy formula, and the stability of the variance-covariance matrix. It is well documented that Wald intervals can perform poorly when the likelihood surface is irregular or the sample size is small, as exemplified by the binomial success probability [
36].
Although the MLEs are straightforward to compute via the invariance principle, their finite-sample performance under progressive censoring (particularly for the entropy functions) remains to be evaluated. This motivates the development of Bayesian alternatives in the following section.
3. Bayesian Estimation
After deriving the MLEs of the uncertainty measures in Equations (
7) and (
8) in the preceding section, we now proceed to Bayesian inference for the Shannon and Rényi entropy measures. This Bayesian approach commences with the definition of a prior distribution and a likelihood function, which collectively yield the posterior distribution of the quantities of interest. Choosing an appropriate prior distribution for unknown parameters is a fundamental challenge in Bayesian inference. In the absence of strong prior knowledge, a gamma distribution was adopted as the prior for both
and
, consistent with prior specifications previously employed in the context of the IG distribution [
37]. The specific numerical values of the prior hyperparameters, along with the corresponding sensitivity analysis, are detailed in the simulation section, where practical performance is assessed under multiple prior scenarios.
A random variable
X is considered to adhere to a gamma distribution, assuming independent gamma priors for
and
, respectively, in this context:
We give the joint prior distribution for
and
as:
We take the log-joint prior distribution for
and
as:
where
. After making calculations using Equations (
10) and (
17), the joint posterior distribution of
and
can be established as follows:
where
is a normalizing constant defined by,
The posterior density function of
is determined by Bayes’ method:
This paper analyzes three forms of loss function: the SE loss function, the GE loss function, and the LINEX loss function. Let
denote an estimator for the entropy functions
H. Subsequently, we develop the loss functions, as illustrated in
Table 1.
The Bayes estimator under loss function can be expressed as:
where
is the transformation applied to the entropy before taking the posterior expectation, and
is the inverse operation that recovers
from the expected transformed value. For SE loss function,
and
is the identity. For GE loss function,
and
. For LINEX loss function,
and
.
Using Equation (
21) and Equation (
19), the Bayes estimates of the Shannon entropy
H with respect to the GE and LINEX loss functions are obtained, respectively, as follows:
By replacing
into Equation (
22), we obtain the Bayes estimate of Shannon entropy
H concerning the SE loss function. Likewise, we employ Equation (
21) and Equation (
19) to derive the Bayes estimates of the Rényi entropy
based on the aforementioned loss functions.
Computing closed-form solutions for the ratio of the two integrals presented in Equations (
22) and (
23) is intricate. To tackle this issue, we utilize Lindley’s approximation technique.
4. Lindley’s Approximation
In this section, we derive Lindley’s approximation for Bayesian estimates, which depend on two parameters,
and
. The main equation was proposed by Lindley [
38]. It is expressed as follows:
where
can be evaluated as
where
That approximation method has been employed by numerous researchers, including Nassar et al. [
39], Kundu and Pradhan [
40], Xu et al. [
41], Kim et al. [
42], Sultan and Ahmad [
43], Sana and Faizan [
44], and Ren and Hu [
45].
- ⇒ Firstly;
To apply Lindley’s approximation, the function
appearing in the posterior expectation must be specified for each loss function. From the general form given in Equation (
21), we obtain the following (detailed derivations and the required partial derivatives are provided in
Section S2):
Bayesian estimators of the Shannon entropy under the SE, GE, and LINEX loss function, respectively, as follows:
Bayesian estimators of the Rényi entropy under the SE, GE, and LINEX loss function, respectively, as follows:
- ⇒ Secondly;
we obtain the derivatives of the ML equations (in
Section S2):
- ⇒ Thirdly;
we obtain the derivatives of the log-joint prior distribution from Equation (
18):
- ⇒ Fourthly;
we substitute it into Equation (
25) to obtain the result. We change the objective function (
) and its derivatives (
,
,
,
,
and
) each time due to the different loss functions every time, while keeping the other derivatives related to the maximum likelihood function (
,
,
,
,
,
,
and
), Fisher matrix elements (
,
,
, and
) and also the derivatives of joint prior distribution (
and
) fixed.
Thus, the Bayes estimate of Shannon entropy
H with respect to the GE loss function is obtained as;
By substituting
in Equation (
26), we can obtain the Bayes estimate of
H with respect to the SE loss function. Using a similar procedure, we can obtain the Bayes estimates of the Rényi entropy
with respect to the above loss functions.
Therefore, the Bayes estimate of Shannon entropy
H with respect to the LINEX loss function is obtained as;
Using a similar procedure, we can obtain the Bayes estimate of the Rényi entropy
with respect to the above loss function by using Equation (
27).
Although Lindley’s approximation provides a computationally efficient way to obtain Bayesian estimates, it does not easily produce credible intervals for entropy measures. So, we now introduce the importance sampling procedure, which makes it easy to build HPD in addition to point estimates.
5. Importance Sampling
This paper examines the importance sampling approach for calculating Bayes estimates of unknown parametric functions as defined in Equations (
7) and (
8). The exception in IG is that we need to set a different proposal for each parameter
and
, while in most classical distributions, a conjugate distribution is enough to cover everything. First, we define the proposal distribution (
) from which we generate the parameters related to the IG
and
. Note that it is not necessary for the proposal distribution to be the same as the prior distribution. We need to determine the distribution of the proposal using the joint posterior distribution of
and
as follows:
We focus on the parts that contain
:
This represents the form of the gamma distribution, so the most suitable proposal distribution
for
is the gamma distribution (G).
We focus on the parts that contain
:
It seems that
is more complicated because it contains this specific part
, since it does not resemble the gamma distribution. Instead, the log-posterior density can be locally approximated in the neighborhood of the maximum likelihood estimator
using a second-order Taylor expansion. Consequently, the posterior distribution is approximately normal around
, which motivates the use of a normal proposal distribution. To make it clear, we follow these steps:
We take the logarithm:
We find the first derivative and equating it to
:
We find the second derivative to determine the maximum and minimum values:
If
means that point is a minimum, then
also means that point is a maximum (saddle point).
Looking at the previous expression , what determines whether it is positive or negative is the numerator , because the denominator is always positive anyway. So, we plug in numbers into the numerator and look for the values that make it negative so the curve goes down, which means that point is a maximum. The larger the value of the quantity , the more negative the second derivative.
Because the functional form of the proposal distribution for is unknown, we use Laplace approximation to determine an appropriate Gaussian form, where the logarithm of the likelihood function is expanded around the maximum likelihood estimate of using a second-order Taylor series, which leads to a normal approximation of the proposal distribution given by , where denotes the observed Fisher information. This approximation provides a convenient and efficient proposal distribution for the importance sampling procedure.
However, since
, it is more appropriate to propose a truncated normal distribution because the standard normal distribution extends from
, so if
, it could take a positive or negative value, which would be illogical in this context. Therefore,
where
represents the truncation limits (that is, values outside the interval are not possible). In this approach, it is necessary to reformulate the joint posterior distribution of
and
as presented in Equation (
19). It is provided by
For each pair generated
, the importance weight is computed as
where
(before normalization). The normalized weights are then obtained as
Later, we will use these weights to calculate Bayesian estimates of any parametric function
as
The following procedure can be used to obtain Bayes estimates of a function, denoted as
, with respect to the GE and LINEX loss functions:
- Step 1.
Generate from a gamma distribution with shape parameter and scale parameter , denoted as .
- Step 2.
For the given obtained in Step 1., approximate the MLE round for , the form approaching .
- Step 3.
Execute Step 1. and Step 2. for N iterations to derive , .
- Step 4.
The Bayes estimates of the parametric function
under the GE and LINEX loss functions are derived, respectively, as follows:
and
The Bayes estimate of
concerning the SE loss function
can be obtained from Equation (
28) for
. Furthermore, within the framework of the GE loss function, Bayesian estimates of the Shannon and Rényi entropy functions can be derived from Equation (
28). Similarly, for the LINEX loss function, Bayesian estimates of the Shannon and Rényi entropy functions can be obtained from Equation (
29), where
corresponds to the Shannon entropy and
pertains to the Rényi entropy.
- Step 5.
Propose intervals for the estimation of the Shannon entropy function and the Rényi entropy function. This method was used by Chen and Shao [
46] for this purpose. Define
and
where
and
for
are posterior samples generated from previous steps for
and
, respectively. Each sample represents a part of the posterior distribution, and the size of that part (its proportion) is given by the normalized weight,
.
- Step 6.
Estimate the
quantile of
:
Let be the ordered values of , and let be the corresponding normalized weights for these ordered values.
- Step 7.
Establish the typical credible interval with a
confidence level: Let
p be the target coverage probability (the confidence level), where
. For a 95% credible interval,
and
. The bottom bound of the credible interval is the
quantile of the posterior distribution of
. The top limit of the credible interval is the
quantile of the posterior distribution of
. The standard credible interval, sometimes referred to as the equal-tail interval, is computed utilizing the quantile estimations from Equation (
30).
where,
is the estimated quantile below which
of the posterior distribution of the entropy lies.
is the estimated quantile below which
of the posterior distribution lies.
Although importance sampling provides accurate estimates when the proposal distribution is well-chosen, it does not automatically explore the full posterior. We therefore also employ MCMC, which constructs a Markov chain targeting the exact posterior and serves as the gold-standard simulation-based method in this study.
6. Monte Carlo Markov Chain
MCMC algorithms offer a versatile approach to create approximate samples from any desired distribution. They are extensively utilized in contemporary statistics, particularly in Bayesian analysis. In Bayesian inference, the posterior distribution is the primary emphasis; nevertheless, it frequently cannot be expressed in a closed form, as is the case here. Two prevalent MCMC methods utilized in Bayesian estimation include the Metropolis–Hastings algorithm, presented by Hastings [
47], and the Gibbs sampler, proposed by Geman and Geman [
48]. Both methodologies utilize marginal posterior distributions throughout the sampling procedure. In this approach, it is necessary to reformulate the joint posterior distribution of
and
as presented in Equation (
19). It is provided by
When examining the posterior distribution in Equation (
19), the complete conditional posterior distributions for the parameter
and the parameter
are derived utilizing the informative gamma priors, as delineated below.
and
Due to the inability to derive the marginal distributions and in closed form, we employ the Metropolis–Hastings algorithm, which facilitates the estimation of Bayesian point estimates and credible intervals for unknown parameters and , in addition to the entropy measures H and . A cyclic implementation of the Metropolis–Hastings sampling process to acquire approximate samples from the posterior distribution . This can be acquired using the subsequent steps:
- Step 1.
Specify starting values and (assume MLEs of and ) and specify .
- Step 2.
Generate and from the normal proposal distributions and , respectively, where and are the variances in and , which can be estimated from the inverse of Fisher information matrix.
- Step 3.
Determine the following acceptance probabilities:
- Step 4.
Generate samples and from uniform distribution .
- Step 5.
If (acceptance probability), accept the proposal and specify , otherwise . Similarly, if , accept the proposal and specify , otherwise .
- Step 6.
Compute the Shannon entropy and Rényi entropy indicators from Equation (
7) and Equation (
8), respectively:
and
- Step 7.
Specify
- Step 8.
Repeat Step 1. to Step 6.,
(the overall number of iterations) times to obtain MCMC samples.
,
, …,
represent the generated samples obtained from the MH algorithm. After discarding the first
M number of burn-in samples, the remaining
samples are used to compute Bayesian estimates of
H and
. The Bayes estimate of
under the SE, GE, and LINEX loss functions can now be computed as:
and
The Bayes estimate of
with respect to the SE loss function can be derived from Equation (
36) when
.
- Step 9.
Order the values
ascendingly as
. Assuming the desired confidence level is
(where
is the significance level), the standard Bayesian credible interval for the parameter
is given by
where
denotes the integer part (floor function).
is the
element in the ordered sequence.
is the left-tail probability, and
is the right-tail probability. Therefore, the HPD of
can be constructed.
With all three Bayesian computational methods now defined (Lindley’s approximation, importance sampling, and MCMC). This methodological summary is illustrated in Algorithm 1, their practical performance in estimating Shannon and Rényi entropies under progressive Type-II censoring is assessed through extensive simulations in the following section.
| Algorithm 1: Bayesian estimation of H(μ, λ) and Hα(μ, λ) for the IG distribution under progressive Type-II censoring |
 |
7. Simulation Study
A comprehensive simulation study was carried out to assess the performance of the proposed estimation methods under progressive Type-II censoring of the entropy functions given by Equations (
7) and (
8). The study was based on 1000 Monte Carlo replications. Let
n be the total sample size and
m (
) be the effective sample size after censoring. Progressive Type-II censored schemes are defined by the removal vector
, where
units are randomly removed at the
failure time. Three censoring schemes (S1, S2, and S3) were examined for different sample sizes (
) and effective sample sizes (
). The schemes are summarized in
Table 2. Two parameter settings were considered to evaluate performance under different distributional shapes: Setting I with
,
, yielding true Shannon entropy
and Rényi entropy
(at
); and Setting II with
,
, yielding true Shannon entropy
and Rényi entropy
(at
). For the Bayesian procedures, the informative priors
and
were adopted, yielding prior means of 1.5 and 2, respectively, consistent with the parameter values of Setting I. Notably, these prior means do not match the parameter values of Setting II, thereby providing an implicit robustness check: the Bayesian procedures were tested under a prior specification centered away from the true values in Setting II. The results confirmed the stability of the MCMC and importance sampling methods across both settings, reflecting the dominance of the likelihood over the prior.
In each replication, samples were generated from an IG distribution with parameters
and
using the progressive Type-II censoring algorithm presented by Balakrishnan and Sandhu [
49] as follows:
- Step 1.
Generate m independent Uniform (0,1) observations .
- Step 2.
For a chosen censoring scheme from
Table 2, set the removal vector
for
.
- Step 3.
Set for .
- Step 4.
Set for .
- Step 5.
Set for . Then, is the required progressive Type-II censored sample from the Uniform(0,1) distribution.
- Step 6.
Finally, the progressive Type-II censored sample from the IG distribution is obtained by setting , where is the inverse CDF from Equation (4), which must be solved numerically.
For the MCMC method, we ran the parameter generation chain for 10,000 iterations, discarding the first 2000 as the burn-in period. For importance sampling, we generated 5000 parameter samples and then subjected them to the specified progressive censoring scheme. For each replication, point and interval estimates were calculated. Summary measures, such as mean estimates, bias, and coverage probabilities, are obtained by averaging over the 1000 Monte Carlo runs. The simulation results are summarized in
Table 3,
Table 4 and
Table 5 as shown:
In
Table 3, Pr. MLE exhibited poor performance, with a substantial positive bias
and a high mean relative error
, showing only limited improvement as the sample size increased. In contrast, the IS, MCMC, and Lindley methods (under the GE and LINEX loss functions) produced highly accurate estimates, with low mean relative errors
and biases close to
, whereas the Lindley estimator under the SE loss function was the least efficient among these superior methods. The inferior performance of the Pr. MLE can be attributed to the Shannon entropy formula, which contains the highly sensitive term
. This term amplifies parameter estimation errors arising from the complex likelihood surface of the IG distribution. By contrast, the Bayesian methods and IS overcome this limitation by relying on the entire posterior (or sampling) distribution of the entropy rather than on a single point estimate.
In
Table 4, performance of the Pr. MLE improved considerably compared with the Shannon entropy results. It yielded a smaller negative bias
to
and an acceptable mean relative error
, with clear improvement as the sample size increased. Nevertheless, the IS, MCMC, and Lindley methods remained more accurate, achieving MRE values ranging from
to
. However, the differences among all estimation methods became less pronounced, and the performance of the different loss functions within the Lindley approach was remarkably similar. This improvement can be explained by the mathematical form of Rényi entropy, which depends on the modified Bessel function
. This function is smoother and less prone to magnifying estimation errors, while the parameter moderates the influence of variations in the ratio
, making the entropy less sensitive to parameter estimation errors.
In
Table 5, Wald-CIs consistently produced excessive coverage (with the coverage probability often reaching 1.000), but at the expense of excessively wide and impractical interval lengths. For example, the interval length reached 4.33 for Shannon entropy when
and remained approximately three to four times longer than those of the competing methods even when
. In contrast, the IS and MCMC approaches (using both equal-tail confidence intervals and HPD credible intervals) generated substantially shorter intervals (
–
for Shannon entropy when
) while maintaining coverage probabilities close to the nominal 0.95 level. The excessive width of the Wald intervals reflects the instability of the covariance matrix caused by the irregular likelihood surface. In comparison, the simulation-based methods produce more efficient interval estimates because they are constructed from the full empirical distribution of the entropy, thereby capturing the dependence structure between the model parameters. It is also noteworthy that the interval lengths for Rényi entropy were consistently shorter than those for Shannon entropy across all methods, further confirming the greater numerical stability of the Rényi entropy formulation.
In
Table 6, Pr. MLE exhibited a positive bias ranging from 0.74 to 0.90 and a mean relative error between 0.49 and 0.58, both of which were higher than those observed under the first set of simulation settings. The Lindley method showed some variability in performance, with relatively large mean squared error values at small sample sizes, particularly under Scenario S1, although its accuracy improved noticeably as the sample size increased. In contrast, the IS and MCMC methods produced more accurate estimates, with mean relative errors ranging from 0.067 to 0.12 and biases closer to
, while maintaining stable performance across all simulation scenarios.
In
Table 7, Pr. MLE performed relatively better than it did for Shannon entropy, yielding a negative bias ranging from −0.015 to −0.126 and a mean relative error between 0.077 and 0.207. The stability issues observed for the Lindley method were limited to the SE loss function at small sample sizes, whereas the performance of the different loss functions became increasingly similar as the sample size grew. The IS and MCMC methods maintained consistently stable performance, with mean relative errors ranging from 0.068 to 0.113 and no notable outlying values.
In
Table 8, for Shannon entropy, the Wald-CIs were relatively wide, and their coverage probability declined as the sample size increased, reaching as low as 0.500 in some scenarios. In contrast, the Wald-CIs for Rényi entropy maintained relatively high coverage probabilities but remained wider than the corresponding intervals produced by the competing methods. The IS and MCMC interval estimators achieved coverage probabilities close to the nominal level in most cases while producing considerably shorter intervals than the Wald-CIs, although slight reductions in coverage were observed for certain sample sizes. Overall, the interval estimation results for Rényi entropy were more stable than those for Shannon entropy across all estimation methods.
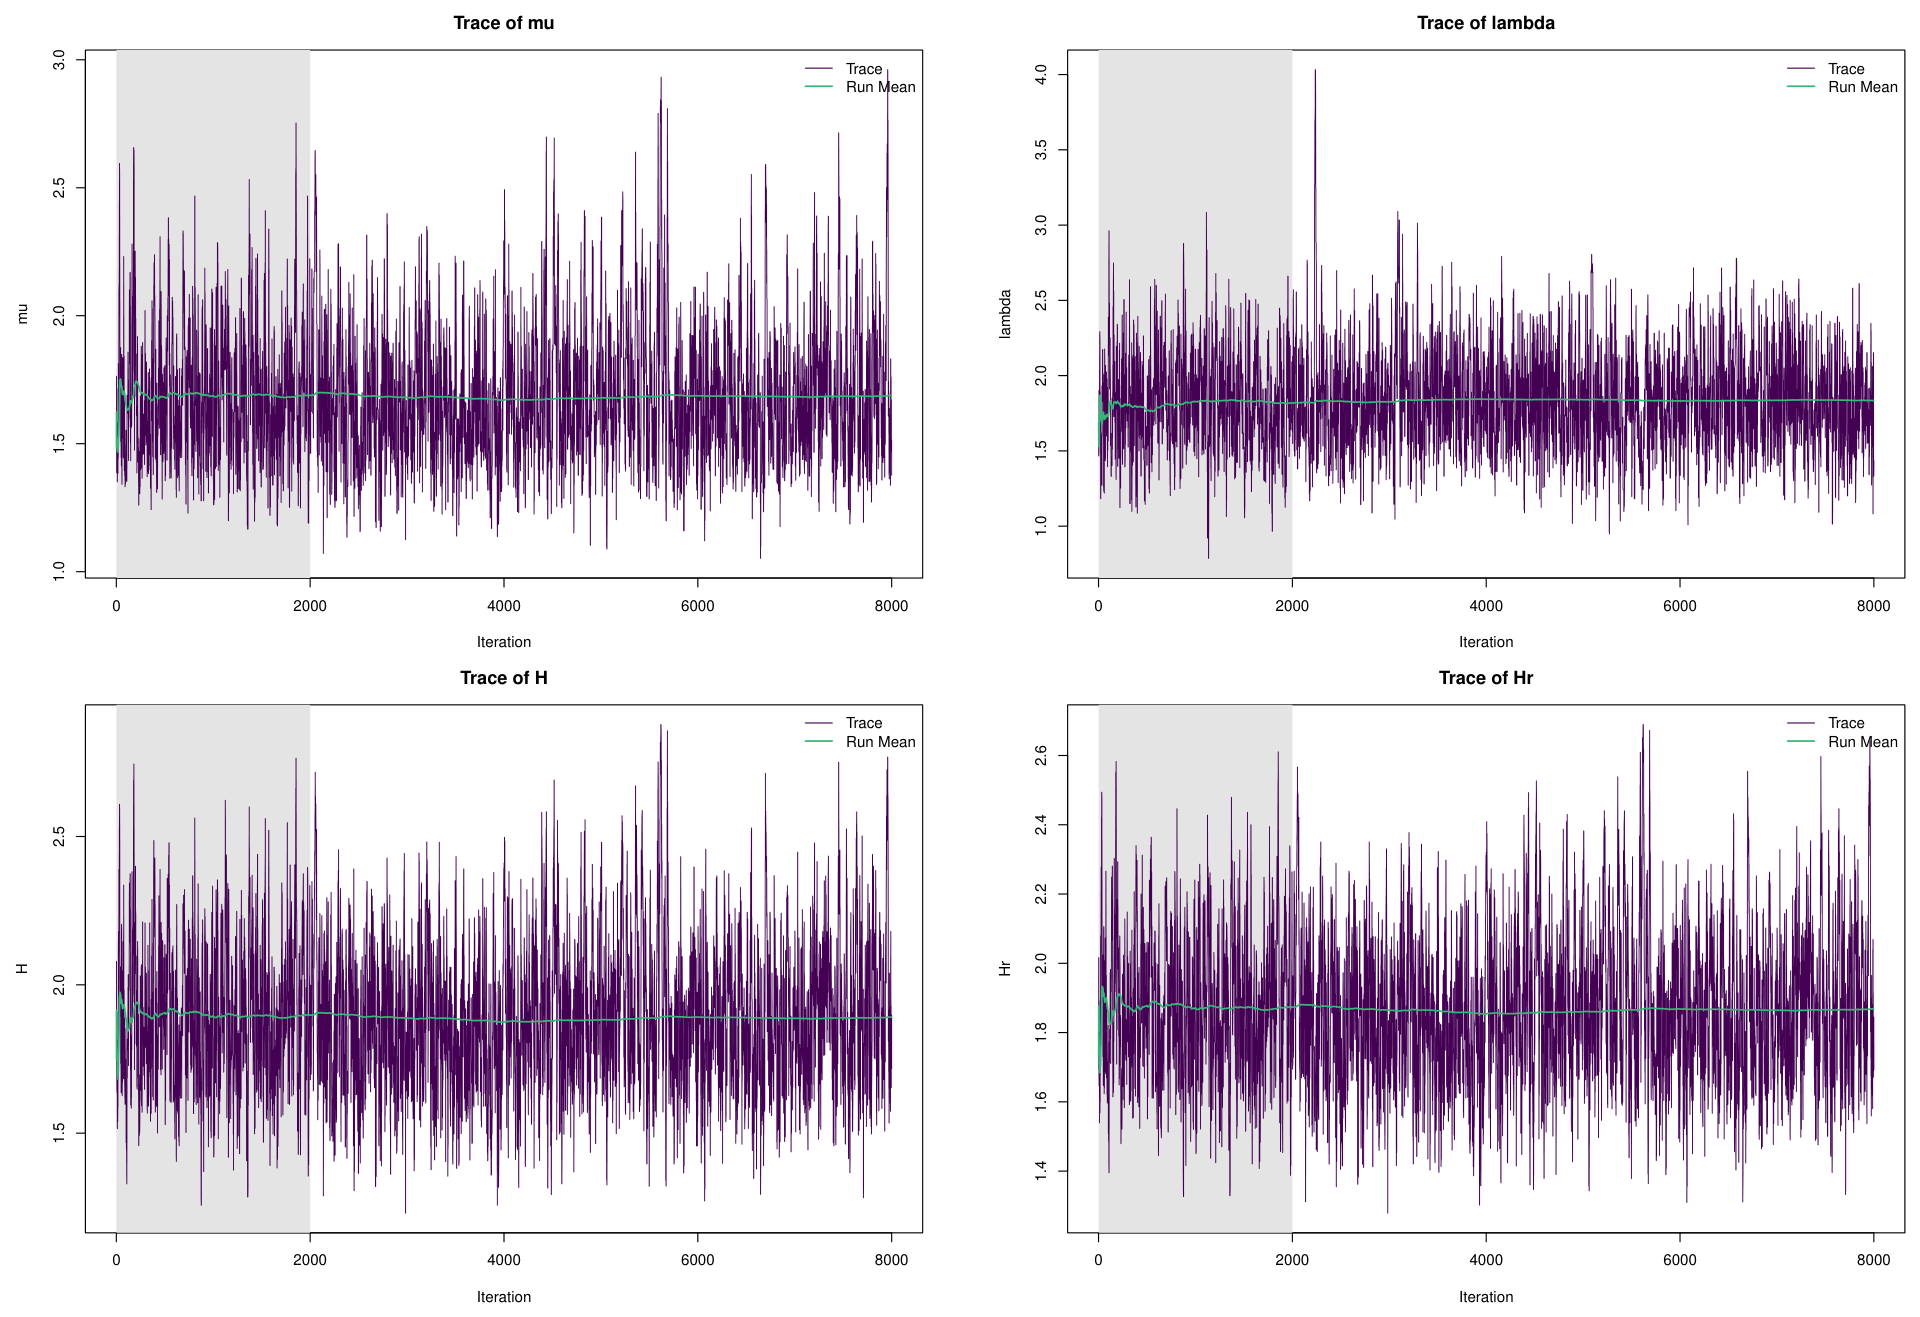
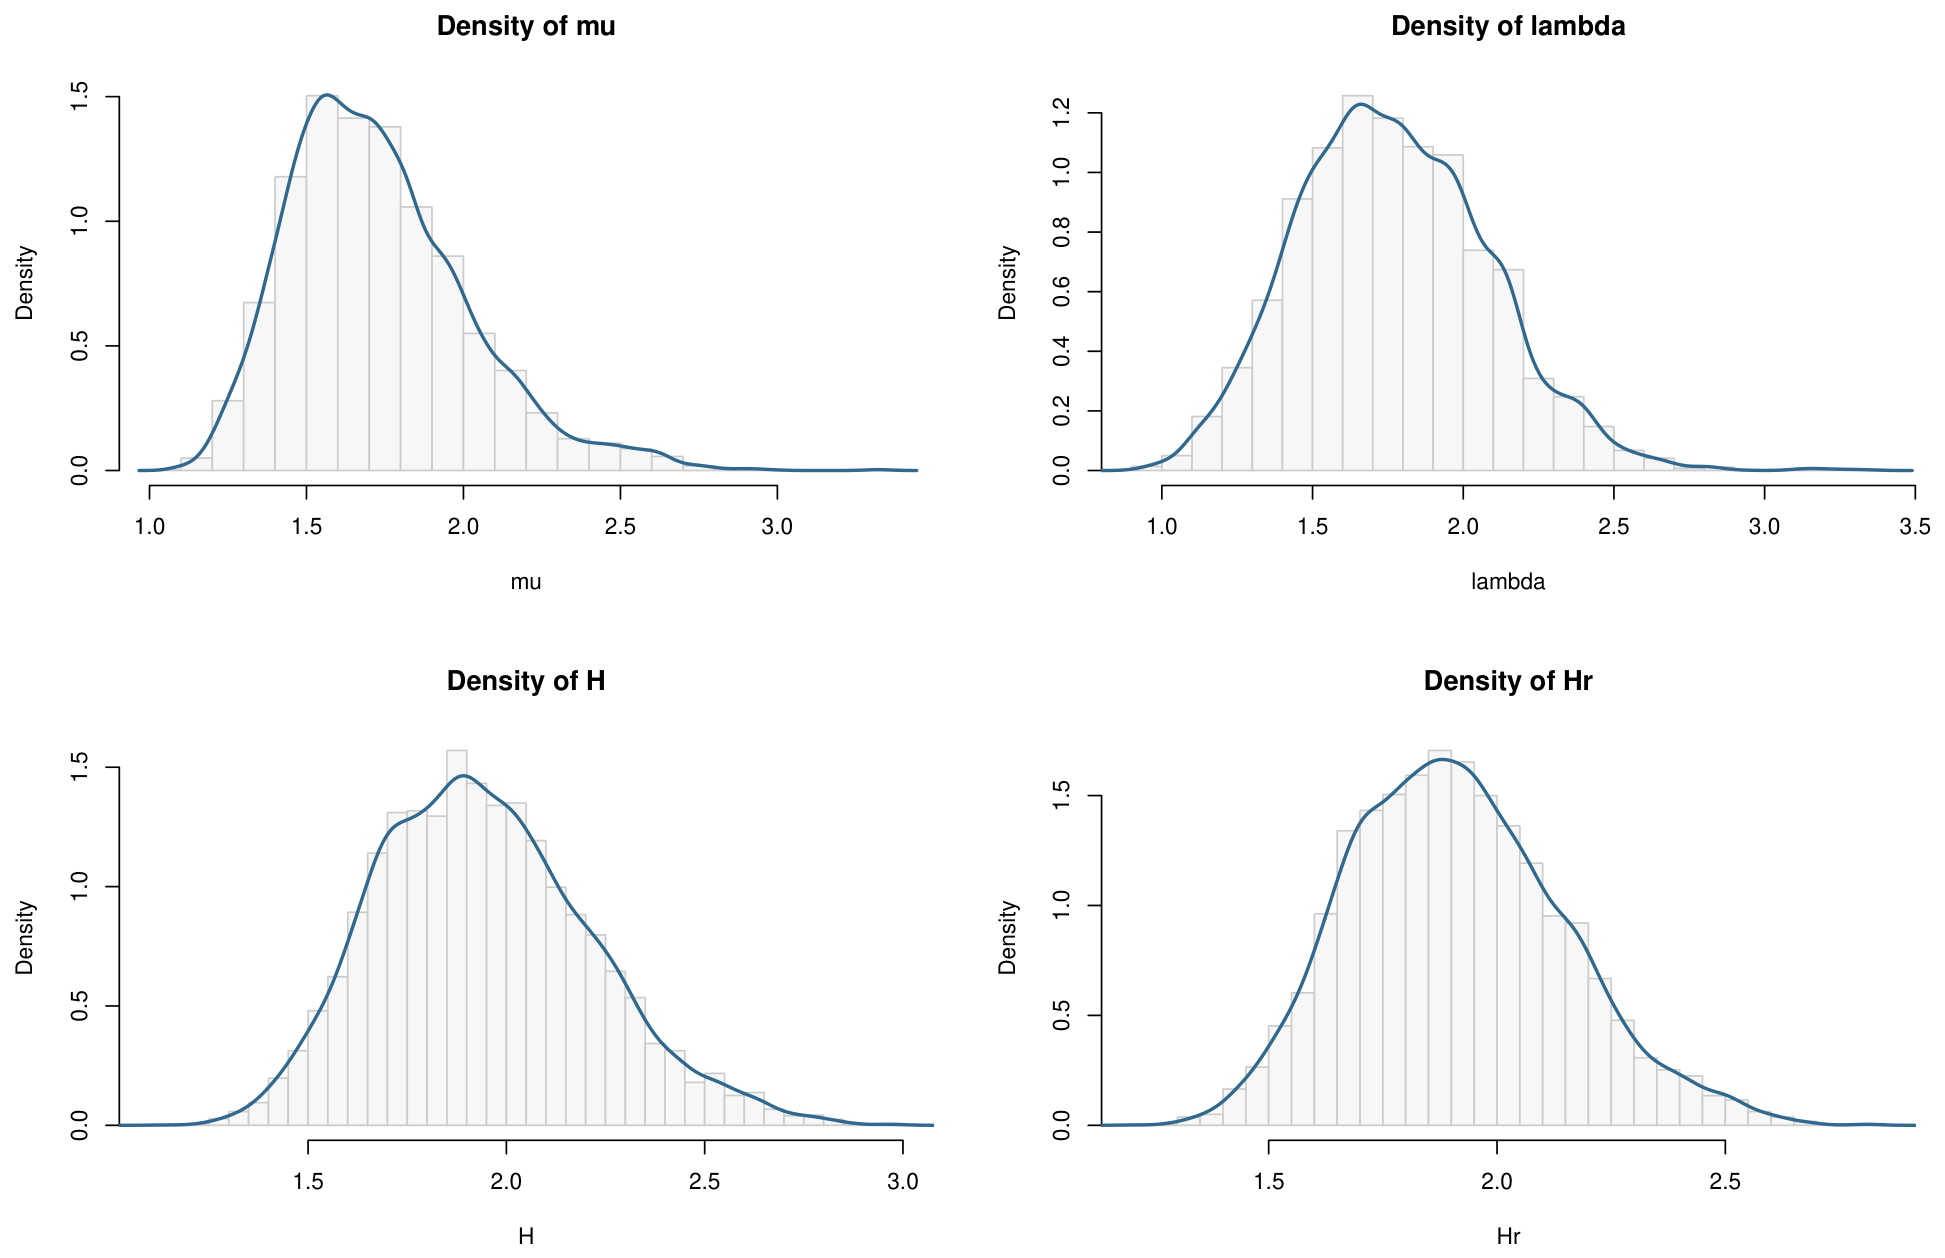
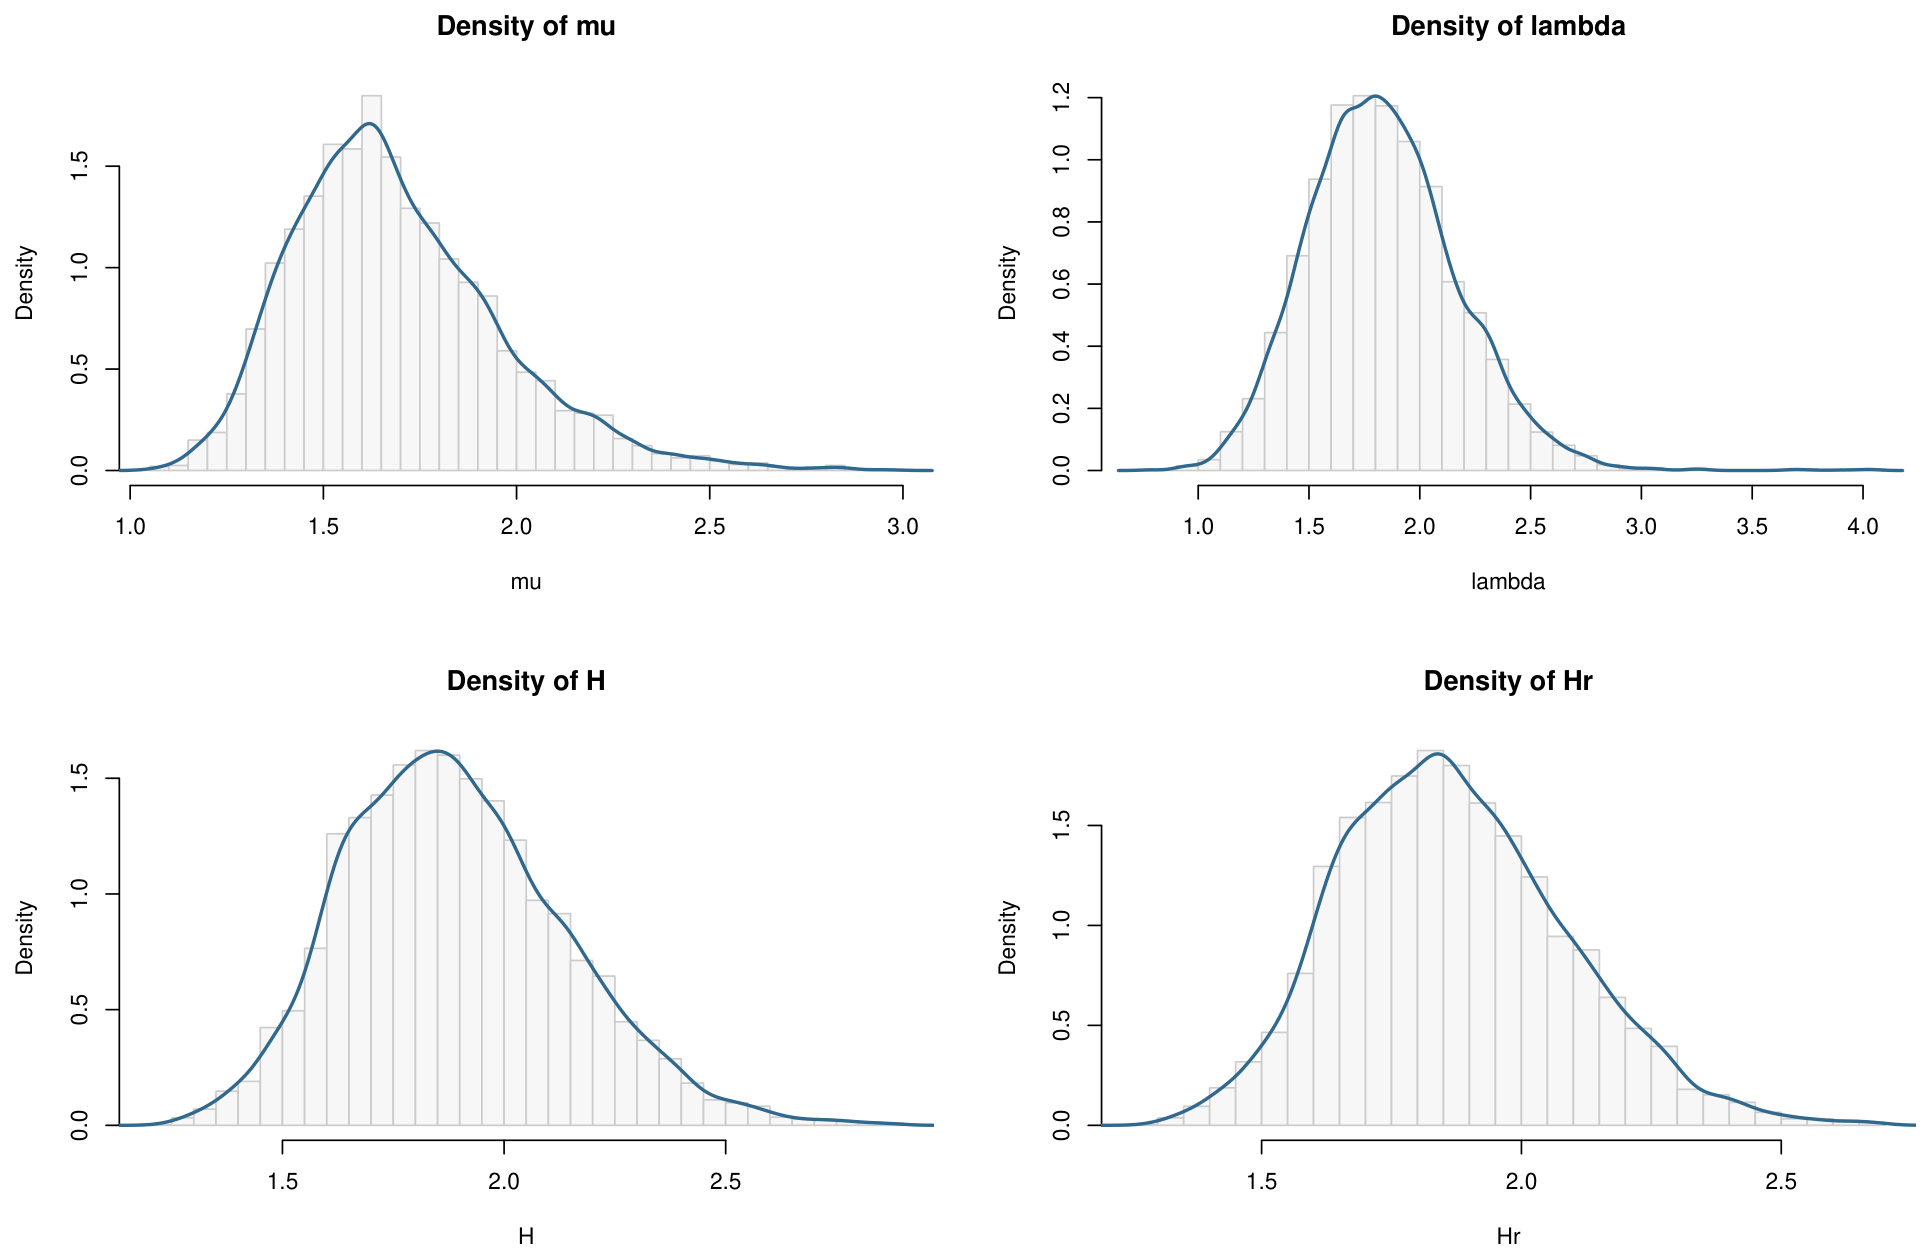
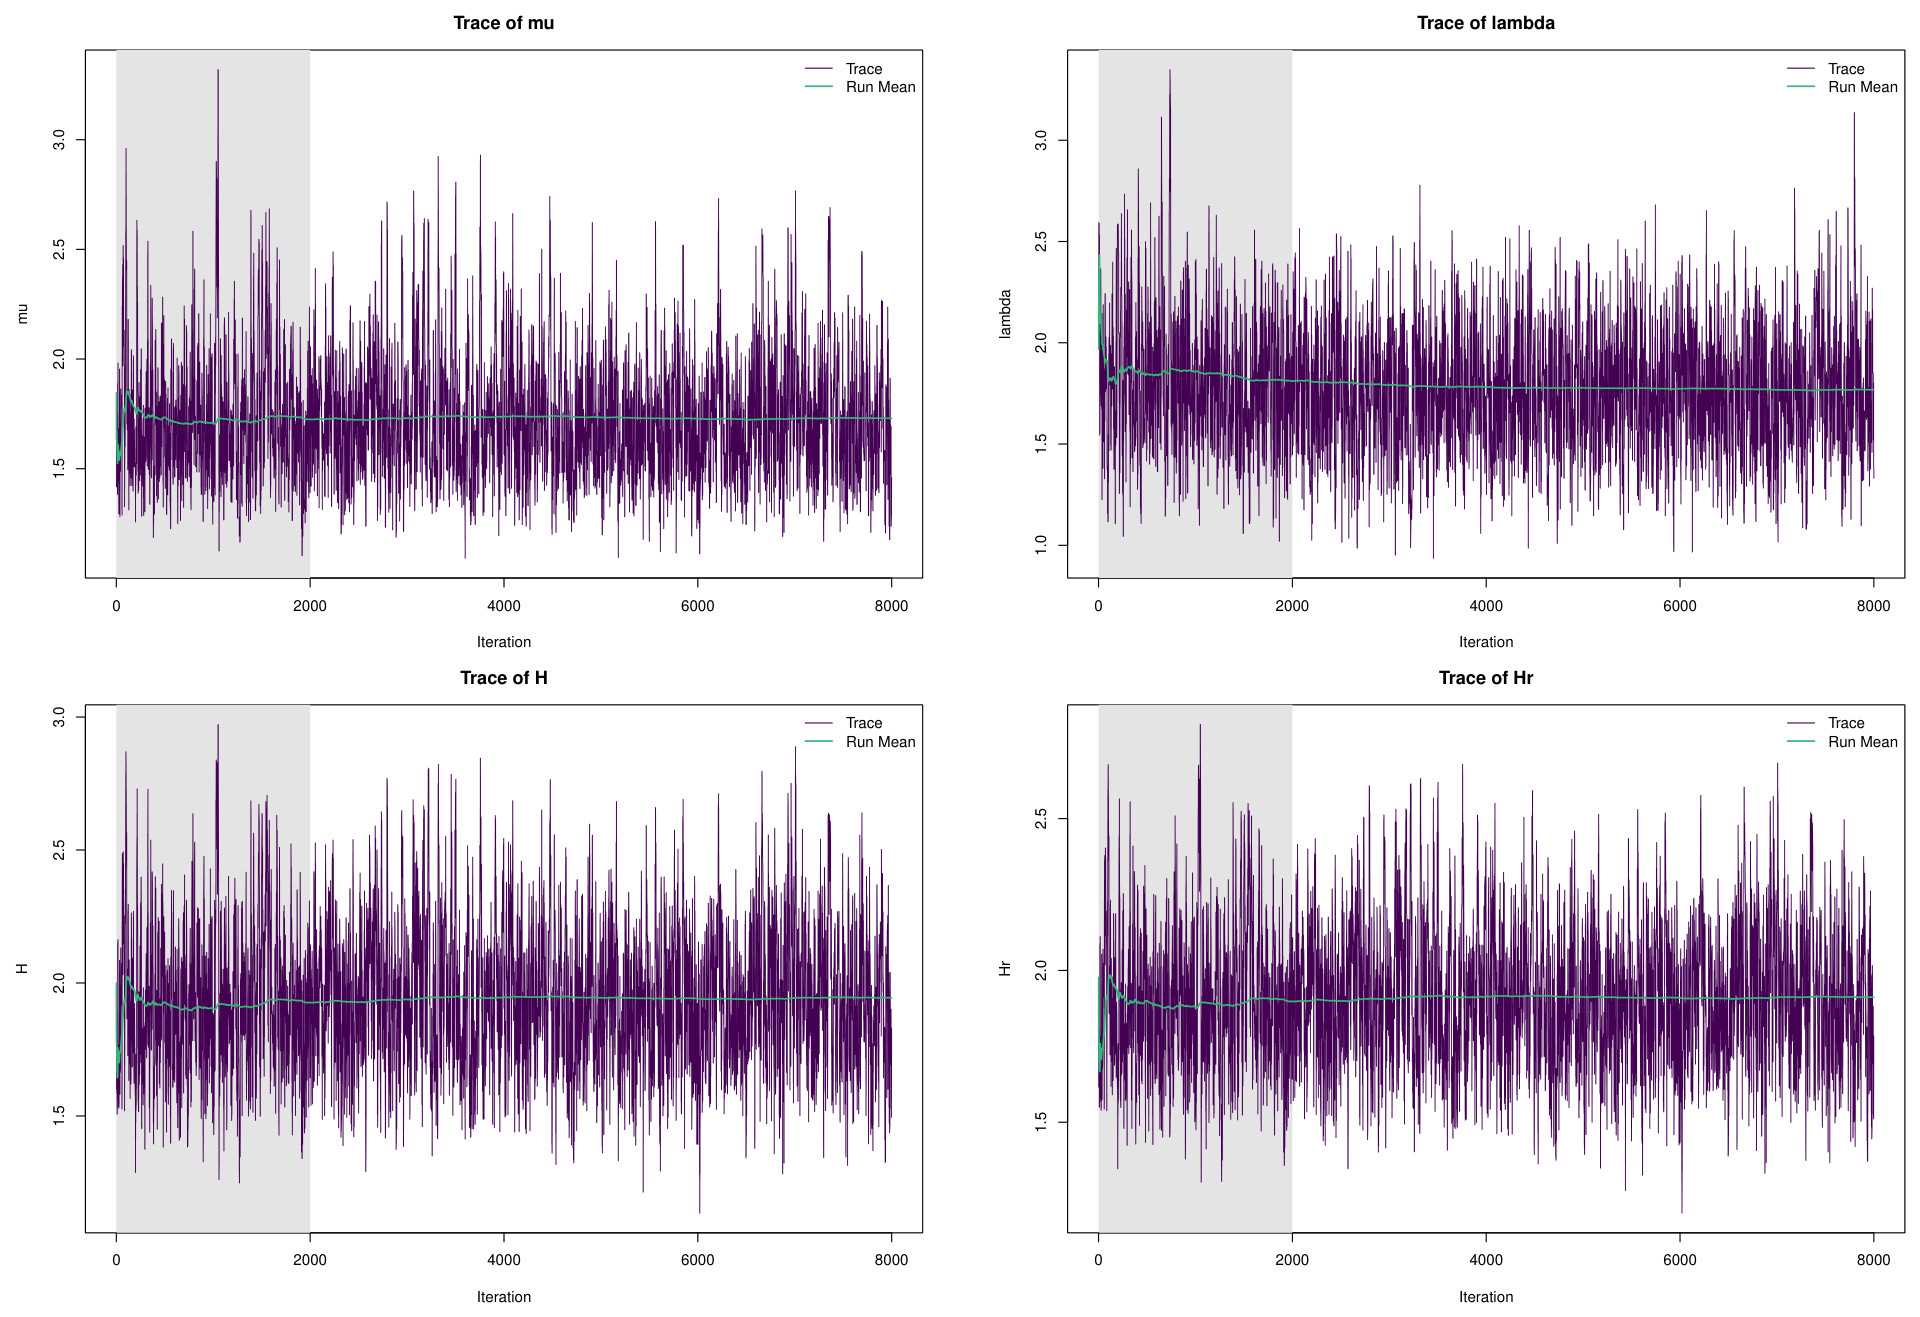
The results of
Figure 2,
Figure 3,
Figure 4 and
Figure 5 show the effectiveness of the MCMC approach for a variety of parameters and entropy measures settings. This suggests that the MCMC approach is a powerful and reliable method to sample complex distributions.
8. Real Data
Across both Dataset I and Dataset II, the IG distribution consistently demonstrated superior performance compared to the following distributions based on both the AIC criterion and the Kolmogorov–Smirnov goodness-of-fit test results; Epanechnikov–Weibull (EpW) distribution; Perks (Perk) distribution; Gompertz–Lindley (GomLin) distribution; Gamma (Gam) distribution; Power Muth (PMuth) distribution; Chen distribution; Type-II Heavy-Tailed Weibull (T2HTW) distribution; Generalized Exponential (GExp) distribution; Power Lindley (PLin) and Weibull (W) distribution; and Power Rayleigh (PRay) distribution.
8.1. Data Set I
The dataset consists of the follow-up times (in months) for 35 children undergoing growth hormone therapy, measured from the initiation of treatment until reaching the targeted developmental age: 2.15, 2.20, 2.55, 2.56, 2.63, 2.74, 2.81, 2.90, 3.05, 3.41, 3.43, 3.43, 3.84, 4.16, 4.18, 4.36, 4.42, 4.51, 4.60, 4.61, 4.75, 5.03, 5.10, 5.44, 5.90, 5.96, 6.77, 7.82, 8.00, 8.16, 8.21, 8.72, 10.40, 13.20, 13.70. Data were obtained from the Minas Gerais Health Secretariat Hormonal Program, Brazil, and were previously used in a published study to apply new statistical distributions in biomedical and epidemiological contexts [
50].
Table 9 presents parameter and entropy estimates under different removal scenarios. With complete data, the results are automatically identical. It is observed that removal from the beginning or middle of the data affects the estimates to a greater extent than removal from the end, particularly at higher deletion rates, as reflected in the variation in Shannon entropy values and the widening of confidence intervals for the parameter
. These results suggest that the impact of data removal depends not only on the deletion rate but also on the position of the removed values, which should be taken into account when dealing with incomplete data.
Table 10 shows that the IG distribution achieves the lowest information criterion values (AIC = 153.96, BIC = 157.53) and the highest
p-values for the goodness-of-fit tests (AD
p = 0.987, KS
p = 0.979), indicating a better fit to the data. It is followed by GomLin, while the Chen and PMuth distributions show the weakest performance. The information criteria and goodness-of-fit tests agree on the ranking of distributions without contradiction, with a clear gap between IG and its closest competitor.
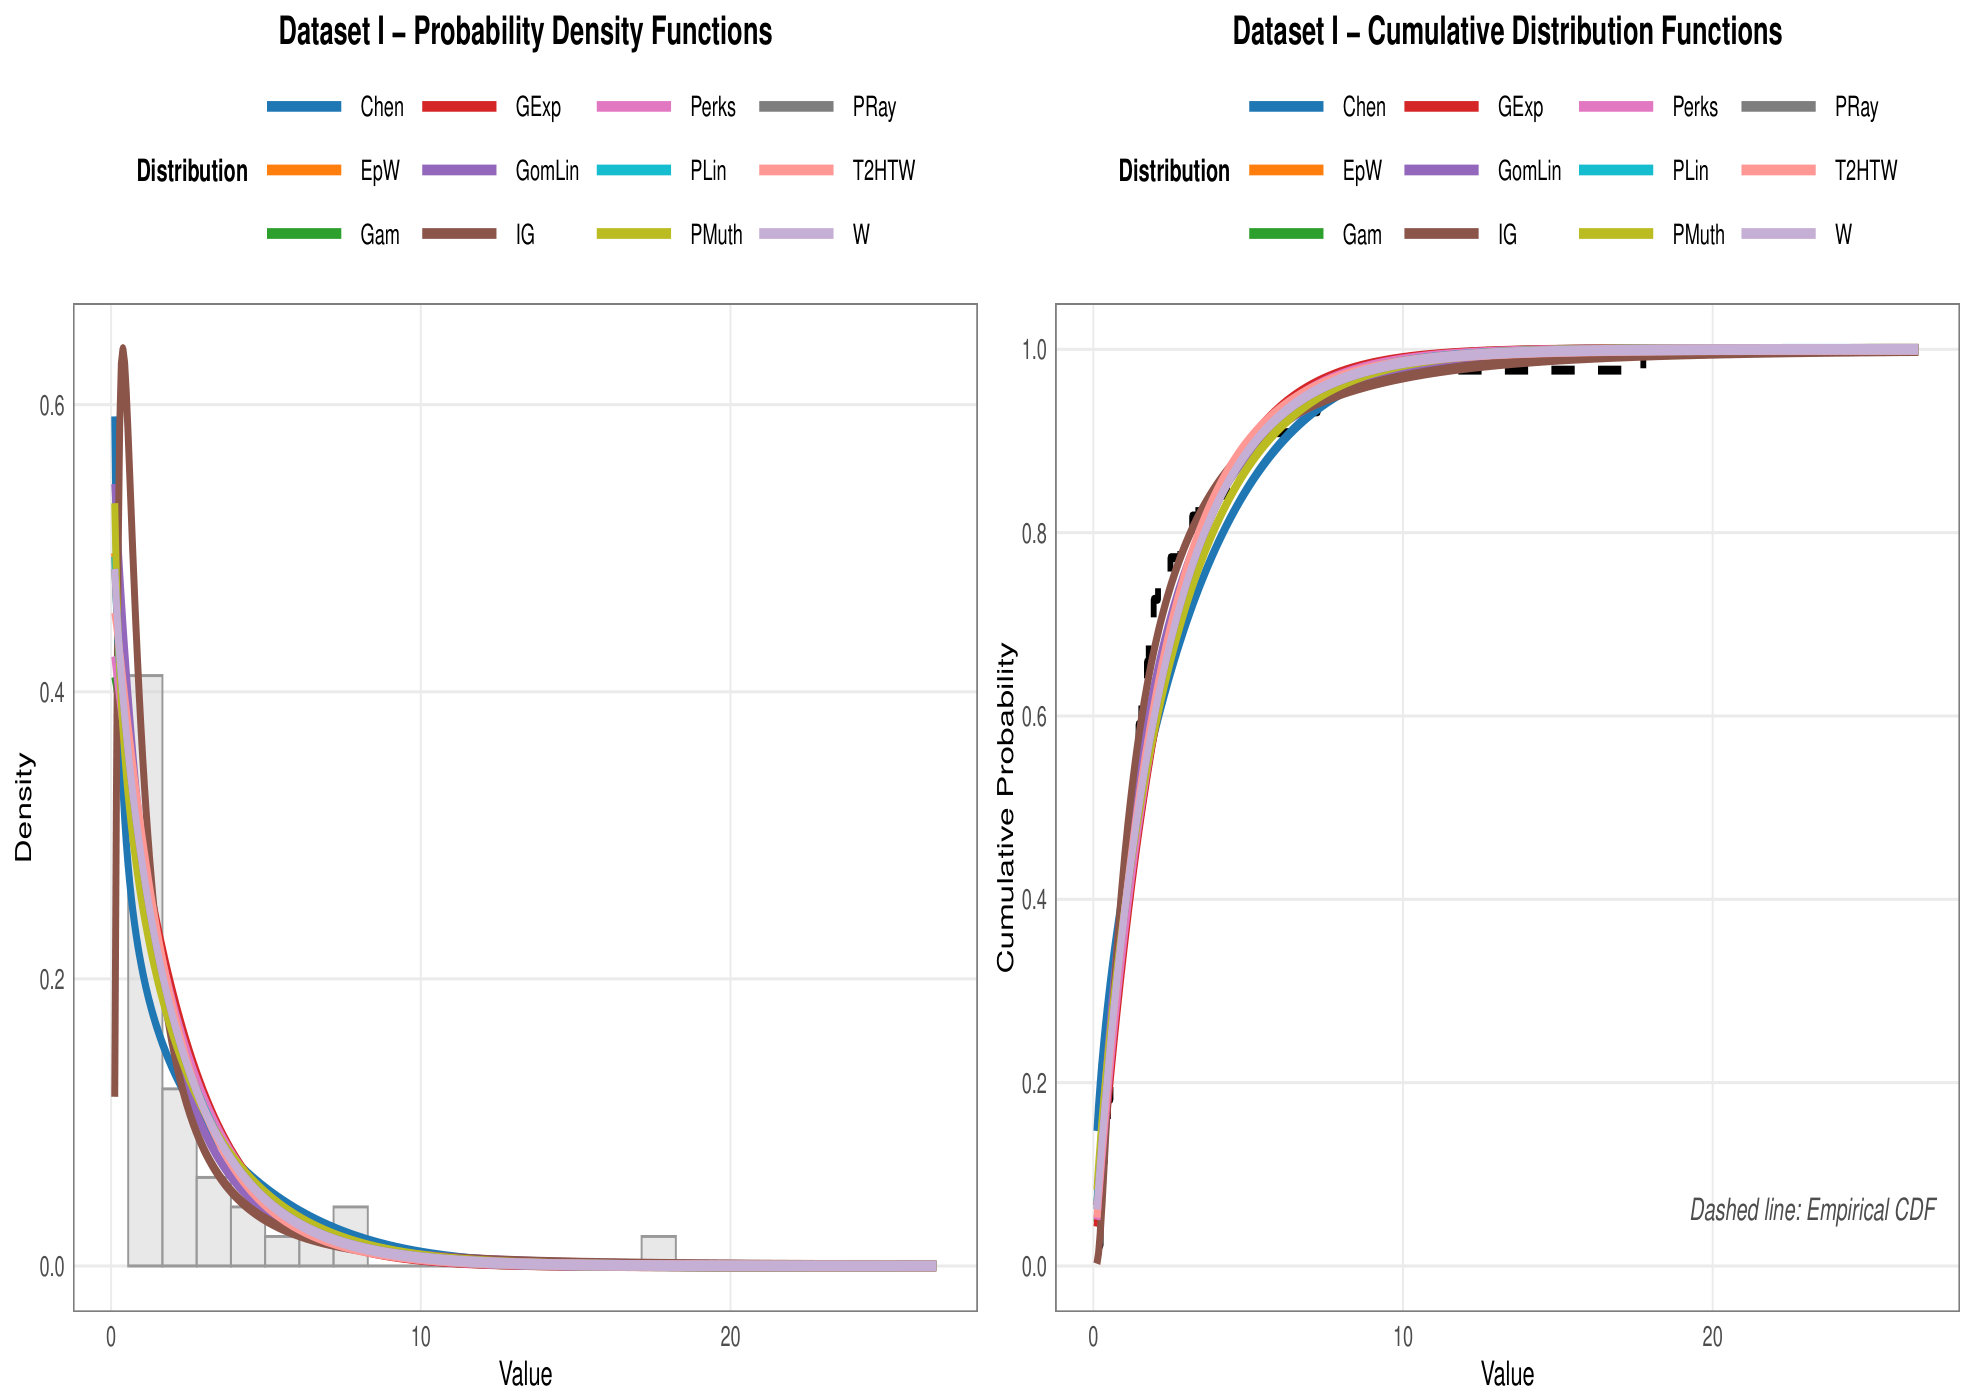
Figure 6 provides a comprehensive comparison of all distributions in terms of probability density and cumulative distribution functions. Most curves converge around the lower values, but differences appear in the upper tail of the data, where the IG distribution maintains a better representation of the general behavior compared to distributions that deviate from the empirical histogram.
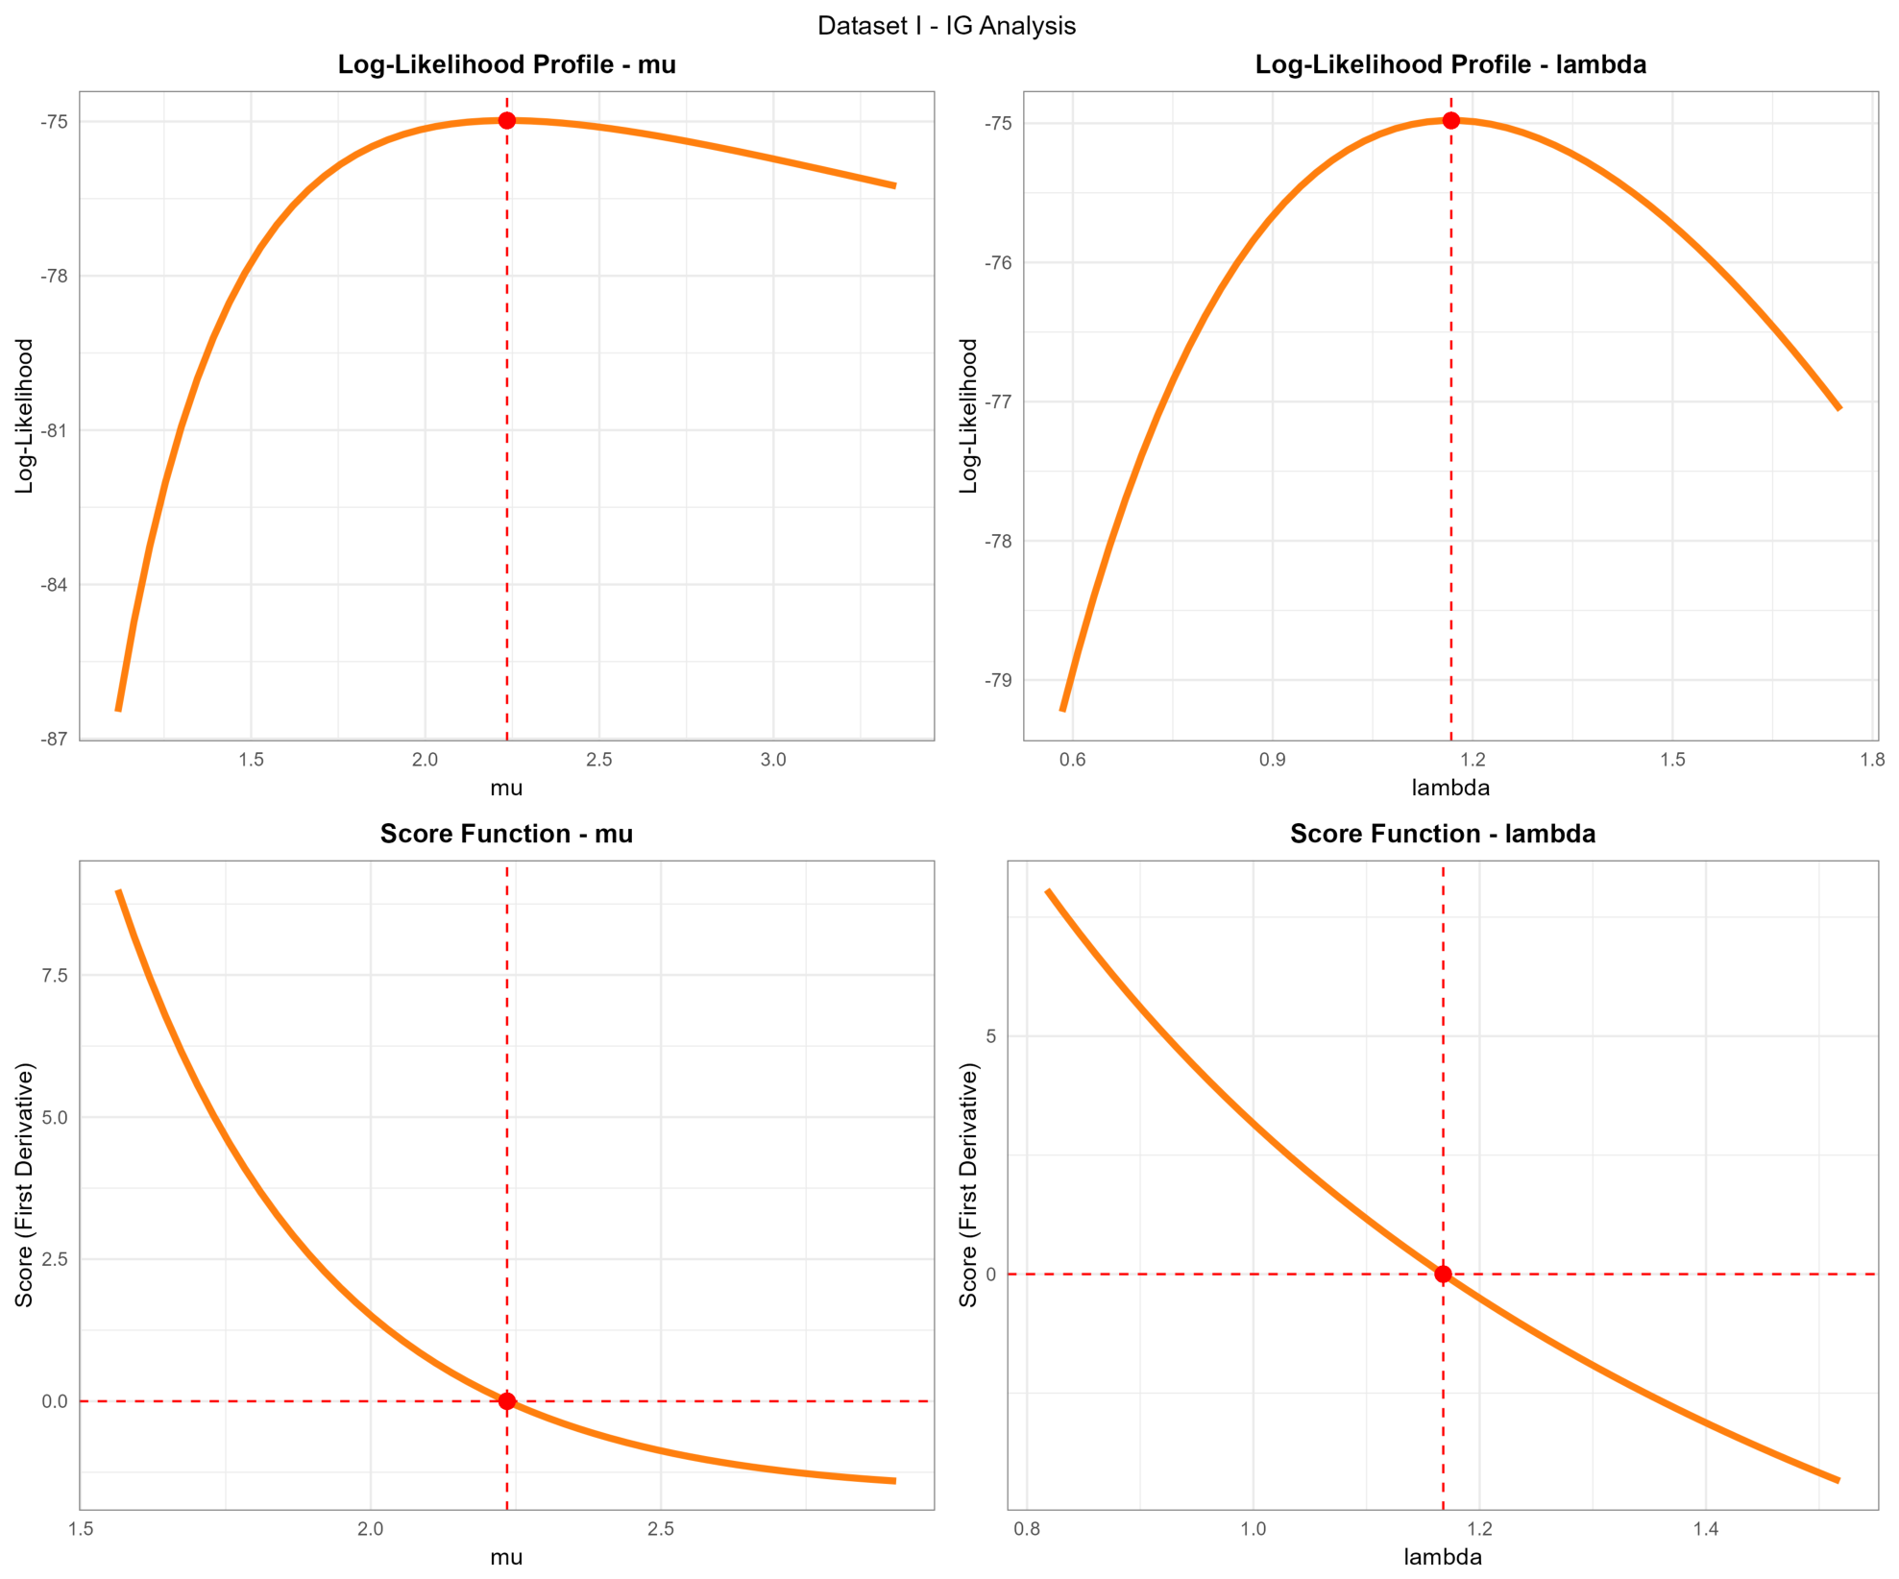
Figure 7 displays the parameter estimation for the IG distribution via MLE. The top plots show a convex logarithmic likelihood profile, while the bottom plots present the score function intersecting
, confirming that the values chosen for the parameters
and
are the optimal estimates.
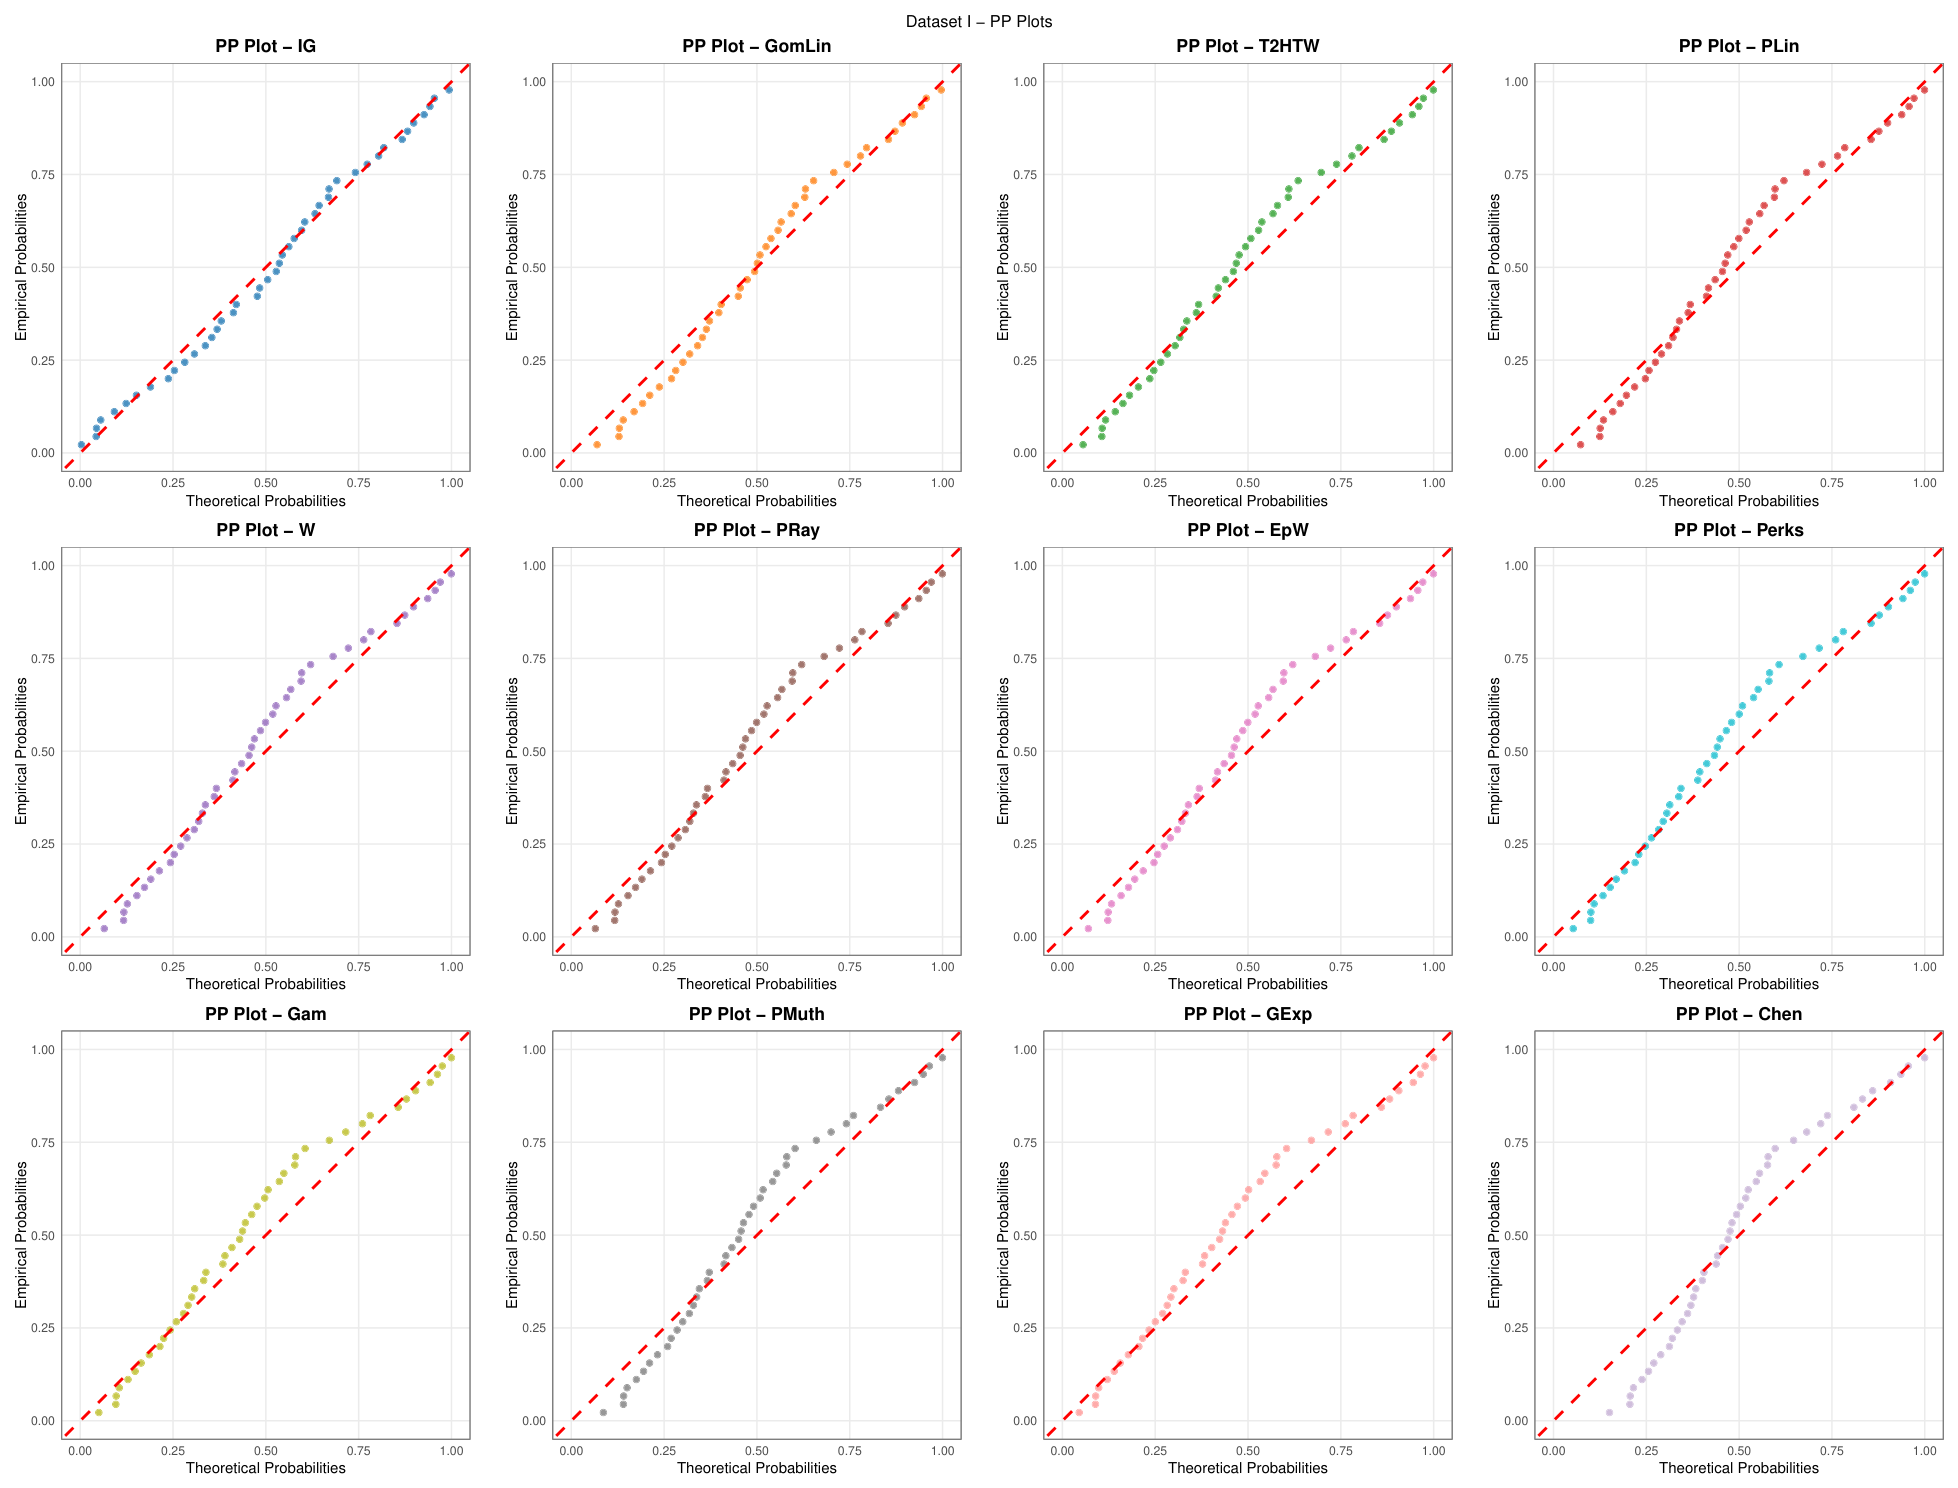
Figure 8 compares empirical probabilities against theoretical probabilities for 12 distributions. The IG distribution exhibits close alignment with the red diagonal line, whereas other distributions, such as Chen and Plin, show noticeable deviation. These results indicate that the IG distribution provides a better fit for the data compared to the other models.
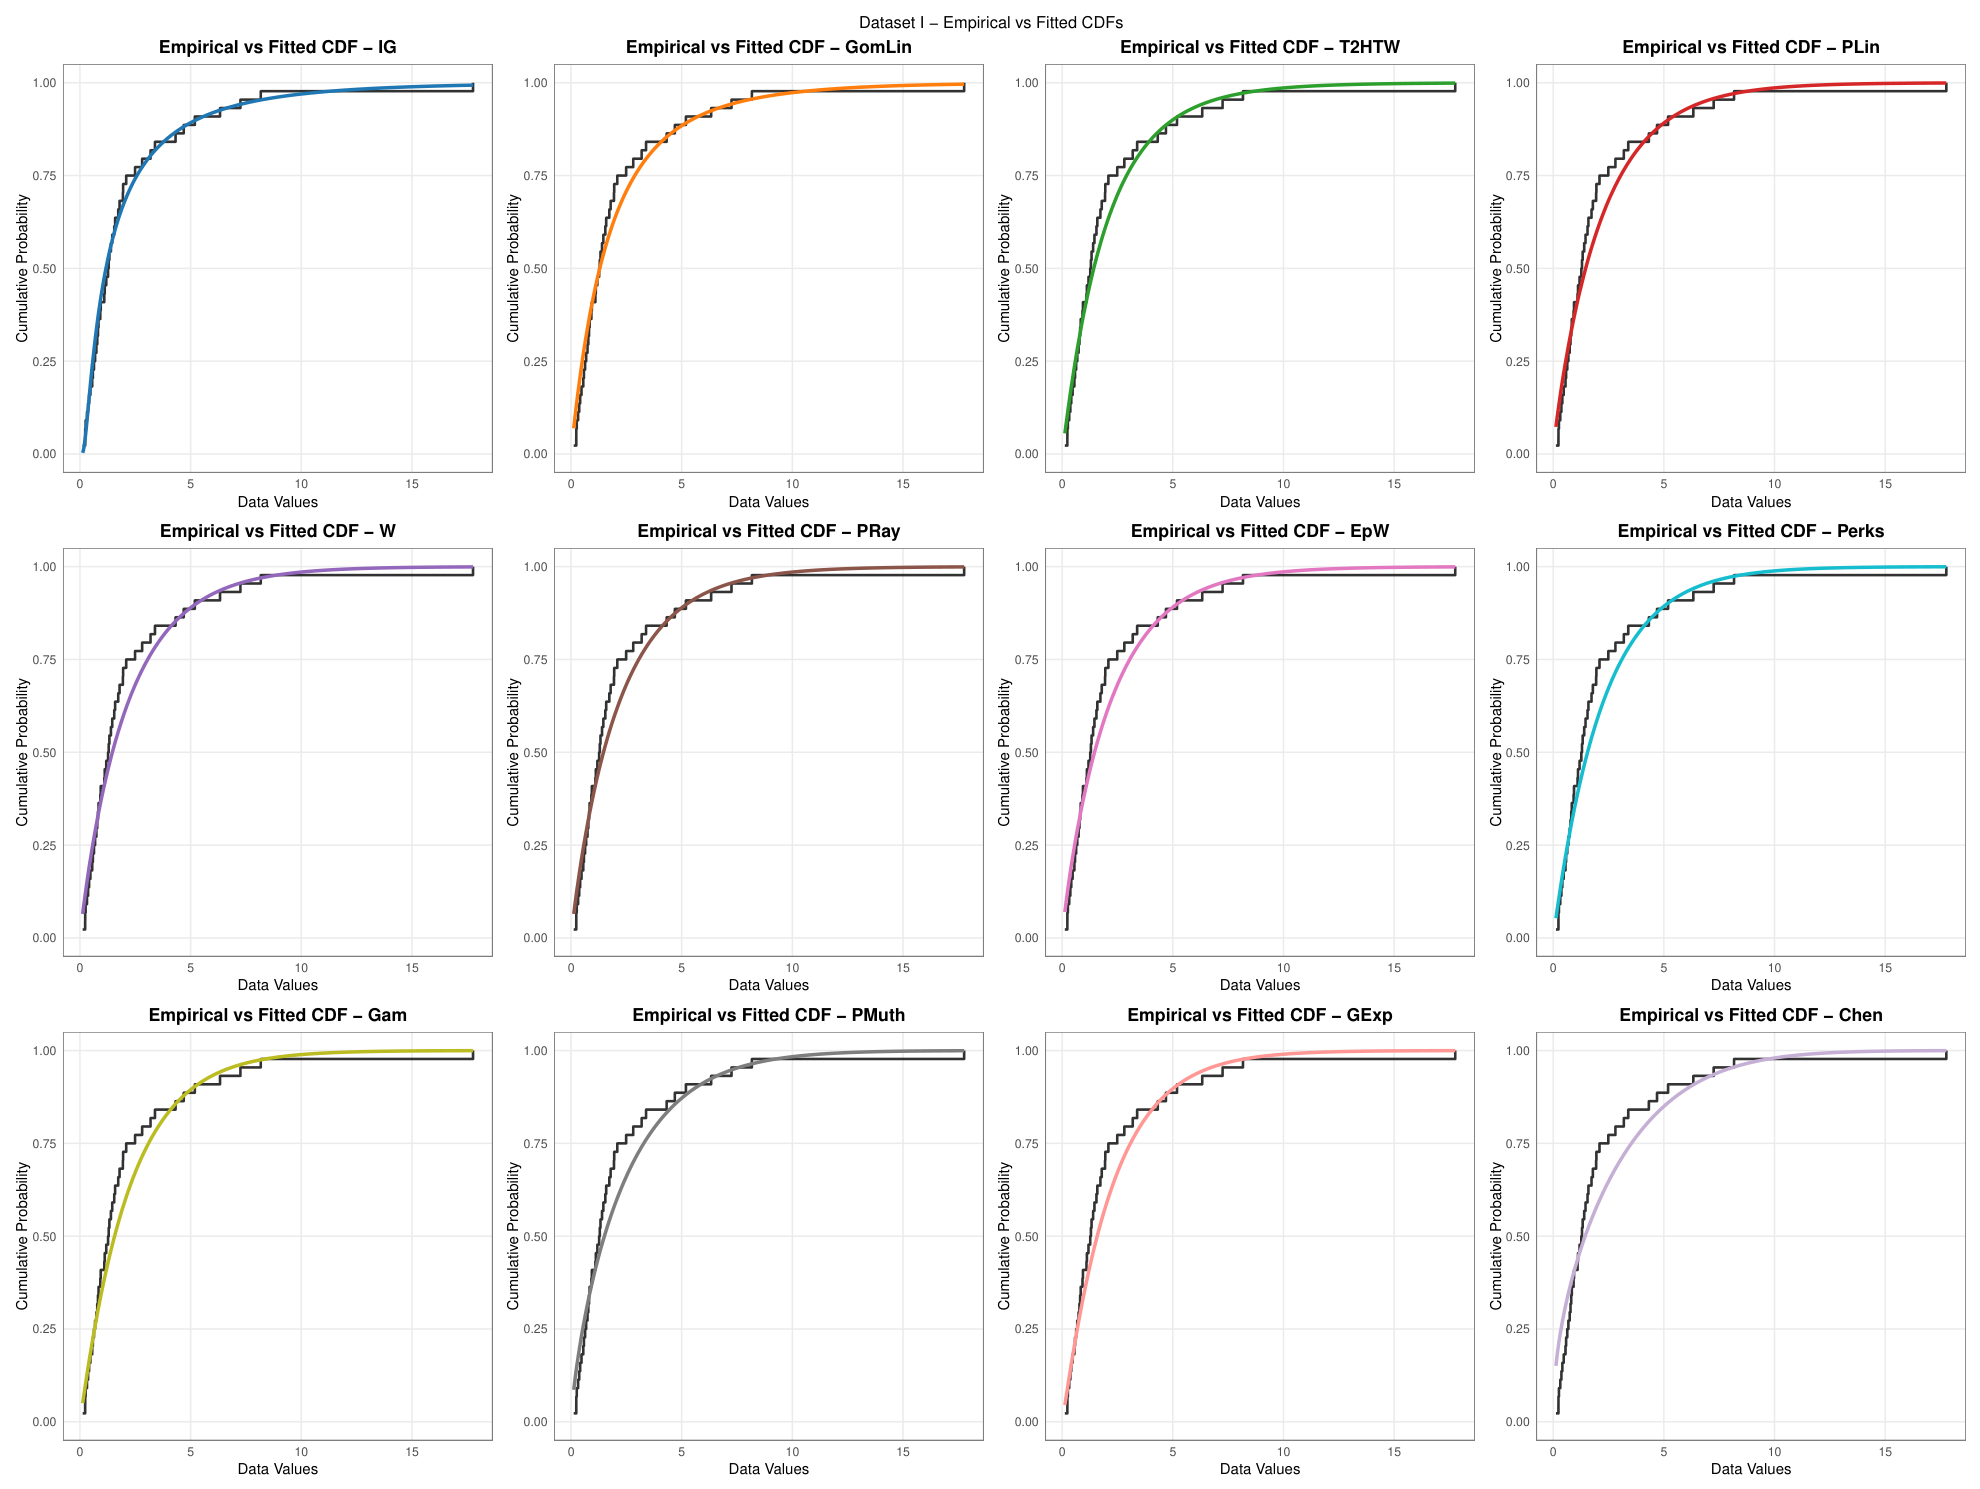
Figure 9 compares the empirical cumulative distribution function (black stepped line) with the theoretical functions of various distributions. Good agreement is observed for the IG and GomLin distributions with the empirical data, while other distributions show deviation in the tail regions, supporting the quality of the IG distribution in representing the cumulative structure of the data.
8.2. Data Set II
This dataset represents the survival times (in days) of 44 patients with Head and Neck Cancer (HNC) who underwent a combined radiation therapy and chemotherapy treatment regimen. 0.1220, 0.2356, 0.2374, 0.2587, 0.3198, 0.3700, 0.4135, 0.4738, 0.5546, 0.5836, 0.6347, 0.6846, 0.7447, 0.7826, 0.8143, 0.8400, 0.9200, 0.9400, 1.1000, 1.1200, 1.1900, 1.2700, 1.3000, 1.3300, 1.4000, 1.4600, 1.5500, 1.5900, 1.7300, 1.7900, 1.9400, 1.9500, 2.0900, 2.4900, 2.8100, 3.1900, 3.3900, 4.3200, 4.6900, 5.1900, 6.3300, 7.2500, 8.1700, 17.7600, showing a classic right-skewed distribution common in survival analysis, where most events occur early but a long tail extends to the right. Such data are typically modeled using heavy-tailed probability distributions (like the ZLindley or generalized Weibull models mentioned in the titles) to accurately capture the risk of mortality over time and to assess the efficacy of the simultaneous treatment protocol.
Table 11 presents parameter and entropy estimates under different removal scenarios. With complete data, the results are automatically identical. It is evident that removal from the middle (S2) and beginning (S3) affects estimates to a greater extent than removal from the end (S1), particularly at higher deletion rates, as reflected in the variation in Shannon entropy values and the widening of confidence intervals for the parameter
. This pattern is consistent with what was observed for the growth hormone data, confirming that the impact of data removal depends on the position of the removed values and not only on the deletion rate. This should be taken into account when dealing with incomplete data.
Table 12 summarizes the comparative performance of the candidate probability distributions fitted to Dataset II. Among the competing models, the IG distribution consistently provides the best fit, as evidenced by the smallest information criteria (AIC = 160.38 and BIC = 163.49) and the largest goodness-of-fit
p-values (AD
p = 0.87, CvM
p = 0.84, and KS
p = 0.93). These findings identify the IG distribution as the most suitable model for Dataset II. The GExp and Gam distributions rank next in terms of model adequacy, whereas the Chen and PMuth distributions provide comparatively poorer fits. All criteria and tests agree on the ranking of distributions without contradiction, reinforcing confidence in the adoption of IG for modeling.
To avoid digression,
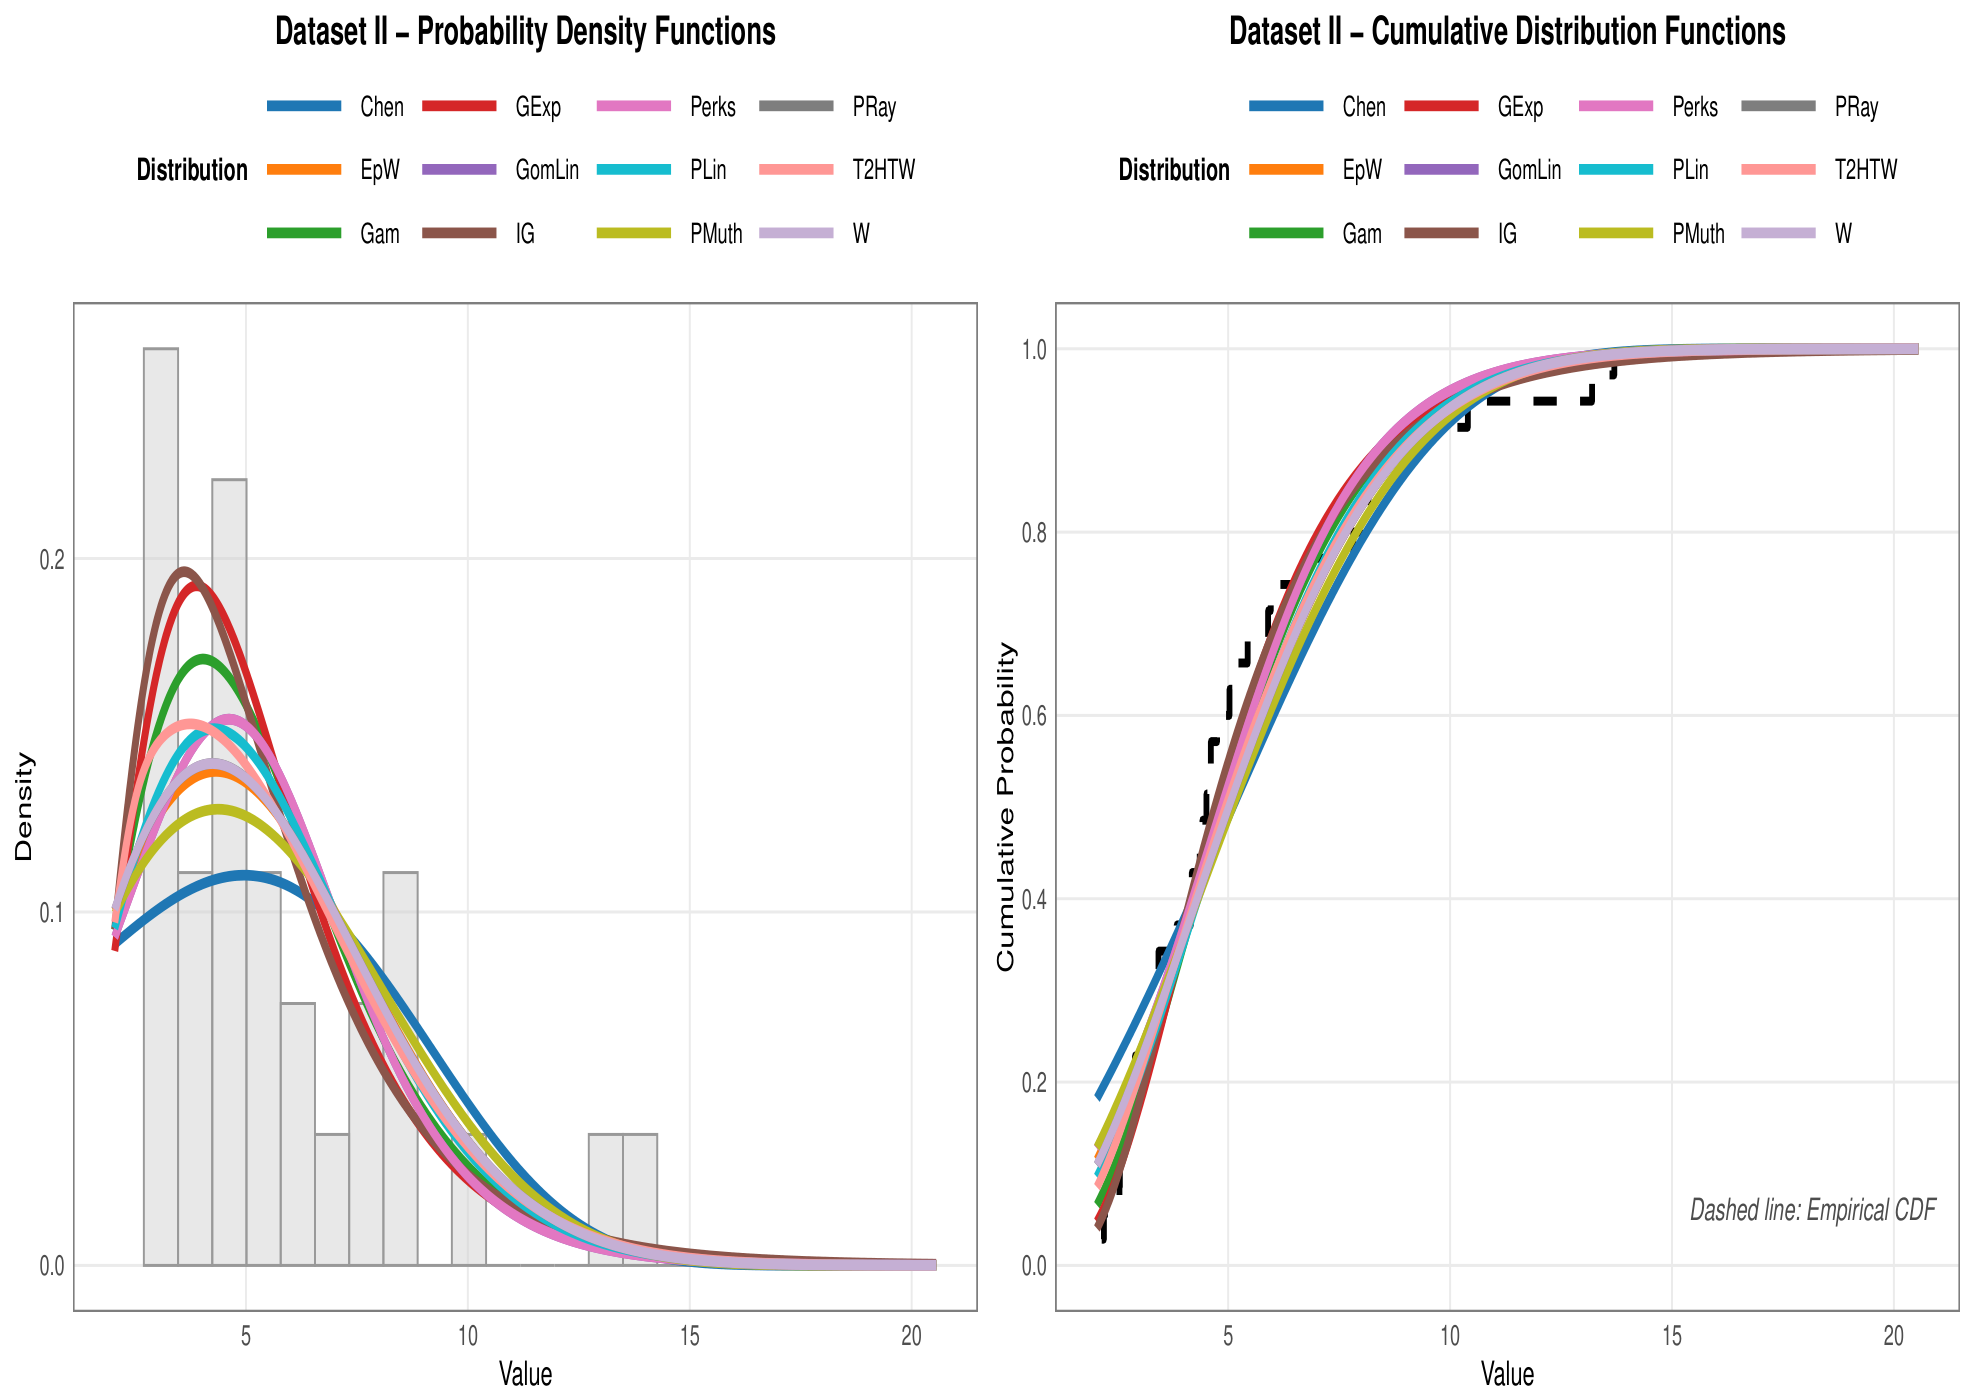
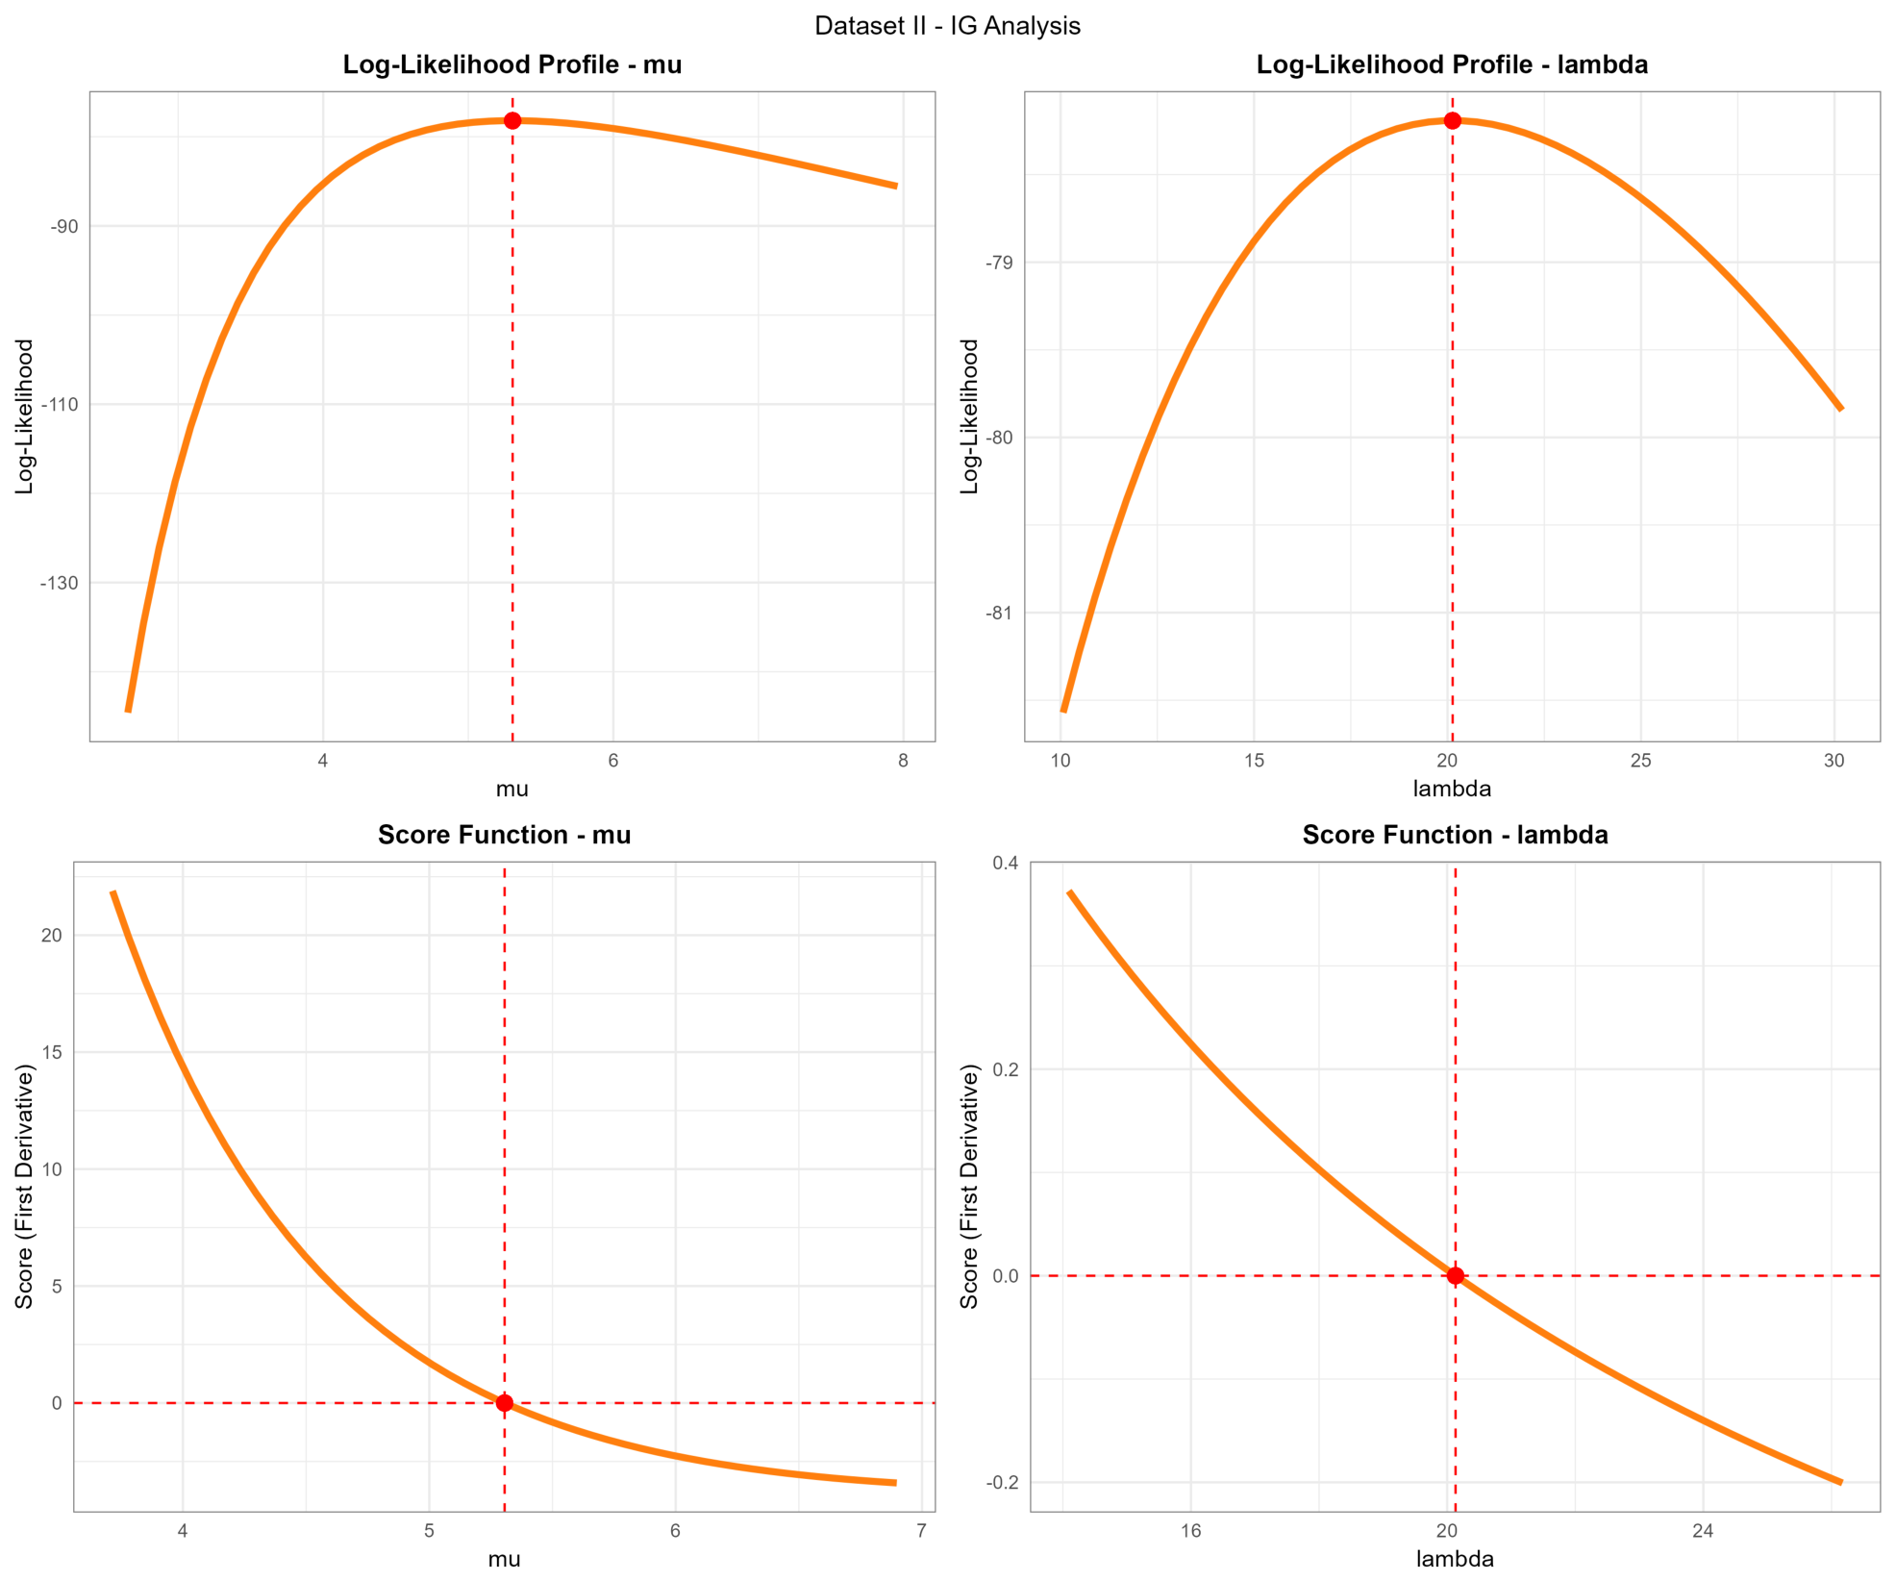
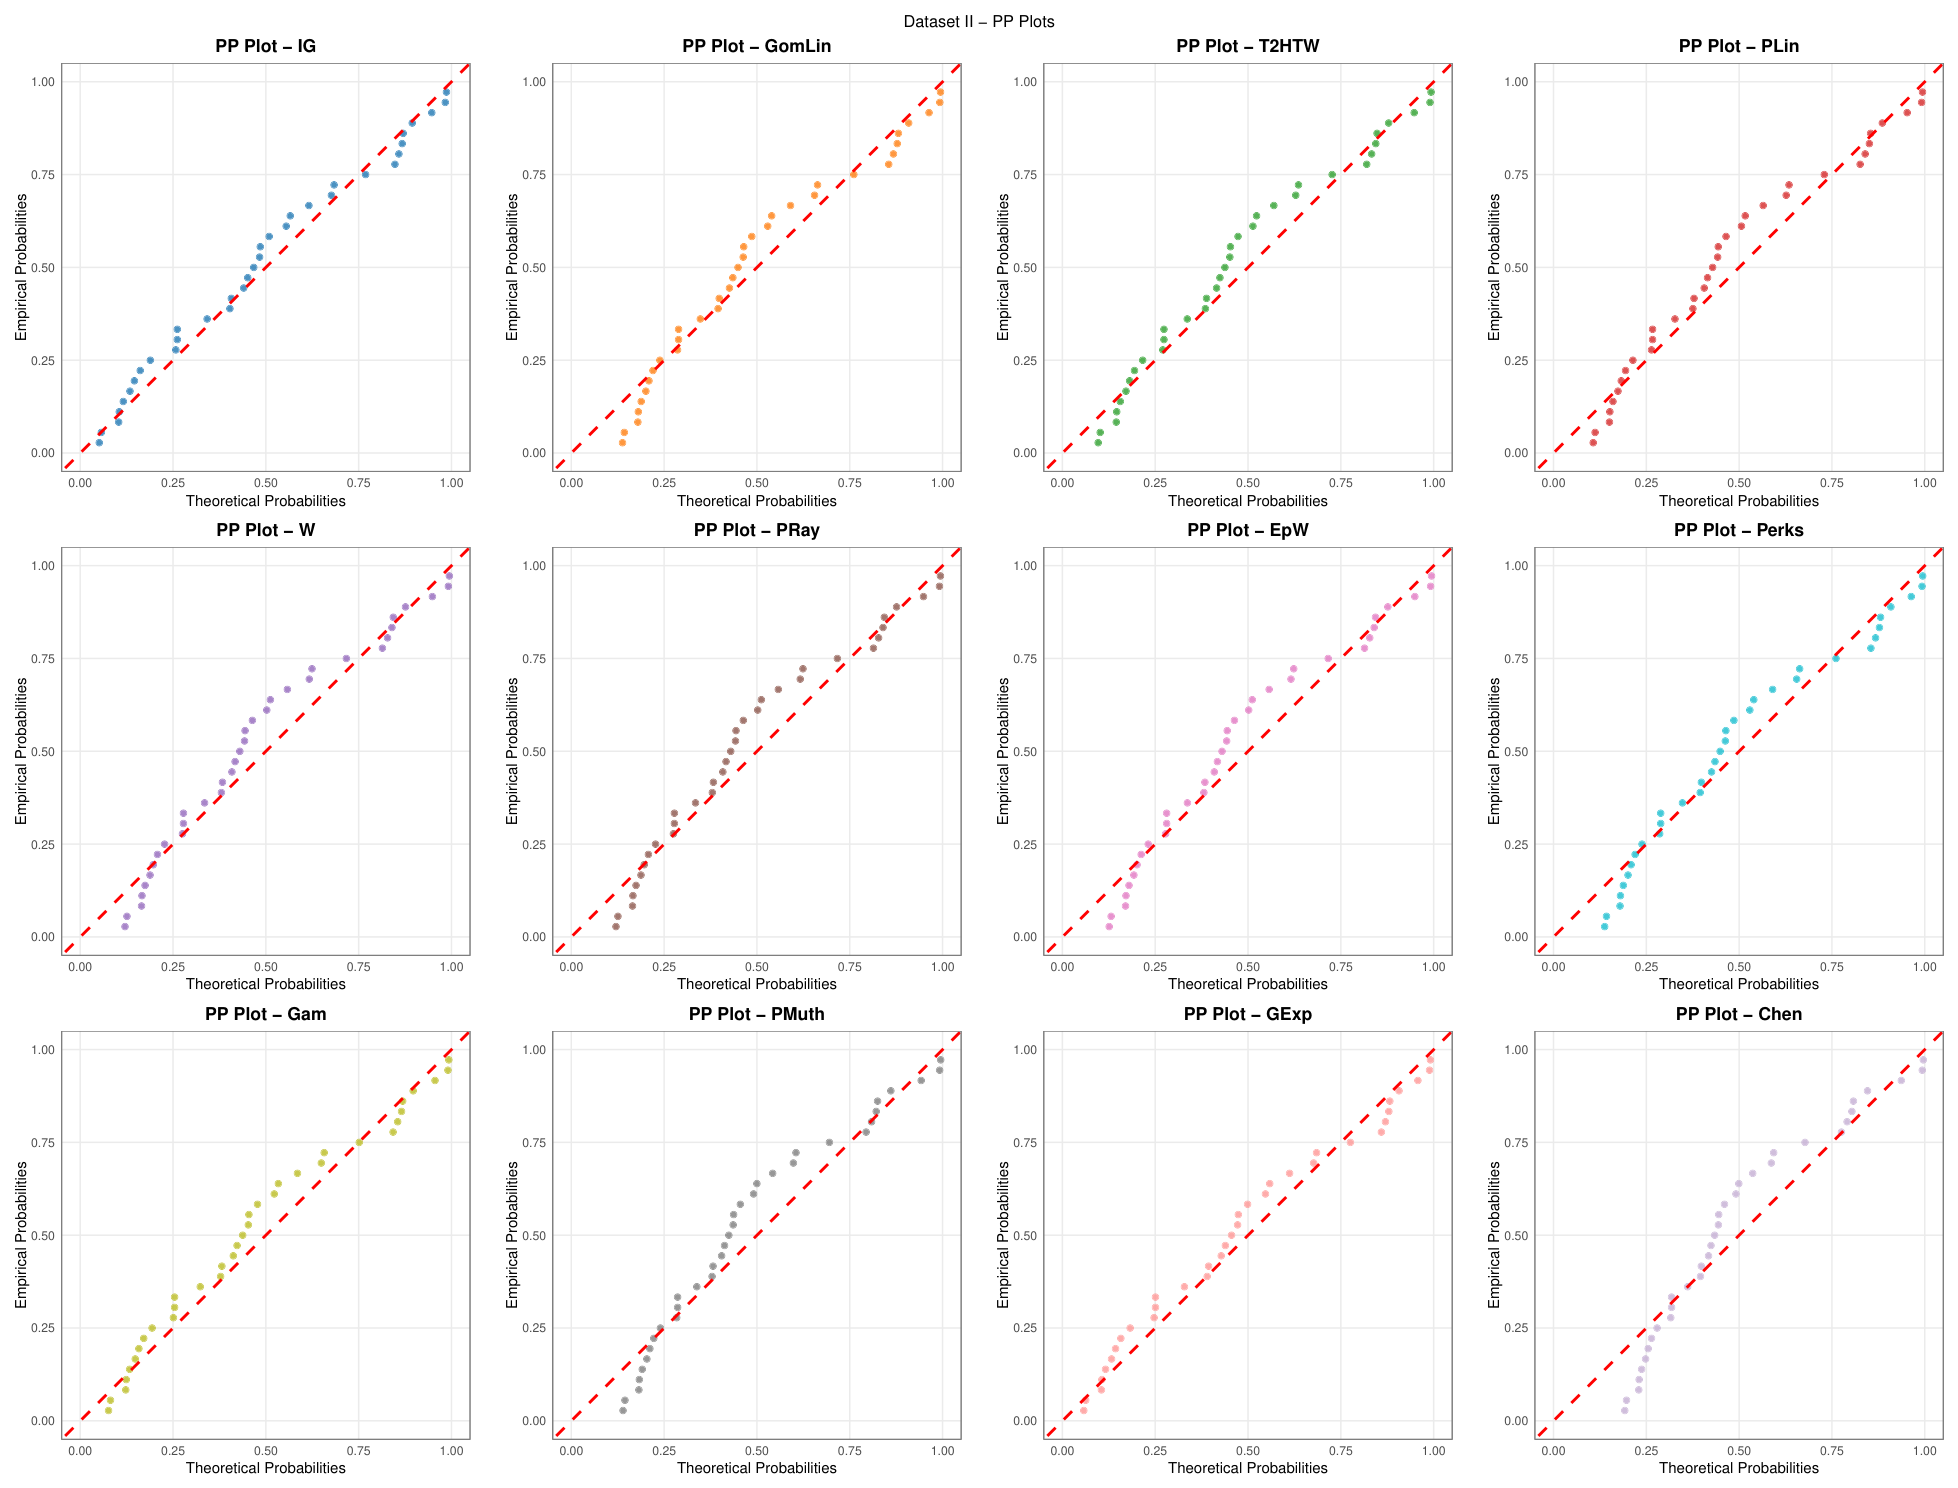
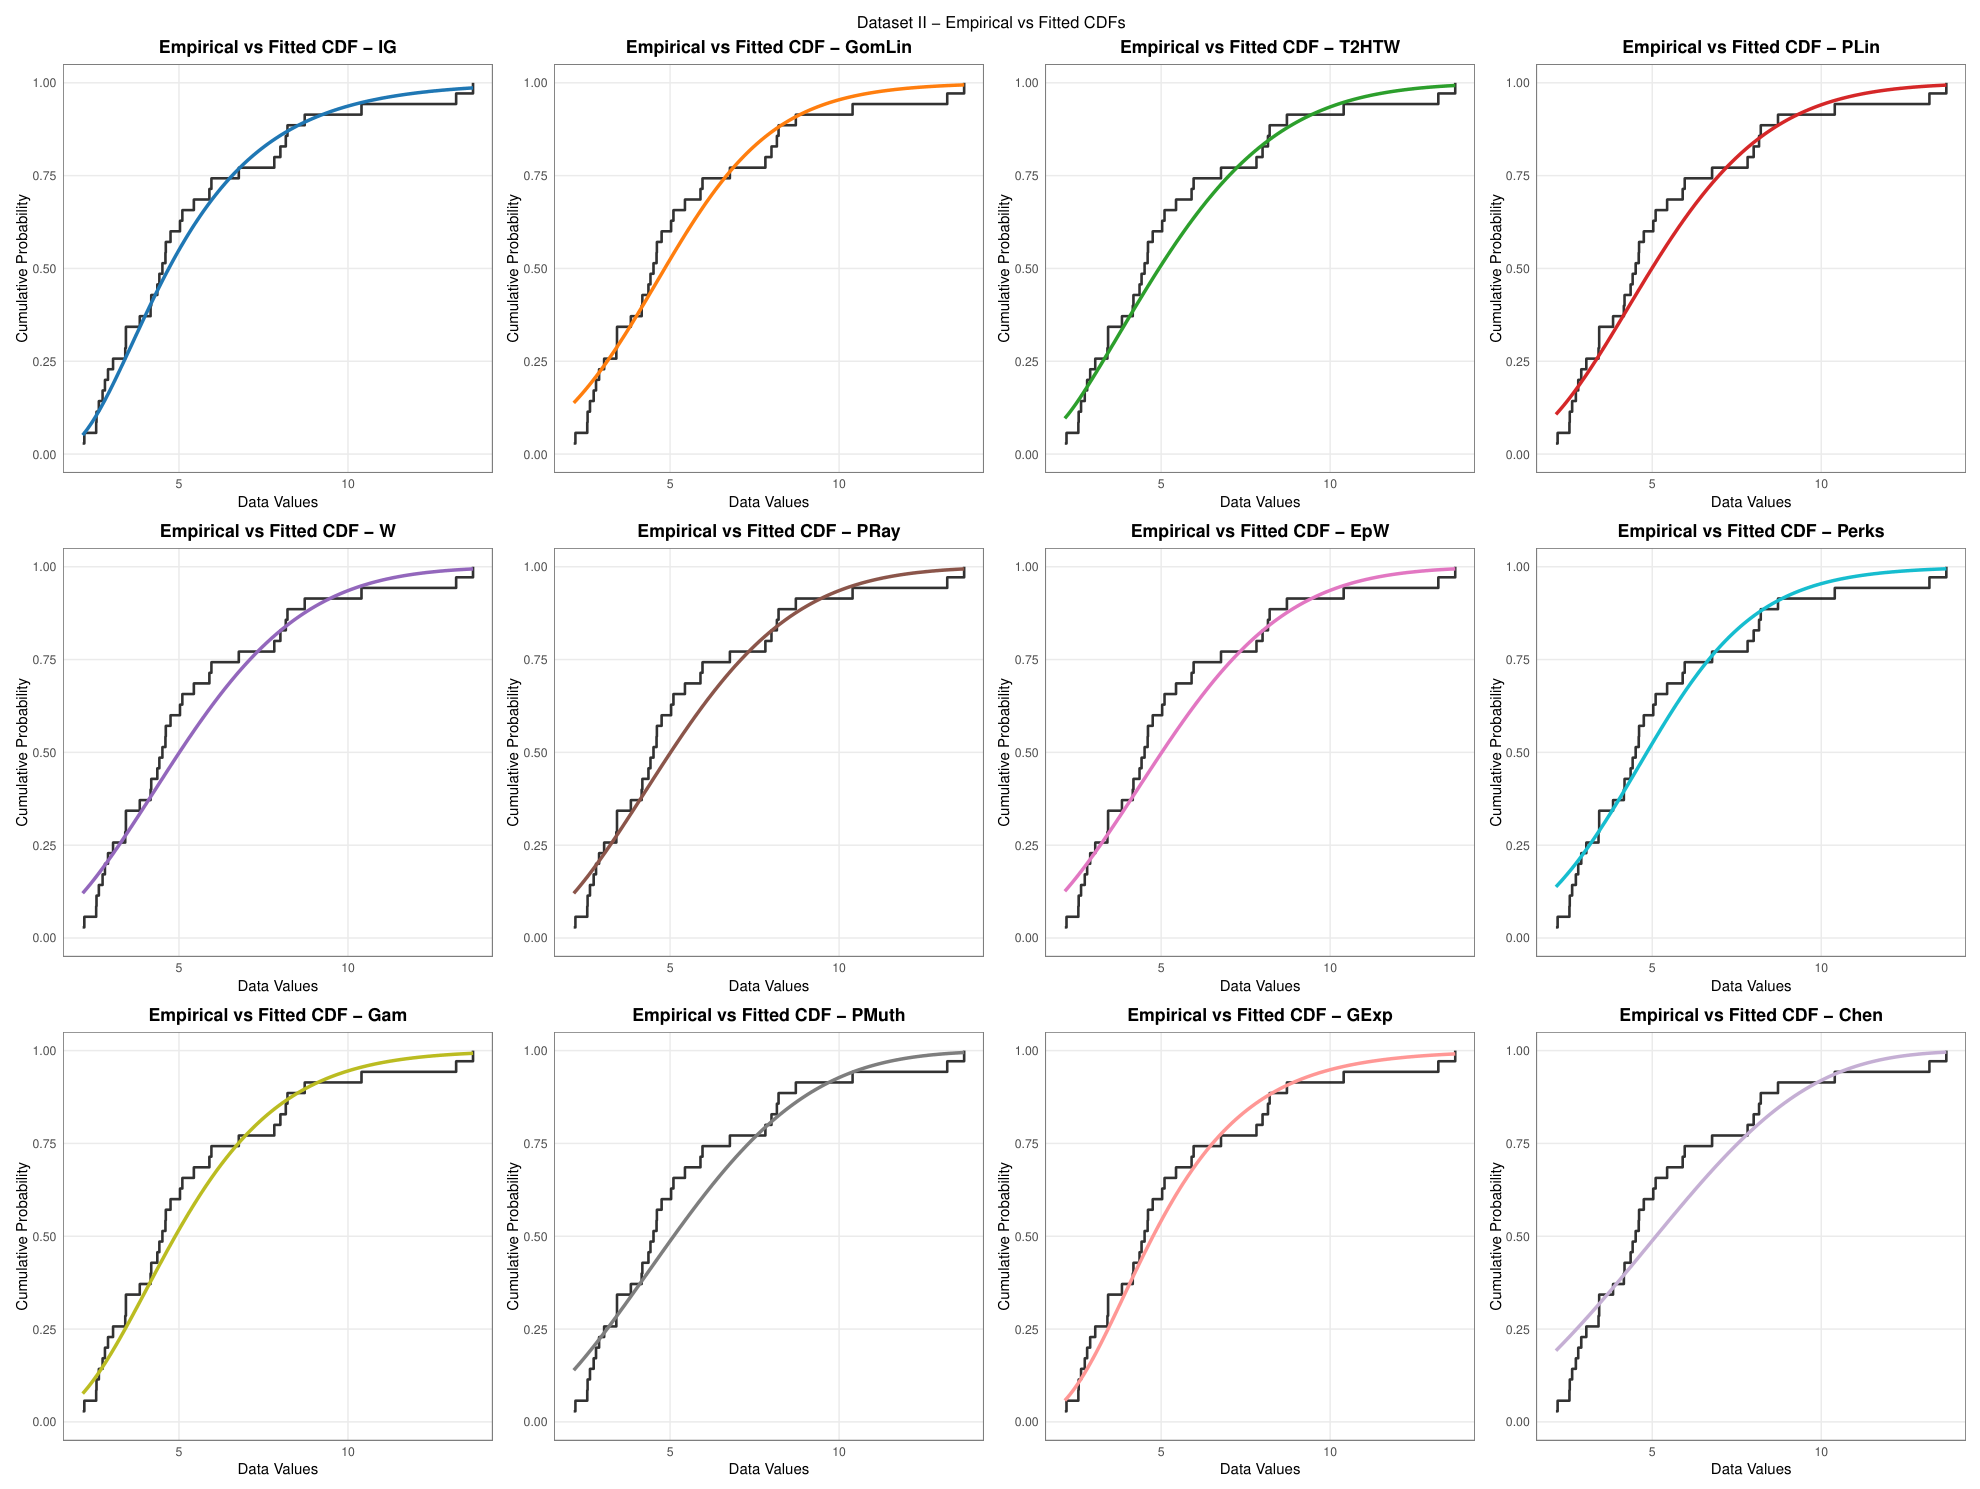
Figure 10,
Figure 11,
Figure 12 and
Figure 13 for dataset II also demonstrate the clear superiority of the Gauss inverse, as shown in
Table 12 where results of dataset II confirm the pattern observed in dataset I, where the IG distribution is the best fit. All graphical displays (PP, CDF, Likelihood) showed consistent performance, in contrast to the clear poor fit of the other distributions.



 ,