


Abstract
Spurious correlations between time series are a persistent problem: simple, low-complexity patterns are abundant, so unrelated series can easily exhibit high Pearson correlation. We argue that Kolmogorov complexity—a series’ resistance to compression—provides a principled diagnostic for flagging such cases. We prove an algorithmic trilemma: a pair of binary sequences cannot simultaneously be algorithmically independent, highly correlated, and highly complex. This gives a deterministic complexity ceiling for independent correlated pairs and a probabilistic bound under which spurious correlations among independent high-complexity pairs are exponentially rare; we further bridge these results to an effective Hausdorff dimension obstruction. These guarantees hold for binary sequences under Hamming correlation; their extension to real-valued series via serialisation and LZ compression is empirically validated rather than proved, so the joint indicator is a calibrated diagnostic, not a causal test. On two toy models—coupled logistic maps and multivariate fractional Brownian motion ()—false positives are far more common among low-complexity series. Because noise inflates complexity and non-stationary processes can be both complex and spuriously correlated, we recommend a two-stage workflow: establish stationarity, then report alongside .
1. Introduction
Understanding and predicting time series is fundamental to many areas of mathematics, science, finance, and beyond [1]. Detecting correlations in time series is important across science and engineering [2,3], while distinguishing genuine causal links from coincidental alignment is notoriously difficult [4,5]. Yule [6] identified this problem a century ago, asking “Why do we sometimes get nonsense-correlations between Time-Series?”, and the question remains practically relevant.
The core difficulty is that simple: low-dimensional patterns are abundant in many natural datasets. For example, series taking forms , , or will appear correlated (at least for short time intervals). More comically, plotting the distance between Neptune and the Sun with burglar rates over a certain time period, or the popularity of the name Theodore and the stock price of HDFC Bank, show how high Pearson correlations can result not because of any fundamental link but because all of these series are themselves simple monotone or near-monotone trends (Figure 1).
Figure 1.
Canonical spurious correlations. Both arise because the underlying series are simple monotone trends with low Kolmogorov complexity. Figures by Tyler Vigen (http://www.tylervigen.com/spurious-correlations (accessed on 1 March 2026)).
Here, we argue that reporting the Kolmogorov complexity of the two series alongside its Pearson correlation provides a principled diagnostic: a high correlation between two high-complexity series constitutes substantially stronger evidence of a genuine relationship than the same correlation between two low-complexity series. For finite binary strings under Hamming correlation, this is more than a heuristic—it follows from a complexity ceiling that we prove in Section 2 and which we extend in Section 2.5.1 to an effective-Hausdorff-dimension obstruction for infinite binary sequences. For real-valued time series, the same principle becomes a theoretically motivated, empirically calibrated diagnostic: the binary theorems do not transfer directly through the serialisation–quantisation–compression pipeline, and the operational behaviour of the diagnostic is validated through the toy-model experiments of Section 4 and Section 5 rather than derived from the theorems.
1.1. Two Mechanisms, One Workflow
It is useful to distinguish two distinct mechanisms by which spurious correlations arise, because the present paper addresses one and inherits the other from classical econometrics. (i) Simple deterministic trends—monotone or near-monotone patterns of low algorithmic complexity, exemplified by the Tyler Vigen catalogue (Figure 1)—produce high because both series happen to share an elementary functional form. This is the regime targeted directly by our complexity screen. (ii) Integrated non-stationary stochastic processes—random walks, fBm paths, and other unit-root-type series—also produce high between independent realisations, the “nonsense correlations” identified by Yule [6] and analysed for econometric regressions by Granger and Newbold [7]. These are algorithmically complex (Section 5) and are therefore invisible to a pointwise complexity screen until they are differenced to stationary increments.
We therefore advance the stationarity-first, complexity-second workflow as a central methodological contribution rather than as a caveat: the stationarity step (testing for a unit root, differencing, or detrending) targets Yule-type non-stationary stochastic correlations, while the complexity screen (computing and comparing against a calibrated threshold or family rule) targets correlations plausibly driven by shared low-complexity deterministic structure. Neither step alone is sufficient: complexity ignores integrated processes, and stationarity testing ignores trend-driven coincidences. The full algorithm is given in Section 7; we make the two-stage structure explicit throughout this paper.
This workflow defines the intended boundary of applicability. In bounded dynamical settings where the serialised complexity proxy has real dynamic range, is a cheap marginal-complexity screen, and an operating threshold such as can be calibrated directly. In stationary Gaussian-increment settings such as fGn under fine serialisation, pointwise LZ complexity saturates, so should not be advertised as an absolute or rank-based cutoff; the relevant output is instead the false-positive risk as a function of an estimated memory/smoothness family parameter such as H. Thus, estimating H is not a competitor to the diagnostic but the correct calibration coordinate for this particular data class, while retains its screening role in data classes whose encoding preserves complexity contrast.
1.2. Why Existing Diagnostics Leave a Gap
Three classes of existing methods address spurious correlations partially. Permutation and phase-randomisation surrogate tests [8] reject the chosen null hypothesis when the observed correlation is inconsistent with an i.i.d. or linear-Gaussian null, but a pair of simple monotone trends typically passes such tests because the correlation is real against the chosen null—it is the null itself that is inappropriate. Cointegration and unit-root tests [9] address mechanism (ii) above but say nothing about mechanism (i). MDL-based causal-discovery methods [10,11] are structurally heavyweight: they aim to recover a full directed acyclic graph and are not designed for the question “is this single Pearson correlation worth trusting?”. The complexity screen we propose fills this lightweight, single-pair gap, complementing rather than replacing the three classes above (see Section 6 for the detailed contrast).
This paper is organised as follows: Section 2 develops the theoretical framework connecting Kolmogorov complexity, Hausdorff dimension, and spurious correlations, including the noise-complexity link. Section 3 describes our complexity estimators and the improved joint indicator. Section 4 presents experiments on coupled logistic maps. Section 5 presents experiments on multivariate fractional Brownian motion. Section 6 compares our approach with existing spurious-correlation diagnostics. Section 7 consolidates threshold selection and sensitivity into a single practical recipe. Section 8 illustrates the framework on stylised real-world patterns. Section 9 discusses implications, limitations, and connections to causal inference.
An important caveat, discussed in detail in Remark 3, is that the proposed framework assumes approximately stationary series. Non-stationarity—such as stochastic trends or structural breaks—can inflate LZ complexity estimates and should be diagnosed and corrected (e.g., by differencing or detrending) before applying our screening indicators.
2. Theoretical Framework
This section develops the algorithmic-information-theoretic foundation of this paper. We begin by reviewing Kolmogorov complexity and the Solomonoff prior (Section 2.1 and Section 2.2), which explain why simple patterns are overrepresented in naturally generated data. We then turn to the core theoretical contribution: an algorithmic trilemma stating that a pair of binary sequences cannot simultaneously be independent, highly correlated, and highly complex (Section 2.4). We formalise this as two propositions—a deterministic complexity ceiling for algorithmically independent pairs, and a probabilistic alignment bound for statistically independent pairs drawn from the Solomonoff prior. We connect the complexity rate of individual sequences to the classical Hausdorff dimension of sets (Section 2.5), discuss how measurement noise inflates observed complexity via the Posobin–Shen theorem (Section 2.6), and close with the connection to algorithmic causality (Section 2.7).
2.1. Kolmogorov Complexity
Within theoretical computer science, algorithmic information theory (AIT) [12,13,14] connects computability theory and information theory. The central quantity of AIT is Kolmogorov complexity, , which measures the complexity of an individual object x as the amount of information required to describe or generate x. is more technically defined as the length of a shortest program which runs on an optimal prefix universal Turing machine (UTM) [15], generates x, and halts. Intuitively, is a measure of the compressed version of a data object. Objects containing simple or repeating patterns like 010101010101 will have low complexity, while objects lacking patterns will have high complexity.
The most commonly used variant of Kolmogorov complexity is prefix complexity [16,17], also denoted (and its conditional version ), which is defined as the minimum length of a program which generates some output x (given side information y) and halts when run on a prefix universal Turing machine U:
is formally uncomputable, meaning that there cannot exist an algorithm that takes any arbitrary string x and returns the complexity value [16]. This uncomputability is related to the Halting Problem and, more broadly, to the logical problems of self-referential statements. Real-world applications of Kolmogorov complexity typically rely on approximations to this uncomputable quantity, and these mostly take the form of data compression algorithms such as methods inspired by Lempel–Ziv (LZ) complexity [18]. The use of LZ compression to approximate Kolmogorov complexity in dynamical systems has been explored in several works, including the computable-information-density framework of Benci, Bonanno, Galatolo, Menconi, and Virgilio [19] and the compression-based time-sequence analysis of Puglisi, Benedetto, Caglioti, Loreto, and Vulpiani [20], as well as applications to entropy estimation in neural and chaotic systems [21,22]. While real-world compression algorithms will fall short of accurately estimating the true Kolmogorov complexity, approximations often work very well at capturing meaningful features of complexity distributions [23,24,25,26,27].
2.2. Algorithmic Probability
An important result in AIT is Levin’s coding theorem [28], which establishes a fundamental connection between and probability predictions. Mathematically, it states that
where is the probability that a (prefix-optimal) universal Turing machine, when fed with a random binary program, outputs x. Probability estimates based on the Kolmogorov complexity of output patterns are called algorithmic probability. We will also refer to Equation (2) as the Solomonoff prior.
While directly applying algorithmic probability in real-world applications is problematic (due to uncomputability), approximations to algorithmic probability for real-world input–output maps have been developed, leading to the observation of a phenomenon known as simplicity bias [27,29]. This shows that even though algorithmic probability is an abstract concept from computer science, it can usefully be applied in real-world settings, including, e.g., statistical data analysis.
2.3. Spurious Correlations
According to the Solomonoff prior, strings with low are exponentially more probable under the universal distribution. This means that simple patterns such as monotone trends, periodic sequences, and simple polynomial functions are much more likely to appear in naturally generated data, as compared to if the data were generated by coin flips. See [30,31] for more discussion and empirical exploration of simplicity bias in natural time series.
It follows that two independently generated simple sequences are far more likely to coincide than two independently generated complex ones (cf. results in [32]), or at least be correlated. The next subsection makes this intuition precise through an algorithmic trilemma: a pair of binary sequences cannot simultaneously be independent, highly correlated, and highly complex.
2.4. Incompatibility of Algorithmic Independence, High Complexity, and Spurious Correlations
We formalise a fundamental trilemma in Algorithmic Information Theory concerning pairs of binary sequences: a pair cannot simultaneously exhibit independence, high complexity, and high empirical correlation. We explore this trilemma through two dual frameworks. First, we prove a deterministic pointwise bound demonstrating that algorithmically independent strings cannot exceed a complexity ceiling determined by their correlation. Second, we prove a conditional probabilistic bound showing that statistically independent, highly complex generative processes yield spuriously correlated sequences with exponentially decaying probability.
2.4.1. The Algorithmic Trilemma
Consider two binary sequences of length n. We wish to analyse three specific properties that a pair of such sequences might possess:
- Independence: the sequences share no hidden mutual information.
- High Correlation: the sequences are structurally very similar (e.g., a high Pearson correlation coefficient).
- High Complexity: the sequences contain dense algorithmic information (i.e., they are incompressible).
The underlying physical law in Algorithmic Information Theory governing these properties is a strict trilemma: You can only pick two. Table 1 summarises these three pairwise regimes.
Table 1.
The three pairwise regimes in the algorithmic trilemma. Any two of independence, high correlation, and high complexity may hold together, but all three cannot hold simultaneously except by algorithmically non-independent alignment.
If two sequences are highly correlated and highly complex, they must be mathematically dependent, sharing significant mutual information to achieve that complex alignment. If they are independent and complex, they will look like distinct white noise and lack structural correlation. If they are independent and highly correlated, they must both be highly simple (e.g., two strings of all zeros).
This trilemma can be formalised from two different perspectives: deterministic (algorithmic) independence and probabilistic (statistical) independence.
2.4.2. Preliminaries and Definitions
To avoid notational conflict with the real-valued time series of Section 3, Section 4 and Section 5, we use lightface (and capitals for random variables) for binary strings throughout this section.
Throughout this section, the length satisfies : the normalised complexity and the Hamming correlation defined below are undefined at , and the asymptotic (effective-dimension) statements are understood in the limit . For , the normalised complexity is defined as . Two strings are c-algorithmically independent if knowing u does not help compress v, formally if . The normalised Hamming Correlation (also called bipolar overlap) for is defined as , where is the Hamming distance. Thus, a correlation confines v to a Hamming ball around u of radius exactly , where . The number of strings in this ball is bounded by , where is the binary entropy function. The length-conditioned Solomonoff-type prior for is defined as , where the normalisation constant . This is a length-conditioned normalisation of the universal a priori weights over strings of fixed length n; it should not be confused with the unconditioned universal semimeasure.
2.4.3. Pearson vs. Hamming Correlation
and , where is the bitwise complement. The same is true for the empirical Pearson correlation coefficient (see Definition A1 in Appendix A or Equation (3)). Indeed, they closely match each other in general but are not exactly equal (if u and v are each balanced, then both correlations coincide). While the propositions below are formulated using this Hamming correlation for geometric clarity, essentially the same capacity bounds hold for the standard empirical Pearson correlation. Bounding the Pearson volume requires an empirical entropy bound rather than a simple Hamming ball, resulting in an additional polynomial factor which in Proposition 1 is absorbed in the term and in Proposition 2 increases the prefactor to . The proof of this Pearson volume bound is provided in Appendix A.
2.4.4. The Duality of Independence
The trilemma can be expressed through two distinct frameworks of independence:
Algorithmic Independence focuses on the final, realised sequences. It states that if you assume strings are both algorithmically independent and highly correlated, they are mathematically forbidden from crossing a specific “complexity ceiling”.
Statistical Independence focuses on the generative processes. It models two isolated rooms flipping coins governed by the universal prior . The physical processes are independent, so their joint probability factorises. In this framework, we can enforce the condition that the sequences must be highly complex. The trilemma dictates that any highly correlated, highly complex pair of strings must be algorithmically dependent. For statistically independent processes to generate such an algorithmically dependent pair, they must do so by pure, astronomically rare luck.
We first prove that algorithmic independence and high correlation upper-bound the allowable complexity of the individual strings.
Proposition 1
(Deterministic complexity ceiling). Let be c-algorithmically independent. If u and v exhibit an empirical correlation , then
or equivalently, after dividing by n, both of their normalised Kolmogorov complexities are bounded away from 1:
The bound is asymptotically informative only when ; the algorithmic-independence constant c contributes additively to the complexity ceiling at the unnormalised level and as at the normalised level. Throughout this paper, we work in the regime .
Proof.
Assume . As established geometrically, v must reside in a restricted Hamming ball surrounding u of cardinality at most .
An algorithm can perfectly reproduce v if provided with u and the specific index of v within that bounded ball. Storing this index requires at most bits. Therefore, the conditional Kolmogorov complexity is bounded:
The takes care of encoding to sufficient accuracy. By the chain rule of Kolmogorov complexity, the joint complexity is . Substituting this into the c-algorithmic independence assumption , we obtain:
Subtracting from both sides yields:
By symmetry, swapping the roles of u and v yields the same bound on . Dividing by n completes the proof. Because , neither independent sequence is permitted to be uniformly complex. □
We now shift to the probabilistic framework. We ask the following: given that two statistically independent processes generate highly complex sequences, what is the probability they randomly exhibit a spurious correlation?
Proposition 2
(Spurious probabilistic alignment bound). Let be independent random variables drawn from the length-conditioned Solomonoff-type prior . For any correlation threshold and complexity thresholds , provided , the conditional probability of a spurious high correlation given that both strings are complex is exponentially small:
We need to achieve exponential decay, where . For instance, for , we have and , so a complexity threshold lies above the entropy ceiling by roughly ; the decay is then about , consistent with Proposition 1 implying that for sufficiently long algorithmically independent strings.
Proof.
Let and denote the respective events that the strings are complex: and . By the definition of conditional probability for statistically independent variables:
Let be the Hamming ball of highly correlated matches around u, where .
Step 1: Bounding the Numerator. We expand the joint probability in the numerator by marginalising over u:
For every v in the inner sum, , implying . Its weight is bounded by . Bounding the inner sum by its maximum volume times the maximum uniform weight gives:
Substituting this bound back into the outer sum over u reveals:
Step 2: Algebraic Cancellation. Substituting the bounded numerator into the Bayes fraction causes to cancel:
This cancellation demonstrates that conditioning on the complexity of U mathematically shields us from paying the probability penalty of generating it.
Step 3: Lower-Bounding the Denominator Mass. We must ensure the remaining denominator does not decay exponentially, which would weaken the bound. Out of strings, at most have complexity strictly less than . Thus, there are more than sequences with . For sufficiently large n, , ensuring these sequences belong to .
By the Invariance Theorem, a universal Turing machine can output any string by reading its length (≤ bits) followed by its literal bits. Thus, uniformly, . Summing this minimum weight over the volume of complex strings guarantees a polynomial lower bound:
Step 4: Final Synthesis. Substituting this polynomial lower bound into Step 2 yields:
By symmetric marginalisation (evaluating over v first to cancel ), we obtain the independent constraint . Because the true conditional probability must simultaneously satisfy both upper bounds, we take the minimum of the two limits, yielding the final exponent:
□
The algorithmic bound (Proposition 1) dictates that crossing the complexity ceiling is logically impossible for algorithmically independent strings. The probabilistic bound (Proposition 2) measures the exponentially tiny probability of statistical independent processes accidentally generating dependent strings that violate this ceiling. Together, they formalise the boundaries of spurious structural alignment.
2.4.5. From Theory to Practice
Propositions 1 and 2 provide rigorous bounds for binary strings of length n under Hamming correlation (with Pearson correlation handled by the polynomial-factor reduction noted above and proved in Appendix A); their asymptotic counterpart is the effective-Hausdorff-dimension obstruction stated in Section 2.5.1 (Propositions 3 and 4). The practical pipeline introduced in Section 3 extends this to real-valued time series through two additional approximation steps: (i) serialisation of floating-point values to byte strings (Section 3.2.1), and (ii) the use of LZ compression as a computationally tractable proxy for the uncomputable Kolmogorov complexity. Both steps are well motivated—any lossless computable compression scheme yields an upper bound on [16]—but neither is covered by the formal guarantees of the propositions. Section 3.1 makes this layering explicit through a four-level taxonomy (binary strings → real vectors → serialised byte strings → compressed byte strings) and emphasises that the procedure should be interpreted as a theoretically motivated, empirically calibrated diagnostic operating at the deepest level rather than as a direct consequence of the binary theorems. The experimental validation on coupled logistic maps (Section 4) and fractional Brownian motion (Section 5) demonstrates that the qualitative prediction of the trilemma (fewer spurious correlations at higher complexity) holds robustly for real-valued series under compression-based proxies. Closing this gap formally—by extending the bounds to quantised real-valued sequences and bounding the approximation error of LZ compression relative to true Kolmogorov complexity—is an important direction for future work.
2.4.6. Relation to the Indicator
Proposition 2 shows that exponential decay of spurious alignment requires —i.e., at least one of the two series must be sufficiently complex. The practical screening indicator introduced in Section 3 imposes the strictly stronger condition that both series be individually complex. Section 3 motivates this choice empirically: on asymmetric pairs, an indicator based on max (closer to the theorem’s minimal hypothesis) is too permissive, flagging pairs as trustworthy when one series is a simple trend.
2.5. Hausdorff Dimension and the KC-Dimension Bridge
In mathematics, the Hausdorff dimension provides a rigorous metric for characterising the “roughness” or fractal complexity of a set. Developed by Felix Hausdorff in 1918, it generalises the intuitive notion of dimension by allowing for non-integer values. For standard Euclidean objects, the Hausdorff dimension aligns with topological dimension: A singleton point has a dimension of 0; a line segment has a dimension of 1; a square has a dimension of 2; a cube has a dimension of 3.
For sets defining smooth manifolds or polytopes, typical of classical geometry, the Hausdorff dimension is an integer equivalent to the dimension of the space the shape occupies. For infinite sequences, the connection between Kolmogorov complexity and geometric complexity is made precise by the following foundational result.
Definition 1
(Complexity rate/normalised Kolmogorov complexity). The complexity rate (or normalised Kolmogorov complexity ) of an infinite sequence is
where denotes the prefix of length r. This quantity measures the asymptotic compressibility of individual sequences: for eventually periodic sequences and for algorithmically random ones.
Definition 2
(Kolmogorov complexity relative to an oracle). For an oracle set , the Kolmogorov complexity relative to A is , where is a universal prefix-free Turing machine with oracle access to A. The unconditional complexity corresponds to . The complexity rate relative to A is .
The connection between the complexity rate of individual sequences and the Hausdorff dimension of sets is made precise by the foundational result of Lutz [33]: the complexity rate coincides with the effective Hausdorff dimension of the sequence; the corresponding generalisation of this complexity-rate notion to general metric spaces was given by Galatolo [34]. More generally, the classical Hausdorff dimension of a set can be recovered from the complexity rates of its points via the point-to-set principle [35]: for any set ,
where the minimum is over all oracle sets A. In words, the Hausdorff dimension of a set equals the supremum of the oracle-relative complexity rates of its points, minimised over all possible oracles. Equivalently, for the classical Hausdorff dimension of the graph of a fractional Brownian motion (fBm) path with Hurst parameter H,
2.5.1. Effective Hausdorff Dimension Bridge
Proposition 1 is a finite-string statement: it controls at fixed length n. The natural asymptotic counterpart is an obstruction on the effective Hausdorff dimension of infinite binary sequences. We state this obstruction in two forms—persistent and subsequential—and discuss its scope.
Scope
The theorem below is an asymptotic result about infinite binary sequences under Hamming correlation. It rigorously bridges the finite Hamming-ball complexity ceiling of Proposition 1 to the effective-dimension framework of Lutz [33] and Staiger [36], justifying the Hausdorff-dimension framing of the binary theory. It does not apply directly to real-valued time series, Pearson correlation, fractional Brownian motion sample paths, or LZ-compressed serialised data; for those, the empirical pipeline of Section 3, Section 4 and Section 5 and the -as-diagnostic interpretation apply instead.
For , write for the length-n prefix. Define the effective Hausdorff dimension of x as in Definition 1, , and the upper effective dimension (or effective packing dimension) by .
Proposition 3
(Effective-dimension obstruction to persistent correlation). Let , and suppose
(algorithmic independence up to mutual information). Fix and set . If for all sufficiently large n,
then
and consequently and . Equivalently (the exact contrapositive), if , then x and y cannot be simultaneously algorithmically independent up to mutual information and τ-correlated for all sufficiently large n. In particular, the same conclusion holds under the stronger condition , which expresses the intended interpretation that both sequences have high effective dimension.
Proof.
Let , . The correlation assumption gives eventually, i.e., . Hence, lies in the Hamming ball , whose cardinality is at most by the standard entropy bound. Conditional on , the string can be encoded by its index inside this ball using at most bits, plus bits for the length n and decoding conventions. Therefore
By the chain rule, . Combining with the -independence assumption and cancelling yields
Dividing by n and taking gives , hence also . Interchanging the roles of and in the conditional-encoding step yields the same bound for x. □
Proposition 4
(Subsequential effective-dimension obstruction). Under the same independence assumption , if there exists an infinite sequence such that for every j, then
Proof.
Apply the Hamming-ball argument along the subsequence to obtain , and symmetrically for x. Taking lim inf along bounds from above. □
Remark 1.
Persistent correlation for all sufficiently large n controls the upper effective dimension (Proposition 3); subsequential correlation controls only the lower effective dimension (Proposition 4). The distinction matters because in general, with equality only when the limit exists.
From Effective to Classical Hausdorff Dimension
Propositions 3 and 4 give a pointwise algorithmic version of the Hausdorff-dimension obstruction. The effective Hausdorff dimension is, by the Lutz–Staiger results [33,36] and the point-to-set principle [35] stated above, the individual-sequence analogue of classical Hausdorff dimension. Consequently, two algorithmically independent infinite binary sequences of sufficiently large effective dimension cannot maintain high Hamming correlation asymptotically. This justifies the Hausdorff-dimension framing of the binary-sequence theory. It does not prove that the LZ-compressed length of a serialised real-valued time series is a consistent estimator of Kolmogorov complexity, of effective Hausdorff dimension, or of the classical Hausdorff dimension of any underlying attractor; that empirical translation requires the calibration of Section 3, Section 4 and Section 5.
For fBm specifically, the classical graph dimension satisfies , so smaller H corresponds to rougher paths and larger graph dimension. The empirical compression ratio of a finite sampled path (the normalised LZ estimator is formally defined in Section 3.2, where the symbol-sequence generation, compression step, and normalisation are specified), however, depends on the chosen finite-resolution encoding (Section 3.2.1, Table 2). The mfBm experiments of Section 5 should therefore be read as empirical evidence consistent with the effective-dimension perspective of Propositions 3 and 4, rather than as a direct theorem about real-valued sample paths.
A time series with normalised LZ complexity has its values lying on an attractor whose Hausdorff dimension is related to , but the relationship is not one-to-one in general. In the binary-string setting, the Staiger [36] and Lutz [33] results directly identify the complexity rate with the effective Hausdorff dimension of the sequence. For dynamical systems, however, the connection between the entropy rate (which the normalised LZ complexity approximates) and the dimension of the attractor is mediated by the Lyapunov spectrum through the Ruelle–Pesin formula [37,38] and the Kaplan–Yorke conjecture [39]:
where are the Lyapunov exponents and k is the largest integer for which . In the special case of one-dimensional maps (such as the logistic map used in Section 4), there is a single Lyapunov exponent . In chaotic regimes with an absolutely continuous invariant measure, the entropy rate is then governed by the positive Lyapunov exponent (, with as the attractor fills the interval), whereas in periodic windows the entropy is zero and the attractor is a finite set. For higher-dimensional systems, the normalised LZ complexity remains a proxy for the entropy rate , but recovering the attractor dimension additionally requires knowledge of the Lyapunov spectrum. In our coupled logistic map experiment (Section 4), each uncoupled map is one-dimensional, and the coupled system is two-dimensional with a transversal Lyapunov exponent that we compute explicitly.
Two independent series lying on high-dimensional attractors must “wander” over a large region, making incidental alignment geometrically improbable.
2.6. Noise Increases Kolmogorov Complexity
Measuring the complexity of a time series is not entirely straightforward. One issue is that observed time series from natural sources typically contain measurement noise. In general, random noise will increase the complexity of a data object. The Posobin–Shen theorem [40] shows how it increases Kolmogorov complexity in a quantifiable way.
Proposition 5
(Posobin–Shen [40]). Let x be a binary string of length n whose Kolmogorov complexity satisfies , where for some and is the binary Shannon entropy. Suppose each bit of x is independently flipped with probability τ. Then, with probability at least the complexity of the perturbed string satisfies (the Posobin–Shen result is stated for plain (non-prefix) Kolmogorov complexity , whereas Section 2 uses prefix complexity ; the two quantities differ by at most for strings of length n [16], so the asymptotic bounds carry over to the prefix setting with only sub-linear corrections)
where . Moreover, for infinite sequences, the effective Hausdorff dimension increases almost surely.
This result implies that the increase in complexity depends both on the initial complexity class of the string and on the noise level . In the ideal binary setting, the lower bound holds with high probability, but for finite real-valued time series, the exact complexity increase depends on the representation and noise characteristics. Consequently, empirical thresholds (such as the threshold used later in Section 7) should be interpreted as application-dependent heuristics rather than universal constants.
If a “simple” binary string with true normalised Kolmogorov complexity is corrupted by independent bit-flip noise with rate (say – as a stylised model of measurement error), the Posobin–Shen lower bound shows that its complexity rate becomes at least rather than zero, where H here is the binary Shannon entropy of . Numerically, , , , so for plausible measurement-noise rates, the analytical binary noise floor sweeps the interval . The upper end of this range is close to the bounded-logistic operating threshold , so practitioners working at appreciable noise levels should re-calibrate the threshold against surrogates of their own noise process. The empirical floor on (the byte-level LZ ratio used throughout this paper) is a different quantity that depends on the serialisation: under pickle+float32, a noiseless periodic logistic orbit gives (Table 2), and added Gaussian noise on the same orbit raises this only modestly. The two floors should not be conflated; the empirical screening threshold is a bounded-logistic operating value rather than a consequence of the binary noise bound (Section 7).
Figure 2 illustrates this numerically for fBm series and analytically for the binary case.
Figure 2.
(Left) LZ complexity increases monotonically with noise level for fBm series with different Hurst parameters. (Right) The Posobin–Shen analytical lower bound as a function of for different initial complexities . Even small noise () pushes a simple series () to .
2.7. Connection to Algorithmic Causality
In this work, we are interested in how complexity can help assess the evidential weight of an observed correlation—specifically, whether it provides grounds for further causal investigation. According to the Algorithmic Markov Condition (AMC) [41], the true causal network is the one minimising Kolmogorov complexity (see also [42]). When two time series have high algorithmic mutual information and both have individually high complexity , this constitutes evidence that the correlation reflects a non-trivial relationship rather than coincidence—because independently drawn high-complexity sequences are algorithmically independent with overwhelming probability. Our complexity-filtered correlation test can thus be seen as a practical, computable screening step: it identifies correlations worth investigating with dedicated causal discovery methods, analogous to MDL-based approaches [10,11]. We emphasise that our framework does not, by itself, establish causation; it provides a principled criterion for distinguishing correlations that are likely meaningful from those that are likely accidental.
3. Complexity Estimators and the Joint Indicator
This section describes the empirical complexity estimators used throughout this paper and introduces the joint complexity indicator , the main methodological contribution. We first define the LZ-based and spectral-entropy complexity proxies together with their normalisations then address the two principal practical concerns: sensitivity to serialisation choice and sample-size requirements. We close with the screening criterion and contrast it with the alternative similarity indicator .
3.1. From Binary Strings to Real-Valued Time Series
Before introducing the estimators, it is useful to make explicit the gap between the rigorous binary-string theory of Section 2 and the empirical pipeline applied to real-valued time series. We distinguish four levels:
Only Level 1 is fully rigorous in the present theory: Propositions 1 and 2 apply to binary strings under Hamming correlation, and the effective-dimension bridge of Section 2.5.1 applies to infinite binary sequences. Appendix A shows that, for binary strings, replacing Hamming correlation by the empirical Pearson correlation changes the counting bound only by a polynomial factor and therefore preserves the same exponential entropy rate . This result does not establish an analogous volume bound for arbitrary real-valued vectors in ; the chain of rigorous coverage is
and only the first two arrows are covered by the finite-string theory. Levels 3 and 4 are methodological translations: they invoke a chosen serialisation (Section 3.2.1) and a chosen lossless compressor as a computationally tractable upper bound on K [16], and the resulting numerical quantities depend explicitly on those choices. The transition from binary strings to real-valued time series is therefore handled empirically, through serialisation, compression, and calibration.
Throughout the remainder of this paper, the empirical procedure should therefore be read as a theoretically motivated, empirically calibrated diagnostic operating at Level 4, with the rigorous guarantees confined to the binary Levels 1–2. The toy-model experiments of Section 4 and Section 5 provide the empirical calibration; the binary theorems and the effective-dimension bridge provide the conceptual motivation. We do not claim that the Level-4 compression ratio is a consistent estimator of Kolmogorov complexity, of effective Hausdorff dimension, or of the classical Hausdorff dimension of any underlying attractor.
3.2. Complexity Estimators
We use two primary empirical complexity measures, each a proxy for Kolmogorov complexity: LZ-based complexity and spectral entropy. We also discuss ordinal/permutation entropy as a useful robustness check, but it is not used in the reported experiments.
- LZ-Based Complexity
The Lempel–Ziv (LZ) complexity provides a practical, compression-based proxy for Kolmogorov (algorithmic) complexity. Given a real-valued time series (we use boldface throughout to distinguish real-valued series from the binary strings of Section 2), we proceed as follows:
- Symbol sequence generation. Map to a byte string by serialising the sequence as a float32 array via Python’s pickle protocol (pickle.dumps(x.astype(np.float32))). This yields a byte string of approximate length , where bytes is the pickle header overhead. Alternative serialisations (raw IEEE-754 float64 via struct.pack, uniform int16 or int8 quantisation) are compared in Section 3.2.1; all main-text experiments in this paper use pickle+float32 to match the original implementation, with robustness to the alternatives reported separately.
- Compression-based complexity. Compress the byte string using the LZ77-based zlib algorithm:where denotes the resulting compressed length in bytes. More regular (low-complexity) series admit more repeated patterns and thus compress to shorter lengths, whereas high-complexity (e.g., chaotic) series yield larger .
- Normalisation. To compare series of equal length N, we normalise by the original byte-string length M:This ensures scale-invariant comparisons. The constant is the small fixed overhead of the compressor’s pickle and zlib headers and dictionary state; for the experiments in this paper, , and Table 2 indeed reports values up to on incompressible inputs.
A perfectly periodic series compresses nearly to zero; a chaotic or rough series compresses poorly, giving .
3.2.1. Serialisation: Choice and Robustness
Because LZ compression operates on byte streams, the conversion from a real-valued time series to bytes is part of the method and needs to be made explicit. We consider four schemes:
- pickle+float32. Python’s pickle.dumps(x.astype(np.float32))— 4 bytes per value plus a small header. This is the original implementation used throughout this paper.
- struct+float64. Raw IEEE-754 double-precision bytes via struct.pack—8 bytes per value, no framing.
- int16. Uniform quantisation onto levels over the observed range, packed as 2 bytes per value.
- int8. Uniform quantisation onto levels, 1 byte per value.
Table 2 reports under all four schemes on six canonical signal classes: bounded recurrent orbits (periodic and chaotic logistic), unbounded Gaussian increments (fGn, three Hurst values), their cumulative sums (fBm paths, three Hurst values), and uniform white noise.
Table 2.
under four serialisation schemes, averaged over 20–30 realisations. Logistic series use ; fGn/fBm series use . Standard deviations are below in every cell.
Reading the Table
Several patterns emerge:
(1) Every serialisation separates the periodic logistic from the chaotic one. All four schemes give at and a chaotic value substantially higher (ranging from 0.46 for int8 to 0.97 for int16). The bounded recurrent logistic orbit is the regime where LZ discrimination is sharpest, and results are robust across serialisation.
(2) int8 collapses chaotic logistic but reveals fBm roughness. int8 is the only scheme that produces a strong H-dependence on fBm paths: drops from 0.954 at to 0.497 at , a factor-of-two change. This is because coarse (256-level) quantisation of smooth paths produces long runs of identical bytes that zlib exploits; rough paths do not admit such runs. int8 is also, however, the only scheme that distorts the chaotic logistic case (reducing its to 0.46). No single scheme dominates on both toy models.
(3) Finer serialisations saturate on Gaussian-valued data. int16, struct+float64, and pickle+float32 all give – for fGn and fBm paths essentially regardless of H, because each sample has a nearly unique byte representation. The small trend visible in the pickle+float32 column (0.919–0.897 across for fBm paths) is the signal analysed in Section 5; it is real but modest, a relative variation rather than the strong monotone law suggested by the theoretical Hausdorff relation .
(4) The path-versus-increment compression comparison is encoding-dependent. The relative compressibility of an fBm path and its fGn increments has no universal ordering; it depends on the serialisation. Under coarse encodings such as int8, smooth (high-H) fBm paths can become much more compressible than their fGn increments, because the path contains long low-variation runs that the compressor exploits, whereas rough (low-H) paths remain close to their increments. Under fine encodings such as pickle+float32, these differences are much smaller because sample-level numerical variation dominates the byte stream (the pickle+float32 columns of Table 2 differ by only a few percent between the fBm-path and fGn rows at matching H). The path-versus-increment comparison should therefore not be summarised by a universal ordering. The operative point for this paper is the separate one that smooth trends drive the Yule nonsense-correlation phenomenon, which is handled by the stationarity pre-step rather than by the pointwise compressibility comparison.
Choice for the Main Experiments
For continuity with this paper’s original figures, we report main-text results using pickle+float32, the scheme under which those figures were generated. We do not claim this is optimal: for bounded recurrent dynamics, struct+float64 and int16 give cleaner contrast, and for smoothness-sensitive discrimination on Gaussian-valued paths, int8 is substantially more informative. The screening conclusion of this paper—that periodic/simple regimes produce spurious correlations frequently and chaotic/rough regimes do not—is preserved under every scheme in Table 2, because this conclusion is driven by the large periodic-versus-chaotic contrast (a gap of ∼0.9 in every column). Finer comparisons within the Gaussian-valued family are not preserved across schemes: the fine-quantisation columns (pickle+float32, struct+float64, int16) and the coarse-quantisation column (int8) can rank individual fBm/fGn rows differently, which is precisely the phenomenon motivating the open question below.
An Open Question: Task-Optimal Serialisation
Table 2 raises a question we pose but do not solve. The same fBm path at yields under int16 but under int8—a spread of roughly half the unit interval for identical underlying data. The two columns answer different questions: int16 records the individual Gaussian samples faithfully and reports that each sample is, in isolation, near-incompressible; int8 records a much coarser approximation in which the smoothness of consecutive values produces compressible runs. Which is correct depends on what one is trying to discriminate. For bounded recurrent orbits where the absolute values carry the signal (e.g., distinguishing a period-2 logistic orbit from a chaotic one), finer quantisation preserves the relevant structure. For Gaussian-valued paths where only the local difference structure carries the smoothness signal, coarse quantisation is essential—the fine quantisation destroys the signal by preserving per-sample noise that dominates the compression budget.
A principled formulation of this trade-off is the natural next step. Given a signal class (e.g., fGn parametrised by H) and a discrimination task T (e.g., screening independent pairs for spurious correlation), one would ask for the quantisation that maximises the mutual information between and a sufficient statistic for T at a fixed description-length budget. We conjecture this is a rate–distortion problem with a task-specific distortion measure and that the optimal interpolates between the two extremes visible in Table 2 as the signal class moves from bounded-recurrent to Gaussian-valued. Working out this correspondence—and replacing the empirical table with a closed-form prescription—is left for future work. We emphasise that the main-text experiments of this paper are internally consistent: all figures use the documented pickle+float32 pipeline, and no conclusion relies on a claim about which serialisation is globally optimal.
Limitations of the Pointwise Estimator for Gaussian Data
On Gaussian-valued processes (fGn, fBm at fine serialisations), the pointwise is a weak discriminator across smoothness regimes: the compressibility is dominated by the bits per sample required to distinguish N Gaussian samples on a fine alphabet, and variations due to autocorrelation contribute only a small correction. Two mitigations carry information where the pointwise estimator does not:
- Use coarser serialisation when smoothness discrimination matters. int8 (or equivalently, symbolic dynamics via partition) reveals the H-dependence that finer schemes miss (Table 2).
- Use the pairwise false-positive rate. As demonstrated in Section 5, the rate of spurious Pearson correlations between independent pairs is a sharp function of H even when the pointwise is nearly flat. This is the empirical signal that actually validates the screening framework on Gaussian data.
Practical Implication
For any specific data class, the practitioner should empirically calibrate by comparing under candidate serialisations to a known null distribution at matching sample size and distribution (Step 2–3 of the recipe in Section 7). Symbolic encodings adapted to the domain (for example, the left/right partition for interval maps) often outperform uniform quantisation when domain knowledge is available [43].
Sample-Size Requirements
For short time series (), becomes unreliable because the compressor’s dictionary overhead dominates the compressed output. We recommend for stable estimates; at , fGn sweeps already resolve the false-positive transition in the smooth-H regime (Section 5).
Summary of Practical Choices
Table 3 collects the key recommendations.
Table 3.
Practical recommendations for LZ complexity estimation.
Table 4.
The four power-mean candidates evaluated on representative asymmetric pairs. A pair is “flagged ✓” at a given threshold if the indicator exceeds . Values for the logistic pairs use pickle+float32; fBm values use .
Fourier-Bounded Complexity (Spectral Entropy)
Justified by the Staiger [36] identification of Hausdorff dimension with the entropy of a language, we use the spectral entropy as a Fourier-domain complexity proxy. Given a real-valued time series , we proceed through the following steps:
- 1.
- Detrending. Subtract the mean: , . (Optionally, a linear trend can be removed and a window function applied to mitigate spectral leakage, though in our implementation we use only mean subtraction.)
- 2.
- Discrete Fourier transform (DFT). Compute the one-sided DFT for :(An alternative method inspired by [44] to more directly approximate complexity via DFT is discussed in Appendix C.)
- 3.
- Power spectral density (PSD). Form the power at each frequency: , .
- 4.
- Normalisation to a probability distribution. Normalise so that :
- 5.
- Normalised Shannon spectral entropy. Compute:Note that the sum starts at and the normalising denominator uses rather than : detrending in Step 1 forces and hence , so only bins carry mass, and the maximum attainable entropy is .
A signal concentrated in one frequency (periodic) has ; white noise (flat spectrum) has . This serves as a Fourier-bounded proxy for Kolmogorov complexity. The informal chain holds rigorously only in restricted settings (for binary infinite sequences via Staiger [36] and Lutz [33] and for one-dimensional dynamical systems where a single Lyapunov exponent suffices); for higher-dimensional dynamics, the entropy rate–dimension relationship is mediated by the Lyapunov spectrum (Section 2.5), and on Gaussian-valued data, the approximation is qualitative rather than quantitative (Section 3.2.1, Table 2).
Remarks on Spectral Entropy
Unlike time-domain correlation, spectral entropy captures how energy is distributed across frequencies, making it responsive to subtle synchronisation in chaotic signals even when pointwise correlation is low. The choice of natural logarithm (used consistently in both numerator and normalising denominator) ensures . Spectral entropy is closely related to the spectral flatness measure in signal processing and to the inverse participation ratio in physics.
Ordinal and Permutation-Based Complexity Measures
An alternative class of complexity measures uses ordinal encodings. Permutation entropy measures the Shannon entropy of ordinal patterns extracted from the time series and has been widely used as a robust complexity indicator for non-linear dynamical systems. Because ordinal methods depend only on rank ordering rather than numerical precision, they are less sensitive to floating-point representation and may serve as useful robustness checks alongside compression-based estimators such as [43].
Pearson Correlation
For completeness (and since this indicator is used throughout the experiments alongside our complexity-based indicators), the empirical Pearson correlation of two real-valued series and is
The binary-string counterpart used in the theoretical section is given by Definition A1 in Appendix A; the two formulas coincide when real-valued entries are restricted to .
Computational Cost
All complexity estimators are lightweight. For a time series of length (our standard experimental setting), on a single core of a standard workstation (Intel i7, 3.2 GHz), LZ compression via zlib takes approximately 0.3 ms per series (including byte serialisation); spectral entropy computation takes approximately 0.8 ms (dominated by the FFT). The zlib compression step is approximately linear in the input length in the regime considered here (zlib’s DEFLATE uses a fixed-size sliding window of 32 KB and hash chains, giving amortised linear cost in N), while the FFT used for spectral entropy has complexity.
A structural advantage worth highlighting is that depends only on the individual marginal complexities and , not on any joint quantity, so for a population of K candidate series, the LZ values can be cached per series and reused across all pairs: only K compressions are needed in total, not . The Pearson correlations themselves remain per-pair at each. Concretely, screening all pairwise correlations among series (≈500,000 pairs) requires ≈0.3 s for all LZ computations (cached), ≈0.8 s for all spectral entropies (cached), and the remaining cost is the ≈500,000 Pearson evaluations themselves; the complexity-related overhead is negligible relative to the correlation computation. The contrast with the Normalised Compression Distance (Section 6) is structural: NCD requires pairwise compressions of concatenated series and cannot be cached the same way.
3.3. Complexity-Similarity Indicators
3.3.1. (Complexity Similarity Only)
It might be suggested that we can measure how similar the complexities of the two series are according to:
However, while it is true that when two series are equally complex, this does not capture whether they are jointly complex. Two simple series with identical low LZ complexity will have , thereby incorrectly suggesting that the high-complexity criterion is met.
3.3.2. Shortlist of Candidate Joint-Complexity Indicators
To require that both series individually have high complexity, five natural candidates suggest themselves:
The first four are all generalised means of the two individual complexities, satisfying by the power-mean inequality; all four collapse to on equal-complexity pairs. The fifth () is a fundamentally different construction based on the Normalised Compression Distance (Section 6) that detects joint dependence rather than joint complexity; we include it here only for completeness and return to it in Section 6.
3.3.3. How the Four Means Differ on Asymmetric Pairs
Since all four means agree on symmetric pairs, the comparison is driven entirely by asymmetric ones. Table 4 reports the values on four representative asymmetric pairs drawn from the logistic map and fBm, together with the screening decision each indicator would make at threshold .
3.3.4. Theoretical Guidance vs. Practical Robustness
Proposition 2 gives a formal hint: exponential suppression of spurious alignment requires , so the theorem’s minimal hypothesis is only that at least one series be sufficiently complex. That would suggest . In practice, however, the screening task is asymmetric: the false-positive risk comes from the case where one series is a simple monotone trend and the other is noisy, precisely the scenario where is blind (row 1 of Table 4). A practical screening indicator should flag this case as untrustworthy, which rules out.
Of the three remaining candidates (geometric mean, harmonic mean, min), all three correctly flag the asymmetric logistic pair as simple. They differ mainly in how aggressively they penalise moderate asymmetry: the geometric mean is the gentlest, the harmonic mean intermediate, and the min the most conservative. Which is preferable depends on the user’s trade-off between false positives and false negatives. On this paper’s toy models, these three indicators give identical screening decisions at every threshold we consider:
- On the chaotic coupling sweep, throughout.
- On the independent-pair false-positive sweep , the three means agree to within at every r.
- On the fBm asymmetric pair under int8 quantisation (row 4), the three means disagree substantially in magnitude but all three screen the pair as “trustworthy” at .
3.3.5. Our Recommendation: as Primary, as Principled Alternative
Following Occam’s razor, we adopt
as the primary joint complexity indicator throughout the remainder of this paper. It is the simplest of the three non-pathological candidates, the most conservative (strictly underestimates the geometric mean), and gives identical screening decisions to the other two on all experiments in this paper. Readers who prefer a smoother indicator with the same operational behaviour may substitute without changing any conclusion, as reported alongside for representative pairs in Table 4.
3.3.6. What Not to Do
As a cautionary counterexample, an early draft considered the indicator , which combines the floor with an asymmetry penalty. This is pathological: a pair with complexities scores 0.1—lower than two uniformly simple series at which score —directly contradicting the design goal. Any indicator that penalises asymmetry in addition to taking a low aggregate of the two complexities will have this failure mode; the generalised means are the natural family because they respect the ordering constraint .
Remark 2.
Note the distinction between and . The joint complexity indicator is a screening criterion evaluated before inspecting a reported correlation: a pair is flagged as complexity-trustworthy only if for some empirically chosen threshold θ. The similarity indicator instead measures whether the two series converge in complexity as a function of coupling strength ε and is the quantity plotted in the numerical experiments of Section 4. The two serve entirely different purposes.
3.3.7. Interpretation Table
The joint indicator should be read together with the magnitude of the Pearson correlation. Table 5 summarises the intended interpretation.
Table 5.
Interpretation of Pearson correlation together with the joint LZ-complexity screening indicator . High correlation with high is treated as worth further investigation, whereas high correlation with low is treated as suspicious because it may be driven by shared low-complexity structure.
A high- pair with high is therefore not a causal conclusion: it merely survives the low-complexity spurious-correlation screen. Common drivers, confounding, non-stationarity, and model misspecification must still be addressed by domain-specific analysis or causal-discovery methods.
Figure 3 illustrates the distinction between the similarity score and the joint screening score on coupled logistic maps.
Figure 3.
Joint-complexity screening on coupled logistic maps with under pickle+float32 serialisation (). (Left) (red dashed) and (blue solid) as functions of the coupling strength . At , the two maps are independent and individually complex, giving . Near the pre-synchronisation transition window , both marginal complexities collapse from approximately to approximately , and hence drops sharply. After full synchronisation, around , the maps again trace a common chaotic orbit and returns to approximately . In contrast, remains close to zero throughout because the two marginal complexities track one another closely; it therefore detects similarity of complexity levels but not whether the shared complexity is high or low. (Right) scatter plot of coloured by . Weak coupling produces low-correlation, high-complexity pairs; strong coupling produces high-correlation, high-complexity pairs; and the transition window produces low-, intermediate-to-high-correlation points. The red dashed lines mark the reference screening thresholds and .
4. Experiment 1: Coupled Logistic Maps
This section provides empirical validation on a fully controlled toy model: two symmetrically coupled logistic maps. The logistic parameter r tunes each map’s complexity continuously from periodic (low r) to chaotic (high r), while the coupling sets the true degree of dependence—making it the ideal benchmark for testing whether correctly separates spurious from genuine correlations. We report three interlocking results: (i) complexity along the bifurcation diagram tracks the Lyapunov exponent; (ii) false-positive rate of Pearson correlation is determined almost entirely by complexity and not by ; and (iii) detects a pre-synchronisation collapse of individual complexity just before the transition coupling .
4.1. Coupled Logistic Map Model
We use two symmetrically diffusively coupled logistic maps:
with , , transient of 1000 iterates discarded, recorded. The coupling determines the strength of correlations between the two series. We use two dynamical regimes, one of low and one of high complexity:
- : period-2 orbit (low complexity, );
- : fully developed chaos (high complexity, ).
The logistic parameter determines the complexity of the time series. For values , the series are simple, while for most larger values of r, the series is chaotic and complex. Figure 3 illustrates the contrast between and on the chaotic coupled maps. at , correctly identifying the independently generated chaotic series as jointly complex; throughout and is therefore uninformative about the absolute level of complexity. The right panel confirms that high correctly tags pairs as “genuine relationship” candidates once also becomes large.
4.2. Complexity Along the Bifurcation Diagram
Figure 4a shows LZ complexity, spectral entropy, and Lyapunov exponent as functions of the logistic parameter r. Complexity and the Lyapunov exponent rise together: positive marks chaos, and both and jump from near zero to near one as r crosses the period-doubling cascade. The vertical lines at and mark our two experimental regimes.
Figure 4.
Coupled logistic maps: complexity structure and synchronisation. (a) Complexity and the Lyapunov exponent along the bifurcation diagram. (b) Synchronisation indicators versus coupling. (a) Normalised LZ complexity (top; compressed length divided by original byte length), spectral entropy (middle), and Lyapunov exponent (bottom) vs. logistic parameter r. Complexity grows with chaos and tracks the Lyapunov exponent. For the one-dimensional logistic map in the chaotic regime, the entropy rate equals the positive Lyapunov exponent (), so and are useful proxies for entropy-rate/algorithmic-complexity behaviour. The connection to attractor dimension is indirect and, for higher-dimensional dynamical systems, additionally depends on the full Lyapunov spectrum (Section 2.5). (b) Synchronisation indicators vs. coupling for (left) and (right). The secondary axis (right side of each panel, dotted lines) shows the individual LZ complexity values . In both regimes, the two individual complexities track one another almost exactly, so stays flat at zero throughout. In the chaotic regime, both individual complexities collapse together symmetrically in a narrow window around , just before the synchronisation threshold marked by the vertical dotted line; this joint collapse is invisible to but visible in (Figure 3).
4.3. Synchronisation Indicators vs. Coupling
Figure 4b shows and as functions of for both regimes. The secondary y-axis shows the individual LZ complexity values and , which are crucial for interpreting in context.
A key empirical observation is that the two individual LZ complexities track one another almost exactly throughout the entire sweep, in both the periodic and the chaotic regimes: the maximum over our sweep is ≲0.001. As a consequence, is essentially flat at zero everywhere, including across the synchronisation transition. This matters because it falsifies a tempting interpretation of the pre-synchronisation phenomenon: the dip we observe is not an asymmetric event in which one trajectory collapses onto a periodic attractor while the other remains chaotic (which would drive to ). Instead, both trajectories simplify together symmetrically as the system is forced toward a common simpler attractor; both values fall together while their difference stays near zero.
The early-warning signature is therefore visible in but not in : as shown in Figure 3 (left), drops sharply from ≈0.89 to ≈0.01 in a window around , just before the synchronisation threshold , signalling the imminent collapse of joint complexity. Since measures only the difference of complexities and the collapse is symmetric, records nothing. This is a concrete demonstration of why the level-based is the operationally useful indicator and the difference-based is not.
Synchronisation Threshold
For the chaotic regime, there exists a critical coupling above which the two maps achieve full synchronisation (i.e., for all n after transients). This threshold can be predicted from the transversal Lyapunov exponent. Define
where is the maximal Lyapunov exponent of the uncoupled logistic map at . Full synchronisation ( for all n) occurs when , giving
Below , Pearson remains near zero despite genuine coupling—this is the regime where complexity-based indicators provide early warning of synchronisation.
4.4. False Positive Rate vs. Complexity
The core claim of this paper is that simple series produce more spurious correlations. We verify this directly: for each , we generate 200 independent pairs (different initial conditions, ) and record the fraction with , i.e., correlations of non-trivial magnitude.
The result is stark (Figure 5a): periodic series always spuriously correlate because their symbolic itinerary is low-complexity (a finite, eventually periodic orbit), whereas chaotic series never spuriously correlate because they have positive entropy and generate high-complexity symbolic itineraries, even though the state space is one-dimensional. The logistic map’s own bimodal complexity distribution— in the periodic regime and in the chaotic regime, with almost no values in between except in narrow periodic windows—means the 5% crossover is not resolved by this model; it occurs somewhere inside the narrow bifurcation at . The screening threshold adopted in Section 7 is a conservative operating point for this bounded logistic setting: it assigns all periodic pairs to "screen out" and all chaotic pairs to "screen in". The smoother fGn experiment (Figure 6b) provides the complementary family-level false-positive calibration as a function of memory/smoothness.
Figure 5.
Coupled logistic maps: false positives and sample trajectories. (a) False-positive rate versus complexity. (b) Representative short time series at weak coupling. (a) False-positive rate (fraction of independent pairs with ) vs. mean LZ complexity (left) and vs. (right), coloured by r. The dashed horizontal line marks the 5% significance level; the dotted vertical line in the right panel marks the screening threshold . At (periodic, –): false-positive rate . At (chaotic, ): false-positive rate . The transition is essentially bimodal: the logistic map has a sharp chaos onset near , so there is very little intermediate population, and FP rate drops from 100% to 0% over a narrow window in r. Points in the mid-range – correspond to periodic windows embedded in the chaotic region (e.g., the period-3 window near ) and show intermediate FP rates of 60–75%. (b) First 200 iterates of (blue) and (red dashed) at . (Left) (periodic). (Right) (chaotic). Both series at look independent despite genuine coupling, illustrating why LZ-based early warning is valuable.
4.5. Short Time Series Examples
Figure 5b shows representative time series at for both regimes, with complexity and correlation statistics annotated. The periodic case () shows perfectly synchronised square-wave-like orbits even at very weak coupling; the chaotic case () shows independent-looking wandering despite the same .
4.6. Summary of Experiment 1
The coupled logistic map experiment provides clean, controlled evidence for this paper’s central claim, because the complexity of each series can be tuned continuously via r while the true coupling strength is known exactly. Three interlocking results emerge.
4.6.1. Complexity Determines False-Positive Rate, Not Coupling
The most direct test is the false-positive experiment (Section 4, Figure 5a): independent pairs () at produce spurious correlations in 100% of trials, whereas independent pairs at produce zero false positives. The transition is monotone in but not smoothly resolved: the logistic map’s chaos onset at is sharp, so jumps from ≈0.02 to ≈0.88 across a narrow r-window and the 5% crossing is contained within it. The underlying reason is dynamical: periodic orbits have a low-complexity symbolic description (a finite, eventually periodic set of values), so any two period-k orbits with similar r are trivially correlated regardless of whether they share any causal connection. Chaotic orbits, by contrast, have positive entropy and produce high-complexity, effectively aperiodic symbolic itineraries that cannot accidentally align, even though the logistic state space is itself one-dimensional. The fGn experiment of Section 5 resolves the smooth-process false-positive transition more precisely as a function of H.
4.6.2. Captures Joint Complexity; Does Not
A subtler finding concerns what happens when the two maps are genuinely coupled. measures the difference of individual complexities, which is nearly zero for both regimes (the two maps always have similar ) and is therefore uninformative about whether that shared complexity is high or low. The instead measures the level of joint complexity: it reads ≈0.89 for the independent chaotic maps at , correctly tagging them as jointly complex; it reads ≈0.01 for the periodic maps, correctly flagging their correlation as unreliable. The right panel of Figure 3 makes this concrete: the scatter cleanly separates into the correct quadrants.
4.6.3. Complexity Collapses at the Synchronisation Transition
A physically interesting side-effect of the is that it detects the synchronisation transition in the chaotic regime. Just before the critical coupling , the two maps are being forced toward a common simpler attractor; in this brief window, both individual complexities and drop together from ≈0.89 to ≈0.01, while their difference (and hence ) stays near zero. Because tracks the level of joint complexity rather than its asymmetry, it dips sharply to ≈0 across this window. Once full synchronisation is achieved (), the two maps again trace a common high-complexity chaotic orbit, and recovers to ≈0.89. This dip is a genuine pre-synchronisation warning visible in but invisible in (which is flat at zero throughout, since both complexities move together), providing a concrete illustration of why the joint screening criterion is more informative than the difference-based one.
4.6.4. Practical Takeaway
When reporting a correlation between two time series, the first question to ask is not whether is large but whether is large. A high correlation among high-complexity series (top-right quadrant of Figure 3) is substantially less likely to be explained solely by shared low-complexity structure and is therefore worth investigating further—though it does not, by itself, establish causation or rule out common drivers, confounding, or model misspecification. The same correlation among low-complexity series (bottom-left quadrant) is essentially uninformative: simple series are, by Solomonoff’s prior, exponentially more likely to align by chance, and the logistic map experiment confirms this quantitatively.
4.6.5. Uncertainty Quantification
The false-positive rates reported in Figure 5a are empirical proportions from 200 independent pairs per r-value. Treating each pair as a Bernoulli trial, the Wilson 95% confidence intervals at the two endpoints of the curve are at (observed FP rate ) and at (observed FP rate ); the separation of the two regimes is therefore not in doubt within these intervals. In the narrow transition window , the periodic windows embedded in the chaotic region (e.g., the period-3 window at ) produce intermediate FP rates of 60– with 95% Wilson CIs roughly percentage points wide; the qualitative transition shape is robust under these intervals.
5. Experiment 2: Multivariate Fractional Brownian Motion
The multivariate fractional Brownian motion (mfBm) [45] provides a second toy model, complementary to the coupled logistic maps of Section 4. It is analytically tractable in a different way: the Hurst parameter H directly controls the roughness and classical Hausdorff dimension of the paths (), giving a continuous family decoupled from any coupling parameter. We use this structure to (i) compare finite-resolution complexity proxies with the theoretical Hausdorff dimension on fBm paths (the signal is modest under fine serialisation and much sharper under coarser encodings, as reported below); (ii) demonstrate the Yule nonsense-correlation phenomenon for smooth (high-H) fBm paths and its sharp dependence on path roughness; and (iii) calibrate false-positive risk as a function of the memory/smoothness family.
5.1. Model
A p-multivariate fractional Brownian motion (mfBm) with Hurst parameters is the unique Gaussian, H-self-similar process with stationary increments:
Its covariance structure is given by Proposition A1 in Appendix B. The increments of each component, the fractional Gaussian noise (fGn), are a stationary process with covariance .
Key Property: Hausdorff Dimension
The graph of (as a subset of ) has Hausdorff dimension [46]. Thus:
- (rough, highly irregular): , high LZ complexity.
- (smooth, trending): , low LZ complexity, behaves like a random walk.
This dimension statement is about the fBm path graph. The stationary fGn increments inherit the same Hurst parameter as a memory/smoothness coordinate, but they are not themselves governed by the graph-dimension identity . We therefore use H in two related but distinct ways: as a Hausdorff-dimension coordinate for fBm paths, and as a family parameter for calibrating false-positive risk in stationary fGn. The empirical prediction is that spurious correlation rates should decrease as H decreases, i.e., as the associated paths become rougher and the stationary increments become less smooth/less persistent.
We simulate fGn exactly using the Wood–Chan circulant embedding algorithm [47]. All mfBm experiments use time steps and 500 independent trials per Hurst value, with the Hurst grid .
5.2. Complexity Proxies on fBm Paths
A first question is whether the pointwise complexity proxies track the theoretical Hausdorff dimension for fBm. The prediction is that rough paths (H small, close to 2) should have higher than smooth paths (H close to 1, close to 1). We find this prediction qualitatively confirmed but quantitatively modest under this paper’s main serialisation (pickle+float32): on fBm paths () decreases from at to at —a monotone but shallow trend of about across the full roughness range. Spectral entropy shows a larger and more monotone decrease over the same range. Figure 6a presents both.
Figure 6.
fBm complexity and the central false-positive result. (a) LZ complexity (left), spectral entropy (centre), and both vs. Hausdorff dimension (right) on fBm paths as functions of the Hurst parameter H. Spectral entropy decreases monotonically as H increases, tracking the decrease in theoretical dimension . under pickle+float32 shows the same monotone trend but with a much smaller magnitude; finer serialisations (struct+float64, int16) saturate near the compression limit and make the trend invisible, while coarser serialisation (int8) recovers it with a larger range (Table 2). See Section 3.2.1 for discussion. (b) False-positive rate () for independent pairs of fGn (blue) and fBm paths (red), measured over 500 independent trials at each of 12 values of ( per realisation, pickle+float32 serialisation). (Left) vs. Hurst H. (Centre) vs. mean . (Right) vs. the associated fBm path dimension (used as a calibration coordinate, not as a theorem about fGn increments). The fGn curve empirically supports the qualitative prediction: rough/less persistent stationary series essentially never produce spurious correlations at (FP rate for ), while smooth/persistent series do so increasingly often as (7.2% at , 20.8% at ). The 5% threshold is crossed around (equivalently, for the associated fBm path, ), as read off the left panel. The fBm paths (red) are non-stationary and produce spurious correlations in 27– of trials regardless of H, replicating the classical Yule nonsense-correlation phenomenon. This underscores that the complexity diagnostic must be applied only after ensuring stationarity; see Remark 3. In the centre panel, the fGn points cluster near for all H (the pointwise estimator saturates on Gaussian-valued data under pickle+float32, as shown in Table 2); the false-positive transition is therefore better read off the left panel (as a function of H) than off the centre panel (as a function of ). At the smooth end of the grid, the Davies–Harte exact-circulant method of [47] fails to produce a positive-semidefinite embedding for at , so we restrict the grid to ; the trend is monotonically increasing throughout.
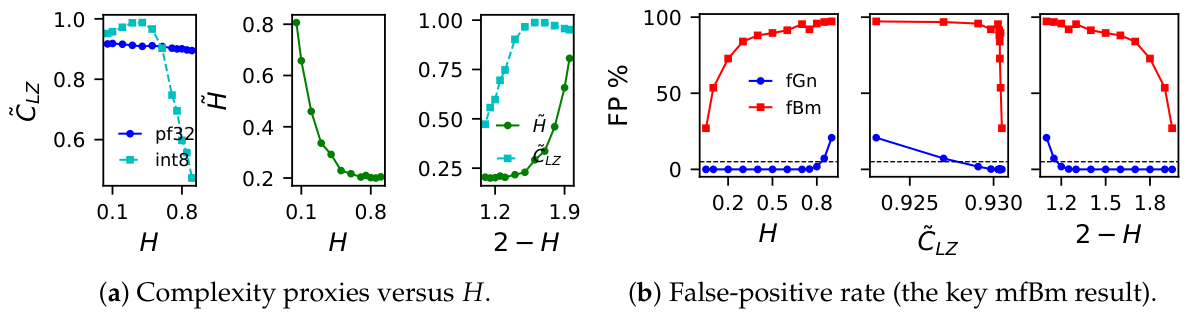
5.2.1. The Signal Sharpens Under Coarser Serialisation
The modesty of the -versus-H signal under pickle+float32 is an artefact of the serialisation rather than of the data: on the same fBm paths, int8 quantisation reveals a much larger range (Table 2, at down to at ) because coarse quantisation of smooth paths produces long runs of identical bytes that LZ exploits. Symbolic encodings adapted to the specific dynamics—the classical left/right partition for interval maps, partition-based encodings for attractors—typically give even sharper discrimination. We keep pickle+float32 in the main figures for continuity with this paper’s original implementation and note the serialisation-dependence as a feature rather than a flaw.
5.2.2. Why the Framework Still Works
The screening argument in this paper rests on two separable claims: (i) in the binary-string model, high Kolmogorov complexity suppresses spurious Hamming/Pearson alignment under the hypotheses of Proposition 2; and (ii) empirically, smooth or persistent real-valued series produce many spurious correlations while rougher stationary series produce few. Claim (ii) is the operationally testable one for fGn/fBm data, and it is a statement about pairs of series rather than individual compression values. As Section 5.3 shows, the false-positive rate under independent-pair fGn is a sharp function of H at , 500 trials per Hurst (going from ≤1.8% at to at and at ) even when the pointwise scale is compressed. The pointwise estimator is a practical proxy when the encoding has useful dynamic range; in Gaussian-increment families where it saturates, the pairwise Pearson false-positive curve is the empirical calibration target.
5.3. False Positive Rate: The Key mfBm Result
Figure 6b shows the main result for the mfBm toy model. For stationary fGn increments at over 500 trials per Hurst (with Wilson 95% confidence intervals computed on the binomial proportion):
- – (rough to mildly smooth; associated fBm path dimension ): false positive rate (CI upper bound ; essentially zero for ).
- : false positive rate (95% CI ; just past the 5% threshold).
- : false positive rate (95% CI ).
The separation between rough and smooth regimes is therefore not in doubt within these intervals. For the non-stationary fBm paths, false-positive rates are uniformly high (27–97%) across all H—this is exactly the Yule nonsense-correlation phenomenon [6,7]: integrated non-stationary series spuriously correlate regardless of their roughness. Note that the LZ complexity diagnostic alone does not flag this case: under pickle+float32, fBm paths have , slightly below the corresponding fGn (≈0.93) but within a window narrow enough that the pointwise complexity does not cleanly separate stationary from non-stationary regimes (Table 2). The appropriate response is the two-stage pipeline of Remark 3: first test for stationarity and difference if needed, then apply the complexity screen to the stationary residual.
Remark 3
(Stationarity and complexity are distinct diagnostics). It is important to distinguish the roles of stationarity and complexity. The fBm paths illustrate that non-stationarity (specifically, integrated processes with stochastic trends) can produce spurious correlations regardless of the roughness of the increments. The pointwise LZ complexity does not cleanly separate fBm paths from their fGn increments under pickle+float32 serialisation (Table 2): both are Gaussian-valued and saturate the estimator near –. The practical implication is that our framework should be applied in two stages: (1) test for stationarity (e.g., ADF test [9]) and first-difference if needed; (2) apply the complexity diagnostic to the stationary residuals. The fGn results (Figure 6b) support the qualitative prediction that stationary rough/less persistent series produce fewer false-positive correlations than smooth/persistent ones. The formal guarantees of Section 2, however, remain binary-string results; the real-valued compression workflow is an empirically calibrated diagnostic in this setting.
Figure 7a shows the distribution of Pearson for independent pairs at (rough) and (smooth). The smooth series distribution has heavy tails far beyond the threshold, while the rough series distribution is tightly concentrated near zero.
Figure 7.
fGn roughness, correlation distributions, and bivariate regimes. (a) Sample paths and Pearson- distributions for rough versus smooth fGn. (b) Four regimes of bivariate fBm. ((a) Left) fGn sample paths for different H (rougher = lower H = less persistent; for the associated fBm path, corresponds to a rough graph with dimension , while corresponds to a smoother graph with dimension ). (Right) distribution of Pearson for 500 independent fGn pairs. Smooth series (, red) have a wide distribution with many spurious correlations; rough series (, blue) are tightly concentrated near zero. (b) Four parameter regimes of bivariate fBm ( per panel, an illustrative length distinct from the used in the quantitative false-positive sweep of Figure 6b). (Top row) rough (). (Bottom row) smooth (). (Left column) uncorrelated target (). (Right column) correlated target (). Each panel annotates the realised and under pickle+float32. Note the smooth uncorrelated case (bottom-left) can show appreciable purely from the shared random-walk structure—a spurious correlation. The values saturate near on Gaussian paths under pickle+float32 (Section 5.2), so the discrimination here is qualitative; the quantitative discrimination on Gaussian data comes from the pairwise false-positive curve (Figure 6b) rather than from the pointwise estimator.
5.4. Bivariate mfBm: Genuine vs. Spurious Correlation
Figure 7b shows bivariate fBm paths under four combinations of roughness and target correlation . The key distinction:
- Smooth () and uncorrelated (): both series drift similarly due to random walk behaviour— can be appreciably non-zero despite no true correlation, the Yule phenomenon.
- Rough () and correlated (): the observed correlation reflects genuine dependence because independent rough series would not align.
5.5. as a Screening Criterion for mfBm Pairs
The joint complexity indicator can be evaluated on any pair of fGn series and used as a pre-screening step before trusting a reported . As observed in Section 5.2, however, under this paper’s main serialisation saturates around for all , so on a single pair of fGn series carries limited information in absolute terms. For stationary Gaussian-valued fGn under pickle+float32, pointwise saturates and is not an effective absolute threshold. In this regime, the useful calibration is instead the false-positive curve as a function of the memory/smoothness parameter H (or an estimated surrogate-family parameter). Thus, the fGn experiment calibrates the risk of Pearson false positives across a complexity-spanning family rather than providing a universal numerical cutoff on . The wider int8 dynamic range in Table 2 occurs on non-stationary fBm paths, not on fGn increments, and therefore should not be used as an increment-level screening threshold.
Where does retain a useful screening role on mfBm data is the non-stationary case. fBm paths themselves (as opposed to their fGn increments) are non-stationary and produce very strong spurious correlations [48]; differing from the stationary fGn is Step 1 of the recipe in Section 7 and picked up automatically by the stationarity check in Remark 3. On the stationary fGn itself, the diagnostic power of the framework comes predominantly from the pairwise false-positive curve of Figure 6b—which is measured directly rather than inferred from individual complexities—and from the surrogate calibration.
Remark 4.
The operating threshold used in is a calibrated threshold for the bounded logistic examples and for data classes/encodings where has useful dynamic range. It should not be read from the fGn complexity values. In the mfBm false-positive experiment, the left panel of Figure 6b gives a family-level risk calibration parameterised by H: the 5% transition occurs at , equivalently, for the associated fBm path graph, at . This transition cannot be re-expressed as an absolute cutoff because, under pickle+float32, the pointwise of fGn saturates near across the entire Hurst range (Table 2), and coarsening to int8 does not change this for fGn increments. The pronounced int8 drop to is exhibited only by the non-stationary fBm paths (Table 2), which the stationarity pre-step removes before screening. The mfBm model therefore calibrates false-positive risk as a function of the memory/smoothness family, not a universal numerical cutoff on .
5.6. Summary of Experiment 2
The mfBm experiment complements Experiment 1 by grounding this paper’s framework in continuous stochastic processes whose fBm path graphs have an analytically known Hausdorff dimension. Three main findings emerge.
5.6.1. Complexity and Hausdorff Dimension Are Empirically Linked
The Hurst parameter H controls the Hausdorff dimension of the associated fBm path exactly as . Figure 6a shows that this path-level theoretical quantity is tracked qualitatively—monotonically but not strongly—by under this paper’s pickle+float32 serialisation: on fBm paths varies only between ≈0.92 at and ≈0.90 at , a ∼2% relative trend over the full roughness range. The same data under int8 quantisation produce a much sharper trend ( at down to ≈0.50 at ; Table 2). Spectral entropy tracks this path-level dimension more strongly under all schemes. The pointwise estimator is therefore consistent with the Section 2 picture qualitatively but is a weak quantitative proxy for on Gaussian-valued data; the operationally meaningful signal is the pairwise false-positive rate of the next paragraph.
5.6.2. False-Positive Rate Is Controlled by the Memory/Smoothness Parameter H
The key result (Figure 6b) shows that spurious correlations among independent fGn pairs are suppressed as the memory/smoothness parameter H decreases (equivalently, as the associated fBm paths become rougher and have larger graph dimension); under pickle+float32, pointwise LZ complexity only weakly reflects this transition because saturates. The transition is sharp and monotone: pairs with have FP rates , while pairs at and produce spurious correlations in and of trials, respectively. The false-positive rate is the primary quantity of interest here; it is measured directly as a function of H in Figure 6b and drives the family-level risk calibration in Section 7. The centre panel of Figure 6b, which expresses the same rate against , is a post hoc reparameterisation; because saturates for fGn (Section 5.2), this curve should be read as showing the false-positive transition as H crosses into the very smooth regime, rather than as a monotone complexity-dependent law.
5.6.3. Non-Stationarity Is a Separate Confound That Complexity Alone Cannot Resolve
The fBm paths (as opposed to their fGn increments) show uniformly high false-positive rates regardless of H, replicating the classical Yule nonsense-correlation phenomenon. The appropriate response is to difference first (recovering the stationary fGn) and then apply the complexity screen. This two-stage pipeline (stationarity test → complexity screen) is the recommended practical procedure.
5.6.4. as a Screening Criterion on mfBm
On stationary fGn, does not function as an absolute or rank-based cutoff: as noted above, saturates for Gaussian-valued increments under pickle+float32, so on a single fGn pair carries little information. What the fGn experiment calibrates is the risk of Pearson false positives as a function of the memory/smoothness parameter H across a complexity-spanning family. The mfBm family therefore provides a natural calibration environment for screening risk, even though the absolute scale carries limited information on its own.
5.6.5. Direction of the Random-Shuffle Comparison
Random-shuffle surrogates destroy temporal dependence while preserving the one-point marginal distribution. Therefore, a smooth or strongly autocorrelated series should typically have lower compression complexity than its shuffled surrogate because the shuffle removes the temporal regularity and produces a more noise-like (less compressible) sequence. Conversely, a rough or nearly noise-like series may already lie close to its shuffled surrogate in compression complexity. Shuffle surrogates are thus useful for detecting temporal structure, but they should not be confused with the independent matched-memory surrogates used to estimate false-positive correlation rates (Section 7); the two answer different questions.
6. Comparison with Existing Spurious Correlation Diagnostics
A natural question is how the complexity-filtered correlation test relates to existing methods for detecting spurious correlations. We briefly discuss four alternatives and clarify the complementary role of our approach. Table 6 summarises the contrast in one place.
Table 6.
Existing spurious-correlation diagnostics and the proposed screen. Each method targets a different aspect of the problem and is best understood as complementary rather than competing.
The proposed screen is meant to complement, not replace, the methods above. We now discuss each in turn.
6.1. Permutation (Surrogate) Testing
The standard approach to testing whether an observed is statistically significant is to generate surrogate pairs by randomly permuting one series, compute for each surrogate pair, and reject the null hypothesis of independence if the observed exceeds the p-th quantile of the surrogate distribution [8]. For i.i.d. data, this controls the false-positive rate at any desired level. However, for time series with temporal structure (e.g., autocorrelation, periodicity, or long-range dependence), naïve permutation destroys the temporal dependence and produces anti-conservative p-values. Phase-randomisation surrogates [8] preserve the power spectrum but not higher-order structure.
Common surrogate-generation methods include random-shuffle surrogates for testing independence under an i.i.d. null, Fourier-transform surrogates that preserve the power spectrum while randomising the phase, and amplitude-adjusted Fourier surrogates that additionally preserve the amplitude distribution of the original signal [43]. These approaches test specific stochastic null models, whereas the complexity diagnostic proposed here instead evaluates the structural richness of the time series themselves.
It is important to recognise that surrogate testing and complexity filtering address fundamentally different null hypotheses and are therefore complementary:
- Surrogate testing asks: “Is the observed correlation consistent with the data being i.i.d. or linear noise?” A significant result means the correlation exceeds what would arise from the chosen null model.
- Complexity filtering asks: “Given the structural richness (complexity) of the series involved, how surprising is the observed level of correlation?”
A correlation can be “significant” against a red-noise null (surrogates reject) yet still be spurious if both series are simple monotone trends. This is precisely the class of cases highlighted by the Tyler Vigen examples (Figure 1). We recommend using both tools in tandem: surrogate testing to establish that the correlation exceeds what would arise from linear stochastic processes, and to assess whether the data are complex enough for that correlation to be informative.
6.2. Cointegration and Unit-Root Tests
For non-stationary series, the Augmented Dickey–Fuller test and Johansen cointegration test [9] are standard tools. These directly address the Yule phenomenon (integrated series spuriously correlate). Our recommendation to first difference or detrend non-stationary series before applying the complexity diagnostic (Section 9, Remark 3) is fully consistent with this classical approach. The complexity diagnostic adds value after stationarity is established by distinguishing genuinely complex stationary dynamics from simple periodic or near-periodic patterns that can also produce spurious alignment.
6.3. MDL-Based Causal Inference
Methods like GLOBE [10] and CASCADE [11] use the Minimum Description Length principle—a computable approximation to Kolmogorov complexity—to infer full causal DAGs. Our test is a lightweight screening step that can be applied before expensive causal discovery: pairs failing the complexity threshold (low ) are flagged as likely spurious without running a full MDL search.
6.4. Normalised Compression Distance (NCD)
A natural candidate baseline is the Normalised Compression Distance of Cilibrasi and Vitányi [23,24], a compression-based approximation to the Universal Similarity Metric:
where denotes the compressed length under a lossless compressor (we use the same zlib used for ). Theoretically, iff and are maximally algorithmically dependent (one a computable function of the other), and iff they are algorithmically independent.
It is important to recognise that and answer different questions:
- asks: are and algorithmically dependent? (Does one help compress the other?)
- asks: are and each individually complex enough that an observed Pearson correlation is unlikely to be accidental?
They are therefore complementary rather than competing: is a dependence detector, while is a reliability filter on Pearson correlations. A thorough workflow could use both in sequence: to decide whether a reported correlation is worth investigating, then to confirm algorithmic dependence directly.
6.5. Empirical Comparison on Coupled Logistic Maps
Figure 8 shows alongside and Pearson on the coupled logistic system for both regimes. The two complexity-based indicators behave qualitatively differently:
Figure 8.
(purple solid) and (green dashed) as functions of coupling for coupled logistic maps. (Left) (periodic). (Right) (chaotic). The red dotted line marks the screening threshold on . detects the algorithmic coupling of the two series (drops from at to once in the chaotic regime), while detects individual complexity (stays at throughout the chaotic regime apart from a narrow pre-synchronisation collapse window and stays at throughout the periodic regime). The two indicators are complementary rather than competing: NCD answers “are these series joint-compressible?”; answers “are these series individually complex?”.
- In the chaotic regime (), as coupling increases from to , drops monotonically from (algorithmically independent) at to (maximally dependent) once , correctly detecting the synchronisation transition. Over the same sweep, stays at outside the narrow pre-synchronisation window , where it momentarily collapses to together with the individual complexities (the symmetric joint-collapse phenomenon of Section 4); for , it returns to because both series continue to trace high-complexity chaotic orbits, just the same orbit after synchronisation. Both indicators thus carry information, but about different physical quantities: NCD encodes pairwise dependence; encodes pointwise complexity. They agree on the screen verdict (“trustworthy” on both sides of the transition window) but disagree on the dependence structure (NCD low after sync; blind to coupling per se).
- In the periodic regime (), across all (partial dependence from the shared period-2 structure) while across all (both series are simple and compressible; cf. the pickle+float32 periodic value in Table 2).
Both behaviours are correct, and neither indicator can substitute for the other: cannot tell us that synchronised chaotic maps are dependent (they both look complex individually), while cannot tell us that the spurious Pearson in the periodic regime is coming from simple, near-identical orbits rather than a genuine coupling signal.
6.6. When Is Preferable
For the specific task of screening a reported Pearson correlation—“is this number worth trusting?”— has three practical advantages: (i) Computational cost. is structurally cheaper for screening tasks. For a population of K candidate series, requires only K individual compressions (each with zlib’s bounded-window DEFLATE) since the indicator depends on the two marginal complexities and these can be cached per series and reused across all pairs. NCD, by contrast, requires pairwise compressions of the concatenated series at each since the joint compressed length cannot be obtained from the marginals. The asymptotic gap is therefore vs. in compressions; for , this is roughly three orders of magnitude. (ii) Calibration: the threshold or family rule for can be calibrated using independent surrogate or complexity-spanning calibration ensembles (Section 7); lacks an equally clean calibration. (iii) Design intent: is designed to complement Pearson correlation, whereas replaces it with a different similarity measure altogether.
6.7. When Is Preferable
Conversely, has genuine advantages: (i) Metric structure: is (approximately) a metric on the space of sequences, with strong information-theoretic guarantees [24]; is a heuristic screening indicator. (ii) Direct dependence detection: if the question of interest is “are these two sequences algorithmically related?” (e.g., phylogenetic inference, plagiarism detection), answers it directly, whereas only rules out trivial spuriousness. (iii) Fine-grained similarity: in the intermediate regime , it gives a continuous similarity score; gives only a pass/fail decision at the chosen threshold.
7. Threshold Selection and Sensitivity
The false-positive rate thresholds ( for logistic maps, for fGn) and the threshold of deserve justification.
For the correlation thresholds, we chose in the logistic experiment because the periodic regime () produces deterministic orbits where exactly, so any reasonable threshold yields the same qualitative result. The fGn experiment uses the stricter because the effect is subtler for stationary Gaussian processes; we verified that the monotone relationship between false-positive rate and Hausdorff dimension persists for thresholds , and (the curves shift vertically but the ordering is unchanged).
For the threshold, the value is motivated by a two-step argument. First, Table 2 shows that under pickle+float32 serialisation, a truly periodic logistic trajectory has , so the noise floor in the idealised periodic case is effectively zero. The practical floor is set instead by finite-sample effects, small departures from pure periodicity, and (analytically) the Posobin–Shen contribution from measurement noise: for typical noise rates , the analytical floor sweeps the interval (Section 2.6), with the upper end close to . For , we observe for smooth logistic signals (periodic windows, damped oscillations) in the noiseless case; the screening threshold must be strictly above this floor and should be re-calibrated upward when measurement noise is substantial. Second, the fGn false-positive experiment (Figure 6b, left panel) provides family-level calibration for the smooth-process regime: the false-positive rate drops below 5% as H falls below ≈0.83. This transition is parameterised by H rather than by an absolute value: under pickle+float32, the pointwise of fGn saturates near for all H, and even under int8 it remains near for all H (Table 2), so the transition is invisible in space under either serialisation. Calibration must therefore be performed by estimating false-positive risk across a complexity-spanning family parameterised by H (or by an estimated memory/smoothness parameter), rather than by ranking against a matched-memory null or by applying a fixed threshold. The value is retained as a conservative operating point for the bounded logistic pipeline; for fGn-type Gaussian-valued processes, the pointwise under pickle+float32 sits near for all H (Table 2), so risk calibration must be parameter-family-based rather than an absolute or rank-based test.
7.1. Do Not Transfer fBm-Path Thresholds to fGn Increments
It is important not to confuse thresholds calibrated on fBm paths with thresholds calibrated on fGn increments. The stationarity-first workflow recommends applying the complexity screen after differencing non-stationary paths, when differencing is appropriate; therefore, if the analysed object is the stationary increment process, must be calibrated on fGn-like calibration ensembles, not on the original fBm paths. In particular, the int8 compression transition observed for smooth fBm paths should not be used as an absolute threshold for fGn increments: for fGn under the encodings considered here, pointwise may remain near saturation across H, so the false-positive transition is better captured by the pairwise correlation false-positive curve (Figure 6b) than by a universal pointwise compression threshold. We therefore do not recommend a universal value for all Gaussian processes and all encodings: should be understood as a toy-model threshold for the documented serialisation and calibration ensemble. For stationary Gaussian increments, threshold selection must be repeated on a calibration family that spans the relevant smoothness or memory parameter.
7.2. Practical Recipe for Threshold Selection
We consolidate the threshold discussion into the following step-by-step procedure:
- Compute for the pair of series under consideration.
- Establish a noise floor. Under pickle+float32 serialisation, a truly periodic logistic orbit gives ; smooth but non-periodic dynamics typically give (for ). For Gaussian-valued processes such as fGn, saturates near for all Hurst parameters under pickle+float32 (near under struct+float64), so the threshold discussion proceeds via surrogate calibration (Step 3) rather than against an absolute floor.
- Generate surrogate and calibration distributions for independent pairs under the null hypothesis of independence. Two distinct purposes must be kept separate here: local surrogate assessment (is this correlation surprising within this marginal class?) and global threshold calibration (which complexity threshold to use across classes?).
- (a)
- Local surrogate assessment (matched-marginal independent surrogates). Given the observed pair , generate independent surrogates that preserve the relevant marginal features of and —length, marginal distribution, variance, and, when appropriate, the memory or smoothness class—and compute on them. This estimates the probability that a correlation as large as the observed one could arise under independence within the same marginal class. It is the most general construction and works for any data class. Note, however, that if the surrogates are matched in smoothness, marginal distribution, and memory, their values may be nearly constant, so this construction alone cannot select a global threshold.
- (b)
- Global threshold or family calibration (complexity-spanning ensemble). A global screening rule cannot be calibrated from a single matched-marginal surrogate class if that class has nearly constant . For signal classes where has meaningful dynamic range, one needs a calibration ensemble that spans a range of complexities—for example an H-sweep of fGn or fBm surrogates, a parameter sweep over dynamical regimes, or a mixture of representative null models. Such a family allows one to estimate as a function of . If the Hurst exponent of stationary Gaussian-increment data is approximately known (or estimable from the spectral slope), the false-positive risk should instead be read from the mfBm curve as a function of H (Figure 6b, left panel).
In short: matched surrogates answer “Is this correlation surprising within this marginal class?”; they do not, by themselves, answer “Which global complexity threshold should be used across classes?”. We also deliberately do not recommend permuting one series and recomputing on the permuted pair: this construction is uninformative for the min-based indicator, since collapses to as under permutation, and the observed is by construction always , making the comparison one-sided and trivial. - Set the threshold or family rule. For signal classes and encodings where has meaningful dynamic range, calibrate against the conditional false-positive rate of as a function of the screening indicator: evaluate across the complexity-spanning calibration population of Step 3 and choose the smallest at which this conditional rate falls below the desired significance level (e.g., ). The value is calibrated and valid for the bounded logistic examples (). For stationary Gaussian increments under fine serialisation, however, saturates; the mfBm curve of Figure 6b should therefore be read as a false-positive calibration as a function of H or the relevant memory/smoothness parameter, not as an absolute cutoff.
- Screen: if the data class has a calibrated threshold and , and is large, the correlation is “complexity-supported” and warrants further investigation. If , flag the correlation as potentially spurious regardless of . For saturating Gaussian-increment data, use the estimated memory/smoothness family and false-positive curve instead of an absolute or rank-based cutoff.
The quadrant diagram (Figure 9) provides the primary interpretive tool; the numerical threshold is secondary and should be adapted to the application domain.
Figure 9.
The four regimes of (complexity, correlation), illustrated on the coupled logistic map. Annotated values of and are empirical (pickle+float32 serialisation, ). (Top-left) (simple, independent ICs, , ): two independent period-2 orbits phase-lock in phase in steady state, so despite zero coupling— regardless, a clean illustration of why classical is uninformative for simple systems. correctly flags the pair as untrustworthy. (Top-right) (simple, weakly coupled): same attractor, , same conclusion. (Bottom-left) (complex, independent, , ): two chaotic trajectories are visibly uncorrelated () and confirms joint complexity. (Bottom-right) (complex, strongly coupled ): synchronised chaotic trajectories with , so , and indicates that the correlation is supported because both series individually remain complex. correctly assigns high scores only to the two bottom cases; the two top cases are screened out regardless of .
Figure 9 illustrates this paper’s central message with concrete examples from the logistic map in all four complexity-correlation regimes.
8. Illustration on Stylised Real-World Patterns
While our main results are demonstrated on controlled toy models (where ground truth is known), we briefly illustrate how the complexity diagnostic applies to real-world-like patterns.
8.1. Monotone Trends (Tyler Vigen Class)
The canonical spurious correlations of Figure 1 involve nearly monotone time series (e.g., the distance between Neptune and the Sun, or the popularity of a name over time). Such series have very low LZ complexity (–) because a monotone trend of length N can be encoded by its start, end, and a short polynomial description. Any pair of such series trivially lands in the “low , high ” quadrant—precisely the regime our framework flags as likely spurious. This is what practitioners may already suspect intuitively; the contribution of our framework is to make this intuition quantitative and to connect it to Kolmogorov complexity and the Hausdorff dimension of the underlying attractor.
8.2. Financial Return Series
As a contrasting example, consider daily log-returns of two stock indices (e.g., S&P 500 and FTSE 100). These series are approximately i.i.d. with heavy tails—they have high LZ complexity (–) and high spectral entropy (–). When two such series exhibit a moderately high correlation (), this lands in the “high , high ” quadrant and should be taken seriously as evidence of genuine co-movement—consistent with the well-known common-factor structure of global equity markets. We emphasise that our framework does not prove causation; it merely identifies which correlations are worth investigating further.
8.3. Limitations of the Real-World Illustration
We deliberately refrain from a full empirical study on real data because the ground truth (genuine vs. spurious) is typically unknown. Our toy models provide the controlled setting needed to validate the theoretical claims. Extending the framework to large-scale empirical benchmarks (e.g., the CauseMe platform [5] or financial datasets with known factor structure) is an important direction for future work.
9. Discussion and Practical Recommendations
9.1. Summary
We have demonstrated, through a theoretical framework grounded in algorithmic information theory and empirical validation on two toy models, that spurious correlations are far more prevalent among low-complexity (simple, smooth) time series than high-complexity (chaotic, rough) ones (Cf. [32]). The theoretical argument assembles three known results into a novel narrative for time-series analysis: (1) the Solomonoff prior assigns higher probability to simple patterns [16]; (2) the Lutz–Mayordomo theorem [33] equates normalised Kolmogorov complexity with the effective Hausdorff dimension; (3) the Posobin-Shen result [40] quantifies how noise inflates observed complexity. We invoked these known results to address the problem of spurious correlations arising from the occurrence of simple patterns in data. We presented a method of how to measure complexity of pairs of series via the and studied examples numerically to investigate how our framework works in practice. Beyond confirming the main thesis, the experiments revealed an additional finding: in the chaotic logistic map, detects the pre-synchronisation collapse of individual complexity near , a genuine dynamical event invisible to similarity-based indicators such as .
9.2. Noise Floor
The Posobin–Shen result implies that real observed series have their LZ complexity inflated by measurement noise. The binary Shannon entropy is , , , so for typical noise rates , the analytical lower bound on the complexity rate sweeps the interval . The upper end of this range sits close to the bounded-logistic operating threshold , so applications with appreciable measurement noise should re-calibrate the screening rule against a noise-matched ensemble. The corresponding empirical noise floor on under pickle+float32 is much lower in absolute terms: a truly periodic logistic orbit gives (Table 2), and smooth-but-not-periodic dynamics give at . The operating value for is calibrated empirically for the bounded logistic examples rather than analytically from a bit-count argument. The fGn experiment supplies a family-level false-positive calibration as a function of memory/smoothness; practitioners applying the framework to a different signal class should re-calibrate the screening rule against a data-class-appropriate calibration ensemble.
9.3. Practical Recommendation
When reporting correlations between time series, we recommend:
- Report for each series alongside .
- Use as the joint complexity indicator.
- Apply extra skepticism when in a data class where this threshold has been calibrated (both series are simple or of very different complexity); for stationary Gaussian increments, use the estimated memory/smoothness family and the false-positive calibration curve instead of a universal cutoff.
- For non-stationary series, complexity alone is insufficient, so first-difference or detrend before analysis (Remark 3).
- Use this diagnostic as a complement to, not a replacement for, standard significance testing (Section 6).
9.4. Limitations
We summarise the principal scope restrictions of the framework as follows:
- The formal theory applies to finite binary strings (Propositions 1 and 2) and to infinite binary sequences (Propositions 3 and 4) under Hamming correlation, not directly to arbitrary real-valued time series under Pearson correlation.
- The effective-Hausdorff-dimension bridge of Section 2.5.1 justifies the Hausdorff-dimension framing of the binary-sequence theory but does not prove that LZ compression of a serialised real-valued time series is a consistent estimator of Kolmogorov complexity, effective Hausdorff dimension, or classical Hausdorff dimension.
- Compression ratios depend on the serialisation scheme, quantisation, compressor, and sample length (Table 2); is therefore not invariant across encodings, and thresholds must be re-calibrated for each application.
- On stationary Gaussian-increment processes such as fGn under fine serialisation, may saturate across the relevant memory range, so should not be used as an absolute or rank-based cutoff; calibration should instead be expressed through the estimated memory/smoothness family.
- Non-stationary stochastic processes (e.g., random walks, integrated processes) can simultaneously be algorithmically complex and produce spuriously high Pearson correlations; the stationarity pre-step is essential and is not provided by the complexity screen itself.
- is a theoretically motivated, empirically calibrated diagnostic and not a causal test; passing the screen identifies correlations worth investigating, not causal relationships.
- Thresholds must be calibrated against a null model appropriate to the data class (Section 7).
- Short time series () may give unreliable LZ estimates due to compressor dictionary overhead.
- The empirical relationship between the chosen finite-resolution encoding and any classical Hausdorff-dimension claim is indirect, and quantitative claims of the form should be interpreted as resolution-dependent empirical phenomena rather than as identities.
We now elaborate on the most consequential of these limitations. First, our toy models each have a single parameter controlling complexity (the logistic parameter r or the Hurst exponent H); real time series exhibit mixed dynamics, seasonality, structural breaks, and multiple confounders. To partially address this, we tested a “mixed-complexity” signal , where is fractional Gaussian noise with Hurst exponent H. By varying the amplitude ratio , we sweep from a regime dominated by the simple periodic component (low complexity) to one dominated by the complex stochastic component (high complexity). Forming pairs of such mixed signals with independent noise realisations and measuring the false-positive rate, we find that correctly tracks the effective complexity of the mixture: when the periodic component dominates (), is low and false positives are frequent; as the noise component dominates, rises and false positives drop, consistent with the theory.
In practice, common real-world complications should be handled as follows: (a) for multiregime series, one should consider windowed complexity estimates; (b) seasonal and trend components should be removed prior to complexity estimation (analogous to the stationarity requirement of Remark 3); and (c) structural breaks locally inflate observed complexity, which may actually be desirable to detect. The complexity diagnostic is meant to be used alongside standard preprocessing (detrending, differencing) rather than as a standalone tool.
Second, the LZ complexity estimator depends on the serialisation scheme and series length (see Section 3), and its relationship to the true Kolmogorov complexity is only asymptotic. Third, the indicator treats both series symmetrically. For asymmetric pairs (one complex, one simple, e.g., , ), the min-based primary indicator gives , which lies below the threshold and correctly flags the pair as untrustworthy: the smoother series is the weak link and dominates the score. Practitioners preferring a softer penalty on asymmetry may substitute the geometric-mean alternative , which would score this pair at ; the two indicators agree to four decimal places on symmetric data.
A specific class of asymmetric relationships deserves explicit comment: the case of a slow exogenous driver (low complexity) entraining a fast complex response (high complexity)—e.g., a 24 h solar forcing entraining a chaotic biological rhythm. Here, the two series are genuinely related, but flags them as untrustworthy because the driver itself is simple. This is by design: the screen exists to suppress false positives among low-complexity data, and the cost of doing so is precisely such asymmetric false negatives. The operationally honest answer is to report both (conservative gate) and (softer alternative) alongside and to escalate confirmed asymmetric candidates to a full causal-discovery pipeline (GLOBE [10], CASCADE [11]) rather than to redesign the screen around the driver–response case. Detecting genuine asymmetric causation is a different task from filtering spurious symmetric correlations, and the right tool for it is a directional dependence estimator, not a complexity floor.
Fourth, the LZ-based pipeline requires for stable estimates; below this length, the compressor’s dictionary overhead dominates. For short-panel applications (–500), two computable alternatives carry the same information at better small-sample behaviour: the spectral entropy already used in this paper as a Fourier-domain proxy, and the permutation entropy of Bandt and Pompe [49], whose finite-sample bias is well characterised. The algorithmic-trilemma argument of Section 2.4 suggests that any proxy monotone in entropy rate can support the same screening principle, but the resulting threshold must be calibrated empirically for the chosen proxy and data class. Adapting the surrogate-calibration recipe of Section 7 to short-panel proxies is left as future work; we have not run the empirical experiments at in the present paper because the mfBm calibration curve we rely on is itself measured at .
Fifth, the spectral entropy measure is only one possible Fourier-domain proxy; wavelet-based alternatives may be more appropriate for non-stationary signals.
9.5. Connections and Future Work
Our complexity-filtered correlation test is a lightweight screening step that naturally precedes full causal discovery methods such as GLOBE [10] and CASCADE [11], which use MDL/Kolmogorov complexity principles to recover directed acyclic graphs. Pairs passing our test (high and high ) are natural candidates for deeper causal analysis; we emphasise, however, that our framework identifies correlations worth investigating, not causal relationships per se.
The multivariate fBm model [45] provides a rich testbed for further experiments: varying (series of mismatched roughness), exploring the asymmetry parameter , and testing on the long-range dependent regime where spurious correlations in the non-stationary case are known to be especially severe [48]. Validating the framework on real-world benchmarks with known causal structure (e.g., CauseMe [5]) and developing sample-size corrections for in the short-series regime () are important next steps. A further open direction, posed explicitly in Section “An Open Question: Task-Optimal Serialisation”, is to formalise the task-optimal serialisation: given a signal class and discrimination task, what quantisation maximises the task-relevant mutual information at fixed description length? This would replace the empirical choice documented in Table 2 with a principled one. The connection to algorithmic mutual information (Section 2.7) also deserves further development: an empirical joint-complexity measure based on compressing the concatenated series could provide a direct estimator of and offer a richer diagnostic than alone.
Our work contributes to ongoing developments in the field of Kolmogorov complexity applications to dynamical series and time series [50,51,52,53,54,55,56,57].
9.6. Relation to a Broader Programme
The complexity-based perspective developed here is consistent with, and complements, an ongoing programme bridging algorithmic information theory and machine learning [58,59,60,61,62,63,64,65,66,67,68,69,70,71], whose foundational parts appeared in Physica D [58,59]. That programme develops Kolmogorov complexity, Solomonoff priors, and Solomonoff kernels as a foundation for kernel-based learning theory; the length-conditioned Solomonoff-type prior of Section 2 is the same algorithmic-information substrate. The present diagnostic for spurious time-series correlations applies that substrate in a complementary direction—to the detection of low-complexity coincidence rather than to learning-theoretic generalisation—and its results are consistent with the programme’s central theme that compressibility governs what can be reliably inferred from data.
Author Contributions
Conceptualization, B.H., M.C., K.D., M.H. and M.T.J.; Methodology, B.H., M.C., M.H. and M.T.J.; Software, B.H.; Investigation, M.T.J.; Writing—original draft, B.H., K.D. and M.T.J. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
No new data were created or analyzed in this study. Data sharing is not applicable to this article.
Acknowledgments
Parts of this work were carried out while BH and MC were resident scholars at the Isaac Newton Institute, Cambridge. We used ChatGPT versions 4 and 5 to refine the language in parts of the text. We acknowledge financial support from the Gulf University for Science and Technology, Kuwait.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
| Meaning | |
| N | Length of real-valued time series |
| n | Length of binary sequence ( under pickle+float32 serialisation) |
| M | Byte-string length after serialisation ( for pickle+float32, for float64, for int16) |
| Real-valued time series | |
| Binary strings (used exclusively in theoretical sections) | |
| Prefix Kolmogorov complexity | |
| Kolmogorov complexity relative to oracle A | |
| Complexity rate | |
| Normalised Kolmogorov complexity of a length-n binary string u | |
| LZ-compressed length (bytes) and its ratio to M | |
| Spectral entropy and its normalised version | |
| Joint complexity screening indicator (primary): | |
| Geometric-mean alternative (operationally equivalent): | |
| Complexity-similarity indicator (diagnostic only): | |
| Empirical Pearson correlation | |
| Bipolar overlap (Hamming correlation) | |
| Correlation threshold, radius , binary entropy function | |
| Complexity thresholds (normalised) | |
| Coupling strength and synchronisation threshold | |
| Lyapunov exponents, transversal and maximal | |
| Kolmogorov–Sinai entropy and Kaplan–Yorke dimension | |
| Hurst parameter, Hausdorff dimension (mfBm) | |
| Length-conditioned discrete Solomonoff prior | |
| Normalisation constant of | |
| Threshold on for pair acceptance |
Appendix A. Pearson Volume Bound
While the main text uses the Hamming correlation for geometric clarity, the same capacity ceiling applies to the standard empirical Pearson correlation, introducing only an additional polynomial factor .
Definition A1
(Empirical Pearson correlation). For binary sequences , the empirical Pearson correlation is the standard statistical correlation coefficient computed by treating their bits as real numbers:
where are the empirical means and are the empirical standard deviations.
Lemma A1
(Pearson Volume Bound). Let be a fixed binary sequence with non-zero empirical variance (the Pearson correlation is otherwise undefined) and a correlation threshold. Let be the set of valid correlated sequences (we count only y with non-zero empirical variance). The cardinality of this set is bounded by
where and is the binary entropy function.
Proof.
The sequence pair defines an empirical joint probability distribution for . The empirical Pearson correlation is exactly the correlation coefficient of this joint distribution.
For a fixed sequence x, its marginal empirical type (the proportion of 0s and 1s in x) is fixed. By the Method of Types ([72], Section 11.1), the number of sequences y that realise a specific joint type alongside x is bounded by , where is the conditional Shannon entropy of the empirical distribution. Given the fixed marginal , there are at most joint empirical types compatible with (where are the marginal counts), so the total number of valid correlated sequences is bounded by:
To bound this maximum entropy, let be a random variable taking the value with probability and with probability . The conditional entropy is . By the law of total variance, . Since Y is binary, its conditional variance is exactly . Because X is also binary, any function of X is perfectly linear, meaning the conditional expectation is identically the linear regression: . Taking the variance yields . Substituting these into the law of total variance yields:
Define the function for so that . One can verify by differentiation that is strictly concave and monotone increasing on its domain. Therefore, by Jensen’s inequality applied to the concave function f:
Because f is monotone increasing and the marginal variance of any binary variable is bounded by , the conditional entropy reaches its absolute global maximum when :
Because our threshold requires , the entropy is upper-bounded by . Substituting this uniform limit into the Method of Types bound completes the proof. □
Appendix B. Multivariate Fractional Brownian Motion: Model Details
Proposition A1
(Cross-covariance of mfBm, [45]). A bivariate mfBm with Hurst parameters has cross-covariance for :
where and is the asymmetry parameter.
Simulation
The mfBm simulations in this paper use the standard circulant-embedding construction described in the cited references [45,73]. Concretely, the Wood–Chan algorithm [47] constructs exact fGn samples by embedding the covariance matrix determined by Proposition A1 in a circulant matrix and using the FFT to generate samples with the exact covariance structure; the bivariate paths are then obtained by cumulative summation of the coupled fGn increments. Since the explicit spectral factorisation of the cross-spectral density is not used in any of the theoretical arguments of this paper, we omit the full derivation and provide only the model definition above together with the simulation parameters needed for reproducibility (Appendix D); the code repository contains the implementation used for the figures.
Appendix C. Kolmogorov Complexity via the Discrete Fourier Transform
The Fourier basis offers one constrained description language, and the sparsest exact description in that language provides a useful operational complexity measure: the smaller the exact lossless Fourier representation, the lower the estimated complexity. This is because spatiotemporal patterns with stronger regularity can be reconstructed from fewer retained coefficients, while more irregular or chaotic patterns need denser frequency support.
Ordinarily, Fourier compression is lossy because frequency filtering removes information; however, [44] showed that for binary images, some loss can be corrected during a final binarisation step. This means that if the inverse-transformed image is only perturbed mildly (i.e., by removing insignificant Fourier coefficients), thresholding is able to resolve the loss in the final reconstruction to regain the original binary image.
Let be a binary image, its 2D discrete Fourier transform, and a binary mask that selects which Fourier coefficients to preserve or drop. The compressed representation is thus , where ⊙ denotes element-wise multiplication. The key insight is that can equal s despite z being a filtered version of (retaining the minimal subset of most significant coefficients). Reconstruction proceeds by , where is a hard thresholding operator with threshold (denoted rather than to avoid conflict with the screening threshold of Section 7). So the final image becomes lossless after quantisation (even though the Fourier filtering step by itself is lossy).
Although designed for 2D binary images, the same principles naturally extend to 1D sequences, , by replacing the 2D DFT with its 1D counterpart. A sparse subset of Fourier coefficients sufficient to reconstruct the original sequence exactly after inverse transformation followed by thresholding is then found the same as before. The complexity of s can be quantified by the minimal support of the filter mask that selects the optimal subset of frequency components.
This perspective provides a concrete proxy for Kolmogorov complexity under a restricted description language (i.e., the complexity of s is approximated by the size of the smallest Fourier support that yields exact recovery under thresholding). This basis-dependent measure offers a practically tractable way to relate spectral sparsity to structural regularity.
Appendix D. Reproducibility
We collect here the practical settings used to generate the figures of Section 3, Section 4, Section 5, Section 6, Section 7 and Section 8. All experiments were run in Python 3.11 on a single CPU core (Intel i7-class workstation), using the following packages: numpy 1.26, scipy 1.11, matplotlib 3.8, zlib (Python standard library, DEFLATE level 6), pickle protocol 4. fGn/fBm sampling uses the Wood–Chan circulant-embedding method [47] as implemented using NumPy primitives.
Appendix D.1. Logistic-Map Experiments (Section 4)
Initial conditions , ; transient of 1000 iterates discarded; record length . The coupling sweep uses 51 equally spaced values in . The false-positive rate experiment uses 200 independent pairs at each of (sampled on a uniform grid of width ), with independent random initial conditions drawn uniformly in for each pair. The synchronisation criterion is sustained for the final 500 iterates. The threshold used in Figure 5a is the value at which the periodic regime () trivially exceeds the threshold (since exactly there), and the chaotic regime () sits well below it.
Appendix D.2. mfBm Experiments (Section 5)
Path length ; 500 independent realisations per Hurst value; Hurst grid . Wood–Chan circulant embedding requires positive-semidefinite extension and fails at for , so the grid is truncated at . The false-positive threshold is chosen because the effect at stationary Gaussian processes is subtler than the deterministic logistic regime; the monotone H-dependence of the false-positive rate persists for thresholds – (only the absolute level shifts).
Appendix D.3. Serialisation Comparison (Table 2)
Logistic series at , 20 realisations per row; fGn/fBm series at , 30 realisations per row. Standard deviations are below in every reported cell. Quantisation for int16 and int8 uses uniform binning across the observed dynamic range of each individual realisation (no global scaling).
Appendix D.4. NCD Comparison (Figure 8)
is evaluated via three zlib compressions per pair: , , , where denotes the concatenation of the two pickle+float32 byte representations with no inter-stream marker. zlib compression level 6 (the default) is used throughout.
Appendix D.5. Threshold and fGn Family Calibration
The fGn false-positive curve of Figure 6b locates the 5% transition at . This transition has no absolute coordinate: fGn increments saturate near under pickle+float32 and remain near under int8 for all H (the int8 drop to ≈0.5 belongs to the non-stationary fBm paths, not the increments; Table 2). The threshold therefore cannot be applied as a fixed or rank-based cutoff for fGn increments; the false-positive risk must be read from an H- or memory-parameter calibration curve. The value is the operating point used for the bounded logistic pipeline and for data classes/encodings where has calibrated dynamic range.
Appendix D.6. Source Code
The reproduction package accompanying this revision contains the scripts used to generate the figures and tables, including the logistic-map sweeps, fGn/fBm simulations, serialisation comparison, NCD comparison, and threshold-calibration tables. A permanent public repository link will be provided in the published version.
References
- Chatfield, C. The Analysis of Time Series: Theory and Practice; Chapman and Hall: London, UK, 1975. [Google Scholar]
- Runge, J.; Nowack, P.; Kretschmer, M.; Flaxman, S.; Sejdinovic, D. Detecting and quantifying causal associations in large nonlinear time series datasets. Sci. Adv. 2019, 5, eaau4996. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Mueen, A.; Nath, S.; Liu, J. Fast approximate correlation for massive time-series data. In Proceedings of the 2010 ACM SIGMOD International Conference on Management of Data; Association for Computing Machinery: New York, NY, USA, 2010; pp. 171–182. [Google Scholar]
- Liang, X.S. Unraveling the cause-effect relation between time series. Phys. Rev. E 2014, 90, 052150. [Google Scholar] [CrossRef] [Scilit]
- Runge, J.; Bathiany, S.; Bollt, E.; Camps-Valls, G.; Coumou, D.; Deyle, E.; Glymour, C.; Kretschmer, M.; Mahecha, M.D.; Muñoz-Marí, J.; et al. Inferring causation from time series in earth system sciences. Nat. Commun. 2019, 10, 2553. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Yule, G.U. Why do we sometimes get nonsense-correlations between time-series?—A study in sampling and the nature of time-series. J. R. Stat. Soc. 1926, 89, 1–63. [Google Scholar] [CrossRef] [Scilit]
- Granger, C.W.J.; Newbold, P. Spurious regressions in econometrics. J. Econom. 1974, 2, 111–120. [Google Scholar] [CrossRef] [Scilit]
- Theiler, J.; Eubank, S.; Longtin, A.; Galdrikian, B.; Farmer, J.D. Testing for nonlinearity in time series: The method of surrogate data. Phys. D Nonlinear Phenom. 1992, 58, 77–94. [Google Scholar] [CrossRef] [Scilit]
- Johansen, S. Estimation and hypothesis testing of cointegration vectors in Gaussian vector autoregressive models. Econometrica 1991, 59, 1551–1580. [Google Scholar] [CrossRef] [Scilit]
- Marx, A.; Vreeken, J. Formally Justifying MDL-based Inference of Cause and Effect. In Proceedings of the AAAI Workshop on Information-Theoretic Methods for Causal Inference and Discovery (ITCI’22), Virtual, 1 March 2022. [Google Scholar]
- Cüppers, J.; Xu, S.; Musa, A.; Vreeken, J. Causal Discovery from Event Sequences by Local Cause-Effect Attribution. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS); Curran Associates, Inc.: Nice, France, 2024; Volume 37. [Google Scholar]
- Solomonoff, R.J. A Preliminary Report on a General Theory of Inductive Inference; Technical Report V-131; Revision published in November 1960 as Report ZTB-138; Zator Company: Cambridge, MA, USA, 1960. [Google Scholar]
- Kolmogorov, A. Three approaches to the quantitative definition of information. Probl. Inf. Transm. 1965, 1, 3–11. [Google Scholar]
- Chaitin, G.J. A theory of program size formally identical to information theory. J. ACM (JACM) 1975, 22, 329–340. [Google Scholar] [CrossRef] [Scilit]
- Turing, A.M. On computable numbers, with an application to the Entscheidungsproblem. Proc. Lond. Math. Soc. 1937, 42, 230–265. [Google Scholar] [CrossRef] [Scilit]
- Li, M.; Vitanyi, P. An Introduction to Kolmogorov Complexity and Its Applications, 4th ed.; Texts in Computer Science; Springer: Berlin/Heidelberg, Germany; New York, NY, USA, 2019. [Google Scholar]
- Calude, C.S. Information and Randomness: An Algorithmic Perspective, 2nd ed.; Springer: Berlin/Heidelberg, Germany, 2002. [Google Scholar] [CrossRef] [Scilit]
- Lempel, A.; Ziv, J. On the complexity of finite sequences. Inf. Theory IEEE Trans. 1976, 22, 75–81. [Google Scholar] [CrossRef] [Scilit]
- Benci, V.; Bonanno, C.; Galatolo, S.; Menconi, G.; Virgilio, M. Dynamical systems and computable information. Discret. Contin. Dyn. Syst.-Ser. B 2004, 4, 935–960. [Google Scholar] [CrossRef] [Scilit]
- Puglisi, A.; Benedetto, D.; Caglioti, E.; Loreto, V.; Vulpiani, A. Data compression and learning in time sequences analysis. Phys. D Nonlinear Phenom. 2003, 180, 92–107. [Google Scholar] [CrossRef] [Scilit]
- Amigó, J.M.; Szczepański, J.; Wajnryb, E.; Sanchez-Vives, M.V. Estimating the entropy rate of spike trains via Lempel–Ziv complexity. Neural Comput. 2004, 16, 717–736. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Szczepański, J.; Amigó, J.M.; Wajnryb, E.; Sanchez-Vives, M.V. Characterizing spike trains with Lempel–Ziv complexity. Neurocomputing 2004, 58–60, 79–84. [Google Scholar] [CrossRef]
- Cilibrasi, R.; Vitányi, P.; de Wolf, R. Algorithmic clustering of music based on string compression. Comput. Music J. 2004, 28, 49–67. [Google Scholar] [CrossRef] [Scilit]
- Cilibrasi, R.; Vitányi, P.M.B. Clustering by compression. IEEE Trans. Inf. Theory 2005, 51, 1523–1545. [Google Scholar] [CrossRef] [Scilit]
- Vitányi, P.M. Similarity and denoising. Philos. Trans. R. Soc. A Math. Phys. Eng. Sci. 2013, 371, 20120091. [Google Scholar] [CrossRef] [Scilit]
- Vitányi, P. How incomputable is Kolmogorov complexity? Entropy 2020, 22, 408. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Dingle, K.; Camargo, C.Q.; Louis, A.A. Input–output maps are strongly biased towards simple outputs. Nat. Commun. 2018, 9, 761. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Levin, L. Laws of information conservation (nongrowth) and aspects of the foundation of probability theory. Probl. Peredachi Informatsii 1974, 10, 30–35. [Google Scholar] [CrossRef] [Scilit]
- Dingle, K.; Pérez, G.V.; Louis, A.A. Generic predictions of output probability based on complexities of inputs and outputs. Sci. Rep. 2020, 10, 4415. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zenil, H.; Delahaye, J. An algorithmic information theoretic approach to the behaviour of financial markets. J. Econ. Surv. 2011, 25, 431–463. [Google Scholar] [CrossRef] [Scilit]
- Dingle, K.; Kamal, R.; Hamzi, B. A note on a priori forecasting and simplicity bias in time series. Phys. A Stat. Mech. Its Appl. 2023, 609, 128339. [Google Scholar] [CrossRef] [Scilit]
- Dingle, K. Curious Coincidences and Kolmogorov Complexity. In Networks, Games, and Dynamics: From Dynamical Systems and Stochastic Analysis to Transportation Theory and Optimal Control; Springer: Cham, Switzerland, 2025; pp. 95–118. [Google Scholar] [CrossRef] [Scilit]
- Lutz, J.H. The dimensions of individual strings and sequences. Inf. Comput. 2003, 187, 49–79. [Google Scholar] [CrossRef] [Scilit]
- Galatolo, S. Pointwise information entropy for metric spaces. Nonlinearity 1999, 12, 1289–1298. [Google Scholar] [CrossRef] [Scilit]
- Lutz, J.H.; Lutz, N. Who Asked Us? How the Theory of Computing Answers Questions about Analysis. In Complexity and Approximation: In Memory of Ker-I Ko; Du, D.Z., Wang, J., Eds.; Lecture Notes in Computer Science; Springer: Cham, Switzerland, 2020; Volume 12000. [Google Scholar] [CrossRef] [Scilit]
- Staiger, L. Kolmogorov complexity and Hausdorff dimension. Inf. Comput. 1993, 103, 159–194. [Google Scholar] [CrossRef] [Scilit]
- Pesin, Y.B. Characteristic Lyapunov exponents and smooth ergodic theory. Russ. Math. Surv. 1977, 32, 55–114. [Google Scholar] [CrossRef] [Scilit]
- Ruelle, D. An inequality for the entropy of differentiable maps. Bol. Soc. Bras. Matemática 1978, 9, 83–87. [Google Scholar] [CrossRef] [Scilit]
- Kaplan, J.L.; Yorke, J.A. Chaotic behavior of multidimensional difference equations. In Functional Differential Equations and Approximation of Fixed Points; Peitgen, H.O., Walther, H.O., Eds.; Lecture Notes in Mathematics; Springer: Berlin/Heidelberg, Germany, 1979; Volume 730, pp. 204–227. [Google Scholar] [CrossRef] [Scilit]
- Posobin, G.; Shen, A. Random Noise Increases Kolmogorov Complexity and Hausdorff Dimension. In Proceedings of the 36th International Symposium on Theoretical Aspects of Computer Science (STACS 2019); Leibniz International Proceedings in Informatics (LIPIcs); Schloss Dagstuhl–Leibniz-Zentrum für Informatik: Wadern, Germany, 2019; Volume 126, pp. 57:1–57:14. [Google Scholar] [CrossRef]
- Janzing, D.; Schölkopf, B. Causal inference using the algorithmic Markov condition. IEEE Trans. Inf. Theory 2010, 56, 5168–5194. [Google Scholar] [CrossRef] [Scilit]
- Zenil, H.; Kiani, N.A.; Marabita, F.; Deng, Y.; Elias, S.; Schmidt, A.; Ball, G.; Tegner, J. An algorithmic information calculus for causal discovery and reprogramming systems. iScience 2019, 19, 1160–1172. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Tan, E.; Walker, D.; Small, M.; Thorne, B. Dynamics, Complexity and Time Series Analysis. arXiv 2026, arXiv:2601.04515. [Google Scholar] [CrossRef] [Scilit]
- Terry-Jack, M.; O’Keefe, S. Fourier transform bounded Kolmogorov complexity. Phys. D Nonlinear Phenom. 2023, 453, 133824. [Google Scholar] [CrossRef] [Scilit]
- Amblard, P.O.; Coeurjolly, J.F.; Lavancier, F.; Philippe, A. Basic properties of the multivariate fractional Brownian motion. arXiv 2012, arXiv:1007.0828. [Google Scholar]
- Falconer, K. Fractal Geometry: Mathematical Foundations and Applications; Wiley: Hoboken, NJ, USA, 2003. [Google Scholar]
- Wood, A.T.; Chan, G. Simulation of stationary Gaussian processes in [0, 1]d. J. Comput. Graph. Stat. 1994, 3, 409–432. [Google Scholar] [CrossRef] [Scilit]
- Orcutt, G.; James, S. Testing the significance of correlation between time series. Biometrika 1948, 35, 397–413. [Google Scholar] [CrossRef] [Scilit]
- Bandt, C.; Pompe, B. Permutation entropy: A natural complexity measure for time series. Phys. Rev. Lett. 2002, 88, 174102. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Brudno, A.A. The complexity of the trajectories of a dynamical system. Russ. Math. Surv. 1978, 33, 197–198. [Google Scholar] [CrossRef] [Scilit]
- White, H.S. Algorithmic complexity of points in dynamical systems. Ergod. Theory Dyn. Syst. 1993, 13, 807–830. [Google Scholar] [CrossRef] [Scilit]
- Mihailovic, D.T.; Mimic, G.; Nikolic-Djoric, E.; Arsenic, I. Novel measures based on the Kolmogorov complexity for use in complex system behavior studies and time series analysis. arXiv 2013, arXiv:1310.1304. [Google Scholar]
- Zimmermann, E. Fiber entropy and algorithmic complexity of random orbits. arXiv 2021, arXiv:2108.13019. [Google Scholar]
- Dingle, K.; Alaskandarani, M.; Hamzi, B.; Louis, A.A. Exploring Simplicity Bias in 1D Dynamical Systems. Entropy 2024, 26, 426. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Mihailović, D.T.; Malinović-Milićević, S.; Frau, F.J.; Singh, V.P.; Han, J. Predictability of monthly streamflow by considering complexity measures. J. Hydrol. 2024, 634, 131103. [Google Scholar] [CrossRef] [Scilit]
- Hamzi, B.; Dingle, K. Simplicity bias, algorithmic probability, and the random logistic map. Phys. D Nonlinear Phenom. 2024, 463, 134160. [Google Scholar] [CrossRef] [Scilit]
- Dingle, K.; Hamzi, B.; Hutter, M.; Owhadi, H. Retrodicting Chaotic Systems: An Algorithmic Information Theory Approach. arXiv 2025, arXiv:2507.04780. [Google Scholar] [CrossRef] [Scilit]
- Hamzi, B.; Hutter, M.; Owhadi, H. Bridging Algorithmic Information Theory and Machine Learning: A New Approach to Kernel Learning. Phys. D Nonlinear Phenom. 2024, 464, 134153. [Google Scholar] [CrossRef] [Scilit]
- Hamzi, B.; Hutter, M.; Owhadi, H. Bridging Algorithmic Information Theory and Machine Learning: Clustering, Density Estimation, Kolmogorov Complexity-Based Kernels, and Kernel Learning in Unsupervised Learning. Phys. D Nonlinear Phenom. 2025, 476, 134669. [Google Scholar] [CrossRef] [Scilit]
- Hamzi, B.; Hutter, M. Learning Theory from the Viewpoint of Algorithmic Information Theory: Kolmogorov Complexity Meets Kernel Methods (Part III). Preprint 2025. Available online: https://www.researchgate.net/publication/394846987_Learning_Theory_from_the_Viewpoint_of_Algorithmic_Information_Theory_Kolmogorov_Complexity_Meets_Kernel_Methods (accessed on 1 March 2026).
- Hamzi, B.; Hutter, M.; Owhadi, H.; Wilson, A.G. Bridging Algorithmic Information Theory and Machine Learning, Part IV: Solomonoff Gaussian Hilbert Spaces, Solomonoff Gaussian Processes, and Solomonoff Gaussian Fields. Preprint 2026. Available online: https://www.researchgate.net/publication/400705692_Bridging_Algorithmic_Information_Theory_and_Machine_Learning_Part_IV_Solomonoff_Gaussian_Hilbert_Spaces_Solomonoff_Gaussian_Processes_and_Solomonoff_Gaussian_Fields (accessed on 1 March 2026).
- Hamzi, B.; Hutter, M.; Owhadi, H.; Wilson, A.G. Bridging Algorithmic Information Theory and Machine Learning, Part V: Learning Theory in Solomonoff Gaussian Hilbert Spaces. Preprint 2026. Available online: https://www.researchgate.net/publication/402794637_Bridging_Algorithmic_Information_Theory_and_Machine_Learning_Part_V_Learning_Theory_in_Solomonoff_Gaussian_Hilbert_Spaces (accessed on 1 March 2026).
- Hamzi, B.; Hutter, M.; Owhadi, H.; Wilson, A.G. Bridging Algorithmic Information Theory and Machine Learning, Part VI: Deep Kolmogorov Complexity Kernels. California Institute of Technology: Pasadena, CA, USA, 2026; manuscript in preparation.
- Hamzi, B.; Hutter, M.; Owhadi, H. Bridging Algorithmic Information Theory and Machine Learning, Part VII: Maximum Mean Discrepancy, Kernel Stein Discrepancy, and the Hilbert–Schmidt Independence Criterion. California Institute of Technology: Pasadena, CA, USA, 2026; manuscript in preparation.
- Hamzi, B.; Hutter, M.; Owhadi, H. Bridging Algorithmic Information Theory and Machine Learning, Part VIII: Kernel Flows, Random Dynamical Systems, and Algorithmic Information Theory. California Institute of Technology: Pasadena, CA, USA, 2026; manuscript in preparation.
- Hamzi, B.; Hutter, M.; Owhadi, H. Bridging Algorithmic Information Theory and Machine Learning, Part IX: Solomonoff–Barron Spaces. California Institute of Technology: Pasadena, CA, USA, 2026; manuscript in preparation.
- Hamzi, B.; Hutter, M.; Owhadi, H. Bridging Algorithmic Information Theory and Machine Learning, Part X: Hardness and Tractability of Kernel-Method Dynamical-System Identification. California Institute of Technology: Pasadena, CA, USA, 2026; manuscript in preparation.
- Hamzi, B.; Hutter, M.; Owhadi, H. Bridging Algorithmic Information Theory and Machine Learning, Part XI: Kolmogorov Complexity, Kolmogorov Entropy, and Rademacher Complexity. California Institute of Technology: Pasadena, CA, USA, 2026; manuscript in preparation.
- Hamzi, B.; Hutter, M.; Owhadi, H. Bridging Algorithmic Information Theory and Machine Learning, Part XII: Operator-Adapted Multiresolution for Solomonoff Kernels. California Institute of Technology: Pasadena, CA, USA, 2026; manuscript in preparation.
- Hamzi, B.; Hutter, M.; Owhadi, H. Bridging Algorithmic Information Theory and Machine Learning, Part XIII: Solomonoff–Gromov Model Selection: Learning Algorithmic Metric–Measure Geometry Before Kernels. California Institute of Technology: Pasadena, CA, USA, 2026; manuscript in preparation.
- Hamzi, B.; Hutter, M. Computable Approaches to Solomonoff Induction: A Survey from Universal Prediction to Kernels, Operators, and Metric–Measure Geometry. California Institute of Technology: Pasadena, CA, USA, 2026; manuscript in preparation.
- Cover, T.M.; Thomas, J.A. Elements of Information Theory, 2nd ed.; Wiley-Interscience: Hoboken, NJ, USA, 2006. [Google Scholar]
- Didier, G.; Pipiras, V. Integral representations and properties of operator fractional Brownian motions. Bernoulli 2011, 17, 1–33. [Google Scholar] [CrossRef] [Scilit]
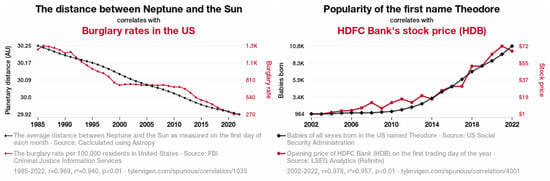
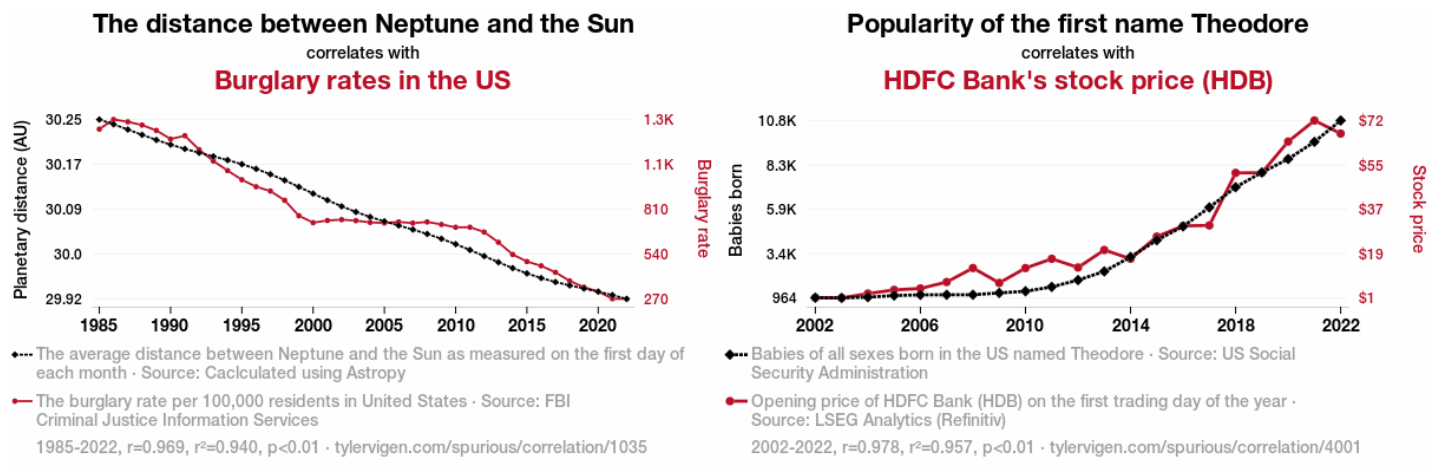
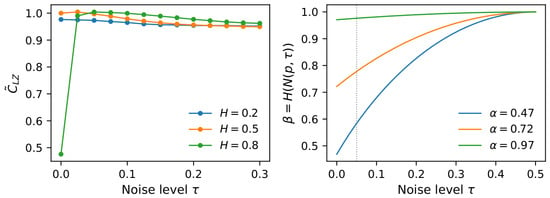
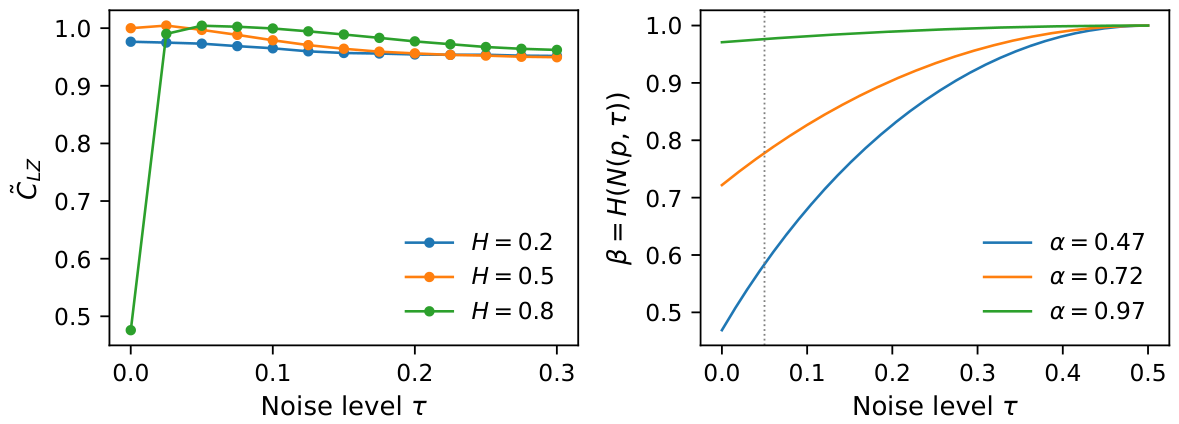
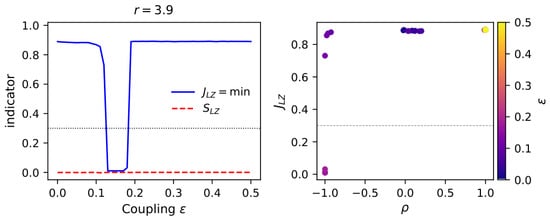
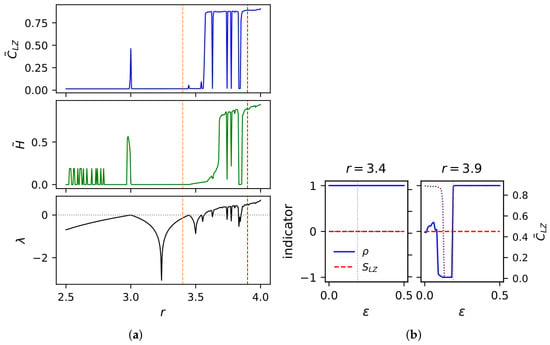
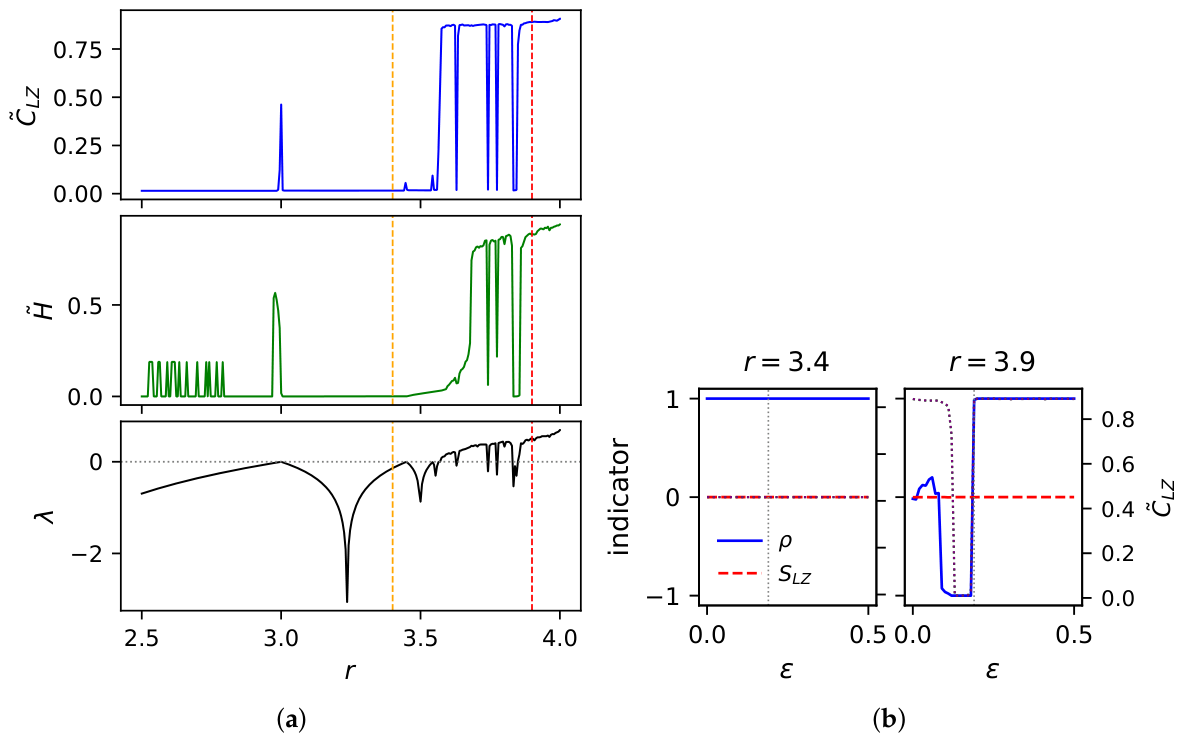
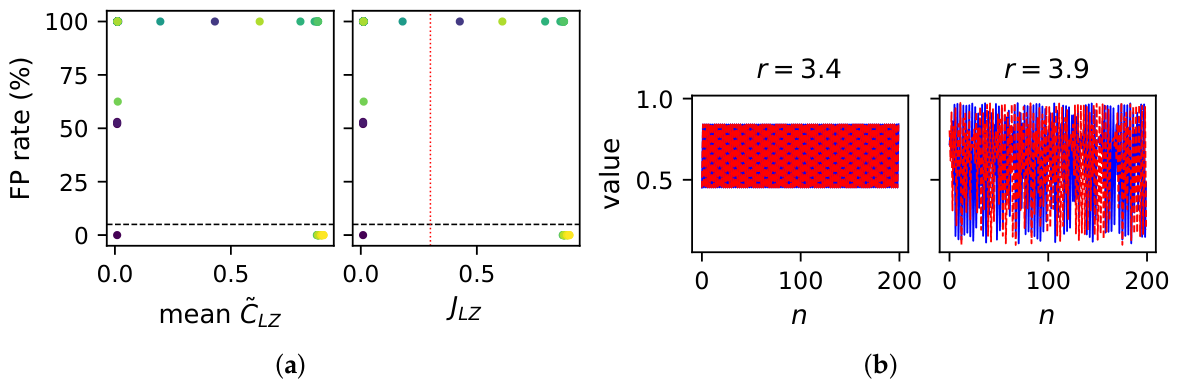
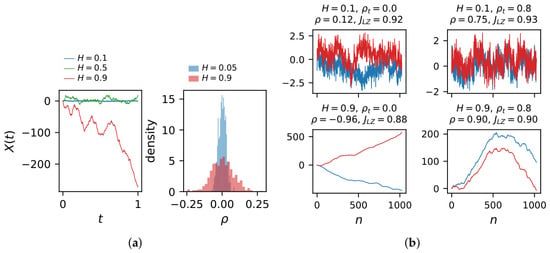
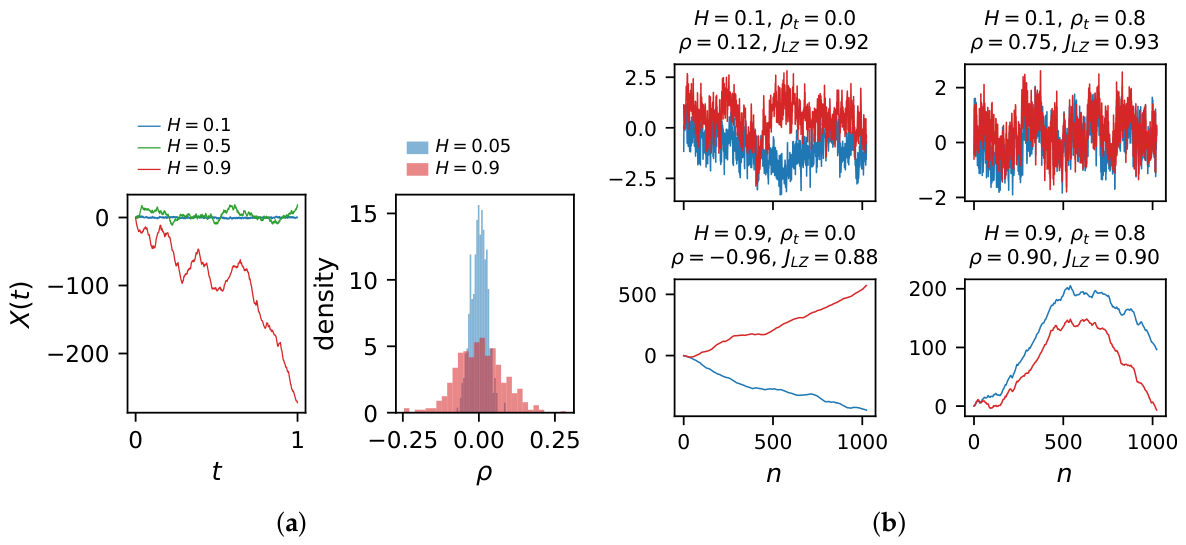
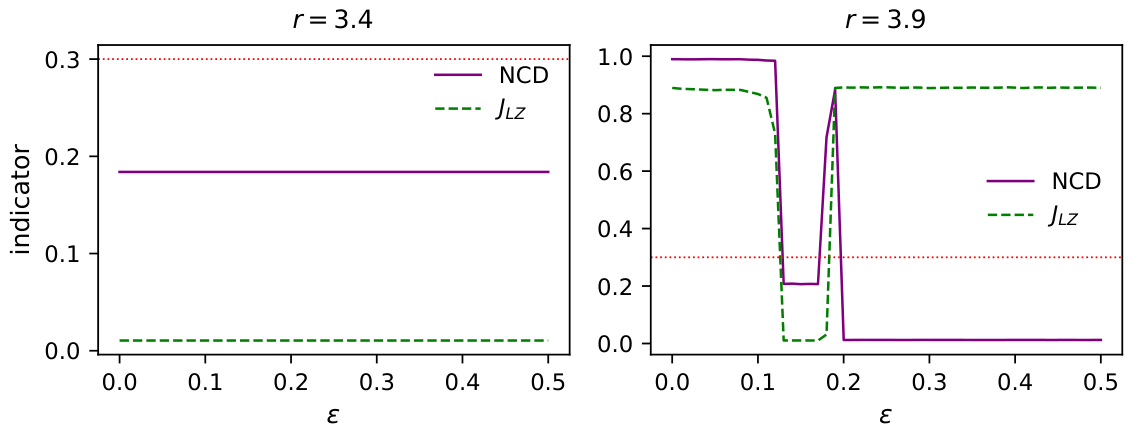
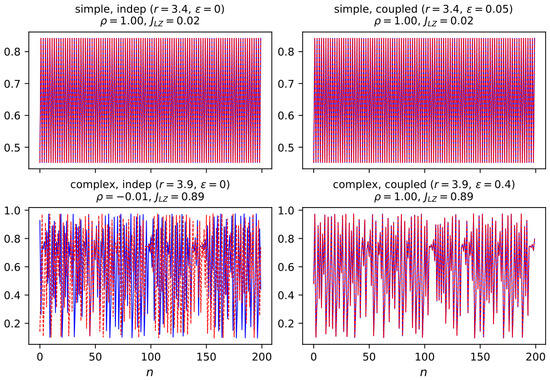
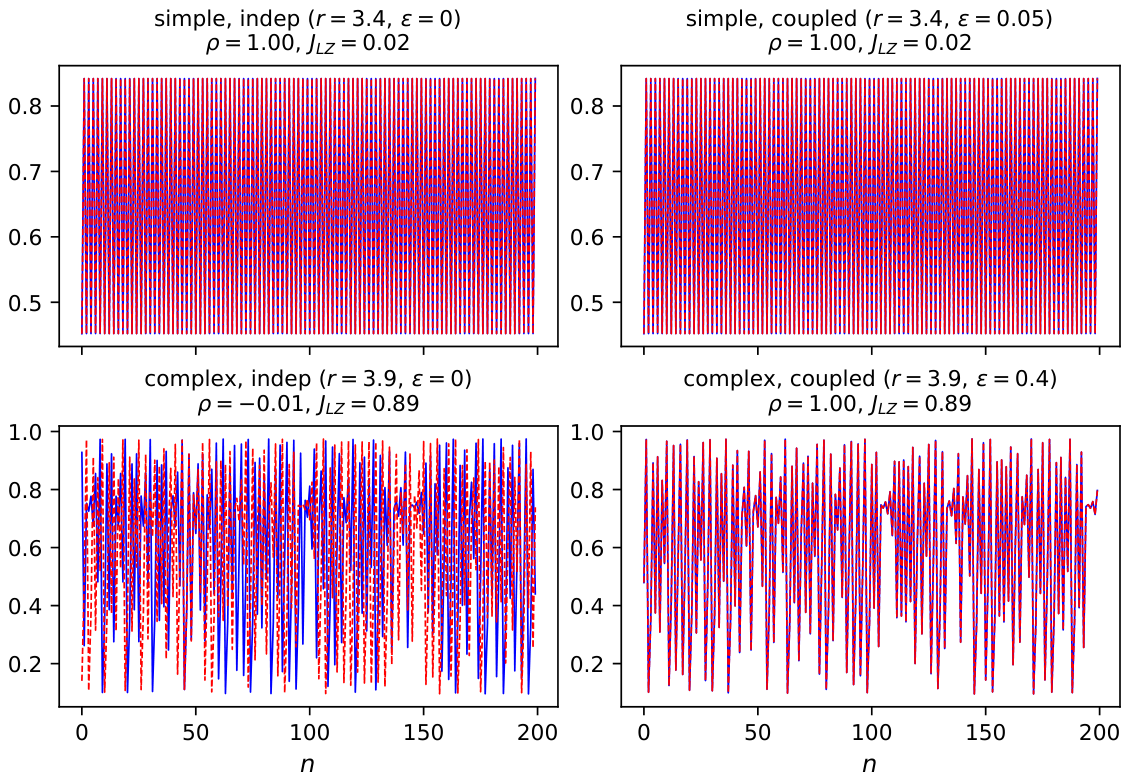

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.