


Abstract
A multilayer linear response model (MLRM) is proposed to generate time-series data based on linear response theory. The proposed MLRM is designed to generate data for anomalous dynamics by extending the conventional single-layer linear response model (SLRM) into multiple layers. While the SLRM is a linear equation with respect to external forces, the MLRM introduces nonlinear interactions, enabling the generation of a wider range of dynamics. The MLRM is applicable to various fields, such as finance, as it does not rely on machine learning techniques and maintains interpretability. We investigated whether the MLRM could generate anomalous dynamics, such as those observed during the coronavirus disease 2019 (COVID-19) pandemic, using pre-pandemic data. Furthermore, an analysis of the log returns and realized volatility derived from the MLRM-generated data demonstrated that both exhibited heavy-tailed characteristics, consistent with empirical observations. These results indicate that the MLRM can effectively reproduce the extreme fluctuations and tail behavior seen during high-volatility periods.
1. Introduction
Recently, remarkable progress has been made in data generation technology, especially in the text and image generation fields. In addition, attempts have been made in the financial sector to generate financial time-series data, e.g., stock prices, with numerous studies utilizing generative adversarial networks (GANs) [1] for this purpose. For example, Ref. [2] proposed Quant GAN, which comprises generator and discriminator functions using temporal convolutional networks (TCNs) [3] to capture long-range dependencies, e.g., the presence of volatility clusters. Similarly, Ref. [4] proposed Stock GAN, based on the Wasserstein GAN (WGAN) [5,6], to address the optimal transport problem [7]. More recently, Ref. [8] proposed Sig-Wasserstein GAN (Sig-WGAN), which combines rough path theory [9] and the expected signature [10] to improve training stability and sample quality. Building on this, Ref. [11] extended the Sig-WGAN framework to the conditional setting and proposed a conditional Sig-WGAN for modeling the distribution of future time series given past observations. Moreover, Ref. [12] proposed a conditional GAN-based market simulator that reacts to experimental agent behavior, enabling realistic and responsive market simulations to evaluate trading strategies. In addition, Ref. [13] introduced Fin-GAN, a GAN-based model for financial time series forecasting, which outperforms traditional methods like LSTM [14] and ARIMA [15] in both predictive accuracy and classification performance.
Recently, diffusion models [16] have been developed rapidly and employed for the generation of time-series data. For example, Ref. [17] introduced a two-way variational autoencoder, VAE, with diffusion, denoising, and disentanglement, to address multivariate time-series forecasting problems. The VAE model improves denoising diffusion and score matching by treating discrete observations as continuous values in the function space. In the context of missing value imputation, which is critical for practical financial applications, Ref. [18] proposed a conditional score-based diffusion model (CSDI). Furthermore, Ref. [19] introduced a structured state space diffusion (SSSD) model, which is particularly effective at capturing long-term dependencies in time-series data. More recently, Ref. [20] proposed a conditional diffusion model as a denoiser for financial time-series data, demonstrating an improved signal-to-noise ratio, return predictability, and trading performance compared to existing methods such as denoising autoencoders and moving averages. In addition, Ref. [21] proposed FTS-Diffusion, a diffusion-based generative framework that specifically models the irregular and scale-invariant patterns of financial time series, achieving high fidelity in synthetic data generation and significant improvements in downstream forecasting tasks.
In parallel with these developments, transformer-based architectures have attracted significant attention in financial time-series forecasting and generation. Unlike traditional RNNs and LSTMs, transformers leverage self-attention to capture long-term dependencies and complex patterns, and they have been shown to outperform conventional deep learning approaches for stock prediction tasks [22,23,24]. These advances highlight the growing importance of and attention-based models in financial and commodity time-series modeling.
However, there are several problems in applying machine learning models, including GANs, diffusion models, and transformer-based architectures, to financial time-series data. First, the numerous parameters in these models make them “black boxes,” making it difficult to explain the causal relationship between inputs and outputs. Second, there is a significant risk of overfitting to the training data, where even subtle differences between the input and training data can lead to substantially different outputs. In addition, existing machine learning approaches, including RNNs, LSTMs, and even transformer-based models, face fundamental limitations in financial contexts: traditional linear and parametric models struggle to capture the nonlinear and non-stationary dynamics of financial time series, while deep learning models often face difficulty modeling long-term dependencies and effectively selecting relevant features from high-dimensional or noisy inputs. This is particularly true due to the lack of explicit feature-level attention mechanisms, which can be crucial for accurate multivariate time-series forecasting [25]. Recently, it has been reported that explainable machine learning models, such as LightGBM, can achieve high prediction accuracy in financial time-series tasks by leveraging their feature importance and transparency [26]. Linear response theory (LRT), a physics-based method grounded in the framework of nonequilibrium statistical mechanics, offers a potential solution to these problems [27,28]. In LRT, the input is treated as an external force (i.e., a cause), and the output is the generated data (i.e., the result); this framework enables the system to produce robust responses to external force, as the coupling of these causal relationships is interpreted as a second-order fluctuation in the system.
In a related study applying LRT to finance, Ref. [29] analyzed NASDAQ data from 862 stocks and identified log-return as the most appropriate conjugate variable, demonstrating strong agreement between theoretical predictions and empirical average responses. Their study also examined the semi-strong efficiency of various financial markets, including Forex (EUR/USD, USD/HKD), Bitcoin, commodities (oil and gold), and the S&P500. Despite being a physical model, LRT accurately captures average price reactions to market events, providing valuable insights into market dynamics [30].
Previously, we proposed a linear response model (LRM) [31] to generate time-series data based on LRT. The LRM is derived under the assumption that the distribution of the time-series data follows an energy-based model (EBM) [32], with the energy function approximated up to the second-order around the mean. A key advantage of the LRM is that it avoids overfitting because model training is not required, and it avoids the black box issue because the causal relationships are explicitly known. In addition, the LRM offers several other benefits, e.g., very low computational costs. The LRM can be applied to financial time-series to generate data with fluctuations of various magnitudes; however, it is difficult to reproduce dynamics involving typically large fluctuations, e.g., those caused by COVID-19. While the LRM is primarily designed as a data generation method, there has been increasing attention in recent years to the detection and modeling of anomalous dynamics, which are often associated with extreme events. In this context, machine learning models such as normalizing flows have attracted considerable interest, and a variety of approaches have been explored to better capture rare anomalies and extreme dynamics in time-series data [33].
In order to overcome this issue, we propose the multilayer LRM (MLRM) to generate anonymous dynamics. The proposed MLRM is constructed by extending the LRM to multiple layers, which means that the MLRM incorporates the output data of the LRM iteratively. As a result, the fluctuations in the generated time-series data are amplified, thereby producing time-series data with anomalous dynamics. However, the data generated via the proposed MLRM may diverge. To solve this problem, it is necessary to consider methods to suppress divergence. Note that this approach is analogous to renormalization in quantum field theory [34], which is employed to avoid divergence in self-energy calculations.
By applying the proposed MLRM to financial time-series data, we attempted to determine whether large fluctuation dynamics can be generated using the information of fluctuations prior to COVID-19. Furthermore, we calculated the return distribution and the distribution of realized volatility from the data generated via the proposed MLRM. The return distribution exhibited pronounced fat-tailed behavior, with the estimated tail index being significantly smaller than 3 and close to 2, thereby deviating from the so-called inverse cubic law [35,36], and resembling the inverse square law observed during the COVID-19 pandemic and other extreme market periods [37,38]. The realized volatility distribution was well described by an inverse gamma distribution [39,40].
Praetz [41] demonstrated that Student’s t distribution provides a more accurate model for financial returns than the normal distribution, as it can accommodate the heavy tails observed in empirical data. Separately, the nonextensive statistical mechanics framework, originally formulated by Tsallis and his colleagues, offers a theoretical foundation for understanding the emergence of power-law distributions in complex systems, including financial markets [42]. In particular, this approach explains the frequent observation of fat-tailed return distributions and the breakdown of conventional Boltzmann–Gibbs statistics in empirical financial data. Our results, which show extremely heavy tails in the return distributions generated via the MLRM, are consistent with the predictions of nonextensive statistics and further support the relevance of this framework for modeling extreme market events, such as those observed during the COVID-19 pandemic.
2. Theory
First, in Section 2.1, we explain the theoretical framework of our previously proposed LRM [31] as a generative model for time-series data under external forces. Specifically, we begin by introducing the probability distribution of time-series data using an EBM, and then we incorporate external forces into the energy function to define the probability distribution of time-series data subject to such external forces. By approximating the energy function up to the second order, we demonstrate that time-series generation under external forces can be characterized by the product of the second-order fluctuation (evaluated in the absence of external forces) and the applied external force. Subsequently, in Section 2.2, we extend the LRM described in Section 2.1 to a multilayer framework. In this extension, the external force is treated as a random variable, enabling the generation of time-series data under various external forces. Furthermore, we assume that the fluctuations in data generated under various external forces themselves follow the LRM, and by iteratively applying this procedure, we derive the MLRM. Finally, since the derived MLRM may exhibit divergence under certain conditions, we also discuss methods to suppress such divergence and ensure the stability of the model.
2.1. LRM
Here, we review the theory of a single-layer LRM (SLRM) or a simple LRM for the generation of time-series data [31]. Let be the time domain for which we observe the real-valued M-dimensional time-series. Then, for each , the observing values
are considered to be the realization of the random variables , where is the underlying set of a filtered probability space .
Assume that, for the random variable
the following function exists:
This is referred to as an energy function, where the probability density function, , of is expressed as follows:
Here, , and we have the following:
In other words, our description is based on the EBM introduced by [32].
In addition, the notation represents the ensemble average, i.e., for a function, we obtain the following for :
Next, we consider the Taylor expansion of (4) around a mean value:
As a result, if we assume that can be approximated up to the second-order term of the displacement random vector , we obtain
where
is the gradient vector, and
is the Hessian matrix. Under the assumption that the gradient is zero () at the mean value, (8) becomes the following:
In addition, the first term, , in (10) is a constant. Thus, the numerator and denominator in (4) cancel each other out, and finally, with the substitution of (10) with (4), (4) is rewritten as follows:
where
Note that (11) takes the form of a multidimensional Gaussian distribution; however, it is dependent on both s and t. In addition, the Hessian matrix is equivalent to the following inverse matrix (refer to Section 1.4 in the literature [27]):
where
Next, assume that an external force vector acts on the system, and the external force energy term is added to the original energy function as follows:
Thus, the probability distribution under external forces is expressed as follows:
where
To obtain the response under external forces, it is sufficient to take the partial derivative of the logarithm of (17) with respect to , as follows:
The notation represents the ensemble average under the external force for :
To calculate (18), the variable transformation for (17) makes it possible to obtain the following:
In this derivation, we have used the relation and , where is the identity matrix for , and the zero matrix otherwise.
By substituting (20) with (18), we obtain the following:
(21) is the equation of the LRM for time-series data and discrete time. If the time moves continuously in the interval , then (21) can be rewritten as follows:
where , , and are regarded as , , and functions of continuous time, respectively. (22) takes the form of the green function in physics. We refer to or as a two-time covariance matrix or function. In addition, (22) can be interpreted as the function that minimizes the following variational function:
With a return to the discrete time version, (21) can be rewritten as follows:
where
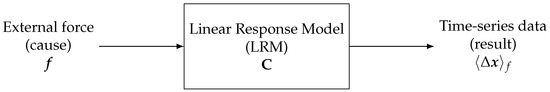
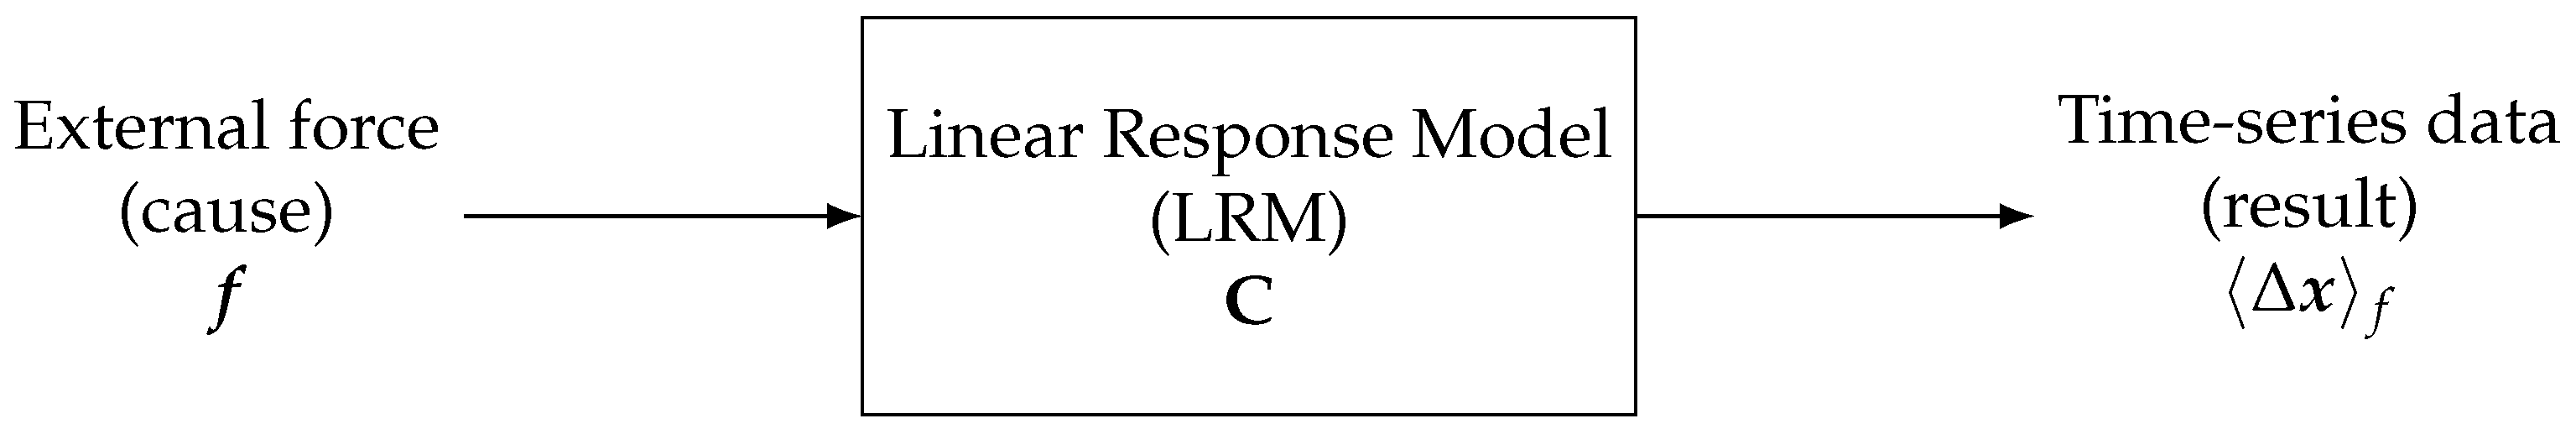
Here, , , and for are the vector of , the matrix of the expanded versions in the time direction of , and the vector of , respectively. Figure 1 shows a schematic representation of the LRM. Here, the input is treated as an external force (i.e., a cause), and the output is the generated data (i.e., the result); furthermore, the coupling of these causal relationships is considered a second-order fluctuation of the system.
Figure 1.
Data generation using the LRM.
2.2. MLRM
In the following section, we extend the conventional LRM to multiple layer in order to construct the proposed MLRM.
First, let the external force be the observing values of a random variable, . The probability density function of is represented as . Then, becomes a conditional expectation of , given . Here, denotes the data generated via the n-layer LRM. Then, (24) of the SLRM can be expressed as follows:
where , .
The two-time covariance matrix of the data generated via the SLRM is given as follows:
where the relationship was used, and
Under the assumption that the data generated via the first layer of the LRM follow the second layer of the LRM, the displacement of the second layer of the LRM at that time is denoted as , which is expressed as follows:
(28) represents the data generation of the two-layer LRM. The equation for the two-layer LRM is expressed as follows:
By repeating these operations n times, we can derive the data generation equation for an n-layer LRM (n-LRM). Here, the following series is obtained:
where
for .
By substituting (31) with (30), we obtain the following:
where
Note that is generally an asymmetric matrix.
In the following, we consider a case when the number of layers proceeds to infinity. Here, we refer to the resulting model as the ∞-LRM. In other words, if n in (32) is set to infinity, we obtain the following:
where
Here, is the two-time covariance matrix when (32) converges at infinity and becomes the finite values.
The eigenvalue problem for the asymmetric matrix is solved as follows:
Here, is a matrix of a column of right eigenvectors for , is a matrix of a column of left eigenvectors for , and is a diagonal matrix whose ith diagonal element ( ) is an eigenvalue corresponding to the ith column vector of and of . With the results of the eigenvalue problem in use, (34) can be decomposed by the eigenvectors as follows:
where
Note that, when , is one of the types called a Lacunary function ([43]). In addition, (42) is rewritten as follows:
When , (43) diverges because n is increased. In other words, to prevent from diverging, the eigenvalues of must satisfy for . Generally, (30) or (32) diverges because some eigenvalues with exist. To control this divergence, we introduce the hyperparameter and modify (30) as follows:
When , (45) becomes (30); thus, . A well-chosen can prevent (45) from diverging. In addition, we define the following:
Thus, the modified n-LRM is expressed as follows:
In this study, (47) is used to generate the data in the proposed MLRM. Figure 2 shows a schematic representation of the proposed MLRM. Here, the proposed MLRM is constructed by extending the LRM to multiple layers, which means that the MLRM incorporates the output data of the LRM iteratively.
Figure 2.
Data generation using the MLRM.
3. Method
Section 3.1 describes the principal component analysis (PCA) used for estimating external forces, introducing a dimensionality reduction technique. Section 3.2 details the estimation of two time covariance matrices, which are used for PCA and for data generation in the proposed MLRM. Section 3.3 outlines the method used for estimating external force vectors. Section 3.4 presents the approach that uses the proposed MLRM for data generation. Section 3.5 introduces dynamic time warping (DTW), which is employed to evaluate the data generated by the proposed MLRM.
3.1. PCA of Two-Time Covariance Matrix
PCA is employed in Section 3.3 as part of the procedure for estimating external forces. In this section, we consider a real–symmetric eigenvalue problem of with an orthonormal condition that is similar to those found in PCA.
Here, we obtain , , and , which are the eigenvector, eigenvalue, and unit matrices, respectively. Note that is a diagonal matrix whose ith diagonal element ( ) is the variance of the ith PC, and the ith column vector of is the corresponding eigenvector.
We consider approximating using only a few top components with the contribution ratio of the eigenvalues. Typically, is sorted in descending order such that the first PC shows the greatest variance , and the corresponding column vector of indicates the eigenvector of .
3.2. Estimation of Two-Time Covariance Matrix
Here, let for be the vector of M-dimensional stock price vectors in the intraday on the date indexed by d, where and represent the start and end dates of the interval used in the estimation period, respectively. In addition, let k be a positive integer, and consider the interval starting from the k days prior to the current date, d through d. Then, the two-time covariance matrix , estimated by the sample data from through d, is defined as follows:
3.3. Estimation of External Force Vector
Here, we consider and for to be the external force vector and the observed displacement vector in the intraday on day d, respectively. Using the observed and the estimated , we can estimate by solving the following system of linear equations using the LRM:
However, the number is large; thus, may generally fall in an ill-conditioned matrix. Therefore, it is difficult to solve (55) directly. To address this problem, we apply a dimension reduction technique to (55) via PCA (refer to Section 3.1). Let and be the eigenvalue and eigenvector matrix of , respectively. In this case, we fix the parameter to cut off the eigenvalue close to zero. Let be a number of elements in the set , i.e., . We consider the projection with as follows:
Then, (55) for this projection space is expressed as follows:
where
By setting successfully and removing the components with small eigenvalues, is well conditioned.
Finally, to convert to approximately in the original dimension L, the following equation is applied for :
We then use the force vectors estimated using (60). In addition, we estimate as follows:
3.4. Data Generation by MLRM
Here, we explain the data generation process using the proposed MLRM. Let be a fixed day, and let for be the approximated external force vectors given by (60). Then, we obtain the following data generation equation using the MLRM:
where
for , and is selected to prevent (62) from diverging. Note that and are calculated using (52) and (61), respectively.
3.5. DTW
In this study, we use DTW [44] to compare the generated and real time-series data. DTW represents the distance between the generated time-series data and the real time-series data . Note that a small DTW value means that the dynamics of the two sets of time-series data are similar. In addition, the cost function associated with a warping path is obtained by computing with respect to all pairwise distances :
The warping path that incurs the minimum cost associated with the alignment is referred to as the optimal warping path. DTW is defined as the cost function with the optimal warping path as follows:
4. Experimental Results
4.1. Experimental Data
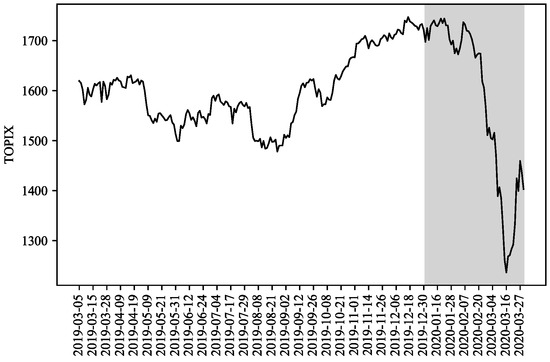
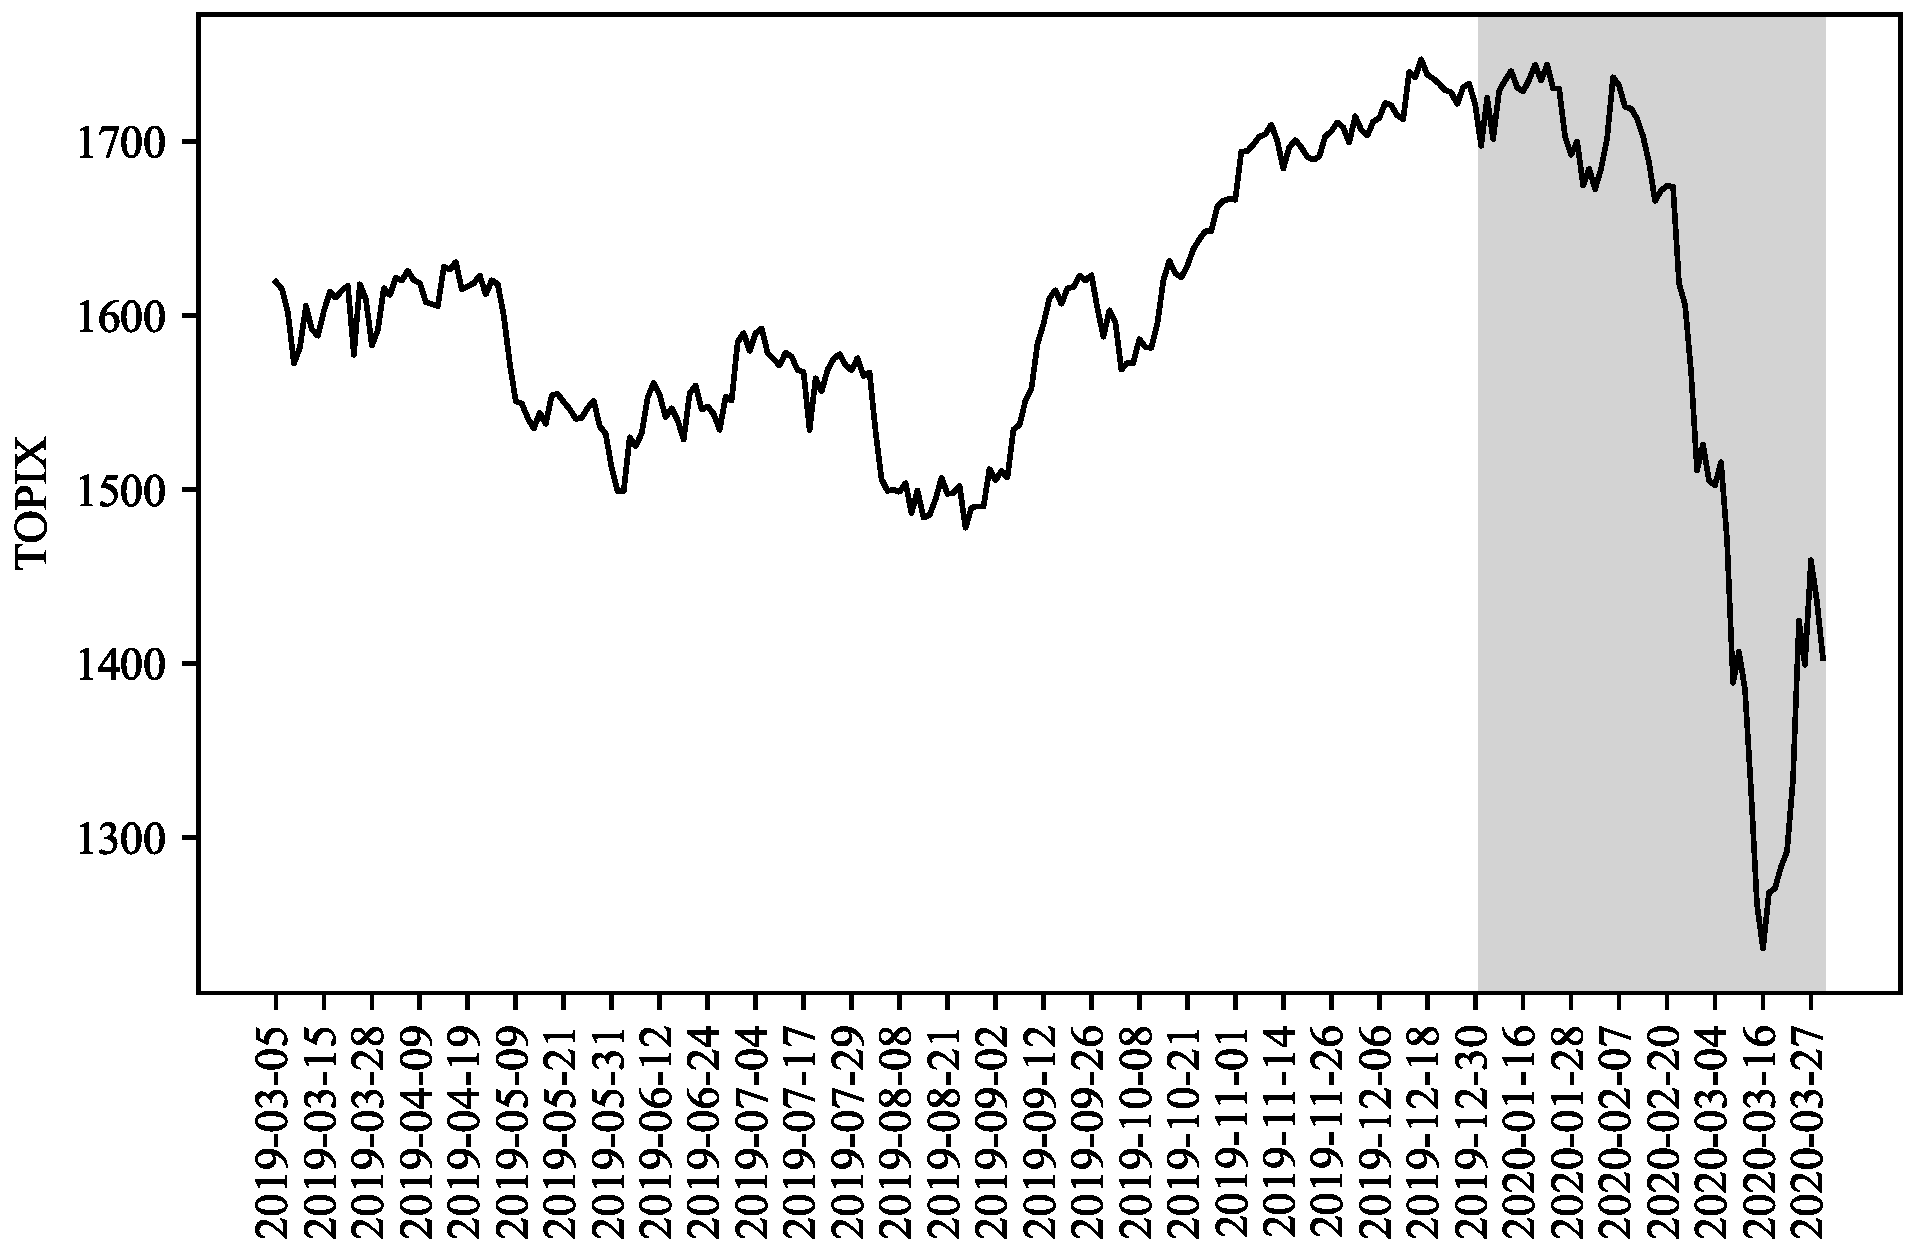
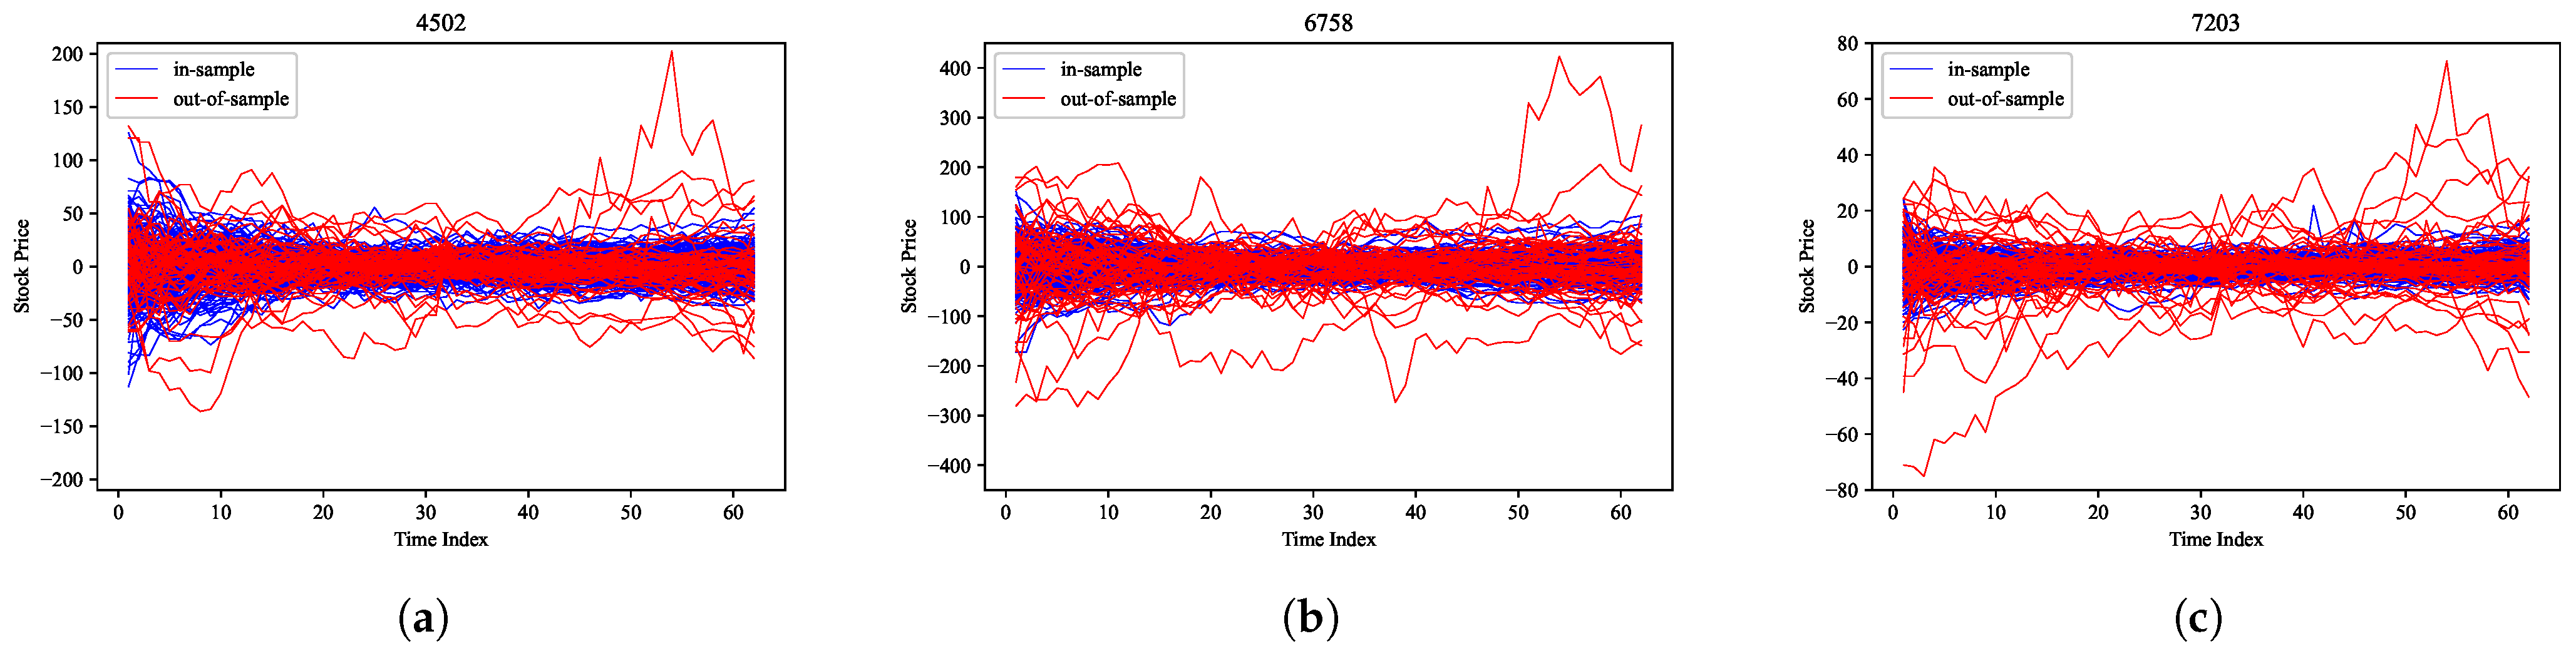
To evaluate the proposed model, we selected the Tokyo Stock Exchange (TSE) as the target market and used time-series data for stock prices extracted from the FLEX Full data which is a dataset that Japan Exchange Group (JPX) constructs with the real-time stock market data from the TSE on a daily basis and provides it as historical information. The Tokyo Stock Price Index (TOPIX) is a capitalization-weighted index of all companies listed in the First Section of the TSE. The black line in Figure 3 shows the time evolution in the TOPIX from March 2019 to March 2020. The COVID-19 shock caused the TOPIX to decline sharply in both February 2020 and March 2020. Here, we divided this period into two smaller periods without and with the COVID-19 shock, respectively, and we refer to these periods as the in-sample and out-of-sample periods, respectively. The latter period is shown as a gray region in Figure 3. As target stocks, we selected stocks, i.e., Takeda Pharmaceutical Co., Ltd. (4502), Sony Corporation (6758), and Toyota Motor Corporation (7203) from the group of stocks listed on the TSE between March 2019 and March 2020 and included in the TOPIX CORE 30, which is the stock price index comprising 30 stocks with considerably high market capitalization and liquidity among all stocks on the TSE. In addition, we selected 09:00 to 11:30 (morning session) and 12:30 to 15:00 (afternoon session) as the time zones and used snapshots of the stock price data every 5 min. This resulted in time-series data for a total of 62 time points (9:00 to 11:30 ( representing 31-time points) and 12:30 to 15:00 (representing 31-time points) per day. In addition, all stock prices are preprocessed to make their averages zero in the time direction, which are denoted for and . Thus, and the dimension of for was , and the index of this dimension was referred to as a Time-Stock Index. The red and blue lines in Figure 4 show the time-series data for the three stock prices in the in-sample and out-of-sample periods, respectively.
Figure 3.
TOPIX: the black line represents the time evolution of the TOPIX from March 2019 to March 2020, while the gray region denotes the out-of-sample period (January 2020 to March 2020).
Figure 4.
Time-series data of stock prices: (a) Takeda Pharmaceutical Co., Ltd. (4502), (b) Sony Corporation (6758), and (c) Toyota Motor Corporation (7203). The red line represents the in-sample data; the blue line denotes the out-of-sample data.
4.2. Estimation of External Force Vectors
In this evaluation, we set and , and we estimated using (52). In addition, we determined the number D of the eigenvalues , such that the sum of eigenvalue ratios for just exceeds . This value of D was employed to remove eigenvalues that are close to zero. Using the number of reduced eigenvalues , we calculated the reduced matrix with the projection vectors (refer to (58)).
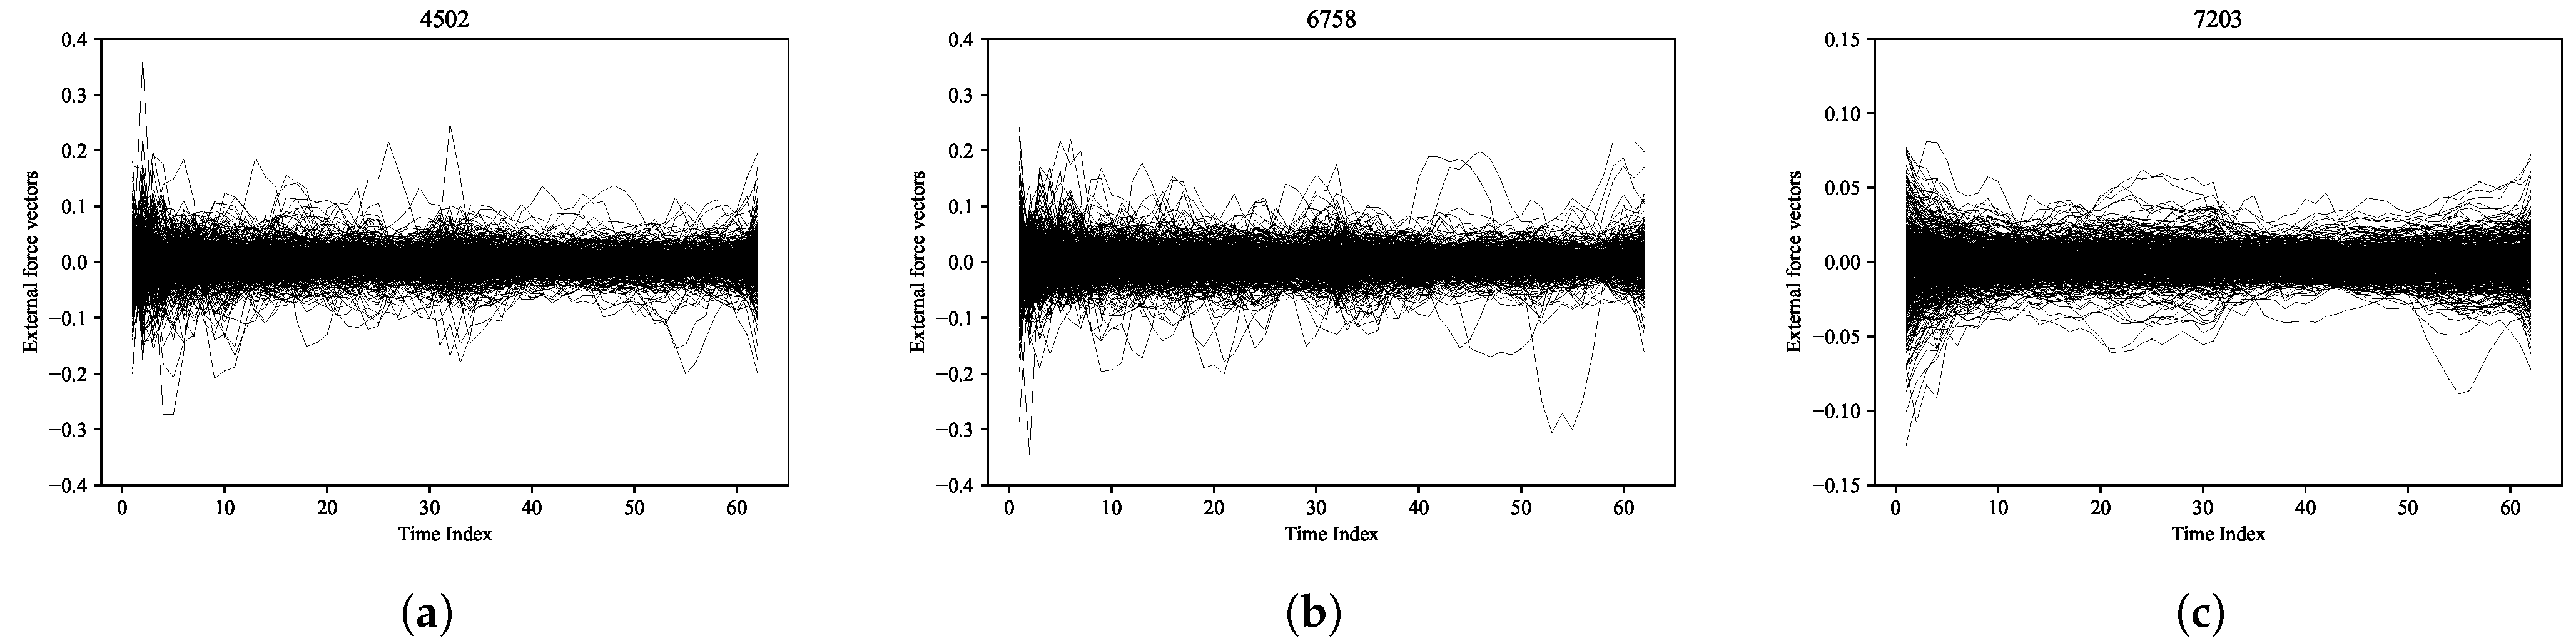
The set is the real stock price data, which we considered to be under the influence of external forces. We calculated by subtracting the expected values of . We then obtained using the projection vectors (refer to (56)). Next, we estimated using (57).
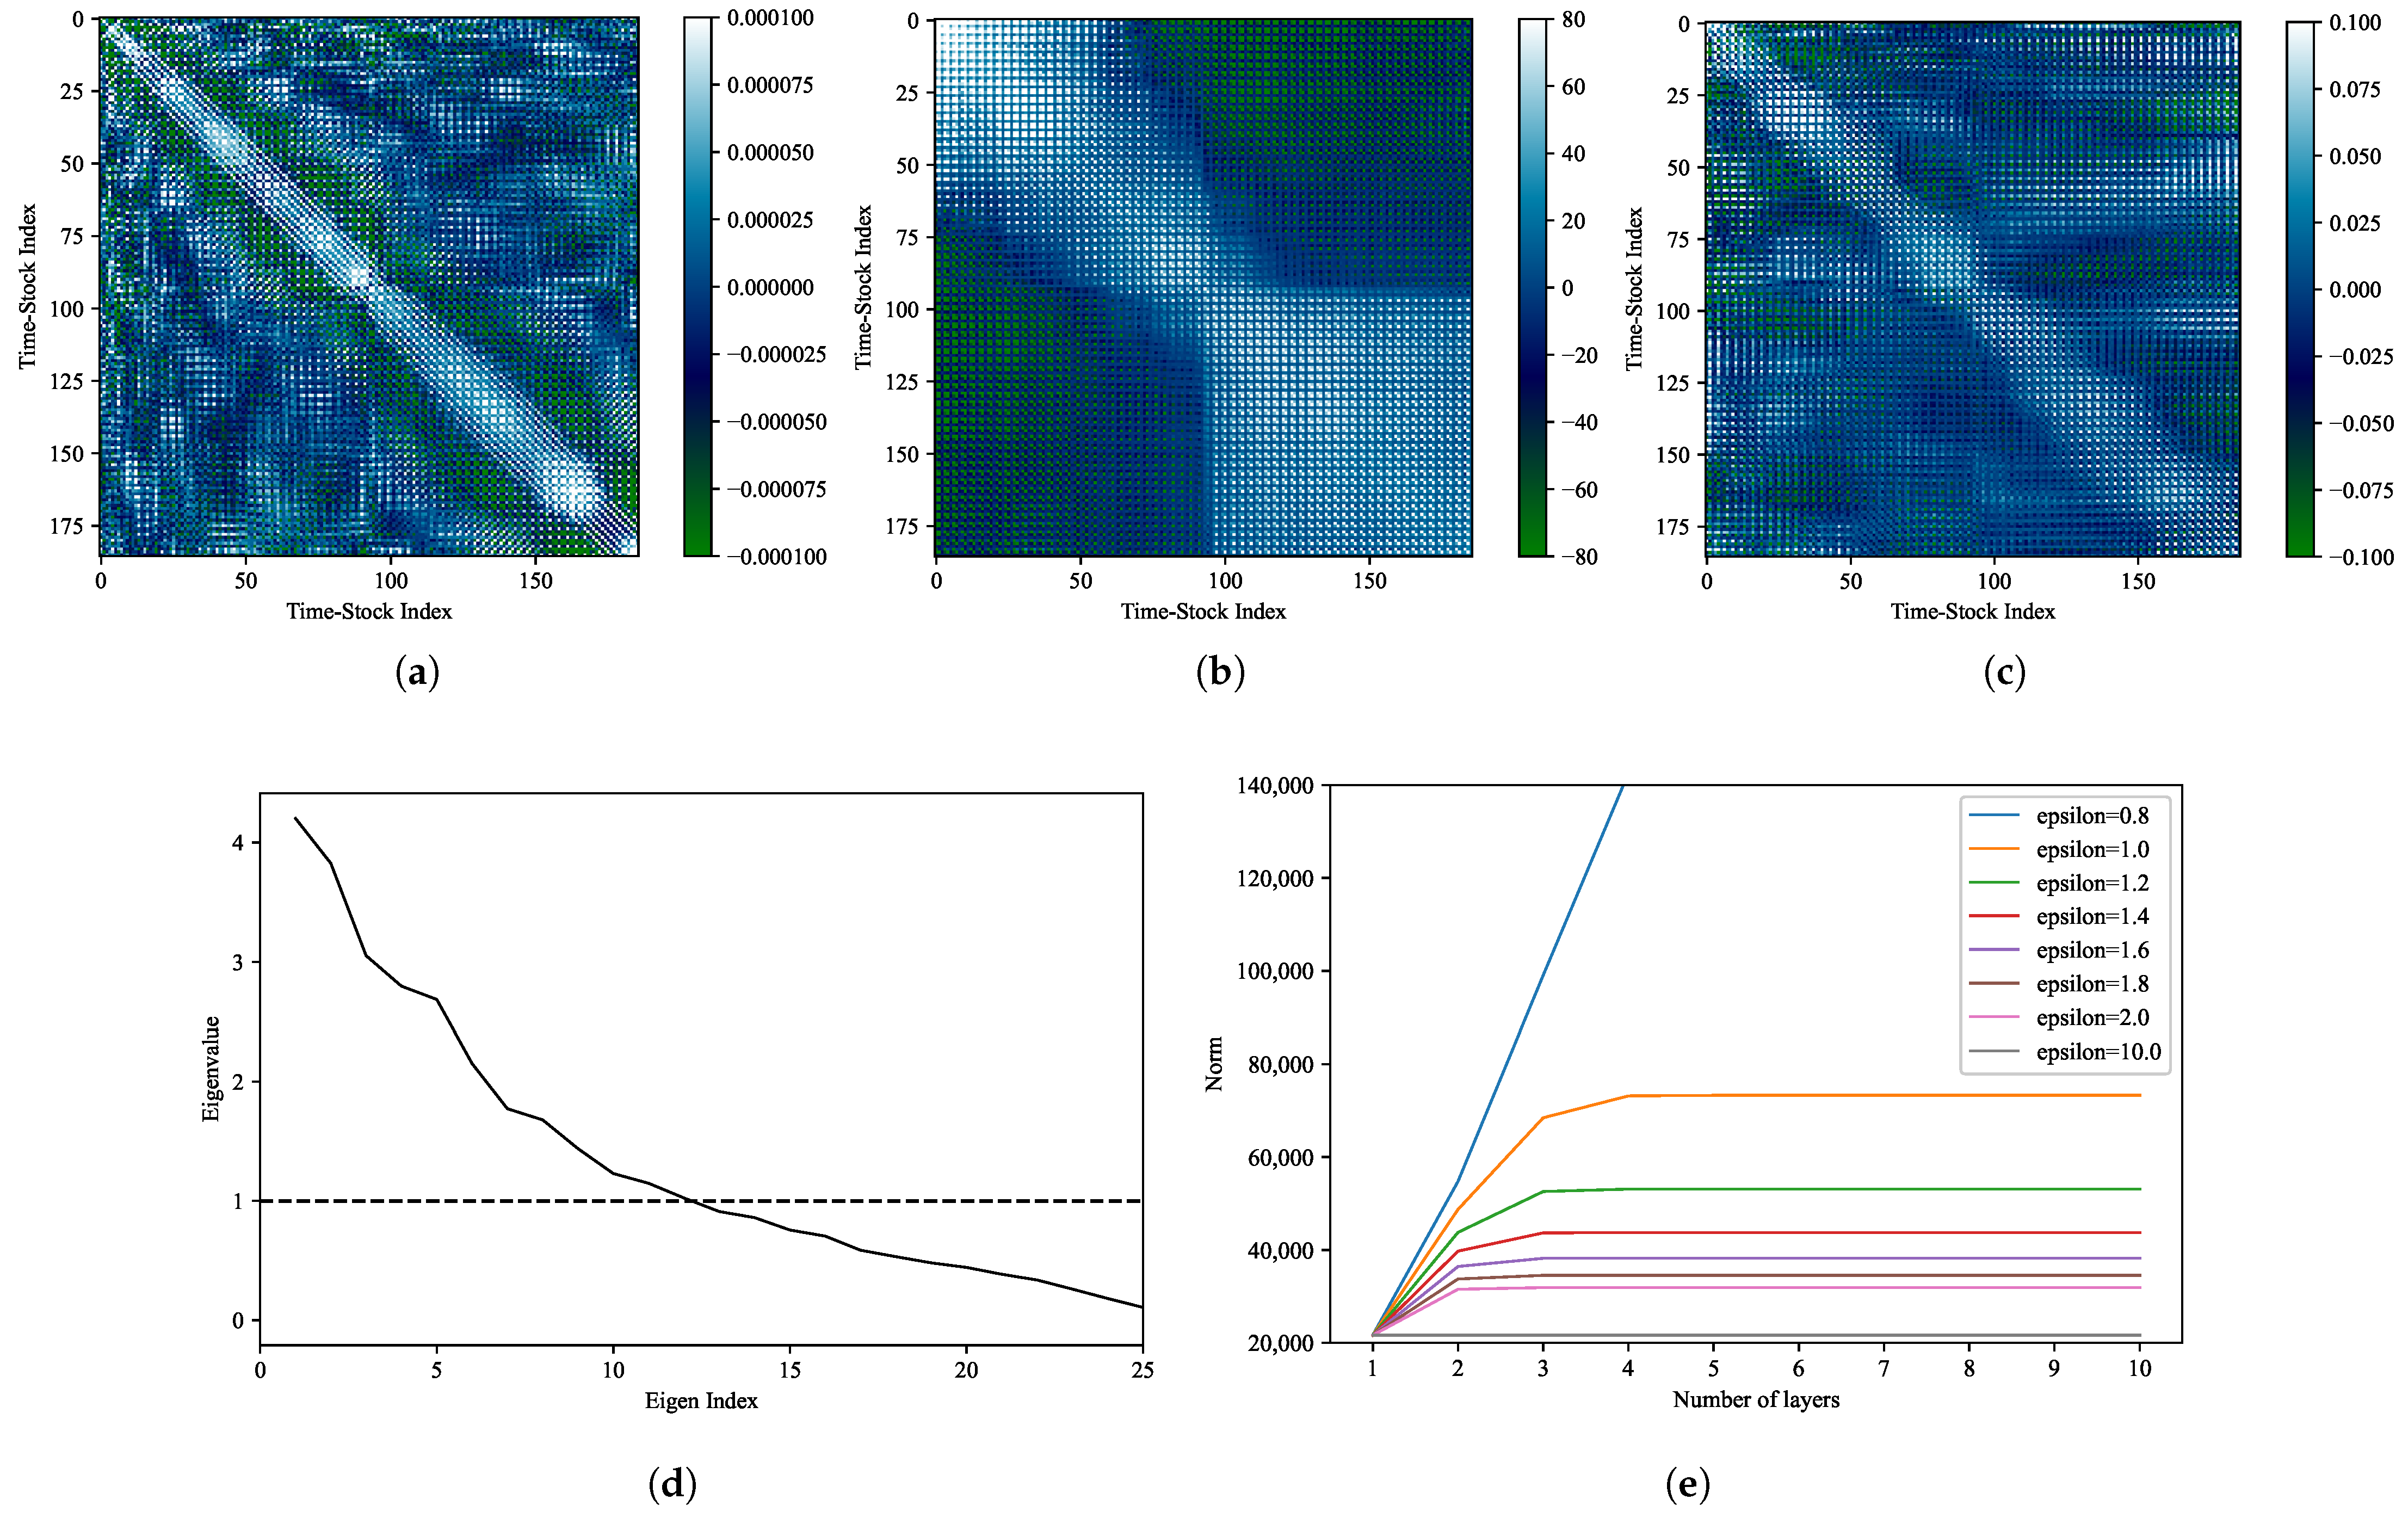
Note that are vectors in a lower-dimensional space; thus, we approximated by transforming them back to the original dimension using (60). From these transformations, we obtained various patterns of external forces based on the historical data. The results for Takeda Pharmaceutical Co., Ltd. (Tokyo, Japan) (4502), Sony Corporation (Tokyo, Japan) (6758), and Toyota Motor Corporation (Toyota, Japan) (7203) are shown in Figure 5a–c, respectively. Using the calculated external forces, we computed using (61), and the results are presented in Figure 6a. As can be seen, the matrix is symmetric, and it exhibits a strong positive correlation near the diagonal.
Figure 5.
External force vectors: (a) Takeda Pharmaceutical Co., Ltd. (4502), (b) Sony Corporation (6758), and (c) Toyota Motor Corporation (7203) for .
Figure 6.
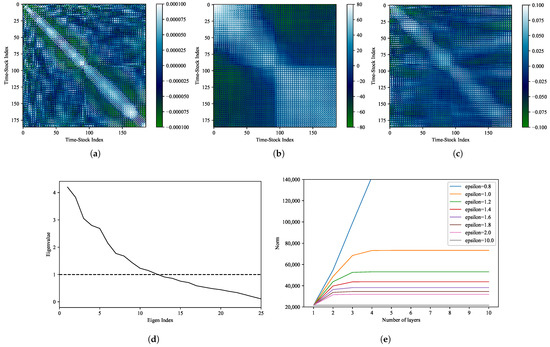
Matrices using the MLRM and its convergence: (a) , (b) , (c) , (d) eigenvalues of and (e) norms of ( and ).
4.3. Estimation of and
We selected the day , i.e., 30 December 2019, which is the last date in the in-sample period. The corresponding two-time covariance matrix is shown in Figure 6b, which shows the existence of high values near the diagonal and a negative correlation between the morning and afternoon sessions.
Figure 6c shows the matrix estimated by (35), which is an asymmetric matrix. Here, we obtained the eigenvalues by solving the eigenvalue problem for using (39) to (41). Figure 6d shows the eigenvalues of from 1 to 25. As can be seen, the eigenvalues of include values that are greater than 1.0, which means that the MLRM diverges as the number of layers increases. To address this divergence problem, data generation using the MLRM was performed by introducing the parameter to realize the sufficient suppression of divergence.
Next, we examined the convergence speed, depending on , using in (63). Here, we evaluated how the norm of changed as we increased the number of layers, with values ranging from 0.8 to 100.0. Figure 6e shows the results of the norm values of . The results confirm that, as the number of layers increases, a large value typically approaches the SLRM, and a small value diverges. In this study, we selected among candidates for which the convergence of the norm was confirmed. In addition, we confirmed that 10 layers are sufficient for convergence; thus, the number of layers for the MLRM was set to , thereby resulting in a 10-layer LRM (10-LRM).
4.4. Data Generation Using MLRM
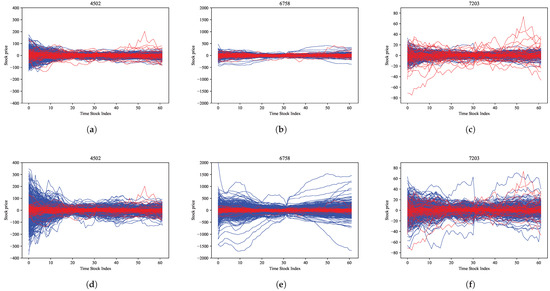
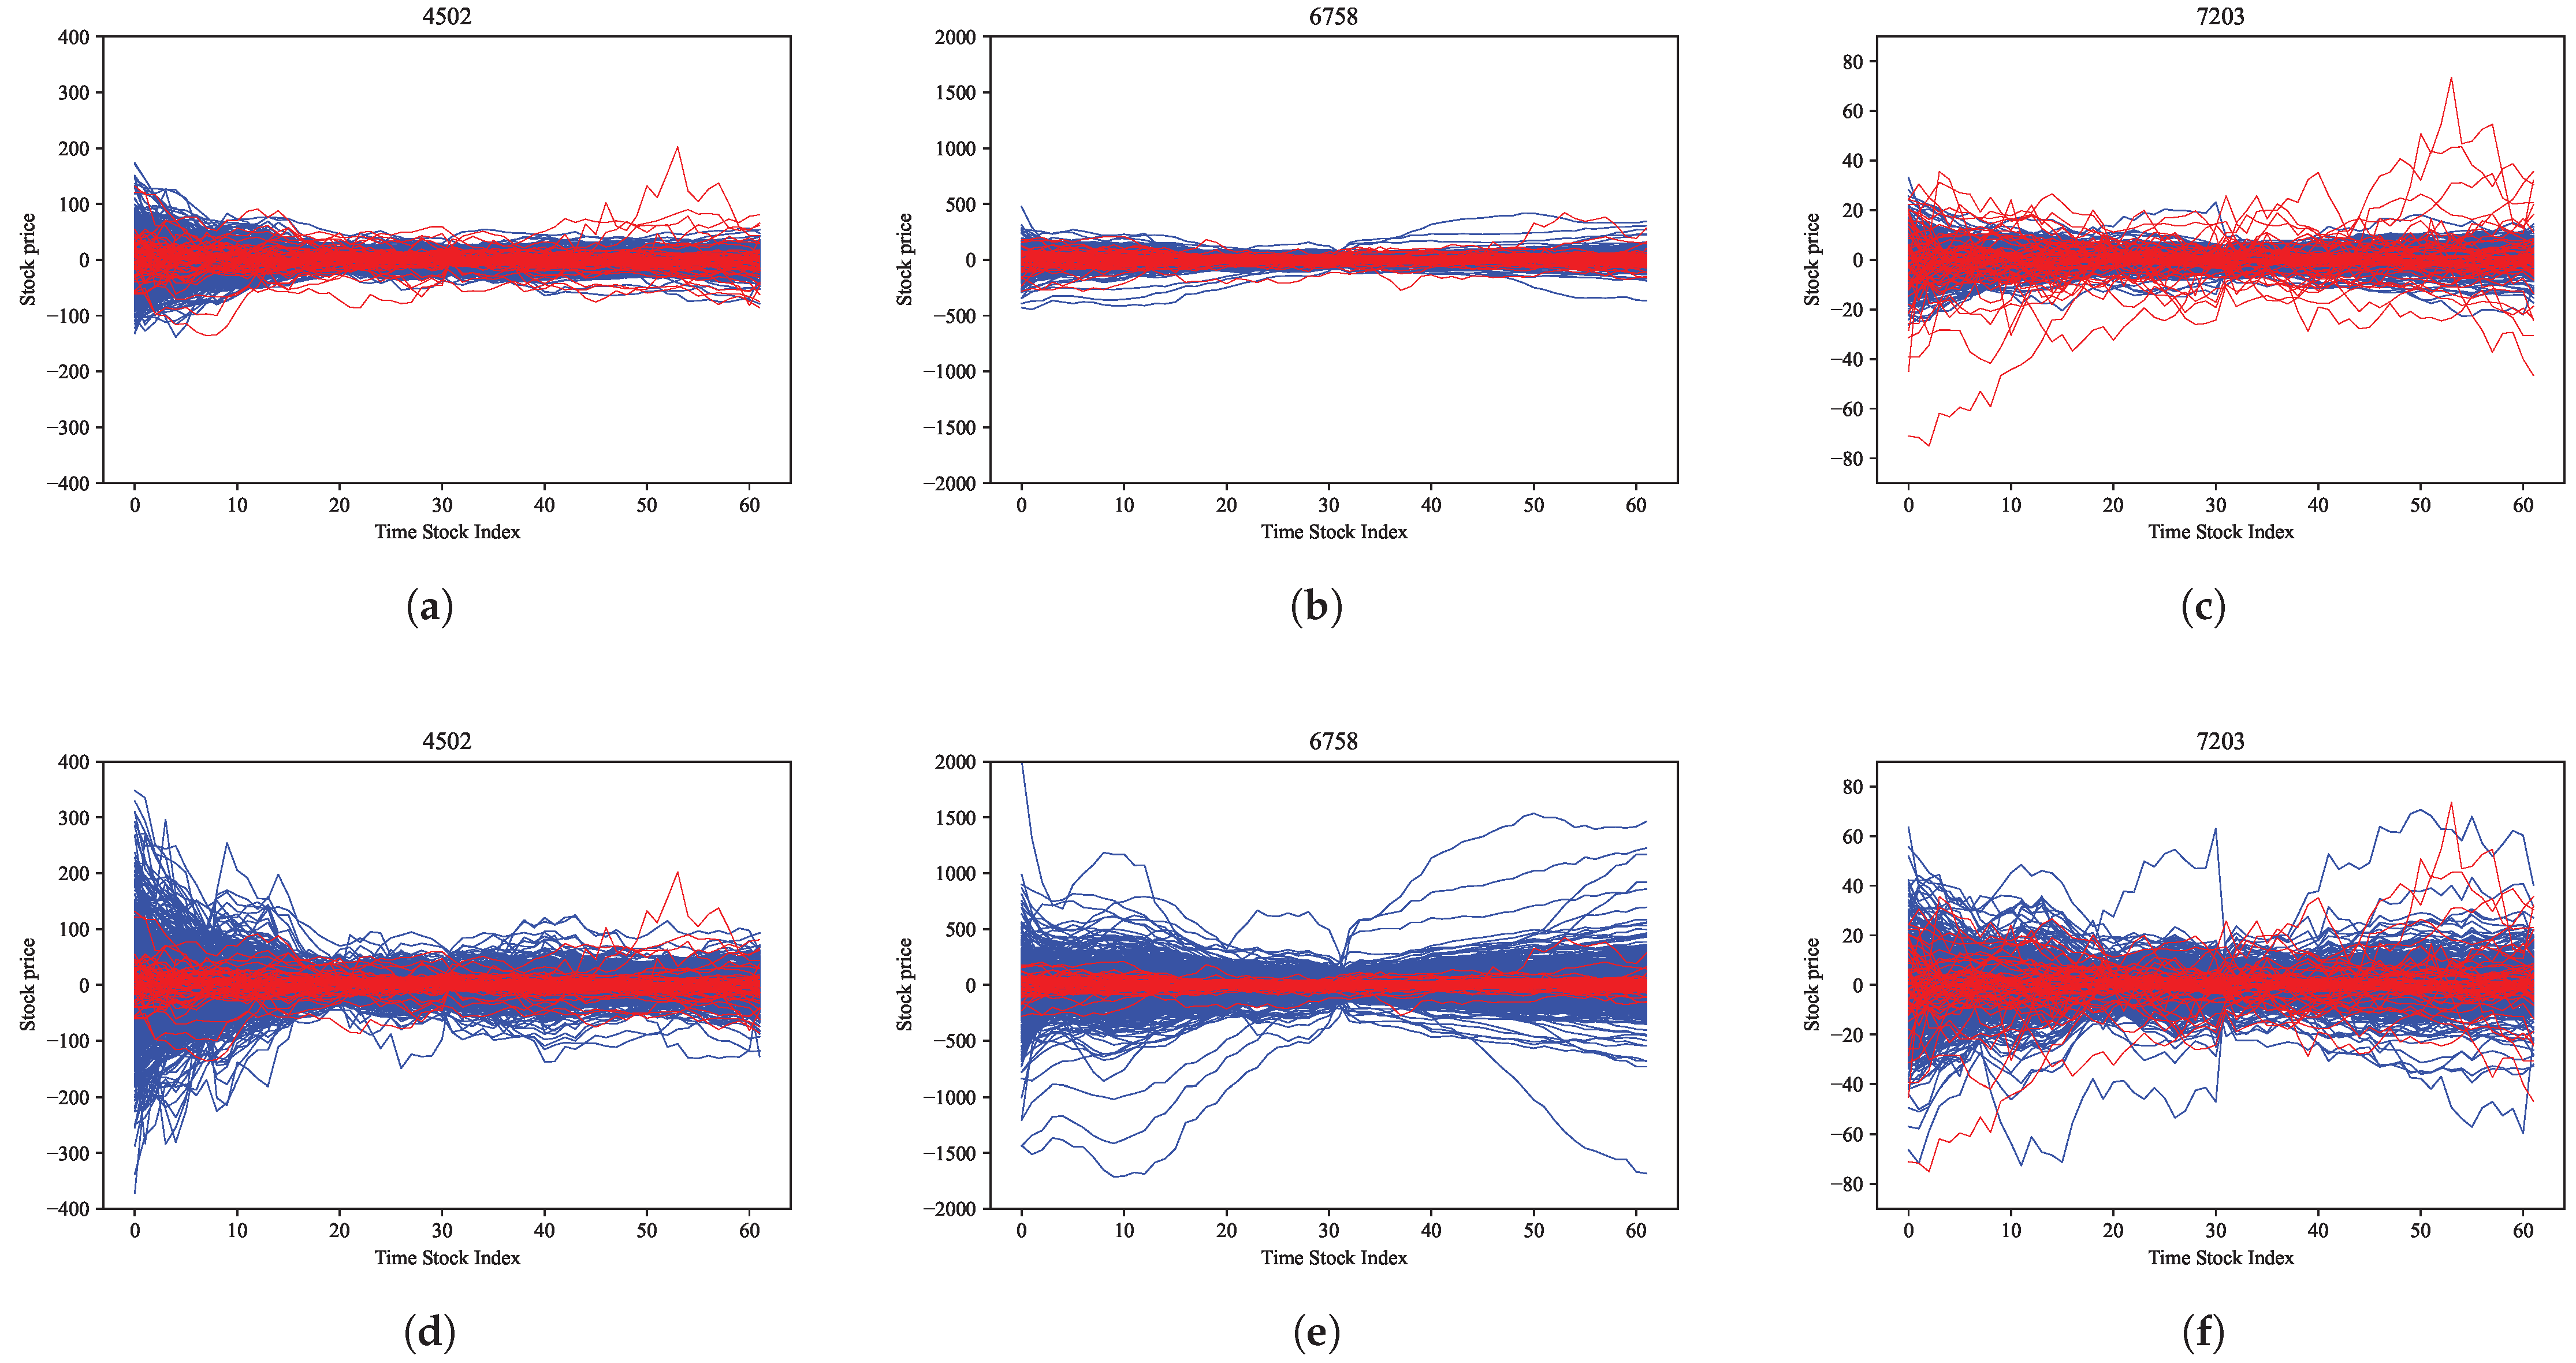
In this evaluation, we set and , and the data generation for each stock by the proposed MLRM was performed using (62). Figure 7 shows the data generation results for Takeda Pharmaceutical Co., Ltd., Sony Corporation, and Toyota Motor Corporation, respectively. In Figure 7, the upper (a,b,c) and lower (d,e,f) graphs show the size of the data generated via the SLRM and MLRM (10-LRM) (blue lines), respectively, and the red lines represent the real out-of-sample data, which include samples with very large fluctuations due to the COVID-19 pandemic. A comparison of the SLRM and MLRM methods shows that the MLRM generates time-series with larger fluctuations than the SLRM. The time-series data generated via the proposed MLRM indicate that the out-of-sample fluctuations are covered. These results suggest that the data generation results obtained using the proposed MLRM contain information about the dynamics that is similar to that of the out-of-sample data.
Figure 7.
Comparison of the stock price data generated via the SLRM and the MLRM. (a–c) show the results of the SLRM, and (d–f) show the results of the MLRM for three representative stocks: (a,d) Takeda Pharmaceutical Co., Ltd. (4502); (b,e) Sony Corporation (6758); and (c,f) Toyota Motor Corporation (7203). The blue lines represent the generated stock price data via the SLRM and MLRM (10-layer MLRM), and the red lines represent the real out-of-sample data.
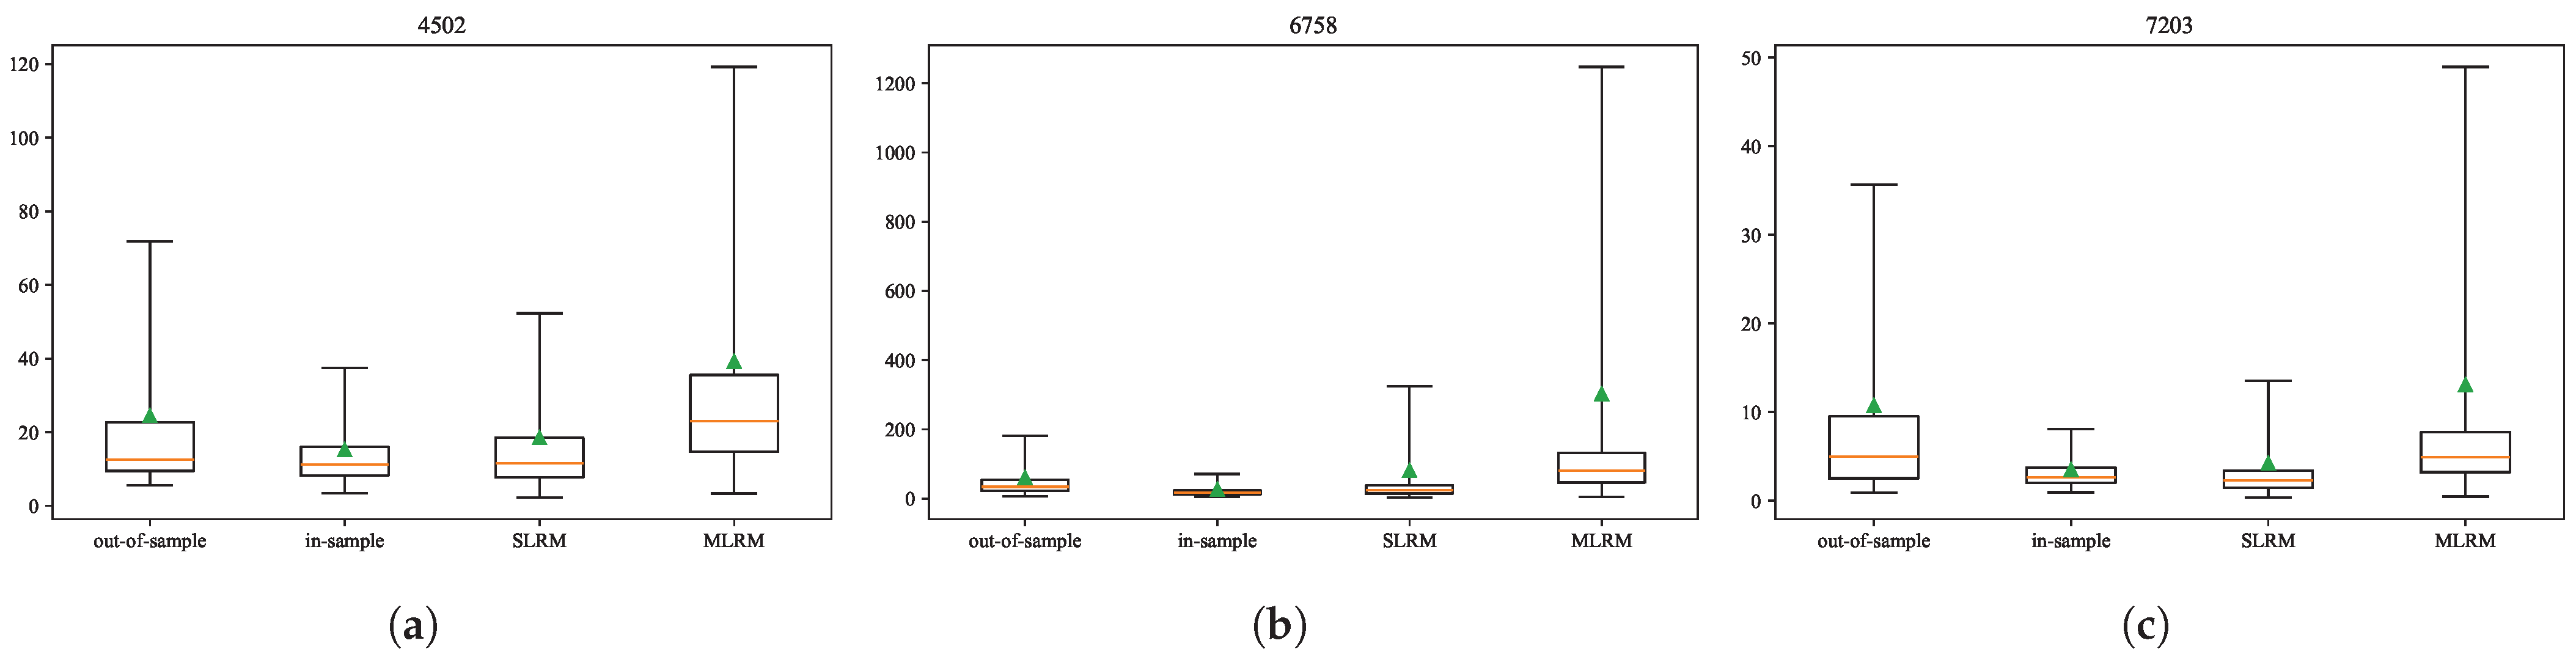
Figure 8 shows box plots for the percentile of the stock price’s standard deviation (SD) calculated using the in-sample data, out-of-sample data, SLRM, and proposed MLRM. As can be seen, the fluctuations in the out-of-sample data are much larger than those in the in-sample data, which only partially capture the fluctuations observed in the out-of-sample period. The data generated via the SLRM show an improvement compared to the in-sample data, except for Sony Corporation (6752); however, the fluctuations captured via the SLRM do not fully account for those observed in the out-of-sample data. In contrast, the proposed MLRM generated significantly larger fluctuations, thereby effectively covering the out-of-sample fluctuations. These results demonstrate that the data generated via the proposed MLRM are more similar to the out-of-sample data than to the other sample data.
Figure 8.
Box plots of the percentiles of the stock price’s SD: (a) Takeda Pharmaceutical Co., Ltd. (4502), (b) Sony Corporation (6758), and (c) Toyota Motor Corporation (7203). The black horizontal lines represent the 0th, 25th, 75th, and 100th percentiles (from the bottom), and the orange line indicates the 50th percentile. The triangles represent the averages.
4.5. Comparison of DTW
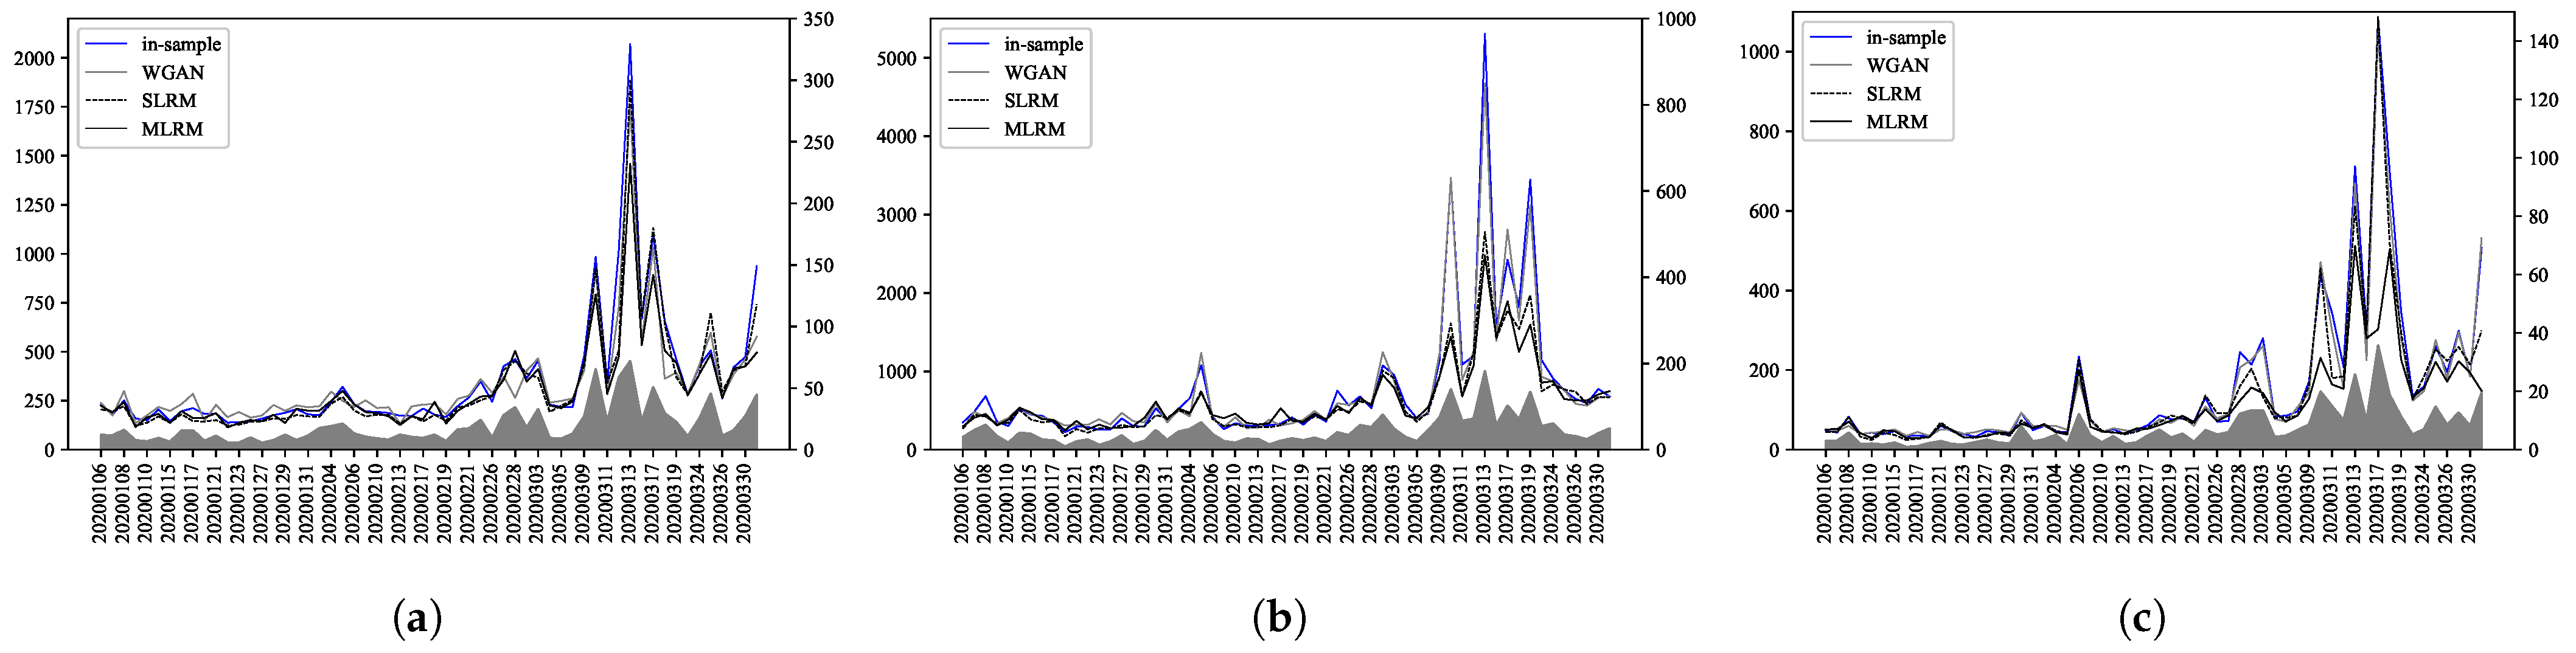
We employed DTW to evaluate the similarity between the out-of-sample stock price data and the generated time-series dynamics. We also compared the results with those obtained using the WGAN. The WGAN is a machine learning method that generates time-series data by learning the in-sample data distribution through adversarial training. These comparisons are illustrated in Figure 9. We define minDTW as the minimum DTW distance between the out-of-sample data and any of the generated data samples. The left axis of Figure 9 shows the minDTW value for each day.
Figure 9.
Comparison of daily minDTW for (a) Takeda Pharmaceutical Co., Ltd. (4502), (b) Sony Corporation (6758), (c) Toyota Motor Corporation (7203). The minDTW (left axis) is shown for the in-sample (blue line), SLRM (black dotted line), proposed MLRM (black line), and WGAN (gray line). The light gray areas represent the SD of the stock prices (right axis).
Here, a smaller minDTW indicates higher similarity between the two time-series data. The right axis shows the SD of the stock price. Notably, there are areas that exhibit high SD, particularly between 10 March 2020, and 19 March 2020, which is likely due to market disruptions caused by the COVID-19 pandemic. The in-sample results exhibit very high minDTW during periods heavily influenced by COVID-19, which indicates that the in-sample data does not contain time-series data that are similar to those for the COVID-19 period, thereby contributing to the high minDTW. The SLRM obtained better results than the in-sample results because the extrapolation representation of the SLRM, which is a first-order approximation relative to external forces, works very effectively. However, the proposed MLRM realized the most significant improvement in the minDTW during the COVID-19 period, which suggests that the MLRM captured large fluctuation dynamics effectively. In contrast, the results obtained via the WGAN were similar to the in-sample results, with higher minDTW during the COVID-19 period. These findings indicate that it is difficult to generate time-series data that are similar to those during the COVID-19 period using machine learning models that are dependent on historical data.
Table 1, Table 2 and Table 3 show the minDTW for the top 10 highest-SD days for each stock in the out-of-sample data, sorted by the SD, where the bold numbers indicate the lowest values in each column. The results in these tables confirm that the MLRM is able to generate data closer to the out-of-sample data than other methods on high-SD days. As expected, the MLRM successfully generates data with large fluctuations.
Table 1.
minDTW of the top 10 highest-SD days for 4502. Bold indicates the minimum value among the methods in each row.
Table 2.
minDTW of the top 10 highest-SD days for 6752. Bold indicates the minimum value among the methods in each row.
Table 3.
minDTW of the top 10 highest-SD days for 7203. Bold indicates the minimum value among the methods in each row.
Next, Table 4, Table 5 and Table 6 show the minDTW for the top 10 lowest-SD days for each stock in the out-of-sample data, also sorted by the SD. The results confirm that the SLRM is able to generate data closer to the out-of-sample data than other methods on low-SD days. This suggests that the SLRM is effective for generating data without large fluctuations.
Table 4.
minDTW of the top 10 lowest-SD days for 4502. Bold indicates the minimum value among the methods in each row.
Table 5.
minDTW of the top 10 lowest-SD days for 6552. Bold indicates the minimum value among the methods in each row.
Table 6.
minDTW of the top 10 lowest-SD days for 7203. Bold indicates the minimum value among the methods in each row.
In summary, the evaluation results demonstrate that the proposed MLRM is a more effective tool for capturing the dynamics of anomalous events, such as those we faced during the COVID-19 pandemic. Moreover, by utilizing data generated from both the SLRM and MLRM, we can obtain artificial data that reflects the dynamics of both small and large fluctuations.
4.6. Comparison of Real Dynamics and Data Generated by MLRM
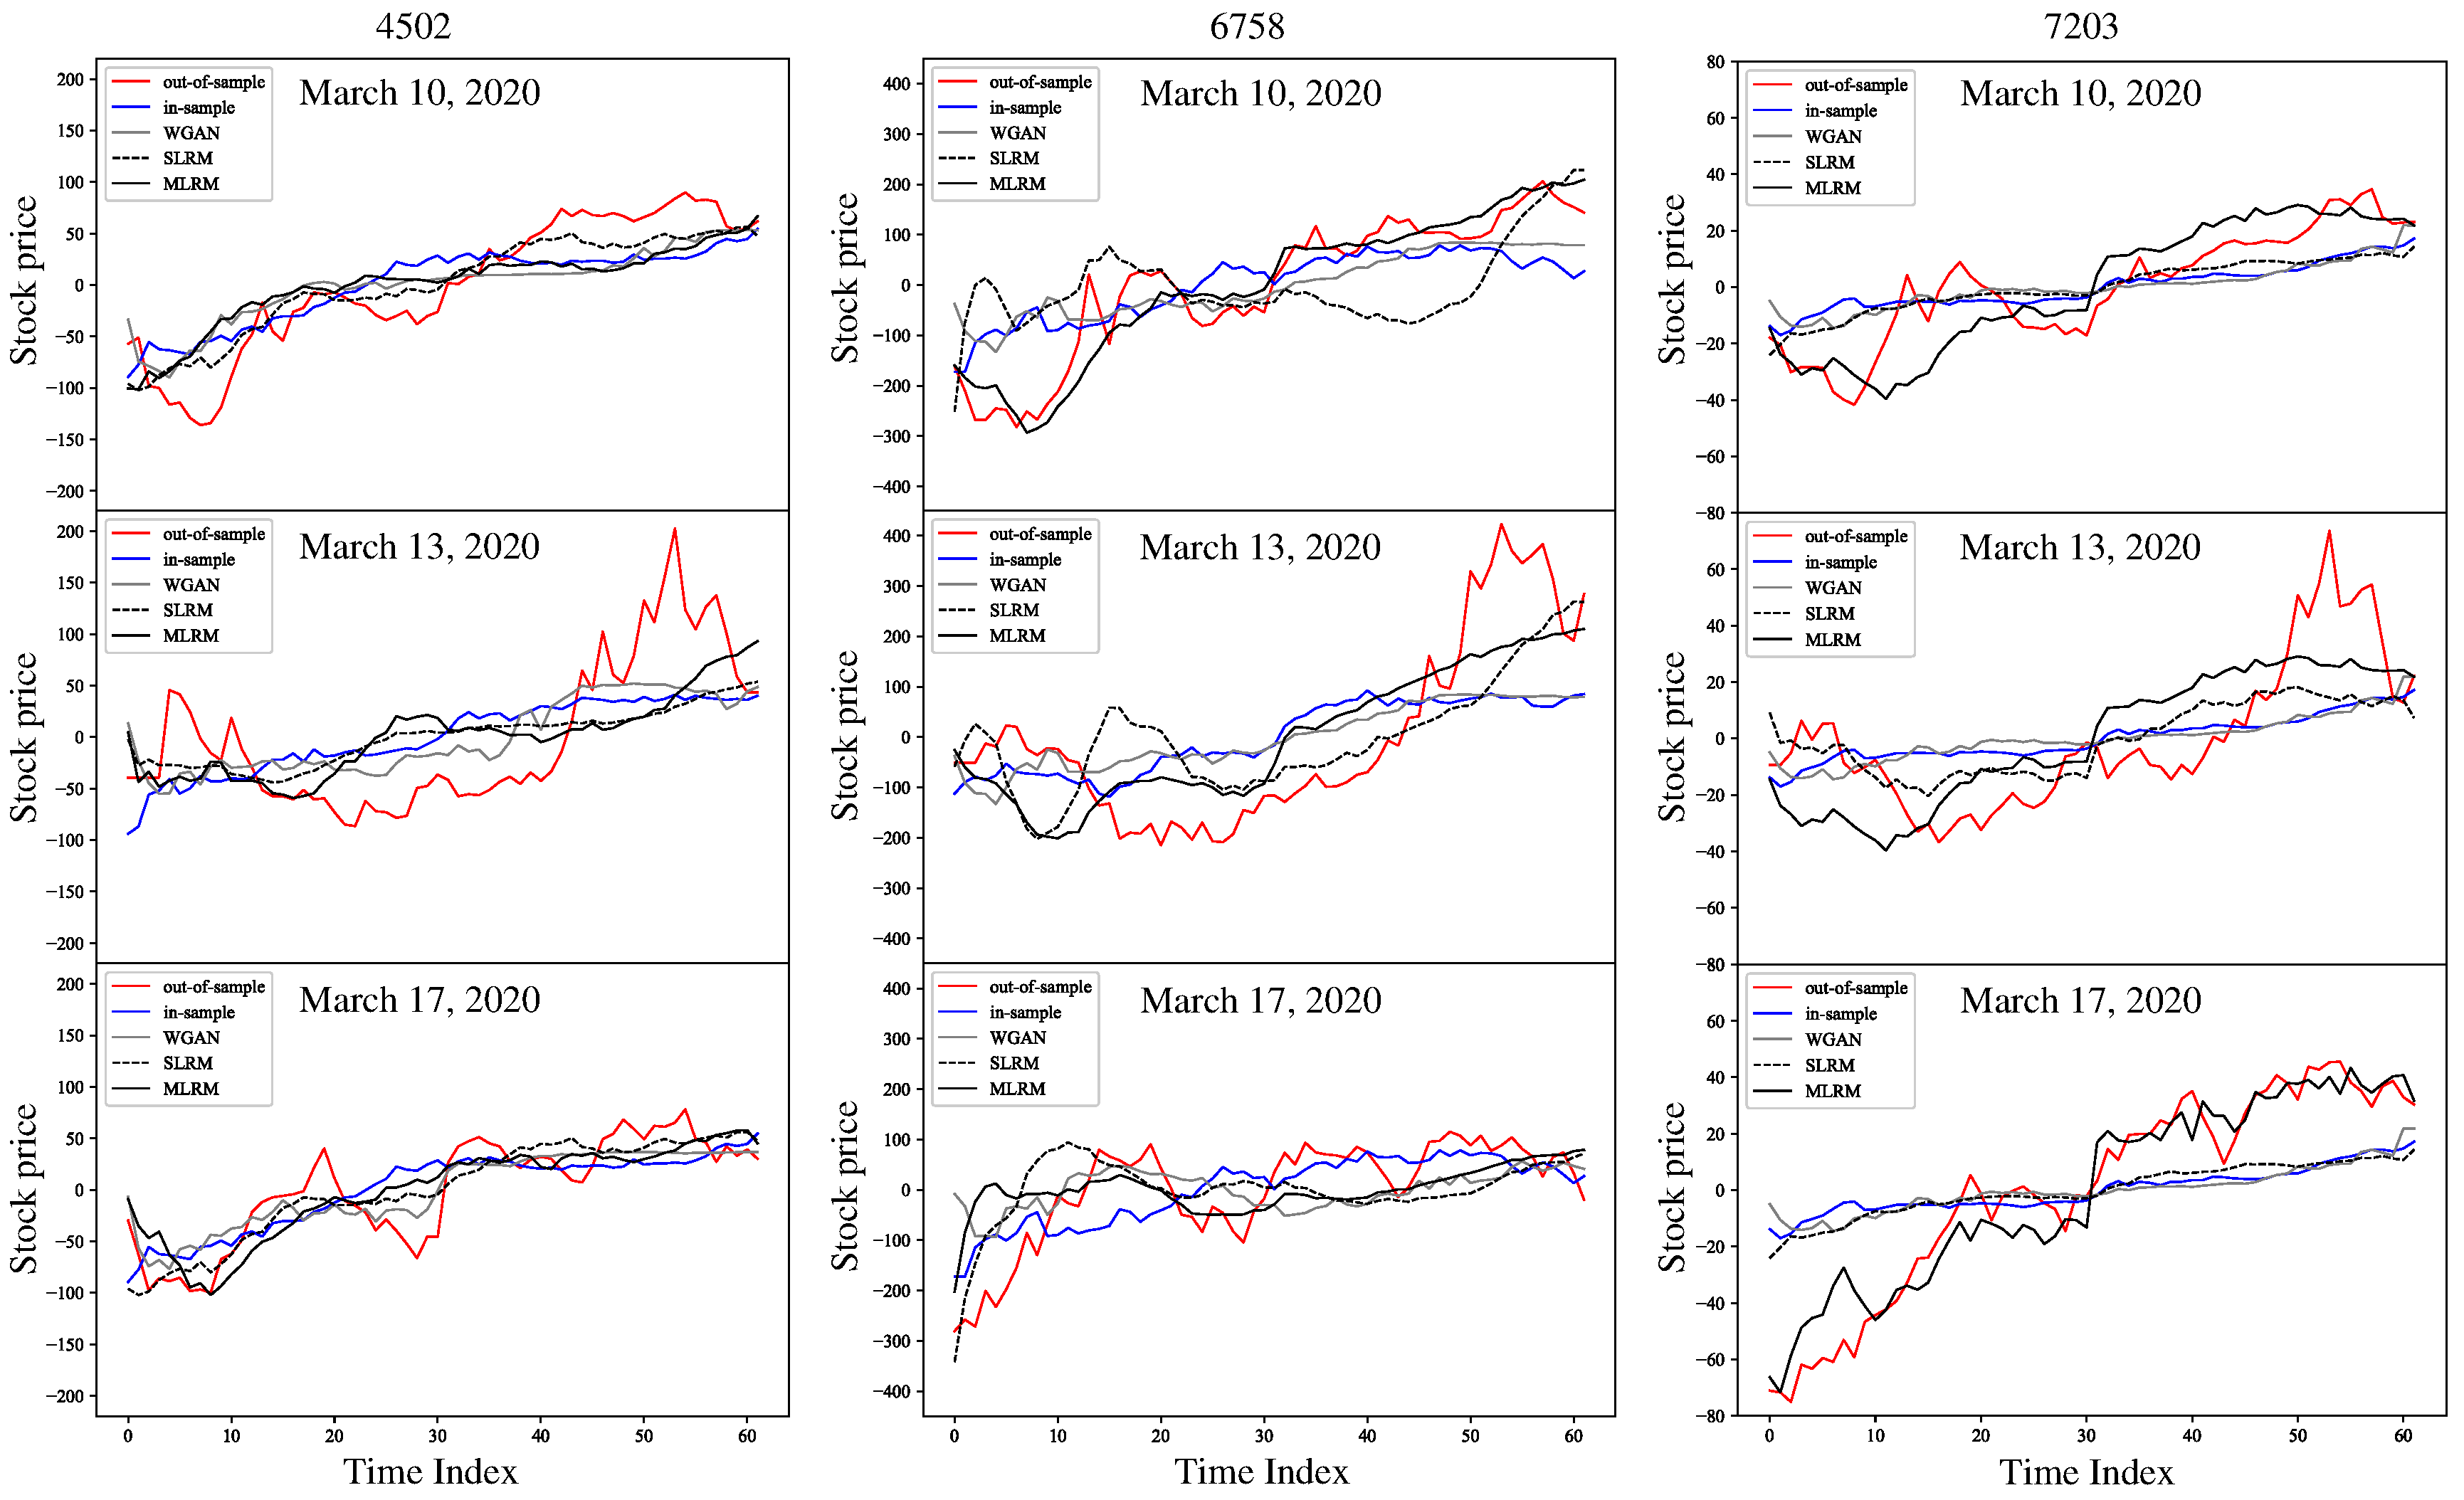
Furthermore, we compared the stock price dynamics of the generated and real data. Here, we focused on 10 March, 13 March, and 17 March 2020, when stock prices experienced significant fluctuations due to the impact of the COVID-19 pandemic. Figure 10 compares the dynamics between the real and generated data for the in-sample, WGAN, SLRM, and proposed MLRM, where each was selected based on the minDTW.
Figure 10.
Comparison of dynamics on 10 March 2020, 13 March 2020, and 17 March 2020. The time-series data for the out-of-sample (red line), in-sample (blue line), WGAN (grey line), SLRM (dotted black line), and MLRM (black line) are shown. Each was selected based on the minDTW.
On 10 March, 13 March, and 17 March 2020, the minDTW values of the MLRM were lower than those of the in-sample, WGAN, and SLRM in most cases from Table 1, Table 2 and Table 3. Specifically, as shown in Figure 10, the stock price dynamics for Sony Corporation (6758) on 10 March 2020, and Toyota Motor Corporation (7203) on 17 March 2020, generated via the proposed MLRM were highly similar to the real data. This indicates that the MLRM faces challenges in generating stock price dynamics under highly uncertain conditions. Therefore, we expect that the MLRM will be applicable to various problems in the financial domain, e.g., risk management and scenario testing.
4.7. Tail Behavior of Log-Return Distributions
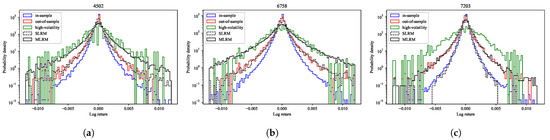
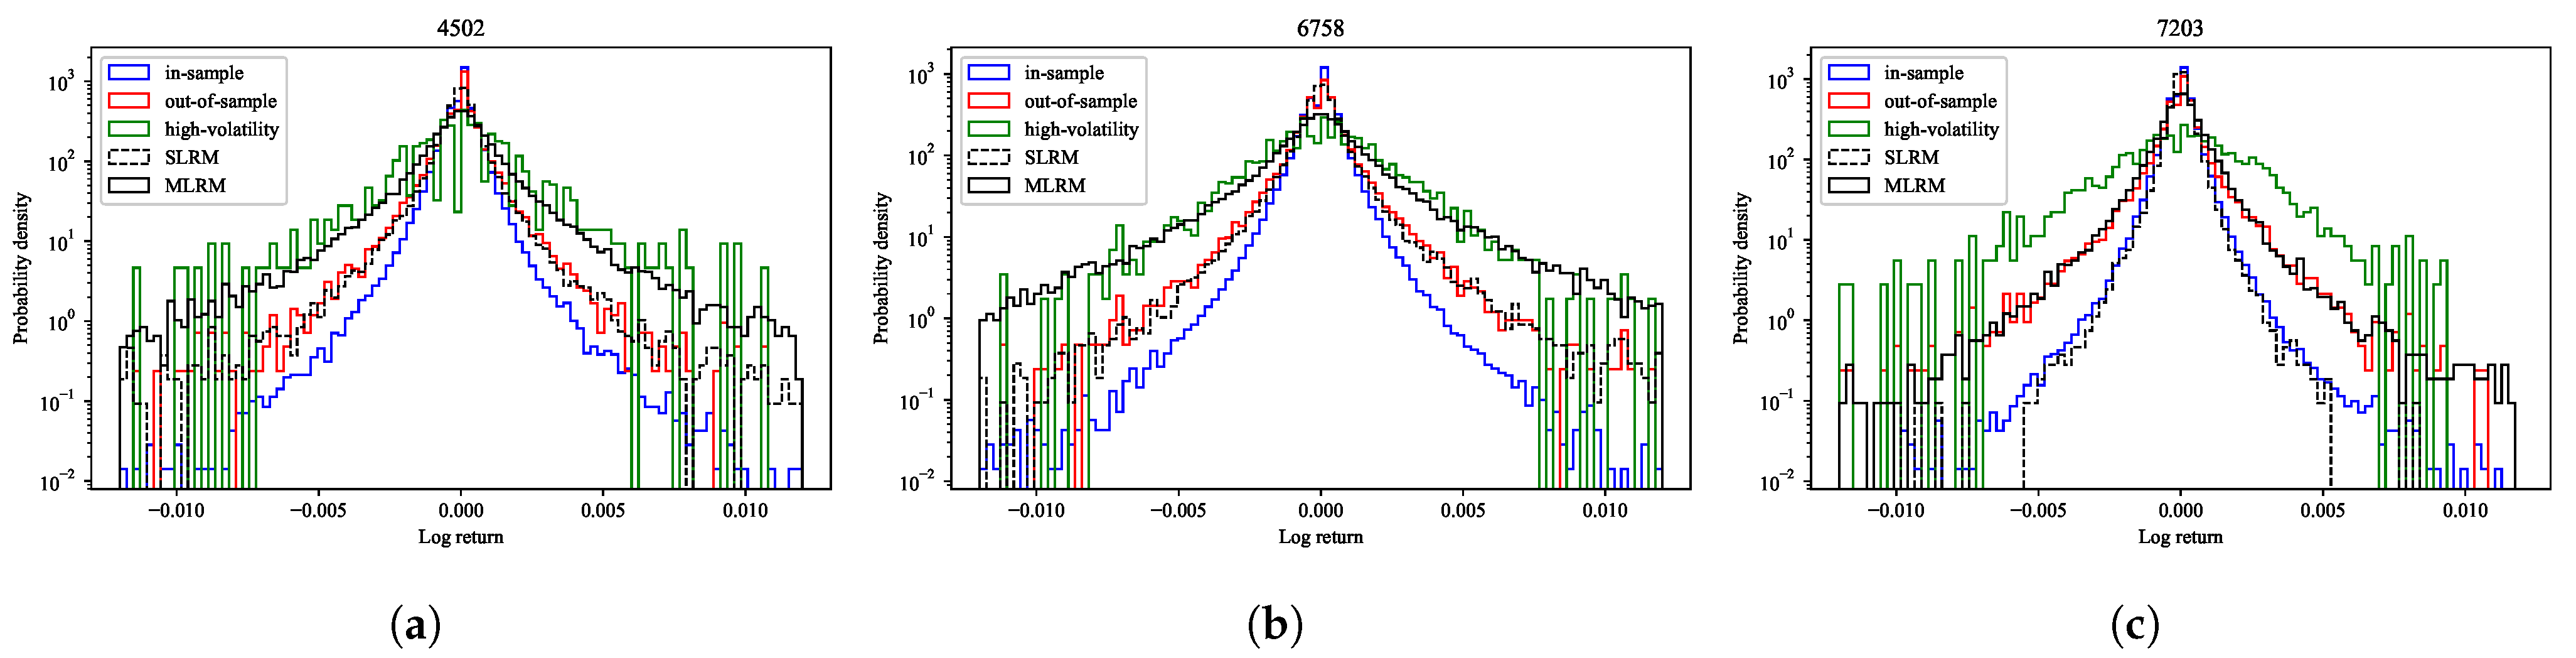
Figure 11 presents the distributions of log returns for three representative stocks (4502, 6758, and 7203). The vertical axis denotes the probability density on a logarithmic scale, while the horizontal axis corresponds to the log return. The empirical distributions for the in-sample period, out-of-sample period, and a subset of high-volatility observations are compared with those generated by the SLRM and the MLRM. The realized volatility used in this analysis is computed on a daily basis from intraday log returns sampled at 5 min intervals. Specifically, for each trading day, d, the realized volatility, , is defined as follows:
where denotes the t-th 5-min log return on day d, and T is the number of such intervals within a trading day. The high-volatility sample is constructed by selecting out-of-sample observations for which the realized volatility exceeds the upper bound of the interquartile range (IQR), thereby isolating periods characterized by elevated market volatility. It is important to note that the SLRM and MLRM generate stock price series as zero-mean intraday fluctuations, lacking absolute price level information. To ensure consistency with the empirical data, we restore the price level by adding the mean of the in-sample stock price series to the generated outputs before computing the log returns. This procedure enables a meaningful comparison of return distributions across empirical and model-generated data. The distribution generated via the MLRM exhibits heavier tails than that produced using the SLRM, with tail behavior that lies between the empirical distributions of the out-of-sample period and the high-volatility sample. This finding indicates that the MLRM is capable of more effectively capturing the non-stationary dynamics and intricate correlation structures that emerge in the market under high-volatility conditions. By contrast, the SLRM yields a distribution with comparatively thinner tails, consistent with return behavior observed during more typical market regimes.
Figure 11.
Distributions of log returns for three representative stocks: (a) 4502, (b) 6758, and (c) 7203. The vertical axis shows the probability density on a logarithmic scale; the horizontal axis indicates the log return. The empirical distributions are shown for the in-sample period (blue solid line), out-of-sample period (red solid line), and high-volatility period (green solid line). The distributions generated via the SLRM (black dotted line) and the MLRM (black solid line) are also displayed. The MLRM-generated distributions exhibit heavier tails and closely match the empirical distributions observed during high-volatility periods.
Table 7 shows the estimated excess kurtosis () of the log-return distributions for stocks 4502, 6758, and 7203. The excess kurtosis of a random variable, X, with mean and standard deviation , is defined as
Excess kurtosis characterizes the heaviness of the distribution tails relative to a normal distribution. A normal distribution has ; positive values of indicate heavier tails and a higher likelihood of extreme returns, while negative values indicate lighter tails. In the MLRM-generated data, increasing the number of model layers leads to higher kurtosis, enabling the model to capture extreme market fluctuations and the heavy-tailed behavior observed in real financial markets effectively.
Table 7.
Parameter estimates for the in-sample data, the out-of-sample data, and data generated via the MLRM with varying numbers of layers.
The parameter , estimated from the log-return distributions and reported in Table 7, corresponds to the exponent of the power-law tail, characterizing the rate of decay in the distribution’s tails. Empirical studies of financial markets have shown that the tail behavior of log returns typically follows , where the so-called cubic law suggests that is approximately 3 under ordinary market conditions—specifically in developed markets, characterized by high liquidity and institutional maturity. Values of lower than 3 indicate heavier tails, implying a higher frequency of extreme returns. In this study, we estimated the tail index using the Hill estimator with a truncation level of 7.5%, following the approach recommended in the literature for developed markets [36]. Our results show that is consistently below 3 across all stocks in both the out-of-sample data and the data generated via the MLRM, demonstrating that the model effectively captures the heavy-tailed nature observed in real financial markets.
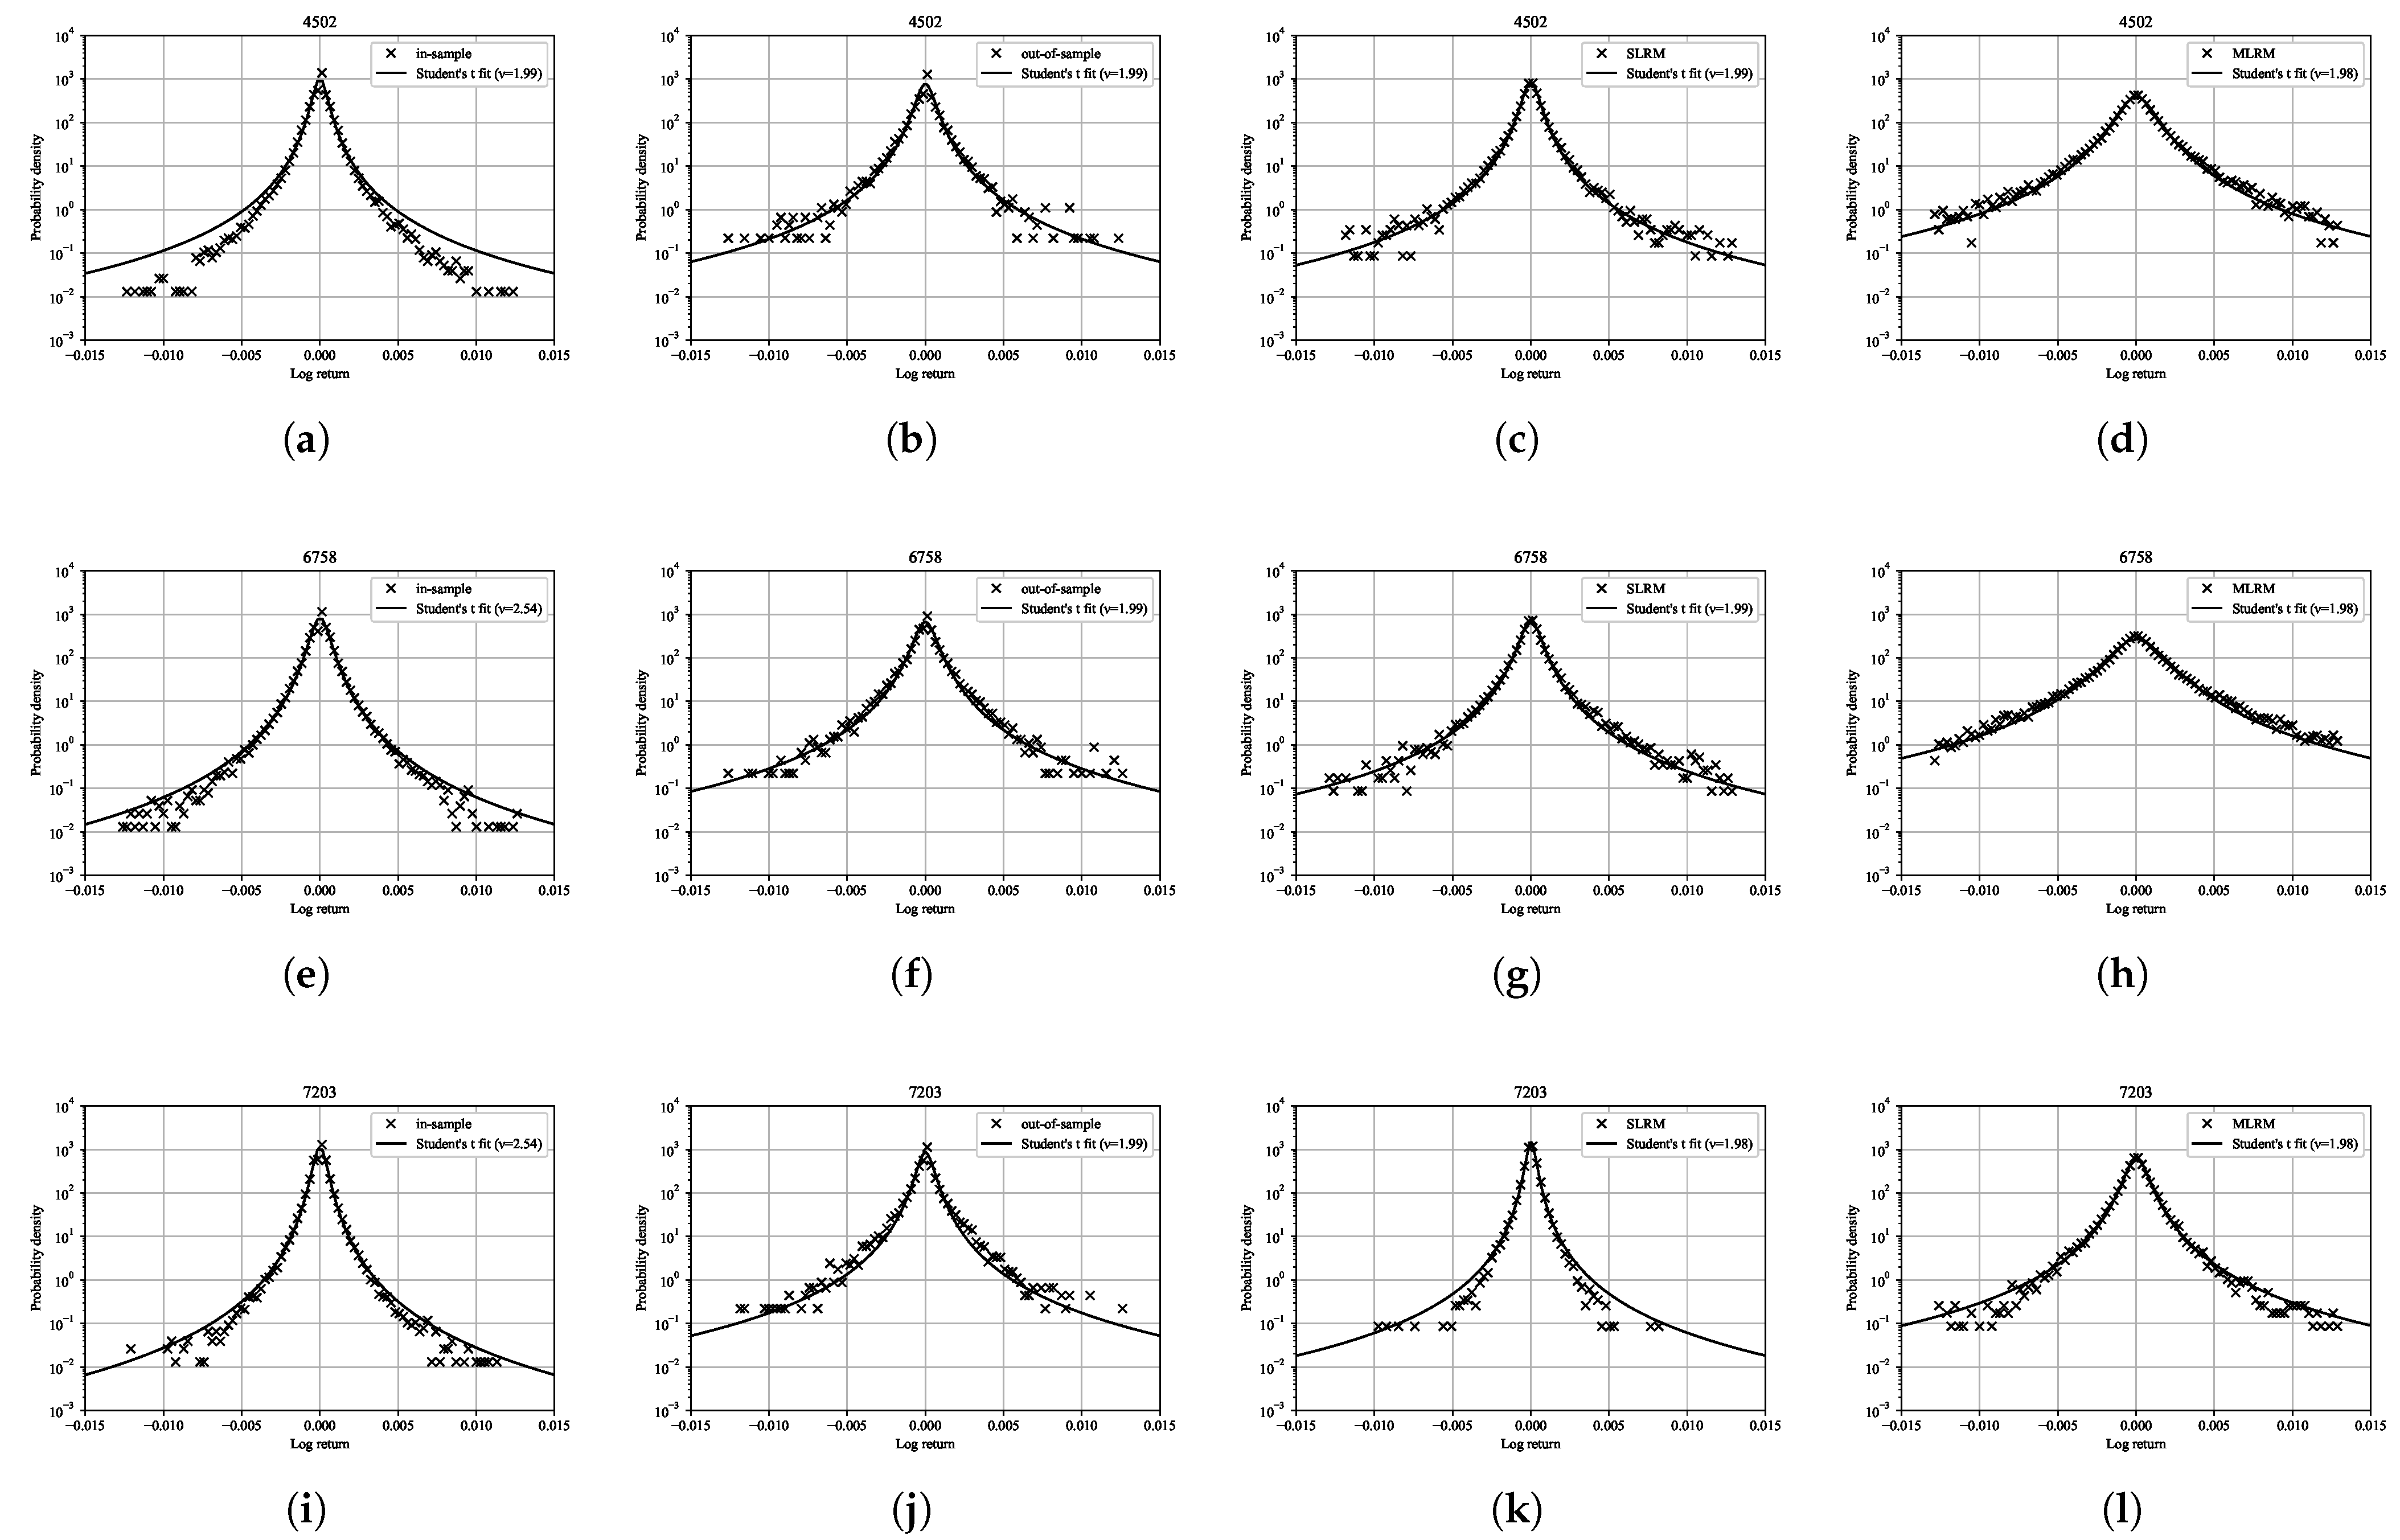
Given that the normal distribution cannot adequately capture such heavy-tailed behavior, we follow the approach of Praetz [41], who demonstrated that heavy-tailed financial returns are well described by Student’s t (or q-Gaussian) distribution. Figure 12 presents the results of fitting Student’s t distributions to the log-return distributions of three representative stocks (4502, 6758, and 7203). The Student’s t distribution with degrees of freedom is defined by the probability density function
where denotes the gamma function. This distribution is symmetric and bell-shaped like the normal distribution but exhibits heavier tails, particularly for small values of . The degree of freedom, , governs the tail heaviness: smaller values of indicate heavier tails and a higher frequency of extreme returns. The fits are shown for the in-sample period, the out-of-sample period, and for data generated via the SLRM and the MLRM, with the estimated degrees of freedom indicated in each panel. The results show that the estimated degrees of freedom remain consistently around 2 across all data sets, reflecting the presence of heavy-tailed behavior in both empirical and model-generated distributions. Both the SLRM and the MLRM successfully reproduce this characteristic, with the MLRM providing slightly better alignment with the empirical tail behavior in some cases. These findings suggest that the models effectively capture the high frequency of extreme returns observed in real financial markets.
Figure 12.
Student’s t distribution fits for the log-return distributions of three representative stocks (4502, 6758, and 7203). For each stock, four types of data are shown: in-sample data (a,e,i), out-of-sample data (b,f,j), data generated via the SLRM (c,g,k), and data generated via the MLRM (d,h,l). Each distribution is fitted with a Student’s t distribution, and the estimated degrees of freedom are indicated in the legend. The probability density is shown on a logarithmic scale to highlight the heavy-tailed behavior. The results demonstrate that both the SLRM and the MLRM can reproduce the heavy-tailed nature of real financial returns, with the MLRM providing a better fit across all three stocks.
4.8. Tail Behavior of Realized Volatility Distributions
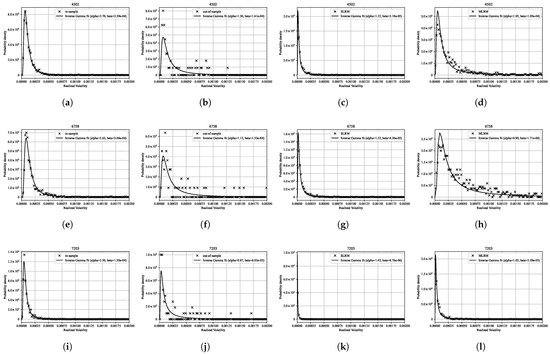
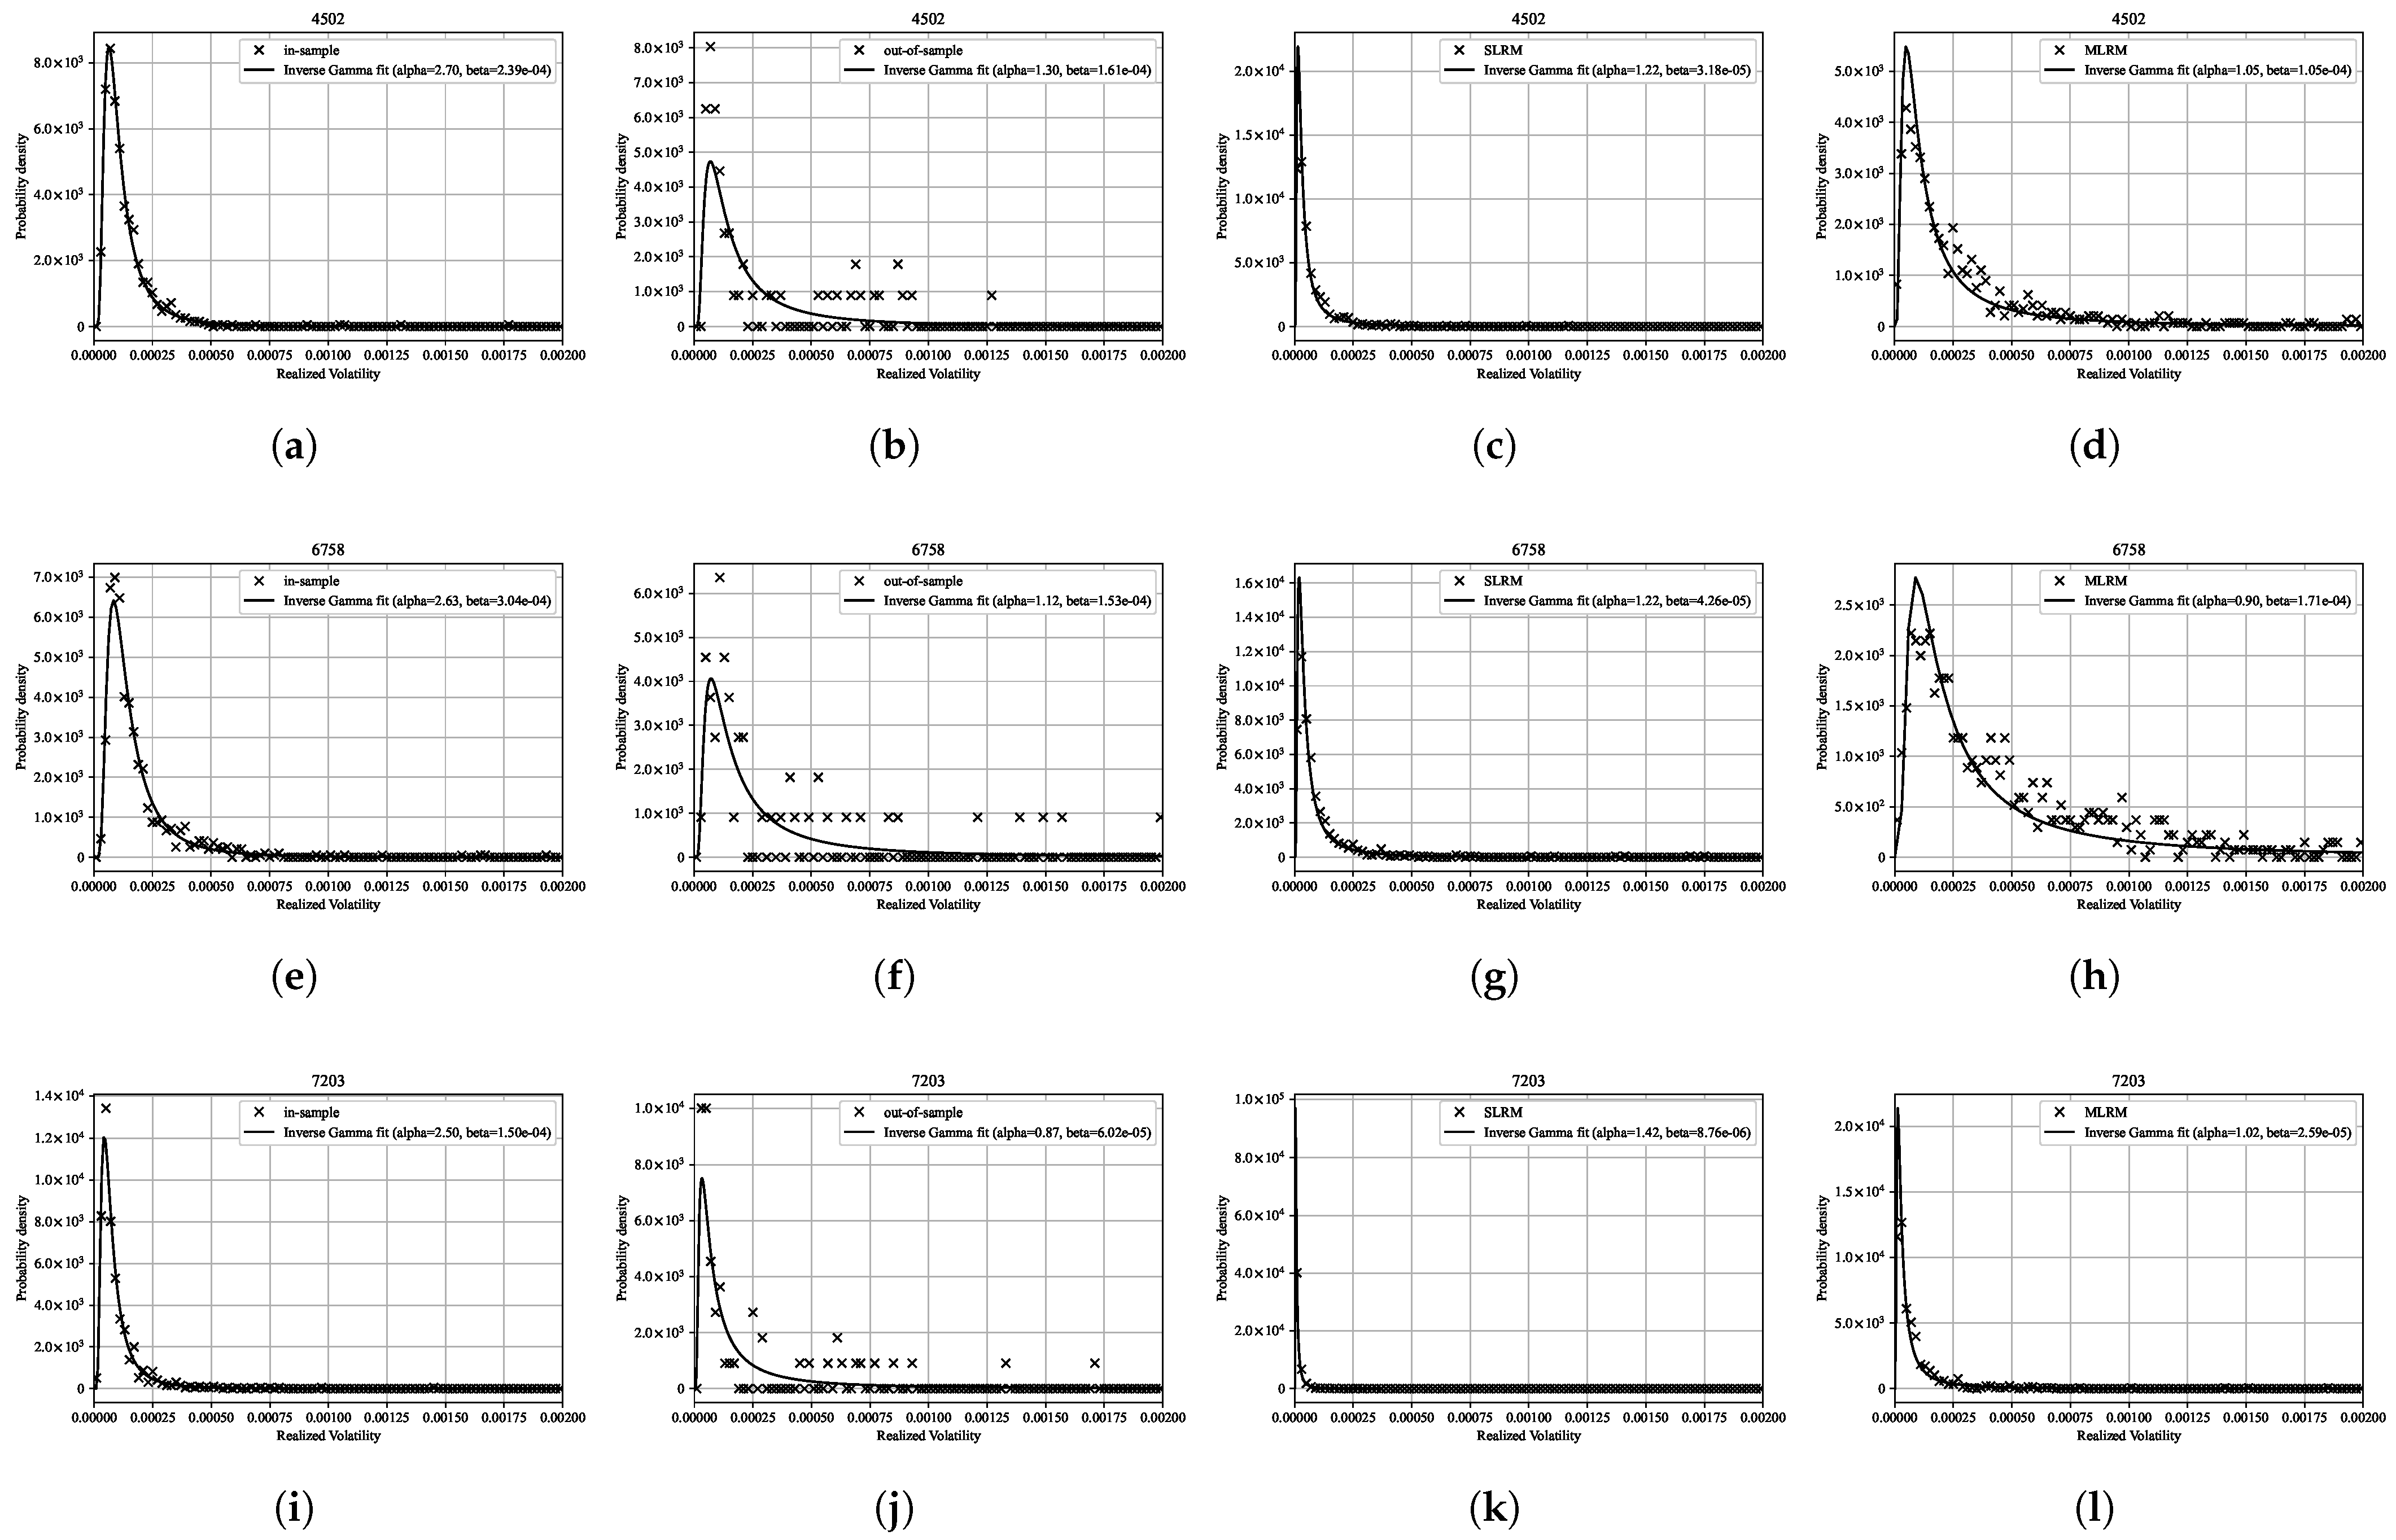
Figure 13 presents the distributions of realized volatility for three representative stocks (4502, 6758, and 7203), along with their corresponding inverse gamma distribution fits. The inverse gamma distribution, commonly used to model heavy-tailed positive variables such as volatility, is defined by its probability density function:
where is the shape parameter and is the scale parameter. For each stock, the distributions are shown for the in-sample period, out-of-sample period, and for data generated via the SLRM and the MLRM. The MLRM-generated distributions closely match the empirical distributions, particularly in the tails, across all three stocks. It should be noted that the out-of-sample distributions exhibit greater variability due to the limited number of data points available, which results in less stable fits to the inverse gamma distribution.
Figure 13.
Distributions of realized volatility for three representative stocks (4502, 6758, and 7203), along with their corresponding inverse gamma distribution fits. For each stock, results are presented for the in-sample period (a,e,i), the out-of-sample period (b,f,j), and for data generated via the SLRM (c,g,k) and the MLRM (d,h,l). The estimated parameters of the inverse gamma distribution (, ) are reported in each panel. These results demonstrate that, while the SLRM tends to underestimate the probability density in the tails, the MLRM more accurately captures the heavy-tailed characteristics of the empirical volatility distributions observed in real financial markets.
Furthermore, it is known that there exists a theoretical relationship between the power-law exponent of the inverse gamma distribution fitted to the realized volatility and the degrees of freedom of the Student’s t distribution fitted to the log-return distribution, given by [45]. This relationship arises from models that describe the log returns as a mixture distribution driven by stochastic volatility, implying consistency between the tail behaviors of returns and volatility. In our results, the estimated ratio is generally close to 2 (see Table 7), which is in good agreement with the theoretical expectation. This observation further supports the conclusion that the data generated via the MLRM successfully capture both the tail behavior of returns and their relationship to the underlying volatility structure observed in real financial markets.
5. Conclusions
This paper has proposed the MLRM to generate time-series data. The proposed MLRM focuses on generating data for extreme fluctuations and anomalous dynamics and is constructed by extending the conventional SLRM to multiple layers. In this study, we evaluated the effectiveness of the proposed model by generating stock price data for the COVID-19 period using pre-COVID-19 pandemic data. The results demonstrated that the stock price data generated via the proposed MLRM exhibited a higher degree of similarity to real data during the COVID-19 period compared to other methods. However, because the MLRM estimates external forces based on historical data, it may be challenging to apply the MLRM to phenomena, such as regime switching, where the external forces driving future stock prices differ substantially from those observed historically. Nonetheless, this limitation may be overcome in future research by devising methodologies that model external forces independently of historical data.
In addition to generating realistic price trajectories, we further evaluated the tail behavior of the log-return and realized volatility distributions. The MLRM-generated data exhibited heavier tails in the log-return distributions, closely matching the empirical behavior observed during COVID-19 periods. The estimated power-law exponent and excess kurtosis confirm that the MLRM successfully reproduces the heavy-tailed nature of financial returns, which is critical for modeling extreme market movements. Moreover, the degrees of freedom of the Student’s t distribution fitted to the generated returns remained consistently low (around 2), which is consistent with empirical data, further supporting the model’s ability to replicate extreme return behavior.
Similarly, for realized volatility, the MLRM accurately captured the heavy-tailed nature of the empirical distributions, as evidenced by the fit to the inverse gamma distribution. Importantly, the theoretical relationship between the volatility and return tail parameters was approximately satisfied by the MLRM-generated data, suggesting that the model can coherently capture the joint dynamics of returns and volatility observed in real markets.
Although it is generally difficult for machine learning models to generate data that is not included in the historical dataset, the MLRM can pre-generate rare events with extreme fluctuations, such as the COVID-19 pandemic. We believe that the artificial data reflecting both small and large fluctuations generated by the SLRM and the MLRM can be applied to various domains. In particular, the ability of the MLRM to reproduce realistic tail behavior is especially valuable for applications in financial risk management, stress testing, and scenario generation involving extreme market events. The results of this study have several practical implications for financial modeling and risk management. The proposed MLRM provides a transparent and computationally efficient framework for generating realistic synthetic financial time-series data, which can be utilized for scenario analysis, stress testing, and the development of algorithmic trading strategies. Furthermore, because the MLRM is based on explicit causal relationships, it offers enhanced interpretability relative to black-box machine learning models, making it particularly suitable for applications where model transparency is required, such as regulatory compliance and model validation. The ability to generate data that replicates extreme market fluctuations also enables more robust evaluation of risk measures and financial products under rare but critical market conditions. We believe that further development of the MLRM and related methodologies will contribute to more robust and interpretable approaches for modeling extreme events in financial markets.
Author Contributions
All authors declare that they jointly contributed to this research article. Y.N. was responsible for the majority of the work, including conceptualization, methodology, software implementation, data analysis, and manuscript preparation. T.A. supervised the project and provided primary guidance, while T.T. contributed as a co-supervisor and provided secondary supervision. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
The original FLEX Full dataset was purchased from the JPX and cannot be shared due to contractual restrictions. However, the synthetic data generated in this study using the MLRM, which was trained on the JPX dataset, is available from the corresponding author upon reasonable request.
Acknowledgments
This research was supported by the Research Center for Quantitative Finance, Tokyo Metropolitan University.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Goodfellow, I.J.; Pouget-Abadie, J.; Mirza, M.; Xu, B.; Warde-Farley, D.; Ozair, S.; Courville, A.; Bengio, Y. Generative adversarial nets. Adv. Neural Inf. Process. Syst. 2014, 27, 2672–2680. [Google Scholar] [CrossRef] [Scilit]
- Wiese, M.; Knobloch, R.; Korn, R.; Kretschmer, P. Quant GANs: Deep generation of financial time series. Quant. Financ. 2020, 20, 1419–1440. [Google Scholar] [CrossRef] [Scilit]
- Oord, A.; Dieleman, S.; Zen, H.; Simonyan, K.; Vinyals, O.; Graves, A.; Kalchbrenner, N.; Senior, A.; Kavukcuoglu, K. Wavenet: A generative model for raw audio. arXiv 2016, arXiv:1609.03499. [Google Scholar] [CrossRef] [Scilit]
- Li, J.; Wang, X.; Lin, Y.; Sinha, A.; Wellman, M.P. Generating Realistic Stock Market Order Streams. arXiv 2020, arXiv:2006.04212. [Google Scholar] [CrossRef] [Scilit]
- Arjovsky, M.; Chintala, S.; Bottou, L. Wasserstein GAN. arXiv 2017, arXiv:1701.07875. [Google Scholar] [CrossRef] [Scilit]
- Gulrajani, I.; Ahmed, F.; Arjovsky, M.; Dumoulin, V.; Courville, A. Improved training of wasserstein GANs. In Proceedings of the 31st International Conference on Neural Information Processing Systems, Red Hook, NY, USA, 4–9 December 2017; NIPS’17. pp. 5769–5779. [Google Scholar]
- Villani, C. Topics in Optimal Transportation; American Mathematical Society: Providence, RI, USA, 2003. [Google Scholar] [CrossRef] [Scilit]
- Ni, H.; Szpruch, L.; Sabate-Vidales, M.; Xiao, B.; Wiese, M.; Liao, S. Sig-wasserstein GANs for time series generation. In Proceedings of the Second ACM International Conference on AI in Finance, New York, NY, USA, 3–5 November 2021. ICAIF ’21. [Google Scholar] [CrossRef] [Scilit]
- Chevyrev, B.I.; Lyons, T. Characteristic Functions of Measures on Geometric Rough Paths. Annu. Probab. 2016, 44, 4049–4082. [Google Scholar] [CrossRef] [Scilit]
- Morrill, J.; Fermanian, A.; Kidger, P.; Lyons, T. A Generalised Signature Method for Multivariate Time Series Feature Extraction. arXiv 2021, arXiv:2006.00873. [Google Scholar] [CrossRef] [Scilit]
- Liao, S.; Ni, H.; Sabate-Vidales, M.; Szpruch, L.; Wiese, M.; Xiao, B. Sig-Wasserstein GANs for conditional time series generation. Math. Financ. 2024, 34, 622–670. [Google Scholar] [CrossRef] [Scilit]
- Coletta, A.; Prata, M.; Conti, M.; Mercanti, E.; Bartolini, N.; Moulin, A.; Vyetrenko, S.; Balch, T. Towards realistic market simulations: A generative adversarial networks approach. In Proceedings of the Second ACM International Conference on AI in Finance, Virtual Event, 3–5 November 2021; Association for Computing Machinery: New York, NY, USA, 2022. ICAIF ’21. [Google Scholar] [CrossRef] [Scilit]
- Vuletić, M.; Prenzel, F.; Cucuringu, M. Fin-GAN: Forecasting and classifying financial time series via generative adversarial networks. Quant. Financ. 2024, 24, 175–199. [Google Scholar] [CrossRef] [Scilit]
- Hochreiter, S.; Schmidhuber, J. Long Short-Term Memory. Neural Comput. 1997, 9, 1735–1780. [Google Scholar] [CrossRef] [Scilit]
- Tsay, R.S. Analysis of Financial Time Series, 3rd ed.; John Wiley & Sons: Hoboken, NJ, USA, 2005. [Google Scholar]
- Sohl-Dickstein, J.; Weiss, E.A.; Maheswaranathan, N.; Ganguli, S. Deep unsupervised learning using nonequilibrium thermodynamics. In Proceedings of the 32nd International Conference on International Conference on Machine Learning, JMLR.org, Lille, France, 6–11 July 2015; ICML’15. Volume 37, pp. 2256–2265. [Google Scholar]
- Li, Y.; Lu, X.; Wang, Y.; Dou, D. Generative time series forecasting with diffusion, denoise, and disentanglement. In Proceedings of the 36th International Conference on Neural Information Processing Systems, New Orleans, LA, USA, 28 November 2022–9 December 2022. NIPS ’22. [Google Scholar]
- Tashiro, Y.; Song, J.; Song, Y.; Ermon, S. CSDI: Conditional Score-based Diffusion Models for Probabilistic Time Series Imputation. In Advances in Neural Information Processing Systems; Ranzato, M., Beygelzimer, A., Dauphin, Y., Liang, P., Vaughan, J.W., Eds.; Curran Associates, Inc.: Red Hook, NY, USA, 2021; Volume 34, pp. 24804–24816. [Google Scholar]
- Alcaraz, J.M.L.; Strodthoff, N. Diffusion-Based Time Series Imputation and Forecasting with Structured State Space Models. arXiv 2022, arXiv:2208.09399. [Google Scholar] [CrossRef] [Scilit]
- Wang, Z.; Ventre, C. A Financial Time Series Denoiser Based on Diffusion Models. In Proceedings of the 5th ACM International Conference on AI in Finance, New York, NY, USA, 14–17 November 2024; ICAIF’24. pp. 72–80. [Google Scholar] [CrossRef] [Scilit]
- Huang, H.; Chen, M.; Qiao, X. Generative Learning for Financial Time Series with Irregular and Scale-Invariant Patterns. In Proceedings of the Twelfth International Conference on Learning Representations, Vienna, Austria, 7–11 May 2024. [Google Scholar]
- Zhang, Q.; Qin, C.; Zhang, Y.; Bao, F.; Zhang, C.; Liu, P. Transformer-based attention network for stock movement prediction. Expert Syst. Appl. 2022, 202, 117239. [Google Scholar] [CrossRef] [Scilit]
- Wang, C.; Chen, Y.; Zhang, S.; Zhang, Q. Stock market index prediction using deep Transformer model. Expert Syst. Appl. 2022, 208, 118128. [Google Scholar] [CrossRef] [Scilit]
- Mozaffari, L.; Zhang, J. Predictive Modeling of Stock Prices Using Transformer Model. In Proceedings of the 2024 9th International Conference on Machine Learning Technologies, Oslo, Norway, 24–26 May 2024; ICMLT’24. pp. 41–48. [Google Scholar] [CrossRef] [Scilit]
- Huang, S.C.; Wu, C.F.; Chen, K.C.; Lin, M.C.; Chiou, C.C. Intelligent dual-stage attention-based deep networks for energy market predictions. Alex. Eng. J. 2025, 122, 625–644. [Google Scholar] [CrossRef] [Scilit]
- Wu, C.F.; Lin, M.C.; Chao, T.W.; Chiou, C.C. Omnipresent AI and Big data for financial early warning: Integrating financial indicators and text sentiment analysis in Chinese real estate. Enterp. Inf. Syst. 2025, 19, 2434742. [Google Scholar] [CrossRef] [Scilit]
- Kubo, R.; Toda, M.; Hashitsume, N. Statistical Physics II: Nonequilibrium Statistical Mechanics, 2nd ed.; Solid-State Sciences; Springer: Berlin/Heidelberg, Germany, 1991. [Google Scholar]
- Zubarev, D.N. Nonequilibrium Statistical Thermodynamics; Springer: New York, NY, USA, 1973. [Google Scholar]
- Puertas, A.M.; Trinidad-Segovia, J.E.; Sánchez-Granero, M.A.; Clara-Rahora, J.; de las Nieves, F.J. Linear response theory in stock markets. Sci. Rep. 2021, 11, 23076. [Google Scholar] [CrossRef] [Scilit]
- Puertas, A.M.; Clara-Rahola, J.; Sánchez-Granero, M.A.; de las Nieves, F.J.; Trinidad-Segovia, J.E. A new look at financial markets efficiency from linear response theory. Financ. Res. Lett. 2023, 51, 103455. [Google Scholar] [CrossRef] [Scilit]
- Naritomi, Y.; Adachi, T. Time Series Data Generation by Linear Response Model. Trans. Jpn. Soc. Artif. Intell. 2024, 39, 1–9. [Google Scholar] [CrossRef] [Scilit]
- Teh, Y.W.; Osindero, S.; Hinton, G.E. Energy-Based Models for Sparse Overcomplete Representations. J. Mach. Learn. Res. 2003, 4, 1235–1260. [Google Scholar]
- Zhao, X.; Liu, P.; Mahmoudi, S.; Garg, S.; Kaddoum, G.; Hassan, M.M. DDANF: Deep denoising autoencoder normalizing flow for unsupervised multivariate time series anomaly detection. Alex. Eng. J. 2024, 108, 436–444. [Google Scholar] [CrossRef] [Scilit]
- Peskin, M.E.; Schroeder, D.V. An Introduction to Quantum Field Theory; Westview Press: Boulder, CO, USA, 1995. [Google Scholar]
- Gopikrishnan, P.; Meyer, M.; Amaral, L.A.N.; Stanley, H.E. Inverse cubic law for the distribution of stock price variations. Eur. Phys. J. B-Condens. Matter Complex Syst. 1998, 3, 139–140. [Google Scholar] [CrossRef] [Scilit]
- Gu, Z.; Ibragimov, R. The “Cubic Law of the Stock Returns” in emerging markets. J. Empir. Financ. 2018, 46, 182–190. [Google Scholar] [CrossRef] [Scilit]
- Drożdż, S.; Kwapień, J.; Osświęcimka, P.; Stanisz, T.; Waṫorek, M. Complexity in Economic and Social Systems: Cryptocurrency Market at around COVID-19. Entropy 2020, 22, 1043. [Google Scholar] [CrossRef] [Scilit]
- Takaishi, T. Recent scaling properties of Bitcoin price returns. J. Phys. Conf. Ser. 2021, 1730, 012124. [Google Scholar] [CrossRef] [Scilit]
- Takaishi, T. Analysis of Realized Volatility in Superstatistics. Evol. Institutional Econ. Rev. 2010, 7, 89–99. [Google Scholar] [CrossRef] [Scilit]
- Andersen, T.G.; Bollerslev, T.; Diebold, F.X.; Labys, P. The Distribution of Realized Exchange Rate Volatility. J. Am. Stat. Assoc. 2001, 96, 42–55. [Google Scholar] [CrossRef] [Scilit]
- Praetz, P.D. The Distribution of Share Price Changes. J. Bus. 1972, 45, 49–55. [Google Scholar] [CrossRef] [Scilit]
- Tsallis, C.; Anteneodo, C.; Borland, L.; Osorio, R. Nonextensive statistical mechanics and economics. Phys. A Stat. Mech. Its Appl. 2003, 324, 89–100. [Google Scholar] [CrossRef] [Scilit]
- Mandelbrojt, S. Lacunary series. Rice Inst. Pam.-Rice Univ. Stud. 1923, 14, 261–284. [Google Scholar]
- Myers, C.; Rabiner, L.; Rosenberg, A. Performance tradeoffs in dynamic time warping algorithms for isolated word recognition. IEEE Trans. Acoust. Speech Signal Process. 1980, 28, 623–635. [Google Scholar] [CrossRef] [Scilit]
- Gelman, A.; Carlin, J.B.; Stern, H.S.; Dunson, D.B.; Vehtari, A.; Rubin, D.B. Bayesian Data Analysis, 3rd ed.; CRC Press: Boca Raton, FL, USA, 2013. [Google Scholar]

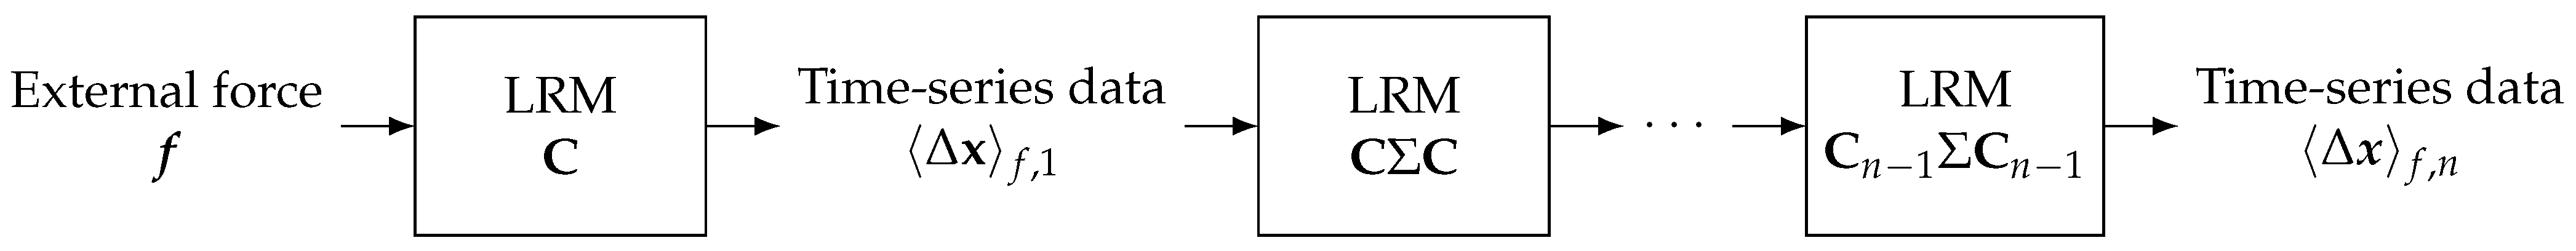

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).