
Proceeding Paper

Long-Tail Zero and Few-Shot Learning via Contrastive Pretraining on and for Small Data †
by
Nils Rethmeier
1,2,* and
Isabelle Augenstein
2
1
German Research Center for AI, SLT-Lab, Alt-Moabit 91c, 10559 Berlin, Germany
2
Department of Computer Science, Copenhagen University, Universitetsparken 1, 2100 Copenhagen, Denmark
*
Author to whom correspondence should be addressed.
Presented at the AAAI Workshop on Artificial Intelligence with Biased or Scarce Data (AIBSD), Online, 28 February 2022.
Comput. Sci. Math. Forum 2022, 3(1), 10; https://doi.org/10.3390/cmsf2022003010

Published: 20 May 2022

Abstract

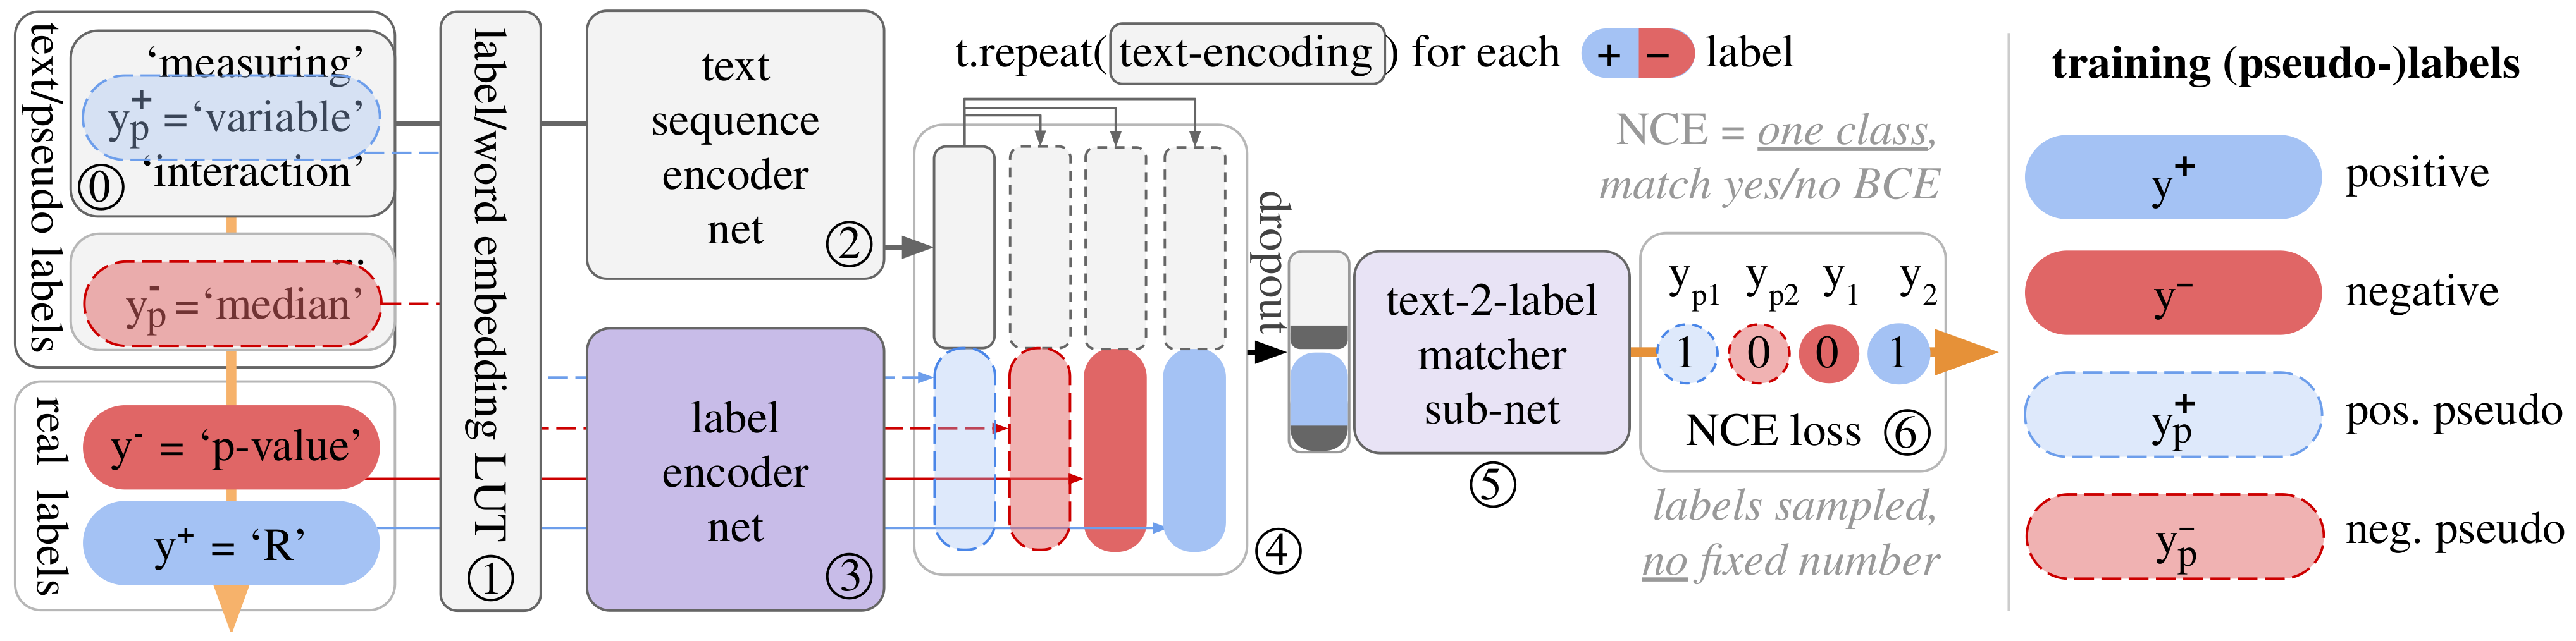
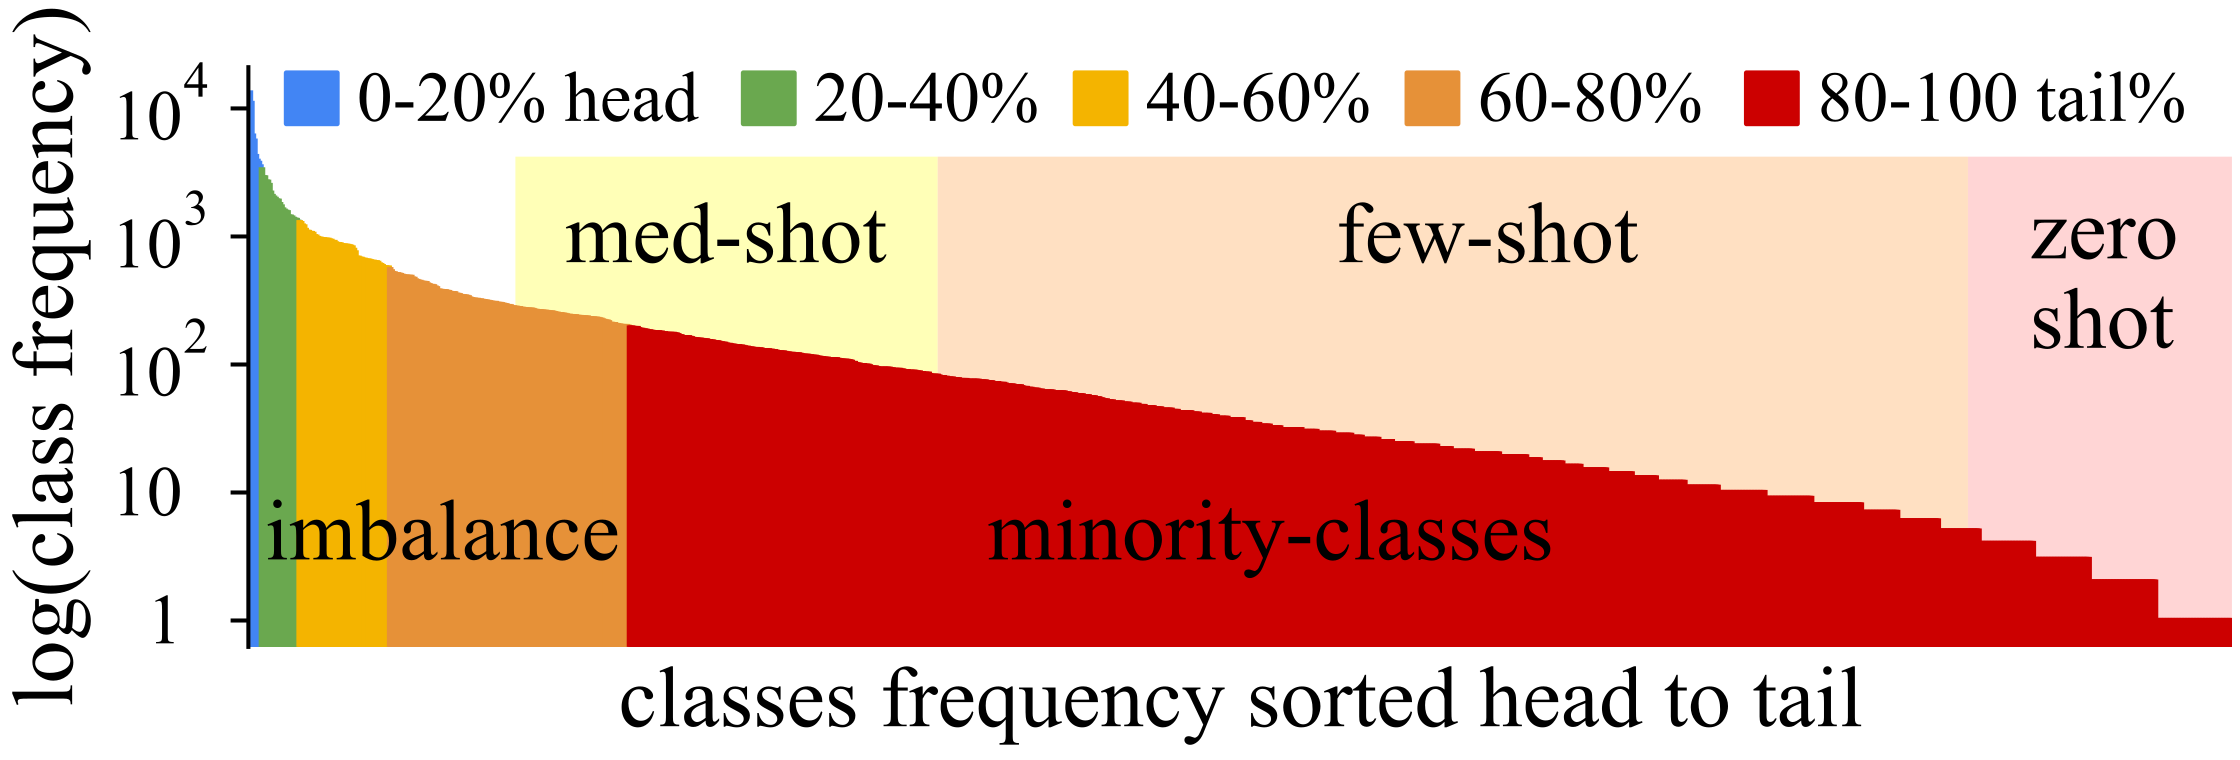
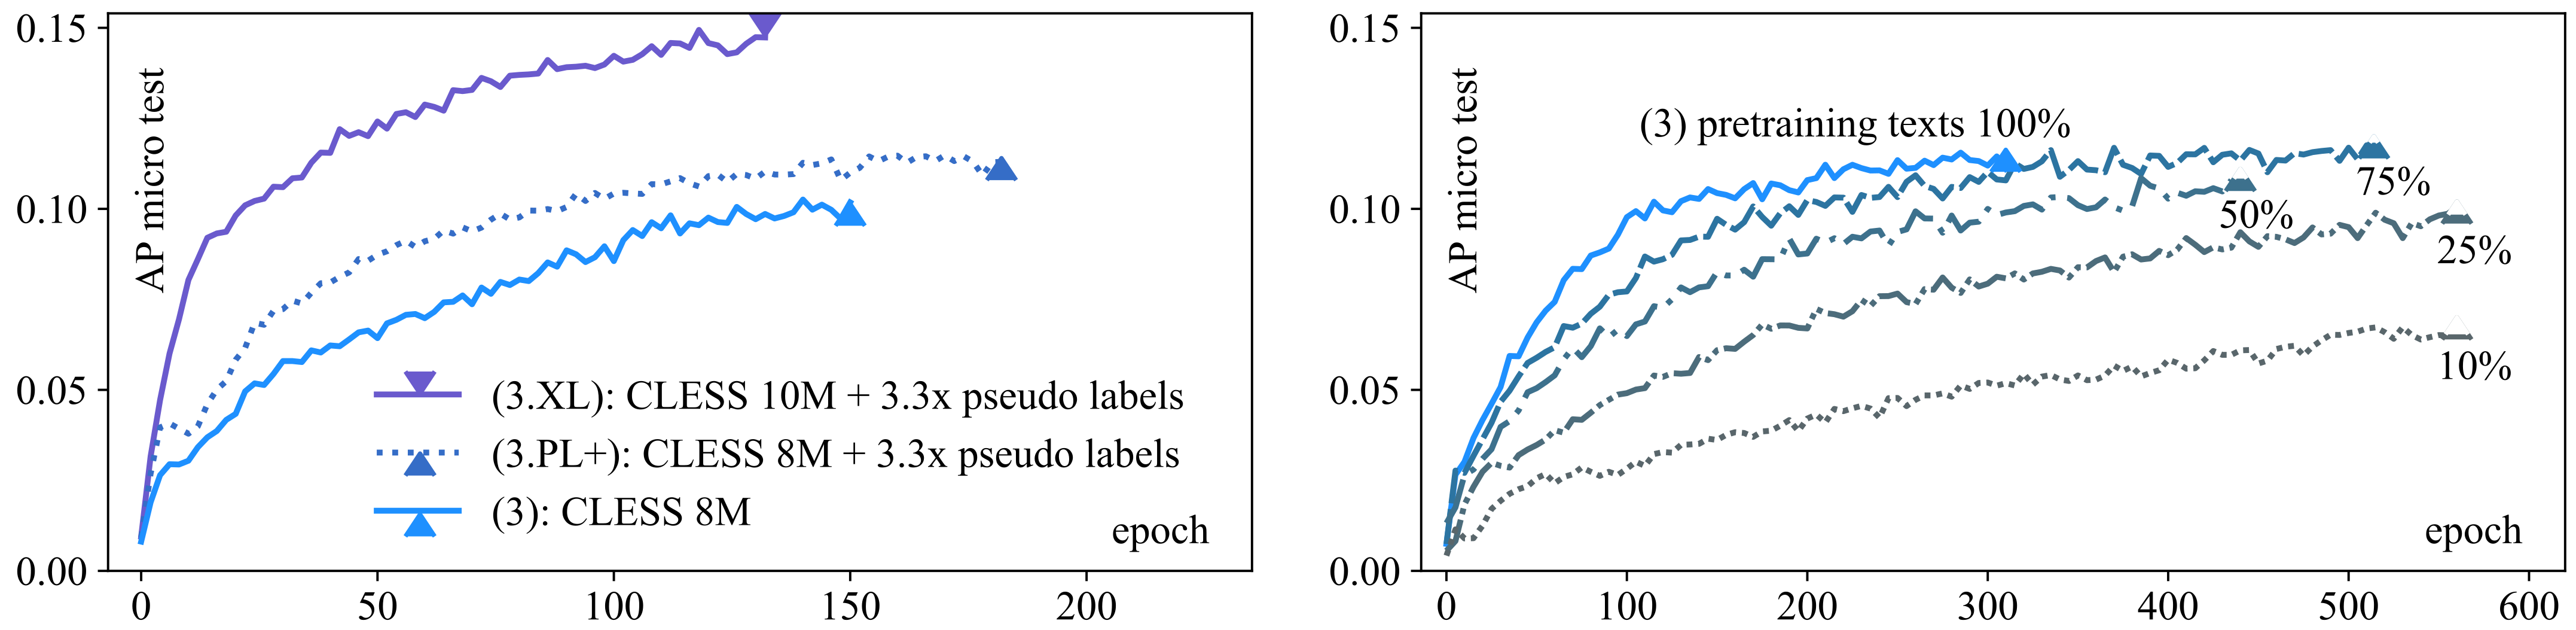
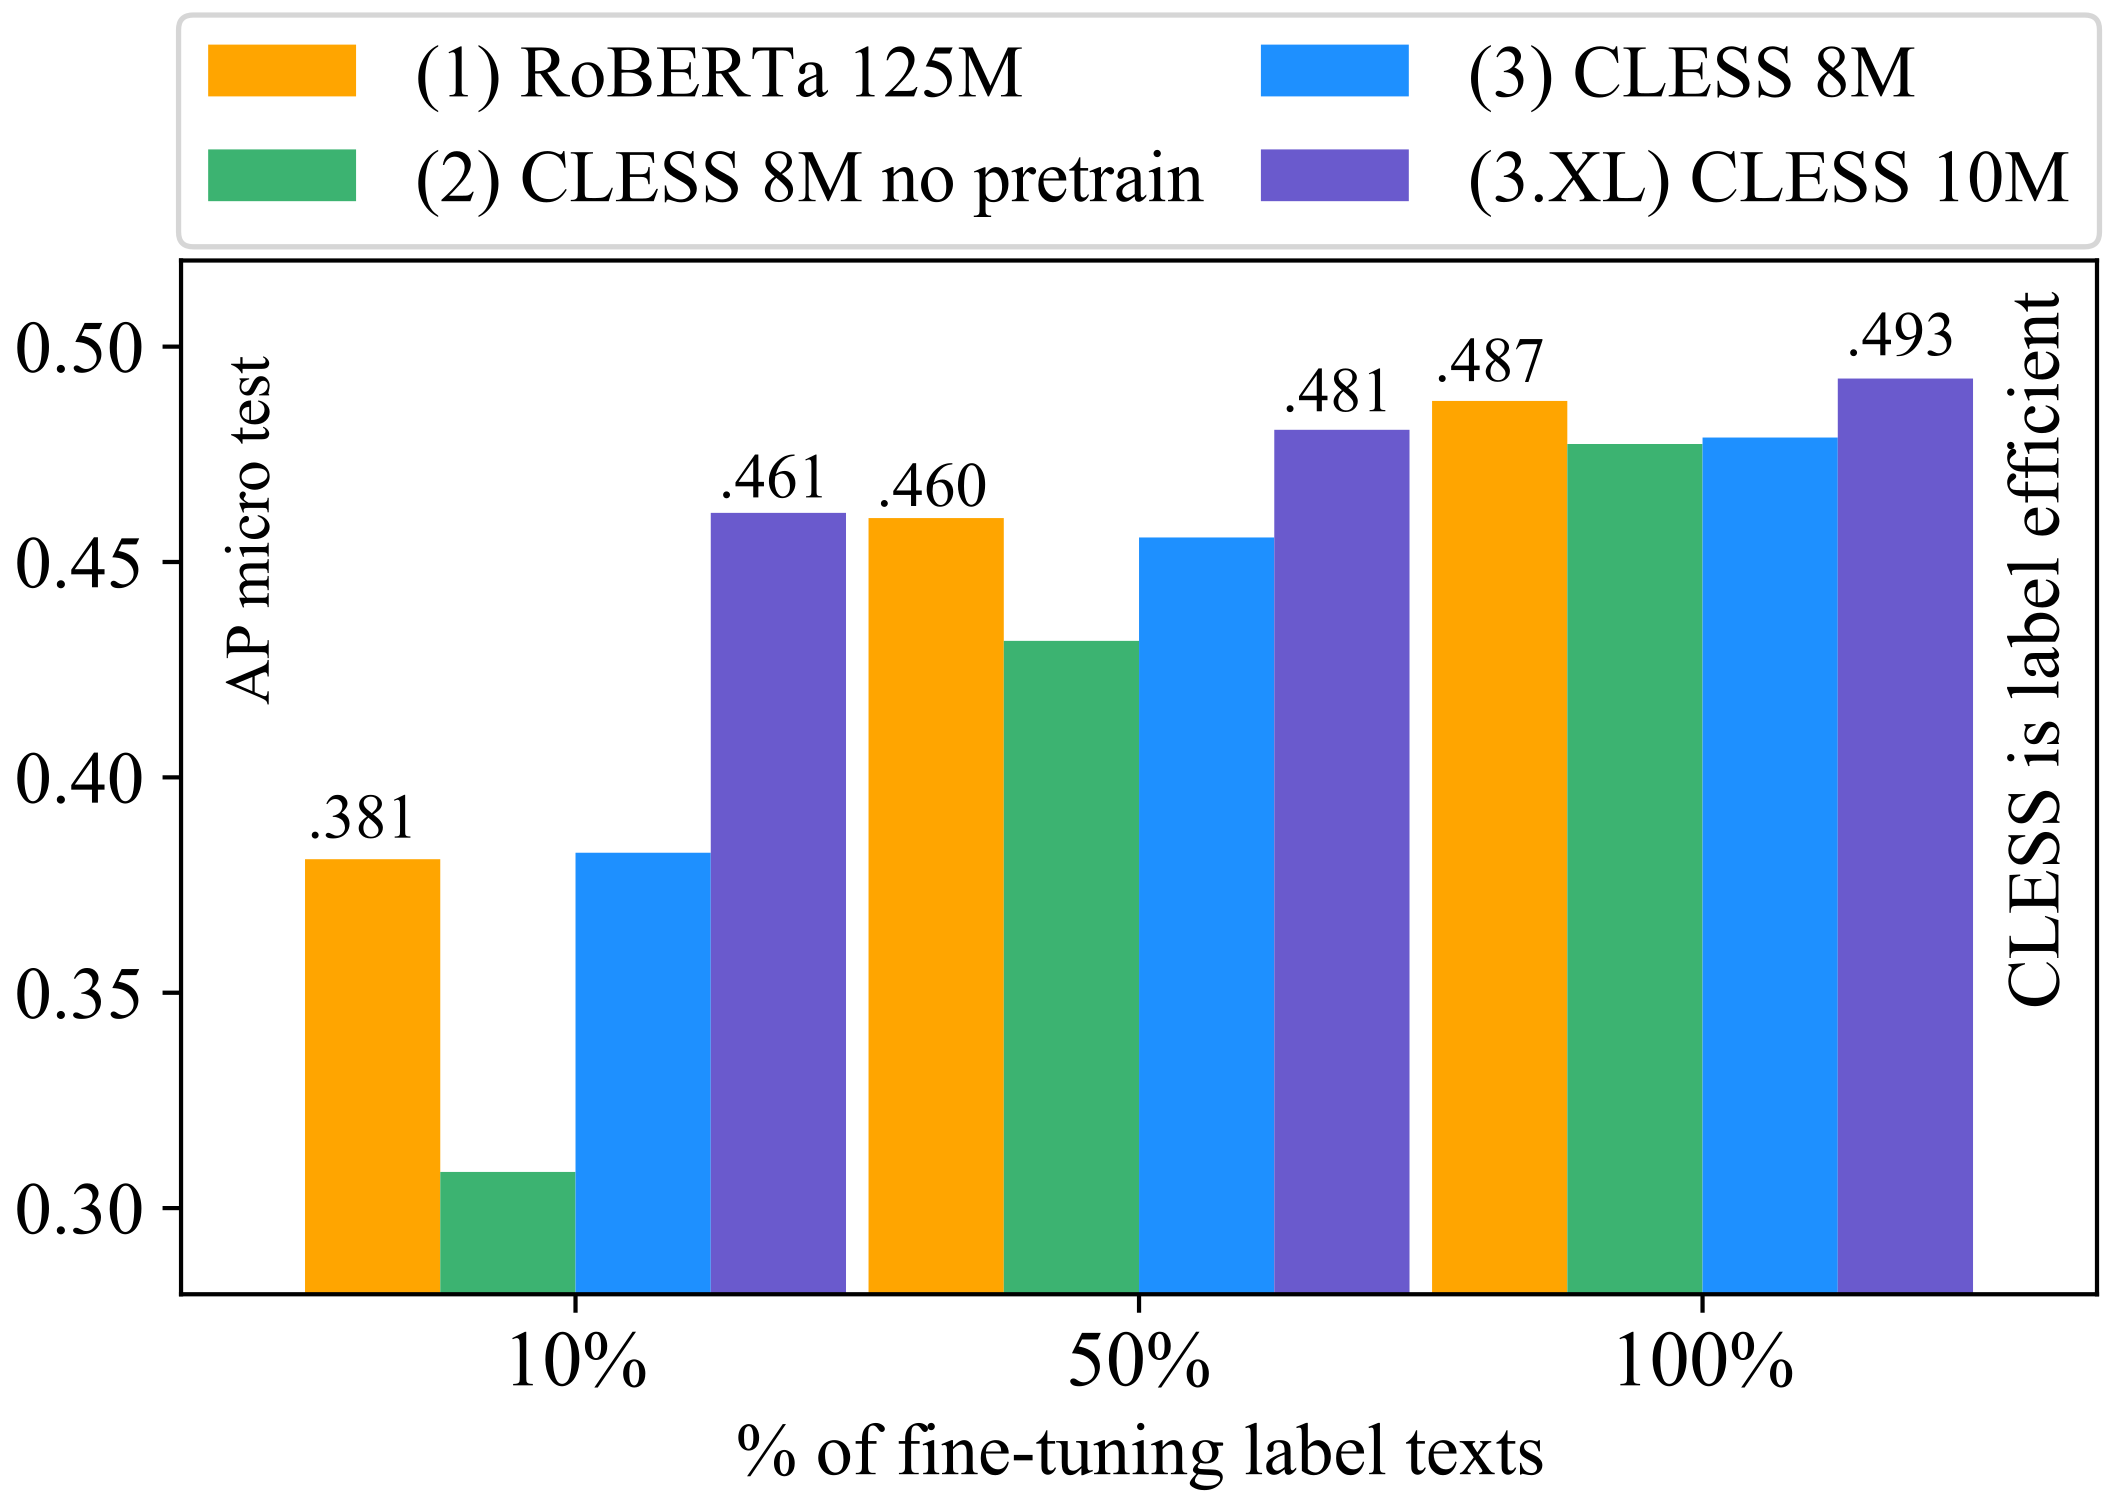
Preserving long-tail, minority information during model compression has been linked to algorithmic fairness considerations. However, this assumes that large models capture long-tail information and smaller ones do not, which raises two questions. One, how well do large pretrained language models encode long-tail information? Two, how can small language models be made to better capture long-tail information, without requiring a compression step? First, we study the performance of pretrained Transformers on a challenging new long-tail, web text classification task. Second, to train small long-tail capture models we propose a contrastive training objective that unifies self-supervised pretraining, and supervised long-tail fine-tuning, which markedly increases tail data-efficiency and tail prediction performance. Third, we analyze the resulting long-tail learning capabilities under zero-shot, few-shot and full supervision conditions, and study the performance impact of model size and self-supervision signal amount. We find that large pretrained language models do not guarantee long-tail retention and that much smaller, contrastively pretrained models better retain long-tail information while gaining data and compute efficiency. This demonstrates that model compression may not be the go-to method for obtaining good long-tail performance from compact models.
Keywords: contrastive language models; long-tail compression; text-to-text; self-supervised contrastive pretraining; contrastive autoencoder contrastive language models; long-tail compression; text-to-text; self-supervised contrastive pretraining; contrastive autoencoder