


Abstract
This article provides an exact formula for the survival probability of Brownian motion with drift when the absorbing boundary is defined as an intermittent step barrier, i.e., an alternate sequence of time intervals when the boundary is piecewise constant, and time intervals without any defined boundary. Numerical implementation is dealt with by a simple and robust Monte Carlo integration algorithm directly derived from the formula, which compares favorably with conditional Monte Carlo simulation. Exact analytical benchmarks are also provided to assess the accuracy of the numerical implementation.
Keywords:
survival probability; Brownian motion; boundary crossing; first-passage time; intermittent barrier; step barrier; barrier option; dimension; numerical integration; Monte Carlo integration MSC:
60J70
1. Introduction
The question of the survival probability of a diffusion process in finite time is an active area of research in applied probability, as it serves as a fundamental modeling tool for a large variety of phenomena in many different mathematical sciences such as biology, economics, engineering reliability, epidemiology, finance, genetics, seismology, and sequential statistical analysis [1]. The term “survival” refers to problems in which the variations of some random dynamics have to be kept contained within certain limits or inside a given domain for a particular property to hold. When the first-passage time of the process to the boundary of the domain entails the end of that property, the boundary is said to be absorbing. An absorbing boundary is often called a “barrier”, a metaphor making it clear that the boundary must not be hit. In other words, the crossing of the barrier means the elimination of the necessary conditions for a certain property to remain active or to continue to be alive. The barrier may be located above the current value of the process (upward barrier or ‘up-barrier’), below it (downward barrier or ‘down-barrier’), and both above and below (double barrier, also called two-sided). The barrier may be crossed at any instant in continuous time (in which case it is called ‘continuous’) or only at one or a few predefined instants (in which case it is called ‘discrete’).
There are very few exact, closed-form results in this field. The ones that are known essentially apply to Brownian motion. The seminal and most classical of them is the so-called Bachelier–Levy formula [2], which provides the first-passage time density of Brownian motion to a linear boundary. This result was extended to a two-sided linear boundary in [3], but only in infinite time. The generalization to a closed time interval was given in [4], who was also able to integrate the density. The first-passage time density of Brownian motion to a quadratic barrier was obtained independently in [5,6], while [7] worked out the hitting time of Brownian motion to a square root barrier. However, the numerical evaluation is so involved in both cases that one can hardly speak of a “closed form” solution.
Most of the extant literature focuses on numerical approximation methods dealing with the following:
- -
- Specific processes, usually diffusions closely related to Brownian motion that have precise applications, e.g., Ornstein–Uhlenbeck processes [8,9];
- -
- Specific boundaries, e.g., a square root one [10,11] or a curved one [12];
- -
- General classes of diffusion processes [13,14];
- -
- General classes of boundaries [7,15,16,17,18,19].
A form of boundary that is frequently encountered in applications is the step barrier, i.e., a barrier defined as a step function of time. For example, a substantial fraction of the so-called “barrier options”, which are the most extensively traded non-vanilla options in the financial markets, rely on step barriers. Exact, closed-form results are known for arithmetic and geometric Brownian motion when the step barrier is piecewise constant [20] and when it is piecewise linear or exponential [21]. Stochastic exponential barriers are also dealt with in Guillaume [22]. However, all these results assume that the step barrier is piecewise continuous, i.e., the only discontinuities considered are jumps at the times when the step barrier takes on a new value. To the best of our knowledge, no exact result has ever been published when the step barrier is intermittent, i.e., alternately active and non-active in time, with sequences of time subintervals left without exposure to the danger of absorption. Yet, this is a variant that can be useful in a number of applications. For example, in finance, holders of long positions in barrier options are subjected to the risk of “knocking-out”, i.e., of the option becoming deactivated upon hitting the barrier at any time before the option’s expiry. A simple and effective way of mitigating this risk is to remove the barrier during specific periods of time, e.g., when there is an expected spike in the volatility of the option’s underlying asset. This is precisely what an intermittent step barrier allows investors to achieve. The property of intermittence does not mean that the barrier is eliminated once and for all. It can be reset at later times, at another value, and in another direction (upward if it was downward before the temporary removal or downward if it was upward). An intermittent step barrier is thus a particularly flexible way of managing risk, allowing option holders to optimize the trade-off between security enhancement and cost reduction. It leaves them entirely free to define exactly when they want to be insured against adverse market fluctuations and what level of protection they wish to fix.
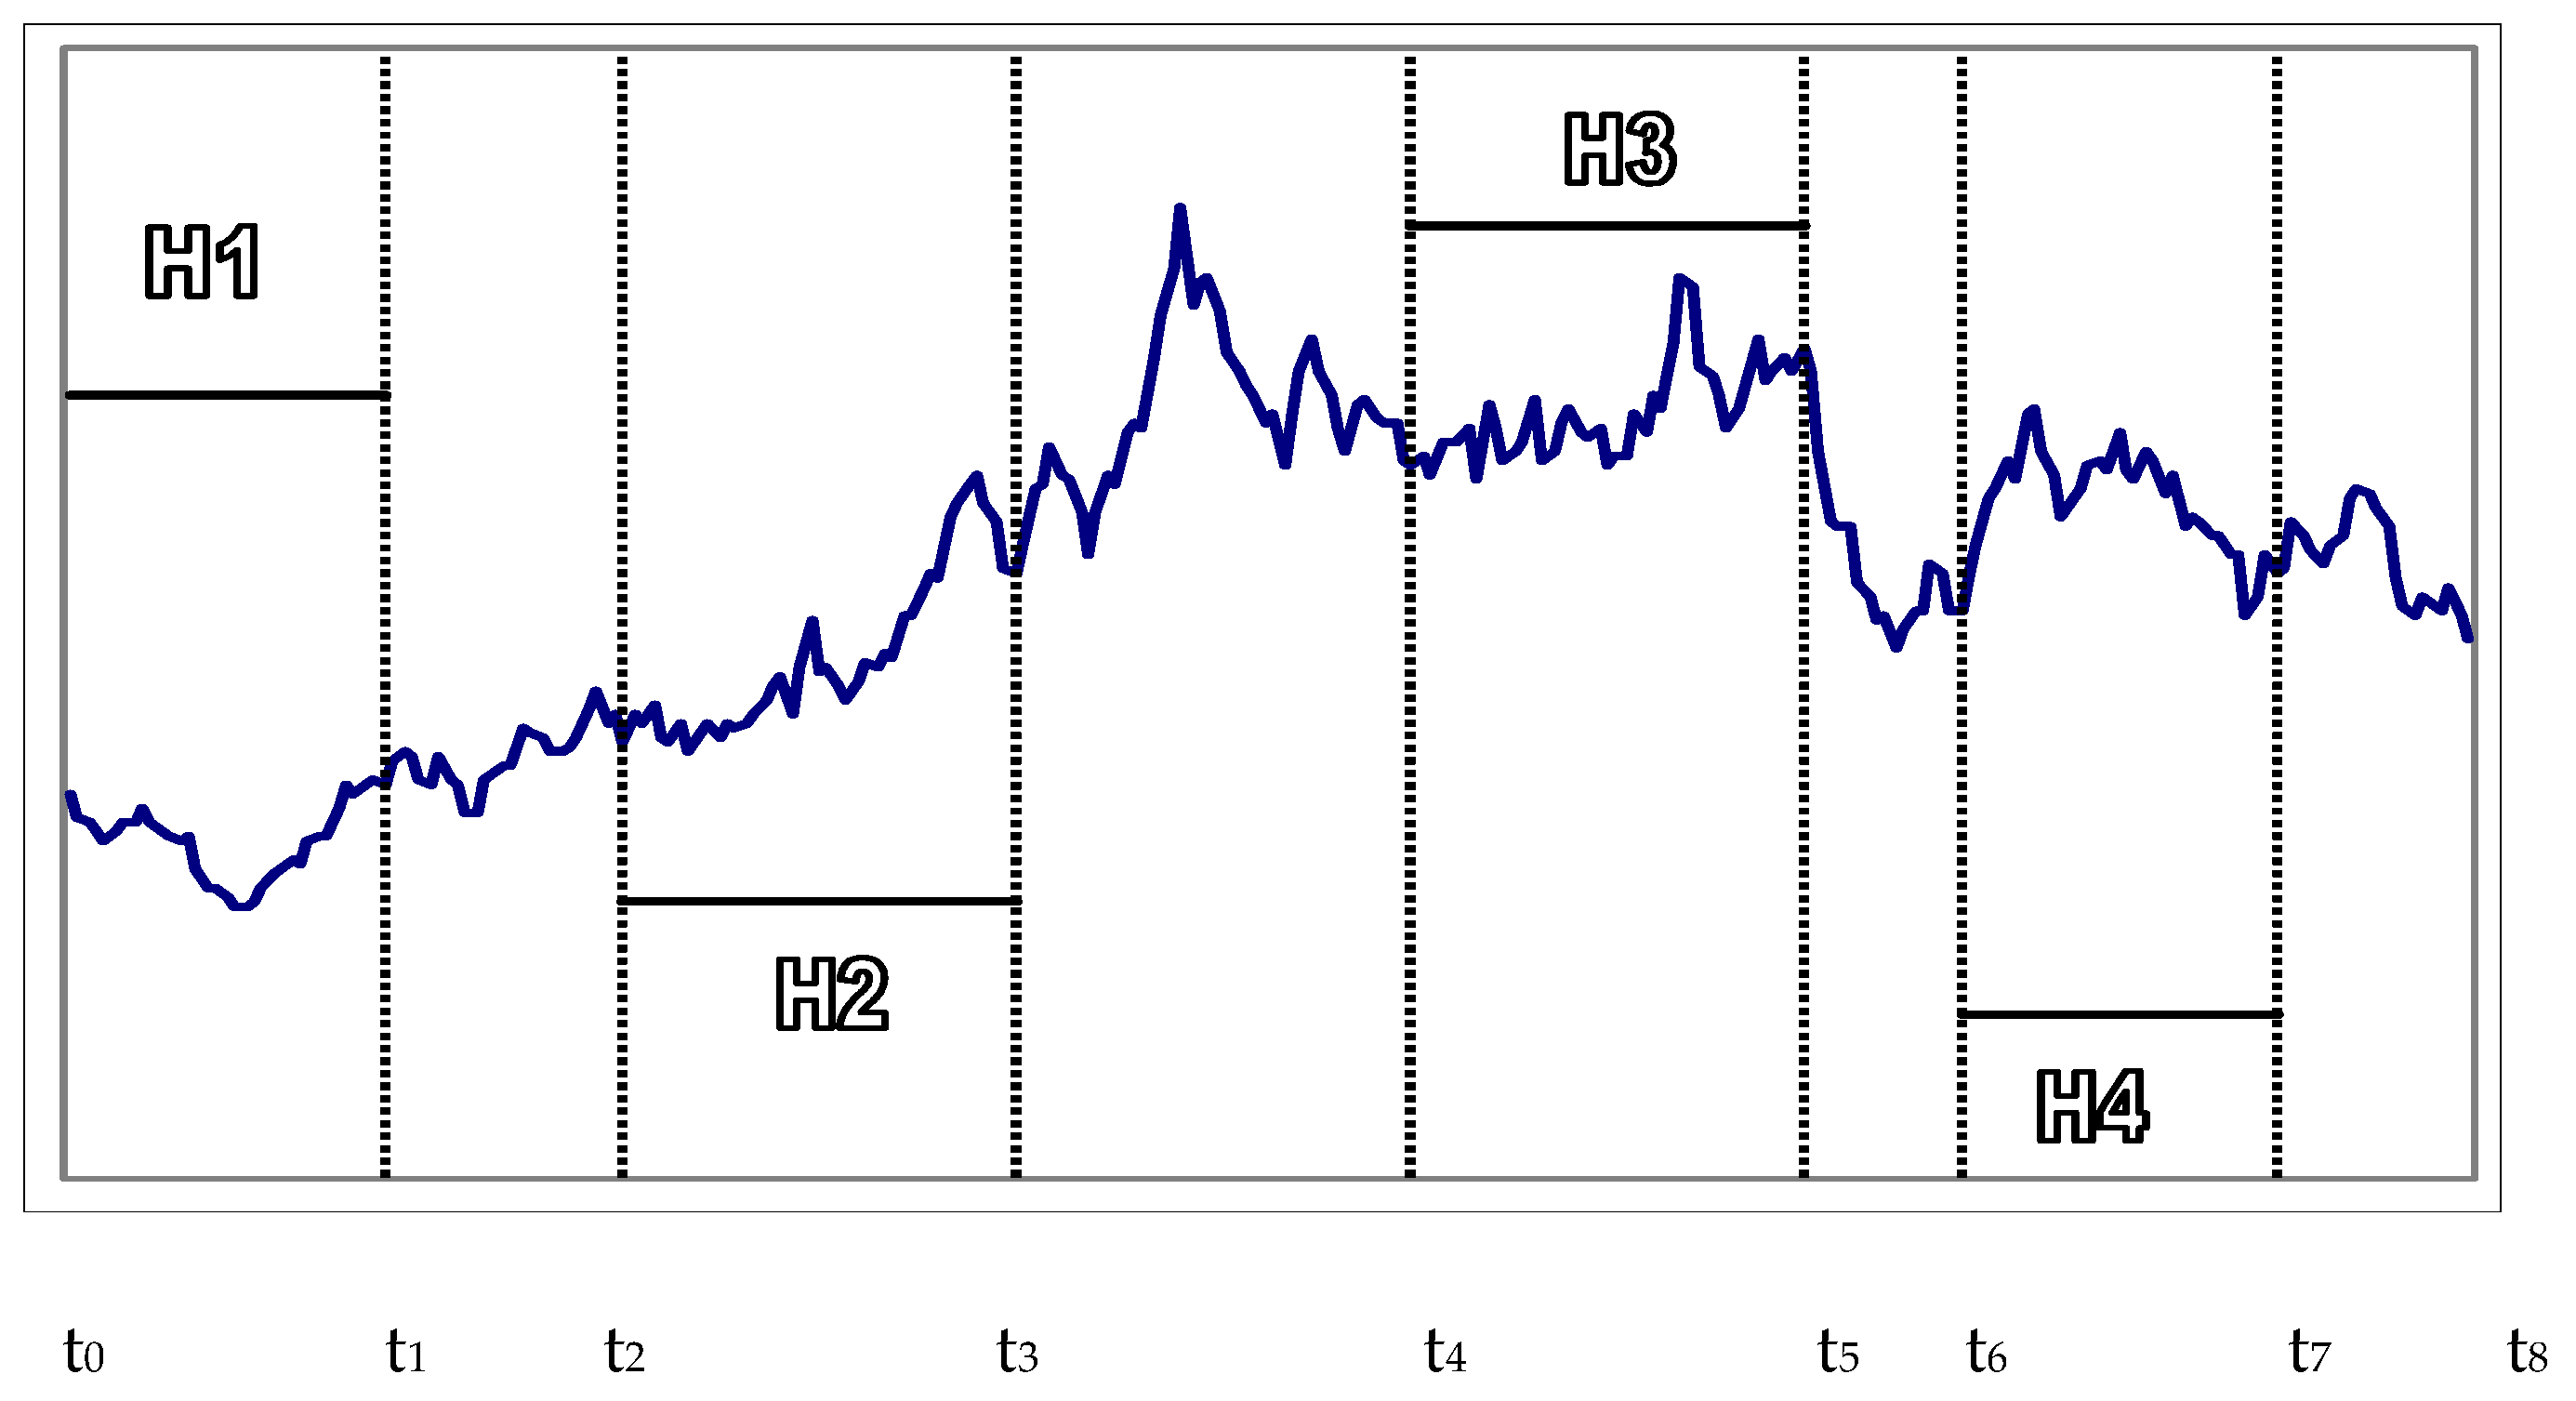
One may object that the intermittent barrier framework can be tackled by the existing formulae applicable to non-intermittent barriers by taking appropriate limits on the barrier levels during the periods devoid of risk of absorption, e.g., decreasing a down-barrier or increasing an up-barrier to such an extent that the probability of hitting it becomes negligible. But such an approach is actually flawed because of the entailed numerical errors, which can be substantial. That is why this article solves the problem of calculating the survival probability of Brownian motion with drift exposed to an intermittent absorbing step barrier with four alternately up and down steps, as illustrated by the following Figure 1:
Figure 1.
A path of geometric Brownian motion staying within the confines of an intermittent absorbing step barrier with four alternately up and down steps.
In addition to the continuous steps , and of the barrier, discrete barriers can also be defined at the various ’s. The obtained formula is a general result that nests a large number of known distributions with non-intermittent steps as particular cases. The formula is a continuous function of its variables; consequently, “small” changes in the parameters can be accommodated without entailing numerical instability. The formula is actually more than a continuous function; it is even differentiable. This property is particularly attractive for option traders, as it allows them to compute precise hedging parameters by mere differentiation of the valuation formula, according to the classical dynamic hedging strategy. Although the analytical calculations involved are non-trivial, the main issue is the dimension of the multiple integrals that solve the problem, which rapidly increases, especially if one wants to extend the given result to a higher number of steps. To solve this problem, a simple, efficient, and robust numerical integration scheme is designed that can handle very high-dimensional integrals, as its computational time grows only linearly with dimension, like a Monte Carlo simulation.
Given the prevalence of the boundary-crossing probability framework in scientific modeling, there is no doubt that potential applications exist in subjects other than mathematical finance. When applying the results of this article to different contexts, researchers should remain aware, though, of the main assumptions underlying our work, especially the modeling of random dynamics by a geometric Brownian motion. This precludes the application of the derived formulae to settings in which randomness needs to be represented by a discontinuous process, e.g., because “large” variations may occur in “small” time intervals. Also, it should be stressed that each step of the barrier is supposed to be constant, although non-constant steps could be dealt with only slightly more effort using results provided in [21] for deterministic non-constant steps or in [22] for steps modeled as geometric Brownian motions.
2. Statement and Proof of the Main Formula
Let be a geometric Brownian motion whose instantaneous rate of change, under a given measure , is given by the following:
where , and is a standard Brownian motion defined on a probability space with right-continuous natural filtration .
The probability measure is characterized by or, equivalently, by
If we refer to the arithmetic Brownian process , the differential under is given by
Our objective is to find an exact formula for the following cumulative distribution function:
where is the set constructed by the following intersection of subsets of :
Let the function be defined by the following dimensional integral:
Then, the exact value of is given by the following result.
Proposition 1.
where :
Corollary 1.
It suffices to multiply by all the arguments in each function and to swap all and operators (i.e., each becomes and conversely) in Proposition 1 to obtain an exact formula for the following probability:
Corollary 2.
The riskless interest rate is denoted by , assumed to be constant, with the no-arbitrage value of an option with a payoff based on the intersection of events in set with expiry (which can be called an intermittent up-and-down knock-out call, following the terminology in mathematical finance), which is given by
where
and
To obtain the no-arbitrage value of an option with a payoff based on (15) with expiry (i.e., an intermittent down-and-up knock-out put), replace with in (16).
End of Proposition 1.
Proof of Proposition 1.
Since the log function is strictly increasing, we have
where
and are given by (7). The solution of Equation (1) is given by
Therefore, each , , is an absolutely continuous random variable, normally distributed with expectation and variance . Moreover, , as a diffusion, is a Markov process. Hence, the probability sought can be expanded as the following integral:
where
The function is obtained by differentiating the classical formula for the joint cumulative distribution of the maximum of a Brownian motion with drift and its endpoint over a closed time interval (see, e.g., [23]):
The function is easily derived from the bivariate normality of the pair :
To handle the function , we begin by conditioning the conditional expectation of w.r.t. with the filtration at time . Through the substitution of with and the substitution of with in , we obtain in :
where is the univariate standard normal cumulative distribution function.
Equation (30) can be rewritten as follows:
Therefore, by differentiating (31) w.r.t. , we obtain
By the symmetry of paths of Brownian motion, we have
Hence,
The rest of the proof, whose cumbersome details are omitted, then consists of solving the integral in (22) to obtain the linear combination of sixteen functions given in Proposition 1. The origin of the function is that, when , , turns out to be the standardized finite-dimensional cumulative distribution function of order of Brownian motion with drift as can be verified by easy calculations, i.e., , we have
where
Corollary 1 comes from the property of symmetry of Brownian paths.
As for Corollary 2, according to the theory of non-arbitrage pricing in a complete market [24,25], the value of an option with a payoff based on the intersection of events in set , i.e., of an intermittent up-and-down knock-out call, is given by
where is the unique equivalent martingale measure, under which the instantaneous variations of verify
An elementary application of the Cameron–Martin–Girsanov theorem yields
where is the measure equivalent to whose Radon–Nikodym derivative is given by
□
3. Numerical Implementation
The function is a special case of the function , i.e., the multivariate standard normal cumulative distribution of order , which has the advantage of rendering both analytical and numerical computations much easier by allowing the vast majority of the pairwise correlation coefficients to be removed thanks to the Markov property of Brownian motion.
It is possible to express the sought probability as a linear combination of functions by expanding it as the following integral:
where
We have used well-known formulae to expand in (43) and in (44) (see, e.g., [26]).
But, for each one of the sixteen functions involved, there are 28 pairwise correlation coefficients to deal with, compared with only 4 pairwise correlation coefficients when using functions, and it must be very tedious and time-consuming to analytically solve the integral in (41), not to mention the very cumbersome size of the resulting formula. There is no upside in using functions from a numerical standpoint either since they are by no means simpler to evaluate than functions. The opposite is true, actually, since any quadrature rule used to compute requires fewer function evaluations than the computation of .
Whether one uses or functions, the numerical evaluation of by way of a quadrature is arguably not the proper approach to pursue anyway, owing to the dimension of the integral. Even though it can be shown that the dimension of , which is an 8-dimensional integral, can be reduced by a factor of 2 [20], this still leaves us with a 6-dimensional integral, which is not efficient to evaluate by means of a quadrature rule, since the latter involves a multiple sum of order 6. Even if a low-degree quadrature rule, such as a 16-point Gauss–Legendre rule, were sufficient in terms of accuracy, a total of 16,777,216 integrand evaluations would be needed to evaluate only one of the sixteen functions involved in Proposition 1. Since high absolute values of the correlation coefficients entail numerical instability, a fixed-degree rule would not be reliable in general anyway, thus necessitating a subregion adaptive algorithm that increases the number of integrand evaluations in the subregions where the rate of change of the integrand accelerates.
The good news is that a closed-form result such as Proposition 1 allows the development of a simple and robust integration scheme. Indeed, the exact value of the function can be approximated by Algorithm 1, where denotes the normal distribution with expectation and variance :
| Algorithm 1: Numerical evaluation of the function |
| (i) Draw a number of 8–tuples , , of independent standard normal coordinates using, e.g., the Box-Muller algorithm [27] (ii) Turn these 8–tuples into 8–tuples of correlated standard normal coordinates according to the simple correlation structure that characterizes the function, i.e., |
This integration scheme is essentially a Monte Carlo integration scheme since it relies on the generation of random numbers. As such, it satisfies the fundamental attractive property that its rate of convergence grows linearly with dimension, unlike a quadrature rule, whose rate of convergence grows exponentially with dimension, thus leading to the notorious ‘curse of dimensionality’ in numerical integration. In practice, the rate of convergence of Algorithm 1 varies according to the random number generator used. It is well-known that convergence can be accelerated by resorting to a quasi-random generator instead of a pseudo-random one due to the greater uniformity of the distributions of numbers generated by low discrepancy sequences relative to those generated by linear congruential generators [27].
One way to assess the quality of a numerical algorithm is to test its ability to match known, exact analytical benchmarks as closely as possible. The idea, which is at the center of the method of control variates in Monte Carlo simulation, for instance, is to find an exact formula for a random quantity that shares similar features as the targeted one but which can be numerically evaluated easily, i.e., by means of functions that can be computed with arbitrary accuracy as fast as required for practical purposes. Each time a numerical value is obtained for the targeted random quantity, i.e., the probability in our case, the gap measured between the exact value of the analytical benchmark and its approximated value provided by the numerical algorithm (using the same random numbers) is an indicator of the reliability of the value obtained for the targeted random quantity. In this respect, the forthcoming Proposition 2 provides an exact formula for the value of the following probability:
The combination of events that characterizes is identical to the combination of events in up until time . But the dimension of the integral resulting from the computation of is only 3 compared with 8 for , which makes it possible to evaluate numerically with all the required accuracy and efficiency, as will be shown by the forthcoming Proposition 5. In the meantime, let us state Proposition 2.
Proposition 2.
The exact value of as defined by (48) is given by
where
and all other symbols and notations are identically defined as in Proposition 1.
Proof of Proposition 2.
Following the same steps as at the beginning of the proof of Proposition 1, the problem at hand can be expressed as the following integral:
where the functions are given by (24), (25), and (26), respectively.
Performing the necessary calculations yields Proposition 2.
- □
Next, Proposition 3 provides an analytical benchmark of dimension 4, which is still very easy to evaluate numerically and has more “information” in common with than the benchmark provided by Proposition 2, as it matches the combination of events in up until time .
Proposition 3.
where
and all other symbols and notations are identically defined as in Proposition 1.
Proof of Proposition 3.
Performing the necessary calculations yields Proposition 3.
- □
Finally, Proposition 4 provides an analytical benchmark that shares even more information with as it matches the combination of events in up until time . Its dimension is 5, but it can be brought down to an effective numerical dimension of 3, as will be shown in Proposition 5.
Proposition 4.
where all symbols and notations are identically defined as in Proposition 1.
Proof of Proposition 4.
Performing the necessary calculations yields Proposition 4.
- □
The analytical benchmarks provided by Propositions 2, 3, and 4 are all the more convenient as their dimension can be reduced by a factor of two, as shown by the following result.
Proposition 5.
(i) The triple integral defining the function
can be rewritten as the following one-dimensional integral:
(ii) The quadruple integral defining the function
can be rewritten as the following two-dimensional integral:
(iii) The quintuple integral defining the function
can be rewritten as the following three-dimensional integral:
Proposition 5 ensues from simple algebra and straightforward changes of variables in the integrals, and its proof is therefore omitted; the required application of Fubini’s theorem is elementary since both the exponential of a negative number and the function, as a cumulative distribution function, are bounded by zero and 1.
Since the function can be evaluated with arbitrary precision for all practical purposes, and the exponential function is of class , the numerical evaluation of the integrals (55), (56), and (57) can be implemented using a classical Gauss–Legendre quadrature method of orders 1, 2 and 3, respectively, thus effectively reducing dimension by a factor of two in all three cases.
Table 1 reports a few evaluations of for various levels of the volatility of . The first three rows implement Proposition 1 by means of Algorithm 1 with pseudo-random numbers generated by the robust Mersenne Twister algorithm [28]. The next three rows implement Proposition 1 by means of Algorithm 1 with quasi-random numbers generated by Sobol low-discrepancy sequences, which are considered particularly reliable by experts in this field [29]. The final three rows provide approximations of Proposition 1 by Monte Carlo simulation using the powerful variance reduction technique known as “conditional Monte Carlo” or “Brownian bridge”, which essentially consists of making use of the analytically computed probability of not hitting a barrier between times and conditional on the values of and that have been “randomly” drawn, so that the path of between times and does not have to be simulated [26]. In terms of computational complexity, the CMC (Conditional Monte Carlo) method and our proposed algorithm are equivalent. Both approaches rely on random number generation and imply the exact same number of random variates to be generated at each run of the algorithm. However, Algorithm 1 does not require the function evaluations entailed by CMC and thus avoids a great number of calls to exponential and quadratic functions. The total number of runs of the algorithm required to reach a given level of accuracy may also not be identical in both numerical schemes. Compared computational times between the two methods will be shortly illustrated and discussed. In terms of inputs, the initial value of is , the drift coefficient is equal to , the final time is equal to 1.5, and the step barrier is given by on , on , on , on . The list of parameters is given by
Table 1.
Numerical evaluations of .
In its first row, Table 2 reports a few evaluations of the first analytical benchmark for various levels of the volatility of by implementing (55) with a 96-point Gauss–Legendre single quadrature, and then, in its following rows, it reports the absolute values of the differences between the benchmark and each numerical approximation, expressed as a percentage of the benchmark. Table 3 and Table 4 do the same for the second and the third analytical benchmarks, i.e., and , by implementing (56) and (57) with 96-point Gauss–Legendre double and triple quadratures, respectively. The inputs are the same as those of Table 1.
Table 2.
Numerical evaluations of .
Table 3.
Numerical evaluations of .
Table 4.
Numerical evaluations of .
It can be observed in Table 1 that there is an increasing convergence between the values obtained by the implementation of Proposition 1 and those obtained by CMC (Conditional Monte Carlo) simulation as more and more ‘random’ numbers are drawn, which not only provides an empirical ‘validation’ of the analytical calculations performed to obtain Proposition 1 but also highlights the good stability property of Algorithm 1, which is not subject to oscillations around the exact value; simply put, to obtain more accurate approximations, simply add more pseudo-random numbers—on condition that your pseudo-random number generator is uniform enough and has a sufficiently large period, though. Interestingly, smaller samples of pseudo-random variates seem necessary to attain a given level of convergence when implementing Proposition 1 by Algorithm 1 than those required by CMC. This finding was borne out by further numerical experiments performed with randomly drawn parameters of the model: on average, the number of pseudo-random variates required was divided by 2.6 when implementing Proposition 1 for three consecutive levels of convergence (1, 2, and 3 decimals of the probability expressed as a percentage). The computational times to evaluate one function when implementing Proposition 1 by Algorithm 1, as measured on a computer equipped with an Intel Core i7 CPU (made in Ireland), are the following:
- -
- 0.11 s for n = 500,000;
- -
- 0.39 s for n = 2,000,000;
- -
- 1.87 s for n = 10,000,000.
They are significantly shorter than those observed when using CMC. This is due to the fact that, in addition to having to generate pseudo-random variates, CMC involves a lot of arithmetical operations and calls to exponential and quadratic functions in order to simulate all the ’s and to compute the conditional probabilities required by the method, whereas Algorithm 1 only involves generating pseudo-random variates. However, this does not mean that resorting to Algorithm 1 to evaluate a probability will always be faster than CMC since the latter does not require drawing a new set of pseudo-random numbers for each function. In practice, the computational time differential will depend on the number of functions in the formula for the evaluated probability, which, in turn, essentially depends on the number of steps in the step barrier. To put it simply, the larger the number of steps in the barrier, the more the computational time differential in favor of Algorithm 1 will tend to shrink as a result of the increased burden entailed by a larger number of functions to evaluate. As regards , which involves sixteen eight-dimensional Gaussian integrals, the total computational time measured ranges from 1.6 s when to 27.3 s when when implementing Proposition 1 by Algorithm 1, whereas a CMC approximation takes 1.9 s when , 8.7 s when and 39.3 s when , where we recall that the number refers to the size of the sample of pseudo-random variates for each function evaluation in the case of the implementation of Proposition 1, while it refers to the number of paths simulated in the case of CMC. Since a number of simulated paths seems necessary to attain the level of convergence attained with when implementing Proposition 1, one can conclude that the latter is not only more accurate but also more efficient than CMC to evaluate .
The convergence attained by using quasi-random numbers instead of pseudo-random ones is very satisfactory, considering the small sizes of the samples used. For , the level of accuracy obtained is much higher than when using pseudo-random numbers, while only a number of simulated paths in a CMC simulation would yield very poor results. If only moderate accuracy is needed, then implementing Proposition 1 with a quasi-random number generator such as the one used here (Sobol) can be a good approach. However, the numerical experiments have not been conducted beyond for two reasons:
- -
- As increases, it becomes more and more time-consuming to maintain the same level of uniformity when computing the successive points in the low discrepancy sequence [29]; for instance, taking , as for the pseudo-random variates, would result in quite slow computational times and make the method insufficiently competitive w.r.t. to the other methods considered;
- -
- Yet more importantly, it becomes rapidly complicated and often intractable to compute the error bound entailed by quasi-random integration, and the pattern of convergence is not as simple as that of pseudo-random integration.
In Table 2, Table 3 and Table 4, one can also observe closer and closer convergence between the values obtained by implementing Propositions 2, 3, and 4 by Algorithm 1 and the values obtained by performing CMC simulation as more and more random numbers are drawn. One can also observe a seemingly faster convergence using Algorithm 1 rather than CMC simulation, similar to what is observed in Table 1. One can also clearly notice that the approximation error of all numerical methods examined, as measured by the scaled absolute value of the difference with the analytical benchmark, increases with volatility. This makes sense intuitively since volatility can be interpreted as sensitivity to randomness and unpredictability, so the higher the volatility is, the more the numerical values obtained are subject to the errors entailed by both the lack of statistical uniformity of the random number generator and the finiteness of the samples used. The error of all numerical methods examined also increases with dimension, as can be expected.
Overall, the reliability of Algorithm 1 is validated since the error is always less than 0.1% for all levels of volatility when . The smaller sample of is not accurate enough since it does not allow the relatively modest error threshold of 0.1% to be achieved for one value of in Table 2, two values of out of three in Table 3, and all three values of in Table 4. As regards CMC simulation, as many as simulated paths are necessary for the error threshold of 0.1% to be secured, whatever the value of , which is quite time-consuming. These observations are a reminder that, despite the moderate dimension tackled here, analytical formulae and semi-analytical schemes need to be carefully implemented as the inaccuracies and inefficiencies entailed by the evaluation of multidimensional integrals are significant, even when the integrand is as smooth as a Gaussian one.
4. Conclusions
This article has provided an exact formula for the survival probability of Brownian motion with drift exposed to an intermittent absorbing step barrier with four alternately up and down steps. Moreover, it has shown how to implement the formula in a simple and efficient manner and given benchmarks to assess the accuracy of the numerical implementation. As more and more steps are added to the barrier, exact formulae become bulkier and bulkier, so conditional Monte Carlo simulation may be preferred for its simplicity. However, the formula provided in this article still remains a valuable tool in at least two ways: either as a powerful variance reduction technique allowing the extension of the Brownian bridge over a longer period of time, thus eliminating the need to draw a vast number of intermediate values of the underlying process, or as an effective control variate displaying a high degree of correlation with the simulated payoff. Finally, the algorithm provided can be applied to other problems involving high-dimensional Gaussian integrals based on the values of a Brownian motion observed at a large number of points in time, e.g., the valuation of discretely monitored barriers or lookback options.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
No new data were created or analyzed in this study. Data sharing is not applicable to this article.
Conflicts of Interest
The author declares no conflict of interest.
References
- Metzler, R.; Oshanin, G.; Redner, S. First-Passage Phenomena and Their Applications; World Scientific: Singapore, 2014. [Google Scholar]
- Levy, P. Process. Stochastiques et Mouvement Brownien; Gauthier-Villars: Paris, France, 1948. [Google Scholar]
- Doob, J.L. Heuristic Approach to the Kolmogorov-Smirnov Theorem. Ann. Math. Statist. 1949, 20, 393–403. [Google Scholar] [CrossRef] [Scilit]
- Anderson, T.W. A Modification of the Sequential Probability Ratio Test to Reduce the Sample Size. Ann. Math. Statist. 1960, 31, 165–197. [Google Scholar] [CrossRef] [Scilit]
- Salminen, P. On the first hitting time and last exit time for a Brownian motion to/from a moving boundary. Adv. Appl. Probab. 1988, 20, 411–426. [Google Scholar] [CrossRef] [Scilit]
- Groeneboom, P. Brownian motion with a parabolic drift and Airy functions. Probab. Theory Relat. Fields 1989, 81, 79–109. [Google Scholar] [CrossRef] [Scilit]
- Novikov, A.; Frishling, V.; Kordzakhia, N. Approximations of boundary crossing probabilities for a Brownian motion. J. Appl. Probab. 1999, 36, 1019–1030. [Google Scholar] [CrossRef]
- Alili, L.; Patie, P.; Pedersen, J.L. Representation of the first hitting time density of an Ornstein-Uhlenbeck process. Stoch. Models 2005, 21, 967–980. [Google Scholar] [CrossRef] [Scilit]
- Lo, C.F.; Hui, C.H. Computing the first passage time density of a time-dependent Ornstein-Uhlenbeck process to a moving boundary. Appl. Math. Lett. 2006, 19, 1399–1405. [Google Scholar] [CrossRef] [Scilit]
- Breiman, L. First exit times from a square root boundary. In Proceedings of the Fifth Berkeley Symposium on Mathematical Statistics and Probability; Statistical Laboratory of the University of California: Berkeley, CA, USA; pp. 9–16.
- Sato, S. Evaluation of the first-passage time probability to a square root boundary for the Wiener process. J. Appl. Probab. 1977, 14, 850–856. [Google Scholar] [CrossRef] [Scilit]
- Daniels, H.E. Approximating the first crossing-time density for a curved boundary. Bernoulli 1996, 2, 133–143. [Google Scholar] [CrossRef]
- Wang, L.; Pötzelberger, K. Crossing probabilities for diffusion processes with piecewise continuous boundaries. Methodol. Comput. Appl. Probab. 2007, 9, 21–40. [Google Scholar] [CrossRef] [Scilit]
- Downes, A.N.; Borovkov, K. First passage densities and boundary crossing probabilities for diffusion processes. Methodol. Comput. Appl. Probab. 2008, 10, 621–644. [Google Scholar] [CrossRef] [Scilit]
- Park, C.; Schuurmann, F.J. Evaluation of barrier-crossing probabilities of Wiener paths. J. Appl. Probab. 1976, 13, 267–275. [Google Scholar] [CrossRef] [Scilit]
- Jennen, C.; Lerche, H.R. First exit densities of Brownian motion through one-sided moving boundaries. Z. Wahr. Verw. Geb. 1981, 55, 133–148. [Google Scholar] [CrossRef] [Scilit]
- Durbin, J. The first-passage density of a continuous Gaussian process to a general boundary. J. Appl. Probab. 1985, 2, 99–122. [Google Scholar] [CrossRef] [Scilit]
- Pötzelberger, K.; Wang, L. Boundary crossing probability for Brownian motion. J. Appl. Probab. 2001, 38, 152–164. [Google Scholar] [CrossRef] [Scilit]
- Fu, J.C.; Wu, T.L. Linear and nonlinear boundary crossing probabilities for Brownian motion and related processes. J. Appl. Probab. 2010, 47, 1058–1071. [Google Scholar] [CrossRef] [Scilit]
- Guillaume, T. On the computation of the survival probability of Brownian motion with drift in a closed time interval when the absorbing boundary is a step function. J. Probab. Stat. 2015, 2015, 391681. [Google Scholar] [CrossRef] [Scilit]
- Guillaume, T. Computation of the survival probability of Brownian motion with drift in a closed time interval when the absorbing boundary is an affine or an exponential function of time. Int. J. Stat. Probab. 2016, 5, 119–138. [Google Scholar] [CrossRef] [Scilit]
- Guillaume, T. Closed form valuation of barrier options with stochastic barriers. Ann. Oper. Res. 2022, 313, 1021–1050. [Google Scholar] [CrossRef] [Scilit]
- Karatzas, I.; Shreve, S. Brownian Motion and Stochastic Calculus; Springer: New York, NY, USA, 2000. [Google Scholar]
- Harrison, J.M.; Kreps, D. Martingales and arbitrage in multiperiod securities markets. J. Econ. Theory 1979, 20, 381–408. [Google Scholar] [CrossRef] [Scilit]
- Harrison, J.M.; Pliska, S. Martingales and stochastic integrals in the theory of continuous trading. Stoch. Process. Their Appl. 1981, 11, 312–316. [Google Scholar] [CrossRef] [Scilit]
- Wang, L.; Pötzelberger, K. Boundary crossing probability for Brownian motion and general boundaries. J. Appl. Probab. 1997, 34, 54–65. [Google Scholar] [CrossRef] [Scilit]
- Dagpunar, J.S. Simulation and Monte Carlo; Wiley: Hoboken, NJ, USA, 2007. [Google Scholar]
- Matsumoto, M.; Nishimura, T. Mersenne Twister: A 623-dimensionally equidistributed uniform pseudo-random number generator. ACM Trans. Model. Comput. Simul. 1998, 8, 3–30. [Google Scholar] [CrossRef] [Scilit]
- Dick, J.; Kuo, F.Y.; Sloan, I.H. High-dimensional integration: The quasi-Monte Carlo way. Acta Numer. 2013, 22, 133–288. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2024 by the author. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).