


Abstract
Over the past decade, more than a thousand new psychoactive substances (NPSs) have emerged worldwide. This rapid proliferation of “designer drugs” poses significant challenges for drug control, forensic analysis, and public health. Artificial intelligence (AI) has increasingly been applied to address these challenges in NPS design and analysis. This review provides a comprehensive overview of AI methodologies—including deep learning, generative models, and quantitative structure–activity relationship (QSAR) modeling—and their applications in the synthesis, prediction, and identification of NPSs. We discuss how AI-driven generative models have been used to design novel psychoactive compounds and predict their pharmacological activity, how QSAR models can forecast potency and toxicological profiles, and how machine learning is enhancing analytical chemistry workflows for NPS identification. Special emphasis is placed on mass spectrometry (MS)-based techniques, where AI algorithms (e.g., for spectral prediction and pattern recognition) are revolutionizing the detection and characterization of unknown NPSs. A dedicated section examines the legal and regulatory implications of AI-generated psychoactive substances in the European Union (EU) and United States (USA), highlighting current policies, potential gaps, and the need for proactive regulatory responses. The review concludes with a discussion of the benefits and limitations of AI in this domain and outlines future directions for research at the intersection of AI, analytical chemistry, and drug policy.
1. Introduction
Novel psychoactive substances (NPSs)—often called designer drugs or research chemicals—are synthetic analogues of controlled drugs engineered to evade existing drug laws [1,2]. In the last ten years, the global drug market has seen an unprecedented influx of NPSs. By the end of 2021, over 830 NPSs were being monitored in Europe (with roughly 2 new NPSs reported each week), and more than 1100 NPSs had been documented worldwide [3]. These compounds span diverse classes (synthetic cannabinoids, cathinones, opioids, phenethylamines, etc.), and most have never undergone formal safety testing. Consequently, many NPSs have been linked to severe toxic effects and fatalities, creating a public health threat [4,5]. Regulatory bodies have struggled to keep pace with the NPS phenomenon. Lawmakers often ban specific new compounds once identified, but clandestine chemists rapidly respond by synthesizing close analogues with slight structural modifications that circumvent the law. This “cat-and-mouse” cycle has led to the de facto proliferation of ever more NPS analogues despite control efforts. Traditional forensic workflows for identifying NPSs (e.g., gas or liquid chromatography coupled to mass spectrometry, GC-MS/LC-MS) rely on library matching against known reference spectra or on certified reference standards. However, acquiring reference materials for each newly emerging NPS is costly and time-consuming, and libraries are quickly outdated with the emergence of novel analogues. These challenges have spurred interest in new technological solutions to predict, detect, and characterize NPSs more efficiently [4].
Artificial intelligence has rapidly become a pivotal tool in addressing the NPS challenge. Advanced machine learning algorithms can learn complex structure–activity relationships from data and make predictions or decisions without explicit human programming. In the past few years, researchers have leveraged AI in multiple facets of NPS science. Generative models (e.g., deep neural networks) are being used to design hypothetical new psychoactive molecules and predict their likely effects [6]. Deep learning and QSAR models can screen large chemical spaces to flag candidates with high affinities for drug targets (or high toxicity) before they are ever synthesized [6,7]. Similarly, AI-driven analysis in forensic laboratories is enhancing the identification of unknown substances, for example, by predicting mass spectra of novel compounds [4] or by classifying spectra with machine learning. These approaches can drastically reduce the time required to recognize a new drug on the market [8].
This review provides an extensive overview of how AI techniques have been applied over the past decade to the design and analysis of NPSs. We survey state-of-the-art deep learning and generative modeling methods for de novo NPS design, QSAR and other predictive models for assessing NPS activity, and AI applications in analytical chemistry (particularly mass spectrometry-based detection). In addition, we examine the legal and regulatory implications of AI-generated psychoactives in the EU and USA as regulators contend with the prospect of virtually unlimited designer drug analogues.
2. AI Methods for NPS Design and Analysis
AI methodologies have shown great promise in both the design of novel psychoactives and the analysis of their properties. The key approaches include deep generative models for molecule generation, the machine learning-based screening and prediction of biological activity (e.g., QSAR), and AI tools in chemical synthesis planning.
2.1. AI-Driven Generative Models for Novel Psychoactives
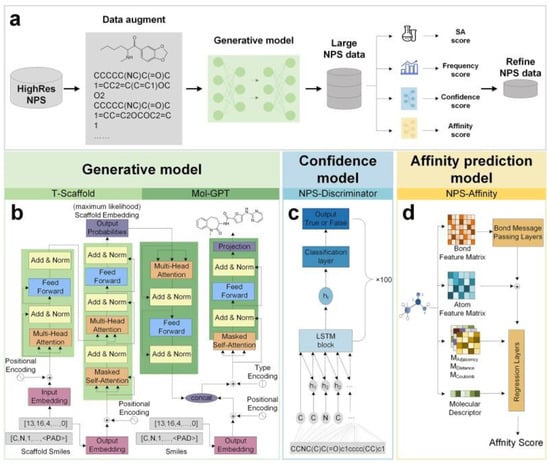
Generative models seek to create new molecule structures with desired characteristics by learning the underlying patterns of known compounds. In the context of NPSs, generative deep learning has been used to anticipate the “next” designer drugs before they appear on the street. For example, Skinnider et al. [8] introduced the DarkNPS approach, one of the first deep generative models for NPSs. DarkNPS was trained on a database of known high-resolution mass spectra of NPSs to learn the distribution of structural features in these compounds. By sampling this model, the authors generated a vast library of plausible NPS-like structures (structural “priors”), which could aid in elucidating the identity of unknown designer drugs. Notably, a majority of recently discovered NPSs fell within the chemical space covered by the model’s generated compounds, validating the approach. One limitation of this early model was the need to sample billions of molecules to ensure novel coverage, leading to many false positives. Subsequent work has built on this foundation with more targeted generative strategies. A significant advance in AI-driven NPS design is the STNGS framework (Scaffold and Transformer-Based NPS Generation and Screening) developed by Liu et al. [6]. STNGS combines a scaffold-based molecular generative model with a multi-factor scoring system to prioritize generated candidates. Instead of free-form generation, it focuses on known core scaffolds common in NPSs and uses a transformer-based neural network (a T-scaffold encoder–decoder and a MolGPT module) to generate analogues around those scaffolds. The generated molecules are then filtered and ranked by an ensemble of criteria, including synthetic accessibility, a novelty/frequency score, a confidence score from an NPS-trained discriminator network, and an affinity score predicting target receptor activity. This multi-objective ranking ensures that the suggested compounds are not only novel and synthesizable but also likely to be psychoactively potent. Using STNGS, researchers successfully identified three new synthetic cannabinoids that showed significant activity at cannabinoid receptors. These AI-proposed cannabinoids were confirmed via biological assays, demonstrating the real-world utility of AI in discovering NPS leads. Figure 1 illustrates the overall STNGS workflow, from data augmentation of known NPS scaffolds to the generation of candidate structures and their subsequent screening.
Figure 1.
A schematic overview of an AI-driven generative framework (STNGS) for novel psychoactive substance discovery. (a) The model generates new molecules based on known NPS scaffolds and then applies multiple filters (b) including synthetic accessibility (SA), predicted frequency (novelty), (c) a confidence score from an NPS classifier, and (d) a neural network-based affinity prediction to refine and prioritize the candidate NPSs. In a case study, this approach led to the identification of active novel synthetic cannabinoids.
Other researchers have similarly employed generative models tailored to specific NPS classes. Zhang et al. [9] focused on fentanyl analogues, a notorious group of synthetic opioids, by training deep generative models (SeqGAN and MolGPT) on known fentanyl derivatives. Their AI system generated over 11,000 plausible fentanyl-like structures, some of which were chemically quite distinct from the training set (indicating true novelty). From these, the team selected ten candidate molecules predicted to have characteristic fentanyl-like properties. Remarkably, after chemical synthesis and laboratory characterization, all ten turned out to be previously unreported fentanyl analogues.
This was the first demonstration that deep learning could generate chemically diverse analogues of fentanyl that had not yet been identified by law enforcement. Such generative efforts not only help authorities stay ahead in the opioid crisis by populating databases with potential analogues, but they also highlight a double-edged sword: the same technology could theoretically be used by bad actors to design new illicit opioids. We return to this concern in Section 6.
Generative models have also been applied to other NPS families and general drug-like chemical spaces. Approaches using recurrent neural networks (RNNs) and variational autoencoders (VAEs) have been reported to produce focused libraries of psychoactive-looking molecules [8]. Modern chemical language models (which treat molecular representations like a language) can capture complex chemical distributions and have been used to navigate sparsely populated regions of chemical space where NPSs often reside [4]. These advances suggest that AI can enumerate a practically infinite set of potential NPSs, limited only by chemical feasibility. In practice, the value of generative models is greatly enhanced by integrating them with predictive filters (as STNGS and others have done) to sort the “wheat from the chaff”, i.e., to predict which AI-designed structures are likely to be active and hazardous. This leads us to AI-driven screening and QSAR methods.
2.2. QSAR Modeling and AI-Based Screening
Quantitative structure–activity relationship (QSAR) modeling is a longstanding computational technique in drug design, using statistical or machine learning models to predict biological activities from chemical structure descriptors. In recent years, QSAR and related machine learning models have been developed specifically to evaluate NPS analogues, providing a fast way to assess the potential potency or risk of a novel compound in silico. These models can guide forensic chemists and regulators by flagging which new analogues might be the most potent (and thus dangerous) or by identifying inactive ones.
One prominent example is QSAR modeling for synthetic cannabinoids, a major group of NPSs that activate cannabinoid receptors (CB1/CB2). Jang et al. [10] developed a QSAR model to predict the binding affinity of synthetic cannabinoids to the CB1 receptor, which is responsible for cannabis-like psychoactive effects. They synthesized or obtained a series of 14 synthetic cannabinoids (across several structural subfamilies such as naphthoylindoles, benzoylindoles, cyclohexylphenols, etc.), measured their CB1 affinities, and used these data to train the model. The resulting QSAR model showed good predictive performance and was able to correlate molecular structural features with receptor binding strength. This tool can predict the abuse potential of various synthetic cannabinoids and help control their illicit use by identifying which new chemical modifications might produce a high-affinity (and likely high-effect) compound. In essence, such a model acts as an early warning system: if a new cannabinoid analogue emerges, its structure can be input to the model to estimate if it is a potent CB1 agonist (suggesting a strong psychoactive and addictive profile).
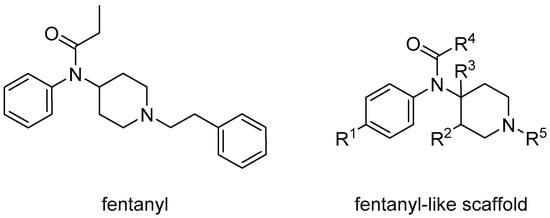
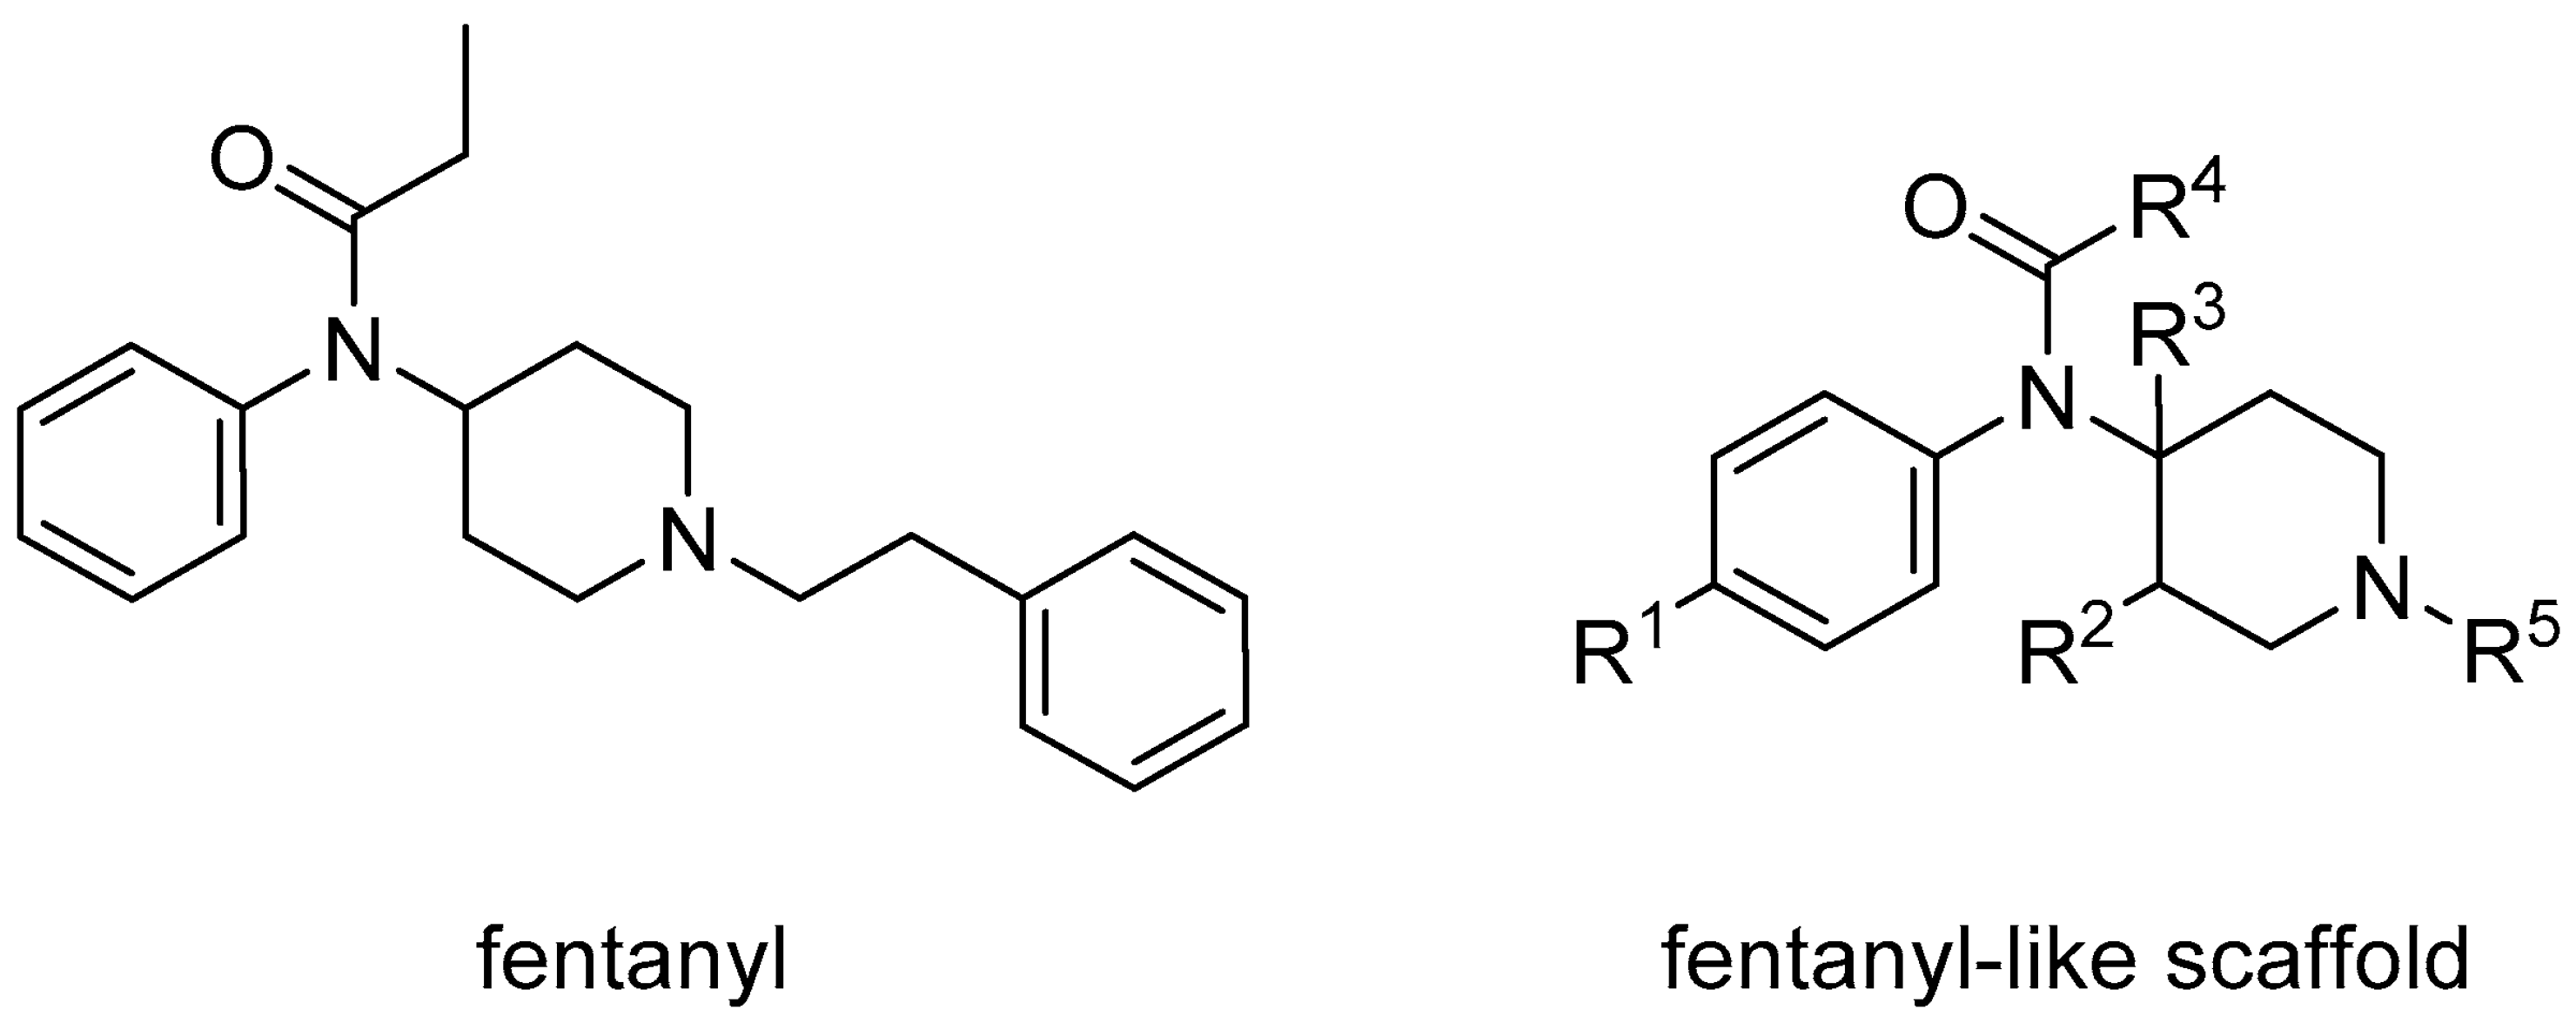
Similar efforts have targeted synthetic opioids. Floresta et al. [7] reported a multi-QSAR modeling approach for fentanyl analogues, aiming to predict the μ-opioid receptor (μOR) binding affinities of newly designed analogues. They compiled a dataset of 115 fentanyl-related structures with known μOR binding data and built three QSAR models using 2D and 3D molecular descriptors [11]. By combining these into a consensus model, they achieved robust predictions of binding affinity. The authors then virtually generated 3000 hypothetical fentanyl analogues using a scaffold-hopping strategy (systematically varying substituents on the fentanyl core as in Figure 2) [12].
Figure 2.
Structure of fentanyl and fentanyl-like compounds.
The QSAR consensus model was applied to screen this library and successfully identified numerous analogues predicted to have high μOR affinity [11]. Notably, some analogues identified through this virtual screening correspond to compounds that the U.S. Drug Enforcement Administration (DEA) had already pre-emptively placed in Schedule I (controlled) despite limited lab testing [13].
This underscores QSAR’s practical impact: virtual screening can flag potent analogues even before they appear in circulation, informing law enforcement and scheduling decisions. Indeed, the authors suggest that such in silico methods could “facilitate the identification and classification of new μOR ligands” for regulatory purposes [14].
More broadly, QSAR models (when sufficiently validated) allow chemists to explore chemical modifications on paper and estimate their effects on activity, thus guiding the synthesis of only the most relevant analogues.
Beyond receptor binding affinity, AI models have been employed to predict other properties relevant to NPSs. For instance, machine learning has been used to predict the metabolic stability and toxicity of new analogues, which is crucial since some NPSs may act as prodrugs or have toxic metabolites. Additionally, AI regression models can predict chromatographic retention times or mass spectral fragmentation patterns (topics we delve into in Section 5) to assist in analytical detection. One study developed a model to predict the GC-MS retention indices of synthetic cannabinoids, which can help forensic labs to rapidly recognize a compound’s identity by its retention time, even without a perfect library match [15].
Another emerging application is docking simulations and virtual screening for NPS—essentially using AI to predict how strongly a novel compound might bind to a target protein (such as a neurotransmitter receptor or transporter). For example, virtual docking combined with machine learning scoring has been applied to predict which new psychoactive analogues will activate the serotonin 5-HT2A receptor (implicated in psychedelic effects) versus which will not, aiding in distinguishing true psychedelic and potentially therapeutic species from inactive analogues (though specific published cases of this are just beginning to appear).
2.3. AI in Synthetic Chemistry for NPSs: Present and Prospective
While not as extensively documented in the literature as generative design and QSAR, AI is also making inroads in the synthesis of NPSs. Retrosynthetic planning tools driven by AI can propose synthetic routes to novel compounds, potentially enabling or streamlining the laboratory production of NPS analogues. Advances in automated synthesis (“self-driving” laboratories) could, in the future, allow for the rapid synthesis of AI-designed psychoactives for testing. From a law enforcement perspective, the flip side is concerning: the availability of AI-driven recipe generation could lower the barrier for the clandestine synthesis of new drugs. For example, an AI system given a target molecular structure can now suggest step-by-step synthetic routes, including the needed precursors and reaction conditions, with success rates that approach those of expert human chemists. If such tools were applied to an AI-designed NPS structure, a viable synthesis might be identified in minutes. While we did not find specific public reports of AI being directly used by illicit NPS manufacturers, this remains a potential risk as technology becomes more accessible. On the positive side, the same tools can assist legitimate laboratories in quickly making reference material of newly discovered NPSs for analytical and toxicological evaluation.
AI methods—from deep learning generative models to predictive QSAR and property models—are transforming how we approach the design and initial evaluation of novel psychoactives. Rather than reacting after a new drug appears, scientists and regulators can proactively explore the chemical landscape of possible NPSs. AI can generate virtual libraries of analogues, predict which ones are likely potent or dangerous, and thus help prioritize resources (for synthesis, scheduling, or monitoring) toward the most concerning candidates. In the next section, we focus on how AI is improving the detection and identification of NPSs, especially in the realm of analytical chemistry and mass spectrometry, which is critical for the forensic confirmation of these substances.
3. Mass Spectrometry and AI in NPS Identification
Mass spectrometry (MS) is the workhorse technique for identifying unknown drugs in seized materials and biological samples. In forensic toxicology and drug chemistry, analysts typically use GC-MS or LC-MS/MS to detect NPSs, looking for characteristic fragmentation patterns (“mass spectra”) [16]. The challenge with NPSs is that reference spectra or standards for new compounds are often unavailable at the time of first encounter. Traditionally, an unknown spectrum might be tentatively identified by its similarity to known analogues, but this can be error-prone if the compound is truly novel. AI and machine learning are now addressing these challenges on multiple fronts: by predicting mass spectra from molecular structure, by searching large databases of theoretical spectra, and by classifying or clustering spectra to recognize novel compounds.
A major breakthrough in this area is the development of deep learning models that can predict an organic molecule’s MS/MS spectrum directly from its structure. Recently, Wang et al. [4] introduced NPS-MS, a deep learning system tailored for NPS identification via tandem MS. The NPS-MS model was trained via transfer learning: first tested on a large generic dataset of MS/MS spectra and then fine-tuned on a curated set of known NPS spectra. Given a molecular structure (e.g., a proposed formula or analogue), NPS-MS can generate a predicted MS/MS fragmentation spectrum. In tandem, the authors created a database of ~8.7 million hypothetical NPS structures (sourced from the “DarkNPS” library and other combinatorial enumerations [8]) and predicted spectra for all of them. When an unknown sample is analyzed, its experimental MS/MS spectrum can be compared against this vast library of predicted spectra to find the best match, even if the compound has never been seen before [17].
Impressively, NPS-MS achieved higher identification accuracy than conventional spectral matching or rule-based tools in tests [18].
The model was validated on a real-case scenario: it correctly identified a novel phencyclidine (PCP) analogue present in an unknown powder seized in Denmark, without any reference standard [4]. The AI predicted the spectrum for the candidate 3-chloro-PCP structure, which matched the observed spectrum, leading to the substance’s identification and confirmation.
This example demonstrates a powerful paradigm shift; using AI, labs can identify a new drug by theory alone (structure and predicted spectrum), rather than requiring months to obtain a standard and record its spectrum. The NPS-MS tool has been made available as a public web server, providing forensic scientists with on-demand MS/MS predictions and an automated NPS spectral library search.
Machine learning has also enhanced in silico fragmentation tools that existed before [18]. For instance, Competitive Fragmentation Modeling (CFM) is a machine learning approach that predicts likely fragmentation pathways and intensities. The earlier CFM-ID 3.0 model (2019) [19] and the improved CFM-ID 4.0 (2021) [20] demonstrated substantial accuracy in predicting the electrospray MS/MS spectra of small molecules.
CFM-ID 4.0, in particular, incorporated neural network predictions and achieved higher spectral prediction accuracy than rule-based methods on diverse metabolites and drugs.
These tools are not NPS-specific, but their adoption in forensic workflows has grown. Wang et al. [20] reported that integrating CFM-ID into NPS identification pipelines significantly boosted correct structure annotations for unknown spectra compared to traditional library searches.
Another tool, SIRIUS 4 [17], uses a combinatorial fragmentation tree approach (with some machine learning) to deduce molecular formulas and substructures from MS/MS. While SIRIUS performed well for many metabolites and some NPSs, it sometimes proposed structures that were chemically very different if the compound was outside its training distribution.
AI models like NPS-MS address that gap by specializing in the “chemist’s creativity” zone of NPS analogues.
Apart from predicting spectra, AI can directly assist in spectral matching and classification. Traditionally, an unknown spectrum is searched against a database of known spectra for a match. But when the unknown spectrum is absent from the database, this yields no result. One strategy is “suspect screening”, where one compiles a list of possible candidates (suspects) and their expected spectra. The HighResNPS online database [21,22] (created in 2019) is an example of a crowd-sourced repository that collects high-resolution MS data for known and suspected NPSs.
Mardal et al. [21] described HighResNPS as containing consensus fragment ions for >1000 NPS, enabling spectrum-based screening: if an unknown spectrum contains certain diagnostic fragment peaks, it can be matched to candidates in the database even without an exact library spectrum.
Building on this, Davidsen et al. [22] demonstrated an MS screening method for over 1000 NPSs using those consensus fragments. Their approach uses fragment presence/absence patterns and simple machine learning rules to narrow down which NPS family or specific compound an unknown substance might belong to.
This still relies on known fragment data, but it extends identification capabilities to hundreds of NPSs in one LC-HRMS run.
In forensic laboratories, analysts also leverage diagnostic ions and neutral losses characteristic of certain NPS subclasses, sometimes guided by AI pattern recognition [5]. For example, fentanyl analogues often show a common product ion at m/z 188 (aniline fragment), and machine learning classifiers can be trained to detect such patterns across spectra. Swanson et al. [23] used a database of fentanyl analogue mass spectra to train a model that recognizes these diagnostic ions and can flag an unknown as a fentanyl-class substance even if it is not an exact library match.
Similar logic applies to synthetic cannabinoid metabolites, cathinones (which often show a function of the β-keto fragment), etc. These ML-assisted rules give analysts rapid presumptive IDs (e.g., “this unknown is likely a fentanyl derivative”) to prioritize confirmation.
Another application of AI in MS-based NPS analysis is untargeted data mining. High-resolution mass spectrometers produce enormous amounts of data, and AI can sift through full-scan MS data to detect features that might represent unknown drugs or metabolites. Unsupervised machine learning clustering has been used to group related spectra, which can reveal the presence of an unknown compound along with its analogues or metabolites, forming a cluster apart from known compounds. In metabolomics, such “molecular networking” approaches (e.g., on the GNPS platform) use spectral similarity networks to discover new molecules; these have been applied to find new NPS metabolites in biological samples by linking them to parent drug spectra. While not yet mainstream, one can envision forensic labs using unsupervised ML to automatically flag suspicious spectra that do not match any known substance, essentially triaging novel NPSs for further analysis.
It is also worth noting how AI improves other analytical modalities for NPS detection in complement to MS. One example is in Raman spectroscopy: Tian et al. [24] developed a method combining Shifted-Excitation Raman Difference Spectroscopy (SERDS) with machine learning to identify NPSs rapidly on-site. By using SERDS to acquire fluorescence-free Raman spectra of samples, they then applied algorithms including support vector machines (SVMs) and neural networks to classify the spectra among 37 different NPSs and related substances. The optimized SVM model achieved >97% accuracy in classifying an unknown as one of three drug families (fentanyl analogues, amphetamine-type stimulants, or synthetic cannabinoids).
This demonstrates AI’s utility beyond MS—in this case, enabling a nondestructive field test that can differentiate classes of NPSs in seconds using a handheld Raman device. Similarly, AI has been used in IR spectroscopy and ion mobility spectrometry data analysis for NPS, offering complementary tools when MS is not available. However, mass spectrometry remains the gold standard for definitive identification, and thus our focus is on MS here.
In summary, AI is significantly enhancing the mass spectrometry-based identification of NPSs in several ways:
- Spectrum Prediction: Deep learning models predict the fragmentation patterns of novel compounds, allowing for the creation of “theoretical” spectral libraries for newly emergent NPSs. This reduces dependence on laboratory-synthesized reference standards and speeds up identification.
- Automated Spectral Matching: Machine learning algorithms compare unknown spectra against large databases of predicted or experimental spectra to find the best match, even for compounds not previously observed.
- Pattern Recognition: AI picks up diagnostic fragmentation patterns (specific ions or losses) indicative of certain substructures, flagging the likely class of an unknown (e.g., fentanyl versus cathinone).
- Data Mining: Unsupervised learning can detect clusters or outliers in complex MS datasets, potentially discovering new NPSs or metabolites without prior assumptions.
The net effect is a more robust and rapid identification pipeline. Using AI, forensic labs have, in some cases, cut the identification time for a new designer drug from months to days. This is critical for public health responses, as a quicker identification enables earlier warnings to hospitals and law enforcement about a new dangerous substance in circulation.
4. Legal and Regulatory Considerations for AI-Generated Psychoactive Substances
The intersection of AI, novel psychoactive substances, and drug policy raises important legal and regulatory questions. Both the European Union (EU) and the United States (USA) have struggled to adapt their drug control frameworks to the fast pace of NPS innovation. The advent of AI-driven drug design—which could potentially produce countless novel analogues—further challenges the traditional reactive scheduling approach. In this section, we examine how the EU and USA are addressing NPSs, and what implications AI-generated substances hold for future policy.
4.1. European Union
In the EU, NPSs are tackled through a combination of early warning, risk assessment, and control measures coordinated by the European Monitoring Centre for Drugs and Drug Addiction (EMCDDA), now the European Union Drugs Agency (EUDA). Since 1997, the EMCDDA/EUDA has run an early warning system (EWS) to rapidly share information on new drugs among member states.
When a new NPS is detected, the EWS facilitates data exchange on its chemistry, availability, and health incidents. This can lead to a formal risk assessment and a recommendation for EU-wide control. Over the years, the European legal framework for NPSs was found to be too slow; under the old procedure (Council Decision 2005/387/JHA) [25], it often took many months or years to control a substance, during which it could spread widely.
Recognizing this, the EU revised its legislation in 2017 to streamline the NPS control process, introducing shorter deadlines and a faster risk assessment mechanism.
The newer system (Regulation (EU) 2017/2101 and related measures, effective 2018) significantly reduced the time from detection to union-wide ban, as illustrated by the compressed timelines in recent EUDA reports [26].
Despite these improvements, EU authorities acknowledge that traditional control (banning one substance at a time) cannot keep up if hundreds of new analogues appear. Some EU member states have adopted innovative legal responses. For example, Ireland and Poland enacted “generic” legislation that bans whole classes of substances based on their core structure, rather than individual molecules
The United Kingdom (while it was in the EU) implemented the Psychoactive Substances Act 2016, a blanket ban on any substance with psychoactive effect (with exemptions for established ones like alcohol, caffeine, and medicines) [27,28].
However, such broad approaches have drawbacks; they may inadvertently criminalize benign substances or face challenges in court over definitions of psychoactivity.
An EU-wide blanket ban was considered, but not adopted, partly due to these concerns.
Instead, the EU relies on the enhanced EWS and faster scheduling, combined with continuous updates to definitions of controlled substance families. The legal implication of AI in this scenario is that regulators might have to start anticipating substances before they emerge. With AI tools like generative models predicting likely new NPSs, the EUDA could proactively add those to monitoring lists or even recommend pre-emptive controls if a particular analogue is forecasted to be highly potent and dangerous. There is some precedent: as mentioned, the DEA in the US (see below) temporarily class-scheduled fentanyl analogues due to a surge; an analogous move in the EU could be to class-schedule entire families (the EUDA has suggested generic controls for groups like synthetic cannabinoids).
The EU’s current legal framework does not explicitly address AI-designed drugs, but it is moving toward speed and flexibility, which will be crucial as AI accelerates the rate of innovation in NPSs.
Another consideration is the regulation of AI tools themselves under EU law. The EU is at the forefront of AI regulation (with a proposed AI Act). If an AI system is used to design potentially harmful substances, questions arise: should such software be regulated or restricted? Currently, there is no law preventing the open publication of generative models that could be misused to create NPSs or even more dangerous chemicals. EU authorities, including the Organisation for the Prohibition of Chemical Weapons (OPCW), which works closely with EU states, have begun discussing the “dual-use” nature of AI in chemistry [29].
While those discussions have focused more on chemical weapons, the concern extends to illicit drugs. Policymakers may consider classifying certain AI drug design software as dual-use technology that requires oversight if it is capable of suggesting syntheses of controlled substances. This is still a nascent policy discussion, and no concrete proposals have been made in the EU specific to AI and illicit drug design as of this writing.
4.2. United States
The USA addresses NPSs primarily through the Controlled Substances Act (CSA) scheduling system and the Controlled Substance Analogue Enforcement Act of 1986 (often called the “Analog Act”). The Analog Act stipulates that any substance “substantially similar” in structure and effect to a Schedule I or II controlled drug, and intended for human consumption, can be treated as a Schedule I controlled substance (the highest level of control). This has been a key tool for US prosecutors to go after NPS traffickers without requiring Congress to schedule each new analogue. However, determining a “substantially similar” structure and effect often involves expert testimonies and has been legally contentious at times. AI could potentially aid here by quantitatively assessing structural similarity or by predicting the pharmacological effect similarity of a novel analogue to a known drug, thereby supporting analogue prosecutions with data-driven evidence. Still, the Analog Act is reactive; it comes into play after a substance exists and is argued to be an analogue of an existing drug.
US authorities have also used emergency scheduling via the DEA to temporarily control NPSs that pose imminent hazards, followed by permanent scheduling through legislative or administrative action. One notable response to the explosion of fentanyl analogues was the DEA’s 2018 decision to place all fentanyl-related substances (defined by a core chemical scaffold and certain substitutions) into Schedule I as a class. This class-wide scheduling, repeatedly extended by Congress, was an attempt to pre-empt the endless stream of new fentanyl analogues by making any modified fentanyl automatically illegal [30].
This move has been somewhat controversial (due to concerns that it could hinder medical research on new analgesics), but it illustrates a proactive approach that may become more common. If AI design means that, for any controlled drug, a clever chemist (or an AI itself) can generate dozens of not-yet-illegal analogues, regulators may respond by scheduling entire classes of compounds, broadly defined by structure. The downside to this is that it may over-schedule innocuous or inactive analogues and hamper therapeutic drug development. Policymakers will need to balance these considerations.
Regarding AI-generated substances, at present, the USA has no distinct legal category for them. If an AI were used to create a novel psychoactive that is not structurally similar to any controlled drug (thus evading the Analog Act), that substance would initially be legal at the federal level until specifically scheduled. This is the classic loophole NPS creators exploit. AI could potentially widen that loophole by finding active compounds that are not obvious analogues of known drugs. For example, an AI might design a molecule that produces opioid-like effects but is not structurally an opioid; such a compound would fall outside of current analogue laws. This possibility raises the question: do we need new laws to handle drugs by effect rather than structure (like the UK’s approach)? Or even laws addressing the act of creating harmful psychoactives via AI? These discussions are still hypothetical, but the legal framework may need modernization if AI starts yielding qualitatively new classes of psychoactives.
On the positive side, US regulatory and public health agencies are also harnessing AI to combat NPSs. The FDA and NIH have been exploring machine learning for predictive toxicology, for instance, to predict if a novel substance is likely to cause seizures or other adverse effects, which can inform scheduling decisions. The Office of National Drug Control Policy (ONDCP) in 2021 highlighted the need to leverage technology to forecast emerging drug threats. Using AI to analyze trends (e.g., web chatter, forensic lab data) might even predict which NPSs are gaining popularity so that law enforcement can act quickly.
4.3. Dual-Use Concerns and Regulatory Response
A crucial aspect when discussing AI-generated psychoactive substances is the dual-use nature of AI in chemistry. The same generative AI tools that can aid pharmaceutical discovery can be misused to design harmful substances. A striking proof-of-concept was published by Urbina et al. [29], where researchers demonstrated that by inverting the objectives of a drug-design AI (seeking toxicity rather than avoiding it), the AI could invent thousands of chemical warfare agent analogues in a matter of hours.
Among these were novel molecules similar in potency to VX (a deadly nerve agent) [31,32].
While that study was focused on chemical weapons, it serves as a wake-up call for illicit drugs as well: an AI model directed to maximize psychoactive effect could potentially devise ultra-potent stimulants or hallucinogens beyond current human imagination. This possibility is not far-fetched; in fact, AI has already suggested opioids more potent than fentanyl in theoretical studies (though they have not been synthesized, to public knowledge).
Regulators in both the EU and USA are beginning to consider these scenarios under the umbrella of chemical security and biosecurity. There have been calls for greater oversight on the dissemination of AI models that could be misused.
Some experts suggest an international framework akin to non-proliferation treaties, where researchers and publishers exercise restraint or at least notification when AI is used to design hazardous substances. In the context of NPSs, one proposal could be creating an international “watch list” of AI-predicted high-risk compounds. If AI predicts a molecule that is a super-potent opioid or hallucinogen, authorities could consider taking preventive action (for example, quietly synthesizing a reference sample and studying it, or even scheduling it preemptively). However, this raises practical and ethical questions: predictive models are not infallible, and the pre-emptive control of substances that do not yet exist (or have no abuse cases) would be unprecedented and potentially controversial.
In the EU, the legal framework does allow for the controlling of a substance based on potential risk (even if it is not yet widespread), so an AI-flagged compound could be controlled if the risk assessment justifies it. In the US, the bar for scheduling includes evidence of abuse potential; in the absence of any actual abuse, it might be difficult under current law to schedule a molecule solely because AI predicts it would be very potent. Thus, legal reforms might be needed to empower proactive action. Policymakers are likely to tread carefully here, balancing innovation with precaution.
Both the EU and USA are actively improving their NPS regulatory responses—the EU via faster scheduling and information exchange and the US via broad analogue/control measures and class scheduling. AI-generated NPSs amplify the need for agile and forward-looking drug policies. Regulators may increasingly rely on scientific forecasting (potentially AI-driven) to inform policy decisions, and they must also consider regulating the use of AI when it crosses into producing illicit drug recipes or structures. At present, no jurisdiction has laws specific to “AI-designed drugs”, but the evolving dialogue suggests that legal systems will adapt as this becomes a more tangible issue.
5. Impact on Analytical Chemistry and Forensic Identification
The application of AI in the realm of novel psychoactive substances is a quintessential double-edged sword. On one side, AI offers powerful solutions to scientific and forensic challenges: it can accelerate drug discovery in beneficial ways, help forensic labs stay ahead of traffickers, and provide insights into the vast chemical space of psychoactives that were previously beyond human grasp. On the other side, the same technology can be co-opted to create ever more potent or elusive illicit drugs, stressing the limits of current legal control regimes. In this discussion, we synthesize the key impacts of AI on NPS research and control, and consider the broader implications, limitations, and future needs highlighted by our review.
The integration of AI has begun to transform analytical workflows for NPSs. Deep learning models that predict mass spectra or interpret spectral data have effectively extended the capabilities of forensic laboratories. A task that traditionally required a physical reference standard and weeks of expert analysis—identifying a new drug structure—can now sometimes be achieved in silico within hours using AI-driven spectral prediction [4].
This boosts the responsiveness of public health warnings and law enforcement actions. Moreover, AI models do not tire or bias; they can continuously monitor data streams (mass spectra, social media signals, etc.) for anomalies, providing an automated early warning of emerging substances. These enhancements improve both the sensitivity (detecting obscure novel compounds that might be missed by human analysts) and speed of NPS identification. However, one must temper their enthusiasm with the current limitations: AI predictions are only as good as the training data and chemical knowledge base. Many generative or predictive models might struggle when confronted with a truly novel core structure outside their training distribution. In such cases, expert human interpretation remains vital. Thus, rather than replacing human analysts, AI serves as an adjunct, handling the heavy data crunching and suggesting hypotheses that experts can confirm.
The in silico design and screening of psychoactives using AI is a field still in its adolescence, yet it has shown that, in principle, machines can innovate in the psychopharmacological space. The success of AI in generating active new analogues of cannabinoids and fentanyl [6,9] suggests that future recreational or therapeutic drugs might originate from a computer’s imagination as often as from a chemist’s. This raises an intriguing scientific point: AI models might design molecules that humans would not intuitively think of, potentially leading to the discovery of entirely new classes of psychoactives (for example, non-classical cannabinoids or opioids that do not resemble known scaffolds). For medicinal chemistry, this could be beneficial (e.g., finding novel analgesics with less addiction potential), but for illicit drug markets, it could circumvent existing laws by introducing drugs that defy conventional structural categories. One limitation we observed in the current studies is that AI-designed NPSs have so far mostly stuck to known scaffolds (because models are trained on known NPSs or close analogues). Truly novel scaffolds will require either expanding training data or employing creative generative strategies that encourage exploration beyond known chemical families. Ensuring that predictive models (like QSARs) remain accurate for these novel designs is another challenge; extrapolating QSAR beyond known chemistry can lead to unreliability. Therefore, a continuous loop is needed: as AI proposes new structures and some are synthesized and tested, those results should be fed back to refine the models. This iterative improvement will gradually widen the reliable predictive space.
6. Regulatory and Ethical Implications
Perhaps the most profound questions lie in how society will manage the consequences of AI in the drug domain. Regulatory agencies may need to rethink how drugs are scheduled—for instance, moving towards mechanistic or effect-based scheduling (controlling any substance that activates a certain receptor beyond a threshold, regardless of structure). Such approaches would rely on rapid computational assessments of new molecules’ likely pharmacology, an area where AI could be the linchpin. There is also the concept of “digital drugs”, in a sense; an AI model can output thousands of virtual substances, but they are not drugs until someone synthesizes them. Regulating that knowledge (i.e., the lists of AI-generated structures or the AI model itself) enters tricky legal territory around freedom of information and research. Up to now, chemists have published papers listing new compounds (sometimes psychoactive) without legal issue. Will publishing an AI model that could be misused be seen differently? The dual-use discussion in the chemical weapons sphere indicates a growing sentiment that certain capabilities should be restricted or monitored.
The community may develop guidelines or a code of conduct for researchers using AI in drug discovery to mitigate misuse (for example, avoiding explicitly publishing the “blueprints” for deadly substances, or at least alerting authorities if such findings occur).
It is important to highlight some technical limitations encountered in the literature. Many deep learning models for molecule generation struggle with ensuring the synthetic feasibility of their proposed structures; a molecule may look interesting on a screen but be nearly impossible or extremely expensive to actually synthesize. Methods like STNGS tackled this by incorporating a synthetic accessibility score [33], but not all studies have. Also, AI models can inadvertently generate toxic or unstable compounds (as seen when the model’s objective is not carefully constrained). Another limitation is the accuracy of property prediction: QSAR models and docking simulations for NPSs are only as good as the underlying data, which in the case of NPSs are often sparse or of variable quality (since these substances are not studied as extensively as pharmaceuticals). This means any AI-driven prioritization of new NPSs comes with uncertainty; false positives and negatives are possible. For instance, an AI might predict a certain analogue to be potent and dangerous, but in reality it could metabolize quickly to an inactive form, leading to an overestimation of risk if taken at face value. Conversely, an unpredictable “black swan” compound could emerge that the models fail to flag.
Analytical challenges also persist. In mass spectrometry, while spectrum prediction is greatly improved, certain complex molecules (especially those prone to unusual fragmentation or rearrangements) can still fool the algorithms, yielding mismatches. The community is working on hybrid approaches combining rule-based expert systems with machine learning to cover such cases. Data sharing is another issue: the success of AI in identifying NPSs hinges on access to comprehensive spectral libraries and activity data. Efforts like HighResNPS and crowdsourced databases are steps in the right direction [21], but proprietary or siloed data can limit model performance. There is a strong argument for international collaboration to compile NPS datasets (structures, spectra, bioassays) in the public domain to fuel AI development for the common good.
7. Future Directions
Based on this review, several future directions emerge:
- Improved Generative AI: The development of generative models that can propose truly novel scaffolds with desired psychoactive profiles, moving beyond close-in analogues. This may involve training on not just known NPSs but broader chemical and pharmacological data to encourage novelty.
- Integrating Toxicology Predictions: Next-generation models will likely integrate multiparameter objectives—not just potency, but also toxicity, metabolic stability, blood–brain barrier penetration, etc.—to predict overall “danger” scores for hypothetical substances. This could guide both drug designers and regulators.
- Real-Time Surveillance Systems: It is possible to imagine an AI system that continuously monitors forensic lab data worldwide. As soon as a few labs report an unknown spectrum, the AI could aggregate that information, predict the structure, check online discussions, and notify the authorities—all in near-real-time. This kind of AI-driven surveillance network could greatly shorten the time between a new NPSs’ appearance and its identification and control.
- Policy Innovation: Regulators might invest in predictive modeling groups whose job is to use AI to map out the landscape of likely NPSs and advise on pre-emptive controls. They will also need to craft legal frameworks for cases like “structurally novel but functionally similar” substances. International cooperation will be key, since NPS manufacturing and distribution is a global issue.
- Ethical AI Deployment: The scientific community will need to set ethical guardrails. Similarly to how certain gain-of-function biological experiments are approached with caution, AI experiments that intentionally seek harmful compounds may require oversight or justification. Conversely, withholding scientific advancements is also problematic. Achieving a balance, perhaps through classified channels or responsible communication, will be important.
AI has indisputably become an important ally in the fight against novel psychoactive substances, offering tools to predict and detect these drugs faster than ever before. The synergy between AI and human expertise can markedly improve our ability to protect public health from the harms of NPSs. Yet, as this review has detailed, the same technology introduces new challenges by potentially enabling the creation of more novel and potent substances. The coming years will test our ability not only to innovate scientifically but also to adapt our legal and ethical frameworks to a world where “virtual chemists” might design the drugs of tomorrow. Close collaboration between data scientists, chemists, toxicologists, and policymakers will be essential to fully harness AI’s benefits while managing its risks in the context of psychoactive substances.
8. Conclusions
AI is reshaping the landscape of novel psychoactive substances from multiple angles. Over the past decade, AI-driven methods have proven their value in designing new chemical entities, predicting their properties, and identifying them analytically. Deep learning and generative models can explore chemical possibilities at a scale and speed unattainable by traditional approaches, which could lead to both innovative therapeutics and new illicit drugs. In analytical chemistry, machine learning algorithms—especially in mass spectrometry—are dramatically improving the speed and accuracy of NPS identification, addressing a critical bottleneck in forensic science. These advancements come at an opportune time, given the relentless emergence of NPSs globally.
At the same time, the rise of AI in this domain forces a re-examination of regulatory strategies. The EU and USA have made strides in adapting their policies to faster control NPSs, but they will need to remain agile. AI may soon allow the illicit drug supply to diversify even further, calling for international coordination on monitoring and possibly the consideration of pre-emptive controls based on AI predictions. Ensuring that legal frameworks do not lag dangerously behind technological capabilities will be an ongoing challenge.
For researchers and practitioners, several future directions are clear. The continued development of specialized AI models for NPSs, the improved sharing of data (spectral, structural, and clinical) to train these models, and interdisciplinary efforts to validate AI predictions with laboratory experiments will all be important. On the policy side, dialogues between scientists, legal experts, and ethicists should progress in parallel to update laws in step with scientific reality and to set guidelines for responsible AI use. There is also an educational component: as AI tools become more common in forensic labs and law enforcement, practitioners will need training to understand and correctly interpret AI outputs (for example, understanding confidence levels of an AI identification and the possibility of error).
In summary, AI offers a potent means to tame the chaos of an ever-evolving designer drug market. By leveraging computational power, we can predict the unpredictable and detect the undetectable. However, as this review emphasizes, vigilance is required to ensure that we are not simultaneously opening Pandora’s box. With thoughtful application and robust oversight, the benefits of AI in combating the challenges posed by NPSs can far outweigh the risks. The future likely holds an even deeper integration of AI into chemistry and public health, and with it, the hope that we can stay one step ahead in the ongoing battle against substance abuse and its associated harms.
Funding
This research received no external funding.
Conflicts of Interest
The author declares no conflicts of interest.
References
- Baumann, M.H.; Volkow, N.D. Abuse of New Psychoactive Substances: Threats and Solutions. Neuropsychopharmacology 2016, 41, 663–665. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Hill, S.L.; Thomas, S.H.L. Clinical Toxicology of Newer Recreational Drugs. Clin. Toxicol. 2011, 49, 705–719. [Google Scholar] [CrossRef] [Scilit]
- Reuter, P.; Pardo, B. New Psychoactive Substances: Are There Any Good Options for Regulating New Psychoactive Substances? Int. J. Drug Policy 2017, 40, 117–122. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wang, F.; Pasin, D.; Skinnider, M.A.; Liigand, J.; Kleis, J.N.; Brown, D.; Oler, E.; Sajed, T.; Gautam, V.; Harrison, S.; et al. Deep Learning-Enabled MS/MS Spectrum Prediction Facilitates Automated Identification of Novel Psychoactive Substances. Anal. Chem. 2023, 95, 18326–18334. [Google Scholar] [CrossRef] [Scilit]
- Varì, M.R.; Mannocchi, G.; Tittarelli, R.; Campanozzi, L.L.; Nittari, G.; Feola, A.; Ronchi, F.U.; Ricci, G. New Psychoactive Substances: Evolution in the Exchange of Information and Innovative Legal Responses in the European Union. Int. J. Environ. Res. Public Health 2020, 17, 8704. [Google Scholar] [CrossRef] [Scilit]
- Liu, D.; Liu, D.; Sheng, K.; Cheng, Z.; Liu, Z.; Qiao, Y.; Cai, S.; Li, Y.; Wang, J.; Chen, H.; et al. STNGS: A Deep Scaffold Learning-Driven Generation and Screening Framework for Discovering Potential Novel Psychoactive Substances. Brief. Bioinform. 2024, 26, bbae690. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Floresta, G.; Rescifina, A.; Abbate, V. Structure-Based Approach for the Prediction of Mu-Opioid Binding Affnity of Unclassified Designer Fentanyl-like Molecules. Int. J. Mol. Sci. 2019, 20, 2311. [Google Scholar] [CrossRef] [Scilit]
- Skinnider, M.A.; Wang, F.; Pasin, D.; Greiner, R.; Foster, L.J.; Dalsgaard, P.W.; Wishart, D.S. A Deep Generative Model Enables Automated Structure Elucidation of Novel Psychoactive Substances. Nat. Mach. Intell. 2021, 3, 973–984. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.; Jiang, Q.; Li, L.; Li, Z.; Xu, Z.; Chen, Y.; Sun, Y.; Liu, C.; Mao, Z.; Chen, F.; et al. Predicting the Structure of Unexplored Novel Fentanyl Analogues by Deep Learning Model. Brief. Bioinform. 2022, 23, bbac418. [Google Scholar] [CrossRef] [Scilit]
- Lee, W.; Park, S.J.; Hwang, J.Y.; Hur, K.H.; Lee, Y.S.; Kim, J.; Zhao, X.; Park, A.; Min, K.H.; Jang, C.G.; et al. QSAR Model for Predicting the Cannabinoid Receptor 1 Binding Affinity and Dependence Potential of Synthetic Cannabinoids. Molecules 2020, 25, 6057. [Google Scholar] [CrossRef] [Scilit]
- Floresta, G.; Cilibrizzi, A.; Abbate, V.; Spampinato, A.; Zagni, C.; Rescifina, A. 3D-QSAR Assisted Identification of FABP4 Inhibitors: An Effective Scaffold Hopping Analysis/QSAR Evaluation. Bioorg. Chem. 2019, 84, 276–284. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Floresta, G.; Cilibrizzi, A.; Abbate, V.; Spampinato, A.; Zagni, C.; Rescifina, A. FABP4 Inhibitors 3D-QSAR Model and Isosteric Replacement of BMS309403 Datasets. Data Br. 2019, 22, 471–483. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Awuchi, C.G.; Aja, M.P.; Mitaki, N.B.; Morya, S.; Amagwula, I.O.; Echeta, C.K.; Igwe, V.S. New Psychoactive Substances: Major Groups, Laboratory Testing Challenges, Public Health Concerns, and Community-Based Solutions. J. Chem. 2023, 2023, 5852315. [Google Scholar] [CrossRef] [Scilit]
- Cherkasov, A.; Muratov, E.N.; Fourches, D.; Varnek, A.; Baskin, I.I.; Cronin, M.; Dearden, J.; Gramatica, P.; Martin, Y.C.; Todeschini, R.; et al. QSAR Modeling: Where Have You Been? Where Are You Going To? J. Med. Chem. 2014, 57, 4977–5010. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wu, L.; Xiao, F.; Luo, X.; Yun, K.; Wen, D.; Lin, J.; Yang, S.; Li, T.; Xiang, P.; Shi, Y. Predicting the Retention Time of Synthetic Cannabinoids Using a Combinatorial QSAR Approach. Heliyon 2023, 9, e16671. [Google Scholar] [CrossRef] [Scilit]
- Ruttkies, C.; Schymanski, E.L.; Wolf, S.; Hollender, J.; Neumann, S. MetFrag Relaunched: Incorporating Strategies beyond in Silico Fragmentation. J. Cheminform. 2016, 8, 1–16. [Google Scholar] [CrossRef] [Scilit]
- Dührkop, K.; Fleischauer, M.; Ludwig, M.; Aksenov, A.A.; Melnik, A.V.; Meusel, M.; Dorrestein, P.C.; Rousu, J.; Böcker, S. SIRIUS 4: A Rapid Tool for Turning Tandem Mass Spectra into Metabolite Structure Information. Nat. Methods 2019, 16, 299–302. [Google Scholar] [CrossRef] [Scilit]
- Blaženović, I.; Kind, T.; Torbašinović, H.; Obrenović, S.; Mehta, S.S.; Tsugawa, H.; Wermuth, T.; Schauer, N.; Jahn, M.; Biedendieck, R.; et al. Comprehensive Comparison of in Silico MS/MS Fragmentation Tools of the CASMI Contest: Database Boosting Is Needed to Achieve 93% Accuracy. J. Cheminform. 2017, 9, 1–12. [Google Scholar] [CrossRef] [Scilit]
- Djoumbou-Feunang, Y.; Pon, A.; Karu, N.; Zheng, J.; Li, C.; Arndt, D.; Gautam, M.; Allen, F.; Wishart, D.S. Cfm-Id 3.0: Significantly Improved Esi-Ms/Ms Prediction and Compound Identification. Metabolites 2019, 9, 72. [Google Scholar] [CrossRef] [Scilit]
- Wang, F.; Liigand, J.; Tian, S.; Arndt, D.; Greiner, R.; Wishart, D.S. CFM-ID 4.0: More Accurate ESI-MS/MS Spectral Prediction and Compound Identification. Anal. Chem. 2021, 93, 11692–11700. [Google Scholar] [CrossRef] [Scilit]
- Mardal, M.; Andreasen, M.F.; Mollerup, C.B.; Stockham, P.; Telving, R.; Thomaidis, N.S.; Diamanti, K.S.; Linnet, K.; Dalsgaard, P.W. HighResNPS.Com: An Online Crowd-Sourced HR-MS Database for Suspect and Non-Targeted Screening of New Psychoactive Substances. J. Anal. Toxicol. 2019, 43, 520–527. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Davidsen, A.; Mardal, M.; Linnet, K.; Dalsgaard, P.W. How to Perform Spectrum-Based LC-HR-MS Screening for More than 1000 NPS with HighResNPS Consensus Fragment Ions. PLoS ONE 2020, 15, e0242224. [Google Scholar] [CrossRef] [Scilit]
- Swanson, K.D.; Shaner, R.L.; Krajewski, L.C.; Bragg, W.A.; Johnson, R.C.; Hamelin, E.I. Use of Diagnostic Ions for the Detection of Fentanyl Analogs in Human Matrices by LC-QTOF. J. Am. Soc. Mass Spectrom. 2021, 32, 2852–2859. [Google Scholar] [CrossRef] [Scilit]
- Tian, L.; Jiang, H.; Chen, T. A Rapid and Nondestructive Approach for Forensic Identification of Novel Psychoactive Substances Using Shifted-Excitation Raman Difference Spectroscopy and Machine Learning. J. Raman Spectrosc. 2023, 54, 540–550. [Google Scholar] [CrossRef] [Scilit]
- European Union. Directive-2017/2103-EN-EUR-Lex; European Union: Brussels, Belgium, 2017. [Google Scholar]
- EUDA. EUDA European Drug Report 2024: Trends and Developments; EUDA: Lisbon, Portugal, 2024; ISBN 9789291686940. [Google Scholar]
- Reuter, P.; Pardo, B. Can New Psychoactive Substances Be Regulated Effectively? An Assessment of the British Psychoactive Substances Bill. Addiction 2017, 112, 25–31. [Google Scholar] [CrossRef] [Scilit]
- Hill, R.G. Understanding the UK Psychoactive Substances Act. Br. J. Clin. Pharmacol. 2020, 86, 499–504. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Urbina, F.; Lentzos, F.; Invernizzi, C.; Ekins, S. Dual Use of Artificial-Intelligence-Powered Drug Discovery. Nat. Mach. Intell. 2022, 4, 189–191. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Sacco, N.L. Class-Wide Scheduling of Fentanyl-Related Substances (FRS)|Congress.Gov|Library of Congress. The Congress of the United States of America: Washington, DC, USA, 2025. [Google Scholar]
- National Research Council (US) Committee on Toxicology. Review of Acute Human-Toxicity Estimates for Selected Chemical-Warfare Agents; National Academies Press: Washington, DC, USA, 1997. [Google Scholar]
- Aroniadou-Anderjaska, V.; Apland, J.P.; Figueiredo, T.H.; De Araujo Furtado, M.; Braga, M.F. Acetylcholinesterase Inhibitors (Nerve Agents) as Weapons of Mass Destruction: History, Mechanisms of Action, and Medical Countermeasures. Neuropharmacology 2020, 181, 108298. [Google Scholar] [CrossRef] [Scilit]
- Ertl, P.; Schuffenhauer, A. Estimation of Synthetic Accessibility Score of Drug-like Molecules Based on Molecular Complexity and Fragment Contributions. J. Cheminform. 2009, 1, 8. [Google Scholar] [CrossRef] [Scilit]
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the author. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).