
Benchmarking Normative AI Assistants Under Inconsistent Evidence with Paraconsistent Trace Semantics

 ,
Abstract
1. Introduction
2. Related Work
2.1. RAG, Legal Reasoning Benchmarks, and Contract Datasets
2.2. Faithfulness, Hallucination, and Automated RAG Evaluation
2.3. Argumentation, Defeasible Reasoning, and Paraconsistent Logic
2.4. Reasoning-Oriented External Baselines
3. Problem Definition
4. Materials and Methods
4.1. Benchmarking Object: Post-Retrieval Normative Reasoning Assistant
4.2. Benchmark Scenario Schema
4.3. Paraconsistent Trace Graph
| Algorithm 1. Status computation for a proposition under trace and priority relations. |
| STATUS(p, T, P0): reject priority cycles; mark their comparisons unresolved P_plus:= transitive_closure(P0 after removing unresolved components) Args:= evidence-grounded arguments in T Att:= grounded attack edges after internal-target propagation Att_active:= {alpha in Att | not neutralized_by_priority(alpha, P_plus)} IN:= {A in Args | A has no incoming edge in Att_active} OUT:= {A in Args | some B in IN attacks A} repeat IN_new:= IN union {A | every active attacker of A is in OUT} OUT_new:= OUT union {A | some B in IN_new actively attacks A} IN, OUT:= IN_new, OUT_new until IN and OUT no longer change label every remaining argument UNDEC active_support:= exists A in IN with conc(A) = p active_attack:= exists A in IN with conc(A) = not(p) or exists B in IN actively attacking an argument for p map (active_support, active_attack) by Definition 5 The iteration starts from unattacked arguments and returns the least grounded labeling; mutual or odd attack cycles therefore remain UNDEC unless resolved by an external IN argument. |
4.4. Formal Trace Semantics
Design Rationale for the Paraconsistent Trace Semantics
4.5. Operational Semantics and Scoring Algorithms
| Algorithm 2. Scenario construction and annotation |
| Input: normative document set D, query q, target conclusion c 1. Select evidence fragments E relevant to q and c. 2. Annotate atomic facts F grounded in E. 3. Annotate defeasible rules R grounded in E. 4. Identify conflicts C between facts, rules, arguments, or conclusions. 5. Annotate priority relations P when exceptions, hierarchy, source authority, or specificity applies. 6. Compute expected status y in {accepted, rejected, both, undecidable} using STATUS. 7. Build gold trace T_gold linking E -> F -> R -> C/P -> y. Output: S = (q, E, F, R, C, P, y, T_gold). |
| Algorithm 3. Paraconsistent trace scoring |
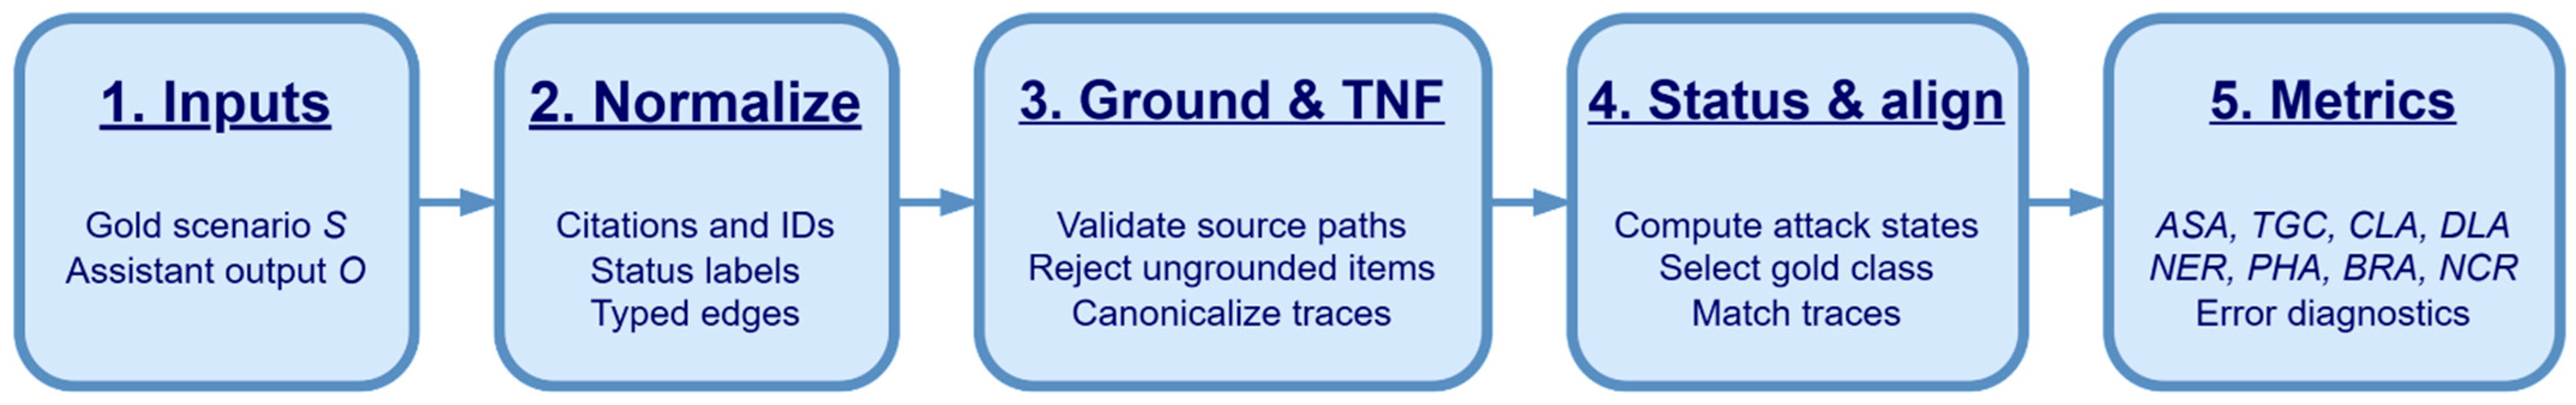
| Input: gold scenario S and assistant output O 1. Normalize assistant citations and extracted objects. 2. Convert assistant and gold traces to trace normal form. 3. Score mandatory grounded edges (TGC). 4. Score gold conflict cases (CLA) and controlled defect classes (DLA). 5. On gold-inconsistent scenarios I_gold, flag unsupported-unrelated outputs and compute NER. 6. Compare active/defeated attacks using lic(alpha), targetRules, and P_plus. 7. Compare predicted and gold status (ASA) and paired-update status (BRA). 8. Compute correctness-gated robustness. Output: M = (ASA, TGC, CLA, DLA, NER, PHA, BRA, NCR). |
| Algorithm 4. Mandatory-edge extraction, trace-normal-form alignment, and matching |
| Input: gold trace T_gold, assistant trace T_hat, evidence package E, target conclusion c 1. Canonicalize evidence identifiers, clause references, status labels, propositions, and typed attack targets. 2. Convert serialized attack records or provenance-event encodings to typed attack edges. 3. Reject any fact, rule, conflict, priority, attack, or proof object that lacks a valid source path to E. 4. Enumerate inclusion-minimal grounded subtraces of T_gold that reproduce the gold support/attack labels and status(c). 5. For each subtrace, retain required evidence, derivation, attack, priority/defeat, and status edges; merge duplicate derivations with identical semantic effects. 6. Represent alternative minimal subtraces with the same semantic effect as an equivalence class M(T_gold,c). 7. Map assistant edges to gold edges when node/edge types, grounded source fragments, semantic relations, attack targets, active/defeated states, and STATUS effects match. 8. Select the admissible gold set with minimum edit distance to TNF(T_hat); resolve ties by canonical edge-identifier order. 9. Credit one matched assistant edge per required gold equivalence class and retain unsupported edges for diagnostic error analysis. Output: selected mandatory gold edge set, matched edges, missing edges, and unsupported assistant edges. |
| Algorithm 5. Operational unsupported-conclusion and NCR scoring |
| Input: gold scenario S, normalized assistant trace TNF(T_hat), target c, finite edit set Delta_N 1. Use the gold contradiction flag to determine membership in I_gold. 2. Mark emitted non-required z as unsupported when no evidence-grounded argument concludes z. 3. Compute NER on I_gold; record UUCR diagnostically. 4. Enumerate fact, rule, exception, priority-edge, and attack-edge edits in Delta_N. 5. Use unit cost for every atomic edit in the reported experiments. 6. Search edit sets in non-decreasing cost and canonical lexicographic order; recompute TNF and STATUS. 7. Let d_N be the first cost that flips status; if no admissible edit flips it, right-censor at |Delta_N| + 1. 8. Set NCR_case = 0 when the original predicted status is wrong; otherwise use d_N or the right-censor value. 9. Report the arithmetic mean of NCR_case over the stated evaluation split. Output: NER/UUCR diagnostics, raw d_N witnesses, and the correctness-gated NCR score. |
4.6. Assistant Configurations, Baselines, and Evidence Access
4.6.1. Implementation Details of Baselines
4.6.2. External Reasoning Baselines
5. Benchmark Metrics
6. Controlled and External Validation
6.1. Controlled Validation
6.2. Access Conditions and Controlled Results
6.3. External Real-World Validation
6.4. Statistical Reliability and Cross-Model Validation
6.5. Prompt-Fairness, Repeated-Run Stability, and Efficiency Controls
6.6. Deterministic Component-Dependency Audit
6.7. Example Scenario
7. Reproducibility Package
8. Discussion
9. Conclusions
Author Contributions
Funding
Institutional Review Board Statement
Informed Consent Statement
Data Availability Statement
Acknowledgments
Conflicts of Interest
Appendix A. Model Provenance and Inference Settings
Appendix A.1. Run Dates
Appendix A.2. Execution Environment
Appendix A.3. Model Identifiers
Appendix A.4. Generation Parameters
Appendix A.5. Runs
Appendix A.6. Prompting Strategy
Appendix A.7. Evidence Access Constraints
Appendix A.8. Output Handling and Scoring
Appendix A.9. Repository
Appendix B. Case Walkthroughs for Trace-Aware Scoring

| Layer | Gold Object | Expected Assistant Behavior | Primary Metric Pressure |
|---|---|---|---|
| Query | Can the buyer claim a contractual penalty for late delivery? | Return a status and expose the support/attack/defeat path rather than citing only the penalty clause. | ASA, TGC |
| Evidence | Penalty clause, force-majeure clause, notification clause, gross-negligence exception. | Link every extracted fact and rule to an evidence fragment and clause-level identifier. | TGC |
| Facts/rules | Delay(x); ForceMajeure(x); GrossNegligence(x); r1: Delay -> Penalty; r2: ForceMajeure -> not Penalty; r3: GrossNegligence defeats force majeure. | Extract the competing rules without deleting the exception. | TGC, CLA |
| Conflict/priority | r2 attacks Penalty(x); r3 > r2 deactivates the attack for status computation. | Preserve the attack edge and mark it as defeated by priority. | CLA, PHA |
| Gold status | accepted | Conclude accepted only after showing that the force-majeure attack is preserved and then defeated. | ASA, NER, NCR |
| Layer | Gold Object | Expected Assistant Behavior | Primary Metric Pressure |
|---|---|---|---|
| Query | Must the guarantor pay under a demand that was submitted after an amended deadline? | Return a status that accounts for the original deadline, the addendum, and the formal demand requirements. | ASA |
| Evidence | Original guarantee text, later addendum, demand notice, receipt log, and template clause with inconsistent numbering. | Normalize old and new clause identifiers without losing the amended deadline. | TGC |
| Facts/rules | DemandReceived(x); SubmittedAfterOriginalDeadline(x); AddendumExtendsDeadline(x); DemandFormIncomplete(x). | Distinguish a timing conflict from a form-defect conflict. | CLA |
| Conflict/priority | Addendum priority over original deadline; mandatory form requirement remains independently active. | Apply temporal/document-version priority while keeping the form attack active. | PHA |
| Gold status | both or undecidable depending on form evidence completeness | Avoid collapsing the case into a simple payable/not-payable answer when one attack is resolved and another remains evidentially incomplete. | ASA, NER, BRA |
| Layer | Gold Object | Expected Assistant Behavior | Primary Metric Pressure |
|---|---|---|---|
| Query | Was emergency access to a restricted system permissible without prior manager approval? | Return a status and identify whether the emergency exception overrides the ordinary approval rule. | ASA, PHA |
| Evidence | Access-control policy, emergency-access appendix, incident ticket, post-fact approval record, and audit-log excerpt. | Ground the ordinary prohibition, the exception, and the post-fact reporting duty separately. | TGC |
| Facts/rules | RestrictedAccess(x); NoPriorApproval(x); EmergencyIncident(x); PostFactApprovalLogged(x); r1: no prior approval -> prohibited; r2: emergency incident -> permitted; r3: post-fact logging required. | Represent permission and prohibition as competing normative conclusions rather than rewriting one away. | CLA |
| Conflict/priority | Emergency exception defeats ordinary prior-approval prohibition only if incident and post-fact logging are both grounded. | Use exception priority conditionally; do not infer general permission for unrelated accesses. | PHA, NER |
| Gold status | accepted if both emergency and post-fact logging are grounded; otherwise both or undecidable | Revise the status if the post-fact approval record is removed or contradicted. | BRA, NCR |
Appendix C. Trace-Normal-Form Equivalence Examples
Appendix C.1. Equivalent Direct and Transport-Level Attack Encodings
Appendix C.2. Equivalent Proof-Chain Variants
Appendix C.3. Non-Equivalent Trace
Appendix C.4. Computational Scope
Appendix C.5. NCR Cost-Sensitivity Example
Appendix D. External Corpus and Annotation Protocol
Appendix D.1. Retained Corpus Audit Fields
Appendix D.2. Annotation and Adjudication Checklist
References
- Lewis, P.; Perez, E.; Piktus, A.; Petroni, F.; Karpukhin, V.; Goyal, N.; Küttler, H.; Lewis, M.; Yih, W.; Rocktäschel, T.; et al. Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks. Adv. Neural Inf. Process. Syst. 2020, 33, 9459–9474. [Google Scholar]
- Gao, Y.; Xiong, Y.; Gao, X.; Jia, K.; Pan, J.; Bi, Y.; Dai, Y.; Sun, J.; Wang, M.; Wang, H. Retrieval-Augmented Generation for Large Language Models: A Survey. arXiv 2024, arXiv:2312.10997. [Google Scholar] [CrossRef] [Scilit]
- Barnett, S.; Kurniawan, S.; Thudumu, S.; Brannelly, Z.; Abdelrazek, M. Seven Failure Points When Engineering a Retrieval Augmented Generation System. In Proceedings of the IEEE/ACM 3rd International Conference on AI Engineering, Lisbon, Portugal, 14–15 April 2024. [Google Scholar] [CrossRef] [Scilit]
- Guha, N.; Nyarko, J.; Ho, D.; Re, C.; Chilton, A.; Chohlas-Wood, A.; Peters, A.; Waldon, B.; Rockmore, D.; Zambrano, D.; et al. LegalBench: A Collaboratively Built Benchmark for Measuring Legal Reasoning in Large Language Models. In Proceedings of the Neural Information Processing Systems, New Orleans, LA, USA, 10–16 December 2023. [Google Scholar]
- Pipitone, N.; Houir Alami, G. LegalBench-RAG: A Benchmark for Retrieval-Augmented Generation in the Legal Domain. arXiv 2024, arXiv:2408.10343. [Google Scholar] [CrossRef] [Scilit]
- Zheng, L.; Guha, N.; Arifov, J.; Zhang, S.; Skreta, M.; Manning, C.D.; Henderson, P.; Ho, D.E. A Reasoning-Focused Legal Retrieval Benchmark. In Proceedings of the 2025 Symposium on Computer Science and Law, Munich, Germany, 25–27 March 2025; pp. 169–193. [Google Scholar] [CrossRef] [Scilit]
- Magesh, V.; Surani, F.; Dahl, M.; Suzgun, M.; Manning, C.D.; Ho, D.E. Hallucination-Free? Assessing the Reliability of Leading AI Legal Research Tools. J. Empir. Leg. Stud. 2025, 22, 216–242. [Google Scholar] [CrossRef] [Scilit]
- Koreeda, Y.; Manning, C.D. ContractNLI: A Dataset for Document-level Natural Language Inference for Contracts. In Findings of the Association for Computational Linguistics: EMNLP 2021; Association for Computational Linguistics: Stroudsburg, PA, USA, 2021; pp. 1907–1919. [Google Scholar] [CrossRef] [Scilit]
- Hendrycks, D.; Burns, C.; Chen, A.; Ball, S. CUAD: An Expert-Annotated NLP Dataset for Legal Contract Review. In Proceedings of the Neural Information Processing Systems (NeurIPS) Datasets and Benchmarks Track, Virtual, 5–14 December 2021. [Google Scholar]
- Wang, S.H.; Scardigli, A.; Tang, L.; Chen, W.; Levkin, D.; Chen, A.; Ball, S.; Woodside, T.; Zhang, O.; Hendrycks, D. MAUD: An Expert-Annotated Legal NLP Dataset for Merger Agreement Understanding. In Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing; Association for Computational Linguistics: Stroudsburg, PA, USA, 2023; pp. 16369–16382. [Google Scholar] [CrossRef] [Scilit]
- Jacovi, A.; Goldberg, Y. Towards Faithfully Interpretable NLP Systems: How Should We Define and Evaluate Faithfulness? In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, Online, 5–10 July 2020; pp. 4198–4205. [Google Scholar] [CrossRef] [Scilit]
- Maynez, J.; Narayan, S.; Bohnet, B.; McDonald, R. On Faithfulness and Factuality in Abstractive Summarization. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, Online, 5–10 July 2020; pp. 1906–1919. [Google Scholar] [CrossRef] [Scilit]
- Es, S.; James, J.; Espinosa-Anke, L.; Schockaert, S. RAGAS: Automated Evaluation of Retrieval Augmented Generation. In Proceedings of the European Chapter of the Association for Computational Linguistics: System Demonstrations; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024. [Google Scholar]
- Saad-Falcon, J.; Khattab, O.; Potts, C.; Zaharia, M. ARES: An Automated Evaluation Framework for Retrieval-Augmented Generation Systems. arXiv 2023, arXiv:2311.09476. [Google Scholar] [CrossRef] [Scilit]
- Dung, P.M. On the Acceptability of Arguments and Its Fundamental Role in Nonmonotonic Reasoning, Logic Programming and n-Person Games. Artif. Intell. 1995, 77, 321–357. [Google Scholar] [CrossRef] [Scilit]
- Baroni, P.; Caminada, M.; Giacomin, M. An Introduction to Argumentation Semantics. Knowl. Eng. Rev. 2011, 26, 365–410. [Google Scholar] [CrossRef] [Scilit]
- Prakken, H.; Sartor, G. Argument-Based Extended Logic Programming with Defeasible Priorities. J. Appl. Non-Class. Log. 1997, 7, 25–75. [Google Scholar] [CrossRef] [Scilit]
- Gordon, T.F.; Prakken, H.; Walton, D. The Carneades Model of Argument and Burden of Proof. Artif. Intell. 2007, 171, 875–896. [Google Scholar] [CrossRef] [Scilit]
- Belnap, N.D. A Useful Four-Valued Logic. In Modern Uses of Multiple-Valued Logic; Dunn, J.M., Epstein, G., Eds.; Springer: Dordrecht, The Netherlands, 1977; pp. 5–37. [Google Scholar]
- Priest, G.; Tanaka, K.; Weber, Z. Paraconsistent Logic. In Stanford Encyclopedia of Philosophy; Metaphysics Research Lab, Stanford University: Stanford, CA, USA, 2024. [Google Scholar]
- Edge, D.; Trinh, H.; Cheng, N.; Bradley, J.; Chao, A.; Mody, A.; Truitt, S.; Larson, J. From Local to Global: A Graph RAG Approach to Query-Focused Summarization. arXiv 2024, arXiv:2404.16130. [Google Scholar] [CrossRef] [Scilit]
- Yao, S.; Zhao, J.; Yu, D.; Du, N.; Shafran, I.; Narasimhan, K.; Cao, Y. ReAct: Synergizing Reasoning and Acting in Language Models. In Proceedings of the 11th International Conference on Learning Representations (ICLR), Kigali, Rwanda, 1–5 May 2023. [Google Scholar]
- Madaan, A.; Tandon, N.; Gupta, P.; Hallinan, S.; Gao, L.; Wiegreffe, S.; Alon, U.; Dziri, N.; Prabhumoye, S.; Yang, Y.; et al. Self-Refine: Iterative Refinement with Self-Feedback. arXiv 2023, arXiv:2303.17651. [Google Scholar] [CrossRef] [Scilit]
- Yao, S.; Yu, D.; Zhao, J.; Shafran, I.; Griffiths, T.L.; Cao, Y.; Narasimhan, K. Tree of Thoughts: Deliberate Problem Solving with Large Language Models. In Proceedings of the 36th Annual Conference on Neural Information Processing Systems (NeurIPS), New Orleans, LA, USA, 10–16 December 2023. [Google Scholar]
- Khattab, O.; Singhvi, A.; Maheshwari, P.; Zhang, Z.; Santhanam, K.; Haq, S.; Sharma, A.; Joshi, T.T.; Moazam, H.; Miller, H.; et al. DSPy: Compiling Declarative Language Model Calls into Self-Improving Pipelines. In Proceedings of the 12th International Conference on Learning Representations (ICLR), Vienna, Austria, 7–11 May 2024. [Google Scholar]
- Moreau, L.; Missier, P. PROV-DM: The PROV Data Model; W3C Recommendation; World Wide Web Consortium (W3C): Cambridge, MA, USA, 2013. [Google Scholar]
- Tabassi, E. Artificial Intelligence Risk Management Framework (AI RMF 1.0); NIST AI 100-1; National Institute of Standards and Technology: Gaithersburg, MD, USA, 2023. [CrossRef] [Scilit]

| Benchmark/Framework | Primary Evaluation Target | Main Unit of Annotation | What It Does Not Evaluate Directly | ParaTraceBench Complement |
|---|---|---|---|---|
| LegalBench [4] | General legal reasoning ability of LLMs | Task instance and answer label | Grounded contradiction localization, priority defeat, non-explosion, and gold diagnostic traces | Adds trace-level evaluation under inconsistent normative evidence |
| LegalBench-RAG [5] | Precise retrieval for legal RAG | Query and relevant legal snippets | Whether a retrieved contradiction is preserved and normatively resolved | Adds conflict, priority, status, and revision scoring after retrieval |
| ContractNLI [8] | Contractual natural-language inference | Contract, hypothesis, entailment/contradiction/not-mentioned label | Defeasible rule priority, exception defeat, and assistant trace diagnostics | Connects contractual evidence to explicit facts, rules, attacks, and statuses |
| CUAD [9] | Contract clause extraction | Clause category spans | Normative conclusion status under conflicting clauses | Uses extracted clauses as evidence fragments for trace-based reasoning |
| MAUD [10] | Merger agreement understanding and clause extraction | Expert-labeled agreement provisions | Contradiction-aware assistant behavior and belief revision | Extends clause understanding toward normative conflict evaluation |
| RAGAS [11] | Automated RAG evaluation | Question, context, answer, faithfulness/relevance scores | Gold conflict traces, priority handling, and non-explosion | Adds contradiction-specific diagnostic metrics to RAG evaluation |
| ARES [12] | Automated RAG evaluation and scoring | RAG outputs and evaluator models | Deterministic graph comparison against facts, rules, conflicts, and priorities | Adds structured, auditable scoring for inconsistent evidence cases |
| ParaTraceBench | Normative assistant behavior under inconsistent and defeasible evidence | Query, evidence, facts, rules, conflicts, priorities, status, gold trace | Not a substitute for domain-specific expert judgment | Provides contradiction-aware framework and controlled validation protocol |
| Field | Description | Example in Normative Reasoning | Evaluation Role |
|---|---|---|---|
| query | User question to the assistant | Can an organization impose a penalty despite a force majeure claim? | Defines target normative issue |
| evidence_fragments | Legal, contractual, policy, regulatory, or ethical text spans | Penalty clause; force majeure clause; internal policy exception | Grounds facts and rules |
| facts | Atomic propositions extracted from evidence | Delay, NoticeSent, ConsentObtained, SafetyRisk | Input to formal reasoning |
| rules | Extracted legal, policy, contractual, or ethical rules | Delay implies penalty; safety exception overrides permission | Defines defeasible normative reasoning structure |
| conflicts | Explicit attacks or inconsistent propositions | Rule permits action; another rule prohibits it | Tests contradiction preservation |
| priorities | Priority relations between rules or sources | Specific policy overrides general guideline; later rule overrides earlier rule | Tests defeasible reasoning |
| expected_status | Expected normative status | accepted, rejected, both, undecidable | Target for answer-status scoring |
| gold_trace | Gold diagnostic trace | Evidence -> fact -> rule -> conflict -> priority -> status | Enables trace-level scoring |
| Configuration | Capabilities | Inference Input | Withheld During Inference | Expected Weakness Under Inconsistency |
|---|---|---|---|---|
| B1: citation-only baseline | Answer generation and source citation over the supplied evidence package | q + identical evidence fragments E | F, R, C, P, y, T_gold, defect labels | May cite a relevant source while ignoring exceptions or conflicts |
| B2: self-checking baseline | Citation-based answering plus a self-check for missing evidence and contradictions | q + identical evidence fragments E | F, R, C, P, y, T_gold, defect labels | May verbalize conflicts but fail to preserve deterministic diagnostic trace |
| B3: structured extraction | Extracts facts and rules before answering | q + identical evidence fragments E | F, R, C, P, y, T_gold, defect labels | May detect rules but lose the path needed for localization |
| B4: trace-based assistant | Extracts facts, rules, conflicts, priorities, status, and diagnostic trace | q + identical evidence fragments E | F, R, C, P, y, T_gold, defect labels | Designed to support localization, priority handling, and non-explosion but can still fail when evidence or priority cues are underspecified |
| Baseline | Operational Adaptation in This Study | Evidence Access | Expected Limitation Under ParaTraceBench |
|---|---|---|---|
| LegalBench-RAG-style | Answer with legal-style retrieval grounding and final status; no required conflict graph | q + identical E | Can retrieve/cite relevant clauses but may not preserve conflict and priority structure |
| GraphRAG-style evidence graph | Builds an evidence-level entity/relation graph before answer generation | q + identical E | Improves cross-fragment linking but does not by itself compute attack/defeat status |
| ReAct-style | Interleaves reasoning steps and evidence inspection actions before final status | q + identical E | May reason over exceptions but trace steps are not mandatory graph objects |
| Self-Refine-style | Initial answer, self-feedback for missing exceptions/conflicts, then revised answer | q + identical E | Can correct some omissions but may rationalize rather than localize conflict |
| Tree-of-Thought-style | Generates several candidate normative paths and selects one by self-evaluation | q + identical E | Explores alternatives but may collapse both-supported-and-attacked cases into a single path |
| DSPy-style structured pipeline | Composable extraction, checking, and answer modules optimized to the metric prompt | q + identical E | Improves structure but lacks explicit paraconsistent status and priority-defeat semantics unless added |
| Metric | Formula or Definition | What It Evaluates |
|---|---|---|
| Answer Status Accuracy (ASA) | N(correct status)/N(all) | Whether the assistant selects the correct normative conclusion status |
| Trace Grounding Completeness (TGC) | verified mandatory TNF edges/mandatory gold TNF edges | Grounded required trace edges; equivalent derivation paths are accepted |
| Contradiction Localization Accuracy (CLA) | N(correct conflict layer)/N(conflict cases) | Whether the assistant identifies the source of inconsistency |
| Operational Non-Explosion Rate (NER) | 1 − N(inconsistent cases with unsupported-unrelated conclusions)/N(inconsistent cases) | Output-level avoidance of unsupported unrelated conclusions under inconsistency; not a proof of logical explosion resistance |
| Priority Handling Accuracy (PHA) | N(correct priority application)/N(priority cases) | Whether exceptions and priority rules are applied correctly |
| Belief Revision Accuracy (BRA) | N(correct revised status)/N(update cases) | Whether the assistant revises its answer under new evidence |
| Normative Conclusion Robustness (NCR) | Mean correctness-gated minimum edit cost; wrong status = 0; no-flip case = |Delta_N| + 1 | Correctness-conditioned semantic status robustness under the stated finite edit set |
| Defect Localization Accuracy (DLA) | N(correct injected defect class)/N(defective controlled cases) | Controlled-suite localization of injected pipeline defects; not used as external CLA |
| Scenario Class | Number of Cases | Injected Defect | Expected Benchmark Signal |
|---|---|---|---|
| No defect | 20 | None | Accepted trace and correct status |
| Missing evidence fragment | 20 | Relevant clause or norm removed | Low grounding and missing coverage |
| Incomplete query coverage | 20 | One target element omitted | Lower trace completeness and possible unsupported status |
| Extraction error | 20 | Fact or rule incorrectly extracted | Grounding or rule consistency failure |
| Priority inversion | 20 | Defeasible priority reversed | Conflict-preservation failure; operational NER decreases only if unsupported outputs are also emitted |
| Attack edge deletion | 20 | Conflict relation removed | Contradiction preservation and operational unsupported-conclusion failure |
| Invalid proof node | 20 | Unsupported node added to trace | Trace validation failure |
| Method | Answer Status Accuracy | Defect Localization Accuracy (DLA) | Operational Unsupported-Conclusion Evaluation |
|---|---|---|---|
| B1: citation-only baseline (gpt-5.2-2025-12-11) | 28.6% (40/140) | 0% (0/120) | Not explicit |
| B2: self-checking baseline (gpt-5.2-2025-12-11) | 61.4% (86/140) | 43.3% (52/120) | Self-check only |
| B3: structured extraction (gpt-5.2-2025-12-11) | 76.4% (107/140) | 66.7% (80/120) | Partial |
| B4: trace-based assistant (gpt-5.2-2025-12-11) | 98.6% (138/140) | 90.8% (109/120) | Explicit |
| Gold Status/Predicted Status | Accepted | Rejected | Both | Undecidable | Row Total |
|---|---|---|---|---|---|
| accepted | 39 | 0 | 1 | 0 | 40 |
| rejected | 0 | 35 | 0 | 0 | 35 |
| both | 0 | 0 | 34 | 1 | 35 |
| undecidable | 0 | 0 | 0 | 30 | 30 |
| column total | 39 | 35 | 35 | 31 | 140 |
| Case Identifier | Gold Status | B4 Output Status | Failure Mechanism | Affected Metrics |
|---|---|---|---|---|
| CV-P20-07 | accepted | both | The assistant extracted both the penalty rule and force majeure attack, but did not activate the gross-negligence priority r3 > r2. The conflict was preserved, but the attack was not defeated. | ASA, PHA, NCR |
| CV-AE-14 | both | undecidable | The assistant detected an attack edge but failed to ground the supporting rule in an evidence fragment after normalization. The strict scorer rejected the unsupported support path. | ASA, TGC, DLA |
| Defect Class | Cases | Correctly Localized by B4 | Localization Rate | Common Residual Failure |
|---|---|---|---|---|
| Missing evidence fragment | 20 | 19 | 95% | One case was reported as incomplete query coverage because the missing fragment also removed a target element. |
| Incomplete query coverage | 20 | 18 | 90% | Two cases were treated as missing support rather than omitted target coverage. |
| Extraction error | 20 | 19 | 95% | One fact/rule extraction error was hidden by a compensating but overly general rule. |
| Priority inversion | 20 | 17 | 85% | Three cases preserved the conflict but did not identify the direction of the priority inversion. |
| Attack edge deletion | 20 | 18 | 90% | Two cases were classified as undecidable rather than conflict-preservation failures. |
| Invalid proof node | 20 | 18 | 90% | Two unsupported proof nodes were removed during normalization, reducing explicit defect visibility. |
| Total defective cases | 120 | 109 | 90.8% | Residual errors are concentrated in priority direction and boundary cases between missing evidence and incomplete coverage. |
| Source Type | Cases | Share | Sampling/Inclusion Role |
|---|---|---|---|
| Contracts | 124 | 21.9% | Contractual duties, penalties, exceptions, addenda, and clause conflicts |
| Banking guarantees | 101 | 17.8% | Demand-form requirements, deadlines, independence-principle interactions, amended terms |
| Compliance | 112 | 19.8% | Internal and regulatory compliance duties, sanctions, disclosures, ownership and threshold ambiguity |
| Internal policies | 120 | 21.2% | Policy hierarchy, emergency exceptions, approvals, audit and access-control conflicts |
| Regulatory/legal materials | 110 | 19.4% | Regulatory triggers, statutory or quasi-statutory norms, EAEU-related cross-source conflicts |
| Total | 567 | 100.0% total; displayed category shares sum to 100.1% because of one-decimal rounding | Expert-selected contradiction-rich and trace-annotated external validation corpus |
| Metric | B1: Citation-Only | B2: Self-Check | B3: Structured Extraction | B4: Trace-Based |
|---|---|---|---|---|
| ASA | 29.5% (167/567) | 57.1% (324/567) | 73.4% (416/567) | 85.7% (486/567) |
| TGC | 8.0% | 33.1% | 63.0% | 86.1% |
| CLA | 12.1% (50/414) | 46.9% (194/414) | 65.7% (272/414) | 85.5% (354/414) |
| NER | 44.9% (186/414) | 67.1% (278/414) | 79.0% (327/414) | 94.2% (390/414) |
| PHA | 10.7% (23/214) | 36.4% (78/214) | 62.1% (133/214) | 84.1% (180/214) |
| BRA | 29.2% (52/178) | 57.3% (102/178) | 70.8% (126/178) | 83.7% (149/178) |
| NCR | 0.9 | 1.5 | 2.2 | 3.5 |
| Method | ASA | CLA | NER | PHA | BRA |
|---|---|---|---|---|---|
| LegalBench-RAG-style | 63.1% (358/567) | 50.0% (207/414) | 72.2% (299/414) | 42.5% (91/214) | 58.4% (104/178) |
| GraphRAG-style evidence graph | 74.3% (421/567) | 67.1% (278/414) | 83.6% (346/414) | 62.1% (133/214) | 67.4% (120/178) |
| ReAct-style | 68.3% (387/567) | 56.3% (233/414) | 76.6% (317/414) | 52.3% (112/214) | 63.5% (113/178) |
| Self-Refine-style | 72.0% (408/567) | 61.4% (254/414) | 81.2% (336/414) | 58.4% (125/214) | 66.3% (118/178) |
| Tree-of-Thought-style | 73.7% (418/567) | 64.5% (267/414) | 82.9% (343/414) | 60.7% (130/214) | 69.1% (123/178) |
| DSPy-style structured pipeline | 77.1% (437/567) | 69.6% (288/414) | 85.5% (354/414) | 65.9% (141/214) | 71.9% (128/178) |
| B4 trace-based reference | 85.7% (486/567) | 85.5% (354/414) | 94.2% (390/414) | 84.1% (180/214) | 83.7% (149/178) |
| Case ID | Domain | Gold Status | B4 Status | Failure Mechanism | Affected Metrics |
|---|---|---|---|---|---|
| CN-002 | Contracts | both | accepted | A support edge was rejected after evidence-ID normalization because the citation used the old appendix number. | ASA; TGC/CLA/PHA/NCR depending on edge |
| BG-007 | Banking guarantees | accepted | undecidable | A support edge was rejected after evidence-ID normalization because the citation used the old appendix number. | ASA; TGC/CLA/PHA/NCR depending on edge |
| CP-004 | Compliance | accepted | both | The exception was identified, but the burden-of-proof node was attached to the wrong party. | ASA; TGC/CLA/PHA/NCR depending on edge |
| IP-001 | Internal policy | accepted | undecidable | A support edge was rejected after evidence-ID normalization because the citation used the old appendix number. | ASA; TGC/CLA/PHA/NCR depending on edge |
| RL-015 | Regulatory/legal | undecidable | rejected | A conflict was localized at document level, not at the clause level required by the scorer. | ASA; TGC/CLA/PHA/NCR depending on edge |
| Validation Item | Result | Scope | Interpretation |
|---|---|---|---|
| Cohen kappa: conclusion status | 0.84 | 567 cases | substantial-to-near-perfect agreement |
| Krippendorff alpha: conclusion status | 0.82 | 567 cases | stable status annotation |
| Cohen kappa: conflict layer | 0.80 | 414 contradiction cases | substantial agreement |
| Cohen kappa: priority relation | 0.76 | 214 priority cases | hardest label; acceptable after adjudication |
| Evidence-span alignment F1 | 0.88 | all evidence fragments | high but affected by OCR and boundary noise |
| ASA 95% CI by baseline | B1 [25.8;33.3], B2 [53.0;61.2], B3 [69.6;76.8], B4 [82.6;88.4] | 567 cases | Wilson intervals for case-level status correctness |
| CLA 95% CI by baseline | B1 [9.3;15.6], B2 [42.1;51.7], B3 [61.0;70.1], B4 [81.8;88.6] | 414 contradiction cases | Wilson intervals for conflict localization |
| NER 95% CI by baseline | B1 [40.2;49.7], B2 [62.5;71.5], B3 [74.8;82.6], B4 [91.5;96.1] | 414 contradiction cases | Wilson intervals for non-explosion |
| PHA 95% CI by baseline | B1 [7.3;15.6], B2 [30.3;43.1], B3 [55.5;68.4], B4 [78.6;88.4] | 214 priority cases | Wilson intervals for priority handling |
| BRA 95% CI by baseline | B1 [23.0;36.3], B2 [50.0;64.3], B3 [63.7;77.0], B4 [77.6;88.4] | 178 paired update cases | Wilson intervals for belief revision |
| B4 TGC 95% CI | [84.3;87.8] | edge-level bootstrap | reported for trace-grounding completeness |
| B4 vs. B3 ASA | BH-adjusted q < 0.001; +12.3 pp | 137 B4-only correct vs. 67 B3-only correct | McNemar paired comparison |
| B4 vs. B3 CLA | BH-adjusted q < 0.001; +19.8 pp | 414 contradiction cases | paired improvement after correction |
| B4 vs. B3 NER | BH-adjusted q < 0.001; +15.2 pp | 414 contradiction cases | paired improvement in operational unsupported-conclusion avoidance |
| B4 vs. B3 PHA | BH-adjusted q < 0.001; +22.0 pp | 214 priority cases | paired improvement after correction |
| B4 vs. B3 BRA | BH-adjusted q = 0.006; +12.9 pp | 178 update pairs | paired improvement after correction |
| Multiple-comparison correction | Benjamini–Hochberg q = 0.05 | ASA, CLA, NER, PHA, BRA | all five B4-vs-B3 claims remain significant |
| Model Family/Snapshot Used in April 2026 Runs | ASA | CLA | NER | PHA | BRA |
|---|---|---|---|---|---|
| GPT-family (gpt-5.2-2025-12-11) | 85.7% (486/567) | 85.5% (354/414) | 94.2% (390/414) | 84.1% (180/214) | 83.7% (149/178) |
| Claude-family (claude-opus-4-20250514) | 82.5% (468/567) | 82.4% (341/414) | 90.3% (374/414) | 80.4% (172/214) | 80.9% (144/178) |
| Gemini-family (gemini-2.5-pro) | 76.5% (434/567) | 75.8% (314/414) | 84.3% (349/414) | 75.7% (162/214) | 75.3% (134/178) |
| Llama-family (llama-4-maverick-17b-128e-instruct) | 69.7% (395/567) | 69.6% (288/414) | 76.6% (317/414) | 68.2% (146/214) | 67.4% (120/178) |
| Configuration | Few-Shot | Output Schema | ASA | CLA | NER | PHA | BRA |
|---|---|---|---|---|---|---|---|
| B3-standard | 0 | common-v1 | 67.6 ± 3.5 | 64.1 ± 7.0 | 78.6 ± 3.2 | 62.1 ± 4.8 | 67.7 ± 4.0 |
| B3-five-shot | 5 | common-v1 | 74.2 ± 5.4 | 69.9 ± 3.2 | 84.7 ± 3.6 | 74.7 ± 8.2 | 68.4 ± 7.7 |
| B4-zero-shot | 0 | trace-v2 + common-v1 | 79.4 ± 3.2 | 83.3 ± 4.2 | 92.9 ± 2.5 | 76.8 ± 6.3 | 80.7 ± 7.9 |
| B4-compact | 5 | trace-v2 + common-v1 | 85.2 ± 4.3 | 84.1 ± 4.5 | 91.8 ± 2.9 | 79.5 ± 4.7 | 76.8 ± 4.2 |
| B4-standard | 5 | trace-v2 + common-v1 | 83.2 ± 3.3 | 90.4 ± 4.5 | 94.5 ± 3.5 | 79.0 ± 6.5 | 89.0 ± 6.7 |
| Split/Configuration | ASA Mean ± SD | Same Status, All 5 Runs | Mean Pairwise Status Agreement | Median/p95 Latency, s | Mean Input/Output Tokens | Valid JSON/Repaired/Hard Failure |
|---|---|---|---|---|---|---|
| controlled_140/B3-standard | 77.0 ± 3.4% | 31.4% | 61.9% | 5.105/5.804 | 3367/561 | 97.29%/2.71%/0% |
| controlled_140/B4-standard | 87.9 ± 3.0% | 53.6% | 78.1% | 8.294/9.141 | 7628/1082 | 95.14%/4.71%/0.14% |
| external_100/B3-standard | 67.6 ± 3.5% | 19.0% | 51.0% | 5.437/6.233 | 4142/562 | 98.20%/1.80%/0% |
| external_100/B4-standard | 83.2 ± 3.3% | 43.0% | 70.9% | 8.668/9.583 | 8407/1087 | 97.60%/2.40%/0% |
| Audit Variant | Deterministic Transformation | Status Effect | Directly Affected Metrics | Permitted Interpretation |
|---|---|---|---|---|
| Full representation | None | Defined | All metrics defined | Dependency map only; not a causal ablation |
| No priority/defeat edges | Keep every grounded attack active | May change | TGC lacks priority edges; PHA unavailable; BRA may change | Tests dependence on explicit priority/defeat relations |
| No conflict/attack edges | Remove typed attacks from the normalized trace | May change | TGC lacks attacks; CLA and PHA unavailable; BRA may change | Tests conflict and defeat observability |
| No operational NER scorer | Skip the unsupported-output check | Unchanged | NER unavailable; all other metrics unchanged | Diagnostic removal cannot change model status |
| No TNF alignment | Require exact canonical edge identity | Unchanged | TGC, CLA, and PHA may under-credit equivalent traces | Tests matching dependence, not assistant reasoning |
| No trace graph | Observe only answer, citations, facts, and rules | Answer status observable | Trace metrics partial or unavailable; BRA remains observable | Not equivalent to an independently prompted B3 system |
| Trace Layer | Gold Object | Possible Assistant Failure | Benchmark Metric Affected |
|---|---|---|---|
| Evidence | Penalty, force majeure, notice, gross negligence clauses | Missing exception clause | TGC, ASA |
| Facts | Delay, ForceMajeure, NoticeSent, GrossNegligence | Fact omitted or unsupported | TGC, CLA |
| Rules | r1, r2, r3 | Exception rule not extracted | ASA, PHA |
| Conflict | Penalty vs. not Penalty | Conflict hidden or flattened | CLA, NER |
| Priority | r2 > r1; r3 > r2 | Priority inverted or ignored | PHA, ASA |
| Conclusion | Penalty accepted only if r3 defeats r2 | Arbitrary or unsupported conclusion | ASA, NER, NCR |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Share and Cite
Ulizko, M.V.; Chernikov, A.V.; Tomilov, I.V.; Gusarova, N.F.; Vatian, A.S. Benchmarking Normative AI Assistants Under Inconsistent Evidence with Paraconsistent Trace Semantics. AI 2026, 7, 321. https://doi.org/10.3390/ai7080321
Ulizko MV, Chernikov AV, Tomilov IV, Gusarova NF, Vatian AS. Benchmarking Normative AI Assistants Under Inconsistent Evidence with Paraconsistent Trace Semantics. AI. 2026; 7(8):321. https://doi.org/10.3390/ai7080321
Chicago/Turabian StyleUlizko, Maksim V., Aleksandr V. Chernikov, Ivan V. Tomilov, Natalia F. Gusarova, and Aleksandra S. Vatian. 2026. "Benchmarking Normative AI Assistants Under Inconsistent Evidence with Paraconsistent Trace Semantics" AI 7, no. 8: 321. https://doi.org/10.3390/ai7080321
APA StyleUlizko, M. V., Chernikov, A. V., Tomilov, I. V., Gusarova, N. F., & Vatian, A. S. (2026). Benchmarking Normative AI Assistants Under Inconsistent Evidence with Paraconsistent Trace Semantics. AI, 7(8), 321. https://doi.org/10.3390/ai7080321