Article

Benchmarking Normative AI Assistants Under Inconsistent Evidence with Paraconsistent Trace Semantics


by
Maksim V. Ulizko
*,
Aleksandr V. Chernikov
,
Ivan V. Tomilov
,
Natalia F. Gusarova
and
Aleksandra S. Vatian
*
School of Translational Information Technologies, ITMO University, 197101 St. Petersburg, Russia
*
Authors to whom correspondence should be addressed.
AI 2026, 7(8), 321; https://doi.org/10.3390/ai7080321
Submission received: 19 June 2026 / Revised: 25 July 2026 / Accepted: 13 August 2026 / Published: 20 August 2026

Abstract

Normative AI assistants are increasingly used in domains governed by duties, permissions, prohibitions, exceptions, priorities, and institutional policies. Existing retrieval-augmented generation (RAG) and legal AI benchmarks evaluate answer accuracy, retrieval quality, citation grounding, natural-language inference, clause extraction, or general legal reasoning ability. These dimensions are necessary but insufficient when supplied evidence is incomplete, mutually inconsistent, or defeasible. The objective of this study is to introduce ParaTraceBench, a paraconsistent trace-based benchmarking framework for post-retrieval normative reasoning over fixed evidence packages. Each scenario contains a query, evidence fragments, extracted facts, defeasible rules, typed attack edges, priority relations, an expected conclusion status, and a gold diagnostic trace. The formalism uses evidence-grounded arguments, a single edge-based attack representation, explicit attack-licensing rules, acyclic priority bases with a transitive closure, grounded argument labeling, trace-normal-form alignment, and deterministic scoring. The operational NER metric is explicitly interpreted as inconsistency-conditioned unsupported-conclusion avoidance rather than proof of logical non-explosion. We evaluated the framework using 140 scenarios, external validation on 567 anonymized Russian-language cases from Russian Federation and EAEU-related materials, reasoning-oriented baseline adaptations, five-run prompt-fairness and stability controls, and a deterministic component-dependency audit. On the full external set, the trace-based configuration reached 85.7% answer-status accuracy, 85.5% contradiction-localization accuracy, 94.2% operational NER, 84.1% priority-handling accuracy, and 83.7% belief-revision accuracy. These results indicate that contradiction-aware trace evaluation provides diagnostic information beyond final-answer accuracy under the evaluated fixed-evidence conditions, while not establishing causal architectural superiority, logical non-triviality, or end-to-end RAG performance.

1. Introduction

Normative AI assistants based on large language models (LLMs) and retrieval-augmented generation (RAG) are increasingly used in domains where answers are constrained by rules, duties, permissions, prohibitions, exceptions, priorities, and institutional policies. These domains include legal question answering, contract review, regulatory compliance, internal policy support, safety governance, and ethics-oriented decision support. RAG reduces dependence on parametric model memory, but it does not guarantee that the assistant correctly handles conflicting evidence, exceptions, or priority relations between norms.
Recent RAG and legal-domain benchmarks have substantially improved the evaluation of retrieval, grounding, legal reasoning, clause extraction, natural-language inference, and downstream question answering. LegalBench, LegalBench-RAG, ContractNLI, CUAD, MAUD, RAGAS, and ARES represent important and complementary evaluation families. However, they primarily evaluate whether relevant information is retrieved, whether an answer is supported by context, whether a clause or entailment label is correct, or whether broad legal reasoning performance improves. They do not jointly evaluate whether an assistant preserves inconsistent normative evidence, localizes the source of contradiction, applies defeasible priorities, avoids explosive inference, and revises the conclusion when new evidence changes the normative status of the case.
This distinction matters because contradiction is not always a data-cleaning error in normative domains. A contract may contain a general obligation and a specific exception. A policy may authorize an action under ordinary conditions but prohibit it under safety constraints. A regulation may impose a duty while another rule creates an exemption. The correct assistant behavior is not necessarily to select one clean answer, but to represent support, attack, priority, and unresolved status in a way that remains grounded in the evidence.
We therefore claim that the unresolved evaluation problem is contradiction-aware benchmarking. A benchmark for normative AI assistants should test whether an assistant can reason over inconsistent evidence without collapsing into arbitrary conclusions; preserve and localize contradictions; apply exceptions and priority relations; distinguish accepted, rejected, both-supported-and-attacked, and undecidable statuses; and revise its answer when the evidence package changes.
The benchmarked object is a normative assistant operating over a supplied evidence package. In deployment, that package may be produced by retrieval, filtering, or human selection; in the present experiments, it is fixed and identical across configurations. The measured object is therefore post-retrieval evidence-to-status reasoning, not retrieval recall or end-to-end RAG performance.
ParaTraceBench contributes an operational benchmark and evaluation protocol for post-retrieval normative reasoning. Its novel elements are a contradiction-aware scenario schema linking natural-language evidence to symbolic annotations, trace-normal-form alignment, deterministic scoring of status and diagnostic behavior, a controlled injected-defect suite, and an external contradiction-rich, trace-annotated corpus. The framework reuses established argumentation, defeasible-reasoning, and paraconsistent concepts; B4 is a reference configuration rather than the contribution itself.

2. Related Work

2.1. RAG, Legal Reasoning Benchmarks, and Contract Datasets

RAG was introduced as a method for knowledge-intensive NLP tasks and has become a dominant architecture for grounding LLM outputs in external corpora [1,2,3]. General RAG evaluation focuses on retrieval performance, answer faithfulness, context relevance, and grounded generation. These dimensions are essential for normative assistants, but they do not fully capture the logic of rule application, exceptions, conflicts, and priorities.
LegalBench evaluates broad legal reasoning capabilities across heterogeneous legal tasks [4]. LegalBench-RAG and a reasoning-focused legal retrieval benchmark move evaluation toward precise retrieval of legally relevant snippets [5,6], while empirical audits of legal research assistants demonstrate that citation presence alone does not eliminate unsupported answers [7]. ContractNLI evaluates document-level natural-language inference over contracts [8], and CUAD and MAUD provide expert-annotated resources for clause extraction and agreement understanding [9,10]. These resources remain essential, but their primary labels do not preserve a complete support-attack-priority trace.

2.2. Faithfulness, Hallucination, and Automated RAG Evaluation

Faithfulness and hallucination evaluation ask whether generated answers are supported by evidence and whether explanations reflect the actual decision process [11,12]. RAGAS and ARES provide automated evaluation frameworks for RAG systems [13,14]. These approaches are useful for evaluating groundedness, answer relevance, and context quality, but they can be insufficient when the correct evidence package contains mutually inconsistent or defeasible statements. In such cases, the correct behavior is not simply to select a citation; it is to represent the conflict, determine which attacks remain active after priority handling, and assign a status such as accepted, rejected, both, or undecidable.

2.3. Argumentation, Defeasible Reasoning, and Paraconsistent Logic

Formal argumentation provides a natural framework for modeling normative conflicts. Dung-style abstract argumentation represents arguments and attacks [15,16], while defeasible reasoning frameworks introduce priorities, exceptions, and burdens [17,18]. Paraconsistent logic is relevant because it allows inconsistent information to be represented without trivializing the theory [19,20]. This is important for normative assistants because conflicting rules or evidence fragments should not automatically imply arbitrary conclusions.
ParaTraceBench operationalizes selected concepts from argumentation, defeasible reasoning, and paraconsistent logic as evaluable benchmark artifacts. It connects natural-language evidence and symbolic annotations to gold diagnostic traces, trace-normal-form equivalence classes, deterministic matching rules, and metric definitions applicable to both black-box and structured assistant outputs.
The key observation from Table 1 is that existing resources cover important parts of the evaluation problem, but they do not combine natural-language normative evidence, symbolic contradiction labels, defeasible priorities, conclusion-status labels, and a gold diagnostic trace in one benchmark object. ParaTraceBench is designed to fill that specific evaluation gap.

2.4. Reasoning-Oriented External Baselines

A separate comparison is needed because strong general-purpose reasoning frameworks can improve multi-step answers without explicitly preserving normative contradictions. GraphRAG builds graph-based representations over text collections and is useful when retrieval must exploit entity or community structure [21]. ReAct interleaves reasoning traces and actions [22]. Self-Refine adds iterative feedback and revision [23]. Tree of Thoughts explores multiple candidate reasoning paths before selecting an answer [24]. DSPy treats language-model calls as compositional, optimizable modules rather than isolated prompt strings [25]. These frameworks represent meaningful external baselines for ParaTraceBench because they test whether contradiction-aware trace scoring adds value beyond generic reasoning or graph-augmented retrieval.
ParaTraceBench does not claim that these approaches are weak. The claim is narrower: they do not, by default, expose the benchmark objects required for deterministic contradiction-aware scoring, namely grounded conflicts, priority relations, active and defeated attacks, four-valued conclusion status, and trace-normal-form alignment. For this reason, Section 4.6.2 defines external baseline adaptations that receive the same evidence packages and are scored with the same deterministic metric suite as B1–B4.

3. Problem Definition

Let q be a normative user query and D be a corpus of documents. A normative AI assistant receives q and may retrieve an evidence set E_q from D. It then generates an answer a and, in some systems, an explanation or trace t. Classical benchmarking usually evaluates a against a reference answer and E_q against gold evidence. ParaTraceBench evaluates an enriched object: the assistant treatment of facts, rules, conflicts, priorities, and conclusion status.
A benchmark scenario is defined as follows.
S = q ,   E ,   F ,   R ,   C ,   P ,   y ,   T g o l d .
Here q is the query; E is the evidence set; F contains extracted facts; R contains normative rules; C contains conflicts; P contains priority relations; y is the expected status; and T_gold is the adjudicated diagnostic trace.
This representation was selected because it covers the minimum auditable components of contradiction-aware normative reasoning. Evidence fragments ground the answer; facts and rules express the extracted normative content; conflicts preserve mutually attacking or incompatible propositions; priorities encode exception, hierarchy, specificity, temporal, or source-authority relations; the expected status tests the final normative outcome; and the gold trace records the diagnostic path that makes the status reproducible. Removing any of these components would collapse at least one target failure mode into an unobservable final-answer error.
The assistant output is represented as follows.
O = a ,   E ^ ,   F ^ ,   R ^ ,   C ^ ,   P ^ ,   y ^ ,   T ^ .
The hatted objects are assistant-produced or deterministically reconstructed evidence, facts, rules, conflicts, priorities, status, and trace. The benchmark compares this object with the gold scenario package.
The central evaluation problem is therefore not only whether a is textually correct, but whether the assistant can maintain the normative distinction between support, attack, exception, priority, and absence of proof. This distinction is critical in domains where a conclusion may be accepted, rejected, both supported and attacked, or undecidable depending on the available evidence.
For the avoidance of ambiguity, ParaTraceBench treats the assistant as a configurable reasoning pipeline. In the controlled validation reported below, retrieval variance is intentionally removed: all configurations receive the same query q and the same normalized evidence fragments E. What is benchmarked is therefore the downstream normative treatment of that evidence: whether the assistant keeps the relevant facts and rules grounded, preserves conflicts, applies priority relations, avoids explosive conclusions, and assigns the correct conclusion status. In retrieval-enabled deployments, retrieval can be evaluated as a separate layer, but it is not the main variable in the present controlled validation.

4. Materials and Methods

4.1. Benchmarking Object: Post-Retrieval Normative Reasoning Assistant

ParaTraceBench benchmarks a concrete product class: a normative assistant that transforms a supplied evidence package into a checkable conclusion status and, when supported by the architecture, a diagnostic trace. In deployment, the evidence package may come from RAG retrieval, document selection, or a human-prepared file set. In the validation reported here, the evidence package is fixed and identical across configurations so that the measured variable is not retrieval recall, but the downstream normative treatment of the supplied evidence.
The controlled experiments separate the upstream retrieval or selection layer from the experimental variable. They begin with the fixed evidence package E, construct candidate facts, rules, attacks, and priorities, apply deterministic status semantics, and then compute status-level and diagnostic metrics.
In the neuro-symbolic implementation that motivates the framework, the LLM is constrained to candidate extraction from evidence fragments through a fixed structured schema. Instead of being asked to issue the final legal decision directly, it returns candidate fact identifiers, rule identifiers, element types, normalized propositions, source identifiers, fragment identifiers, span boundaries, extraction confidence, and links to target query elements. This design separates extraction from normative decision-making and makes intermediate artifacts auditable.
After extraction, a deterministic parser-validator checks schema conformance, source and fragment links, predicate types, rule syntax, and the absence of unsupported rules. Elements that cannot be linked to a source fragment or that violate the schema are not treated as grounded facts or grounded rules for scoring. They can still be used diagnostically as evidence of unsupported extraction, missing grounding, or malformed trace construction.
The argumentation layer follows the same intuition as the original verification-oriented system. A basic Dung-style argumentation graph represents arguments and attacks, while the normative extension adds defeasible rules, exceptions, source hierarchy, specificity, temporal order, and priority-based defeat. A priority relation can deactivate an attack for status computation, but it does not erase the underlying contradiction from the trace. This distinction is central to ParaTraceBench: the assistant is rewarded for preserving the conflict and explaining why it is active, defeated, or unresolved.
The four baseline configurations in Section 4.6 should be read as progressively richer instantiations of this product class. B1 exposes only citation-level answering; B2 adds self-checking; B3 extracts facts and rules; B4 attempts to produce facts, rules, conflicts, priorities, status, and trace edges. None of these configurations receives gold annotations during inference. The benchmark therefore evaluates how much of the evidence-to-status pipeline the assistant can reconstruct from the same evidence package.

4.2. Benchmark Scenario Schema

Each ParaTraceBench scenario contains both natural-language and symbolic layers. The natural-language layer makes the benchmark suitable for AI assistants that operate on text. The symbolic layer enables deterministic evaluation of contradiction handling, defeasible priority use, and trace consistency.
Intuitively, gold-trace construction proceeds from text to status in four steps. First, annotators identify the evidence spans that are relevant to the target query. Second, they normalize these spans into facts and defeasible rules while preserving source links. Third, they mark conflicts and priority relations, including exceptions, hierarchy, specificity, temporal precedence, and source authority where applicable. Fourth, they compute the expected status and record the mandatory evidence-to-fact-to-rule-to-conflict/priority path as the gold diagnostic trace. This intuitive workflow is formalized below so that scoring remains deterministic.
The most important fields in Table 2 are not the query and answer, but the conflict, priority, expected status, and gold trace fields. These fields make the benchmark different from ordinary normative QA: they force the assistant to expose how the conclusion behaves under conflicting evidence rather than only producing a fluent response.

4.3. Paraconsistent Trace Graph

For each scenario and target conclusion c, ParaTraceBench defines the following trace graph.
T r a c e q ,   c = N G ,   E G ,   t y p e ,   s r c ,   v a l .
N_G contains target-query, evidence-fragment, fact, rule, priority, argument, conclusion, proof, and status nodes. E_G contains typed grounding, derivation, attack, priority/defeat, and status edges. An attack is always a typed directed edge in E_G and is never a semantic node in N_G. Transport-level attack records are converted deterministically into this edge representation before STATUS, CLA, TGC, or graph matching.
A trace is evidence-grounded when every scored fact, rule, priority, argument, proof/status node, and every scored attack or defeat edge is connected through a valid source path to a cited evidence fragment. This requirement is intentionally strict: a fluent explanation is not accepted as a diagnostic trace unless the relevant semantic objects and relations can be aligned with the supplied evidence package. Provenance links follow the same source-path principle as established provenance data models [26].
Before scoring, the gold and assistant traces are converted to trace normal form TNF(T). Let M(T_gold, c) denote the family of inclusion-minimal grounded edge sets whose induced subtraces reproduce the annotated support/attack labels and status of conclusion c. Each admissible set contains the evidence-to-fact and evidence-to-rule edges required by active support or attack arguments, the relevant derivation edges, every status-relevant attack edge, every priority or defeat edge that changes whether such an attack is active, and the final status edge.
Duplicate grounded derivations with the same semantic effect are merged, while alternative minimal derivations with the same support, attack, defeat, and status effect form equivalence classes. Alignment selects the admissible gold set with minimum edit distance to the normalized assistant trace; ties are resolved by canonical edge-identifier order. A mandatory edge is therefore defined relative to the selected minimal status-justifying equivalence class and is derived algorithmically rather than chosen informally.
TNF canonicalization proceeds in six deterministic stages: (i) normalize evidence identifiers, clause references, propositions, status labels, and attack targets; (ii) convert serialized attack records or provenance-event representations into typed attack edges; (iii) reject ungrounded semantic objects; (iv) compute grounded IN/OUT/UNDEC argument labels and STATUS by Algorithm 1; (v) collapse duplicate proof chains that have the same grounded source set and the same support/attack/defeat effect; and (vi) assign canonical identifiers to the remaining nodes, edges, and equivalence classes. Two traces are TNF-equivalent only when they preserve the same grounded evidence obligations, attack target and kind, active/defeated attack state, and conclusion status. Surface similarity or a shared final answer is insufficient. Worked equivalent and non-equivalent examples are provided in Appendix C.
Algorithm 1. Status computation for a proposition under trace and priority relations.
STATUS(p, T, P0):
    reject priority cycles; mark their comparisons unresolved
    P_plus:= transitive_closure(P0 after removing unresolved components)
    Args:= evidence-grounded arguments in T
    Att:= grounded attack edges after internal-target propagation
   Att_active:= {alpha in Att | not neutralized_by_priority(alpha, P_plus)}
   IN:= {A in Args | A has no incoming edge in Att_active}
   OUT:= {A in Args | some B in IN attacks A}
   repeat
       IN_new:= IN union {A | every active attacker of A is in OUT}
       OUT_new:= OUT union {A | some B in IN_new actively attacks A}
        IN, OUT:= IN_new, OUT_new
   until IN and OUT no longer change
   label every remaining argument UNDEC
   active_support:= exists A in IN with conc(A) = p
   active_attack:= exists A in IN with conc(A) = not(p)
                                       or exists B in IN actively attacking an argument for p
   map (active_support, active_attack) by Definition 5
The iteration starts from unattacked arguments and returns the least grounded labeling; mutual or odd attack cycles therefore remain UNDEC unless resolved by an external IN argument.

4.4. Formal Trace Semantics

This section defines the deterministic benchmark semantics used to score evidence grounding, support, attack, priority defeat, and operational unsupported-conclusion diagnostics.
Definition 1 (evidence-grounded argument). 
For a proposition p, an evidence-grounded argument has the following form: E_A is a non-empty set of cited evidence fragments, F_A is a set of facts grounded in E_A, R_A is a finite set of rules grounded in E_A, and p is obtained through a finite acyclic derivation over F_A and R_A. The conclusion is conc(A) = p. An argument is invalid for scoring if a required fact or rule lacks a source path.
A = E A ,   F A ,   R A ,   p .
Definition 2 (typed attack and licensing rule). 
An attack has the following edge record: A_s is an evidence-grounded attacking argument; x_t is an argument, conclusion, rule, or premise targeted by the attack; kind is rebut, undercut, or undermine; src is the evidence path; and lic(alpha) is the final evidence-grounded rule licensing the attack. An attack on a mandatory internal rule or premise is expanded to every containing argument whose derivation depends on that element. Reified user-interface or provenance events are normalized away before semantic scoring.
α = A s ,   x t ,   k i n d ,   s r c ,   l i c .
Definition 3 (priority base and strict order). 
P_0 is the finite, evidence-grounded base relation explicitly annotated for a scenario. It must be irreflexive and acyclic. The relation used for status computation is its transitive closure P_plus, which is a strict partial order. Thus r_1 > r_2 and r_2 > r_3 entail r_1 >+ r_3 even if the transitive edge is not serialized. Incomparable rules remain incomparable. Cyclic, opposing, or ungrounded assistant-produced comparisons are marked unresolved_priority; affected attacks remain active, and no defeat is inferred from the unresolved component.
P + = T C P 0 , P 0   acyclic .
Definition 4 (target-rule selection, neutralization, and defeat). 
targetRules(alpha,A_t) returns the attacked rule for an undercut, the last-link rules supporting a rebutted conclusion for a rebut, and the rules whose derivations depend on an attacked premise for an undermine attack. An evidence-grounded attack is neutralized only when an applicable target-side rule r_t satisfies r_t >+ lic(alpha) outside an unresolved priority component. If several target-side rules are applicable, one grounded dominating rule is sufficient; if none is comparable, the attack remains active. Defeat of a mandatory internal element propagates to every dependent argument. Priority never deletes an attack edge; it changes only its active/defeated label.
Definition 5 (grounded support and attack labels). 
First, neutralized priority attacks are marked defeated, and attacks on internal elements are propagated to their containing arguments. Algorithm 1 then computes the least grounded IN/OUT/UNDEC labeling of the remaining attack graph. support(p) = 1 when an IN-labeled argument concludes p. attack(p) = 1 when an IN-labeled argument concludes not(p), or an IN-labeled attacker targets an argument for p. Otherwise, the corresponding label is 0.
The four-valued status mapping is defined below. The both status is a valid benchmark state rather than a system failure.
s t a t u s p = a c c e p t e d ,   s ,   a = 1 ,   0 ,   r e j e c t e d ,   s ,   a = 0 ,   1 ,   b o t h ,   s ,   a = 1 ,   1 ,   u n d e c i d a b l e ,   s ,   a = 0 ,   0 .
Definition 6 (inconsistency-conditioned unsupported-conclusion avoidance). 
Let I_gold be the set of scenarios whose adjudicated gold trace has support(p) = 1 and attack(p) = 1 for at least one proposition. Let U_i contain emitted conclusions that are unrelated to the target or required sub-conclusions and lack an evidence-grounded argument in TNF(T_hat). The operational NER is evaluated on I_gold, not on whether the assistant itself preserved the conflict. This prevents a system from leaving the denominator by omitting an attack. UUCR is the proportion of emitted non-required conclusions that lack an evidence-grounded argument, with UUCR = 0 when no such conclusions are emitted.
N E R = 1 # { i I g o l d : U i } I g o l d .
NER is an output-level inconsistency-conditioned unsupported-conclusion avoidance measure. It is not a proof of logical non-triviality and does not establish that an unsupported conclusion was caused by inconsistency. The present study does not include a matched consistent-case UUCR control; this limitation is stated explicitly, and no causal paraconsistency claim is made.
A conclusion is conceptually benchmark-correct when the following complete trace-level predicate holds.
K p a r a = G r o u n d P r e s e r v e N o n E x p l o d e o p V a l i d P r i o r i t y S t a t u s M a t c h T r a c e M a t c h .
Ground checks source-linked facts and rules; Preserve retains conflicts; NonExplode_op is the operational check in Definition 6; ValidPriority checks priority application; StatusMatch compares predicted and gold status; and TraceMatch checks the diagnostic path. K_para remains an all-or-nothing conceptual specification because B1-B3 do not expose all six components; empirical results therefore report the components separately.

Design Rationale for the Paraconsistent Trace Semantics

The semantic choices are intentionally conservative and benchmark-driven. A binary contradiction flag would not distinguish a supported conclusion, an attacked conclusion, a conclusion that is both supported and attacked, and a conclusion for which neither side is grounded. The Belnap-like four-valued status mapping is therefore used because it separates acceptance, rejection, unresolved conflict, and absence of proof in a way that can be scored at the output level [19,20].
Priority-based defeat is used because normative domains rarely treat all conflicts symmetrically. Source hierarchy, specificity, temporal order, explicit exceptions, and burden allocation can change whether an attack remains active without deleting the underlying contradiction. This is why ParaTraceBench preserves attack edges in the trace even when priority deactivates them for status computation.
The trace graph is used instead of a plain explanation string because benchmark scoring must verify source links, fact and rule grounding, conflict localization, and status computation. Trace normal form accommodates multiple admissible derivation paths by crediting semantically equivalent grounded paths while rejecting unsupported or ungrounded proof nodes. Together, these choices provide an operational semantics for auditable benchmark comparison.

4.5. Operational Semantics and Scoring Algorithms

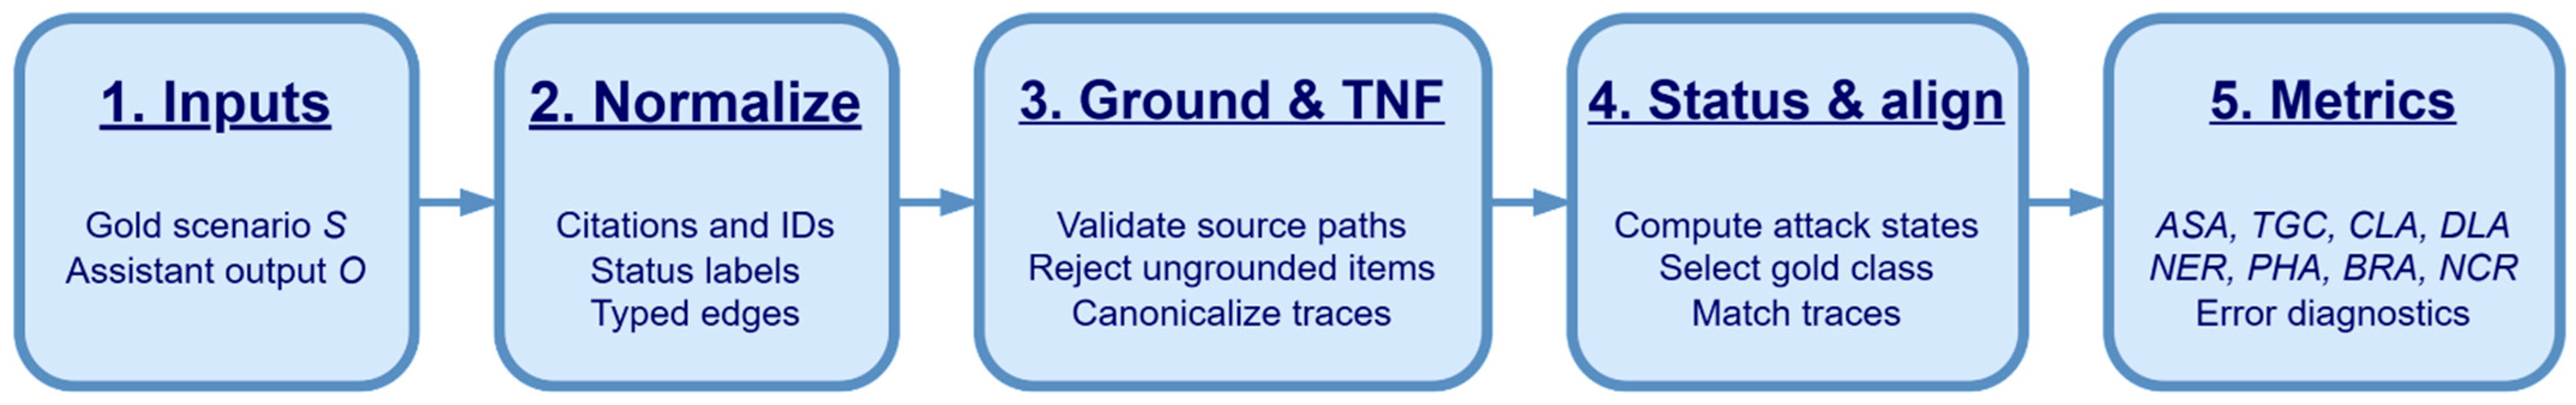
ParaTraceBench evaluates model outputs through deterministic graph comparison rather than inferred intent. As summarized in Figure 1, the scorer normalizes and grounding-validates the gold scenario and assistant output, constructs TNF and STATUS representations, aligns the traces, and computes the metric suite. Only explicit or deterministically reconstructable objects contribute to diagnostic scoring. Algorithm 2 specifies scenario construction and annotation, and Algorithm 3 specifies paraconsistent trace scoring.
Algorithm 2. Scenario construction and annotation
Input: normative document set D, query q, target conclusion c
1. Select evidence fragments E relevant to q and c.
2. Annotate atomic facts F grounded in E.
3. Annotate defeasible rules R grounded in E.
4. Identify conflicts C between facts, rules, arguments, or conclusions.
5. Annotate priority relations P when exceptions, hierarchy, source authority, or specificity applies.
6. Compute expected status y in {accepted, rejected, both, undecidable} using STATUS.
7. Build gold trace T_gold linking E -> F -> R -> C/P -> y.
Output: S = (q, E, F, R, C, P, y, T_gold).
Algorithm 3. Paraconsistent trace scoring
Input: gold scenario S and assistant output O
1. Normalize assistant citations and extracted objects.
2. Convert assistant and gold traces to trace normal form.
3. Score mandatory grounded edges (TGC).
4. Score gold conflict cases (CLA) and controlled defect classes (DLA).
5. On gold-inconsistent scenarios I_gold, flag unsupported-unrelated outputs and compute NER.
6. Compare active/defeated attacks using lic(alpha), targetRules, and P_plus.
7. Compare predicted and gold status (ASA) and paired-update status (BRA).
8. Compute correctness-gated robustness.
Output: M = (ASA, TGC, CLA, DLA, NER, PHA, BRA, NCR).
Mandatory-edge extraction, trace-normal-form alignment, and matching are specified in Algorithm 4.
Algorithm 4. Mandatory-edge extraction, trace-normal-form alignment, and matching
Input: gold trace T_gold, assistant trace T_hat, evidence package E, target conclusion c
1. Canonicalize evidence identifiers, clause references, status labels, propositions, and typed attack targets.
2. Convert serialized attack records or provenance-event encodings to typed attack edges.
3. Reject any fact, rule, conflict, priority, attack, or proof object that lacks a valid source path to E.
4. Enumerate inclusion-minimal grounded subtraces of T_gold that reproduce the gold support/attack labels and status(c).
5. For each subtrace, retain required evidence, derivation, attack, priority/defeat, and status edges; merge duplicate derivations with identical semantic effects.
6. Represent alternative minimal subtraces with the same semantic effect as an equivalence class M(T_gold,c).
7. Map assistant edges to gold edges when node/edge types, grounded source fragments, semantic relations, attack targets, active/defeated states, and STATUS effects match.
8. Select the admissible gold set with minimum edit distance to TNF(T_hat); resolve ties by canonical edge-identifier order.
9. Credit one matched assistant edge per required gold equivalence class and retain unsupported edges for diagnostic error analysis.
Output: selected mandatory gold edge set, matched edges, missing edges, and unsupported assistant edges.
The worst-case cost of enumerating all inclusion-minimal status-preserving subtraces is exponential in the number of candidate gold edges, O(2^|E_G| × C_STATUS), where C_STATUS is the cost of fixed-point status recomputation. Canonicalization and matching are polynomial once the admissible minimal family has been generated. In the benchmark, traces are deliberately compact; the released scorer uses pruning by grounded reachability, required status-effect edges, and memoized STATUS signatures. The complexity statement concerns the worst case and does not imply that arbitrary large argumentation graphs can be normalized cheaply. Operational unsupported-conclusion and NCR scoring are specified in Algorithm 5.
Algorithm 5. Operational unsupported-conclusion and NCR scoring
Input: gold scenario S, normalized assistant trace TNF(T_hat), target c, finite edit set Delta_N
1. Use the gold contradiction flag to determine membership in I_gold.
2. Mark emitted non-required z as unsupported when no evidence-grounded argument concludes z.
3. Compute NER on I_gold; record UUCR diagnostically.
4. Enumerate fact, rule, exception, priority-edge, and attack-edge edits in Delta_N.
5. Use unit cost for every atomic edit in the reported experiments.
6. Search edit sets in non-decreasing cost and canonical lexicographic order; recompute TNF and STATUS.
7. Let d_N be the first cost that flips status; if no admissible edit flips it, right-censor at |Delta_N| + 1.
8. Set NCR_case = 0 when the original predicted status is wrong; otherwise use d_N or the right-censor value.
9. Report the arithmetic mean of NCR_case over the stated evaluation split.
Output: NER/UUCR diagnostics, raw d_N witnesses, and the correctness-gated NCR score.
For m = |Delta_N|, exhaustive robustness search has worst-case complexity O(2^m (C_TNF + C_STATUS)). The reported aggregate is correctness-gated: an initially incorrect status receives zero robustness credit, which permits a mean below one (including the B1 value 0.9); a correct no-flip case is right-censored at m + 1 rather than averaged as infinity. Values 0.9, 1.5, 2.2, and 3.5 are therefore split-level means under the same unit-cost and gating convention. Uniform positive rescaling preserves witness ordering up to scale; non-uniform weighting can change the minimum witness. Appendix C.5 provides an explicit cost-sensitivity example.
ParaTraceBench does not require every tested assistant to be a symbolic system. A black-box assistant can still be evaluated through answer status, cited evidence, contradiction handling, and revision behavior, while a white-box system can be evaluated more deeply through trace matching.

4.6. Assistant Configurations, Baselines, and Evidence Access

The benchmark is intended to compare several classes of normative AI assistants. To avoid giving the trace-producing configuration an oracle advantage, all configurations receive the same query q and the same evidence fragments E during inference. Gold facts, rules, conflicts, priorities, expected statuses, defect labels, and gold traces are withheld from every configuration. Differences between configurations concern only the output format and the reasoning procedure requested from the assistant.
The metrics are reported in two layers. ASA and BRA are final-status metrics that can be compared directly across configurations under equal evidence access. TGC, CLA, PHA, NER, and NCR are diagnostic trace-oriented metrics: for B1-B3 they are computed only from explicit or deterministically reconstructable objects, whereas B4 exposes the full trace schema. Lower trace-oriented scores for B1–B3 therefore indicate limited diagnostic observability under their output schemas, not that their final answers are necessarily less useful.
The primary fairness constraint is equal access to q and E with all gold annotations withheld. Section 6.5 additionally evaluates B4 zero-shot, B3 matched five-shot, a compact B4 prompt with an approximately matched prompt/example token budget, a common top-level output schema, and repeated runs. These controls narrow but do not eliminate prompt and schema confounding. Because B1 and B2 were not rerun with matched five-shot examples, prompt-fairness conclusions are restricted to the B3–B4 comparison.
The key comparison in Table 3 is between citation-level behavior and trace-level behavior. B4 is not an oracle because it receives no gold annotations and must construct its own trace from the same evidence available to B1-B3. The scorer compares B4 output with the gold scenario package only after inference. This separation is essential for avoiding circular evaluation.

4.6.1. Implementation Details of Baselines

The controlled validation uses fixed evidence packages rather than open retrieval. This isolates reasoning and trace construction from retrieval variance. All four configurations, B1-B4 were run with the same backbone, gpt-5.2-2025-12-11, under the same fixed decoding settings. This equal-backbone design removes model-version asymmetry and isolates the effect of output representation, prompting strategy, trace construction, and scoring. The comparison should therefore be read as a controlled validation of representation and reasoning procedure rather than as a model-family ranking. Cross-model trace-prompt results are reported separately in Section 6.4 and Appendix A. Full model provenance, run dates, execution environment, generation parameters, prompting constraints, and output-handling rules are reported in Appendix A and in the reproducibility package.
All runs used fixed decoding settings: temperature = 0, top_p = 1.0, and max_tokens = 4096. The same query q and the same normalized evidence fragments E were provided to each baseline. Gold facts, rules, conflicts, priorities, expected statuses, gold traces, and injected defect labels were not included in any prompt. Outputs were scored only after generation by deterministic normalization and graph alignment against the gold scenario package. These parameters were held constant across configurations; however, fixed decoding settings do not guarantee bitwise-identical outputs from a hosted model endpoint.
B1 used a citation-only prompt that asked the model to answer the query, cite the provided evidence fragments, and return a final normative status. B2 used the same citation prompt plus a self-check block asking the model to inspect the answer for missing exceptions, contradictions, unresolved uncertainty, and source coverage before returning the final status. B3 used a structured extraction prompt that first required JSON-like extraction of facts and rules grounded in evidence, followed by a final answer and status; it did not require explicit attack edges, priority defeat, or trace edges. B4 used few-shot prompting with explicit instructions to output JSON matching the scenario schema in Table 2, including evidence identifiers, facts, rules, conflicts, priorities, conclusion status, trace edges, and citations. The few-shot examples were excluded from the controlled validation set.
For B4, malformed JSON was not manually corrected. The scorer applied only deterministic repairs that can be reproduced in the released scripts: trimming markdown fences, normalizing evidence identifiers, canonicalizing status labels, converting serialized attack records to typed edges, and rejecting trace edges that could not be linked to a cited evidence fragment. Rejected edges remained in diagnostic logs but did not contribute to grounding or trace matching. An aggregate rejected-edge percentage is not reported because B1 and B2 do not emit comparable edge objects, and the repeated-run efficiency protocol instrumented B3/B4 only. This restriction is stated explicitly to prevent an invalid B1-B4 edge-rejection comparison.
The additional control phase used the same model snapshot and fixed decoding settings for five configurations: B3-standard, B3-five-shot, B4-zero-shot, B4-compact, and B4-standard. All configurations returned the common top-level fields: final_status, evidence_ids, conflict_detected, priority_applied, and uncertainty; B4 variants additionally returned trace-v2 objects. B3-standard and B4-zero-shot used no examples, whereas B3-five-shot, B4-compact, and B4-standard used five held-out examples. B3-five-shot used approximately 4700 system-plus-example tokens, while B4-compact used approximately 4590, providing the closest token-budget control. B4-standard retained the full trace instruction and used approximately 5940 system-plus-example tokens. Five repeated runs were performed for B3-standard and B4-standard on all 140 controlled cases and for all five fairness configurations on a stratified 100-case external subset. B1/B2 matched-example controls were not performed and are not implied by the fairness analysis.

4.6.2. External Reasoning Baselines

To avoid evaluating ParaTraceBench only against internally defined B1-B4 configurations, we added external reasoning-oriented baselines. These baselines are adaptations of widely used reasoning or graph-augmented paradigms rather than replications of their full original benchmark settings. All baselines receive exactly the same normalized evidence fragments E and the same query q. Gold facts, rules, conflicts, priorities, statuses, and traces are hidden during inference. The same deterministic scorer is then applied to the normalized outputs.
The purpose of Table 4 is methodological rather than architectural. It ensures that the proposed benchmark is tested against recognized reasoning paradigms such as graph-augmented retrieval, reasoning-and-acting, self-refinement, deliberate search, and modular LM pipelines. This directly tests whether trace semantics and contradiction-aware scoring capture behavior that generic reasoning pipelines do not expose. The suffix “-style” is intentional: these are operational adaptations under equal evidence access and deterministic ParaTraceBench scoring, not claims of full reproduction of each original framework or its native evaluation setting.

5. Benchmark Metrics

ParaTraceBench uses metrics that evaluate both final-answer behavior and internal or reconstructed reasoning behavior. We intentionally avoid reducing the benchmark to one aggregate score because different failure modes have different normative significance. ASA and BRA are status-level metrics. TGC, CLA, the operational NER, PHA, and NCR are diagnostic metrics that test whether a system exposes the reasoning artifacts needed for audit: grounded trace edges, conflict localization, avoidance of unsupported unrelated conclusions under inconsistency, priority defeat, and status robustness. NER is an output-level proxy and is not presented as proof of logical non-triviality.
The main point of Table 5 is that answer accuracy is only one row. The remaining metrics capture behaviors central to normative reliability: preserving links to evidence, localizing contradictions, avoiding unsupported unrelated conclusions under inconsistent evidence, applying priority relations, revising conclusions, and estimating fragility. The metrics are interpreted separately because a single aggregate would conceal whether a failure arose from final status, grounding, conflict preservation, priority, or trace observability.
Trace coverage must be interpreted under non-monotonicity. ParaTraceBench does not require the assistant to reproduce a single predetermined proof path, because the same status can be supported by several admissible derivations. TGC is therefore computed on required normalized trace edges in TNF(T_gold), not on the set of all logically possible paths. If an assistant provides an alternative path that is evidence-grounded and equivalent with respect to support, attack, priority defeat, and conclusion status, deterministic alignment can credit it as satisfying the corresponding gold equivalence class.
T G C = E v e r i f i e d T N F E m a n d a t o r y g o l d , T N F .
Accordingly, the trace-coverage component of TGC measures completeness of the normalized diagnostic trace rather than the percentage of all theoretically available non-monotonic derivation paths. This prevents the score from varying solely because a theory contains several syntactically different ways to derive the same proposition.
For robustness, ParaTraceBench first computes a raw minimal normative edit distance and then applies a correctness gate for aggregate comparison.
d N c ,   T = m i n S Δ N { c o s t S : s t a t u s c ,   T s t a t u s c ,   a p p l y T ,   S } .
N C R c a s e = 0 , y ^ y , d N c ,   T , y ^ = y   and   d N < , Δ N + 1 , y ^ = y   and   no   admissible   edit   flips   the   status .
Every reported atomic edit has unit cost. A wrong original status receives NCR_case = 0; a correct finite case receives its minimal edit distance; and a correct case with no flipping edit in the finite candidate set is right-censored at |Delta_N| + 1. The tabled NCR value is the mean of NCR_case over the stated split. This is a correctness-gated robustness score, not an unbounded mean of raw distances.
Under this convention, NCR is a status-level robustness metric rather than a single-proof fragility score. After every candidate S subset Delta_N is applied, the scorer recomputes TNF and STATUS. If one support path disappears but another grounded and undefeated path remains, the status is unchanged and the change set is not a robustness witness. Multiple independent support or attack paths therefore increase NCR. The exhaustive search is exponential in |Delta_N| in the worst case, although canonical ordering, pruning, and memoization reduce the practical search space for the compact benchmark traces.
As an example, consider a penalty case where r1 supports Penalty(x), r2 attacks it through force majeure, and r3 defeats r2 through a gross-negligence exception. If changing only the priority r3 > r2 flips the status from accepted to both, then NCR = 1. If the same status survives removal of r3 because an independent grounded exception also defeats r2, one change is insufficient and NCR > 1. Under a non-uniform cost function, the minimum witness could change; because no weighted sensitivity experiment is reported, the present NCR results are claims only under the stated unit-cost convention.

6. Controlled and External Validation

6.1. Controlled Validation

The controlled validation is designed to test whether the proposed metric suite can detect and localize known defects injected into normative reasoning scenarios. It complements the final external real-world validation set rather than replacing it. The scenario set contains 140 controlled cases with injected defects: 20 correct scenarios without injected defects and 120 defective scenarios distributed across six defect classes.
The most important rows in Table 6 are priority inversion and attack edge deletion. These cases distinguish ParaTraceBench from simple citation evaluation: the relevant text may be present, but the normative conclusion is still wrong if the exception, priority, or conflict relation is mishandled.

6.2. Access Conditions and Controlled Results

The controlled comparison reports all four baseline configurations on the same 140-case-controlled-validation suite. B1 tests whether a citation-only baseline can handle inconsistent normative evidence without explicit reasoning structure. B2 tests whether adding an LLM self-check improves contradiction awareness. B3 tests whether fact/rule extraction improves status accuracy and defect localization even without an explicit trace graph. B4 tests whether explicit trace production further improves localization, priority handling, operational unsupported-conclusion checks, and robustness computation.
All tested configurations receive the same normalized evidence fragments and the same query. In retrieval-enabled experiments, retrieval can be evaluated separately; in the controlled validation reported here, the evidence package is fixed so that the diagnostic test isolates reasoning, conflict handling, priority handling, and trace validation. The gold objects F, R, C, P, y, T_gold and injected defect labels are never included in prompts. B4 is treated as a trace-producing configuration, not as an oracle: it receives no gold labels during inference and is scored only after producing its own trace.
Table 7 reports status accuracy and controlled Defect Localization Accuracy (DLA). DLA classifies the six injected pipeline defects and must not be interpreted as CLA, whose denominator is restricted to adjudicated conflict cases. The increasingly structured configurations expose defect classes that citation-only scoring cannot localize; external contradiction localization is reported separately in Section 6.3.
Table 8 explains the 138/140 B4 status accuracy. The two errors are status-level errors, not necessarily full trace failures. In one accepted case, B4 preserved the conflict but failed to activate the priority edge required to defeat the attack, so it predicted both. In one both case, B4 detected uncertainty but failed to retain an evidence-linked support path, so the strict scorer assigned an undecidable prediction.
The examples in Table 9 are important because they show that B4 is not treated as an oracle. It can preserve a contradiction while still failing to apply priority correctly, or it can identify a conflict while still losing the grounding edge required for a valid support path. The scorer therefore rewards trace quality only when the trace is evidence-linked and normatively coherent.
Table 10 shows that the controlled DLA is not merely a final-answer comparison. The benchmark identifies which layer of the trace failed. The weakest localization class is priority inversion, which is expected because priority direction often depends on source hierarchy, specificity, or exception wording rather than surface contradiction alone.

6.3. External Real-World Validation

External validation used 567 anonymized Russian-language normative scenarios derived from Russian Federation and EAEU-related materials dated 2022–2026. Sampling was purposive rather than random: the unit was a query-centered scenario, and the set was designed to concentrate duties, permissions, prohibitions, exceptions, conflicts, and priority relations across five source categories. It is not a representative census. The source organization permitted research use of anonymized, content-adjusted scenario objects; materials involving personal data, banking secrecy, NDA restrictions, or non-releasable commercial information were excluded. The corpus distribution and construction protocol are summarized in Table 11.
Inclusion required: (i) a concrete normative query and target conclusion; (ii) at least one relevant duty, permission, prohibition, exception, priority, or conflict; (iii) evidence spans sufficient for an adjudicated trace; and (iv) anonymization without loss of normative structure. Exclusion covered restricted data, unrecoverable OCR corruption, exact or evident near-duplicates, purely factual cases, and cases whose meaning could not survive anonymization. The retained registry records scenario identifier, source category, jurisdictional/time scope, contradiction flag, priority flag, update-pair membership, and split membership. Original-document lengths, OCR proportions, candidate-pool counts, and numerical duplicate-exclusion counts were not captured prospectively and are not reconstructed retrospectively. Appendix D lists the retained and unavailable audit fields.
Anonymization was manual and checked by the source organization. Names, counterparties, monetary values, document numbers, internal identifiers, personal identifiers, and sensitive operational details were removed, generalized, or content-adjusted, while clause structure, source hierarchy, temporal relations, and trace-relevant references were preserved. The released benchmark artifacts do not reproduce the original corporate documents.
The external validation set contains 414 cases with explicit normative contradictions, 214 cases with explicit priority relations, and 178 paired update cases for belief-revision testing. All baselines received the same normalized evidence fragments and the same query. Gold facts, rules, conflicts, priorities, expected statuses, adjudicated labels, and gold traces were withheld during inference. The cases were not used in prompts, few-shot examples, or the controlled validation set.
Two legally trained analysts independently annotated evidence spans, facts, rules, typed attacks, priority relations, expected status, and gold trace objects after a pilot calibration round. Disagreements were referred to a legal/domain expert designated by the source organization, and only the adjudicated object entered the scorer. Mandatory TNF edges were then generated algorithmically by Algorithm 4 rather than marked as a second subjective layer. The retained study metadata documents role-based legal training but not degrees or years of experience; the manuscript therefore makes no stronger qualification claim. Pre-adjudication edge-level agreement was not retained. Difficult cases and the operational annotation checklist are provided in Appendix B and Appendix D.
In Table 12, CLA and operational NER use the 414 gold-annotated contradiction cases as their denominator, PHA uses 214 priority cases, and BRA uses 178 paired updates. A system does not leave the NER denominator by omitting a conflict from its own trace. NER records the absence of unsupported, unrelated conclusions and is not interpreted causally. B4 has the highest observed values under the evaluated evidence-access, prompt, and scoring conditions.
Table 13 reports an additional descriptive comparison with reasoning-oriented external baselines. Under the operational adaptations used in this study, these approaches produced higher scores than citation-only answering, while their observed CLA, NER, and PHA values remained lower than those of B4. The adaptations are not complete reproductions of the original frameworks, and no paired significance tests were performed for B4 versus these external baselines.
Among the adapted external baselines, the DSPy-style pipeline was closest to B4. The descriptive B4-minus-DSPy differences were +8.6 percentage points for ASA, +15.9 for CLA, +8.7 for NER, +18.2 for PHA, and +11.8 for BRA. These are effect-size descriptions, not confirmatory architectural comparisons: the adaptations do not reproduce the original frameworks, and the study did not pre-specify paired tests for them. Confirmatory paired inference remains restricted to B4 versus B3.
Table 14 is included to make the result auditable rather than only aggregate. The trace-based configuration usually detects the relevant normative structure, but it can still fail when a support edge is rejected after identifier normalization, when the burden-of-proof node is attached to the wrong party, or when a conflict is localized at the document level rather than at the clause level required by the scorer.

6.4. Statistical Reliability and Cross-Model Validation

The external validation reports pre-adjudication agreement, 95% confidence intervals, paired tests, percentage-point effects, and multiple-comparison correction. Wilson intervals are used for binary case-level metrics. B4 TGC uses an edge-level bootstrap because its unit is a mandatory TNF edge. B4-versus-B3 comparisons use two-sided exact McNemar tests on paired binary outcomes for ASA, CLA, NER, PHA, and BRA. The five resulting p-values are adjusted by Benjamini–Hochberg at q = 0.05; Table 15 reports the adjusted q-values. Mandatory TNF edges are generated from the adjudicated trace rather than selected manually. Matched consistent-case UUCR and separate pre-adjudication edge-level agreement were not retained and are not claimed.
The agreement scores indicate that the scenario labels are reproducible enough for benchmark use while still reflecting the difficulty of real normative annotation. Priority relations remain the least stable layer, which matches the qualitative error analysis: priority direction often depends on source hierarchy, specificity, temporal order, or expert interpretation rather than on a surface lexical contradiction.
Table 16 separates the benchmark claim from a single model-family result. The same evidence packages and trace-output schema were used across GPT-, Claude-, Gemini-, and Llama-family assistants, and gold labels were withheld in all cases. Exact model or deployment identifiers used in the April 2026 runs are listed in the table and in Appendix A. The ordering should not be read as a final vendor ranking because deployment conditions, provider aliases, and model snapshots can change; its purpose is to show that the benchmark can compare assistant families on the same contradiction-aware metrics.

6.5. Prompt-Fairness, Repeated-Run Stability, and Efficiency Controls

The additional controls were conducted in April 2026 with the same gpt-5.2-2025-12-11 backbone, temperature = 0, top_p = 1, max_tokens = 4096, and seed 42 where supported. These parameters were fixed across control variants but were not assumed to make repeated API outputs identical. The external control subset was selected with seed 4418211 and stratified by source domain: 22 contract, 18 banking-guarantee, 20 compliance, 21 internal-policy, and 19 regulatory/legal cases. It contained 73 contradiction cases, 38 priority cases, and 31 paired update cases. No control case appeared in the held-out few-shot examples. Prompt-fairness results are summarized in Table 17, and repeated-run stability and efficiency controls are summarized in Table 18.
The fairness controls show that example count alone does not explain the trace-oriented difference. B3 improved when five examples were added, but B4-zero-shot remained higher on all five reported metrics. B3-five-shot and B4-compact used approximately matched total prompt/example budgets, while all variants shared the same backbone, evidence access, and common top-level fields. The compact B4 prompt produced the highest mean ASA, whereas B4-standard produced the highest CLA, NER, and BRA. These results support a narrow association between explicit trace requirements and diagnostic observability; they do not isolate a causal architecture effect. Prompt wording and trace-schema detail still contribute, and B1/B2 matched-five-shot variants were not evaluated.
Across five repeated runs, B4-standard had higher mean status accuracy and higher pairwise status agreement than B3-standard on both splits, so the mean rank ordering was stable for this B3-B4 comparison. B4 also required approximately twice as many input tokens and 3–4 additional seconds of median latency. Structured-output reliability remained high: the only hard failure occurred in one of 700 controlled B4 calls and was scored as incorrect.
The original one-run B4 result of 98.6% on controlled_140 and the five-run B4-standard mean of 87.9 ± 3.0% are not interchangeable because the repeated-run control used a harmonized common-v1 plus trace-v2 output contract. Monetary API cost is not reported because commercial pricing is provider- and contract-specific; token counts, latency, and a provider-neutral cost template are supplied instead. Repeated-run efficiency and JSON statistics were collected for B3/B4, not all B1-B4 configurations, and no cross-configuration rejected-edge percentage is claimed.

6.6. Deterministic Component-Dependency Audit

We performed a deterministic component-dependency audit on the B4 normalized representation and scorer. The audit asks which outputs are definitionally affected when a component is removed; it does not rerun or retrain an assistant and does not estimate a causal performance contribution. Quantitative rows from the earlier scorer-side ablation were removed because disabling a diagnostic check cannot, without an additional semantic transformation, be interpreted as changing model status accuracy. Prompt-fairness and repeated-run results in Section 6.5 remain the empirical controls.
Table 19 makes the dependency boundary explicit. Removing attack or priority edges removes the objects needed for CLA or PHA; disabling the operational NER diagnostic leaves STATUS unchanged; and removing TNF changes matching rather than model reasoning. The audit therefore supports transparency about scorer dependencies only. Empirical claims are based on the controlled, external, prompt-fairness, and repeated-run experiments, not on this deterministic audit.

6.7. Example Scenario

Consider a contract supply scenario as one instance of a broader normative reasoning task. The buyer asks whether a contractual penalty can be claimed for late delivery when the supplier invokes force majeure. The evidence package contains a penalty clause, a force majeure clause, a notification clause, and a clause excluding force majeure protection in cases of gross negligence. The extracted rules are: r1: Delay(x) => Penalty(x); r2: ForceMajeure(x) => not Penalty(x); r3: GrossNegligence(x) => Penalty(x). The priority relations are r2 > r1 and r3 > r2.
If the assistant concludes that Penalty(x) is accepted, the gold trace requires it to show not only support through r1, but also the attack through r2 and the defeat of r2 by r3. If r3 is omitted, the correct status may become rejected or undecidable. If r3 is present but lacks a source, the error is a grounding failure. If r3 has a source but r3 > r2 is not recognized, the error is a priority-handling failure. A citation-only system may cite the penalty clause and still miss the normative reason why the conclusion survives or fails.
The case illustrates why citation-level correctness is insufficient. A citation-only answer can point to the penalty clause and still be wrong if it ignores force majeure. It can also cite the force majeure clause and still be wrong if the gross-negligence exception defeats the force majeure attack. The trace-based evaluation therefore asks whether the assistant exposes all three layers: support, attack, and priority-based defeat.
In the gold trace, the answer is not accepted simply because a penalty clause exists. It is accepted only after the attack licensed by r2 is preserved and then neutralized by the higher-priority r3. If the assistant deletes the attack, CLA decreases; if it preserves the attack but ignores r3 > r2, PHA and ASA decrease; if it emits unrelated sanctions without a grounded argument while the trace is inconsistent, the operational NER decreases; and if it reaches the correct status through an unsupported rule, TGC decreases. This case-level analysis makes the benchmark auditable at the same granularity as the metrics.
The key row in Table 20 is the conflict row. ParaTraceBench does not treat the presence of both Penalty(x) and not Penalty(x) as a fatal parsing error. It treats it as a normatively meaningful state that must be preserved until priorities, exceptions, or lack of proof resolve the status. This is the practical role of paraconsistent trace semantics in the benchmark.

7. Reproducibility Package

The reproducibility package separates controlled data, prompts, scorer code, model/run metadata, raw and normalized outputs, annotation metadata, and result artifacts. The complete controlled suite is public. Original corporate documents and restricted external scenario text are not redistributed; consequently, the manuscript does not claim full independent reconstruction of every external-case result from public source documents. Release-permitted derived objects and aggregate artifacts support partial audit without exposing restricted context.
The public repository includes the controlled suite, B1-B4 and external-baseline prompts, scorer implementation, metrics tables, annotation protocol, agreement report, run manifest, anonymization notes, and release-permitted outputs. experiment_expansion_result.xlsx contains fairness, stability, efficiency, prompt, subset-manifest, run-level, case-registry, and provider-neutral cost sheets. The run manifest records model aliases, dates, parameters, and artifact availability. A versioned archival release is required before final publication; original corporate documents remain unavailable.

8. Discussion

ParaTraceBench reframes normative AI evaluation from answer checking to contradiction-aware behavior testing. This shift is important because high-stakes normative AI systems may fail even when they provide citations. A cited answer can still be normatively unreliable if the assistant ignores exceptions, collapses a conflict into a single unsupported answer, or fails to revise its conclusion after new evidence appears. This layered evaluation is consistent with risk-management guidance that requires evidence, measurement, and documented limitations for high-impact AI systems [27].
The framework is architecture-agnostic. ParaTraceBench evaluates black-box assistants through answers, citations, and update behavior, and it evaluates white-box or neuro-symbolic assistants more deeply through trace comparison. B4 demonstrates the full-trace evaluation path, while the LegalBench-RAG-, GraphRAG-, ReAct-, Self-Refine-, Tree-of-Thought-, and DSPy-style baselines test whether generic reasoning structures expose the same contradiction-aware artifacts.
A central design choice is the preservation of typed conflict/attack edges together with four-valued status labels. The dependency audit shows which metrics require these objects, while the prompt controls show that observed differences persist under zero-shot, matched-five-shot, compact-prompt, common-schema, and repeated-run conditions. Neither analysis isolates a causal architecture effect. Operational NER remains an output-level unsupported-conclusion measure rather than proof of logical paraconsistency.
The controlled validation, external reasoning-baseline comparison, prompt-fairness controls, repeated-run analysis, component-dependency audit, and external validation should be interpreted together. The controlled scenarios show that the metric suite detects known defects. The 567-case validation demonstrates applicability to anonymized practical cases. On the 100-case fairness subset, B4-zero-shot remained above B3-five-shot across ASA, CLA, NER, PHA, and BRA, and B4-standard showed higher pairwise status agreement. At the same time, B4 uses more tokens, has higher latency, remains sensitive to output-contract design, and was not compared with five-shot B1/B2 controls. The evidence supports diagnostic observability under the evaluated conditions, not jurisdiction-independent generality, end-to-end RAG performance, or a fully isolated causal architecture claim.
The sample-size and corpus-construction limitations should be interpreted carefully. ParaTraceBench is a dense, trace-annotated corpus of 567 expert-selected contradiction-rich scenarios from Russian Federation and EAEU-related materials, not a representative census. Each case includes evidence-span alignment, fact/rule extraction, conflict and priority annotation, conclusion-status adjudication, and gold-trace construction. Original-document length, source-format and OCR proportions, evidence-fragment distribution, and counts of excluded duplicate/near-duplicate source cases were not prospectively retained and cannot be reconstructed reliably from the anonymized scenario objects. The corpus should not be treated as representative of all legal domains, languages, jurisdictions, or document types.
Trace normal form is both a reproducibility mechanism and a limitation. It makes matching deterministic and allows equivalent grounded paths to receive credit, but worst-case minimal-subtrace enumeration is exponential, and the equivalence relation depends on the adjudicated scenario annotation protocol. Mandatory edges are algorithmically derived from that gold trace, yet separate pre-adjudication edge-level agreement was not retained. ParaTraceBench should therefore be interpreted as a benchmark for auditable contradiction-aware assistant behavior, not as a complete enumeration of every legal argument that an expert could construct from the same documents.
A further limitation is the fixed-evidence setting: retrieval recall and end-to-end RAG performance are not measured. Repeated-run controls cover B3/B4 on the controlled set and a stratified external subset rather than every configuration on all 567 cases. K_para is conceptual, matched consistent-case UUCR was not collected, and weighted NCR results are limited to the analytic example in Appendix C.5. Future work should add retrieval-enabled experiments, prospectively logged source/OCR and deduplication statistics, matched consistent controls, full repeated runs, additional jurisdictions and languages, and future model snapshots. The benchmark should be revalidated whenever model aliases or provider deployments change [27].

9. Conclusions

This paper introduced ParaTraceBench, a paraconsistent trace-based benchmarking framework for post-retrieval normative AI assistants operating under inconsistent, incomplete, and defeasible evidence. The main claim is that current evaluation protocols for RAG and AI assistants insufficiently test contradiction-aware normative behavior after evidence has been supplied. ParaTraceBench addresses this gap by representing each benchmark scenario as a structured package containing query, evidence, facts, rules, conflicts, priorities, expected conclusion status, and a gold diagnostic trace.
The resulting framework combines a single typed-edge attack model, explicit attack licensing and target selection, an acyclic priority base with transitive closure, least-grounded IN/OUT/UNDEC labeling, TNF matching, gold-conditioned operational NER, and correctness-gated robustness scoring. Controlled DLA is separated from external CLA, and the deterministic component audit is explicitly separated from empirical prompt and repeated-run controls.
A controlled validation on 140 cases provides evidence that a progression from citation-only baseline answering to self-checking, structured extraction, and trace-based reasoning can reveal defects that citation-level evaluation cannot localize. The external corpus contains 567 anonymized Russian-language cases from the Russian Federation and EAEU-related materials: B4 reached 85.7% ASA, 85.5% CLA, 94.2% operational NER, 84.1% PHA, and 83.7% BRA.
Under the separate five-run harmonized protocol, B4-standard reached 87.9 ± 3.0% ASA on the controlled set and 83.2 ± 3.3% on the external 100-case subset, compared with 77.0 ± 3.4% and 67.6 ± 3.5% for B3-standard. B4-zero-shot also remained above B3-five-shot on the five reported external-subset metrics. These results characterize diagnostic observability, run variability, and output-contract sensitivity; they do not establish causal superiority of an architecture, logical non-triviality, end-to-end retrieval performance, or generality beyond the evaluated corpus.

Author Contributions

Conceptualization, I.V.T., M.V.U., N.F.G. and A.S.V.; methodology, I.V.T. and M.V.U.; software, M.V.U. and A.V.C.; validation, I.V.T. and M.V.U.; formal analysis, I.V.T., M.V.U., A.S.V. and N.F.G.; investigation, all authors; writing—original draft preparation, M.V.U. and A.V.C.; writing—review and editing, all authors; visualization, M.V.U.; supervision, A.S.V. All authors have read and agreed to the published version of the manuscript.

Funding

This work was supported by the Ministry of Economic Development of the Russian Federation (IGK 000000C313925P4C0002), agreement No. 139-15-2025-010.

Institutional Review Board Statement

Ethical review and approval were waived because the study did not involve human participants, interventions, or the processing of identifiable personal data. The external validation materials were converted into anonymized and content-adjusted benchmark scenarios with permission from the source organization. Under the applicable institutional procedures, no separate ethics committee or legal approval was required for the use of these derived research artifacts.

Informed Consent Statement

Not applicable.

Data Availability Statement

The complete controlled validation suite, prompt templates, scorer implementation, raw and normalized outputs where release is permitted, metrics, run manifests, annotation protocol, inter-annotator agreement report, external-baseline result tables, cross-model result tables, anonymization notes, and experiment_expansion_result.xlsx are available at https://github.com/thecontrey/parabench (accessed on 12 August 2026). For the external corpus, only release-permitted derived scenario objects, outputs, and aggregate artifacts are public. Original corporate documents and restricted scenario text are unavailable because of organizational permission and confidentiality constraints; therefore, full source-level reconstruction of all 567 cases is not claimed.

Acknowledgments

The authors thank the source organization for confirming the permissible use of anonymized and content-adjusted scenario artifacts and for checking anonymization quality. The authors also thank the maintainers of the public software and benchmark resources used for comparison.

Conflicts of Interest

The authors declare no conflicts of interest.

Appendix A. Model Provenance and Inference Settings

To ensure reproducibility and transparency, the following parameters and constraints were maintained during the controlled validation, external real-world validation, external reasoning-baseline comparison, component-dependency audit, and cross-model trace-prompt phases.

Appendix A.1. Run Dates

Controlled validation (N = 140): 10 March 2026–25 March 2026.
External real-world validation (N = 567): 14 April 2026–17 May 2026.

Appendix A.2. Execution Environment

Environment: Python 3.11.8 environment using a custom internal API wrapper for standardized logging and error handling.
API provider: Azure OpenAI Service for the primary B1-B4 baseline runs using the same deployed model snapshot; cross-model auxiliary runs used the corresponding provider deployments recorded in the run manifest.
API version: deployment metadata recorded in the repository run manifest.
Region/deployment: recorded in the repository run manifest.

Appendix A.3. Model Identifiers

B1 (citation-only baseline): gpt-5.2-2025-12-11.
B2 (self-checking baseline): gpt-5.2-2025-12-11.
B3 (structured extraction): gpt-5.2-2025-12-11.
B4 (trace-based assistant): gpt-5.2-2025-12-11.
External reasoning baselines: LegalBench-RAG-style, GraphRAG-style evidence graph, ReAct-style, Self-Refine-style, Tree-of-Thought-style, and DSPy-style structured pipeline prompts were evaluated with the same external evidence packages and with gold labels withheld. Cross-model trace-prompt assistants were evaluated with the same external evidence packages and output schema. The April 2026 cross-model identifiers were: GPT-family: gpt-5.2-2025-12-11; Claude-family: claude-opus-4-20250514; Gemini-family: gemini-2.5-pro; Llama-family: llama-4-maverick-17b-128e-instruct. Provider aliases and deployment metadata were preserved in the run manifest when the API did not expose immutable build identifiers.
The primary B1-B4 comparison uses the same backbone and deterministic settings. The comparison should therefore be interpreted as a controlled validation of prompting strategy, trace representation, and output schema, rather than as a claim about model-family superiority.

Appendix A.4. Generation Parameters

temperature: 0.
top_p: 1.0.
max_tokens: 4096.
seed: 42, fixed where supported by the API.
frequency_penalty: 0.0.
presence_penalty: 0.0.

Appendix A.5. Runs

Number of runs per scenario: 1 for the main 567-case baseline evaluation. The additional control phase used five runs per configuration: B3-standard and B4-standard on all 140 controlled cases, and B3-standard, B3-five-shot, B4-standard, B4-zero-shot, and B4-compact on the stratified external 100-case subset. The repeated-run statistics report mean, sample standard deviation, all-five-run status stability, and pairwise status agreement.
Total controlled scenarios: 140.
Total external real-world scenarios: 567.
Total model calls: 8498 primary calls in the original controlled, full external, external-baseline, and cross-model phases, plus approximately 210 automated retries. The additional control phase added 3900 calls (1400 controlled-set calls and 2500 external-subset calls), 38 retries, and one hard structured-output failure. Component-dependency variants were computed deterministically from B4 normalized outputs and did not require additional LLM calls.

Appendix A.6. Prompting Strategy

B1 prompt: citation-only answer with final normative status.
B2 prompt: citation-only answer plus an explicit self-check block requiring the model to inspect for missing exceptions, contradictions, and unresolved uncertainty before finalizing the status.
B3 prompt: structured fact/rule extraction in JSON format plus final normative status.
B4 prompt: trace-based JSON output requiring explicit evidence IDs, facts, rules, conflicts, priorities, conclusion status, and trace edges.
External reasoning-baseline prompts: LegalBench-RAG-style grounded answer prompt; GraphRAG-style evidence-graph construction prompt; ReAct-style reasoning/action prompt; Self-Refine-style initial-feedback-revision prompt; Tree-of-Thought-style multi-path deliberation prompt; and DSPy-style modular extraction-checking-answer prompt.
Component-dependency protocol: deterministic component-dependency mapping on B4 normalized outputs and scorer pipeline; no manual correction; no additional gold labels; no additional LLM calls. This protocol is not a full system ablation of independently prompted assistants.
Few-shot examples used for B4: yes, five examples drawn from a held-out development set.
Prompt-fairness controls: B3-standard (0 examples; 1680 system-prompt tokens), B3-five-shot (5 examples; 1680 system + 3020 example tokens), B4-zero-shot (0 examples; 2460 system-prompt tokens), B4-compact (5 examples; 1110 system + 3480 example tokens), and B4-standard (5 examples; 2460 system + 3480 example tokens). All variants returned common-v1 top-level fields; B4 variants additionally returned trace-v2 fields.
External validation cases used in few-shot examples: no.
Controlled-validation cases used in few-shot examples: no.

Appendix A.7. Evidence Access Constraints

All baselines received the same normalized evidence fragments: yes.
Gold facts, rules, conflicts, priorities, statuses, and traces were hidden during inference: yes.
Retrieval was disabled and the evidence package was fixed to isolate reasoning, conflict handling, and trace validation from retrieval variance.

Appendix A.8. Output Handling and Scoring

Manual correction of outputs: no. Human intervention was prohibited during scoring.
JSON repair policy: deterministic only.
Applied repairs: trimming markdown code fences; evidence-ID normalization, such as mapping E_01 or Evidence 1 to canonical E-01; status-label canonicalization; conversion of attack records or provenance-event encodings to typed attack edges; and rejection of edges without a valid cited-source path. Rejected edges were retained in diagnostic logs but excluded from TGC and trace matching. Aggregate rejected-edge rates were not compared across B1-B4 because B1/B2 do not emit a commensurate edge schema.
Additional control reliability: valid JSON without repair ranged from 95.14% to 98.20% in the B3/B4 stability comparisons and from 97.40% to 98.20% across external prompt-fairness variants. Repair rates ranged from 1.80% to 4.71%. One hard failure occurred in 700 controlled B4-standard calls; it was not manually corrected and was scored as an incorrect output.
Scorer type: deterministic graph alignment script (src/scorer.py) comparing normalized assistant outputs against the gold scenario package.

Appendix A.9. Repository

Reproducibility package URL: https://github.com/thecontrey/parabench (accessed on 12 August 2026).
The public repository includes the controlled validation suite, prompt templates for B1-B4, external reasoning-baseline prompts, raw outputs and normalized traces where release is permitted, scorer implementation, metrics tables, annotation protocol, inter-annotator agreement report, run manifest, and anonymization notes. The additional control phase is documented in the single workbook experiment_expansion_result.xlsx. Original real-world corporate source documents are withheld from the public release. A versioned release tag and archival DOI can be provided upon acceptance for the public reproducibility artifacts.

Appendix B. Case Walkthroughs for Trace-Aware Scoring

The following compact walkthroughs illustrate how the external corpus is represented and why the benchmark scores trace quality rather than only the final answer. The examples are anonymized, simplified for publication, and do not reproduce any commercially sensitive source text.
Table A1. Contract penalty and force-majeure walkthrough.
LayerGold ObjectExpected Assistant BehaviorPrimary Metric Pressure
QueryCan the buyer claim a contractual penalty for late delivery?Return a status and expose the support/attack/defeat path rather than citing only the penalty clause.ASA, TGC
EvidencePenalty clause, force-majeure clause, notification clause, gross-negligence exception.Link every extracted fact and rule to an evidence fragment and clause-level identifier.TGC
Facts/rulesDelay(x); ForceMajeure(x); GrossNegligence(x); r1: Delay -> Penalty; r2: ForceMajeure -> not Penalty; r3: GrossNegligence defeats force majeure.Extract the competing rules without deleting the exception.TGC, CLA
Conflict/priorityr2 attacks Penalty(x); r3 > r2 deactivates the attack for status computation.Preserve the attack edge and mark it as defeated by priority.CLA, PHA
Gold statusacceptedConclude accepted only after showing that the force-majeure attack is preserved and then defeated.ASA, NER, NCR
Interpretation: a citation-only answer may be textually plausible but still unsafe if it cites the penalty clause and omits the force-majeure attack, or cites force majeure and omits the gross-negligence priority. ParaTraceBench therefore rewards the preserved conflict and the defeated attack, not merely the final accepted status.
Table A2. Banking-guarantee demand-form walkthrough.
LayerGold ObjectExpected Assistant BehaviorPrimary Metric Pressure
QueryMust the guarantor pay under a demand that was submitted after an amended deadline?Return a status that accounts for the original deadline, the addendum, and the formal demand requirements.ASA
EvidenceOriginal guarantee text, later addendum, demand notice, receipt log, and template clause with inconsistent numbering.Normalize old and new clause identifiers without losing the amended deadline.TGC
Facts/rulesDemandReceived(x); SubmittedAfterOriginalDeadline(x); AddendumExtendsDeadline(x); DemandFormIncomplete(x).Distinguish a timing conflict from a form-defect conflict.CLA
Conflict/priorityAddendum priority over original deadline; mandatory form requirement remains independently active.Apply temporal/document-version priority while keeping the form attack active.PHA
Gold statusboth or undecidable depending on form evidence completenessAvoid collapsing the case into a simple payable/not-payable answer when one attack is resolved and another remains evidentially incomplete.ASA, NER, BRA
Interpretation: the difficult layer is not retrieval of the addendum, but the separation of two normative mechanisms: temporal priority resolves the deadline conflict, whereas the demand-form requirement may still attack payment. This is why the case stresses priority handling and non-explosive status assignment.
Table A3. Internal-policy emergency-access walkthrough.
LayerGold ObjectExpected Assistant BehaviorPrimary Metric Pressure
QueryWas emergency access to a restricted system permissible without prior manager approval?Return a status and identify whether the emergency exception overrides the ordinary approval rule.ASA, PHA
EvidenceAccess-control policy, emergency-access appendix, incident ticket, post-fact approval record, and audit-log excerpt.Ground the ordinary prohibition, the exception, and the post-fact reporting duty separately.TGC
Facts/rulesRestrictedAccess(x); NoPriorApproval(x); EmergencyIncident(x); PostFactApprovalLogged(x); r1: no prior approval -> prohibited; r2: emergency incident -> permitted; r3: post-fact logging required.Represent permission and prohibition as competing normative conclusions rather than rewriting one away.CLA
Conflict/priorityEmergency exception defeats ordinary prior-approval prohibition only if incident and post-fact logging are both grounded.Use exception priority conditionally; do not infer general permission for unrelated accesses.PHA, NER
Gold statusaccepted if both emergency and post-fact logging are grounded; otherwise both or undecidableRevise the status if the post-fact approval record is removed or contradicted.BRA, NCR
Interpretation: This case tests whether the assistant can preserve an apparent policy contradiction while applying the emergency exception only under its grounded preconditions. If a later update removes the post-fact approval record, the expected status changes; this is directly evaluated by belief-revision accuracy.

Appendix C. Trace-Normal-Form Equivalence Examples

Appendix C.1. Equivalent Direct and Transport-Level Attack Encodings

Trace A contains the semantic edge attack(A_s, r_2, undercut) with licensing rule r_3 and source fragment E-04. Trace B serializes the same relation as an attack record with source_argument_id = A_s, target_type = rule, target_id = r_2, kind = undercut, licensing_rule_id = r_3, and source_fragment_id = E-04. During normalization the record in Trace B is converted into the same typed edge as Trace A. The traces are TNF-equivalent because their grounded source, target, attack kind, licensing rule, activity state, and STATUS effect are identical; the transport representation does not create an additional semantic node.

Appendix C.2. Equivalent Proof-Chain Variants

Trace A derives p by E-01 -> f_1, E-02 -> r_1, and (f_1,r_1) -> p. Trace B introduces a proof alias u with (f_1,r_1) -> u and u -> p, where u has no independent normative content and the same grounded source set. Canonicalization collapses the alias chain, and both traces yield the same support label, no active attack, and status accepted. They are credited as one equivalence class. By contrast, an alternative derivation through a different grounded exception is equivalent only when the adjudicated gold trace lists it as a status-preserving minimal alternative.

Appendix C.3. Non-Equivalent Trace

Suppose both traces preserve support for p and the rebutting attack licensed by r_2, but only Trace A contains the grounded priority edge r_3 > r_2 that neutralizes the attack. Trace A yields accepted, whereas Trace B yields both. The traces are not TNF-equivalent even if their final natural-language answers are similar, because the active/defeated attack state and STATUS effect differ. Likewise, omitting an evidence path, changing an undercut into a rebut, or targeting a different internal rule prevents equivalence.

Appendix C.4. Computational Scope

Enumerating all minimal status-preserving subtraces and all NCR edit subsets is exponential in the worst case. The benchmark constrains traces to compact scenario-level graphs and uses grounding reachability, semantic-effect pruning, canonical ordering, and memoized STATUS signatures. These engineering constraints make the released benchmark reproducible but do not turn the underlying combinatorial problems into polynomial-time procedures for arbitrary graphs.

Appendix C.5. NCR Cost-Sensitivity Example

Under unit costs, changing the priority edge r3 > r2 in the penalty example costs 1 and is the minimum status-flipping witness. If priority edits are assigned weight 2 while rule edits retain weight 1, the same witness costs 2 and ties a two-rule witness. If priority edits receive weight 3, the two-rule witness becomes cheaper. Uniform scaling changes only the numeric scale, whereas non-uniform weights can change the selected witness. For this reason, the reported NCR values are restricted to the stated unit-cost convention.

Appendix D. External Corpus and Annotation Protocol

Appendix D.1. Retained Corpus Audit Fields

The scenario registry retains scenario ID, source category, Russian Federation/EAEU-related scope, 2022–2026 time scope, contradiction flag, priority flag, paired-update membership, and experimental split. The benchmark unit is a query-centered scenario rather than a complete source document. Original-document page or character length, source-format and OCR flags, candidate-pool size, and exact duplicate/near-duplicate exclusion counts were not collected prospectively and are not reconstructed from anonymized objects.

Appendix D.2. Annotation and Adjudication Checklist

The operational checklist was: identify query-relevant spans; normalize evidence-linked facts and rules; type rebut, undercut, and undermine edges; annotate explicit priority bases; compute the grounded status; build the gold trace; compare the two independent analyst objects; adjudicate disagreements through the designated legal/domain expert; and derive mandatory TNF edges algorithmically. Difficult cases include implicit priority direction, partially inconsistent addenda, OCR-related clause-number noise, and document-level versus clause-level conflict localization. Role-based legal training is documented, but individual degrees and years of experience are not retained.

References

  1. Lewis, P.; Perez, E.; Piktus, A.; Petroni, F.; Karpukhin, V.; Goyal, N.; Küttler, H.; Lewis, M.; Yih, W.; Rocktäschel, T.; et al. Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks. Adv. Neural Inf. Process. Syst. 2020, 33, 9459–9474. [Google Scholar]
  2. Gao, Y.; Xiong, Y.; Gao, X.; Jia, K.; Pan, J.; Bi, Y.; Dai, Y.; Sun, J.; Wang, M.; Wang, H. Retrieval-Augmented Generation for Large Language Models: A Survey. arXiv 2024, arXiv:2312.10997. [Google Scholar] [CrossRef] [Scilit]
  3. Barnett, S.; Kurniawan, S.; Thudumu, S.; Brannelly, Z.; Abdelrazek, M. Seven Failure Points When Engineering a Retrieval Augmented Generation System. In Proceedings of the IEEE/ACM 3rd International Conference on AI Engineering, Lisbon, Portugal, 14–15 April 2024. [Google Scholar] [CrossRef] [Scilit]
  4. Guha, N.; Nyarko, J.; Ho, D.; Re, C.; Chilton, A.; Chohlas-Wood, A.; Peters, A.; Waldon, B.; Rockmore, D.; Zambrano, D.; et al. LegalBench: A Collaboratively Built Benchmark for Measuring Legal Reasoning in Large Language Models. In Proceedings of the Neural Information Processing Systems, New Orleans, LA, USA, 10–16 December 2023. [Google Scholar]
  5. Pipitone, N.; Houir Alami, G. LegalBench-RAG: A Benchmark for Retrieval-Augmented Generation in the Legal Domain. arXiv 2024, arXiv:2408.10343. [Google Scholar] [CrossRef] [Scilit]
  6. Zheng, L.; Guha, N.; Arifov, J.; Zhang, S.; Skreta, M.; Manning, C.D.; Henderson, P.; Ho, D.E. A Reasoning-Focused Legal Retrieval Benchmark. In Proceedings of the 2025 Symposium on Computer Science and Law, Munich, Germany, 25–27 March 2025; pp. 169–193. [Google Scholar] [CrossRef] [Scilit]
  7. Magesh, V.; Surani, F.; Dahl, M.; Suzgun, M.; Manning, C.D.; Ho, D.E. Hallucination-Free? Assessing the Reliability of Leading AI Legal Research Tools. J. Empir. Leg. Stud. 2025, 22, 216–242. [Google Scholar] [CrossRef] [Scilit]
  8. Koreeda, Y.; Manning, C.D. ContractNLI: A Dataset for Document-level Natural Language Inference for Contracts. In Findings of the Association for Computational Linguistics: EMNLP 2021; Association for Computational Linguistics: Stroudsburg, PA, USA, 2021; pp. 1907–1919. [Google Scholar] [CrossRef] [Scilit]
  9. Hendrycks, D.; Burns, C.; Chen, A.; Ball, S. CUAD: An Expert-Annotated NLP Dataset for Legal Contract Review. In Proceedings of the Neural Information Processing Systems (NeurIPS) Datasets and Benchmarks Track, Virtual, 5–14 December 2021. [Google Scholar]
  10. Wang, S.H.; Scardigli, A.; Tang, L.; Chen, W.; Levkin, D.; Chen, A.; Ball, S.; Woodside, T.; Zhang, O.; Hendrycks, D. MAUD: An Expert-Annotated Legal NLP Dataset for Merger Agreement Understanding. In Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing; Association for Computational Linguistics: Stroudsburg, PA, USA, 2023; pp. 16369–16382. [Google Scholar] [CrossRef] [Scilit]
  11. Jacovi, A.; Goldberg, Y. Towards Faithfully Interpretable NLP Systems: How Should We Define and Evaluate Faithfulness? In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, Online, 5–10 July 2020; pp. 4198–4205. [Google Scholar] [CrossRef] [Scilit]
  12. Maynez, J.; Narayan, S.; Bohnet, B.; McDonald, R. On Faithfulness and Factuality in Abstractive Summarization. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, Online, 5–10 July 2020; pp. 1906–1919. [Google Scholar] [CrossRef] [Scilit]
  13. Es, S.; James, J.; Espinosa-Anke, L.; Schockaert, S. RAGAS: Automated Evaluation of Retrieval Augmented Generation. In Proceedings of the European Chapter of the Association for Computational Linguistics: System Demonstrations; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024. [Google Scholar]
  14. Saad-Falcon, J.; Khattab, O.; Potts, C.; Zaharia, M. ARES: An Automated Evaluation Framework for Retrieval-Augmented Generation Systems. arXiv 2023, arXiv:2311.09476. [Google Scholar] [CrossRef] [Scilit]
  15. Dung, P.M. On the Acceptability of Arguments and Its Fundamental Role in Nonmonotonic Reasoning, Logic Programming and n-Person Games. Artif. Intell. 1995, 77, 321–357. [Google Scholar] [CrossRef] [Scilit]
  16. Baroni, P.; Caminada, M.; Giacomin, M. An Introduction to Argumentation Semantics. Knowl. Eng. Rev. 2011, 26, 365–410. [Google Scholar] [CrossRef] [Scilit]
  17. Prakken, H.; Sartor, G. Argument-Based Extended Logic Programming with Defeasible Priorities. J. Appl. Non-Class. Log. 1997, 7, 25–75. [Google Scholar] [CrossRef] [Scilit]
  18. Gordon, T.F.; Prakken, H.; Walton, D. The Carneades Model of Argument and Burden of Proof. Artif. Intell. 2007, 171, 875–896. [Google Scholar] [CrossRef] [Scilit]
  19. Belnap, N.D. A Useful Four-Valued Logic. In Modern Uses of Multiple-Valued Logic; Dunn, J.M., Epstein, G., Eds.; Springer: Dordrecht, The Netherlands, 1977; pp. 5–37. [Google Scholar]
  20. Priest, G.; Tanaka, K.; Weber, Z. Paraconsistent Logic. In Stanford Encyclopedia of Philosophy; Metaphysics Research Lab, Stanford University: Stanford, CA, USA, 2024. [Google Scholar]
  21. Edge, D.; Trinh, H.; Cheng, N.; Bradley, J.; Chao, A.; Mody, A.; Truitt, S.; Larson, J. From Local to Global: A Graph RAG Approach to Query-Focused Summarization. arXiv 2024, arXiv:2404.16130. [Google Scholar] [CrossRef] [Scilit]
  22. Yao, S.; Zhao, J.; Yu, D.; Du, N.; Shafran, I.; Narasimhan, K.; Cao, Y. ReAct: Synergizing Reasoning and Acting in Language Models. In Proceedings of the 11th International Conference on Learning Representations (ICLR), Kigali, Rwanda, 1–5 May 2023. [Google Scholar]
  23. Madaan, A.; Tandon, N.; Gupta, P.; Hallinan, S.; Gao, L.; Wiegreffe, S.; Alon, U.; Dziri, N.; Prabhumoye, S.; Yang, Y.; et al. Self-Refine: Iterative Refinement with Self-Feedback. arXiv 2023, arXiv:2303.17651. [Google Scholar] [CrossRef] [Scilit]
  24. Yao, S.; Yu, D.; Zhao, J.; Shafran, I.; Griffiths, T.L.; Cao, Y.; Narasimhan, K. Tree of Thoughts: Deliberate Problem Solving with Large Language Models. In Proceedings of the 36th Annual Conference on Neural Information Processing Systems (NeurIPS), New Orleans, LA, USA, 10–16 December 2023. [Google Scholar]
  25. Khattab, O.; Singhvi, A.; Maheshwari, P.; Zhang, Z.; Santhanam, K.; Haq, S.; Sharma, A.; Joshi, T.T.; Moazam, H.; Miller, H.; et al. DSPy: Compiling Declarative Language Model Calls into Self-Improving Pipelines. In Proceedings of the 12th International Conference on Learning Representations (ICLR), Vienna, Austria, 7–11 May 2024. [Google Scholar]
  26. Moreau, L.; Missier, P. PROV-DM: The PROV Data Model; W3C Recommendation; World Wide Web Consortium (W3C): Cambridge, MA, USA, 2013. [Google Scholar]
  27. Tabassi, E. Artificial Intelligence Risk Management Framework (AI RMF 1.0); NIST AI 100-1; National Institute of Standards and Technology: Gaithersburg, MD, USA, 2023. [CrossRef] [Scilit]
Figure 1. Deterministic ParaTraceBench scoring pipeline. Gold scenario packages and assistant outputs are normalized and grounding-validated, converted to trace normal form, evaluated under STATUS semantics, aligned, and scored with the full metric suite.
Ai 07 00321 g001
Table 1. Comparison of ParaTraceBench with selected strong benchmarks and RAG evaluation frameworks.
Benchmark/FrameworkPrimary Evaluation TargetMain Unit of AnnotationWhat It Does Not Evaluate DirectlyParaTraceBench Complement
LegalBench [4]General legal reasoning ability of LLMsTask instance and answer labelGrounded contradiction localization, priority defeat, non-explosion, and gold diagnostic tracesAdds trace-level evaluation under inconsistent normative evidence
LegalBench-RAG [5]Precise retrieval for legal RAGQuery and relevant legal snippetsWhether a retrieved contradiction is preserved and normatively resolvedAdds conflict, priority, status, and revision scoring after retrieval
ContractNLI [8]Contractual natural-language inferenceContract, hypothesis, entailment/contradiction/not-mentioned labelDefeasible rule priority, exception defeat, and assistant trace diagnosticsConnects contractual evidence to explicit facts, rules, attacks, and statuses
CUAD [9]Contract clause extractionClause category spansNormative conclusion status under conflicting clausesUses extracted clauses as evidence fragments for trace-based reasoning
MAUD [10]Merger agreement understanding and clause extractionExpert-labeled agreement provisionsContradiction-aware assistant behavior and belief revisionExtends clause understanding toward normative conflict evaluation
RAGAS [11]Automated RAG evaluationQuestion, context, answer, faithfulness/relevance scoresGold conflict traces, priority handling, and non-explosionAdds contradiction-specific diagnostic metrics to RAG evaluation
ARES [12]Automated RAG evaluation and scoringRAG outputs and evaluator modelsDeterministic graph comparison against facts, rules, conflicts, and prioritiesAdds structured, auditable scoring for inconsistent evidence cases
ParaTraceBenchNormative assistant behavior under inconsistent and defeasible evidenceQuery, evidence, facts, rules, conflicts, priorities, status, gold traceNot a substitute for domain-specific expert judgmentProvides contradiction-aware framework and controlled validation protocol
Table 2. ParaTraceBench scenario schema.
FieldDescriptionExample in Normative ReasoningEvaluation Role
queryUser question to the assistantCan an organization impose a penalty despite a force majeure claim?Defines target normative issue
evidence_fragmentsLegal, contractual, policy, regulatory, or ethical text spansPenalty clause; force majeure clause; internal policy exceptionGrounds facts and rules
factsAtomic propositions extracted from evidenceDelay, NoticeSent, ConsentObtained, SafetyRiskInput to formal reasoning
rulesExtracted legal, policy, contractual, or ethical rulesDelay implies penalty; safety exception overrides permissionDefines defeasible normative reasoning structure
conflictsExplicit attacks or inconsistent propositionsRule permits action; another rule prohibits itTests contradiction preservation
prioritiesPriority relations between rules or sourcesSpecific policy overrides general guideline; later rule overrides earlier ruleTests defeasible reasoning
expected_statusExpected normative statusaccepted, rejected, both, undecidableTarget for answer-status scoring
gold_traceGold diagnostic traceEvidence -> fact -> rule -> conflict -> priority -> statusEnables trace-level scoring
Table 3. Baseline assistant configurations and equal evidence-access constraints.
ConfigurationCapabilitiesInference InputWithheld During InferenceExpected Weakness Under Inconsistency
B1: citation-only baselineAnswer generation and source citation over the supplied evidence packageq + identical evidence fragments EF, R, C, P, y, T_gold, defect labelsMay cite a relevant source while ignoring exceptions or conflicts
B2: self-checking baselineCitation-based answering plus a self-check for missing evidence and contradictionsq + identical evidence fragments EF, R, C, P, y, T_gold, defect labelsMay verbalize conflicts but fail to preserve deterministic diagnostic trace
B3: structured extractionExtracts facts and rules before answeringq + identical evidence fragments EF, R, C, P, y, T_gold, defect labelsMay detect rules but lose the path needed for localization
B4: trace-based assistantExtracts facts, rules, conflicts, priorities, status, and diagnostic traceq + identical evidence fragments EF, R, C, P, y, T_gold, defect labelsDesigned to support localization, priority handling, and non-explosion but can still fail when evidence or priority cues are underspecified
Table 4. External reasoning baselines and equal evidence-access constraints.
BaselineOperational Adaptation in This StudyEvidence AccessExpected Limitation Under ParaTraceBench
LegalBench-RAG-styleAnswer with legal-style retrieval grounding and final status; no required conflict graphq + identical ECan retrieve/cite relevant clauses but may not preserve conflict and priority structure
GraphRAG-style evidence graphBuilds an evidence-level entity/relation graph before answer generationq + identical EImproves cross-fragment linking but does not by itself compute attack/defeat status
ReAct-styleInterleaves reasoning steps and evidence inspection actions before final statusq + identical EMay reason over exceptions but trace steps are not mandatory graph objects
Self-Refine-styleInitial answer, self-feedback for missing exceptions/conflicts, then revised answerq + identical ECan correct some omissions but may rationalize rather than localize conflict
Tree-of-Thought-styleGenerates several candidate normative paths and selects one by self-evaluationq + identical EExplores alternatives but may collapse both-supported-and-attacked cases into a single path
DSPy-style structured pipelineComposable extraction, checking, and answer modules optimized to the metric promptq + identical EImproves structure but lacks explicit paraconsistent status and priority-defeat semantics unless added
Table 5. Benchmark metrics for contradiction-aware normative AI assistants.
MetricFormula or DefinitionWhat It Evaluates
Answer Status Accuracy (ASA)N(correct status)/N(all)Whether the assistant selects the correct normative conclusion status
Trace Grounding Completeness (TGC)verified mandatory TNF edges/mandatory gold TNF edgesGrounded required trace edges; equivalent derivation paths are accepted
Contradiction Localization Accuracy (CLA)N(correct conflict layer)/N(conflict cases)Whether the assistant identifies the source of inconsistency
Operational Non-Explosion Rate (NER)1 − N(inconsistent cases with unsupported-unrelated conclusions)/N(inconsistent cases)Output-level avoidance of unsupported unrelated conclusions under inconsistency; not a proof of logical explosion resistance
Priority Handling Accuracy (PHA)N(correct priority application)/N(priority cases)Whether exceptions and priority rules are applied correctly
Belief Revision Accuracy (BRA)N(correct revised status)/N(update cases)Whether the assistant revises its answer under new evidence
Normative Conclusion Robustness (NCR)Mean correctness-gated minimum edit cost; wrong status = 0; no-flip case = |Delta_N| + 1Correctness-conditioned semantic status robustness under the stated finite edit set
Defect Localization Accuracy (DLA)N(correct injected defect class)/N(defective controlled cases)Controlled-suite localization of injected pipeline defects; not used as external CLA
Table 6. Controlled validation scenario suite.
Scenario ClassNumber of CasesInjected DefectExpected Benchmark Signal
No defect20NoneAccepted trace and correct status
Missing evidence fragment20Relevant clause or norm removedLow grounding and missing coverage
Incomplete query coverage20One target element omittedLower trace completeness and possible unsupported status
Extraction error20Fact or rule incorrectly extractedGrounding or rule consistency failure
Priority inversion20Defeasible priority reversedConflict-preservation failure; operational NER decreases only if unsupported outputs are also emitted
Attack edge deletion20Conflict relation removedContradiction preservation and operational unsupported-conclusion failure
Invalid proof node20Unsupported node added to traceTrace validation failure
Table 7. Controlled comparison of four baseline configurations.
MethodAnswer Status AccuracyDefect Localization Accuracy (DLA)Operational Unsupported-Conclusion Evaluation
B1: citation-only baseline
(gpt-5.2-2025-12-11)
28.6%
(40/140)
0%
(0/120)
Not explicit
B2: self-checking baseline
(gpt-5.2-2025-12-11)
61.4%
(86/140)
43.3%
(52/120)
Self-check only
B3: structured extraction
(gpt-5.2-2025-12-11)
76.4%
(107/140)
66.7%
(80/120)
Partial
B4: trace-based assistant
(gpt-5.2-2025-12-11)
98.6%
(138/140)
90.8%
(109/120)
Explicit
Table 8. B4 answer-status confusion matrix for the controlled validation set.
Gold Status/Predicted StatusAcceptedRejectedBothUndecidableRow Total
accepted3901040
rejected0350035
both0034135
undecidable0003030
column total39353531140
Table 9. Representative B4 errors in the controlled validation set.
Case IdentifierGold StatusB4 Output StatusFailure MechanismAffected Metrics
CV-P20-07acceptedbothThe assistant extracted both the penalty rule and force majeure attack, but did not activate the gross-negligence priority r3 > r2. The conflict was preserved, but the attack was not defeated.ASA, PHA, NCR
CV-AE-14bothundecidableThe assistant detected an attack edge but failed to ground the supporting rule in an evidence fragment after normalization. The strict scorer rejected the unsupported support path.ASA, TGC, DLA
Table 10. B4 defect-class localization analysis.
Defect ClassCasesCorrectly Localized by B4Localization RateCommon Residual Failure
Missing evidence fragment201995%One case was reported as incomplete query coverage because the missing fragment also removed a target element.
Incomplete query coverage201890%Two cases were treated as missing support rather than omitted target coverage.
Extraction error201995%One fact/rule extraction error was hidden by a compensating but overly general rule.
Priority inversion201785%Three cases preserved the conflict but did not identify the direction of the priority inversion.
Attack edge deletion201890%Two cases were classified as undecidable rather than conflict-preservation failures.
Invalid proof node201890%Two unsupported proof nodes were removed during normalization, reducing explicit defect visibility.
Total defective cases12010990.8%Residual errors are concentrated in priority direction and boundary cases between missing evidence and incomplete coverage.
Table 11. External validation corpus distribution and construction protocol.
Source TypeCasesShareSampling/Inclusion Role
Contracts12421.9%Contractual duties, penalties, exceptions, addenda, and clause conflicts
Banking guarantees10117.8%Demand-form requirements, deadlines, independence-principle interactions, amended terms
Compliance11219.8%Internal and regulatory compliance duties, sanctions, disclosures, ownership and threshold ambiguity
Internal policies12021.2%Policy hierarchy, emergency exceptions, approvals, audit and access-control conflicts
Regulatory/legal materials11019.4%Regulatory triggers, statutory or quasi-statutory norms, EAEU-related cross-source conflicts
Total567100.0% total; displayed category shares sum to 100.1% because of one-decimal roundingExpert-selected contradiction-rich and trace-annotated external validation corpus
Table 12. External validation results on 567 anonymized real-world Russian-language normative cases.
MetricB1: Citation-OnlyB2: Self-CheckB3: Structured ExtractionB4: Trace-Based
ASA29.5% (167/567)57.1% (324/567)73.4% (416/567)85.7% (486/567)
TGC8.0%33.1%63.0%86.1%
CLA12.1% (50/414)46.9% (194/414)65.7% (272/414)85.5% (354/414)
NER44.9% (186/414)67.1% (278/414)79.0% (327/414)94.2% (390/414)
PHA10.7% (23/214)36.4% (78/214)62.1% (133/214)84.1% (180/214)
BRA29.2% (52/178)57.3% (102/178)70.8% (126/178)83.7% (149/178)
NCR0.91.52.23.5
Table 13. External validation against reasoning-oriented external baselines on the same 567-case corpus.
MethodASACLANERPHABRA
LegalBench-RAG-style63.1% (358/567)50.0% (207/414)72.2% (299/414)42.5% (91/214)58.4% (104/178)
GraphRAG-style evidence graph74.3% (421/567)67.1% (278/414)83.6% (346/414)62.1% (133/214)67.4% (120/178)
ReAct-style68.3% (387/567)56.3% (233/414)76.6% (317/414)52.3% (112/214)63.5% (113/178)
Self-Refine-style72.0% (408/567)61.4% (254/414)81.2% (336/414)58.4% (125/214)66.3% (118/178)
Tree-of-Thought-style73.7% (418/567)64.5% (267/414)82.9% (343/414)60.7% (130/214)69.1% (123/178)
DSPy-style structured pipeline77.1% (437/567)69.6% (288/414)85.5% (354/414)65.9% (141/214)71.9% (128/178)
B4 trace-based reference85.7% (486/567)85.5% (354/414)94.2% (390/414)84.1% (180/214)83.7% (149/178)
Table 14. Representative B4 errors in the external validation set.
Case IDDomainGold StatusB4 StatusFailure MechanismAffected Metrics
CN-002ContractsbothacceptedA support edge was rejected after evidence-ID normalization because the citation used the old appendix number.ASA; TGC/CLA/PHA/NCR depending on edge
BG-007Banking guaranteesacceptedundecidableA support edge was rejected after evidence-ID normalization because the citation used the old appendix number.ASA; TGC/CLA/PHA/NCR depending on edge
CP-004ComplianceacceptedbothThe exception was identified, but the burden-of-proof node was attached to the wrong party.ASA; TGC/CLA/PHA/NCR depending on edge
IP-001Internal policyacceptedundecidableA support edge was rejected after evidence-ID normalization because the citation used the old appendix number.ASA; TGC/CLA/PHA/NCR depending on edge
RL-015Regulatory/legalundecidablerejectedA conflict was localized at document level, not at the clause level required by the scorer.ASA; TGC/CLA/PHA/NCR depending on edge
Table 15. Statistical reliability and annotation-agreement checks for the external validation.
Validation ItemResultScopeInterpretation
Cohen kappa: conclusion status0.84567 casessubstantial-to-near-perfect agreement
Krippendorff alpha: conclusion status0.82567 casesstable status annotation
Cohen kappa: conflict layer0.80414 contradiction casessubstantial agreement
Cohen kappa: priority relation0.76214 priority caseshardest label; acceptable after adjudication
Evidence-span alignment F10.88all evidence fragmentshigh but affected by OCR and boundary noise
ASA 95% CI by baselineB1 [25.8;33.3], B2 [53.0;61.2], B3 [69.6;76.8], B4 [82.6;88.4]567 casesWilson intervals for case-level status correctness
CLA 95% CI by baselineB1 [9.3;15.6], B2 [42.1;51.7], B3 [61.0;70.1], B4 [81.8;88.6]414 contradiction casesWilson intervals for conflict localization
NER 95% CI by baselineB1 [40.2;49.7], B2 [62.5;71.5], B3 [74.8;82.6], B4 [91.5;96.1]414 contradiction casesWilson intervals for non-explosion
PHA 95% CI by baselineB1 [7.3;15.6], B2 [30.3;43.1], B3 [55.5;68.4], B4 [78.6;88.4]214 priority casesWilson intervals for priority handling
BRA 95% CI by baselineB1 [23.0;36.3], B2 [50.0;64.3], B3 [63.7;77.0], B4 [77.6;88.4]178 paired update casesWilson intervals for belief revision
B4 TGC 95% CI[84.3;87.8]edge-level bootstrapreported for trace-grounding completeness
B4 vs. B3 ASABH-adjusted q < 0.001; +12.3 pp137 B4-only correct vs. 67 B3-only correctMcNemar paired comparison
B4 vs. B3 CLABH-adjusted q < 0.001; +19.8 pp414 contradiction casespaired improvement after correction
B4 vs. B3 NERBH-adjusted q < 0.001; +15.2 pp414 contradiction casespaired improvement in operational unsupported-conclusion avoidance
B4 vs. B3 PHABH-adjusted q < 0.001; +22.0 pp214 priority casespaired improvement after correction
B4 vs. B3 BRABH-adjusted q = 0.006; +12.9 pp178 update pairspaired improvement after correction
Multiple-comparison correctionBenjamini–Hochberg q = 0.05ASA, CLA, NER, PHA, BRAall five B4-vs-B3 claims remain significant
Table 16. Cross-model trace-prompt comparison on the same 567-case external validation set.
Model Family/Snapshot Used in April 2026 RunsASACLANERPHABRA
GPT-family
(gpt-5.2-2025-12-11)
85.7% (486/567)85.5% (354/414)94.2% (390/414)84.1% (180/214)83.7% (149/178)
Claude-family
(claude-opus-4-20250514)
82.5% (468/567)82.4% (341/414)90.3% (374/414)80.4% (172/214)80.9% (144/178)
Gemini-family
(gemini-2.5-pro)
76.5% (434/567)75.8% (314/414)84.3% (349/414)75.7% (162/214)75.3% (134/178)
Llama-family
(llama-4-maverick-17b-128e-instruct)
69.7% (395/567)69.6% (288/414)76.6% (317/414)68.2% (146/214)67.4% (120/178)
Table 17. Five-run prompt-fairness controls on external_100 (mean ± SD, %).
ConfigurationFew-ShotOutput SchemaASACLANERPHABRA
B3-standard0common-v167.6 ± 3.564.1 ± 7.078.6 ± 3.262.1 ± 4.867.7 ± 4.0
B3-five-shot5common-v174.2 ± 5.469.9 ± 3.284.7 ± 3.674.7 ± 8.268.4 ± 7.7
B4-zero-shot0trace-v2 + common-v179.4 ± 3.283.3 ± 4.292.9 ± 2.576.8 ± 6.380.7 ± 7.9
B4-compact5trace-v2 + common-v185.2 ± 4.384.1 ± 4.591.8 ± 2.979.5 ± 4.776.8 ± 4.2
B4-standard5trace-v2 + common-v183.2 ± 3.390.4 ± 4.594.5 ± 3.579.0 ± 6.589.0 ± 6.7
Table 18. Five-run stability and efficiency controls for B3-standard and B4-standard.
Split/ConfigurationASA Mean ± SDSame Status, All 5 RunsMean Pairwise Status AgreementMedian/p95 Latency, sMean Input/Output TokensValid JSON/Repaired/Hard Failure
controlled_140/B3-standard77.0 ± 3.4%31.4%61.9%5.105/5.8043367/56197.29%/2.71%/0%
controlled_140/B4-standard87.9 ± 3.0%53.6%78.1%8.294/9.1417628/108295.14%/4.71%/0.14%
external_100/B3-standard67.6 ± 3.5%19.0%51.0%5.437/6.2334142/56298.20%/1.80%/0%
external_100/B4-standard83.2 ± 3.3%43.0%70.9%8.668/9.5838407/108797.60%/2.40%/0%
Table 19. Deterministic component-dependency audit of the trace/scoring representation.
Audit VariantDeterministic TransformationStatus EffectDirectly Affected MetricsPermitted Interpretation
Full representationNoneDefinedAll metrics definedDependency map only; not a causal ablation
No priority/defeat edgesKeep every grounded attack activeMay changeTGC lacks priority edges; PHA unavailable; BRA may changeTests dependence on explicit priority/defeat relations
No conflict/attack edgesRemove typed attacks from the normalized traceMay changeTGC lacks attacks; CLA and PHA unavailable; BRA may changeTests conflict and defeat observability
No operational NER scorerSkip the unsupported-output checkUnchangedNER unavailable; all other metrics unchangedDiagnostic removal cannot change model status
No TNF alignmentRequire exact canonical edge identityUnchangedTGC, CLA, and PHA may under-credit equivalent tracesTests matching dependence, not assistant reasoning
No trace graphObserve only answer, citations, facts, and rulesAnswer status observableTrace metrics partial or unavailable; BRA remains observableNot equivalent to an independently prompted B3 system
Table 20. Example paraconsistent diagnostic trace for a normative scenario.
Trace LayerGold ObjectPossible Assistant FailureBenchmark Metric Affected
EvidencePenalty, force majeure, notice, gross negligence clausesMissing exception clauseTGC, ASA
FactsDelay, ForceMajeure, NoticeSent, GrossNegligenceFact omitted or unsupportedTGC, CLA
Rulesr1, r2, r3Exception rule not extractedASA, PHA
ConflictPenalty vs. not PenaltyConflict hidden or flattenedCLA, NER
Priorityr2 > r1; r3 > r2Priority inverted or ignoredPHA, ASA
ConclusionPenalty accepted only if r3 defeats r2Arbitrary or unsupported conclusionASA, NER, NCR
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.