


Abstract
Traditional learning curve theory assumes a constant learning rate regardless of the number of units produced. However, a collection of theoretical and empirical evidence indicates that learning rates decrease as more units are produced in some cases. These diminishing learning rates cause traditional learning curves to underestimate required resources, potentially resulting in cost overruns. A diminishing learning rate model, namely Boone’s learning curve, was recently developed to model this phenomenon. This research confirms that Boone’s learning curve systematically reduced error in modeling observed learning curves using production data from 169 Department of Defense end-items. However, high amounts of variability in error reduction precluded concluding the degree to which Boone’s learning curve reduced error on average. This research further justifies the necessity of a diminishing learning rate forecasting model and assesses a potential solution to model diminishing learning rates.
1. Introduction
The U.S. Government Accountability Office (GAO) critiqued the cost and schedule performance of the Department of Defense (DoD)’s $1.7 trillion portfolio of 86 major weapons systems in their 2018 “Weapons System Annual Assessment.” The GAO cited realistic cost estimates as a reason for the relatively low cost growth of the portfolio in comparison to earlier portfolios [1]. Congress and its oversight committees maintain a watchful eye on the DoD’s complex and expensive weapons system portfolio. Inefficient programs are scrutinized and may be terminated if inefficiencies persist. Funding of inefficient programs will also lead to the underfunding of other programs. In the public sector, these terminated and underfunded programs may result in capability gaps that negatively impact our nation’s defense. In the private sector, the inefficient use of resources often spells failure for a company.
A key to the efficient use of resources is accurately estimating the resources required to produce an end-item. Learning curves are a popular method of forecasting required resources as they predict end-item costs using the item’s sequential unit number in the production line. Learning curves are especially useful when estimating the required resources for complex products. The most popular learning curve models used in the government sector are over 80 years old and may be outdated in today’s technology-rich production environment. Additionally, researchers have demonstrated both theoretically and empirically that the effects of learning slow or cease over time [2,3,4].
A new model, named Boone’s learning curve, has been recently proposed to account for diminishing rates of learning as more units are produced [5]. The purpose of this research is to survey the need for alternative learning curve models and further examine how Boone’s learning curve performs in comparison to the traditional learning curve theories in predicting required resources. This research uses a large number of diverse production items to compare Boone’s model to the traditional theories of Wright and Crawford. While many different learning curve models exist (i.e., DeJong, Stanford B, Sigmoid, etc.), some of these others may not be as accurate in cases where the learning rate decreases over time. The next section is a review of the learning curve literature relevant to diminishing learning rates, followed by a description of our methodology and analysis to compare Boone’s learning curve to traditional models. We conclude the paper discussing managerial implications and limitations followed by recommendations for the way forward.
2. Literature Review and Background
The two learning curve models cited by the GAO Cost Estimating and Assessment Guide (2009) are Wright’s cumulative average learning curve theory developed in 1936 and Crawford’s unit learning curve theory developed in 1947. Although both learning curve theories use the same general equation, the theories have contrasting variable definitions. Wright’s learning curve is shown in Equation (1):
where is the cumulative average cost of the first x units, A is the theoretical cost to produce the first unit, x is the cumulative number of units produced, and b is the natural logarithm of the learning curve slope (LCS) divided by the natural logarithm of two. Note, the LCS is the complement of the percent decrease in cost as the number of units produced doubles. For example, with a learning curve slope of 80% and a first unit cost of 100 labor hours, the average cost of the first two units would be 80 labor hours, or 60 labor hours for the second unit. Regardless of the number of units produced, there is a constant decrease in labor costs with each doubling of units due to the constant learning rate.
Several years following the creation of Wright’s cumulative average learning curve theory, J.R. Crawford formulated the unit learning curve theory. Crawford’s theory deviates from Wright’s by assuming that the individual unit cost (as opposed the cumulative average unit cost) decreases by a constant percentage as the number of units produced doubles. Crawford’s model is shown in Equation (2):
where Y is the individual cost of unit x, A is the theoretical cost of the first unit, x is the unit number of the unit cost being forecasted, and b is the natural logarithm of the LCS divided by the natural logarithm of two. For example, with a learning curve slope of 80% and a first unit cost of 100 labor hours, the cost of the second unit would be 80 labor hours. Note, Crawford’s unit theory is the similar to Wright’s in function form; but the difference arises in the variable interpretation lead to a different forecast.
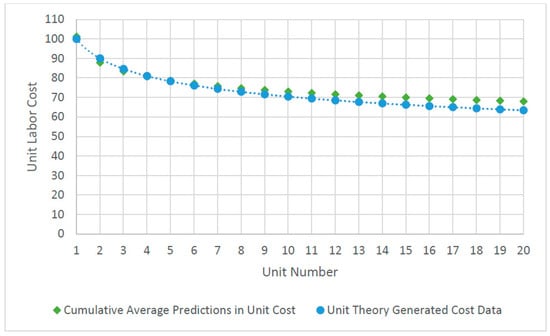
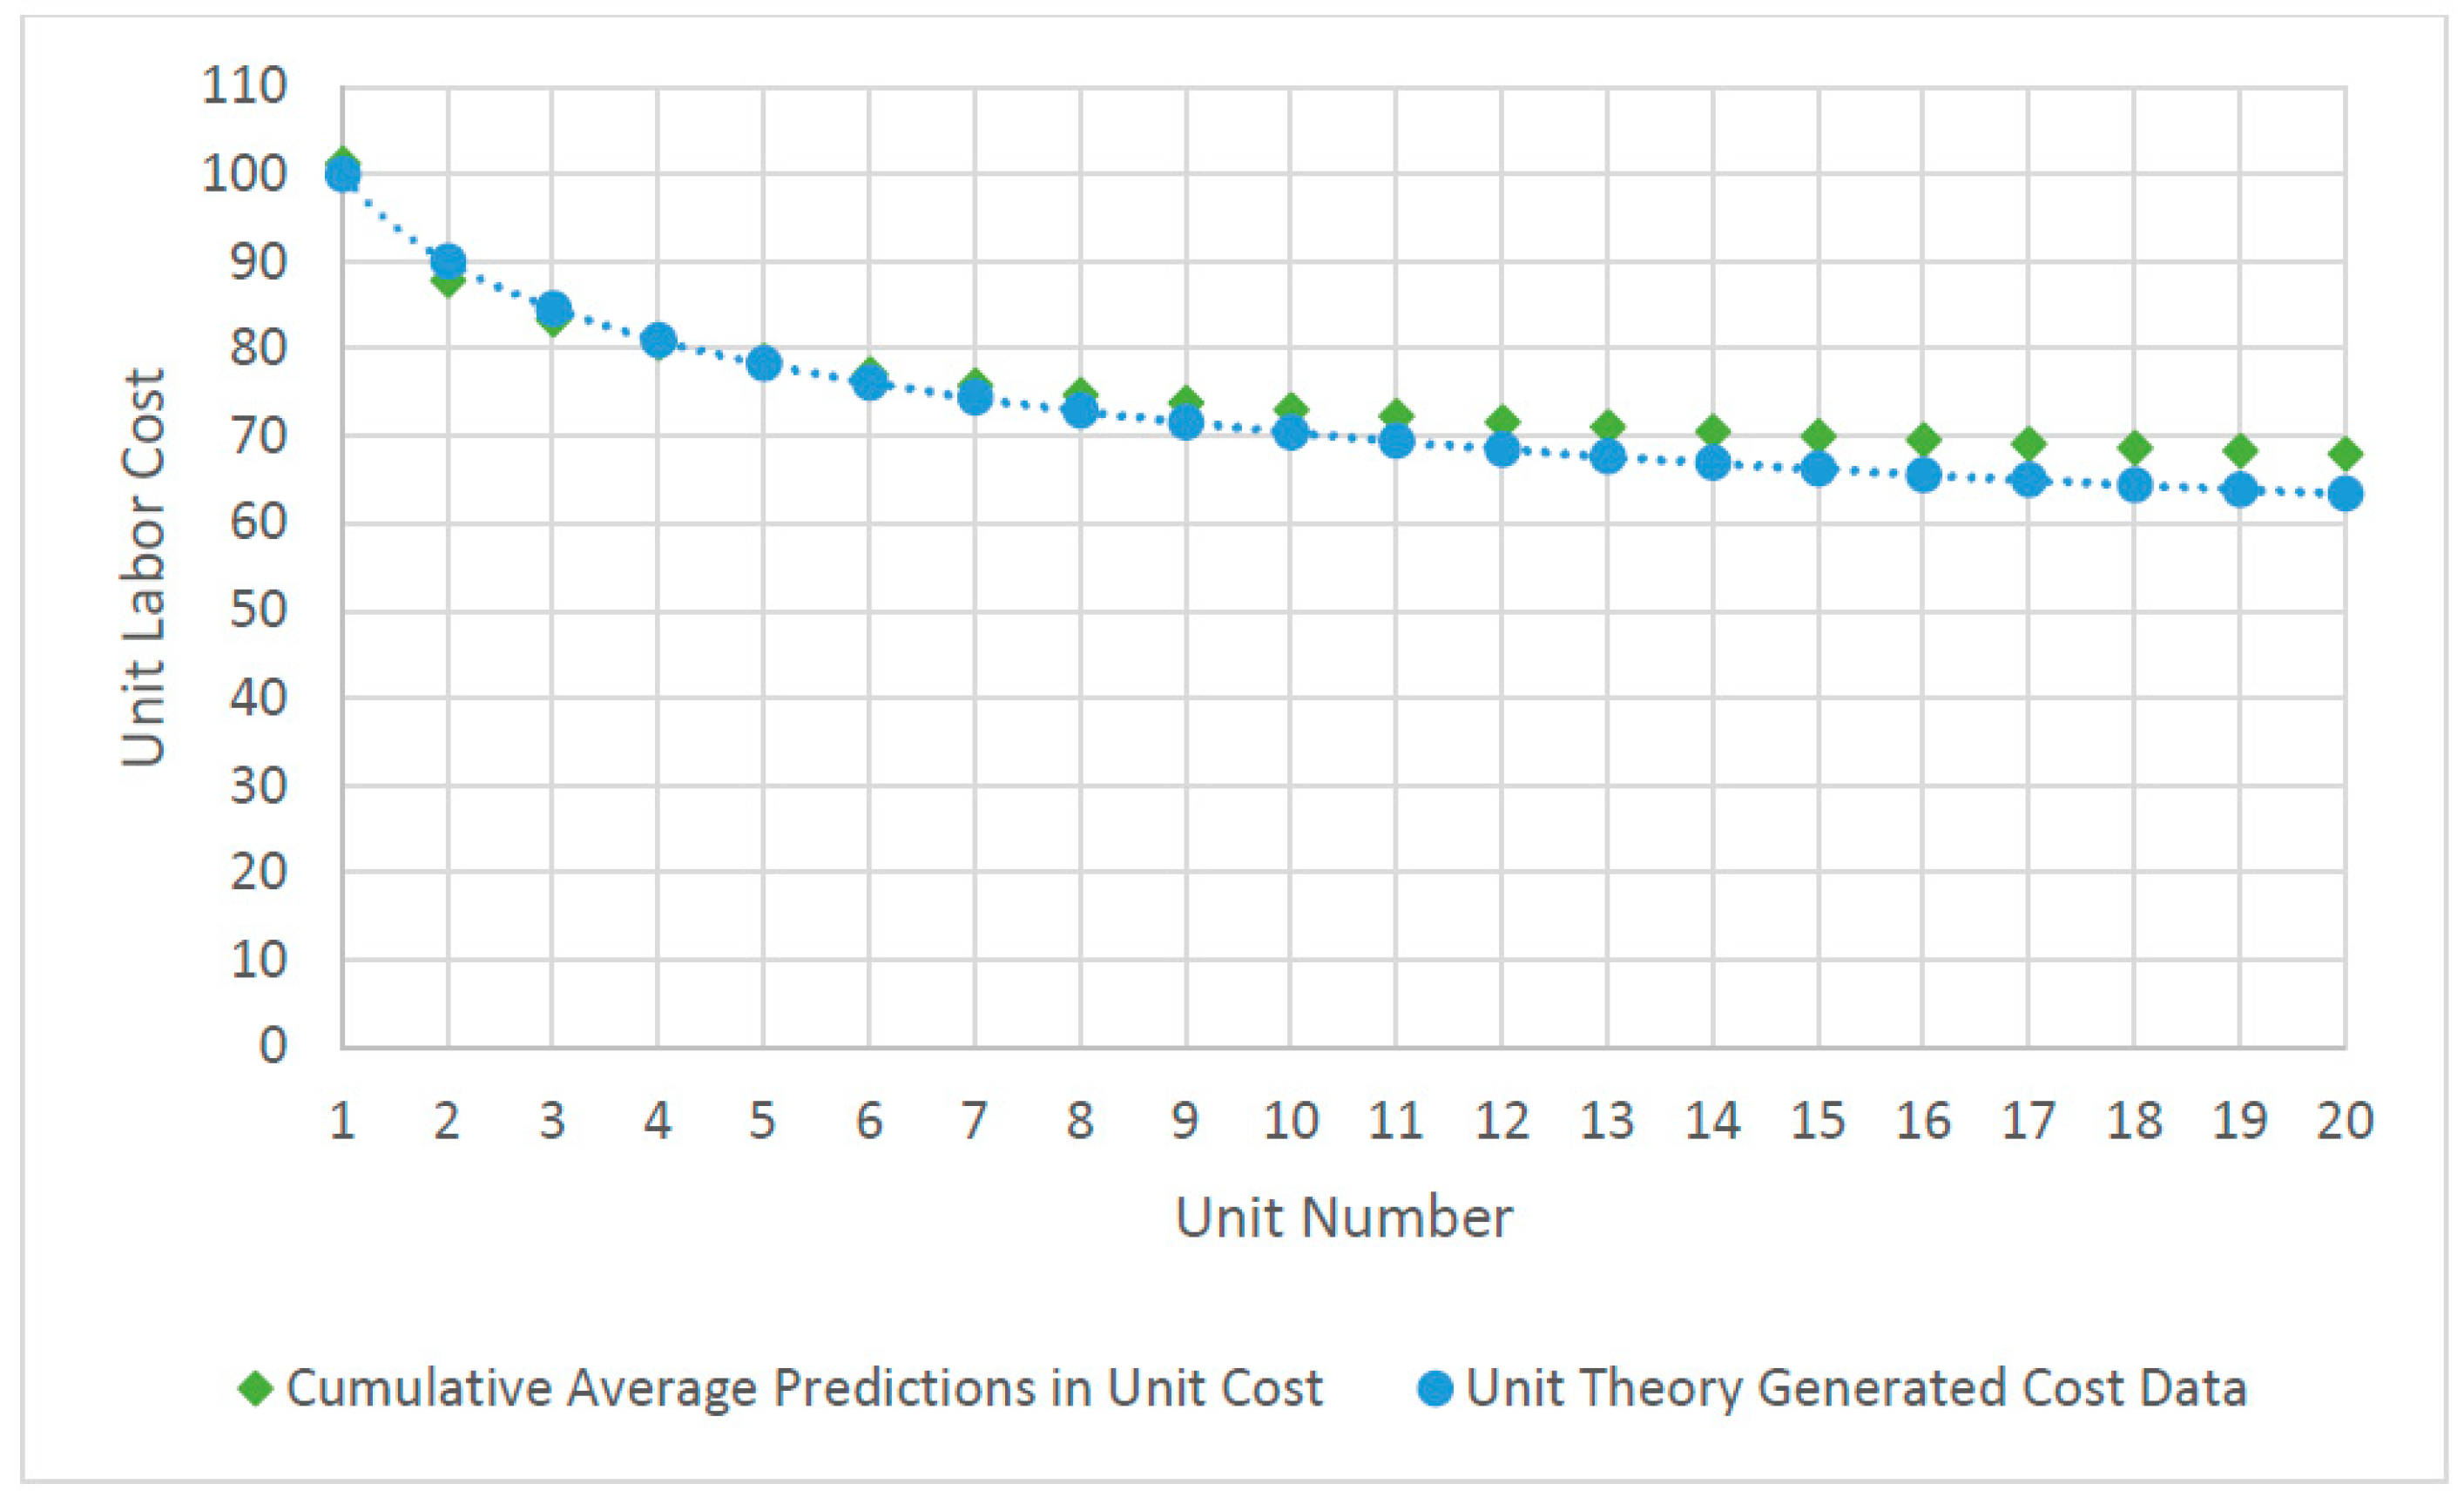
Figure 1 below shows a comparison between Wright’s and Crawford’s theories using the two numerical examples provided. Cumulative average theory and unit theory will produce different predicted costs provided the same set of data despite all predicted costs being normalized to unit costs. Figure 1 demonstrates this point where unit theory was used to generate data using a first unit cost of 100 and a learning curve slope of 90%. The original unit theory data was converted to cumulative averages in order to estimate cumulative average theory learning curve parameters.
Figure 1.
Wright’s Cumulative Average Theory vs. Crawford’s Unit Theory.
Cumulative average theory learning curve parameters. Cumulative average theory estimated a learning curve slope of 93% and a first unit cost of 101.24. These Cumulative Average Theory parameters were then used to predict cumulative average costs. These predicted costs were then converted to unit costs. This conversion allows for the cumulative average predictions to be directly compared to the original Unit Theory generated data. As shown in Figure 1, the cumulative average learning curve predictions first overestimate, then underestimate, and ultimately overestimate the generated unit theory data for all remaining units. Together, Wright’s and Crawford’s theories form the basis of the traditional learning curve theory.
One assumption of these traditional learning curve theories is that they only apply to processes that may benefit from learning. Typically, these costs are only a subset of total program costs; hence appropriate costs must be considered when applying learning curve theory to yield viable parameter estimates. In a complex program, costs can be viewed in a variety of ways to include recurring and non-recurring costs, direct and indirect costs, and costs for various activities and combinations of end-items that can be stated in units of hours or dollars. Learning curve analysis focuses solely on recurring costs in estimating parameters because these costs are incurred repeatedly for each unit produced [6]. Researchers have also focused solely on direct labor costs due to the theoretical underpinnings of learning occurring at the laborer level [2,3]. Additionally, researchers have historically studied end-items that include only the manufactured or assembled hardware and software elements of the end-item [2,3]. Lastly, labor hours in lieu of labor dollars are generally used in analysis so that data can be compared across fiscal years without the need to adjust for inflation. Therefore, the literature indicates using direct, recurring, labor costs in units of labor hours. These costs should be considered only for the certain elements that include the manufacturing or assembly of hardware and software of an end-item.
An implicit assumption in the traditional learning curve theories is that knowledge obtained through learning does not depreciate. However, empirical evidence demonstrates that knowledge depreciates in organizations [7,8]. Argote [7] showed that knowledge depreciation occurs at both the individual and the organizational levels. Many variations of the traditional models make use of the concept of performance decay (commonly called forgetting) to model non-constant rates of learning. Forgetting and its relationship to learning can take many forms and is essential to consider in contemporary learning curve analysis.
Forgetting is the concept that an individual or organization will experience a decline in performance over time resulting in non-constant rates of learning. Badiru [4] theorizes that forgetting and resulting performance decay is a result of factors “including lack of training, reduced retention of skills, lapse in performance, extended breaks in practice, and natural forgetting” (p. 287). According to Badiru [4], these factors may be caused by internal processes or external factors. Badiru [4] lists three cases in which forgetting arises. First, forgetting may occur continuously as a worker or organization progresses down the learning curve due in part to natural forgetting [4]. The impact of forgetting may not wholly eclipse the impact of learning but will hamper the learning rate while performance continues to increase at a slower rate. Second, forgetting may occur at distinct and bounded intervals, such as during a scheduled production break [4] or towards the end of production as workers are transferred to other duties. Finally, forgetting may intermittently occur at random times and for stochastic intervals such as during times of employee turnover [4]. Others have expanded on the causes of forgetting and have drawn similar conclusions to Badiru [4,9,10,11]. This decline in performance decays the learning rate and causes longer manufacturing times and higher costs than would be forecasted using traditional learning curve theory.
The concept of forgetting and its impact on non-constant rates of learning has proven relevant in contemporary learning curve research. Several forgetting models have been developed to include the learn-forget curve model (LFCM) [11], the recency model (RCM) [12], the power integration and diffusion (PID) model [13], and the Depletion-Power-Integration-Latency (DPIL) model [13] among others [10]. However, these forgetting models focus solely on the phenomenon of forgetting due to interruptions of the production process [9,10,14]. Jaber [9] states that “there has been no model developed for industrial settings that considers forgetting as a result of factors other than production breaks” (pp. 30–31) and mentions this as a potential area of future research. Although forgetting models have emerged after Jaber’s [9] article, a review of the popular forgetting models cited confirms Jaber’s statement.
A related concept to the forgetting phenomenon is the plateauing phenomenon. According to Jaber [9] (2006), plateauing occurs when the learning process ceases and manufacturing enters a production steady state. This ceasing of learning results in a flattening or partial flattening of the learning curve corresponding to rates of learning at or near zero. There remains debate as to when plateauing occurs in the production process or if learning ever ceases completely [3,9,15,16,17]. Jaber [9] provides several explanations to describe the plateauing phenomenon that include concepts related to forgetting. Baloff [18,19] recognized that plateauing is more likely to occur when capital is used in the production process as opposed to labor. According to some researchers, plateauing can be explained by either having to process the efficiencies learned before making additional improvements along the learning curve or to forgetting altogether [20]. According to other researchers, plateauing can be caused by labor ceasing to learn or management’s unwillingness to invest in capital to foster induced learning [21]. Related to this underinvestment to foster induced learning, management’s doubt as to whether learning efficiencies related to learning can occur is cited as another hindrance to constant rates of learning [22]. Li and Rajagopalan [23] investigated these explanations and concluded that no empirical evidence supports or contradicts them while ascribing plateauing to depreciation in knowledge or forgetting. Jaber [9] concludes that “there is no tangible consensus among researchers as to what causes learning curves to plateau” and alludes that this is a topic for future research (pp. 30–39).
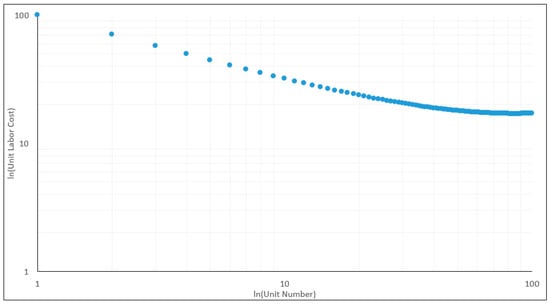
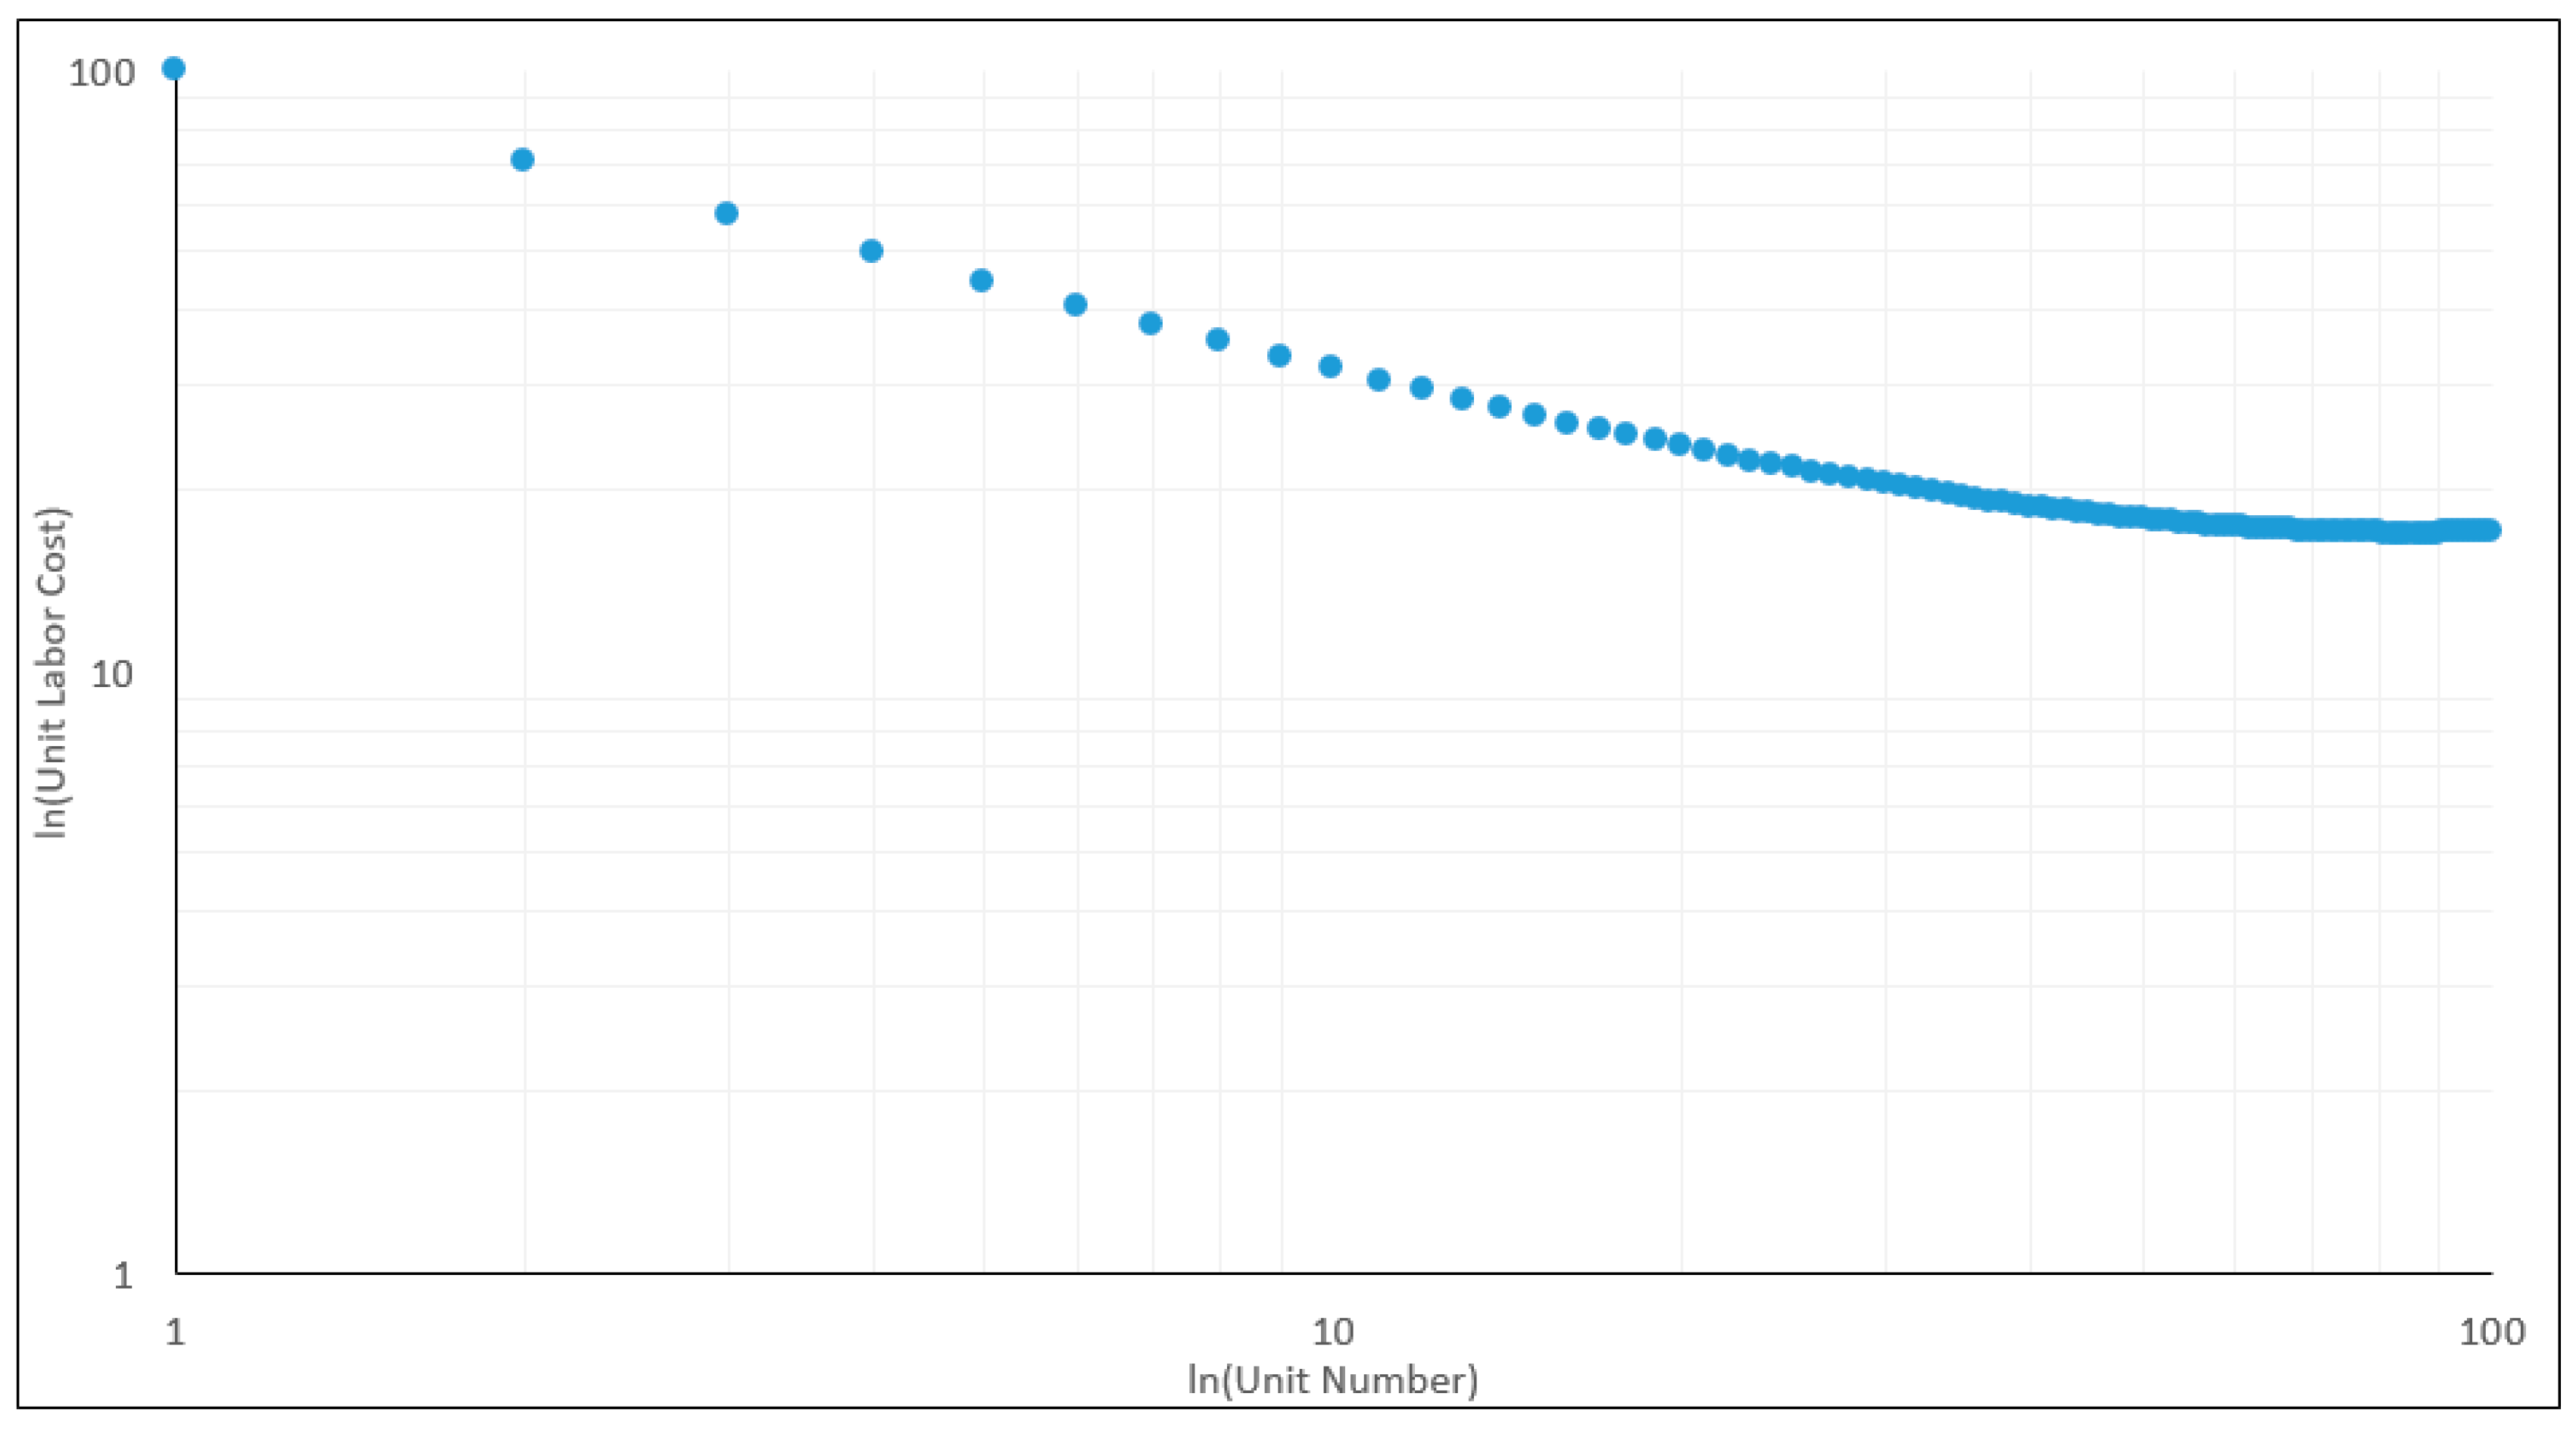
Despite the controversy in the research surrounding forgetting and plateauing effects, empirical studies have shown learning curves to exhibit diminishing rates of learning. For instance, the plateauing phenomenon at the tail end of production was investigated by Harold Asher in a 1956 RAND study. The U.S. Air Force contracted RAND after the service noticed traditional learning curves were underestimating labor costs at the tail end of production [3]. Asher intended to study if the logarithmically transformed traditional learning curves were approximately linear. This linearity would indicate constant rates of learning throughout the production cycle. The alternative hypothesis for these learning curves was a convexity of the logarithmically-transformed traditional learning curves that would indicate diminishing rates of learning as the number of units increased [3]. An example of a learning curve with a diminishing learning rate is shown in Figure 2 in logarithmic scale. The first unit cost is 100 with an initial learning curve slope of 80% decaying at a rate of 0.25% with each additional unit. For example, the second unit’s learning curve slope is 80.25%.
Figure 2.
Unit Theory learning curve with a Decaying Learning Curve Slope.
Asher investigated this hypothesis of convex logarithmically transformed learning curves by analyzing the learning curves of the various shops within a manufacturing department producing aircraft. Asher used airframe cost data with the appropriate amount of detail to perform a learning curve analysis on the lower level job shops within the manufacturing department. He divided the eleven major kinds of aircraft manufacturing operations into four shop groups each with a set of direct labor cost data [3]. If non-constant rates of learning were present, the shop group curves would differ in their rates of learning and may themselves be convex in logarithmic scale. This would indicate their aggregate learning curve would also be convex in logarithmic scale.
Asher’s results showed that the learning curves of the manufacturing shop group had different learning slopes and were convex in logarithmic scale [3]. Asher claims the convexity within the manufacturing shop group learning curves is due to the disparate operations within the job shops and stated that each had their own unique learning curve [3]. He asserts that a linear approximation is reasonable for a relatively small quantity of airframes produced but becomes increasingly unwarranted for larger quantities. This is due in part because larger quantities of produced end-items are likely to experience diminishing rates of learning. Moreover, highly aggregated learning curves are also likely to experience diminishing rates of learning. Because the aggregated manufacturing cost curve is usually the lowest level of detail on which learning curve analysis is performed, the manufacturing cost curve will have diminishing rates of learning as cumulative output increases. These results further justify a learning curve model with diminishing rates of learning.
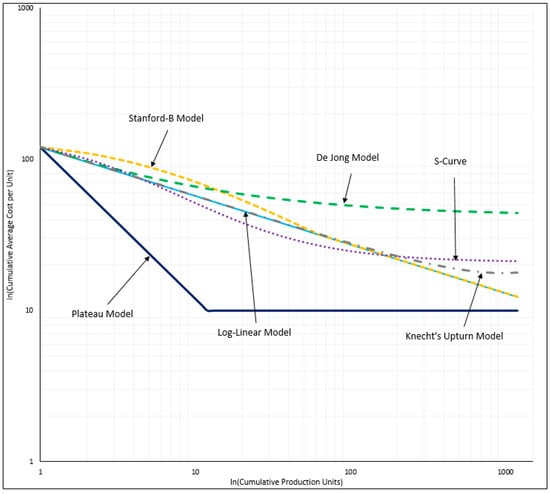
Wright’s and Crawford’s learning curve theories provided the basis of the traditional approach that learning occurs at a constant rate as the number of units produced increases. Since this initial discovery, several log-linear learning curve models were founded in attempts to more accurately model data from manufacturing processes. These contemporary models diverge from constant rates of learning by including adjustments in various forms. The six most popular models (including the traditional model) are shown in Figure 3 in logarithmic scale and include log-log graphing lines to more clearly illustrate the differences between models. These illustrated models include the traditional log-linear model or Wright/Crawford curves, the plateau model [19], the Stanford-B model [24], the De Jong model [25], the S-curve model [21], and Knecht’s upturn model [26].
Figure 3.
Comparison of Learning Curve Models (adapted from Badiru [27]).
Recent studies have investigated whether the Stanford-B, De Jong, and S-Curve models more accurately predict program costs in comparison to the traditional theories. Moore [16] and Honious [17] studied how prior experience in the manufacturing of an end-item along with the proportion of touch labor in the manufacturing process affected the accuracy of the Stanford-B, De Jong, and S-curve models in comparison to the traditional models. The authors concluded that these models improved upon the traditional curves for only a narrow range of parameter values. Their research provided insight that the traditional learning curve models become less accurate at the tail-end of production when the proportion of human labor is high in the manufacturing process. Moreover, Honious [17] explicitly references a plateauing effect at the end of production. These findings provide further justification for investigating non-constant rates of learning.
The Stanford-B, De Jong, and S-Curve univariate models illustrated in Figure 3 alter the resulting learning curve slope based on alterations to the theoretical first unit cost parameter A. However, the learning curve slopes of these models are not directly a function of the number of cumulative units produced. The plateau model and Knecht’s upturn model also illustrated in Figure 3 each produce a learning curve whose slope is directly affected by the number of cumulative units produced. The plateau model uses a step function to reduce the learning rate to 0% (i.e., the learning curve slope is 100%) past a certain number of cumulative units produced. In contrast, Knecht’s Upturn Model amends the learning curve exponent term b by multiplying b by Euler’s number e raised to the term of a constant multiplied by the number of cumulative units produced. Mathematically, this is expressed , where is the cumulative average unit cost, A is the theoretical first unit cost, x is the number of cumulative units produced, b is the natural logarithm of the learning curve slope divided by the natural logarithm of 2, and c is a constant. The forgetting models stated within the manuscript also amend the learning curve slope based indirectly on the number of cumulative units but only apply when interruptions to the production process occur.
In response to these researchers’ findings, Boone [5] developed a learning curve model with a learning rate that diminishes as more units are produced. Conversely, the traditional learning curve theories diminish the rate of cost reductions as the number of units produced doubles. However, the existing literature provides evidence that the cost reductions with each doubling of units may not be constant as the number of units produced increases. Therefore, Boone [5] sought to attenuate the cost reductions that occur with each doubling of units produced by decreasing the learning rate as the number of units increases.
Boone [5] devised a model that decreases the learning curve exponent b as the number of units produced x increases. He first considered a model without an additional parameter to reduce the learning curve exponent b directly by the unit number. However, he decided to temper the effect each additional unit has on the parameter b by adding an additional parameter c. The resulting learning curve is shown in Equation (3):
where is the cumulative average cost of the first x units, A is the theoretical cost to produce the first unit, x is the cumulative number of units produced, b is the natural logarithm of the learning curve slope (LCS) divided by the natural logarithm of two, and c is a positive decay value. For example, a learning curve slope of 80%, first unit cost of 100 labor hours, and decay value of 100, Boone’s model yields a cumulative average cost at the second unit of 80.35 labor hours—or 60.70 labor hours for the second unit. What began as an 80% learning curve model has decayed to an 80.35% learning curve for the second unit. In comparison to Wright’s learning curve using the same parameters, the effect of learning has decreased slightly in the production of unit two. The inclusion of the decay value increases the learning curve slope, and hence decreases the learning rate as more units are produced. Note, Boone’s model can also be modified to incorporate Crawford’s unit theory–refer to Equation (3) for the necessary modifications.
Boone’s learning curve diverges from the constant learning assumptions in both Wright’s and Crawford’s learning curve models by incorporating the unit number in the denominator of the exponent—thus decreasing the effect of b as the number of units produced increases. Furthermore, the decay value moderates this diminishing effect, so the amount of learning decreases more slowly. In general, Boone’s model is flatter near the end of production and steeper in the early stages compared to the traditional theories. Note, as the decay value approaches zero (holding other factors constant), the exponent term approaches zero representing a learning curve slope approaching 100%. As the decay value approaches infinity, the parameter b remains constant, and Boone’s learning curve simplifies to the traditional learning curve [5].
Boone [5] tested his learning curve using unit theory to provide a consistent comparison to Crawford’s learning curve. Based on the scope of his research and lack of comparison using cumulative average theory, a more robust examination and analysis of Boone’s learning curve should be accomplished.
3. Methodology
One goal of this research is to examine the accuracy of Boone’s learning curve in comparison to the popular Wright and Crawford learning curve theories. In order to perform this analysis, production cost and quantity data from a diverse set of DoD systems was collected from government Functional Cost-Hour Reports, Progress Curve Reports, and the Air Force Life Cycle Management Center Cost Research Library. The dataset consisted of recurring costs (either in dollars or labor hours) by production lot for 169 unique end-items. Our data included end-items from a variety of systems (i.e., bomber, cargo, and fighter aircraft, missiles, and munitions), contractors, and time periods (1957–2018). Additionally, only production runs with at least four lots were included. The dataset for the Cumulative Average Theory analysis only includes 140 of the 169 end-items. This theory relies on continuous data because each lot’s cumulative average cost and cumulative quantity is a function of all previous lots’ costs and quantities. In order to compare Boone’s model to the traditional theories, each model will be fitted to data: (1) Boone’s and Wright’s models using cumulative average theory, and (2) Boone’s and Crawford’s models using unit theory. Then, the predicted values for each model will be compared to the actual costs using root mean squared error (RMSE) and mean absolute percentage error (MAPE).
Labor costs were collected from the work breakdown structure (WBS) for the specific item being manufactured (e.g., aircraft frame) or from the documentation provided by the government. Our data included three broad functional cost categories: labor, material, and other. These costs are included in both forms of recurring and non-recurring costs. There are also four functional labor categories delineated that include manufacturing, tooling, engineering, and quality control labor. These four labor category costs, when summed with the material costs and other costs, comprise the total cost for each WBS element for recurring and non-recurring costs.
The definition for the manufacturing labor cost category most clearly aligns with the extant literature to be the focus as the pertinent labor cost category for learning curve research. According to the WBS elements, the manufacturing labor category “includes the effort and costs expended in the fabrication, assembly, integration, and functional testing of a product or end item. It involves all the processes necessary to convert raw materials into finished items [28].” This manufacturing labor category aligns with the categories examined by Wright, which he called “assembly operations [2],” along with those cost categories Crawford studied, which he called “airframe-manufacturing processes [3].” Therefore, the manufacturing labor cost category as defined by the government is associated with the types of labor costs studied by traditional learning curve theorists and succeeding research.
The learning curve parameters for each model (i.e., Equations (1)–(3)) will be estimated by minimizing the sum of squares error (SSE) using Excel’s generalized reduced gradient (GRG) nonlinear solver and evolutionary solver. The SSE is calculated by squaring the vertical difference of the observed data and predicted data for each lot and summing these squared differences across all lots.
With lot data, cumulative theory models can be estimated directly. Conversely, when utilizing unit learning curve theory, Crawford’s and Boone’s models are estimated using an iterative process based on lot midpoints, adapted from Hu and Smith [29]. The algebraic lot midpoint is defined as “the theoretical unit whose cost is equal to the average unit cost for that lot on the learning curve” [6]. The lot midpoint supplants using sequential unit numbers when using lot cost data.
Lot midpoints and model parameters are calculated iteratively due to the lack of a closed-form solution for the lot midpoint. First, an initial lot midpoint (for each lot) is determined using a parameter-free approximation formula [6]—see Equation (4):
where F is the first unit number in a lot and L is the last unit number in a lot. These lot midpoint estimates are then used to estimate the learning curve parameters for Crawford’s model (Equation (2)) using the GRG non-linear optimization algorithm. Next, using the estimated parameter b, a new set of lot midpoints are determined using a simple and popular formula—Asher’s Approximation [6]; see Equation (5):
where F is the first unit number in a lot, L is the last unit number in a lot, and b is the estimated value from Equation (2). Learning curve parameters will then be re-estimated using these more precise lot midpoint estimates. The iterative process is repeated until changes between successive values of the estimated lot midpoints and b are sufficiently small [29] (see Appendix A for a summary of this process). In order to use an iterative process for Boone’s model, Asher’s Approximation from Equation (5) was adapted to incorporate Boone’s decaying learning curve slope. This adaptation allows the lot costs of Boone’s learning curve to decrease as more units are produced which affects the lot midpoint estimates; the formula is shown in Equation (6):
where F is the first unit number in a lot, L is the last unit number in a lot, and i is the iteration number.
This iterative process of calculating the lot mid-point then solving a non-linear least squares problem requires the execution of a series of non-linear optimization algorithms. Boone’s model requires the GRG algorithm which found solutions in a longer but still reasonable amount of time. While more burdensome than the traditional models due to the longer run time and the requirement to provide bounds for the parameters. For Boone’s model, the bounds for A and b have a fairly straightforward basis by which to define the bounds. In practice, the A parameter is often supported by a point estimate of the cost of the first theoretical unit. Thus, a bound can be built around this value with tools such as a confidence interval. The b parameter is defined by the learning curve slope which for all practical purposes will be in the (0, 1) interval—most likely on the higher end. As for the c parameter, the basis for the bound is more of a challenge. From a model implementation standpoint, the bound can be arbitrarily large if a long solve time is not limiting. Practically, the bound should be reasonably set; this aspect of the model is an avenue of future research which is discussed in the conclusion. This algorithm does allow the analyst to define stopping conditions such as convergence threshold, maximum number of iterations, or maximum amount of time. Additionally, there is an option called multi-start which uses multiple initial solutions to help locate a global solution verse possibly only finding a local solution. These options allow the user to mitigate the extra burden if necessary. Overall, the computing burden to calculate these models was on the order of minutes per weapon system.
The final estimated parameters for Boone’s model and the traditional learning curves were used to create predicted learning curves. These predicted curves were then compared to observed data. Total model error was calculated by comparing the difference between observations and predicted values to understand how accurately the models explained variability in the data. Two measures were used to determine the overall model error. The first error measure was Root Mean Square Error (RMSE) that is calculated by taking the square root of the total SSE divided by the number of lots. RMSE is not robust to outliers—i.e., the effects of outliers may unduly influence this measure. RMSE is often interpreted as the average amount of error of the model as stated in the model’s original units.
The second measure was mean absolute percentage error (MAPE). MAPE is calculated by subtracting the predicted value from the observed value, dividing this difference by the observed value, taking the absolute value, and multiplying by 100%. These absolute percent errors are then summed over all observations and divided by the total number of observations. MAPE provides a unit-less measure of accuracy and is interpreted as the average percent of model inaccuracy. Unlike RMSE, MAPE is robust to outliers.
After calculating these measures of overall model error, a series of paired difference t-tests are conducted to determine if reductions in error from Boone’s learning curve are statistically significant. In order to conduct the first paired difference t-test, Boone’s learning curve RMSE using cumulative average theory will be subtracted from Wright’s learning curve RMSE, and the difference will be divided by Wright’s learning curve RMSE. This calculation will yield a percentage difference rather than raw difference to compare end-items of varying differences in magnitude equitably. The null hypothesis posits that Boone’s learning curve results in an equal amount (or more) of error in predicting observed values compared to Wright’s learning curve. The alternative hypothesis is that the percentage difference is greater than zero. Support for the alternative hypothesis signifies that Boone’s learning curve results in less error predicting observed values than Wright’s learning curve. This methodology will be repeated five times to examine each learning curve theory using the two error measures and the different units of production costs—see Table 1.
Table 1.
Paired Difference Hypothesis Tests Conducted.
An assumption to utilize the paired difference t-test is that the data are approximately normally distributed. For hypothesis tests with large sample sizes, the central limit theorem can be invoked. Alternatively, a Shapiro–Wilk test will be used to evaluate the normality assumption for small samples. If the Shapiro–Wilk test does not support the normality assumption, the non-parametric Wilcoxon Rank Sum test will be used. A 0.05 level of significance will be used for all statistical tests.
4. Analysis & Results
The detailed results for Wright’s and Boone’s learning curves using cumulative average theory are provided in Appendix B Table A1 and Table A2. A total of 118 end-items in units of total dollars and 22 components in units of labor hours were analyzed. Each entry lists the program number, number of production lots, number of items produced, type of end-item, and units of the production costs. Additionally, each entry lists both error measures and the respective percent difference between the models. Positive (negative) differences indicate Boone’s model has less (more) error than Wright’s.
Boone’s curve performs better for two reasons. First, Boone’s model can explain costs to at least the same degree of accuracy as the traditional learning curve theories due to the extra parameter. Second, increased accuracy could also be explained by Boone’s functional form. Despite these theoretical explanations, Boone’s model had more error than Wright’s for some observations; these negative percentage differences occur because an upper bound was placed on Boone’s decay value. An upper bound of 5000 was used for the decay value (same as Boone’s original paper). The practical effect of this particular bound can be observed by the number of end-items where the traditional models significantly outperformed Boone’s (i.e., a MAPE difference larger than 0.5%): 7 out of 140 for cumulative average theory and 15 out 169 for unit theory. Thus, the majority of the results were not affected by this artificial limitation which was chosen by trial and error. In practice, the bound could be set arbitrarily large so that it is not binding. Boone’s learning curve. This upper bound was necessary s since the GRG algorithm requires bounds on the estimated parameters.
Some percentage error differences are approximately (but not exactly) zero. Observations with percentage error differences of approximately zero were defined as those within the bounds . These bounds were used by the researchers to distinguish between observations with approximately zero and non-zero percentage error differences in order to inform the descriptive statistics.
Boone’s model had less error for 41% of observations, was approximately equal to Wright’s for 50% of observations, and had more error for 9% of observations. While Boone’s model is an improvement on Wright’s for some observations, many times the models fit the data equally well (i.e., an approximate zero difference).
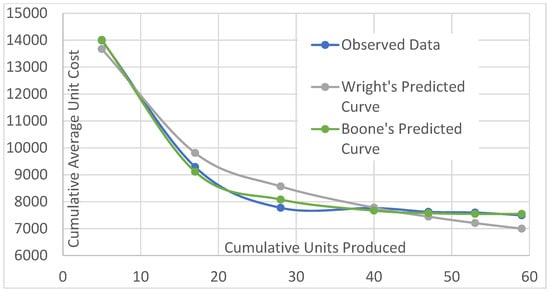
The results of the paired difference t-tests for cumulative average theory are shown in Table 2 and a sample graph is shown in Figure 4. No outliers, as defined by a value which fell more than three interquartile ranges from the upper 90% and lower 10% quantiles, were present in any of the tests.
Table 2.
Cumulative Average Theory Descriptive and Inferential Statistics.
Figure 4.
Comparison of Program 20 PME Air Vehicle.
The results of these hypothesis tests were mixed. For the RMSE percentage difference (measured in total dollars) and MAPE percentage difference, the paired difference t-tests led to rejection of the null hypothesis—indicating the increase in accuracy is statistically significant. Conversely, RMSE percentage difference (measured in hours) failed to reject the null hypothesis. Due to the small sample size, large sample theory could not be used, and the data failed a Shapiro–Wilk test (p-value = 0.721). Therefore, a Wilcoxon rank signed test was used. This indicates that Boone’s improvement in accuracy over Wright’s is not statistically significant when costs are measured in labor hours. However, small sample sizes can cause paired difference tests to have low power that may cause hypothesis tests to incorrectly fail to reject the null hypothesis [30].
Now considering unit theory, the results from Crawford’s and Boone’s learning curve models are presented in Appendix B. A total of 141 end-items (measured in total dollars) and 28 end-items (measured in labor hours) were analyzed.
Similar to cumulative average theory, observations with percent error differences of approximately zero were defined as those within the bounds . Boone’s model had less error for 43% of observations across all percent difference error measures in comparison to crawford’s learning curve. Boone’s learning curve error was approximately equal for 52% of observations, and had more error for 5% of observations.
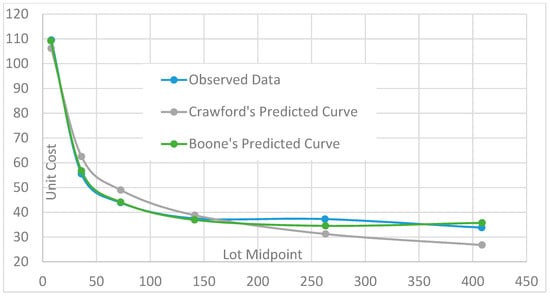
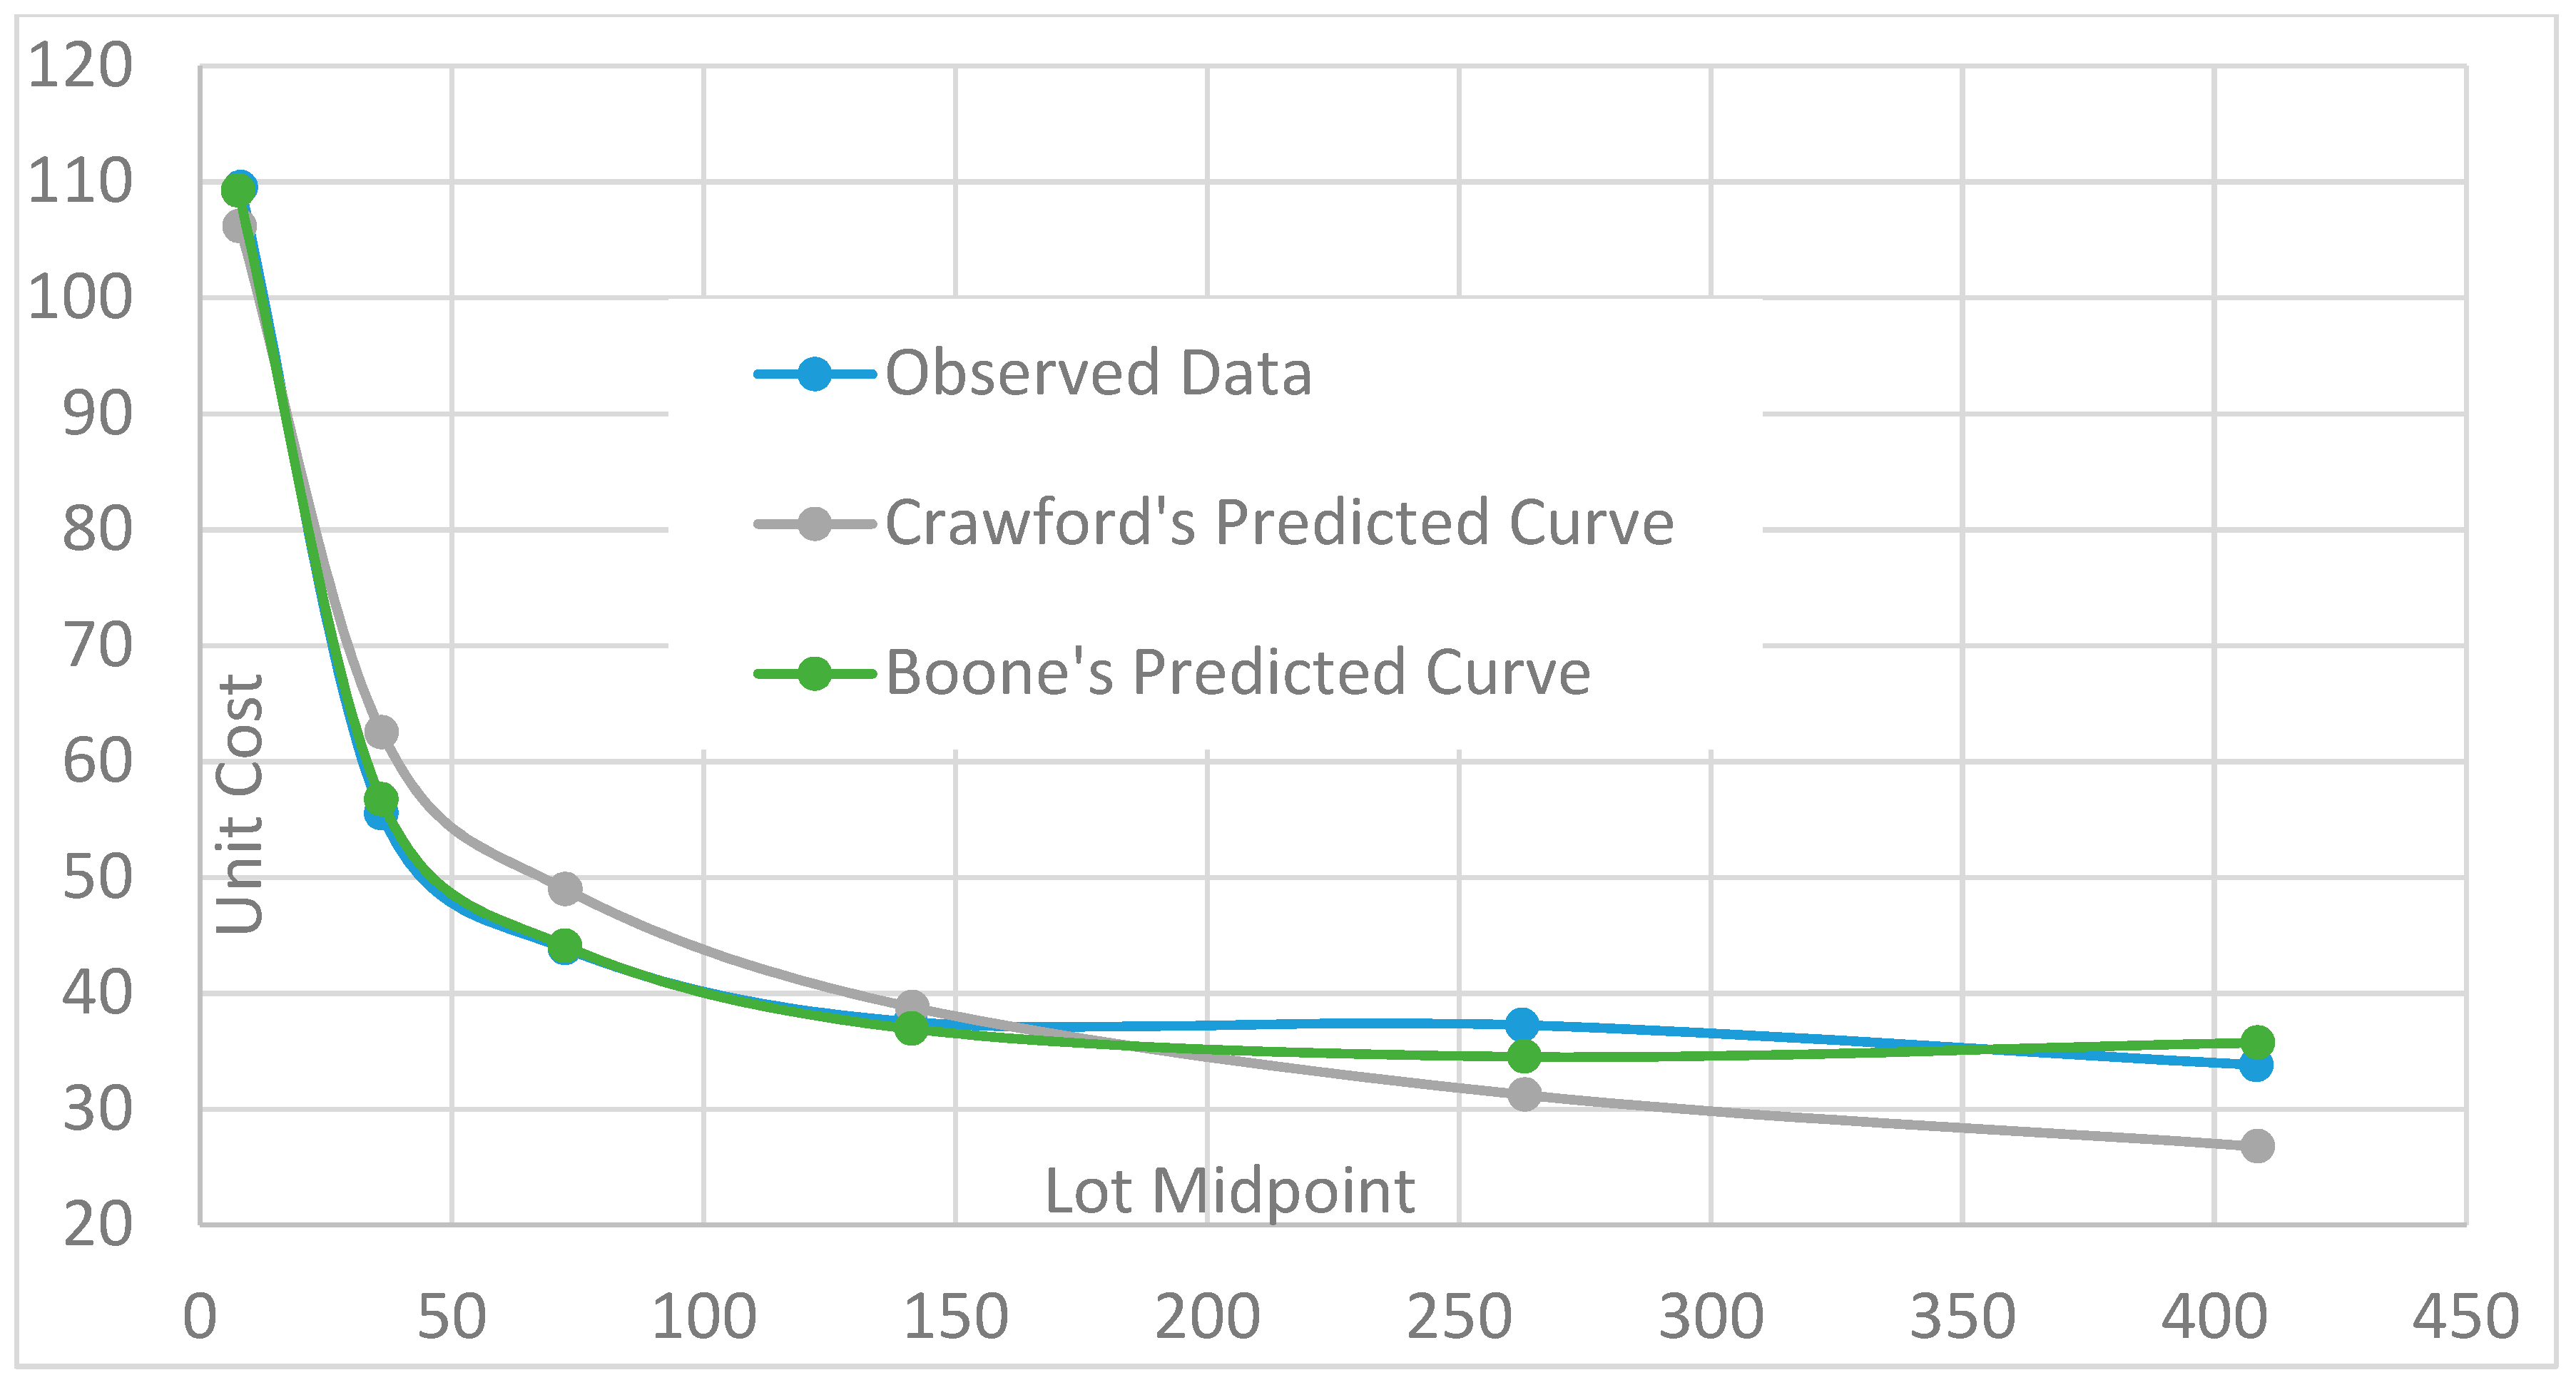
The results of the paired difference testing for unit theory are provided in Table 3 and a sample graph is shown in Figure 5. Again, no outliers were present in any of the paired difference t-tests.
Table 3.
Unit Theory Descriptive and Inferential Statistics.
Figure 5.
Comparison of Program 1 PME Air Vehicle.
The results of these paired difference tests indicate the improvement with Boone’s model is statistically significant. Again, the RMSE percent difference (for labor hours) used a Wilcoxon rank sum test (due to the failure of the Shapiro–Wilk test with a p-value less than 0.001).
5. Conclusions
A large, diverse dataset of DoD production programs was used to test if Boone’s learning curve more accurately explained error in comparison to traditional learning curve theories. The direct recurring cost data from bomber, cargo, and fighter aircraft along with missiles and munitions programs in units of total dollars and labor hours were analyzed using Cumulative Average and Unit Learning Curve theories. Various components of these programs were analyzed from wings and data link systems to the airframes and air vehicles. Boone’s learning curve was tested against both cumulative average and unit learning curve theories using two different measures of model error that resulted in six paired difference tests. This methodology resulted in 998 total observations across all measures and ensured the generalizability of Boone’s learning curve was tested.
Boone’s learning curve improved upon the traditional learning curve estimates for approximately 42% of the sampled program components while approximately equaling the traditional learning curve error for approximately 51% of program components. Boone’s learning curve resulted in a range of mean percentage difference reductions of 6% to 18.6% across all measures. The standard deviations of these improvements were high with coefficients of variation ranging from 150% to 247% across all measures. Absent additional analysis, these high amounts of variability make it challenging to conclude the degree to which Boone’s learning curve will improve the accuracy of explaining program component costs in comparison to the traditional estimation methods. Specifically, more research is needed to understand the shape of the learning curve and how it behaves related to production circumstances. It remains unclear which programs are more accurately modelled using Boone’s learning curve and to what degree Boone’s learning curve will more accurately model program component costs.
The paired difference tests between Boone’s learning curve and the traditional theories indicate that Boone’s learning curve reduces error to a significant degree across a wide range of measures. Five of the six paired difference tests resulted in rejecting the null hypothesis that Boone’s learning curve had an equal amount or more error than the traditional theories at a significance level of 0.05.
Due to data availability, program lot data was used instead of unitary data. Although Boone’s learning curve should perform just as well using either type of data, this research cannot conclusively state that Boone’s learning curve will more accurately explain programs in unitary data. Also, the majority of data utilized were end-item components in units of total dollars. The total dollar cost includes all cost categories rather than solely labor costs. These data are not ideal when applying learning curve theory and may bias learning curves to display diminishing rates of learning. Despite these potential issues, total dollar cost data are regularly utilized by cost estimators in the field due to data availability. Therefore, the practical applications of this analysis remain valid despite the limitations of using imperfect total dollar cost data in learning curve analysis.
Boone’s learning curve was tested on programs whose lot costs were already known and whose parameters can be directly estimated. In other words, Boone’s learning curve was tested against the traditional theories on how well it explained rather than predicted program costs. In order to utilize Boone’s learning curve to predict costs, a decay value would be selected a priori. Similar to the learning curve slope, an analyst could use the decay value from similar programs to provide a range values to make predictions. Additionally, future research should investigate if Boone’s Decay Value can be predicted using various attributes of a program. Tests could be performed on how well Boone’s learning curve predicts costs for a program using analogous programs in comparison to the traditional theories. Lastly, additional labor hour data should be collected and analyzed in order to dispel the potential bias of learning curves displaying diminishing rates of learning when analyzed in units of total dollars.
Author Contributions
Conceptualization, D.H., J.E., C.K. and J.R.; methodology, D.H., J.E., C.K., J.R. and A.B.; software, D.H. and S.V.; validation, D.H., J.E., C.K. and J.R.; formal analysis, D.H., J.E., C.K. and J.R.; investigation, D.H., J.E., C.K., J.R. and S.V.; resources, D.H., A.B. and S.V.; data curation, D.H., J.E. and S.V.; writing—original draft preparation, D.H., J.E. and C.K.; writing—review and editing D.H., J.E., C.K., J.R. and A.B.; visualization, D.H. and A.B.; supervision, J.E., C.K., J.R. and A.B.; project administration, D.H., J.E., C.K. and J.R.; funding acquisition, J.E., J.R. and A.B. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Conflicts of Interest
The authors declare no conflict of interest.
Appendix A. Calculation Process for Lot Midpoint Estimation
The following process was implemented to estimate parameters for lot midpoint estimation.
- Parameter-free lot midpoint approximations (Equation (4)) were calculated for each production lot.
- Crawford’s learning curve parameters A and b were initially estimated using OLS regression.
- Average unit cost was the dependent variable while lot midpoint, calculated in Step 1, was the independent variable.
- These initial learning curve parameter estimates were used as starting values to more precisely estimate Crawford’s learning curve parameters using GRG non-linear solver. This process generated intermediate estimates of Crawford’s learning curve parameters.
- The intermediate estimate of Crawford’s learning curve b parameter was used to calculate a more precise set of lot midpoints using Asher’s approximation (Equation (5)).
- Applying these more precise lot midpoint approximations, Crawford’s learning curve parameters A and b were more accurately estimated using GRG nonlinear solver.
Steps 4 and 5 were repeated until the iterative process converged on a solution to produce final estimates of Crawford’s learning curve parameters and lot midpoint approximations.
Appendix B. Learning Curve Error Comparisons Using Cumulative Average and Unit Theories
Table A1.
Error Comparison using Cumulative Average Theory.
Table A2.
Error Comparison using Unit Theory.
References
- United States Government Accountability Office; Oakley, S.S. Weapon Systems Annual Assessment: Knowledge Gaps Pose Risks to Sustaining Recent Positive Trends: Report to Congressional Committees; United States Government Accountability Office: Washington, DC, USA, 2018.
- Wright, T.P. Factors Affecting the Cost of Airplanes. J. Aeronaut. Sci. 1936, 3, 122–128. [Google Scholar] [CrossRef] [Scilit]
- Asher, H. Cost-Quantity Relationships in the Airframe Industry. Ph.D. Thesis, The Ohio State University, Columbus, OH, USA, 1956. [Google Scholar]
- Boone, E.R.; Elshaw, J.J.; Koschnick, C.M.; Ritschel, J.D.; Badiru, A.B. A Learning Curve Model Accounting for the Flattening Effect in Production Cycles. Def. Acquis. Res. J. 2021. in-print. [Google Scholar]
- Mislick, G.K.; Nussbaum, D.A. Cost Estimation: Methods and Tools; John Wiley & Sons: Hoboken, NJ, USA, 2015. [Google Scholar]
- Argote, L.; Beckman, S.L.; Epple, D. The Persistence and Transfer of Learning in Industrial Settings. Manag. Sci. 1990, 36, 140–154. [Google Scholar] [CrossRef] [Scilit]
- Argote, L. Group and Organizational Learning Curves: Individual, System and Environmental Components. Br. J. Soc. Psychol. 1993, 32, 31–51. [Google Scholar] [CrossRef] [Scilit]
- Jaber, M.Y. Learning and Forgetting Models and Their Applications. Handb. Ind. Syst. Eng. 2006, 30, 30–127. [Google Scholar]
- Glock, C.H.; Grosse, E.H.; Jaber, M.Y.; Smunt, T.L. Applications of Learning Curves in Production and Operations Management: A Systematic Literature Review. Comput. Ind. Eng. 2019, 131, 422–441. [Google Scholar] [CrossRef] [Scilit]
- Jaber, M.Y.; Bonney, M. Production Breaks and the Learning Curve: The Forgetting Phenomenon. Appl. Math. Model. 1996, 2, 162–169. [Google Scholar] [CrossRef] [Scilit]
- Nembhard, D.A.; Uzumeri, M.V. Experiential Learning and Forgetting for Manual and Cognitive Tasks. Int. J. Ind. Ergon. 2000, 25, 315–326. [Google Scholar] [CrossRef] [Scilit]
- Sikström, S.; Jaber, M.Y. The Depletion–Power–Integration–Latency (DPIL) Model of Spaced and Massed Repetition. Comput. Ind. Eng. 2012, 63, 323–337. [Google Scholar] [CrossRef] [Scilit]
- Anzanello, M.J.; Fogliatto, F.S. Learning Curve Models and Applications: Literature Review and Research Directions. Int. J. Ind. Ergon. 2011, 41, 573–583. [Google Scholar] [CrossRef] [Scilit]
- Crossman, E.R. A Theory of the Acquisition of Speed-Skill∗. Ergonomics 1959, 2, 153–166. [Google Scholar] [CrossRef] [Scilit]
- Moore, J.R.; Elshaw, J.J.; Badiru, A.B.; Ritschel, J.D. Acquisition Challenge: The Importance of Incompressibility in Comparing Learning Curve Models; US Air Force Cost Analysis Agency: Arlington, TX, USA, 2015. [Google Scholar]
- Honious, C.; Johnson, B.; Elshaw, J.; Badiru, A. The Impact of Learning Curve Model Selection and Criteria for Cost Estimation Accuracy in the DoD; Air Force Institute of Technology: Wright Patterson AFB, OH, USA, 2016. [Google Scholar]
- Baloff, N. Startups in Machine-Intensive Production Systems. J. Ind. Eng. 1966, 17, 25. [Google Scholar]
- Baloff, N. Startup Management. IEEE Trans. Eng. Manag. 1970, 4, 132–141. [Google Scholar] [CrossRef] [Scilit]
- Corlett, E.N.; Morecombe, V.J. Straightening Out Learning Curves. Pers. Manag. 1970, 2, 14–19. [Google Scholar]
- Yelle, L.E. The Learning Curve: Historical Review and Comprehensive Survey. Decis. Sci. 1979, 10, 302–328. [Google Scholar] [CrossRef] [Scilit]
- Hirschmann, W.B. Profit from the Learning-Curve. Harv. Bus. Rev. 1964, 42, 125–139. [Google Scholar]
- Li, G.; Rajagopalan, S. A Learning Curve Model with Knowledge Depreciation. Eur. J. Oper. Res. 1998, 105, 143–154. [Google Scholar] [CrossRef] [Scilit]
- Chalmers, G.; DeCarteret, N. Relationship for Determining the Optimum Expansibility of the Elements of a Peacetime Aircraft Procurement Program; Stanford Research Institute: Menlo Park, CA, USA, 1949. [Google Scholar]
- De Jong, J.R. The Effects of Increasing Skill on Cycle Time and Its Consequences for Time Standards. Ergonomics 1957, 1, 51–60. [Google Scholar] [CrossRef] [Scilit]
- Knecht, G.R. Costing, Technological Growth and Generalized Learning Curves. J. Oper. Res. Soc. 1974, 25, 487–491. [Google Scholar] [CrossRef] [Scilit]
- Badiru, A.B. Computational Survey of Univariate and Multivariate Learning Curve Models. IEEE Trans. Eng. Manag. 1992, 39, 176–188. [Google Scholar] [CrossRef] [Scilit]
- Office of the Secretary of Defense. 1921-1 Data Item Description. Available online: https://cade.osd.mil/content/cade/files/csdr/dids/archive/1921-1.DI-FNCL-81566B.pdf (accessed on 29 September 2020).
- Hu, S.-P.; Smith, A. Accuracy Matters: Selecting a Lot-Based Cost Improvement Curve. J. Cost Anal. Parametr. 2013, 6, 23–42. [Google Scholar] [CrossRef] [Scilit]
- Cohen, J. Quantitative Methods in Psychology. Nature 1938, 141, 613. [Google Scholar] [CrossRef] [Scilit]
- Badiru, A.B. Half-Life Learning Curves in the Defense Acquisition Life Cycle. Def. Acquis. Res. J. 2012, 19, 283–308. [Google Scholar]

Publisher’s Note: MDPI stays neutral with regard to jurisdictional claims in published maps and institutional affiliations. |
© 2020 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).