Article

Improved Doubly Robust Inference with Nonprobability Survey Samples Using Finite Mixture Models: Application to Health Monitoring SMS Survey Data

1
Department of Medical Statistics, School of Public Health, Sun Yat-sen University, No. 74, Zhongshan Second Road, Guangzhou 510080, China
2
Research Center of Health Informatics, Sun Yat-sen University, Guangzhou 510080, China
3
Sun Yat-sen Global Health Institute, School of Public Health and Institute of State Governance, Sun Yat-sen University, Guangzhou 510080, China
4
Guangzhou Joint Research Center for Disease Surveillance, Early Warning, and Risk Assessment, Guangzhou 510080, China
5
Guangdong Key Laboratory of Health Informatics, Guangzhou 510080, China
*
Author to whom correspondence should be addressed.
Mathematics 2026, 14(1), 118; https://doi.org/10.3390/math14010118
Submission received: 4 November 2025 / Revised: 21 December 2025 / Accepted: 24 December 2025 / Published: 28 December 2025
(This article belongs to the Section D: Statistics and Operational Research)

Abstract

Nonprobability sampling has been increasingly used in epidemiologic research, yet direct inference based on such samples is subject to selection bias. Current adjustment methods commonly rely on a reference probability-based survey sample that shares a set of covariates with the nonprobability sample. However, these common covariates are often limited and may bias estimates in the presence of population heterogeneity. Existing methods generally assume population homogeneity in models and fail to address such heterogeneity adequately. To overcome this limitation, we propose the Nonprobability Heterogeneity-adjusted Doubly Robust (NHDR) method, a novel inference framework that explicitly accounts for population heterogeneity during selection bias adjustment. NHDR proceeds in three stages: (1) identifying latent subpopulations via finite mixture modeling; (2) incorporating the resulting latent-class structure as a grouping variable into mixed-effects models for both the propensity score and outcome projection; and (3) constructing a doubly robust estimator that integrates these adjusted models. The key methodological contribution of NHDR is its formal integration of latent-class-based population structure into a doubly robust estimation framework, which enables more reliable inference under heterogeneous population settings. Simulation studies demonstrate that the proposed method control the coverage probabilities well in most scenarios. Under heterogeneous conditions, NHDR consistently outperforms existing methods achieving an average reduction in relative bias of approximately 1.8–4.5% and a corresponding decrease in mean squared error of about 5.1–15.5 compared to the benchmark method. We illustrate the practical utility of NHDR by applying it to estimate nine health indicators using data from the Health Monitoring SMS Survey in Guangzhou, China, with the seventh Guangdong Health Service Survey serving as the reference sample.

1. Introduction

Probability sampling has long been considered the gold standard for obtaining representative samples due to its well-established theoretical basis [1]. However, the implementation of probability sampling methods is increasingly challenged by declining response rates and rising costs [2,3,4]. In the last decade, nonprobability sampling, especially online surveys, has gained momentum as a cost-effective alternative. Reports indicate that online surveys comprise 73% of survey research, with 90% employing nonprobability sampling methods [5]. However, direct inference from nonprobability samples is vulnerable to selection and coverage bias. This is because participants are not randomly selected, and the underlying selection mechanism is generally unknown [6,7,8,9]. Furthermore, online nonprobability surveys may face self-selection biases, non-response and attrition, which heighten the risk of selection bias [1,10]. Therefore, adjusting for selection bias is essential when making inference from nonprobability samples [11,12,13]. A common solution is to integrate a probability sample (termed a reference sample) that shares a set of common covariates. The design weights from this reference sample are then used to anchor population-level inference.
Current methods for adjusting selection bias in inference with nonprobability samples broadly fall into three categories: (i) global adjustment, including methods such as inverse probability weighting (IPW) [14], propensity score matching [15], and kernel smoothing methods [16,17]; (ii) outcome-specific adjustment, including methods such as the superpopulation (SP) model [1,18], model-based calibration [1,18], and multilevel poststratification regression [19]; (iii) the combined approach, including the doubly robust (DR) method [20] and the multiply robust method [21]. These methods typically rely on a set of common covariates Z , available in both the nonprobability sample and the reference sample, to model the selection mechanism R and the outcome Y . This common set Z is often limited to basic socio-demographics, as the reference survey was designed for different purposes. A critical, yet often unstated, assumption underlying these methods is the homogeneity of the Z R and Z Y relationships across the population. However, this assumption is frequently violated by latent population heterogeneity, where the population comprises unobserved subgroups with distinct behavioral or risk profiles. When key drivers of inclusion or the outcome are unmeasured, this latent heterogeneity causes the Z R and Z Y relationships to vary substantially across subpopulations, leading to model misspecification. Consequently, inverse probability weighted, outcome-projected, and even doubly robust estimators can yield biased estimates; increasing the size of the nonprobability sample does not, by itself, resolve this problem. This failure mode is common in health behavior studies, where unmeasured attitudes or contextual factors segment the population into groups with distinct Z R and Z Y patterns.
In our context, latent population heterogeneity is defined by the existence of unobserved subpopulations (latent class, L C ) that differ both in distribution of their characteristics Z and in their underlying data-generating mechanisms [22,23]. Formally, for k l , not only does the joint distribution P ( Z | L C = k ) differ from P ( Z | L C = l ) , but the functional relationships also differ: f ( Y | Z , L C = k ) f ( Y | Z , L C = l ) and P ( R | Z , L C = k ) P ( R | Z , L C = l ) . For instance, Herschbach et al. reported that distributions of smoking, exercise, and other factors differed between sexes, and their effects on stroke risk also varied by sex [24]. Delineating such heterogeneity often requires multiple indicators, with the number of latent groups being an empirical question. For example, to explore health status variations among COVID-19 survivors in Vietnam, Lan et al. utilized six indicators and identified two subpopulations [25], whereas Lv et al. used seven indicators and identified three subpopulations among residents aged 18–64 in Hangzhou, China [26]. Therefore, accurately identifying and accounting for this heterogeneity is crucial for constructing valid propensity score and outcome projection models.
Existing methods for addressing potential heterogeneity can be categorized into four types: (i) latent class models; (ii) the two-step approach; (iii) random parameter models; and (iv) latent classes models with random parameters within classes [27,28]. Among these, the two-step approach is the most widely used due to its computational simplicity and modelling flexibility, while the others may face challenges such as unstable parameter estimates, incorrect specification of parameter distributions, and excessive computational burden [27,28]. In the two-step approach, analysts first use unsupervised clustering to identify distinct subpopulations and then fit the analysis models within, or conditional on, the identified groups. Common clustering techniques include finite mixture modeling (FMM), latent class analysis, latent profile analysis, K-means, and Ward clustering. We adopt FMM for its distinctive advantages in identifying latent subpopulations in survey settings. Unlike methods such as K-means, which require pre-specified cluster numbers and are limited to continuous data, FMM provides a principled statistical framework that objectively determines the number of latent classes using information criteria. Crucially, FMM inherently accommodates mixed-type variables (continuous, binomial, and multinomial) [6,29]—exactly the form of typical survey covariates such as age, sex, and education level. This capability allows us to utilize the full set of available covariates without transformation or approximate distance measures, yielding a more faithful representation of the underlying heterogeneous population structure.
We propose a Nonprobability Heterogeneity-adjusted Doubly Robust (NHDR) inference method for nonprobability samples that explicitly accounts for population heterogeneity when adjusting for selection bias, thereby improving the reliability and accuracy of resulting inferences. The proposed method employs a two-step strategy with three stages. In stage 1, we use the FMM to identify heterogeneous subpopulations (referred as heterogeneous groups). In stage 2, we construct the propensity score model and the outcome projection model using mixed-effects models, with the heterogeneous groups defined in the first stage serving as a level-2 variable. In stage 3, we construct a doubly robust estimator by combining the results from these two models, following the method described by Chen et al. [20], and stabilize weights via kernel smoothing. The NHDR method makes a key methodological contribution by being the first, to our knowledge, to formally integrate latent classes—identified via FMM—directly into both the propensity score and outcome models within a doubly robust framework. Unlike standard methods that assume population homogeneity, NHDR explicitly models the group-specific Z R and Z Y relationships by incorporating the latent class membership as a grouping variable, thereby addressing the fundamental problem of model misspecification under heterogeneity. We then perform extensive simulation studies to examine the coverage probabilities, relative bias, mean squared error, and confidence interval width of the proposed methods. Finally, we apply NHDR method to the Health Monitoring SMS Survey data collected in Guangzhou China, using the data from the seventh Guangdong Health Service Survey as the reference sample.

2. Methods

2.1. Notations and Basic Settings

Let U = { 1,2 , , N } represent the finite population of size N . Let S A denote a sample of size n A obtained from U through nonprobability sampling, and S B denote a reference sample of size n B obtained through probability sampling. The sampling weight for individual i in S B is denoted as d i . Let Y i represent the target outcome for individual i , and Z i = z 1 i , z 2 i , , z m i T be a vector of m covariates. Note that Y i is collected only in S A , while Z i is collected in both S A and S B . In this study, the inference parameters of interest are the means for continuous outcome, and the prevalence for binary outcomes. We define R i as an indicator variable for inclusion in S A , where a value of 1 indicates that individual i belongs to S A and a value of 0 indicates that individual i belongs to S B . Key notations in Section 2 are summarized in Table 1. The propensity score model for estimating inclusion probability of individual i in U can be expressed as:
π i = P R i = 1 Z i , Y i ,       i U
The following assumptions are made for the above model [20,30,31]:
Assumption 1.
Positivity: All individuals in U have a positive probability of inclusion in S A , that is, π i > 0 for i U .
Assumption 2.
Independence: The probabilities of inclusion in S A for different individual are independent given the covariates Z i , that is, c o v R i , R j | Z i , Z j = 0 for i j .
Assumption 3.
Non-informativity: The nonprobability sample selection is uncorrelated with the target outcome given the covariates, that is, P R i = 1 Z i , Y i = P R i = 1 Z i for i U .

2.2. Overview of the Proposed NHDR Method

The NHDR framework adjusts for selection bias in nonprobability samples when latent population heterogeneity is present. As illustrated in Figure 1, the procedure consists of three sequential stages:
Stage 1 (Identification of latent subpopulations): A finite mixture model (FMM) is fitted to the pooled covariate data from both samples to uncover the underlying latent class structure that captures population heterogeneity.
Stage 2 (Heterogeneity-adjusted modeling): The estimated latent class memberships are incorporated as a grouping variable into mixed-effects models, enabling the estimation of class-specific propensity scores and the projection of outcomes. This explicitly accounts for differing covariate-outcome and covariate-selection relationships across subpopulations.
Stage 3 (Doubly robust estimation): A doubly robust estimator is formed by combining the kernel-smoothed inverse propensity weights with the model-projected outcomes.
The following subsections detail the technical implementation of each stage.

2.3. Stage 1: Identification of Heterogeneous Populations Using Finite Mixture Modelling

Finite mixture modelling treats the population as a weighted combination of K latent classes, with covariates distributions varying across classes. It classifies individuals into mutually exclusive latent classes by computing the posterior probabilities of class membership [32]. In this study, to identify heterogeneous populations, we fit a finite mixture model using the combined samples from S A and S B , based on the common covariates Z i :
f Z i = k = 1 L C P L C i = k f k Z i L C i = k = k = 1 L C P L C i = k j = 1 m f k z j i L C i = k
Here L C i = k indicates that individual i belongs to latent class k , with k = 1 , , L C , where L C is the optimal number of latent classes. We determine L C through three steps:
(1)
Set an upper limit for the number of latent classes L C M based on the research question; if prior information is unavailable, L C M can be set to 1–10 [33];
(2)
For each candidate number of classes from 1 to L C M , fit the corresponding FMMs.
(3)
The optimal number of latent classes, L C , is then selected by minimizing the Bayesian Information Criterion (BIC), as its penalty term for model complexity is l o g ( n ) , which allows for asymptotically consistent selection of the true number of classes as the sample size increases [34]. This has been shown to provide a stable and reliable solution in mixture modeling [35,36].
P L C i = k is the probability that individual i belongs to latent class k and f k Z i L C i = k is the distribution of Z i given L C i = k . Assuming independence among covariates, f k Z i L C i = k = j = 1 m f k z j i L C i = k . The Expectation-Maximization (EM) algorithm is used to estimate the posterior probabilities of class membership for each individual, which can be obtained directly by the depmixS4 package in the R statistical software [37]. The monotonicity and convergence properties of the EM algorithm are justified in Supplementary Section S2. Each individual is then classified into the latent class with the highest posterior probability.

2.4. Stage 2: Construction of Propensity Score Model and Outcome Projection Model Accounting for Population Heterogeneity

(1)
Propensity score model accounting for population heterogeneity: A logistic mixed effects model is used to estimate inclusion probabilities, treating the heterogeneous groups identified in stage 1 as a level-2 variable. The model is fitted with common covariates Z i using the combined sample from S A and S B , with S B weighted by d i = a · d i , where a = n B i S B d i . This scaling adjustment is applied to stabilize the estimation process by mitigating the disproportionate influence that can arise from the disparity in effective sample size between the weighted S B and S A . Specifically, it prevents the composite likelihood from being dominated by a small number of units with extremely large design weights. As a result, this adjustment is crucial for achieving stable and efficient estimation of the model parameters [30]. We denote the model as π ( Z i , L C i , d i ; α ) , specified as:
Level-1:
ln P R i k = 1 1 P R i k = 1 = α 0 k + j = 1 m α j k z j i k ,   k = 1 , , L C
Level-2:
α 0 k = α 00 + ε 0
α j k = α j 0 + ε j ,             j = 1 , , m
where R i k is the inclusion indicator for individual i in latent class k identified in stage 1, and z j i k is the j th covariate for that individual. α 0 k and α j k are level-1 intercept and slopes, and α 00 and α j 0 are corresponding parameters for level-2. ε 0 and ε j are normally distributed residual terms.
(2)
Outcome projection model accounting for population heterogeneity: A generalized linear mixed effects model is constructed between common covariates Z i and Y i based on S A . This model is used to project outcomes in S B . Denote the model as m ( Y i | Z i , L C i ; β ) with the following specification:
Level-1:
g Y i k = β 0 k + j = 1 m β j k z j i k + e i k ,   k = 1 , , L C
Level-2:
β 0 k = β 00 + e 0
β j k = β j 0 + e j ,             j = 1 , , m
where g ( · ) is the link function. For continuous outcomes, the identity link is used; for binary outcomes, the logit link is employed. Y i k is the outcome for individual i in latent class k . β 0 k and β j k are the level-1 intercept and slopes, and β 00 and β j 0 are level-2 parameters. e i k , e 0 and e j are normally distributed residual terms.
For both the propensity score model and the outcome projection model, we fitted linear-mixed effects using the lme4 package [38]. The model specification included random intercepts and random slopes for all predictors across the L C groups, utilizing an unstructured covariance matrix for the random effects. This comprehensive structure posits that the class-specific coefficients follow a multivariate normal distribution, which enables ‘borrowing strength’ across classes for more efficient estimation, particularly in cases where some classes have limited data. By adopting this approach, the model directly estimates the variance components between classes for both baseline levels and covariate effects. Consequently, it effectively captures the nuanced differences in the relationships between Z and Y , as well as Z and R , across subpopulations, which is essential for addressing the core challenge of latent population heterogeneity. Parameter estimation proceeded in two stages: the conditional modes of the random effects were predicted via the penalized iteratively reweighted least squares (PIRLS) algorithm, while the covariance parameters (i.e., the variance components) were estimated by maximizing the restricted maximum likelihood (REML) criterion.

2.5. Stage 3: Construction of a Doubly Robust Estimator

Using the improved propensity score model π ( Z i , L C i , d i ; α ^ ) and the outcome projection model m ( Y i | Z i , L C i ; β ^ ) , we construct a doubly robust estimator for inference following Chen et al. [20].
First, compute the projected outcomes for the reference sample via m ( Y i | Z i , L C i ; β ^ ) , i.e., Y ^ i ,   i S B .
Next, for individuals in S A , compute the linear predictors q i = ln P i 1 P i , with P i = P R i = 1 . Then apply kernel smoothing to q i as in Wang et al. [30], to obtained a more stable weight w i :
w i = m S B K q i A q m B h n S A K q n A q m B h · d m
where q n A is the linear predictor for individual n in S A , and q m B for individual m in S B . K ( · ) is a kernel function. In this study, standard normal function is selected. The bandwidth h is determined by applying Silverman’s rule of thumb to the linear predictors in S A , i.e., h = 0.9 · m i n ( σ ^ q A , I Q R q A 1.349 ) . This rule provides a data-driven plug-in bandwidth selector that is derived to asymptotically minimize the mean integrated squared error (MISE) for kernel density estimation under a Gaussian reference [39]. The weights w i can be obtained by KWML package. The asymptotic efficiency improvement from kernel smoothing is sated in the following lemma:
Lemma 1.
Let μ ^ I P W be an estimator constructed using the unsmoothed inverse-probability weights ω i I P W = 1 / π i , and μ ^ s m o o t h be the corresponding estimator using kernel-smoothed weights ω i s m o o t h . Under regularity conditions C1–C5 (stated in Supplementary Section S1), the asymptotic variance of μ ^ s m o o t h is no longer than that of μ ^ I P W , i.e., lim n A V a r ( μ ^ s m o o t h ) lim n A V a r ( μ ^ I P W ) (see proof of Lemma 1 in Supplementary Section S3).
Last, combine the projected outcome in S B and stabilized weights w i . For continuous outcome, the mean estimator is:
μ ^ N H D R = 1 i S A w i i S A w i ( Y i Y ^ i ) + 1 i S B d i i S B d i Y ^ i
We denote this method as Nonprobability Heterogeneity-adjusted Doubly Robust Inference (NHDR). The resulting estimator retains the double robustness property under the latent class structure. Specifically, μ ^ N H D R is consistent if, within each latent stratum defined by L C i , either the propensity model π ( Z i , L C i , d i ; α ^ ) or the outcome model m ( Y i | Z i , L C i ; β ^ ) is correctly specified. This follows from the fact that consistency of either model within a stratum ensures unbiased estimation of a stratum-specific mean; the population estimator, as a weighted average across strata, thus remains consistent if this condition holds stratum-wise. The consistency and asymptotic normality of μ ^ N H D R is sated in the following theorem:
Theorem 1
(Consistency and Asymptotic Normality of μ ^ N H D R ). Under conditions C1–C8 in Supplementary Section S1, and assuming that the latent class membership L C i obtained from the Stage 1 finite mixture model is consistent, i.e., the classification probability is O p ( n A 1 / 2 ) , we have, as N
μ ^ N H D R p μ
and
n A μ ^ N H D R μ d N 0 ,   V N H D R
with the asymptotic variance V N H D R defined below. A detailed proof is provided in Supplementary Section S4.
Referring to Chen et al. [20] and Wang et al. [30], the finite population variance of μ ^ N H D R is V a r μ ^ N H D R = V N H D R + o ( n A 1 ) , where
V N H D R = 1 N 2 i = 1 N 1 π i π i w i Y i m Y i Z i , L C i ; β ^ μ e b T Z i 2 + b T D 1 b + D 2
with b T = i = 1 N π i 1 π i Y i m Y i Z i , L C i ; β ^ μ e w i / α T i = 1 N π i 1 π i Z i Z i T 1 , μ e = 1 N i = 1 N Y i m Y i Z i , L C i ; β ^ , D 1 = N 2 V p i = 1 N I R i = 0 d i π i Z i , D 2 = N 2 V p i = 1 N I R i = 0 d i m Y i Z i , L C i ; β ^ N 1 i = 1 N m Y i Z i , L C i ; β ^ , where V p denotes the design-based variance under the probability sampling design for S B , I R i = 0 indicates that individual i belongs to S B . A consistent sample estimator of V N H D R can be obtained by substituting the finite population quantities by consistent sample estimators. Detailed derivation can be found in Supplementary Section S5. Proof of consistency of NHDR variance estimator is shown in Supplementary Section S6.

3. Simulation Studies

We evaluate the reliability and accuracy of the proposed NHDR method through simulation studies under scenarios with and without population heterogeneity. For comparison, we include the unadjusted estimates (denoted as Naïve) and three existing methods: the doubly robust (DR) method, the inverse propensity weighting (IPW), and the superpopulation (SP) model.

3.1. Data-Generating Models

We consider a finite population of size 100,000, a size that better approximates real-world population scales, to enhance the practical relevance of our simulation study. The data-generating models for the outcome Y and the inclusion probabilities π differ between scenarios with and without population heterogeneity.
(1)
Under scenarios without population heterogeneity, continuous outcomes are generated as follows [20]:
Y i = t 1 z 1 i + t 2 z 2 i + t 3 z 3 i + t 4 z 4 i + t 5 z 5 i + ϵ i
where Z i = z 1 i , z 2 i , z 3 i , z 4 i , z 5 i T comprises variables following Bernoulli, Uniform, Poisson, Chi-squared, and Normal distributions, respectively. This mixture reflects realistic data structures with diverse variable types. The covariance matrix is set to be an identity matrix, reflecting the conditional independence assumption common in FMMs. T = t 1 , t 2 , t 3 , t 4 , t 5 T encodes the signs of coefficients. ϵ i ~ N ( 0 , σ ϵ 2 ) . We set σ ϵ 2 to satisfy σ ϵ 2 σ Z 2 + σ ϵ 2 = ρ , where σ Z 2 = j = 1 5 V a r z j is the total variance of the covariates. The parameter ρ reflects both Z Y and Z R correlations. Binary outcomes are generated as: log p i 1 p i = ω 0 + Y i , where ω 0 is chosen so that the overall prevalence is 50%.
The inclusion probabilities for nonprobability sample S A depend on the covariates Z i through the following logistic model:
log π i 1 π i = θ 0 + t 1 z 1 i + t 2 z 2 i + t 3 z 3 i + t 4 z 4 i + t 5 z 5 i + ϵ i
where θ 0 is chosen such that i = 1 N π i = n A . The sample S A was then generated via Poisson sampling based on these probabilities.
(2)
Under scenarios with population heterogeneity, the population consists of at least two subpopulations. We define N L C as the number of heterogeneous populations. Here we illustrate the data-generating models for N L C = 2 . For individuals in subpopulation 1 ( L C i = 1 ) and subpopulation 2 ( L C i = 2 ), continuous outcomes are generated as:
Y 1 i = 5 + t 10 + t 11 z 11 i + t 12 z 12 i + t 13 z 13 i + t 14 z 14 i + t 15 z 15 i + ϵ 1 i
Y 2 i = 5 + t 20 + t 21 z 21 i + t 22 z 22 i + t 23 z 23 i + t 24 z 24 i + t 25 z 25 i + ϵ 2 i
The distributions of z k j i are the same as in the N L C = 1 case but with parameters set differently. ϵ 1 i ~ N ( 0 , σ ϵ 1 2 ) and ϵ 2 i ~ N ( 0 , σ ϵ 2 2 ) . For k = 1 ,   2 , σ ϵ k 2 is set to satisfy σ ϵ k 2 σ Z k 2 + σ ϵ k 2 = ρ . The value of t 10 and t 20 are chosen so that the intraclass correlation coefficient (ICC) equals to a prespecified value, where ICC controls the degree of heterogeneity. A detailed determination is provided in Supplementary Section S7.
Binary outcomes for L C i = 1 and L C i = 2 are generated as:
log p 1 i 1 p 1 i = ω 10 + Y 1 i
log p 2 i 1 p 2 i = ω 20 + Y 2 i
with ω 10 and ω 20 chosen so that the prevalences in both subpopulations are 50%.
The nonprobability inclusion probabilities for L C i = 1 and L C i = 2 are given by:
log π 1 i 1 π 1 i = θ 10 + t 10 + t 11 z 11 i + t 12 z 12 i + t 13 z 13 i + t 14 z 14 i + t 15 z 15 i + ϵ 1 i
log π 2 i 1 π 2 i = θ 20 + t 20 + t 21 z 21 i + t 22 z 22 i + t 23 z 23 i + t 24 z 24 i + t 25 z 25 i + ϵ 2 i
where θ 10 and θ 20 are chosen such that i = 1 N 1 π 1 i = n A 1 and i = 1 N 2 π 2 i = n A 2 . Poisson sampling is used within each subpopulation to obtain S A 1 and S A 2 , and S A is formed by combining them. Under both scenarios with and without heterogeneity, S B is obtained via random sampling with sampling weights d i = N / n B .

3.2. Simulated Scenarios

Following existing studies [25,40,41], we set the number of latent classes ( N L C ) to range from 1 to 5, with 5 set as the empirically supported upper limit to cover the practical range of population heterogeneity. Specifically, N L C = 1 indicates no heterogeneity and N L C 2 indicates heterogeneous scenarios. With L C M fixed at 4 for the NHDR method, N L C [ 2 , 4 ] corresponds to settings where NHDR can fully identify the heterogeneity, while N L C = 5 corresponds to settings in which NHDR fails to capture the heterogeneity. The distribution parameters of Z i for the five subpopulations are specified in Supplementary Table S1. We consider two parameterizations: (1) D i s t = 1 : Distributions of Z i vary systematically across subpopulations, with parameters increasing monotonically from L C i = 1 to L C i = 5 ; (2) D i s t = 2 : Distributions of Z i vary irregularly, with parameters fluctuating without a monotone trend from L C i = 1 to L C i = 5 . For N L C 2 , we define n Z and n P to describe the sign configurations of the associations between Z i and Y i , and between Z i and R i . Specifically, n Z denotes the number of covariates whose effects differ in sign across subpopulations. For scenarios with N L C heterogeneous subpopulations, a minimum of N L C 1 covariates must display sign changes to distinguish all subpopulations; thus, n Z [ N L C 1 , 5 ] . Let n P denote the number of subpopulations whose covariate-effect directions are opposite to those of the remaining subpopulations for the n Z covariates. By symmetry, n P and N L C n P describe the same configuration, so n P N L C / 2 . To ground these definitions in a practical context, we draw on a preliminary analysis of depression risk factors. This example involves modeling depression using three covariates (gender, age, education), with two latent subgroups ( N L C = 2) hypothesized based on lifestyle [42]. A pooled analysis of the entire population suggests uniform negative associations for all covariates with depression (Supplementary Table S2). However, stratification by lifestyle reveals that gender and education exhibit directionally opposite associations between the two subgroups. This real-world case corresponds to a scenario with n Z = 2 covariates showing sign reversal and n P = 1 subgroup displaying effect directions opposite to the rest. It illustrates how latent class structure, if ignored, can mask opposing subgroup effects and bias pooled estimates. For each combination of ( N L C ,   n Z ,   n P ) , the corresponding sign vector T = t 1 , t 2 , t 3 , t 4 , t 5 T is specified in Supplementary Table S3.
For N L C = 1 , we use the Z i distribution parameters for L C i = 1 from Supplementary Table S1, and generated data using T from Supplementary Table S3 corresponding to N L C = 1, n Z = 0, and n P = 0. For N L C = 2 , we use L C i = 1 and L C i = 2 from Table S1 as the Z i distribution parameters for the two subpopulations, and generated data using T values corresponding to various ( n Z , n P ) combinations from Table S3. The settings for N L C = 3–5 follow the same logic, with additional subpopulations and appropriate parameter choices.
Four sample size combinations ( n A , n B ) are considered: (500, 2000), (2000, 2000), (500, 5000), and (2000, 5000). To systematically evaluate method performance across a spectrum of Z Y and Z R correlations, the correlation parameter ρ was set to three levels (0.3, 0.5, 0.8), corresponding to weak, moderate, and strong correlations between the covariates Z and both the outcome Y and the inclusion mechanism R . This range reflects the varying explanatory power that observed covariates may hold in practical applications. Additionally, the intraclass correlation coefficient (ICC) was varied across three values (0.3, 0.5, 0.8) to induce low, moderate, and high levels of outcome heterogeneity across the latent subpopulations, thereby enabling a thorough assessment of the method’s robustness to differing degrees of within-cluster dependence.

3.3. Evaluating Criteria

Relative bias (RB) and mean squared error (MSE) are used for assessing performance of point estimate. Coverage probability (CP) and confidence interval width (CIW) are used for assessing performance of CI estimate. The four criteria are calculated as follows:
R B = 1 B b = 1 B μ ^ b μ y μ y × 100
M S E = 1 B b = 1 B ( μ ^ ( b ) μ y ) 2
C P = 1 B b = 1 B I μ y C I b × 100
C I W = 1 B b = 1 B U ( b ) L ( b )
where μ y denotes the true mean of the outcome. B denotes the number of simulations. According to Morris et al. [43], the minimum required number of simulations is 2120. More details of the calculation can be found in Supplementary Section S8. With B = 3000, the acceptable lower limit of CP is 94.2%. Values of all simulation parameters are listed in Supplementary Table S4.

3.4. Results

The proposed NHDR method demonstrates robust performance in coverage probabilities (CP) across heterogeneous scenarios, maintaining nominal levels in most scenarios where existing methods show substantial deterioration. As summarized in Table 2 for a representative setting (continuous outcomes, ρ = 0.5 , D i s t = 1 , n A , n B = ( 500 , 2000 ) ), NHDR consistently maintains nominal coverage across the entire spectrum of heterogeneity considered ( N L C [ 1 ,   4 ] ). In stark contrast, the coverage of both DR and SP estimators deteriorates systematically upon the introduction of heterogeneity ( N L C 2 ). Although valid under homogeneity ( N L C = 1 ), their confidence intervals become anti-conservative, with coverage deficit increasing monotonically as a function of the complexity of the latent structure—specifically, with the number of heterogeneous populations ( N L C ), the number of covariates exhibiting sign reversal ( n Z ) and the count of subpopulations with opposing effect directions ( n P ). This pattern stems from fundamental model misspecification: these approaches assume homogeneous covariate-outcome relationships, producing biased estimates when pooling data from subpopulations with divergent response processes. When true heterogeneity exceeds the specified model capacity ( N L C = 5 with L C M = 4 ), NHDR shows moderate coverage decline. This is attributed to residual confounding arising from the unmodeled latent class. Nevertheless, NHDR maintains superior coverage compared to existing methods under identical conditions, demonstrating that partial adjustment for population heterogeneity provides meaningful improvements over complete omission. Simulated CP under other sample sizes and correlation values (Supplementary Tables S5–S15) follow similar trends: all methods perform similarly across n A , n B and ρ under N L C = 1 (Supplementary Figure S1), while DR, IPW and SP exhibit reduced CPs with larger n A , n B and higher ρ for N L C 2 (Supplementary Figures S2–S5).
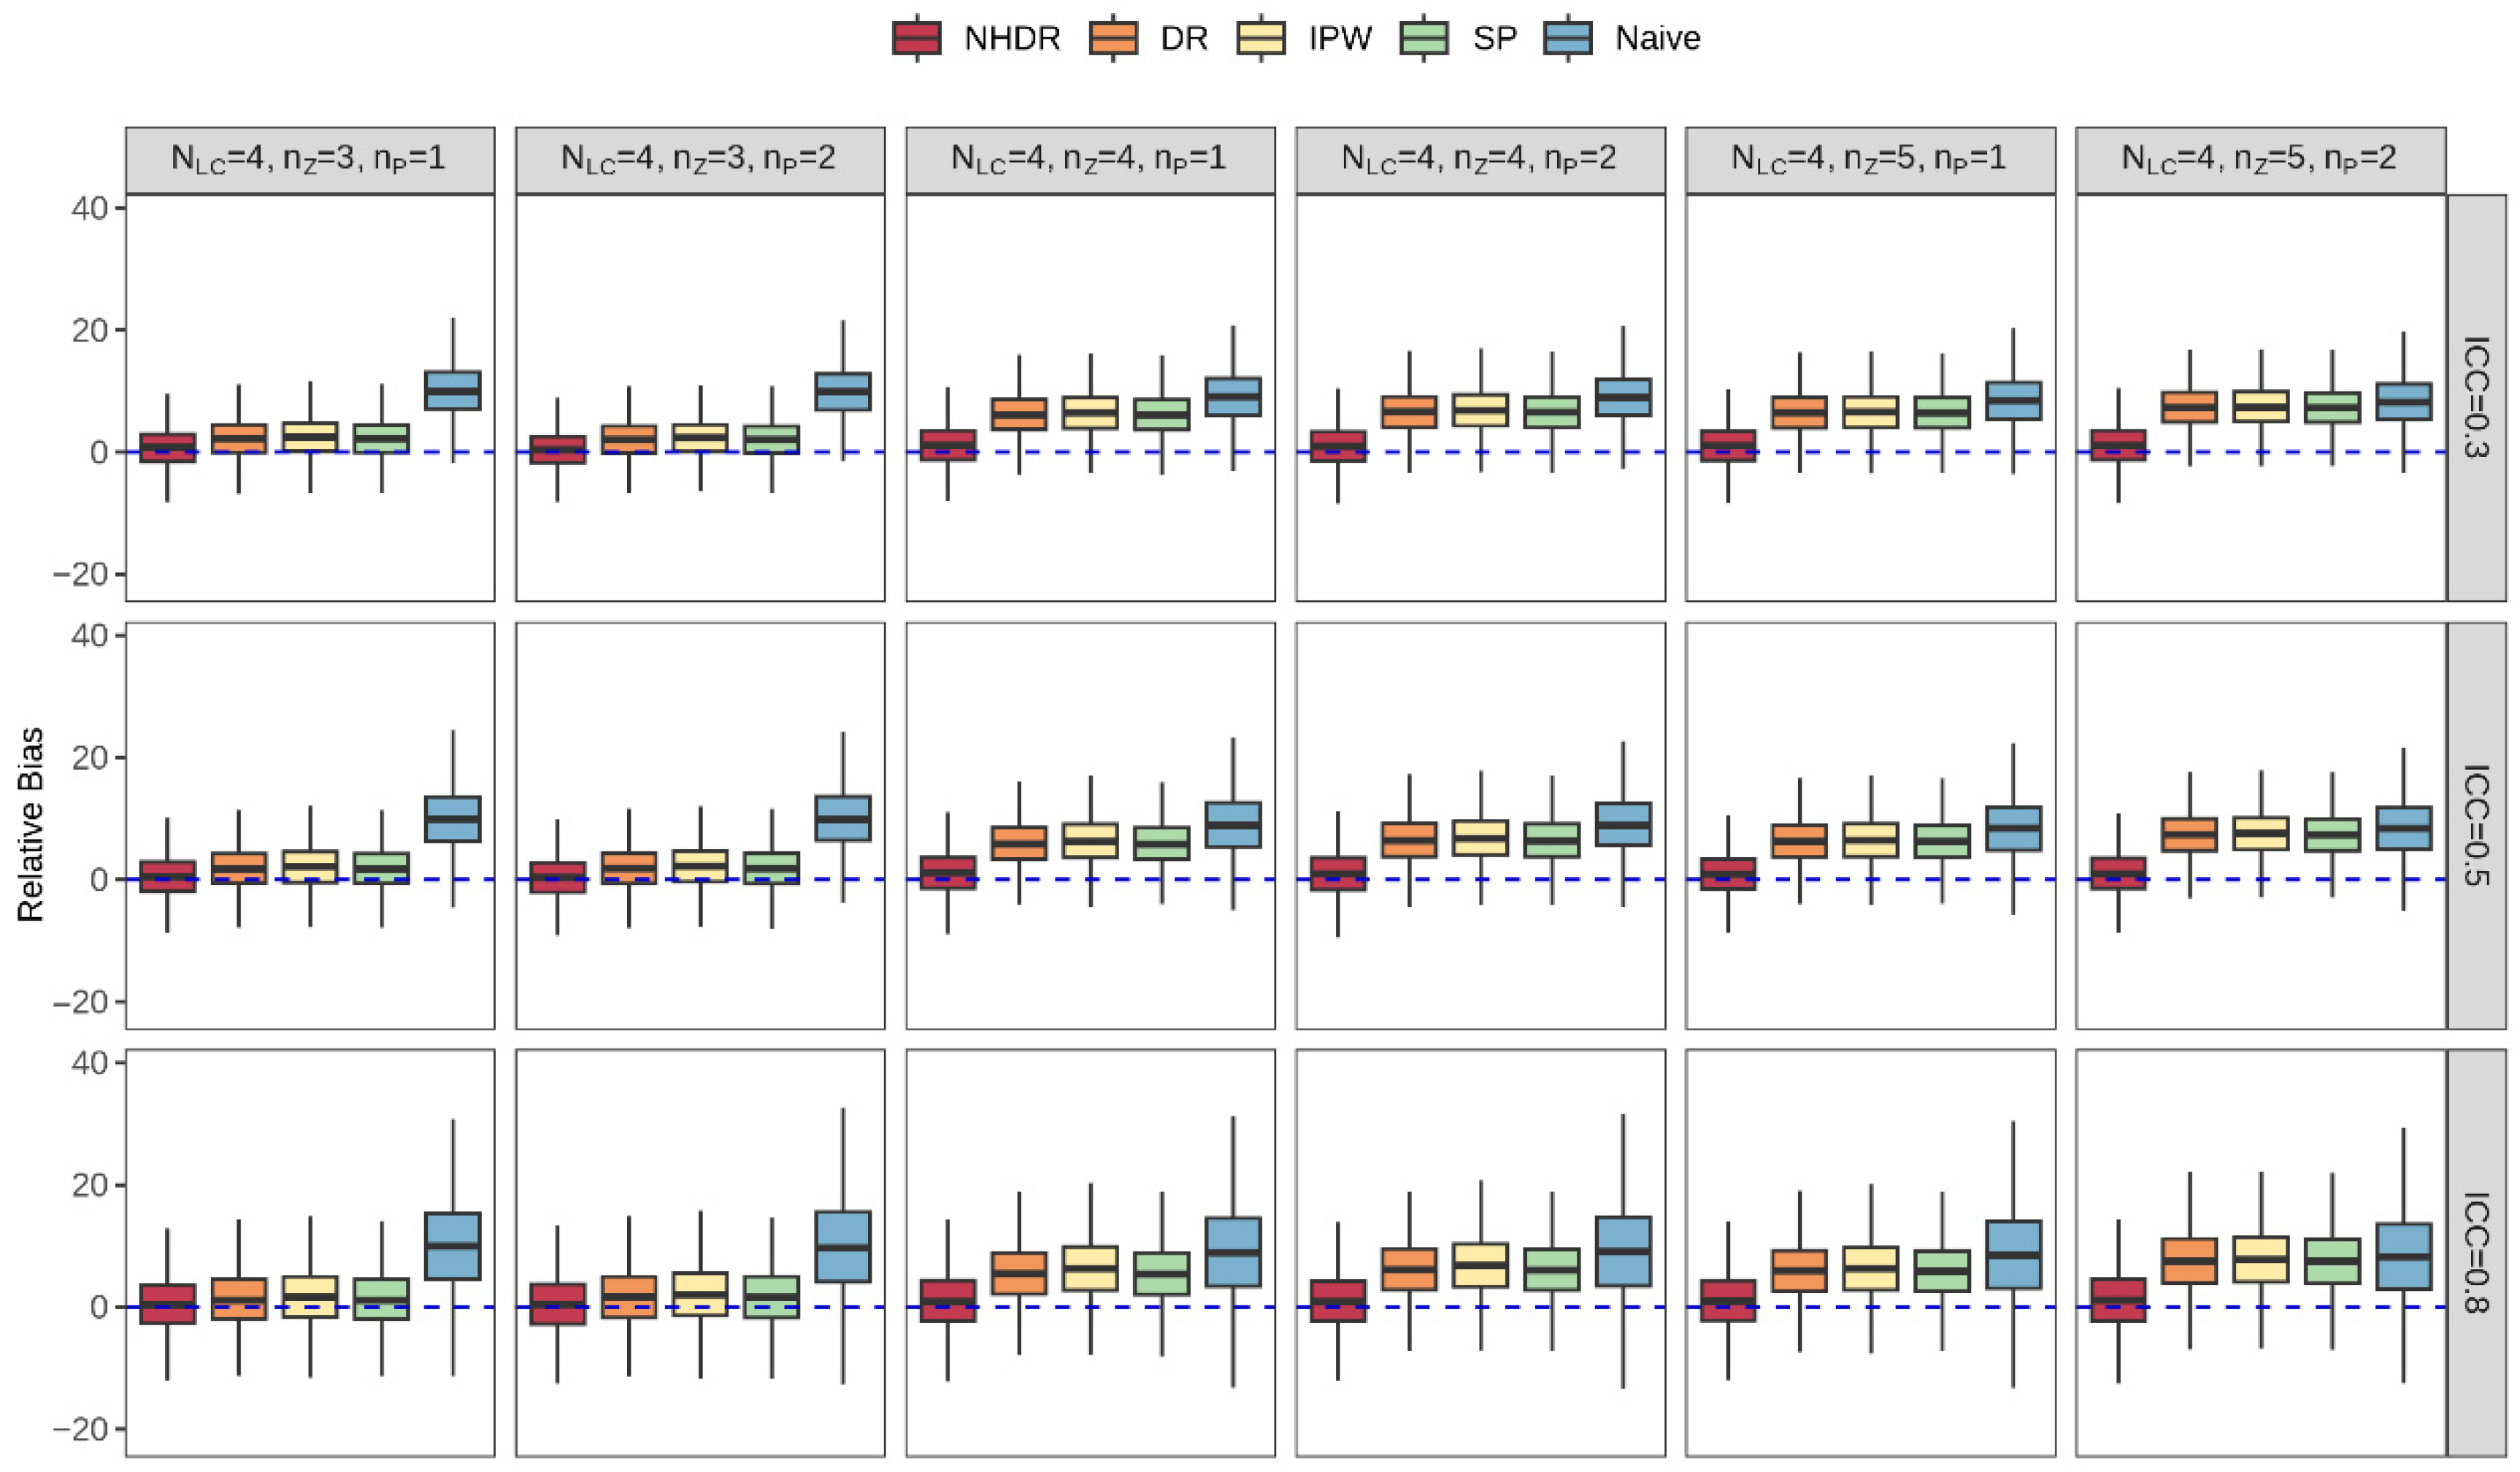
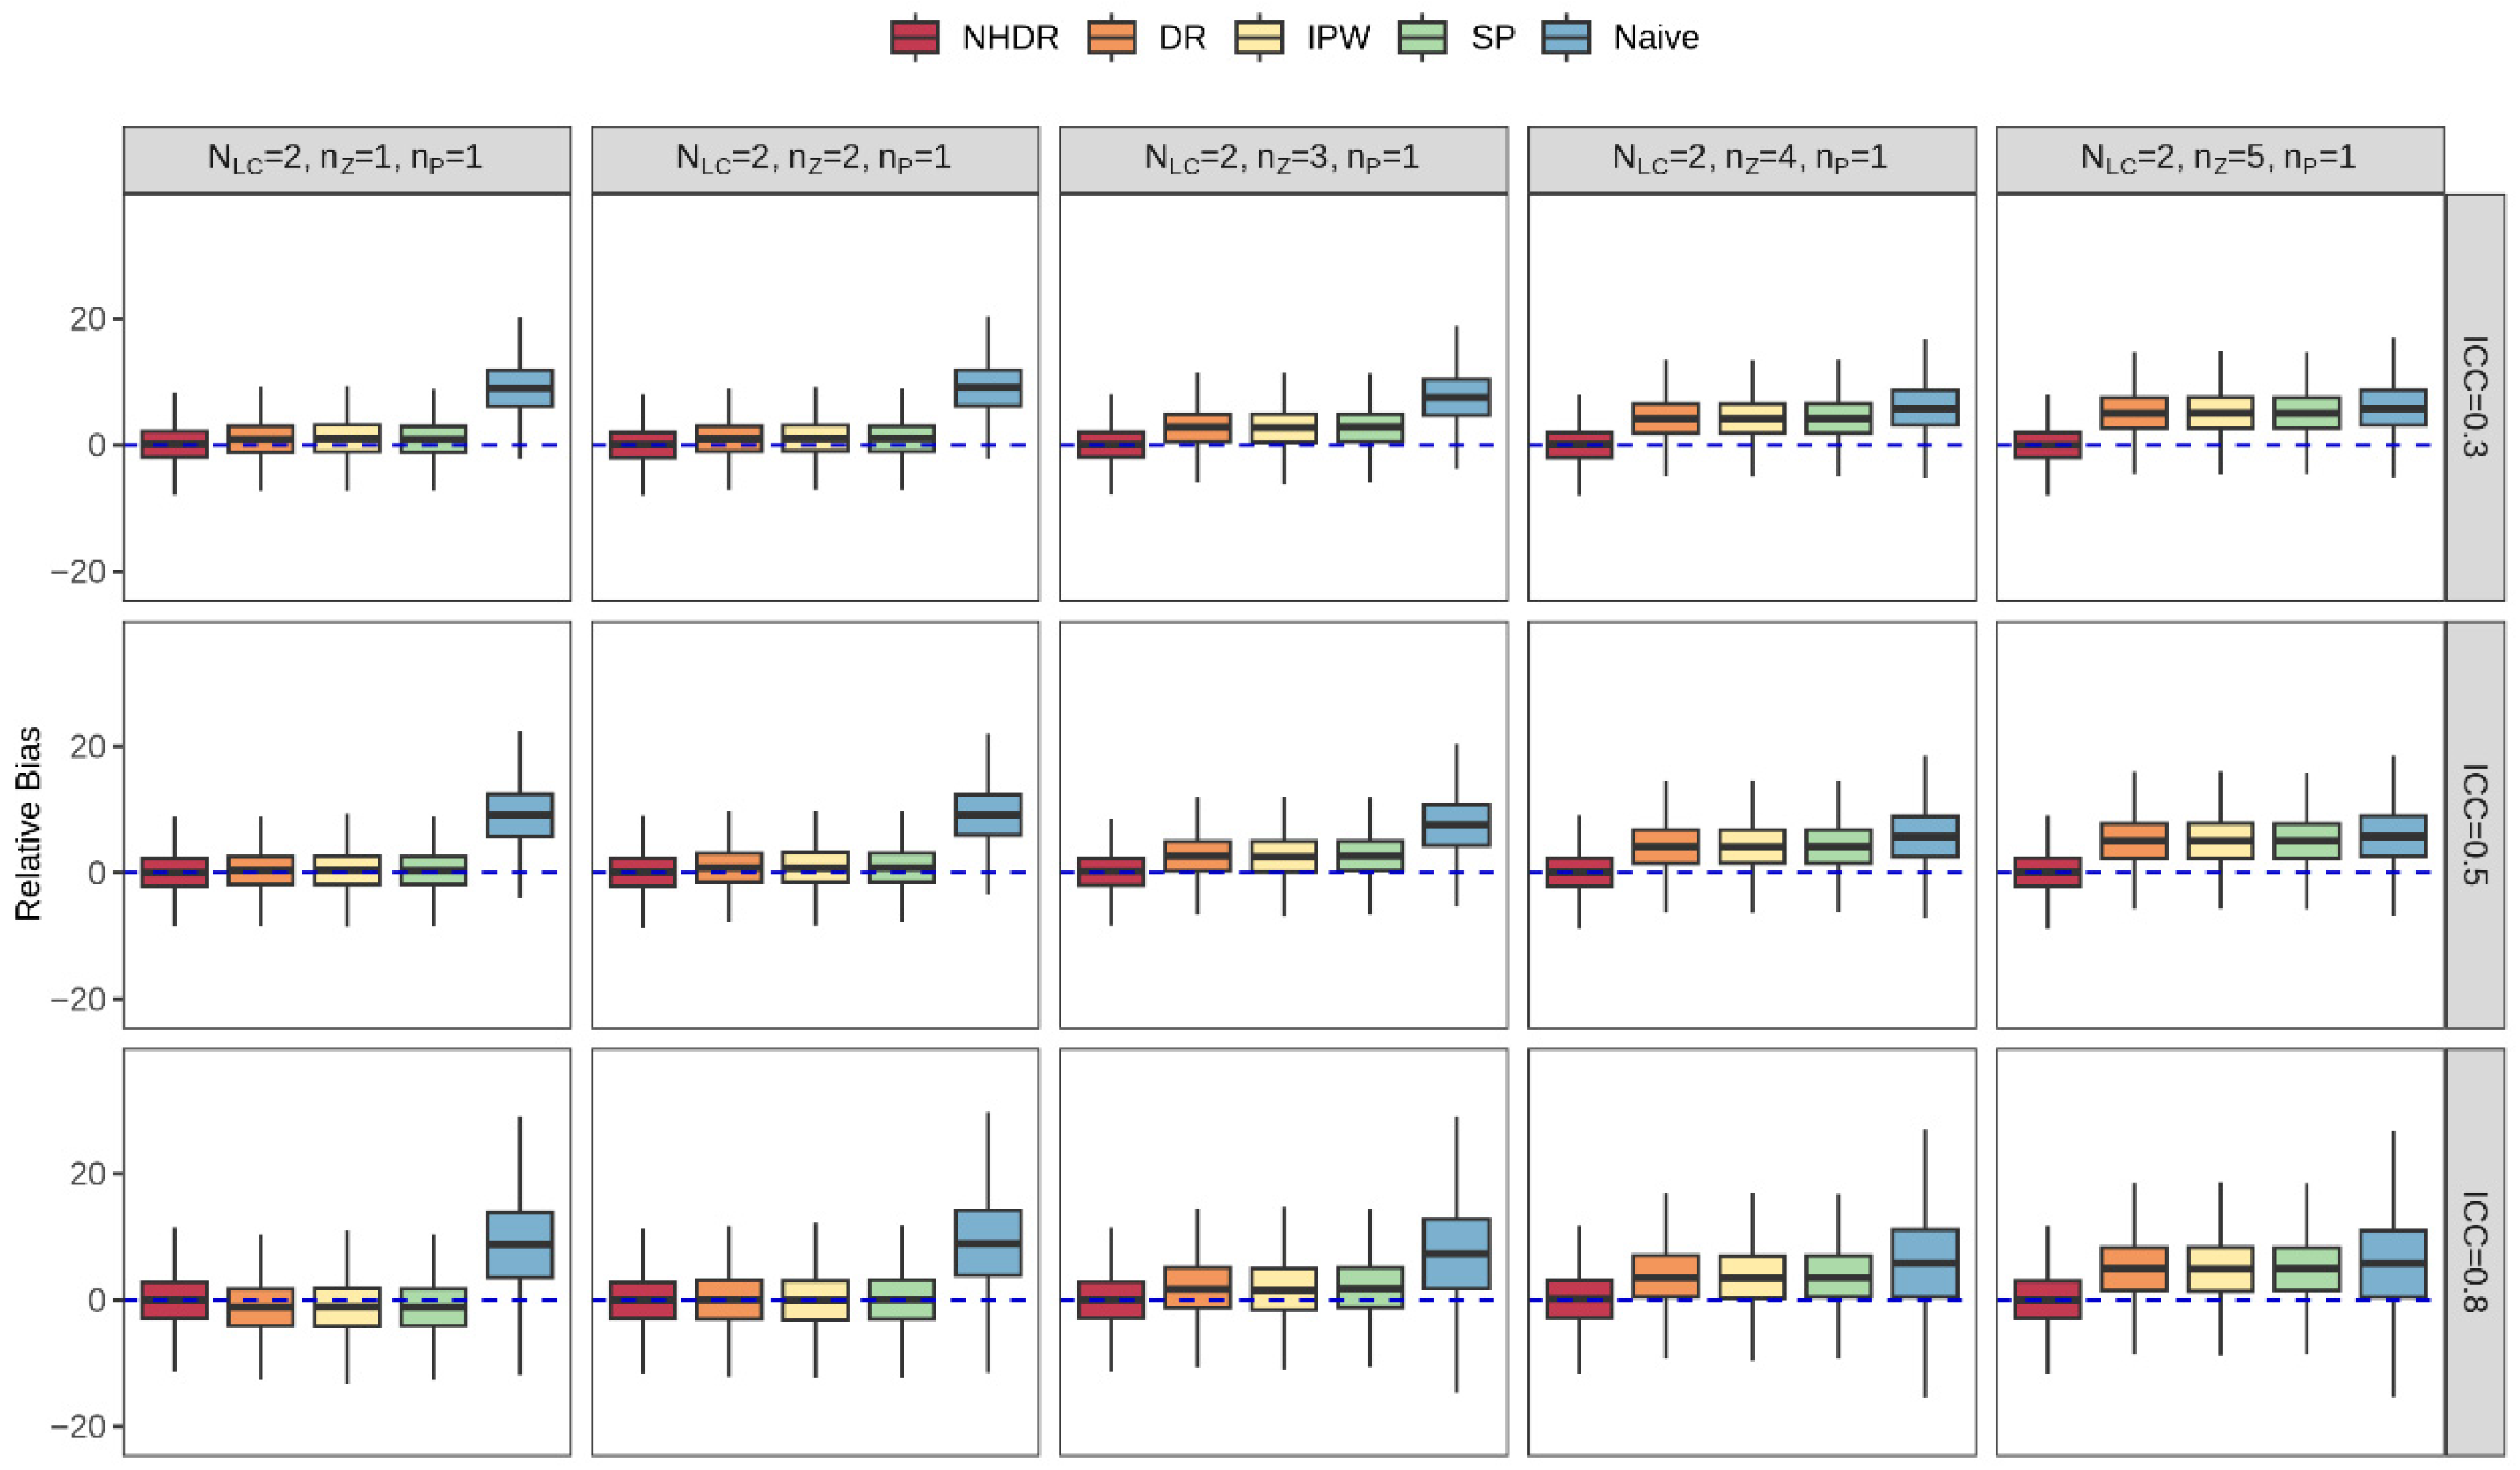
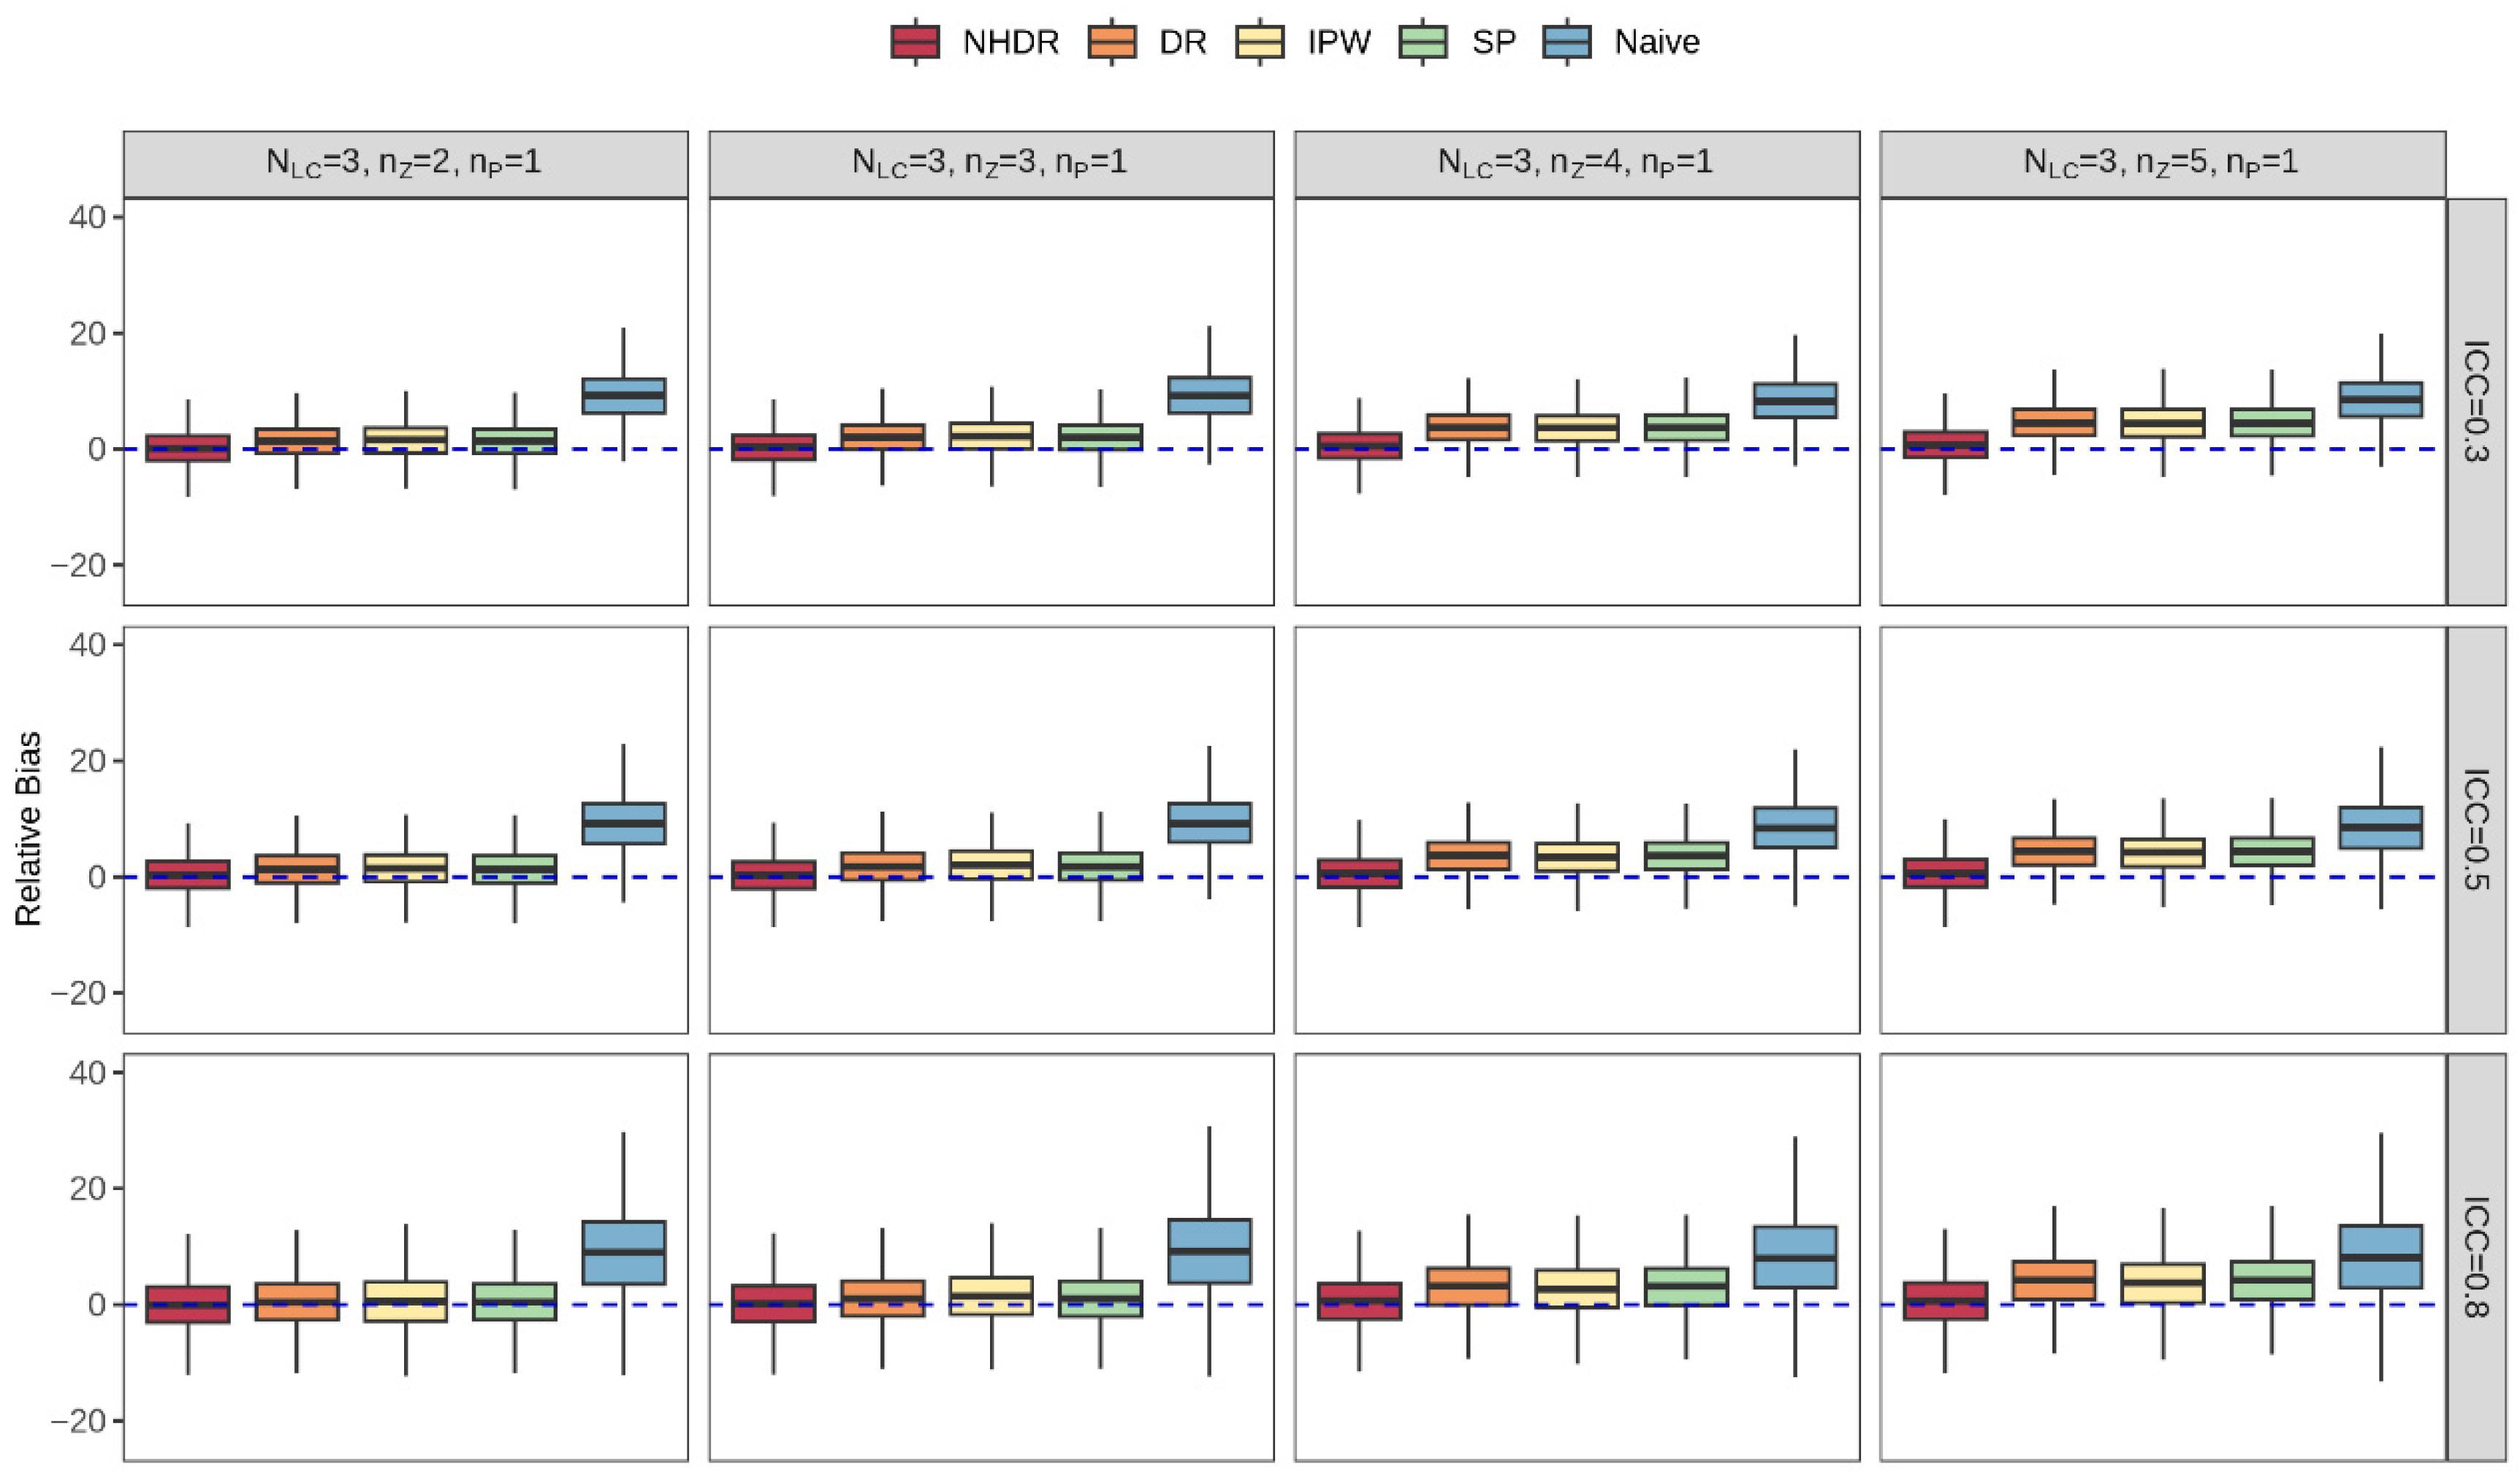
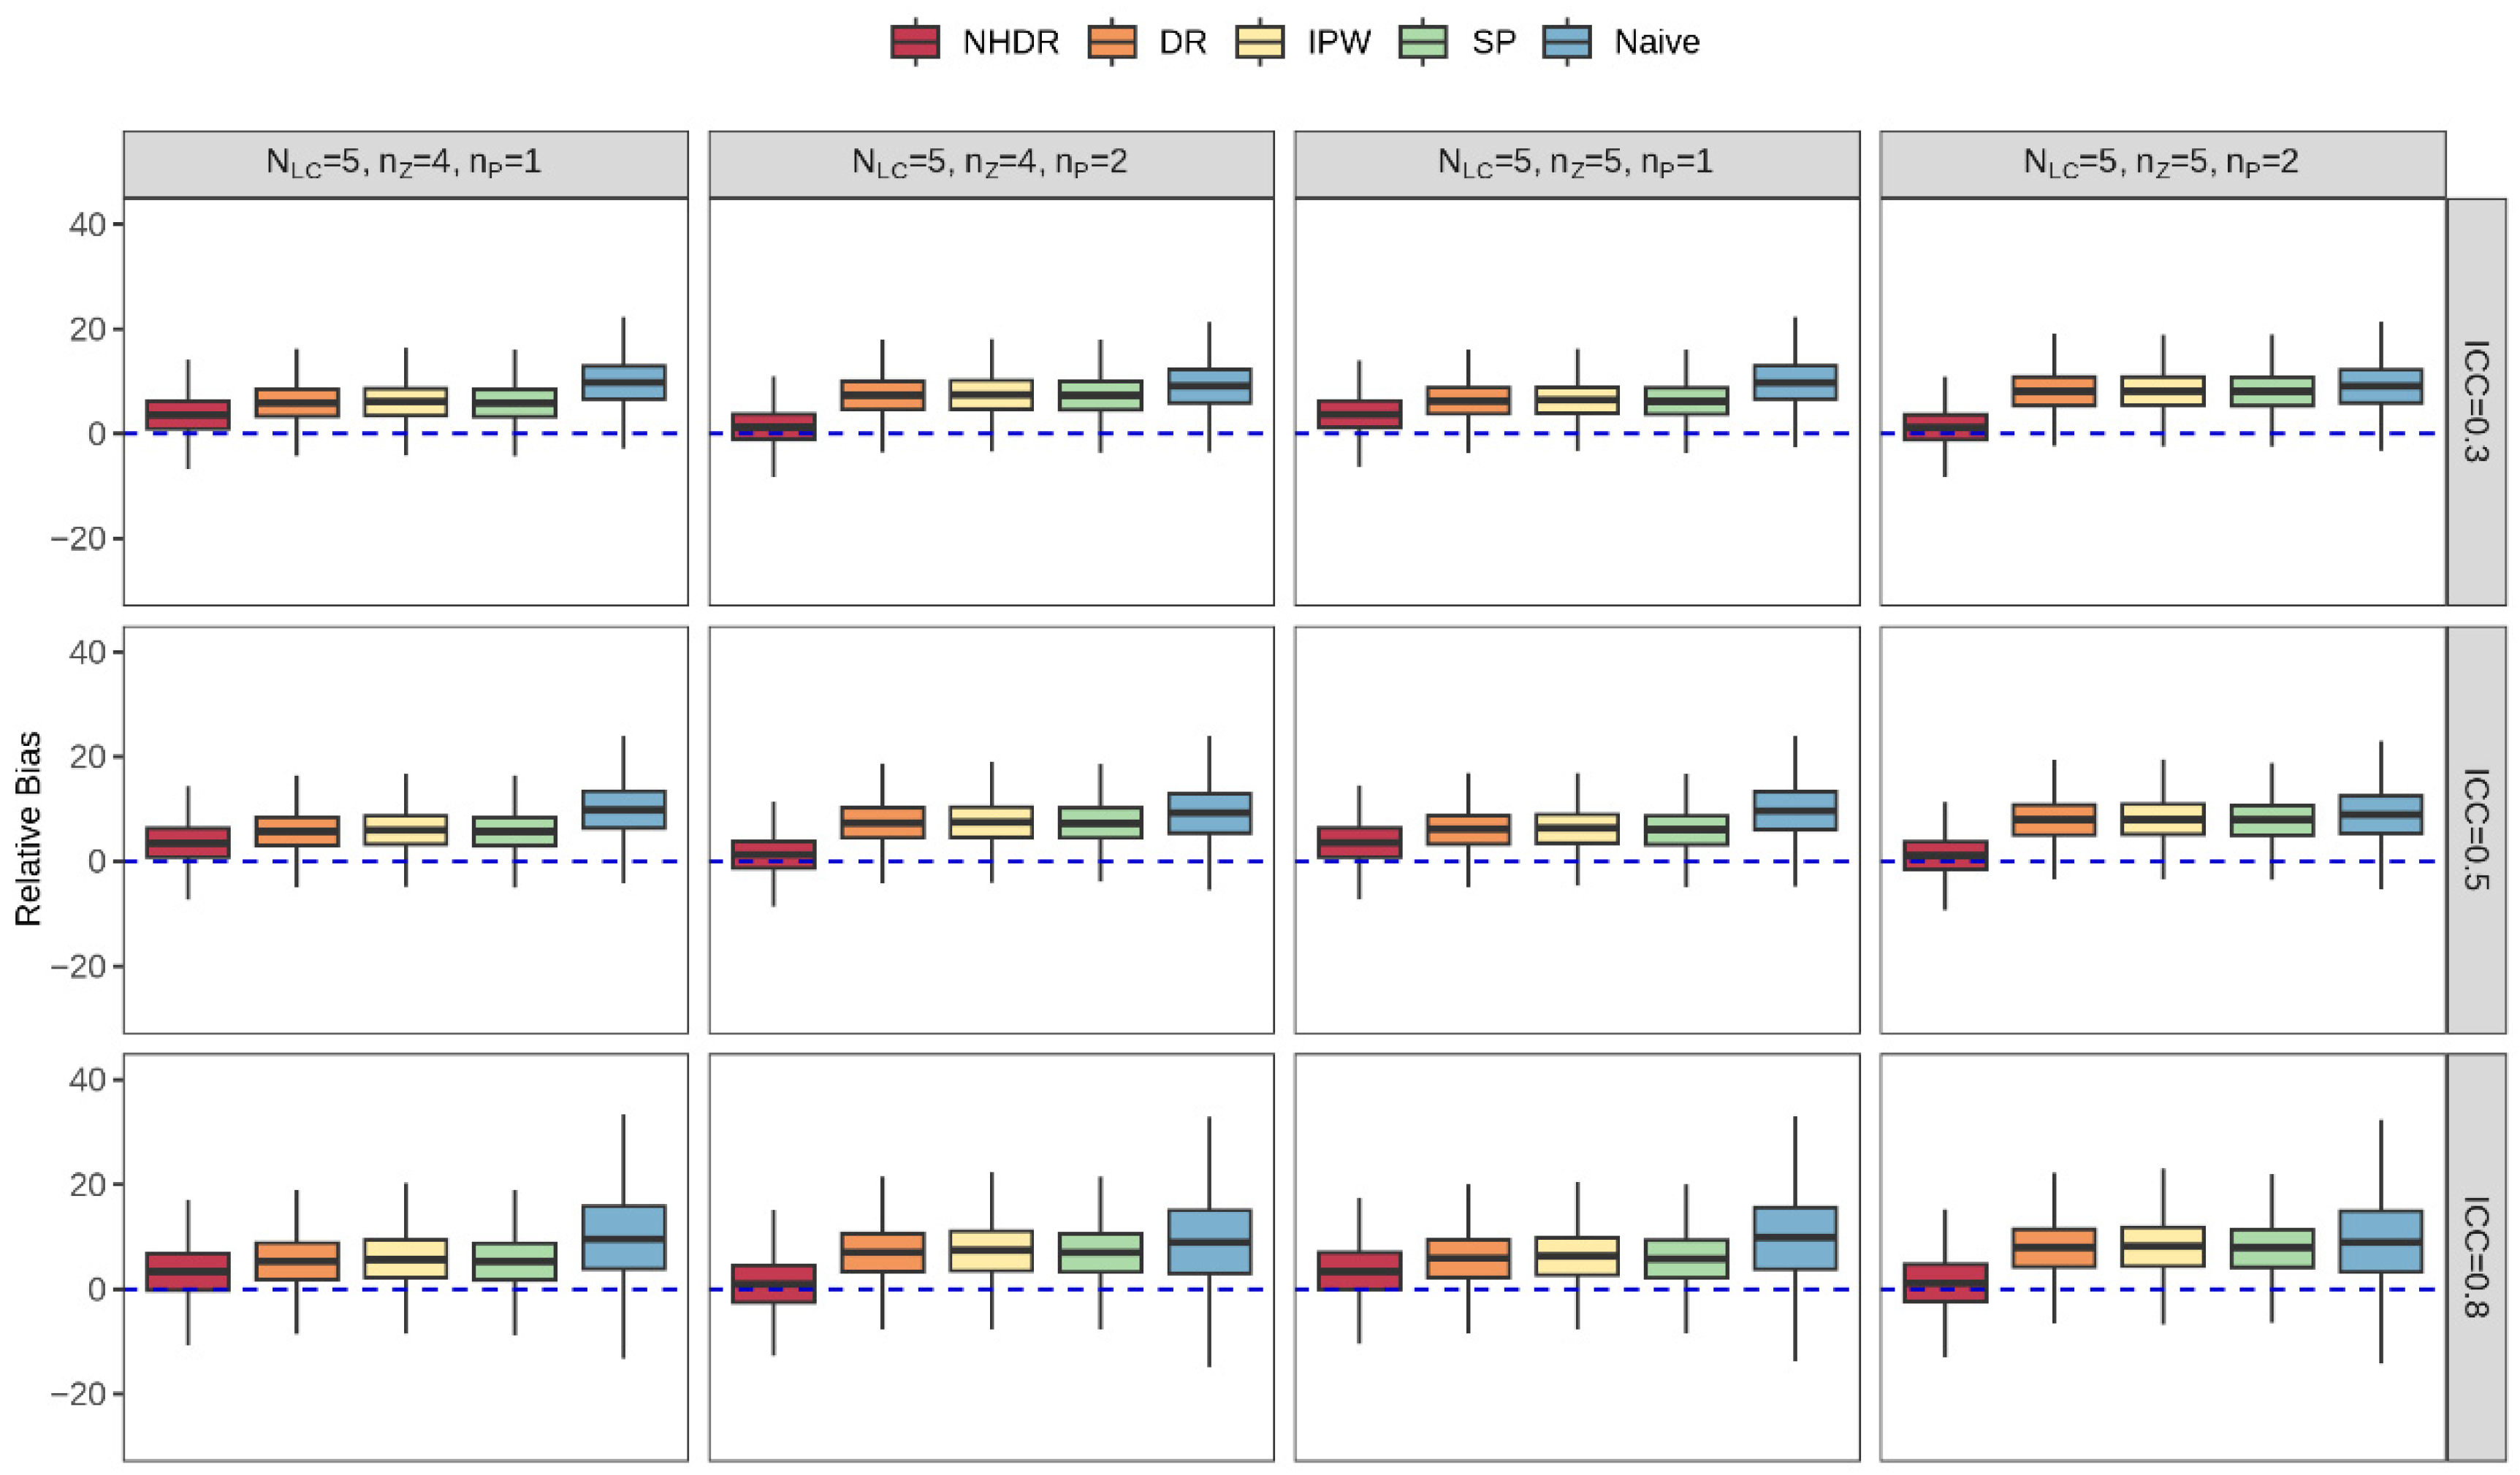
A key strength of the NHDR estimator is its ability to deliver asymptotically unbiased estimation across all heterogeneity configurations, a property that standard methods forfeit as heterogeneity increases. Under homogeneous populations ( N L C = 1 ), all methods demonstrate negligible relative bias (RB), as shown in Supplementary Figure S6. However, the RB performance of DR, SP, and IPW escalates predictably as a function of the latent structure complexity, specifically with the number of latent classes ( N L C ) and the number of covariates with sign-reversed effects ( n Z ). As Figure 2, Figure 3, Figure 4 and Figure 5 demonstrate, for N L C 2 and n Z 3 , these estimators exhibit substantial bias, while NHDR maintains RB near zero. This performance advantage reflects NHDR’s capacity to properly account for latent population heterogeneity, thereby outperforming methods that assume population-level homogeneous effects. The RB patterns remain consistent across different parameter values, with greater variability observed under larger intraclass correlation coefficients (ICC) and smaller nonprobability samples (Supplementary Figures S6–S26).
NHDR achieves superior estimation efficiency under heterogeneity, as quantified by a systematically lower mean squared error (MSE) than conventional methods. This efficiency gain, as demonstrated in identical scenarios in Table 3, is attributable to its dual mechanism of bias correction and variance control: by modeling group-specific relationships, NHDR eliminates the bias component that grows with heterogeneity complexity ( N L C , n Z , and n P ) in conventional methods, while its kernel smoothing mitigates the variance inflation from extreme weights that plague IPW. The IPW estimator exhibits characteristically elevated MSE due to extreme weights inducing high variance, despite maintaining adequate CP in most scenarios. This pattern confirms that IPW’s apparent validity in coverage metrics comes at the cost of estimation precision, substantially limiting its practical utility. MSE increases across methods with smaller n A . With larger ρ , these methods show smaller MSE for N L C = 1 (Supplementary Figure S27); however, for N L C 2 , MSE of three existing methods increase with ρ , while NHDR maintains lower values (Supplementary Figures S28–S31). Regarding confidence interval width (CIW), NHDR achieves precision comparable to DR and SP (Table 4), while IPW produces consistently wider intervals due to its inherent instability. This demonstrates NHDR’s optimal balance between precision and reliability, a pattern that persists across other parameter configurations (Supplementary Tables S16–S37).
All performance patterns remain consistent under alternative data-generating processes, including irregular covariate distributions ( D i s t = 2 ; Supplementary Tables S38–S74 and Figures S32–S48) and binary outcomes (Supplementary Tables S75–S146 and Figures S49–S82). This consistency confirms NHDR’s robustness to variations in distributional assumptions and outcome types.
In summary, our simulations yield a key practical insight: NHDR effectively addresses fundamental limitations in existing methods for handling heterogeneous populations. It provides valid, unbiased, and efficient inference precisely in those complex scenarios where existing approaches show systematic deficiencies. For continuous outcomes, NHDR achieves an average reduction in relative bias of 1.8%, 2.1%, 4.5%, and 3.8% compared to the best-performing existing method (DR) under scenarios with N L C = 2, 3, 4, and 5, respectively. Corresponding reductions in mean squared error are 5.1, 5.7, 15.5, and 11.9. The method’s performance advantage is most pronounced under moderate to strong heterogeneity ( N L C [ 2 , 4 ] ) with multiple divergent covariates ( n Z 3 ). Even when heterogeneity is underestimated ( N L C = 5 ), NHDR maintains a competitive advantage over all existing methods, demonstrating the value of partial heterogeneity adjustment. Notably, NHDR achieves these improvements while introducing minimal efficiency penalty under homogeneous conditions.

4. Application to Health Monitoring SMS Survey Data

We applied our proposed method to data from Health Monitoring SMS Survey (HMSS), a nonprobability online survey targeting Guangzhou residents aged 18–60 in China. The HMSS is administered via the Guangzhou Health Hotline 12320, a government-operated platform focusing on health education and promotion. The 12320 system randomly generated mobile phone numbers based on the demographic distribution across Guangzhou’s 11 districts. Data collection proceeded in two steps: invitations were first sent by SMS to the randomly selected phone numbers; followed by distribution of the survey link over the next day to collect responses via an electronic questionnaire. For this analysis, we use data collected in October 2024 to describe health-monitoring indicators among adult residents of Guangzhou, with a sample size of n A = 1527 participants. Nine health monitoring indicators are analyzed, with corresponding survey questions listed in Supplementary Table S147.
For the reference sample, we used data from the seventh Guangdong Health Service Survey (GHSS-7) for Guangzhou, whose surveyed period was close to that of the HMSS. The GHSS-7 employed a multi-stage stratified cluster sampling design. We denote Guangzhou data from GHSS-7 as GHSS-GZ-7. After excluding individuals aged under 18 or over 60, the final GHSS-GZ-7 sample comprises n B = 9299 individuals. Common covariates Z between HMSS and GHSS-GZ-7 include sex, age, employment status, marital status, educational level, and district.
We first compared the distributions of the common variables between the HMSS and GHSS-GZ-7 datasets using chi-square tests. Table 5 shows that all covariates differ statistically significant between the two samples. Compared to GHSS-GZ-7, the HMSS sample has higher proportions of individuals who are female, aged younger, employed, unmarried, and who had attained a college degree or higher. The HMSS sample is more concentrated in central urban districts.
We then applied our proposed NHDR method to estimate health indicators using the HMSS dataset, setting the maximum number of latent classes L C M to 5 as supported by existing studies [25,40,41]. The FMM within the NHDR procedure was fitted using the six common covariates available in both samples. Electronic screen use was treated as continuous outcome, while all other indicators were binary. For comparison, we include estimates from three existing methods (DR, IPW, and SP) as well as a naïve method for comparison. Finite mixture modelling identified five socio-demographically distinct latent classes, with significant differences across all covariates (all p < 0.001; Supplementary Table S148). The distribution of these classes was uneven, ranging from 8.8% (older retired women) to 33.6% (prime aged married residents in peripheral districts). Point estimates, 95%CI, and CIWs are summarized in Table 6. The adjusted estimates differ from the naïve estimates, confirming that covariates used for adjustment are correlated with both the health indicators and inclusion in HMSS. Estimates from DR, IPW, and SP are generally similar, while NHDR produces lower prevalence estimates for exercise over 150 min per week and poor sleep quality, and higher estimates for depression and stress. No notable differences are observed across methods for the remaining outcomes. These patterns suggest the presence of population heterogeneity underlying the outcome model. For example, regression coefficients of covariates for depression obtained from a mixed-effects model that accounts for latent classes (Supplementary Table S149) reveal divergent effects of all covariates across the five classes. Such heterogeneity is obscured in a pooled analysis of the full sample, which would lead to biased inference. In terms of precision, NHDR showed a mixed pattern relative to DR and SP: confidence intervals were similar or slightly narrower for some outcomes (e.g., weekly alcohol assumption, short sleep) but moderately wider for others, including depression and stress. The NHDR estimates remained nearly identical across analyses conducted with different random seeds (Supplementary Table S150), indicating stability with respect to initialization. Regarding computational cost, the average runtimes for DR, IPW, SP, and NHDR were 0.31 s, 0.25 s, 0.11 s, and 1765.33 s (approximately 29.4 min), respectively, reflecting the higher computational demand of the proposed method.

5. Discussion

This study introduces a Nonprobability Heterogeneity-adjusted Doubly Robust (NHDR) estimator. Its core methodological contribution is the formal integration of latent-class discovery—implemented via finite mixture modeling—into the doubly robust estimation framework, thereby addressing the well-documented failure of standard methods under latent population heterogeneity. Unlike conventional approaches that presume global homogeneity in the covariate–outcome/selection relationships, NHDR explicitly accommodates heterogeneity through a principled, three-stage procedure: (1) identification of latent subpopulations using finite mixture modeling; (2) incorporation of the estimated class memberships as a grouping variable in mixed-effects models for both the propensity score and the outcome projection; and (3) construction of a kernel-smoothed doubly robust estimator. This architecture preserves the double-robustness property within each latent stratum, ensuring consistency when either the stratum-specific propensity score or outcome model is correctly specified. Extensive simulations substantiate this theoretical advance. In heterogeneous settings where standard estimators exhibit systematic under-coverage and bias, NHDR robustly maintains nominal coverage and approximate unbiasedness. Furthermore, it delivers uniformly lower mean squared error and confidence intervals of comparable or superior precision, demonstrating a more favorable bias–variance trade-off. Critically, this performance profile is corroborated by applied evidence: estimates of health indicators from the Health Monitoring SMS Survey obtained via NHDR not only align with the simulation-based performance trends but also differ substantively from those produced by unadjusted or conventional adjustment methods—a pattern consistent with the presence of latent subgroups. Collectively, these findings establish NHDR as a valid and efficient inferential tool for nonprobability samples drawn from heterogeneous populations.
The primary contribution of NHDR lies in its identification and adjustment for the population heterogeneity. By detecting heterogeneous subpopulations via FMM, NHDR effectively reduces bias stemming from heterogeneous relationships between covariates and both the outcome ( Y ) and selection mechanism ( R ). This is achieved by integrating the estimated latent class structure into both the propensity score and outcome projection models. The method requires pre-specifying the maximum number of latent classes ( L C M ), with the optimal number ( L C ) determined using BIC. However, if L C M is set lower than the true number of classes, NHDR’s performance may deteriorate, as observed in simulations when N L C = 5 . Thus, when prior knowledge is available, it should guide the choice of L C M ; in the absence of such information, we recommend a conservative value of L C M as suggested in literature [33] to improve detection of underlying heterogeneous subpopulations.
To simulate the heterogeneous scenarios, we draw upon empirical studies that typically report fewer than five distinct subgroups in population-level data [25,40,41]. Accordingly, we varied the number of heterogeneous populations ( N L C ) from 1 to 5, where N L C = 1 corresponds to the homogeneity scenario, and N L C [ 2 ,   5 ] represents the heterogeneous scenarios. For each value of N L C , we further diversify the heterogeneity patterns using two parameters: n Z (number of covariates exhibiting subpopulation-specific effects) and n P (number of subpopulations demonstrating reversed effect directions). The degree of between-subpopulation heterogeneity was rigorously controlled through the intraclass correlation coefficient (ICC), set as low, moderate, and high levels for each combination of N L C , n Z and n P . This comprehensive simulation design ensures a realistic representation of heterogeneous conditions. The robust performance of NHDR across these simulated scenarios confirms its reliability and applicability.
We also observe that larger nonprobability sample sizes ( n A ) lead to marked declines in CPs for the three existing methods. These underscores a critical pitfall in the analysis of nonprobability samples: increased sample size does not automatically mitigate selection bias and may even amplify it, resulting in more severely biased estimates and erroneous conclusions [44]. Moreover, a stronger association between covariates ( Z ) and the outcome or selection mechanism (as represented by higher ρ ) further impair the performance of existing methods. This suggests that even high informative auxiliary variables cannot correct for bias if underlying heterogeneity in the relationship between Z Y and Z R is ignored. Therefore, accurately accounting for population heterogeneity is essential for valid inference from nonprobability samples.
In the applied analysis, the proposed NHDR estimator produced moderately wider confidence intervals for several outcomes compared to conventional methods—a pattern not fully mirrored our simulation results. This discrepancy can be attributed to how latent heterogeneity is formally incorporated within the NHDR framework. Specifically, NHDR introduces the latent-class variable as a second-level grouping factor in mixed-effects models, thereby explicitly modeling between-class heterogeneity in both the outcome-generating ( Z Y ) and selection ( Z R ) mechanisms. This modeling strategy introduces an additional variance component that naturally inflates the estimator’s variance when underlying heterogeneity exists, resulting in wider intervals that more accurately reflect the underlying sampling uncertainty in a heterogeneous population. The variance estimator for NHDR conditions on the point-estimated latent-class assignments from the first-stage finite mixture model—a pragmatic simplification typical of two-step frameworks to preserve computational feasibility. Critically, our simulation studies demonstrated that NHDR consistently achieved nominal coverage across diverse heterogeneous scenarios. This indicates that, for the settings considered, the practical consequence of this simplification on inference validity is minimal. Thus, the wider intervals observed in practice are a coherent and expected outcome of modeling latent subgroups, not an indication of instability. They represent a more statistically honest quantification of uncertainty when population heterogeneity is present. Future work could explore variance estimators that more fully integrate clustering uncertainty.
The NHDR framework provides a principled approach for selection bias adjustment under latent heterogeneity. Its effective implementation involves several methodological trade-offs. First, NHDR’s performance depends on whether the common covariate set Z can capture latent heterogeneity. Simulation results show that even with moderate population-level correlation (e.g., ρ = 3 ) between Z and the outcome/selection mechanism, NHDR retains a clear advantage over methods that ignore heterogeneity, as it explicitly models subgroup-specific Z Y and Z R relationships. Only when Z is entirely uninformative for both latent classes and direct associations would NHDR offer no improvement over conventional approaches. Second, NHDR is sensitive to the number of latent classes specified. Under-specification (e.g., setting L C M = 4 when N L C = 5 ) leads to residual confounding and reduced coverage, as our simulations confirm. Over-specification, while less harmful to bias, increases model complexity and may destabilize mixed-effects estimates. Empirical evidence suggests that substantively interpretable latent subgroups in regional populations are typically limited in number; thus, instability from moderate over-specification is of low practical concern. The key recommendation is to avoid under-specifying the number of classes. Third, NHDR relies on the conditional-independence assumption of covariates within latent classes—a standard but strong simplification for public-health data. The estimator’s dependence on between-class distributional differences suggests potential robustness to mild violations; however, strongly correlated covariates may affect latent-class recovery and estimate stability. Future work should explicitly examine performance under correlated covariate structures. Finally, practitioners should recognize an inherent efficiency–complexity trade-off: improved inferential validity under heterogeneity comes with increased computational cost. NHDR is therefore most appropriate when latent heterogeneity is plausible and substantively justified covariates are available.
The NHDR method has several advantages. First, by leveraging covariates to identify latent population structure, it adjusts for heterogeneity in both the propensity score and outcome projection models, improving inferential accuracy. Second, although the variance estimator for NHDR does not fully account for the additional uncertainty introduced by the random effects in our mixed-effects models, the empirically robust simulated coverage probabilities provide strong reassurance against this theoretical limitation. Third, FMM accommodates mixed variable types (binary, multinomial and continuous), enhancing flexibility and practical utility compared to traditional methods such as latent class analysis or latent profile analysis, which are limited to single type of variable [45].
Nonetheless, there are some limitations in the NHDR method. First, our current approach assumes the same latent population structure for both the propensity score and outcome projection models. However, this may not hold true in practice since relationships for Z Y and Z R may be different. Thus, identification of outcome-specific latent population structure will be our future research interest. Second, the assumed linearity in the mixed-effects models may fail to capture more complex relationships. Future research could extend this method to accommodate non-linear associations for further improvement. Third, the current simulation study did not examine more complex conditions—such as correlated covariates and imbalanced class sizes—that are often encountered in real-world survey data. Further research is therefore needed to evaluate the method’s robustness under these more realistic and challenging scenarios. Fourth, the HMSS relies on self-reported measures, which are subject to recall and social-desirability biases. These data-collection limitations do not affect the relative performance of the methods compared but caution against over-generalizing the absolute prevalence estimates beyond the study context. Fifth, the NHDR method incurs a substantially higher computational cost than conventional adjustment methods, reflecting the complexity of its two-stage modeling framework. Future work should focus on algorithmic improvements to enhance scalability.

6. Conclusions

With the increasing use of nonprobability sampling in epidemiologic research, selection bias poses a critical threat to the validity and accuracy of inference. A common shortcoming of existing adjustment methods is their neglect of the latent heterogeneity in the covariate-outcome and covariate-inclusion relationships, which can bias conclusions drawn from nonprobability samples. To address this gap, we propose the Nonprobability Heterogeneity-adjusted Doubly Robust (NHDR) method, which explicitly accounts for population heterogeneity during bias adjustment by identifying and integrating latent subpopulations into the adjustment procedure. The core contribution of NHDR lies in its formal integration of latent-class-based population structure into a doubly robust framework, enabling more reliable inference under heterogeneous population structures. Simulation results show that the proposed method control the coverage probabilities well in most scenarios. Under the simulated scenarios with population heterogeneity, the proposed method consistently exhibits lower relative bias and mean squared error compared to existing methods. We apply the proposed method to Health Monitoring SMS Survey data in Guangzhou China, results of which are generally consistent with the simulation evidence. Therefore, when population heterogeneity is present, NHDR provides more accurate inference than existing approaches and represents a recommended option for analysis. The proposed method is subject to several limitations. First, inference depends on a limited set of common covariates available across samples and may be sensitive to misspecification of the latent class structure. Additionally, further investigation is needed to assess its performance in more complex settings—such as high-dimensional data and scenarios where the conditional independence assumption is violated.

Supplementary Materials

The following supporting information can be downloaded at: https://www.mdpi.com/article/10.3390/math14010118/s1, Section S1: Regularity conditions; Section S2: Justification of the Monotonicity and Convergence of the EM Algorithm; Section S3: Proof of Lemma 1 (Asymptotic Efficiency Improvement from Kernel Smoothing); Section S4: Proof of Theorem 1 (Consistency and Asymptotic Normality of NHDR Estimator); Section S5: Derivation of V N H D R ; Section S6: Proof of Consistency of the NHDR Variance Estimator; Section S7: Determination of intercept terms for the outcome-generating models when N L C = 2 ; Section S8: Minimum number of simulation times; Table S1: Distribution parameters of covariates across different subpopulations; Table S2: Regression coefficients of sex, age, and educational level for depression risk (Overall and within lifestyle subgroups); Table S3: Sign configuration for covariates across different scenarios; Table S4: Values of parameters in simulation studies; Tables S5–S15: Simulated coverage probabilities (%) of different methods under Dist = 1 and other parameter values for continuous outcomes; Tables S16–S26: Simulated mean squared error (×103) of different methods under Dist = 1 and other parameter values for continuous outcomes; Tables S27–S37: Simulated confidence interval width of different methods under Dist = 1 and other parameter values for continuous outcomes; Tables S38–S49: Simulated coverage probabilities (%) of different methods under Dist = 2 for continuous outcomes; Tables S50–S62: Simulated mean squared error (×103) of different methods under Dist = 2 for continuous outcomes; Tables S63–S74: Simulated confidence interval width of different methods under Dist = 2 for continuous outcomes; Tables S75–S98: Simulated coverage probabilities (%) of different methods for binary outcomes; Tables S99–S122: Simulated mean squared error (×103) of different methods for binary outcomes; Tables S123–S146: Simulated confidence interval width (×103) of different methods for binary outcomes; Table S147: Survey questions of nine health monitoring indicators in application to the HMSS data; Table S148: Characteristics of the five latent classes identified by finite mixture modelling in the combined HMSS and GHSS-GZ-7 sample (%); Table S149: Comparison of regression coefficients for depression: overall model vs. latent-class-specific models obtained via mixed-effects modeling; Table S150: Nine health indicators among adult Guangzhou residents in October 2024 as estimated by the NHDR method: point estimates, 95%CI, and CIW; Figure S1: Simulated coverage probabilities of different methods under N L C = 1 and Dist = 1 for continuous outcomes; Figures S2–S5: Simulated coverage probabilities of different methods under N L C = 2–5, ρ = 0.5, and Dist = 1 for continuous outcomes; Figures S6–S22: Simulated relative bias of different methods under Dist = 1 and other parameter values for continuous outcomes; Figures S23–S26: Simulated relative bias of different methods under N L C = 2–5, ICC = 0.5, and Dist = 1 for continuous outcomes; Figure S27: Simulated mean squared error (×103) of different methods under N L C = 1 and Dist = 1 for continuous outcomes; Figures S28–S31: Simulated mean squared error (×103) of different methods under N L C = 2–5, ICC = 0.5, and Dist = 1 for continuous outcomes; Figures S32–S48: Simulated relative bias of different methods under Dist = 2 for continuous outcomes; Figures S49–S82: Simulated relative bias of different methods for binary outcomes.

Author Contributions

Conceptualization: Z.Y., X.W., W.W., and J.G.; Methodology: Z.Y.; Formal analysis and investigation: Z.Y. and X.W.; Writing—original draft preparation: Z.Y.; Writing—review and editing: J.G.; Supervision: J.G. All authors have read and agreed to the published version of the manuscript.

Funding

The authors declare that no funds, grants, or other support were received during the preparation of this manuscript.

Institutional Review Board Statement

This study was performed in line with the principles of the Declaration of Helsinki. Approval was granted by the Ethics Committee of Sun Yat-sen University (No. 2020-005).

Informed Consent Statement

Informed consent was obtained from all individual participants included in the study.

Data Availability Statement

The datasets presented in this article are not readily available because the data are part of an ongoing study. Requests to access the datasets should be directed to the corresponding author.

Conflicts of Interest

The authors have no relevant financial or non-financial interests to disclose.

Software and Implementation Details

The complete R code for implementing the NHDR estimator and reproducing the simulation study is publicly available at https://github.com/ZiyingYang118/NHDR (accessed on 21 December 2025). All analyses were performed using R version 4.2.3. Critical packages included lme4 (version 1.1-35.1) for fitting generalized linear mixed-effects models, depmixS4 (version 1.5.0) for estimating finite mixture models via the EM algorithm, and KWML (version 1.0.1) for calculating kernel-smoothed weights. In the simulation study, performance metrics were estimated over 3000 independent Monte Carlo replicates without a fixed global random seed to approximate the expected long-run frequentist properties of the estimators. For the applied analysis, results are reproducible using the specific random seed indicated below the table.

References

  1. Elliott, M.R.; Valliant, R. Inference for Nonprobability Samples. Stat. Sci. 2017, 32, 249–264. [Google Scholar] [CrossRef] [Scilit]
  2. Czajka, J.L.; Beyler, A. Declining Response Rates in Federal Surveys: Trends and Implications; Background Paper; Mathematica Policy Research: Washington, DC, USA, 2016. [Google Scholar]
  3. Barbier, S.; Loosveldt, G.; Carton, A. (Eds.) The flemish survey climate: An analysis based on the survey of social-cultural changes in flanders. In Proceedings of the International Workshop on Household Survey Nonresponse, Leuven, Belgium, 2–4 September 2015. [Google Scholar]
  4. Valliant, R.; Dever, J.A.; Kreuter, F. Practical Tools for Designing and Weighting Survey Samples; Springer International Publishing: Cham, Switzerland, 2018. [Google Scholar]
  5. Matias, J.; Leavitt, A. COVID-19 Social Science Research Tracker. 2020. Available online: https://github.com/natematias/covid-19-social-science-research (accessed on 21 December 2025).
  6. Green, R.K.; Nieser, K.J.; Jacobsohn, G.C.; Cochran, A.L.; Caprio, T.V.; Cushman, J.T.; Kind, A.J.; Lohmeier, M.; Shah, M.N. Differential effects of an emergency department-to-home care transitions intervention in an older adult population: A latent class analysis. Med. Care 2023, 61, 400–408. [Google Scholar] [CrossRef] [Scilit]
  7. del Mar Rueda, M.; Pasadas-del-Amo, S.; Rodríguez, B.C.; Castro-Martín, L.; Ferri-García, R. Enhancing estimation methods for integrating probability and nonprobability survey samples with machine-learning techniques. An application to a Survey on the impact of the COVID-19 pandemic in Spain. Biom. J. 2023, 65, 2200035. [Google Scholar] [CrossRef] [Scilit]
  8. Wu, C. Statistical inference with non-probability survey samples. Surv. Methodol. 2022, 48, 283–311. [Google Scholar]
  9. Baker, R.; Brick, J.M.; Bates, N.A.; Battaglia, M.; Couper, M.P.; Dever, J.A.; Gile, K.J.; Tourangeau, R. Summary report of the AAPOR task force on non-probability sampling. J. Surv. Stat. Methodol. 2013, 1, 90–143. [Google Scholar] [CrossRef] [Scilit]
  10. Bradley, V.C.; Kuriwaki, S.; Isakov, M.; Sejdinovic, D.; Meng, X.-L.; Flaxman, S. Unrepresentative big surveys significantly overestimated US vaccine uptake. Nature 2021, 600, 695–700. [Google Scholar] [CrossRef] [Scilit]
  11. Yang, S.; Kim, J.K. Statistical data integration in survey sampling: A review. Jpn. J. Stat. Data Sci. 2020, 3, 625–650. [Google Scholar] [CrossRef] [Scilit]
  12. Cornesse, C.; Blom, A.G.; Dutwin, D.; Krosnick, J.A.; De Leeuw, E.D.; Legleye, S.; Pasek, J.; Pennay, D.; Phillips, B.; Sakshaug, J.W.; et al. A Review of Conceptual Approaches and Empirical Evidence on Probability and Nonprobability Sample Survey Research. J. Surv. Stat. Methodol. 2020, 8, 4–36. [Google Scholar] [CrossRef] [Scilit]
  13. Valliant, R. Comparing Alternatives for Estimation from Nonprobability Samples. J. Surv. Stat. Methodol. 2020, 8, 231–263. [Google Scholar] [CrossRef] [Scilit]
  14. Valliant, R.; Dever, J.A. Estimating Propensity Adjustments for Volunteer Web Surveys. Sociol. Methods Res. 2011, 40, 105–137. [Google Scholar] [CrossRef] [Scilit]
  15. Castro-Martín, L.; del Mar Rueda, M.; Ferri-García, R. Combining statistical matching and propensity score adjustment for inference from non-probability surveys. J. Comput. Appl. Math. 2022, 404, 113414. [Google Scholar] [CrossRef] [Scilit]
  16. Wang, L.; Graubard, B.I.; Katki, H.A.; Li, Y. Improving external validity of epidemiologic cohort analyses: A kernel weighting approach. J. R. Stat. Soc. Ser. A (Stat. Soc.) 2020, 183, 1293–1311. [Google Scholar] [CrossRef] [Scilit]
  17. Kern, C.; Li, Y.; Wang, L. Boosted Kernel Weighting—Using Statistical Learning to Improve Inference from Nonprobability Samples. J. Surv. Stat. Methodol. 2021, 9, 1088–1113. [Google Scholar] [CrossRef] [Scilit]
  18. Dagdoug, M.; Goga, C.; Haziza, D. Model-Assisted Estimation Through Random Forests in Finite Population Sampling. J. Am. Stat. Assoc. 2023, 118, 1234–1251. [Google Scholar] [CrossRef] [Scilit]
  19. Downes, M.; Gurrin, L.C.; English, D.R.; Pirkis, J.; Currier, D.; Spittal, M.J.; Carlin, J.B. Multilevel Regression and Poststratification: A Modeling Approach to Estimating Population Quantities From Highly Selected Survey Samples. Am. J. Epidemiol. 2018, 187, 1780–1790. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  20. Chen, Y.; Li, P.; Wu, C. Doubly robust inference with nonprobability survey samples. J. Amer. Stat. Assoc. 2020, 115, 2011–2021. [Google Scholar] [CrossRef] [Scilit]
  21. Chen, S.; Haziza, D. General purpose multiply robust data integration procedures for handling nonprobability samples. Scand. J. Stat. 2023, 50, 697–724. [Google Scholar] [CrossRef] [Scilit]
  22. Muthin, B.O. Latent variable modeling in heterogeneous populations. Psychometrika 1989, 54, 557–585. [Google Scholar] [CrossRef] [Scilit]
  23. Fitch, P.J.R.; Lovell, M.A.; Davies, S.J.; Pritchard, T.; Harvey, P.K. An integrated and quantitative approach to petrophysical heterogeneity. Mar. Pet. Geol. 2015, 63, 82–96. [Google Scholar] [CrossRef] [Scilit]
  24. Myint, P.K.; Luben, R.N.; Wareham, N.J.; Bingham, S.A.; Khaw, K.-T. Combined effect of health behaviours and risk of first ever stroke in 20 040 men and women over 11 years’ follow-up in norfolk cohort of european prospective investigation of cancer (EPIC norfolk): Prospective population study. BMJ 2009, 338, b349. [Google Scholar] [CrossRef] [Scilit]
  25. Le, L.T.H.; Hoang, T.N.A.; Nguyen, T.T.; Dao, T.D.; Do, B.N.; Pham, K.M.; Vu, V.H.; Pham, L.V.; Nguyen, L.T.H.; Nguyen, H.C.; et al. Sex Differences in Clustering Unhealthy Lifestyles Among Survivors of COVID-19: Latent Class Analysis. JMIR Public Health Surveill. 2024, 10, e50189. [Google Scholar] [CrossRef] [Scilit]
  26. Lv, J.; Liu, Q.; Ren, Y.; Gong, T.; Wang, S.; Li, L.; Community Interventions for Health (CIH) Collaboration. Socio-demographic association of multiple modifiable lifestyle risk factors and their clustering in a representative urban population of adults: A cross-sectional study in hangzhou, China. Int. J. Behav. Nutr. Phys. Act. 2011, 8, 40. [Google Scholar] [CrossRef] [Scilit]
  27. Mannering, F.L.; Shankar, V.; Bhat, C.R. Unobserved heterogeneity and the statistical analysis of highway accident data. Anal. Methods Accid. Res. 2016, 11, 1–16. [Google Scholar] [CrossRef] [Scilit]
  28. Kim, S.H. How heterogeneity has been examined in transportation safety analysis: A review of latent class modeling applications. Anal. Methods Accid. Res. 2023, 40, 100292. [Google Scholar] [CrossRef] [Scilit]
  29. Kelly, S.; Kaye, S.-A.; Oviedo-Trespalacios, O. What factors contribute to the acceptance of artificial intelligence? A systematic review. Telemat. Inform. 2023, 77, 101925. [Google Scholar] [CrossRef] [Scilit]
  30. Wang, L.; Graubard, B.I.; Katki, H.A.; Li, Y. Efficient and robust propensity-score-based methods for population inference using epidemiologic cohorts. Int. Stat. Rev. 2022, 90, 146–164. [Google Scholar] [CrossRef] [Scilit]
  31. Wang, L.; Valliant, R.; Li, Y. Adjusted logistic propensity weighting methods for population inference using nonprobability volunteer-based epidemiologic cohorts. Stat. Med. 2021, 40, 5237–5250. [Google Scholar] [CrossRef] [Scilit]
  32. Kim, S.H.; Mokhtarian, P.L. Finite mixture (or latent class) modeling in transportation: Trends, usage, potential, and future directions. Transp. Res. Part B Methodol. 2023, 172, 134–173. [Google Scholar] [CrossRef] [Scilit]
  33. Lezhnina, O.; Kismihók, G. Latent Class Cluster Analysis: Selecting the number of clusters. MethodsX 2022, 9, 101747. [Google Scholar] [CrossRef] [Scilit]
  34. Henson, J.M.; Reise, S.P.; Kim, K.H. Detecting Mixtures From Structural Model Differences Using Latent Variable Mixture Modeling: A Comparison of Relative Model Fit Statistics. Struct. Equ. Model. A Multidiscip. J. 2007, 14, 202–226. [Google Scholar] [CrossRef] [Scilit]
  35. McLachlan, G.J.; Lee, S.X.; Rathnayake, S.I. Finite mixture models. Annu. Rev. Stat. Its Appl. 2019, 6, 355–378. [Google Scholar] [CrossRef] [Scilit]
  36. Sinha, P.; Calfee, C.S.; Delucchi, K.L. Practitioner’s guide to latent class analysis: Methodological considerations and common pitfalls. Crit. Care Med. 2021, 49, e63–e79. [Google Scholar] [CrossRef] [Scilit]
  37. R Core Team. R: A Language and Environment for Statistical Computing; R Foundation for Statistical Computing: Vienna, Austria, 2020. [Google Scholar]
  38. Bates, D. Computational methods for mixed models. Vignette Lme4 2011, 1045, 1046. [Google Scholar]
  39. Harpole, J.K.; Woods, C.M.; Rodebaugh, T.L.; Levinson, C.A.; Lenze, E.J. How bandwidth selection algorithms impact exploratory data analysis using kernel density estimation. Psychol. Methods 2014, 19, 428–443. [Google Scholar] [CrossRef] [Scilit]
  40. Bretos-Azcona, P.E.; Sánchez-Iriso, E.; Cabasés Hita, J.M. Tailoring integrated care services for high-risk patients with multiple chronic conditions: A risk stratification approach using cluster analysis. BMC Health Serv. Res. 2020, 20, 806. [Google Scholar] [CrossRef] [Scilit]
  41. Zhang, Z.; Abarda, A.; Contractor, A.A.; Wang, J.; Dayton, C.M. Exploring heterogeneity in clinical trials with latent class analysis. Ann. Transl. Med. 2018, 6, 119. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  42. Bourke, M.; Wang, H.F.W.; McNaughton, S.A.; Thomas, G.; Firth, J.; Trott, M.; Cairney, J. Clusters of healthy lifestyle behaviours are associated with symptoms of depression, anxiety, and psychological distress: A systematic review and meta-analysis of observational studies. Clin. Psychol. Rev. 2025, 118, 102585. [Google Scholar] [CrossRef] [Scilit]
  43. Morris, T.P.; White, I.R.; Crowther, M.J. Using simulation studies to evaluate statistical methods. Stat. Med. 2019, 38, 2074–2102. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  44. Boyd, R.J.; Powney, G.D.; Pescott, O.L. We need to talk about nonprobability samples. Trends Ecol. Evol. 2023, 38, 521–531. [Google Scholar] [CrossRef] [Scilit]
  45. Van Lissa, C.J.; Garnier-Villarreal, M.; Anadria, D. Recommended Practices in Latent Class Analysis Using the Open-Source R-Package tidySEM. Struct. Equ. Model. A Multidiscip. J. 2024, 31, 526–534. [Google Scholar] [CrossRef] [Scilit]
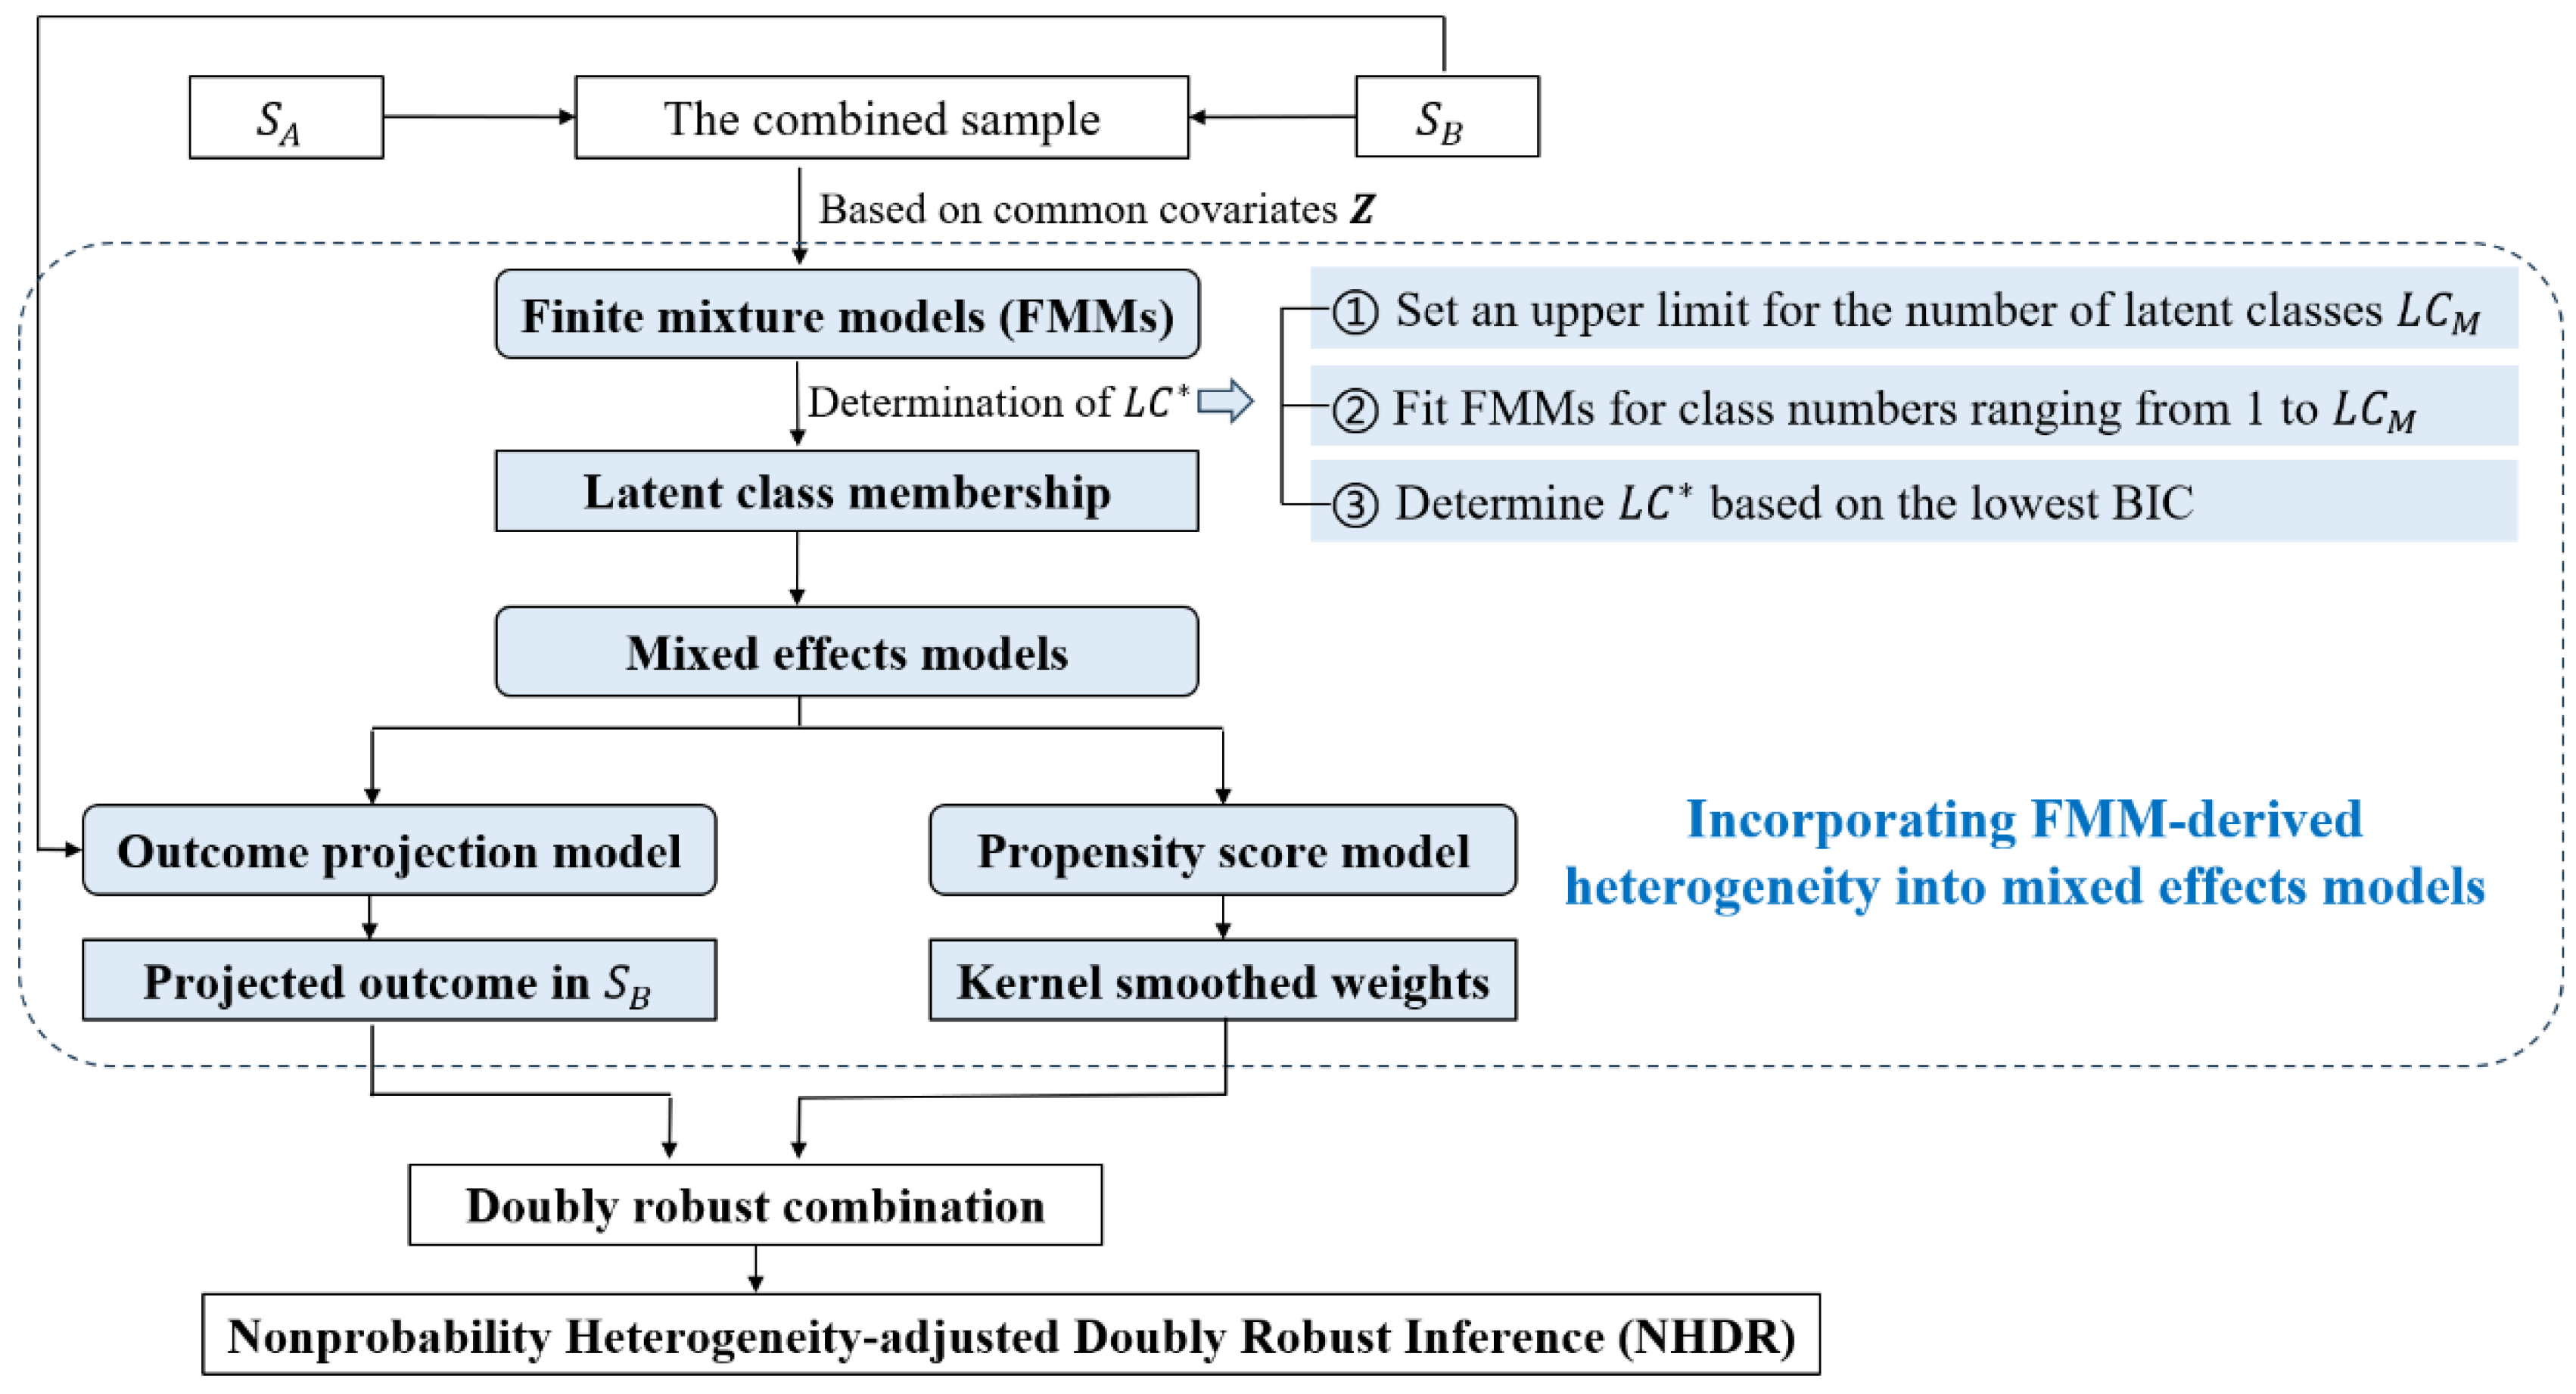
Figure 1. Flowchart of the NHDR framework.
Mathematics 14 00118 g001
Figure 2. Simulated relative bias of different methods under N L C = 2 when Dist = 1, ( n A , n B ) = (500, 2000), and ρ = 0.5 for continuous outcomes.
Mathematics 14 00118 g002
Figure 3. Simulated relative bias of different methods under N L C = 3 when Dist = 1, ( n A , n B ) = (500, 2000), and ρ = 0.5 for continuous outcomes.
Mathematics 14 00118 g003
Figure 4. Simulated relative bias of different methods under N L C = 4 when Dist = 1, ( n A , n B ) = (500, 2000), and ρ = 0.5 for continuous outcomes.
Mathematics 14 00118 g004
Figure 5. Simulated relative bias of different methods under N L C = 5 when Dist = 1, ( n A , n B ) = (500, 2000), and ρ = 0.5 for continuous outcomes.
Mathematics 14 00118 g005
Table 1. Summary of key notations in Section 2.
NotationDescription
U Finite population of size N
S A Nonprobability sample of size n A
S B Reference probability sample of size n B
d i Sampling weight for individual i in S B
Y i Target outcome for individual i in S A
Z i Vector of m covariates z 1 i , z 2 i , , z m i
R i Inclusion indicator for the nonprobability sample ( R i = 1 if i S A )
L C M Pre-specified upper limit for the number of latent classes
L C Optimal number of latent classes selected via FMMs
L C i Latent class membership ( L C [ 1 , L C ] )
d i Scaled sampling weights for individual i in S B
π ( Z i , L C i , d i ; α ) Logistic mixed effects model for the propensity score
m ( Y i | Z i , L C i ; β ) Generalized linear mixed effects for outcome projection
q i Linear predictors from π ( Z i , L C i , d i ; α )
K ( · ) Kernel function (standard normal)
h Bandwidth parameter for kernel smoothing
w i The kernel smoothed weights for individual i in S A
Table 2. Simulated coverage probabilities (%) of different methods under D i s t = 1 , n A , n B = ( 500 , 2000 ) , and ρ = 0.5 for continuous outcomes.
ICC N L C n Z n P NHDRDRIPWSPNaïve
NA10095.6695.27100.0095.270.23
0.321196.2093.83100.0093.870.60
22195.6993.67100.0093.730.67
23196.4387.0799.8386.801.33
24196.0677.6398.2777.632.37
25196.2170.7096.0370.572.37
32195.6193.07100.0093.070.63
33195.4789.8399.9389.970.93
34194.8679.1099.8079.331.07
35193.9671.1099.1371.601.20
43194.8990.1099.9390.200.60
43295.9691.1399.9791.400.47
44192.7960.4796.3360.631.10
44293.7558.8096.2359.001.03
45192.9656.9095.1357.131.03
45293.6451.2091.1751.731.20
54185.7563.5097.9764.370.77
54293.1852.0792.9052.300.93
55186.2162.1796.9762.900.67
55293.7545.8789.0046.371.00
0.521195.4994.83100.0094.971.07
22195.2294.40100.0094.430.97
23196.2588.0799.9388.032.13
24197.1679.4099.8779.603.37
25196.5373.8799.4374.003.23
32195.9193.27100.0093.471.20
33195.0791.67100.0091.771.10
34195.4182.57100.0082.801.53
35194.8777.7099.9777.902.33
43194.8691.77100.0092.101.33
43294.3590.70100.0090.771.10
44194.2468.4799.6768.371.03
44294.7865.0399.7365.632.03
45193.9662.3799.3362.471.70
45294.0055.9098.8056.071.50
54187.9270.1099.9070.701.33
54294.5357.9398.9758.271.57
55187.7467.6799.8368.271.20
55294.9352.2798.9052.671.67
0.821195.3594.03100.0094.073.47
22196.0995.40100.0095.373.60
23195.4193.20100.0093.105.37
24195.9788.40100.0088.235.57
25196.4883.60100.0083.675.53
32195.4494.73100.0094.703.93
33195.5494.57100.0094.603.10
34194.7890.23100.0090.374.33
35195.3785.67100.0085.773.90
43195.5593.90100.0093.973.40
43294.8293.73100.0093.733.90
44194.7680.47100.0080.434.30
44294.9079.77100.0079.874.13
45194.4178.77100.0078.634.17
45295.0769.27100.0069.434.40
54191.2882.20100.0082.303.20
54294.8173.67100.0073.973.97
55191.3479.33100.0079.503.97
55295.2569.20100.0069.433.77
Table 3. Simulated mean squared error (×103) of different methods under D i s t = 1 , n A , n B = ( 500 ,   2000 ) , and ρ = 0.5 for continuous outcomes.
ICC N L C n Z n P NHDRDRIPWSPNaïve
NA1002.092.002.122.0024.47
0.32112.232.472.632.4724.68
2212.262.542.682.5525.04
2312.224.444.504.4718.56
2412.347.557.527.5612.76
2512.339.739.769.7212.78
3212.372.843.092.8425.98
3312.493.563.883.5526.06
3412.626.206.066.1621.95
3512.748.268.028.2122.93
4312.843.994.363.9830.47
4322.573.644.013.6229.17
4413.7512.8313.8312.7025.47
4423.5313.6414.0613.5222.33
4513.6014.3115.2514.1425.17
4523.6717.0817.4316.8921.78
5417.0512.4612.9012.2529.14
5423.8817.4217.8117.2626.00
5517.0913.3213.8213.1129.55
5523.7820.4420.6920.2225.71
0.52112.712.682.912.6826.90
2212.672.893.082.9026.78
2312.704.754.834.7720.35
2412.647.927.887.9314.12
2512.7010.3610.4210.3514.23
3212.803.223.533.2327.41
3312.943.764.143.7428.26
3413.016.295.996.2623.99
3513.127.927.547.8824.35
4313.274.054.484.0331.46
4323.254.284.784.2531.87
4413.9512.4513.9312.3127.10
4423.8213.6014.2713.4724.43
4514.0714.4915.7814.3227.09
4523.9317.5918.2317.4124.36
5417.2312.1212.9311.9331.97
5424.1718.0018.6517.7928.56
5517.3813.2313.9813.0230.98
5524.1220.3320.7920.1027.06
0.82114.895.285.755.2733.71
2214.695.195.595.1934.62
2314.806.386.546.4028.73
2414.919.409.389.4323.54
2514.8612.5412.6312.5322.66
3215.175.325.795.3136.36
3315.035.556.165.5237.10
3415.307.757.507.7432.09
3515.319.999.309.9732.88
4315.636.357.076.3341.48
4325.756.837.726.8041.67
4416.4514.0316.7713.8737.86
4426.2515.4016.5815.2434.30
4516.2415.9018.7015.6937.61
4526.5021.1622.3520.9632.64
5419.4213.8615.3713.6743.20
5427.0319.4820.9919.2838.94
5519.6015.1216.7714.9041.73
5527.0122.8423.9622.6237.93
Table 4. Simulated confidence interval width of different methods under D i s t = 1 , n A , n B = ( 500 ,   2000 ) , and ρ = 0.5 for continuous outcomes.
ICC N L C n Z n P NHDRDRIPWSPNaïve
NA1000.590.551.060.560.03
0.32110.620.591.380.590.04
2210.620.601.350.600.04
2310.650.631.300.630.04
2410.700.681.220.680.04
2510.710.711.170.710.04
3210.640.611.370.610.04
3310.640.621.360.620.04
3410.660.641.330.650.04
3510.660.651.300.660.04
4310.660.651.390.650.04
4320.660.651.380.650.04
4410.700.711.320.710.04
4420.710.721.300.720.04
4510.710.721.300.720.04
4520.720.741.260.740.04
5410.820.731.380.730.04
5420.750.761.340.760.04
5510.810.731.370.730.04
5520.750.771.310.770.04
0.52110.680.641.760.640.04
2210.670.651.710.660.04
2310.700.681.670.680.04
2410.750.731.60.730.04
2510.750.761.560.760.04
3210.690.661.750.660.04
3310.690.671.730.670.04
3410.710.691.720.690.04
3510.730.701.690.710.04
4310.720.701.780.700.05
4320.710.701.760.700.05
4410.760.761.730.760.05
4420.760.781.720.770.05
4510.750.771.720.770.05
4520.770.791.690.790.05
5410.860.781.810.780.05
5420.810.811.780.810.05
5510.870.791.800.790.05
5520.810.831.760.830.05
0.82110.900.882.990.880.07
2210.890.912.910.910.07
2310.920.922.900.930.07
2410.950.972.850.970.07
2510.961.002.821.000.07
3210.910.903.020.900.07
3310.920.903.000.900.07
3410.940.913.010.920.07
3510.940.932.980.940.07
4310.960.953.090.950.07
4320.960.963.080.960.07
4410.981.003.101.000.07
4421.001.013.081.010.07
4510.981.013.091.000.07
4521.001.033.061.030.07
5411.081.023.221.020.08
5421.041.043.211.040.07
5511.091.033.211.020.08
5521.041.063.211.060.07
Table 5. Distributions of common variables in HMSS and GHSS-GZ-7 (%).
HMSSGHSS-GZ-7p
N = 1527N = 9299
Age (Mean ± SD)37.6 ± 9.1642.7 ± 11.0<0.001
Sex 0.0110
  Male44.8648.42
  Female55.1451.58
Employment status <0.001
  Employed81.7375.52
  Student2.161.74
  Retired4.989.18
  Unemployed or others11.1313.55
Marital status <0.001
  Married62.6779.29
  Unmarried30.9816.81
  Divorced or others6.353.90
Educational level <0.001
  Primary school or below0.5210.64
  Middle school4.3227.10
  High school or vocational high school12.1820.08
  college or above82.9742.19
District <0.001
  Central urban districts51.329.8
  Peripheral districts48.770.2
SD, standard deviation.
Table 6. Point estimate, 95%CI, and CIW of nine health indicators among adult residents of Guangzhou in October 2024.
NaïveDRIPWSPNHDR
Estimate95%CICIWEstimate95%CICIWEstimate95%CICIWEstimate95%CICIWEstimate95%CICIW
Electronic screen use11.72(11.49, 11.95)0.4609.62(9.10, 10.14)1.0419.60(8.70, 10.50)1.8039.58(9.04, 10.13)1.0918.85(7.83, 9.87)2.044
Poor/very poor self-rated health (%)7.53(6.26, 8.97)0.02710.75(7.47, 14.03)0.06610.59(6.28, 14.90)0.08610.84(7.20, 14.47)0.0738.04(3.29, 12.78)0.095
Weekly alcohol consumption over 14 units (%)6.35(5.18, 7.69)0.0256.27(4.12, 8.43)0.0436.02(3.55, 8.48)0.0496.84(4.61, 9.07)0.0456.20(4.34, 8.06)0.037
Exercise over 150 min per week (%)17.22(15.36, 19.21)0.03919.24(15.59, 22.90)0.07320.61(15.06, 26.16)0.11118.35(13.93, 22.76)0.08816.50(9.81, 23.2)0.134
Daily sleep duration less than 5 h (%)8.38(7.04, 9.89)0.0297.91(5.51, 10.32)0.0487.86(4.69, 11.03)0.0637.95(5.40, 10.50)0.0517.40(5.01, 9.80)0.048
Poor/very poor sleep quality (%)14.21(12.5, 16.06)0.03615.83(12.43, 19.23)0.06815.23(10.76, 19.69)0.08916.50(12.66, 20.34)0.07711.59(7.70, 15.48)0.078
Depression (%)37.39(34.96, 39.88)0.05034.77(30.44, 39.10)0.08735.40(29.31, 41.5)0.12235.78(31.13, 40.43)0.09342.50(25.93, 59.07)0.331
Anxiety (%)26.26(24.07, 28.54)0.04524.67(20.79, 28.55)0.07822.91(17.75, 28.06)0.10325.62(21.56, 29.68)0.08119.33(14.90, 23.76)0.089
High/very high stress (%)64.51(62.05, 66.91)0.04959.23(54.93, 63.54)0.08657.76(51.36, 64.15)0.12859.37(54.32, 64.42)0.10162.57(48.61, 76.52)0.279
Random seed of NHDR: 20251202.
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.