


Abstract
The growth of intelligent manufacturing systems has led to a wealth of computation-intensive tasks with complex dependencies. These tasks require an efficient offloading architecture that balances responsiveness and energy efficiency across distributed computing resources. Existing task offloading approaches have fundamental limitations when simultaneously optimizing multiple conflicting objectives while accommodating hierarchical computing architectures and heterogeneous resource capabilities. To address these challenges, this paper presents a cloud–fog hierarchical collaborative computing (CFHCC) framework that features fog cluster mechanisms. These methods enable coordinated, multi-node parallel processing while maintaining data sensitivity constraints. The optimization of task distribution across this three-tier architecture is formulated as a multi-objective problem, minimizing both system latency and energy consumption. To solve this problem, a fractal-based multi-objective optimization algorithm is proposed to efficiently explore Pareto-optimal task allocation strategies by employing recursive space partitioning aligned with the hierarchical computing structure. Simulation experiments across varying task scales demonstrate that the proposed method achieves a 20.28% latency reduction and 3.03% energy savings compared to typical and advanced methods for large-scale task scenarios, while also exhibiting superior solution consistency and convergence. A case study on a digital twin manufacturing system validated its practical effectiveness, with CFHCC outperforming traditional cloud–edge collaborative computing by 12.02% in latency and 11.55% in energy consumption, confirming its suitability for diverse intelligent manufacturing applications.
Keywords:
task offloading; fog computing; evolutionary algorithm; hierarchical computing; smart manufacturing MSC:
90B18
1. Introduction
Smart manufacturing integrates cyber–physical systems, IoT, and artificial intelligence to implement unprecedented levels of automation and intelligence in industrial production [1]. These manufacturing environments deploy computer-intensive applications such as quality inspection, predictive maintenance, and digital twin modeling, which generate massive data streams that require immediate processing [2,3]. However, resource-constrained local manufacturing equipment cannot meet these exponentially growing computational demands while maintaining stringent latency requirements [4], necessitating distributed computing architectures that effectively leverage external resources while preserving time-sensitive industrial operations.
Edge computing addresses latency challenges by bringing computational resources closer to data sources, enabling anomaly detection [5], process control [6], and robot coordination [7]. These deployments commonly employ containerized microservices (e.g., Docker and Kubernetes) for flexible task execution and message queuing protocols (e.g., MQTT and OPC UA) for data exchange between shopfloor devices and edge gateways. However, resource-constrained edge infrastructure encounters performance bottlenecks when multiple production lines simultaneously offload interdependent tasks. This leads to prolonged queuing delays and elevated energy consumption due to redundant data transmissions and imbalanced workload distribution across computing layers [8]. The traditional edge–cloud architecture faces two critical challenges: escalating latency bottlenecks caused by insufficient processing capacity at edge nodes during peak production periods, and significant energy inefficiency due to suboptimal resource allocation across isolated computing tiers [9,10]. These architectural limitations become critical as interconnected production systems generate complex computational workloads, which demand sophisticated coordination and scalable processing capabilities exceeding the capacity of isolated edge nodes.
To address computational coordination challenges in smart manufacturing, Li et al. [11] proposed an edge–cloud collaborative framework enabling cloud-trained models to be deployed at the edge for real-time scheduling decisions. By contrast, Nie et al. [12] extended this approach from single-edge to multi-edge scenarios. Hong et al. [13] further introduced fog computing as an intermediate layer, constructing a cloud–fog–edge hierarchical architecture for distributed synchronized manufacturing. However, these architectures employ relatively rigid task allocation strategies where simple tasks are assigned to edge nodes while complex tasks are offloaded to the cloud. This method lacks the flexibility to dynamically coordinate resources across multiple computing tiers based on real-time production demands. For distributed edge collaboration modeling, Li et al. [14] designed a two-phase greedy algorithm for edge-layer resource scheduling with latency constraints, and Cai et al. [15] proposed a deep reinforcement learning-based approach for multitask hybrid offloading. Current mathematical models primarily focus on distributed edge collaboration, with limited consideration given to comprehensive multi-tier coordination mechanisms. This combination of inflexible architectures and incomplete modeling frameworks leads to imbalanced latency–energy trade-offs in practical deployments. Existing studies predominantly optimize latency while overlooking computational energy consumption [16,17], which increasingly contributes to the overall energy footprint of smart factories. These research gaps necessitate a more adaptive hierarchical framework with comprehensive multi-objective optimization capabilities.
To address these challenges, this study develops a hierarchical cloud–fog collaborative optimization framework that simultaneously minimizes the latency of task completion and energy consumption for dependent task offloading in smart manufacturing. Our research focuses on three key objectives. First, we design a multi-tier fog computing architecture that coordinates resource allocation across hierarchical computing layers. Second, we model task dependencies to ensure workflow integrity during cross-tier offloading. Third, we develop multi-objective optimization algorithms that efficiently explore the latency–energy trade-off space by leveraging a hierarchical structure. The framework is evaluated using two key performance metrics: (1) the latency of task completion, which indicates the complete task time end-to-end from submission to completion across all computing tiers, and (2) energy consumption, which quantifies the total energy consumed by all participating computing nodes during task execution.
The remainder of this paper is organized as follows: Section 2 reviews related works; Section 3 presents the cloud–fog architecture; Section 4 formulates the mathematical model for task offloading; Section 5 describes the offloading algorithm; Section 6 presents experimental evaluations; and Section 7 concludes the paper and discusses future directions.
2. Related Work
This section reviews three key areas of existing research: task offloading architectures, data dependency and sensitivity modeling, and multi-objective optimization algorithms for distributed computing. We analyze representative studies, compare their methodologies, and identify unresolved technical challenges, as summarized in Table 1.
Table 1.
Comparison of representative task offloading studies in distributed computing environments.
At the architectural level, studies have predominantly focused on device–edge or edge–cloud frameworks [14,18], while multi-tier architectures with intermediate coordination layers remain underexplored in how they handle complex manufacturing workflows that span multiple production stages. From a modeling perspective, research has mainly concentrated on independent task formulations [19], whereas the integration of data dependencies and sensitivity constraints inherent in manufacturing processes represents an evolving area. In practical manufacturing scenarios, proprietary process parameters and real-time sensor data contain critical intellectual property and competitive advantages, making data sensitivity a paramount concern that requires strict control over data placement and movement across computing tiers [30]. Regarding optimization methodologies, there has been limited investigation into how optimization algorithms can effectively exploit the structural properties of multi-tier architectures, particularly when computing tiers expand or task characteristics become more complex. These observations indicate opportunities in integrated frameworks that combine multi-tier coordination, dependency-aware task modeling with sensitivity considerations, and optimization algorithms tailored to hierarchical computing systems.
Fog computing extends the edge computing paradigm by introducing an intermediate layer of distributed computational resources between edge devices and cloud servers [31]. Recent research has demonstrated the effectiveness of cloud–fog collaboration in addressing latency and resource constraints for IIoT applications. Studies have investigated intelligent decision-making mechanisms to dynamically determine offloading destinations between the fog and cloud based on task characteristics [32]; cost-performance trade-offs through DAG-based scheduling strategies that balance application execution time and resource expenses [33]; and hierarchical resource coordination using SDN-based architectures to handle saturated fog domains [34]. Researchers have formulated mathematical optimization models to minimize transmission delays through joint fog-to-fog and fog-to-cloud offloading [35] and employed evolutionary algorithms to select optimal computing devices for real-time tasks [36]. However, these efforts predominantly address either single-objective optimization focusing on isolated performance metrics or employ simple two-tier architectures that lack intermediate coordination mechanisms. The challenge lies in developing integrated frameworks that combine multi-tier hierarchical coordination with dependency-aware task modeling and multi-objective optimization strategies tailored to manufacturing constraints [37].
Task completion latency and energy consumption constitute critical performance metrics in smart manufacturing, necessitating simultaneous optimization of both objectives [20,27]. Multi-objective evolutionary algorithms have been applied to address this challenge across various distributed computing scenarios, including NSGA-II-based approaches for latency–energy trade-offs in edge computing [38], decomposition-based methods for resource allocation in cloud–edge environments [39], and particle swarm optimization variants for energy-efficient task scheduling [40]. However, these algorithms typically treat the solution space uniformly without exploiting the structural properties of hierarchical computing architectures. Fractal structures, characterized by self-similarity and recursive organization patterns, exhibit natural alignment with multi-tier computing hierarchies where computational tasks at different scales mirror the nested device-edge–fog–cloud structure [41]. This structural correspondence suggests that fractal-based approaches could enhance optimization efficiency by decomposing the solution space according to the inherent hierarchy of the computing architecture. However, their application to task offloading in manufacturing environments remains unexplored.
The main contributions of this paper are as follows:
(1) A cloud–fog hierarchical collaborative computing framework is proposed that organizes fog nodes into master–slave clusters to enhance horizontal scalability and resource coordination across the device, fog, and cloud layers.
(2) A comprehensive mathematical model is formulated that integrates directed acyclic graphs to represent task dependencies, incorporates dynamic factors such as real-time node load and queue depth, and enforces data-sensitivity constraints to ensure local processing of critical manufacturing data. The model features a dual objective of minimizing both end-to-end latency and overall energy consumption.
(3) The Fractal Space-Aware NSGA-II algorithm is developed by integrating fractal geometry principles with evolutionary computation. This algorithm employs fractal Brownian motion for diverse population initialization and recursive space partitioning for multi-scale searches. These methods utilize fractal self-similarity to efficiently navigate the hierarchical offloading decision space.
3. Cloud–Fog Hierarchical Collaborative Computing Architecture (CFHCC) in Manufacturing
To address the challenges of latency and energy efficiency in large-scale intelligent manufacturing, the computational resources are categorized into cloud servers, fog nodes, and fog clusters. A cloud–fog hierarchical collaborative computing framework (CFHCC) is designed for smart manufacturing environments. Table 2 summarizes all symbols involved in the architecture design and modeling section.
Table 2.
Symbol.
3.1. Hierarchical Architecture of CFHCC
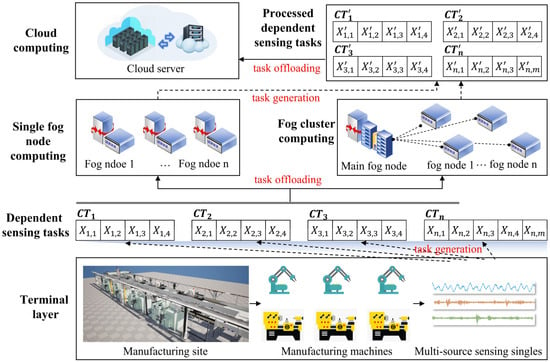
The CFHCC is designed as a four-layer structure, which builds upon the established paradigm of edge–cloud computing architectures [2], while introducing novel coordination mechanisms tailored to manufacturing environments. Each layer is responsible for specific functions and is interconnected via dedicated communication protocols, enabling efficient and adaptive task offloading and resource coordination. The four hierarchical layers of CFHCC, as shown in Figure 1, are described below:
Figure 1.
Cloud–fog hierarchical collaborative computing architecture.
(1) Execution Terminal Layer (ETL):
This layer comprises the front-line manufacturing equipment, such as CNC machines, industrial robots, and automated guided vehicles (AGVs), each embedded with its own controllers and sensors. The ETL is responsible for real-time operational data acquisition, preliminary signal processing, and the direct execution of control commands [42]. By preprocessing data and filtering irrelevant information at the source, ETL reduces the volume of data transmitted to upper layers and minimizes communication latency.
(2) Fog Node Computing Layer (FNCL):
The FNCL consists of distributed fog nodes deployed near the shop floor, such as industrial gateways, embedded edge servers, and smart routers [43]. Each fog node independently processes time-sensitive and location-dependent tasks. The FNCL supports task offloading from the ETL, local decision-making, protocol translation, and acts as a bridge between terminal devices and higher-level computing resources.
(3) Fog Cluster Computing Layer (FCCL):
This layer aggregates multiple fog nodes into dynamically formed clusters, which are managed via MQTT protocols. The FCCL enables parallel and distributed processing of computationally intensive or collaborative manufacturing tasks that exceed the capabilities of a single-fog node. Tasks can be partitioned and scheduled across cluster members based on workload balancing, resource availability, and network topology. The FCCL provides a middle ground between localized fog computation and remote cloud services.
(4) Cloud Computing Layer (CCL):
The CCL is composed of remote high-performance servers and data centers. It provides centralized resources for large-scale optimization, global data analytics, historical data storage, and long-term planning. The cloud layer is responsible for handling tasks that require substantial computing power or global coordination, such as cross-workshop scheduling and the training of complex artificial intelligence models.
To ensure robust collaboration among these layers, CFHCC integrates multiple communication technologies: a wired Ethernet for high-speed local connections, industrial wireless networks (e.g., Wi-Fi 6 or 5G) for flexible device access, and LAN/VPN tunnels for secure inter-layer data exchange. This multi-layered architecture enables fine-grained, context-aware task allocation and dynamic resource management, effectively matching the computational requirements of diverse manufacturing scenarios with the most suitable computational resources.
3.2. Fog Computing Deployment Framework
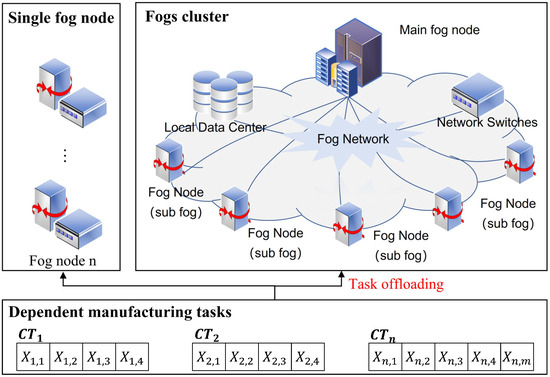
Building upon the hierarchical structure of CFHCC, the fog computing deployment framework is designed to extend beyond traditional edge computing models by enabling collaborative processing among multiple fog nodes. The proposed framework organizes fog nodes into a coordinated network that supports the distribution of task execution and resource sharing. As illustrated in Figure 2, the FCCL comprises a fog management node, a local data center, a network switch, and several distributed fog nodes. Both the fog management node and subordinate fog nodes are equipped with computational and storage resources, as well as the ability to handle dynamic task loads. The fog management node, often known as the main fog, is responsible for global coordination within the fog layer [34]. It orchestrates resource allocation, manages task scheduling, and monitors the operational status of subordinate fog nodes (sub-fogs). This hierarchical control mechanism ensures efficient load balancing and fault tolerance within the fog cluster. High-bandwidth communication links connect terminal devices to the fog nodes, establishing a robust, low-latency network between the CFHCC and ETL. This network enables rapid data exchange and close coordination between edge devices and fog nodes. The deployment of such an interconnected fog network enables the real-time decomposition and parallel processing of computational tasks, allowing distributed edge resources to be efficiently utilized within intelligent manufacturing workshops.
Figure 2.
Deployment of the FCCL.
4. Mathematical Model for Computational Task Offloading in CFHCC
4.1. Mathematical Problem Statement
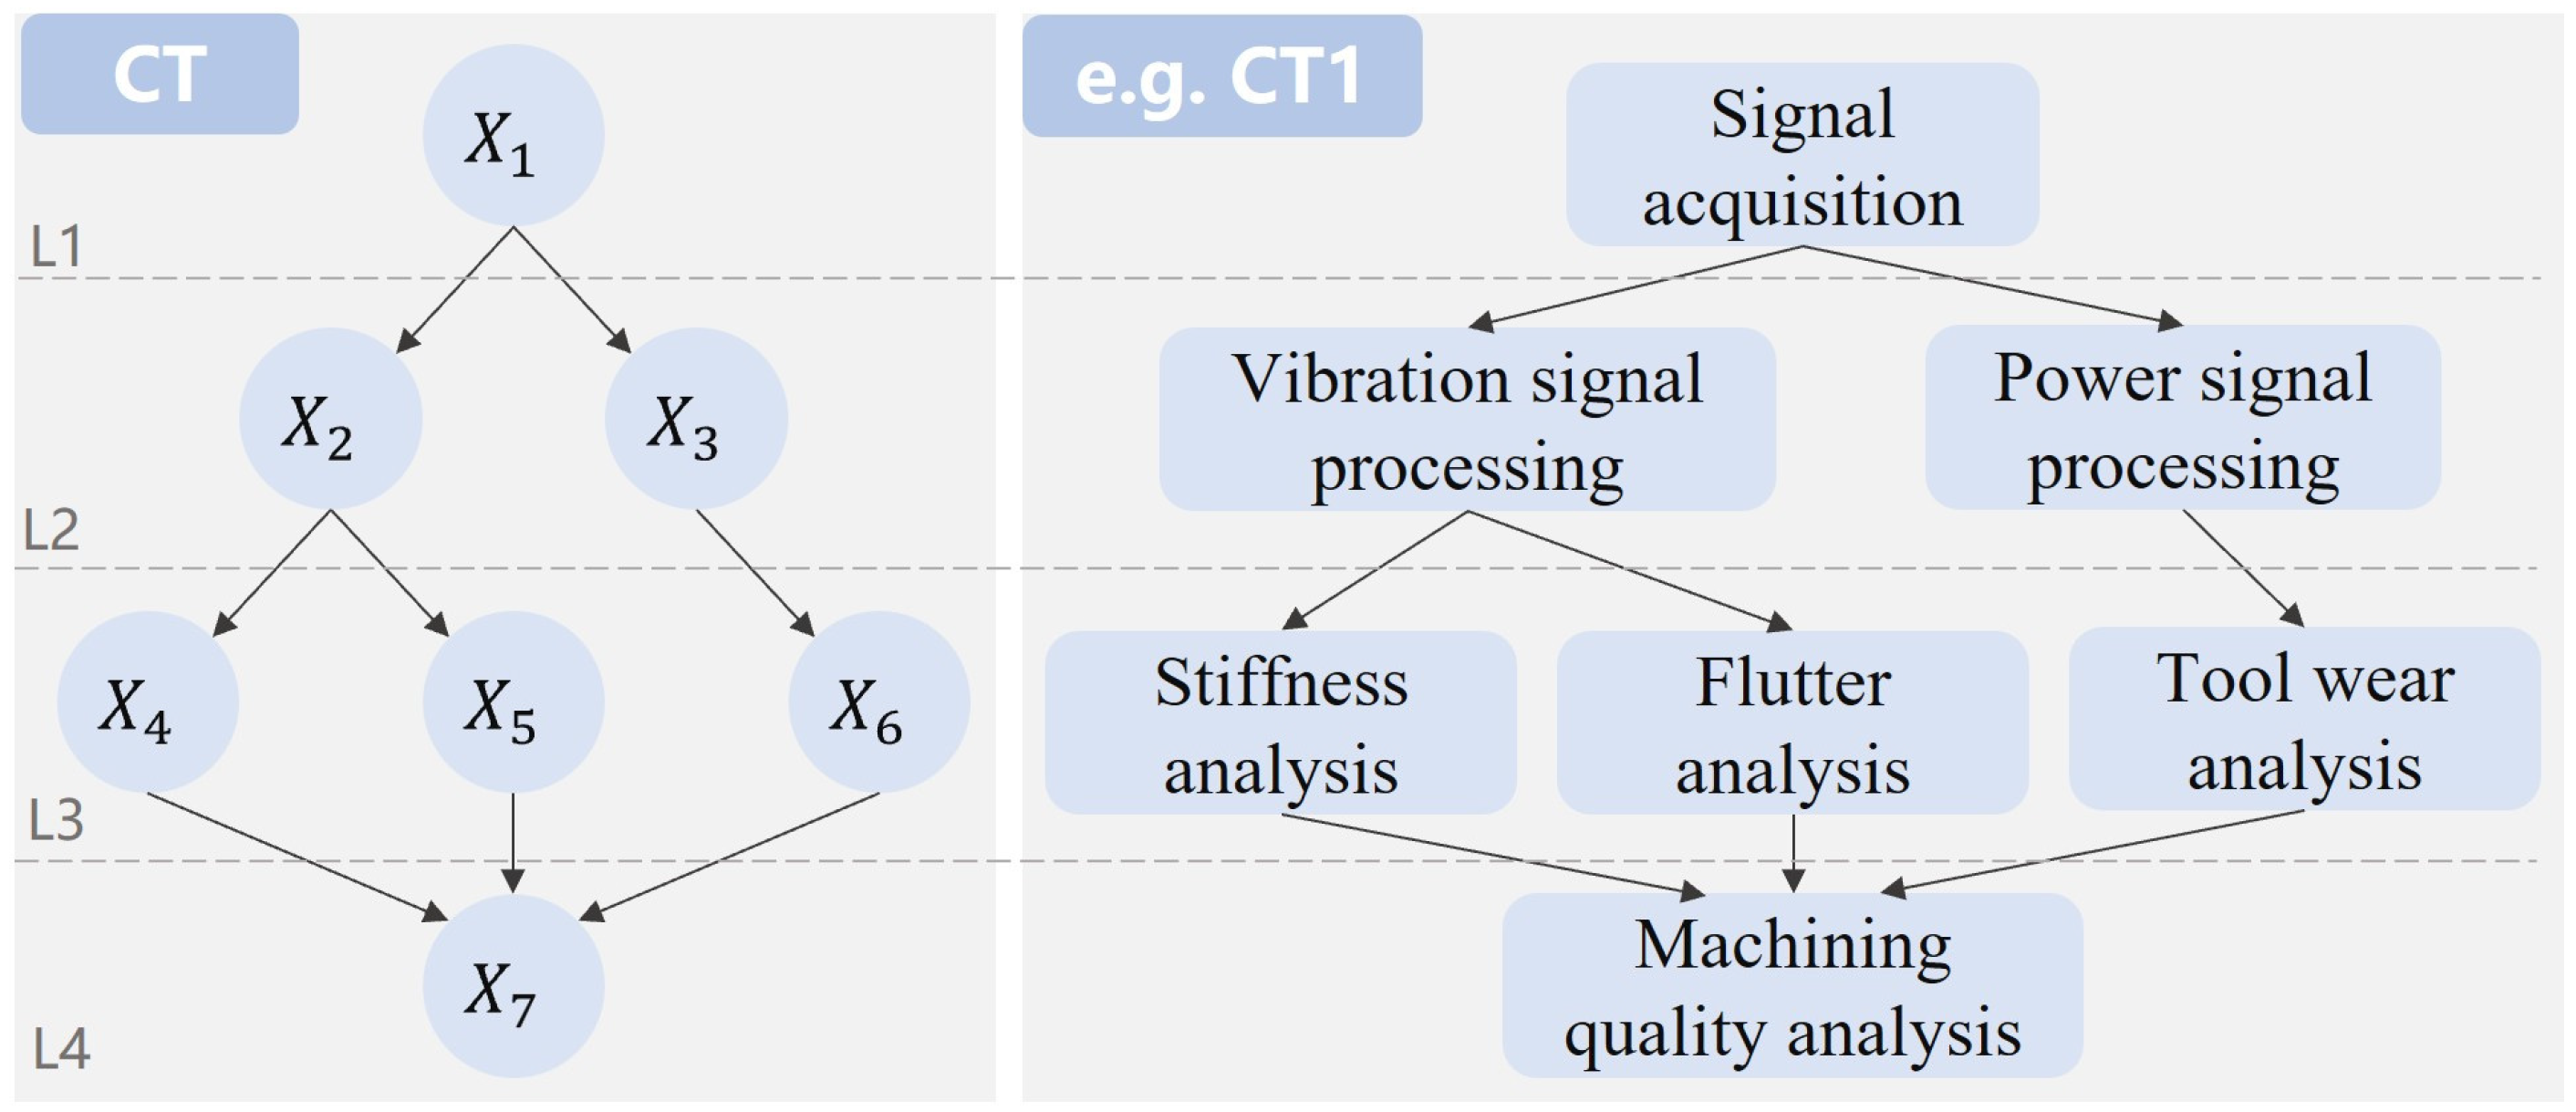
The computational tasks of smart manufacturing are no longer presented in a simple single-threaded execution mode but exhibit characteristics of polynomiality, concurrency, and composition. Figure 3 illustrates a representative computational task from industrial condition monitoring and quality control applications [44]. As shown in the CT, the task contains seven sub-tasks, and the tasks and are executed only after task is completed. Therefore, the execution level of task belongs to the highest level, which is denoted as . The , and belong to the third execution level, and they are not executed until and are completed; similarly, is executed after all the above tasks are completed.
Figure 3.
DAG of computational tasks.
Within the CFHCC, the CCL is responsible for decomposing complex computational tasks into multiple sub-tasks with specific execution dependencies. These sub-tasks are assigned to appropriate computing devices across different layers based on both task characteristics and the current status of available computational resources. Upon completion, all intermediate results are returned to the CCL for final aggregation and the global delivery of results.
Given the multi-layer resource structure in CFHCC, task offloading and resource allocation can be categorized into three primary execution modes:
(1) Cloud Execution: The sub-task is executed on the CCL, leveraging centralized high-performance computing resources.
(2) Fog Node Execution: The sub-task is executed independently on a single-fog node within the FNCL, utilizing its local processing capabilities.
(3) Fog Cluster Execution: The sub-task is collaboratively executed by a dynamically formed set of fog nodes in the FCCL, enabling parallel or distributed processing to meet higher computational or reliability requirements.
For efficient task offloading and optimal resource allocation across these modes, the following four technical factors must be considered:
(1) The processing power and available resources of each computing device (cloud server, fog node, or fog cluster) at the time of task assignment.
(2) The data sensitivity constraints of the computational tasks, denoted as , which reflect whether the sub-task contains sensitive sensor or process data.
(3) The expected execution time for sub-tasks operating at the same hierarchical level, including queuing and processing delays.
(4) The time required for data transfer between layers (e.g., ETL to FNCL, FNCL to FCCL, FCCL to CCL), which is affected by network bandwidth, topology, and data volume.
4.2. Task Offloading Model-Based Cloud Server
If is executed in the cloud, the impact of on the time and energy costs incurred during task execution is significant. Therefore, task execution in the cloud needs to be discussed in categories. If the value of is 0, this means the execution process does not need to obtain terminal equipment data under real-time conditions. Consequently, the execution time of only comprises queue time and execution time. Conversely, the execution time adds to the time spent communicating with the industrial site. The above can be expressed as follows:
where represents the time it takes for the cloud server to communicate with terminal equipment; is the time it takes for the cloud server to process . represents the execution of which requires the industrial site to provide a bits digital stream and the average network bandwidth for the industrial site. is the instruction processed by the execution of . is the data processing speed of the cloud server.
is the time it takes for to wait for the predecessor tasks, , to finish, i.e., the time it takes for the latest task in the previous execution level to finish, which is calculated as follows:
The time and cost of CCL are determined as follows:
The energy cost of to be executed by CCL as follows:
The execution energy cost of is only generated in the processing task when industrial site information does not need to be obtained under real-time conditions. Conversely, the energy cost of consists of the processing energy cost and the communication energy cost of the industrial site.
4.3. Task Offloading Model Based on a Single-Fog Node
Tasks that are not very computationally intensive and need to be “tightly linked” to the industrial site can be assigned to a single-fog node for execution. Since the edge-side devices are connected to each other via fiber or Ethernet, their communication time is negligible. Therefore, the execution time can be expressed as follows:
where , , and denote the sending time, queuing time, processing time and receiving time of , respectively. In addition, if the source and result data sizes of are supposed to be and , and the transmission rate from CCL to FCL is , and can be expressed as follows:
Assuming that the processing execution speed of the fog server is , can be expressed as follows:
Then, the execution time for via FNCL is the following:
The energy cost of FNCL consists of three components: the energy cost of task source data transmission, processing, and the transmission of task results.
4.4. Task-Offloading Model Based on a Fog Cluster
Once the FCCL is selected for task execution, the workflow follows a five-phase collaborative process among the cloud, main fog node, and sub-fog nodes. First, the CCL offloads task to a designated main fog node. Second, the main fog node divides into sub-tasks for parallel processing. Third, these sub-tasks are distributed to available fog nodes within the cluster. Fourth, after parallel execution, all intermediate results are collected back to the main fog node. Finally, the main fog node merges these results and returns the final output to the CCL.
Assuming that is divided into sub-tasks, the set of sub-tasks can be expressed as . We can assume that is the set of co-processing , where is the main fog node mentioned above and is responsible for the distribution of . The data transmission time of is as follows:
where is the average data transmission speed between fog nodes. The processing time of is as follows:
Recall that the main fog node is responsible for dividing sub-tasks and merging the results. Therefore, the running time of is the following:
where and are the allocation time and the time it takes for results to merge for on . Therefore, the execution time for via FCCL is as follows:
Specially, ; therefore, the is as follows:
The energy cost of to be determined via FCCL and consists of four components: the energy cost of transmission from CCL to the main fog node, data transfer between fog clusters, processing, and the uploading of results.
4.5. Multi-Objective Combinations of Optimization Problems
In this section, the CFCCA is formulated as a multi-objective stochastic optimization problem, aiming to balance the trade-off between task execution time and energy consumption.
Objective 1:
Objective 2:
where denotes the last task for the computational application. Predictably, balancing execution time and energy consumption requires a minimal completion time for the final task while considering the cumulative energy cost across all sub-tasks. The optimization problem must satisfy the following constraints to ensure feasible and practical task offloading decisions:
(1) Each computational task must be assigned to exactly one execution mode (the cloud, single-fog node, or fog cluster) to avoid conflicts and ensure deterministic execution:
(2) To meet real-time requirements and guarantee quality of service (QoS) in smart manufacturing, each task’s execution time must not exceed its deadline:
(3) When tasks are offloaded to the fog cluster for parallel processing, the division granularity should be limited by the available fog node resources:
(4) Tasks with high data sensitivity must be processed locally to comply with privacy and security requirements in industrial environments:
5. Algorithm Design for Offloading Decisions
To address the challenges of latency minimization and energy efficiency in large-scale intelligent manufacturing task offloading, an advanced optimization algorithm tailored for the CFHCC is proposed. Building upon the principle of multi-objective evolutionary optimization, the Fractal Space-Aware Non-dominated Sorting Genetic Algorithm II (FS-NSGA-II) is developed, which fully leverages hierarchical fractal space partitioning to enhance the global search and local exploitation capabilities for offloading decision optimization. The framework consists of two key modules: initialization based on fractal Brownian motion and NSGA-II modification based on fractal space partitioning. The mathematical models and implementation procedures for each module are detailed below.
5.1. Population Initialization Based on Fractal Brownian Motion
In the classical NSGA-II, the initial population of size is generated through uniform random sampling:
where represents the offloading decision for task in the k-th individual, and and are the lower and upper bounds of node indices. However, this random initialization ignores task temporal constraints and fails to provide multi-scale diversity.
In FS-NSGA-II, for a given task set , each task can be offloaded to a set of available nodes , where denotes the cloud nodes, denotes the individual fog nodes, and denotes the fog cluster nodes. The latest completion time for each task is calculated as follows:
where denotes the response deadline of the overall task; is the set of successive tasks; and is the execution delay of task on node . Accordingly, the latest allowable start time for each task is defined as follows:
A smaller indicates stronger temporal constraints on the scheduling of task . During initialization, tasks are sorted and distributed according to . To enhance initialization diversity, fractal Brownian motion (FBM) is introduced:
where is the Hurst exponent; is the standard Brownian motion; and denotes the Gamma function. is normalized to the interval and mapped to the offloading decision space. Thus, the initial solution of the -th individual is presented by the following:
where is the individual offset of perturbation, and and are the lower and upper bounds of node indices, respectively.
By prioritizing the allocation of time-sensitive tasks and then applying fractal Brownian motion, initialization ensures that the population both adheres to temporal requirements and achieves broad, multi-scale coverage of the solution space.
5.2. NSGA-II Improvement Based on Fractal Space Partitioning
The classical NSGA-II employs a well-established multi-objective optimization framework consisting of (1) non-dominated sorting to classify individuals into Pareto fronts based on dominance relationships, where an individual dominates if for all objectives and strict inequality holds for at least one objective; (2) a crowding distance calculation to maintain solution diversity within the same front; (3) tournament selection based on Pareto rank and crowding distance; (4) simulated binary crossover (SBX) and polynomial mutation; and (5) an elitism strategy that merges parent and offspring populations and retains the best individuals.
However, the uniform crossover and mutation operators in the classical NSGA-II ignore the hierarchical and heterogeneous structure inherent in CFHCC environments. The CFHCC exhibits a multi-layered resource architecture where computational nodes are organized as cloud servers, fog nodes, and fog clusters. When mapping diverse tasks to these resources, the resulting solution space displays recursive clustering and local self-similarity, as groups of high-quality solutions often emerge around certain resource combinations and reappear at different levels of granularity. This phenomenon closely corresponds to fractal theory, which describes complex systems characterized by self-similar patterns across various scales.
Based on this structural alignment, the FS-NSGA-II enhances the classical NSGA-II framework according to three main aspects while preserving its core mechanisms (non-dominated sorting, crowding distance, and elitism): (1) dynamic fractal partitioning of the solution space to mirror the hierarchical and clustered nature of CFHCC resources; (2) multi-scale genetic operators that leverage the nested structure of promising regions; and (3) adaptive, self-similar search mechanisms that facilitate both broad exploration and focused exploitation.
5.2.1. Fractal Space Partitioning
Based on the physical resource heterogeneity of CFHCC, the set solution space is divided as follows:
Each subspace, , is further recursively divided into several self-similar subspaces based on the actual task allocation and resource characteristics after every 10 iterations:
where is the fractal partition operator and is the number of subspaces at level .
5.2.2. Fractal Multi-Scale Crossover Operator
The fractal multi-scale crossover operator replaces the SBX operator in the classical NSGA-II and adaptively adjusts the crossover probability at different fractal levels to realize alternating coarse and fine searches. For the i-th gene of two parents and with fractal levels and respectively, the crossover operator is defined as follows:
where is the crossover probability at the fractal levels and . At lower levels (coarse scales), is larger to promote global recombination; at higher levels (fine scales), is smaller to reinforce local inheritance.
5.2.3. Fractal Adaptive Mutation Operator
The fractal adaptive mutation operator replaces the polynomial mutation in the classical NSGA-II to enabling the performance of multi-scale perturbations. For the i-th gene of individual at fractal level , the mutation operator is as follows:
where , is the adaptive step size for fractal level ; is the fractal index for this level; and are the probabilities for intra-/inter-level perturbations; and controls the proportion of Gaussian fractal micro-perturbations.
This mechanism ensures that a (1) large-scale jump search is conducted at coarse levels to escape local optima, and (2) fine-tuning at refined levels is performed to improve the balance and convergence of the solution set.
5.3. Flow and Pseudocode of FS-NSGA-II
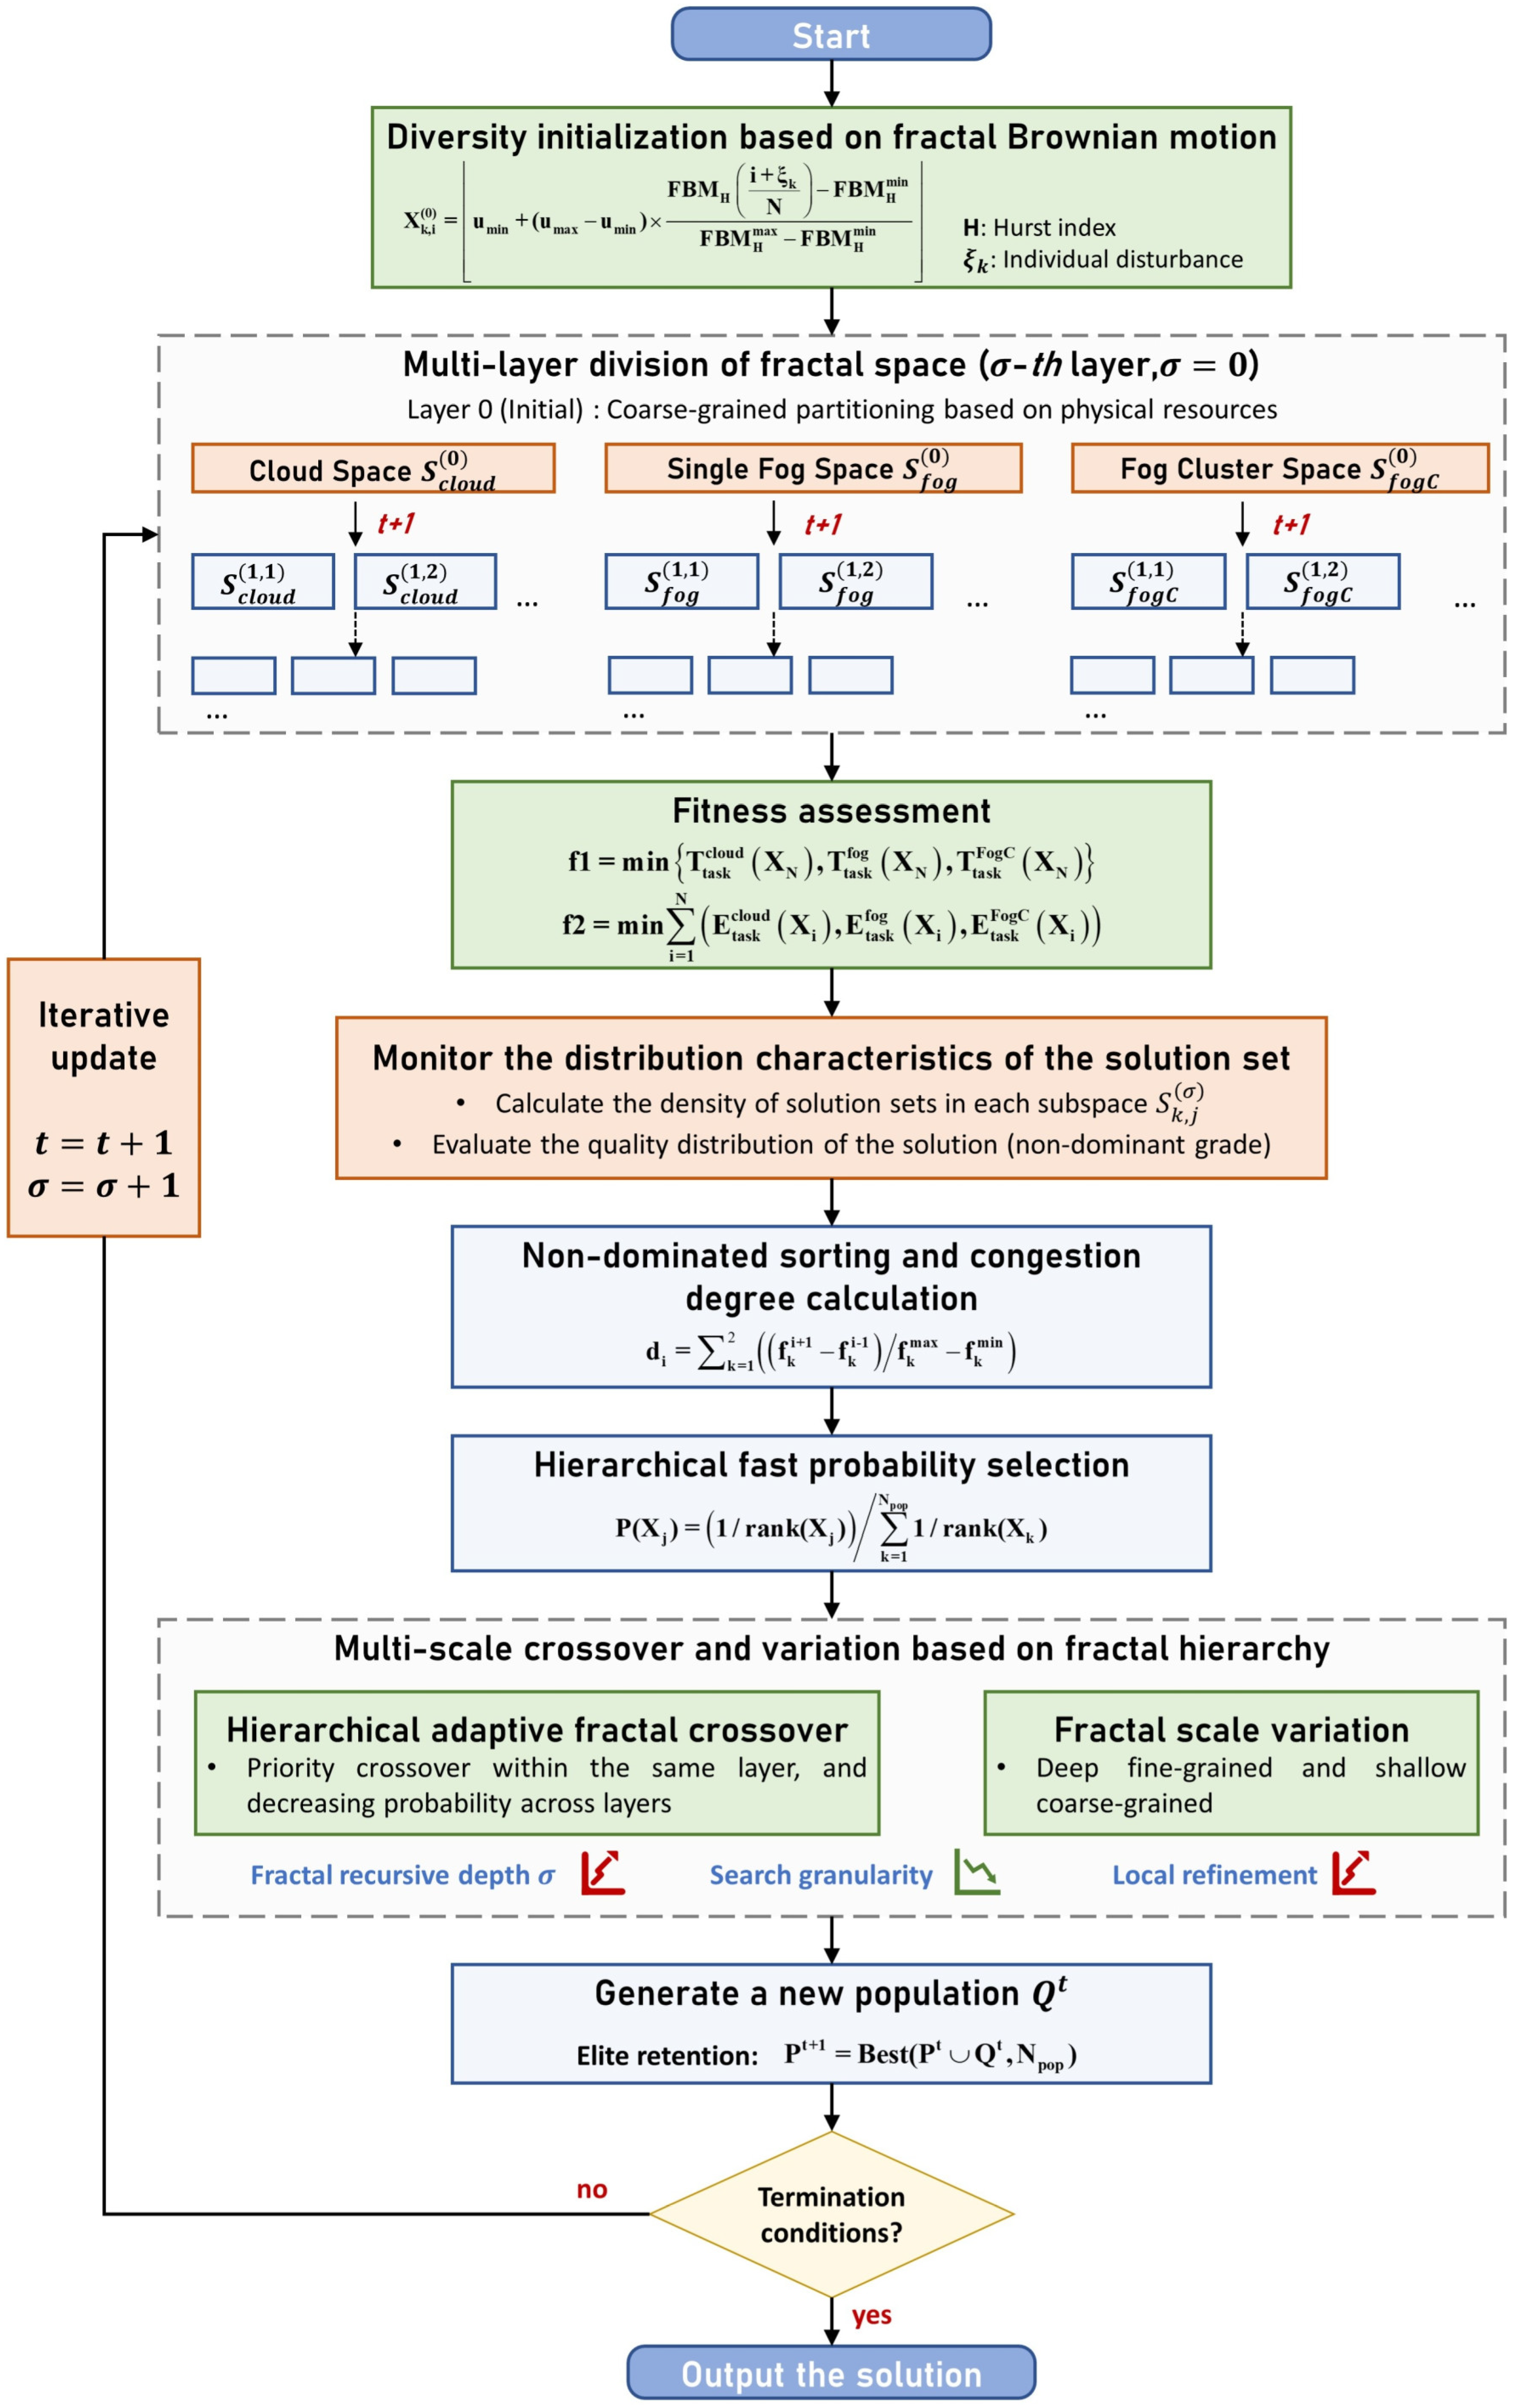
Figure 4 illustrates the proposed FS-NSGA-II framework. The algorithm begins with population initialization based on fractal Brownian motion, ensuring diverse and multi-scale coverage of the solution space. The solution space is then recursively partitioned according to fractal principles, and the search granularity is dynamically adapted based on the distribution of solutions. Evolutionary operators such as crossover and mutation are controlled by the hierarchical structure of the partitions, balancing local refinement and global exploration. This self-adaptive, multi-scale strategy improves both convergence and diversity for large-scale heterogeneous task offloading. The detailed algorithmic steps are presented in Algorithm 1.
| Algorithm 1: FS-NSGA-II | ||
| Input: Maximum iterations , population size , fractal parameter , fractal partition threshold , evolutionary parameters . | ||
| Output: Pareto optimal solution set . | ||
| // Population Initialization using FBM | ||
| for to do | ||
| for to do | ||
| Calculate according to Equation (27); | ||
| Generate normalized according to Equation (28); | ||
| Set according to Equation (29); | ||
| Set ; | ||
| // Main Evolutionary Loop | ||
| for to do | ||
| // Fractal Space Partitioning (every 10 iterations) | ||
| if mod then | ||
| Recursively apply Equations (30) and (31) to obtain fractal subspaces at each level; | ||
| // Fitness Evaluation | ||
| Compute fitness value for all individuals in ; | ||
| // Non-dominated Sorting and Crowding Distance | ||
| Assign individuals to Pareto fronts ; | ||
| Compute crowding distance for each individual; | ||
| // Selection | ||
| Select parents using tournament selection based on Pareto rank and crowding distance; | ||
| // Crossover and Mutation | ||
| for each parent pair do | ||
| Determine fractal levels , ; | ||
| Apply fractal crossover according to Equation (32) to generate offspring; | ||
| Apply fractal mutation according to Equation (33) to mutate offspring; | ||
| // Offspring Evaluation | ||
| Compute fitness value for all individuals in ; | ||
| // Elitism | ||
| Merge , perform non-dominated sorting; | ||
| Select top individuals based on Pareto rank and crowding distance to form | ||
| // Termination Check | ||
| if termination condition is met then | ||
| Set as the current Pareto front ; | ||
| return ; | ||
Figure 4.
The algorithm flow of FS-NSGA-II.
To demonstrate the optimization process, we present a representative calculation for a sample task with five sub-tasks of various data sizes ([1.2, 0.8, 1.5, 1.0, 0.9] MB) and instruction counts ([500, 800, 1200, 600, 400] M). Table 3 shows the evolution of a selected population individual across three generations, illustrating how FS-NSGA-II progressively refines offloading decisions. In the initial generation (Gen 1), a randomly generated solution (where 1 denotes a single-fog node and 2 denotes a fog cluster) yields a completion time of 696 ms and energy consumption of 65.94 J. Through fractal-based crossover and Gaussian mutation, the algorithm explores alternative configurations. By generation 50, an improved solution reduces latency to 673 ms while maintaining energy at 67.21 J. After 200 generations, the algorithm converges to a Pareto-optimal solution achieving 658 ms and 63.85 J, demonstrating simultaneous improvements in both objectives through intelligent search space exploration. The calculation details for objective evaluation—including transmission time, computation time, and energy consumption—follow the mathematical formulations defined in Section 4.
Table 3.
Evolution of a representative solution during the optimization process.
6. Experiments and Analysis
To comprehensively evaluate the effectiveness and applicability of the proposed approach, two types of experiments were conducted: simulation experiments and a practical case study. The simulation experiments were designed to benchmark the algorithm’s performance under various scenarios, and the case study was based on a digital twin-enabled smart manufacturing workshop, aiming to demonstrate the method’s practical value in real-world applications.
6.1. Simulation Experiment
The simulation experiments were carried out in a Python-based environment to assess the optimization performance of the proposed method under different configurations. The experiments were executed on a workstation equipped with an Intel Core i7-12700 CPU and 16 GB of RAM, running Windows 11 and Python 3.10. All algorithms and simulation models were implemented using standard Python libraries and customized modules. The customized modules included a task generator module that allowed users to configure task arrival patterns, dependency structures, and computational characteristics; a resource simulator module that modeled the computing capabilities and network conditions of cloud, fog nodes, and fog clusters; and an offloading decision executor module that implemented the proposed FS-NSGA-II algorithm and baseline methods. Users could modify module parameters through configuration files (in JSON format) to adapt the simulation to different manufacturing scenarios without altering the core code.
The simulation scene parameters were derived from the practical configurations of intelligent manufacturing environments, ensuring that the experimental setup closely reflected real-world industrial applications. In particular, the performance specifications of the computing nodes were aligned with those of commercially available products, providing a realistic basis for evaluating system behavior. The detailed parameter configuration for the cloud–fog hybrid computing scenario is summarized in Table 4, including network topology, computational capabilities, task characteristics, and other essential features to guarantee the representativeness and validity of the simulation environment.
Table 4.
The simulation scene parameter configuration of CFHCC.
The key parameters of the FS-NSGA-II algorithm are summarized in Table 5. The parameter configuration is grounded in evolutionary algorithm theory and established principles of fractal geometry. The evolutionary parameters (, ) adhere to standard multi-objective optimization guidelines, which balance population diversity and computational efficiency. The fractal-specific parameters are initialized based on theoretical foundations: provides optimal recursive partitioning depth for solution spaces with 3–8 decision variables; follows the adaptive decomposition criterion that subspace variance should reduce to 10–20% before further subdivision; and the crossover/mutation probabilities implement the classical 70–30 exploitation–exploration balance with Gaussian perturbations constrained to ±0.6 standard deviations. These theoretically motivated initial values are subsequently validated and refined through the sensitivity analysis presented below.
Table 5.
Parameter configuration of FS-NSGA-II.
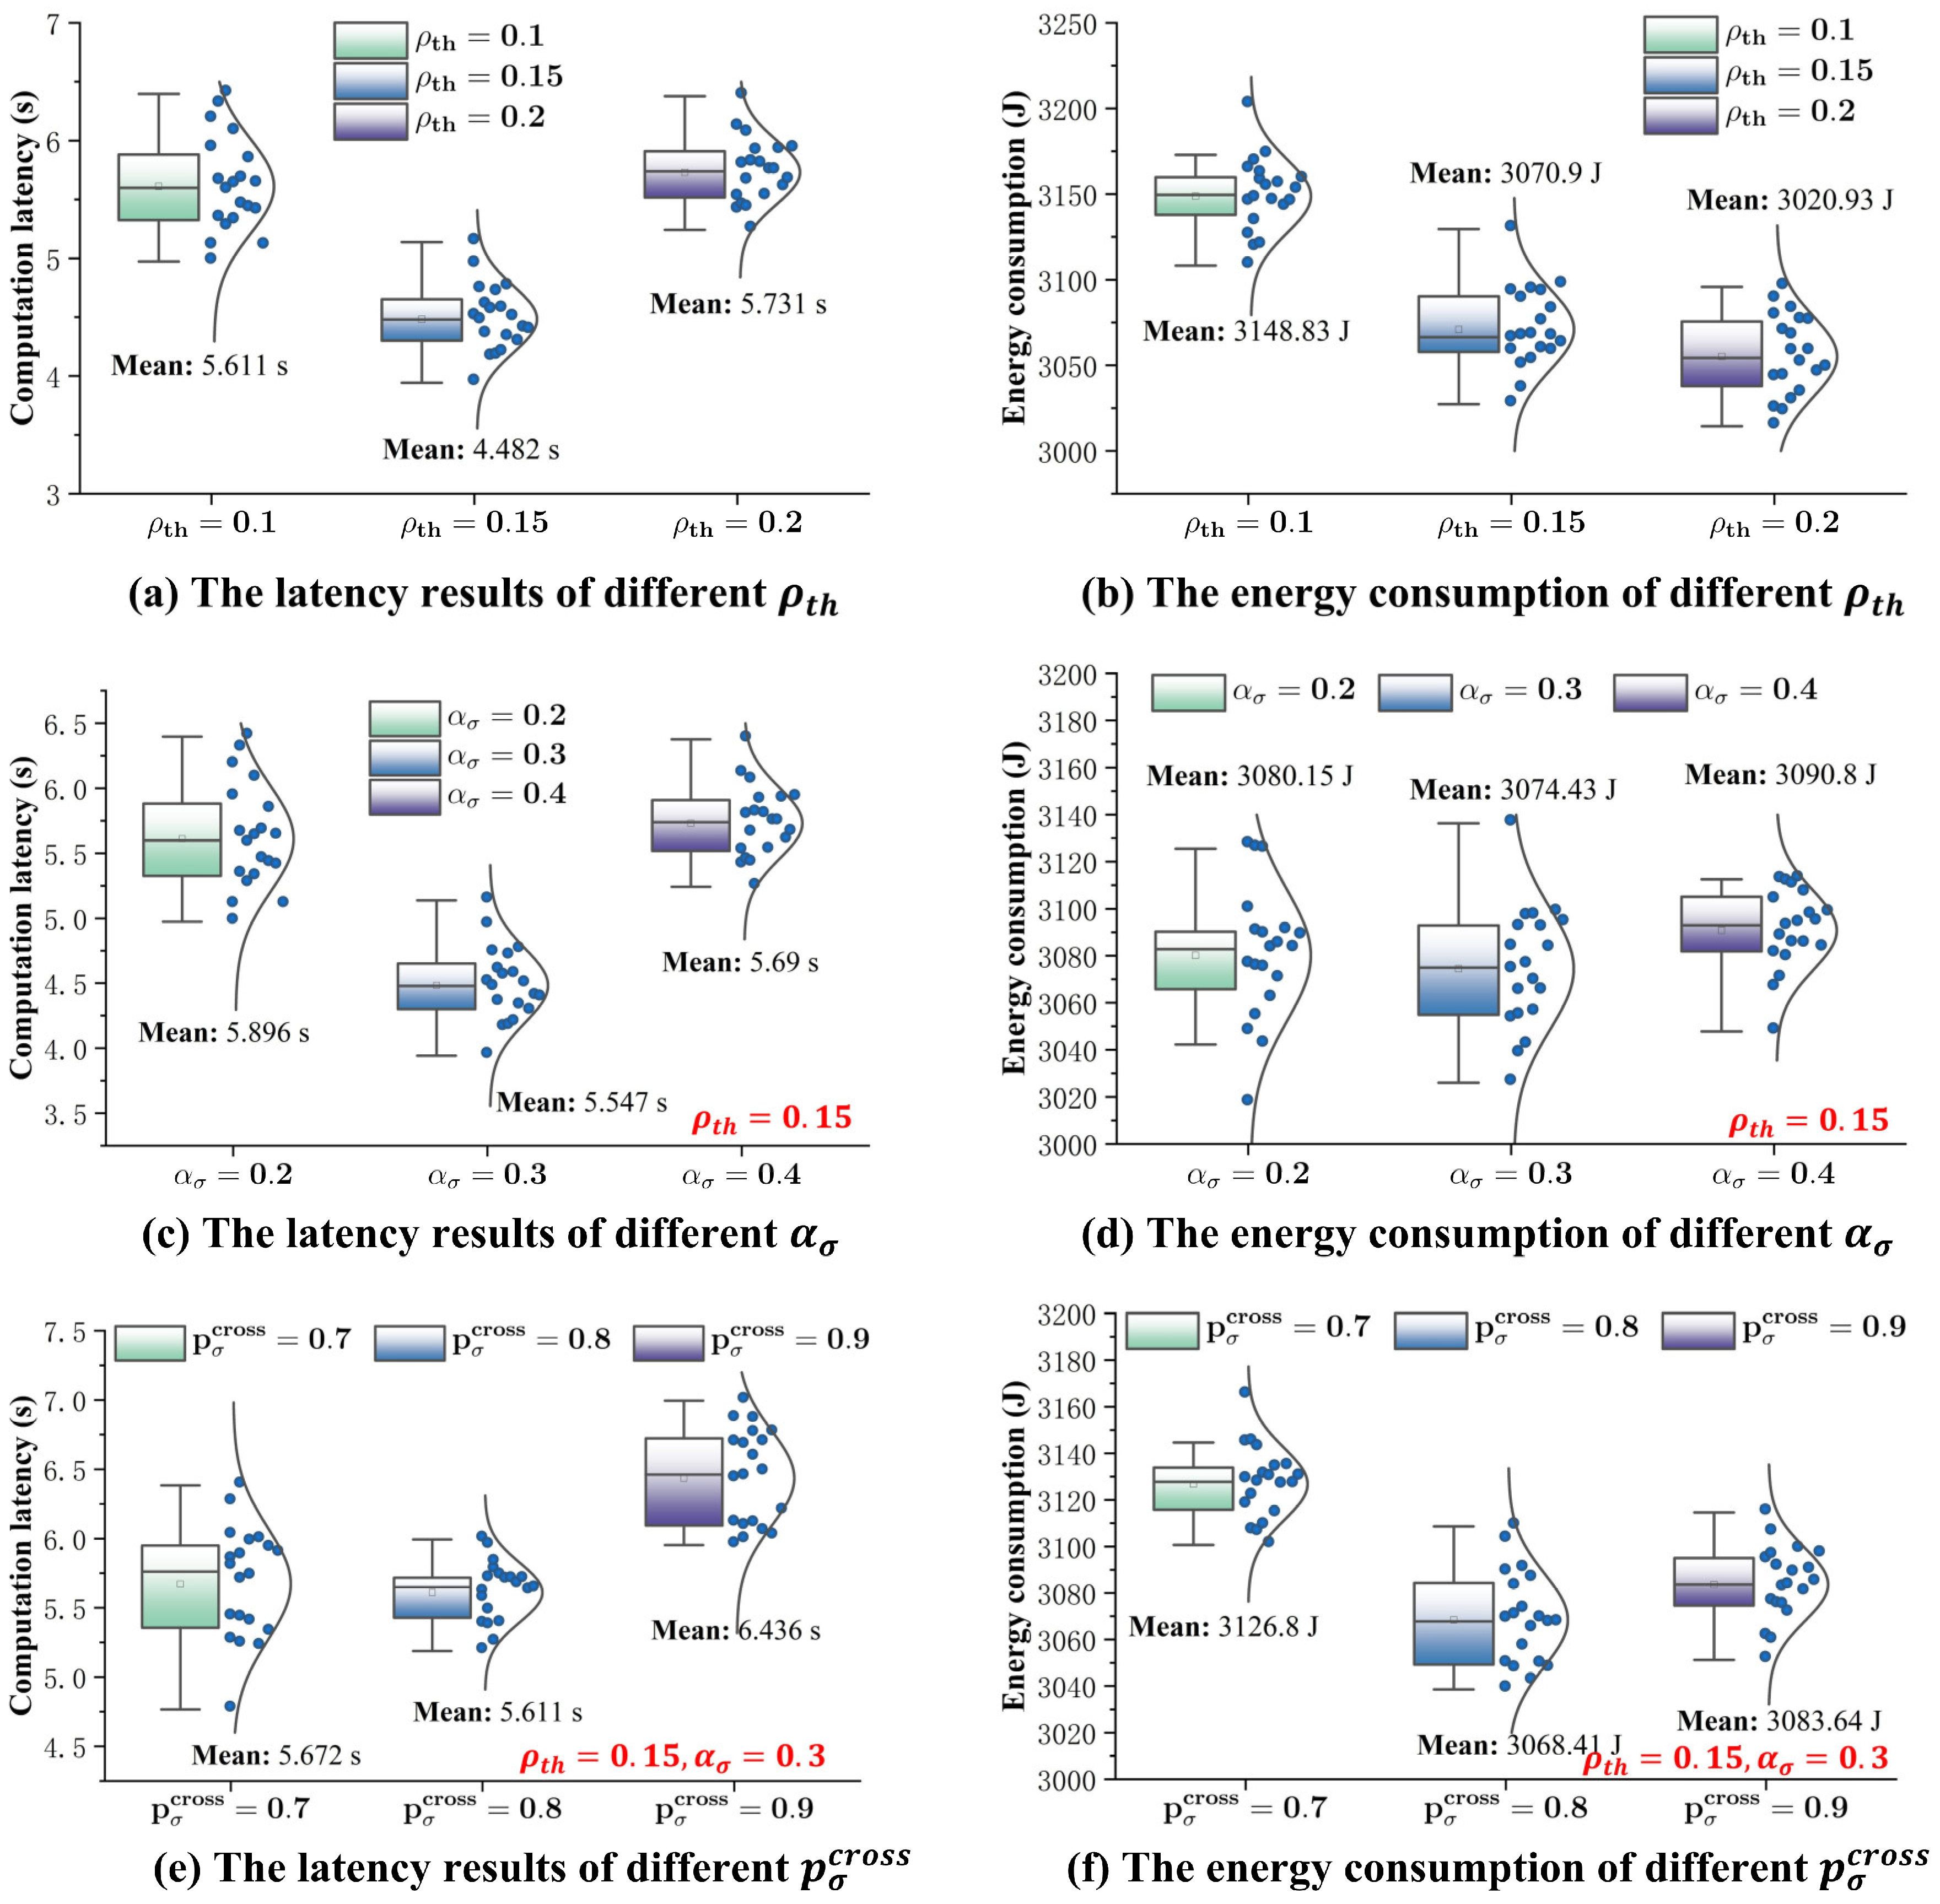
A sensitivity analysis was conducted to evaluate the effect that the core parameters of FS-NSGA-II have on optimization performance. The investigation focused on the fractal partition threshold (), the Gaussian perturbation coefficient (), and the fractal crossover probability (), as these parameters fundamentally influence the algorithm’s search dynamics and solution diversity. The results of the sensitivity test are shown in Figure 5.
Figure 5.
Parameter sensitivity test of FS-NSGA-II.
(1) The fractal partition threshold () controls the granularity of recursive space division: a lower value enables finer partitioning, which enhances local exploitation but may incur higher computational costs, and a higher value favors broader exploration but can reduce solution precision. Experimental results show that setting to an intermediate value (0.15) achieves the best trade-off, yielding the lowest computation latency and energy consumption.
(2) The Gaussian perturbation coefficient () determines the intensity of random perturbations during the generation of solutions. Too small a value may limit the algorithm’s ability to escape local optima, while too large a value introduces excessive randomness that can slow down convergence. The results confirm that setting to 0.3 enhances both convergence speed and solution diversity.
(3) The fractal crossover probability () determines the likelihood of recombination within the fractal subspaces. Higher crossover probabilities promote genetic diversity but can disrupt the preservation of high-quality solutions, whereas lower probabilities may hinder exploration. The experiments indicate that achieves the best balance, leading to further improvements in both latency and energy metrics.
These observations highlight that the performance of FS-NSGA-II depends critically on the interplay between partition granularity, perturbation intensity, and genetic diversity mechanisms. Optimal parameter tuning, guided by their underlying roles, is thus essential for robust and efficient optimization. The recommended settings () were adopted in subsequent experiments.
To further assess the advanced nature and scalability of the proposed FS-NSGA-II, a comparative study was conducted against two representative baselines.
(1) NSGA-II [38]: The classical non-dominated sorting genetic algorithm was adopted as the ablation reference for FS-NSGA-II. This comparison enabled a clear identification of the performance gains introduced by the fractal space partitioning mechanism.
(2) Differential Evolution (DE) [45]: DE is a population-based evolutionary algorithm that demonstrates particular competitiveness in large-scale task offloading scenarios. Its robustness and simplicity in balancing exploration and exploitation make it a strong benchmark for multi-objective optimization in computation offloading problems.
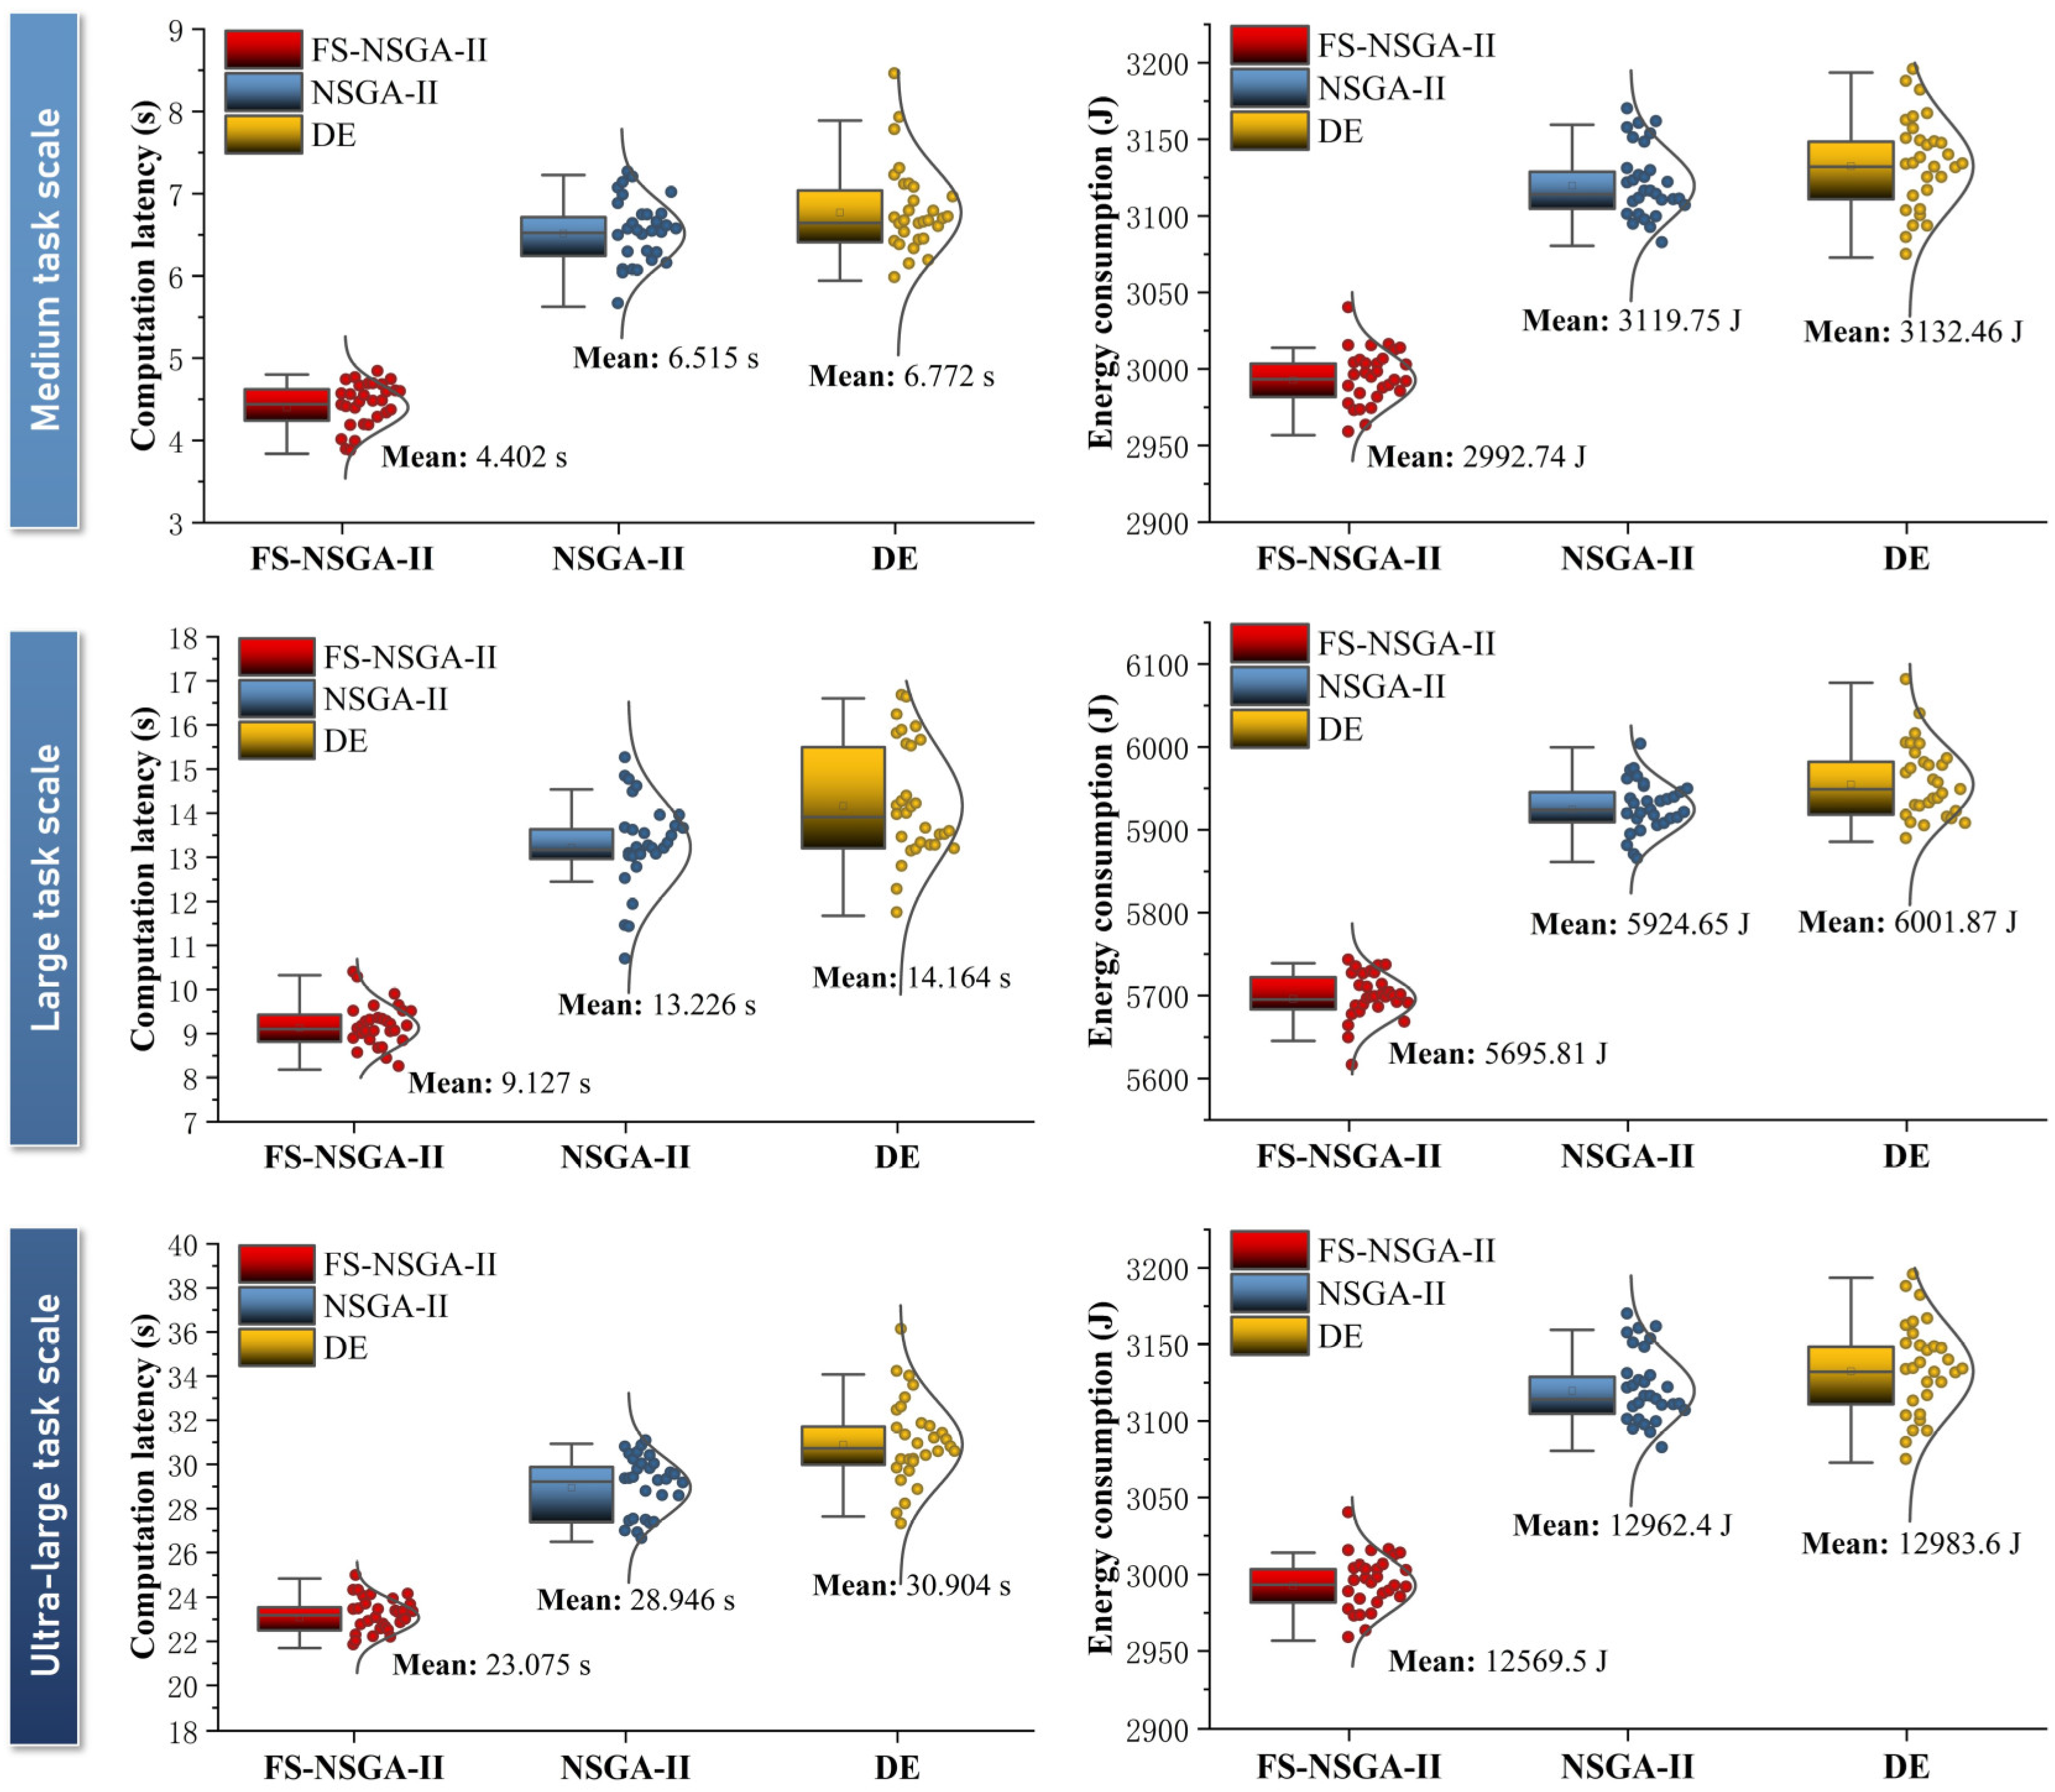
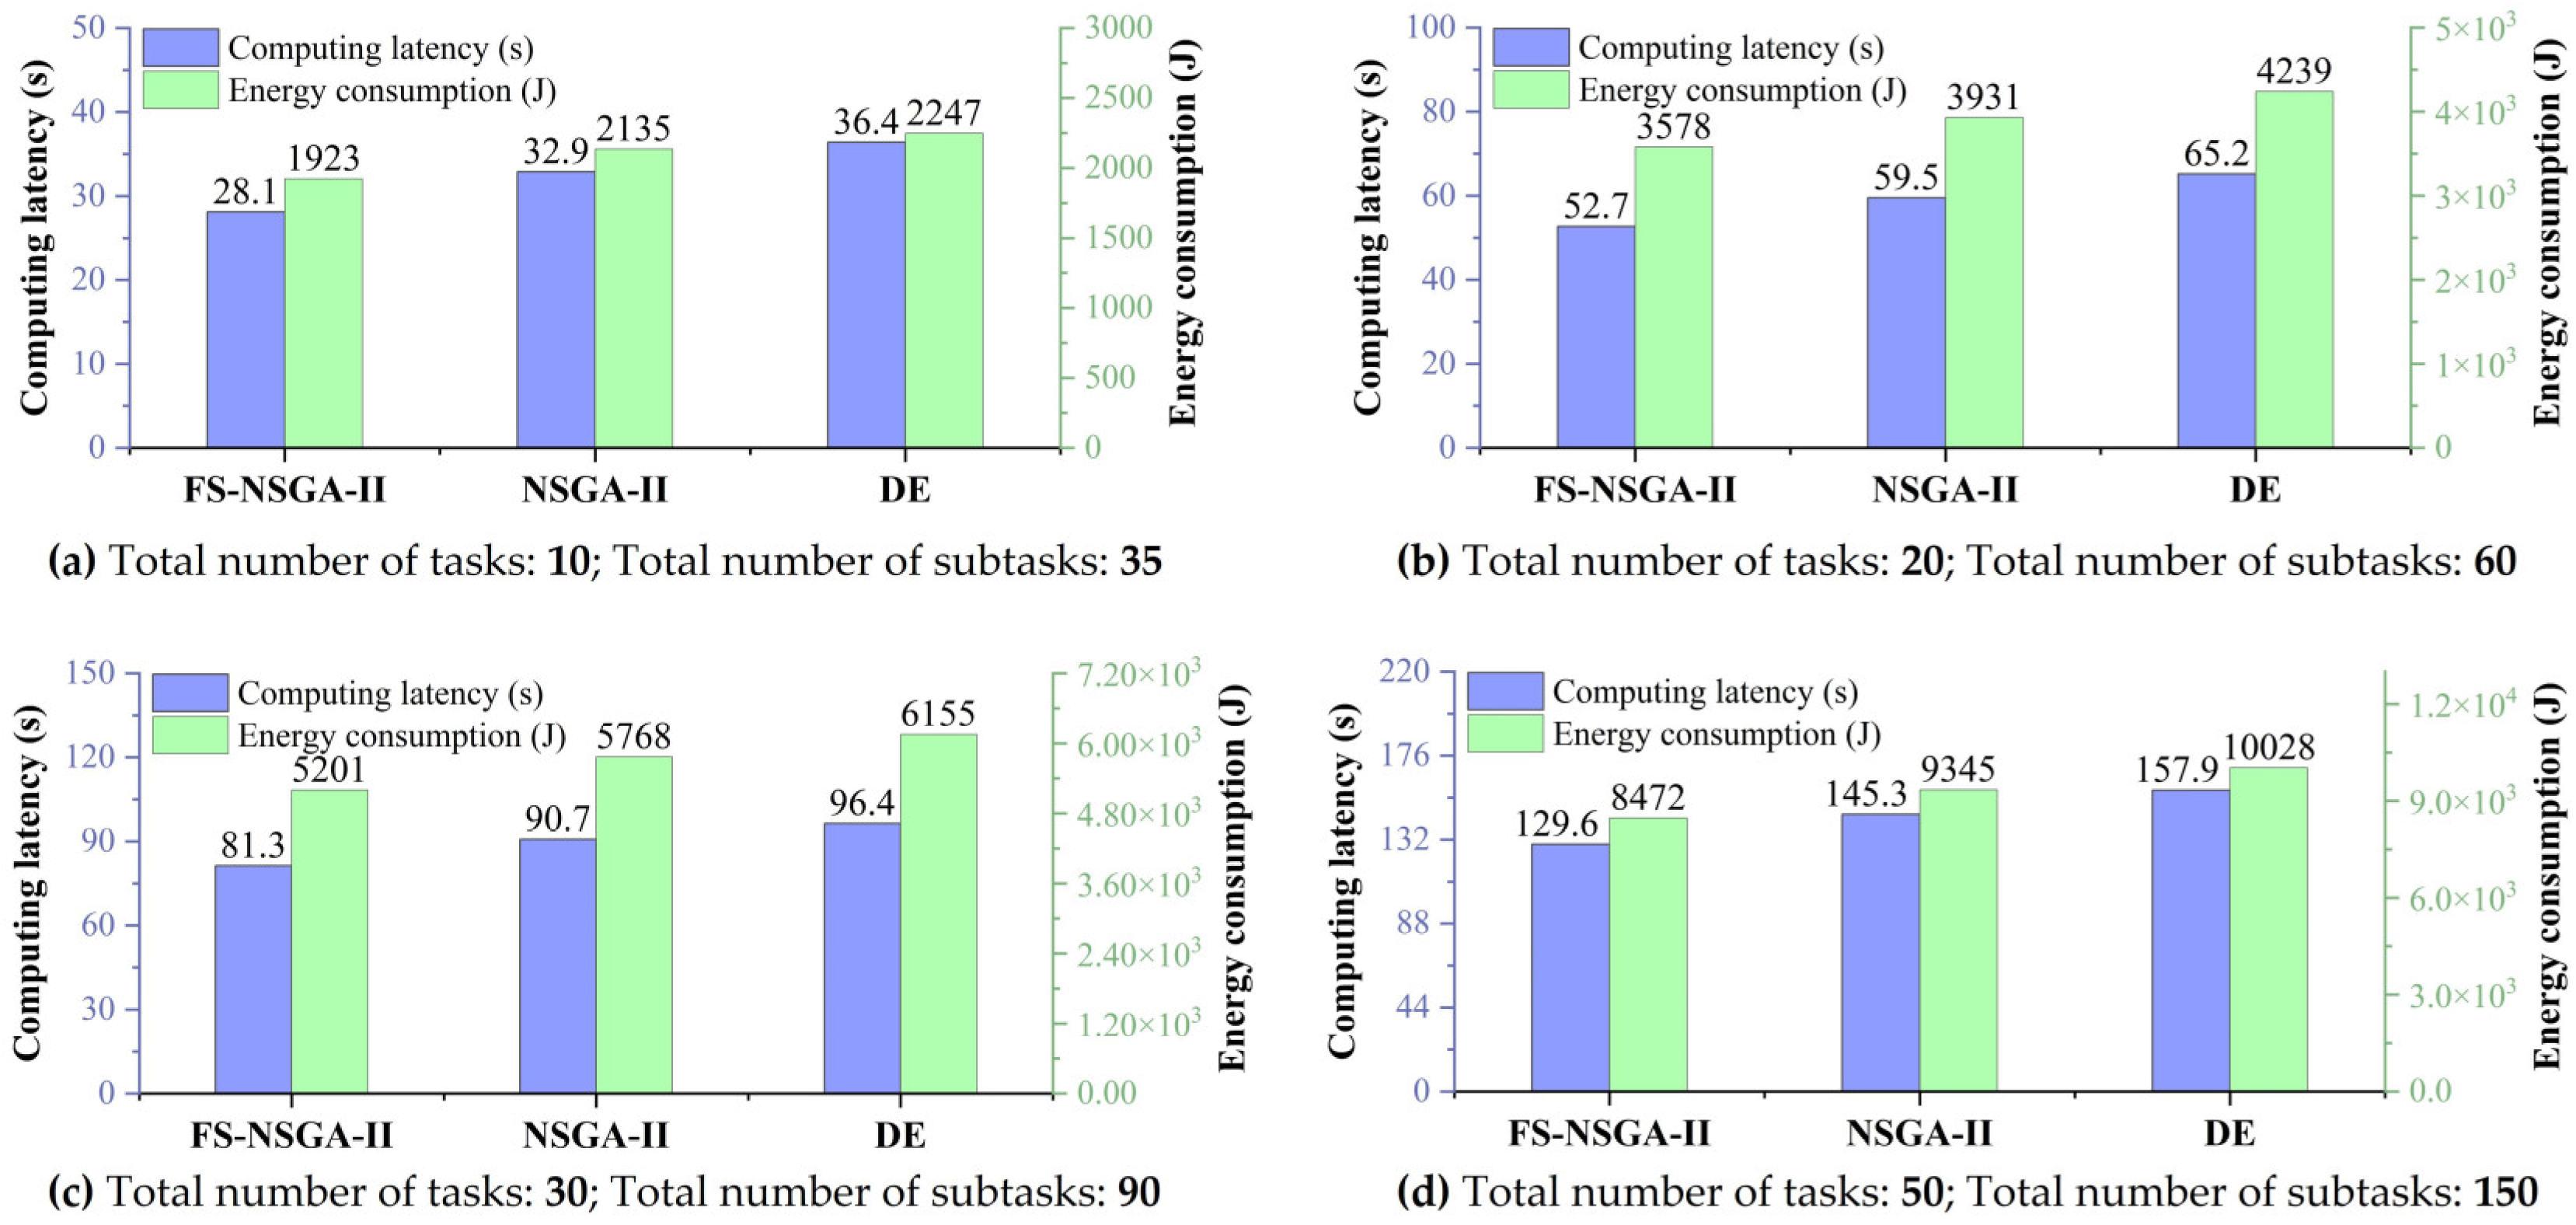
Experiments were performed using three different task scales, specifically medium, large, and ultra-large scenarios, to provide a comprehensive evaluation of the performance of algorithms under varying computational loads. For each scenario, all algorithms were independently applied for 30 runs to obtain statistically robust results. Key performance metrics included computation latency and energy consumption, as illustrated in Figure 6.
Figure 6.
The offloading latency and energy consumption of different methods under various task scales.
The results demonstrate that FS-NSGA-II consistently outperforms both NSGA-II and DE across all task scales in terms of both computation latency and energy consumption. As the task scale increases, the superiority of FS-NSGA-II becomes increasingly pronounced. This can be attributed to the fractal space partitioning mechanism, which adaptively refines the granularity of the search space and maintains population diversity, thereby enabling the more effective exploration of the Pareto front in complex, large-scale environments. In the ultra-large task scenario, FS-NSGA-II achieved an average computation latency of 23.08 s, representing a 20.28% reduction compared to NSGA-II and 25.33% compared to DE. Similarly, the mean energy consumption decreased to 12,569.5 J, which is 3.03% and 3.19% lower than the respective baselines. In addition, as shown by the box plots and distribution curves, FS-NSGA-II not only achieved lower median values but also exhibited a tighter distribution with fewer outliers, indicating its greater robustness and solution consistency. The solution sets obtained by FS-NSGA-II displayed a more compact and symmetric distribution, highlighting its superior ability to maintain both convergence and diversity under varying problem scales.
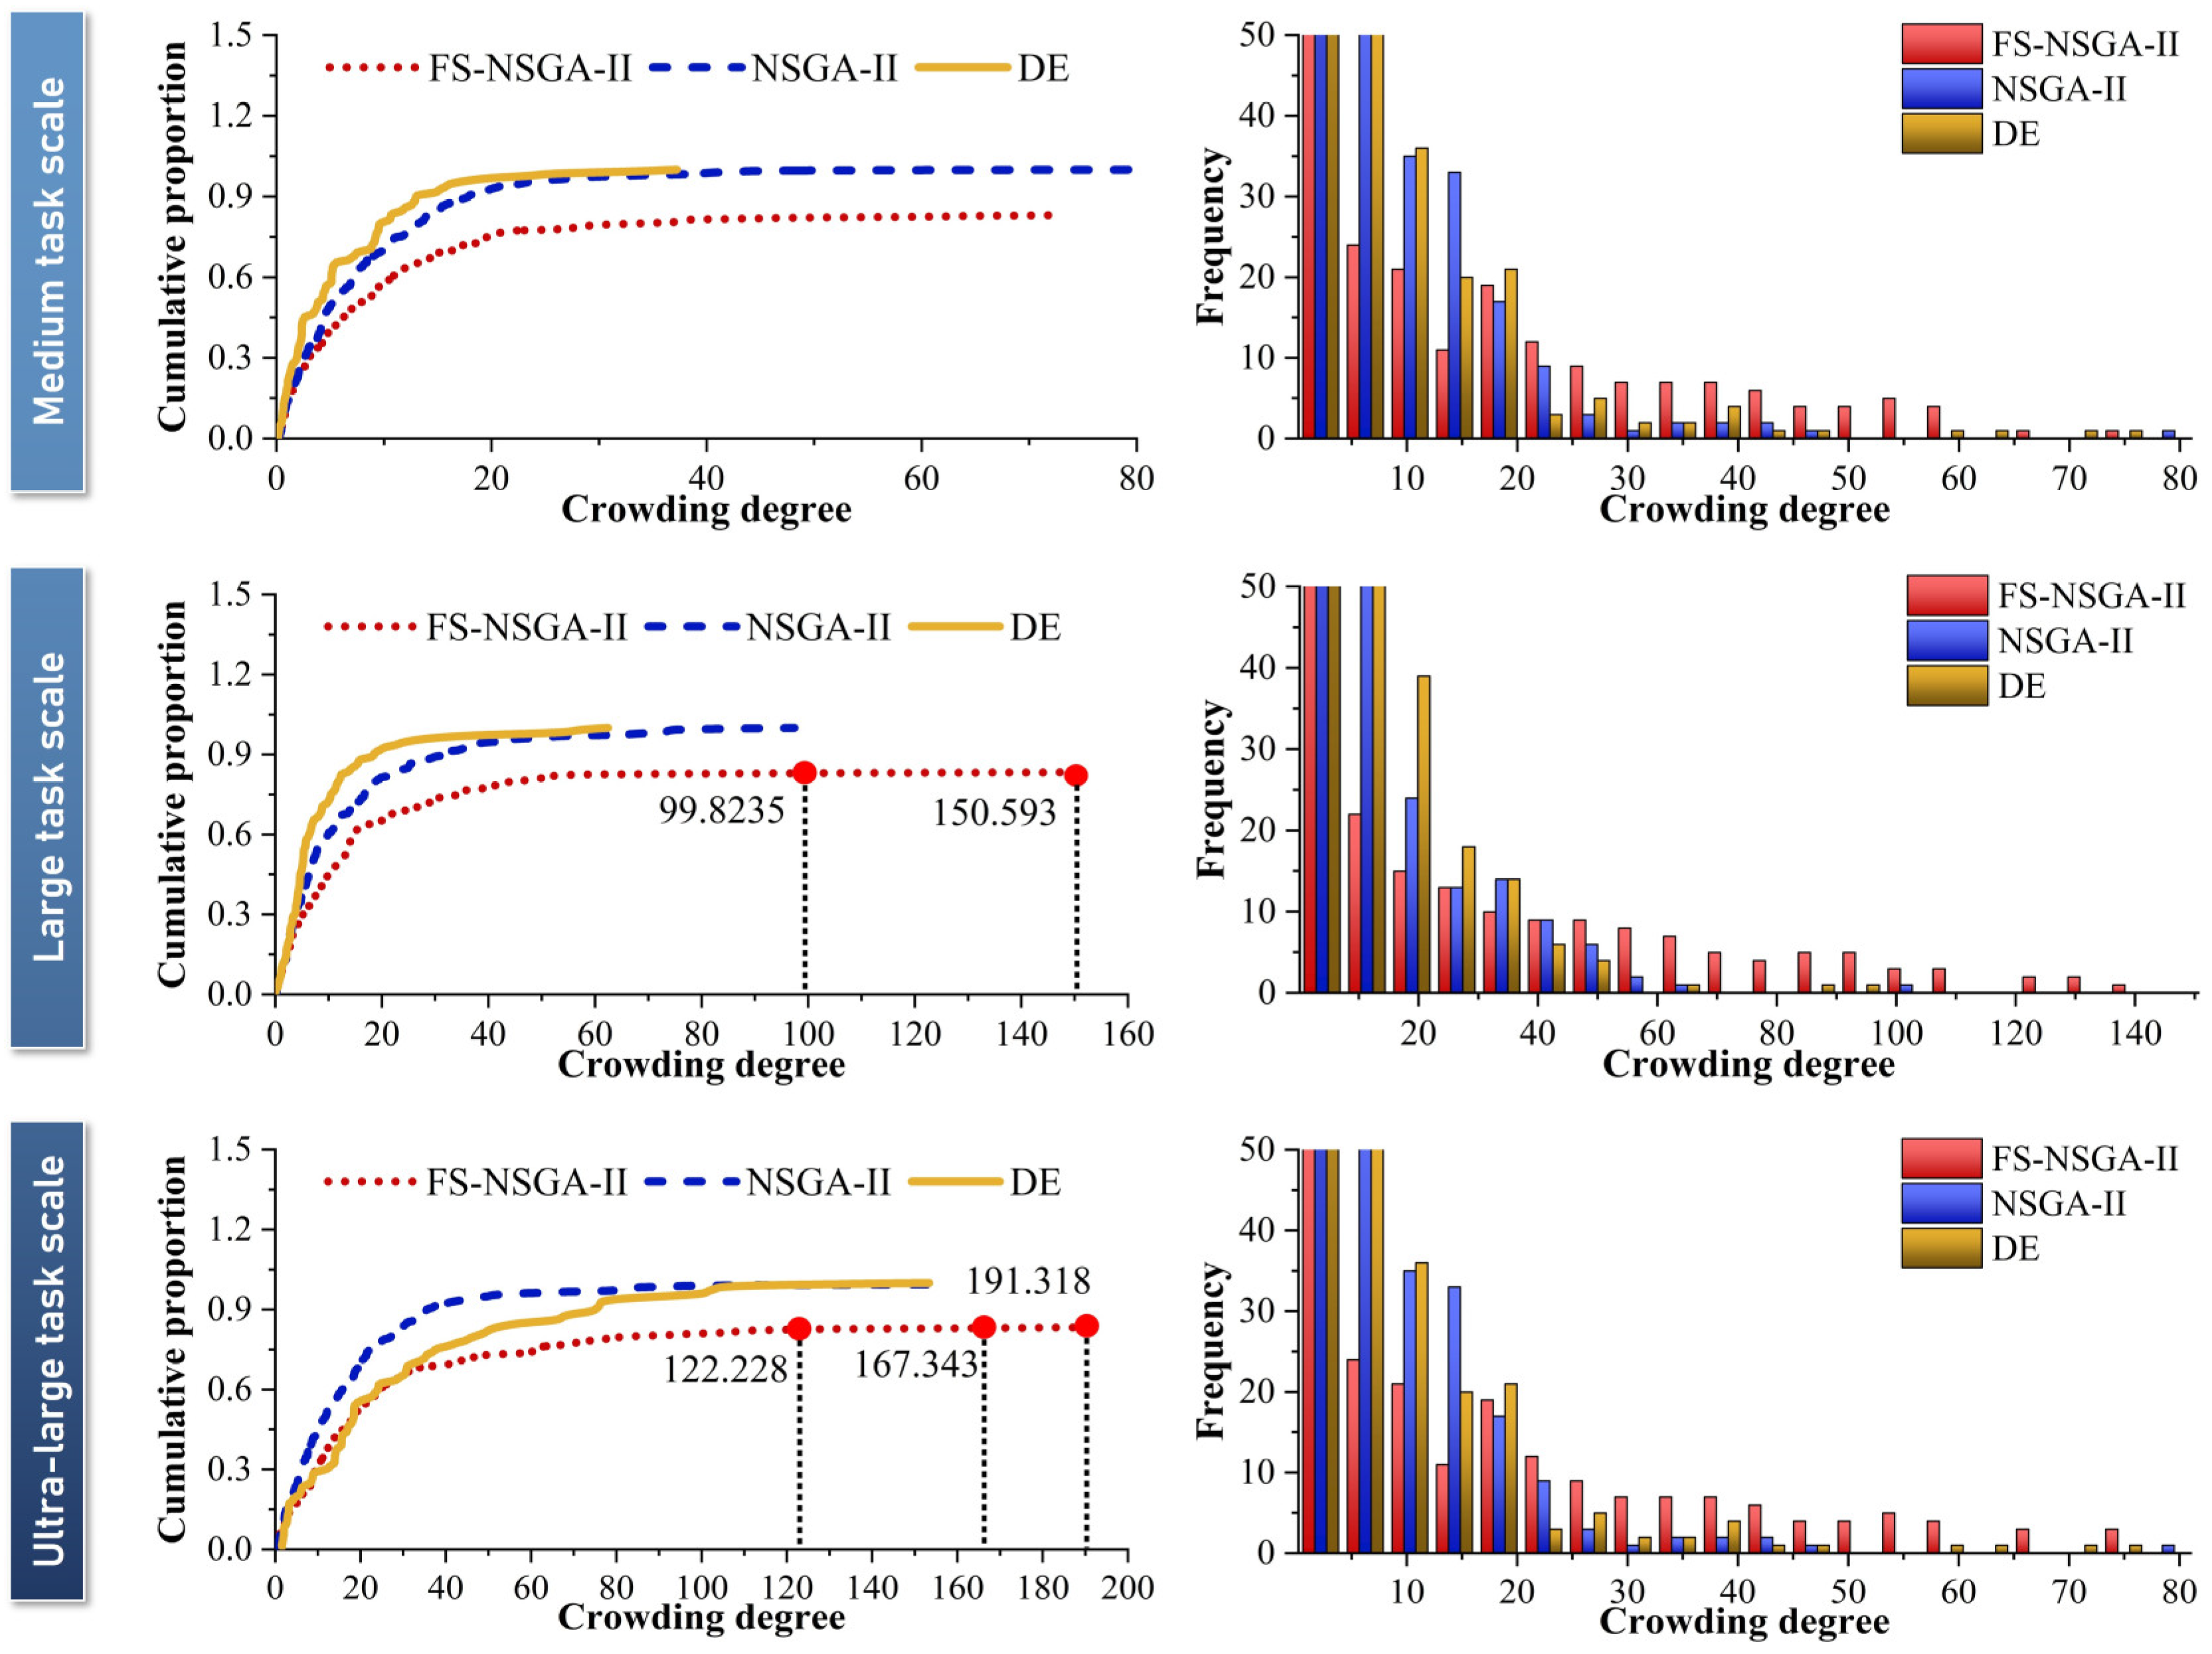
To comprehensively evaluate the diversity of the obtained solution sets, the empirical cumulative distribution function (ECDF) and grouped histograms of crowding degrees are presented for each algorithm under different task scales in Figure 7.
Figure 7.
Comparison of the diversity distribution of congestion degrees from different methods under various task scales.
(1) The ECDF curves reveal that FS-NSGA-II exhibits a noticeable rightward shift compared to NSGA-II and DE. This phenomenon arises because fractal space partitioning recursively decomposes the objective space into hierarchical subspaces, constraining genetic operations within locally bounded regions. This structured decomposition prevents solution overcrowding in globally attractive areas and actively allocates search efforts to underexplored regions, thereby maintaining larger minimum distances between neighboring solutions. This indicates that a higher proportion of Pareto solutions in FS-NSGA-II possess larger crowding degrees, reflecting a more uniform and less clustered distribution of solutions. In the ultra-large task scenario, the 100th percentile crowding degree achieved by FS-NSGA-II reached 0.723. In contrast, NSGA-II and especially DE demonstrate rapid saturation in their ECDFs, implying that a large fraction of solutions are tightly packed, which may hinder the effective exploration of the Pareto front and limit the diversity of trade-offs available to the decision-maker.
(2) The grouped histograms further corroborate these findings. FS-NSGA-II achieves an even broader distribution of crowding degrees, with a substantial number of solutions in higher crowding degree intervals. This suggests that the algorithm not only generates a wider spread of solutions but also avoids premature convergence to high-density regions. By contrast, the histograms for NSGA-II and DE are skewed towards lower crowding degree intervals, indicating a tendency for these algorithms to produce more clustered populations and, thus, limited diversity.
Drawing on the superiority and preceding diversity analysis, Table 6 provides a comprehensive quantitative comparison of all methods under different task scales. FS-NSGA-II consistently achieved the best performance, with the lowest mean maximum latency and energy consumption, as well as a higher number of Pareto solutions and greater mean crowding distance across all scales. Its improvements in IGD and HV further confirm their superior convergence and diversity. The standard deviations of key metrics remained low, reflecting the method’s robustness and stability. In addition, FS-NSGA-II maintained competitive runtime efficiency, with average computation times consistently lower than or comparable to the baselines as task size increased.
Table 6.
Comprehensive comparison results of the performance of various methods under different task scales.
From a mechanism perspective, these improvements are primarily attributed to the synergy between fractal partitioning and evolutionary operators. The adaptive granularity of space partitioning enables the algorithm to allocate search efforts dynamically to underexplored regions; enhanced crossover and perturbation strategies further promote the dispersion and uniformity of solutions. As a result, FS-NSGA-II produces a well-distributed and robust Pareto front, which is particularly advantageous for real-world multi-objective decision-making scenarios.
6.2. Case Study
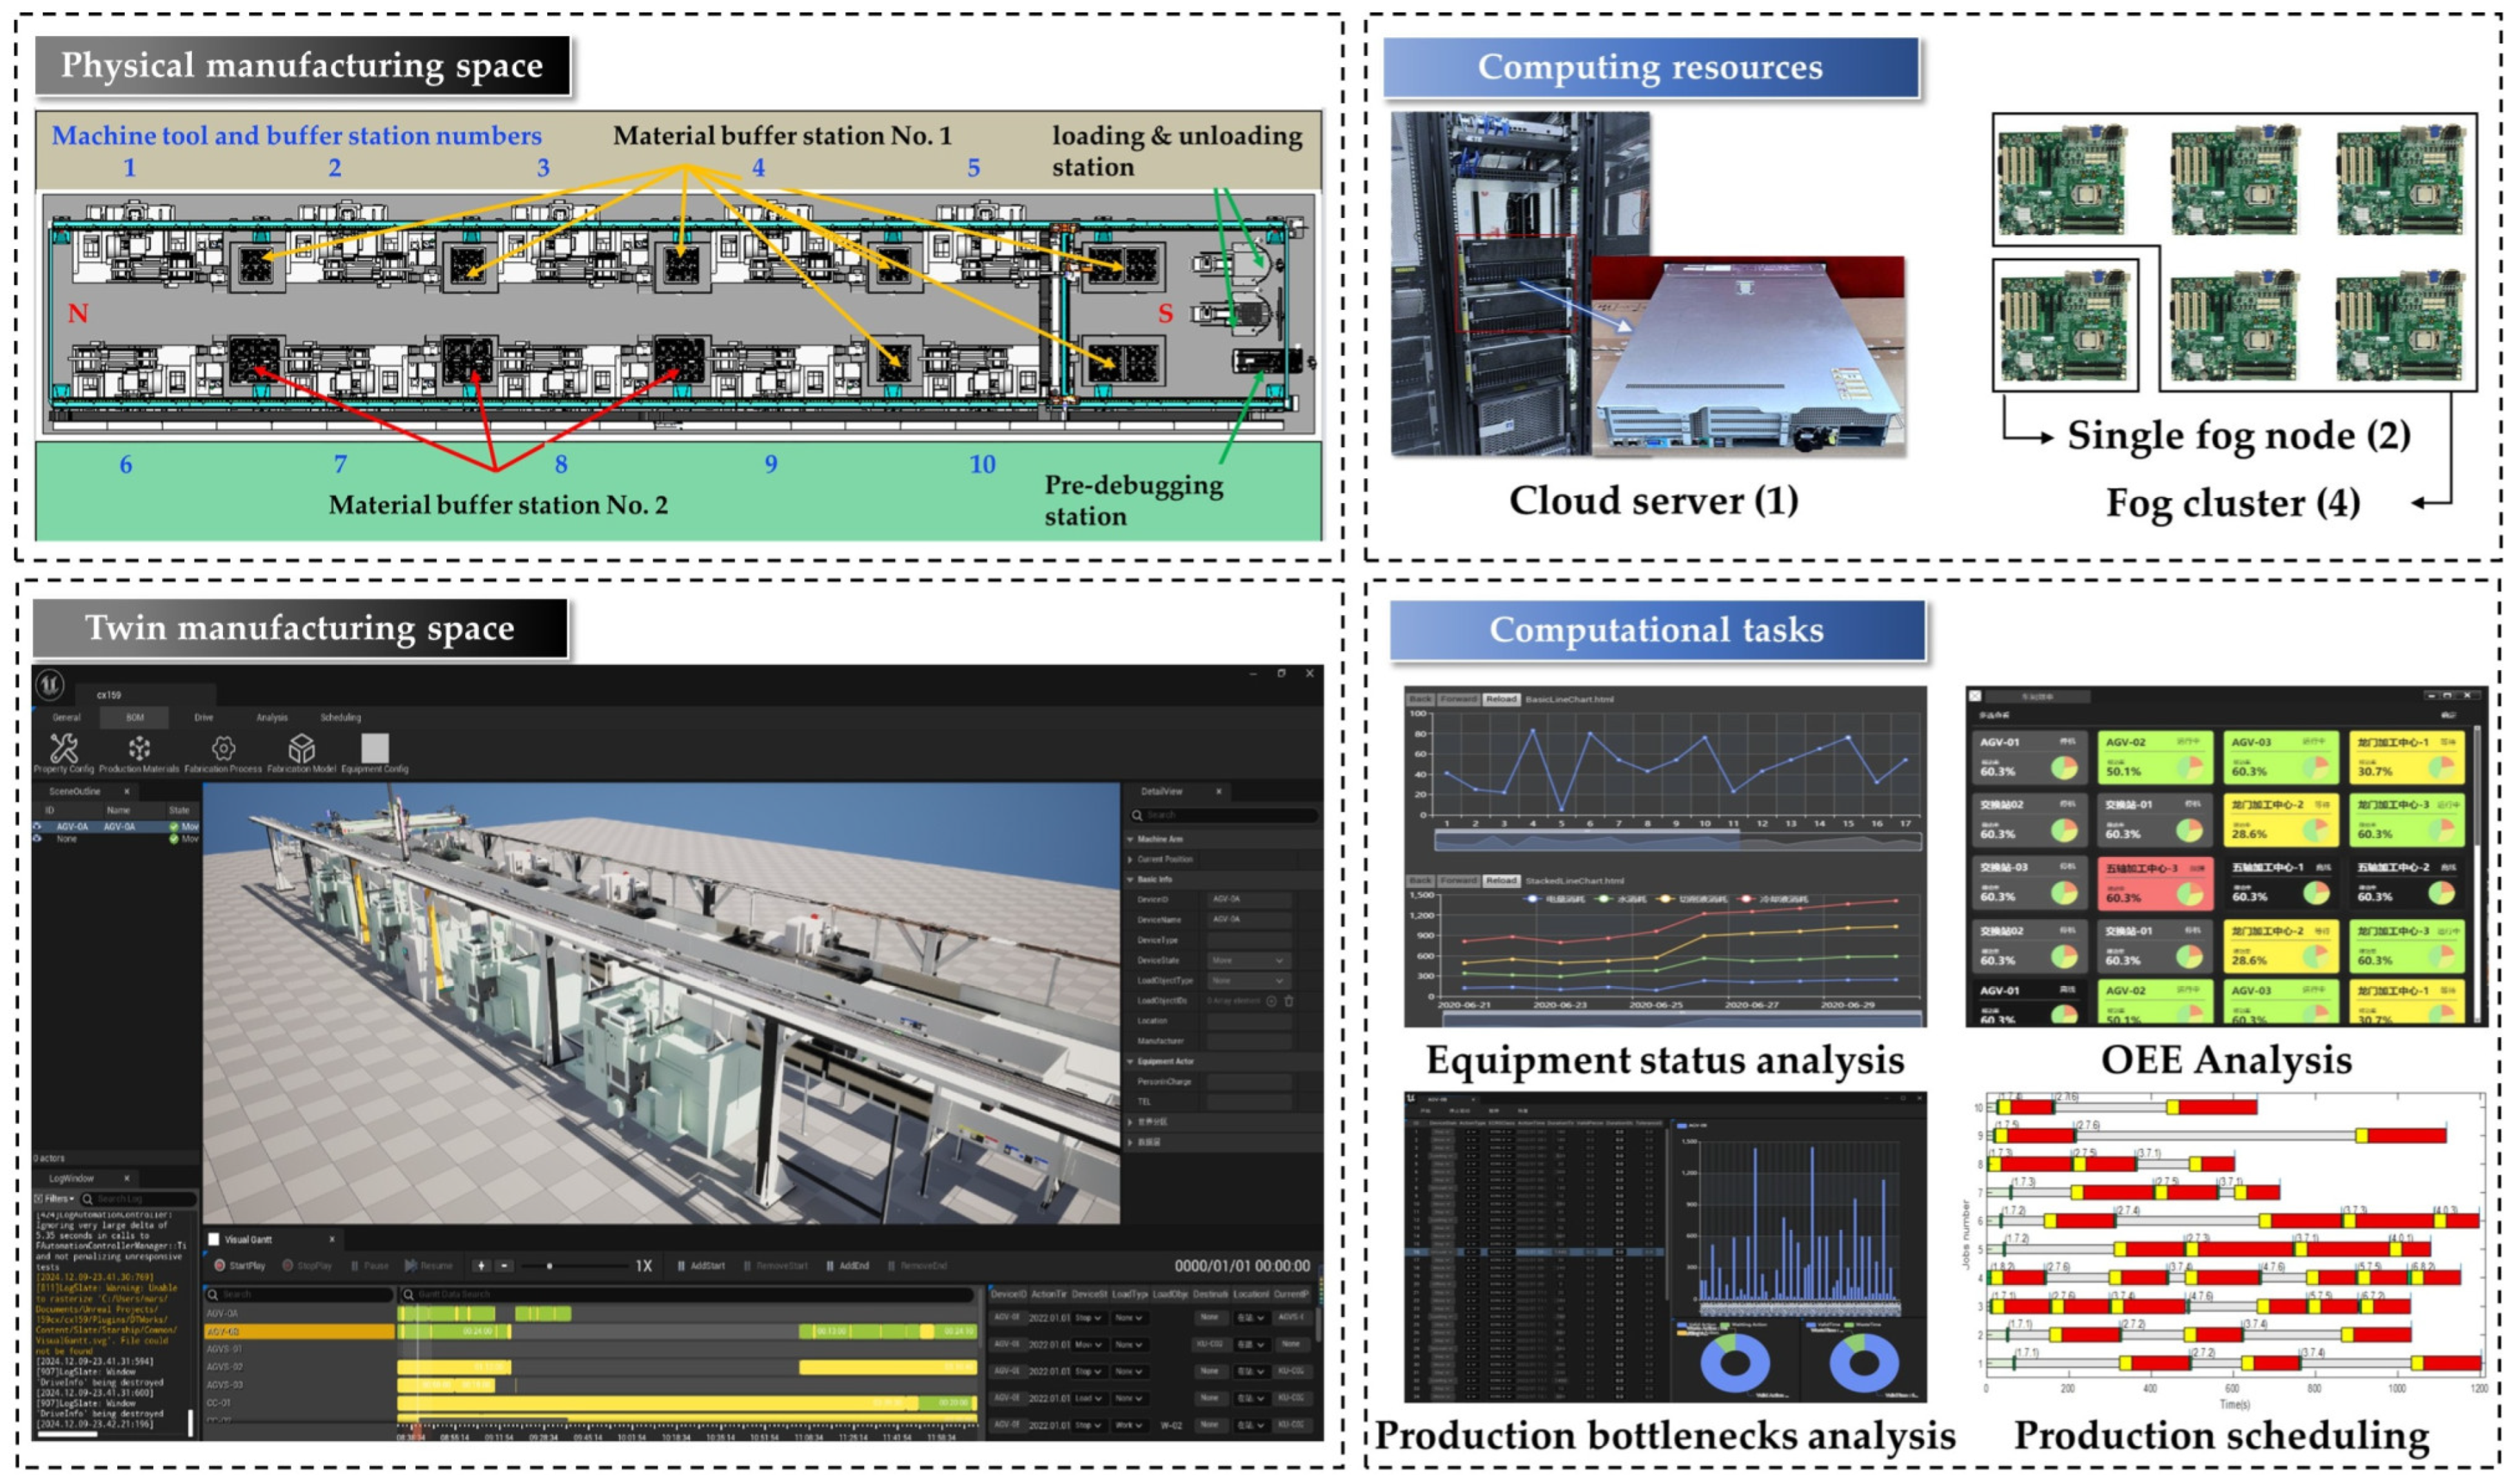
Further tests were conducted to evaluate the engineering applicability of the proposed CFHCC architecture. A digital twin manufacturing system for a specific type of cabin segment was selected as the testbed to investigate the practical benefits of the CFHCC architecture. As illustrated in Figure 8, the physical and twin manufacturing spaces are interconnected through a hierarchical computing infrastructure. The system comprises one cloud server, two single-fog nodes, and four fog clusters, each containing four fog nodes. The cloud server is configured with 20 CPU cores, 128 GB of memory, and a 10 Gbps network interface. Each fog node is equipped with a 6-core processor and 8 GB of memory, and the fog clusters are connected via gigabit Ethernet.
Figure 8.
Computing resources and tasks in the digital twin manufacturing scenario.
Table 7 lists the computational tasks and parameters in the digital twin manufacturing system. Each task consists of several sub-tasks, with explicit data dependencies between them, some of which are designed to be processed in parallel. The data size and computational load of each sub-task are specified according to actual application requirements. These tasks are issued to the digital twin system concurrently at various time points to simulate the dynamic workload of the production environment in a realistic way.
Table 7.
The task list and parameters of the digital twin manufacturing system.
The experiment tested the actual performance of the FS-NSGA-II task offloading optimization method compared to other benchmarks under varying task quantities ranging from 10 to 50; the results are presented in Figure 9. As the task scale expanded, FS-NSGA-II consistently maintained optimal performance with increasing advantages. In large-scale concurrent task offloading environments, the task offloading latency improved by 10.8% and 21.8% compared to NSGA-II and DE, respectively, while computational energy consumption increased by 9.34% and 15.52%, respectively. These results demonstrate that FS-NSGA-II possesses outstanding optimization capabilities in practical application environments.
Figure 9.
The offloading results of different methods under various task scales for actual cases.
To further evaluate the performance of collaborative offloading mechanisms, a series of comparative experiments was conducted. The test baselines are presented as follows:
(1) Cloud–Edge Collaborative Computing Framework (CECC) [45]: Tasks can be offloaded either to the cloud or to a single-edge node, but no collaboration occurs among multiple fog nodes.
(2) Distributed Edge Framework (Edge) [14]: Tasks are processed by independent edge nodes without the involvement of the cloud or any inter-fog coordination.
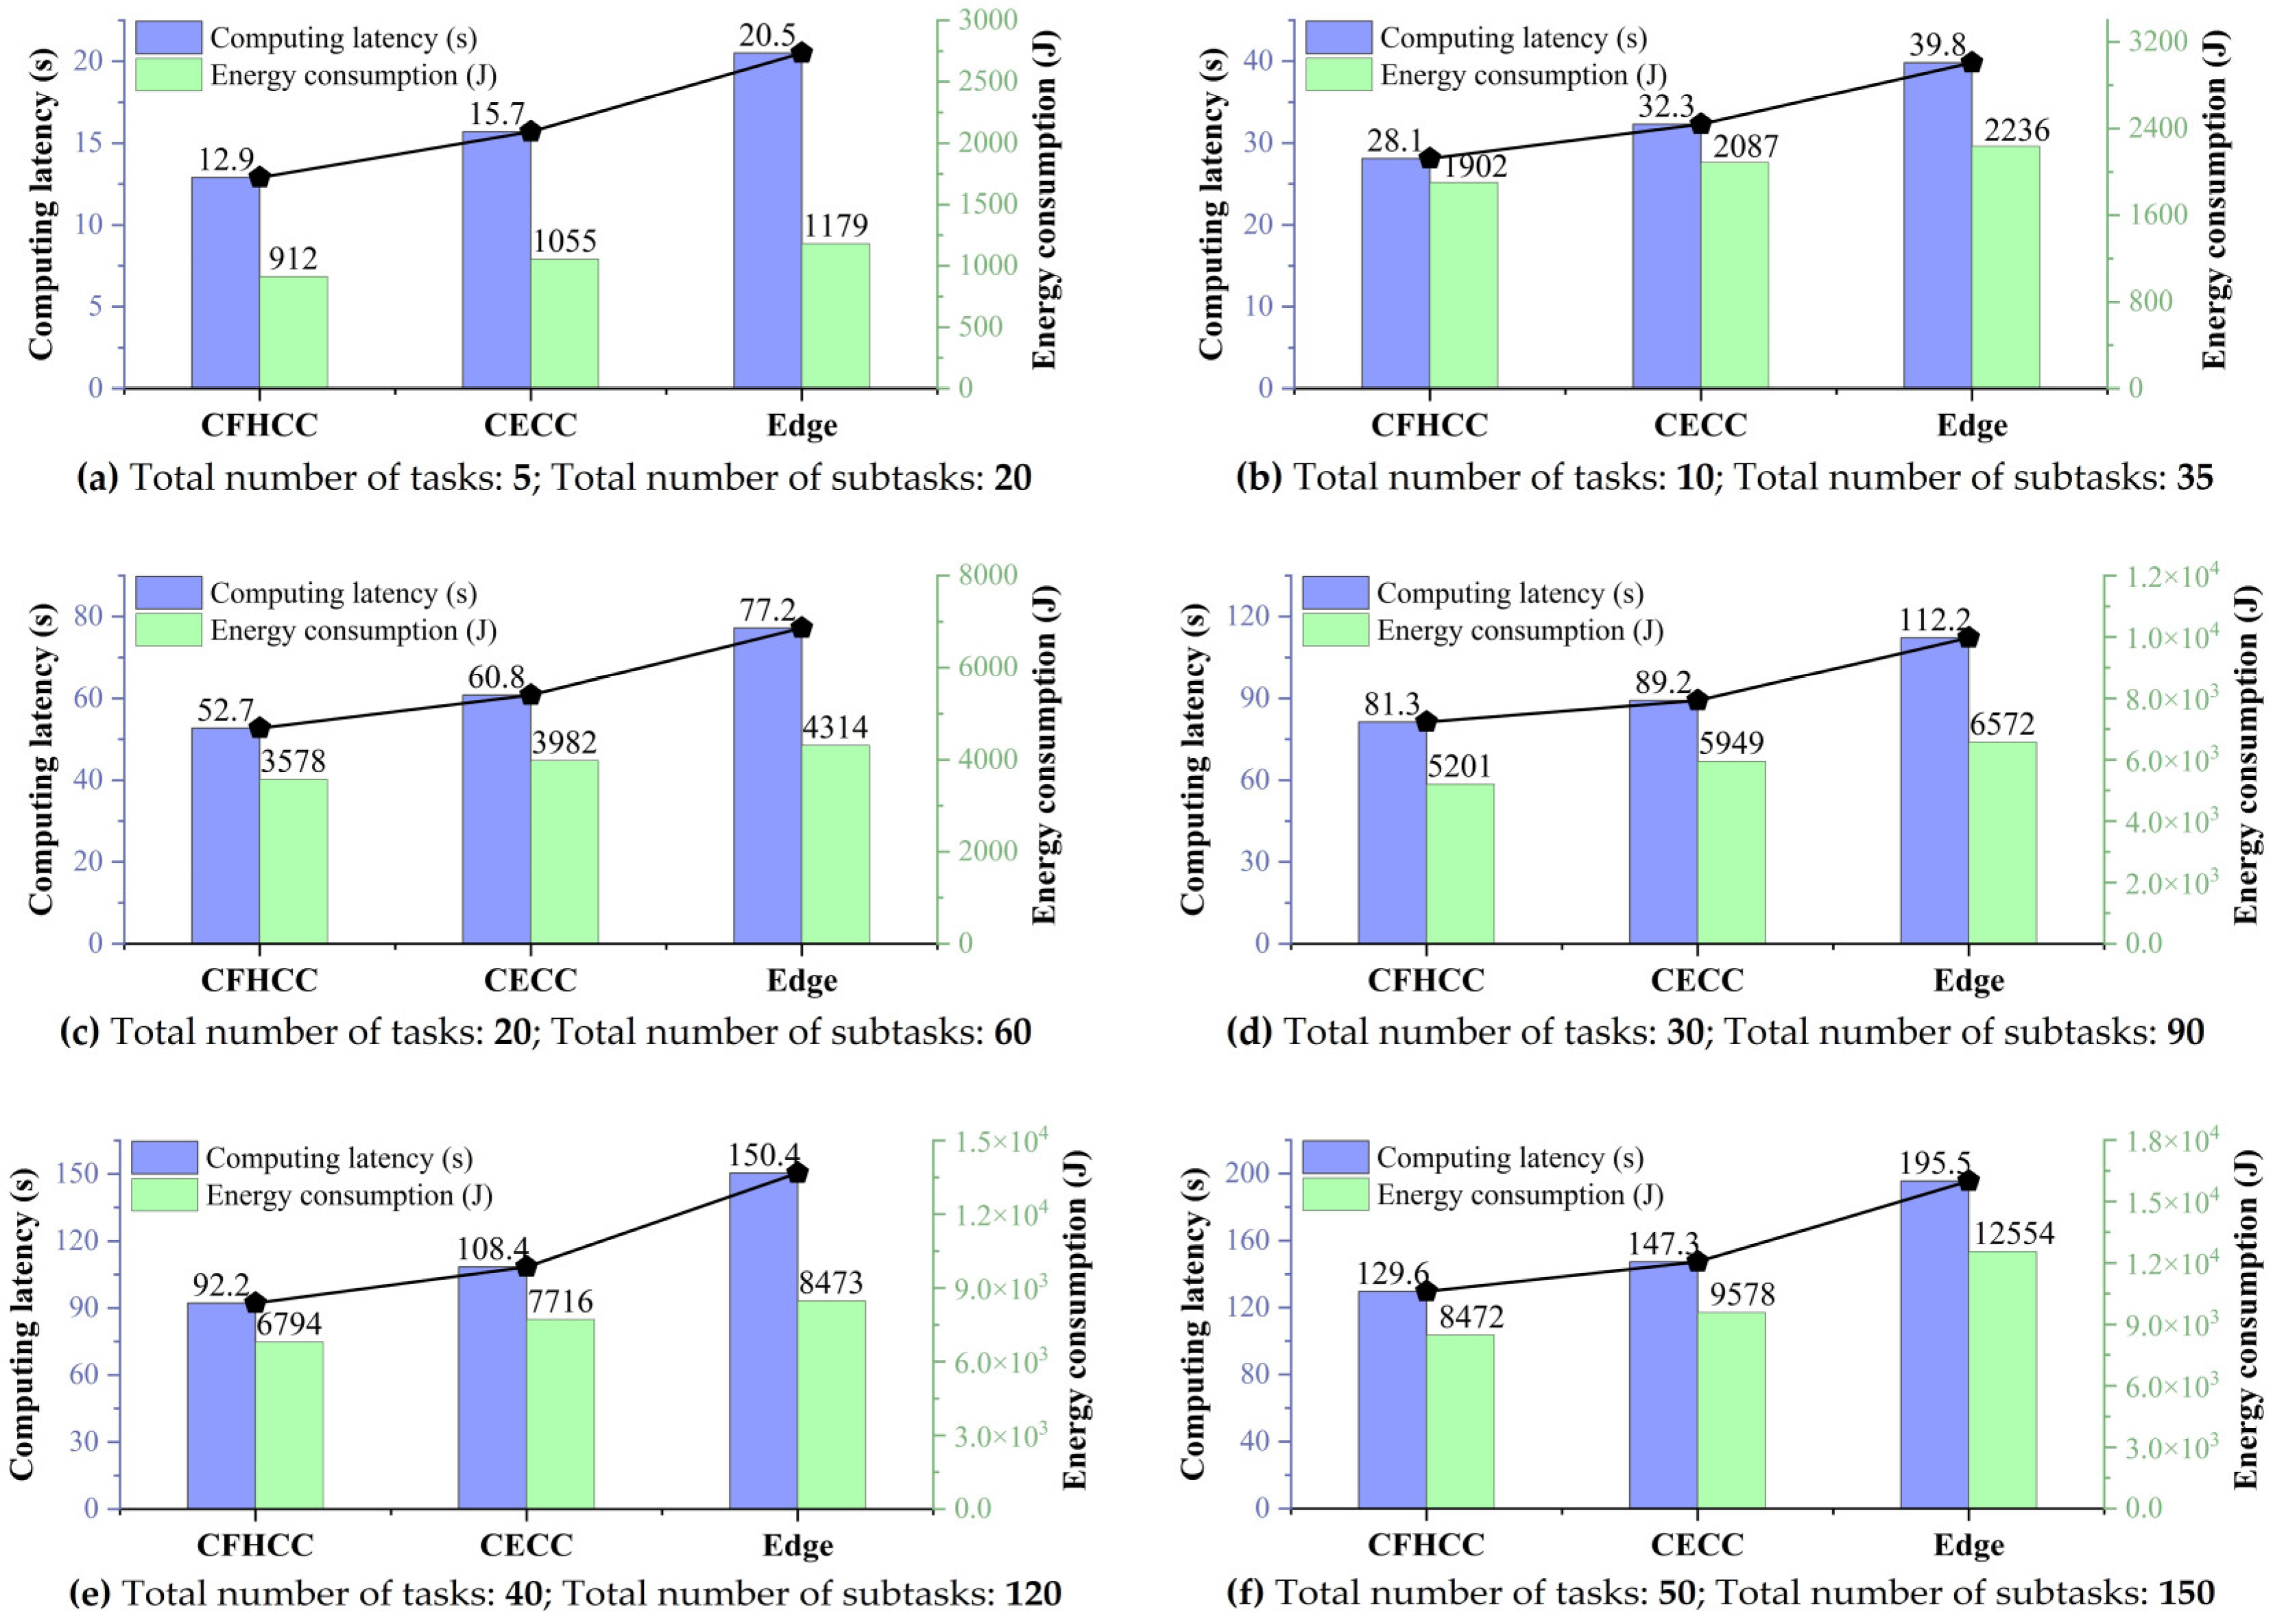
As illustrated in Figure 10, the CFHCC framework demonstrates clear advantages over both CECC and edge frameworks under varying task scales. The CFHCC introduces a fog cluster mechanism that enables parallel processing and dynamic load balancing among multiple fog nodes. This collaborative capability results in reductions of 12.02% and 11.55% for maximum task delay and total energy consumption under large-scale tasks compared to the CECC framework. When compared with the edge framework, CFHCC achieves greater performance stability and efficiency. The absence of cloud participation in edge constrains the system’s capacity to handle computation-intensive or intensive task periods, leading to performance degradation and instability as the task scale grows.
Figure 10.
The offloading results of different computational mode under various task scales for actual cases.
Furthermore, the adoption of the CFHCC framework brings substantial practical benefits to the operation of digital twin systems. For monitoring-oriented tasks, collaborative fog clusters can process and analyze streaming sensor data in parallel, improving computational efficiency by 18.9% compared to the edge framework. For analysis-oriented tasks, the cloud’s abundant computational resources can be utilized for deep learning and large-scale data analysis, while the fog layer ensures timely preprocessing and feedback, improving computational efficiency by 28.3%.
These findings align with previous studies demonstrating the superiority of hierarchical fog–cloud architectures over purely cloud-centric or edge-only approaches [9,10,21]. Although recent edge computing frameworks [5,14] typically employ independent edge nodes with limited local computing capacity, our collaborative fog cluster mechanism enables parallel task processing and dynamic load balancing among multiple fog nodes, resulting in 18.9% efficiency improvement over non-collaborative edge solutions.
While recent work has advocated for fully decentralized edge frameworks to address data privacy concerns, our case study demonstrates that completely eliminating cloud participation leads to significant performance degradation (up to 28.3% efficiency loss for analysis-intensive tasks) and instability under heavy workloads. This diverges from the common assumption in the literature [46] that edge computing inherently trades computational capability for data locality. Our case study demonstrates that appropriately designed fog-level collaboration can simultaneously preserve data privacy at the edge while achieving computational performance comparable to cloud-centric approaches [47], thereby addressing the critical gap between industrial data security requirements and computational efficiency demands.
7. Conclusions and Future Work
This study addresses the critical challenge of efficient task offloading in smart manufacturing environments characterized by complex task dependencies, data sensitivity constraints, and large-scale concurrent processing demands. The principal contributions are summarized as follows:
(1) A novel collaborative computing architecture is proposed, introducing fog cluster mechanisms that enable coordinated multi-node task execution while maintaining data locality. The case study demonstrates that fog cluster collaboration achieves an efficiency improvement of up to 28.3% over non-collaborative edge solutions, effectively reconciling industrial data protection with computational performance requirements as stated in the research objectives.
(2) A comprehensive mathematical model is established that captures the heterogeneous computing capabilities across cloud, single fog, and fog cluster layers, incorporating task dependency constraints, deadline requirements, and energy–latency trade-offs. This formulation extends existing offloading models by explicitly modeling fog cluster collaboration through sub-task decomposition, parallel processing, and result aggregation mechanisms.
(3) A fractal-enhanced multi-objective optimization algorithm is developed that exploits the structural alignment between recursive space partitioning and hierarchical computing architectures. Experimental results demonstrate that FS-NSGA-II achieves 20.28% latency reduction and 3.03% energy savings compared to standard NSGA-II in large-scale scenarios, with a superior diversity of solutions.
Future research will focus on developing adaptive mechanisms that dynamically adjust fog cluster configurations in response to time-varying workload patterns and network conditions, as relatively stable operational environments are assumed in the current framework. A comprehensive sensitivity analysis framework will also be established to quantitatively evaluate system robustness under network volatility and fog cluster scalability scenarios.
Author Contributions
Conceptualization, Z.L. (Zhiwen Lin) and C.C.; methodology, Z.L. (Zhiwen Lin) and J.C.; software, Z.L. (Zhiwen Lin); validation, C.C. and Z.L. (Zhifeng Liu); investigation, J.C.; resources, Z.L. (Zhifeng Liu); writing—original draft preparation, Z.L. (Zhiwen Lin); writing—review and editing, Z.L. (Zhiwen Lin) and J.C.; project administration, Z.L. (Zhifeng Liu). All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by the National Natural Science Foundation of China (No. U23B20104), the Innovation Consortium Project of Machine Tools and Moulds in Dongguan (NO.20251201500012), the Jilin Province Science and Technology Development Plan (No. YDZJ202401314ZYTS), and the Integrated Project of the National Natural Science Foundation of China (Grant. U24B6007).
Data Availability Statement
The original contributions presented in this study are included in the article. Further inquiries can be directed to the corresponding author.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Sarkar, B.D.; Shardeo, V.; Dwivedi, A.; Pamucar, D. Digital transition from industry 4.0 to industry 5.0 in smart manufacturing: A framework for sustainable future. Technol. Soc. 2024, 78, 102649. [Google Scholar] [CrossRef] [Scilit]
- Yang, H.B.; Ong, S.K.; Nee, A.Y.C.; Jiang, G.D.; Mei, X.S. Microservices-based cloud-edge collaborative condition monitoring platform for smart manufacturing systems. Int. J. Prod. Res. 2022, 60, 7492–7501. [Google Scholar] [CrossRef] [Scilit]
- Chheang, V.; Narain, S.; Hooten, G.; Cerda, R.; Au, B.; Weston, B.; Giera, B.; Bremer, P.T.; Miao, H.C. Enabling additive manufacturing part inspection of digital twins via collaborative virtual reality. Sci. Rep. 2024, 14, 29783. [Google Scholar] [CrossRef] [Scilit]
- Marisetty, H.V.; Fatima, N.; Gupta, M.; Saxena, P. Relationship between resource scheduling and distributed learning in IoT edge computing—An insight into complementary aspects, existing research and future directions. Internet Things 2024, 28, 101375. [Google Scholar] [CrossRef] [Scilit]
- Yao, N.F.; Zhao, Y.Q.; Guo, Y.; Kong, S.G. Few-Sample Anomaly Detection in Industrial Images With Edge Enhancement and Cascade Residual Feature Refinement. IEEE Trans. Ind. Inform. 2024, 20, 13975–13985. [Google Scholar] [CrossRef] [Scilit]
- Xiao, G.J.; Huang, Y. Equivalent self-adaptive belt grinding for the real-R edge of an aero-engine precision-forged blade. Int. J. Adv. Manuf. Tech. 2016, 83, 1697–1706. [Google Scholar] [CrossRef] [Scilit]
- Cai, Z.Y.; Du, X.Y.; Huang, T.H.; Lv, T.R.; Cai, Z.H.; Gong, G.Q. Robotic Edge Intelligence for Energy-Efficient Human-Robot Collaboration. Sustainability 2024, 16, 9788. [Google Scholar] [CrossRef] [Scilit]
- Lin, Z.W.; Liu, Z.F.; Yan, J.; Zhang, Y.Z.; Chen, C.H.; Qi, B.B.; Guo, J.Y. Digital thread-driven cloud-fog-edge collaborative disturbance mitigation mechanism for adaptive production in digital twin discrete manufacturing workshop. Int. J. Prod. Res. 2024, 1–29. [Google Scholar] [CrossRef] [Scilit]
- Yin, H.Y.; Huang, X.D.; Cao, E.R. A Cloud-Edge-Based Multi-Objective Task Scheduling Approach for Smart Manufacturing Lines. J. Grid Comput. 2024, 22, 9. [Google Scholar] [CrossRef] [Scilit]
- Ma, J.; Zhou, H.; Liu, C.C.; E, M.C.; Jiang, Z.Q.; Wang, Q. Study on Edge-Cloud Collaborative Production Scheduling Based on Enterprises With Multi-Factory. IEEE Access 2020, 8, 30069–30080. [Google Scholar] [CrossRef] [Scilit]
- Li, H.C.; Cao, Y.P.; Lei, Y.B.; Cao, H.J.; Peng, J.; Jia, Y.C. Energy-aware dynamic rescheduling of flexible manufacturing system using edge-cloud collaborative decision-making method. Int. J. Comput. Integr. Manuf. 2025, 38, 434–449. [Google Scholar] [CrossRef] [Scilit]
- Nie, Q.W.; Tang, D.B.; Liu, C.C.; Wang, L.P.; Song, J.Y. A multi-agent and cloud-edge orchestration framework of digital twin for distributed production control. Robot. Comput.-Integr. Manuf. 2023, 82, 102543. [Google Scholar] [CrossRef] [Scilit]
- Hong, Z.C.; Qu, T.; Zhang, Y.H.; Zhang, Z.F.; Huang, G.Q. Cloud-fog-edge based computing architechture and a hierarchical decision approach for distributed synchronized manufacturing systems. Adv. Eng. Inform. 2025, 65, 103386. [Google Scholar] [CrossRef] [Scilit]
- Li, X.M.; Wan, J.F.; Dai, H.N.; Imran, M.; Xia, M.; Celesti, A. A Hybrid Computing Solution and Resource Scheduling Strategy for Edge Computing in Smart Manufacturing. IEEE Trans. Ind. Inform. 2019, 15, 4225–4234. [Google Scholar] [CrossRef] [Scilit]
- Cai, J.; Fu, H.T.; Liu, Y. Deep reinforcement learning-based multitask hybrid computing offloading for multiaccess edge computing. Int. J. Intell. Syst. 2022, 37, 6221–6243. [Google Scholar] [CrossRef] [Scilit]
- Wang, M.; Zhang, Y.J.; He, X.; Yu, S.H. Joint scheduling and offloading of computational tasks with time dependency under edge computing networks. Simul. Model. Pract. Theory 2023, 129, 102824. [Google Scholar] [CrossRef] [Scilit]
- Chakraborty, C.; Mishra, K.; Majhi, S.K.; Bhuyan, H.K. Intelligent Latency-Aware Tasks Prioritization and Offloading Strategy in Distributed Fog-Cloud of Things. IEEE Trans. Ind. Inform. 2023, 19, 2099–2106. [Google Scholar] [CrossRef] [Scilit]
- Ma, S.Y.; Song, S.D.; Yang, L.Y.; Zhao, J.M.; Yang, F.; Zhai, L.B. Dependent tasks offloading based on particle swarm optimization algorithm in multi-access edge computing. Appl. Soft Comput. 2021, 112, 107790. [Google Scholar] [CrossRef] [Scilit]
- Mannhardt, F.; Petersen, S.A.; Oliveira, M.F. A trust and privacy framework for smart manufacturing environments. J. Ambient. Intell. Smart Environ. 2019, 11, 201–219. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.H.; Su, S.C.; Wang, Y.W. Attention-augmented multi-agent collaboration for Smart Industrial Internet of Things task offloading. Internet Things 2025, 31, 101572. [Google Scholar] [CrossRef] [Scilit]
- Liu, S.F.; Qiao, B.Y.; Han, D.H.; Wu, G. Task offloading method based on CNN-LSTM-attention for cloud-edge-end collaboration system. Internet Things 2024, 26, 101204. [Google Scholar] [CrossRef] [Scilit]
- Bernard, L.; Yassa, S.; Alouache, L.; Romain, O. Efficient Pareto based approach for IoT task offloading on Fog-Cloud environments. Internet Things 2024, 27, 101311. [Google Scholar] [CrossRef] [Scilit]
- Bandyopadhyay, B.; Kuila, P.; Govil, M.C.; Bey, M. Delay-sensitive task offloading and efficient resource allocation in intelligent edge-cloud environments: A discretized differential evolution-based approach. Appl. Soft Comput. 2024, 159, 111637. [Google Scholar] [CrossRef] [Scilit]
- Li, J.J.; Chai, Z.Y.; Li, Y.L.; Zhou, Y.B. Reliable and efficient computation offloading for dependency-aware tasks in IIoT using evolutionary multi-objective optimization. Future Gener. Comput. Syst.-Int. J. Escience 2025, 174, 107923. [Google Scholar] [CrossRef] [Scilit]
- Liu, Z.F.; Lin, Z.W.; Zhang, Y.Z.; Chen, C.H.; Guo, J.Y.; Qi, B.B.; Tao, F. Joint Optimization of Computational Tasks Offloading for Efficient and Secure Manufacturing Through Cloud-Fog-Edge-Terminal Architecture. IEEE Trans. Emerg. Top. Comput. Intell. 2024, 1–15. [Google Scholar] [CrossRef] [Scilit]
- Laili, Y.; Gong, J.B.; Kong, Y.S.; Wang, F.; Ren, L.; Zhang, L. Communication Intensive Task Offloading With IDMZ for Secure Industrial Edge Computing. IEEE Trans. Cloud Comput. 2025, 13, 560–577. [Google Scholar] [CrossRef] [Scilit]
- Laili, Y.; Guo, F.Q.; Ren, L.; Li, X.; Li, Y.L.; Zhang, L. Parallel Scheduling of Large-Scale Tasks for Industrial Cloud-Edge Collaboration. IEEE Internet Things J. 2023, 10, 3231–3242. [Google Scholar] [CrossRef] [Scilit]
- AlShathri, S.I.; Chelloug, S.A.; Hassan, D.S.M. Parallel Meta-Heuristics for Solving Dynamic Offloading in Fog Computing. Mathematics 2022, 10, 1258. [Google Scholar] [CrossRef] [Scilit]
- Ji, X.F.; Gong, F.M.; Wang, N.L.; Du, C.Z.; Yuan, X.B. Task offloading with enhanced Deep Q-Networks for efficient industrial intelligent video analysis in edge-cloud collaboration. Adv. Eng. Inform. 2024, 62, 102599. [Google Scholar] [CrossRef] [Scilit]
- Tang, Z.Y.; Zeng, C.; Zeng, Y.L. Research on data security in industry 4.0 manufacturing industry against the background of privacy protection challenges. Int. J. Comput. Integr. Manuf. 2025, 38, 636–648. [Google Scholar] [CrossRef] [Scilit]
- Qi, Q.L.; Tao, F. A Smart Manufacturing Service System Based on Edge Computing, Fog Computing, and Cloud Computing. IEEE Access 2019, 7, 86769–86777. [Google Scholar] [CrossRef] [Scilit]
- Bukhari, M.M.; Ghazal, T.M.; Abbas, S.; Khan, M.A.; Farooq, U.; Wahbah, H.; Ahmad, M.; Adnan, K.M. An Intelligent Proposed Model for Task Offloading in Fog-Cloud Collaboration Using Logistics Regression. Comput. Intell. Neurosci. 2022, 2022, 3606068. [Google Scholar] [CrossRef] [Scilit]
- Pham, X.Q.; Man, N.D.; Tri, N.D.T.; Thai, N.Q.; Huh, E.N. A cost- and performance-effective approach for task scheduling based on collaboration between cloud and fog computing. Int. J. Distrib. Sens. Netw. 2017, 13, 155014771774207. [Google Scholar] [CrossRef] [Scilit]
- Kabeer, M.; Yusuf, I.; Sufi, N.A. Distributed software defined network-based fog to fog collaboration scheme. Parallel Comput. 2023, 117, 103040. [Google Scholar] [CrossRef] [Scilit]
- Mukherjee, M.; Kumar, S.; Mavromoustakis, C.X.; Mastorakis, G.; Matam, R.; Kumar, V.; Zhang, Q. Latency-Driven Parallel Task Data Offloading in Fog Computing Networks for Industrial Applications. IEEE Trans. Ind. Inform. 2020, 16, 6050–6058. [Google Scholar] [CrossRef] [Scilit]
- Adhikari, M.; Srirama, S.N.; Amgoth, T. Application Offloading Strategy for Hierarchical Fog Environment Through Swarm Optimization. IEEE Internet Things J. 2020, 7, 4317–4328. [Google Scholar] [CrossRef] [Scilit]
- Aazam, M.; Zeadally, S.; Harras, K.A. Deploying Fog Computing in Industrial Internet of Things and Industry 4.0. IEEE Trans. Ind. Inform. 2018, 14, 4674–4682. [Google Scholar] [CrossRef] [Scilit]
- Cui, L.Z.; Xu, C.; Yang, S.; Huang, J.Z.; Li, J.Q.; Wang, X.Z.; Ming, Z.; Lu, N. Joint Optimization of Energy Consumption and Latency in Mobile Edge Computing for Internet of Things. IEEE Internet Things J. 2019, 6, 4791–4803. [Google Scholar] [CrossRef] [Scilit]
- Cai, J.; Liu, W.; Huang, Z.W.; Yu, F.R. Task Decomposition and Hierarchical Scheduling for Collaborative Cloud-Edge-End Computing. IEEE Trans. Serv. Comput. 2024, 17, 4368–4382. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.P.; Zhang, P.; Wang, B.; Zhang, Z.F.; Xu, Y.L.; Lv, B. A hybrid PSO and GA algorithm with rescheduling for task offloading in device-edge-cloud collaborative computing. Clust. Comput.-J. Netw. Softw. Tools Appl. 2025, 28, 101. [Google Scholar] [CrossRef] [Scilit]
- Firmin, T.; Talbi, E.G. Massively parallel asynchronous fractal optimization. In Proceedings of the 2023 IEEE International Parallel and Distributed Processing Symposium Workshops (IPDPSW), St. Petersburg, FL, USA, 15–19 May 2023; pp. 930–938. [Google Scholar] [CrossRef] [Scilit]
- Zhang, X.Y.; Ming, X.G.; Bao, Y.G. A flexible smart manufacturing system in mass personalization manufacturing model based on multi-module-platform, multi-virtual-unit, and multi-production-line. Comput. Ind. Eng. 2022, 171, 108379. [Google Scholar] [CrossRef] [Scilit]
- Wang, J.; Li, D.; Hu, Y.M. Fog Nodes Deployment Based on Space-Time Characteristics in Smart Factory. IEEE Trans. Ind. Inform. 2021, 17, 3534–3543. [Google Scholar] [CrossRef] [Scilit]
- Lou, P.; Liu, S.Y.; Hu, J.M.; Li, R.Y.; Xiao, Z.; Yan, J.W. Intelligent Machine Tool Based on Edge-Cloud Collaboration. IEEE Access 2020, 8, 139953–139965. [Google Scholar] [CrossRef] [Scilit]
- Laili, Y.J.; Wang, X.H.; Zhang, L.; Ren, L. DSAC-configured Differential Evolution for Cloud-Edge-Device Collaborative Task Scheduling. IEEE Trans. Ind. Inform. 2024, 20, 1753–1763. [Google Scholar] [CrossRef] [Scilit]
- Lee, C.K.M.; Huo, Y.Z.; Zhang, S.Z.; Ng, K.K.H. Design of a Smart Manufacturing System With the Application of Multi-Access Edge Computing and Blockchain Technology. IEEE Access 2020, 8, 28659–28667. [Google Scholar] [CrossRef] [Scilit]
- Vaidya, S.; Jethava, G. Elevating manufacturing excellence with multilevel optimization in smart factory cloud computing using hybrid model. Clust. Comput.-J. Netw. Softw. Tools Appl. 2025, 28, 342. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).