


Highlights
What are the main findings?
- MFF-Net integrates multi-scale spatial and multi-frequency feature extraction with a fuzzy uncertainty fusion module to suppress system noise in SAR images and enhance flood detection.
- Compared with the existing methods, this model demonstrates superior performance in flood detection tasks across multiple SAR flood datasets and still achieves commendable results on diverse tasks and data sources.
What are the implications of the main findings?
- The multi-frequency, multi-scale attention mechanism uses wavelet transforms to refine frequency features, reducing SAR noise interference and improving pixel-level detection of subtle flood regions.
- Fuzzy decision-making in uncertainty fusion reduces system noise and enhances accurate identification of fine-grained flood areas.
Abstract
Synthetic Aperture Radar (SAR) images are highly valuable for detecting water surfaces characterized by low roughness and minimal microwave reflection, which makes them essential for flood detection. Despite these advantages, SAR imagery still faces inherent challenges, particularly systematic noise, which limits the accuracy of pixel-level flood detection and causes fine-grained flood areas to be easily overlooked. To tackle these challenges, this study proposes a novel flood detection algorithm, the multi-frequency fuzzy uncertainty fusion network (MFF-Net), which is built upon a multi-scale architecture. Particularly, the multi-frequency feature extraction module in MFF-Net extracts frequency features at different levels, which mitigate systematic noise in the SAR images and improve the accuracy of pixel-level flood detection. The fuzzy uncertainty fusion module further mitigates noise interference and more effectively detects subtle flood areas that may be overlooked. The combined effect of these modules significantly enhances the detection capability for fine-grained flood areas. Experiments validate the effectiveness of MFF-Net on SAR benchmarks, including the MMflood Dataset with 50.2% of IoU, the Sen1Floods11 Dataset with 45.07% of IoU, the ETCI 2021 Dataset with 44.35% and the SAR Poyang Lake Water Body Sample Dataset with 57.27% of IoU, respectively. In addition, it has also been tested on actual flood events.
1. Introduction
According to reports, flooding can pose a severe threat to public safety and property [1], thereby highlighting the importance of remote sensing-based flood detection, which is crucial for accurately detecting floods, enabling the rapid deployment of emergency response measures [2,3,4] as well as facilitating damage assessment for loss compensation. Currently, remote sensing technology has greatly enhanced the response capabilities of rescue teams in flood disasters, while also supporting the creation of flood maps for subsequent risk analysis [5,6,7]. However, challenges remain in identifying fine-grained flood areas in remote sensing images.
During extreme weather events such as heavy rainfall and flooding, persistent cloud cover and precipitation typically occur. Under these conditions, optical remote sensing imagery, which relies on solar reflectance for image formation, becomes significantly less effective. In contrast to optical sensors, synthetic aperture radar (SAR) systems generate images by actively transmitting microwave pulses and receiving backscattered signals from the ground surface. This unique operating principle enables SAR to acquire surface imagery regardless of weather conditions or daylight availability, making it particularly suitable for flood detection [8,9,10,11].
Previous flood detection in SAR imagery predominantly relied on conventional image processing techniques, which can be categorized into threshold-based [12,13,14,15] and hydrology-based [16,17,18]. The thresholding-based methods adopt per-pixel water or non-water classification according to a predetermined backscattering intensity threshold. The hydrology-based methods combine hydrological models and hydrodynamic models to calibrate model parameters, update initial conditions, or directly correct model predictions using SAR images, thereby improving the detection accuracy of flood regions. However, these methods have certain limitations. On the one hand, the threshold method relies on backscattering characteristics, and the system noise of SAR reduces the signal-to-noise ratio, thereby decreasing the detection accuracy for fine-grained flood features. On the other hand, hydrological models themselves contain uncertainties, including inaccurate parameter estimations and low-resolution input data, which can further compromise flood detection accuracy [19,20].
Recently, deep learning techniques have been widely applied to flood detection, achieving competitive performance in comparison to conventional methods. Li et al. [21] firstly introduced CNNs into SAR image flood detection. Following work made improvement via multi-scale representation [22,23,24] and attention mechanisms [25,26]. Multi-scale representation improves flood detection accuracy through feature pyramid structures, with multi-level fusion effectively reducing noise across scales. The attention mechanism enhances feature discrimination via dynamic channel–spatial weighting, suppressing noise. Researchers also explored the fusion of SAR data with optical imagery to improve both the accuracy and timeliness of flood detection. While optical imagery provides high-resolution details, SAR data offers all-weather monitoring capabilities. The complementary nature of these two data sources enhances the overall performance of flood detection [27,28]. In addition, some studies demonstrated significant improvements in flood detection accuracy by utilizing dual-polarized SAR data [29], while other research focused on enhancing the accuracy of multi-temporal SAR data through temporal feature representation and change enhancement mechanisms [30]. Moreover, the scarcity of visual information coupled with similar backscatter signals from non-flood surfaces, e.g., soils and urban shadows, may lead to false alarms, consequently making fine-grained flood areas more prone to being overlooked. Although deep learning techniques have achieved remarkable accomplishments, certain challenges still persist that can affect flood detection accuracy. Specifically, systematic noise in SAR images reduces pixel-level classification precision, while the scarcity of visual information coupled with similar backscatter signals from non-flood surfaces such as smooth soils and urban shadows leads to false alarms, consequently making fine-grained flood areas more prone to being overlooked.
At the same time, remote sensing image segmentation has achieved more significant progress compared to flood detection in SAR images. For instance, Zhang et al. [31] combined ViTs with CNNs to overcome CNNs’ limited receptive fields. Li et al. [32] introduced lightweight attention modules for efficient segmentation, while Li et al. [33] enhanced building segmentation accuracy through optimized feature fusion. For small-area segmentation tasks, researchers often employ efficient YOLO series models [34,35,36,37]. In addition, some researchers have begun to attempt to introduce LLMs (large language models) into remote sensing segmentation. For example, Zhang et al. [38] integrated CLIP with semantic segmentation networks, leveraging text prompts to boost performance. Similarly, Wu et al. [39] employed vision–language models on farmland segmentation, achieving higher accuracy using image–text paired datasets. Although these studies have demonstrated the potential of LLMs in remote sensing segmentation, the characteristics of high training costs and poor interpretability of LLMs themselves will still limit their wide application in the field of remote sensing.
Inspired by remote sensing image segmentation, we propose MFF-Net, a novel multi-scale SAR image flood detection network that incorporates multi-frequency and fuzzy uncertainty fusion. MFF-Net employs a multi-scale architecture with three key modules. The multi-scale feature extraction module uses a feature pyramid to capture spatial features, while the multi-frequency feature extraction module applies a multi-frequency in multi-scale attention mechanism block to extract frequency features, thereby enhancing the accuracy of pixel-level flood detection. Building upon this foundation, the fuzzy decision in the fuzzy uncertainty fusion module effectively detects subtle flood areas that may otherwise be overlooked. Overall, the use of the multi-frequency feature extraction module and the fuzzy uncertainty fusion module effectively suppresses system noise interference and enhances the detection of fine-grained flood areas. The proposed method outperforms existing flood detecting algorithms on the MMflood Dataset, the Sen1Floods11 Dataset, the ETCI 2021 Dataset, and the SAR Poyang Lake Water Body Sample Dataset. In summary, the contributions of this paper are as follows.
- We propose MFF-Net, which is composed of multi-scale spatial feature extraction, multi-frequency feature extraction, and fuzzy uncertainty fusion. It is designed to suppress systematic noise interference in SAR images and enhance the detection of fine-grained flood areas.
- In the multi-frequency feature extraction module, we introduce a multi-frequency in multi-scale attention mechanism that refines frequency features through multi-level wavelet transforms, mitigating the influence of systematic noise and enhancing the accuracy of pixel-level flood detection.
- We introduce uncertainty fusion into flood detection. Specifically, we integrate fuzzy decision into the uncertainty fusion, which can further mitigate systematic noise, enhancing the capability of identifying subtle flood areas.
2. Methodology
2.1. Overview
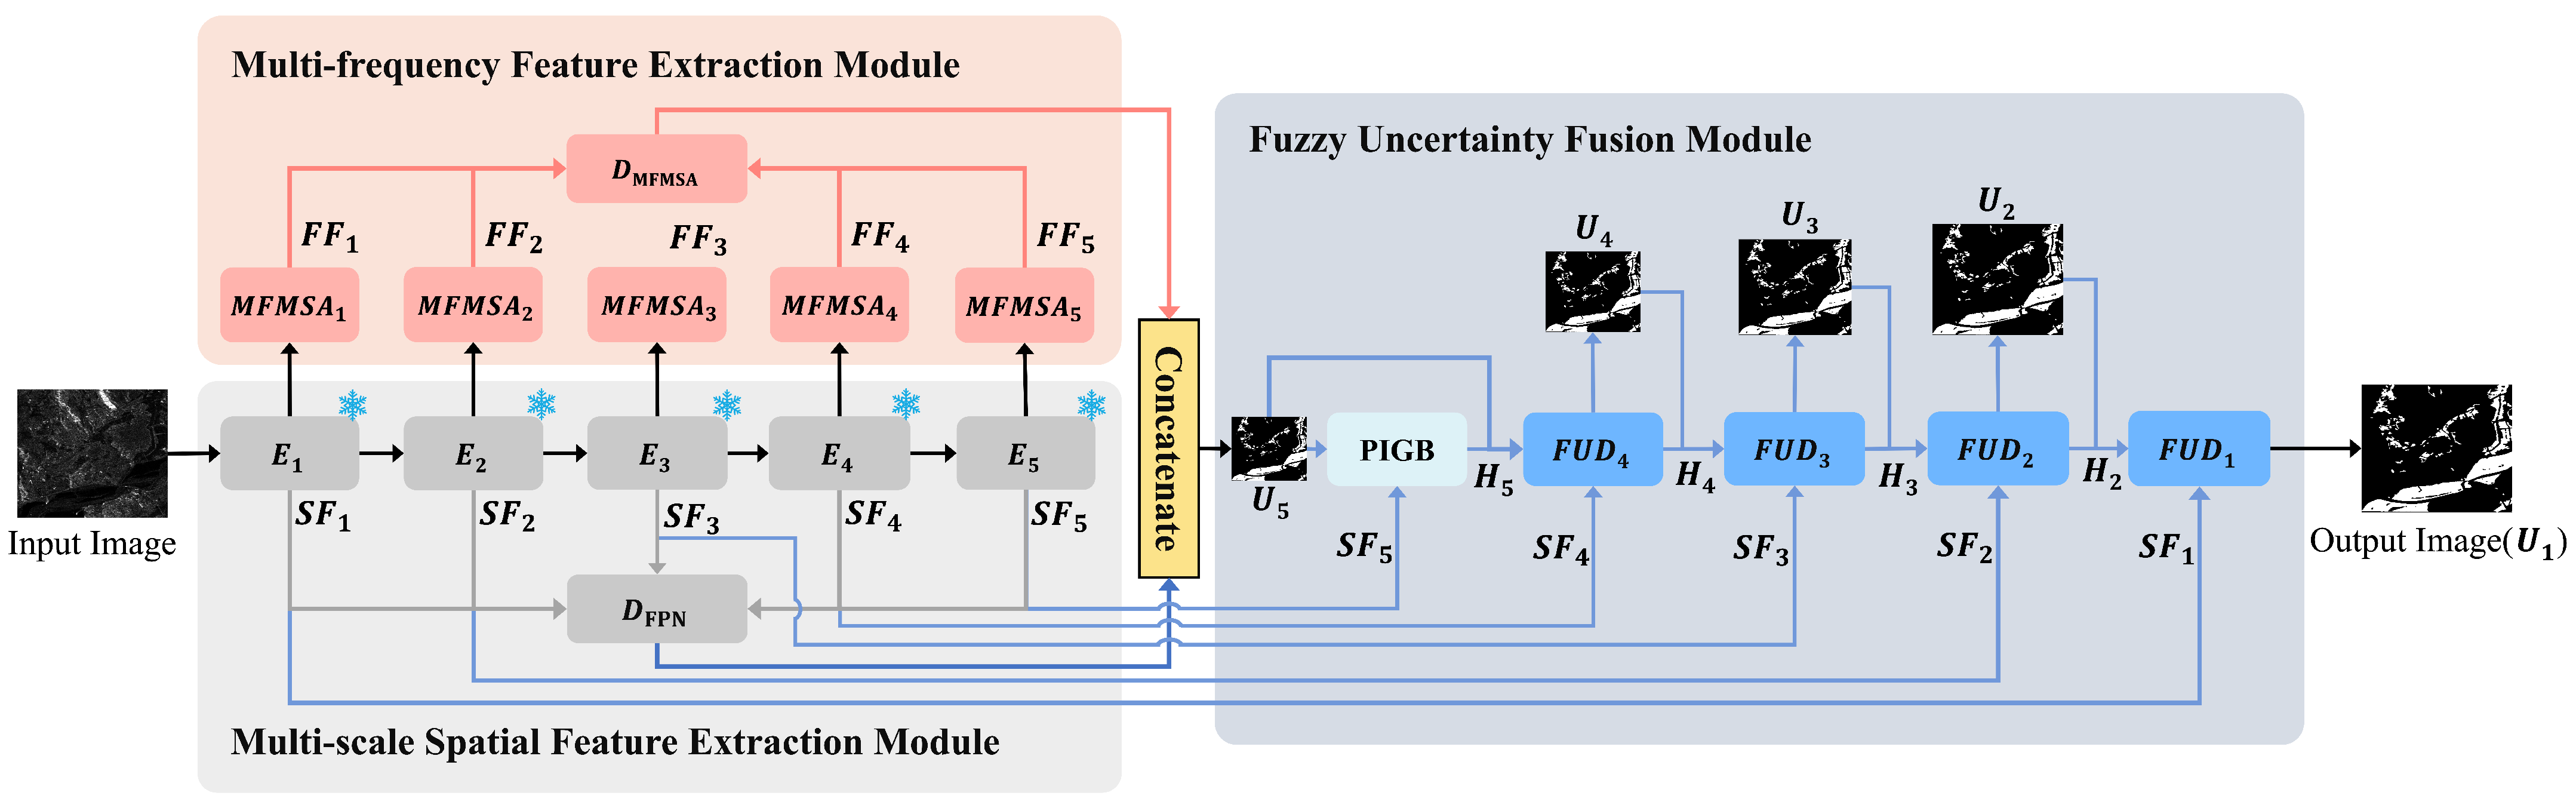
The framework of our proposed MFF-Net is shown in Figure 1. The network consists of three main components: the multi-scale spatial feature extraction module, the multi-frequency feature extraction module, and the fuzzy uncertainty fusion module. Building on this, we adopt an FPN-like architecture for the encoder , designed to extract pyramid-shaped spatial features, which not only aggregate multi-scale spatial features but also support the fuzzy uncertainty fusion module, enhancing the model’s capability to handle complex spatial relationships. In our multi-frequency feature extraction module, we designed multi-frequency in multi-scale attention mechanism blocks (MFMSA), denoted as . These blocks perform multi-level wavelet transformations on the feature maps extracted at different scales by , yielding a comprehensive multi-frequency feature representation. Additionally, we design a fuzzy uncertainty fusion module that receives the aggregated multi-scale spatial and frequency domain features, processes them through cascaded fuzzy uncertainty decision blocks (FUD), denoted as , and ultimately generates the flood detection results. The following sections provide a detailed description of these three modules.
Figure 1.
The framework of the proposed MFF-Net, which comprises three main modules, i.e., multi-scale spatial feature extraction module, multi-frequency feature extraction module, and Fuzzy Uncertainty Fusion Module. Specifically, snowflakes denote the frozen backbone encoder, whose parameters remain fixed during training. represents the backbone module employed for feature extraction, represents the enhanced spatial-domain features, corresponds to the frequency-domain features, denotes the extracted uncertainty map, and represents the enhanced features within the fuzzy uncertainty fusion module. The Prior Information Guidance Block (PIGB) leverages the initial uncertain extraction map as prior knowledge to enhance the highest-level features in both spatial and channel dimensions, thereby improving segmentation accuracy.
2.2. Multi-Scale Spatial Feature Extraction Module
For a given SAR image containing flood areas, a generic encoder–decoder network is first employed to derive a comprehensive multi-scale feature representation. In practice, we employ Res2Net-50 [40] as the backbone encoder, since it can reduce systematic noise effects on SAR feature extraction, meanwhile alleviating gradient vanishing due to the residual connection [41]. The detailed performance of different backbones is shown in Table 9. Specifically, a 5-scale Res2Net-50 is adopted, where each level is denoted as :
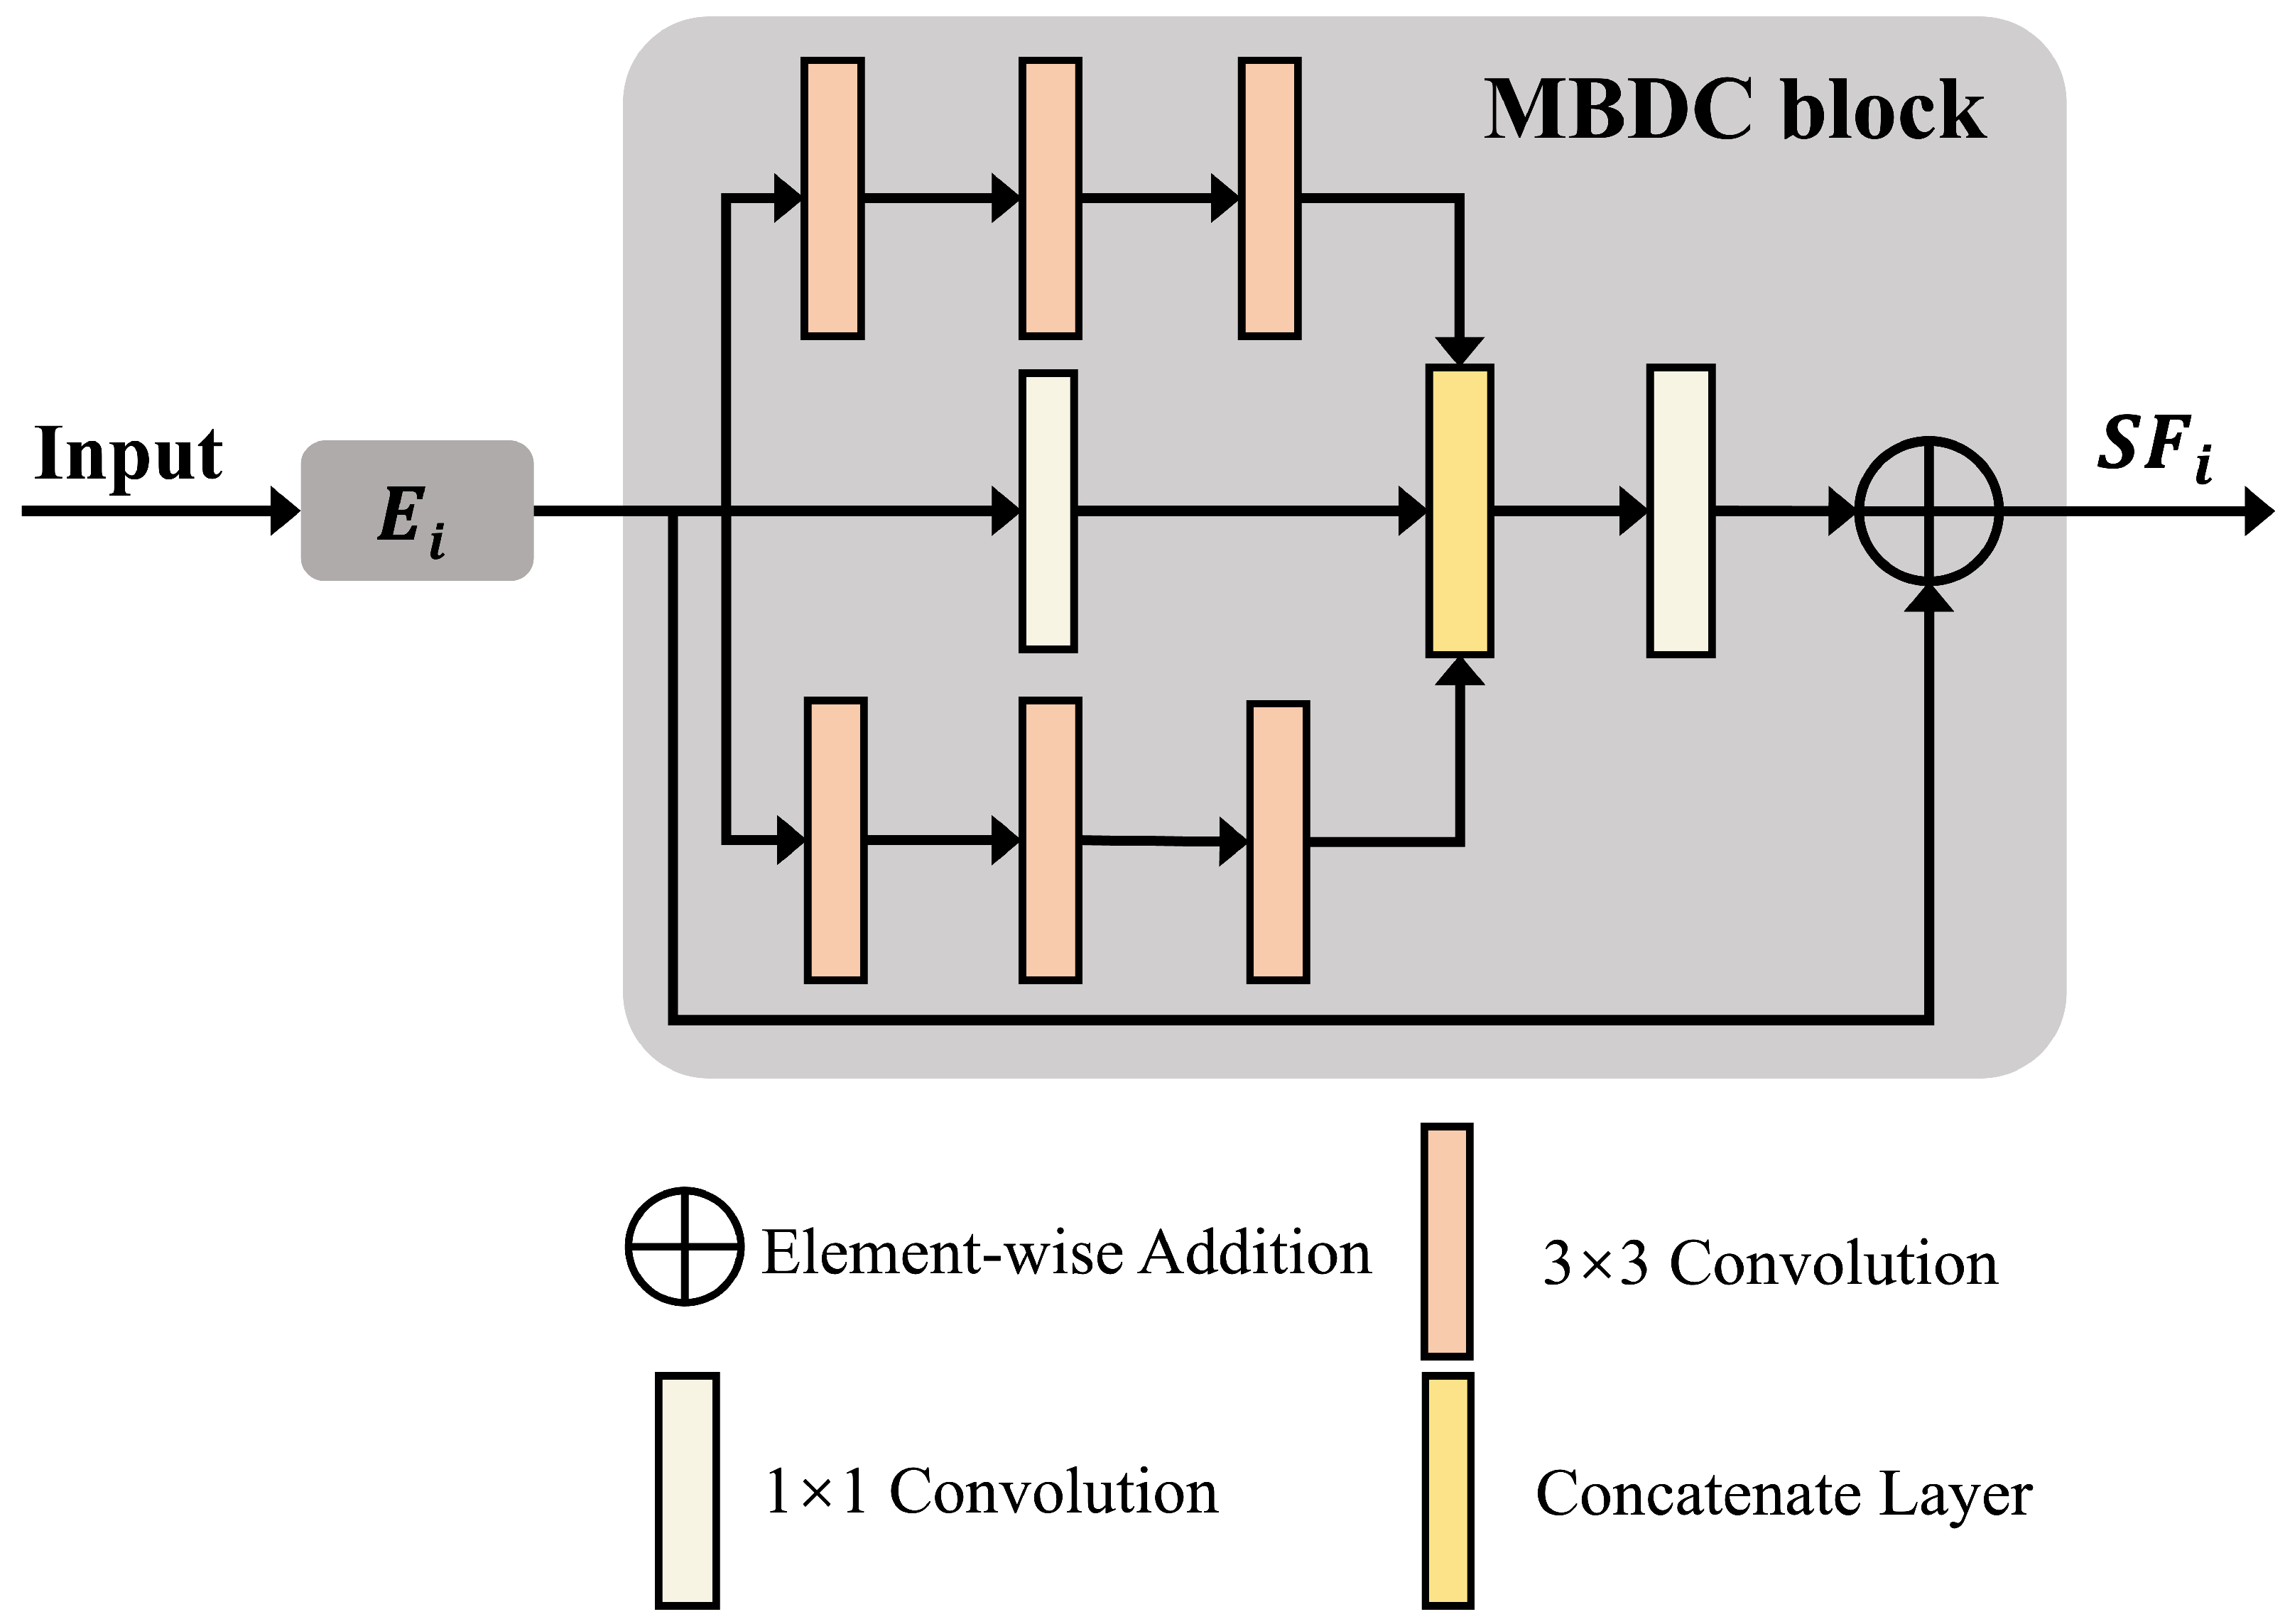
Inspired by previous research [33], we apply a multi-branch dilation convolution (MBDC) block adhering to each encoder to further enhance the extracted features. The detailed implementation of the MBDC block is shown in Figure 2. Based on these, we get the final multi-scale spatial feature
where corresponds to the 5-scales.
Figure 2.
The detail of the multi-branch dilation convolution (MBDC) block, which is adhering to each encoder .
To mitigate the potential loss of spatial information resulting from excessive reliance on frequency-domain features, a classical multi-scale feature pyramid (FPN) is integrated into the spatial domain. The output is denoted as
which is then concatenated with the extracted frequency feature later. This integration allows for the extraction of richer multi-scale spatial feature representations, preserving fine-grained details while enhancing high-level semantic information.
2.3. Multi-Frequency Feature Extraction Module
For the SAR images, water bodies typically generate low-frequency signals owing to the smooth, specular reflections from the water surface, whereas other land features, such as rugged terrain and vegetation, produce higher-frequency signals as additional noise due to more intricate scattering mechanisms [42]. Although previous works have considered incorporating frequency features in remote sensing segmentation [43], they have not fully leveraged frequency domain information.
In this paper, we hypothesized that refining high-frequency features in the frequency domain can preserve as many details as possible, thereby enabling a more effective distinction between water bodies and non-water regions. Specifically, we design a multi-frequency in multi-scale attention mechanism (MFMSA) to fully distinguish the high frequency from the low frequency.
The whole multi-frequency feature extraction module is denoted as
where .
For each of the extracted multi-scale spatial features , it is first sent to the MFMSA block , obtaining the multi-frequency feature, denoted as
and then integrated through a decoder . The final extracted multi-frequency feature is formulated as
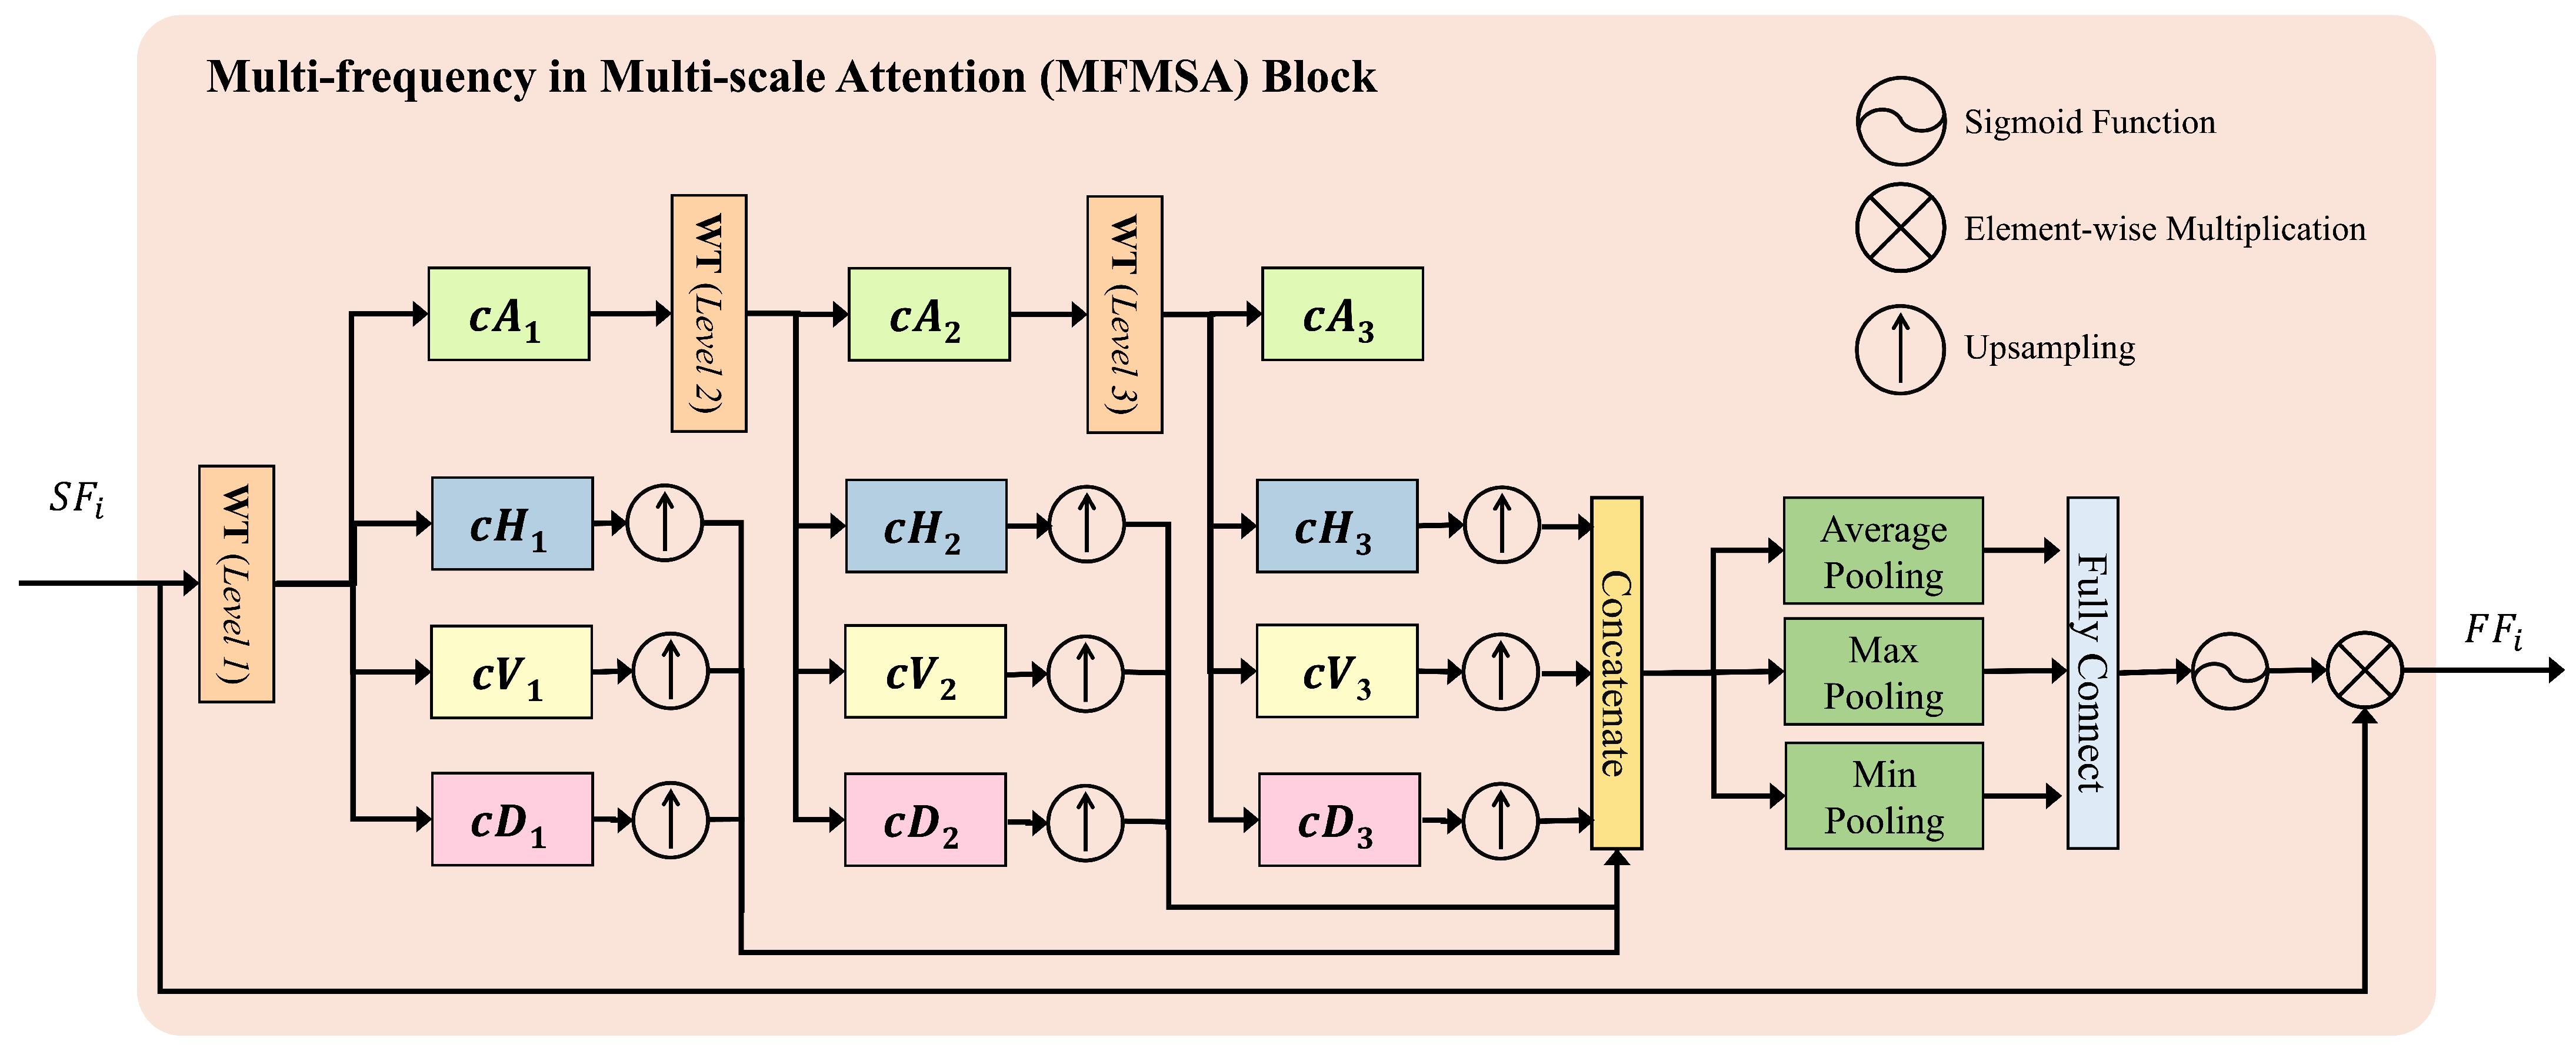
The detailed MFMSA block is illustrated in Figure 3. Particularly, it employs a three-level cascaded Wavelet Transform, applying Wavelet transformations to the low-frequency components in a cascaded manner to fully utilize frequency information and extract as much high-frequency information as possible.
Figure 3.
The structural diagram of the multi-frequency in multi-scale attention mechanism (MFMSA) block in which we illustrates the process. , , , and represent the low-frequency detail coefficients, the horizontal high-frequency detail coefficients, the vertical high-frequency detail coefficients, and the diagonal high-frequency detail coefficients generated by each layer of wavelet transformation, respectively.
The wavelet transform decomposes the features into distinct frequency components, including the low-frequency detail coefficients , the horizontal high-frequency detail coefficients , the vertical high-frequency detail coefficients , and the diagonal high-frequency detail coefficients , denoted as:
where X is the input, and indicates the wavelet basis, where
Note that the Level-1 wavelet transform captures the global high-frequency features, while the Level-2 and Level-3 progressively refine the high-frequency features from the low-frequency components, i.e., and . By doing so, it can fully extract details from the low-frequency components, thereby mitigating the impact of systematic noise in the raw SAR images.
To ensure consistency, we upsample the , , and coefficients to the same size and concatenate them along the channel dimension, enabling a holistic feature representation:
where is the result after upsampling and concatenation.
We then apply average pooling, max pooling, and min pooling to refine and aggregate the . The aggregated features are then passed through fully connected layers to achieve seamless integration. Finally, we generate a composite attention map, which highlights the most salient feature regions. The attention map is multiplied by the , resulting in a weighted output, which yields the frequency-domain features . The architecture of the Decoder is similar to , which generates the final frequency-domain feature .
Finally, the extracted multi-scale spatial feature and the multi-frequency feature are concatenated and sent to the fuzzy uncertainty fusion module .
2.4. Fuzzy Uncertainty Fusion Module
In multi-scale feature processing, low-scale features contain rich detail and background information, which help capture subtle changes but are prone to noise interference. In contrast, high-scale features focus on extracting the main structures and large-scale variations of the foreground, effectively highlighting prominent characteristics but with weaker capacity for fine detail capture [44]. To address this, we introduce a fuzzy uncertainty fusion module to further distinguish the foreground and the background. Particularly, the proposed fuzzy uncertainty decision (FUD) block cannot only preserve the details of low-scale features but also mitigate noise interference in foreground recognition and enhance the performance of high-scale features. Moreover, we utilize the fuzzy decision to effectively capture overlooked subtle flood areas.
As shown in Figure 1, the proposed fuzzy uncertainty fusion module accepts the multi-scale uncertainty map and the extracted spatial feature as inputs. Note that is constructed from the multi-scale spatial feature and the multi-frequency feature . A Prior Information Guidance Block (PIGB) is then utilized to generate the initial feature map . Specifically, it utilizes the prior information from both and . Then, we successively set four fuzzy uncertainty decision (FUD) blocks to reconstruct the detection results progressively. The overall fuzzy uncertainty fusion module can thus be formulated as
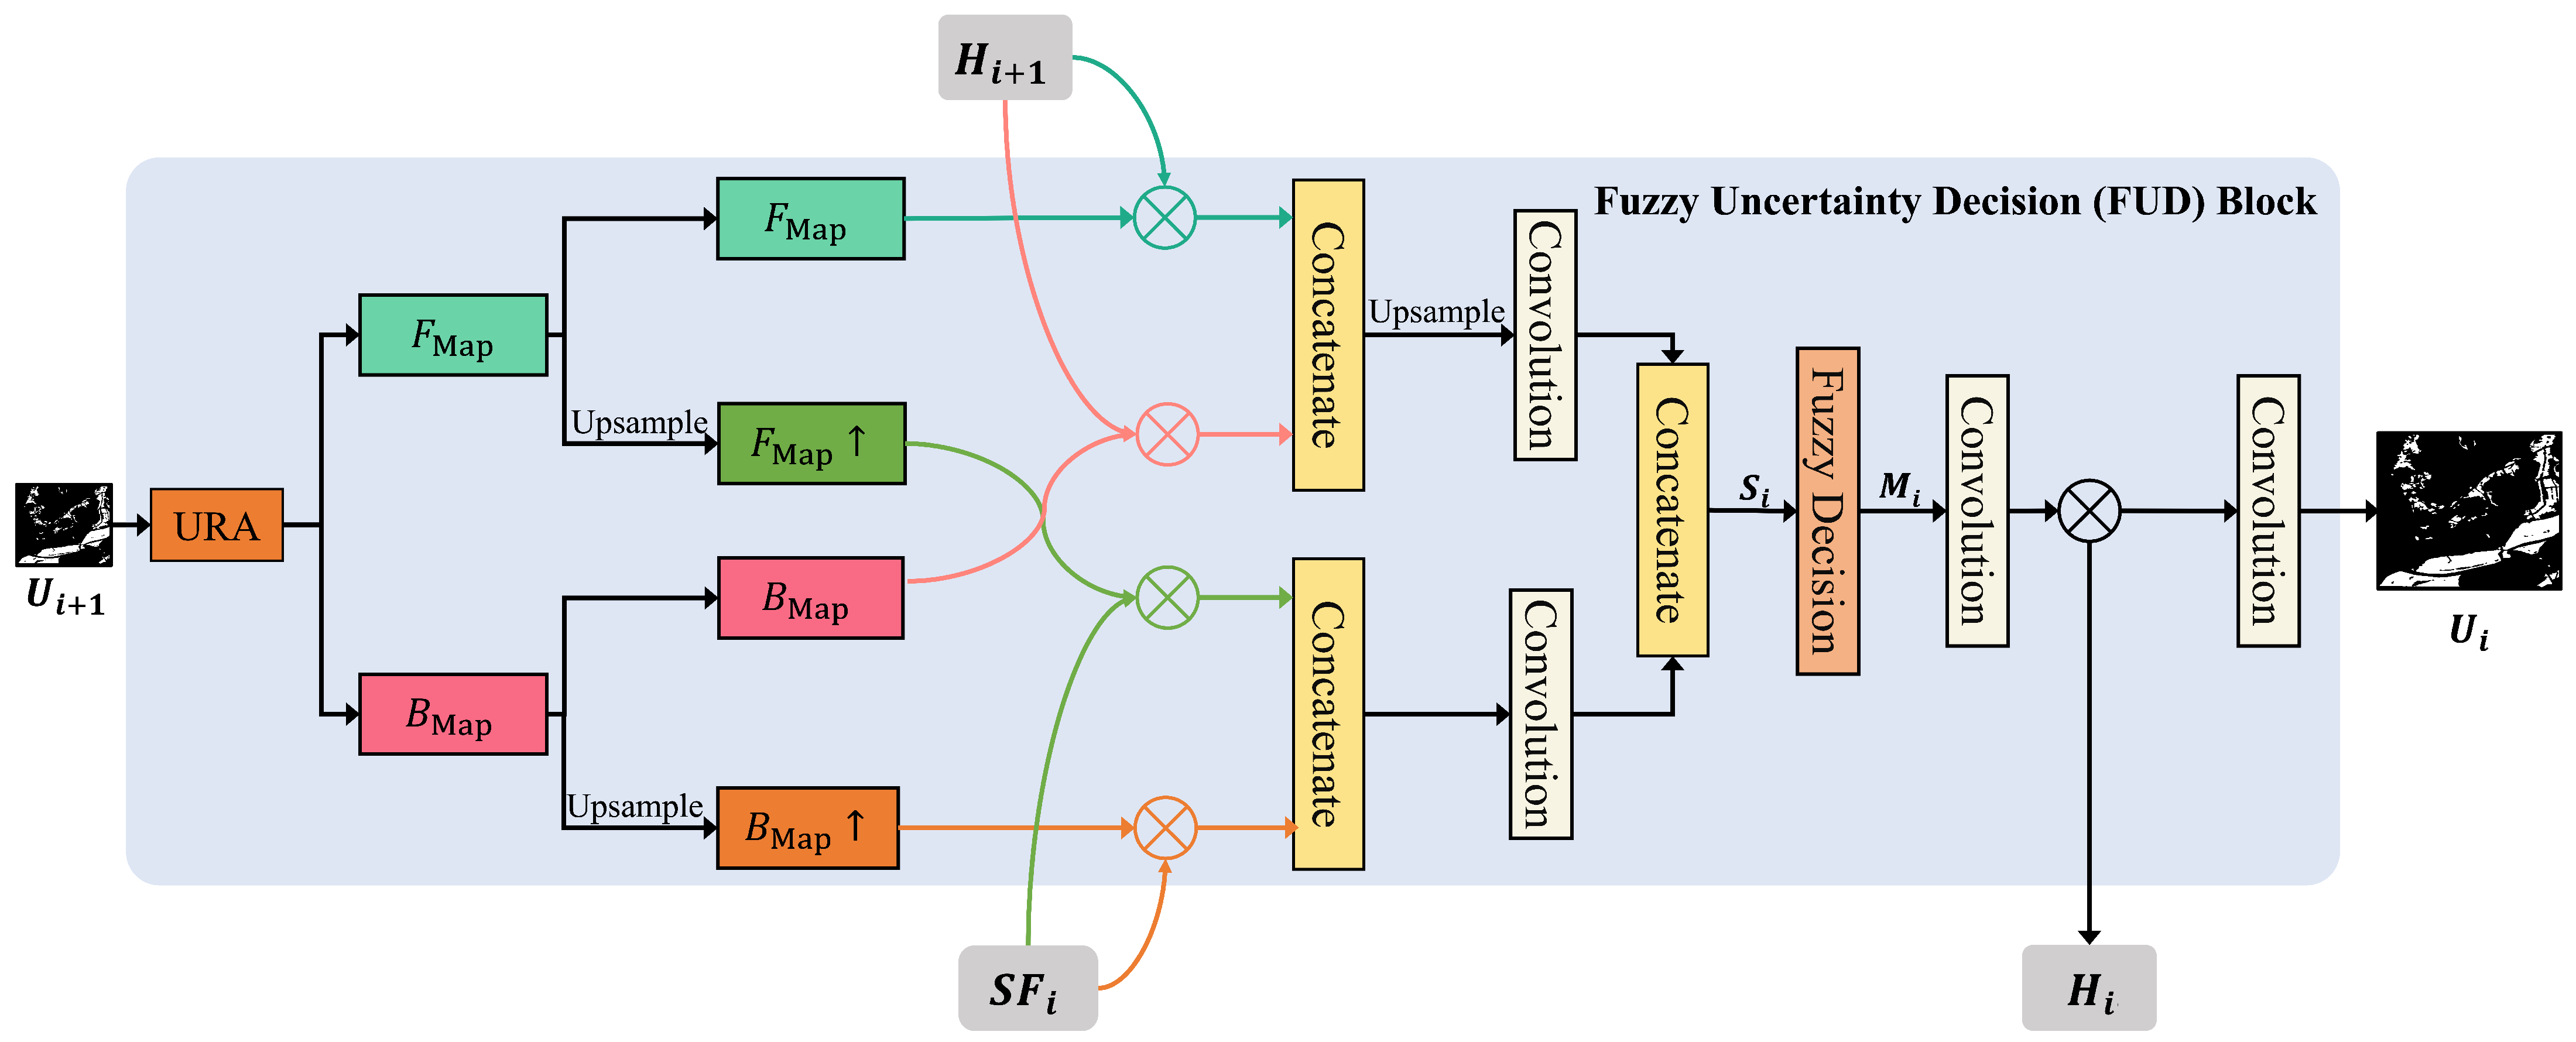
The structure of the proposed fuzzy uncertainty decision (FUD) block is further illustrated in Figure 4. Here, we use the descended subscripts to match the multi-scale backbone. For the ith FUD block, it accepts the feature map and the uncertainty map from the previous FUD block, as well as the spatial feature . Note that the uncertainty map serves as the final output image. The whole procedure of the FUD block can be denoted as
Figure 4.
The structural diagram of the fuzzy uncertainty decision (FUD) block presented here illustrates the overall process. and represents the feature map after upsampling. Ui represents the uncertainty map, Hi represents the enhanced features.
The input is firstly processed by the Uncertainty Ranking Algorithm (URA) to produce two uncertainty maps, i.e., and , which indicate the rough prediction of the foreground and the background, respectively. The process can be formulated as
where W quantifies pixel-wise ambiguity based on the deviation of the sigmoid output from 0.5, the larger W values correspond to higher uncertainty and smaller ones correspond to lower uncertainty. The W can be formulated as
Each of the uncertainty maps is further upsampled to obtain a multi-scale representation. For the foreground component, we multiply with , while multiplying with . The background component follows a similar way. The outputs are then concatenated separately and sent through a series of convolution layers, gaining a fused representation . Note that an upsampling operation is implemented upon the upper branch to align the resolution. Then, it is sent to a fuzzy decision layer and finally produces the feature map and the uncertainty map , respectively.
We specifically utilize the fuzzy decision to distinguish between foreground and background by judging per-pixel values in comparison with a preset threshold. The pixel whose value is greater than the threshold is classified as foreground; vice versa. The process of the fuzzy decision can be formulated as
where is the fuzzy mask, T is the predefined threshold.
Having observed that the low-level feature map emphasizes larger perceived fields and prominent foreground structures, while the high-level feature map captures details and fine-grained patterns, we set the thresholds as a step function form:
where is the initial threshold for the highest layer, and represents the decrement applied to the threshold at each subsequent layer. Note that a higher value would lead to suppression of high-level features, resulting in the loss of semantic information and failure to detect large-scale targets. Otherwise, a lower value would induce noise or irrelevant features. Meanwhile, a higher value would cause a rapid decay of the threshold, failing to filter our system noises. In contrast, a lower value would prevent the decay of the threshold, cause suppression of low-level details, and result in missing detection of subtle flood areas. In practice, we set = 0.4, = 0.1 to rebalance different feature levels for an optimal performance.
2.5. Loss Function
Recognizing that fine-grained flood areas are less prevalent than large-scale ones in flood images, we enhance flood area detection by combining cross-entropy loss and Dice loss [45]. Cross-entropy loss quantifies classification errors at the pixel level, improving overall detection accuracy, which is formulated as
where N is the total number of samples, C is the total number of classes, denotes the true label of the ith sample for the cth class, and is the probability that the model predicts the ith sample belongs to the cth class.
The Dice loss measures the overlap between the predicted area and the ground truth, enhancing the model’s sensitivity to boundary areas while specifically optimizing the detection of fine-grained flood areas. It effectively compensates for the cross-entropy loss’s insensitivity to fine-grained flood areas:
where the is a small constant introduced to prevent the denominator from becoming zero.
In summary, the total loss during the training process can be expressed as follows:
where , are the weighting coefficients that control the effect of pixel-wise classification and regional feature coherence. In practice, we set = 1, = 1 to make a balance between the per-pixel noise suppression and regional shape preservation.
3. Experiment
3.1. Dataset
The SAR images used for flood detection are sourced from the publicly available MMflood Dataset [46], Sen1Floods11 Dataset [47], and ETCI 2021 Dataset [48], while the SAR Poyang Lake Water Body Sample Dataset [49] is employed for water body detection.
The MMflood Dataset is a comprehensive collection specifically designed for flood mapping and detection, derived from dual-polarization Sentinel-1 SAR imagery (VV and VH polarization) acquired through the European Space Agency (ESA)’s Copernicus program. It covers 95 flood events from 42 countries between 2014 and 2021, representing a variety of scenarios and environmental conditions. The SAR images are stored in linear format. It includes a total of 1748 pairs of Sentinel-1 SAR images, providing a solid foundation for flood detection research. Following preprocessing, the dataset is divided into 6181 pairs for training, 559 pairs for validation, and 231 pairs for testing.
The Sen1Floods11 Dataset offers terrain-corrected Sentinel-1 SAR imagery with dual-polarization VV and VH at 10-m spatial resolution, along with expert-validated floodwater masks. The dataset comprises 431 annotated image–label pairs, where each sample is a 512-by-512-pixel tile designed for flood mapping applications. The SAR images are stored in decibel (dB) format. This data is systematically split into three subsets: 252 images for training, 89 for validation, and 90 for testing.
The ETCI 2021 Dataset is derived from the ESA Sentinel-1 synthetic aperture radar (SAR) imagery. It comprises images collected from various geographical regions, including Bangladesh, North Alabama, and Nebraska. Each image pair consists of two polarization channels, VV and VH, which are combined into a three-channel RGB composite following the ESA Polarimetry Guidelines. The dataset is divided into 25,359 pairs for training, 1777 pairs for validation, and 2093 pairs for testing.
The SAR Poyang Lake Water Body Sample Dataset, created by the Chinese Academy of Cultural Heritage, is derived from ESA’s Sentinel-1 SAR data. The selected coverage area corresponds to the Poyang Lake region (115.449–116.979°E, 28.384–29.867°N), with data acquired in August 2021 and November 2021. The downloaded SAR data was radiometrically calibrated and geometrically corrected using the SNAP software (version 11.0.0) provided by ESA. The SAR images are stored in linear format. It contains 1000 SAR image tiles of 256 × 256 pixels and corresponding 1000 label images, with 700 images used for the training set, 100 for the validation set, and 200 for the test set.
Note that the train/validation/test split is based on flood events to prevent possible information leakage.
3.2. Experiment Configuration
All experiments were conducted on an NVIDIA GeForce RTX 3090 GPU with 24 GB of memory using PyTorch 1.12.0 (CUDA 11.8). During training, the Adam optimizer was employed to ensure stable and effective model optimization, and random horizontal and vertical flipping was applied for data augmentation. For the MMflood dataset, where image resolutions vary across samples, and the Sen1Floods11 dataset with a fixed resolution of , a learning rate of and a batch size of were conservatively adopted, and the models were trained for more than 100 epochs. For the ETCI 2021 dataset and the SAR Poyang Lake Water Body Sample Dataset, where all images have a resolution of , the learning rate was also set to , the batch size to , and training was performed for more than 100 epochs.
3.3. Metrics
To comprehensively evaluate the performance of our proposed model, we employ five key metrics: Intersection over Union (IoU), F1-Score (F1), precision, recall, and Overall Accuracy (OA). These metrics are calculated using True Positives (TP), False Positives (FP), False Negatives (FN), and True Negatives (TN), ensuring a thorough assessment of both the model’s accuracy and reliability. Higher values of these metrics indicate superior performance. Precision and recall focus on the model’s ability to correctly identify positive instances, while the F1-Score balances these two metrics. IoU evaluates the overlap between predicted and ground truth areas, and OA provides an overall view of classification accuracy, considering both positive and negative instances. All the evaluation metrics are formulated as follows:
Note that, for all datasets, the same evaluation protocol is followed. During training, raw Sentinel-1 SAR images together with their corresponding ground-truth masks are used as input to learn flood delineation. During testing, only the SAR images are provided as input to generate flood detection results. Each model is trained on the training set and tuned using the validation set. The final trained model is then applied to the test set to generate flood prediction maps, which are quantitatively compared with the corresponding ground-truth masks in the test set. Model performance is evaluated using IoU, F1-Score, Overall Accuracy (OA), precision, and recall. The same data splits and evaluation metrics are adopted for both the proposed method and all benchmark approaches to ensure a fair comparison.
3.4. Performance Comparison on SAR Flood Detection Datasets
To effectively highlight the advantages of our proposed method, we conducted an extensive comparison with 11 well-established area detection techniques, including Decision Tree, K-Means, FCN-8s [50], FCN-32s [50], SegNet [51], SCAttNet [32], YOLOv8 [34], YOLOv9 [37], YOLOv11 [36], ConvLSR-Net [31], and UANet [33]. All methods were re-trained and evaluated under a unified protocol. Hyperparameters for machine learning methods were set based on dataset size and computational resources, while deep learning baselines followed the settings reported in their original publications. Identical data splits and evaluation metrics were used for all methods.
3.4.1. Performance Comparison on MMflood Dataset
The results of all methods on the MMflood Dataset are presented in Table 1. The bold numbers indicate the best results, while underlined numbers denote the second-best results. The flood events shown correspond to the Guyana flood, the Togo flood, and the flood in south-eastern France, respectively. We can see from the table that our proposed MFF-Net outperforms other models on most metrics, showcasing significant advantages in detection performance. Specifically, its IoU reaches 50.2%, which raises 8.18% from YOLOv9 (42.02%), the second-best model. In terms of F1-score, MFF-Net achieves 62.09%, substantially surpassing YOLOv9’s 50.86%, highlighting its superior balance between precision and recall. The inferior performance of Decision Tree and K-Means originates from their limited capacity to capture complex spatial features in flood imagery, in contrast to deep learning models that typically learn features through hierarchical representation levels. Moreover, MFF-Net achieves the higher precision (68.02%) and recall (65.15%) values, which indicate that MFF-Net effectively reduces missed detections while providing more comprehensive coverage of flood regions. These results validate that MFF-Net not only excels in detection accuracy but also exhibits enhanced stability and reliability, offering robust support for fine-grained flood area identification.
Table 1.
Performance comparison on the MMflood Dataset.
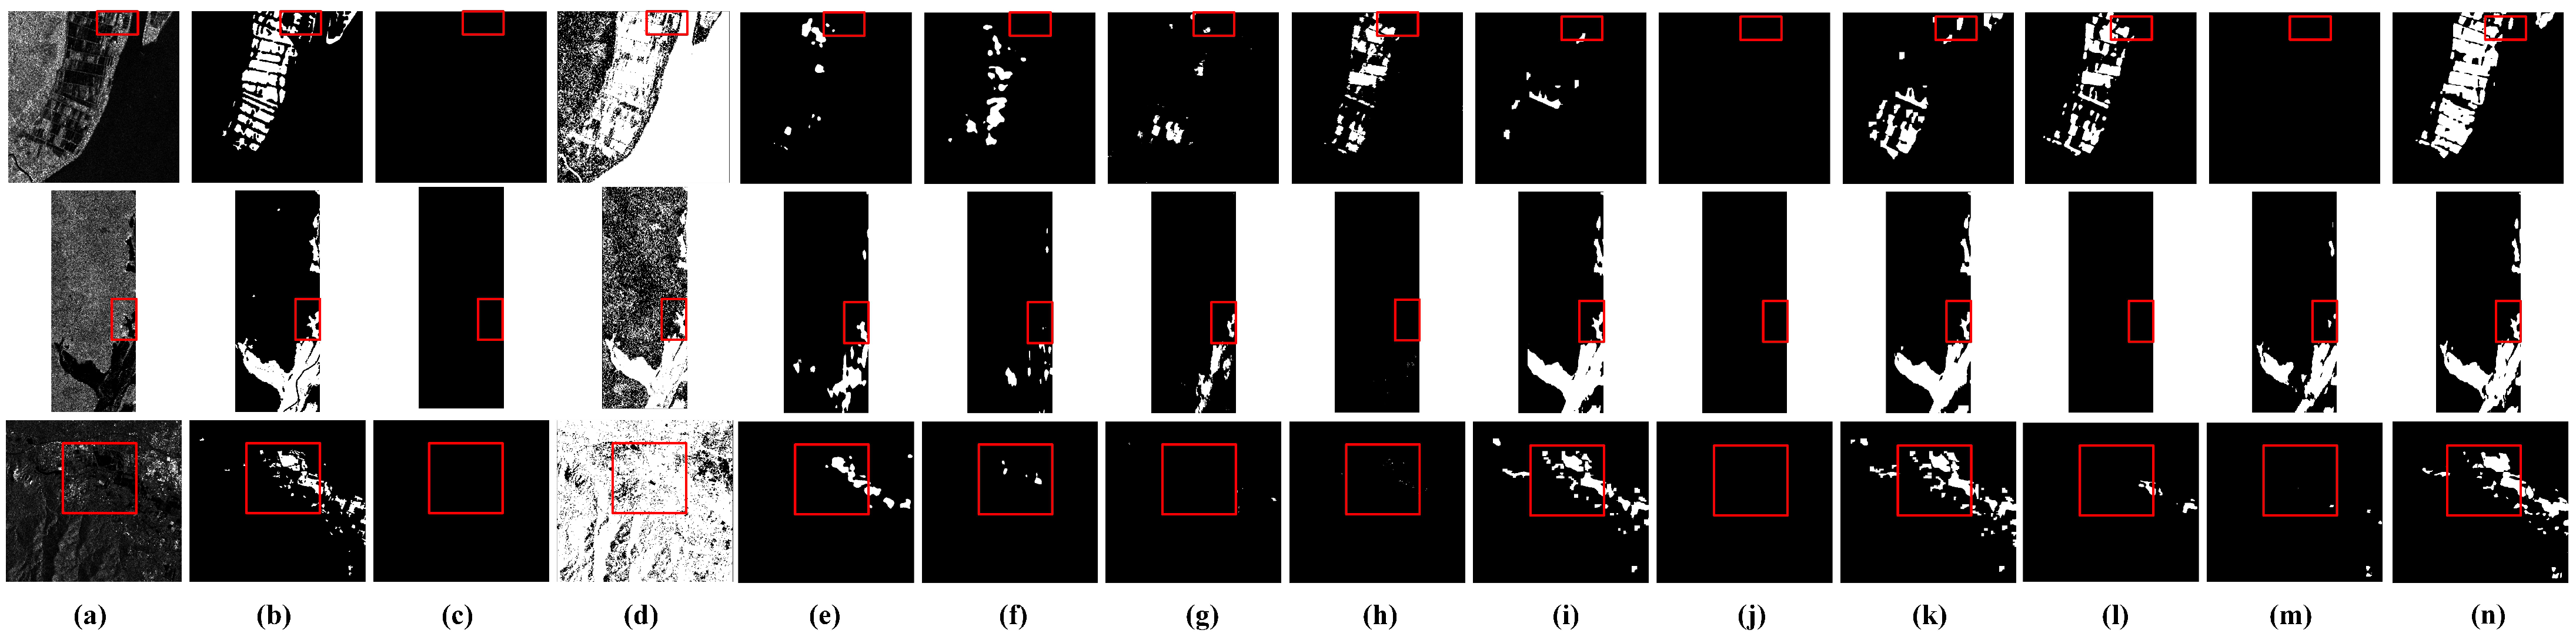
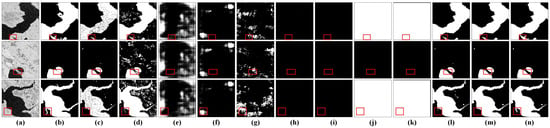
Figure 5 further presents the visualization results of various methods on the MMflood Dataset. The white areas correspond to the flood areas, while the black areas denote the background. Take the first row as an example, Decision Tree, K-Means, FCN-8s, FCN-32s, SegNet, the YOLO series, and UANet fail to accurately identify the flood areas. In contrast, MFF-Net demonstrates significantly better performance, detecting flood regions that closely correspond to the ground truth and outperforming SCAttNet and ConvLSR-Net. For the second row, Decision Tree, K-Means, FCN-8s, FCN-32s, SegNet, SCAttNet, YOLOv9, and ConvLSR-Net struggle to effectively recognize the flooded regions. Moreover, YOLOv8 and YOLOv11 tend to over-identify flood areas. However, ours exhibits a markedly superior ability to detect fine-grained flood areas. We can see from the highlighted red box that our method can better retain the subtle regions.
Figure 5.
The visualization results on the MMflood Dataset. (a) SAR Images. (b) GT. (c) Decision Tree. (d) K-Means. (e) FCN-8s. (f) FCN-32s. (g) SegNet. (h) SCAttNet. (i) YOLOv8. (j) YOLOv9. (k) YOLOv11. (l) ConvLSR-Net. (m) UANet. (n) MFF-Net (Ours). The red box highlights the region of special interest.
3.4.2. Performance Comparison on the Sen1Floods11 Dataset
The results of all methods on the Sen1Floods11 Dataset are presented in Table 2. The bold numbers indicate the best results, while underlined numbers denote the second-best results. We selected two flood events from different regions in Paraguay and one flood event in Sri Lanka. The results demonstrate that the MFF-Net model performs better in all evaluation metrics compared to other models. In particular, it achieves an IoU of 45.07%, representing an improvement of 1.11 percentage points over UANet’s 43.96%, while its leading F1-Score of 57.73% reflects an optimal balance between precision and recall in flood detection tasks. Note that K-Means has achieved a significant improvement in this dataset. We attribute this to the fact that the size of the Sen1Floods11 Dataset is much smaller than that of the MMflood Dataset. K-Means has a lower dependence on the size of the training data, and the flood areas in Sen1Floods11 are more continuous compared to MMflood. Therefore, better results can be achieved on the smaller Sen1Floods11 Dataset. SCAttNet is insufficient to optimize the attention mechanism in the smaller Sen1Floods11 Dataset. Compared to YOLOv9, YOLOv8, and YOLOv11, YOLOv9 focuses on high-precision segmentation of small objects and has difficulty optimizing local boundaries and global continuity in the fewer Sen1Floods11 datasets, resulting in unsatisfactory results.
Table 2.
Performance on the Sen1Floods11 Dataset.
The visualization results are presented in Figure 6, where the white areas correspond to the identified areas, and the black areas represent the background. From the visualization results in the first row, Decision Tree, K-Means, FCN-8s, FCN-32s, SegNet, the YOLO series, ConvLSR-Net, and UANet failed to effectively identify flood areas. In contrast, MFF-Net performed significantly better, detecting regions that closely matched the actual flood areas, especially in the red box areas. From the results in the second and third rows, although Decision Tree and K-Means showed relatively good results, they misclassified some non-flood areas as flood areas. The results from FCN-8s, FCN-32s, SegNet, SCAttNet, and the YOLO series were more average, with difficulties in recognizing certain areas. In comparison, our method showed better performance in detecting fine flood regions, particularly in the red box areas, where small regions were identified with greater precision.
Figure 6.
The visualization results on the Sen1Floods11 Dataset. (a) SAR images. (b) GT. (c) Decision Tree. (d) K-Means. (e) FCN-8s. (f) FCN-32s. (g) SegNet. (h) SCAttNet. (i) YOLOv8. (j) YOLOv9. (k) YOLOv11. (l) ConvLSR-Net. (m) UANet. (n) MFF-Net (Ours). The red box highlights the region of special interest.
3.4.3. Performance Comparison on the ETCI 2021 Dataset
The results of all methods on the ETCI 2021 Dataset are presented in Table 3. The bold numbers indicate the best results, while underlined numbers denote the second-best results. we selected three flood events from different regions in the vicinity of Florence, occurring on 22 May 2018, 3 June 2018, and 1 October 2018. MFF-Net stands out among all the listed models, achieving the highest IoU and F1 score, as well as a strong overall accuracy of 93.26%. It also demonstrates a precision of 86.96% and a recall of 50.36%. This positions MFF-Net competitively in terms of F1 score and overall performance, surpassing other models. Furthermore, the relatively low proportion of flood regions in the ETCI 2021 dataset may hinder the model’s ability to effectively learn the characteristics of floods during training. As a result, the model may be biased toward detecting non-flood regions or producing more false positive results, which explains why YOLO models, despite having high recall, perform poorly in other metrics.
Table 3.
Performance on the ETCI 2021 Dataset.
The visualization results are presented in Figure 7, where the white areas correspond to the identified areas, and the black areas represent the background. Overall, due to the relatively small proportion of flood-affected regions within the ETCI 2021 dataset, models such as FCN-8s, FCN-32s, SegNet, SCAttNet, and the YOLO series were unable to adequately capture the distinctive features of flood areas, resulting in suboptimal performance. In contrast, Decision Tree and K-Means approaches exhibited a considerable amount of noise and erroneous classifications, as reflected in their visualization results. On the other hand, ConvLSR-Net, UANet, and MFF-Net demonstrated superior performance, with MFF-Net displaying enhanced recognition capabilities, particularly in the detailed regions highlighted by the red boxes. Specifically, the first and third rows identified areas that were missed by ConvLSR-Net and UANet, showing a closer alignment with the ground truth.
Figure 7.
The visualization results on the ETCI 2021 Dataset. (a) SAR images. (b) GT. (c) Decision Tree. (d) K-Means. (e) FCN-8s. (f) FCN-32s. (g) SegNet. (h) SCAttNet. (i) YOLOv8. (j) YOLOv9. (k) YOLOv11. (l) ConvLSR-Net. (m) UANet. (n) MFF-Net (Ours). The red box highlights the region of special interest.
3.5. Performance on the Water Body Detection Task
In addition to flood detection, we explore the performance of the proposed method on the water body detection task. Experiments are conducted on the SAR Poyang Lake Water Body Sample Dataset using the same experimental pipeline as that adopted for flood detection. Detailed information on the division is provided in Section 3.1 Dataset. The evaluation metrics of all methods on the SAR Poyang Lake Water Body Sample Dataset are presented in Table 4. The bold numbers indicate the best results, while underlined numbers denote the second-best results. It can be seen from Table 4 that MFF-Net demonstrates superior comprehensive performance, achieving an IoU of 57.27% that exceeds UANet’s 56.22% by 1.05%. Its F1-Score reaches 59.68%, outperforming UANet’s 58.67%, which indicates better segmentation accuracy and balance. Additionally, MFF-Net attains the highest OA of 97.82% among all models. In general, MFF-Net exhibits remarkable accuracy and stability. Note that the results of FCN-32s show a significant drop in comparison with the performance on the MMflood Dataset. It is perhaps that the difference in resolution (256 × 256 in this dataset compared to 512 × 512 in MMflood) causes the feature maps of FCN-32s to become excessively coarse, thereby compromising the accuracy of boundary segmentation. In contrast, FCN-8s demonstrate more robust performance by effectively integrating multi-scale features, making them better suited for handling lower resolution inputs.
Table 4.
Performance on the SAR Poyang Lake Water Body Sample Dataset.
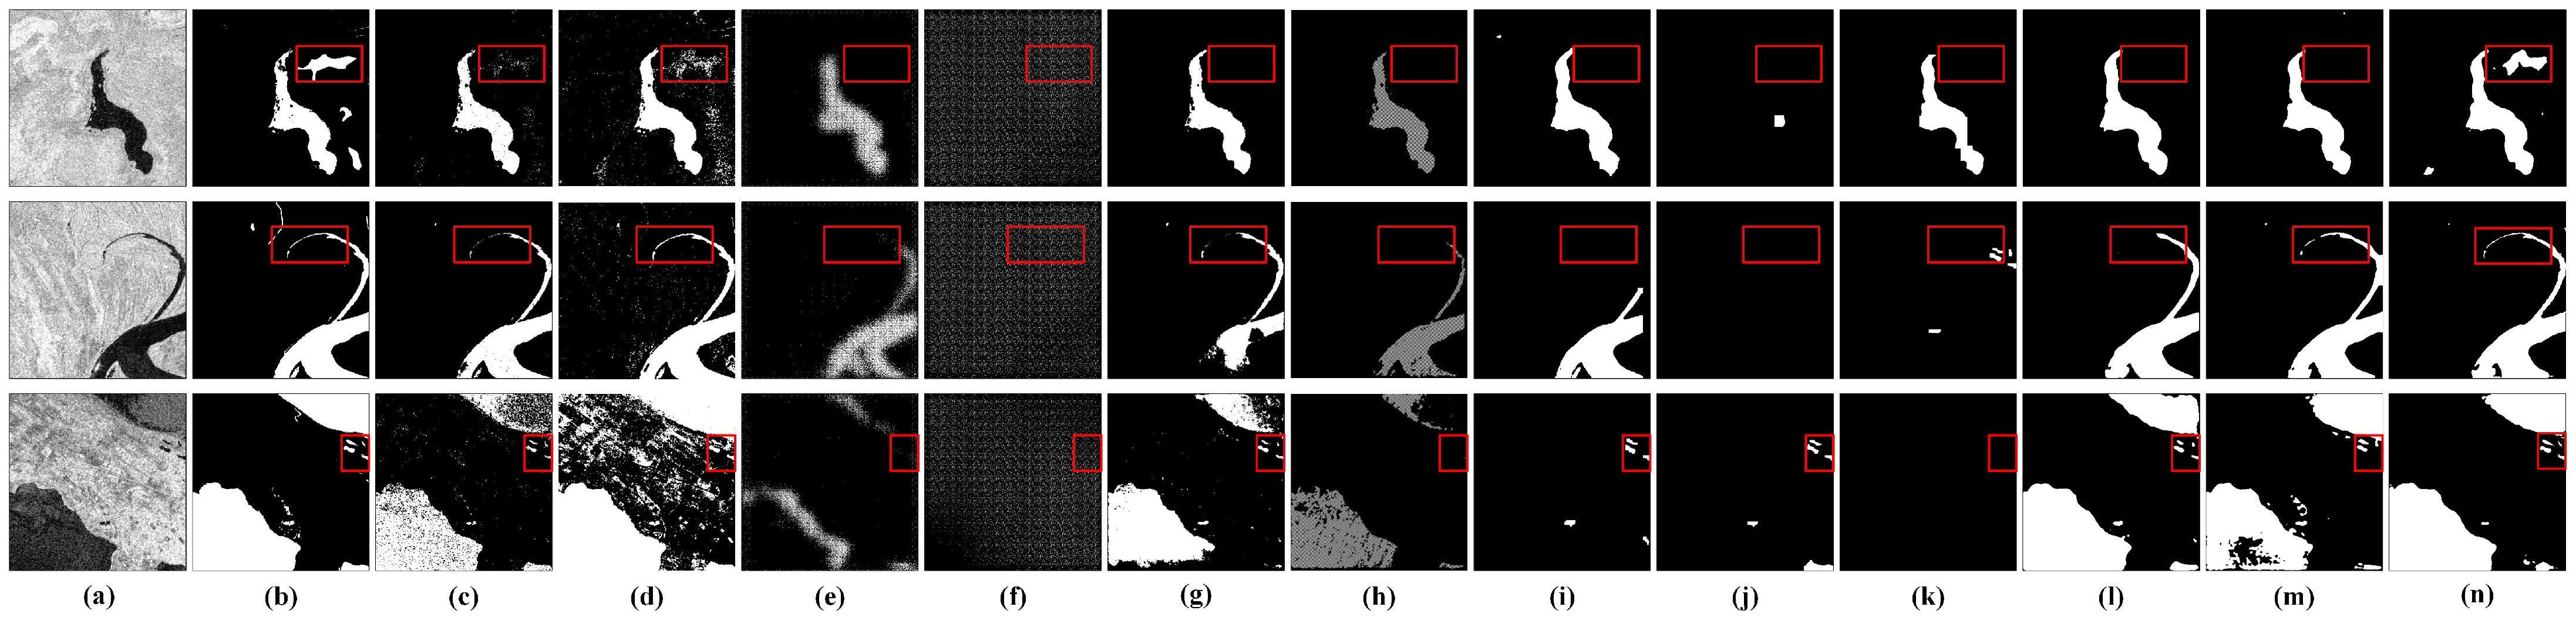
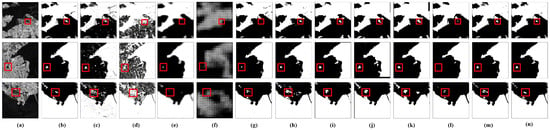
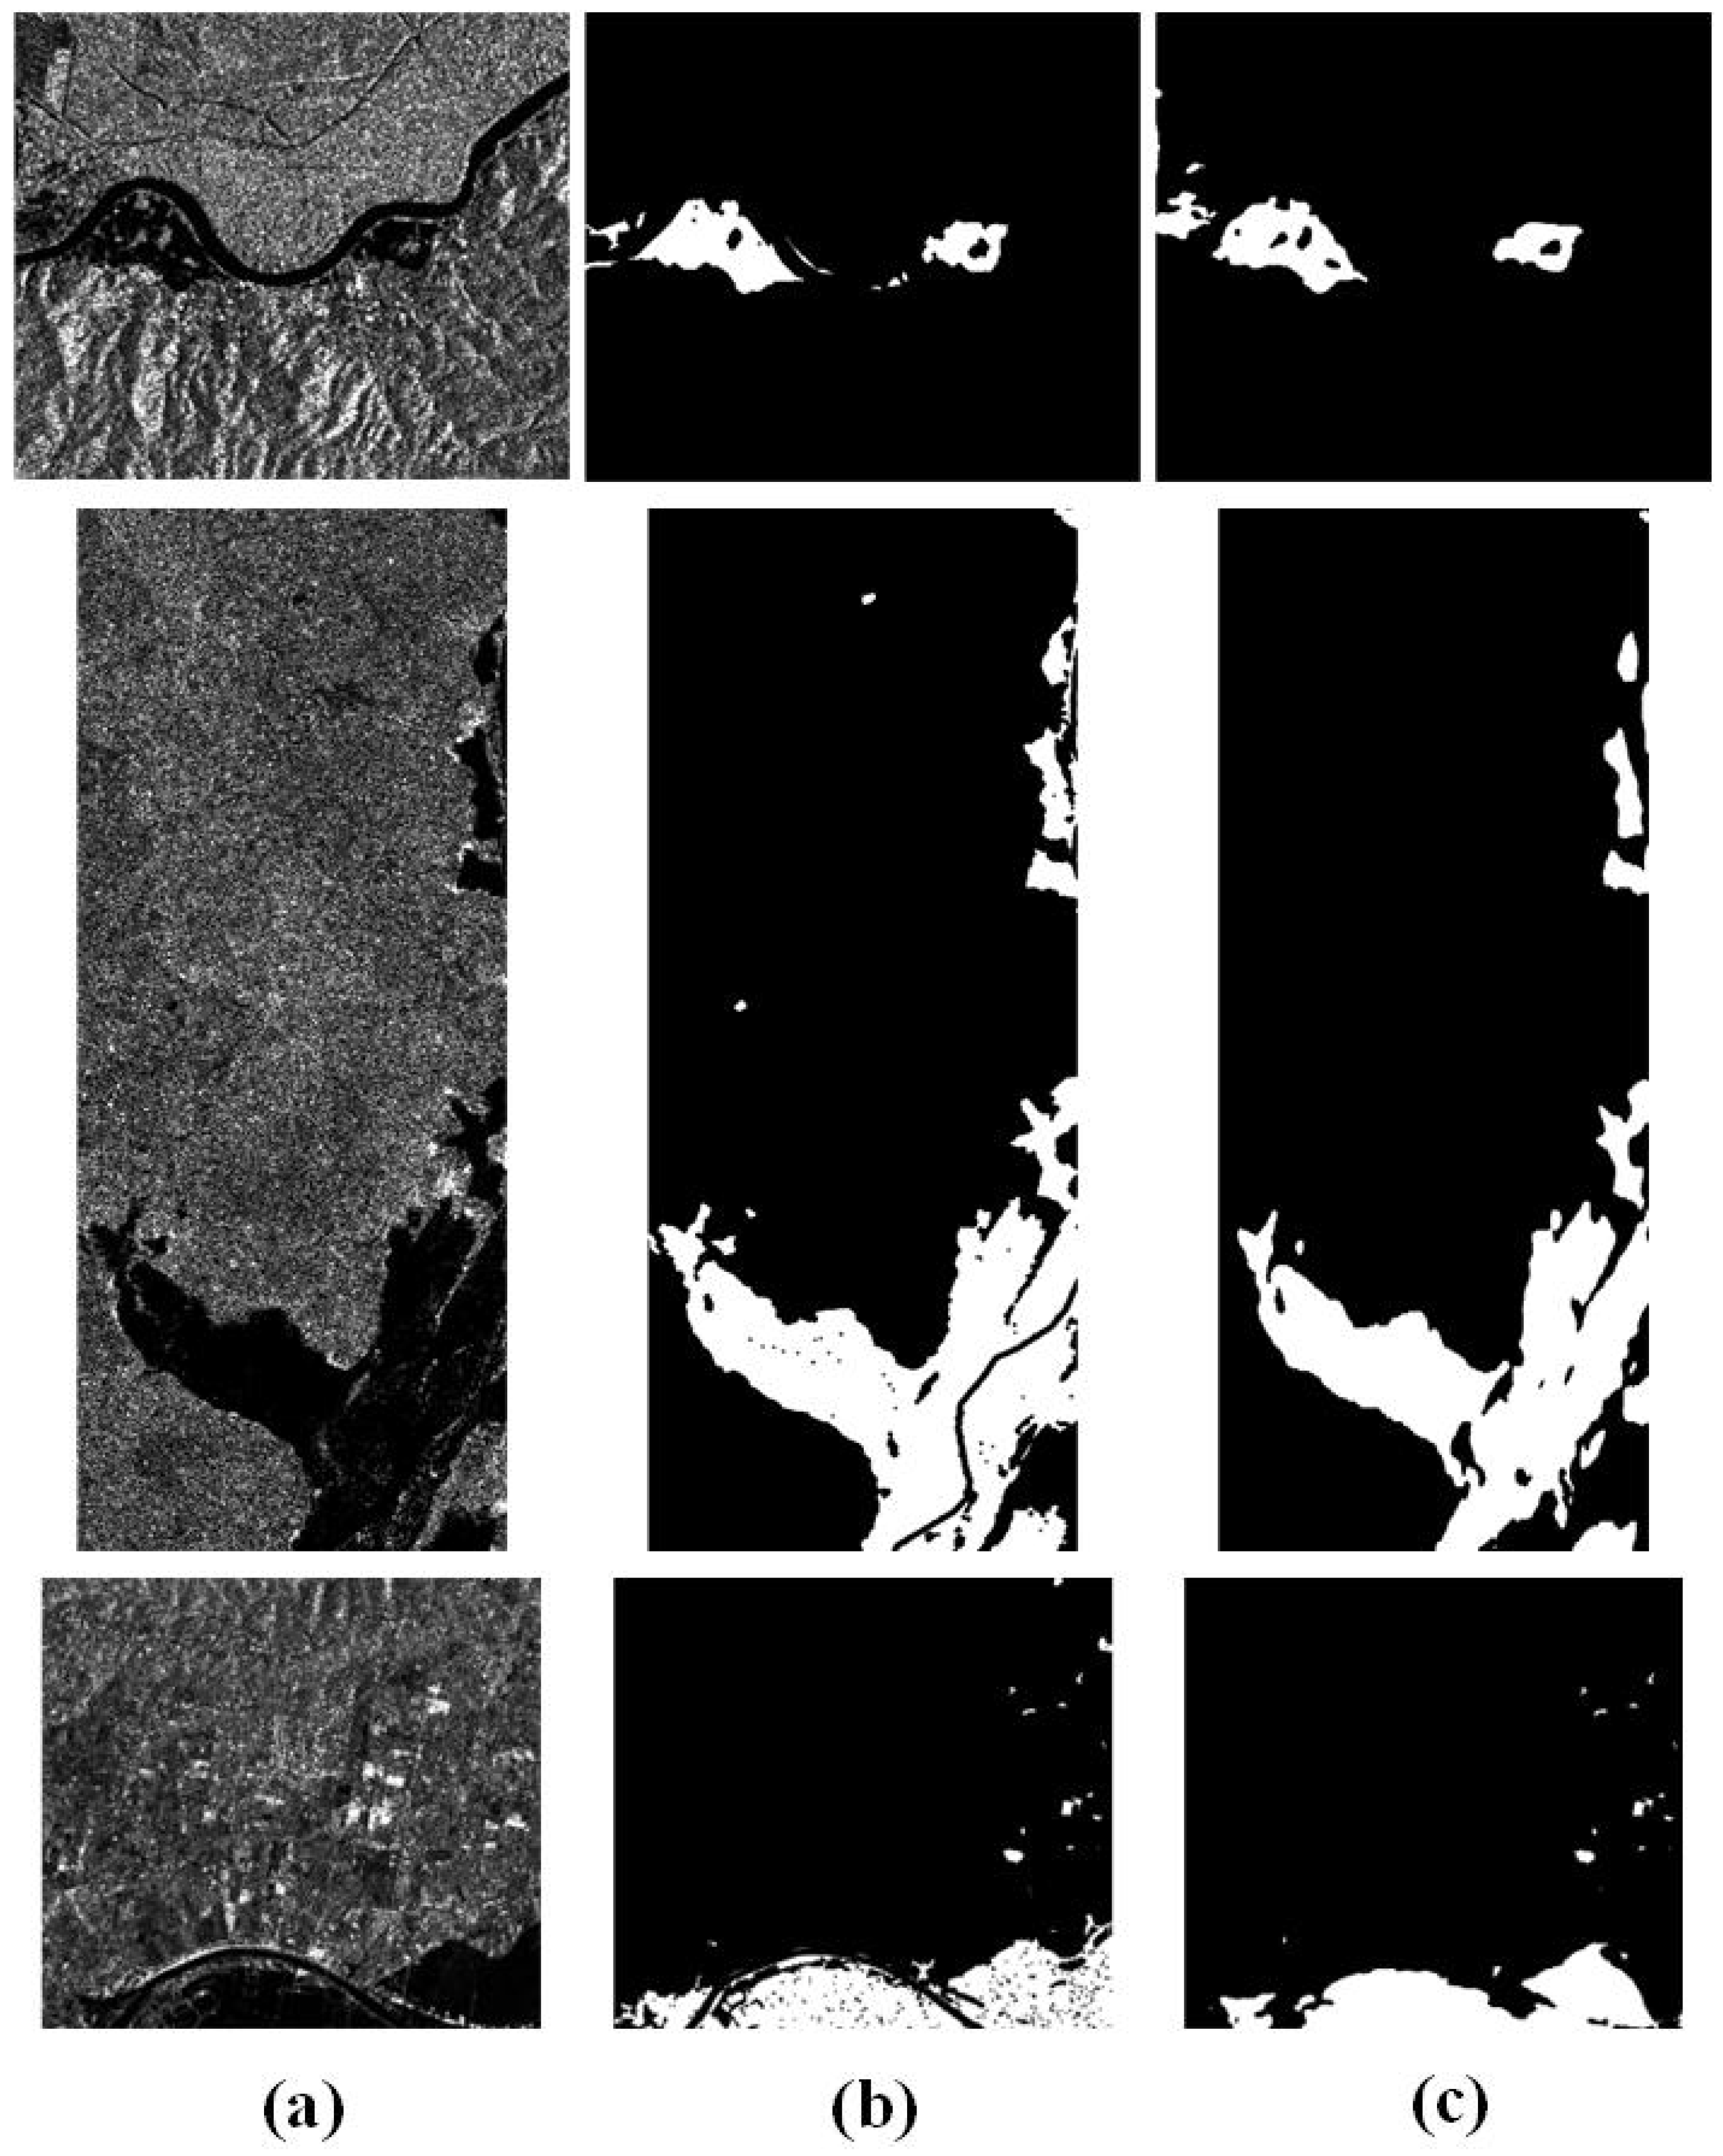
The visualization results are shown in Figure 8, with white regions representing water body areas and black areas indicating the background. It can be seen from the first row that both FCN-8s and SegNet fail to identify the subtle area and produce more blurred boundaries, as highlighted in the red box. FCN-32s does not accurately segment the entire image. The machine learning methods roughly segmented the outline, but there is a large amount of noise in the image. The YOLO series, ConvLSR-Net, UANet, and SCAttNet demonstrate their ability to segment small water body boundaries. However, MFF-Net achieves more accurate shape recognition in comparison. In the second row, it can be seen that only MFF-Net can accurately capture the fine-grained water body boundaries, delivering the closest result to the ground truth, while other methods fail to identify the small water body areas precisely. For the third row, MFF-Net still performs exceptionally well, not only identifying the fine-grained areas within the red box but also preserving boundary details more effectively.
Figure 8.
The visualization results on the SAR Poyang Lake Water Body Sample Dataset. (a) SAR images. (b) GT. (c) Decision Tree. (d) K-Means. (e) FCN-8s. (f) FCN-32s. (g) SegNet. (h) SCAttNet. (i) YOLOv8. (j) YOLOv9. (k) YOLOv11. (l) ConvLSR-Net. (m) UANet. (n) MFF-Net (Ours). The red box highlights the region of special interest.
3.6. Generalization on Other Region
To validate the replicability of our method on other geographical areas, we additionally conducted an experiment using Sentinel-1 images from the 2017 Piura River Basin flood dataset caused by heavy rainfall in multiple regions of Peru [52], including 20 VV-polarized and 20 VH-polarized SAR images. We directly evaluated the pre-trained models of ConvLSR-Net, UANet, and MFF-Net from the MMflood Dataset, which had demonstrated superior performance in previous experiments. Given that the selected baseline models have shown stable performance on multiple public benchmark datasets (including MMFlood, Sen1Floods11, ETCI 2021, and the SAR Poyang Lake Water Body Sample Dataset), baseline methods with comparable performance stability were chosen for comparison. This setup enables a fair analysis of performance differences under consistent conditions and supports the evaluation of model generalization across datasets. The quantitative results are presented in Table 5 and Table 6. The bold numbers indicate the best results, while underlined numbers denote the second-best results.
Table 5.
Performance comparison on VV-polarized Sentinel-1 SAR images from the 2017 Piura River Basin flood dataset.
Table 6.
Performance comparison on VH-polarized Sentinel-1 SAR images from the 2017 Piura River Basin flood dataset.
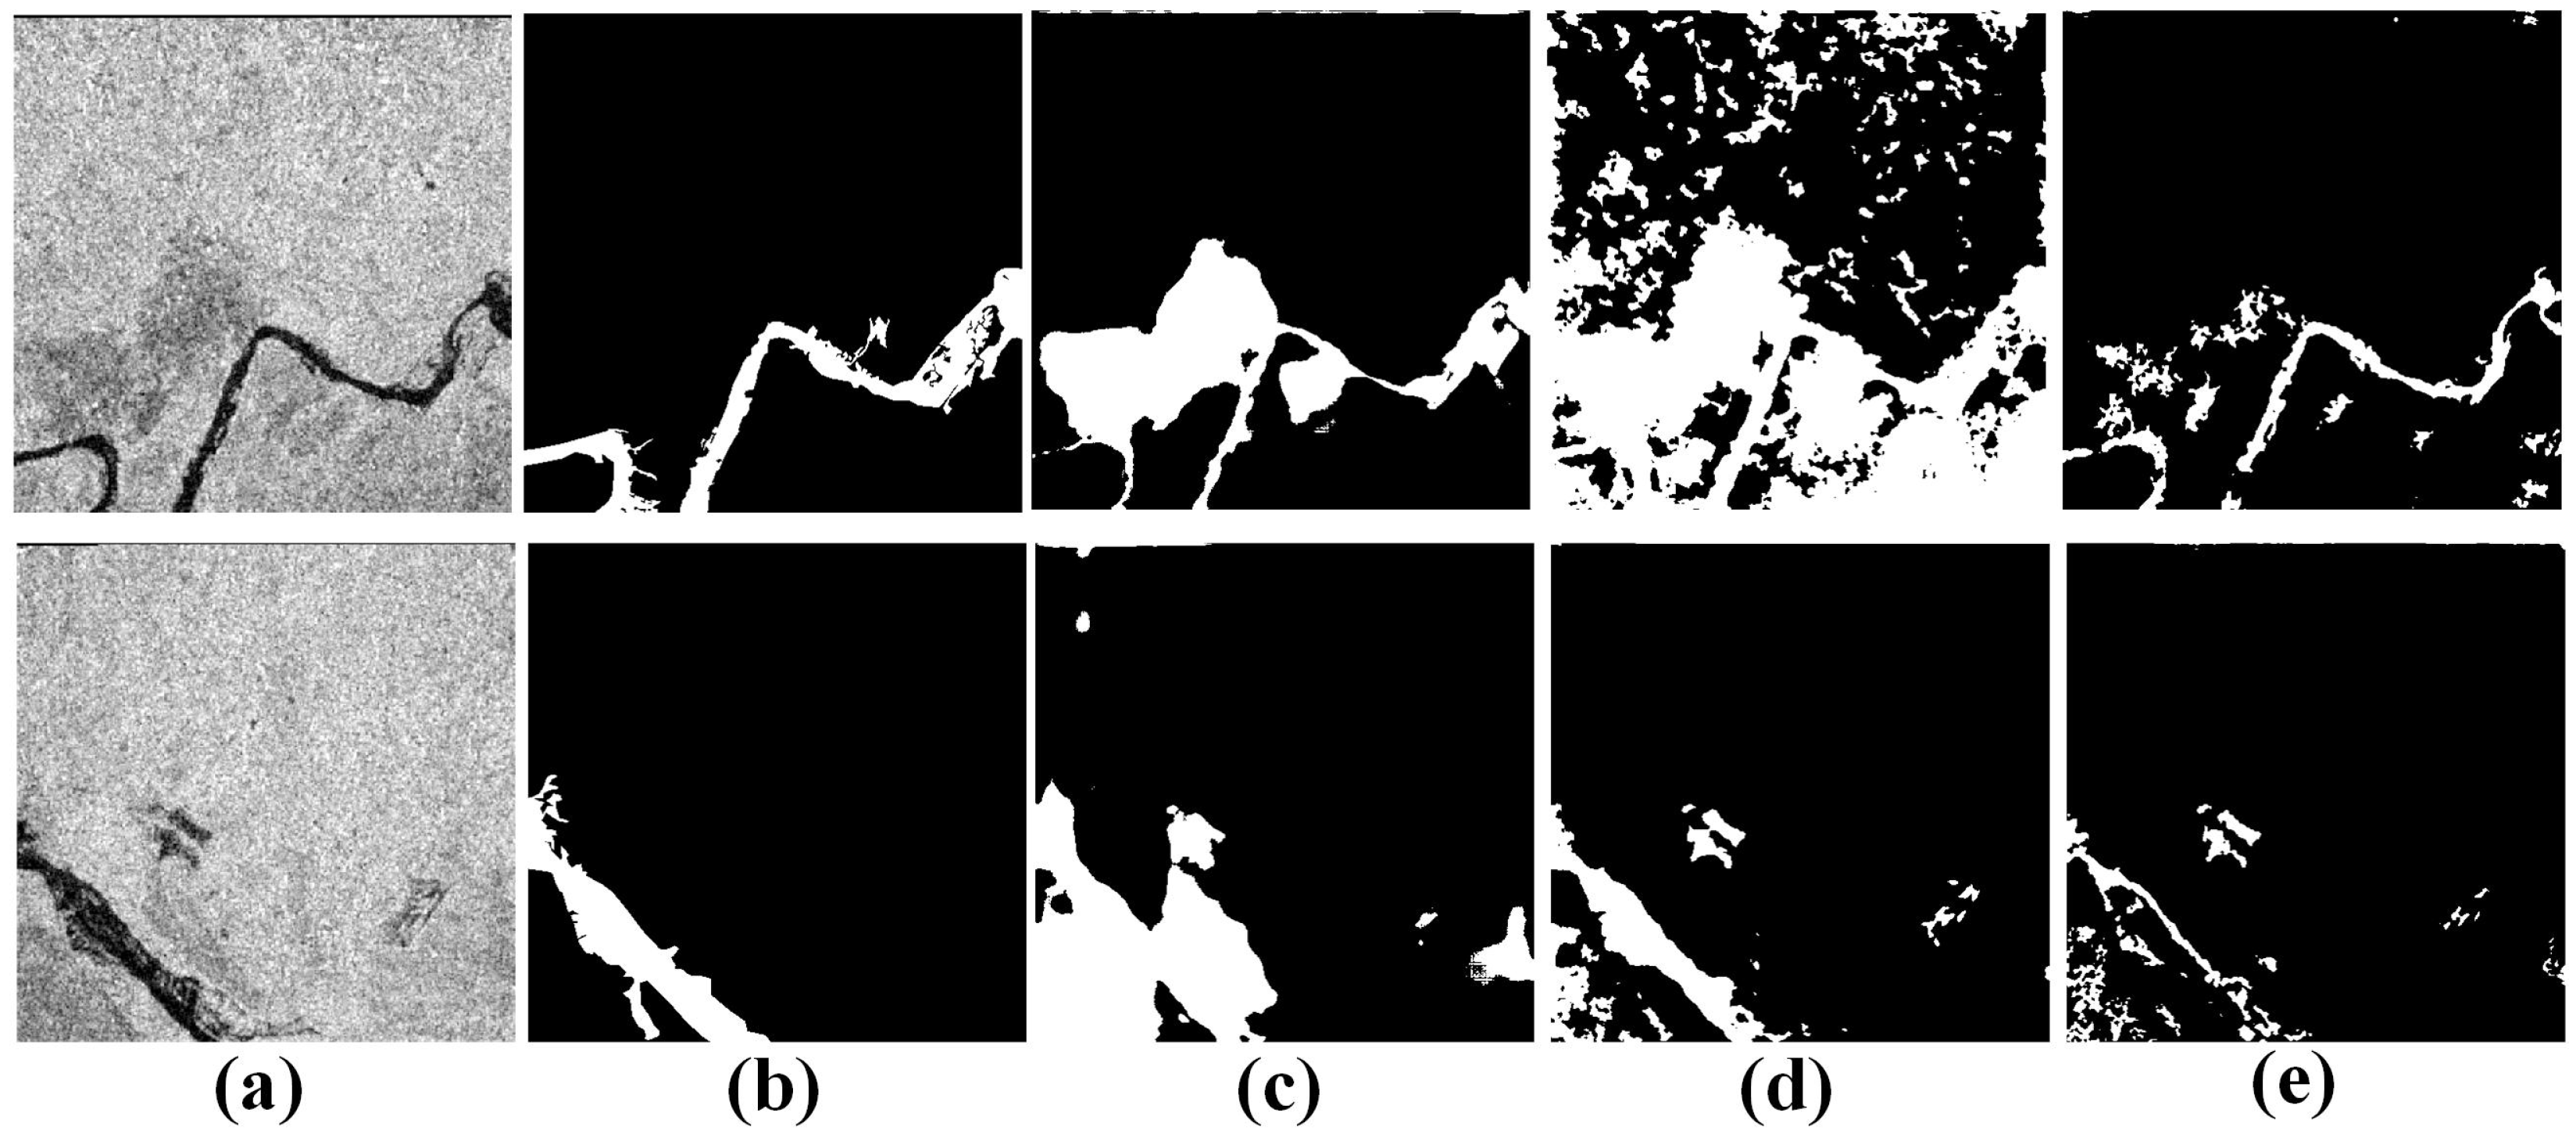
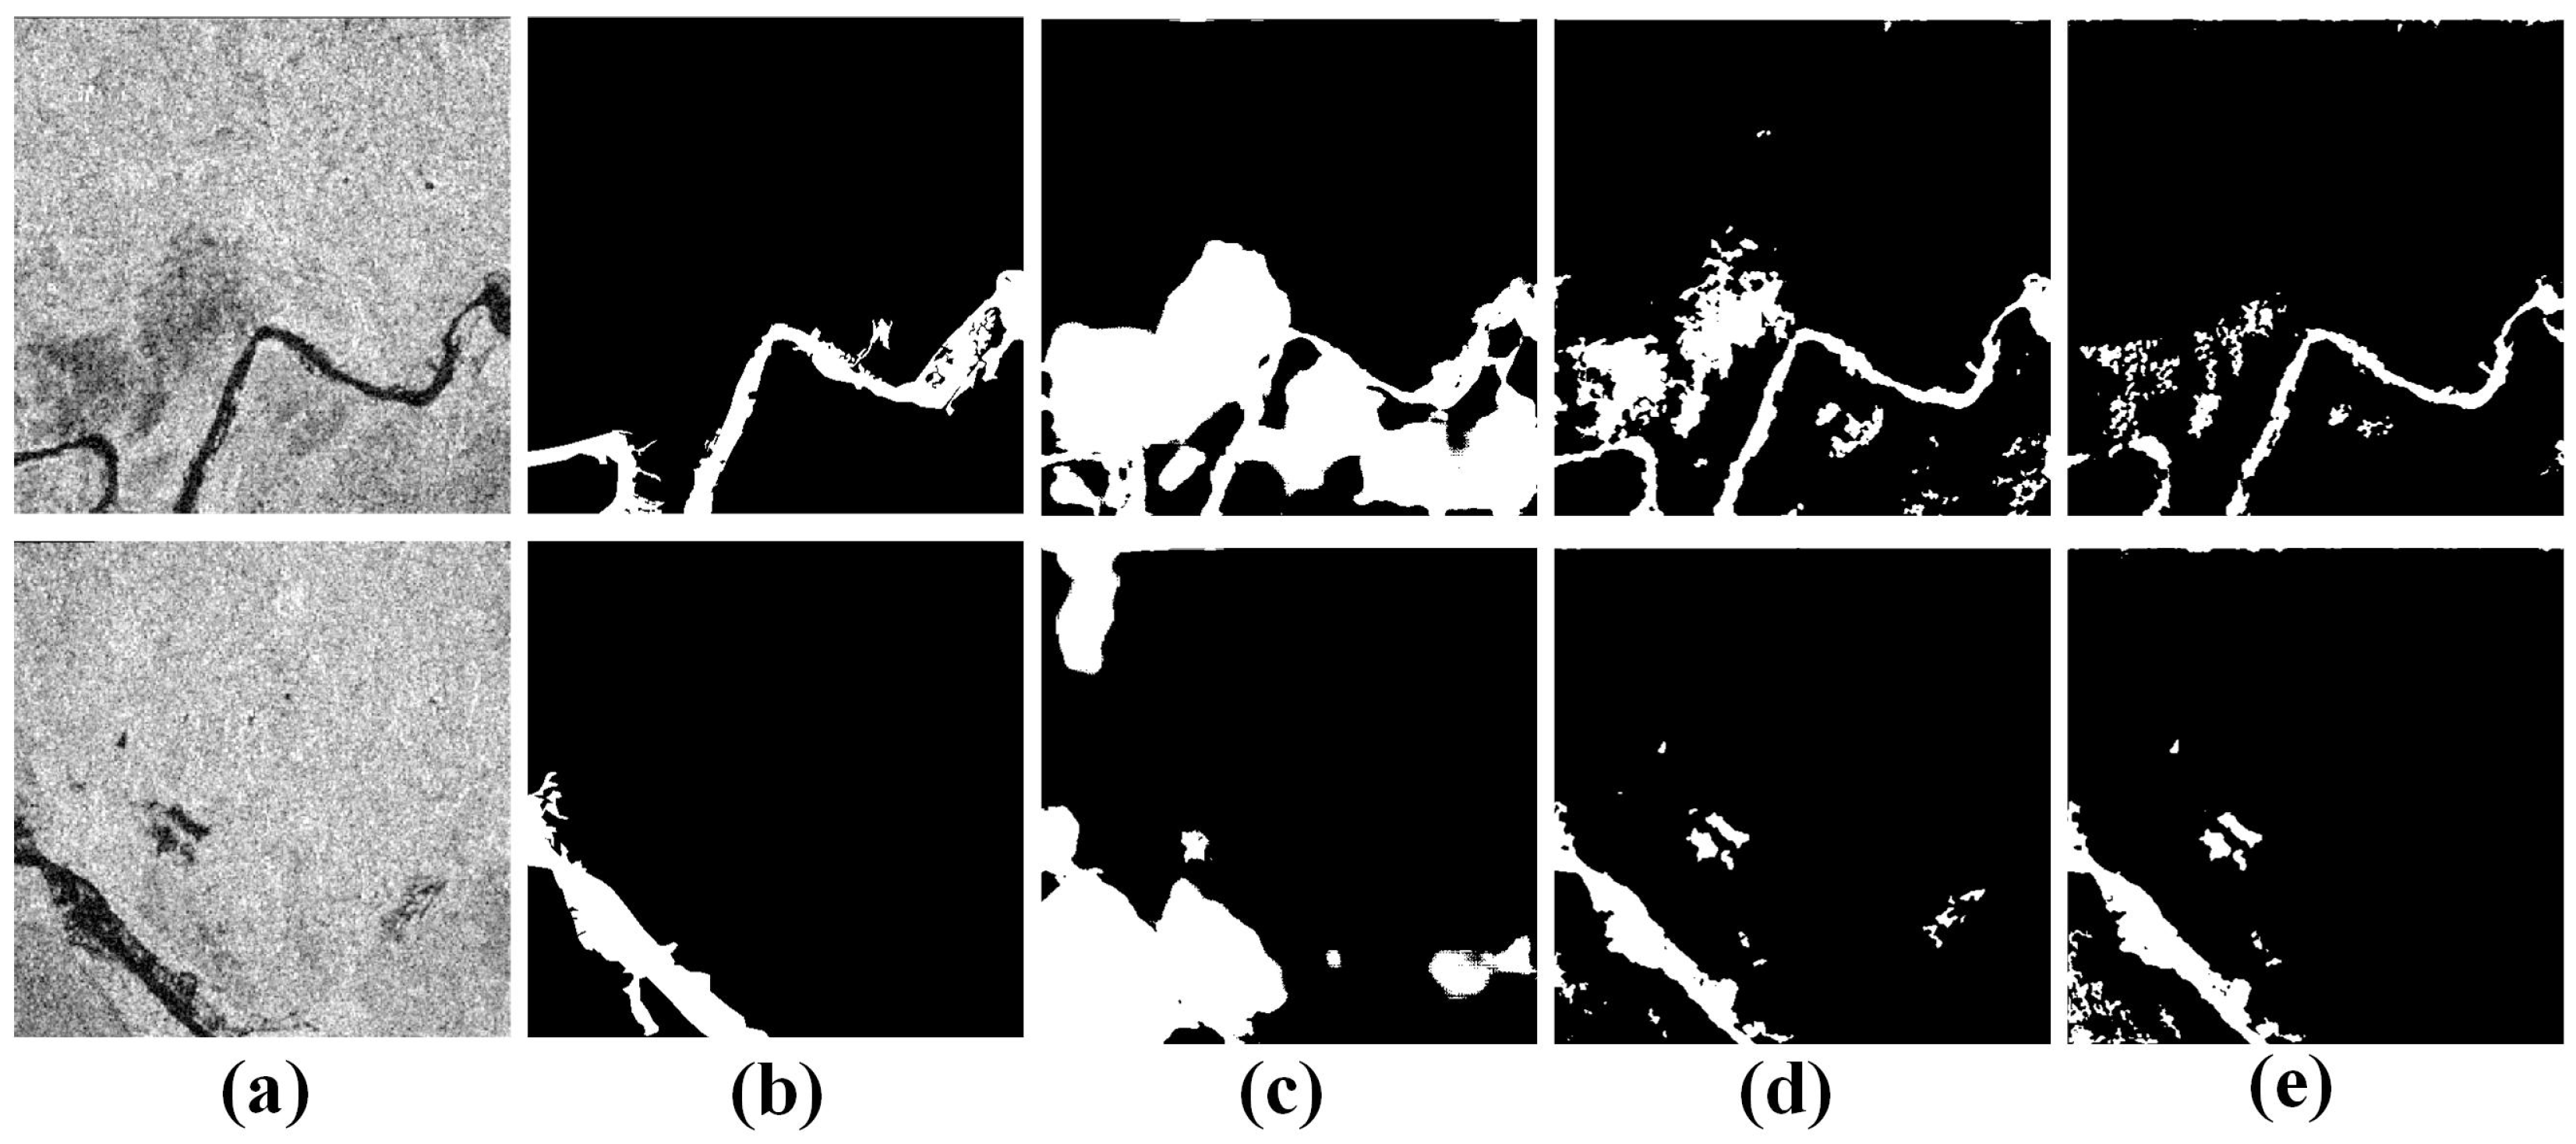
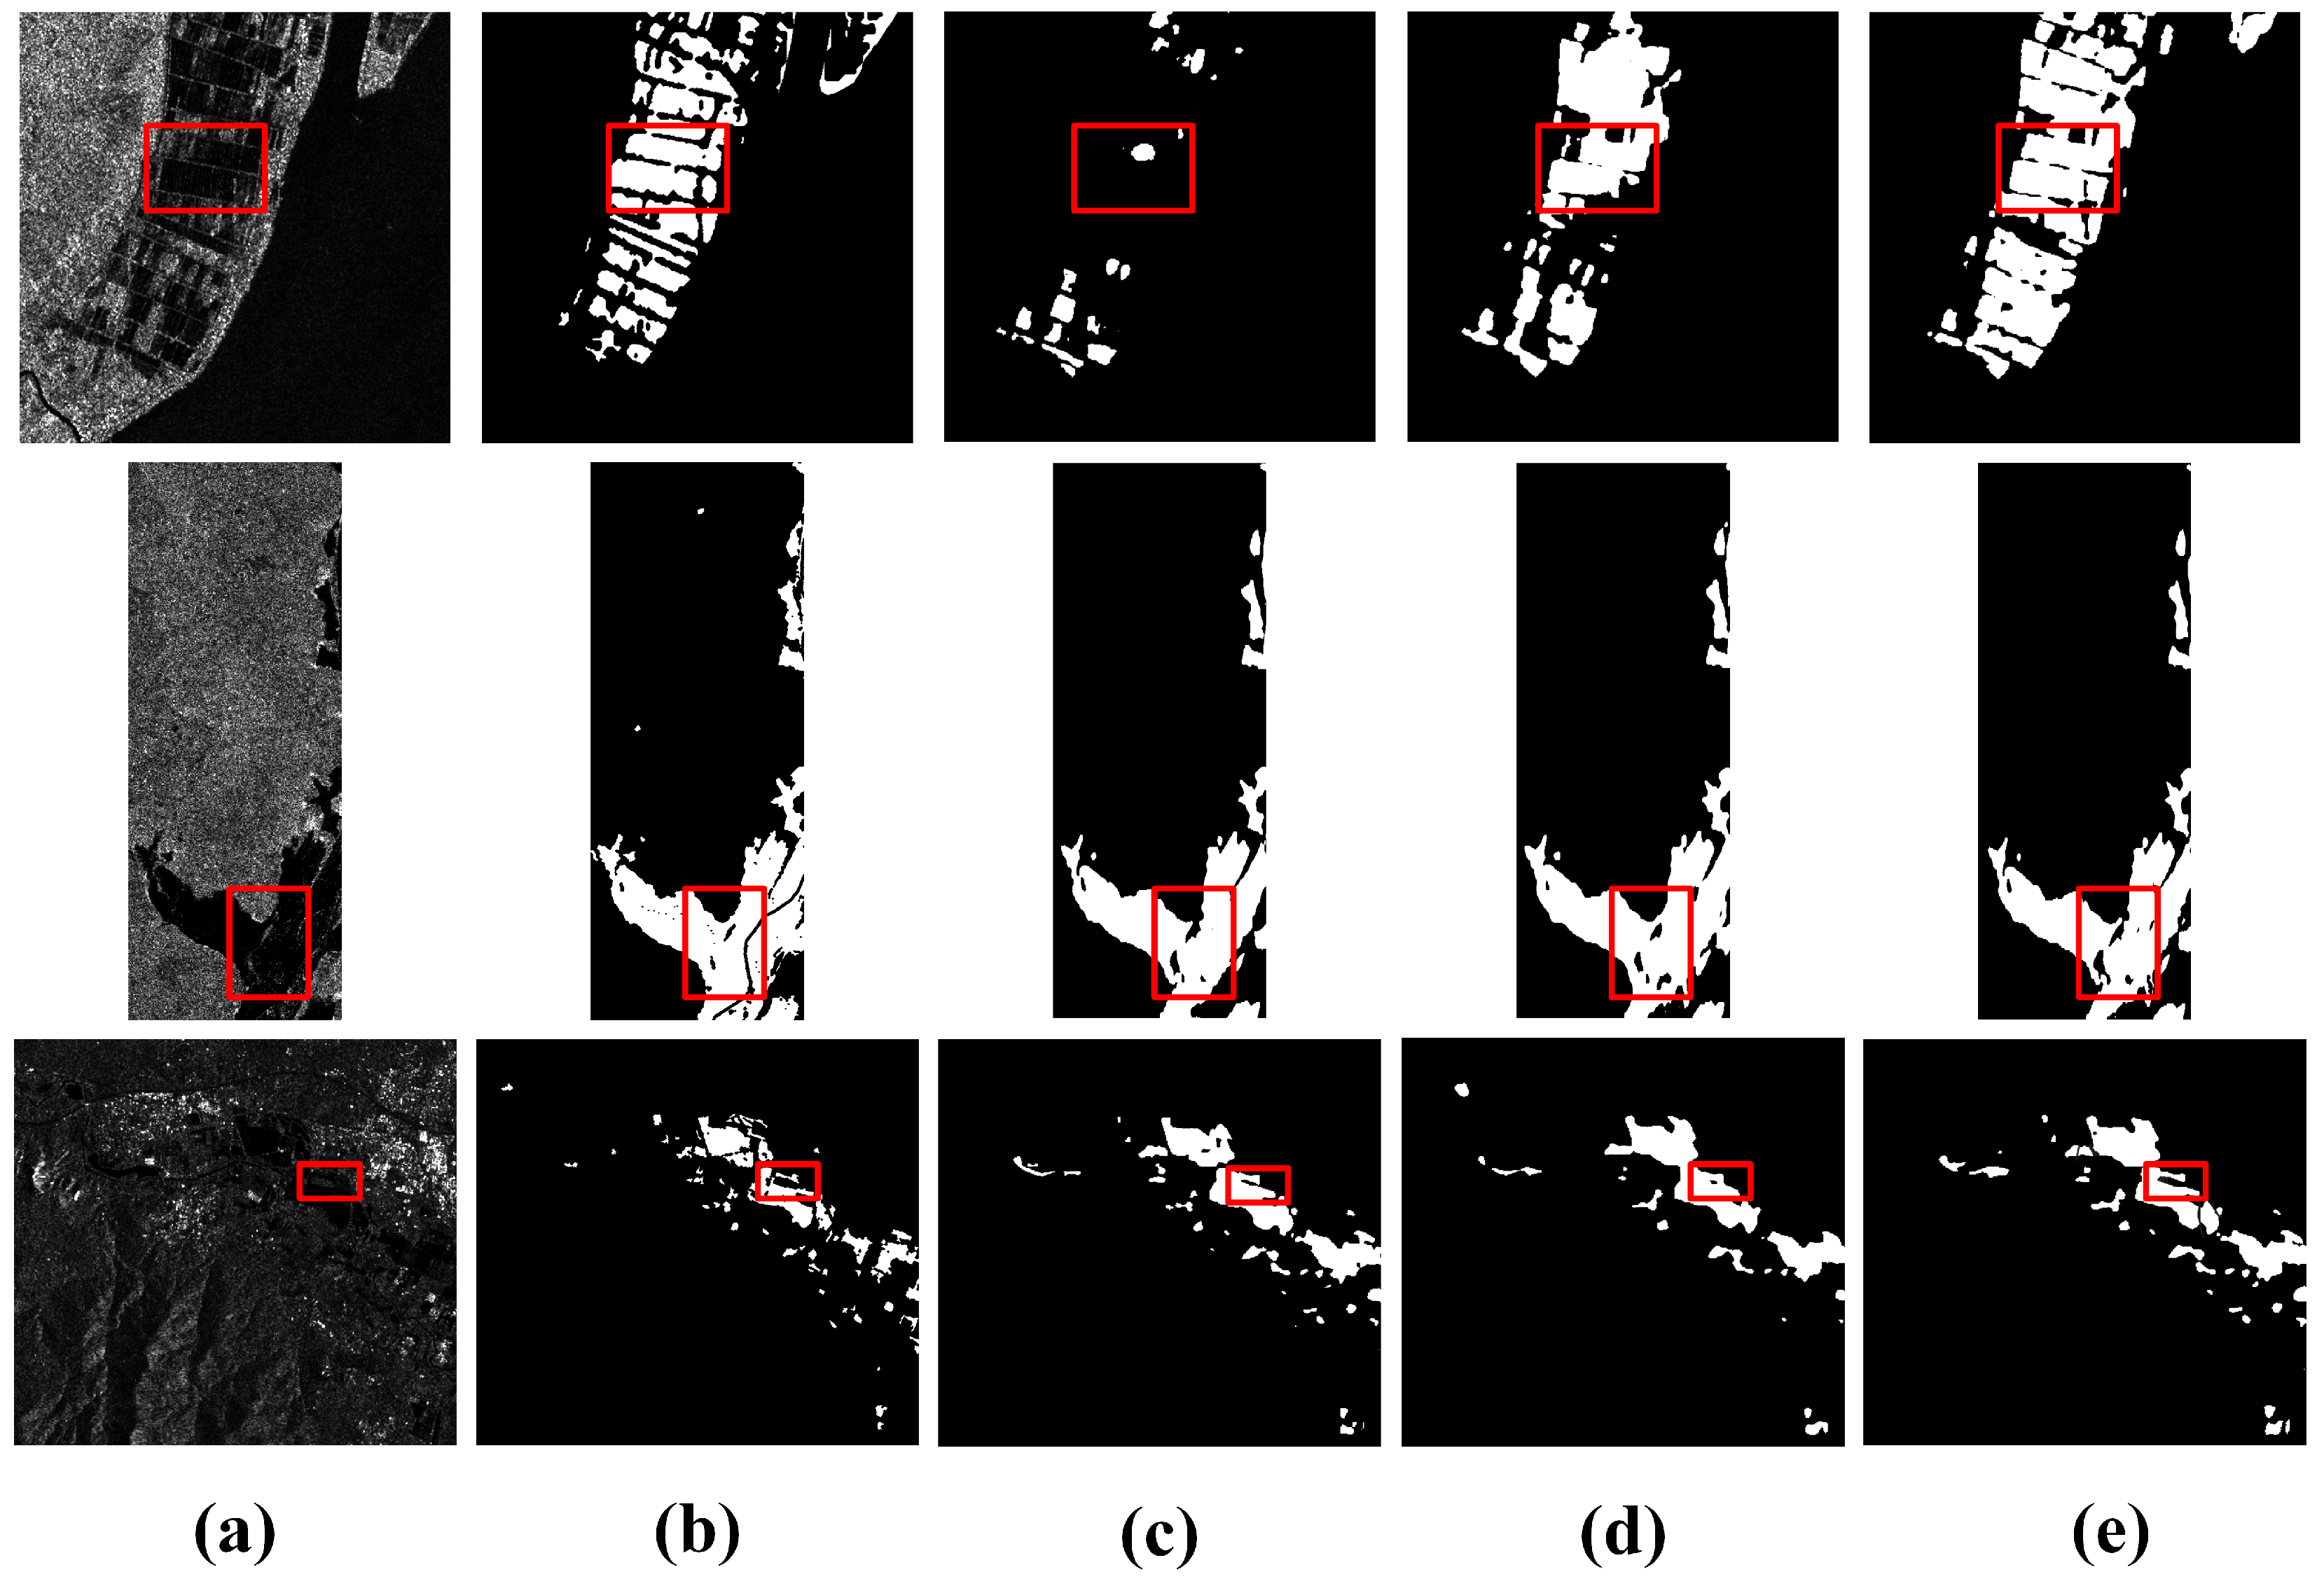
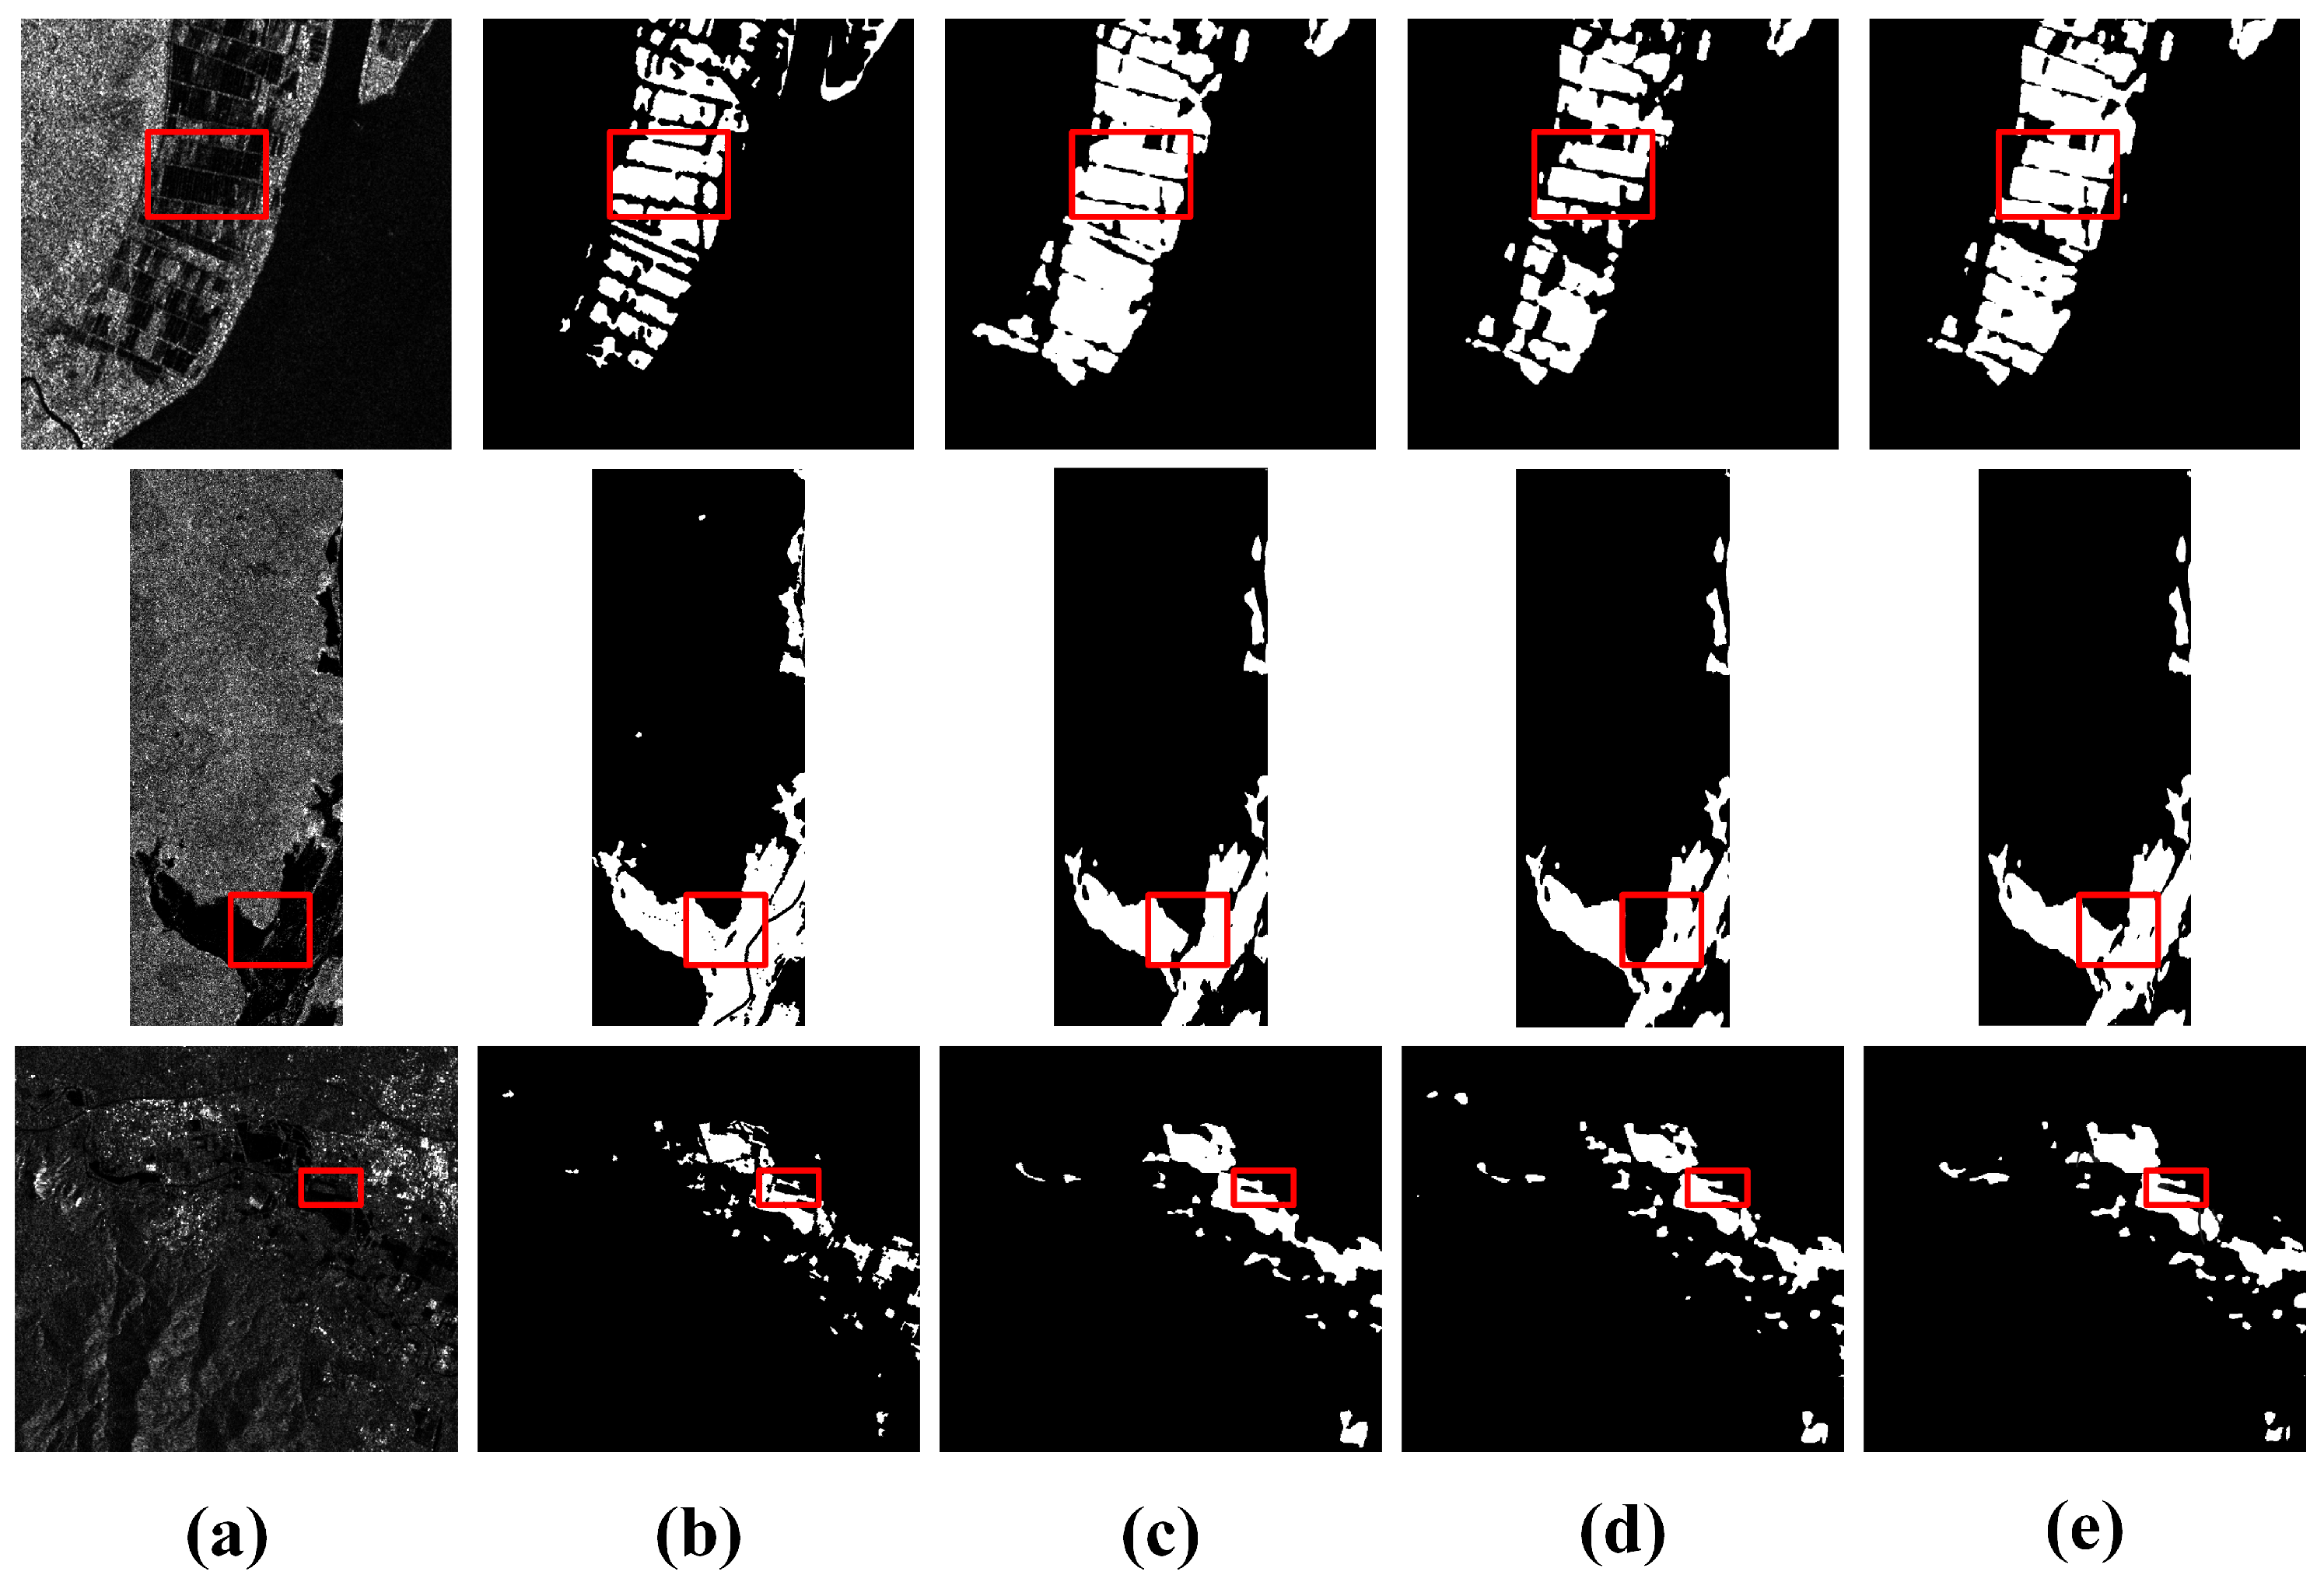
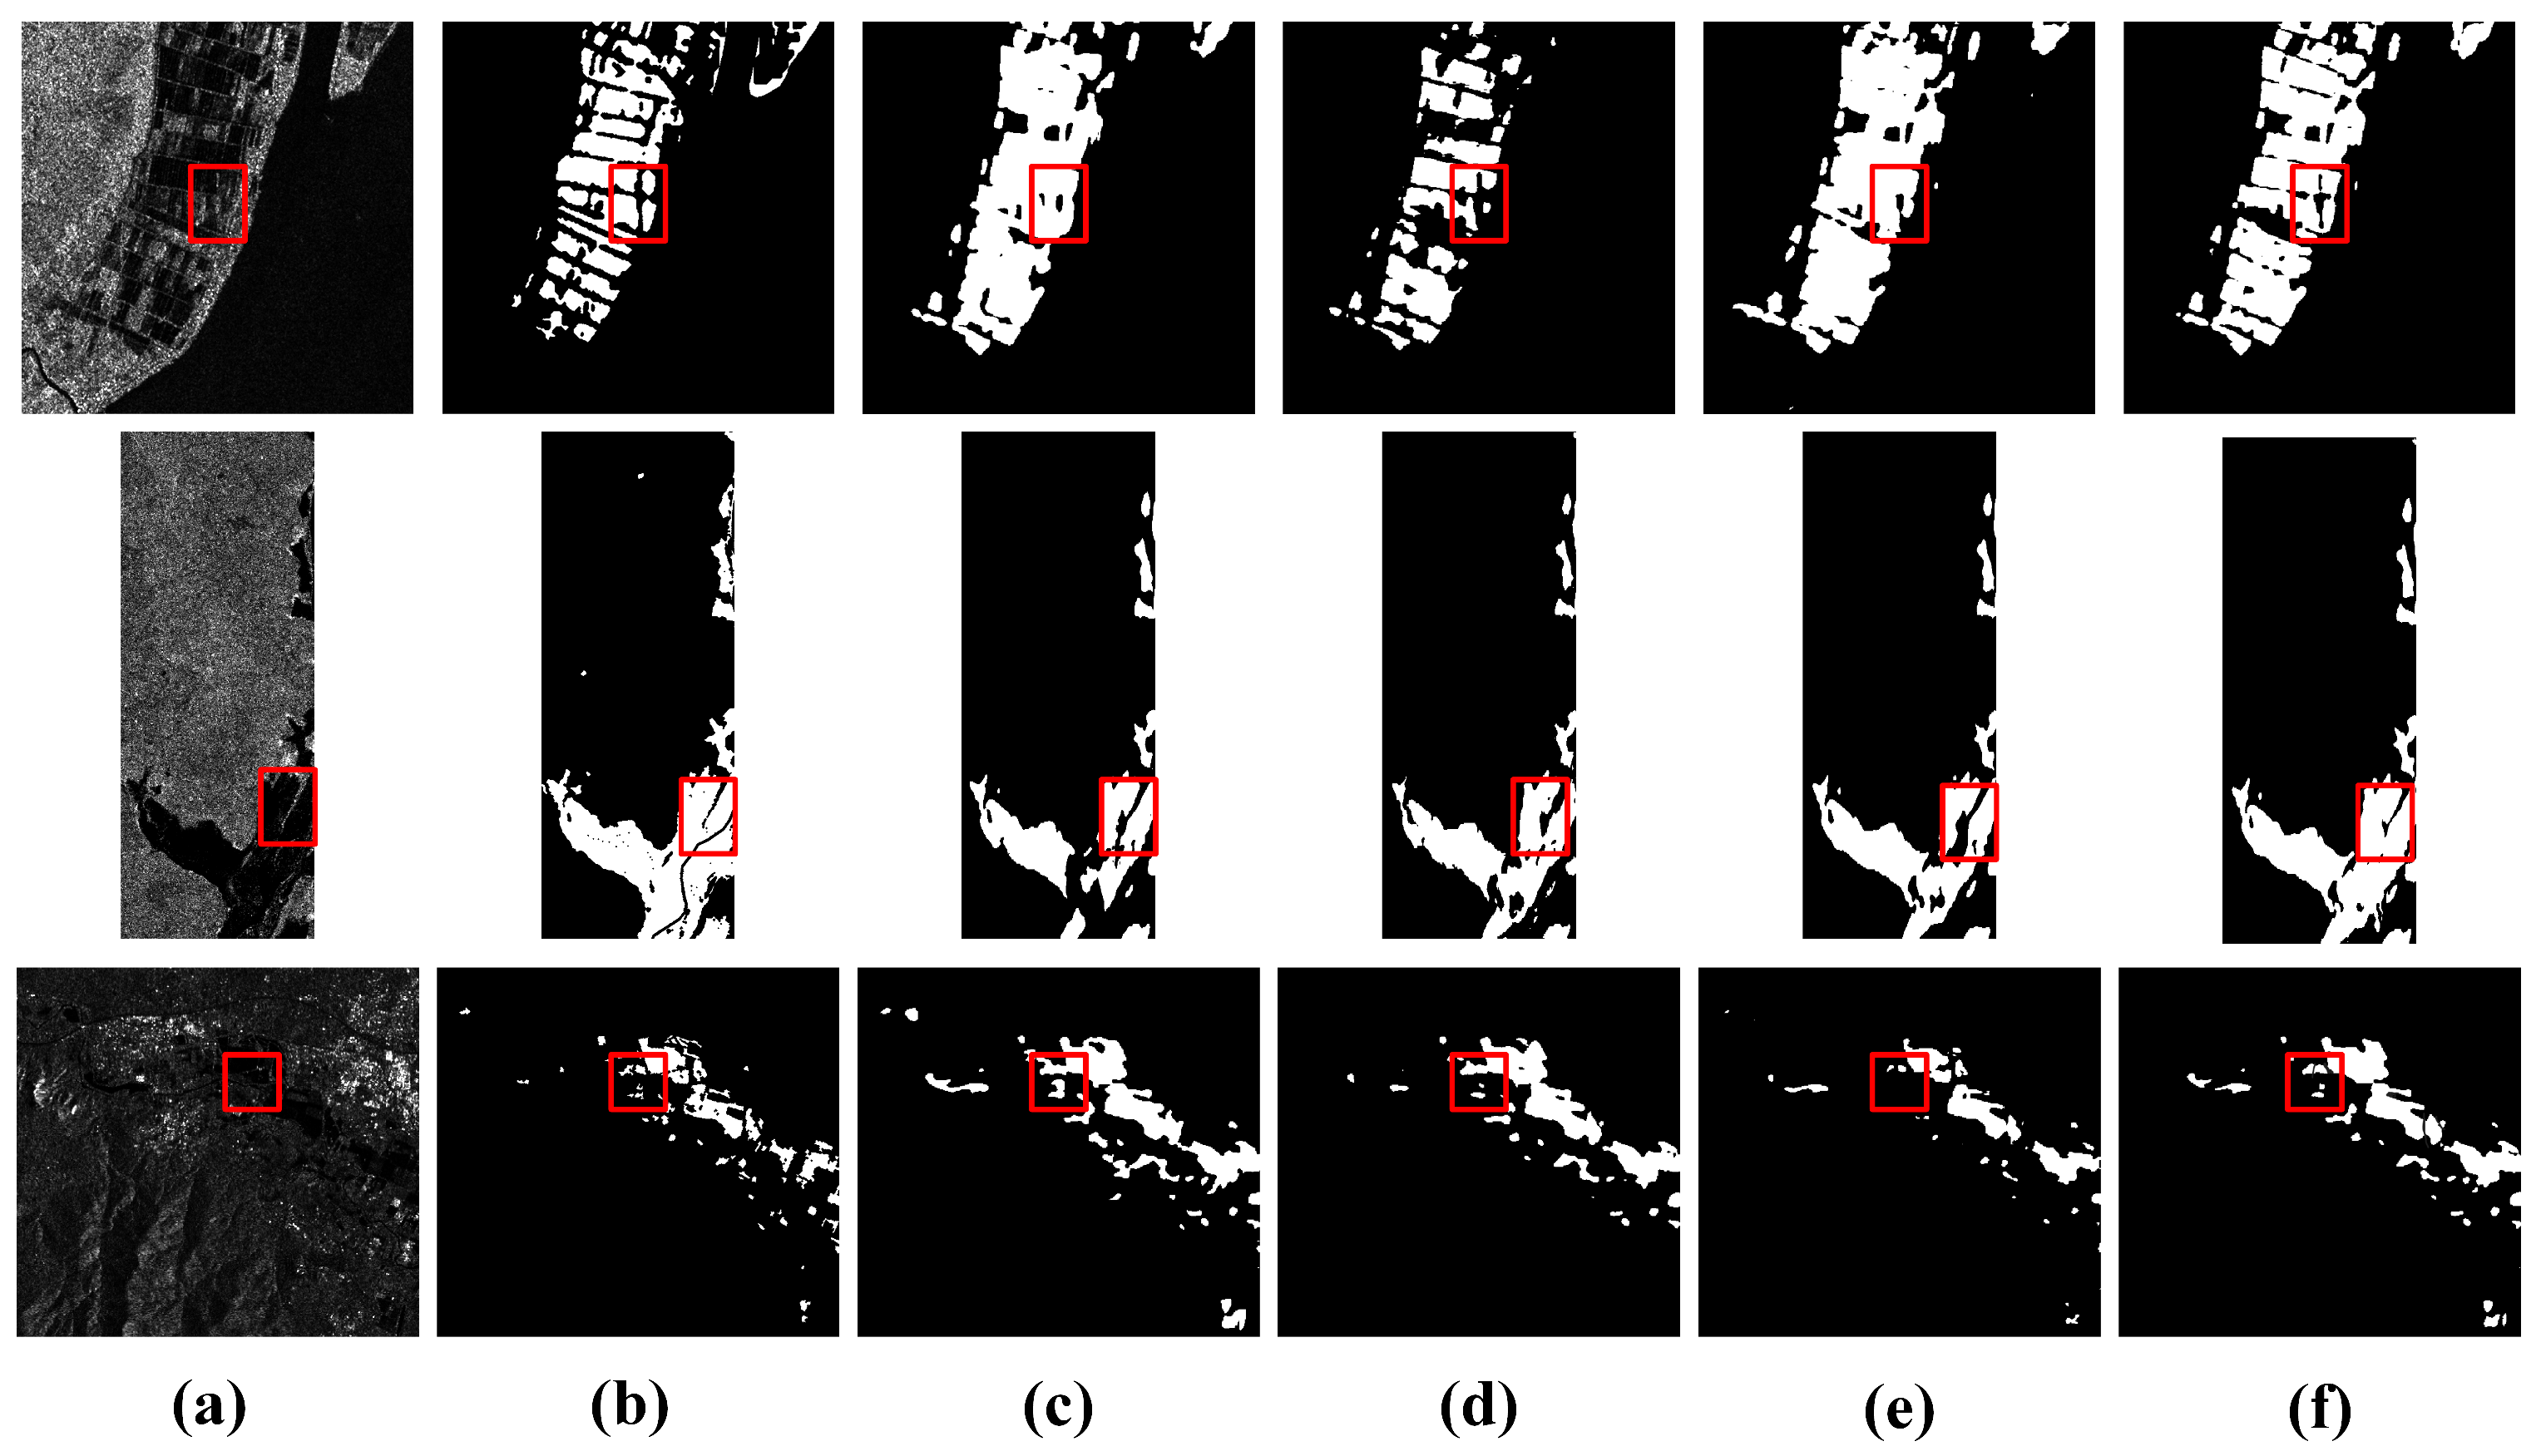
We can see from Figure 9 and Figure 10 that our pre-trained model successfully detected relatively complete flood extents, demonstrating its potential for application in other geographic regions. It also performed well in detecting some subtle flood regions while generating fewer false detections, with overall more superior performance.
Figure 9.
The performance evaluation on VV-polarized Sentinel-1 SAR images from the 2017 Piura River Basin flood dataset. (a) SAR images. (b) GT. (c) ConvLSR-Net. (d) UANet. (e) MFF-Net (Ours).
Figure 10.
The performance evaluation on VH-polarized Sentinel-1 SAR images from the 2017 Piura River Basin flood dataset. (a) SAR images. (b) GT. (c) ConvLSR-Net. (d) UANet. (e) MFF-Net (Ours).
These results validate that our pre-trained model achieves promising metrics and visualization results on the 2017 Piura River Basin flood dataset, with demonstrated potential for application to other geographical regions. Note that the performance is inferior to the MMflood Dataset, which indicates that there is still room for improvement in generalization. Despite the relatively lower recall observed on this dataset, the model continues to exhibit high values in IoU, F1, and OA, highlighting its strong overall detection accuracy and reliable flood region identification across diverse geographical contexts. The overall generalization performance is worth acknowledging, as it demonstrates the model’s ability to adapt well to new, unseen datasets, showcasing its potential for broader applications.
3.7. Ablation Study
3.7.1. Effectiveness of the Different Blocks
To validate the effectiveness of the proposed blocks in MFF-Net, namely the multi-frequency feature extraction module containing MFMSA blocks and the fuzzy uncertainty fusion module composed of FUD blocks, an ablation study was conducted to assess their individual contributions. In this study, MFMSA blocks and FUD blocks serve as the core components of the multi-frequency feature extraction module and the fuzzy uncertainty fusion module, respectively. Specifically, we evaluated the model performance by separately integrating these components into the backbone network, including configurations without MFMSA blocks, without FUD blocks, and with both blocks integrated. The results are listed in Table 7. The bold numbers indicate the best results, while underlined numbers denote the second-best results.
Table 7.
Performance comparison of different blocks. w/o MFMSA indicates that the MFMSA blocks are removed while the FUD blocks are retained, and w/o FUD indicates that the FUD blocks are removed while the MFMSA blocks are retained.
From Table 7, we can see that MFF-Net achieves an IoU of 47.51% and an F1-score of 58.55% when the MFMSA blocks are removed. Meanwhile, removing the FUD blocks results in an IoU of 48.00% and an F1-Score of 59.64%. Note that both of the combinations are significantly lower than the full model, where IoU and F1-score are 50.20% and 62.09%, respectively. It indicates that the proposed MSMFA and FUD blocks both benefit the overall performance in MFF-Net.
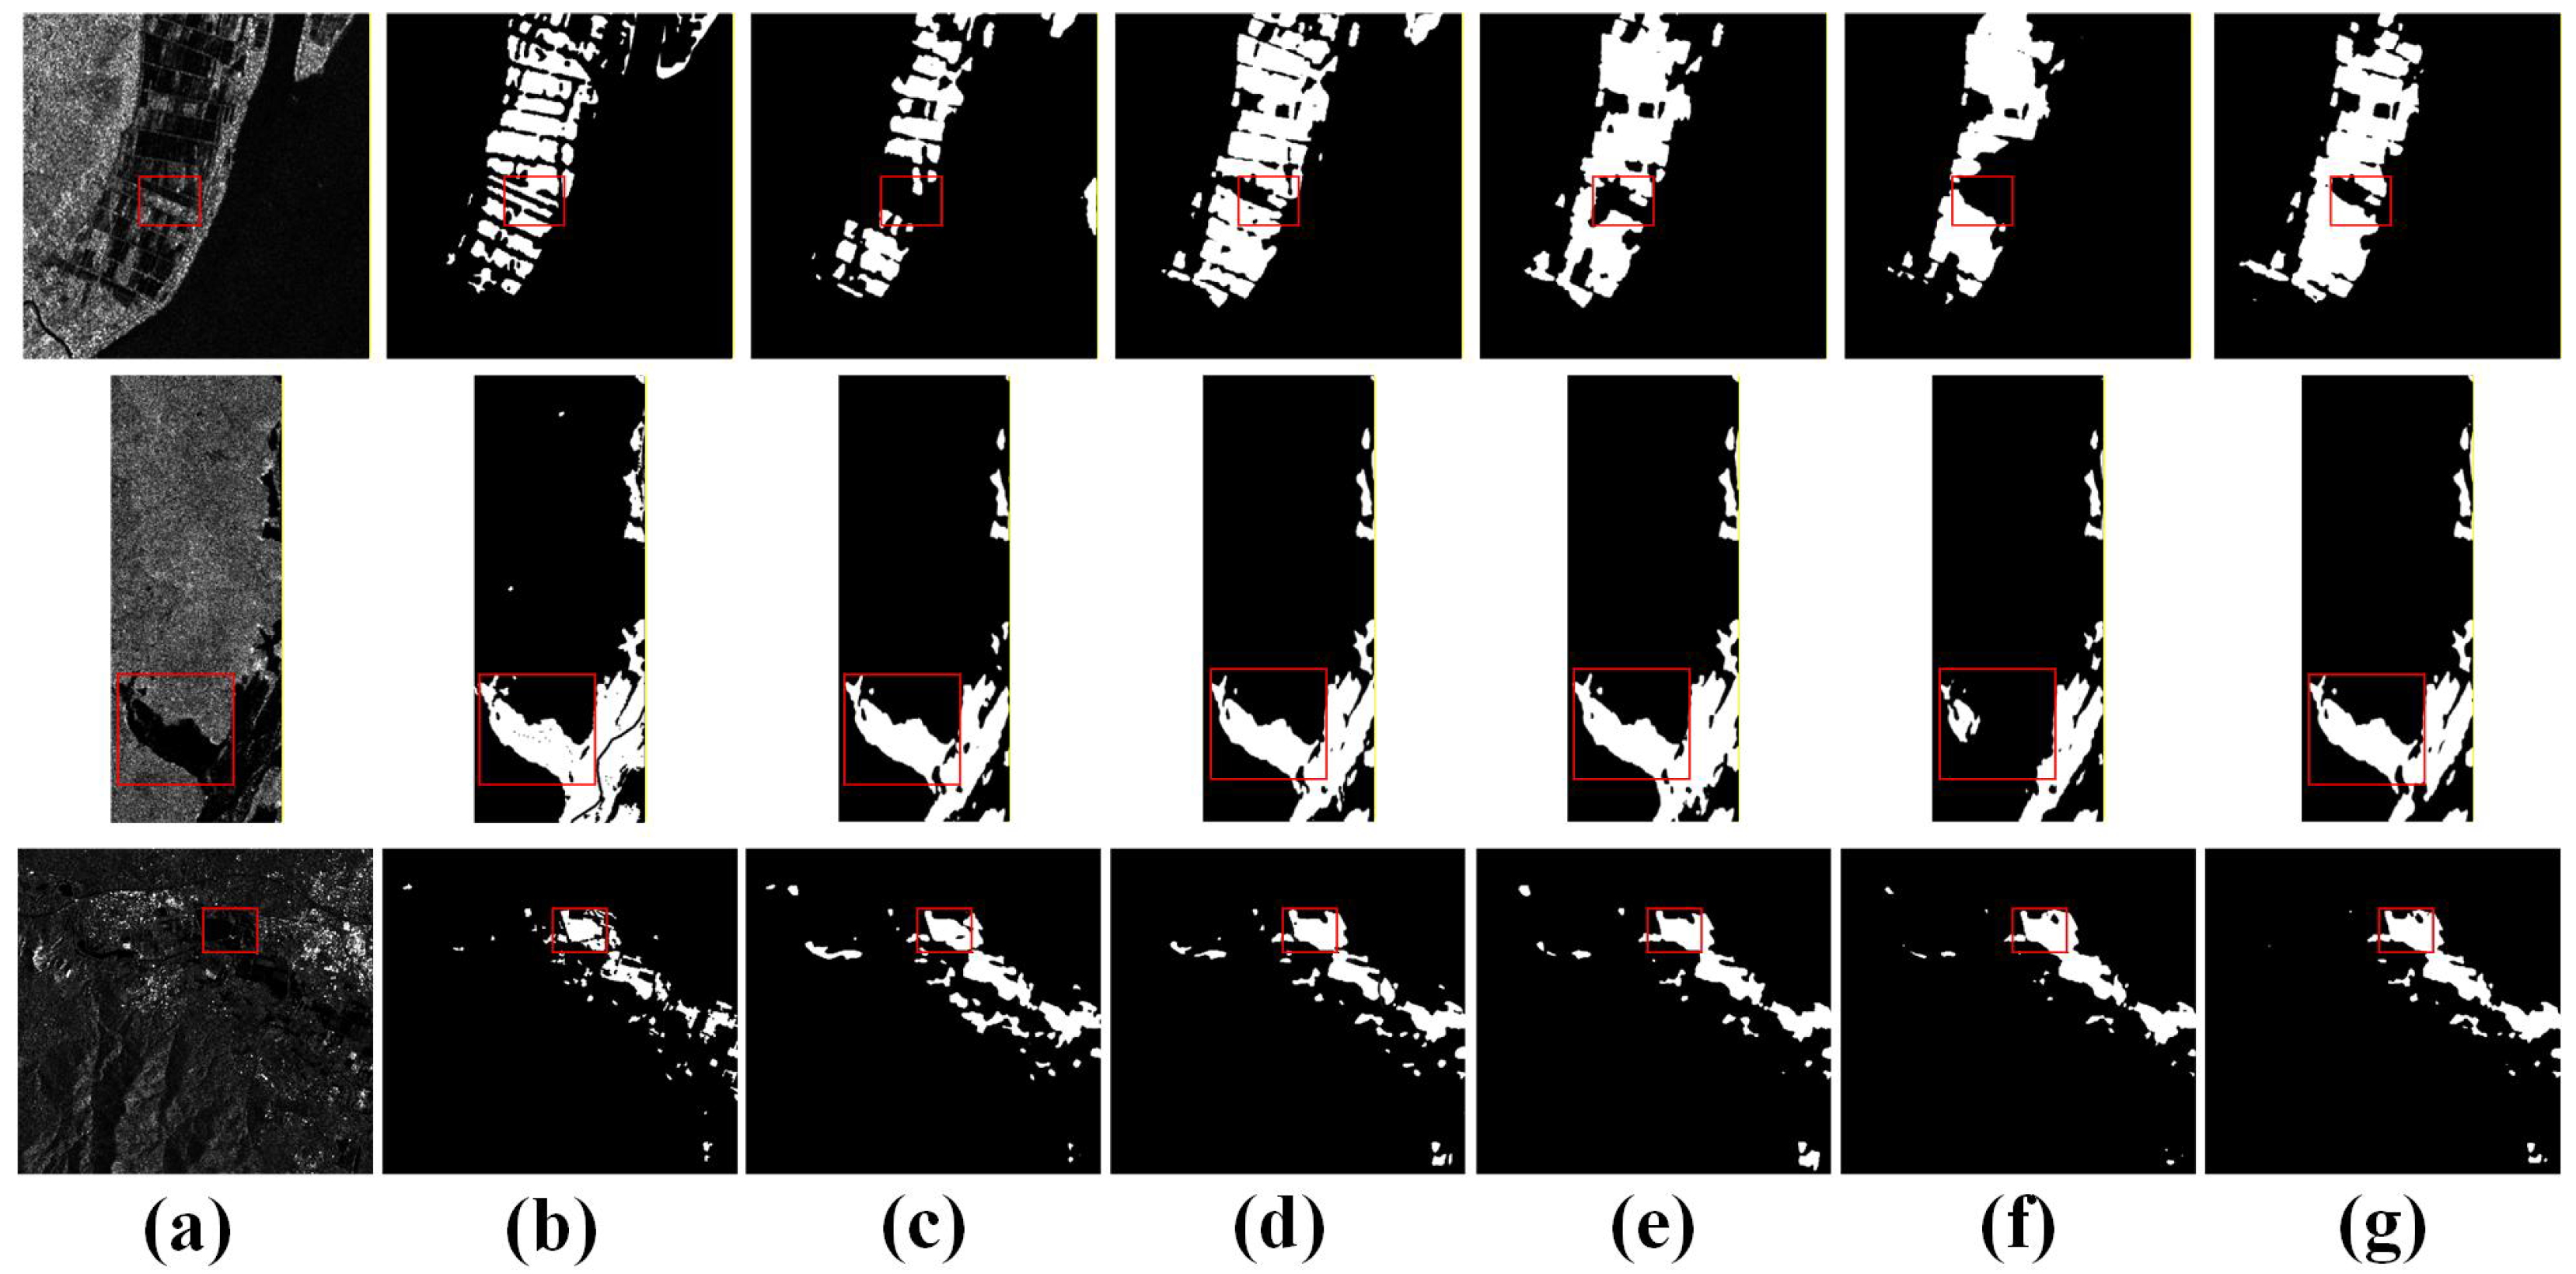
The visualization results of the ablation study are presented in Figure 11. We can see that removing the MFMSA block leads to a noticeably inferior recognition performance, with certain regions becoming difficult to identify. While the exclusion of the FUD blocks exhibits weaker recognition capability on subtle flood regions. As illustrated in the highlighted red box of the third row, the model without the FUD blocks identifies excessive flood areas, indicating its reduced ability to accurately capture fine-grained details. These results demonstrate again that both the MFMSA block and the FUD block play important and complementary roles in improving the performance of MFF-Net.
Figure 11.
Visualization results of MFF-Net with different blocks on the MMflood Dataset. (a) SAR images. (b) GT. (c) w/o MFMSA. (d) w/o FUD. (e) MFF-Net. The red box highlights the region of special interest.
3.7.2. Effectiveness of Different Loss Weight Settings
To evaluate the influence of the weight configuration between the cross-entropy loss and the Dice loss on model performance, a series of ablation experiments were conducted by testing different combinations of the two loss weights and , while keeping the network architecture, training strategy, and data partition unchanged. Table 8 compares the performance of different parameters. The bold numbers indicate the best results, while underlined numbers denote the second-best results.
Table 8.
Performance comparison of different loss weight settings.
The experimental results demonstrate that different loss weight settings have a certain impact on model performance, while the variations in overall performance metrics remain relatively small, indicating that the model exhibits a certain degree of robustness to changes in loss weights. When the cross-entropy loss weight and the Dice loss weight are of the same order of magnitude (e.g., = 1, = 2 and = 2, = 1), the differences among the comprehensive metrics are not significant, suggesting that the model is insensitive to moderate perturbations of the loss weights. As the disparity between the two weights increases (e.g., = 1, = 10 and = 10, = 1), the trade-off among different metrics becomes more pronounced: a larger tends to improve IoU and Recall, whereas a larger is more favorable for enhancing Precision, while the improvement in overall performance remains limited. In contrast, when = = 1, the model achieves the best performance in terms of F1 and OA, while maintaining a more balanced trade-off between Precision and Recall, thereby exhibiting superior overall performance.
As shown in Figure 12, varying the weights of the cross-entropy loss and Dice loss leads to noticeable differences in the delineation of flood regions, particularly along boundaries and small fragmented areas. Imbalanced loss weight settings tend to produce incomplete boundaries or miss fine-grained flood regions, whereas the balanced configuration with yields more coherent flood regions and improved boundary consistency, resulting in predictions that are visually closer to the ground truth.
Figure 12.
Visualization results of MFF-Net with different loss weight settings on MMflood Dataset. (a) SAR images. (b) GT. (c) = 1, = 2. (d) = 2, = 1. (e) = 1, = 10. (f) = 10, = 1. (g) = 1, = 1 (Ours). The red box highlights the region of special interest.
3.7.3. Effectiveness of Different Encoder Backbones
As mentioned before, some researchers have employed other types of backbones to address segmentation tasks. To further demonstrate the effectiveness of using Res2Net-50 in MFF-Net, we conducted experiments by replacing it with alternative backbones, such as VGG-16 and ResNet-50. Table 9 compares the performance of different backbones, including VGG-16, ResNet-50, and Res2Net-50, respectively. The bold numbers indicate the best results, while underlined numbers denote the second-best results.
Table 9.
Performance comparison of different encoder backbones.
It can be seen from Table 9 that Res2Net-50 achieves the best results across all metrics, with a mean IoU of 50.2% and an F1-Score of 62.09%, outperforming ResNet-50 and VGG-16 by a notable margin. Additionally, Res2Net-50 achieves the highest overall accuracy, precision, and recall, indicating its superior segmentation performance and robustness. These results demonstrate the effectiveness of Res2Net-50 as the backbone for MFF-Net compared to commonly used alternatives.
The visualization results of different encoder backbones are presented in Figure 13. In the first and third rows, the performance of the three backbones appears relatively similar. However, in the second row, significant differences can be observed in the detailed region within the highlighted red box: VGG-16 misses part of the area, ResNet-50 fails to identify it correctly, while Res2Net-50 produces results that are closer to the ground truth. It is mainly because Res2Net-50, with a deeper architecture, can capture more complex and fine-grained details during the feature extraction. Furthermore, the deeper structure allows for a larger receptive field, enabling the model to better integrate contextual information over larger areas.
Figure 13.
Visualization results of MFF-Net with different encoder backbones on the MMflood Dataset. (a) SAR images. (b) GT. (c) VGG-16. (d) ResNet-50. (e) Res2Net-50 (Ours). The red box highlights the region of special interest.
3.7.4. Analysis of Different Frequency Transform Strategies
To further investigate the impact of different frequency domain transform strategies within the multi-frequency in multi-scale attention block, we conducted experiments by replacing the current Wavelet transform with Discrete Cosine Transform (DCT), Fourier Transform (FT), and Laplace Transform (LT). This will help to assess how different frequency domain transform strategies influence the effectiveness and overall performance of the model. The results are listed in Table 10. The bold numbers indicate the best results, while underlined numbers denote the second-best results.
Table 10.
Performance comparison of different frequency transform strategies.
As shown in Table 10, the proposed wavelet-based method achieves the best performance, with an IoU of 50.2% and an F1-Score of 62.09%. Compared to the Fourier-based method, the wavelet approach improves the IoU by 2.57% and the F1-Score by 3.23%. Similarly, it outperforms the DCT-based method by 5.39% in IoU and 2.24% in F1-Score. When compared to the Laplace-based method, the wavelet approach shows an improvement of 7.33% in IoU and 7.62% in F1-Score. Additionally, the wavelet-based method also demonstrates favorable results in overall accuracy, precision, and recall.
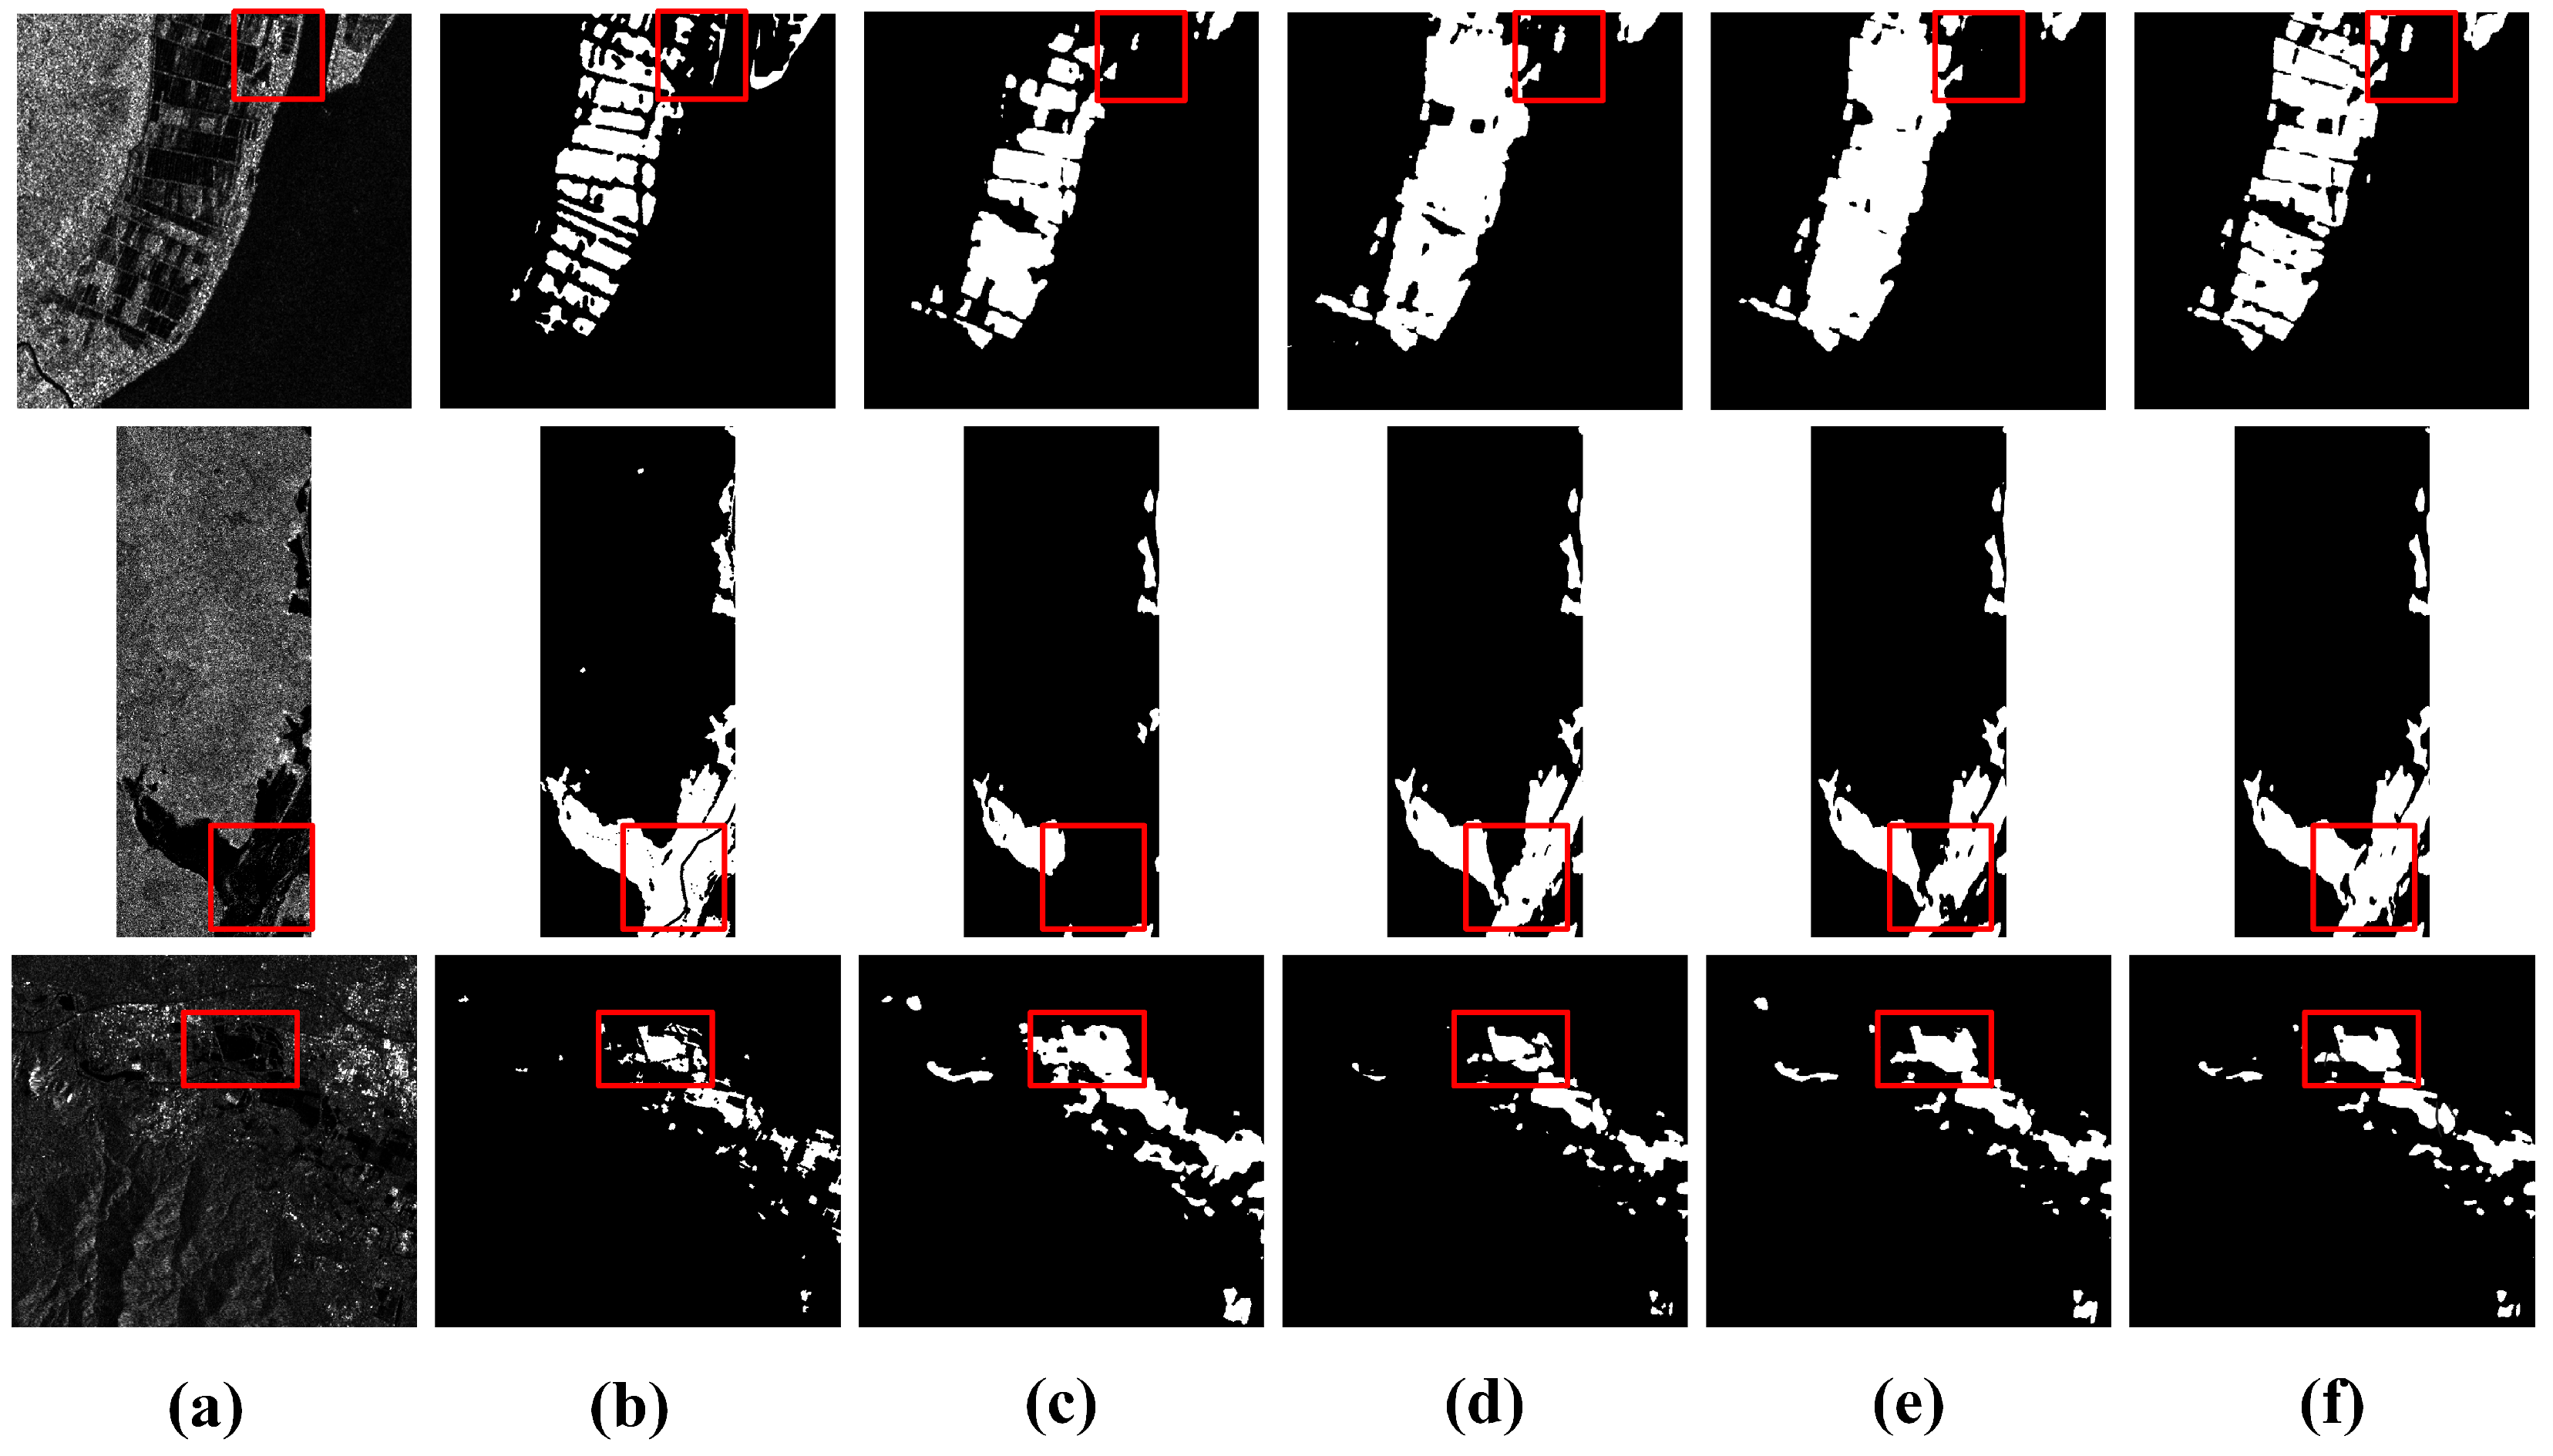
The visualization results of different frequency transform strategies are presented in Figure 14. Across the three examples, the wavelet transform demonstrates a stronger capability to capture intricate details within the source. Other strategies, however, exhibit some limitations, i.e., misclassifications or omissions, as shown in the highlighted red boxes. It is mainly because traditional frequency transform strategies, such as Fourier Transform and DCT, typically focus on analyzing global detail in food boundary areas. In contrast, the wavelet transform conducts localized frequency analysis, achieving a better balance between the frequency domain and spatial domain. This enables it to effectively capture the characteristic variations of different frequency components within flood areas, thereby enhancing segmentation performance.
Figure 14.
Visualization results of MFF-Net with different frequency transform strategies on the MMflood Dataset. (a) SAR images. (b) GT. (c) DCT. (d) Fourier. (e) Laplace. (f) Wavelet (Ours). The red box highlights the region of special interest.
3.7.5. Determination of the Wavelet Transform Levels
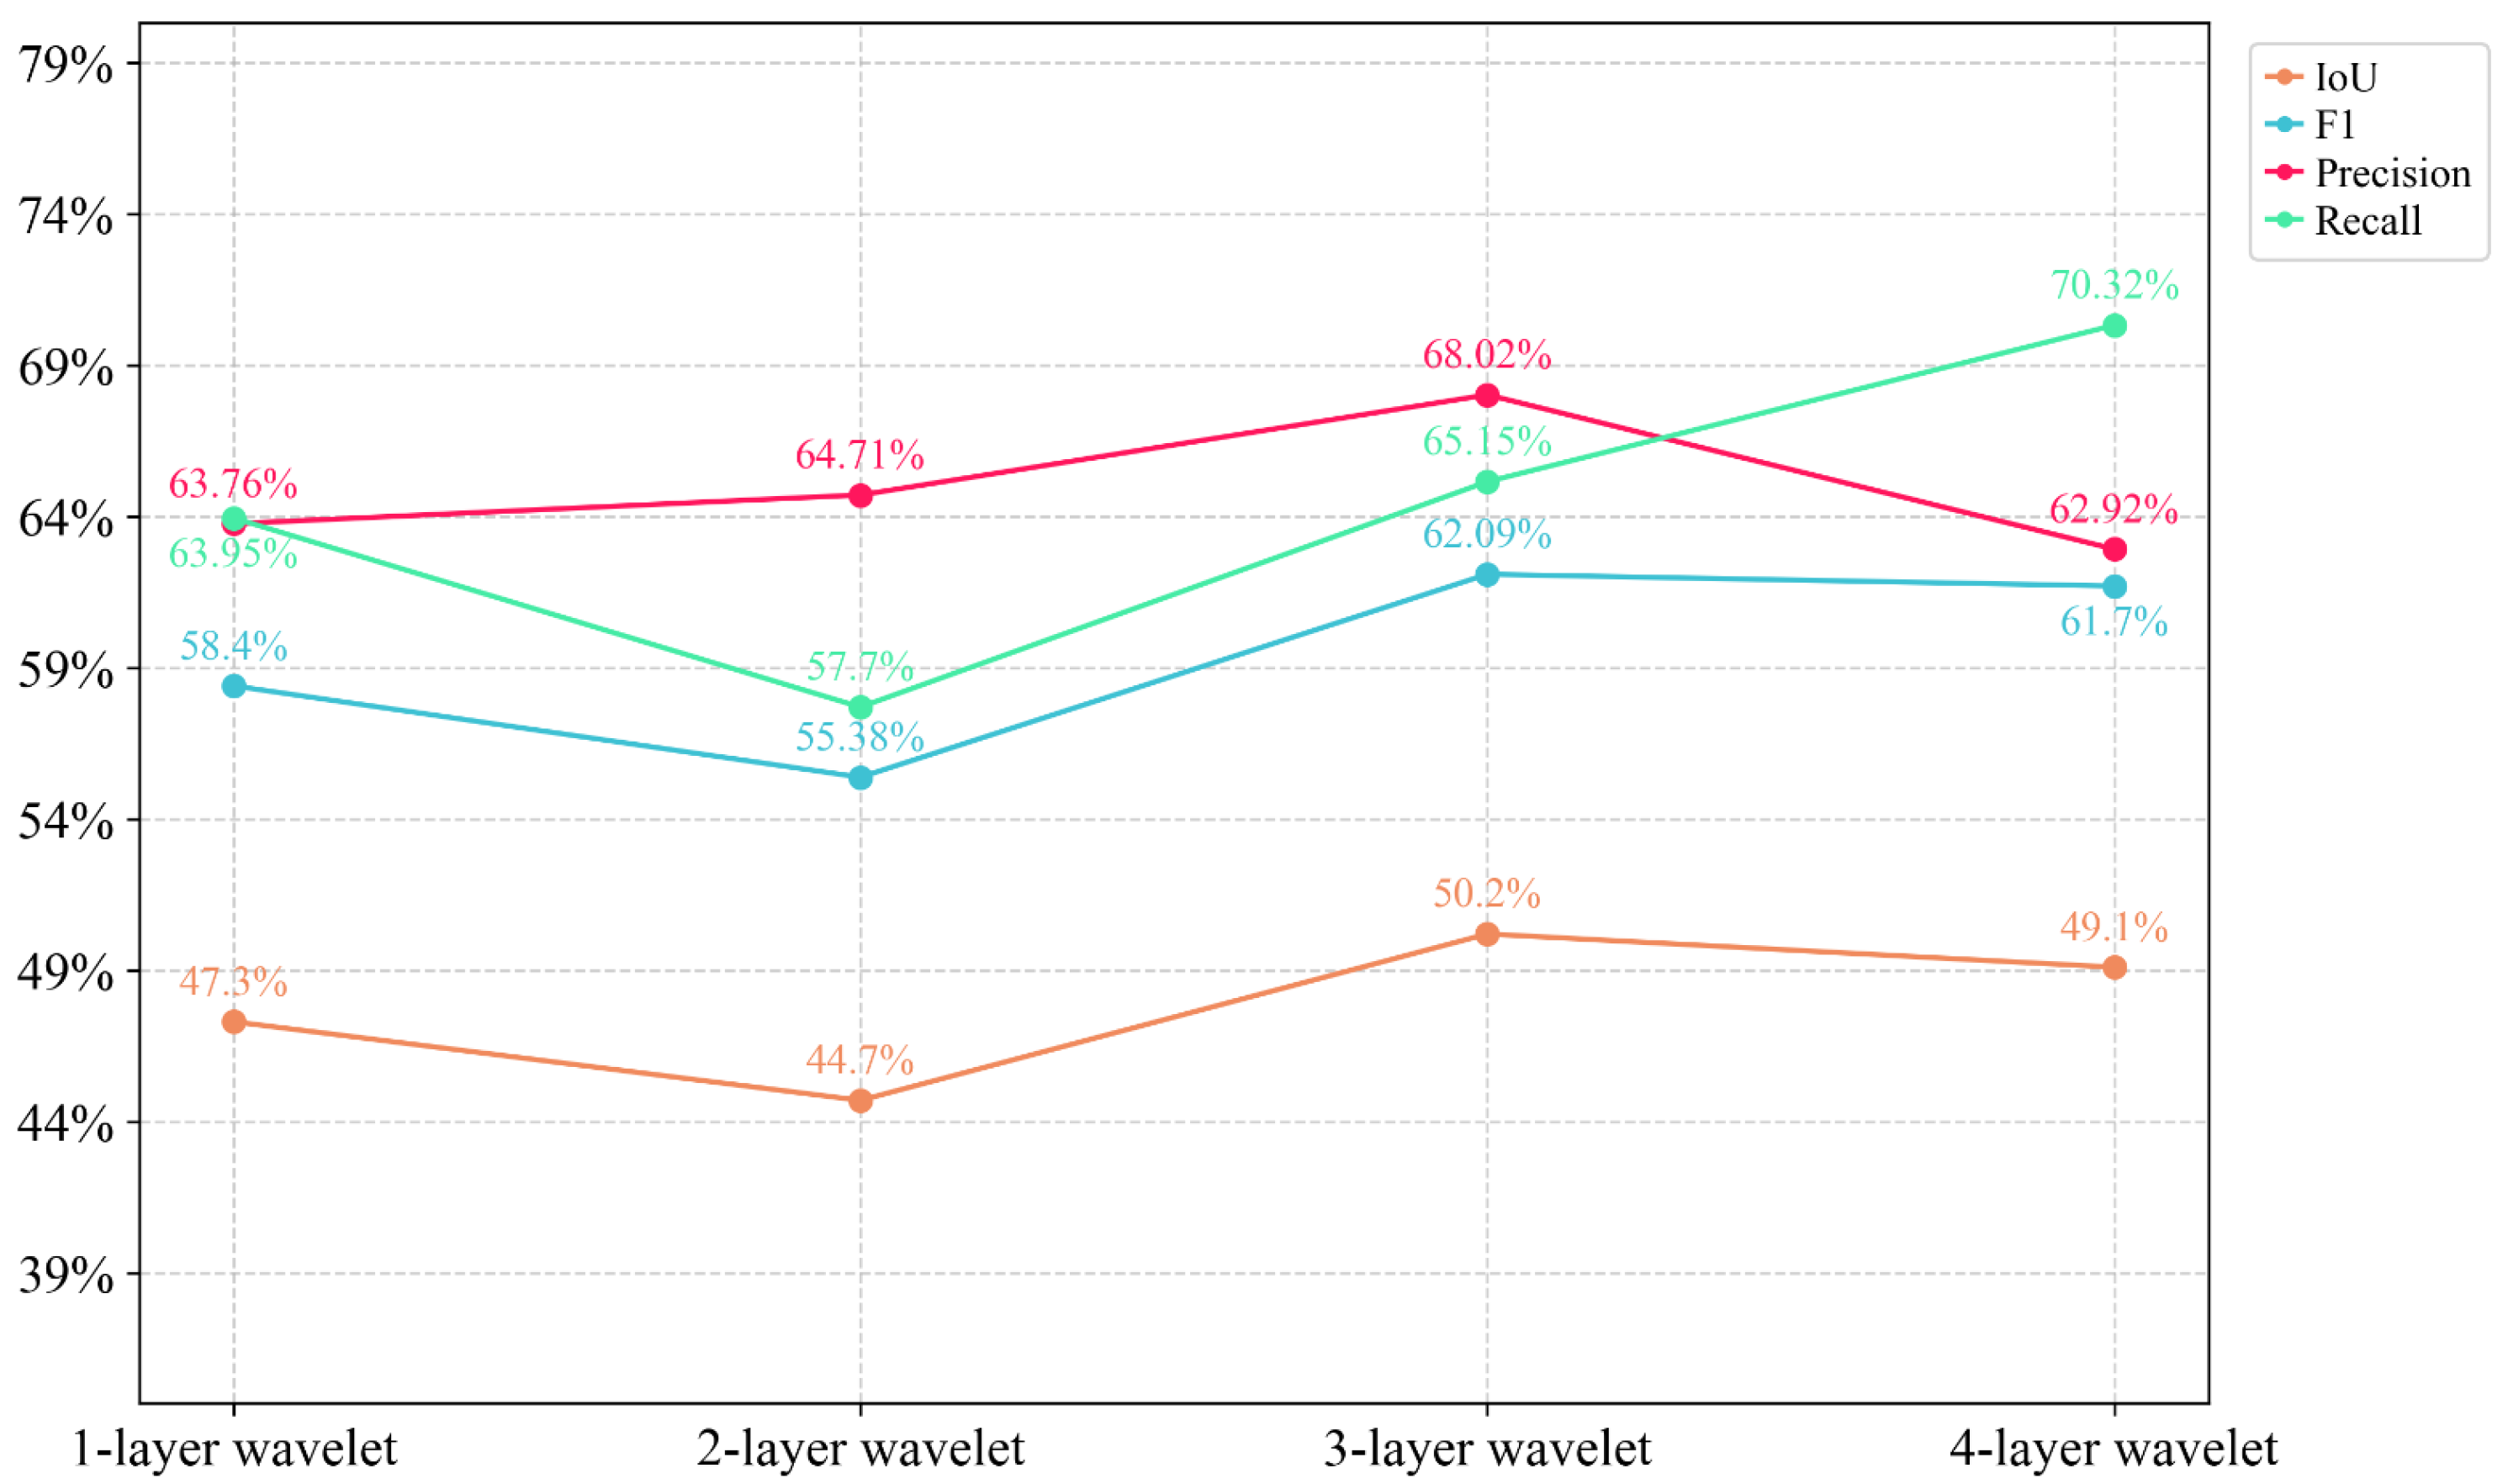
We adopt a three-level wavelet transform strategy in our approach. To demonstrate the effectiveness of this strategy, we conduct experiments on the MMflood Dataset using 1, 2, 3, and 4 levels of wavelet transform, respectively. The results are shown in Figure 15, where the x-axis indicates different levels, and the y-axis indicates the value of IoU, F1-score, precision, and recall.
Figure 15.
The results of MFF-Net using wavelet transforms at different levels.
As shown in Figure 15, the three-level wavelet transform achieves the best comprehensive performance across multiple metrics, particularly IoU, F1-score, and precision. It is mainly because the shallow-level transform may lose information, while the deep-level transform would induce redundancy. Consequently, we chose the three-level wavelet transform in our method.
3.7.6. Determination of Fuzzy Threshold Strategies
As addressed in Section 2, we utilize a step function to determine the fuzzy decision threshold at different scales. To demonstrate the effectiveness of this strategy, we conducted experiments by comparing the proposed threshold strategy with a uniformly low threshold , a uniformly high threshold , and a soft threshold strategy with the Sigmoid function. Note that the soft threshold strategy was applied in [53]. The results are listed in Table 11. The bold numbers indicate the best results, while underlined numbers denote the second-best results.
Table 11.
Performance comparison of different fuzzy thresholds.
Table 11 demonstrates that the proposed step function strategy achieves the best performance across all metrics, with an IoU of 50.2% and an F1-Score of 62.09%. It outperforms the uniformly low threshold () by 1.39% in IoU and 2.19% in F1-Score, and defeats the uniformly high threshold () by 0.42% in mIoU and 0.67% in F1-Score. It also shows a notable improvement in comparison with the Sigmoid-based soft threshold strategy by 0.61% in IoU and 0.51% in F1-Score. These results highlight the effectiveness of our specified threshold strategy against the multiple scales.
The visualization results of different fuzzy threshold strategies are presented in Figure 16. For the first and third rows, all strategies demonstrate relatively similar performance, with no significant differences observed. However, in the second row, the uniformly low threshold method misses large portions of the target areas, leading to significant under-segmentation. The uniformly high threshold and the Sigmoid-based strategies perform better but still fail to capture certain small details. In contrast, the proposed threshold strategy produces results that are more complete and accurate, effectively capturing details in the highlighted red boxes. These results validate that the proposed threshold strategy with a step function can better integrate the multi-scale features and distinguish the foreground and the background during the fuzzy decision.
Figure 16.
Visualization results of MFF-Net with different fuzzy thresholds on the MMflood Dataset. (a) SAR images. (b) GT. (c) Sigmoid feature fusion. (d) Low threshold (0.1). (e) High threshold (0.4). (f) MFF-Net (Ours). The red box highlights the region of special interest.
4. Discussion
This part primarily discusses the application to actual flood events, along with critical factors influencing the model and strengths and limitations.
4.1. Application to Actual Flood Events
To evaluate the performance of our model on real-world flood events, three flood cases were selected from the MMflood Dataset. The detection results are illustrated in Figure 17. Specifically, the first row corresponds to the flood event that occurred in northern Togo, West Africa, from 13 October to 16 October 2020; the second row shows the flood event in northern Bosnia and Herzegovina from 14 May to 28 May 2019; and the third row presents the flood event that occurred along the eastern coastal region of New South Wales, Australia, from 20 March to 25 March 2021. From the visualization results shown in Figure 17, it can be observed that the proposed model achieves satisfactory detection performance on real-world flood events. The predicted flood regions show good spatial agreement with the ground truth, effectively capturing the main inundated areas across different scenarios. Even in complex environments and fragmented flood regions, the model is able to delineate flood extents with limited false detections, demonstrating its robustness and applicability to real flood events.
Figure 17.
The performance on the actual flood events. (a) SAR images. (b) GT. (c) Detection results.
The quantitative evaluation results on three representative real flood events are summarized in Table 12. The results indicate that the proposed model is able to produce reliable flood delineation outcomes across different flood scenarios. Consistent performance is observed for all evaluated metrics, demonstrating the effectiveness of the proposed approach on real-world flood events.
Table 12.
Performance comparison of actual flood events.
4.2. Impact Factor Analysis
This subsection explores three critical aspects that affect the model, specifically the polarization modes and sensor.
4.2.1. Polarization Modes
The generalization on other region experiments indicates that polarization mode selection has a certain influence on SAR-based flood detection. According to Figure 9 and Figure 10, single-polarization SAR images can achieve acceptable flood detection performance, but their effectiveness is inferior to dual-polarization methods due to the lack of polarization information. The dual-polarization approach can combine complementary advantages, potentially enabling more comprehensive flood mapping. However, single-polarization remains practically valuable for real-time monitoring scenarios with limited data availability, where its effective visualization performance offers a feasible solution for practical applications.
4.2.2. Sensor
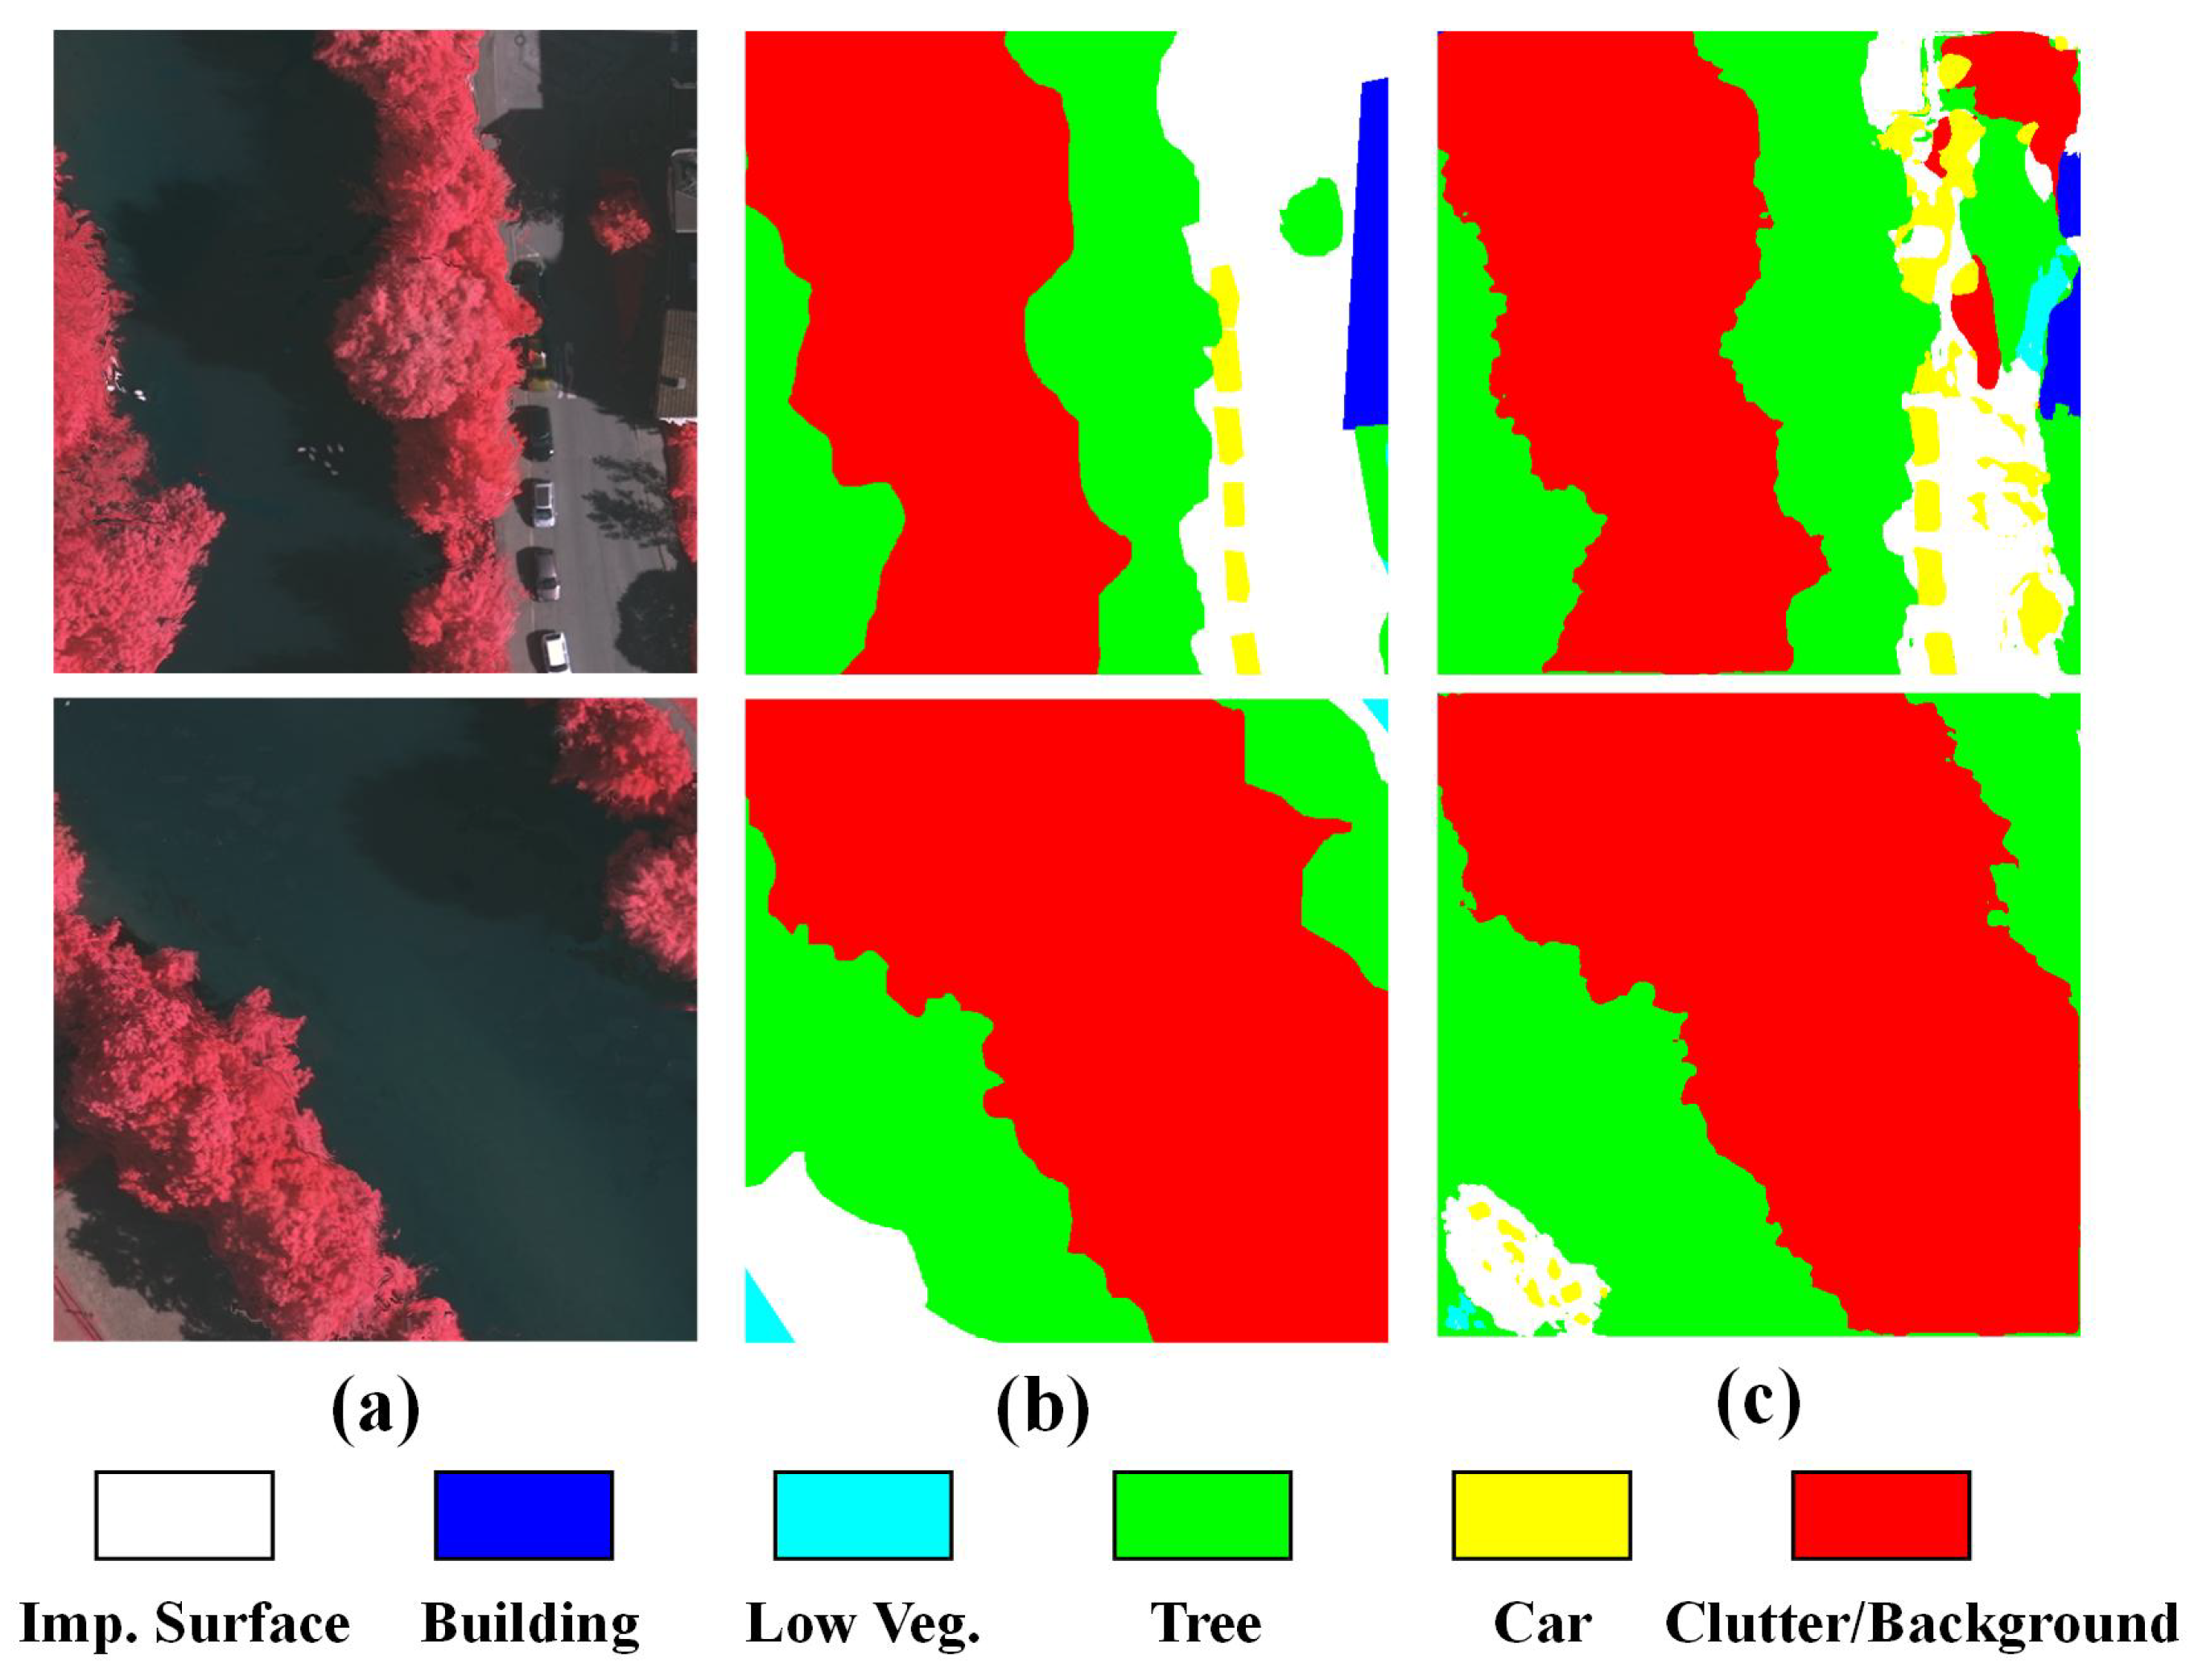
The experiment selected a subset of aerial multispectral optical images containing water bodies from the ISPRS Vaihingen Dataset [54] to evaluate cross-sensor water detection performance. The ISPRS Vaihingen Dataset comprises aerial multispectral optical imagery of the Vaihingen region in Germany, captured using a multispectral airborne sensor system with four spectral bands (NIR, R, G, B). The dataset contains 33 high-resolution true orthophoto tiles averaging 2494 × 2064 pixels each. These images provide five annotated land cover classes (impervious surfaces, buildings, low vegetation, trees, and vehicles) plus background. As shown in Figure 18, the results demonstrate that the model predictions exhibit strong agreement with the ground truth, accurately identifying water regions. These findings validate the method’s effectiveness on optical imagery and suggest its potential adaptability to data from different sensors.
Figure 18.
The performance of water detection from aerial multispectral optical images. (a) Raw images. (b) GT. (c) Detection results.
4.3. Strengths and Limitations
In this study, we focus on flood area detection in SAR imagery with the objective of facilitating effective application of the proposed model in real-world flood scenarios. Experimental results on four SAR-based datasets demonstrate that the proposed approach maintains stable performance across different data distributions, indicating a certain degree of generalization ability and robustness.
From a methodological perspective, the MFMSA block contributes to enhanced feature representation by capturing complementary information in the frequency domain. The fuzzy uncertainty fusion module helps alleviate the influence of noise by retaining fine-scale feature details during the fusion process. In addition, the FUD block enables the model to identify subtle flood regions that may be difficult to distinguish in complex SAR scenes. Collectively, these components contribute to improved robustness of MFF-Net when applied to diverse flood detection scenarios.
While the model can be adapted to other remote sensing data sources through training, our evaluation across multiple datasets and real flood cases reveals certain limitations of MFF-Net. Specifically, datasets such as MMflood utilize VV and VH dual-polarization images stored in linear format, while Sen1Floods11 contains VV and VH dual-polarization data stored in decibel (dB) scale. We observe performance discrepancies between these formats, as the conversion from dB to linear scale introduces quantization errors and dynamic range loss, preventing optimal results. Furthermore, MFF-Net demonstrates superior performance with dual-polarization SAR imagery. Our generalization tests using pre-trained models on flood events in Peru and other actual cases show that direct application to new images with single-polarization (either VV or VH) yields inferior results compared to dual-polarization inputs. We attribute this to the richer scattering information provided by dual-polarization data, where the complementary characteristics of polarization features enable better suppression of system noise, thereby improving flood detection accuracy.
In summary, our method achieves strong performance in flood detection on SAR imagery, as well as in actual flood events and cross-domain segmentation tasks. However, due to the complexity of flood phenomena, relying solely on single-polarization SAR or dB-scaled data can limit detection accuracy. Future research will focus on enhancing the model’s adaptability to various data formats and extracting more informative features from multiple polarization modes to improve the generalization capability and comprehensiveness of flood area detection.
5. Conclusions
This paper proposes a Multi-Frequency Fuzzy Uncertainty Fusion Network (MFF-Net) for flood detection. It integrates spatial and frequency-domain features through a dual-branch feature extraction module. Particularly, we designed an MFMSA block in the frequency-domain feature extraction to enhance the overall accuracy of pixel-aware flood detection. To further improve the detection of subtle flood areas, particularly those that are easily overlooked, we design a fuzzy uncertainty fusion module. It employs an FUD block that applies adaptive fuzzy thresholds to features across different scales, facilitating more effective multi-scale information capture and improving detail representation. Consequently, the combined effects of all the modules and blocks boost the performance of fine-grained flood detection. In the future, we will further investigate the underlying relationship between the frequency domain and the feature domain features. We will also explore the fuzzy decision towards the subtle regions.
Author Contributions
Conceptualization, X.W.; methodology, Y.G.; validation, Y.G.; formal analysis, Y.G. and X.W.; investigation, Y.G.; resources, R.L.; writing—original draft preparation, Y.G. and X.W.; writing—review and editing, X.W., Z.Z., X.C., R.L. and X.L.; supervision, Z.Z., X.C. and X.L. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by the National Science and Technology Major Project under Grant 2022ZD0119502 and the National Natural Science Foundation of China under Grant 62201017.
Data Availability Statement
The original contributions presented in the study are included in the article, further inquiries can be directed to the corresponding author.
Acknowledgments
The authors would like to thank the ESA for providing the Sentinel-1 SAR data.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Prieto, C.; Patel, D.; Han, D. Preface: Advances in flood risk assessment and management. Nat. Hazards Earth Syst. Sci. 2020, 20, 1045–1048. [Google Scholar] [CrossRef] [Scilit]
- Yu, H.; Wang, R.; Li, P.; Zhang, P. Flood Detection in Polarimetric SAR Data Using Deformable Convolutional Vision Model. Water 2023, 15, 4202. [Google Scholar] [CrossRef] [Scilit]
- Schumann, G.J.; Brakenridge, G.R.; Kettner, A.J.; Kashif, R.; Niebuhr, E. Assisting flood disaster response with earth observation data and products: A critical assessment. Remote Sens. 2018, 10, 1230. [Google Scholar] [CrossRef] [Scilit]
- Diriba, D.; Takele, T.; Karuppannan, S.; Husein, M. Flood hazard analysis and risk assessment using remote sensing, GIS, and AHP techniques: A case study of the Gidabo Watershed, main Ethiopian Rift, Ethiopia. Geomat. Nat. Hazards Risk 2024, 15, 2361813. [Google Scholar] [CrossRef] [Scilit]
- Singh, G.; Rawat, K.S. Mapping flooded areas utilizing Google Earth Engine and open SAR data: A comprehensive approach for disaster response. Discov. Geosci. 2024, 2, 5. [Google Scholar] [CrossRef] [Scilit]
- Fox, S.; Agyemang, F.; Hawker, L.; Neal, J. Integrating social vulnerability into high-resolution global flood risk mapping. Nat. Commun. 2024, 15, 3155. [Google Scholar] [CrossRef] [Scilit]
- Patil, S.; Sawant, S.; Joshi, A. Flood detection using remote sensing and deep learning approaches. In Proceedings of the 2023 14th International Conference on Computing Communication and Networking Technologies (ICCCNT), Delhi, India, 6–8 July 2023; IEEE: Piscataway, NJ, USA, 2023; pp. 1–6. [Google Scholar]
- Amitrano, D.; Di Martino, G.; Di Simone, A.; Imperatore, P. Flood detection with SAR: A review of techniques and datasets. Remote Sens. 2024, 16, 656. [Google Scholar] [CrossRef] [Scilit]
- Liang, J.; Liu, D. A local thresholding approach to flood water delineation using Sentinel-1 SAR imagery. ISPRS J. Photogramm. Remote Sens. 2020, 159, 53–62. [Google Scholar] [CrossRef] [Scilit]
- Rambour, C.; Audebert, N.; Koeniguer, E.; Le Saux, B.; Crucianu, M.; Datcu, M. Flood detection in time series of optical and sar images. Int. Arch. Photogramm. Remote Sens. Spat. Inf. Sci. 2020, 43, 1343–1346. [Google Scholar] [CrossRef] [Scilit]
- Saleh, T.; Holail, S.; Zahran, M.; Xiao, X.; Xia, G.S. LiST-Net: Enhanced flood mapping with lightweight SAR transformer network and dimension-wise attention. IEEE Trans. Geosci. Remote Sens. 2024, 62, 5211817. [Google Scholar] [CrossRef] [Scilit]
- Han, C.; Jia, C.; Sun, Y. Remote Sensing Monitoring and Disaster Assessment of Flood Based on Sentinel-1B Sar Data. In Proceedings of the IGARSS 2022—2022 IEEE International Geoscience and Remote Sensing Symposium, Kuala Lumpur, Malaysia, 17–22 July 2022; IEEE: Piscataway, NJ, USA, 2022; pp. 3393–3396. [Google Scholar]
- Wen, X.; Zhao, J.; Wang, H.; Liu, C.; Shao, C.; Dong, Y. Unconditional Image Thresholding Approach of Optical and Sar Data for Large-Scale Flood Mapping. In Proceedings of the IGARSS 2024—2024 IEEE International Geoscience and Remote Sensing Symposium, Athens, Greece, 7–12 July 2024; IEEE: Piscataway, NJ, USA, 2024; pp. 3010–3013. [Google Scholar]
- Long, S.; Fatoyinbo, T.E.; Policelli, F. Flood extent mapping for Namibia using change detection and thresholding with SAR. Environ. Res. Lett. 2014, 9, 035002. [Google Scholar] [CrossRef] [Scilit]
- Pulvirenti, L.; Marzano, F.S.; Pierdicca, N.; Mori, S.; Chini, M. Discrimination of water surfaces, heavy rainfall, and wet snow using COSMO-SkyMed observations of severe weather events. IEEE Trans. Geosci. Remote Sens. 2013, 52, 858–869. [Google Scholar] [CrossRef]
- García-Pintado, J.; Mason, D.C.; Dance, S.L.; Cloke, H.L.; Neal, J.C.; Freer, J.; Bates, P.D. Satellite-supported flood forecasting in river networks: A real case study. J. Hydrol. 2015, 523, 706–724. [Google Scholar] [CrossRef] [Scilit]
- Hostache, R.; Chini, M.; Giustarini, L.; Neal, J.; Kavetski, D.; Wood, M.; Corato, G.; Pelich, R.M.; Matgen, P. Near-real-time assimilation of SAR-derived flood maps for improving flood forecasts. Water Resour. Res. 2018, 54, 5516–5535. [Google Scholar] [CrossRef] [Scilit]
- Schumann, G.; Giustarini, L.; Tarpanelli, A.; Jarihani, B.; Martinis, S. Flood modeling and prediction using earth observation data. Surv. Geophys. 2023, 44, 1553–1578. [Google Scholar] [CrossRef] [Scilit]
- Li, Y.; Matgen, P.; Chini, M. Uncertainty Estimation in SAR-Based Flood Mapping Via Density-Aware Deep Neural Networks. In Proceedings of the IGARSS 2024—2024 IEEE International Geoscience and Remote Sensing Symposium, Athens, Greece, 7–12 July 2024; IEEE: Piscataway, NJ, USA, 2024; pp. 1760–1763. [Google Scholar]
- Moges, E.; Demissie, Y.; Larsen, L.; Yassin, F. Sources of hydrological model uncertainties and advances in their analysis. Water 2021, 13, 28. [Google Scholar] [CrossRef] [Scilit]
- Nemni, E.; Bullock, J.; Belabbes, S.; Bromley, L. Fully convolutional neural network for rapid flood segmentation in synthetic aperture radar imagery. Remote Sens. 2020, 12, 2532. [Google Scholar] [CrossRef] [Scilit]
- Wu, H.; Song, H.; Huang, J.; Zhong, H.; Zhan, R.; Teng, X.; Qiu, Z.; He, M.; Cao, J. Flood detection in dual-polarization SAR images based on multi-scale deeplab model. Remote Sens. 2022, 14, 5181. [Google Scholar] [CrossRef] [Scilit]
- Zhu, B.; Xia, Y.; Zhou, Y.; Lv, X.; Liu, M. Multiscale Feature-Enhanced Water Body Detector of Truncated Gaussian Clutter in SAR Imagery. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2024, 18, 3253–3266. [Google Scholar] [CrossRef] [Scilit]
- Miao, R.; Ren, T.; Zhou, K.; Zhang, Y.; Song, J.; Zhang, G.; Wang, J. A Method of Water Body Extraction Based on Multi-Scale Feature and Global Context Information. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2024, 17, 12138–12152. [Google Scholar] [CrossRef] [Scilit]
- Qin, C.H.; Li, W.B.; Zhang, T.Y.; Ji, W.B.; Feng, X.H.; Ren, Y. Improved DeepLabv3+ based flood water body extraction model for SAR imagery. In Proceedings of the IGARSS 2024-2024 IEEE International Geoscience and Remote Sensing Symposium, Athens, Greece, 7–12 July 2024; IEEE: Piscataway, NJ, USA, 2024; pp. 1196–1199. [Google Scholar]
- Huang, B.; Li, P.; Lu, H.; Yin, J.; Li, Z.; Wang, H. WaterDetectionNet: A new deep learning method for flood mapping with SAR image convolutional neural network. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2024, 17, 14471–14485. [Google Scholar]
- Sanderson, J.; Mao, H.; Abdullah, M.A.; Al-Nima, R.R.O.; Woo, W.L. Optimal fusion of multispectral optical and SAR images for flood inundation mapping through explainable deep learning. Information 2023, 14, 660. [Google Scholar] [CrossRef] [Scilit]
- Fawakherji, M.; Hashemi-Beni, L. Flood detection and mapping through multi-resolution sensor fusion: Integrating UAV optical imagery and satellite SAR data. Geomat. Nat. Hazards Risk 2025, 16, 2493225. [Google Scholar]
- Kim, S.Y.; Lee, Y.; Park, S.E. On Flood Detection Using Dual-Polarimetric SAR Observation. Remote Sens. 2025, 17, 1931. [Google Scholar]
- Saleh, T.; Holail, S.; Xiao, X.; Xia, G.S. High-precision flood detection and mapping via multi-temporal SAR change analysis with semantic token-based transformer. Int. J. Appl. Earth Obs. Geoinf. 2024, 131, 103991. [Google Scholar] [CrossRef] [Scilit]
- Zhang, R.; Zhang, Q.; Zhang, G. LSRFormer: Efficient transformer supply convolutional neural networks with global information for aerial image segmentation. IEEE Trans. Geosci. Remote Sens. 2024, 62, 5610713. [Google Scholar] [CrossRef] [Scilit]
- Li, H.; Qiu, K.; Chen, L.; Mei, X.; Hong, L.; Tao, C. SCAttNet: Semantic segmentation network with spatial and channel attention mechanism for high-resolution remote sensing images. IEEE Geosci. Remote Sens. Lett. 2020, 18, 905–909. [Google Scholar] [CrossRef] [Scilit]
- Li, J.; He, W.; Cao, W.; Zhang, L.; Zhang, H. UANet: An Uncertainty-Aware Network for Building Extraction From Remote Sensing Images. IEEE Trans. Geosci. Remote Sens. 2024, 62, 5608513. [Google Scholar] [CrossRef] [Scilit]
- Redmon, J. You only look once: Unified, real-time object detection. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Las Vegas, NV, USA, 27–30 June 2016. [Google Scholar]
- Li, Y.; Li, Q.; Pan, J.; Zhou, Y.; Zhu, H.; Wei, H.; Liu, C. Sod-yolo: Small-object-detection algorithm based on improved yolov8 for UAV images. Remote Sens. 2024, 16, 3057. [Google Scholar] [CrossRef] [Scilit]
- Khanam, R.; Hussain, M. Yolov11: An overview of the key architectural enhancements. arXiv 2024, arXiv:2410.17725. [Google Scholar] [CrossRef] [Scilit]
- Wang, C.Y.; Yeh, I.H.; Mark Liao, H.Y. Yolov9: Learning what you want to learn using programmable gradient information. In Proceedings of the European Conference on Computer Vision, Milan, Italy, 29 September–4 October 2024; Springer: Cham, Switzerland, 2025; pp. 1–21. [Google Scholar]
- Zhang, S.; Zhang, B.; Wu, Y.; Zhou, H.; Jiang, J.; Ma, J. Segclip: Multimodal visual-language and prompt learning for high-resolution remote sensing semantic segmentation. IEEE Trans. Geosci. Remote Sens. 2024, 62, 5646316. [Google Scholar] [CrossRef] [Scilit]
- Wu, H.; Du, Z.; Zhong, D.; Wang, Y.; Tao, C. FSVLM: A Vision-Language Model for Remote Sensing Farmland Segmentation. IEEE Trans. Geosci. Remote Sens. 2025, 63, 4402813. [Google Scholar] [CrossRef] [Scilit]
- Gao, S.H.; Cheng, M.M.; Zhao, K.; Zhang, X.Y.; Yang, M.H.; Torr, P. Res2net: A new multi-scale backbone architecture. IEEE Trans. Pattern Anal. Mach. Intell. 2019, 43, 652–662. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Hashemi, M.G.; Jalilvand, E.; Alemohammad, H.; Tan, P.N.; Das, N.N. Review of synthetic aperture radar with deep learning in agricultural applications. ISPRS J. Photogramm. Remote Sens. 2024, 218, 20–49. [Google Scholar] [CrossRef] [Scilit]
- Yang, S.; Wang, L.; Yuan, Y.; Fan, L.; Wu, Y.; Sun, W.; Yang, G. Recognition of small water bodies under complex terrain based on SAR and optical image fusion algorithm. Sci. Total Environ. 2024, 946, 174329. [Google Scholar] [CrossRef] [Scilit]
- Yang, Y.; Yuan, G.; Li, J. SFFNet: A Wavelet-Based Spatial and Frequency Domain Fusion Network for Remote Sensing Segmentation. IEEE Trans. Geosci. Remote Sens. 2024, 62, 3000617. [Google Scholar] [CrossRef] [Scilit]
- Chen, K.; Zhang, K.; Pang, F.; Gao, X.; Shi, G. RMANet: Refined-mixed attention network for progressive low-light image enhancement. Signal Process. 2025, 227, 109689. [Google Scholar] [CrossRef] [Scilit]
- Milletari, F.; Navab, N.; Ahmadi, S.A. V-net: Fully convolutional neural networks for volumetric medical image segmentation. In Proceedings of the 2016 Fourth International Conference on 3D Vision (3DV), Stanford, CA, USA, 25–28 October 2016; IEEE: Piscataway, NJ, USA, 2016; pp. 565–571. [Google Scholar]
- Montello, F.; Arnaudo, E.; Rossi, C. Mmflood: A multimodal dataset for flood delineation from satellite imagery. IEEE Access 2022, 10, 96774–96787. [Google Scholar] [CrossRef] [Scilit]
- Bonafilia, D.; Tellman, B.; Anderson, T.; Issenberg, E. Sen1Floods11: A georeferenced dataset to train and test deep learning flood algorithms for sentinel-1. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops, Virtual, 14–19 June 2020; pp. 210–211. [Google Scholar]
- Paul, S.; Ganju, S. Flood segmentation on sentinel-1 SAR imagery with semi-supervised learning. arXiv 2021, arXiv:2107.08369. [Google Scholar] [CrossRef] [Scilit]
- Jiang, C.; Zhang, H.; Wang, C.; Ge, J.; Wu, F. Water surface mapping from Sentinel-1 imagery based on attention-UNet3+: A case study of Poyang Lake region. Remote Sens. 2022, 14, 4708. [Google Scholar] [CrossRef] [Scilit]
- Henry, C.; Azimi, S.M.; Merkle, N. Road segmentation in SAR satellite images with deep fully convolutional neural networks. IEEE Geosci. Remote Sens. Lett. 2018, 15, 1867–1871. [Google Scholar]
- Dong, Y.; Li, F.; Hong, W.; Zhou, X.; Ren, H. Land cover semantic segmentation of port area with high resolution SAR images based on SegNet. In Proceedings of the 2021 SAR in Big Data Era (BIGSARDATA), Nanjing, China, 22–24 September 2021; IEEE: Piscataway, NJ, USA, 2021; pp. 1–4. [Google Scholar]
- Shen, M.; Zhang, F.; Wu, C. Flood Inundation Extraction Based on Decision-Level Data Fusion: A Case in Peru. ISPRS Ann. Photogramm. Remote Sens. Spat. Inf. Sci. 2022, 10, 133–140. [Google Scholar] [CrossRef] [Scilit]
- Mondal, K.; Dutta, P.; Bhattacharyya, S. Fuzzy logic based gray image extraction and segmentation. Int. J. Sci. Eng. Res. 2012, 3, 1–14. [Google Scholar]
- Markus Gerke, I. Use of the Stair Vision Library Within the ISPRS 2D Semantic Labeling Benchmark (Vaihingen). 2014. Available online: https://www.researchgate.net/publication/270104226_Use_of_the_Stair_Vision_Library_within_the_ISPRS_2D_Semantic_Labeling_Benchmark_Vaihingen (accessed on 8 December 2025).

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.