


Abstract
Forest ecosystems, as vital natural resources, are increasingly endangered by wildfires. Effective forest fire management relies on the accurate and early detection of small–scale flames and smoke. However, the complex and dynamic forest environment, along with the small size and irregular shape of early fire indicators, poses significant challenges to reliable early warning systems. To address these issues, this paper introduces SER–YOLOv8, an enhanced detection model based on the YOLOv8 architecture. The model incorporates the RepNCSPELAN4 module and an SPPELAN structure to strengthen multi-scale feature representation. Furthermore, to improve small target localization, the Normalized Wasserstein Distance (NWD) loss is adopted, providing a more robust similarity measure than traditional IoU–based losses. The newly designed SERDet module deeply integrates a multi–scale feature extraction mechanism with a multi-path fused attention mechanism, significantly enhancing the recognition capability for flame targets under complex backgrounds. Depthwise separable convolution (DWConv) is utilized to reduce parameters and boost inference efficiency. Experiments on the M4SFWD dataset show that the proposed method improves mAP50 by 1.2% for flames and 2.4% for smoke, with a 1.5% overall gain in mAP50–95 over the baseline YOLOv8, outperforming existing mainstream models and offering a reliable solution for forest fire prevention.
1. Introduction
Forests serve as the core component of Earth’s ecosystems, playing an irreplaceable role in maintaining global biodiversity, regulating climate, conserving water sources, and preventing soil erosion [1,2]. However, forest fires, as a severe ecological disturbance, not only disrupt forest structure and function—leading to biodiversity loss and habitat degradation [3]—but also release substantial amounts of carbonaceous substances into the atmosphere, exacerbating climate change [4]. Furthermore, they may trigger soil erosion and water pollution, posing profound threats to ecological security and human society [5].
Globally, many countries have been frequently impacted by major forest fires. For instance, the United States, Australia, Brazil, and Canada have all experienced large–scale and highly destructive fire events [6,7,8,9]. The 2023 Lahaina wildfire in the United States resulted in the most severe casualties and property losses since 1900 [10]. Between 2010 and 2019, the annual average burned area from forest fires in the United States exceeded 6 million acres, with direct economic losses surpassing US$6 billion [11]. The 2022 Australian bushfires destroyed over 1500 buildings, leading to approximately 23 fatalities and significant animal casualties [12]. Furthermore, the 2018 California wildfires and the 2019 Amazon rainforest fires each burned millions of acres of land, causing profound ecological and socio-economic losses [13]. Similar situations have been observed in Vietnam: according to statistics from the Vietnam Forest Protection Department, between 2002 and 2010, the country experienced an average of about 704 forest fires annually, damaging 5081.9 hectares of forest [14].
Research indicates that against the backdrop of global warming and increasingly hot, dry summers, future forest fire risks may intensify [15,16,17,18,19,20]. The causes of fires are complex, involving both natural factors (e.g., lightning, earthquakes) and human activities (e.g., discarded cigarette butts, arson) [21,22], among which climatic and topographic factors are particularly critical and have become a major research focus. Consequently, achieving accurate identification and efficient monitoring of forest fires is of paramount importance [23].
Flame segmentation and identification technology is key to enabling precise monitoring and emergency decision-making. Traditional methods such as manual patrols and satellite remote sensing are constrained by manpower, terrain, and response delays, making it difficult to meet demands for high efficiency and accuracy. Although LiDAR-based early fire detection technology offers high sensitivity and does not require a direct line of sight to the fire source, its signal analysis relies on complex methods such as neural network ensembles, and it still faces bottlenecks in real-time performance and automation [24]. In contrast, since their application in forest monitoring in the 1960s, Unmanned Aerial Vehicles (UAVs) have emerged as a vital monitoring platform due to their flexible deployment and advantages in real-time data acquisition [25]. However, UAV imagery still faces challenges such as high variability in fire target scale, low proportion of small fire targets, and strong interference from complex backgrounds, which increase the difficulty of accurate identification and false alarm control.
According to the principles of fire dynamics outlined in the SFPE Handbook [26], fire development exhibits a characteristic exponential growth pattern. In forest environments, early detection enables effective intervention before a fire surpasses the “golden suppression window”—a phase during which the fire’s energy remains low and controllable, thereby preventing its escalation into a large-scale disaster. Accurate early identification is not only a technical objective but also a core strategy for interrupting the nonlinear growth of fires, seizing the critical suppression timeline, and mitigating systemic risks. Therefore, establishing a reliable early fire detection model is of significant importance for enhancing the overall effectiveness of forest fire prevention systems.
To address the numerous challenges in flame detection tasks, researchers have proposed a variety of solutions. Owing to the complexity and diversity of fire scenes, along with significant environmental variations, detection models are required to exhibit strong adaptability and robust feature representation capabilities. Current research efforts are mainly directed toward several key directions: incorporating attention mechanisms to enhance the model’s focus on critical regions; optimizing convolutional structures or designing novel modules to improve multi–scale feature extraction; and refining loss functions to achieve more accurate localization of small-scale flame and smoke targets [27,28,29,30,31,32,33,34,35,36,37,38,39]. Although each of these approaches offers distinct advantages, they also come with certain limitations. The following section will analyze the progress and shortcomings of existing methods through a detailed examination of several representative studies. To meet these requirements, Li et al. [27] enhanced YOLOv8 with a gated dilated mechanism, which effectively expands the receptive field while preserving spatial resolution. This enables the model to capture richer contextual information, improving detection robustness in complex fire scenes. However, the added modules increase architectural complexity and computational overhead. Li et al. [28] introduced R-ShuffleNetV2 by integrating residual connections into ShuffleNetV2, improving feature reuse and gradient propagation while maintaining a lightweight network structure. Nevertheless, its lightweight design limits representational capacity in highly complex environments. Li et al. [29] combined a gated dilation mechanism, an SE–ResNeXtSE detection head, and the Focal–SIoU loss function to enhance feature discrimination, optimize multi–scale learning, and improve convergence stability during training. These improvements collectively strengthen the model’s robustness to scale variation and class imbalance in fire detection tasks. However, the multiple enhancements also reduce training efficiency and make generalization more challenging. Mao et al. [32] proposed an MCCNN–based fire recognition method that automatically learns discriminative RGB features, effectively overcoming the limitations of handcrafted feature extraction and exhibiting strong generalization across different fire types and scenes. This data-driven feature learning paradigm significantly improves recognition accuracy compared with traditional methods. However, it lacks precise localization capability compared to modern object detectors. Zhang et al. [35] incorporated an EMA attention mechanism and a PAN–Bag structure into YOLOv8, enhancing the network’s focus on salient fire and smoke regions while suppressing background interference. This design improves detection accuracy and robustness, particularly for targets with irregular shapes and uneven feature distributions. However, the model’s performance remains sensitive to dataset quality and scene diversity.
Other researchers have shifted their focus towards reducing model complexity, pursuing greater computational efficiency and deployment-friendliness while maintaining detection performance. For instance, Wu et al. [40] integrated a dynamic upsampling module, an enhanced attention mechanism, and a novel loss function, collectively boosting model accuracy while reducing the parameter count. Ishtiaq, Won, et al. [41] proposed YOLO-SIFD, an algorithm based on YOLOv8 that integrates a class–balanced dataset, fractal dimension analysis, and the SAHI technique. It increased mAP:50–95 by over 25% compared to the baseline and suggested future enhancements via DCGAN and diffusion models for optimized fire and smoke detection. Meanwhile, Ma et al. [42] introduced lightweight dynamic frequency domain enhancement and feature enhancement modules, improving performance while reducing parameters by 23.1% compared to the baseline. Similarly, Yun et al. [43] adopted an attention module with asymmetric dilated convolution and replaced standard convolution with lightweight GSConv, enhancing model accuracy while achieving greater lightweighting. In another approach, Lei et al. [44] reduced model parameters by 41% using DSConv and GhostConv. Despite reducing computational costs and improving deployment feasibility, lightweight designs still exhibit notable limitations. Excessive model compression often compromises feature representational capacity, thereby diminishing detection efficacy for subtle or heavily occluded flames. Moreover, many lightweight modules are reliant on specific architectural configurations or training methodologies, which constrain their transferability across different model architectures and task domains. As illustrated in Table 1, the issues discussed above are clearly reflected in the data: flame detection accuracy is generally confined to the range of 80%–90%, struggling to surpass the 90% threshold. Concurrently, lightweight models exhibit, on the whole, lower accuracy. This constitutes a significant challenge currently faced in the field.
Table 1.
Experimental results of other models.
To address the aforementioned issues, this paper proposes the SER–YOLOv8 model, which is designed to enhance the detection performance of small-target flames in complex environments. The model first replaces the original C2f and SPPF modules in YOLOv8 with RepNCSPELAN4 (Reparameterized Cross Stage Partial Efficient Layer Aggregation Network 4) and SPPELAN (Spatial Pyramid Pooling Efficient Layer Aggregation Network) modules, thereby significantly improving both feature extraction capability and computational efficiency. Second, the model introduces a novel SERDet (Selective Enhancement for Regression Detection) module, which integrates a DWConv (depthwise separable convolutions) layer to reduce the number of parameters and accelerate computation; in addition, the SERDet detection head embeds a SaElayer, whose innovative multi-path fusion attention mechanism enables more accurate identification of small-target flames. The model adopts the NWD loss function—unlike traditional IoU-based loss functions such as CIoU, NWD calculates the Wasserstein distance between Gaussian distributions of bounding boxes, providing a smoother and scale-insensitive similarity measure for tiny objects and substantially enhancing the localization accuracy of small targets. Experimental results on the M4SFWD dataset show that the SER-YOLO model achieves flame detection accuracy of 91.5% and smoke detection accuracy of 86.6%. Compared with the baseline YOLOv8 model, the flame detection accuracy is improved by 1.2% and the smoke detection accuracy by 2.4%. While achieving higher detection accuracy, the model still maintains high computational efficiency, serving as a reliable and effective solution for practical flame detection tasks.
2. Model and Method
2.1. YOLOv8
YOLOv8 [45], developed by Ultralytics in 2023, builds upon the strengths of its predecessors by introducing novel modules that substantially enhance both accuracy and inference speed. In its backbone network, components such as CBS, C2f, and SPPF significantly improve feature extraction capability and adaptability to multi-scale targets. This architectural design is particularly suitable for flame detection, given the dynamic scale of flames. Furthermore, YOLOv8 replaces the anchor–based bounding box regression of earlier versions with an anchor-free strategy. This approach employs center-point probability regression for bounding box prediction, eliminating the dependency on predefined anchor boxes. This design not only simplifies the model but also enhances its flexibility in detecting irregularly shaped targets like flames, thereby yielding superior adaptability and generalization in complex wildland fire scenarios
2.2. Model Optimization
2.2.1. SER-YOLOv8 Model
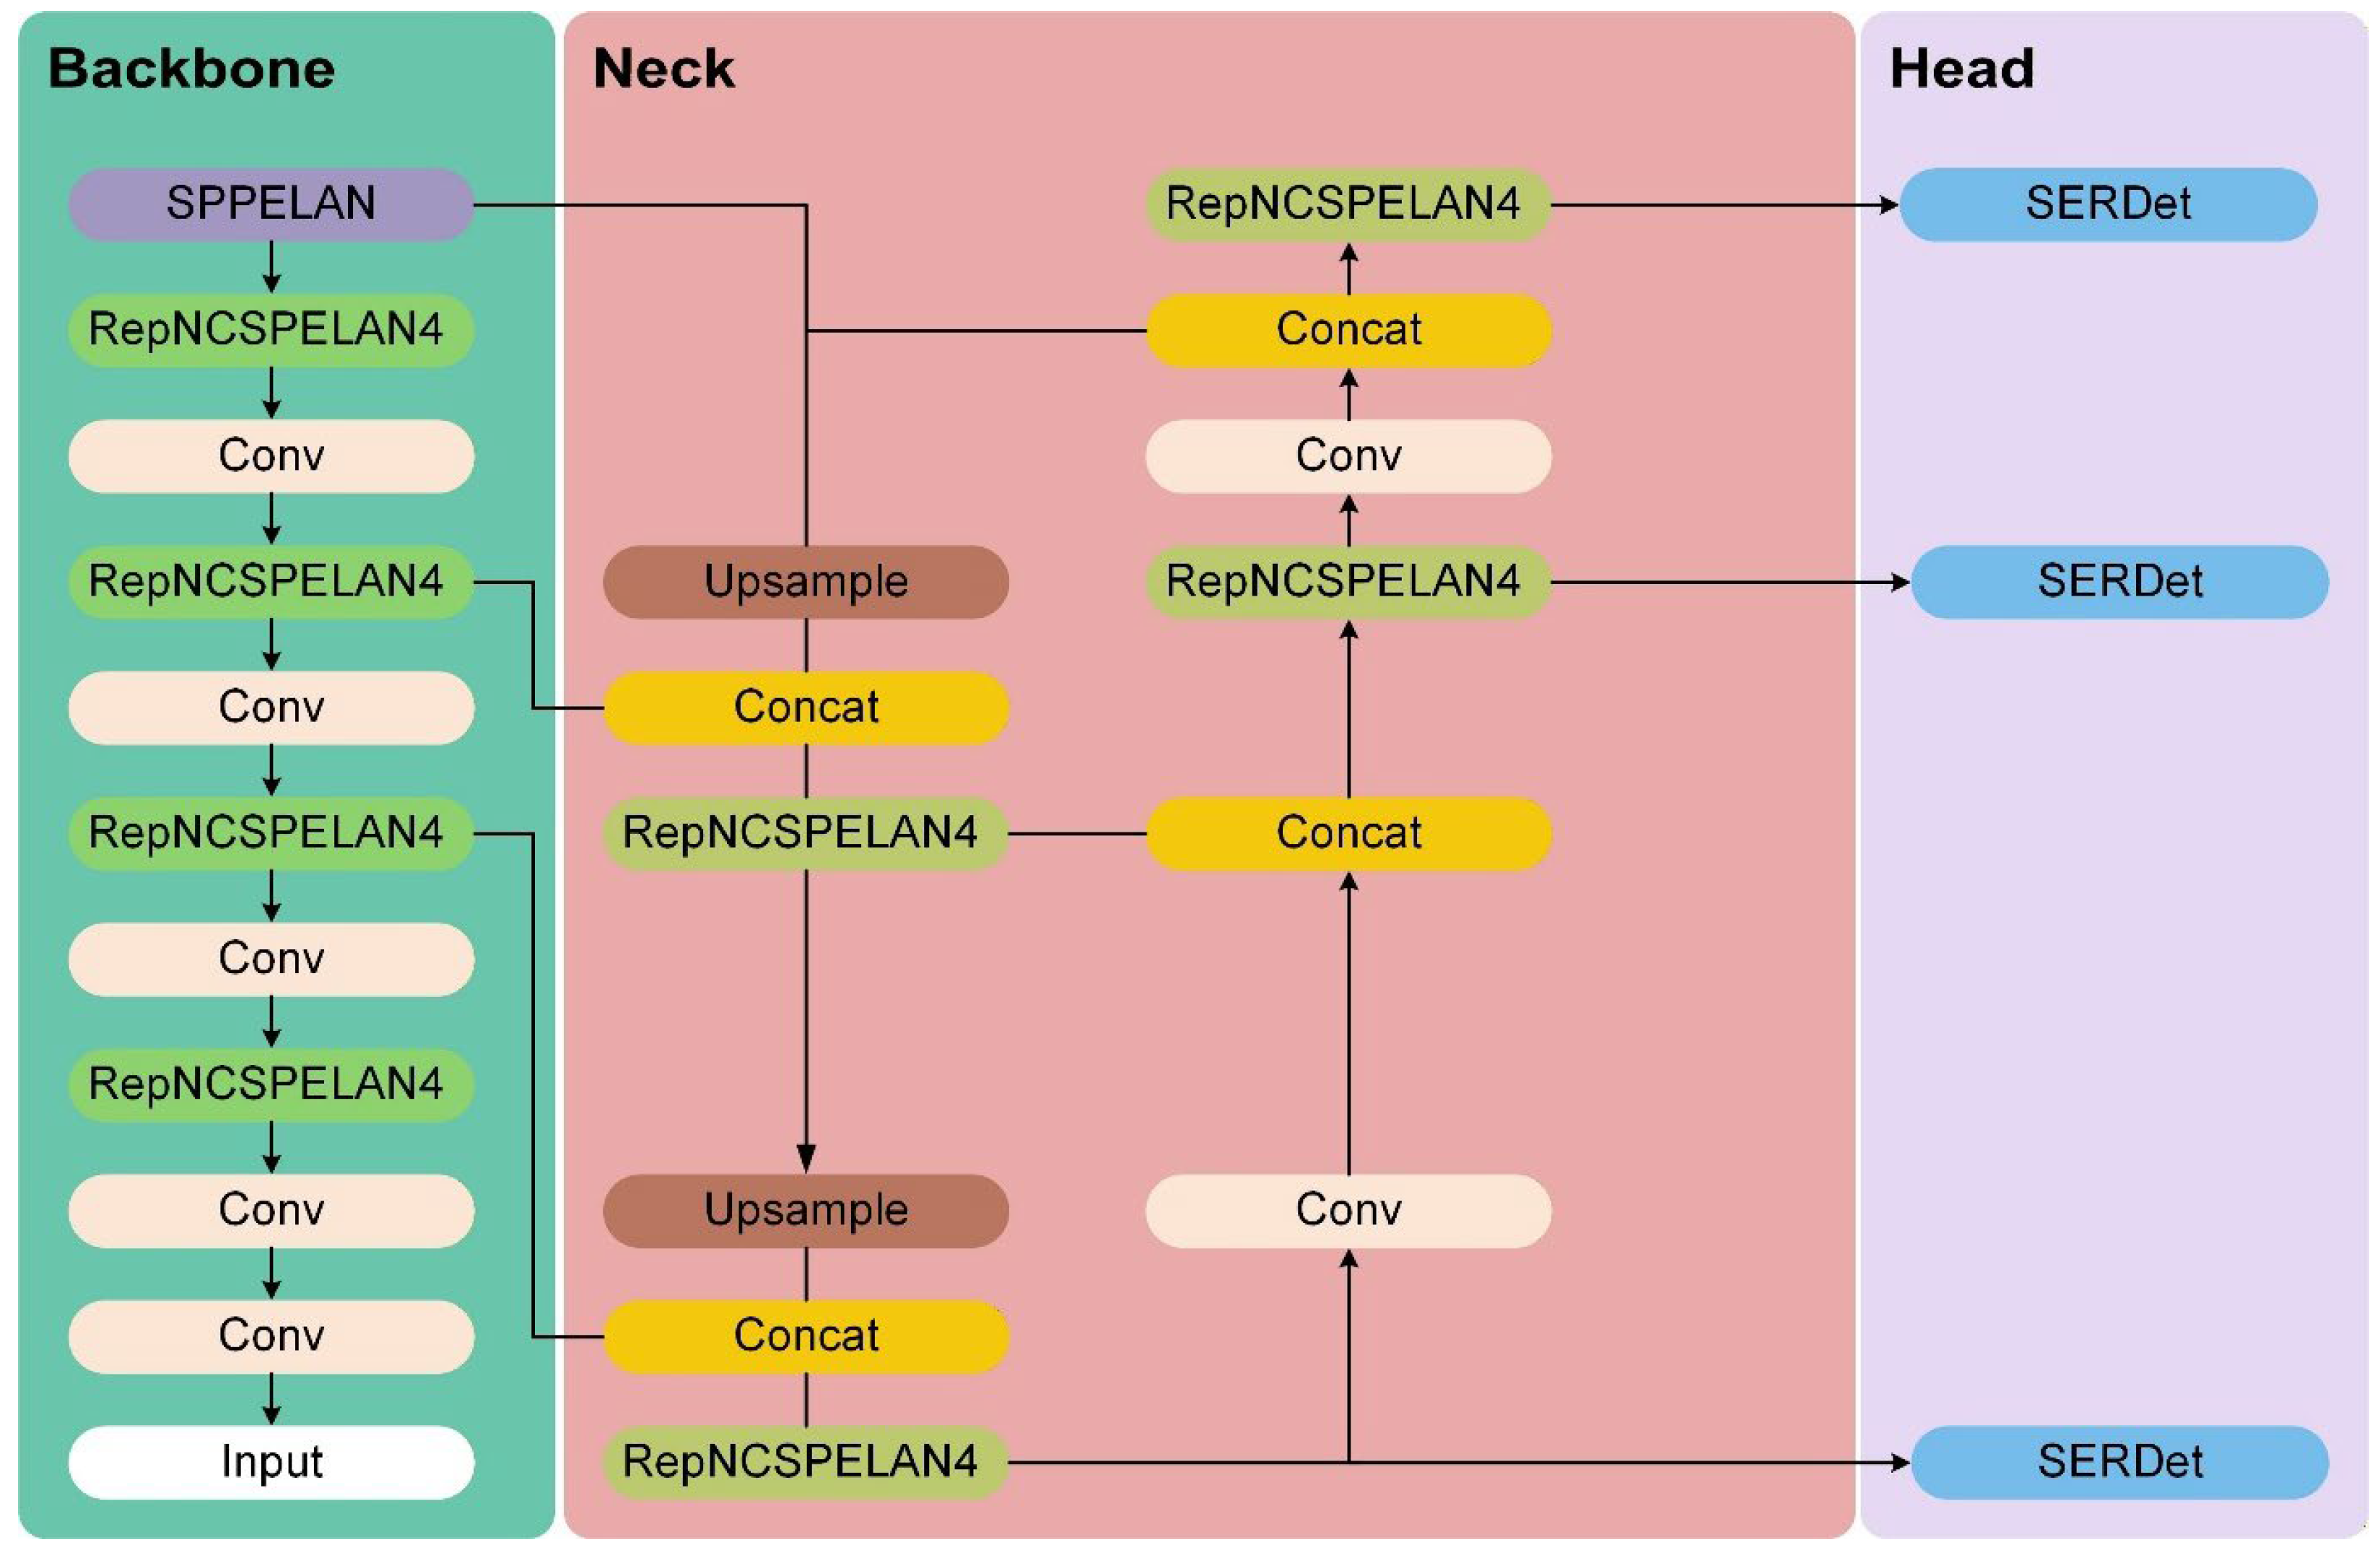
Although YOLOv8 demonstrates relatively strong performance in flame detection, its recognition capability in complex environments requires further improvement, and its detection accuracy for conventional flames can also be enhanced. To address these limitations, this paper proposes the SER–YOLOv8 model. As illustrated in Figure 1, the model integrates the RepNCSPELAN4 module, SPPELAN module, and SERDet module, while incorporating the NWD loss function. These enhancements contribute to a significant improvement in model accuracy and yield notable performance gains in detecting small-target flames.
Figure 1.
SER-YOLOv8, an improved YOLOv8 model, employs Selective Enhancement for Regression (SER), which utilizes multi–head attention to enhance feature representation and optimize the regression task.
By substituting the C2f module with the RepNCSPELAN4 module and the SPPF module with the SPPELAN module, the feature learning and fusion capabilities of the model are significantly strengthened. This improvement enables more sufficient interaction across different feature scales, thereby enhancing the capacity of the model to process and refine multi–scale information. The most significant enhancement resides in the redesigned detection head. This redesign incorporates a Depthwise Convolution (DWConv) layer into the classification branch to effectively reduce model parameters while maintaining robust feature extraction, thereby accelerating inference. Furthermore, the introduction of the SaElayer module implements a multi-path fusion attention mechanism, which enables the model to concentrate on multi-dimensional information and produce more comprehensive channel attention weights. This capability ultimately ensures superior detection accuracy for small objects. The model replaces traditional IoU-based loss functions with the Normalized Wasserstein Distance (NWD) loss. As opposed to conventional IoU variants, the NWD loss provides a smoother and scale–insensitive similarity measure for tiny targets, thereby significantly improving the localization accuracy of small-target flames.
2.2.2. RepNCSPELAN4 and SPPELAN Modules
Existing studies have found that flame features exhibit distinct distributional differences across various network layers. In shallow layers, the network captures sharp edge responses of flames, whereas deeper layers focus more on holistic semantic information [46]. However, as the network depth increases, detailed localization information from earlier layers is substantially lost. Moreover, the unidirectional fusion mechanism in traditional feature pyramids struggles to adequately integrate multi-resolution features, failing to simultaneously meet the dual requirements of precise flame localization and accurate classification. Consequently, it is necessary to improve the original Backbone and Feature Pyramid Network modules in YOLOv8, enabling the new model to achieve efficient multi-scale feature fusion while maintaining superior gradient propagation properties. To address the aforementioned issues, the model introduces a collaborative architecture comprising the RepNCSPELAN4 module and SPPELAN module (Figure 2). This architecture deeply integrates advanced design principles including reparameterization techniques, cross-stage feature reuse, and spatial pyramid pooling. Through the coordinated operation of these two modules, the quality of multi-scale feature fusion is significantly enhanced. By using parallel multi-scale pooling and deep feature integration, this enhancement not only boosts the model’s sensitivity to flames within complex backgrounds but also significantly improves its robustness against variations in flame distance.
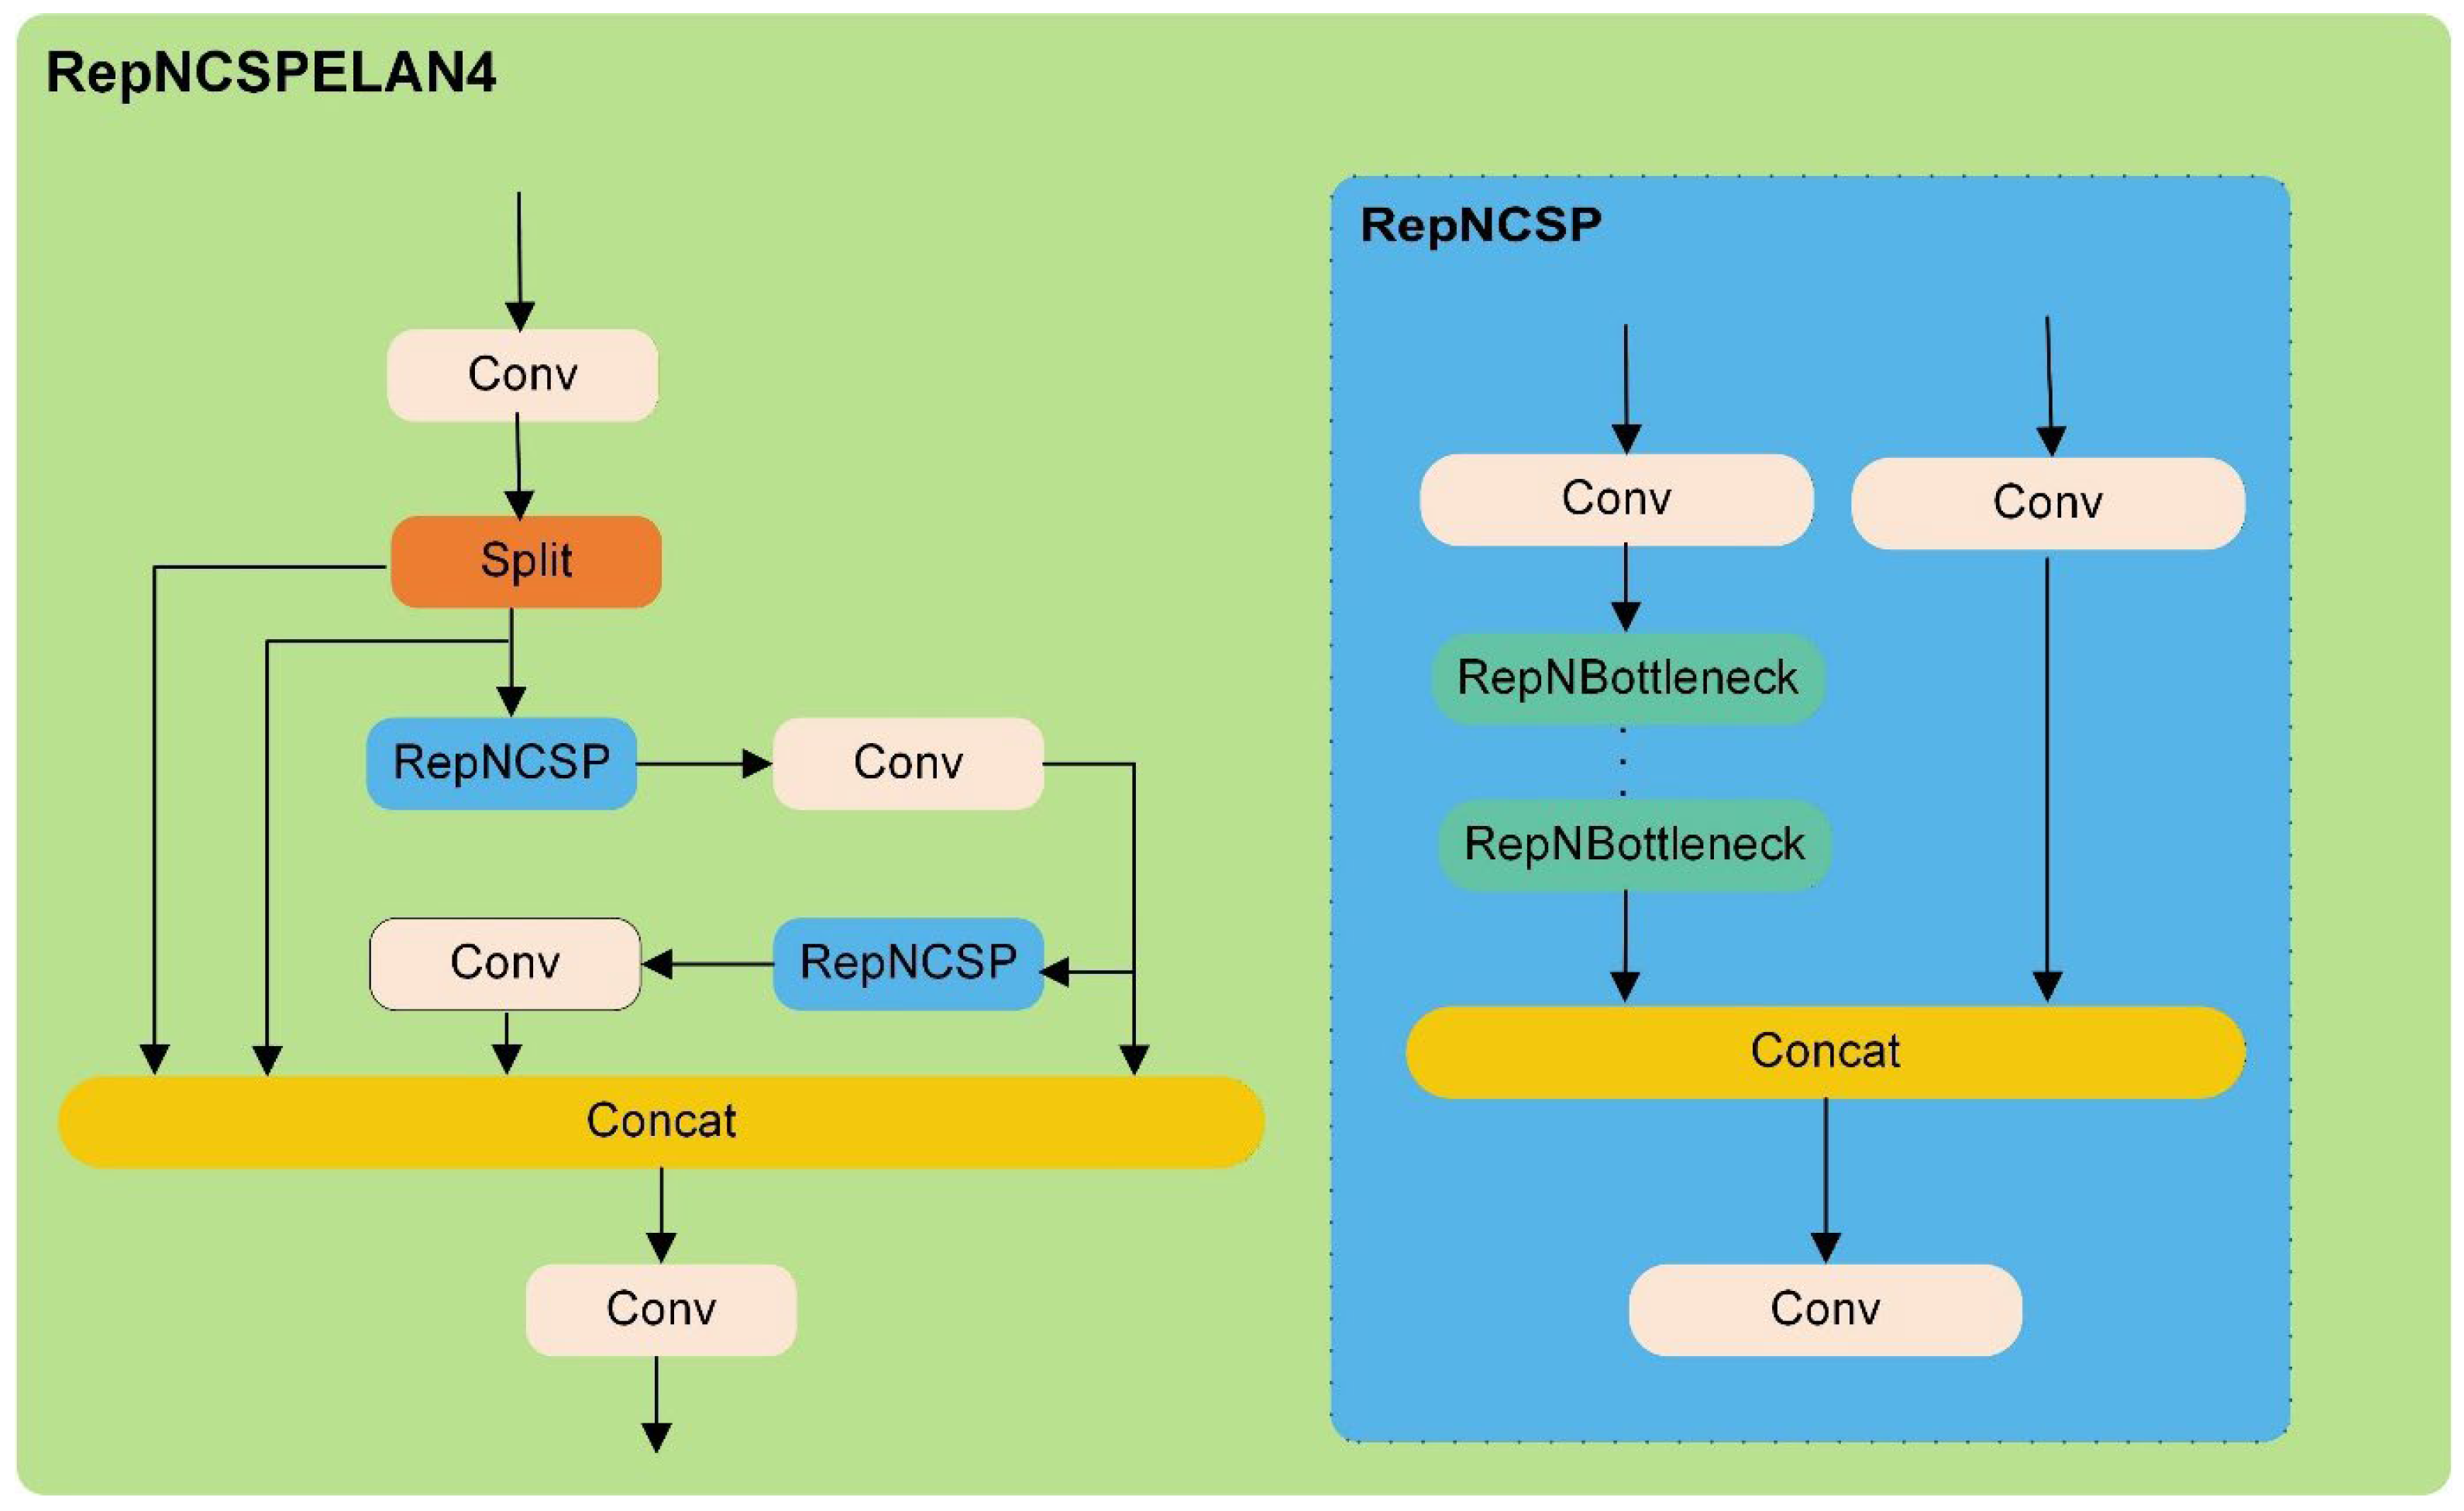
Figure 2.
Structure of the RepNCSPELAN4 module. The joint use of the Conv module and the RepNCSP module, along with the adoption of a multi–branch architecture, not only enhances feature extraction capability but also accelerates operational speed.
In deep learning–based fire recognition algorithms, object detection models are required to achieve rapid and precise localization of flames and smoke in complex and dynamic real–world scenarios. RepNCSPELAN4 module [47] serves as a core building block in modern object detector backbone networks. Its nomenclature reflects a synthesis of key concepts: Reparameterization (Rep), Cross-Stage Partial connection (CSP), Efficient Layer Aggregation Network (ELAN), and Cardinality. By integrating advanced design philosophies including reparameterization, cross–stage partial connections, and efficient layer aggregation, it provides robust technical support for addressing the core challenges in fire recognition.
The input feature map of the module is where , and denote the number of channels, height, and width, respectively. The module first employs the Cross–Stage Partial (CSP) strategy to split the input along the channel dimension:
where , the operation denotes channel-wise halving, and represents an initial convolution applied for preliminary channel adjustment.
The Cross-Stage Partial (CSP) structure constructs two independent processing pathways within the network through feature partitioning. This strategy can effectively alleviate common issues in deep networks such as information redundancy and gradient vanishing, ensuring that all types of fire-related signals ranging from subtle details to macroscopic features can be processed efficiently. The primary branch is designed to preserve and lightly process the original feature information, typically implemented via a convolution. Its mathematical expression is:
where denotes the convolution operation, and represent the weight and bias parameters of the convolutional layer, and is the activation function. The secondary branch serves as the core of the module, where first undergoes compression and is then fed into the ELAN structure:
The ELAN structure performs multi-scale feature extraction through multiple parallel sub-paths (Cardinality). Assuming there are sub-paths, each containing stacked fundamental modules, where is often related to the numeral ‘4’ in its name, the output of the layer in the sub-path can be expressed as:
where denotes the operation of the reparameterized convolution block in the sub-path. The outputs of all sub-paths are concatenated along the channel dimension to form a rich multi-scale feature representation:
Z = Contact (Z1(L), Z2(L), …, ZN(L))
Finally, a convolution is applied to fuse the concatenated features and restore the target channel count:
Through its Efficient Layer Aggregation Network (ELAN) structure, the RepNCSPELAN4 module significantly enhances the perception capability of the model for the multiscale nature and irregular shapes of fire targets. The outputs of the primary and secondary branches are concatenated along the channel dimension and integrated by a final fusion convolution layer:
This completes the full forward propagation process of the module.
During the training phase, fundamental modules such as RepConv employ a multi-branch architecture. For instance, the computation of a typical RepConv during training can be expressed as:
where represents the Batch Normalization layer.
During the inference phase, the multi-branch architecture is equivalently fused into a single convolutional layer through reparameterization. This process is achieved by absorbing the parameters of the Batch Normalization (BN) layers, such as scale factor , bias , running mean , and running variance , into the convolutional kernel and bias . For a convolutional branch followed by a BN layer, the equivalent transformation is performed as follows:
Finally, the equivalent kernels and biases from all branches are combined through element-wise summation, resulting in a unified, branch-free architecture during inference:
Leveraging its reparameterization property, RepNCSPELAN4 fulfills the stringent real–time requirements of fire recognition systems while maintaining high accuracy. Such monitoring systems demand extremely fast model inference, which this module achieves by employing a complex multi–branch topology during training to acquire stronger feature extraction and generalization capabilities. This enables more effective discrimination between actual fires and various interfering objects, thereby significantly reducing false alarms. During deployment and inference, structural reparameterization transforms the multi–branch design equivalently into a single convolutional layer. As a result, the model incurs only minimal computational overhead during inference while retaining the high–accuray benefits of a large–capacity model, thereby enabling real–time, high–precision analysis of video streams even under limited hardware resources.
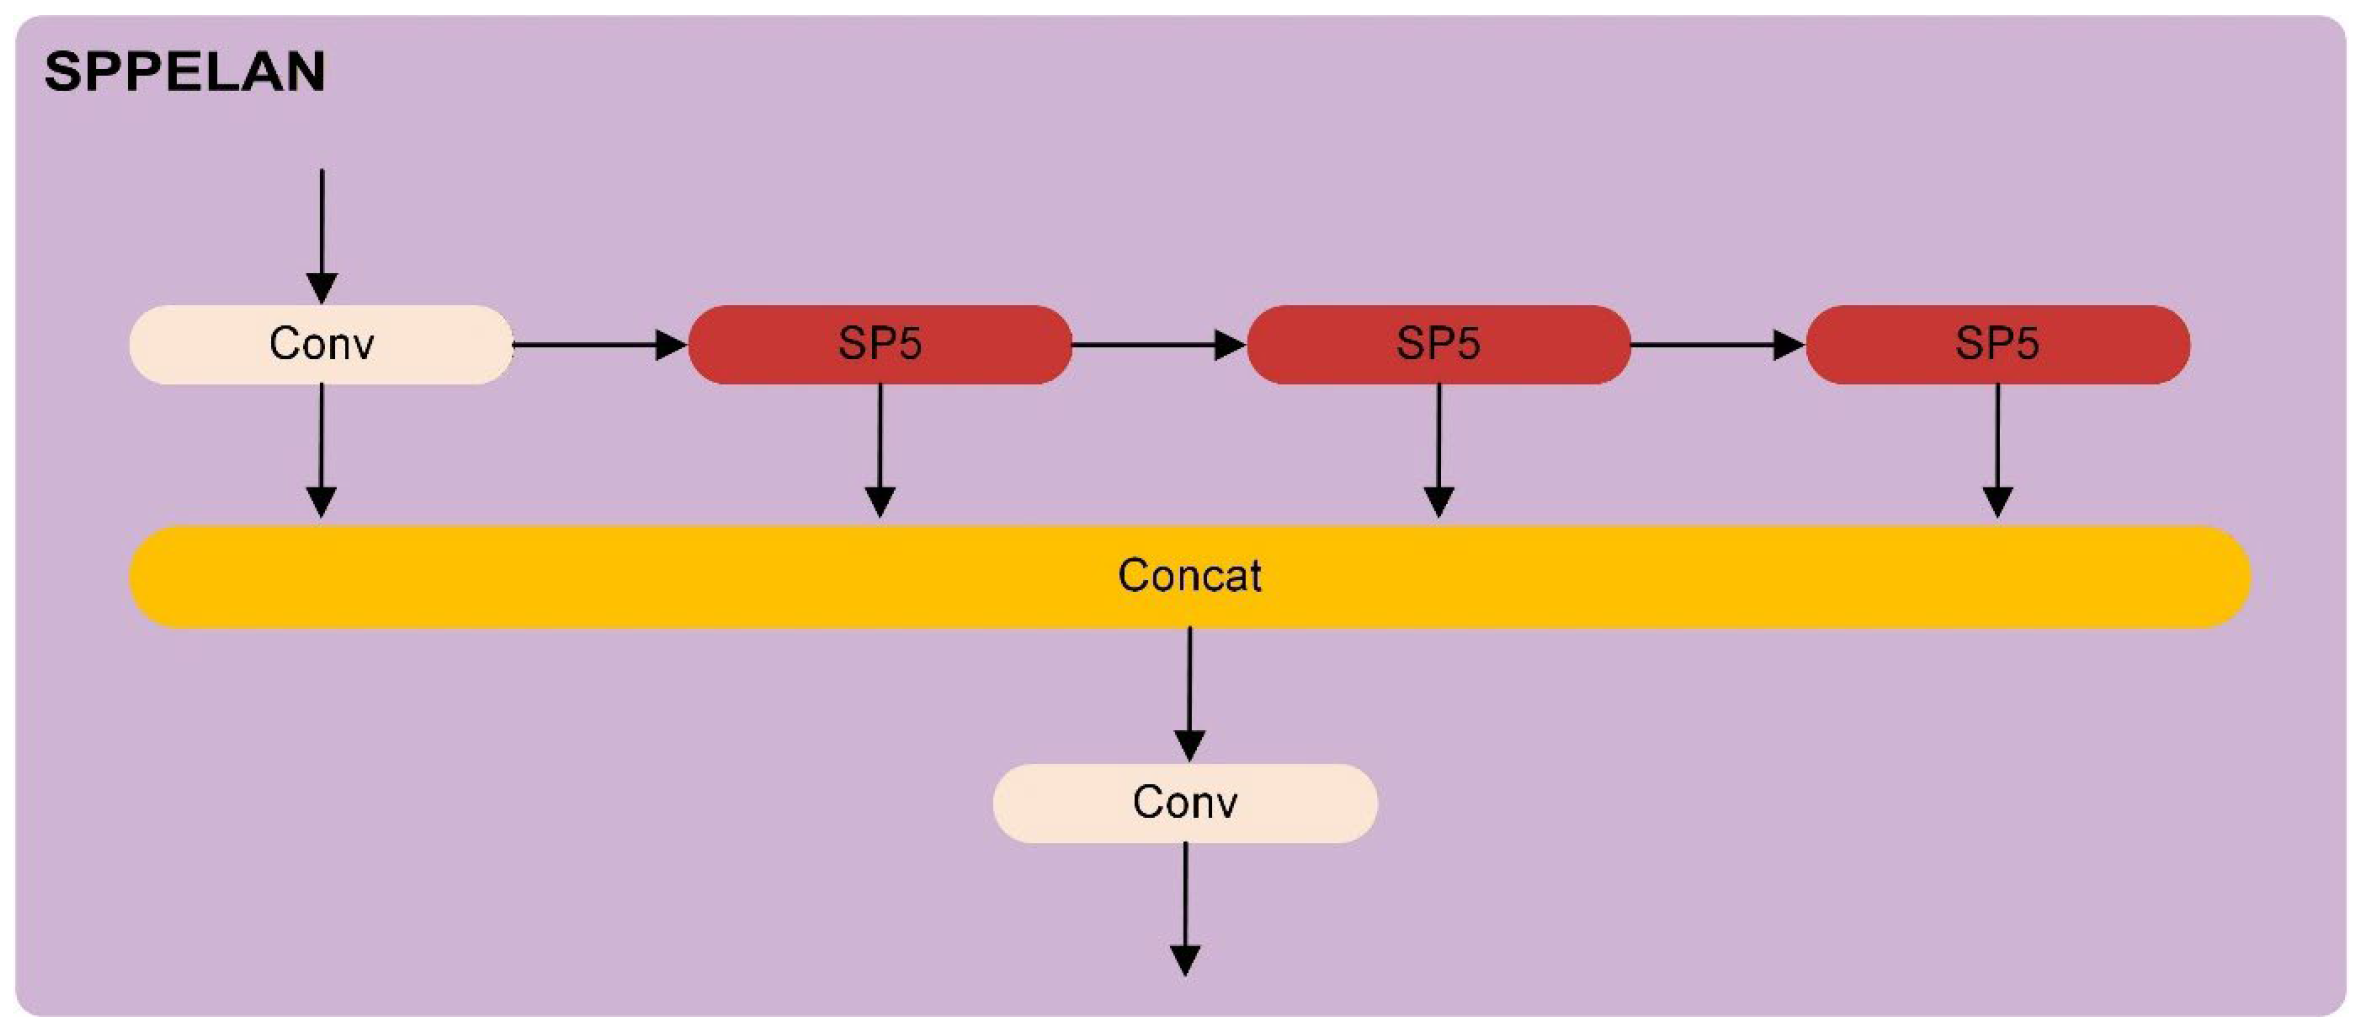
The SPPELAN module [48] (Figure 3) is an efficient multi-scale feature fusion module designed to address the challenges of significant scale variations in targets and insufficient feature extraction in complex scenes. By integrating two core components, Spatial Pyramid Pooling (SPP) and an Enhanced Local Attention Network (ELAN), it effectively expands the receptive field of the model and enhances feature representation capabilities without significantly increasing computational burden, thereby substantially improving detection performance for multi-scale targets.
Figure 3.
Structure of the SPPELAN module. The module integrates ELAN and SPP structures, enhancing multi–scale perceptual capability via multi–branch parallel pooling while maintaining computational efficiency.
The mathematical principle of the SPP component can be formulated as follows: Given an input feature map , the application of pooling operations with different kernel sizes yields a set of multi–scale feature maps . Each pooling operation can be expressed as:
where denotes the output size of the pooling layer. These multi-scale feature maps are subsequently resampled to a uniform spatial dimension and concatenated with the original input feature map along the channel axis:
The ELAN component optimizes local features within SPPELAN by leveraging an efficient attention mechanism to amplify target features and suppress background noise. Its architecture, which incorporates cross–layer connections and feature reuse, enhances feature diversity without compromising efficiency. This capability is crucial in fire detection, as it improves the discrimination of genuine fire sources and reduces false alarms. The mathematical representation of the ELAN component can be described as follows: Given an input feature map , ELAN extracts features at different abstraction levels through multiple parallel convolutional branches, subsequently fusing these features:
where residual connections ensure effective gradient propagation through deep networks, thus mitigating the vanishing gradient problem during training.
SPPELAN module does not simply cascade the SPP and ELAN modules in series, but rather achieves their organic integration through deep feature interaction. A typical architectural design embeds the SPP component within the ELAN framework, enabling the module to simultaneously extract multi–scale contextual information while maintaining excellent local feature perception. This fusion mechanism can be mathematically represented as:
The distinctiveness of SPPELAN lies in an exceptional balance between computational efficiency and feature extraction capability. In fire detection tasks, the SPPELAN module plays a critical role. The SPPELAN module, with its multi–scale pooling architecture, is particularly effective for fire detection. It precisely identifies incipient fires characterized by confined flames and dispersed smoke, while its expansive receptive field enables a holistic representation of fully developed fire scenarios. In complex background scenarios, such as forest fire detection, where flames need to be distinguished from similarly colored elements like autumn leaves or sunlight, the SPPELAN module integrates multi-scale contextual information, enabling the model to make judgments based on the global environment surrounding targets, thereby effectively reducing false alarms.
2.2.3. Selective Enhancement for Regression Detection
Attention mechanisms have emerged as a core technology in the field of object detection, demonstrating outstanding performance in fine-grained recognition tasks within complex scenes. However, conventional convolutional neural networks (CNNs) are inherently constrained by their locally connected architecture, making it difficult to effectively model long-range dependencies, and this limitation is particularly pronounced in flame and smoke detection tasks where sensitivity to spatial contextual cues is crucial. Although studies by Vaswani et al. [49] have demonstrated that self-attention mechanisms can effectively capture global contextual information within feature maps, their computational complexity grows quadratically with image size. This computational bottleneck significantly hinders the practical deployment of such mechanisms in real-time detection systems.
In response to the unique problem of flame and smoke detection tasks, extensive empirical studies have revealed distinctive patterns in their feature distributions. Through feature visualization techniques such as Class Activation Mapping, Frizzi et al. [50] demonstrated that flame regions exhibit a concentrated distribution of high-frequency responses in the feature space, whereas smoke regions are characterized by a dispersed low-frequency energy profile. Zhang et al. [51], in their study on small-target forest fire detection, further indicate that traditional models are constrained by their single-scale receptive fields. Relying solely on feature maps from deep network layers tends to lose shallow-level details that are crucial for localizing small fire spots, making it difficult to simultaneously capture localized flame characteristics and global distribution patterns of smoke. These findings underscore the importance of designing a detection head structure capable of adaptively adjusting receptive fields and enhancing the expression of critical features, which holds significant potential for improving the overall performance of fire detection models.
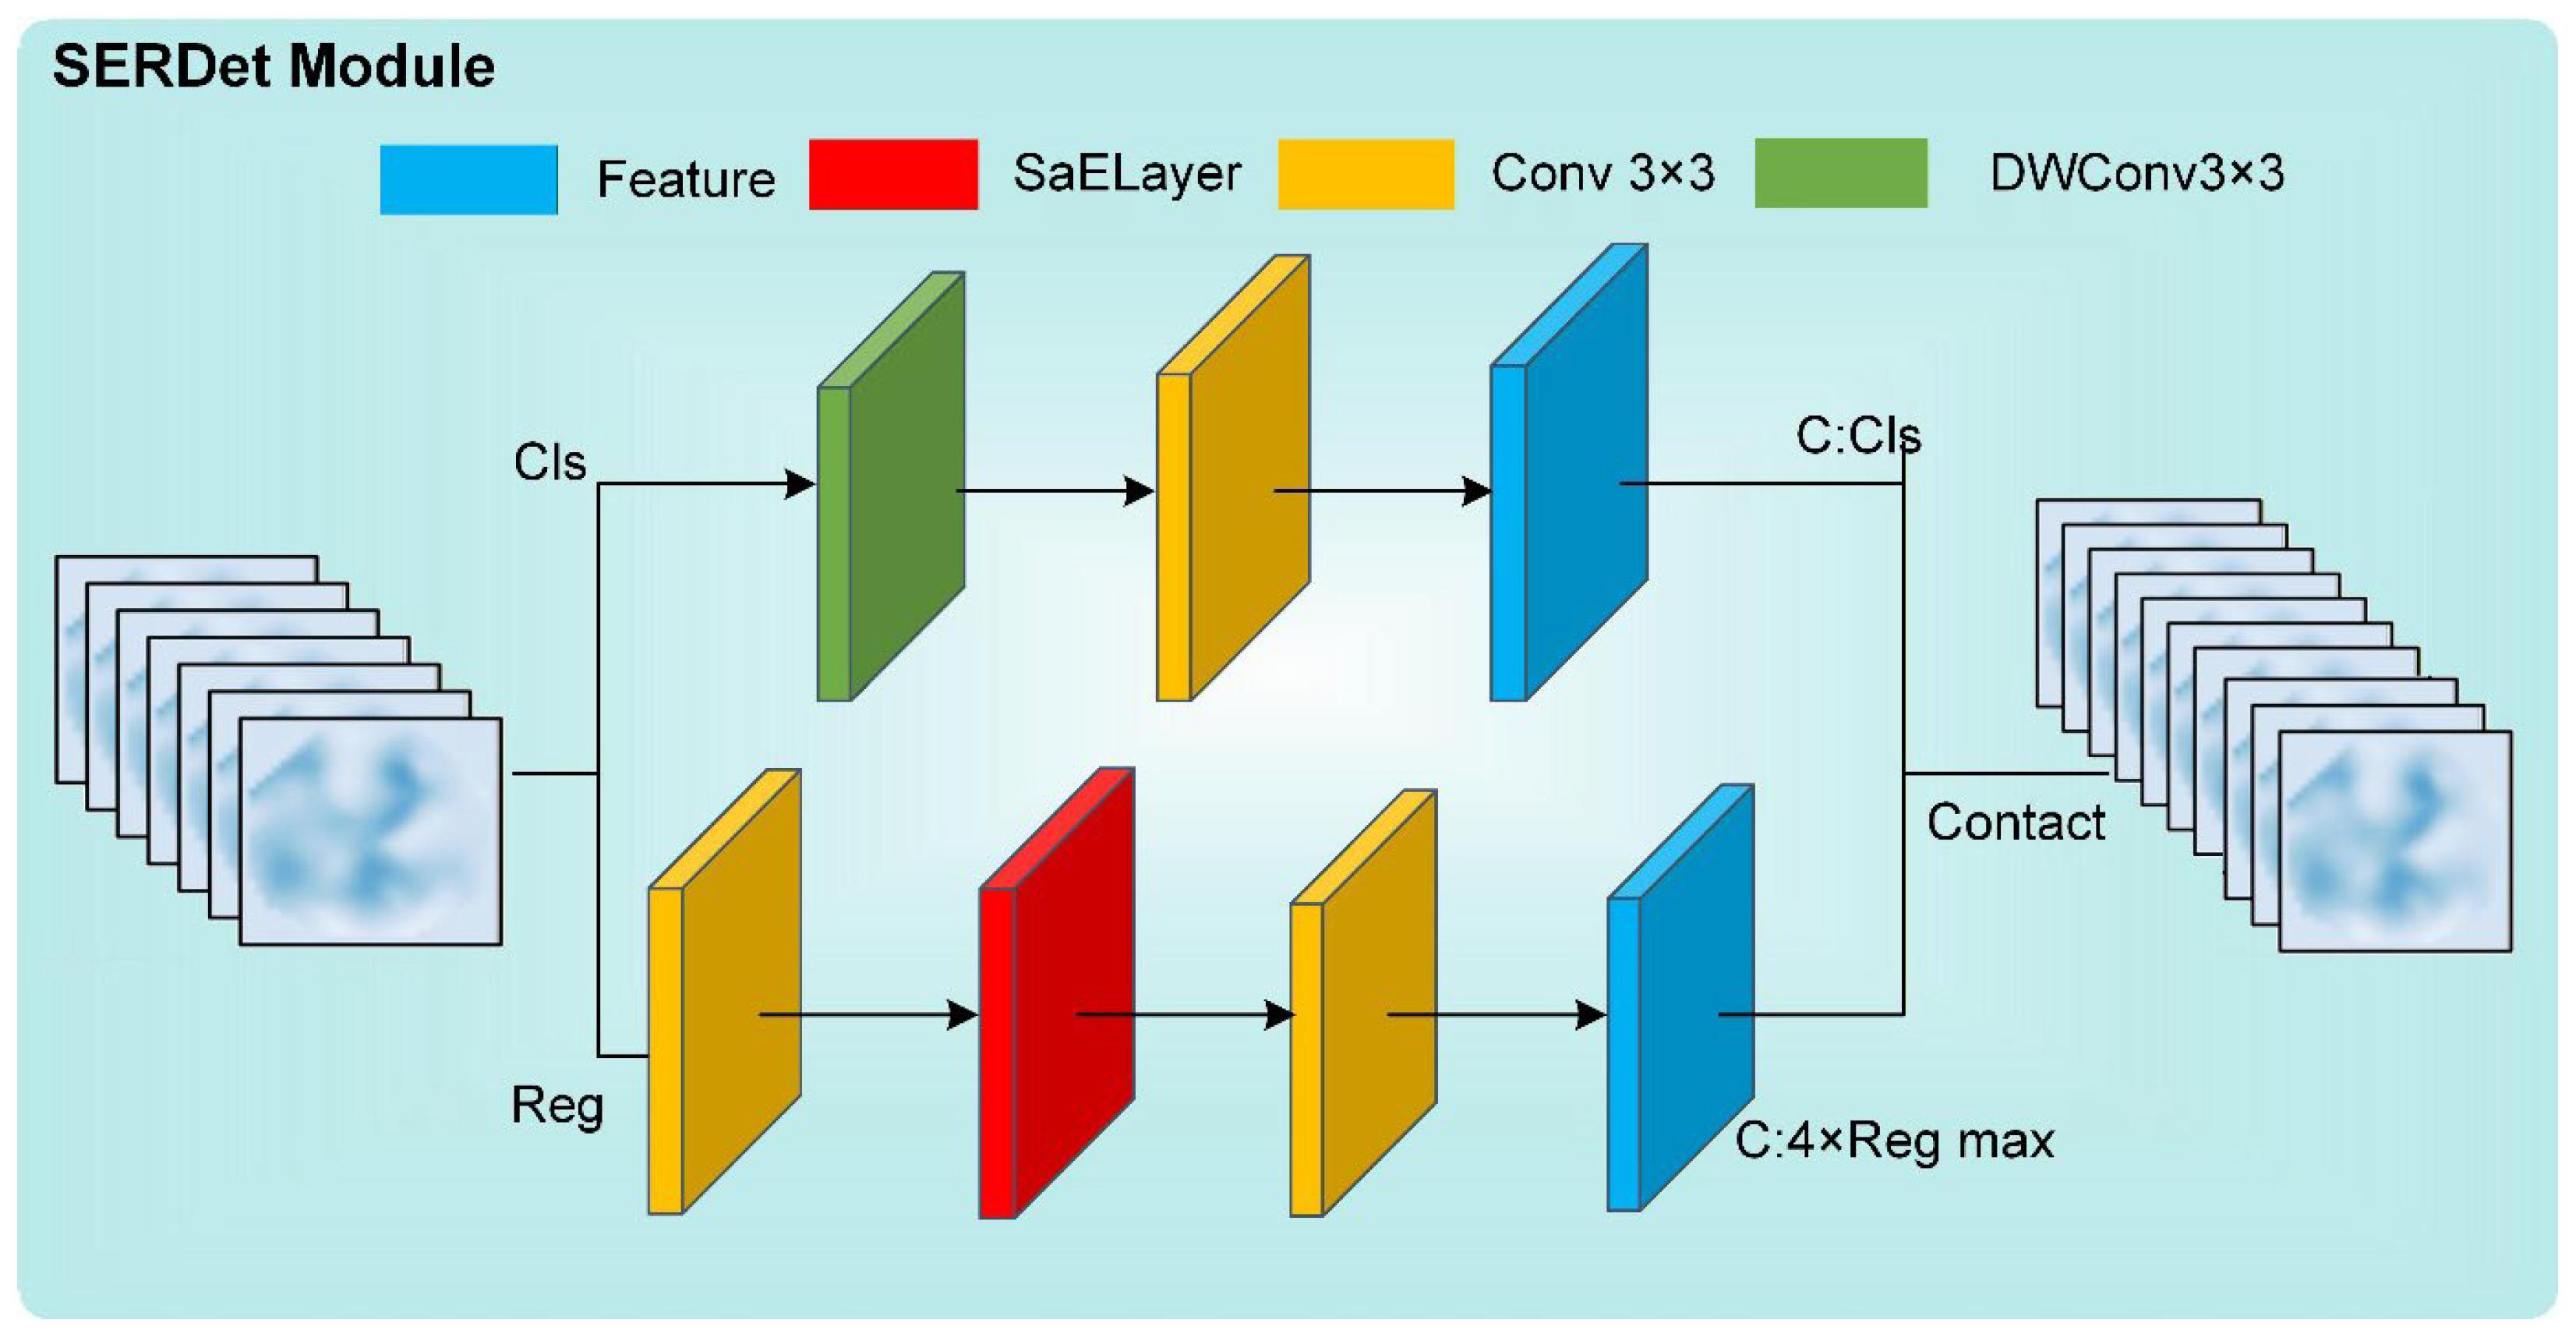
To address the aforementioned problem, this paper innovatively designs a detection head module named SERDet, which integrates Split Enhancement and Reparameterized Attention. This module deeply combines multi-scale feature extraction with channel attention mechanisms, employing a lightweight dual-branch architecture to decouple and optimize feature representations required for classification and regression tasks (Figure 4). SERDet synergistically captures global contextual information and local details, effectively overcoming the spatial limitations of traditional methods. Consequently, it significantly enhances the response capability to flames and smoke while suppressing interference from complex backgrounds.
Figure 4.
Structure of the SERDet module. The classification branch incorporates DWConv, significantly reducing the parameter count, while the regression branch utilizes the SaElayer module to enhance feature extraction capability.
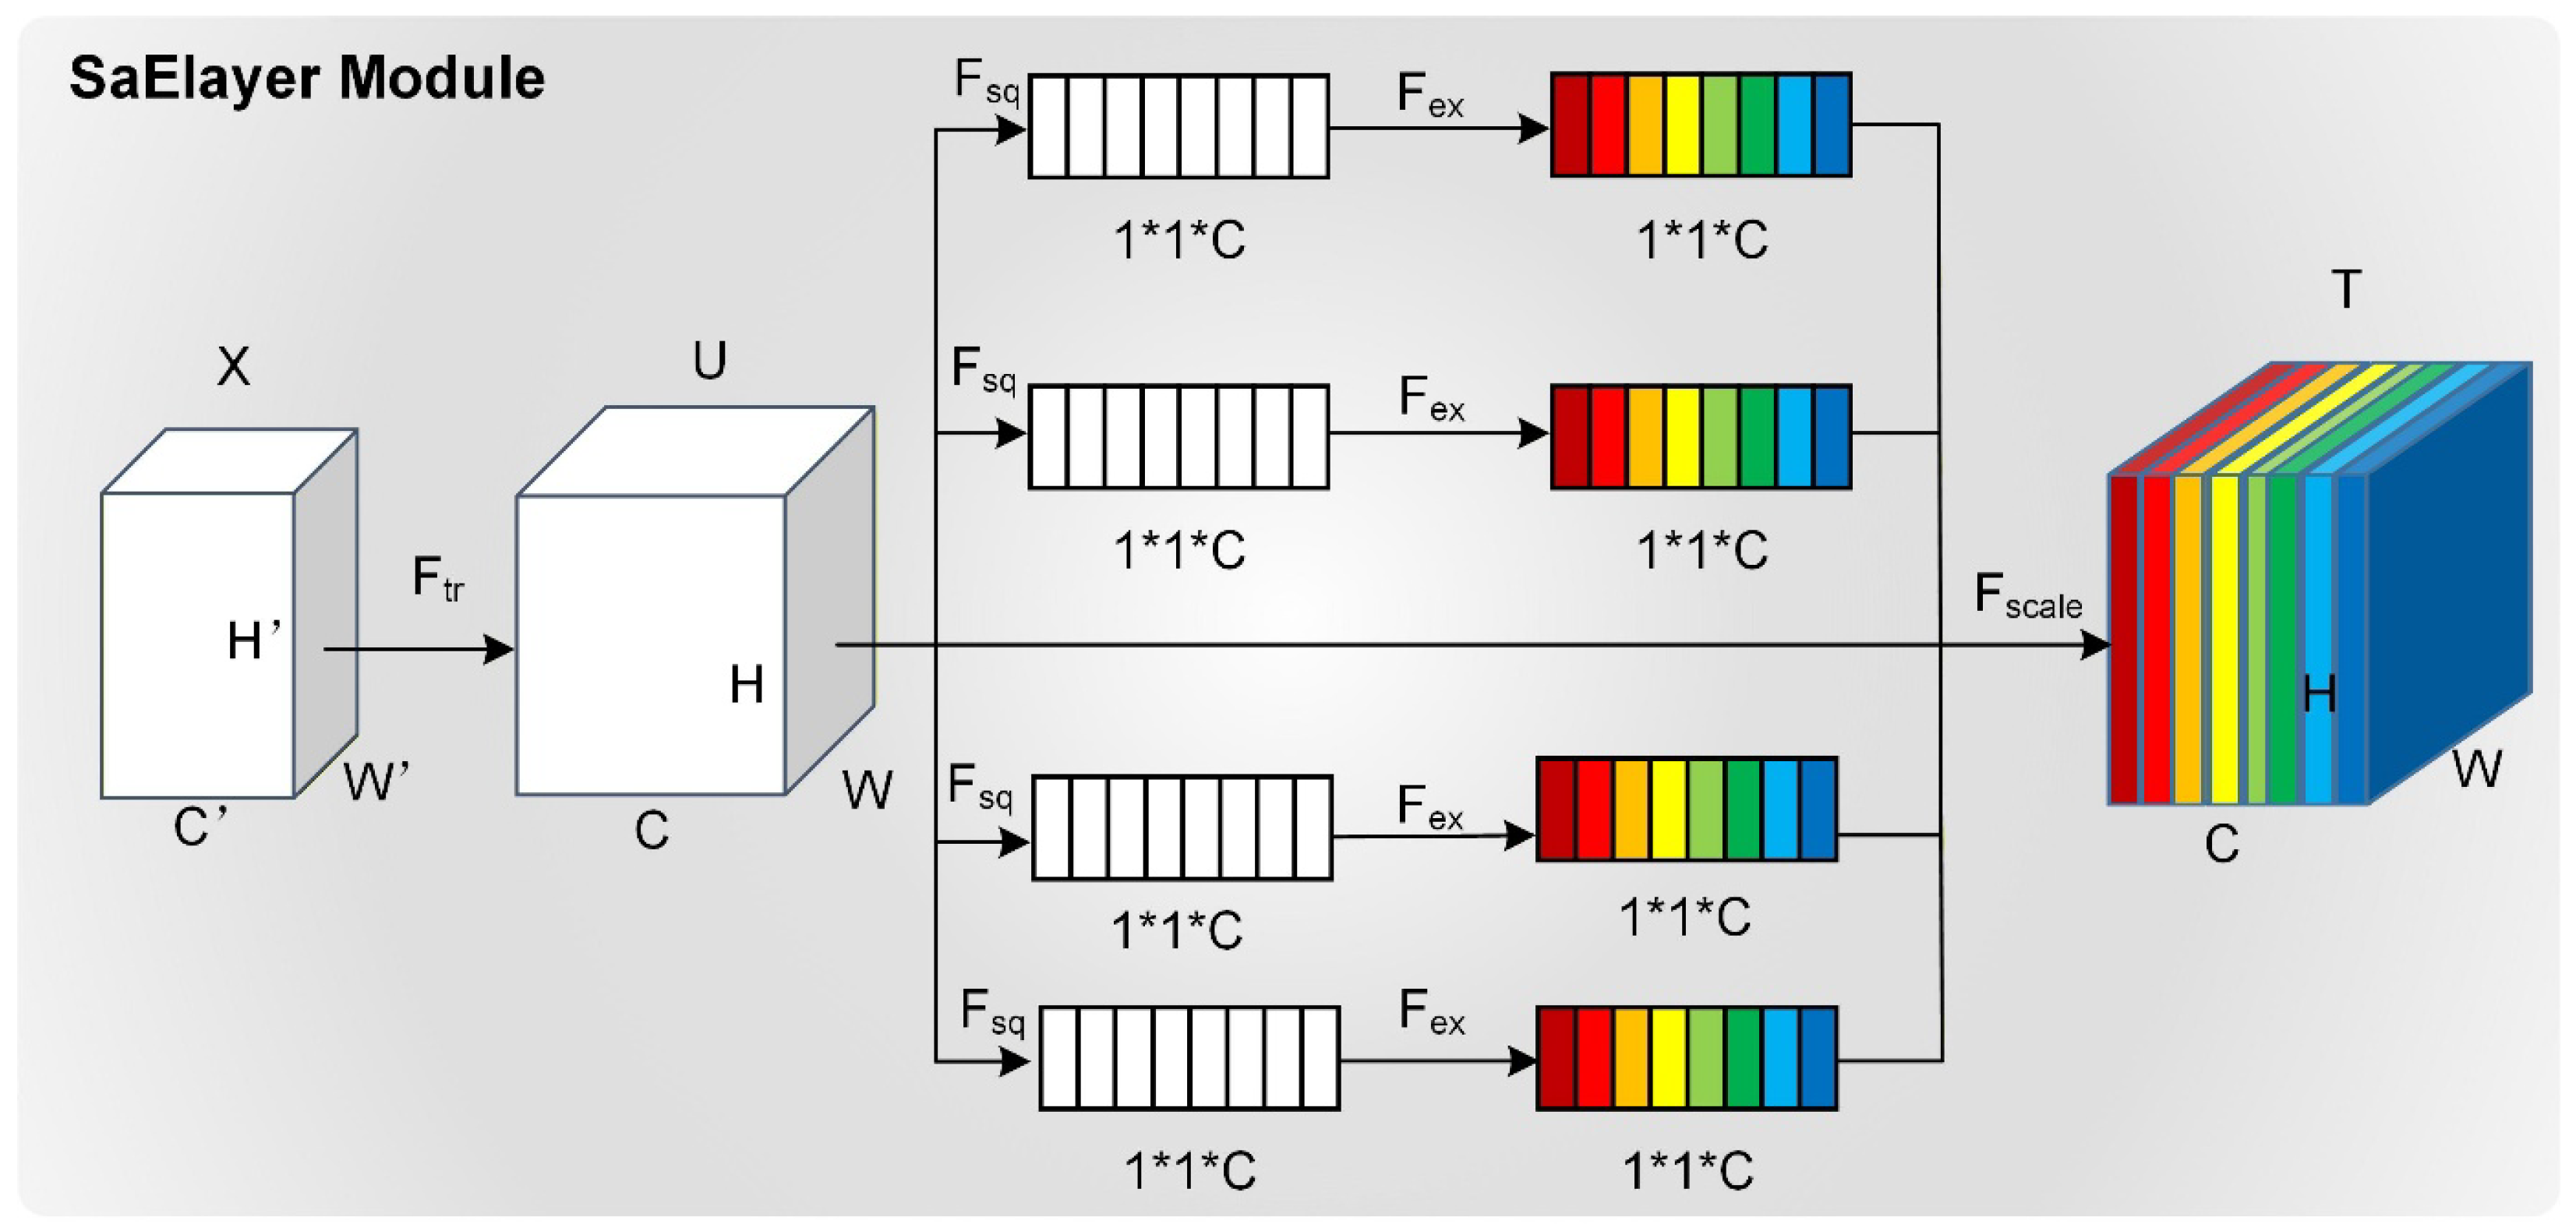
The regression branch adopts a progressive feature extraction strategy. Initially, feature extraction is performed through a convolutional layer. The features then pass through the innovative Split–enhance Attention Layer (SaELayer) for deep feature recalibration (Figure 5), enabling the model to capture diversified channel–wise dependencies and enhancing its perception of key areas such as flame boundaries and smoke diffusion patterns. Finally, the output undergoes a last round of feature extraction via another convolution before regression analysis. The final result is concatenated with the output from the classification branch.
Figure 5.
Structure of the SaElayer module. By designing a four–branch architecture, more comprehensive channel attention weights can be generated, thereby better identifying which channels are most critical for the current detection task.
Regarding the SaElayer, its specific structure is illustrated in the accompanying figure. Unlike the traditional Squeeze-and-Excitation (SE) module [52], which employs a single-path attention mechanism, this module adopts a multi–path fusion attention approach. By integrating information from multiple paths, it generates more refined and comprehensive channel attention weights, thereby more effectively identifying which channels are most critical for the current detection task compared to the single-path SE. The module begins with a transformation operation (Ftr) that converts the input feature map X into an intermediate feature map U. Here, Ftr represents a standard convolution operator, mathematically defined as follows:
Here, represents the input feature map, while and denote the output feature maps. V refers to a set of learned filter kernels, where vc indicates the parameters of the c–th filter. and represent 2D spatial kernels, and the symbol denotes the convolution operation. This convolutional operator formula indicates that each channel of the input feature map is convolved with a 2D spatial kernel, ultimately producing C output feature maps that collectively form the feature map U.
To address the issue of channel dependency, the approach compresses global spatial information into four spatial channel descriptors. This enables each branch to learn distinct types of channel relationships. Through the fusion of these four branches, more refined and comprehensive channel attention weights can be generated. The technique employed to compress spatial information into channel-wise descriptors is global average pooling (referred to as Fsq), which condenses the globally informed feature map into a feature vector z. This compression operation effectively captures inter-channel dependencies while preserving contextual information. The mathematical formulation is defined as follows:
where represents the c-th element of z. This operation is performed for each branch, ultimately yielding four feature vectors.
Each of these four feature vectors undergoes an Excitation (Fex) operation. To comprehensively capture channel dependencies, a gating mechanism composed of two fully connected layers is employed. The first fully connected layer reduces the number of channels to decrease computational complexity, followed by a ReLU nonlinear activation layer. The second fully connected layer restores the channel count, after which a Sigmoid activation function is applied to generate the weight vector s. The formula is defined as follows:
Finally, a Scale operation is performed, where the attention weights obtained from this branch are applied to the features of each channel, producing the final output.
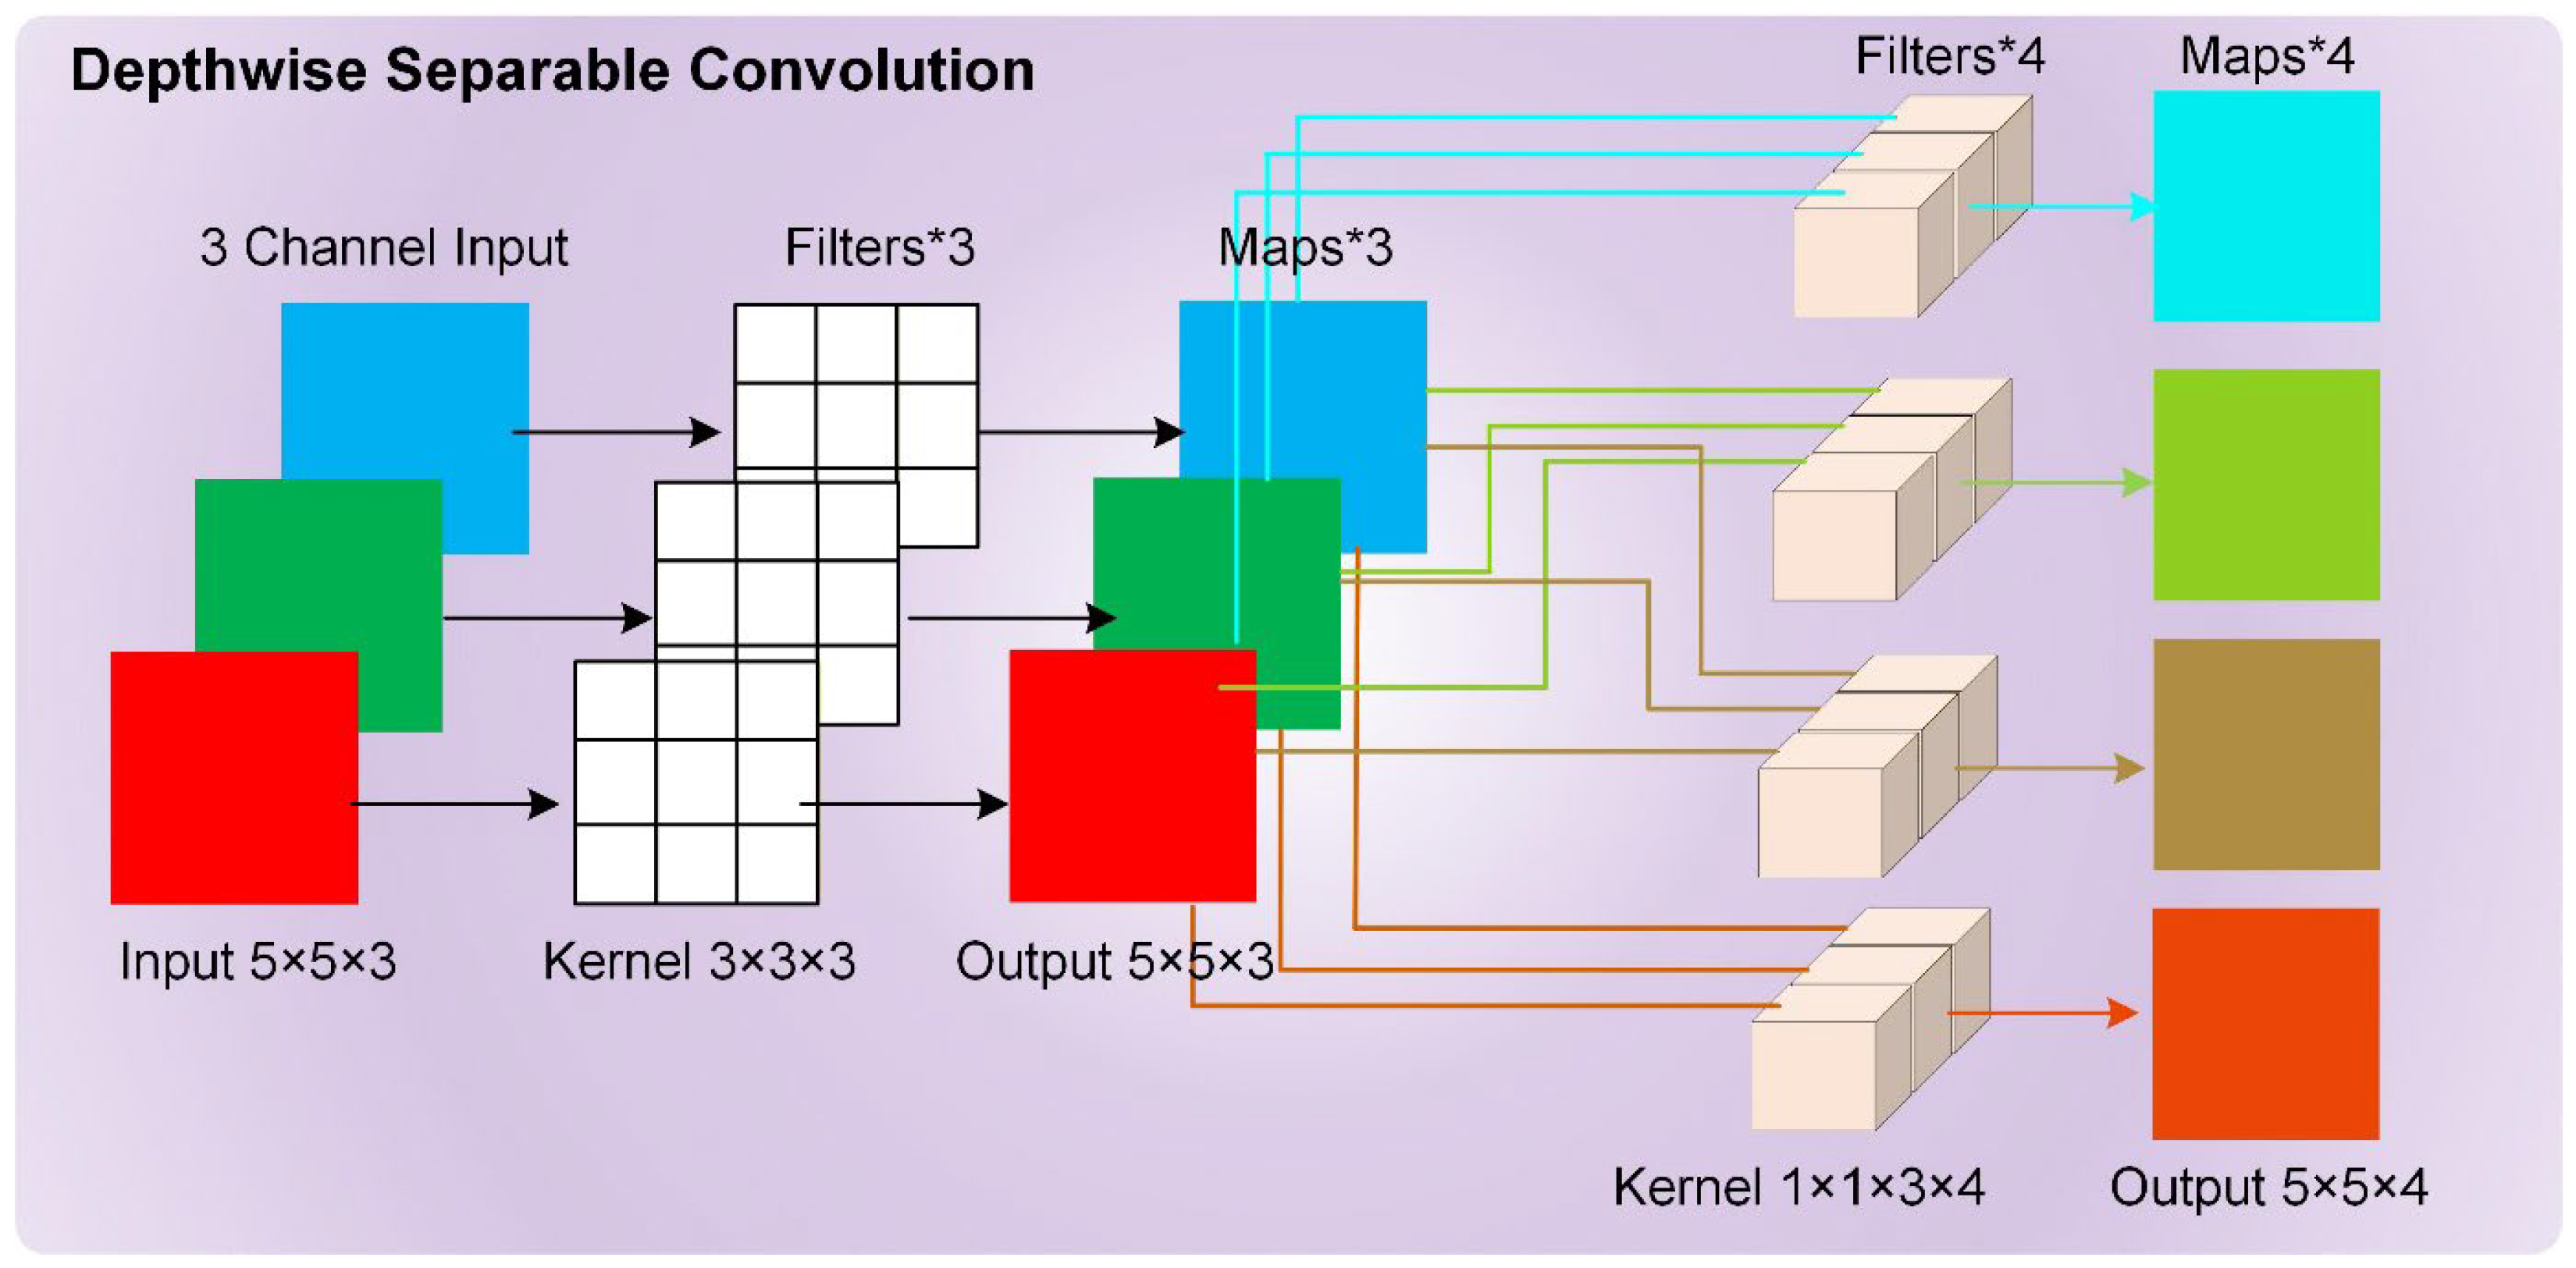
In the classification branch, SERDet strikes a balance between feature representation capability and computational efficiency. By cascading depthwise separable convolutions (DWConv) [53] with standard convolutional layers, this branch not only maintains strong flame feature extraction capabilities but also reduces both parameter count and computational complexity, significantly enhancing overall computational performance. The structure of DWConv, as illustrated in Figure 6, consists of a depthwise convolution and a pointwise convolution. The depthwise convolution extracts spatial features, while the pointwise convolution processes channel features. By combining these two operations, the number of channels can be reduced, effectively decreasing the parameters required in the convolutional layers. This design significantly reduces the parameter of the model count while achieving faster processing speeds. Consequently, it simplifies the computational model and enables high-precision inference on resource-constrained devices, making it particularly suitable for flame detection scenarios in UAV applications.
Figure 6.
Structure of the DWConv module. This module employs a cascade design of depthwise and pointwise convolutions, decoupling the standard convolution into two independent operational steps. This approach significantly reduces the parameter count while maintaining effective feature extraction capability, thereby achieving an excellent balance between model accuracy and inference speed.
2.2.4. NWD Loss Function
Although YOLOv8 demonstrates outstanding performance in general detection tasks, flame recognition requires small object detection capabilities. However, the default CIoU Loss [54] adopted by YOLOv8 proves insufficient for small object detection. As a bounding box regression loss function, CIoU exhibits high sensitivity to localization errors in small targets. When detecting minimal flame areas, even a few pixels of deviation can cause a sharp decline in IoU values. This sensitivity to small targets adversely affects both the optimization process and inference stability, not only slowing convergence through degraded sample assignment but also impairing localization accuracy due to gradient vanishing induced by minor positional deviations in small flame detection. Regarding the NWD loss function employed by the model, NWD models bounding boxes as two-dimensional Gaussian distributions and computes the Wasserstein distance between these distributions. This approach provides a smoother similarity measure for tiny objects that is less sensitive to scale variations. By incorporating this method, the detection and localization of small flame targets can be significantly improved without encountering issues such as gradient vanishing.
The NWD loss function first requires modeling the bounding boxes as Gaussian distributions. From a probabilistic perspective, the bounding boxes are represented as two-dimensional Gaussian distributions, which can reflect the importance of different pixels within the bounding box. For a given horizontal bounding box , where represents the center coordinates and w and h denote the width and height, respectively, it is transformed into a Gaussian distribution . The mean vector and covariance matrix are defined as follows:
This covariance matrix ensures that the density contour ellipse of the Gaussian distribution precisely aligns with the inscribed ellipse of the bounding box. During training, for each ground truth box Bgt and predicted box Bpred, we perform this transformation to obtain their corresponding Gaussian distributions Ngt and Npred. After obtaining these Gaussian distributions, the next step is to compute their similarity. This is achieved by calculating the Wasserstein distance between them, which offers the advantage of effectively capturing spatial correlation even when the two distributions do not overlap. For two two-dimensional Gaussian distributions and , the second-order Wasserstein distance has a closed-form solution and can be simplified as:
represents a distance vector, and the raw result may be a large numerical value. Since similarity metrics require values in the range [0, 1], exponential normalization is applied to convert it into a similarity measure with IoU-like properties, known as the Normalized Wasserstein Distance (NWD):
where is a dataset–so constant used to control the sensitivity of NWD to distance variations. Therefore, the bounding box regression loss in YOLOv8 is replaced with the NWD loss, defined by the following formula:
After incorporating this loss function, it not only enhances the detection accuracy of small targets but also complements the Distribution Focal Loss (DFL) in YOLOv8. DFL models bounding box coordinates as discrete probability distributions, helping the network learn positional information more accurately. Its role is primarily reflected in the microscopic optimization of each coordinate distribution. In contrast, NWD operates at a macroscopic level, supervising the overall quality of bounding box regression with a more robust metric. This combination is particularly suitable for tiny targets like flames, as the optimization objective provided by NWD is less sensitive to minor deviations, thereby contributing to a more stable training process.
3. Experiments and Analysis
3.1. M4SFWD Dataset
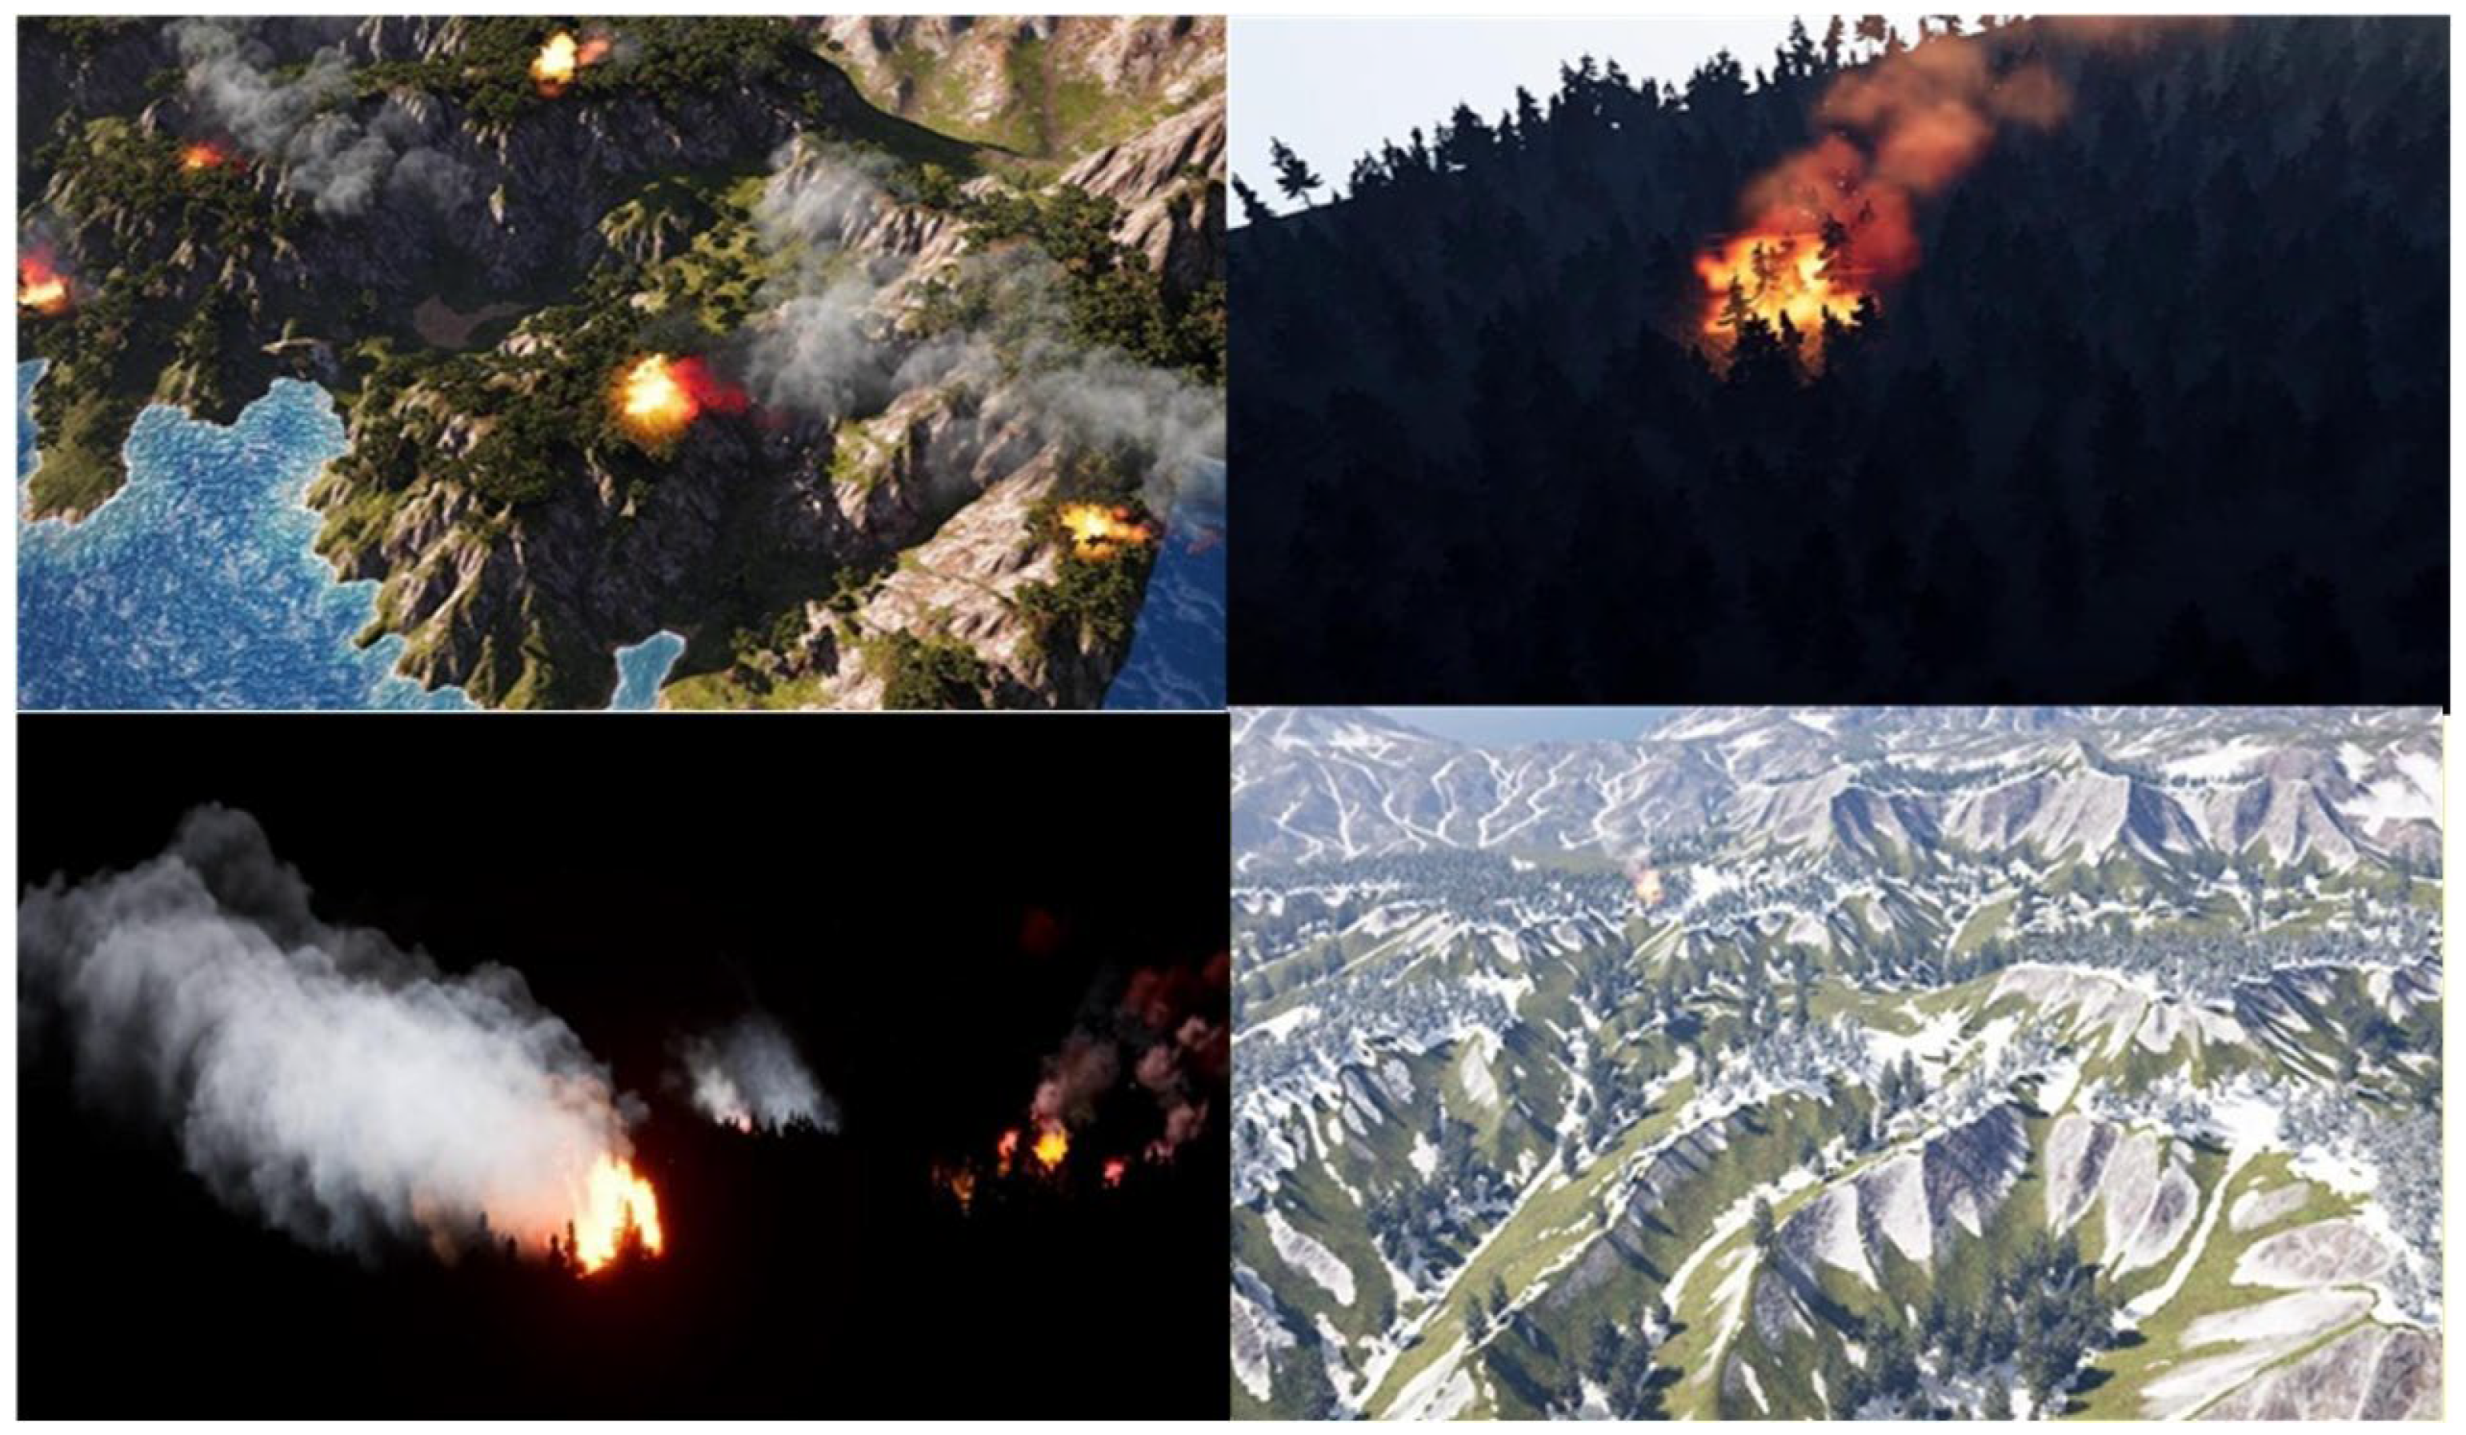
M4SFWD is a synthetic forest fire dataset constructed using Unreal Engine 5. By creating diverse forest scenes, this dataset simulates all-weather lighting intensity variations and incorporates multi-scale wildfire targets, ultimately generating a sample set comprising 3974 images with 17,763 accurately annotated bounding boxes. Its distinctive feature lies in the construction of eight different terrain scenarios encompassing three weather conditions (clear, foggy, rainy/snowy) and three lighting environments (daylight, dusk, nighttime). All data undergo professional pixel-level manual annotation, with some examples illustrated in the accompanying Figure 7. The selected sample images present fire data from volcanic, forest, and snowy mountain scenarios, offering an intuitive illustration of the dataset’s content and coverage.
Figure 7.
The M4SFWD dataset. It presents fire incidents in scenarios such as volcanic areas, forests, and snowy mountains.
3.2. Experimental Environment and Parameter Settings
This experiment utilized the PyTorch (version 2.0.1) framework and Python (version 3.8) programming language. All models were trained on a Windows 10 operating system with the following hardware configuration: an Intel Xeon Platinum 8163 @ 2.50 GHz 24-core processor, an NVIDIA GeForce RTX 4090D GPU (47 GB VRAM), and the CUDA 11.7 computing platform. Detailed training parameters are provided in Table 2.
Table 2.
Experimental parameter settings.
3.3. Model Evaluation
To objectively analyze the performance of various methods in flame and smoke detection, this experiment employs mAP50, parameter count, floating point operations (FLOPs), and real-time performance as evaluation metrics.
- (1)
- Mean Average Precision (mAP)
mAP50 (mean Average Precision at IoU threshold 0.5) is a core and widely adopted evaluation metric in object detection models. It specifically represents the precision performance of the model when the Intersection over Union (IoU) threshold is set to 0.5. This metric primarily focuses on assessing the capability to detect targets accurately, counting only detection instances where the predicted bounding box overlaps with the ground truth annotation by at least 50%, while being relatively insensitive to the precise localization of the bounding box. The specific calculation formula is as follows:
In contrast, mAP50–95 is a more rigorous metric. It progressively increases the IoU threshold from 0.5 to 0.95 in increments, calculates the mAP at each threshold, and then computes the average of these values. This metric provides a more comprehensive evaluation of the precision and adaptability across various scenarios. The specific formula is as follows:
- (2)
- Parameter Count
Parameter count serves as a critical metric for evaluating model complexity. Generally, a higher parameter count enhances the capacity of the model to handle complex scenarios. However, increasing parameters also leads to higher computational demands and places greater strain on hardware resources. Therefore, parameter count remains an indispensable metric in model analysis.
- (3)
- Floating Point Operations (FLOPs)
Floating Point Operations (FLOPs) are a direct metric for quantifying the computational burden of a model. Since flame detection systems often need to operate on computationally constrained devices such as cameras or drones, even if a model is designed for high performance, if its FLOPs are excessively high, it may still lead to impractical deployment outcomes. Given that modern models typically have extremely large FLOPs values, this metric is generally expressed in Giga Floating Point Operations (GFLOPs). The formula is defined as follows:
- (4)
- Real-time Performance
Real–time performance, measured in FPS (Frames Per Second), is a direct indicator of model efficiency. A higher FPS value signifies that the model can process more images per second, indicating faster inference speed and superior real–time capability. Given that fire detection requires extremely rapid response times, this metric is particularly crucial.
3.4. Ablation Experiment
To evaluate the performance of the proposed model, an ablation study was conducted on the M4SFWD dataset. By incrementally incorporating individual modules, the contribution of each component to the overall model performance was systematically analyzed, providing a clear understanding of their respective impacts. The detailed results are summarized in Table 3, where A denotes the RepNCSPELAN4 and SPPELAN modules, B represents the NWD loss function, and C indicates the SERDet module.
Table 3.
Ablation experiments on the M4SFWD dataset.
Based on the analysis of the table above, compared to the baseline YOLOv8 model, the accuracy of the model increases with the addition of each module, indicating that each module contributes positively to the performance. Experiment 1 represents the performance of the traditional YOLOv8 model on the M4SFWD dataset. It can be observed that the model demonstrates strong overall performance, making it a suitable baseline for subsequent experiments. Experiment 2 builds upon the baseline model by incorporating the RepNCSPELAN4 and SPPELAN modules. Compared to the baseline, this configuration achieves a 0.2% improvement in flame detection accuracy, a 0.9% improvement in smoke detection accuracy, and an overall accuracy increase of 0.4%. Experiment 3 replaced the traditional loss function with the NWD loss function on the baseline model, resulting in a 0.3% increase in flame detection accuracy, a 1.2% increase in smoke detection accuracy, and an overall improvement of 0.7% compared to the baseline. Experiment 4, on the other hand, replaced the detection head with SERDet in the baseline model, leading to a 0.7% improvement in flame detection accuracy, a 1.0% improvement in smoke detection accuracy, and an overall enhancement of 0.8% compared to the baseline. When the NWD loss function is further added to the Experiment 2 setup, the model shows additional enhancements: flame detection accuracy increases by 0.4%, smoke detection accuracy by 0.4%, and overall accuracy by 0.5% compared to Experiment 2. Experiment 6 further enhances the model by integrating the SERDet module into the framework of Experiment 5. Compared to Experiment 5, this addition results in a 0.6% improvement in flame detection accuracy, a 0.6% increase in smoke detection accuracy, and an overall accuracy boost of 0.9%. In summary, the cumulative improvements of the proposed model demonstrate significant advancements over the baseline: flame detection accuracy is elevated by 1.2%, smoke detection accuracy by 2.4%, and overall accuracy by 1.5%. Notably, while achieving these precision enhancements, the model maintains competitive processing speed, highlighting its strong practical applicability and generalization capability.
3.5. Comparison with Other Models
This study selected several representative YOLO object detection frameworks to validate the effectiveness of the proposed model, including YOLOv8, YOLOv9 [55], YOLOv10 [56], and YOLOv11 [57]. These frameworks are currently mainstream object detection solutions in the field, capable of effectively reflecting the performance of our proposed model. All comparative experiments were conducted under the same hardware configuration and experimental environment using the M4SFWD dataset, with the results presented in Table 4.
Table 4.
Comparison experiments on the M4SFWD dataset.
As evidenced in Table 4, the proposed SER–YOLOv8 model demonstrates the best overall performance among all compared models. It achieves the highest accuracy in flame detection, smoke detection, and overall detection precision, particularly with a remarkable mAP50–95 score of 51.3%, representing a significant performance milestone. Compared to YOLOv9, which requires substantial parameter counts and shows limited FPS performance, SER-YOLOv8 delivers exceptionally well-balanced results. Although there is some trade–off in FPS, the model maintains a reasonably efficient inference speed. In summary, the proposed model has achieved substantial improvements in detection accuracy, especially in identifying small flame targets, which is a critical capability for early–stage fire detection when flames first emerge. This enhancement enables fires to be more effectively contained at their initial development phase.
3.6. Visualization and Analysis of Results
To more intuitively demonstrate the performance of the proposed model, this paper presents detection results from both the YOLOv8 model and the SER-YOLOv8 model. Figure 8 shows the detection results of the YOLOv8 model.
Figure 8.
Detection results of YOLOv8. The red bounding boxes indicate the localization of objects identified by the YOLOv8 model, while the numbers represent the probability that the detected object belongs to the identified class.
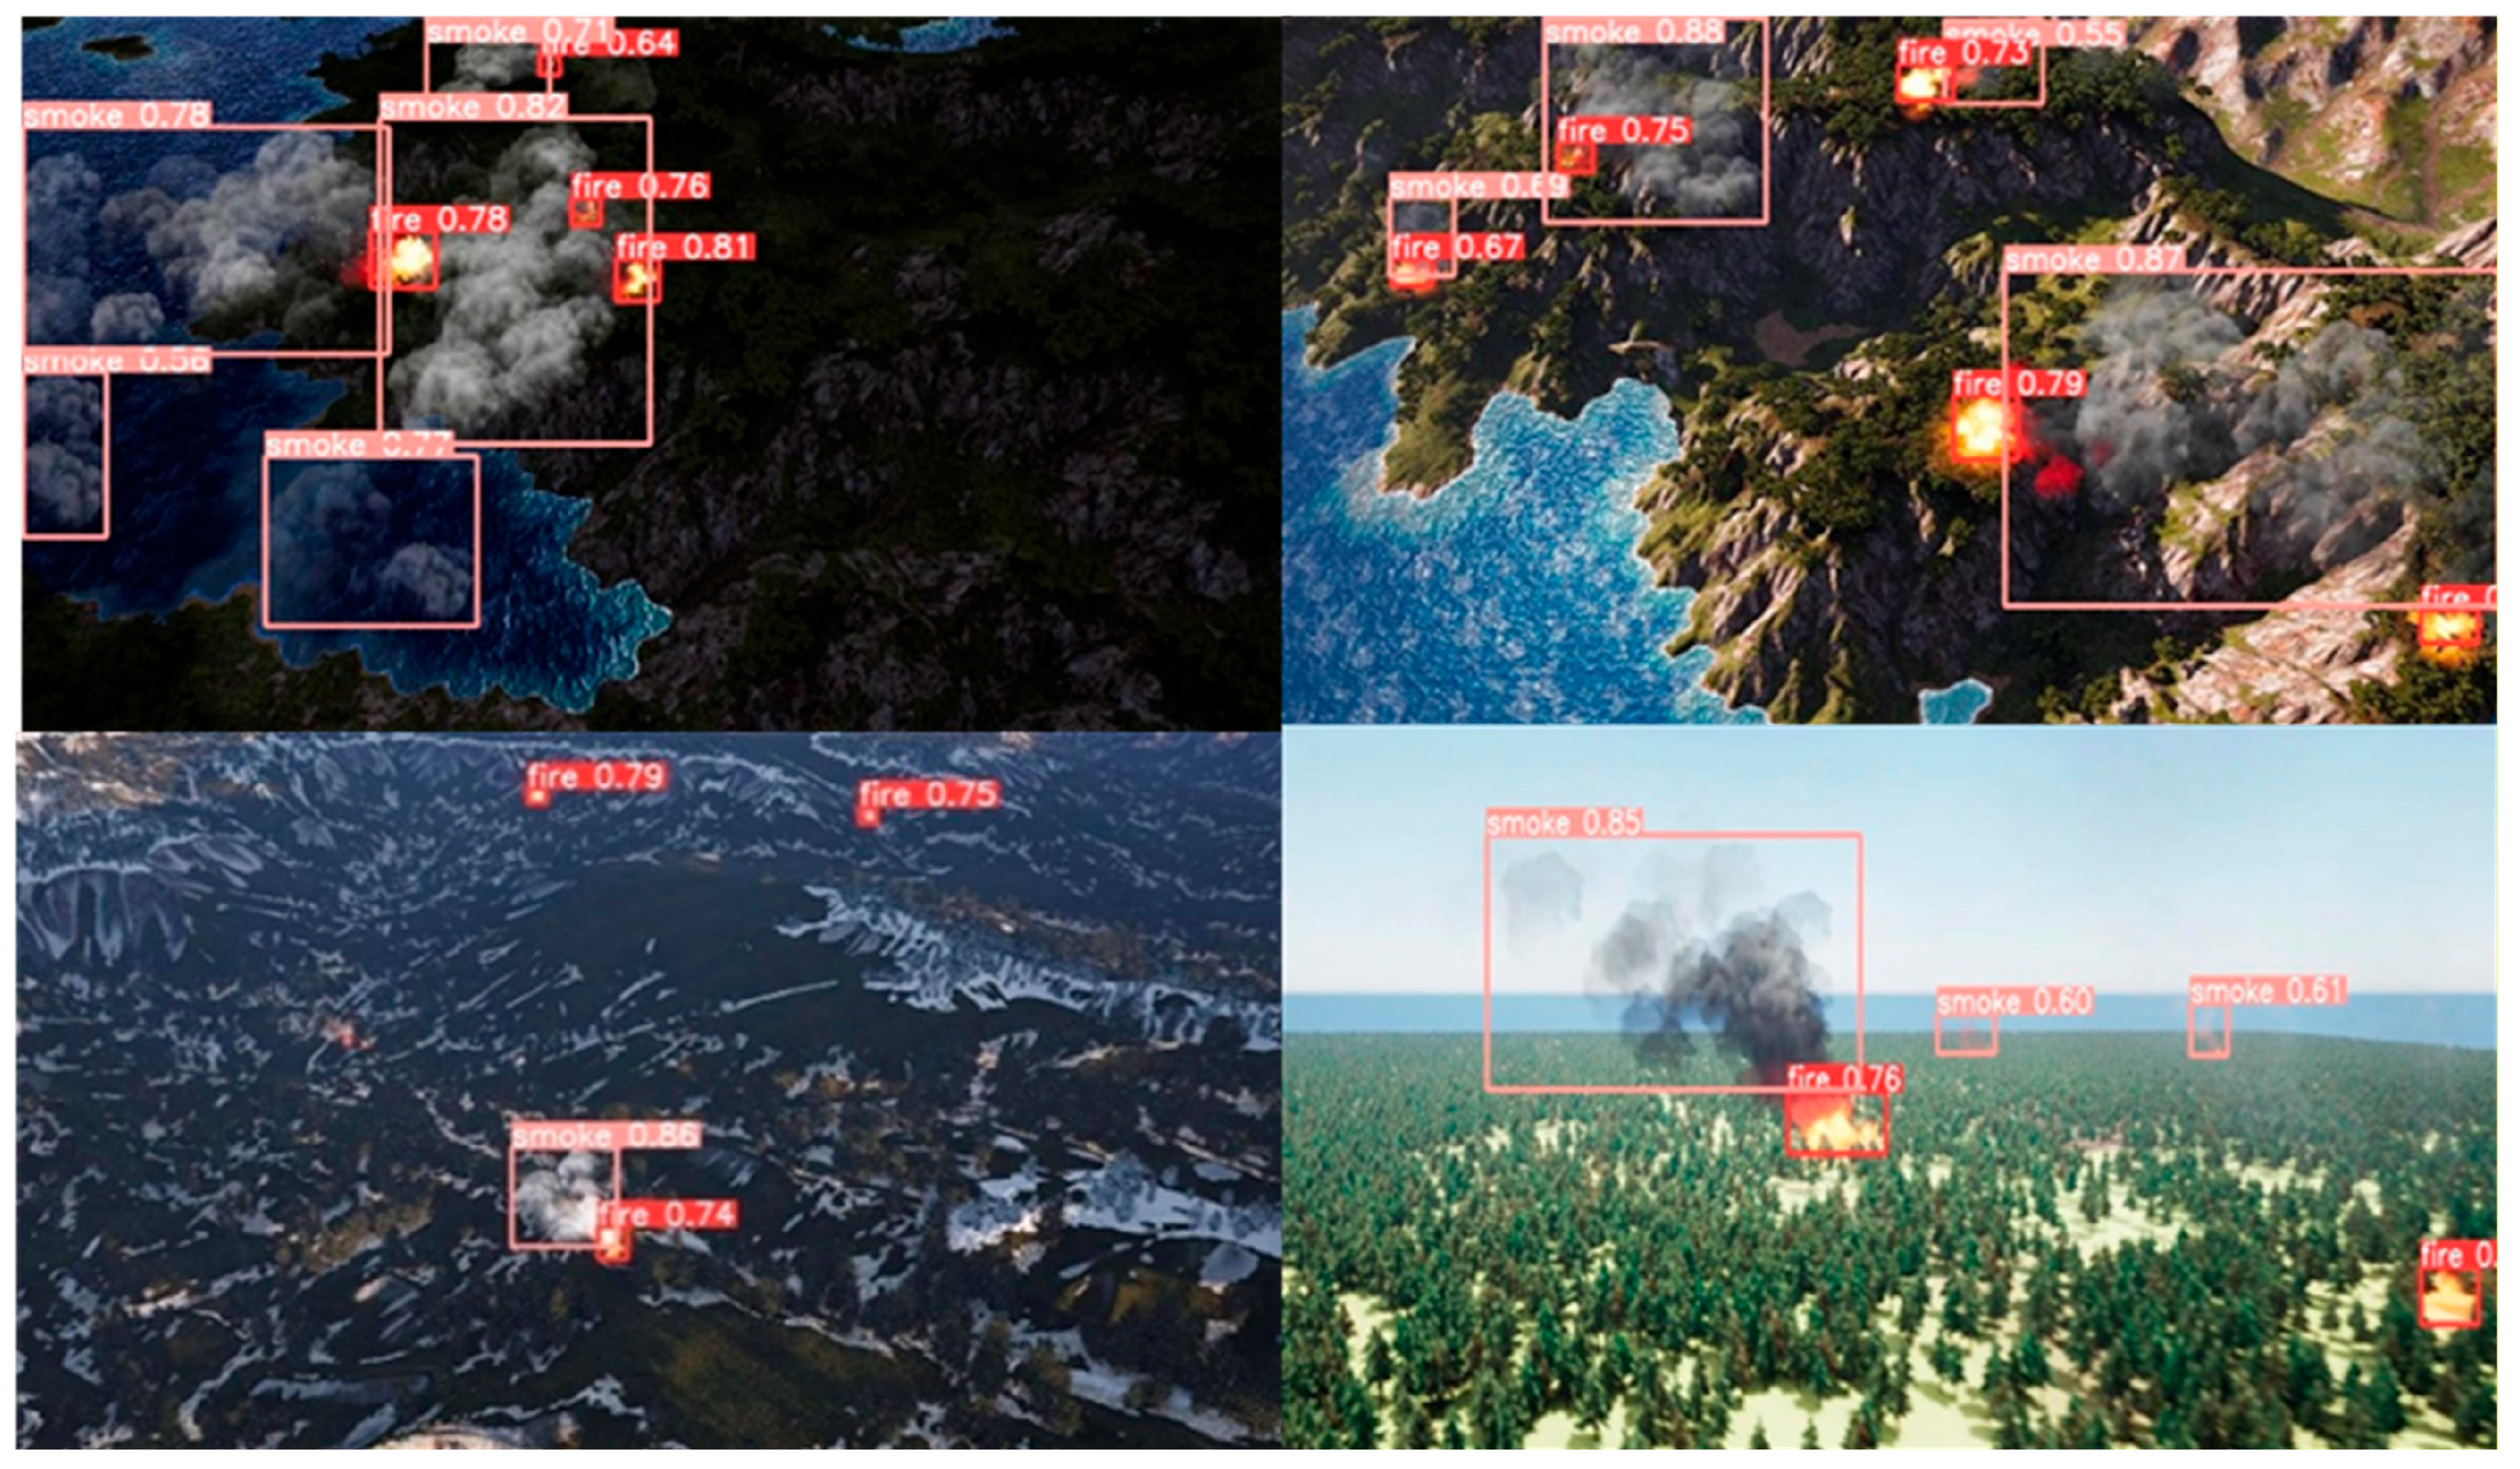
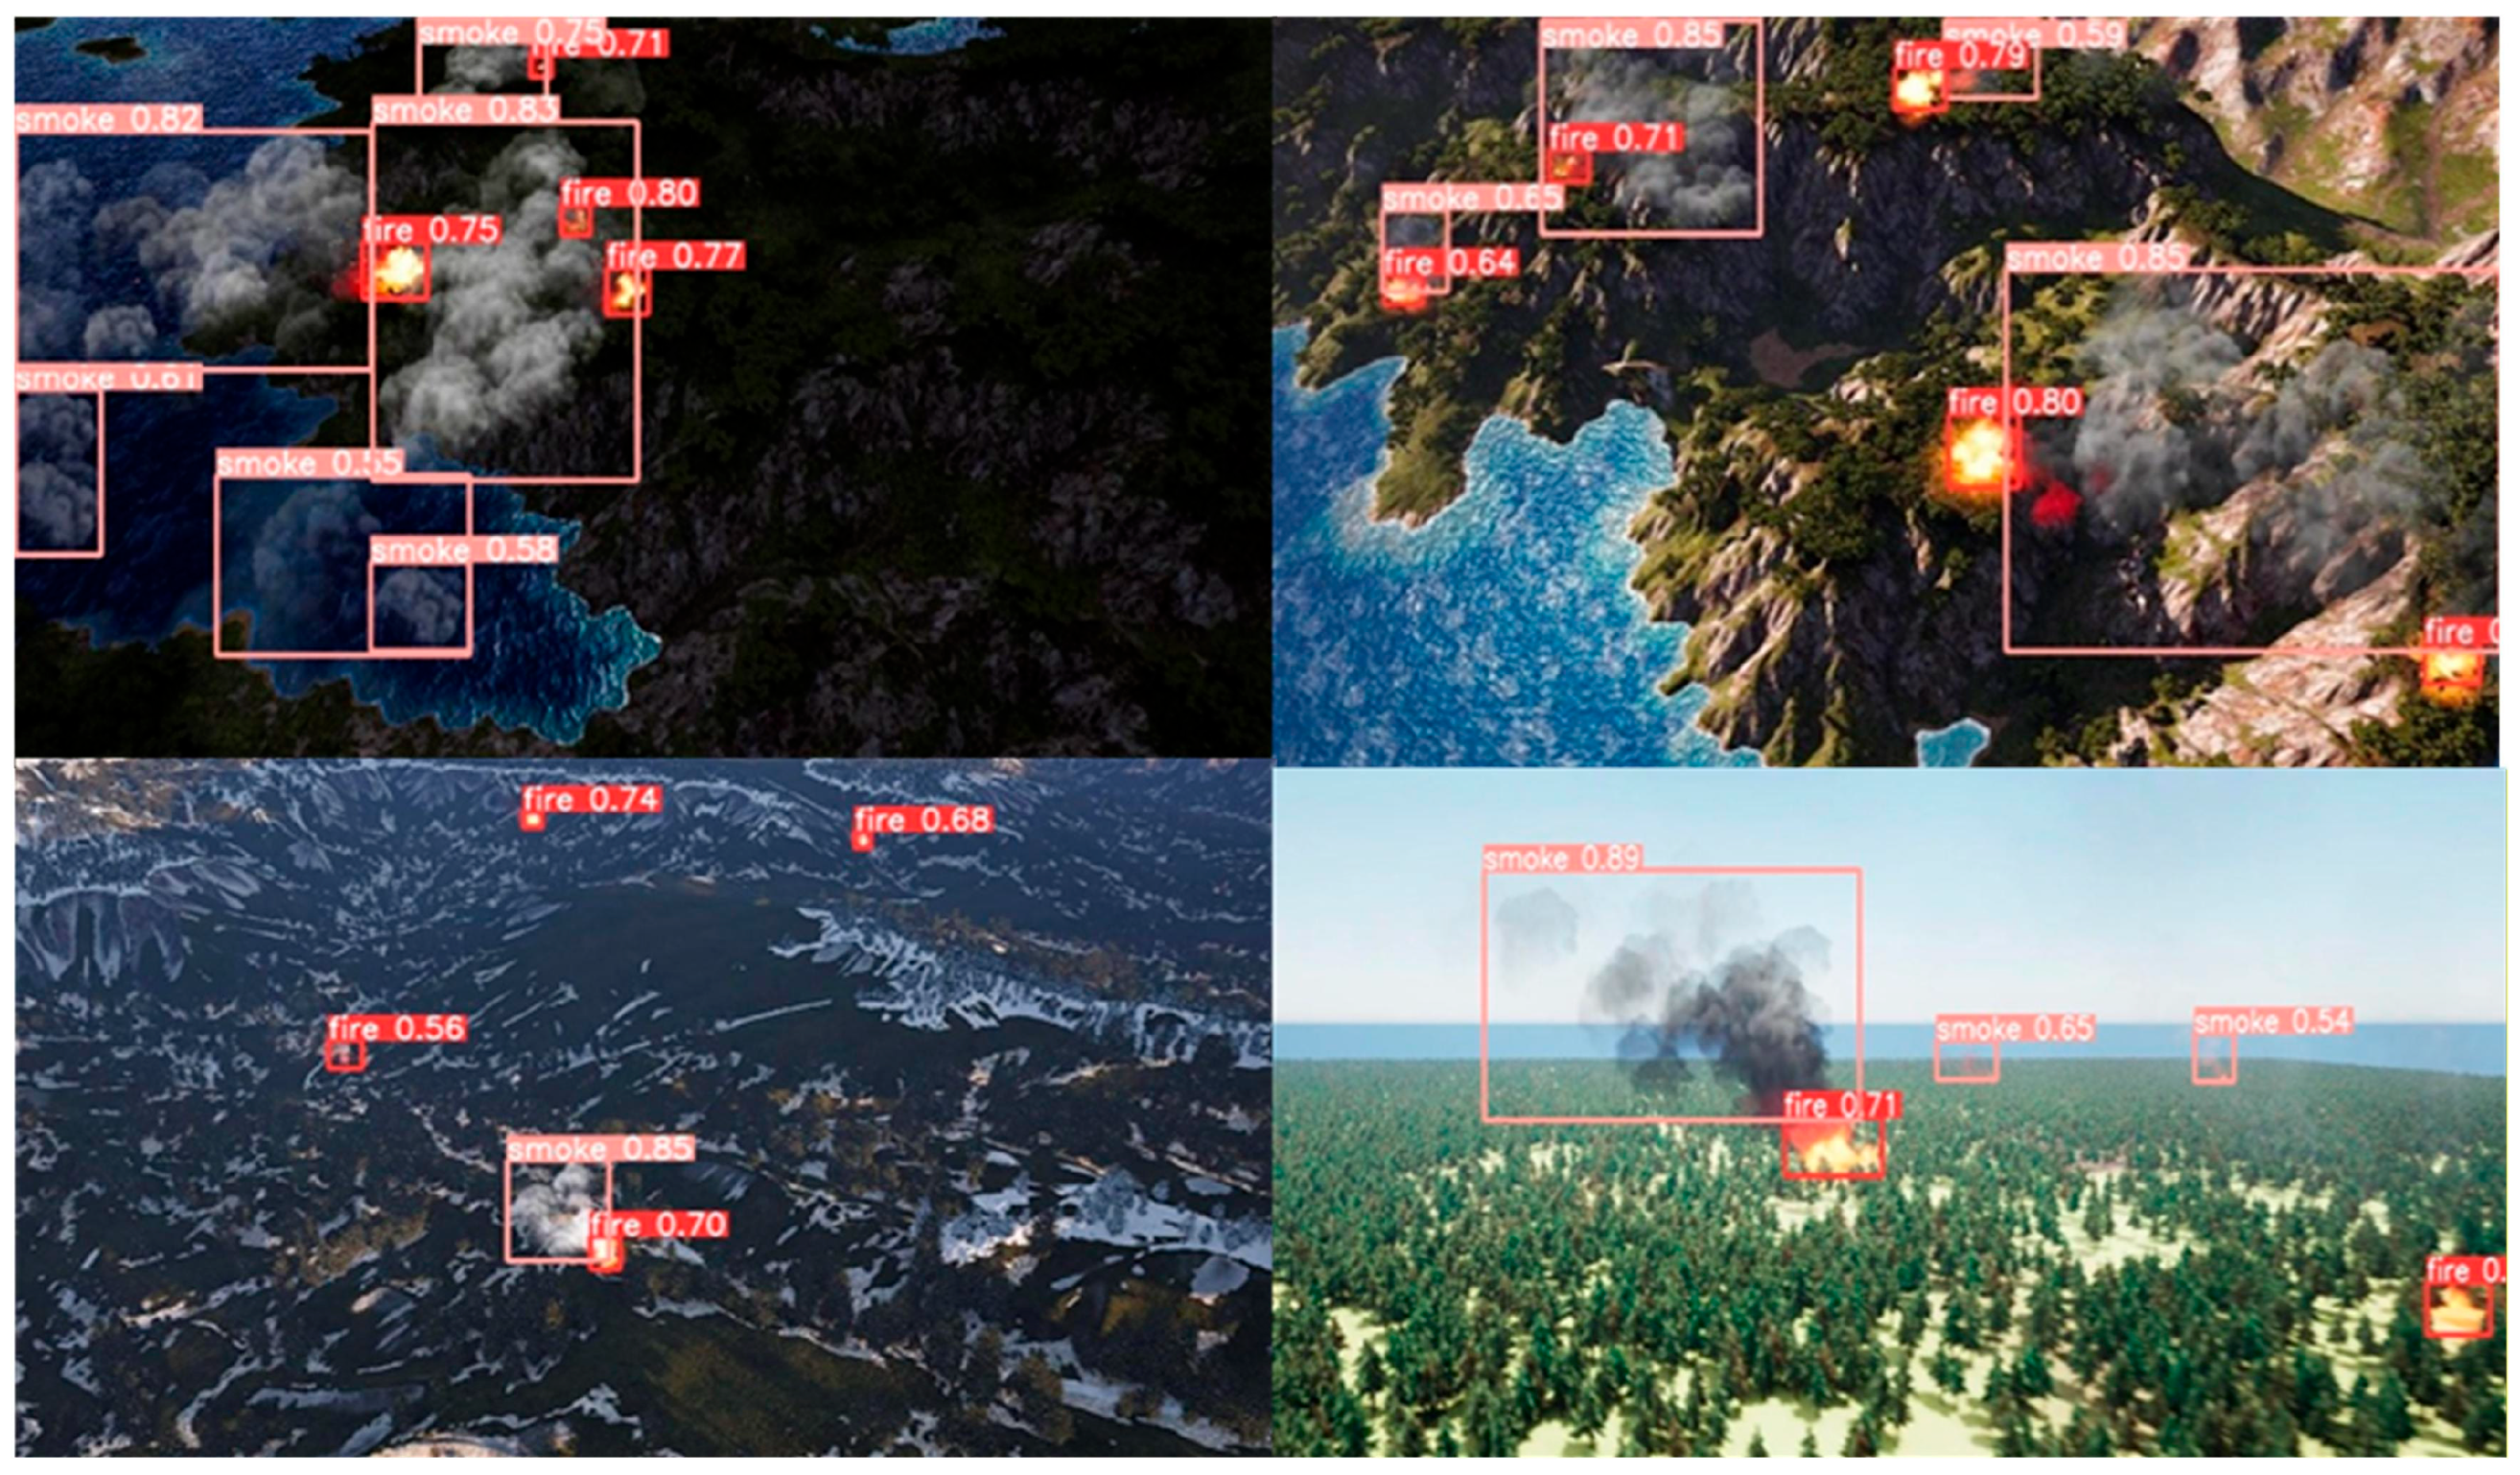
As clearly shown in Figure 8, while YOLOv8 can detect most prominent flames, it tends to miss some very small flame instances. Furthermore, when multiple smoke plumes cluster together, the YOLOv8 model often produces only a single detection bounding box, resulting in insufficient delineation. Figure 9 presents the detection results of SER-YOLO, which demonstrates robust performance in detecting both prominent and small flames. Moreover, even in cases of clustered or partially occluded smoke, SER-YOLO accurately identifies and clearly delineates individual instances. Overall, SER-YOLO exhibits superior advantages in handling small targets, showcasing enhanced detection robustness, improved localization accuracy, and stronger adaptability to complex environmental conditions.
Figure 9.
Detection results of SER–YOLOv8. The red bounding boxes indicate the localization of objects identified by the SER–YOLOv8 model, while the numbers represent the probability that the detected object belongs to the identified class.
4. Further Discussion
To enhance the detection accuracy and feature representation capability of the model in forest fire scenarios, enabling it to focus more on task-relevant features and improve generalization, this study introduces modifications to the YOLOv8 model. Through multiple comparative experiments, the proposed SER-YOLOv8 model demonstrates significantly superior performance in both flame and smoke detection accuracy compared to the original YOLOv8 model. The SER-YOLOv8 model first enhances its feature extraction capability by replacing the original C2f module and SPPF module in the network structure with the RepNCSPELAN4 module and SPPELAN module. Subsequent experiments revealed that while the model’s accuracy improved, the magnitude of enhancement remained limited. To address the limitations of the original IoU-based loss function, this study replaced it with the NWD loss function. This loss function supervises the overall quality of bounding box regression through a more robust metric, making it particularly suitable for small targets like flames. Experimental results confirmed a further improvement in detection accuracy after this modification. Finally, this study innovatively improved the detection head by introducing multi–path fused attention, further enhancing sensitivity to flame detection. Meanwhile, Depthwise Convolution (DWConv) was incorporated to reduce parameter count and accelerate computational speed. Experimental results demonstrated that these modifications led to a substantial improvement in model accuracy. Overall, the proposed model enhances the detection precision for both flames and smoke while enabling the identification of small-scale flames and those in complex backgrounds. Its robust performance contributes to early fire detection and intervention in forest fire prevention, thereby significantly strengthening early warning and forecasting capabilities.
However, the generalization capability of the model across diverse environments and conditions may still have certain limitations. Therefore, future research work could involve training and validating the model on additional datasets to enhance its adaptability. Additionally, with the rapid development of attention mechanisms, integrating supplementary attention modules into other components of the network could further improve feature extraction capacity. Meanwhile, although inference speed remains relatively fast, a reduction has been observed. To address this, future work may explore model pruning techniques to refine the architecture, reduce parameter count, and accelerate operational speed. Furthermore, there is still room for improvement in detection accuracy, which remains a key objective for ongoing optimization.
5. Conclusions
The proposed SER–YOLOv8 model in this study primarily aims to enhance detection accuracy, particularly by improving the model’s capability to identify flames and smoke in complex backgrounds and to detect small-scale flames and smoke. Overall, compared to the original YOLOv8 model, SER–YOLOv8 achieves a 1.2% increase in flame detection accuracy, a 2.4% improvement in smoke detection accuracy, and a 1.5% enhancement in overall accuracy on the M4SFWD dataset. Furthermore, compared to other mainstream YOLO-based object detection models, the proposed model also achieves optimal accuracy, making it a highly suitable solution for early detection of small–scale flames and smoke in forest fire scenarios. Future work will primarily focus on validating its performance across more diverse datasets to enhance generalization capability, while further optimizing inference speed to achieve faster real–time flame detection. These improvements will collectively contribute to improving the accuracy of forest fire monitoring systems. Although the absolute improvements in various accuracy metrics are limited, as outlined in the Introduction, the irregular morphology of flame targets, complex environmental occlusions, and the focus on detecting small–scales objects collectively pose significant technical challenges. Therefore, the performance gains achieved over existing research, particularly the enhancements observed in small–target detection, hold crucial substantive significance. From the perspective of economic and ecological benefits, even a minor improvement in early detection capability can significantly reduce the high costs associated with firefighting and ecological restoration after a fire spreads. The cost of containing fires in their early stages is far lower than that of large–scale firefighting operations. Therefore, the accuracy improvements achieved by our model can contribute to earlier warnings and interventions, thereby avoiding substantial economic losses and preserving the stability and biodiversity of forest ecosystems. This highlights the important practical application value of our work.
Author Contributions
Conceptualization, J.L. and J.F.; methodology, J.L. and J.F.; software, J.L., J.F. and S.W.; validation, J.F. and S.W.; formal analysis, J.L.; data curation, Y.D. and J.G.; resources, J.H.; project administration, Y.L.; funding acquisition, J.L. and J.H.; writing—original draft, S.W., Y.D. and J.G.; investigation, W.X.; writing—review & editing, J.L. and J.F. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by the Basic Research Project of Shanxi Province (Youth) under Grant 202303021222066, the Middle-aged and Young Elite Innovative Talent Cultivation Project under Grant SXAUKY2024002, Lvliang City Key Research and Development Program under Grant 2025NY17, and Graduate Quality Engineering Project of Shanxi Agricultural University under Grant 2025YZLGC033 and 2025JG056.
Institutional Review Board Statement
Not applicable.
Data Availability Statement
The data presented in this study are available on request from the corresponding author.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Kanwal, R.; Rafaqat, W.; Iqbal, M.; Song, W. Data-Drive Approaches for Wildfire Mapping and Prediction Assessment Using a Convolutional Neural Network (CNN). Remote Sens. 2023, 15, 5099. [Google Scholar] [CrossRef] [Scilit]
- Attri, V.; Dhiman, R.; Sarvade, S. A review on status, implications and recent trends of forest fire management. Arch. Agric. 2020, 5, 592–602. [Google Scholar] [CrossRef] [Scilit]
- Yun, T.; Jiang, K.; Li, G.; Eichhorn, M.P.; Fan, J.; Liu, F.; Chen, B.; An, F.; Cao, L. Individual tree crown segmentation from airborne LiDAR data using a novel Gaussian filter and energy function minimization-based approach. Remote Sens. 2021, 256, 112307. [Google Scholar] [CrossRef] [Scilit]
- Li, X.Y.; Jin, H.J.; Wang, H.W.; Marchenko, S.S.; Shan, W.; Luo, D.L.; He, R.X.; Spektor, V.; Huang, Y.D.; Li, X.Y.; et al. Influences of forest fires on the permafrost environment: A review. Adv. Clim. Change Res. 2021, 12, 48–65. [Google Scholar] [CrossRef] [Scilit]
- Bui, D.T.; Le, K.-T.T.; Nguyen, V.C.; Le, H.D.; Revhaug, I. Tropical Forest Fire Susceptibility Mapping at the Cat Ba National Park Area, Hai Phong City, Vietnam, Using GIS-Based Kernel Logistic Regression. Remote Sens. 2016, 8, 347. [Google Scholar]
- Clarke, H.; Cirulis, B.; Penman, T.; Price, O.; Boer, M.M.; Bradstock, R. The 2019–2020 Australian forest fires are a harbinger of decreased prescribed burning effectiveness under rising extreme conditions. Sci. Rep. 2022, 12, 11871. [Google Scholar] [CrossRef] [Scilit]
- Adhikari, R.K.; Grala, R.K.; Grado, S.C.; Grebner, D.L.; Petrolia, R. Landowner concerns related to availability of ecosystem services and environmental issues in the southern United States. Ecosyst. Serv. 2021, 49, 101283. [Google Scholar] [CrossRef] [Scilit]
- Mockrin, M.H.; Fishler, H.K.; Stewart, S.I. After the fire: Perceptions of land use planning to reduce wildfire risk in eight communities across the United States. Int. J. Disaster Risk Reduct. 2020, 45, 101444. [Google Scholar] [CrossRef] [Scilit]
- Bouguettaya, A.; Zarzour, H.; Taberkit, A.M.; Kechida, A. A review on early wildfire detection from unmanned aerial vehicles using deep learning-based computer vision algorithms. Signal Proc. 2022, 190, 108309. [Google Scholar] [CrossRef] [Scilit]
- Jiao, Z.; Zhang, Y.; Xin, J.; Mu, L.; Yi, Y.; Liu, H.; Liu, D. A Deep Learning Based Forest Fire Detection Approach Using UAV and YOLOv3. In Proceedings of the 2019 1st International Conference on Industrial Artificial Intelligence (IAI), Shenyang, China, 23–27 July 2019; pp. 1–5. [Google Scholar]
- Shamsoshoaraa, A.; Afghaha, F.; Razia, A.; Zhenga, L.; Fuléb, P.Z.; Blaschc, E. Aerial imagerypile burn detection using deeplearning: The FLAME dataset. Comput. Netw. 2021, 193, 108001. [Google Scholar] [CrossRef] [Scilit]
- Boylan, J.L.; Lawrence, C. The development and validation of the bushfire psychological preparedness scale. Int. J. Disaster Risk Reduct. 2020, 47, 101530. [Google Scholar] [CrossRef] [Scilit]
- Shakhnoza, M.; Sabina, U.; Sevara, M.; Cho, Y.-I. Novel Video Surveillance-Based Fire and Smoke Classification Using Attentional Feature Map in Capsule Networks. Sensors 2022, 22, 98. [Google Scholar] [CrossRef] [Scilit]
- Thuy, P.T.; Moeliono, M.; Hien, N.T.; Tho, N.H.; Hien, V.T. The Context of REDD+ in Vietnam: Drivers, Agents and Institutions; CIFOR Occasional Paper; CIFOR: Bogor, Indonesia, 2012. [Google Scholar]
- Stacey, R.; Gibson, S.; Hedley, P. European Glossary for Wildfires and Forest Fires; European Union-INTERREG IVC: Cham, Switzerland, 2012. [Google Scholar]
- Chuvieco, E.; Aguado, I.; Yebra, M.; Nieto, H.; Salas, J.; Martín, M.P.; Vilar, L.; Martínez, J.; Martín, S.; Ibarra, P.; et al. Development of a framework for fire risk assessment using remote sensing and geographic information system technologies. Ecol. Model. 2010, 221, 46–58. [Google Scholar] [CrossRef] [Scilit]
- Zheng, Z.; Huang, W.; Li, S.; Zeng, Y. Forest fire spread simulating model using cellular automaton with extreme learning machine. Ecol. Model. 2017, 348, 33–43. [Google Scholar] [CrossRef] [Scilit]
- Mahaveerakannan, R.; Anitha, C.; Thomas, A.K.; Rajan, S.; Muthukumar, T.; Rajulu, G.G. An IoT based forest fire detection system using integration of cat swarm with LSTM model. Comput. Commun. 2023, 211, 37–45. [Google Scholar] [CrossRef] [Scilit]
- Bo, M.; Mercalli, L.; Pognan, F.; Berro, D.C.; Clerico, M. Urban air pollution, climate change and wildfires: The case study of an extended forest fire episode in northern Italy favoured by drought and warm weather conditions. Energy Rep. 2020, 6, 781–786. [Google Scholar] [CrossRef] [Scilit]
- Vardoulakis, S.; Marks, G.; Abramson, M.J. Lessons learned from the Australian bushfires: Climate change, air pollution, and public health. JAMA Intern. 2020, 180, 635–636. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Rybansky, M. Determination of Forest Structure from Remote Sensing Data for Modeling the Navigation of Rescue Vehicles. Appl. Sci. 2022, 12, 3939. [Google Scholar] [CrossRef] [Scilit]
- Sakr, G.E.; Elhajj, I.H.; Huijer, H.A.-S. Support Vector Machines to Define and Detect Agitation Transition. IEEE Trans. Affect. Comput. 2010, 1, 98–108. [Google Scholar] [CrossRef] [Scilit]
- Rubí, J.N.S.; Carvalho, P.H.P.; Gondim, P.R.L. Application of machine learning models in the behavioral study of forest fires in the Brazilian Federal District region. Eng. Appl. Artif. Intell. 2023, 118, 105649. [Google Scholar] [CrossRef] [Scilit]
- Fernandesa, A.M.; Utkinb, A.B.; Lavrovb, A.V.; Vilara, R.M. Development of neural network committee machines for automatic forest re detection using lidar. Pattern Recognit. Soc. 2004, 37, 2039–2047. [Google Scholar] [CrossRef] [Scilit]
- Yuan, C.; Zhang, Y.; Liu, Z. A survey on technologies for automatic forest fire monitoring, detection, and fighting using unmanned aerial vehicles and remote sensing techniques. Can. J. For. Res. 2015, 45, 783–792. [Google Scholar] [CrossRef] [Scilit]
- Hurley, M.J.; Gottuk, D.; Hall, J.R.; Harada, K.; Kuligowski, E.; Puchovsky, M.; Torero, J.; Watts, J.M., Jr.; Wieczorek, C. SFPE Handbook of Fire Protection Engineering, 5th ed.; Springer: New York, NY, USA, 2016; Chapter 3; pp. 53–160. [Google Scholar]
- Li, C.; Wu, D.; Zhang, X.; Wu, P. GSF-YOLOv8: A Novel Approach for Fire Detection Using Gather-Distribute Mechanism and SimAM Attention. IEEE Access 2025, 13, 66051. [Google Scholar] [CrossRef] [Scilit]
- Li, M.; Zhang, Y.; Mu, L.; Xin, J.; Xue, X.; Jiao, S.; Liu, H.; Xie, G.; Yi, Y. A Real-Time Forest Fire Recognition Method Based on R-shufflenetv2. In Proceedings of the 2022 5th International Symposium on Autonomous Systems (ISAS), Hangzhou, China, 8–10 April 2022. [Google Scholar]
- Li, C.; Du, Y.; Zhang, X.; Wu, P. YOLOGX: An improved forest fire detection algorithm based on YOLOv8. Front. Environ. Sci. 2025, 12, 1486212. [Google Scholar] [CrossRef] [Scilit]
- Yang, G.; Wang, J.; Nie, Z.; Yang, H.; Yu, S. A Lightweight YOLOv8 Tomato Detection Algorithm Combining Feature Enhancement and Attention. Agronomy 2023, 13, 1824. [Google Scholar] [CrossRef] [Scilit]
- Zhou, J.; Li, Y.; Yin, P. A wildfire smoke detection based on improved YOLOv8. Int. J. Inf. Commun. Technol. 2024, 25, 6. [Google Scholar] [CrossRef] [Scilit]
- Mao, W.; Wang, W.; Dou, Z.; Li, Y. Fire Recognition Based on Multi-Channel Convolutional Neural Network. Fire Technol. 2018, 54, 531. [Google Scholar] [CrossRef] [Scilit]
- Shang, L.; Hu, X.; Huang, Z.; Zhang, Q.; Zhang, Z.; Li, X.; Chang, Y. YOLO-DKM: A Flame and Spark Detection Algorithm Based on Deep Learning. IEEE Access 2025, 13, 117687. [Google Scholar] [CrossRef] [Scilit]
- Wang, X.; Gao, H.; Jia, Z.; Li, Z. BL-YOLOv8: An Improved Road Defect Detection Model Based on YOLOv8. Sensors 2023, 23, 8361. [Google Scholar] [CrossRef] [Scilit]
- Zhang, T.; Wang, F.; Wang, W.; Zhao, Q.; Ning, W.; Wu, H. Research on Fire Smoke Detection Algorithm Based on Improved YOLOv8. IEEE Access 2024, 12, 117354. [Google Scholar] [CrossRef] [Scilit]
- Wang, G.; Chen, Y.; An, P.; Hong, H.; Hu, J.; Huang, T. UAV-YOLOv8: A Small-Object-Detection Model Based on Improved YOLOv8 for UAV Aerial Photography Scenarios. Sensors 2023, 23, 7190. [Google Scholar] [CrossRef] [Scilit]
- Xu, Y.; Li, J.; Zhang, L.; Liu, H.; Zhang, F. CNTCB-YOLOv7: An Effective Forest Fire Detection Model Based on ConvNeXtV2 and CBAM. Fire 2024, 7, 54. [Google Scholar] [CrossRef] [Scilit]
- Han, K.; Xiao, A.; Wu, E.; Guo, J.; Xu, C.; Wang, Y. Transformer in Transformer. arXiv 2021, arXiv:2103.00112. [Google Scholar]
- Peng, M.; Zhang, W.; Li, F.; Xue, Q.; Yuan, J.; An, P. Weed detection with Improved Yolov7. EAI Endorsed Trans. Internet Things 2023, 9, e1. [Google Scholar]
- Wu, S.; Xia, Y. Enhanced YOLOv7-Tiny for Small-Scale Fire Detection via Multi-Scale Channel Spatial Attention and Dynamic Upsampling. IEEE Access 2025, 13, 126901. [Google Scholar] [CrossRef] [Scilit]
- Ishtiaq, M.; Won, J. YOLO-SIFD: YOLO with Sliced Inference and Fractal Dimension Analysis for Improved Fire and Smoke Detection. Comput. Mater. Contin. 2025, 82, 3. [Google Scholar] [CrossRef] [Scilit]
- Ma, X.; He, Y.; Du, P.; Lv, W.; Yang, Y. Wildfire Detection from a Drone Perspective Based on Dynamic Frequency Domain Enhancement. Forests 2025, 16, 1613. [Google Scholar] [CrossRef] [Scilit]
- Yun, B.; Zheng, Y.; Lin, Z.; Li, T. FFYOLO: A Lightweight Forest Fire Detection Model Based on YOLOv8. Fire 2024, 7, 93. [Google Scholar] [CrossRef] [Scilit]
- Lei, L.; Duan, R.; Yang, F.; Xu, L. Low Complexity Forest Fire Detection Based on Improved YOLOv8 Network. Forests 2024, 15, 1652. [Google Scholar] [CrossRef] [Scilit]
- Varghese, R.; M, S. YOLOv8: A Novel Object Detection Algorithm with Enhanced Performance and Robustness. In Proceedings of the 2024 International Conference on Advances in Data Engineering and Intelligent Computing Systems (ADICS), Chennai, India, 17–18 April 2024; pp. 1–6. [Google Scholar]
- Yang, J.; Jiang, H.; Wang, S.; Ma, X. A Multi-Scale Deep Learning Algorithm for Enhanced Forest Fire Danger Prediction Using Remote Sensing Images. Forests 2024, 15, 1581. [Google Scholar] [CrossRef] [Scilit]
- Lei, Z.; Zhang, Y.; Wang, J.; Zhou, M. Cloud-Edge Collaborative Defect Detection Based on Efficient Yolo Networks and Incremental Learning. Sensors 2024, 24, 5921. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Qiu, Z.; Huang, Z.; Mo, D.; Tian, X.; Tian, X. GSE-YOLO: A Lightweight and High-Precision Model for Identifying the Ripeness of Pitaya (Dragon Fruit) Based on the YOLOv8n Improvement. Horticulturae 2024, 10, 852. [Google Scholar] [CrossRef] [Scilit]
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, J.; Gomez, A. Attention Is All You Need. arXiv 2017, arXiv:1706.03762. [Google Scholar]
- Frizzi, S.; Kaabi, R.; Bouchouicha, M.; Ginoux, J.-M.; Moreau, E.; Fnaiech, F. Convolutional neural network for video fire and smoke detection. In Proceedings of the IECON 2016—42nd Annual Conference of the IEEE Industrial Electronics Society, Florence, Italy, 23–26 October 2016; pp. 877–882. [Google Scholar]
- Zhang, L.; Wang, M.; Ding, Y.; Bu, X. MS-FRCNN: A Multi-Scale Faster RCNN Model for Small Target Forest Fire Detection. Forests 2023, 14, 616. [Google Scholar] [CrossRef] [Scilit]
- Hu, J.; Li, S.; Gang, S. Squeeze-and-Excitation Networks. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Salt Lake City, UT, USA, 18–22 June 2018; pp. 7132–7141. [Google Scholar]
- Han, Q.; Fan, Z.; Dai, Q.; Sun, L.; Cheng, M.; Liu, J.; Wang, J. On the connection between local attention and dynamic depth-wise convolution. arXiv 2022, arXiv:2106.04263. [Google Scholar] [CrossRef] [Scilit]
- Gao, J.; Chen, Y.; Wei, Y.; Li, J. Detection of Specific Building in Remote Sensing Images Using a Novel YOLO-S-CIOU Model. Case: Gas Station Identification. Sensors 2021, 21, 1375. [Google Scholar] [CrossRef] [Scilit]
- Wang, C.; Yeh, I.; Liao, H.M. YOLOv9: Learning What You Want to Learn Using Programmable Gradient Information. arXiv 2024, arXiv:2402.13616. [Google Scholar] [CrossRef] [Scilit]
- Wang, A.; Chen, H.; Liu, L.; Chen, K.; Lin, Z.; Han, J.; Ding, G. YOLOv10: Real-Time End-to-End Object Detection. arXiv 2024, arXiv:2405.14458. [Google Scholar]
- He, L.; Zhou, Y.; Liu, L.; Cao, W.; Ma, J. Research on object detection and recognition in remote sensing images based on YOLOv11. Sci. Rep. 2025, 15, 14032. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.