


Abstract
In this paper, we study a slotted-time system where a base station needs to update multiple users at the same time. Due to the limited resources, only part of the users can be updated in each time slot. We consider the problem of minimizing the Age of Incorrect Information (AoII) when imperfect Channel State Information (CSI) is available. Leveraging the notion of the Markov Decision Process (MDP), we obtain the structural properties of the optimal policy. By introducing a relaxed version of the original problem, we develop the Whittle’s index policy under a simple condition. However, indexability is required to ensure the existence of Whittle’s index. To avoid indexability, we develop Indexed priority policy based on the optimal policy for the relaxed problem. Finally, numerical results are laid out to showcase the application of the derived structural properties and highlight the performance of the developed scheduling policies.
1. Introduction
The Age of Incorrect Information (AoII) is introduced in [1] as a combination of age-based metrics (e.g., Age of Information (AoI)) and error-based metrics (e.g., Minimum Mean Square Error). In communication systems, AoII captures not only the information mismatch between the source and the destination but also the aging process of inconsistent information. Hence, two functions dominate AoII. The first is the time penalty function, which reflects how the inconsistency of information affects the system over time. In real-life applications, inconsistent information will affect different communication systems in different ways. For example, machine temperature monitoring is time-sensitive because the damage caused by overheating will accumulate quickly. However, reservoir water level monitoring is less sensitive to time. Therefore, by adopting different time penalty functions, AoII can capture different aging processes of the mismatch in different systems. The second is the information penalty function, which captures the information mismatch between the source and the destination. It allows us to measure mismatches in different ways, depending on how sensitive different systems are to information inconsistencies. For example, the navigation system requires precise information to give correct instructions, but the real-time delivery tracking system does not need very accurate location information. Since we can choose different penalty functions for different systems, AoII is adaptable to various communication goals, which is why it is regarded as a semantic metric [2].
Since the introduction of AoII, several studies have been performed to reveal its fundamental nature. The authors of [3] consider a system with random packet delivery times and compare AoII with AoI and real-time error via extensive numerical results. The authors of [4] study the problem of minimizing the AoII that takes the general time penalty function. Three real-life applications are considered to showcase the performance advantages of AoII over AoI and real-time error. In [5], the authors investigate the AoII that considers the quantified mismatch between the source and the destination. The optimization problem is studied when the system is resource-constrained. The authors of [6] studied the AoII minimization problem in the context of scheduling. It considers a system where the central scheduler needs to update multiple users at the same time. However, the central scheduler cannot know the states of the sources before receiving the updates. By introducing the belief value, Whittle’s index policy is developed and evaluated. In this paper, we also consider the problem of minimizing AoII in scheduling. Different from [6], we consider the generic time penalty function and study the minimization problem in the presence of imperfect Channel State Information (CSI). Due to the existence of CSI, Whittle’s index policy becomes infeasible in general. Hence, we introduce another scheduling policy that is more versatile and has comparable performance to Whittle’s index policy.
The problem of scheduling to minimize AoI is studied under various system settings in [7,8,9,10,11]. The problem studied in this paper is different and more complicated because AoII considers the aging process of inconsistent information rather than the aging process of updates. Meanwhile, none of them consider the case where CSI is available. The problem of optimizing information freshness in the presence of CSI is studied in [12,13]. However, they focus on the system with a single user and mainly discuss the case where CSI is perfect. The scheduling problems with the goal of minimizing an error-based performance measure are considered in [14,15,16]. Our problem is fundamentally different because AoII also considers the time effect. Moreover, we consider the system where a base station observes multiple sources simultaneously and needs to send updates to multiple destinations.
The main contributions of this work can be summarized as follows. (1) We study the problem of minimizing AoII in a multi-user system where imperfect CSI is available. Meanwhile, the time penalty function is generic. (2) We derive the structural properties of the optimal policy for the considered problem. (3) We establish the indexability of the considered problem under a simple condition and develop Whittle’s index policy. (4) We obtain the optimal policy for a relaxed version of the original problem. By exploring the characteristics of the relaxed problem, we provide an efficient algorithm to obtain the optimal policy. (5) Based on the optimal policy for the relaxed problem, we develop the Indexed priority policy that is free from indexability and has comparable performance to Whittle’s index policy.
The remainder of this paper is organized in the following way. In Section 2, we introduce the system model and formulate the primal problem. Section 3 explores the structural properties of the optimal policy for the primal problem. Under a simple condition, we develop Whittle’s index policy in Section 4. Section 5 presents the optimal policy for a relaxed version of the primal problem. On this basis, we develop the Indexed priority policy in Section 6. Finally, in Section 7, the numerical results are laid out.
2. System Overview
2.1. Communication Model
We consider a slotted-time system with N users and one base station. Each user is composed of a source process, a channel, and a receiver. We assume all the users share the same structure, but the parameters are different. The structure of the communication model is provided in Figure 1.
Figure 1.
The structure of the communication model.
For user i, the source process is modeled by a two-state Markov chain where transitions happen between the two states with probability and self-transitions happen with probability . At any time slot t, the state of the source process will be reported to the base station as an update, and the base station will decide whether to transmit this update through the corresponding channel. The channel is unreliable, but the estimate of the Channel State Information (CSI) is available at the beginning of each time slot. Let be the CSI at time t. We assume that is independent across time and user indices. if and only if the transmission attempt at time t will succeed and otherwise. Then, we denote by the estimate of . We assume that is an independent Bernoulli random variable with parameter , i.e., with probability and with probability . However, the estimate is imperfect. We assume that the error depends only on the user and its estimate. More precisely, we define the probability of error as . We assume because we can flip the estimate if . We are not interested in the case of since is useless in this case. Although the channel is unreliable, each transmission attempt takes exactly one time slot regardless of the result, and the successfully transmitted update will not be corrupted. Every time an update is received, the receiver will use it as the new estimate . The receiver will send an packet to inform the base station of its reception of the new update. Since an packet is generally very small and simple, we assume that it is transmitted reliably and received instantaneously. Then, if is received, the base station knows that the receiver’s estimate changed to the transmitted update. If is received, the base station knows that the receiver’s estimate did not change. Therefore, the base station always knows the estimate at the receiver side.
At the beginning of each time slot, the base station receives updates from each source and the estimates of CSI from each channel. The old updates and estimates are discarded upon the arrival of new ones. Then, the base station decides which updates to transmit, and the decision is independent of the transmission history. Due to the limited resources, at most updates are allowed per transmission attempt. We consider a base station that always transmits M updates.
2.2. Age of Incorrect Information
All the users adopt AoII as a performance metric, but the choices of penalty functions vary. Let and be the true state and the estimate of the source process, respectively. Then, in a slotted-time system, AoII can be expressed as follows
where is the last time instance before time t (including t) that the receiver’s estimate is correct. can be any information penalty function that captures the difference between and . where can be any time penalty function that is non-decreasing in t. We consider the case where the users adopt the same information penalty function but possibly different time penalty functions. To ease the analysis, we require to be unbounded. Combined together, we require if and . Without a loss of generality, we assume , as the source is modeled by a two-state Markov chain, . Hence, Equation (1) can be simplified to
where . Therefore, the evolution of is sufficient to characterize the evolution of AoII. To this end, we distinguish between the following cases.
- When the receiver’s estimate is correct at time , we have . Then, by definition, .
- When the receiver’s estimate is incorrect at time , we have . Then, by definition, .
To sum up, we get
A sample path of is shown in Figure 2. In the remainder of this paper, we use to denote the time penalty function user i adopts.
Figure 2.
A sample path of .
Remark 1.
Under this particular choice of the penalty function, can be interpreted as the time elapsed since the last time the receiver’s estimate is correct. Please note that is different from the Age of Information (AoI) [17], which is defined as the time elapsed since the generation time of the last received update. We can see that AoI considers the aging process of the update, while AoII considers the aging process of the estimation error. At the same time, is also fundamentally different from the holding time, which, according to [18,19], is defined as the time elapsed since the last successful transmission. We notice that the receiver’s estimate can become correct even when no new update is successfully transmitted. Moreover, the information carried by the update may have become incorrect by the time it is received. We also notice that [18,19] consider the problem of minimizing the estimation error. However, by adopting AoII as the performance metric, we study the impact of estimation error on the system.
2.3. System Dynamic
In this section, we tackle the system dynamic. We notice that the status of user i can be captured by the pair . In the following, we will use and interchangeably. Then, the system dynamic can be fully characterized by the dynamic of . Hence, it suffices to characterize the value of given and the base station’s action. To this end, we denote, by , the base station’s action at time t. if the base station transmits the update from user i at time t and otherwise. We notice that given action , users are independent and the action taken on user i will only affect itself. Consequently
Combined with the fact that all the users share the same structure, it is sufficient to study the dynamic of a single user. In the following discussions, we drop the user-dependent subscript i. We recall that is an independent Bernoulli random variable. Then, we have
By definition, and . Then, we only need to tackle the value of . To this end, we distinguish between the following cases
- When , the estimate at time t is correct (i.e., ). Hence, for the receiver, carries no new information about the source process. In other words, regardless of whether an update is transmitted at time t. We recall that if and otherwise. Since the source is binary, we obtain if , which happens with probability p and otherwise. According to (2), we obtain
- When and , where , the channel will not be used and no new update will be received by the receiver, and so, . We recall that if and otherwise. Since and the source is binary, we have if , which happens with probability and otherwise. According to (2), we obtain
- When and where , the transmission attempt will succeed with probability and fail with probability . We recall that if and otherwise. Then, when the transmission attempt succeeds (i.e., ), if and otherwise. When the transmission attempt fails (i.e., ), we have if and otherwise. Combining (2) with the dynamic of the source process we obtain
- When and , where , following the same line, we obtain
Combines together, we obtain the value of in all cases. As only M out of N updates are allowed per transmission attempt, we realize a necessity to require transmission attempts always help minimize AoII. It is equivalent to impose for any . Leveraging the results above, it is sufficient to require . As all the users share the same structure, we assume, for the rest of this paper, that for .
2.4. Problem Formulation
The communication goal is to minimize the expected AoII. Therefore, the problem can be formulated as the following
where is the set of all causal policies. We refer to the constrained minimization problem reported in problem (4) as the Primal Problem (PP). We notice that the PP is a Restless Multi-Armed Bandit (RMAB) Problem. The optimal policy for this type of problem is far from reachable since it is PSPACE-hard in general [20]. However, we can still derive the structural properties of the optimal policy. These structural properties can be used as a guide for the development of scheduling policies and can indicate the good performance of the developed scheduling policies.
3. Structural Properties of the Optimal Policy
In this section, we investigate the structural properties of the optimal policy for PP. We first define an infinite horizon with an average cost Markov Decision Process (MDP) , where
- denotes the state space. The state is where .
- denotes the action space. The feasible action is where and . Note that the feasible actions are independent of the state and the time.
- denotes the state transition probabilities. We define as the probability that action at state will lead to state . It is calculated bywhere is the transition probability from to when the estimate of CSI is and action is taken. The values of can be obtained easily from the results in Section 2.3.
- denotes the instant cost. When the system is at state and action is taken, the instant cost is .
We notice that PP can be cast into . Since , the instant cost is independent of action . Therefore, we abbreviate as . To simplify the analysis, we consider the case of . Equivalently, we investigate the structural properties of the optimal policy for .
Remark 2.
For the case of , we can apply the same methodology. However, as M increases, the action space will grow quickly, resulting in the need to consider more feasible actions in each step of the proof. Hence, to better demonstrate the methodology, we only consider the case of in this paper.
It is well known that the optimal policy for can be characterized by the value function. We denote the value function of state as . A canonical procedure to calculate is applying the Value Iteration Algorithm (VIA). To this end, we define as the estimated value function at iteration of VIA and initialize . Then, VIA updates the estimated value functions in the following way
where is the optimal value of . VIA is guaranteed to converge to the value function [21]. More precisely, when . However, the exact value function is impossible to get since we need infinite iterations and the state space is infinite. Instead, we provide two structural properties of the value function.
Lemma 1 (Monotonicity).
For , is non-decreasing in for .
Proof.
Leveraging the iterative nature of VIA, we use mathematical induction to prove the desired results. The complete proof can be found in Appendix A. ☐
Before introducing the next structural property, we make the following definition.
Definition 1 (Statistically identical).
Two users are said to be statistically identical if the user-dependent parameters and the adopted time penalty functions are the same.
For the users that are statistically identical, we can prove the following
Lemma 2 (Equivalence).
For , if users j and k are statistically identical, where is state with and exchanged.
Proof.
Leveraging the iterative nature of VIA, we use mathematical induction to prove the desired results. At each iteration, we show that for each feasible action at state , we can find an equivalent action at state . Two actions are equivalent if they lead to the same value function. The complete proof can be found in Appendix B. ☐
Equipped with the above lemmas, we proceed with characterizing the structural properties of the optimal policy. We recall that the optimal action at each state can be characterized by the value function. Hence, we denote, by , the value function resulting from choosing user j to update at state . Then, can be calculated by
If for all , it is optimal to transmit the update from user j. When , the two choices are equally desirable. In the following, we will characterize the properties of for any j and k.
Theorem 1 (Structural properties).
For , has the following properties
- if . The equality holds when or .
- is non-increasing in and is non-decreasing in when . At the same time, is independent of for any .
- if . The equality holds when or .
- is non-increasing in if and is non-decreasing in if when . We define and for .
- if , , and users j and k are statistically identical.
Proof.
The proof can be found in Appendix C. ☐
We notice that can be written as
where can be any positive integer. Consequently, is independent of any and indicates the decrease in the probability of increasing caused by action . When is large, action will achieve a small decrease in the probability of increasing . In the following, we provide an intuitive interpretation of why the monotonicity in Property 4 of Theorem 1 depends on . We take the case of as an example and assume that there are only users j and k in the system. Then, according to Section 2.3, the dynamic of and can be divided into the following three cases
- Neither nor increases. In this case, both and become zero.
- Either or increases and the other becomes zero. We denote by the probability that only increases when . The notation for other cases is defined analogously. The probabilities can be obtained easily using the results in Section 2.3.
- Both and increase. We denote by the probability that both and increase when . is defined analogously. The probabilities can be obtained easily using the results in Section 2.3.
We notice that implies the tendency of the base station to choose between the two users. The larger is, the more the base station tends to choose user k. Thus, we investigate the base station’s propensity to choose user k when increases but stays the same. We ignore the case where the resulting is zero since it is independent of the increase in . With this in mind, we first notice that . Meanwhile, we can easily verify that . When , we have . Then, there exists a subtle trade-off. More precisely, choosing user k will result in , but at the cost of . Hence, in this case, the propensity of the base station is hard to determine. Following the same line, we can show that choosing user j will lead to and . Thus, there exists no such trade-off when we investigate the base station’s propensity to choose user j as increases but stays the same.
Leveraging Theorem 1, we can provide some specific structural properties of the optimal policy.
Corollary 1 (Application of Theorem 1).
When , the optimal policy for PP must satisfy the following
- The user i with or will not be chosen unless it is to break the tie.
- When user j is chosen at state , then for state , such that and for , the optimal choice must be in the set .
- When , we consider two states, and , which differ only in the value of . Specifically, . If user j is chosen at state and , the optimal choice at state will also be user j.
- When , we consider two states, and , which differ only in the value of . Specifically, . If user j is chosen at state and , the optimal choice at state will also be user j.
- When all users are statistically identical, the optimal choice at any time slot must be either the user with where or the user with where . Moreover,
- If , it is optimal to choose the user with .
- If , the optimal choice will switch from the user with to the user with when increases from 0 to solely.
Proof.
The first property follows directly from Property 1 and Property 3 of Theorem 1. For the second property, leveraging Property 2 of Theorem 1, we have if , , and for . Thus, the optimal choice will not be user k in this case. Then, we can conclude that the optimal choice must be in the set .
For the third property, we have proved in Property 4 of Theorem 1 that is non-increasing in if . Hence, . As we consider the case of , the optimal choice at state will also be user j. The fourth property can be shown in a similar way by noticing that is non-decreasing in when .
For the last property, we recall from Property 5 of Theorem 1 that it is always better to choose the user with a larger s if they are statistically identical and have the same . Thus, we can conclude that the optimal choice must be either the user with or the user with . Without a loss of generality, we assume and . Now, we distinguish between the following cases
- According to Property 5 of Theorem 1, we can conclude that it is optimal to choose user j when .
- To determine the optimal choice in the case of , we recall that the optimal choice will be user k (i.e., ) if and will be user j (i.e., ) if . At the same time, Property 4 of Theorem 1 tells us that is non-increasing in when users j and k are statistically identical. Therefore, we can conclude that the optimal choice will switch from user k to user j when increases from 0 to solely.
☐
4. Whittle’s Index Policy
Whittle’s index policy is a well-known low-complexity heuristic that shows a strong performance in many problems that belong to RMAB [22,23,24]. In this section, we develop Whittle’s index policy for PP. We first present the general procedures we adopt to obtain Whittle’s index.
- We first formulate a relaxed version of PP and apply the Lagrangian approach.
- Then, we decouple the problem of minimizing the Lagrangian function into N decoupled problems, each of which only considers a single user. By casting the decoupled problem into an MDP, we investigate the structural properties and performance of the optimal policy.
- Leveraging the results above and under a simple condition, we establish the indexability of the decoupled problem.
- Finally, we obtain the expression of Whittle’s index by solving the Bellman equation.
4.1. Relaxed Problem
The first step in obtaining Whittle’s index is to formulate the Relaxed Problem (RP). More precisely, instead of requiring the limit on the number of updates allowed per transmission attempt to be met in each time slot, we relax the constraint such that the limit is not violated in an average sense. Then, RP can be formulated as
As RP is specified, we apply the Lagrangian approach. First of all, we write RP into its Lagrangian form.
where is the Lagrange multiplier. Then, we investigate the problem of minimizing the Lagrangian function. Since is independent of policies, we can ignore it. More precisely, we consider the following minimization problem
4.2. Decoupled Model
In this section, we formulate the decoupled problem and investigate its optimal policy. The decoupled model associated with each user follows the system model with . Since all the users share the same structure, we drop the user-dependent subscript i for simplicity. Then, the decoupled problem can be formulated as
where
is the set of all causal policies when . We notice that problem (8) can be cast into the MDP . We define when there is no restriction on the number of updates allowed per transmission attempt.
We first investigate the structural properties of the optimal policy for when is a given non-negative constant. We start with characterizing the corresponding value function .
Corollary 2 (Extension of Lemma 1).
For , is non-decreasing in s.
Proof.
The proof follows the same steps as in the proof of Lemma 1. The complete proof can be found in Appendix D. ☐
Equipped with the above corollary, we can characterize the structural properties of the optimal policy for (8).
Proposition 1 (Optimal policy for decoupled problem).
The optimal policy for the decoupled problem is a threshold policy with the following properties.
- The optimal policy can be fully captured by . More precisely, when the system is at state , it is optimal to make a transmission attempt only when .
- .
Proof.
We define , where is the value function resulting from taking action a at state x. Then, the optimal action at state x is if , and is optimal otherwise. We use Corollary 2 to characterize the sign of . The complete proof can be found in Appendix E. ☐
In the following, we evaluate the performance of the threshold policy detailed in Proposition 1. More precisely, we calculate the expected AoII and the expected transmission rate resulting from the adoption of threshold policy . We will see in the following that and are essential for establishing the indexability and obtaining the expression of Whittle’s index.
Proposition 2 (Performance).
Under threshold policy ,
where
, and .
Proof.
We notice that the dynamic of AoII under the threshold policy can be fully captured by a Discrete-Time Markov Chain (DTMC). Then, combined with the fact that is an independent Bernoulli random variable, we can obtain the desired results from the stationary distribution of the induced DTMC. The complete proof can be found in Appendix F. ☐
As can be any non-decreasing function, can grow indefinitely. Thus, it is necessary to require that there exists at least one threshold policy that causes a finite . By noting that , we have
The equality is achieved when . Then, we can conclude that it is sufficient to require . This will be the underlying assumption throughout the rest of this paper.
4.3. Indexability
In this section, we establish the indexability of the decoupled problem, which ensures the existence of Whittle’s index. We start with the definition of indexability.
Definition 2
(Indexability). The decoupled problem is indexable if the set of states in which is the optimal action increases with λ, that is,
where is the set of states in which is optimal when Lagrange multiplier λ is adopted.
The Lagrange multiplier can be viewed as a cost associated with each transmission attempt. Intuitively, as increases, the base station should stay idle (i.e., ) for a longer time until s becomes large enough to offset the cost. Although it is intuitively correct that the decoupled problem is indexable, the indexability is hard to establish as the optimal policy is characterized by two thresholds. Thus, Whittle’s index does not necessarily exist. However, the indexability can be established when the following condition is satisfied
Remark 3.
Problem (9) only requires the estimate to be perfect when . In the case of , we still allow the estimate to be inaccurate.
When (9) is satisfied, Propositions 1 and 2 reduce to the following
Corollary 3 (Consequences of (9)).
When (9) is satisfied, the optimal policy for the decoupled problem (8) is the threshold policy . The corresponding and are
where
Proof.
We continue with the same notations as in the proof of Propositions 1 and 2. It is sufficient to show that . To this end, we consider the state . By following the same steps as in the proof of Proposition 1, we have
Therefore, it is optimal to stay idle (i.e., ) at state for any . Equivalently, . Then, the corresponding and can be calculated as a special case of Proposition 2 where , , and . ☐
Leveraging Corollary 3, we can establish the indexability of the decoupled problem.
Proposition 3 (Indexability of decoupled problem).
The decoupled problem is indexable when (9) is satisfied.
Proof.
According to Proposition 2.2 of [25], we only need to verify that the expected transmission rate is strictly decreasing in n. From Corollary 3, we have
As , we can easily verify that is strictly decreasing in n. Thus, the decoupled problem is indexable when (9) is satisfied. ☐
4.4. Whittle’s Index Policy
In this section, we proceed with finding the expression of Whittle’s index and defining Whittle’s index policy. First of all, we give the definition of Whittle’s index.
Definition 3 (Whittle’s index).
When the decoupled problem is indexable, Whittle’s index at state x is defined as the infimum λ, such that both actions are equally desirable. Equivalently, Whittle’s index at state x is defined as the infimum λ such that .
Let us denote by the Whittle’s index at state x. Then, the expression of Whittle’s index is given by the following Proposition.
Proposition 4 (Whittle’s index).
When (9) is satisfied, Whittle’s index is
where and . and are the expected AoII and the expected transmission rate when threshold policy is adopted, respectively. At the same time, is non-negative and is non-decreasing in s.
Proof.
Whittle’s indexes at state and are obtained easily from the proof of Proposition 1. For state , we first use backward induction to calculate the expressions of some value functions. Then, the expression of Whittle’s index can be obtained from its definition. The complete proof can be found in Appendix G. ☐
Definition 4
(Whittle’s index policy). At any state , the base station will transmit the updates from M users with the largest . The ties are broken arbitrarily. is calculated using Proposition 4 with the parameters of user i.
Remark 4.
Whittle’s index policy possesses the structural properties detailed in Corollary 1.
- The first two properties can be verified by noting that and the equality holds when or . At the same time, is non-decreasing in .
- The third and fourth properties can be verified by noting that is non-decreasing in .
- For the last property, we first notice that when users j and k are statistically identical and . Then, the property can be verified by noting that is non-decreasing in both and .
5. Optimal Policy for Relaxed Problem
In this section, we provide an efficient algorithm to obtain the optimal policy for RP, based on which we will develop another scheduling policy for PP in the next section that is free from indexability. At the same time, the performance of the optimal policy for RP forms a universal lower bound because the following ordering holds
where and are the minimal expected AoII of RP and PP, respectively.
Remark 5.
Note that the optimal policy for RP may not necessarily be a valid policy for PP, as the transmitter may transmit more than M updates in one transmission attempt under RP-optimal policy.
To solve RP, we follow the discussion in Section 4.1. More precisely, we take the Lagrangian approach and consider the problem reported in (7). We will see in the following discussion that the optimal policy for RP can be characterized by the optimal policies for problem (7). Therefore, we first cast problem (7) into the MDP . However, the optimal policy for is difficult to obtain because the state space is infinite. Even though we can make the state space finite by imposing an upper limit on the value of s, the state space and the action space grow exponentially with the number of users in the system. To overcome the difficulty, we investigate the optimal policy for where . The superscript i means that the only user in the system is user i. We will show later that the optimal policy for can be fully characterized by the optimal policies for where .
5.1. Optimal Policy for Single User
In this section, we tackle the problem of finding the optimal policy for . Since the users share the same structure, we ignore the superscript i for simplicity. To find the optimal policy, we first use the Approximating Sequence Method (ASM) introduced in [26] to make the state space finite. More precisely, we impose where m is a predetermined upper limit. The state transition probabilities are modified in the following way
The action space and the instant cost remain unchanged. Then, we can apply Relative Value Iteration (RVI) with convergence criteria to obtain the optimal policy. We notice that coincides with the decoupled model studied in Section 4.2. Hence, we can utilize the threshold structure of the optimal policy to improve RVI. To this end, we class a state as active if the optimal action at this state is . Then, the threshold structure detailed in Proposition 1 tells us the following. For any state x, if there exists an active state with and , then x must also be active. Hence, we can determine the optimal action at state x immediately instead of comparing all feasible actions. In this way, we can reduce the running time of RVI. The pseudocode for the improved RVI can be found in Algorithm A1 of Appendix M. A similar technique is also presented in [5].
For , when problem (9) is satisfied, Whittle’s index exists and can be calculated efficiently using Proposition 4. Therefore, we can obtain the optimal policy using Whittle’s index and further reduce the computational complexity. To this end, we denote by the optimal policy for and present the following proposition
Proposition 5 (Optimal deterministic policy).
When (9) is satisfied, the optimal policy for is where n is given by
is the Whittle’s index at state .
Proof.
We first notice that coincides with the decoupled model studied in Section 4.2. Then, we show the optimal action for each state with using the definition of Whittle’s index and the fact that the decoupled problem is indexable when (9) is satisfied. The complete proof can be found in Appendix H. ☐
In the following, we provide a randomized policy that is also optimal for . We will see later that the randomized policy is the key to obtaining the optimal policy for RP.
Theorem 2 (Optimal randomized policy).
There exist two deterministic policies and , which are both optimal for . We consider the following randomized policy : every time the system reaches state , the base station will make the choice between with probability μ and with probability . The chosen policy will be followed until the next choice. Then, the randomized policy is optimal for under any .
Proof.
We show that our system verifies the assumptions given in [27]. Then, leveraging the characteristics of our system, we can obtain the optimal randomized policy. The complete proof can be found in Appendix I. ☐
In practice, we approximate and where is a small perturbation. Then, the deterministic policies and can be obtained by following the discussion at the beginning of this subsection. Note that, in most cases, and are the same.
5.2. Optimal Policy for RP
In this section, we characterize the optimal policy for RP. Let us denote by and the value functions of and , respectively. Then, we can prove the following
Proposition 6 (Separability).
where . In other words, the policy, under which each user adopts its own optimal policy, is optimal for .
Proof.
We show by comparing the Bellman equations they must satisfy. The complete proof can be found in Appendix J. ☐
We denote the optimal policy for as where is the optimal policy for . For simplicity, we define and as the expected AoII and the expected transmission rate associated with , respectively. and are defined analogously for user i under policy . We also define . With Proposition 6 and the above definitions in mind, we proceed with constructing the optimal policy for RP.
Theorem 3 (Optimal policy for RP).
The optimal policy for RP can be characterized by two deterministic policies and where and are both the optimal deterministic policies for . Then, we mix and in the following way: for each user i, every time the user reaches state , the base station will make the choice between with probability and with probability . The chosen policy will be followed by user i until the next choice. Where , the is chosen in such a way as to satisfy
Then, the mixed policy, denoted by , is optimal for RP.
Proof.
According to Lemma 3.10 of [27], a policy is optimal for RP if
- It is optimal for ;
- The resulting expected transmission rate is equal to M.
Then, we construct such a policy using Theorem 2 and Proposition 6. The complete proof can be found in Appendix K. ☐
Since we approximate and in practice, for all i according to the monotonicity given by Lemma 3.4 of [27]. Combining with the definition of , we must have . Therefore, we can always find ’s that realize (11). In this paper, we choose
Then, we describe the algorithm used to obtain the optimal policy for RP. As detailed in Theorem 3, it is essential to find . To this end, we recall that, for any user i under given , the optimal deterministic policy can be obtained using the results in Section 5.1 and the resulting expected transmission rate is given by Proposition 2. Since is non-increasing in for all i according to Lemma 3.4 of [27], is also non-increasing in . Hence, we can regard as a non-increasing function of . Then, according to the definition of , we can use the Bisection search to obtain efficiently. The main steps can be summarized as follows.
- Initialize and .
- Do and until .
- Run Bisection search on the interval until the tolerance is met.
Then, and can simply be the boundaries of the final interval. The pseudocode for the Bisection search can be found in Algorithm A2 of Appendix M. After obtaining and , the optimal policy is detailed in Theorem 3 and the mixing probabilities ’s are given by (12).
Remark 6.
We recall that the optimal deterministic policy for each user can be characterized by two positive thresholds (i.e., ). Consequently, under RP-optimal policy, the base station will never choose the user at state . Then, when M increases, the expected transmission rate achieved by RP-optimal policy will saturate before M reaches N. When the expected transmission rate saturates, the RP-optimal policy is where for . The saturation happens when M is larger than or equal to the expected transmission rate achieved by .
6. Indexed Priority Policy
Although the performance of Whittle’s index policy is known to be good, it requires indexability, which is usually difficult to establish. In this section, based on the primal-dual heuristic introduced in [28], we develop a policy that does not require indexability and has comparable performance to Whittle’s index policy. We start with presenting the primal-dual heuristic.
6.1. Primal-Dual Heuristic
The heuristic is based on the optimal primal and dual solution pair to the linear program associated with RP. To introduce the linear program, we define as the expected time that user i is at state and action is taken according to policy . Then, for any , must satisfy the following problems
The objective function of RP can be rewritten as
where is the instant cost at state . The constraint on the expected transmission rate can be rewritten as
Thus, the linear program associated with RP can be formulated as the following
The corresponding dual problem is
Let and be the optimal primal and dual solution pair to the problems reported in (13) and (14). We define
For any state , let . Then, the heuristic operates in the following way
- If , the base station will choose the M users with the largest among the users.
- If , these users are chosen by the base station. The base station will choose additional users with the smallest .
However, Linear Programming (LP) is a very general technique and does not appear to take advantage of the special structure of the problem. Although there are algorithms for solving rational LP that take time polynomial in the number of variables and constraints, they run extremely slowly in practice [29]. For our problem, we notice that the users have separate activity areas that are linked through a common resource constraint. Therefore, the primal problem can be solved using Dantzig-Wolfe decomposition. Even so, the problem is still computationally demanding when the system scales up. We recall that we solved the exact problem efficiently using MDP-specific algorithms in Section 5. It is more efficient because of the following reasons
- According to Proposition 6, we can decompose the problem into N subproblems.
- For each subproblem, the threshold structure of the optimal policy is utilized to reduce the running time of RVI.
- As we will see later, the developed policy can be obtained directly from the result of RVI in practice.
In the following, we will translate the results in Section 5 into the optimal primal and dual solution pair and propose Indexed priority policy.
6.2. Indexed Priority Policy
We first define the Lagrangian function associated with (13).
Then, the corresponding Lagrangian dual function is
Let be the expected time that user i is at state caused by the adoption of , where is the optimal policy detailed in Theorem 3. Then, we define as follows
- State is where randomization happens (randomization happens when the actions suggested by the two optimal deterministic policies are different), and it has a value of and where is given by (12) and is the action suggested by at state .
- For other values of , we have and .
We also define , , and where is specified in Section 5.2, is the optimal value of , and is the value function associated with . Lastly, we define as follows
Then, we can prove the following proposition.
Proposition 7 (Optimal solution pair).
and are primal and dual solutions to (13), respectively.
Proof.
Since (13) is linear and strictly feasible, it is sufficient to show that and verify the KKT conditions, which can be expressed as the following four conditions.
- Primal feasibility: the constraints in (13) are satisfied.
- Dual feasibility: and for all , , and i.
- Complementary slackness: and for all , , and i.
- Stationarity: the gradient of with respect to vanishes.
Apparently, the first condition is satisfied by . For the second condition, since by definition. For , we can verify that where is the value function resulting from taking action at state . Then, the non-negativity is guaranteed by the Bellman equation. For the third condition, the first term is zero because we choose the ’s given by (12). For the second term, we recall that . According to the definition of , we know if . Combined together, we can conclude that when . Thus, the third condition is satisfied. For the last condition, setting the gradient equal to zero yields a system of linear equations. More precisely, for each and
Then, verifies the system of linear equations by definition. Since all four conditions are satisfied, we can conclude our proof. ☐
According to Proposition 7, we know that and defined above are the optimal solutions to problems (13) and (14), respectively. As the optimal solutions are obtained, we can adopt the heuristic detailed in Section 6.1.
The heuristic can be expressed equivalently as an index policy. To this end, we define the index for state as
According to the complementary slackness, can be reduced to the following.
- For state such that and , we have . Therefore, .
- For state such that and , we have . Therefore, .
- For state such that and , we have . Therefore, .
We can show that possesses the following properties.
Proposition 8 (Properties of ).
For , for any . The equality holds when or . At the same time, is non-decreasing in both and .
Proof.
We notice that can be expressed as a function of and . Meanwhile, coincides with the decoupled model studied in Section 4.2. Then, we can verify the properties of using the results in Section 4.2. The complete proof can be found in Appendix L. ☐
Comparing with the heuristic detailed in Section 6.1, we can define the Indexed priority policy.
Definition 5 (Indexed priority policy).
At any state , the base station will transmit the updates from M users with the largest . The ties are broken arbitrarily.
Remark 7.
Indexed priority policy belongs to the class of priority policies introduced in [30]. These priority policies are asymptotically optimal when certain conditions are satisfied.
Remark 8.
Indexed priority policy possesses the structural properties detailed in Corollary 1.
- The first two properties can be verified by noting that and the equality holds when or . At the same time, is non-decreasing in .
- The third and fourth properties can be verified by noting that is non-decreasing in .
- For the last property, we first notice that when users j and k are statistically identical and . Then, the property can be verified by noting that is non-decreasing in both and .
We notice that ’s and ’s are canceled out by the definition of . Therefore, can be calculated using and the value function of . In practice, we can use either or to approximate , and the value function can be approximated by the result of the RVI detailed in Section 5.1. Since the state space is infinite, we only calculate a finite number of , the number of which depends on the truncation parameter m of ASM. Meanwhile, the probabilities in are modified according to (10).
7. Numerical Results
In this section, we provide numerical results to showcase the performance of the developed scheduling policies. To eliminate the effect of N, we plot the expected average AoII. In particular, we provide the expected average AoII achieved by the Indexed priority policy and Whittle’s index policy when . The policies are calculated using the results detailed in Section 4, Section 5 and Section 6. When obtaining the Indexed priority policy, we set the tolerance in the Bisection search to . Meanwhile, we choose the truncation parameter in ASM and the convergence criteria in RVI . We notice that the calculation of Whittle’s index involves an infinite sum. In practice, we approximate the result by replacing with a large enough number . Here, we choose . For both scheduling policies, the resulting expected average AoII is obtained via simulations. Each data point is the average of 15 runs with 15,000 time slots considered in each run.
We also compare the developed policies with the optimal policy for RP, which can be calculated by following the discussion in Section 5.2. We adopt the same choices of parameters as we used to obtain the developed policies. The corresponding performance is calculated using Proposition 2. Like before, the infinite sum is approximated by replacing with . We also provide the expected average AoII achieved by the Greedy policy to show the performance advantages of the developed policies. When the Greedy policy is adopted, the base station always chooses the user with the largest AoII. The resulting expected average AoII is obtained via the same simulations as applied to the developed policies.
Figure 3 and Figure 4 illustrate the performance when the source processes have different dynamics and when each user’s communication goal is different, respectively. Figure 3a provides the performance when for . For other parameters, the users make the same choices. More precisely, , , and for . Figure 4a provides the performance when for . Same as before, the users make the same choices for other parameters. More precisely, , , and for . In Figure 3b and Figure 4b, we force for all users to ensure the existence of Whittle’s index. Other choices remain the same as in Figure 3a and Figure 4a. According to Corollary 1, the optimal policy will never choose the user with unless it is to break the tie. Therefore, in Figure 3b and Figure 4b, we also consider the Greedy+ policy where the base station always chooses the user with the largest AoII among the users with . The resulting expected average AoII is obtained via the same simulations as applied to the Greedy policy.
Figure 3.
Performance when the source processes vary. We choose , , , , and for .
Figure 4.
Performance when the communication goals vary. We choose , , , , and for .
Figure 5 shows the performance in systems where the parameters for each user are generated uniformly and randomly within their ranges. In Figure 5a, we consider , , , , and , where . There are a total of 300 different choices and the results are sorted by the performance of RP-optimal policy in ascending order. Figure 5b adopts the same system settings except that we impose for to ensure the feasibility of Whittle’s index policy. Meanwhile, we ignore the Greedy policy since the Greedy+ policy achieves a better performance, as indicated by Figure 3b and Figure 4b.
Figure 5.
Performance in systems with random parameters when . The parameters for each user are chosen randomly within the following intervals: , , , , and where .
We can make the following observations from the figures.
- The Greedy+ policy yields a smaller expected average AoII than that achieved by the Greedy policy. Recall that we obtained the Greedy+ policy by applying the structural properties detailed in Corollary 1. Therefore, simple applications of the structural properties of the optimal policy can improve the performance of scheduling policies.
- The Indexed priority policy has comparable performance to Whittle’s index policy in all the system settings considered. The two policies have their own advantages. The Indexed priority policy has a broader scope of application, while Whittle’s index policy has a lower computational complexity.
- The performance of the Indexed priority policy and Whittle’s index policy is better than that of the Greedy/Greedy+ policies and is not far from the performance of the RP-optimal policy. Recall that the performance of the RP-optimal policy forms a universal lower bound on the performance of all admissible policies for PP. Hence, we can conclude that both the Indexed priority policy and Whittle’s index policy achieve good performances.
8. Conclusions
In this paper, we studied the problem of minimizing the Age of Incorrect Information in a slotted-time system where a base station needs to schedule M users among N available users. Meanwhile, the base station has access to imperfect channel state information in each time slot. The problem is a restless multi-armed bandit problem which is SPACE-hard. However, by casting the problem into a Markov decision process, we obtain the structural properties of the optimal policy. Then, we introduce a relaxed version of the original problem and investigate the decoupled model. Under a simple condition, we establish the indexability of the decoupled problem and obtain the expression of Whittle’s index. On this basis, we developed Whittle’s index policy. To get rid of the requirement for indexability, we developed the Indexed priority policy based on the optimal policy for the relaxed problem. The characteristics of the relaxed problem are explored to make the calculation of its optimal policy more efficient. Finally, through numerical results, we show that simple applications of the structural properties can improve the performance of scheduling policies. Moreover, Whittle’s index policy and the Indexed priority policy achieve good and comparable performances.
Author Contributions
Formal analysis, Y.C.; Investigation, Y.C.; Methodology, Y.C.; Supervision, A.E.; Validation, Y.C.; Writing—original draft, Y.C.; Writing—review & editing, Y.C. and A.E. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
Not applicable.
Conflicts of Interest
The authors declare no conflict of interest.
Appendix A. Proof of Lemma 1
We consider two states, and , that differ only in the value of . Without the loss of generality, we assume . Then, it is sufficient to show that, for any , . Leveraging the iterative nature of VIA, we use mathematical induction to prove the monotonicity. First of all, the base case (i.e., ) is true by initialization. We assume the lemma holds at iteration . Then, we want to examine whether it holds at iteration . The update step reported in problem (5) can be rewritten as follows.
where
To prove the desired results, we distinguish between the following cases.
- We first consider the case of and . When and for any , we havewhere is the estimated value function of the state with at iteration (at the risk of abusing the notation, we use and to represent the value functions of two states that differ only in the value of ). Then, we getThe inequalities hold since and Lemma 1 are true at iteration by assumption. Therefore, we have when for any .For the case of where , we notice that . Then, for any , we obtainTherefore, when , we haveThe inequalities hold since and Lemma 1 is true at iteration by assumption. Combining with the case of , holds for any under any feasible action. Since and differ only in the value of and is non-decreasing in for , we can see that for any feasible . Then, by (A1), we can conclude that the lemma holds at iteration when and .
- When and , by replacing the ’s in the above case with ’s, we can achieve the same result.
- When and , we notice thatThen, leveraging the monotonicity of and , we can conclude with the same result.
Combining the three cases, we prove that the lemma also holds at iteration of VIA. Therefore, the lemma holds at any iteration by mathematical induction. Since the results hold for any and VIA is guaranteed to converge to the value function when , we can conclude our proof.
Appendix B. Proof of Lemma 2
We inherit the notations in the proof of Lemma 1. We still use mathematical induction to obtain the desired results. The base case is true by initialization. We assume the lemma holds at iterative and examine whether it still holds at iteration . In the case of , we rewrite (5) as
where
and is the probability that action will lead to state when user i is at state x. To get the desired results, we distinguish between the following cases
- It is obvious that for any , there always exists . Then, we obtainThe second equality follows from the definition of , the property of summation, and the assumption at iteration . The last equality follows from the variable renaming. Then, by the definition of statistically identical, we have , , and . Therefore, we can conclude that .
- Along the same lines, we can easily show that and for .
Combining the above cases with (A2), we prove that . Then, by induction, we have at any iteration . Since VIA is guaranteed to converge to the value function when , we can conclude our proof.
Appendix C. Proof of Theorem 1
For arbitrary j and k
where
With this in mind, we will prove the properties one by one.
Property 1—δj,k (x) ≤ 0 if . The equality holds when
or .
When , transmitting the update from user k will necessarily fail. Therefore, for any and . Then, we have
To identify the sign of , we distinguish between the following cases
- When , we can easily show that for any by noticing that the two possible actions with respect to user j (i.e., and ) are equivalent when . Since is a linear combination of ’s with non-negative coefficients, we can conclude that in this case.
- When and , for any , we haveThe inequality holds because of Lemma 1 and the fact that . We recall that is a linear combination of ’s with non-negative coefficients. Then, we can conclude that in this case.
- When and , by replacing the in (A6) with , we can get the same result. In this case, the equality holds when , or, equivalently, .
Combining the cases, we prove the first property.
Property 2—δj,k (x) is non-increasing in
and is non-decreasing in when
. At the same time, is independent of for any i ≠ j,k.
We first prove the monotonicity of with respect to . To this end, we define and as two states that differ only in the value of . Without a loss of generality, we assume and . Then, we investigate the sign of . We define for . Then, according to (A4), can be written as
Since , we have for any . We recall that the transition probability is independent of when . Combining with the fact that , we also have for any . Combining together, we obtain
Leveraging the above two problems, we have
Consequently, we obtain
In the following, we characterize the sign of
As , for any , we have
The inequality follows from Lemma 1 and the fact that . Since is a linear combination of ’s with non-negative coefficients, we can conclude that . Since , we can see that is non-increasing in .
In a very similar way, we can show that is non-decreasing in . We recall that will not affect the system dynamic if . Consequently, we can conclude that is independent of for any .
Combining together, we prove the second property.
Property 3— if . The equality holds when
or .
Since the probabilities are non-negative, it is sufficient to show that satisfies Property 3 for any . More precisely, it is sufficient to show that for any when and the equality holds when or . We recall that for any when . Hence, for any , we have
Then, we investigate the following quantity for any
To this end, we distinguish between the following cases
- When , we have for any . Thus, we conclude that for any . Consequently, for any .
- When and , for any , we haveThe inequality follows from Lemma 1 and the fact that . Thus, for any .
- When and , by replacing the in (A7) with , we can get the same result. In this case, the equality holds when , or, equivalently, .
Combined together, we can conclude that Property 3 is true.
Property 4— is non-increasing in if
and is non-decreasing in if when . We define and for .
Such as we did in the proof of Property 3, it is sufficient to show that satisfies Property 4 for any . We recall that depends on the values of and . Therefore, we distinguish between the following cases
- In the case of and , for any , (A5) can be written asAs we can verifyWe define and for . Then, we haveCombining with Lemma 1, we can conclude that, for any , is non-increasing in if and is non-decreasing in if .
- In the case of and , by replacing the ’s in the above case with ’s, we can conclude with the same result.
- In the case of , , and , for any , (A5) can be written asAs we can verifyAt the same timeCombined with Lemma 1, we can conclude that, for any , is non-increasing in if and is non-decreasing in if .
- In the case of , , and , by swapping the ’s and ’s in the above case, we can conclude with the same result.
Combined together, we conclude that satisfies Property 3 for any . Consequently, is non-increasing in if and is non-decreasing in if when .
Property 5—
if
and users j and k are statistically identical.
According to Property 3, it is sufficient to consider the case where . We notice that the sign of can be captured by the sign of the quantity . Thus, we divide our discussion into the following cases.
- We first consider the case of and . Leveraging the definition of statistically identical, for any , we havewhere . Then, by substituting the values of and using Lemma 2, we obtainSince users j and k are statistically identical, we have . Then, by Lemma 1, we have for any . Since is a linear combination of ’s with non-negative coefficients, we can conclude that .
- For the case of and , by replacing in with , we can conclude with the same result.
- Then, we consider the case of , , and . We first notice that, for anyAs users j and k are statistically identical, we have and . Leveraging Lemma 1, we haveThen, for anywhere . Such as we did in the previous cases, we can leverage Lemmas 1 and 2 to conclude that for any . Consequently, in this case. The details are omitted for the sake of space.
Combined together, we conclude the proof of Property 5.
Appendix D. Proof of Corollary 2
We follow the same steps as in the proof of Lemma 1. To prove the corollary, it is sufficient to show that when and . We use mathematical induction to prove the monotonicity. First of all, the base case (i.e., ) is true by initialization. We assume the lemma holds at iteration . Then, we want to examine whether it holds at iteration . For the system with a single user, the update step reported in problem (5) can be simplified and rewritten as follows
where
and is the optimal value for . To prove the desired results, we distinguish between the following cases
- We first consider the case of and . When , we haveSubtracting the two expressions yieldsThe inequalities hold since , is non-decreasing in s, and Corollary 2 is true at iteration by assumption.For the case of , we obtainTherefore, when , we haveThe inequalities hold since , is non-decreasing in s, and Corollary 2 is true at iteration by assumption. Combined together, we can see that for any feasible a. Then, by problem (A8), we can conclude that the lemma holds at iteration when and .
- When and , by replacing the ’s in the above case with ’s, we can achieve the same result.
- When and , we notice that and . Then, leveraging the monotonicity of and , we can conclude with the same result.
Combining the three cases, we prove that the lemma holds at iteration of VIA. Therefore, the lemma holds at any iteration by mathematical induction. Since VIA is guaranteed to converge to the value function when , we can conclude our proof.
Appendix E. Proof of Proposition 1
We define where is the value function resulting from taking action a at state x. Then, can be calculated as follows
where is the optimal value for . Hence, the optimal action at state x can be fully characterized by the sign of . More precisely, the optimal action at state x is if , and is optimal otherwise. To determine the sign of for each state, we distinguish between the following cases
- Therefore, . Thus, the optimal action at state is .
- Then,where .
- Finally, we consider the state where . Following the same trajectory, we have
According to Corollary 2 and the fact that , we can see that and are both a constant plus a term that is non-increasing in s. As the time penalty function is unbounded, the value function must also be unbounded. Then, combining the three cases, we can conclude the following. For fixed , there always exists a threshold such that the optimal action at state where is , otherwise is optimal. Since , the optimal policy can be fully captured by the pair .
In the following, we determine the relationship between and . We have
At the same time, for the threshold , we know . Then, we have . Combined with the fact that is non-increasing in s, we can conclude that the ordering is true.
Appendix F. Proof of Proposition 2
We notice that the dynamic of AoII under threshold policy can be fully captured by a Discrete-Time Markov Chain (DTMC). Then, the expected AoII and the expected transmission rate under threshold policy can be obtained from the stationary distribution of the induced DTMC. Let the states of the induced DTMC be the values of s. We recall that is an independent Bernoulli random variable with parameter . Combined with the results in Section 2.3, we can easily obtain the state transition probabilities of the induced DTMC, which are shown in Figure A1.
Figure A1.
DTMC induced by the threshold policy . In the figure, and .
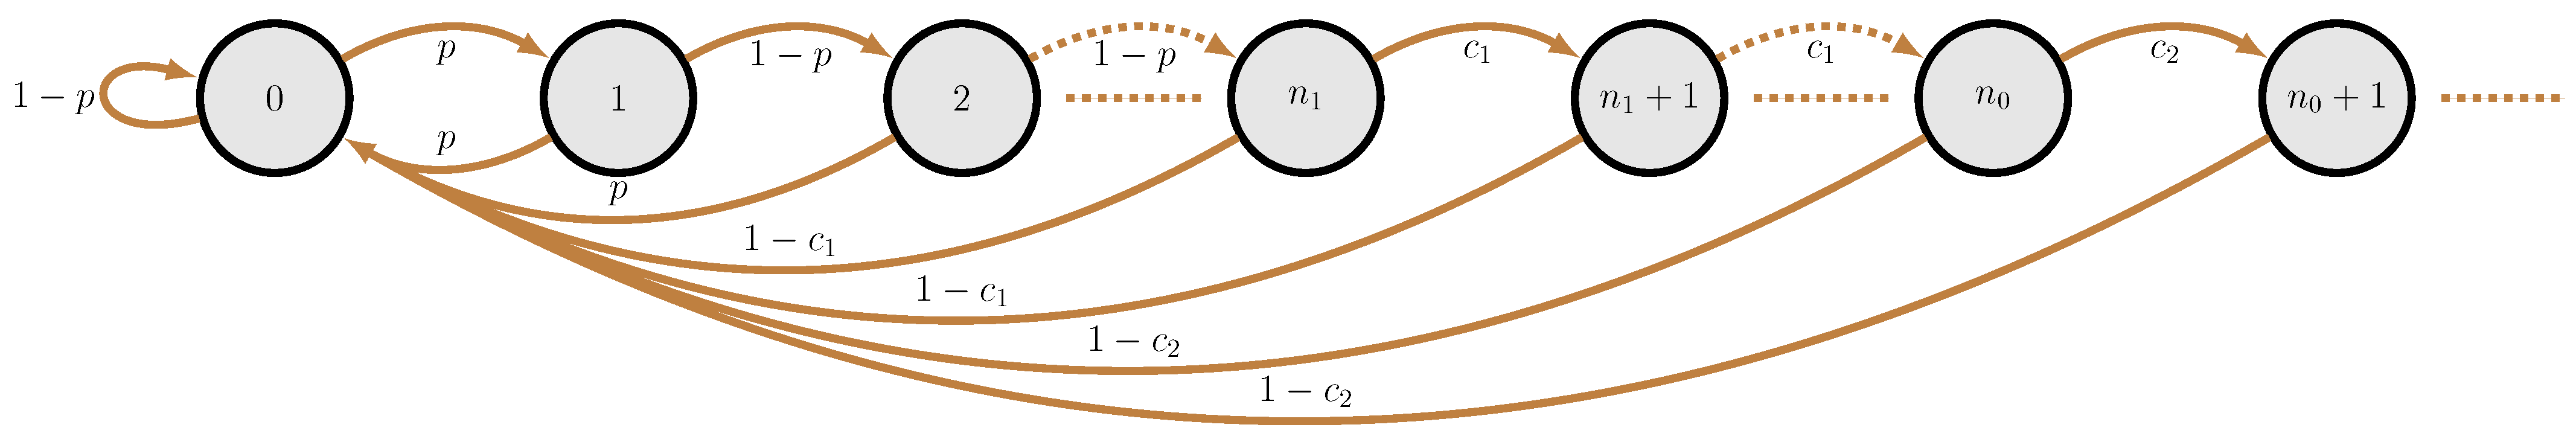
The balance equations of the induced DTMC are the following
Then, we can easily solve the above system of linear equations. After some algebraic manipulation, we obtain the following
Equipped with the above results, we proceed with calculating and . According to problem (6a), the expected AoII is:
Substituting the expressions of ’s, we can get the expression of . Proposition 1 tells us the following.
- For state where , it is optimal to stay idle (i.e., ).
- For state where , it is optimal to make a transmission attempt only when . We recall that is an independent Bernoulli random variable with parameter . Therefore, the expected proportion of time that the system is at state is .
- For state where , it is optimal to make transmission attempt regardless of .
Combined with problem (6b), we have
Substituting the expressions of ’s, we can obtain the closed-form expression of .
Appendix G. Proof of Proposition 4
We first tackle the Whittle’s indexes at state and where . To this end, we distinguish between the following cases
- We first consider the state . By definition, Whittle’s index is the infimum such that . According to (A10), we can conclude that when .
- Then, we consider the state where . We recall that . Then, we can conclude, from (A11), that for all where .
Now, we tackle the Whittle’s index at state where . For convenience, we denote by the Whittle’s index at state . According to the monotonicity of shown in the proof of Proposition 1, we can conclude that threshold policy is optimal when . Then, we can prove the following
Lemma A1.
When (9) is satisfied and , for .
Proof.
Since the value function satisfies the Bellman equation, it is sufficient to show that and satisfy the same Bellman equation. We recall that the Bellman equation for is given by
where
and is the optimal value of the decoupled problem. We recall, from Corollary 3, that the optimal action at state is staying idle (i.e., ) for any s. We also know that threshold policy is optimal when . Therefore, the optimal actions at states and where are the same (i.e., ). Equivalently, we have
According to the system dynamic reported in Section 2.3, we know that the state transition probabilities are independent of when . Meanwhile, does not affect the instant cost. Let and . Then, for any , we have
Hence, according to (A12), we can see that for any . Combined with problem (A13), we can conclude that for any . ☐
By definition, Whittle’s index is the infimum such that . In this case, according to Lemma A1, . Then, and can be written as
Without a loss of generality, we assume . Then, equating the two expressions yields
Combining problems (A14) and (A15), we conclude that is
Since the optimal action at state is , we have . Finally, we obtain
Now, we tackle the expression of . When , the optimal action at state where is staying idle. Then, leveraging Lemma A1, value function where satisfies the following
By backward induction, we end up with the following equation for .
Letting yields
From problem (A17), also satisfies the following
Equating the two expressions of , we obtain
We recall that, when , threshold policy is optimal and both actions at state are equally desirable. Thus, threshold policy is also optimal. Then, we know
where and are the expected AoII and the expected transmission rate under threshold policy , respectively. Finally, combining problems (A16), (A18) and (A19), we obtain
After some algebraic manipulation, we have
where .
In the following, we investigate some properties of Whittle’s index. First of all, is non-negative since and in (A15) are all non-negative. Meanwhile, combining (A15) with the fact that is non-decreasing in n, we can verify that is non-decreasing in n. Combined with the Whittle’s indexes in two other cases (i.e., and where ), we can easily obtain the properties of as detailed in Proposition 4.
Appendix H. Proof of Proposition 5
We notice that coincides with the decoupled model studied in Section 4.2. When problem (9) is satisfied, the decoupled problem is indexable, and, according to Corollary 3, we only need to show that n is the optimal threshold for the states with . We first tackle the case of . To this end, we divide our discussion into the following cases
- For state where , by definition. As the problem is indexable, we have . We recall that . Equivalently, . Then, we know . Combined together, we conclude that . In other words, the optimal action at state where is to stay idle (i.e., ).
- For state where , we first recall that . Consequently, for any , we know . Meanwhile, we have by the monotonicity of Whittle’s index and the definition of n. Hence, we can conclude that . In other words, the optimal action at state where is to make the transmission attempt.
Then, we conclude that n is the optimal threshold for the states with when . In the case of , according to the proof of Proposition 1, we can easily verify that the optimal threshold is 1.
Appendix I. Proof of Theorem 2
We first make the following definitions. When is at state x and action a is taken, cost and are incurred. We denote the expected -cost and the expected -cost under policy as and , respectively. Let G be a non-empty set of states. For the given state i, we define as the class of policies , for which the following hold
- The probability where is the state of at time n.
- The expected time of a first passage from i to G under is finite.
- The expected -cost and the expected -cost of a first passage form i to G under are finite.
With the definitions in mind, we proceed with verifying the assumptions given in [27].
- For all , the set there exists an action a such that is finite: For any state x, the cost satisfies . The equality holds when . Then, the states in must satisfy . Combined with the fact that is a non-decreasing and unbounded function when , we can conclude that is finite.
- There exists a stationary policy e such that the induced Markov chain has the following properties: the state space consists of a single (non-empty) positive recurrent class R and a set U of transient states such that for . Moreover, both and on R are finite: We consider the policy under which the base station makes a transmission attempt at every time slot. According to the system dynamic detailed in Section 2.3, we can see that all the states communicate with state and communicates with all other states. Thus, the state space consists of a single (non-empty) positive recurrent class and the set of transient states can simply be an empty set. and are trivially finite as we can verify using Proposition 2.
- Given any two state , there exists a policy ϕ such that : We notice that, under any policy, the maximum increase of s between two consecutive time slots is 1. Meanwhile, when s decreases, it decreases to zero. Combined with the fact that is an independent Bernoulli random variable, we can conclude that there always exists a path between any x and y with positive probability. , , and are trivially finite.
- If a stationary policy ϕ has at least one positive recurrent state, then it has a single positive recurrent class R. Moreover, if , then : Given that is an independent Bernoulli random variable, we can easily conclude from the system dynamic that all the states communicate with state and communicates with all other states under any stationary policy. Therefore, any positive recurrent class must contain state . Thus, there must have only one positive recurrent class which is .
- There exists a policy ϕ such that and where : We notice that and are nothing but the expected AoII and the expected transmission rate achieved by , respectively. Then, we can easily verify that such policy exists using Proposition 2.
As the assumptions are verified, we proceed with introducing the optimal randomized policy for given . We say a policy is -optimal if the policy is optimal for . We consider two monotone sequences and . Then, there exist subsequences of and such that the corresponding sequences of optimal policies converge. Then, according to Lemma 3.7 of [27], the limit points, denoted by and , are both -optimal. By Proposition 3.2 of [27], the Markov chains induced by and both contain a single non-empty positive recurrent class and state is positive recurrent in both induced Markov chains. Hence, the base station can choose which policy to follow each time the system reaches state while keeping the resulting randomized policy -optimal as suggested by Lemma 3.9 of [27]. More precisely, we consider the following randomized policy: each time the system reaches state , the base station will choose with probability and with probability . The chosen policy will be followed until the next choice. We denote such policy as and conclude that is -optimal under any .
Appendix J. Proof of Proposition 6
The value function and must satisfy their own Bellman equations. More precisely
where and are the optimal values of and , respectively. We recall from Section 2.3 that the users are independent when action and current state are given. Thus
where . Then, we have
We also recall from Section 2.3 that the state of user i depends only on its previous state and the action with respect to user i. Thus
Combined together, we obtain
Then, we sum problem (A20) over all users which yields
We recall that by definition. Then, leveraging problem (A21), we obtain
Since the solution to the Bellman equation is unique [21], we must have and . Then, we can conclude that it is optimal for if each user adopts its own optimal policy.
Appendix K. Proof of Theorem 3
In this proof, we class a policy as -optimal if it is optimal for . In Section 4.2, we ensure that, for each user, there exists at least one threshold policy that yields a finite expected AoII. Therefore, we can conclude that, for RP, there exists at least one policy that causes the expected AoII and the expected transmission rate to be both finite. Then, according to Lemma 3.10 of [27], a policy is optimal for RP if
- It is -optimal;
- The resulting expected transmission rate is equal to M.
We first construct a policy that is -optimal. We recall from Proposition 6 that a policy is -optimal if it consists of the optimal policies for each where . According to Theorem 2, for any i, there exist and that are both optimal for . Then, we can construct the policy in the following way.
- For user i with , the threshold policy is used. Then, the deterministic policy is optimal for andIn this case, the choice of makes no difference.
- For user i with , the randomized policy as detailed in Theorem 2 is used. Then, for any , the randomized policy is optimal for and
Combing the two cases, we conclude that is -optimal under any . Hence, as long as the chosen ’s realize , we can conclude that the randomized policy is optimal for RP.
Appendix L. Proof of Proposition 8
We notice that coincides with the decoupled model studied in Section 4.2. Therefore, we can use the results in Section 4.2 to prove the properties. Since the users share the same structure, we ignore the user index i for simplicity. According to the definition of , we have
Leveraging the results in the proof of Proposition 1, we have the following
- For state , .
- For state where , where .
- For state where , .
From the above three cases, we can easily conclude that and the equality holds when or . As is proven in Corollary 2, is non-decreasing in s. Hence, we can conclude that is also non-decreasing in s. To show that is monotone in , we consider two states and . Then, we have
Therefore, we can conclude that is non-decreasing in .
Appendix M
| Algorithm A1 Improved Relative Value Iteration | |
| Require: | |
| MDP | |
| Convergence Criteria | |
| 1: | procedureRelativeValueIteration(,) |
| 2: | Initialize ; |
| 3: | Choose arbitrarily |
| 4: | while is not converged (RVI converges when the maximum difference between the results of two consecutive iterations is less than ) do |
| 5: | for do |
| 6: | if ∃ active state s.t. and then |
| 7: | |
| 8: | |
| 9: | else |
| 10: | for do |
| 11: | |
| 12: | |
| 13: | |
| 14: | for do |
| 15: | |
| 16: | |
| return | |
| Algorithm A2 Bisection Search | |
| Require: | |
| Maximum updates per transmission attempt M | |
| MDP | |
| Tolerance | |
| Convergence criteria | |
| 1: | procedureBisectionSearch(, M, , ) |
| 2: | Initialize ; |
| 3: | using Section 5.1 and Proposition 6 |
| 4: | using Proposition 2 |
| 5: | while do |
| 6: | ; |
| 7: | using Section 5.1 and Proposition 6 |
| 8: | using Proposition 2 |
| 9: | while do |
| 10: | |
| 11: | using Section 5.1 and Proposition 6 |
| 12: | using Proposition 2 |
| 13: | if then |
| 14: | |
| 15: | else |
| 16: | |
| return | |
References
- Maatouk, A.; Kriouile, S.; Assaad, M.; Ephremides, A. The age of incorrect information: A new performance metric for status updates. IEEE/ACM Trans. Netw. 2020, 28, 2215–2228. [Google Scholar] [CrossRef] [Scilit]
- Uysal, E.; Kaya, O.; Ephremides, A.; Gross, J.; Codreanu, M.; Popovski, P.; Assaad, M.; Liva, G.; Munari, A.; Soleymani, T.; et al. Semantic communications in networked systems. arXiv 2021, arXiv:2103.05391. [Google Scholar]
- Kam, C.; Kompella, S.; Ephremides, A. Age of incorrect information for remote estimation of a binary markov source. In Proceedings of the IEEE INFOCOM 2020-IEEE Conference on Computer Communications Workshops (INFOCOM WKSHPS), Toronto, ON, Canada, 6–9 July 2020; pp. 1–6. [Google Scholar]
- Maatouk, A.; Assaad, M.; Ephremides, A. The age of incorrect information: An enabler of semantics-empowered communication. arXiv 2020, arXiv:2012.13214. [Google Scholar]
- Chen, Y.; Ephremides, A. Minimizing Age of Incorrect Information for Unreliable Channel with Power Constraint. arXiv 2021, arXiv:2101.08908. [Google Scholar]
- Kriouile, S.; Assaad, M. Minimizing the Age of Incorrect Information for Real-time Tracking of Markov Remote Sources. arXiv 2021, arXiv:2102.03245. [Google Scholar]
- Kadota, I.; Sinha, A.; Uysal-Biyikoglu, E.; Singh, R.; Modiano, E. Scheduling policies for minimizing age of information in broadcast wireless networks. IEEE/ACM Trans. Netw. 2018, 26, 2637–2650. [Google Scholar] [CrossRef] [Scilit]
- Hsu, Y.P. Age of information: Whittle index for scheduling stochastic arrivals. In Proceedings of the 2018 IEEE International Symposium on Information Theory (ISIT), Vail, CO, USA, 17–22 June 2018; pp. 2634–2638. [Google Scholar]
- Tripathi, V.; Modiano, E. A whittle index approach to minimizing functions of age of information. In Proceedings of the 2019 57th Annual Allerton Conference on Communication, Control, and Computing (Allerton), Monticello, IL, USA, 24–27 September 2019; pp. 1160–1167. [Google Scholar]
- Maatouk, A.; Kriouile, S.; Assad, M.; Ephremides, A. On the optimality of the Whittle’s index policy for minimizing the age of information. IEEE Trans. Wirel. Commun. 2020, 20, 1263–1277. [Google Scholar] [CrossRef] [Scilit]
- Sun, J.; Jiang, Z.; Krishnamachari, B.; Zhou, S.; Niu, Z. Closed-form Whittle’s index-enabled random access for timely status update. IEEE Trans. Commun. 2019, 68, 1538–1551. [Google Scholar] [CrossRef]
- Nguyen, G.D.; Kompella, S.; Kam, C.; Wieselthier, J.E. Information freshness over a Markov channel: The effect of channel state information. Ad Hoc Networks 2019, 86, 63–71. [Google Scholar] [CrossRef] [Scilit]
- Talak, R.; Karaman, S.; Modiano, E. Optimizing age of information in wireless networks with perfect channel state information. In Proceedings of the 2018 16th International Symposium on Modeling and Optimization in Mobile, Ad Hoc, and Wireless Networks (WiOpt), Shanghai, China, 7–11 May 2018; pp. 1–8. [Google Scholar]
- Shi, L.; Cheng, P.; Chen, J. Optimal periodic sensor scheduling with limited resources. IEEE Trans. Autom. Control 2011, 56, 2190–2195. [Google Scholar] [CrossRef] [Scilit]
- Leong, A.S.; Dey, S.; Quevedo, D.E. Sensor scheduling in variance based event triggered estimation with packet drops. IEEE Trans. Autom. Control 2016, 62, 1880–1895. [Google Scholar] [CrossRef] [Scilit]
- Mo, Y.; Garone, E.; Casavola, A.; Sinopoli, B. Stochastic sensor scheduling for energy constrained estimation in multi-hop wireless sensor networks. IEEE Trans. Autom. Control 2011, 56, 2489–2495. [Google Scholar] [CrossRef] [Scilit]
- Kaul, S.; Yates, R.; Gruteser, M. Real-time status: How often should one update? In Proceedings of the 2012 Proceedings IEEE INFOCOM, Orlando, FL, USA, 25–30 March 2012; pp. 2731–2735. [Google Scholar]
- Leong, A.S.; Ramaswamy, A.; Quevedo, D.E.; Karl, H.; Shi, L. Deep reinforcement learning for wireless sensor scheduling in cyber–physical systems. Automatica 2020, 113, 108759. [Google Scholar] [CrossRef] [Scilit]
- Wang, J.; Ren, X.; Mo, Y.; Shi, L. Whittle index policy for dynamic multichannel allocation in remote state estimation. IEEE Trans. Autom. Control 2019, 65, 591–603. [Google Scholar] [CrossRef] [Scilit]
- Gittins, J.; Glazebrook, K.; Weber, R. Multi-Armed Bandit Allocation Indices; John Wiley & Sons: Hoboken, NJ, USA, 2011. [Google Scholar]
- Russell, S.; Norvig, P. Artificial Intelligence: A Modern Approach, 3rd ed.; Prentice Hall Press: Hoboken, NJ, USA, 2009. [Google Scholar]
- Whittle, P. Restless bandits: Activity allocation in a changing world. J. Appl. Probab. 1988, 25, 287–298. [Google Scholar] [CrossRef] [Scilit]
- Weber, R.R.; Weiss, G. On an index policy for restless bandits. J. Appl. Probab. 1990, 27, 637–648. [Google Scholar] [CrossRef] [Scilit]
- Glazebrook, K.D.; Ruiz-Hernandez, D.; Kirkbride, C. Some indexable families of restless bandit problems. Adv. Appl. Probab. 2006, 38, 643–672. [Google Scholar] [CrossRef] [Scilit]
- Larrañaga, M. Dynamic Control of Stochastic and Fluid Resource-Sharing Systems. Ph.D. Thesis, Université de Toulouse, Toulouse, France, 2015. [Google Scholar]
- Sennott, L.I. On computing average cost optimal policies with application to routing to parallel queues. Math. Methods Oper. Res. 1997, 45, 45–62. [Google Scholar] [CrossRef] [Scilit]
- Sennott, L.I. Constrained average cost Markov decision chains. Probab. Eng. Inf. Sci. 1993, 7, 69–83. [Google Scholar] [CrossRef] [Scilit]
- Bertsimas, D.; Niño-Mora, J. Restless bandits, linear programming relaxations, and a primal-dual index heuristic. Oper. Res. 2000, 48, 80–90. [Google Scholar] [CrossRef] [Scilit]
- Littman, M.L.; Dean, T.L.; Kaelbling, L.P. On the complexity of solving Markov decision problems. arXiv 2013, arXiv:1302.4971. [Google Scholar]
- Verloop, I.M. Asymptotically optimal priority policies for indexable and nonindexable restless bandits. Ann. Appl. Probab. 2016, 26, 1947–1995. [Google Scholar] [CrossRef] [Scilit]
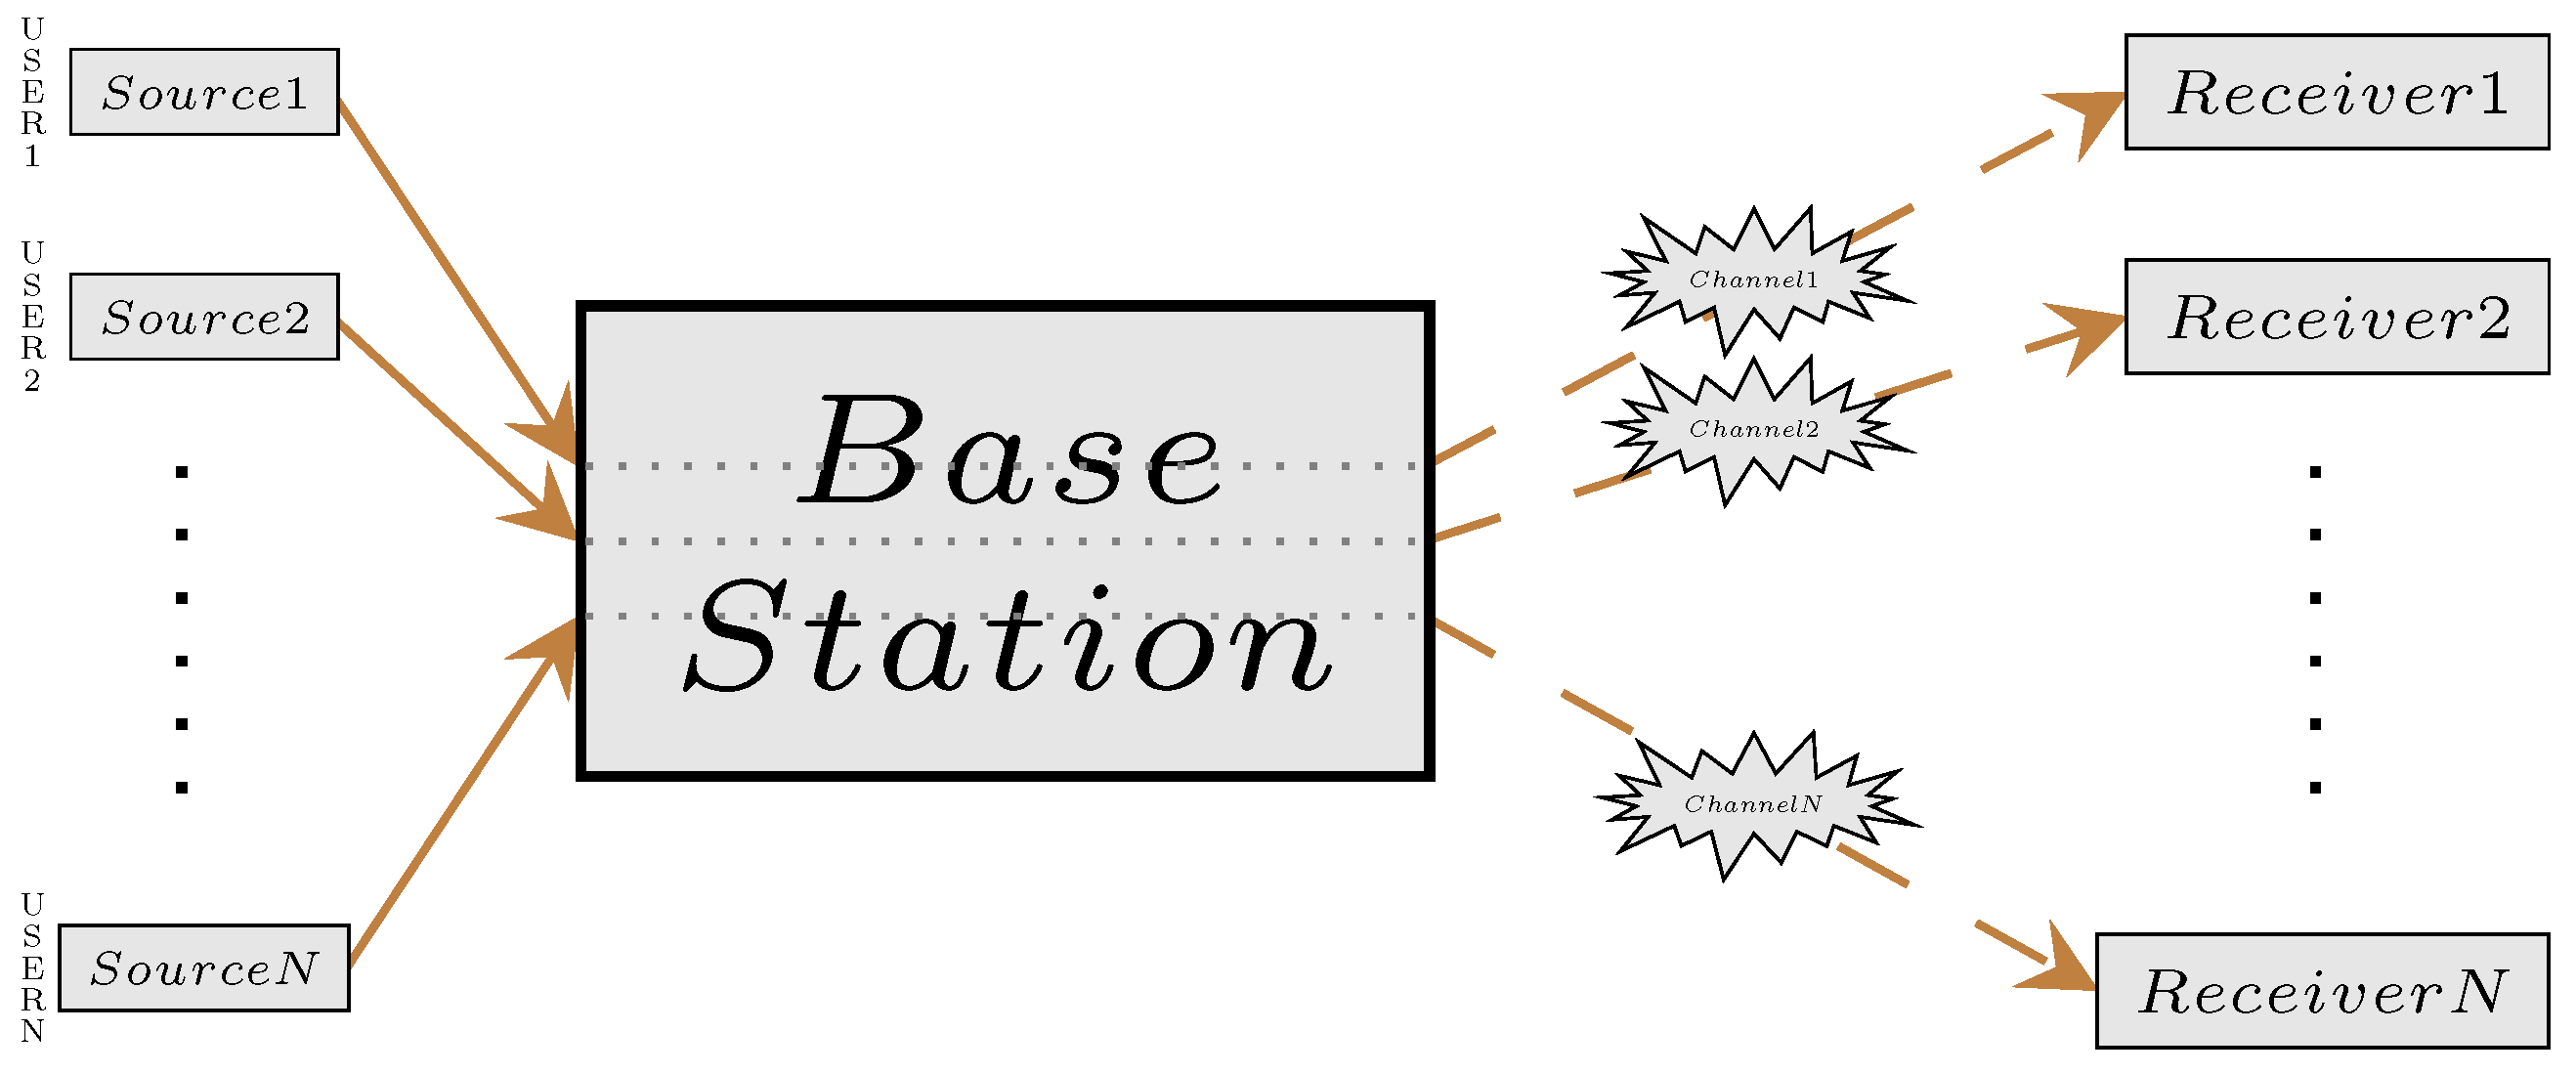
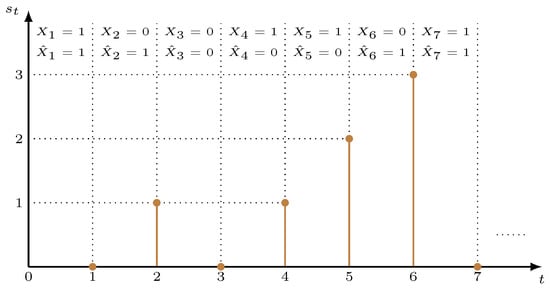
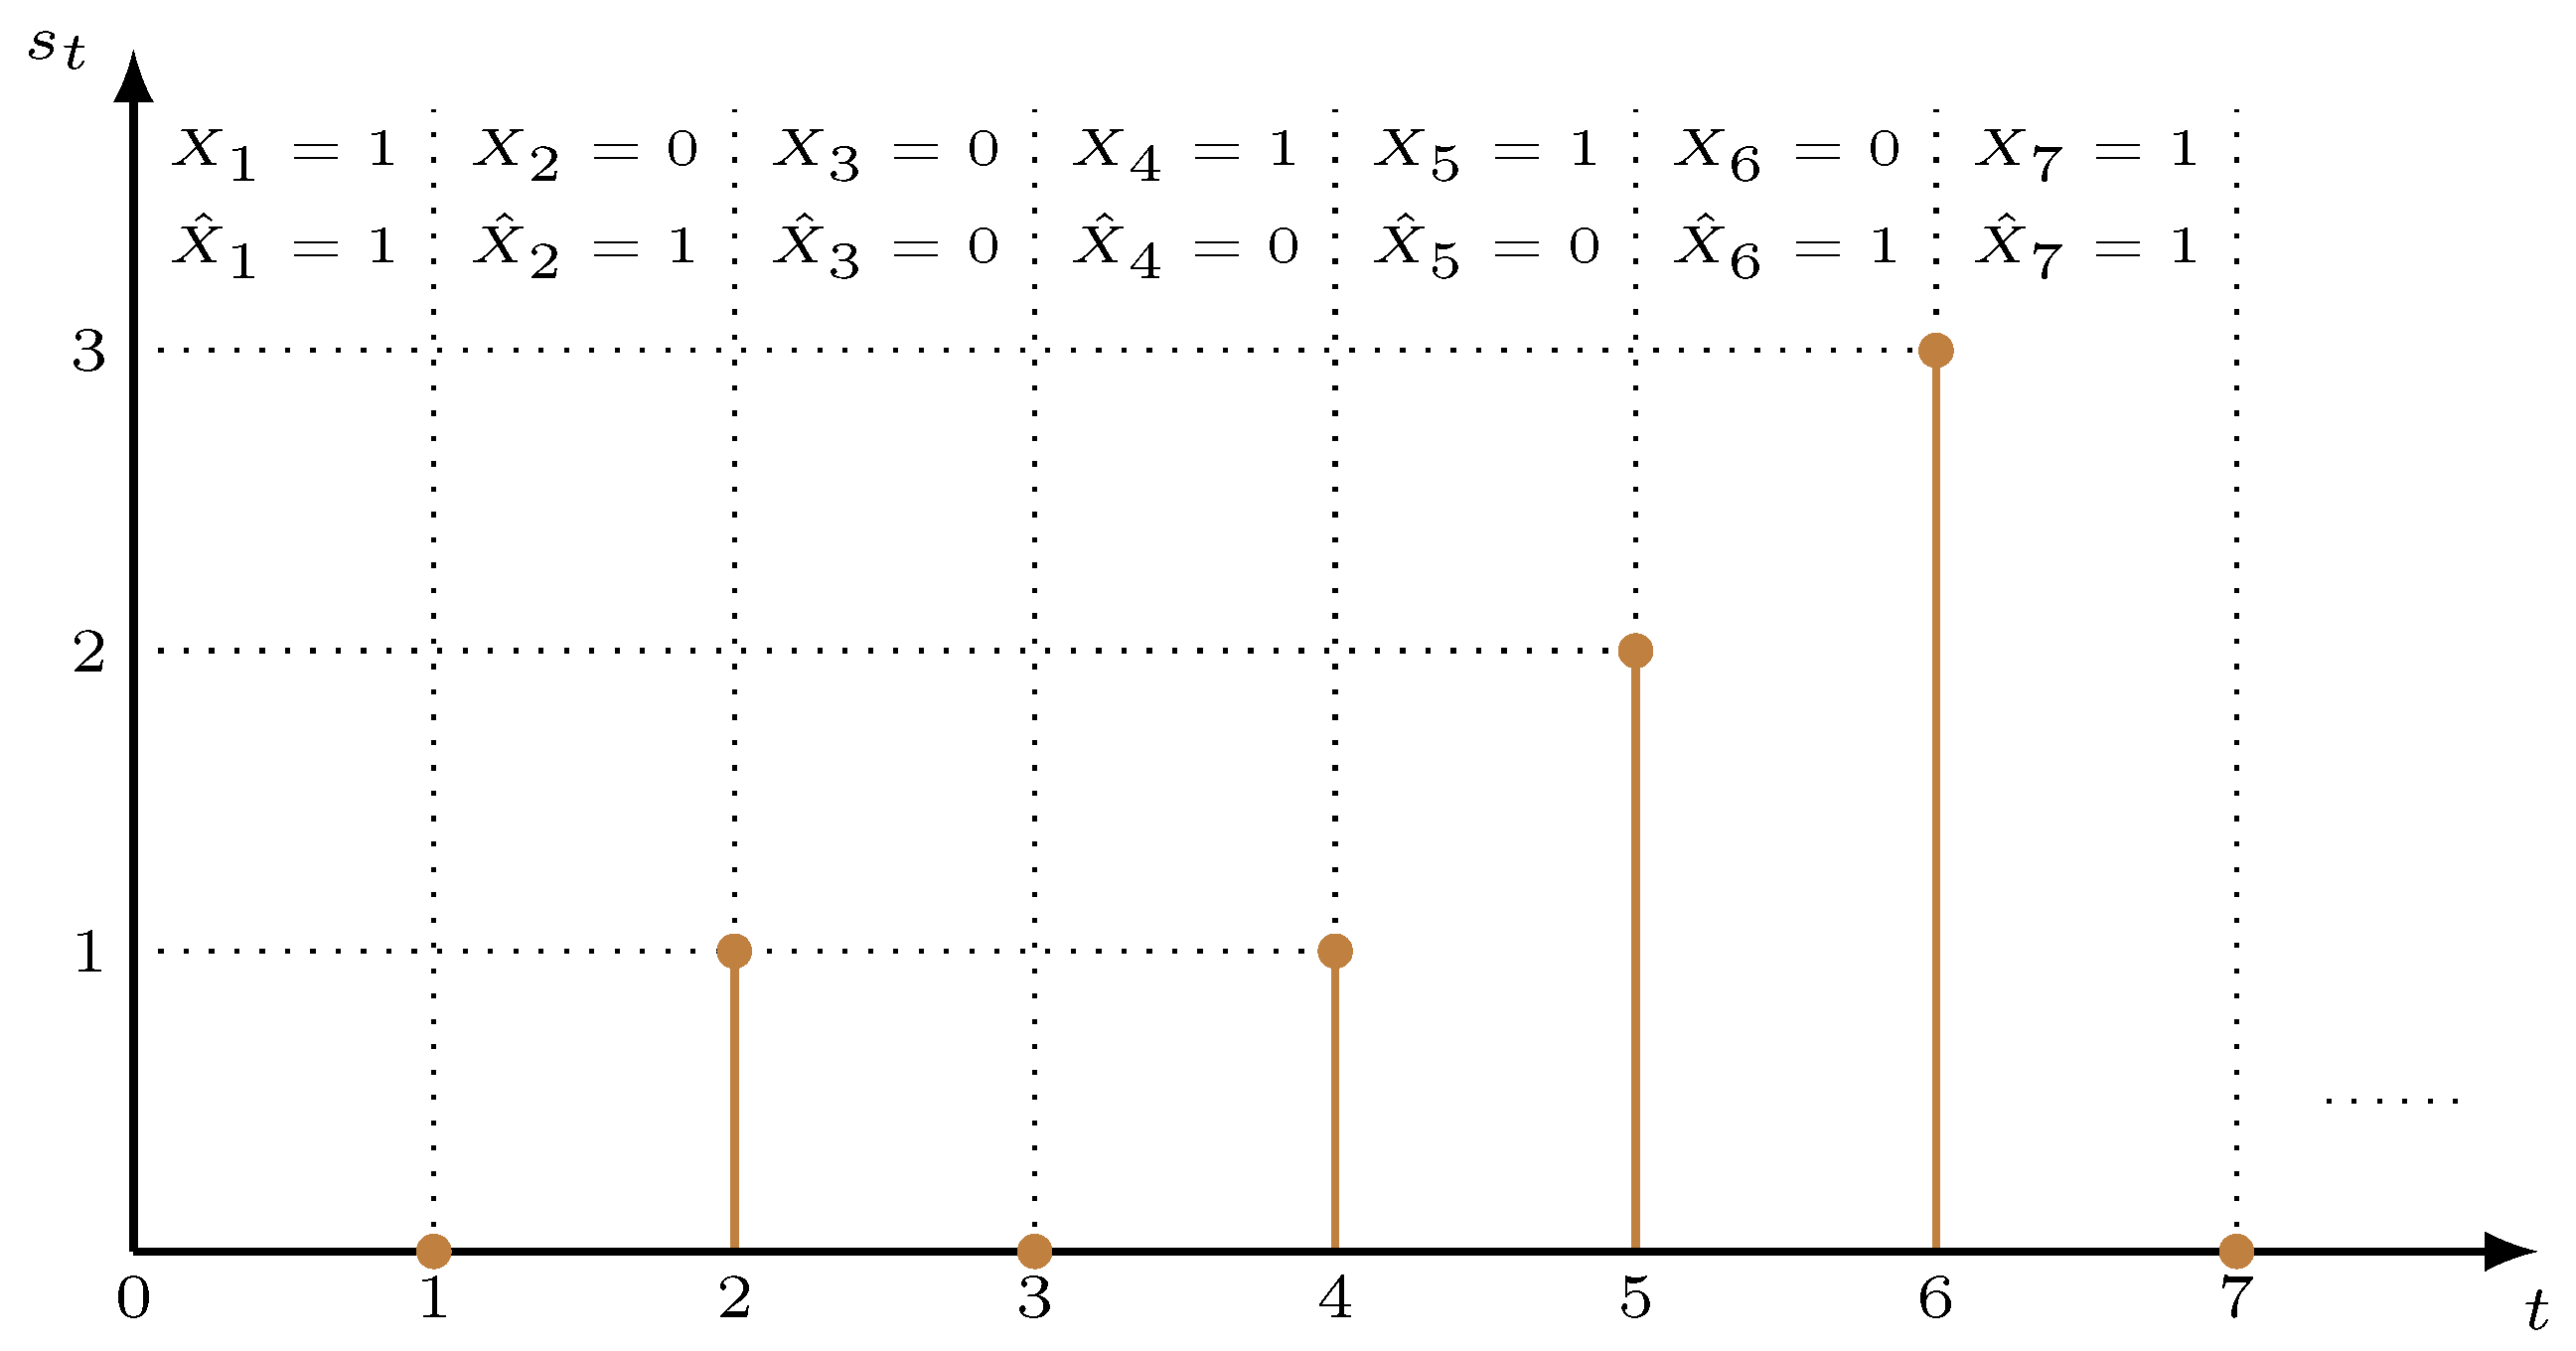
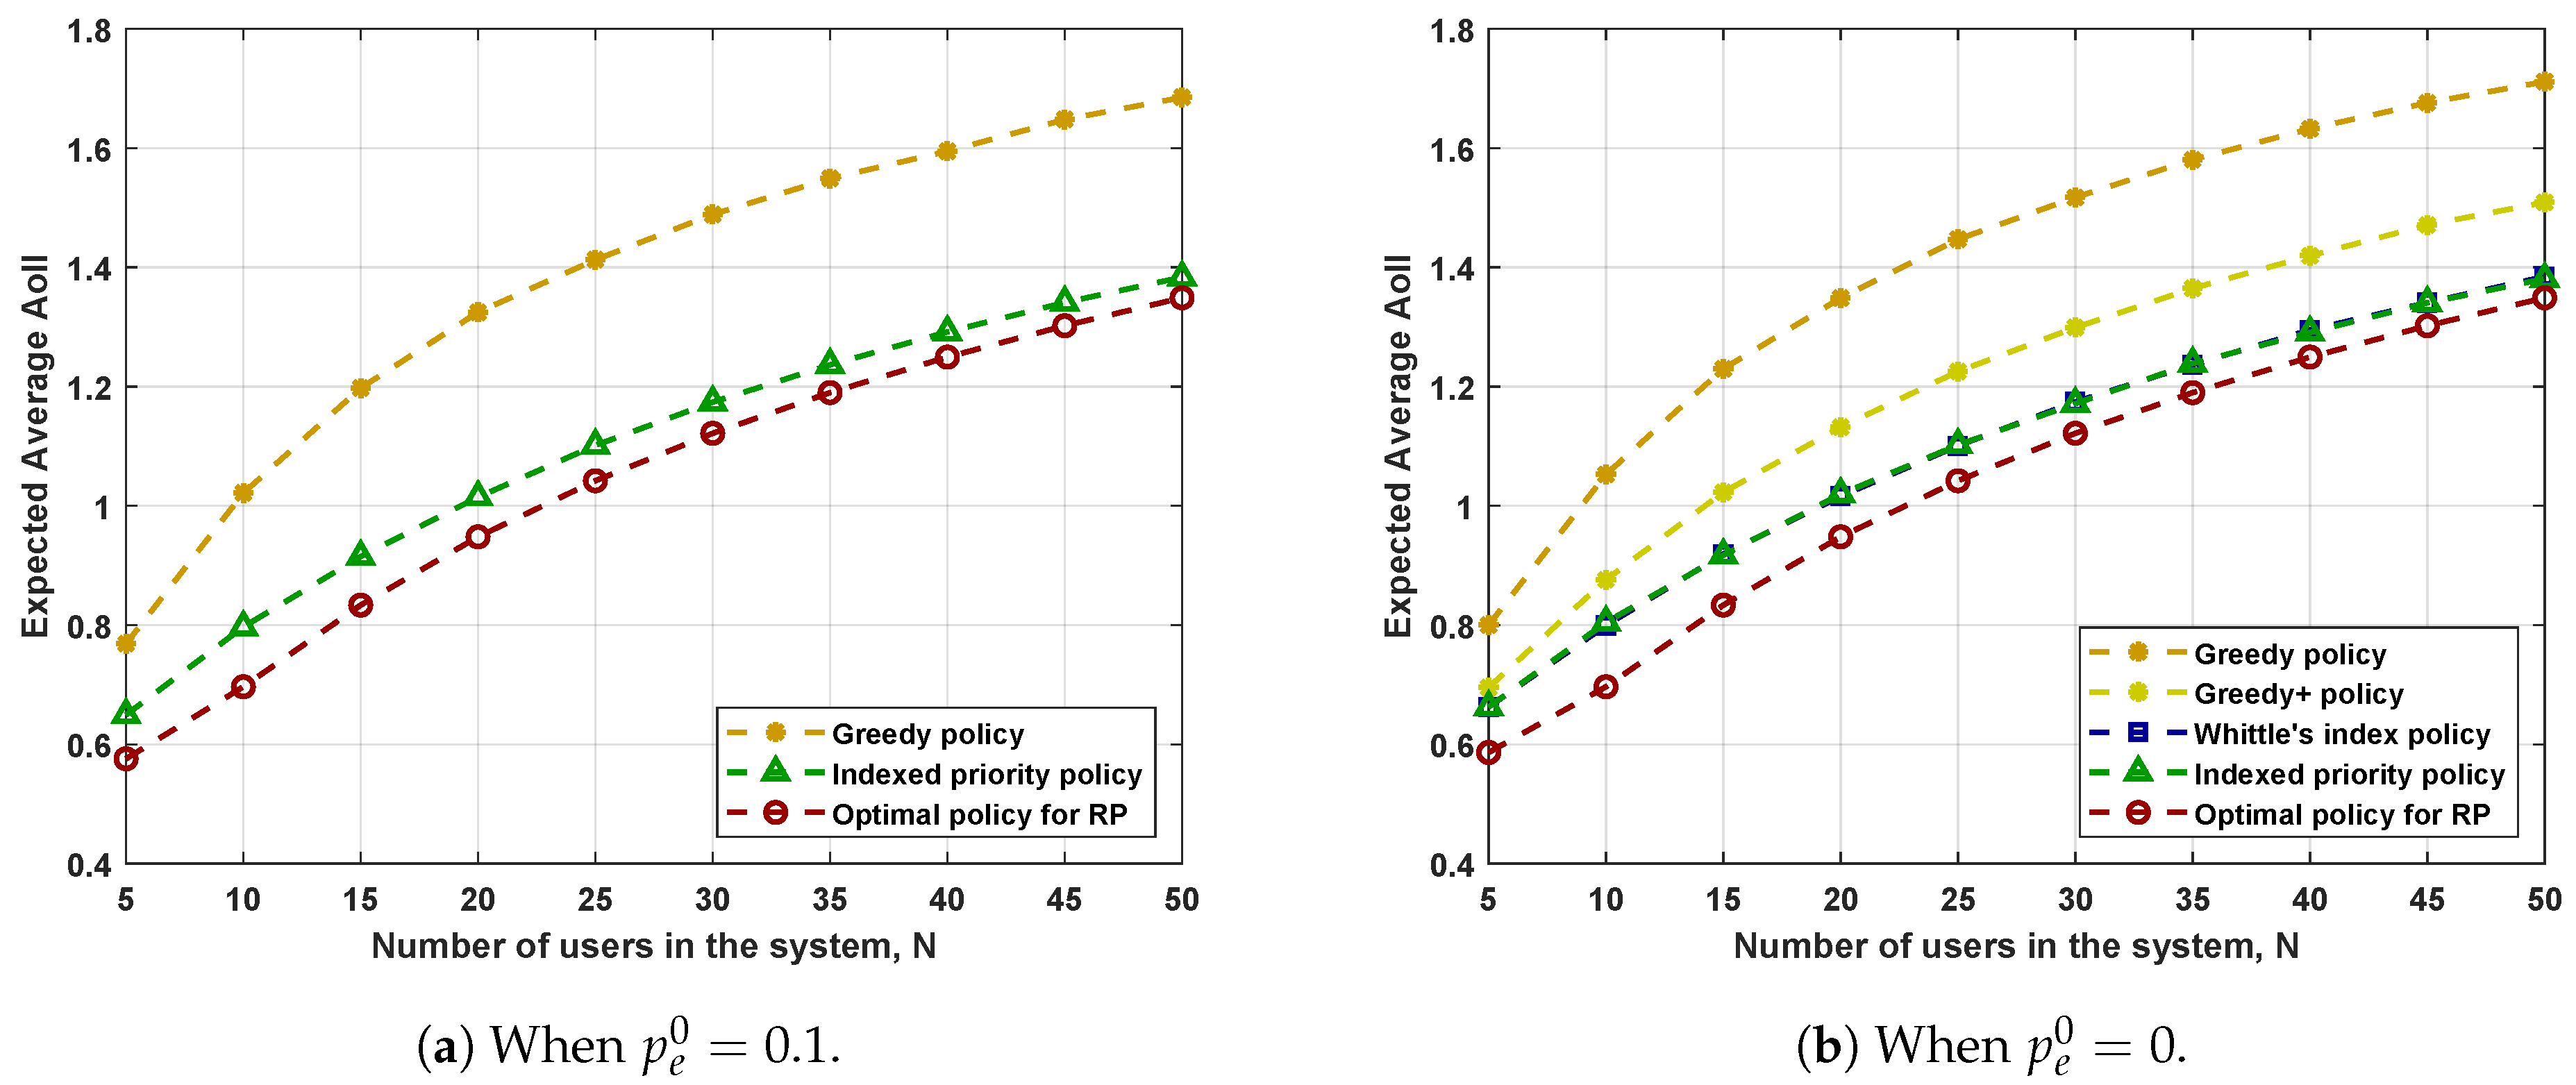
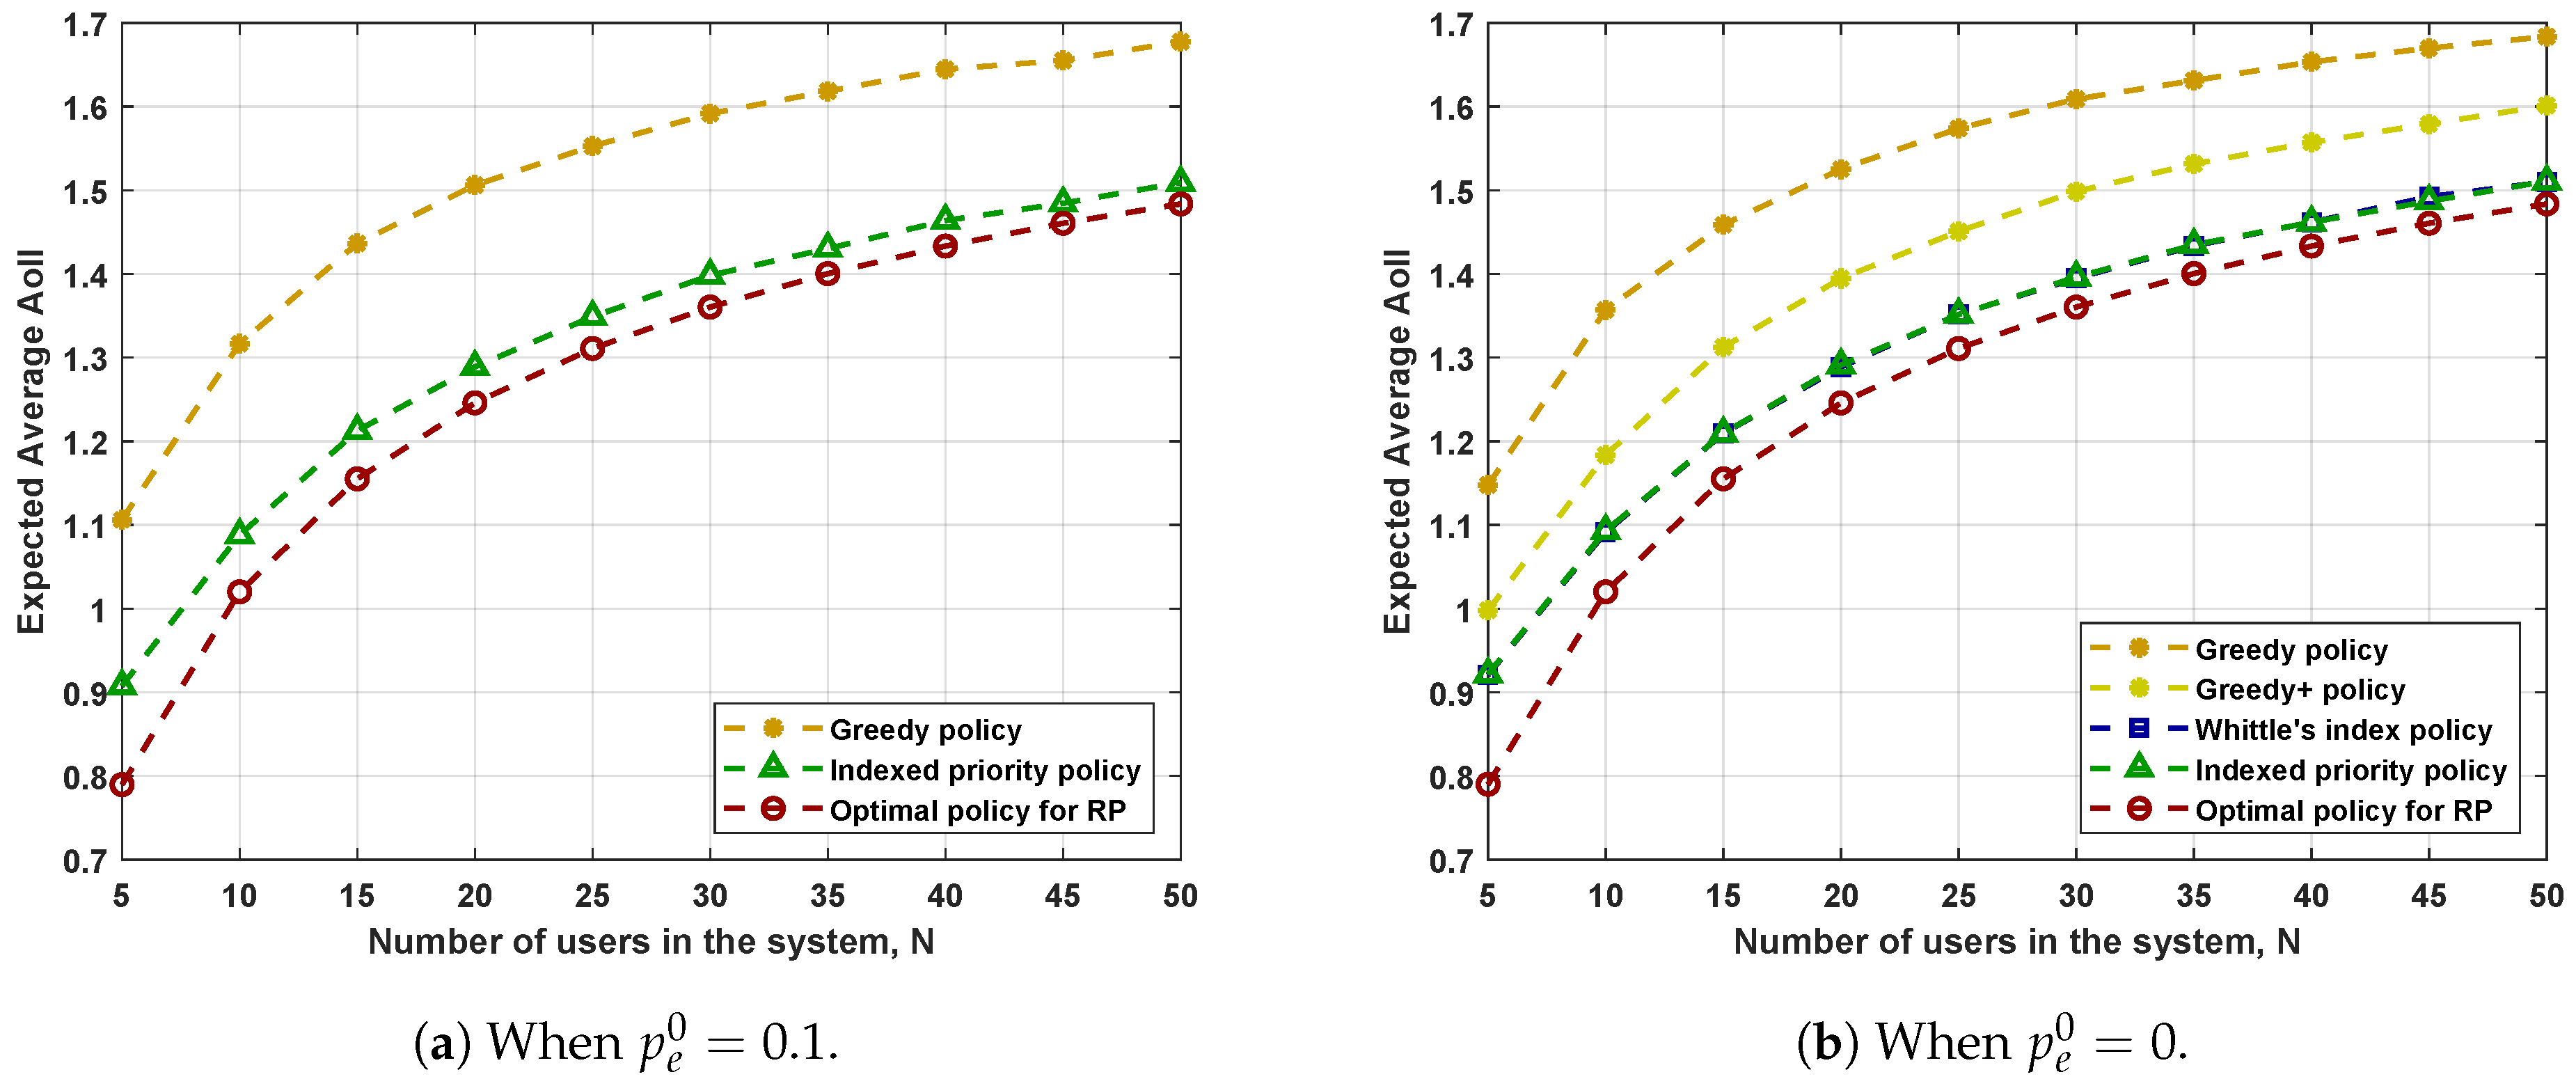
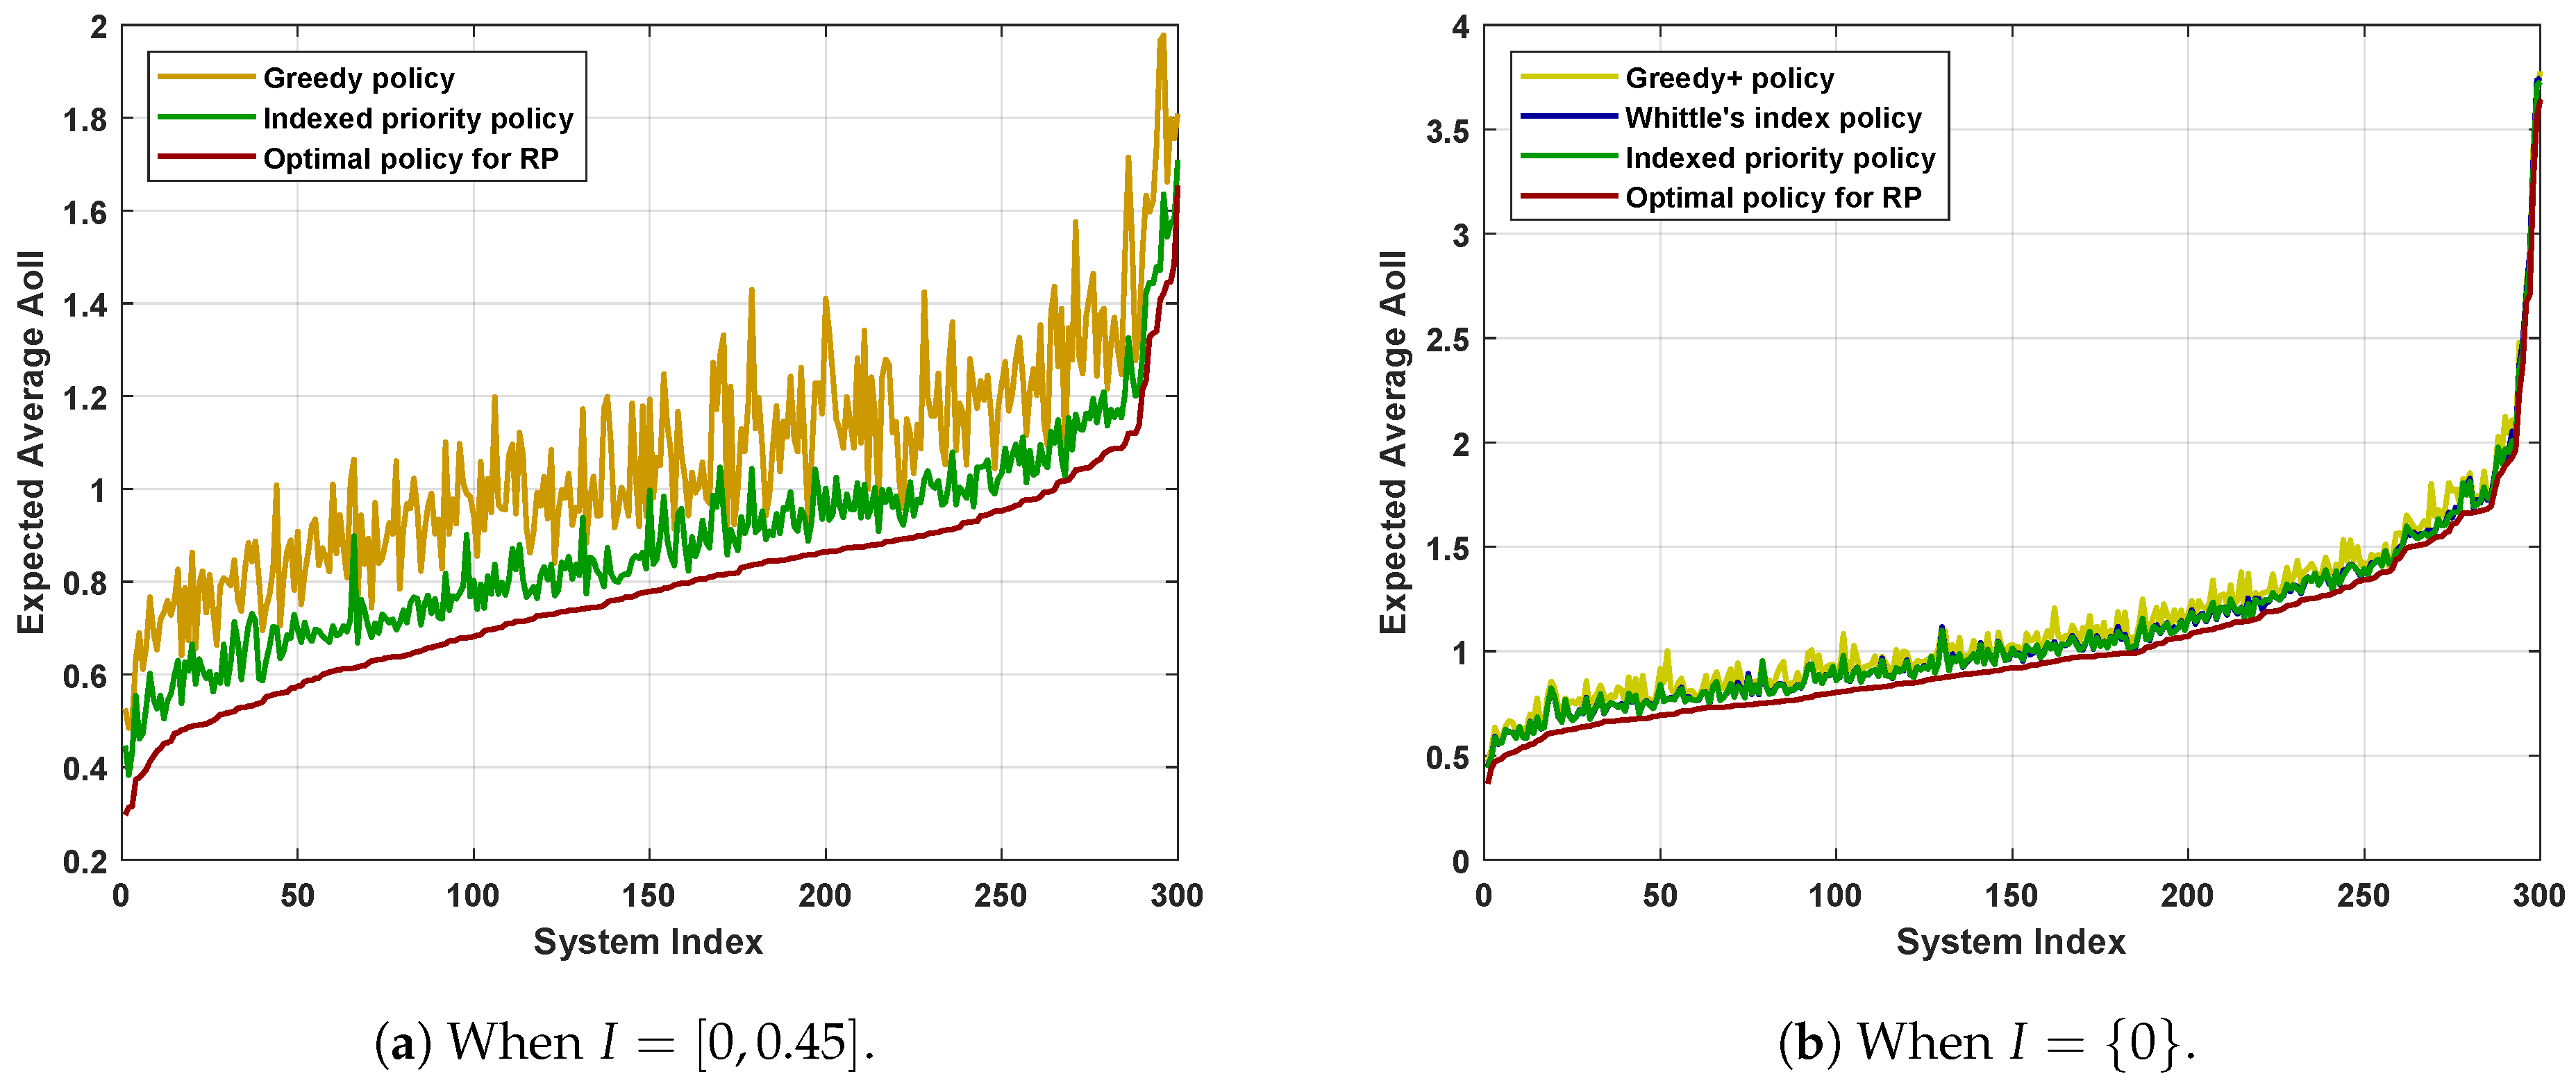
Publisher’s Note: MDPI stays neutral with regard to jurisdictional claims in published maps and institutional affiliations. |
© 2021 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).