


Abstract
One of the most prevalent recommendation systems is ranking-oriented collaborative filtering which employs ranking aggregation. The collaborative filtering study recently applied the ranking aggregation that considers the weight point of items to achieve a more accurate recommended ranking. However, this algorithm suffers in the execution time with an increased number of items. Therefore, this study proposes a new recommendation algorithm that combines the matrix decomposition method and ranking aggregation to reduce the time complexity. The matrix decomposition method utilizes singular decomposition value (SVD) to predict the unrated items. The ranking aggregation method applies weight point rank (WPR) to obtain the recommended items. The experimental results with the MovieLens 100K dataset result in a faster running time of 13.502 s. In addition, the normalized discounted cumulative gain (NDCG) score increased by 27.11% compared to the WP-Rank algorithm.
1. Introduction
The development of internet technology has made it easier for e-commerce to present its items, resulting in e-commerce exploding in popularity. With the increasing number of items, users or consumers may feel confused about buying items. Thus, e-commerce needs to invest resources to provide a list of items suitable to users’ wishes [1,2]. The resources are known as recommendation systems that can automatically generate item lists.
A recommendation system is an information filtering system that sorts items according to the user’s preferences [3]. The primary goal of a recommendation system is to predict user preferences or provide specific items to users from a vast number of things based on their interests [4]. Currently, recommendation systems play a vital role in the immense sales of large e-commerce platforms such as Amazon, Netflix, YouTube, MovieLens, Facebook, and others [1,3].
There are three basic recommender algorithms for generating recommended item lists: collaborative filtering, content-based filtering, and hybrid algorithm [1,3,5]. Among the various algorithms created for recommender systems, collaborative filtering is one of the most well-known, successful, and commonly used algorithms [2,6]. This popularity stems from its ease and effectiveness in making item recommendations depending on the user’s preferences. This recommender system suggests items to an active user based on the active user’s previous ratings and other similar users’ previous ratings, with no additional information about the items or users [2,7].
The collaborative filtering algorithm consists of two categories: rating-oriented collaborative filtering and ranking-oriented collaborative filtering [8,9,10]. The rating-oriented collaborative filtering aims to predict unrated items by active users. The algorithm sorts the items’ predicted ratings to provide a list of recommended items [8]. This approach suffers from a data sparsity problem, which arises when users rate only a few items out of a massive number of items, affecting the accuracy of the recommended items. Meanwhile, the ranking-oriented collaborative filtering approach solves the problem by ranking items directly by calculating user preferences derived from the rating values given previously [11,12].
The ranking-oriented collaborative filtering approach employs two ranking techniques: ranking generation and ranking aggregation [13]. An example of a ranking generation technique is ListWise, resulting in item rankings based on the probability distribution of top item permutation sets in the user’s neighborhood [14]. Meanwhile, the ranking aggregation utilizes user preferences information to create a list of ranked items from similar users. One of the ranking aggregation techniques is BordaRank [9]. This technique employs a voting algorithm to generate the aggregated item ranking by similar users. Another method is called weight point rank (WPR), which aims to improve the relevance of recommended items by generating the items’ weight [15]. WPR can outperform BordaRank with an increase in NDCG average value of 0.022. Although WPR improves recommendation performance, the method still suffers in time complexity due to increasing items.
Some studies applied the singular value decomposition (SVD) method to reduce the increase in items in the recommender system [16,17,18,19,20,21]. SVD aims to decompose a matrix to minimize the dataset’s dimension, which reduces time complexity. Hence, our research proposes a novel recommendation method by combining the SVD and the WPR, called SVD-WPR. The new/innovative element is the matrix factorization process applied in the baseline aggregation ranking algorithm (i.e., WPR). Our study chooses the matrix factorization using SVD because this method simplifies the data dimension through latent factors’ extraction, may remove noise, and can improve algorithm results [17]. In addition, SVD overcomes data sparsity and scalability problems in the recommendation system [16] and is more stable than other matrix factorization methods. Meanwhile, we select the aggregation ranking using WPR because this method improves the relevance of the item’s recommendations to users by creating the item weight [15].
We apply SVD to predict ratings and then calculate the user similarity to obtain neighborhood users relevant to the target user. Meanwhile, we employ WPR to generate final recommendations by aggregating the predicted ratings of neighborhood users. Thus, the contributions of our study consist of two things:
- The proposed SVD-WPR algorithm integrates the matrix factorization and the aggregation ranking to generate the Top-N recommendation in the MovieLens 100K datasets.
- The use of the SVD-WPR algorithm in the Top-N recommendation is to classify similar users’ preferences using the SVD process and predict ranking based on the k neighbors users resulting from similarity calculation using weight rank.
The rest of the paper consists of the following contents. Section 2 explains the related works that include the singular value decomposition (SVD) and weight point rank (WPR). Next, Section 3 presents the phases of our proposed recommendation method. Section 4 reveals the experiment’s results and discussion. Finally, Section 5 summarizes our findings and offers suggestions for further study.
2. Related Work
One of the collaborative filtering approaches is ranking-oriented collaborative filtering. This approach consists of two ranking techniques: ranking generation and aggregation [13]. The ranking generation technique generates a preference order of items for each user without making any rating predictions. Meanwhile, the ranking aggregation technique utilizes user preference information to generate an aggregated ranking of items from similar users.
The oldest ranking-oriented collaborative filtering is EigenRank [12]. The EigenRank algorithm measures user–user similarity based on two users’ preferences over the items. It presents two methods for ranking items based on the preferences of the neighbor set of the target user. Another ranking-oriented collaborative filtering algorithm is VSRank [12]. VSRank aims to improve recommendation accuracy for ranking-oriented collaborative filtering by adapting the vector space model and considering each user as a document and the user’s pairwise relative preferences as terms. The two ranking algorithm methods (EigenRank and VSRank) refer to pairwise ranking-oriented collaborative filtering that suffers from high computational complexity. The following ranking-oriented collaborative filtering algorithm is Listwise [11], which aims to tackle time complexity in a pairwise collaborative filtering algorithm. This algorithm predicts a ranking list of items for each user using the probability distributions over the permutations of items. Although Listwise can reduce the time complexity, it still needs to improve the recommendation accuracy.
Some studies improved traditional ranking-oriented collaborative filtering to increase the performance of the recommendation system. Tang and Tong [9] presented the ranking aggregation technique known as BordaRank. This technique uses a voting algorithm to produce the aggregated item ranking by similar users. Furthermore, the study conducted by [15] presented an improvement of BordaRank by developing the items’ weight to improve the relevance of recommended items. This method is called weight point rank (WPR). The following subsection explains the WPR algorithm in detail.
2.1. Weight Point Rank (WPR)
Weight point rank (WPR) is one of the ranking aggregation techniques that works by optimizing the usage of rating data to generate item weight [15]. The WPR process consists of four steps: calculate the number of the same ratings, calculate the item point, calculate the weight point, and calculate the weight point rank. To explain the steps of the WPR process, we represent the user and item sets as and , respectively. and denote the rating given by the user on and the rating given by the user on .
The following steps present how to count the WPR value [15]:
- Calculate the number of the same ratings given by two users using the formula defined in Equation (1), in which Equation (2) counts the number of the same ratings () by calculating the number of the same ratings for each product (,)).
- Calculate the ranking item point () using the formula defined in Equation (3) and then adding the value of 1 to the sum of point ranks (). Equation (4) formulates the sum of point ranks.
- Calculate the weight point using Equation (5).
- Calculate the weight point rank (WPR) using Equation (6).
Based on the WPR algorithm, the study [15] evaluates the WPR algorithm using MovieLens 100K. The experiment result shows that the WPR increases the average NDCG score by 0.022 compared to BordaRank. The WPR creates the item weights to generate the ranking aggregation. As a result, the WPR improves the relevance of the item’s recommendations, which becomes the advantage of the WPR algorithm.
Although WPR improves recommendation performance, the method still suffers in time complexity due to the increasing number of items. Some studies [16,17,18,19,20,21] utilized the matrix factorization method to reduce the time complexity of the recommendation system. One prevalent matrix factorization method is singular value decomposition (SVD). The following subsection presents the SVD method in detail.
2.2. Singular Value Decomposition (SVD)
Singular value decomposition (SVD) is a popular matrix decomposition method used in recommendation systems [22]. This method aims to reduce the dimensions of the original matrix by dividing it into smaller matrices [23]. The input matrix A of m x n transforms into three matrices: U with dimensions m x f, ∑ with dimensions f x f, and V with dimensions n x f, as shown in Figure 1 [3,24,25].
Figure 1.
Matrix decomposition using SVD.
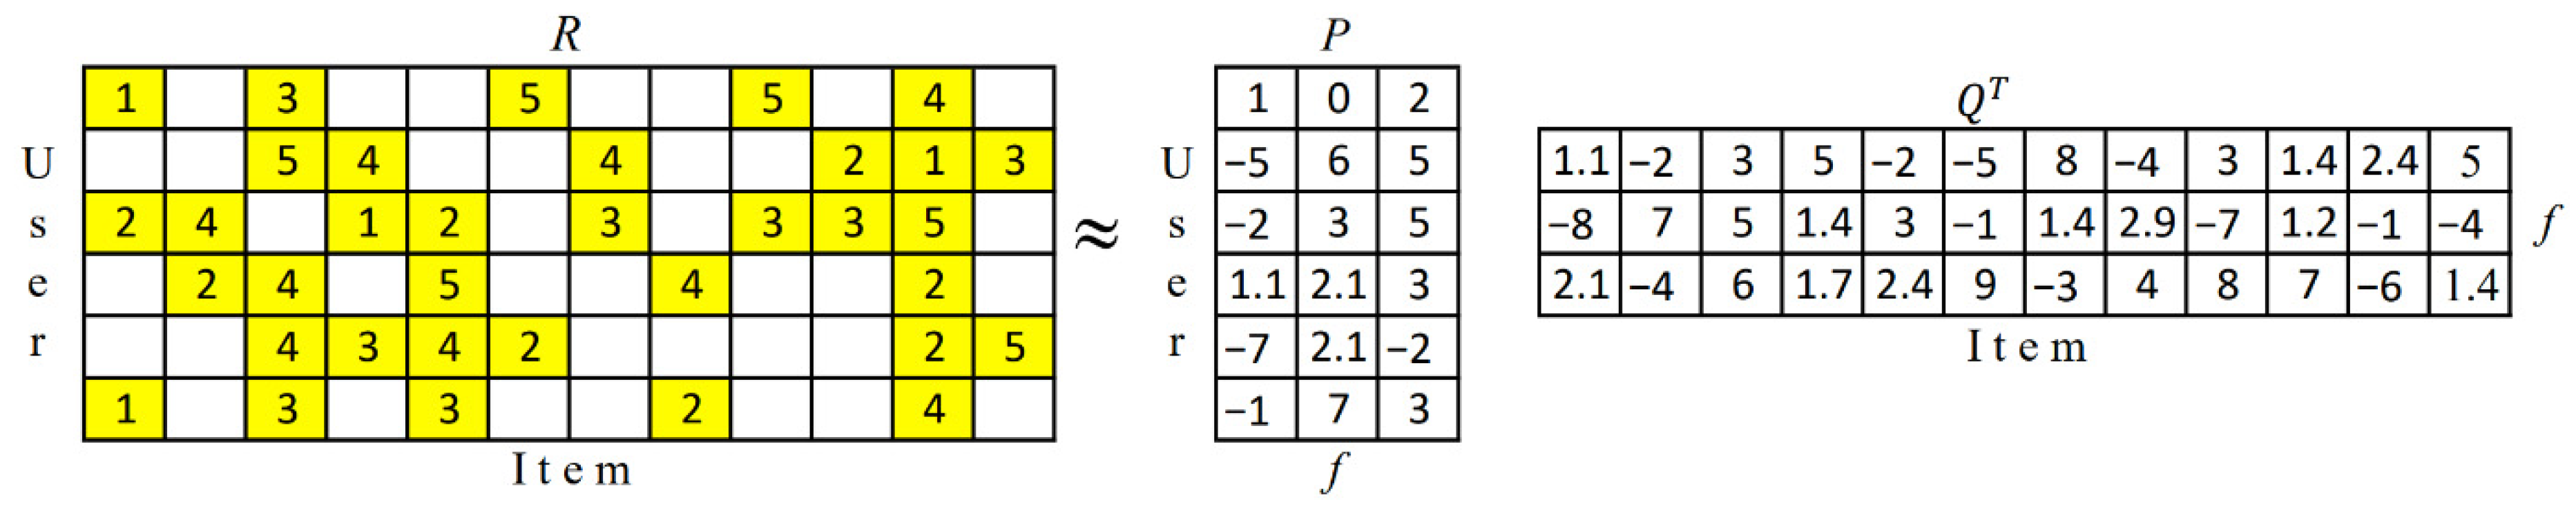
In the recommendation system, SVD divides the rating matrix (R) into two matrices (P and Q). Matrix P represents U × Σ, where Σ is a scalar so that the multiplication of the matrix does not change the dimensions of the matrix U. Therefore, the SVD in the recommendation system formulation becomes Equation (7) with the decomposition rating matrix R illustration in Figure 2.
Figure 2.
Decomposition of rating matrix (R).
R is the rating matrix, P is the user matrix, and Q is the item matrix.
In Figure 2, the matrix R describes the user rating values given to six users on twelve items. The blank value of matrix R represents the matrix sparsity. Matrix P and matrix Q derive from decomposing matrix R. The matrix P expresses a user–concept matrix, and matrix Q depicts an item-concept matrix. These two matrices are of m × f and n × f, respectively. m is the number of users, n is the number of items, and f is the factor formed by the decomposition process. The number of factors (f) can be determined as desired. This factor explains the relationship between users and items [23].
The advantages of the SVD method are the ability to simplify the data dimension through latent factors’ extraction, eliminate noise, enhance algorithm performance, and be more stable than other matrix factorization methods. In addition, SVD overcomes data sparsity and scalability problems in the recommendation system. Based on the advantages of SVD and WPR, our research proposes a novel recommendation method by combining the matrix factorization method (i.e., SVD) and the ranking aggregation process (i.e., WPR), known as SVD-WPR.
The motivations for our proposed ranking-oriented collaborative filtering lie in three aspects: First, our model utilizes the ranking aggregation process by considering the item weight to achieve the relevance recommended. Second, the proposed model can solve the time complexity by reducing the dimension of datasets. Third, the matrix factorization process can predict the unrated items to build the similarity model for finding user preferences.
3. Research Method
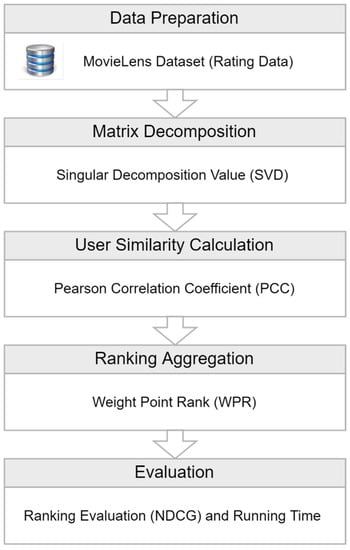
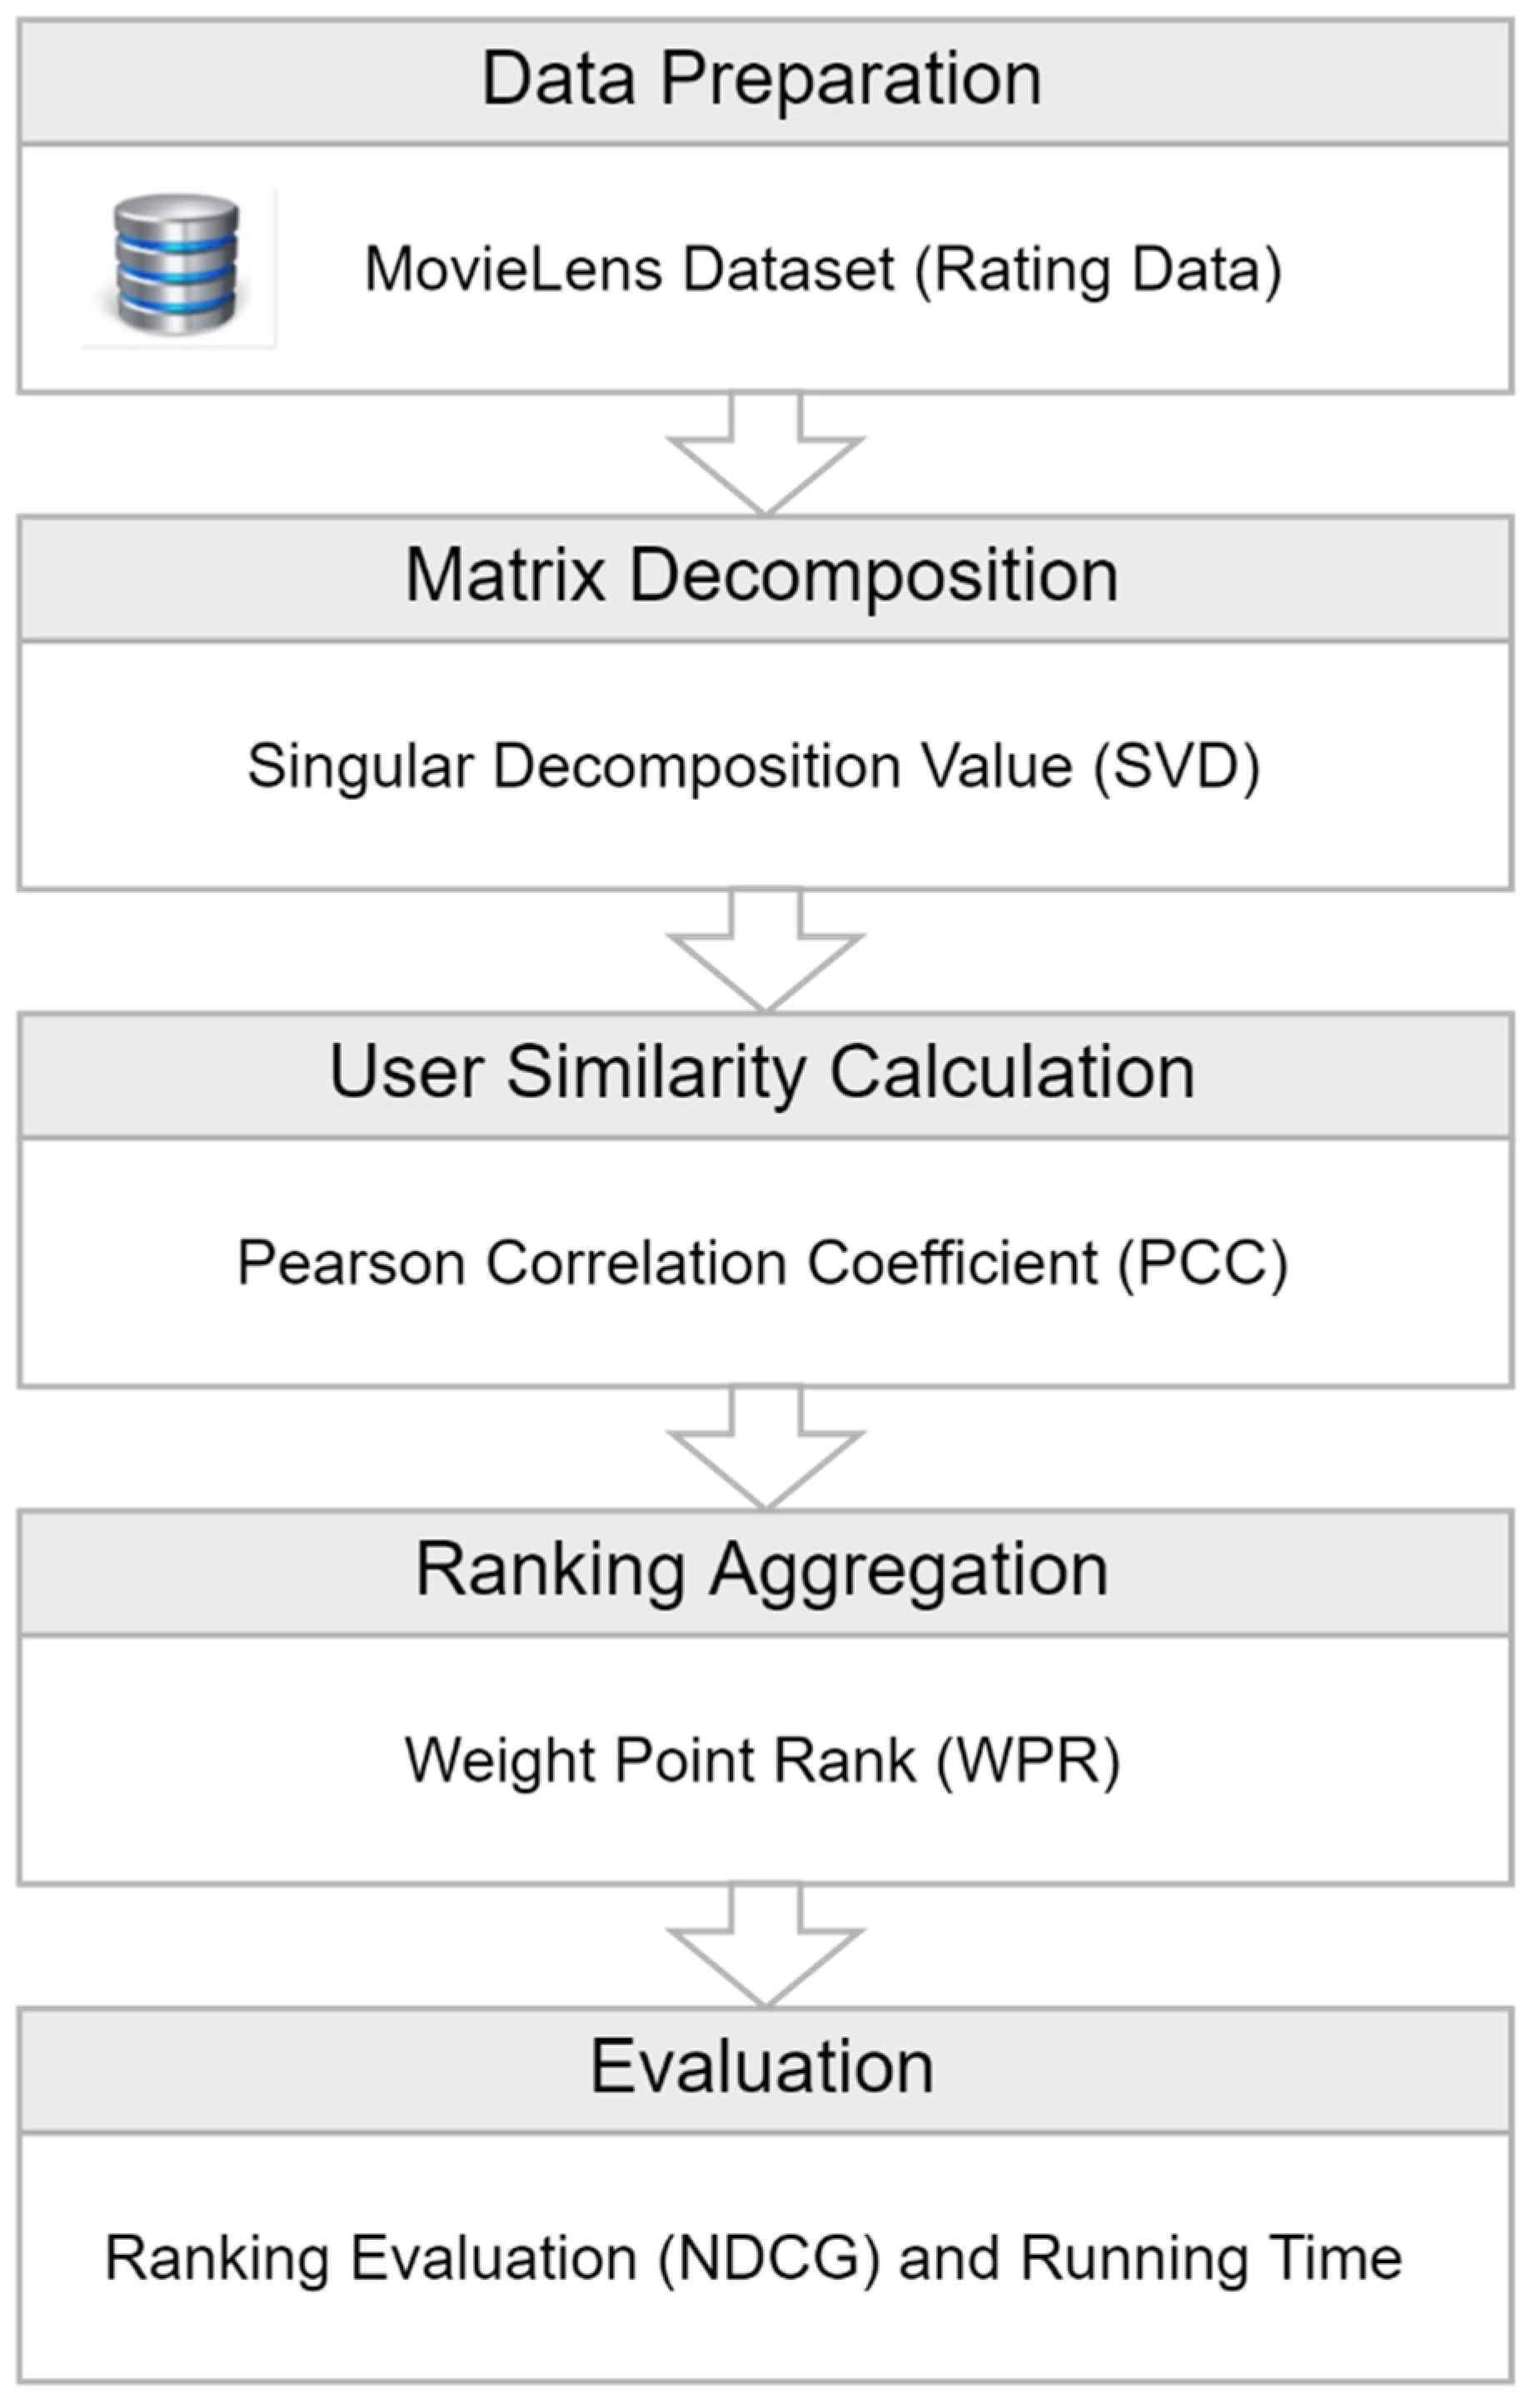
This research proposes a recommendation method incorporating the SVD method and ranking aggregation (i.e., WPR), known as SVD-WPR. Figure 3 shows our proposed recommendation method with five stages: data preparation, matrix decomposition using SVD, user similarity calculation using Pearson correlation coefficient, ranking aggregation using WPR, and evaluation. The following subsection explains each stage in detail.
Figure 3.
Research stages.
3.1. Data Preparation
This study employed the MovieLens 100K dataset to evaluate the proposed method. The MovieLens 100K is a prevalent dataset used in recommender system studies gathered by the GroupLens Research Group of the University of Minnesota [26]. Many ranking-oriented recommendation system studies employed this dataset, such as in [10,15,20,27,28]. The dataset contains 100,000 ratings with scores between 1 and 5, of which 943 users rated 1682 movies. The matrix formulation of the rating matrix is a user–item rating matrix (Rmn). m and n represent the number of users and items, respectively. The sparsity of the rating matrix is 97.3%. In the recommendation system, all items shall have ratings to achieve accurate user preference. Therefore, we utilized the SVD algorithm to predict the unrated items.
3.2. Matrix Decomposition Using SVD
SVD is a well-known matrix decomposition that breaks down large matrices into smaller ones. In this study, SVD functions to predict the unrated rating. The rating matrix (Rmn) derives into a user–factor matrix (Pmk) and a transposed item-factor matrix (QTnk). m, n, and k represent users, items, and factors. Factors describe the characteristics that users or items possess. The predicted rating calculation uses the formula defined in Equation (8) [16,17,18,19,20,21].
represents the predicted rating of user u on item i. µ states the average rating of all items. and are biased values for alleviating the prediction errors of user and item average ratings. denotes the user–factor vector, where and u = 1, 2, 3,…, m. While indicates transposed item–factor vector. and i = 1, 2, 3,…, n.
3.3. User Similarity Calculation
After predicting the unrated rating, this study calculated the user similarity from the user–factor matrix. The user similarity functions to obtain neighborhood users, namely the top users with the highest similarity value to the target user. All neighborhood users will support the ranking aggregation process. Our study employs Pearson correlation coefficient to compute the user similarity, which refers to Equation (9) [29].
and represent the set of items rated by user and user , respectively. Next, and denote the rating values on item by user and user , respectively. Furthermore, and designate the average ratings by user and user . Finally, describes one of the co-rated items by user and user .
3.4. Ranking Aggregation Using WPR
Ranking aggregation aims to achieve the ranking of items for a target user. This study employs WPR to aggregate the predicted ratings of neighborhood users for generating recommended items. WPR method applied several stages to generate the ranking items, namely, calculating the number of the same ratings, the item point, the weight point, and the weight point rank [15]. Section 2.1 details each of the WPR stages.
The following lines illustrate the WPR process. We assume the rating data given by three users to four items, as shown in Table 1. User-1 is a target user, while User-2 and User-3 are neighborhood users.
Table 1.
The ratings of four items by three users.
The first stage of the WPR process is calculating the number of the same rating, which refers to Equation (2). For example, Table 1 shows that User-1 gives a score of 5 to Item-1, and two users (User-2 and User-3) give a score of 2 to Item-1. From this data, the number of the same rating for Item-1 is User-1, with a score of 1. Meanwhile, User-2 and User-3 have a score of 2. Table 2 shows all the calculation results of the number of the same rating by users to items.
Table 2.
The number of the same rating data given by users.
The second stage calculates the item point, which refers to Equation (4). Assume User-1 receives a point of 4 for Item-1 because the rating score of User-1 on Item-1 is greater than the other three items. User-1 receives a point of 2 for Item-3 because the rating score of User-1 on Item-3 is greater than Item-4 but less than Item-1 and Item-2. Table 3 shows the calculation results of item points from all users to all items.
Table 3.
The results of item points.
After calculating the item points, the third stage calculates the weighted point, which refers to Equation (5). The weighted point is the multiplication of the item points (Table 3) with the sum of the number of the same rating (Table 2) and the rating score (Table 1). For example, User-1 gives a rating score of 5 on Item-1 (Table 1), has the number of the same rating of 1 (Table 2), and obtains the item points of 4 (Table 3). As a result, User-1 receives a weighted point of 24. Table 4 shows the calculation results of the weighted points from all users to all items.
Table 4.
The results of the weighted points.
The last stage of the WPR process calculates the weight point rank, calculated by summing each item’s weight point. The final result of WPR is a score for each item, sorted as recommended items. Table 5 shows the calculation results of weight point rank from all items. Based on Table 5, User-1 will be given recommended items in the order of Item-2, Item-1, Item-3, and Item-4.
Table 5.
The results of the weight point rank.
3.5. Evaluation
This study evaluates the performance of our proposed recommender system, a hybrid between the SVD and WPR methods, using two evaluation metrics: ranking evaluation (NDCG) and running time. NDCG stands for normalized discounted cumulative gain and functions to estimate the Top-N items on each ranking list. NDCG also considers relevant and irrelevant items based on actual ratings. The higher the NDCG value, the more relevant the rankings are to users [11,30,31]. Equation (10) defines the NDCG formula for Top-N item ranking.
refers to Equation (11) and is the ideal DCG.
represents the relevant rating of user u and N is the number of items to be evaluated.
4. Experiment
This section starts from the baseline algorithms subsection that presents several ranking algorithms compared with the proposed algorithm. Next, the experimental setting subsection represents the design of our experiments, and the experiment results subsection describes the performance comparison between the proposed method (SVD-WPR) and the previous methods (BordaRank, WP-Rank, and SVD-Borda). The performance comparison of these methods employs two evaluation metrics: ranking evaluation (NDCG) and running time. Finally, the discussion subsection reveals the experiment results’ findings and this research’s shortcomings.
4.1. Baseline Algorithms
We compared our proposed SVD-WPR algorithm with several ranking-oriented collaborative filtering algorithms. The following is a list of baseline algorithms that we compare with our proposed algorithm:
- BordaRank: BordaRank [9] utilized the ranking aggregation method to generate a list of recommendations. This method uses a voting algorithm to produce the aggregated ranking of similar users.
- WP-Rank: WP-Rank [15] aims to improve recommendation performance by ranking aggregation. This method works by maximizing the use of rating data to generate the item weight.
- SVD-Borda: SVD-Borda [13] incorporates the ranking-based collaborative filtering and matrix factorization method to mitigate the sparsity and scalability issues in rating prediction. The ranking-based collaborative filtering utilized the Borda algorithm to aggregate user preferences in the neighborhood, while the matrix factorization method employed singular value decomposition (SVD).
4.2. Experimental Setting
Our experiment divided the dataset into training and testing data to evaluate the performance of the proposed SVD-WPR algorithm. We applied the five-fold cross-validation that separated 80% of training data and 20% of testing data, which refers to many previous studies [6,32,33,34,35,36]. In this five-fold cross-validation process, this study obtained five training data (train1, train2, train3, train4, and train5) and five testing data (test1, test2, test3, test4, and test5). The number of factors (f) equals 50 to obtain the decomposed matrixes using SVD. We also set the fixed number of neighborhoods contributing to the ranking aggregation process at 50.
We compared our proposed SVD-WPR algorithm with other ranking-oriented collaborative filtering algorithms, i.e., BordaRank, WP-Rank, and SVD-Borda. The NDCG@1, NDCG@3, NDCG@5, and NDCG@10 become the evaluation metric in each testing data.
This study utilized the computer specifications of Processor 11th Gen Intel® Core™ i7-1165G7 @ 2.80 GHz, 1690 MHz (4 Core), and Memory of 16 GB. The algorithms in Python were running under Microsoft Windows 7.
4.3. Experimental Results
This subsection aims to compare the performance of the proposed SVD-WPR algorithm with the other three ranking algorithms (i.e., BordaRank, WP-Rank, and SVD-Borda). Our experiment employed the ranking accuracy and running time metrics to evaluate these algorithms’ performances. The ranking accuracy metric used NDCG, which considered the Top-N items on each ranking list. The performance comparison of these algorithms utilized five iterations. The first iteration applied the train1 and test1 datasets, and the second iteration used the train2 and test2 datasets and continued until the fifth iteration.
Table 6 shows the NDCG scores comparison of each algorithm in the MovieLens 100K dataset. The number after the ranking accuracy metric (NDCG) tells the prediction position, which shows the Top-N item ranking. For example, NDCG@5 means how accurately the algorithm has predicted the 5th ranking for the set of users in the MovieLens 100K dataset. The values in this table are average NDCG scores obtained from five iterations of testing data. The bolded values show the best results among the compared algorithms. The scale of the NDCG score is [−1, 1], with the number 1 presenting the optimal ranking.
Table 6.
Comparison of the average NDCG scores of the four ranking algorithms.
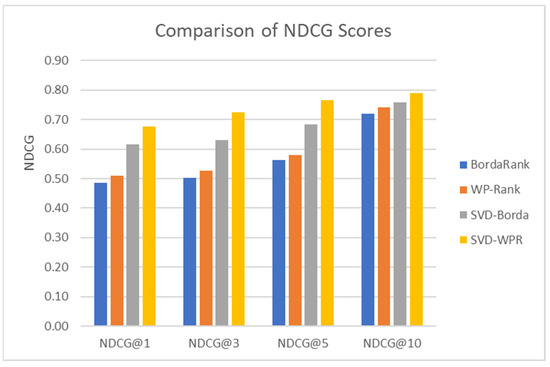
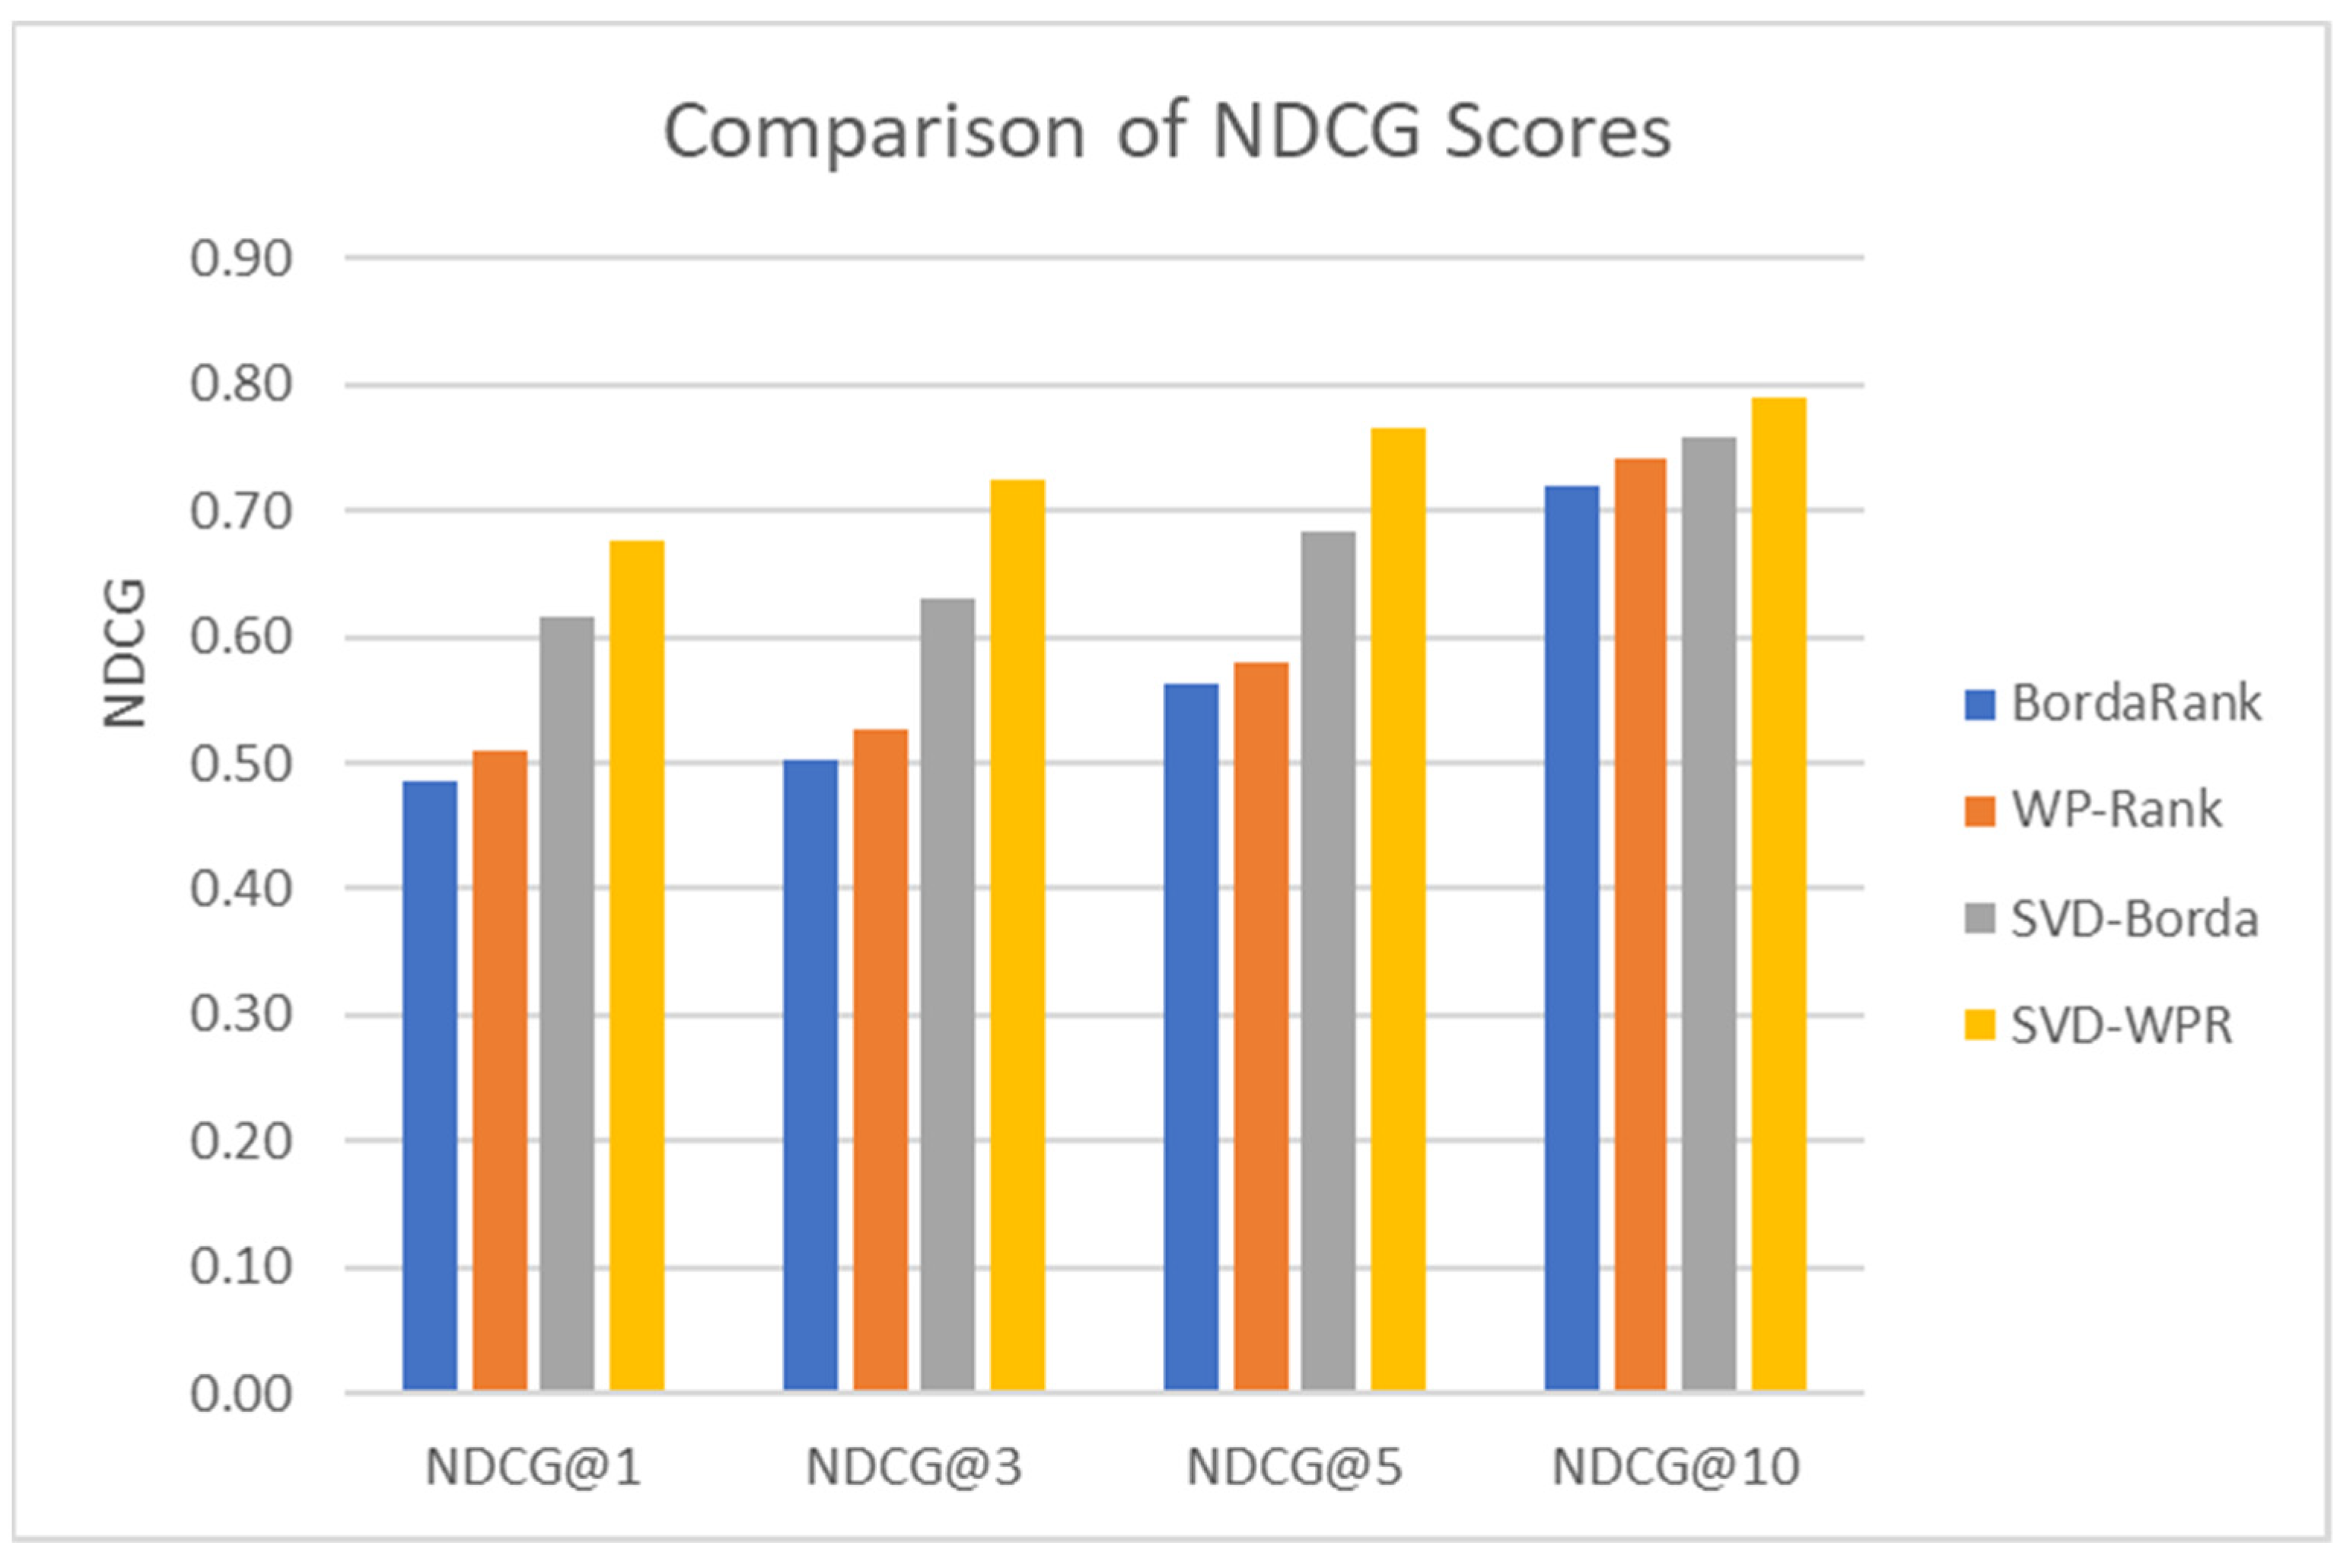
Based on Table 6, an increment in the top recommended items (Top-N items) will increase the average NDCG scores in all algorithms. It shows that the number of Top-N items affects the algorithm’s performance. The average NDCG scores for BordaRank, WP-Rank, SVD-Borda, and SVD-WPR are 0.5676, 0.5897, 0.6720, and 0.7390, respectively. The SVD-WPR algorithm obtains the highest NDCG scores in all the top recommended items. This algorithm gives users a more relevant ranking than the other three algorithms. Compared with SVD-Borda, WP-Rank, and Borda, the SVD-WPR algorithm increases NDCG scores by an average of 10.21%, 27.11%, and 32.32%, respectively. For better readability, Figure 4 illustrates the average NDCG scores of the four algorithms graphically.
Figure 4.
Comparison of NDCG scores of each algorithm on the MovieLens 100K dataset.
By evaluating the ranking accuracy using NDCG, Figure 4 shows the four algorithms’ NDCG scores increase with an increasing number of recommended items. It indicates that the number of recommended items affects the performance of algorithms. Compared with BordaRank and WP-Rank, the NDCG scores of SVD-Borda and SVD-WPR are far ahead of the small number of recommended items (@Top-N = 1, 3, and 5). Meanwhile, at the larger number of recommended items (@Top-N = 10), the NDCG scores of SVD-Borda and SVD-WPR are not far ahead compared to the NDCG scores of BordaRank and WP-Rank. It shows that the matrix decomposition process using SVD affects the accuracy ranking significantly in the small number of recommended items. The NDCG@10 scores represent the highest score in all algorithms. It denotes that the more items that are recommended, the more relevant items there will be.
With the same number of recommended items, the SVD-WPR algorithm is always higher than the other three algorithms, which means that this algorithm generates the most relevant item ranking. It happens because SVD-WPR applied the rating prediction using a matrix decomposition and involved similar users in ranking aggregation. The increase in NDCG in SVD-Borda shows the smallest; on the other hand, the results of NDCG in SVD-WPR are not far ahead of the ranking accuracy of SVD-Borda. The SVD-Borda algorithm also applies a matrix decomposition to predict ratings. It is good to mention that the matrix decomposition using SVD can generate more accurate recommended items compared to the ranking algorithm without a matrix decomposition. In all conditions of the number of recommended items, SVD-WPR performs the highest NDCG scores, which means that the proposed method performs better than the three previous methods.
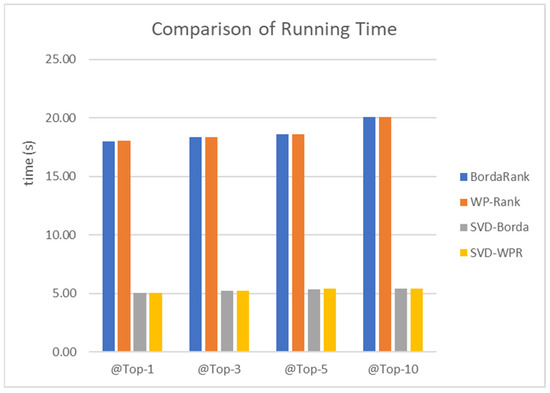
This experiment also calculated the running time to evaluate how the SVD process affected the running time of ranking algorithms. Table 7 compares the average running time in each ranking algorithm using the MovieLens 100K dataset. We evaluate four conditions of Top-N items in this running time comparison. These four conditions are @Top-1, @Top-3, @Top-5, and @Top-10, which state the number of the top recommended items. The bolded values show the fastest running time among these ranking algorithms. The average values show the running time mean in four conditions of @Top-N. Please note that the experiment’s running time combines training and recommendation times.
Table 7.
Comparison of the average running time of the four ranking algorithms.
Based on Table 7, an increment in the number of top recommended items (Top-N items) needs more time to generate recommendations. The average running time for BordaRank, WP-Rank, SVD-Borda, and SVD-WPR are 18.759 s, 18.785 s, 5.270 s, and 5.283 s, respectively. The results show that the SVD-Borda consumes the least time. However, the running time speed is virtually similar to SVD-WPR (only a 0.013 s difference or slower by 0.25% from SVD-Borda). It shows that the SVD-WPR is still competitive compared to SVD-Borda in running time performance. Nevertheless, the SVD-WPR can outperform the baseline algorithms (SVD-Borda, WP-Rank, and BordaRank) regarding ranking accuracy, as shown in Table 6. In addition, SVD-WPR still consumes less time compared to the BordaRank and WP-Rank.
Compared with BordaRank and WP-Rank, the SVD-WPR reduced the running time with a decreased average running time of 13.476 s (or 2.551 faster than the BordaRank) and 13.502 s (or 2.556 faster than the WP-Rank). The results show that the matrix decomposition using SVD can accelerate the running time of these algorithms. For better readability, Figure 5 illustrates the average running time of each algorithm graphically using the MovieLens 100K.
Figure 5.
Running time comparison of each algorithm in the MovieLens 100K dataset.
Based on Figure 5, the running time of the ranking algorithms with SVD (SVD-Borda and the SVD-WPR) is faster than those without SVD (BordaRank and WP-Rank). It shows that the performance of running time employing matrix decomposition is better than without the matrix decomposition process. In other words, the matrix decomposition process helps speed up the running time to generate a recommendation. Compared to SVD-Borda, our proposed SVD-WPR algorithm requires a greater average running time of 0.013 s. This is because the SVD-WPR utilizes the ranking aggregation algorithm, which is more complex than SVD-Borda, to optimize the recommended items ranking. As compensation, the recommended items produced by SVD-WPR are more accurate than those generated by SVD-Borda (see Table 6).
4.4. Discussion
This paper proposes a recommendation algorithm that incorporates the ranking-based collaborative filtering and matrix factorization method to overcome the scalability problem in the ranking aggregation algorithm. The ranking-based collaborative filtering employs the weight point rank algorithm to aggregate user preferences in the neighborhood. Meanwhile, the matrix factorization method utilizes singular value decomposition (SVD) to predict the unrated rating.
We compare the performance of our proposed algorithm with the three previous ranking-based algorithms (i.e., BordaRank, WP-Rank, and SVD-Borda) using the benchmark dataset (MovieLens 100K). We evaluate two metrics (i.e., ranking accuracy and running time) to compare the performance of these algorithms. The ranking accuracy metric employs normative discounted cumulative gain (NDCG). The NDCG scale is [−1.1], where the number 1 denotes the perfect ranking. Meanwhile, running time comparison is simple; the faster, the better.
The experimental results show that incorporating the ranking aggregation and matrix decomposition algorithms can improve the ranking performance by increasing an average NDCG by 32.32%, 27.3%, and 10.21% compared to BordaRank, WP-Rank, and SVD-Borda algorithms, respectively. In addition, the proposed algorithm can reduce the running time by 13.489 s and 13.502 s compared to BordaRank and WP-Rank, but consumes less time (0.013 s) than SVD-Borda. The results show that the SVD-WPR significantly increases in ranking accuracy and can speed up the running time compared to the ranking aggregation algorithms without matrix decomposition (BordaRank and WP-Rank). The more accurate results of SVD-WPR are caused by the ranking aggregation algorithm using the product weighting and predicting the unrated rating before determining the neighborhood users. Furthermore, the speed of running time in SVD WPR occurs because this algorithm applies a smaller matrix dimension to calculate user similarity (using a user–factor matrix resulting from matrix decomposition).
The proposed approach is independent of the field of application. Consequently, other applications can apply the proposed recommendation algorithm, such as book and transportation recommendations. The application domains only require explicit rating data, i.e., the value entered by the user directly when accessing the chosen item. It becomes the advantage of our proposed algorithm.
We also evaluate the performance of SVD-WPR in another dataset (i.e., MovieLens 1M). The average NDCG values for SVD-WPR are 0.8932 based on testing with MovieLens 1M datasets. The average NDCG values by 0.6765, 0.6887, and 0.7326 for baseline algorithms (BordaRank, WPR, and SVD-Borda). The test results on a larger dataset reveals that SVD-WPR performs better than the baseline algorithms (BordaRank, WPR, and SVD-Borda), improving NDCG by 30.03%, 29.69%, and 21.92%, respectively. Additionally, the larger dataset (MovieLens 1M) produces higher NDCG than MovieLens 100K. It demonstrates that the SVD-WPR generates a highly relevant ranking in a larger dataset, which is advantageous for our research.
Recently, several studies [37,38,39] also offered various recommendation algorithms to enhance performance. A study in [37] applied a ranking aggregation algorithm that combined the clustering and Copeland method to reduce the victory frequency with defeat frequency in the pairwise contest. The experiment using MovieLens 100K obtains the average NDCG score is 0.5649. The result has lower NDCG compared to our proposed algorithm (SVD-WPR). It means that the SVD-WPR is superior to Copeland. In addition, the study conducted by [38] suggested an enhanced group recommender system (GRS) by exploiting preference relation (PR), known as GRS-PR. Their experiment result shows that the NDCG@10 average in MovieLens 100K is 0.5519. Based on this result, our proposed algorithm (SVD-WPR) still outperforms GRS-PR by improving the NDCG score to 0.2384. It becomes the advantage of our proposed method to generate relevance of item ranking.
Furthermore, Pujahari and Sisodia [39] utilize matrix factorization-based preference relation to obtain the predicted rating and then applies the graph aggregation method to aggregate the group member’s preferences. Their recommendation algorithm is known as PR-GA-GRS. The experiment using MovieLens 1M yields the NDCG@10 average is 0.5718. This NDCG result is lower than the NDCG result using SVD-WPR, showing that the SVD-WPR also outperforms the PR-GA-GRS.
Although the proposed SVD-WPR algorithm can overcome data sparsity and scalability, reduce running time, and increase recommendation performance in NDCG scores, the SVD-WPR still has shortcomings. During the implementation of our proposed algorithm, one limitation may arise when the dataset drastically increases. The limitation occurs since the singular value decomposition’s factorization process becomes computationally expensive. Meanwhile, the burden of our proposed algorithm is that the user similarity for determining the neighborhood users depends on selecting the number of factors in matrix decomposition. For the ranking aggregation process, we also set a fixed number of neighborhoods (50 in this case). Thus, it needs to explore the optimal number of factors and neighborhoods for processing the ranking aggregation to achieve more accurate results and faster execution time.
5. Conclusions
This paper presents a novel recommendation algorithm called SVD-WPR that utilizes matrix decomposition using SVD and ranking aggregation using WPR. The process begins with decomposing the rating matrix using SVD to predict the unrated items. Afterward, we find the neighborhood users using Pearson correlation coefficient and employ the WPR in the ranking aggregation process to obtain more accurate recommended items.
The experimental work showed that our proposed algorithm could improve the recommendation performance in NDCG on MovieLens 100K dataset compared to the other tested algorithms. The results demonstrated that the SVD-WPR outperforms the previous three algorithms (BordaRank, WP-Rank, and SVD-Borda), with the average NDCG scores increasing by 32.32%, 27.11%, and 10.21%, respectively. In addition, our proposed algorithm can speed up the execution time by 13.489 s and 13.502 s compared to BordaRank and WP-Rank, respectively; however, it was slower than SVD-Borda by 0.013 s.
For future research, accelerating the running time and improving the recommendation performance accuracy will still be challenges to be overcome by investigating the optimal number of factors in matrix decomposition and exploring the other combined collaborative filtering algorithms.
Author Contributions
Conceptualization, T.W. and T.B.A.; methodology, T.W. and T.B.A.; software, T.W. and M.I.A.; validation, T.W., M.I.A. and T.B.A.; formal analysis, T.W. and T.B.A.; investigation, T.W. and M.I.A.; resources, T.W. and M.I.A.; data curation, T.W. and M.I.A.; writing—original draft preparation, T.W.; writing—review and editing, T.W. and T.B.A.; visualization, M.I.A.; supervision, T.B.A.; project administration, T.W. and T.B.A.; funding acquisition, T.B.A. All authors have read and agreed to the published version of the manuscript.
Funding
This research was supported by Directorate General of Higher Education (Dikti), Ministry of Education, Culture, Research and Technology, Research Grant: Penelitian Dasar with contract number 1752/UN1/DITLIT/DitLit/PT.01.03/2022.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The datasets generated and analyzed during the current study are available in the MovieLens dataset (https://grouplens.org/datasets/movielens/, accessed on 15 January 2022).
Conflicts of Interest
The authors declare no conflict of interest.
References
- Nam, L.N.H. Towards comprehensive approaches for the rating prediction phase in memory-based collaborative filtering recommender systems. Inf. Sci. (N. Y.) 2022, 589, 878–910. [Google Scholar] [CrossRef] [Scilit]
- Khojamli, H.; Razmara, J. Survey of similarity functions on neighborhood-based collaborative filtering. Expert Syst. Appl. 2021, 185, 115482. [Google Scholar] [CrossRef] [Scilit]
- Bhalse, N.; Thakur, R. Algorithm for movie recommendation system using collaborative filtering. Mater. Today Proc. 2021, 2, 1–6. [Google Scholar] [CrossRef] [Scilit]
- Afoudi, Y.; Lazaar, M.; Al Achhab, M. Hybrid recommendation system combined content-based filtering and collaborative prediction using artificial neural network. Simul. Model. Pract. Theory 2021, 113, 102375. [Google Scholar] [CrossRef] [Scilit]
- Duan, R.; Jiang, C.; Jain, H.K. Combining review-based collaborative filtering and matrix factorization: A solution to rating’s sparsity problem. Decis. Support Syst. 2022, 156, 113748. [Google Scholar] [CrossRef] [Scilit]
- Widiyaningtyas, T.; Hidayah, I.; Adji, T.B. Recommendation algorithm using clustering-based upcsim (Cb-upcsim). Computers 2021, 10, 123. [Google Scholar] [CrossRef] [Scilit]
- Chen, S.; Peng, Y. Matrix factorization for recommendation with explicit and implicit feedback. Knowl.-Based Syst. 2018, 158, 109–117. [Google Scholar] [CrossRef] [Scilit]
- Shams, B.; Haratizadeh, S. Item-based collaborative ranking. Knowl. -Based Syst. 2018, 152, 172–185. [Google Scholar] [CrossRef] [Scilit]
- Tang, Y.; Tong, Q. BordaRank: A ranking aggregation based approach to collaborative filtering. In Proceedings of the 2016 IEEE/ACIS 15th International Conference on Computer and Information Science (ICIS), Okayama, Japan, 26–29 June 2016. [Google Scholar]
- Shams, B.; Haratizadeh, S. IteRank: An iterative network-oriented approach to neighbor-based collaborative ranking. Knowl.-Based Syst. 2017, 128, 102–114. [Google Scholar] [CrossRef] [Scilit]
- Wang, S.; Huang, S.; Liu, T.-Y.; Ma, J.; Chen, Z.; Veijalainen, J. Ranking-oriented collaborative filtering: A listwise approach. ACM Trans. Inf. Syst. 2016, 35, 1–28. [Google Scholar] [CrossRef] [Scilit]
- Koskela, P. Comparing Ranking-Based Collaborative Filtering Algorithms To A Rating-Based Alternative in Recommender Systems Context. Master’s Thesis, University of Jyväskylä, Jyväskylän, Finland, 2017. [Google Scholar]
- Ardiansyah, M.I.; Adji, T.B.; Setiawan, N.A. Improved ranking based collaborative filtering using SVD and borda algorithm. In Proceedings of the 2019 International Conference of Artificial Intelligence and Information Technology (ICAIIT), Yogyakarta, Indonesia, 13–15 March 2019. [Google Scholar]
- Li, L.; Qin, S.; Guo, F. A listwise collaborative filtering based on Plackett-Luce model. In Proceedings of the 2017 3rd IEEE International Conference on Computer and Communications (ICCC), Chengdu, China, 13–16 December 2017. [Google Scholar]
- Lestari, S.; Adji, T.B.; Permanasari, A.E. WP-Rank: Rank aggregation based collaborative filtering method in recommender system. Int. J. Eng. Technol. 2018, 7, 193–197. [Google Scholar]
- Guan, X.; Li, C.T.; Guan, Y. Enhanced SVD for collaborative filtering. In Proceedings of the 20th Pacific-Asia Conference on Knowledge Discovery and Data Mining (PAKDD), Auckland, New Zealand, 19–22 April 2016. [Google Scholar]
- Guan, X.; Li, C.T.; Guan, Y. Matrix Factorization with Rating Completion: An Enhanced SVD Model for Collaborative Filtering Recommender Systems. IEEE Access 2017, 5, 27668–27678. [Google Scholar] [CrossRef] [Scilit]
- Pan, M.; Yang, Y.; Mi, Z. Research on An Extended SVD Recommendation Algorithm Based on User’s Neighbor Model. In Proceedings of the 2016 7th IEEE International Conference on Software Engineering and Service Science (ICSESS), Beijing, China, 26–28 August 2016. [Google Scholar]
- Xian, Z.; Li, Q.; Li, G.; Li, L. New Collaborative Filtering Algorithms Based on SVD++ and Differential Privacy. Math. Probl. Eng. 2017, 33, 2133–2144. [Google Scholar]
- Cui, L.; Huang, W.; Yan, Q.; Yu, F.R.; Wen, Z.; Lu, N. A novel context-aware recommendation algorithm with two-level SVD in social networks. Futur. Gener. Comput. Syst. 2018, 86, 1459–1470. [Google Scholar] [CrossRef] [Scilit]
- Sali, S. Movie rating prediction using singular value decomposition. Mach. Learn. Proj. Rep. 2008, 242, 1–8. [Google Scholar]
- Koren, Y.; Bell, R.; Volinsky, C. Matrix Factorization Techniques For Recommender Systems. Comput. (Long Beach Calif). 2009, 42, 30–37. [Google Scholar] [CrossRef] [Scilit]
- Ricci, F.; Rokach, L.; Shapira, B.; Kantor, P.B. Recommender Systems Handbook; Springer: NewYork, NY, USA, 2015; pp. 107–140. [Google Scholar]
- Albatayneh, N.; Ghauth, K.; Chua, F.-F. A Semantic Content-Based Forum Recommender System Architecture Based on Content-Based Filtering and Latent Semantic Analysis. Adv. Intell. Syst. Comput. 2014, 287, 369–378. [Google Scholar]
- Aggarwal, C. Recommender Systems; Springer: NewYork, NY, USA, 2016. [Google Scholar]
- Harper, F.M.; Konstan, J.A. The movielens datasets: History and context. ACM Trans. Interact. Intell. Syst. 2015, 5, 1–19. [Google Scholar] [CrossRef] [Scilit]
- Hazrati, N.; Shams, B.; Haratizadeh, S. Entity representation for pairwise collaborative ranking using restricted Boltzmann machine. Expert Syst. Appl. 2017, 116, 161–171. [Google Scholar] [CrossRef] [Scilit]
- Shams, B.; Haratizadeh, S. SibRank: Signed bipartite network analysis for neighbor-based collaborative ranking. Phys. A Stat. Mech. Its Appl. 2016, 458, 364–377. [Google Scholar] [CrossRef] [Scilit]
- Zhang, F.; Zhou, W.; Sun, L.; Lin, X.; Liu, H.; He, Z. Improvement of Pearson similarity coefficient based on item frequency. In Proceedings of the 2017 International Conference on Wavelet Analysis and Pattern Recognition (ICWAPR), Ningbo, China, 9–12 July 2017; Volume 1, pp. 248–253. [Google Scholar]
- Zhang, Q.; Ren, F. Prior-based bayesian pairwise ranking for one-class collaborative filtering. Neurocomputing 2021, 440, 365–374. [Google Scholar] [CrossRef] [Scilit]
- Jalili, M.; Ahmadian, S.; Izadi, M.; Moradi, P.; Salehi, M. Evaluating Collaborative Filtering Recommender Algorithms: A Survey. IEEE Access 2018, 6, 74003–74024. [Google Scholar] [CrossRef] [Scilit]
- Kherad, M.; Bidgoly, A.J. Recommendation system using a deep learning and graph analysis approach. arXiv 2020, arXiv:2004.08100. [Google Scholar] [CrossRef] [Scilit]
- Feng, J.; Fengs, X.; Zhang, N.; Peng, J. An improved collaborative filtering method based on similarity. PLoS ONE 2018, 13, e0206629. [Google Scholar]
- Wang, D.; Yih, Y.; Ventresca, M. Improving neighbor-based collaborative filtering by using a hybrid similarity measurement. Expert Syst. Appl. 2020, 160, 113651. [Google Scholar] [CrossRef] [Scilit]
- Liu, H.; Hu, Z.; Mian, A.; Tian, H.; Zhu, X. A new user similarity model to improve the accuracy of collaborative filtering. Knowl. -Based Syst. 2014, 56, 156–166. [Google Scholar] [CrossRef] [Scilit]
- Polatidis, N.; Georgiadis, C.K. A multi-level collaborative filtering method that improves recommendations. Expert Syst. Appl. 2016, 48, 100–121. [Google Scholar] [CrossRef] [Scilit]
- Lestari, S.; Adji, T.B.; Permanasari, A.E. Performance Comparison of Rank Aggregation Using Borda and Copeland in Recommender System. In Proceedings of the 2018 International Workshop on Big Data and Information Security (IWBIS), Jakarta, Indonesia, 12–13 May 2018. [Google Scholar]
- Guo, Z.; Zeng, W.; Wang, H.; Shen, Y. An Enhanced Group Recommender System by Exploiting Preference Relation. IEEE Access 2019, 7, 24852–24864. [Google Scholar] [CrossRef] [Scilit]
- Pujahari, A.; Sisodia, D.S. Aggregation of preference relations to enhance the ranking quality of collaborative filtering based group recommender system. Expert Syst. Appl. 2020, 156, 113476. [Google Scholar] [CrossRef] [Scilit]
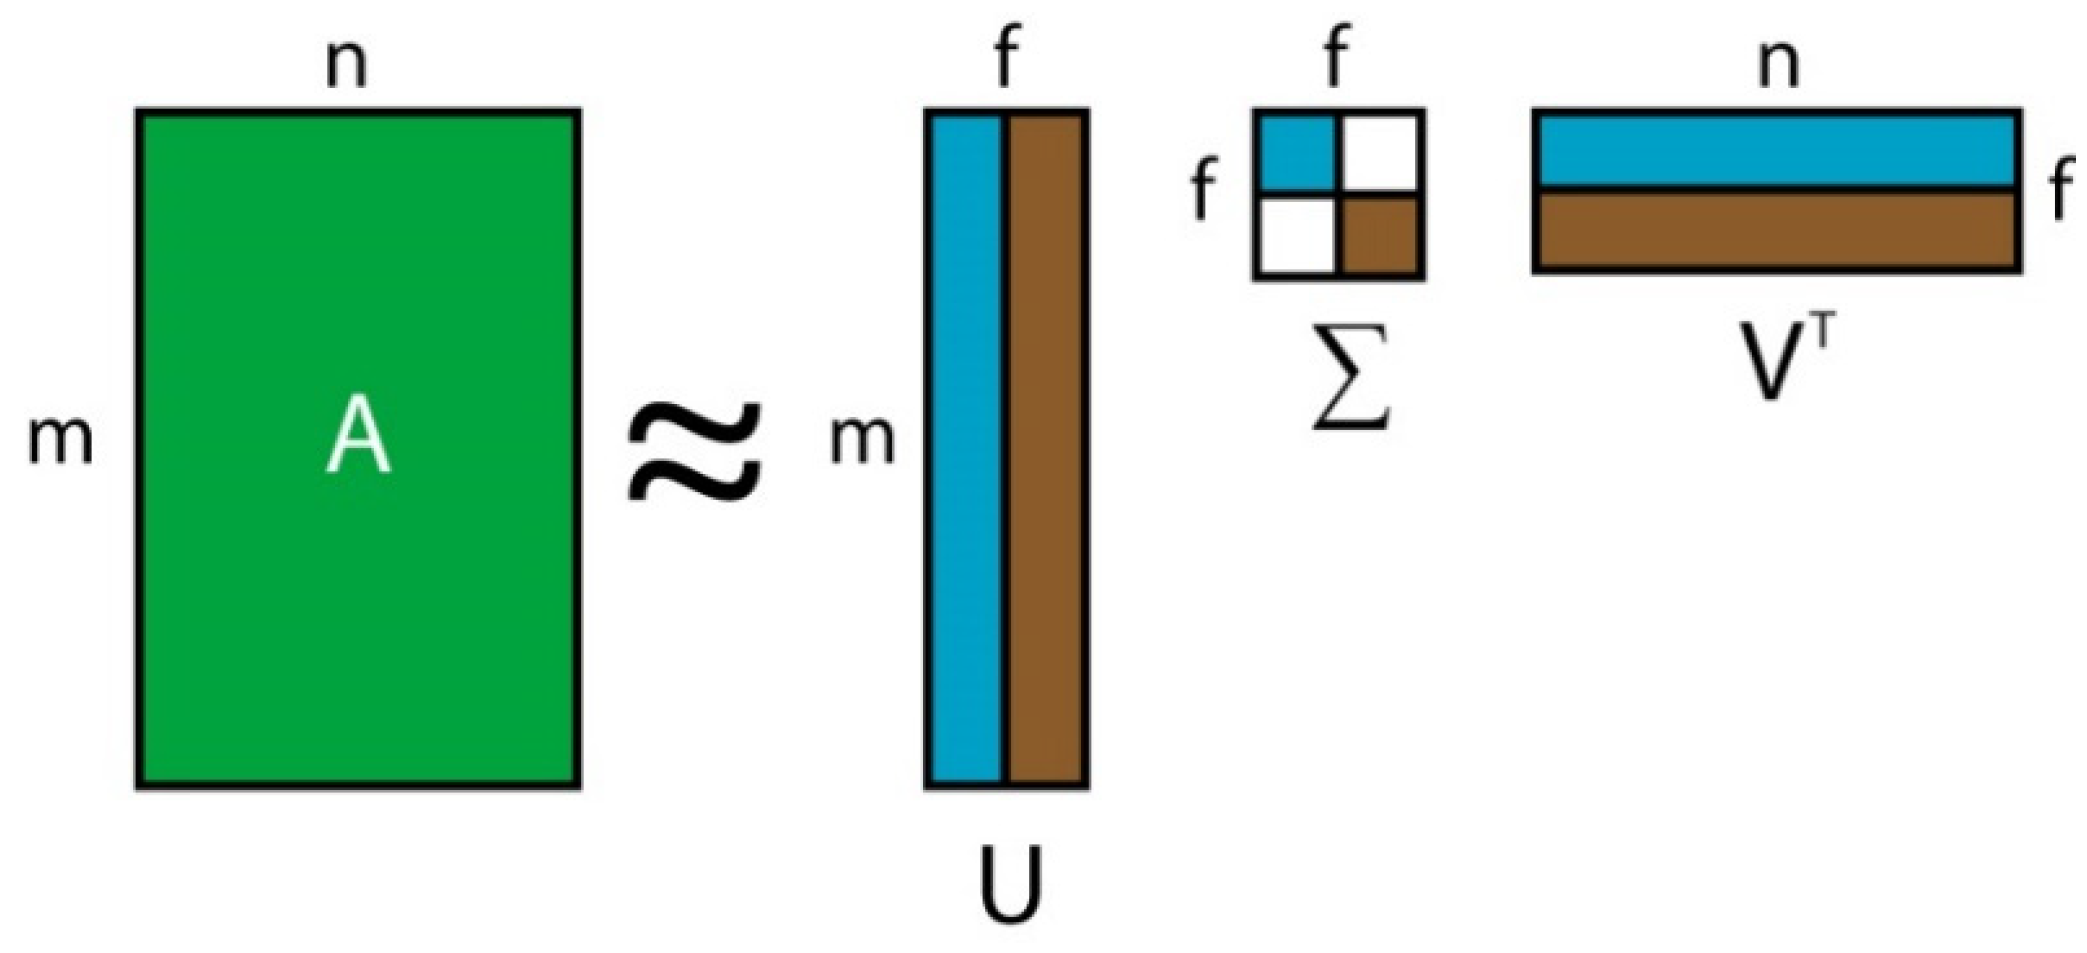

Publisher’s Note: MDPI stays neutral with regard to jurisdictional claims in published maps and institutional affiliations. |
© 2022 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).