


Abstract
Deep generative models trained on sensitive data pose significant privacy risks, yet enforcing differential privacy (DP) in high-dimensional generators often leads to severe utility degradation. We propose Differentially Private Vector-Quantized Generation (DP-VQG), a three-stage generative framework that introduces a discrete latent bottleneck as the interface for privacy preservation. DP-VQG separates geometric structure learning, differentially private discrete latent projection, and non-private prior modeling, ensuring that privacy-induced randomness operates on a finite codebook aligned with the decoder’s effective support. This design avoids off-support degradation while providing formal end-to-end DP guarantees through composition and post-processing. We provide a theoretical analysis of privacy and utility, including explicit bounds on privacy-induced distortion. Empirically, under the privacy budget of , DP-VQG attains Fréchet Inception Distance (FID) scores of 18.21 on MNIST and 77.09 on Fashion-MNIST, surpassing state-of-the-art differentially private generative models of comparable scale. Moreover, DP-VQG produces visually coherent samples on high-resolution datasets such as Flowers102, Food101, CelebA-HQ, and Cars, demonstrating scalability beyond prior end-to-end DP generative approaches.
Keywords:
generative models; differential privacy; discrete latent representations; vector quantization; exponential mechanism; discrete probability distributions MSC:
68T01; 68P27
1. Introduction
Deep generative models are increasingly deployed for data synthesis in privacy-sensitive domains such as medical imaging, biometrics, and personalized content generation. Their ability to model complex, high-dimensional data distributions, however, also raises serious privacy concerns. A growing body of work has shown that high-capacity generators may memorize training samples and enable membership inference or data extraction attacks, particularly in low-data or overparameterized regimes [1,2,3,4,5]. These risks highlight the need for principled privacy guarantees in generative modeling, beyond heuristic anonymization or ad hoc sanitization.
To illustrate the practical urgency of this issue, consider a real-life scenario in cross-institutional medical research. Hospitals often seek to share patient X-ray or MRI datasets to train robust diagnostic models. However, strict regulations (e.g., GDPR, HIPAA) prohibit sharing raw scans, and traditional de-identification methods (such as removing metadata or blurring faces) fail to obscure biometric markers embedded in bone structures or organ textures. In such cases, a privacy-preserving generative model can serve as a crucial enabler by synthesizing high-fidelity, anonymous cohorts that retain the statistical properties of pathologies without exposing the biometric identity of any specific patient. This necessitates a solution that offers rigorous, mathematically quantifiable privacy guarantees rather than relying on empirical obfuscation.
Differential Privacy (DP) has established itself as the de facto standard for privacy-preserving machine learning [6]. In contrast to heuristic techniques such as data anonymization or masking, which are prone to reconstruction attacks in high-dimensional feature spaces, DP offers a rigorous, information-theoretic guarantee against re-identification that remains robust to auxiliary knowledge and linkage attacks. Furthermore, DP satisfies the post-processing property [7]: any computation performed on the output of a DP mechanism incurs no additional privacy loss. This property is particularly instrumental for modular generative architectures, as it allows for the optimization of downstream components on sanitized representations without consuming further privacy budget.
In deep learning, the dominant approach to enforcing DP is Differentially Private Stochastic Gradient Descent (DP-SGD), which clips per-sample gradients and injects calibrated noise during optimization [8]. While DP-SGD has been successfully applied to discriminative models, its application to modern generative architectures remains highly challenging. High-dimensional generators typically require long training horizons and fine-grained signal reconstruction, both of which are acutely sensitive to gradient noise. As a result, end-to-end DP training often leads to severe degradation in sample quality and diversity in practice [9,10].
Existing approaches generally treat private generation as a monolithic task, applying noise uniformly across all model parameters. We argue that this strategy suffers from a fundamental representation—privacy mismatch. Modern latent generative models suggest that synthesis can be decoupled into two components: a universal “machinery” that reconstructs signal fidelity (e.g., textures, edges), and a specific “blueprint” that determines semantic content. Consider a biological analogy: the cellular machinery required to express proteins (e.g., ribosomes) is universal across a species, whereas the genetic code (DNA) is unique to the individual. In privacy-sensitive contexts, the “machinery” of generation, such as knowing how to render an eye or an organ structure, is often generic knowledge learnable from public proxies. The true privacy sensitivity lies in the “DNA”, which represents the specific combination of features that constitutes a private record. Current end-to-end methods effectively waste valuable privacy budget “encrypting the ribosome” alongside the DNA, rather than focusing protection solely where it is needed.
Complementing this semantic perspective, we adopt a geometric view grounded in the Manifold Hypothesis of representation learning [11]. This theory posits that high-dimensional data concentrate near a low-dimensional non-linear manifold embedded in the ambient space. Consequently, decoders are well-conditioned only in neighborhoods supported by this training manifold. When privacy mechanisms interact with continuous interfaces—for example, through noisy optimization trajectories, stochastic latent sampling, or direct perturbation of continuous representations—privacy-induced randomness can easily push the generative process away from these well-supported regions. In high-dimensional settings, even modest perturbations may force the decoder to extrapolate beyond its effective domain, resulting in blurry, unstable, or semantically incoherent samples [12]. We refer to this phenomenon as an off-support (or informally, off-manifold) failure mode. This contrast between continuous and discrete perturbation mechanisms is illustrated in Figure 1.
Figure 1.
Comparison of continuous and discrete latent perturbations under differential privacy.
In this work, we propose Differentially Private Vector-Quantized Generation (DP-VQG), a framework that leverages a discrete privacy bottleneck to resolve these challenges. By shifting privacy mechanisms from continuous parameters to a discrete code selection process, we decouple high-fidelity reconstruction from privacy-preserving semantic generation. This architecture supports two strategies: FP-VQG (Fully Private), which utilizes quantization to prevent off-manifold geometric drift even without public data, and PP-VQG (Public-Prior), which employs auxiliary data to learn the generative “machinery” cost-free, focusing the privacy budget entirely on the semantic “DNA”. Crucially, since the final high-capacity generator operates purely on sanitized discrete codes, it functions as a post-processing step that incurs no additional privacy cost while preserving sample quality.
The contributions of this paper are summarized as follows:
- We propose DP-VQG, a novel framework that integrates vector quantization with differential privacy. It introduces a discrete bottleneck that inherently resists off-manifold degradation and enables the efficient decoupling of universal features from private semantics.
- We provide a theoretical analysis of the privacy–utility trade-off, formalizing the error decomposition of discrete bottlenecks and proving that our approach avoids the high-dimensional distortion scaling typical of continuous mechanisms.
- Extensive experiments on standard image benchmarks demonstrate that DP-VQG significantly outperforms state-of-the-art end-to-end DP generative models in both sample fidelity and downstream utility.
The remainder of the paper is organized as follows. Section 2 reviews related work on differentially private generative modeling. Section 3 introduces background on differential privacy, vector quantization, and discrete mechanisms. Section 4 presents the DP-VQG framework and its theoretical analysis. Section 5 reports experimental results, and Section 6 concludes the paper.
2. Related Work
2.1. Generative Modeling Paradigms
Generative modeling has undergone several major paradigm shifts over the past decade. Early progress was dominated by Generative Adversarial Networks (GANs), which formulate data generation as a minimax game between a generator and a discriminator [13]. Despite their strong empirical performance, GAN-based models are known to suffer from training instability, mode collapse, and sensitivity to architectural and optimization choices, particularly in high-dimensional image domains.
To address these limitations, likelihood-based models such as autoregressive models and normalizing flows were proposed, offering exact or tractable likelihoods at the cost of restrictive architectural assumptions or sequential sampling procedures [14,15,16]. More recently, diffusion-based and score-based generative models have emerged as a dominant paradigm, replacing adversarial objectives with iterative denoising or score matching processes and achieving state-of-the-art sample quality across a wide range of modalities [17,18].
Alongside these model-centric advances, a parallel line of research has emphasized structured or two-stage generative architectures. Rather than modeling the data distribution directly in pixel space, these approaches first learn a compact representation via an autoencoder, tokenizer, or vector quantization module, and subsequently fit a generative prior over the latent space. Representative examples include variational autoencoders with expressive priors [19], vector-quantized generative models [20], latent diffusion models [21], and masked token-based generative models [22,23,24]. This decomposition separates representation learning from density estimation, leading to improved computational efficiency, modularity, and scalability.
The present work follows this multiple-stage generative modeling tradition by adopting a discrete latent interface learned through vector quantization. While prior work primarily motivates such architectures from a modeling or computational perspective, our focus is on how this structural decomposition can be exploited to support privacy-preserving generation under differential privacy constraints.
2.2. Differentially Private Generative Models
Research on Differentially Private Generative Models (DPGMs) have progressed from classical statistical synthesis toward modern neural generative frameworks.
Early privacy-preservation approaches often relied on heuristic techniques such as data anonymization (e.g., k-anonymity, l-diversity), data anatomization, or graph-based de-identification [25,26]. While these methods have proven effective for low-dimensional tabular or structured data, they are ill-suited for high-dimensional unstructured data such as images. For instance, graph-based notation is difficult to define for pixel grids without losing semantic integrity, and simple anonymization is vulnerable to linkage and reconstruction attacks when dealing with high-dimensional feature spaces. Consequently, Differential Privacy (DP) has emerged as the de facto standard for modern generative tasks. Unlike heuristic methods, DP offers a formal, information–theoretic bound on privacy leakage that is robust to post-processing and independent of an attacker’s background knowledge [6], making it the optimal choice for training deep generative models on sensitive distributions.
Building on DP principles, early work on private synthesis focused on estimating low-order statistics or structured distributions, such as marginals and Bayesian networks [27,28]. These methods offer strong theoretical guarantees and interpretability, but their expressiveness is limited when applied to complex perceptual data.
More recent studies have explored the use of expressive neural generators for private data synthesis. This line of work has been systematically reviewed in recent surveys, which organize existing methods by model family, privacy mechanism, and application domain [29]. From a broader perspective, these developments align with emerging theoretical views that regard randomized learning algorithms as a viable means of reconciling statistical performance with normative requirements such as privacy [30].
Within neural generative modeling, existing approaches can be broadly categorized by how differential privacy is enforced. One prominent class builds on the PATE framework [31], in which an ensemble of teacher models trained on disjoint data partitions provides privatized supervision to a student generator. This paradigm has been instantiated in several generative settings, including both tabular and image synthesis [32,33]. While effective in certain regimes, PATE-based methods often require large ensembles or auxiliary unlabeled data, which may limit scalability and practical deployment.
Another major category consists of generative models trained directly with differentially private stochastic gradient descent [8]. DP-SGD has been applied to a variety of architectures, including GANs and diffusion-based models [10,34,35]. Although this approach provides a general and principled privacy mechanism, its application to high-capacity generators frequently leads to a substantial degradation in sample quality under strict privacy budgets, due to the accumulation of noise across high-dimensional parameter spaces.
Beyond these dominant paradigms, a number of works explore alternative formulations of private generative modeling, including gradient sanitization strategies, functional mechanisms, and other hybrid approaches [36,37,38,39]. These methods illustrate the diversity of design choices in differentially private generation, but also highlight the lack of a unified structural principle for mitigating privacy-induced utility loss in complex generative models.
Recent work combines task aligned public pretraining with DP fine tuning to achieve strong generation quality [40]. This line of approaches typically assumes close alignment between public and private data distributions and is often tailored to image synthesis with caption conditioned pipelines, which introduces additional supervision requirements and a more complex multi stage procedure.
Our work builds on this line of research while adopting a distinct perspective. Instead of enforcing privacy solely through end-to-end optimization or ensemble-based supervision, we introduce a discrete latent bottleneck that separates privacy preservation from generative modeling. This representation-level decoupling complements existing DPGM approaches and provides an alternative pathway for improving the privacy–utility trade-off in high-dimensional data generation.
3. Preliminaries
In this section we introduce the mathematical background necessary for the analysis of our privacy-preserving generative framework. We review the formulation of differential privacy, the DP-SGD training mechanism, vector-quantized latent representations, and the exponential mechanism.
3.1. Differential Privacy
Let be the data domain, and let be two adjacent datasets differing in exactly one entry. A randomized mechanism satisfies -differential privacy if, for all measurable sets ,
The parameters and quantify the privacy guarantee: small and enforce indistinguishability of outputs between adjacent datasets.
A fundamental property of differential privacy is post-processing invariance: if is -DP, then for any deterministic mapping h, the composed mechanism is also -DP. Thus, once privacy is ensured by a mechanism, subsequent transformations of its outputs incur no additional privacy cost.
Another key property is sequential composition: if mechanisms and are applied in sequence, with being -DP and being -DP, then the composed mechanism is -DP. This result underlies our analysis of training-time DP and sampling-time DP mechanisms.
3.2. DP-SGD Training Mechanism
Let denote the parameters of a generative model, and let be a per-sample loss function. DP-SGD optimizes via iterative updates while ensuring differential privacy with respect to the dataset D. At iteration t, given a mini-batch , the per-sample gradients are clipped to a maximum norm , averaged, and perturbed with Gaussian noise:
The parameters are updated as
Using Rényi differential privacy (RDP) [41] or Privacy Random Variables (PRVs) [42] accounting, one can track the cumulative privacy loss across iterations and convert it into a final -DP guarantee for the mapping .
3.3. Generative Models and Latent Spaces
We consider generative models represented as measurable mappings
where is a latent space. The latent variable z may be sampled from a prior distribution or obtained from a deterministic encoder applied to some conditioning input. The specific architectural form of is not important for our analysis; in particular, may represent a feed-forward decoder, a normalizing flow, or the denoising trajectory of a diffusion sampler initialized from a latent vector.
The key structural assumption required for our privacy mechanism is that can operate on a finite set of latent codes, introduced below.
3.4. Vector-Quantized Latent Representations
Let be a finite codebook. Given a latent embedding , we define its quantization via the nearest-code assignment
The generator is trained to accept codes from as inputs, so that for any k, the image lies on a region of the data manifold consistent with training. This structure enables latent perturbation to be performed in a discrete space, which is essential for applying the exponential mechanism.
Vector-quantized representations provide a robust interface between continuous latent embeddings and finite code sets. Throughout this work, we assume the codebook has bounded diameter and is fixed during sampling.
3.5. The Exponential Mechanism
The exponential mechanism [43] is a fundamental tool for achieving differential privacy over discrete output spaces. Given a score function and privacy parameter , the mechanism selects an element with probability
where is the sensitivity of the score function:
The mechanism guarantees -DP under changes in its input z.
4. Methodology: The DP-VQG Framework
We propose Differentially Private Vector-Quantized Generation (DP-VQG), a three-stage framework that synthesizes high-fidelity samples under formal differential privacy (DP) guarantees. The core design principle is an operator-level decomposition of generation into (i) geometric structure learning and (ii) density modeling on a sanitized discrete bottleneck.
4.1. Formulation of Private Discrete Bottlenecks
4.1.1. PrivateData and Adjacency
Let denote the data domain and a private dataset. We adopt the standard record-level adjacency: two datasets are adjacent (denoted ) if they differ in exactly one record.
4.1.2. Mechanisms as (Random) Operators
Rather than learning via an end-to-end DP training of a high-dimensional generator, we model the overall release as a composition of three operators:
where denotes the data source used for structure learning. Concretely:
- 1.
- Structure learning : a (possibly randomized) training operator outputting parameters that define an encoder–decoder manifold and a codebook. We write , where is an encoder, a decoder, and a finite codebook.
- 2.
- Latent encoding : a randomized discrete projection that maps each private record to a code index (or code vector) in , producing a sanitized discrete latent dataset .
- 3.
- Prior modeling : a (non-private) learning operator that fits a generative model over and induces a sampler for discrete latents, followed by decoding through G.
This decomposition isolates privacy consumption to the releases ; any subsequent training or sampling based solely on is DP-preserving by post-processing.
4.1.3. Privacy Composition for Discrete Bottlenecks
We state a sufficient end-to-end condition via sequential composition and post-processing.
Lemma 1
(Privacy via Discrete Bottleneck Composition). Assume is -DP w.r.t. when . Conditioned on Θ, assume is -DP w.r.t. and releases . Then, any (possibly randomized) operator trained solely on yields an overall release that is -DP w.r.t. .
Proof.
By sequential composition, releasing and then yields -DP. Since accesses only , the post-processing property implies no additional privacy loss. □
4.1.4. Geometric Rationale: Anchoring on a Discrete Support
A key choice is the latent domain. Continuous DP mechanisms (e.g., Gaussian perturbation in ) often produce off-support latent inputs, where the decoder may be poorly conditioned. DP-VQG instead constrains the DP mechanism to output a valid code in the finite set .
Assumption 1
(Anchored Decoder Regularity). There exists such that the decoder is Lipschitz on the codebook support:
Under Assumption 1, any privacy-induced randomness that changes the selected code remains on-support and admits a controlled error propagation from latent distortion to reconstruction distortion.
4.2. Three-Stage Stochastic Instantiation
Figure 2.
The proposed DP-VQG framework. Privacy is consumed only when accessing : optionally in Stage I (FP-VQG) and necessarily in Stage II. Stage III operates solely on the sanitized latent dataset and is thus purely post-processing.
4.2.1. Stage I: Manifold Learning (Implementation of )
Stage I learns a discrete generative manifold through a VQ-VAE tokenizer, where the codebook induces a finite latent support on which all subsequent operations are constrained. A critical practical requirement for DP-VQG is that the decoder G remain stable under stochastic perturbations of code indices: downstream stages may not always recover the deterministic nearest-code assignment, and rare/inactive codes can lead to catastrophic decoding artifacts if they were never sufficiently exercised during training. Standard VQ-VAE training, however, is typically fragile in this respect because (i) it relies on deterministic top-1 nearest-neighbor assignments, which do not expose G to code mismatch, and (ii) it often yields highly imbalanced code usage, leaving a portion of the codebook weakly trained.
To explicitly improve robustness to discrete latent perturbations, we adopt a stochastic quantization scheme and a code-usage regularizer during tokenizer training.
Stochastic Top-k Code Assignment
Given an encoder feature map , we flatten spatial locations into vectors with . For each location, define squared distances to code vectors
During training, instead of using the deterministic nearest neighbor, we sample a code index from a temperature-controlled distribution. Let
where is a temperature. To reduce variance while preserving stochasticity, we optionally restrict sampling to the top-k nearest candidates: let be the set of k smallest-distance codes under , and sample
At evaluation time, we revert to deterministic quantization . This stochastic assignment can be viewed as discrete data augmentation: it trains the decoder to tolerate moderate code mismatch by exposing it to plausible alternative codes during training.
Entropy Regularization for Balanced Code Usage
To avoid degenerate solutions where only a small subset of codes is active, we encourage balanced utilization of the codebook. Let be the full soft assignment distribution in Equation (7), and define the batch-averaged usage distribution
We maximize the entropy (equivalently, minimize ), which favors a more uniform activation of codes and mitigates the risk of “dead” or rarely-used codes.
Training Objective
Let and be the (stochastically) quantized latent map produced by Equation (8). We optimize the tokenizer parameters via
where is the commitment weight, controls the entropy regularization strength, and is the stop-gradient operator. In practice, we implement Equation (8) using top-k sampling with a temperature and optimize Equation (10) with the straight-through estimator.
The above objective defines a generic procedure for learning a robust discrete manifold. Depending on whether the data used for structure learning contains private records, we consider two instantiations that differ only in the training protocol and privacy accounting of this stage.
Variant A: Fully Private VQG (FP-VQG). If , we train Equation (10) using DP-SGD to ensure -DP for releasing . Since the Exponential Moving Average (EMA) codebook updates bypass per-sample gradient clipping/accounting, we optimize the codebook embeddings via explicit gradients so that all updates are tracked by the privacy accountant.
Variant B: Public-Prior VQG (PP-VQG). If a public dataset is available with , we train Equation (10) on using standard SGD, incurring zero privacy cost w.r.t. (i.e., ).
The two instantiations of Stage I are designed to address complementary data regimes. FP-VQG provides a fully self-contained solution with end-to-end differential privacy guarantees and is particularly suitable for small- to medium-scale datasets whose distributions differ substantially from available public data. In contrast, PP-VQG leverages auxiliary public datasets to learn generic visual structures and low-level statistics without privacy constraints, introducing differential privacy only when modeling the distributional characteristics specific to the private dataset. This separation is especially advantageous for high-dimensional and complex data, as it avoids the excessive noise and blurring effects that can arise when training the encoder–decoder components under DP-SGD in FP-VQG, while still ensuring rigorous privacy protection for sensitive distributional information.
4.2.2. Stage II: DP Discrete Projection via the Exponential Mechanism (Implementation of )
We freeze and encode through an -DP discrete projection operator.
Bounded Representation
To ensure bounded utility sensitivity, we define the -ball projection and use
Then, and for all k.
Utility and Sensitivity
We set the utility
Since , we have and hence, the global sensitivity satisfies
DP Discrete Projection Operator
Define by the exponential mechanism:
Applying independently to each record yields a discrete latent dataset (indices or code vectors). We denote this record-wise randomized encoding as .
It is worth noting that our privacy guarantee is defined at the record level: the encoding mechanism takes one private record x and release its entire discrete latent representation (a code index map in or the corresponding code vectors) as a single DP output. In practice, this can be implemented either (i) as a joint exponential-mechanism release over the whole code map, or (ii) by distributing the total budget across spatial locations so that the overall release remains -DP for each record. Throughout the paper, the reported refers to this total record-level privacy budget.
Lemma 2
(DP of the Exponential-Mechanism Quantizer). With utility Equation (11) and sensitivity bound Equation (12), the operator defines an -DP record-level mechanism that maps a single private record x to its entire discrete latent representation. Consequently, releasing satisfies -DP under record-level adjacency, where denotes the total privacy budget for the record-level encoding release.
Proof.
This follows directly from the standard guarantee of the exponential mechanism with sensitivity . We emphasize that is defined at the record level: it releases the entire discrete latent representation associated with one record as a single DP output. Practical implementations may realize this operator by composing multiple location-wise mechanisms, but such implementations are calibrated to satisfy the same overall record-level guarantee. □
Geometric Interpretation: Soft Voronoi Tessellation
Deterministic VQ partitions into Voronoi cells; Equation (13) induces a Gibbs distribution over cell candidates, yielding a softening of boundaries that masks the precise location of , as shown in Figure 3.
Figure 3.
Comparison of deterministic vs. probabilistic latent quantization. The background colors visualize the decision regions.
4.2.3. Stage III: Masked Generative Modeling on Sanitized Latents (Implementation of )
Stage III learns a generative prior over the sanitized discrete lattice and is purely post-processing.
Let each latent map be , and let M denote a special mask token with index . We discretize time into with a masking schedule (cosine in our implementation). Define the forward corruption kernel as an i.i.d. masking process:
Equivalently, for each site , we sample and set
We parameterize using a bidirectional Transformer that outputs token probabilities at masked sites. The training objective minimizes the masked negative log-likelihood:
Since is DP, optimizing Equation (16) incurs no additional privacy cost.
Inference as an Iterative Reconstruction Map
We initialize as fully masked and iterate S steps. At step s, the model predicts token probabilities for all masked sites; a confidence score (e.g., maximum probability) determines which sites are fixed and which remain masked, following a decreasing remasking schedule aligned with .
Computational Remark
Each inference iteration evaluates the Transformer once on an -length sequence; hence, the sampling complexity scales as , where depends on the Transformer architecture (typically quadratic or linear-time variants in sequence length).
The overall training pipeline, which integrates these three stages to enforce end-to-end differential privacy, is formally outlined in Algorithm 1.
| Algorithm 1 Differentially Private Vector-Quantized Generation (DP-VQG) | |
| Require: Private dataset , public dataset (optional), budgets , codebook size K, temperature . | |
| Ensure: Generative prior , Tokenizer . | |
| 1: Stage I: Robust Manifold Learning | |
| 2: Initialize tokenizer | |
| 3: if Variant is FP-VQG (No public data) then | |
| 4: , Optimizer ← DP-SGD | ▹ Private training |
| 5: else | ▹ PP-VQG (Public Prior) |
| 6: , Optimizer ← Standard SGD | ▹ Zero privacy cost |
| 7: end if | |
| 8: while not converged do | |
| 9: Sample batch | |
| 10: Compute latents and distances | |
| 11: Sample restricted to Top-k | ▹ Stochastic Sampling |
| 12: | ▹ Entropy Reg. (Equation (10)) |
| 13: Update using selected Optimizer | |
| 14: end while | |
| 15: Stage II: DP Discrete Projection | |
| 16: Freeze , initialize sanitized dataset | |
| 17: for each record do | |
| 18: | ▹ Bounded embedding |
| 19: Define utility | |
| 20: Sample | ▹ Exp. Mechanism (Equation (13)) |
| 21: Add to | |
| 22: end for | |
| 23: Stage III: Prior Modeling (Post-Processing) | |
| 24: Initialize Masked Transformer | |
| 25: while not converged do | |
| 26: Sample sanitized latents | |
| 27: Generate masked input | |
| 28: Update minimizing NLL | ▹ Equation (16) |
| 29: end while | |
| 30: return Generator | |
4.3. Theoretical Privacy Analysis and Error Bounds
4.3.1. Privacy Guarantees for Instantiation Variants
We restate end-to-end privacy guarantees as corollaries of Lemmas 1 and 2.
Proposition 1
(Privacy of FP-VQG). If Stage I is -DP (e.g., DP-SGD on ) and Stage II uses , then the overall FP-VQG release is -DP.
Proof.
Stage II is pure -DP (Lemma 2), and Stage III is post-processing; hence, Lemma 1 yields -DP. □
Proposition 2
(Privacy of PP-VQG). If Stage I is trained on with (thus w.r.t. ), and Stage II uses , then PP-VQG is -DP w.r.t. .
Proof.
Stage I is independent of . The only access to is Stage II, which is pure -DP. Stage III is post-processing. □
4.3.2. Utility Analysis of the Discrete Barrier
A key advantage is the scaling of privacy-induced distortion. Continuous Gaussian perturbation typically yields , while discrete selection yields only logarithmic dependence on K.
Theorem 1
(Expected Utility Loss of Discrete Selection). Let be the optimal code associated with record , and let be selected by Equation (13) with . Then, the expected excess squared latent distortion satisfies
Proof.
The proof relies on the fundamental utility analysis of the exponential mechanism. Let denote the set of possible outcomes (code indices). The mechanism selects an outcome with probability proportional to .
A standard result in differential privacy [6] states that for the exponential mechanism, the expected difference between the optimal utility and the utility of the selected element is bounded by:
Substituting our specific utility definition: The optimal utility is . The utility of the selected element is .
Therefore, the expected utility loss corresponds exactly to the expected excess distortion:
We derived the global sensitivity bound in the previous section. Substituting and into the standard bound yields:
This completes the proof. □
The bound in Theorem 1 characterizes the distortion introduced purely by the differentially private discrete projection, and in particular, isolates the effect of the codebook size K on the DP-induced selection noise. In practice, however, the choice of K also affects the intrinsic representational capacity and quantization accuracy of the tokenizer itself. To bridge this gap between the formal DP analysis and practical design, we consider the following representation-level distortion proxy.
Practically, the term implies an explicit design trade-off when choosing the codebook size. Increasing K improves the representational granularity and typically decreases the deterministic quantization error (i.e., the geometric approximation term induced by nearest-code assignment). Meanwhile, under a fixed record-level budget , the DP discrete projection contributes an additional distortion upper-bounded by Theorem 1. This suggests using the following representation-level distortion proxy to interpret the dependence on K:
The first term typically decreases with K, whereas the second term increases with , which predicts a non-monotonic dependence on K. We emphasize that is introduced only as an explanatory proxy (not as a new bound on the end-to-end error) to highlight the competing effects of representation capacity and privacy-induced selection distortion.
Corollary 1
(Record-Level Reconstruction Error under Anchored Regularity). Under Assumption 1 (Anchored Decoder Regularity), the corresponding expected excess reconstruction distortion is bounded as:
Proof.
By Assumption 1, the decoder G is -Lipschitz continuous on the codebook support . This implies that for any two code vectors , the distance in the data space is bounded by the distance in the latent space:
Squaring both sides preserves the inequality since the norms are non-negative:
Let (the selected code) and (the optimal code). Taking the expectation over the randomness of the privacy mechanism :
To rigorously bound the latent distance , we employ the triangle inequality relative to the projected embedding . Using :
Taking expectations on both sides and substituting the bound from Theorem 1 (which states ):
Here, the first term represents the quantization error, and the second term represents the privacy-induced error. In the regime where privacy noise dominates quantization error, the bound is controlled by the term. □
Increasing codebook richness (K) incurs only a logarithmic penalty, contrasting the linear-in-d scaling typical for continuous Gaussian perturbation.
In theoretical analysis, acts as a hard clipping operator. However, to ensure numerical stability and avoid information loss from post-hoc clipping, our practical implementation structurally enforces this constraint. We modify the final layer of the encoder to include a bounding activation (e.g., -normalization or tanh). For instance, applying -normalization ensures (implying ), or using tanh ensures . This architectural constraint guarantees that the sensitivity bound is always satisfied by design, stabilizing the differential privacy accounting.
4.3.3. End-to-End Distributional Error Decomposition
We characterize how the discrepancy between the data distribution and the generated distribution can be decomposed into (i) representation-induced geometric approximation, (ii) distortion introduced by the differentially private discrete projection, and (iii) prior modeling error.
Let denote a random data point from the underlying population distribution on , and let its latent representation be understood at the record level. Define the projected embedding and the projected codebook with . Let
denote the deterministic nearest-code representation. Let be the index selected by the differentially private projection in Stage II, and let denote the corresponding embedded latent representation. Finally, let denote the distribution on induced by the learned prior , and let and denote the distributions of and , respectively.
Proposition 3
(Distributional Error Decomposition in ). Assume and that the projected codebook is bounded. Let be the generated distribution obtained by sampling and decoding . Under Assumption A1, the Wasserstein-2 distance satisfies
Moreover, the distortion introduced by the DP projection admits the bound
Proof.
The decomposition in Equation (19) follows from the triangle inequality in the Wasserstein-2 distance. By Assumption 1, the decoder G is -Lipschitz on the support of . Hence, for any distributions P and Q on ,
To bound , we consider the coupling induced by sampling and generating via nearest-code assignment and the DP projection applied to the same X. This yields
Using with , we obtain
By Theorem 1,
Substituting into Equation (23) gives
Proposition 3 separates the distributional discrepancy induced by the discrete DP projection from the geometric approximation determined by the learned representation and the modeling error of the non-private prior. Only the middle term depends explicitly on the privacy budget .
4.4. Computational Complexity
We analyze the asymptotic time complexity of the proposed framework to demonstrate its scalability. The computational cost is dominated by the three processing stages, all of which operate in polynomial time with respect to the input dimensions.
- Stage I (Tokenizer): The VQ-VAE relies on standard convolutional operations. For an input of size , the encoding cost scales as . The stochastic code selection adds a term , which is linear in the number of pixels.
- Stage II (DP Projection): The exponential mechanism computes utility scores for all K codes for each record. For a dataset of N samples, this step scales as , which is linear in both dataset size and resolution.
- Stage III (Prior): The Transformer prior employs self-attention, scaling quadratically with the latent sequence length . The complexity is . Since L is fixed by the downsampled latent resolution (e.g., or of pixel resolution), this remains highly efficient for standard image benchmarks compared to pixel- space autoregression.
5. Experiments
In this section, we provide an extensive empirical evaluation of the proposed DP-VQG framework.
5.1. Experimental Setup
5.1.1. Datasets
We evaluate our method on a diverse set of benchmarks. First, we use three standard datasets to compare against existing baselines:
- MNIST [44]: A dataset of 70,000 grayscale handwritten digits (), serving as a baseline for mode coverage.
- Fashion-MNIST [45]: A dataset of 70,000 grayscale images of clothing items (), testing the capture of structural details.
- CIFAR-10 [46]: A dataset of 60,000 color images () across 10 classes, representing a challenging scenario due to high variance.
Additionally, to demonstrate the scalability of DP-VQG to high-resolution image generation, we conduct experiments on CelebA-HQ [47], Oxford 102 Flowers [48], Food-101 [49] and Stanford Cars [50].
5.1.2. Evaluation Metrics
To quantitatively assess the performance, we employ the following metrics:
- Fréchet Inception Distance (FID): Measures the distance between the distribution of real and synthetic images in the feature space of an Inception-V3 network. Lower FID indicates better image quality and diversity. We compute FID using the clean-fid [51] library in Python 3.12.3.
- Inception Score (IS): Evaluates the clarity and diversity of generated images by measuring the KL-divergence between the conditional class distribution and the marginal class distribution. Consistent with prior work in this domain, we compute IS using specific CNN classifiers trained on the respective original training datasets, rather than the standard ImageNet-pretrained network.
- Downstream Classification Accuracy (Acc): We train a standard two-layer CNN classifier on the synthetic data generated by our method and evaluate it on the real test set. Higher accuracy indicates better preservation of semantic utility.
5.1.3. Baselines
We compare DP-VQG against several state-of-the-art differentially private generative models:
- DP-GAN [9]: A differentially private Generative Adversarial Network trained with DP-SGD.
- G-PATE [33]: A PATE-based approach that trains a student generator by aggregating private gradients from an ensemble of teacher discriminators.
- DP-Merf [52]: A method utilizing random feature representations of kernel mean embeddings to enforce differential privacy with analytic sensitivity guarantees.
- GS-WGAN [36]: Gradient-Sanitized Wasserstein GAN, a robust DP-GAN variant.
- DataLens [53]: A scalable generative framework utilizing the TopAgg mechanism for compressive gradient aggregation to handle high-dimensional data within a PATE-like setting.
- DP-Sinkhorn [37]: An optimal transport-based method that minimizes the Sinkhorn divergence under privacy constraints, avoiding adversarial training instability.
- PEARL [54]: A framework employing characteristic functions for one-shot data sanitization, allowing model training without iterative privacy budget degradation.
- DP-LFlow [35]: A flow-based model that performs generation in a lower-dimensional latent space to enable effective DP training on high-dimensional images.
- DPDM [10]: A standard DDPM trained directly on pixel space using DP-SGD. Due to its significantly larger model size and computational costs compared to other baselines, we exclude it from comparisons on MNIST and Fashion-MNIST for fairness.
5.1.4. Implementation Details
We implement DP-VQG using PyTorch 2.7.0 and Opacus 1.5.4 [55] for differential privacy accounting. All experiments are conducted on NVIDIA A100 GPUs. The specific hyperparameters and architectural choices are detailed below to ensure reproducibility.
Privacy Settings
For all privacy-preserving experiments, we fix the target privacy parameter and vary the total budget to analyze the privacy–utility trade-off. Privacy costs are tracked using the PRVs [42] accountant. For FP-VQG, the total privacy budget is explicitly split between Stage I and Stage II. In all reported experiments, we allocate the budget in a fixed ratio of = 4:1 (allocating 80% to structure learning and 20% to discrete projection). This asymmetric design is theoretically grounded in the robustness of disentangled representations [56]. We invest the majority of the budget in Stage I to ensure the learning of a high-fidelity semantic manifold, as the quality of the manifold support is critical for generalization [11]. Once a robust geometry is established, the discrete latent space naturally performs semantic clustering [20], making the representation tolerant to local perturbations. This geometric robustness allows Stage II to operate effectively, even under the higher noise levels implied by the lower budget share, preventing the signal degradation typical of continuous DP mechanisms.
Stage I: Structure Learning and Tokenizer
The VQ-VAE consists of a lightweight encoder–decoder network enhanced with Residual Blocks. To align with the theoretical requirements of the exponential mechanism, we enforce specific architectural constraints:
- Sensitivity Control (R): To satisfy the boundedness requirement used in Stage II and in the sensitivity bound of Equation (12), we explicitly enforce an -ball constraint on both encoder embeddings and codebook vectors, i.e., and . Concretely, for any latent vector (including each spatial token embedding output by E and each codebook entry ), we apply the deterministic projectionwith a small for numerical stability (which is set to ), and use and in Stage II. This guarantees and thus deterministically bounds the global sensitivity of the utility in Equation (11) by . We treat R as a dataset-dependent hyperparameter and set it to the 99-th percentile of the empirical norms of the encoder token embeddings on the training data (and enforce the same bound for the learned codebook).
- Stochastic Quantization: During training, we employ stochastic top-k sampling with and a Gumbel-Softmax temperature of . This stochasticity prevents the decoder from overfitting to deterministic codes.
- Loss Weights: We set the commitment loss weight to and the entropy regularization weight to to encourage high codebook utilization.
- Hyperparameters: We use a codebook size of across all datasets. The latent dimension is set to for MNIST/Fashion-MNIST, for CIFAR-10 and for other high-resolution datasets.
For FP-VQG, we train the VQ-VAE from scratch on the private dataset using DP-SGD. We use a batch size of 256 and a learning rate of 1 ×. Crucially, we disable standard Exponential Moving Average (EMA) updates for the codebook and instead optimize the embeddings via explicit gradients to ensure valid privacy tracking.
For PP-VQG, we train a custom high-capacity VQGAN on the public imagenet [57] dataset using standard SGD (). Unlike off-the-shelf pre-trained models, this implementation strictly incorporates our specific architectural constraints to ensure compatibility with the privacy accounting in Stage II. Furthermore, leveraging the absence of privacy constraints in this stage, inspired by taming-transformers [58], we augment the training with a patch-based adversarial discriminator and perceptual loss to maximize geometric fidelity and sharpness before private data encoding.
Stage II: DP Discrete Projection
We freeze the encoder E and codebook . For each private record , we compute the utility scores for all , and sample the discrete code index using the exponential mechanism with sensitivity . This stage consumes the allocated privacy budget .
In practice, the latent representation is a spatial grid of discrete tokens. We instantiate the exponential mechanism independently at each spatial location and account for the resulting privacy loss using Privacy Random Variable (PRV) composition [42]. We calibrate the per-location mechanisms using PRVs such that their composed privacy loss matches the target record-level budget , following standard practice. All privacy budgets reported in the experiments refer to this final record-level guarantee. The detail parameters are shown in Table 1.
Table 1.
Token grid sizes and privacy accounting for Stage II.
Stage III: Masked Generative Modeling
We employ a MaskGIT-based [22] bidirectional Transformer as the generative prior trained via Masked Visual Token Modeling (MVTM). To adapt to the varying complexity of different datasets, we scale the Transformer architecture and training configurations accordingly. These dataset-specific hyperparameters are summarized in Table 2. Across all experiments, we use a cosine learning rate schedule decaying from to , and the inference sampling steps are fixed at .
Table 2.
Hyperparameters for Stage III (Masked Generative Modeling) across different datasets. The Transformer architecture is detailed in terms of embedding dimension (), number of layers (L), and attention heads (h).
5.2. Main Results: Quality and Utility
Table 3 summarizes the quantitative performance on MNIST and Fashion-MNIST under a moderate privacy budget (). Across both datasets, DP-VQG consistently outperforms prior DP generative models, including GAN-based approaches (e.g., DP-GAN, GS-WGAN) and flow-based methods such as DP-LFlow. On MNIST, our method achieves an FID of 18.21, improving upon DP-LFlow by a substantial margin and attains downstream classification accuracy close to that obtained from real data.
Table 3.
Quantitative comparison on MNIST and Fashion-MNIST under privacy budget , . We report Fréchet Inception Distance (FID ↓), Inception Score (IS ↑), and Downstream Accuracy (Acc ↑). Bold indicates the best privacy-preserving performance.
We note that some baseline results are taken from their respective publications and may follow slightly different evaluation protocols; these numbers are therefore used as reference points rather than strict, protocol-matched comparisons. Nevertheless, the overall performance gap is consistent with the visual comparisons in Figure 4, indicating that discrete latent projection preserves fine-grained structure more effectively than pixel-space perturbation under the same privacy budget.
Figure 4.
Qualitative comparison of generated samples across four benchmarks under formal privacy constraints ( = 10.0). Baseline samples are sourced from their respective original publications for fair comparison. On standard grayscale datasets (MNIST and Fashion-MNIST), our FP-VQG generates samples with higher realism and structural fidelity compared to prior arts. On challenging high-dimensional datasets (CIFAR-10 and CelebA), where existing methods typically suffer from severe blurring or noise, our PP-VQG significantly outperforms baselines, breaking the quality barrier to produce sharp, high-fidelity images with coherent semantics.
Beyond generative fidelity, DP-VQG demonstrates exceptional semantic preservation. On MNIST, the downstream classification accuracy reaches 97.22%, closely approaching the upper bound of real data (99.4%) and surpassing the previous best by a clear margin. Even on the more structurally complex Fashion-MNIST dataset, our method maintains this advantage, achieving an FID of 77.09 and an accuracy of 81.7%. These results indicate that the discrete codebook in Stage I effectively captures and preserves class-discriminative features, ensuring high data utility while robustly managing differential privacy noise.
5.3. Privacy–Utility Trade-Off Analysis
To comprehensively evaluate the robustness of DP-VQG under varying privacy constraints, we conduct a sensitivity analysis on MNIST and Fashion-MNIST by sweeping the privacy budget from strict () to relaxed () settings, while fixing . Figure 5 illustrates the Fréchet Inception Distance (FID) trends compared against state-of-the-art baselines.
Figure 5.
FID comparison under different privacy budgets . (Left) MNIST. (Right) Fashion-MNIST.
The results demonstrate that DP-VQG consistently maintains the lowest FID scores across the entire privacy spectrum, exhibiting exceptional robustness in high-privacy regimes. Specifically, at extremely low privacy budgets (), traditional GAN-based methods (e.g., DP-GAN, GS-WGAN) suffer from severe mode collapse, resulting in FID scores exceeding 300. In contrast, our method effectively disentangles privacy preservation from generative quality via the latent codebook, maintaining FID scores below 100 even at . Furthermore, while the competitive baseline DP-LFlow shows strong performance at higher budgets, our DP-VQG demonstrates faster convergence to optimal utility. As observed in the curves, our performance gain is most pronounced in the strict privacy interval, after which the FID metric stabilizes around , suggesting that our model is highly budget-efficient and can generate high-fidelity samples without requiring excessive privacy costs.
5.4. High-Resolution Image Synthesis with Public Priors
Existing differentially private generative models struggle to scale to high-resolution image synthesis, as protecting high-dimensional pixel or continuous latent representations requires injecting excessive noise, often leading to severe perceptual degradation.
We address this challenge with the PP-VQG variant, which leverages a public VQGAN pre-trained on ImageNet as a strong perceptual prior. By decoupling low-level visual representation from semantic and compositional modeling, PP-VQG restricts privacy-sensitive learning to the discrete latent code space. Differential privacy is applied only to the selection of discrete codes, while the encoder and decoder—responsible for encoding and rendering general visual primitives—are trained entirely on public data.
Figure 6 presents qualitative samples generated under a moderate privacy budget of on five datasets, CIFAR-10, Oxford-102 Flowers, Food-101, CelebA-HQ, and Stanford Cars, all synthesized at a resolution of . Across these diverse domains, PP-VQG produces visually coherent and photorealistic images, preserving global structure and fine-grained details.
Figure 6.
Images synthesized by PP-VQG under using a VQGAN pre-trained on ImageNet. All datasets are synthesized at a resolution of , except for CIFAR-10, which is generated at its native resolution of .
The robustness of PP-VQG to privacy noise stems from its discrete latent formulation. Since privacy perturbations affect only code selection, errors primarily manifest as localized structural or compositional deviations, while overall perceptual quality remains stable. This contrasts with pixel-space DP models, where noise directly corrupts continuous representations and often results in global blurring.
Table 4 reports FID and Kernel Inception Distance (KID) [59] scores under on a set of higher-resolution datasets. At this resolution, these metrics serve primarily as coarse distributional references rather than definitive indicators of sample quality, as quantitative evaluation under differential privacy is rarely reported beyond low-resolution benchmarks. Existing DP generative models are typically restricted to or images, for example, DPDM [10] reporting an FID of 97.7 on CIFAR-10 and 78.3 on CelebA downsampled to , or DP-LFlow [35] exhibiting substantially higher FID values at comparable scales. In contrast, our results show that DP-VQG remains stable when applied to datasets, producing coherent samples while maintaining formal privacy guarantees. These experiments highlight the scalability of discrete latent projection under differential privacy, complementing the low-resolution quantitative gains reported earlier.
Table 4.
Quantitative evaluation of samples generated by PP-VQG under a formal differential privacy constraint with privacy budget . Lower FID and KID indicate better generative quality.
While PP-VQG leverages a public dataset to learn the encoder–decoder and codebook, the resulting tokenizer is lightweight compared to end-to-end DP generative baselines. In particular, the model size and training cost of our public VQGAN tokenizer are substantially smaller than pixel-space DP diffusion models such as DPDM [10], which require large-scale models and multi-GPU training even on low-resolution datasets. In practice, PP-VQG enables fast single-GPU training for downstream private datasets once the public tokenizer is learned.
Overall, these results demonstrate that PP-VQG enables practical high-resolution image synthesis under differential privacy by exploiting public visual priors and shielding low-level visual representations from privacy noise.
5.5. Parameter Experiments
We investigate the effect of the codebook size K on generative performance under a fixed privacy budget. Figure 7 reports the Fréchet Inception Distance (FID) obtained with different values of K, while keeping all other components of DP-VQG unchanged, including the privacy parameter , the tokenizer training protocol, and the generative prior.
Figure 7.
Effect of codebook size K on FID under a fixed privacy budget . (Left) MNIST. (Right) Fashion-MNIST.
As K increases from small values, the generation quality improves substantially. This regime reflects the benefit of a richer discrete representation: a larger codebook enables a finer partition of the latent space and reduces the intrinsic quantization error, leading to more accurate geometric approximation of the data manifold. However, beyond an intermediate range, further enlarging the codebook results in degraded performance.
This non-monotonic behavior is consistent with our theoretical analysis. On the one hand, increasing K improves the deterministic nearest-code approximation and thus reduces the geometric error term in the end-to-end decomposition. On the other hand, under a fixed privacy budget, the expected distortion introduced by the differentially private discrete projection scales logarithmically with K. When K becomes too large, this privacy-induced selection noise dominates the representation gain, leading to a degradation in generation quality.
We further note that the optimal range of K is closely related to the intrinsic complexity of the underlying dataset. Datasets with low visual diversity and simple geometric structure such as MNIST can be well represented with a relatively small codebook, as the geometric approximation error is already small. In contrast, datasets with richer visual diversity and higher-dimensional latent manifolds require larger K to adequately capture the underlying structure and suppress quantization artifacts. However, for any fixed privacy budget , excessively increasing K inevitably amplifies the DP-induced selection distortion through the logarithmic term, which limits the practically optimal codebook size even for complex datasets.
Overall, these results reveal a clear trade-off between representation capacity and privacy robustness, and highlight the importance of choosing an appropriate codebook size that balances geometric fidelity with the stability of private discrete selection. In practice, we select K by jointly monitoring the tokenizer reconstruction error and the effective codebook utilization under the target privacy budget, choosing the smallest K that sufficiently suppresses quantization artifacts while avoiding the regime where privacy-induced selection noise dominates.
5.6. Ablation Study and Robustness Analysis
5.6.1. The “Privacy–Fidelity Gap” in Continuous Latent Spaces
To examine the effect of where privacy noise is injected, we construct a controlled comparison between continuous and discrete latent perturbations. Both variants share the same encoder–decoder architecture, latent dimensionality, and privacy budget; the only difference lies in whether noise is applied directly to continuous latent vectors or to discrete code selection. This comparison is not intended to represent all continuous DP generative methods, but rather to isolate the practical impact of noise placement under an otherwise matched setup.
We conducted a “stress test” by relaxing the privacy budget from strict () to non-private levels (1000). As visualized in Figure 8, the continuous baseline suffers from a “signal drowning” effect. At standard privacy budgets (), the reconstruction is dominated by noise, resulting in unrecognizable outputs. Remarkably, the continuous model requires an impractical budget of to produce recognizable digits. In sharp contrast, our DP-VQG achieves high-fidelity reconstruction with sharp structural details at a strict budget of . These results indicate that, under this controlled setting, discrete latent projection provides greater robustness to privacy noise than direct perturbation of continuous latents.
Figure 8.
Reconstruction results on the MNIST dataset with different perturbation strategies on latent representations. Using a DP-trained VQ-VAE (), the comparison highlights the superior robustness of discrete codebook selection (b) over continuous noise injection (a).
5.6.2. Component Analysis of Robust Discrete Representation
We perform a component-wise ablation study to verify the necessity of the two mechanisms introduced in our robust tokenizer: Stochastic Code Sampling and Entropy Regularization. We aim to disentangle their individual contributions towards mitigating the noise sensitivity of the discrete bottleneck. Table 5 summarizes the FID scores on MNIST and Fashion-MNIST under a fixed privacy budget (). We compare four variants of the tokenizer training strategy against a non-private reference baseline.
Table 5.
Ablation study of robust tokenizer components on MNIST and Fashion-MNIST. We report FID scores (lower is better) under the same differential privacy budget. The first row provides a non-private reference (lower bound) using our robust model with deterministic code selection. The symbols 3 and 7 denote the presence and absence of components, respectively. Bold values highlight the best results among the privacy-preserving methods.
Vulnerability of Standard VQ-VAE
The Standard VQ-VAE (trained with deterministic argmin and no regularization) exhibits catastrophic degradation when subjected to differential privacy noise. As shown in Table 5, the FID spikes to 48.5 on MNIST and 141.3 on Fashion-MNIST. This confirms that without robust training, the decoder overfits to precise codebook vectors and fails to generalize to the stochastic perturbations introduced by the DP mechanism, rendering the generated images structurally incoherent.
Individual Contributions
Deploying either mechanism individually yields substantial improvements. Stochastic-Only training forces the decoder to tolerate code selection jitter, reducing FID to 20.0 on MNIST. Similarly, Entropy-Only training prevents codebook collapse and ensures a dense latent space, achieving an FID of 19.8. While both variants significantly outperform the standard baseline, neither achieves optimal performance in isolation, suggesting that addressing noise sensitivity and codebook utilization separately is insufficient.
Synergistic Effect
The proposed Robust VQ-VAE combines both mechanisms to achieve the best trade-off, lowering the FID to 18.2 on MNIST and 77.1 on Fashion-MNIST. This demonstrates a synergistic effect: entropy regularization ensures a rich and utilized representation space, while stochastic sampling explicitly prepares the decoder for the inevitable noise injection during the privacy-preserving stage. Comparing these results to the Reference (Deterministic) baseline (Row 1), our method successfully closes the gap caused by DP noise, whereas the standard approach suffers from an unacceptable loss of utility.
5.7. Empirical Validation of Theoretical Analysis
Several key components of our theoretical analysis rely on structural assumptions and worst-case bounds. In this subsection, we provide empirical validation and diagnostic analyses to quantify how these theoretical components manifest in practice.
5.7.1. Empirical Verification of Anchored Decoder Regularity
Assumption 1 postulates that the decoder G is -Lipschitz on the support of the projected codebook . Since exact Lipschitz constants of deep networks are difficult to compute, we adopt an empirical proxy to characterize the local regularity of G on the discrete latent support.
Specifically, for randomly sampled code pairs , we estimate the ratio
and report summary statistics over random pairs and nearest-neighbor pairs on the codebook graph. This proxy directly measures the effective Lipschitz behavior of G restricted to the latent support used at generation time.
Table 6 reports the empirical distributions of across datasets. We observe that low-dimensional datasets such as MNIST exhibit smaller and more concentrated values, whereas higher-resolution datasets (e.g., CelebA-HQ) yield larger and more dispersed ratios. These results support the dataset-dependent nature of and empirically validate Assumption 1 in all evaluated settings.
Table 6.
Empirical Lipschitz proxy of the decoder on the projected codebook support.
5.7.2. Empirical Decomposition of the Error Bound
Proposition 3 decomposes the end-to-end Wasserstein-2 discrepancy into three conceptual components: geometric approximation, DP projection distortion, and prior modeling error. Since Equation (19) is an upper bound, it does not define a unique additive partition of . To provide quantitative insight into which component dominates across datasets and privacy budgets, we introduce computable empirical proxies aligned with the three theoretical sources of error.
Geometric Approximation Proxy
We measure representation-induced distortion by the non-private nearest-code quantization error:
DP Projection Distortion Proxy
We quantify the additional distortion introduced by the exponential-mechanism projection as the expected excess distortion:
Prior Modeling Proxy
To approximate the modeling discrepancy between sanitized latents and the learned prior , we compare their empirical token distributions on the lattice via the Jensen–Shannon divergence:
Table 7 reports across datasets and privacy budgets. We observe that the geometric approximation and DP projection terms are of comparable magnitude, while the prior modeling proxy is smaller in most settings. Moreover, under record-level budgeting over dense token grids, the DP-induced excess distortion varies only mildly within practical privacy ranges, indicating that geometric quantization error dominates the end-to-end discrepancy beyond moderate privacy budgets. These empirical findings are consistent with the conservative nature of the worst-case bound in Proposition 3.
Table 7.
Empirical proxies aligned with the three components in Proposition 3: geometric approximation , DP-induced excess distortion , and prior modeling mismatch (Jensen–Shannon divergence between token histograms).
6. Conclusions
In this work, we presented DP-VQG, a differentially private generative framework that enforces privacy through a discrete latent bottleneck rather than through end-to-end noise injection in high-dimensional continuous spaces. By decomposing the generative pipeline into (i) representation learning, (ii) differentially private discrete latent projection, and (iii) non-private generative modeling, DP-VQG isolates privacy-sensitive operations to a compact and structured interface while treating the subsequent generative process as pure post-processing.
From a conceptual perspective, DP-VQG highlights the importance of aligning privacy mechanisms with the structure of modern generative models. Our analysis shows that, when privacy is enforced via discrete latent selection, the resulting utility degradation scales logarithmically with the codebook size rather than with the ambient latent dimension. This property contrasts sharply with continuous perturbation mechanisms, which often suffer from severe off-support effects under realistic privacy budgets. Theoretical results formalize this distinction through explicit bounds on latent and reconstruction-space distortion, while the end-to-end Wasserstein decomposition clarifies how privacy-induced error interacts with geometric approximation and prior modeling.
Empirically, DP-VQG achieves a strong privacy–utility trade-off across a range of benchmarks. On standard low-resolution datasets, it consistently outperforms existing differentially private generative baselines in both sample quality and downstream utility. Moreover, the public–prior variant demonstrates that high-resolution image synthesis under formal differential privacy is feasible when privacy noise is confined to a discrete latent interface, enabling visually coherent generation in regimes where prior end-to-end DP approaches struggle to scale.
While DP-VQG provides a principled and scalable alternative to continuous DP perturbations, several open questions remain. In particular, for very large generative models, the required codebook size may increase by one or two orders of magnitude. In these regimes, it becomes increasingly critical to investigate the computational cost and privacy-induced distortion associated with differentially private discrete selection. Exploring hierarchical, structured, or adaptive codebooks that preserve the advantages of discrete privacy mechanisms at scale is a promising direction for future work.
Overall, this work suggests that discrete latent interfaces offer a robust foundation for privacy-preserving generative modeling, providing a favorable balance between formal privacy guarantees and practical sample quality. We hope that DP-VQG will encourage further research on structurally aligned privacy mechanisms for large-scale generative models beyond end-to-end noisy training.
Author Contributions
Conceptualization, Y.G. and H.Y.; methodology, Y.G.; software, Y.G.; validation, H.Z.; formal analysis, Y.G.; data curation, Y.G.; writing—original draft, Y.G.; writing—review and editing, H.Y.; supervision, H.Z.; funding acquisition, H.Z. All authors have read and agreed to the published version of the manuscript.
Funding
This research was partially supported by Guizhou Provincial Science and Technology Department (Grant No. 2023-221) and National Natural Science Foundation of China (Grant No. 71771006).
Data Availability Statement
The data presented in this study are available in [ImageNet] [https://doi.org/10.1109/CVPR.2009.5206848]; [Stanford Cars] [https://doi.org/10.1109/ICCVW.2013.77]; [CelebA-HQ] [https://mmlab.ie.cuhk.edu.hk/projects/CelebA.html (accessed on 6 December 2025)]; [Food-101] [https://link.springer.com/chapter/10.1007/978-3-319-10599-4_29 (accessed on 6 December 2025)]; and [Oxford 102 Flowers] [https://www.robots.ox.ac.uk/~vgg/data/flowers/102/ (accessed on 6 December 2025)].
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Hayes, J.; Melis, L.; Danezis, G.; De Cristofaro, E. LOGAN: Membership Inference Attacks Against Generative Models. Proc. Priv. Enhanc. Technol. 2019, 1, 133–152. [Google Scholar] [CrossRef] [Scilit]
- Hilprecht, B.; Härterich, M.; Bernau, D. Monte carlo and reconstruction membership inference attacks against generative models. Proc. Priv. Enhanc. Technol. 2019, 4, 232–249. [Google Scholar] [CrossRef] [Scilit]
- Kong, F.; Duan, J.; Ma, R.; Shen, H.T.; Shi, X.; Zhu, X.; Xu, K. An Efficient Membership Inference Attack for the Diffusion Model by Proximal Initialization. In Proceedings of the Twelfth International Conference on Learning Representations, Vienna, Austria, 7–11 May 2024. [Google Scholar]
- Carlini, N.; Hayes, J.; Nasr, M.; Jagielski, M.; Sehwag, V.; Tramer, F.; Balle, B.; Ippolito, D.; Wallace, E. Extracting training data from diffusion models. In Proceedings of the 32nd USENIX Security Symposium (USENIX Security 23), Anaheim, CA, USA, 9–11 August 2023; pp. 5253–5270. [Google Scholar]
- Pang, Y.; Wang, T.; Kang, X.; Huai, M.; Zhang, Y. White-box Membership Inference Attacks against Diffusion Models. Proc. Priv. Enhanc. Technol. 2025, 2, 398–415. [Google Scholar] [CrossRef] [Scilit]
- Dwork, C. Differential privacy. In Proceedings of the International Colloquium on Automata, Languages, and Programming; Springer: Berlin/Heidelberg, Germany, 2006; pp. 1–12. [Google Scholar]
- Dwork, C.; Roth, A. The algorithmic foundations of differential privacy. Found. Trends® Theor. Comput. Sci. 2014, 9, 211–407. [Google Scholar] [CrossRef] [Scilit]
- Abadi, M.; Chu, A.; Goodfellow, I.; McMahan, H.B.; Mironov, I.; Talwar, K.; Zhang, L. Deep learning with differential privacy. In Proceedings of the 2016 ACM SIGSAC Conference on Computer and Communications Security, Vienna, Austria, 24–28 October 2016; pp. 308–318. [Google Scholar]
- Xie, L.; Lin, K.; Wang, S.; Wang, F.; Zhou, J. Differentially Private Generative Adversarial Network. arXiv 2018, arXiv:1802.06739. [Google Scholar] [CrossRef] [Scilit]
- Dockhorn, T.; Cao, T.; Vahdat, A.; Kreis, K. Differentially Private Diffusion Models. arXiv 2022, arXiv:2210.09929. [Google Scholar]
- Bengio, Y.; Courville, A.; Vincent, P. Representation learning: A review and new perspectives. IEEE Trans. Pattern Anal. Mach. Intell. 2013, 35, 1798–1828. [Google Scholar] [CrossRef] [Scilit]
- Loaiza-Ganem, G.; Ross, B.L.; Hosseinzadeh, R.; Caterini, A.L.; Cresswell, J.C. Deep Generative Models through the Lens of the Manifold Hypothesis: A Survey and New Connections. arXiv 2024, arXiv:2404.02954. [Google Scholar] [CrossRef] [Scilit]
- Goodfellow, I.; Pouget-Abadie, J.; Mirza, M.; Xu, B.; Warde-Farley, D.; Ozair, S.; Courville, A.; Bengio, Y. Generative adversarial networks. Commun. ACM 2020, 63, 139–144. [Google Scholar] [CrossRef] [Scilit]
- Van den Oord, A.; Kalchbrenner, N.; Espeholt, L.; Vinyals, O.; Graves, A. Conditional image generation with pixelcnn decoders. In Proceedings of the Advances in Neural Information Processing Systems (NIPS), Barcelona, Spain, 5–10 December 2016; pp. 4797–4805. [Google Scholar]
- Dinh, L.; Sohl-Dickstein, J.; Bengio, S. Density estimation using Real NVP. In Proceedings of the International Conference on Learning Representations, Toulon, France, 24–26 April 2017. [Google Scholar]
- Kingma, D.P.; Dhariwal, P. Glow: Generative flow with invertible 1 × 1 convolutions. arXiv 2018, arXiv:1807.03039. [Google Scholar]
- Ho, J.; Jain, A.; Abbeel, P. Denoising diffusion probabilistic models. Adv. Neural Inf. Process. Syst. 2020, 33, 6840–6851. [Google Scholar]
- Song, Y.; Sohl-Dickstein, J.; Kingma, D.P.; Kumar, A.; Ermon, S.; Poole, B. Score-Based Generative Modeling through Stochastic Differential Equations. In Proceedings of the International Conference on Learning Representations, Vienna, Austria, 4 May 2021. [Google Scholar]
- Kingma, D.P.; Welling, M. Auto-encoding variational bayes. arXiv 2013, arXiv:1312.6114. [Google Scholar]
- Van Den Oord, A.; Vinyals, O. Neural discrete representation learning. In Proceedings of the Advances in Neural Information Processing Systems (NIPS), Long Beach, CA, USA, 4–9 December 2017; pp. 6306–6315. [Google Scholar]
- Rombach, R.; Blattmann, A.; Lorenz, D.; Esser, P.; Ommer, B. High-resolution image synthesis with latent diffusion models. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, New Orleans, LA, USA, 18–24 June 2022; pp. 10684–10695. [Google Scholar]
- Chang, H.; Zhang, H.; Jiang, L.; Liu, C.; Freeman, W.T. Maskgit: Masked generative image transformer. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, New Orleans, LA, USA, 18–24 June 2022; pp. 11315–11325. [Google Scholar]
- Gupta, A.; Tian, S.; Zhang, Y.; Wu, J.; Martín-Martín, R.; Fei-Fei, L. MaskViT: Masked Visual Pre-Training for Video Prediction. In Proceedings of the Eleventh International Conference on Learning Representations, Kigali, Rwanda, 1–5 May 2023. [Google Scholar]
- Yu, L.; Lezama, J.; Gundavarapu, N.B.; Versari, L.; Sohn, K.; Minnen, D.; Cheng, Y.; Gupta, A.; Gu, X.; Hauptmann, A.G.; et al. Language Model Beats Diffusion—Tokenizer is key to visual generation. In Proceedings of the Twelfth International Conference on Learning Representations, Vienna, Austria, 7–11 May 2024. [Google Scholar]
- Sweeney, L. k-anonymity: A model for protecting privacy. Int. J. Uncertain. Fuzziness Knowl.-Based Syst. 2002, 10, 557–570. [Google Scholar] [CrossRef] [Scilit]
- Xiao, X.; Tao, Y. Anatomy: Simple and effective privacy preservation. In Proceedings of the 32nd International Conference on Very Large Data Bases, Seoul, Republic of Korea, 12–15 September 2006; pp. 139–150. [Google Scholar]
- Zhang, Z.; Rubinstein, B.; Dimitrakakis, C. On the differential privacy of Bayesian inference. In Proceedings of the AAAI Conference on Artificial Intelligence, Phoenix, AR, USA, 12–17 February 2016; Volume 30. [Google Scholar]
- McKenna, R.; Miklau, G.; Sheldon, D. Winning the NIST Contest: A scalable and general approach to differentially private synthetic data. J. Priv. Confidentiality 2021, 11, 1–22. [Google Scholar] [CrossRef] [Scilit]
- Hu, Y.; Wu, F.; Li, Q.; Long, Y.; Garrido, G.M.; Ge, C.; Ding, B.; Forsyth, D.; Li, B.; Song, D. Sok: Privacy-preserving data synthesis. In Proceedings of the 2024 IEEE Symposium on Security and Privacy (SP), San Francisco, CA, USA, 20–22 May 2024; IEEE: Piscataway, NJ, USA, 2024; pp. 4696–4713. [Google Scholar]
- Oneto, L.; Ridella, S.; Anguita, D. Towards algorithms and models that we can trust: A theoretical perspective. Neurocomputing 2024, 592, 127798. [Google Scholar] [CrossRef] [Scilit]
- Papernot, N.; Abadi, M.; Erlingsson, Ú.; Goodfellow, I.; Talwar, K. Semi-supervised Knowledge Transfer for Deep Learning from Private Training Data. In Proceedings of the International Conference on Learning Representations, Toulon, France, 24–26 April 2017. [Google Scholar]
- Jordon, J.; Yoon, J.; Van Der Schaar, M. PATE-GAN: Generating synthetic data with differential privacy guarantees. In Proceedings of the International Conference on Learning Representations, Vancouver, BC, Canada, 30 April–3 May 2018. [Google Scholar]
- Long, Y.; Wang, B.; Yang, Z.; Kailkhura, B.; Zhang, A.; Gunter, C.; Li, B. G-pate: Scalable differentially private data generator via private aggregation of teacher discriminators. Adv. Neural Inf. Process. Syst. 2021, 34, 2965–2977. [Google Scholar]
- Torkzadehmahani, R.; Kairouz, P.; Paten, B. DP-CGAN: Differentially Private Synthetic Data and Label Generation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) Workshops, Long Beach, CA, USA, 15–20 June 2019. [Google Scholar]
- Jiang, D.; Sun, S. DP-LFlow: Differentially private latent flow for scalable sensitive image generation. Trans. Mach. Learn. Res. 2023. [Google Scholar]
- Chen, D.; Orekondy, T.; Fritz, M. Gs-wgan: A gradient-sanitized approach for learning differentially private generators. Adv. Neural Inf. Process. Syst. 2020, 33, 12673–12684. [Google Scholar]
- Cao, T.; Bie, A.; Vahdat, A.; Fidler, S.; Kreis, K. Don’t generate me: Training differentially private generative models with sinkhorn divergence. Adv. Neural Inf. Process. Syst. 2021, 34, 12480–12492. [Google Scholar]
- Jiang, D.; Sun, S.; Yu, Y. Functional renyi differential privacy for generative modeling. Adv. Neural Inf. Process. Syst. 2023, 36, 14797–14817. [Google Scholar]
- Greenewald, K.; Yu, Y.; Wang, H.; Xu, K. Privacy without Noisy Gradients: Slicing Mechanism for Generative Model Training. In Proceedings of the Advances in Neural Information Processing Systems, Vancouver, BC, Canada, 10–15 December 2024; Globerson, A., Mackey, L., Belgrave, D., Fan, A., Paquet, U., Tomczak, J., Zhang, C., Eds.; Curran Associates, Inc.: Red Hook, NY, USA, 2024; Volume 37, pp. 125702–125728. [Google Scholar]
- Li, K.; Gong, C.; Li, Z.; Zhao, Y.; Hou, X.; Wang, T. PrivImage: Differentially private synthetic image generation using diffusion models with Semantic-Aware pretraining. In Proceedings of the 33rd USENIX Security Symposium (USENIX Security 24), Philadelphia, PA, USA, 14–16 August 2024; pp. 4837–4854. [Google Scholar]
- Mironov, I. Rényi differential privacy. In Proceedings of the 2017 IEEE 30th Computer Security Foundations Symposium (CSF), Santa Barbara, CA, USA, 21–25 August 2017; IEEE: Piscataway, NJ, USA, 2017; pp. 263–275. [Google Scholar]
- Gopi, S.; Lee, Y.T.; Wutschitz, L. Numerical Composition of Differential Privacy. In Proceedings of the Advances in Neural Information Processing Systems, Online, 6–14 December 2021; Curran Associates, Inc.: Red Hook, NY, USA, 2021; Volume 34, pp. 11631–11642. [Google Scholar]
- McSherry, F.; Talwar, K. Mechanism Design via Differential Privacy. In Proceedings of the 48th Annual IEEE Symposium on Foundations of Computer Science (FOCS’07), Providence, RI, USA, 21–23 October 2007; pp. 94–103. [Google Scholar] [CrossRef] [Scilit]
- Deng, L. The MNIST Database of Handwritten Digit Images for Machine Learning Research [Best of the Web]. IEEE Signal Process. Mag. 2012, 29, 141–142. [Google Scholar] [CrossRef] [Scilit]
- Xiao, H.; Rasul, K.; Vollgraf, R. Fashion-mnist: A novel image dataset for benchmarking machine learning algorithms. arXiv 2017, arXiv:1708.07747. [Google Scholar] [CrossRef] [Scilit]
- Krizhevsky, A.; Hinton, G. Learning Multiple Layers of Features from Tiny Images. 2009. Available online: https://www.cs.toronto.edu/~kriz/learning-features-2009-TR.pdf (accessed on 6 December 2025).
- Liu, Z.; Luo, P.; Wang, X.; Tang, X. Deep Learning Face Attributes in the Wild. In Proceedings of the International Conference on Computer Vision (ICCV), Santiago, Chile, 7–13 December 2015. [Google Scholar]
- Nilsback, M.E.; Zisserman, A. Automated flower classification over a large number of classes. In Proceedings of the 2008 Sixth Indian Conference on Computer Vision, Graphics & Image Processing, Bhubaneswar, India, 16–19 December 2008; IEEE: Piscataway, NJ, USA, 2008; pp. 722–729. [Google Scholar]
- Bossard, L.; Guillaumin, M.; Van Gool, L. Food-101–mining discriminative components with random forests. In Proceedings of the European Conference on Computer Vision, Zurich, Switzerland, 6–12 September 2014; Springer: Berlin/Heidelberg, Germany, 2014; pp. 446–461. [Google Scholar]
- Krause, J.; Stark, M.; Deng, J.; Li, F.-F. 3D Object Representations for Fine-Grained Categorization. In Proceedings of the 2013 IEEE International Conference on Computer Vision Workshops, Sydney, Australia, 1–8 December 2013; pp. 554–561. [Google Scholar] [CrossRef] [Scilit]
- Parmar, G.; Zhang, R.; Zhu, J.Y. On aliased resizing and surprising subtleties in gan evaluation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, New Orleans, LA, USA, 18–24 June 2022; pp. 11410–11420. [Google Scholar]
- Harder, F.; Adamczewski, K.; Park, M. Dp-merf: Differentially private mean embeddings with randomfeatures for practical privacy-preserving data generation. In Proceedings of the International Conference on Artificial Intelligence and Statistics, Online, 13–15 April 2021; pp. 1819–1827. [Google Scholar]
- Wang, B.; Wu, F.; Long, Y.; Rimanic, L.; Zhang, C.; Li, B. Datalens: Scalable privacy preserving training via gradient compression and aggregation. In Proceedings of the 2021 ACM SIGSAC Conference on Computer and Communications Security, Online, 15–19 November 2021; pp. 2146–2168. [Google Scholar]
- Liew, S.P.; Takahashi, T.; Ueno, M. PEARL: Data Synthesis via Private Embeddings and Adversarial Reconstruction Learning. In Proceedings of the International Conference on Learning Representations, Online, 25 April 2022. [Google Scholar]
- Yousefpour, A.; Shilov, I.; Sablayrolles, A.; Testuggine, D.; Prasad, K.; Malek, M.; Nguyen, J.; Ghosh, S.; Bharadwaj, A.; Zhao, J.; et al. Opacus: User-Friendly Differential Privacy Library in PyTorch. In Proceedings of the NeurIPS 2021 Workshop Privacy in Machine Learning, Online, 14 December 2021. [Google Scholar]
- Wang, X.; Chen, H.; Tang, S.; Wu, Z.; Zhu, W. Disentangled representation learning. IEEE Trans. Pattern Anal. Mach. Intell. 2024, 46, 9677–9696. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Deng, J.; Dong, W.; Socher, R.; Li, L.J.; Li, K.; Li, F.-F. ImageNet: A large-scale hierarchical image database. In Proceedings of the 2009 IEEE Conference on Computer Vision and Pattern Recognition, Miami, FL, USA, 20–25 June 2009; pp. 248–255. [Google Scholar] [CrossRef] [Scilit]
- Esser, P.; Rombach, R.; Ommer, B. Taming transformers for high-resolution image synthesis. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Nashville, TN, USA, 20–25 June 2021; pp. 12873–12883. [Google Scholar]
- Bińkowski, M.; Sutherland, D.J.; Arbel, M.; Gretton, A. Demystifying MMD GANs. In Proceedings of the International Conference on Learning Representations, Vancouver, BC, Canada, 30 April–3 May 2018. [Google Scholar]
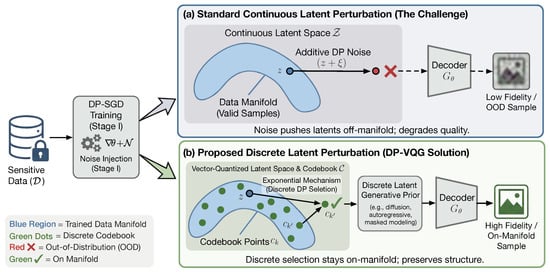
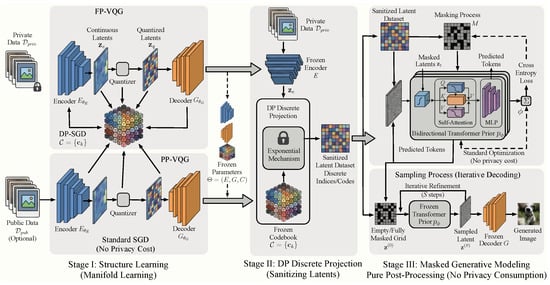
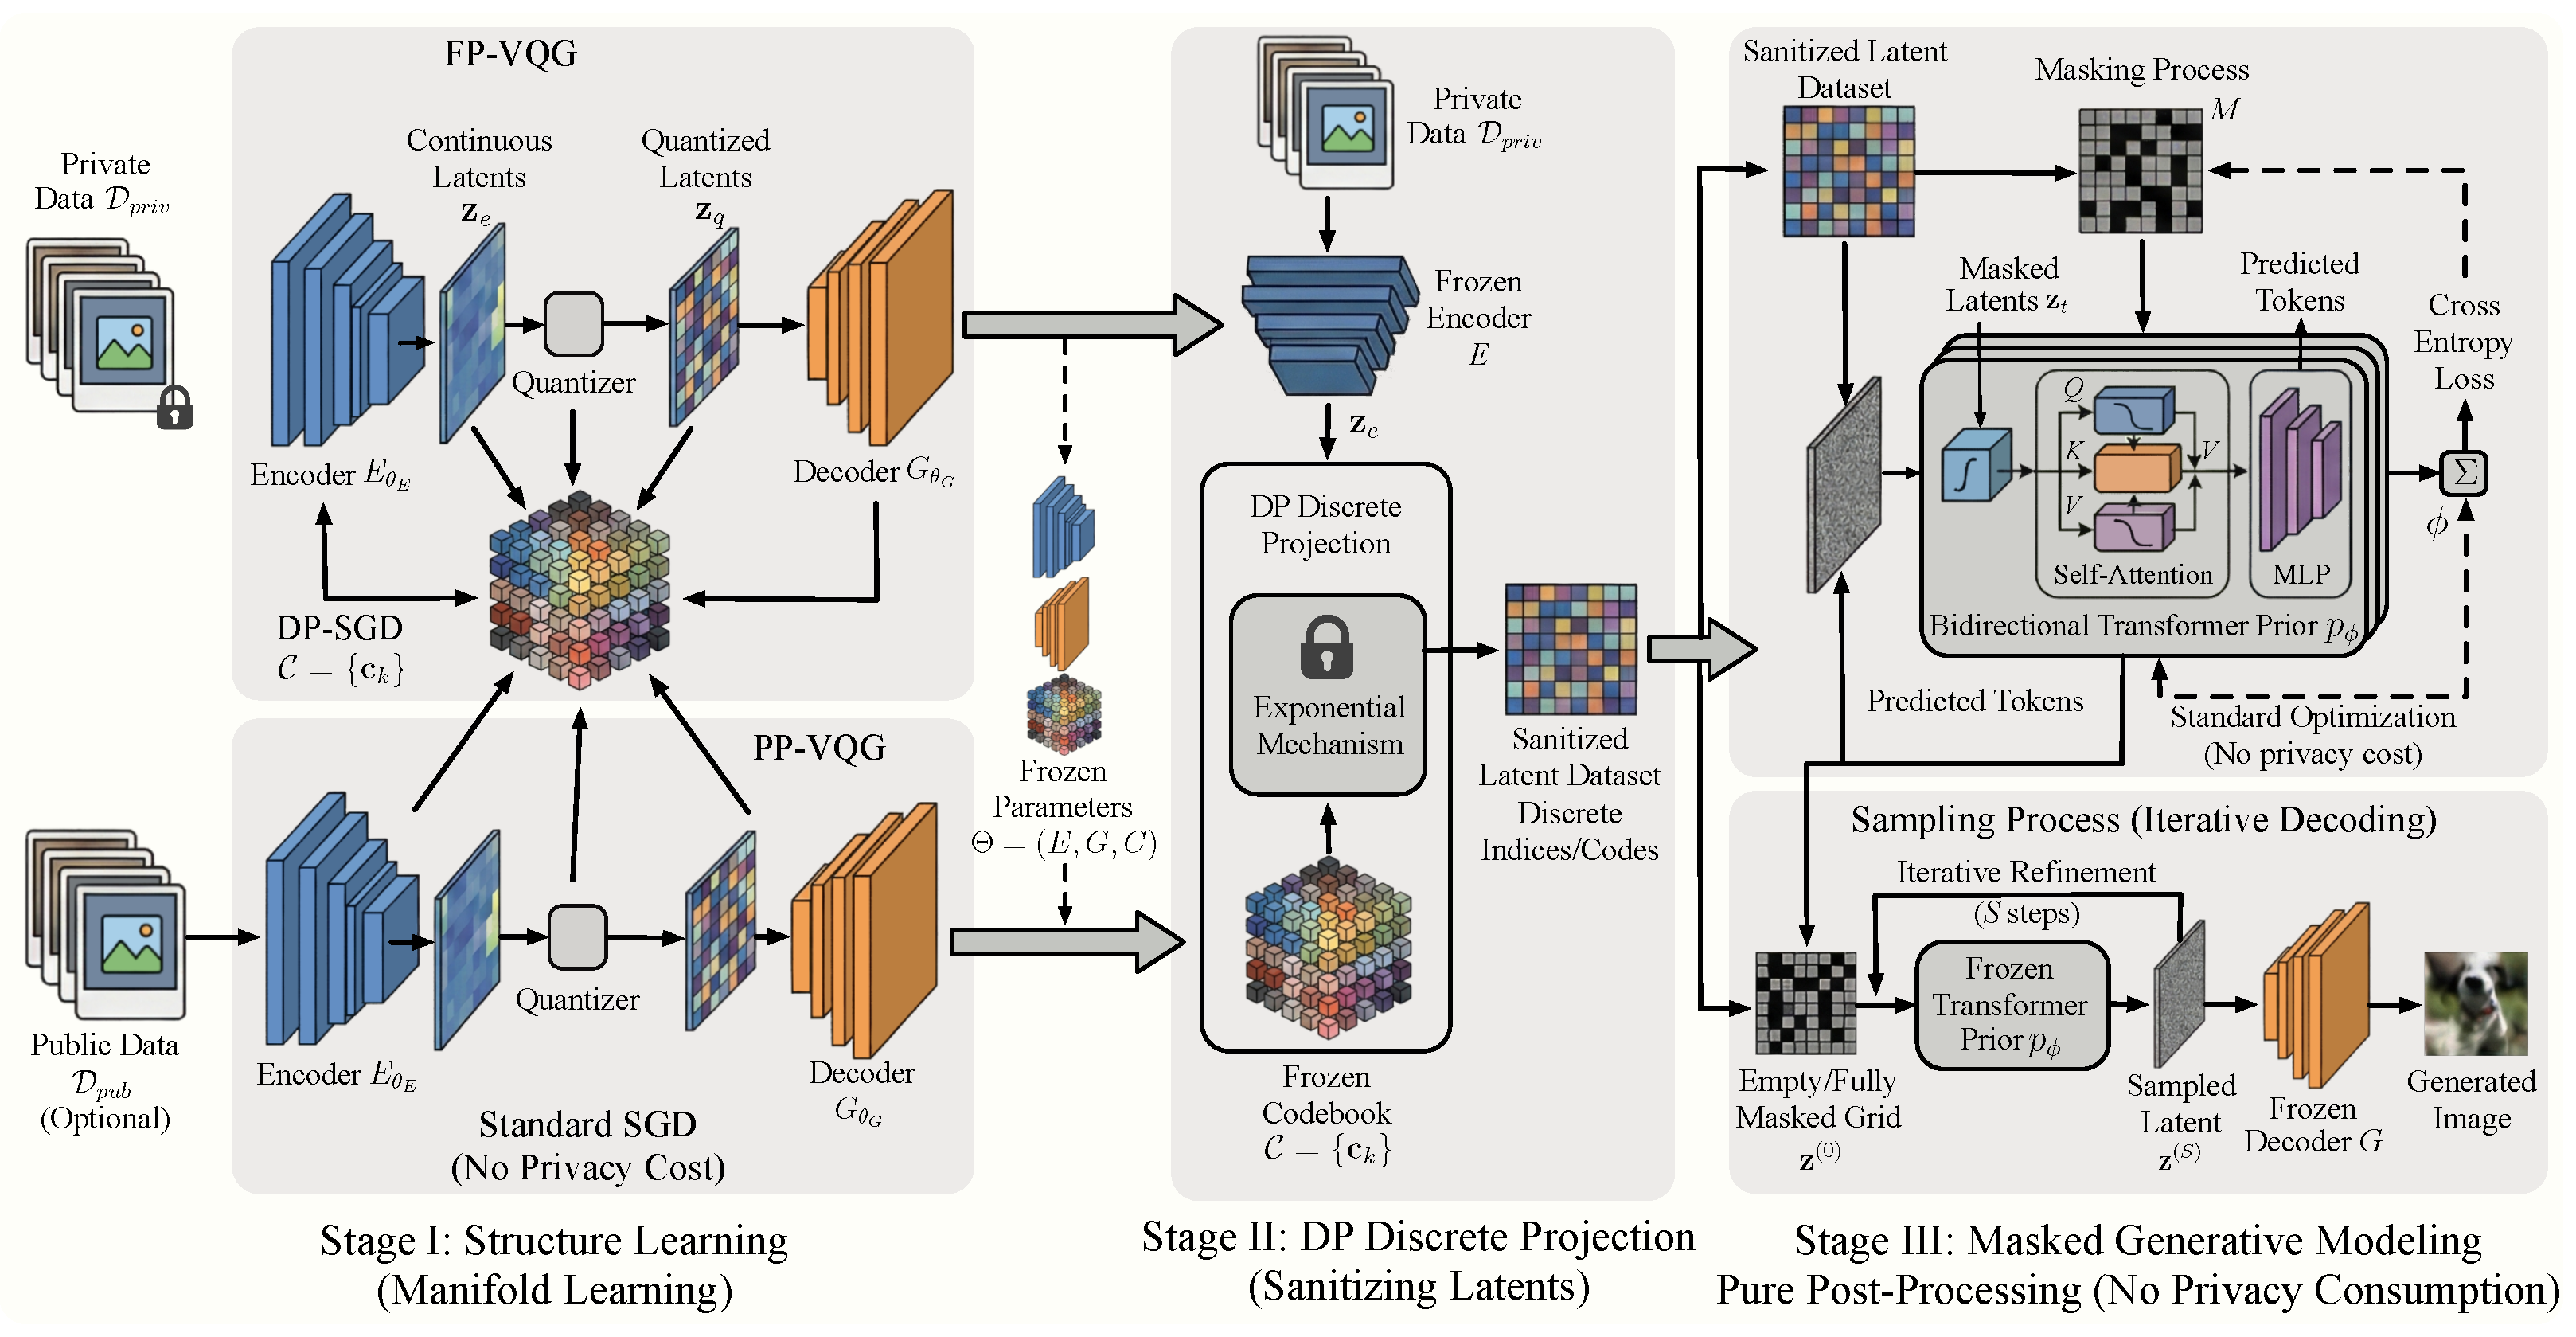
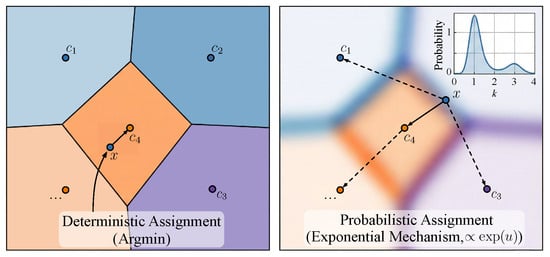
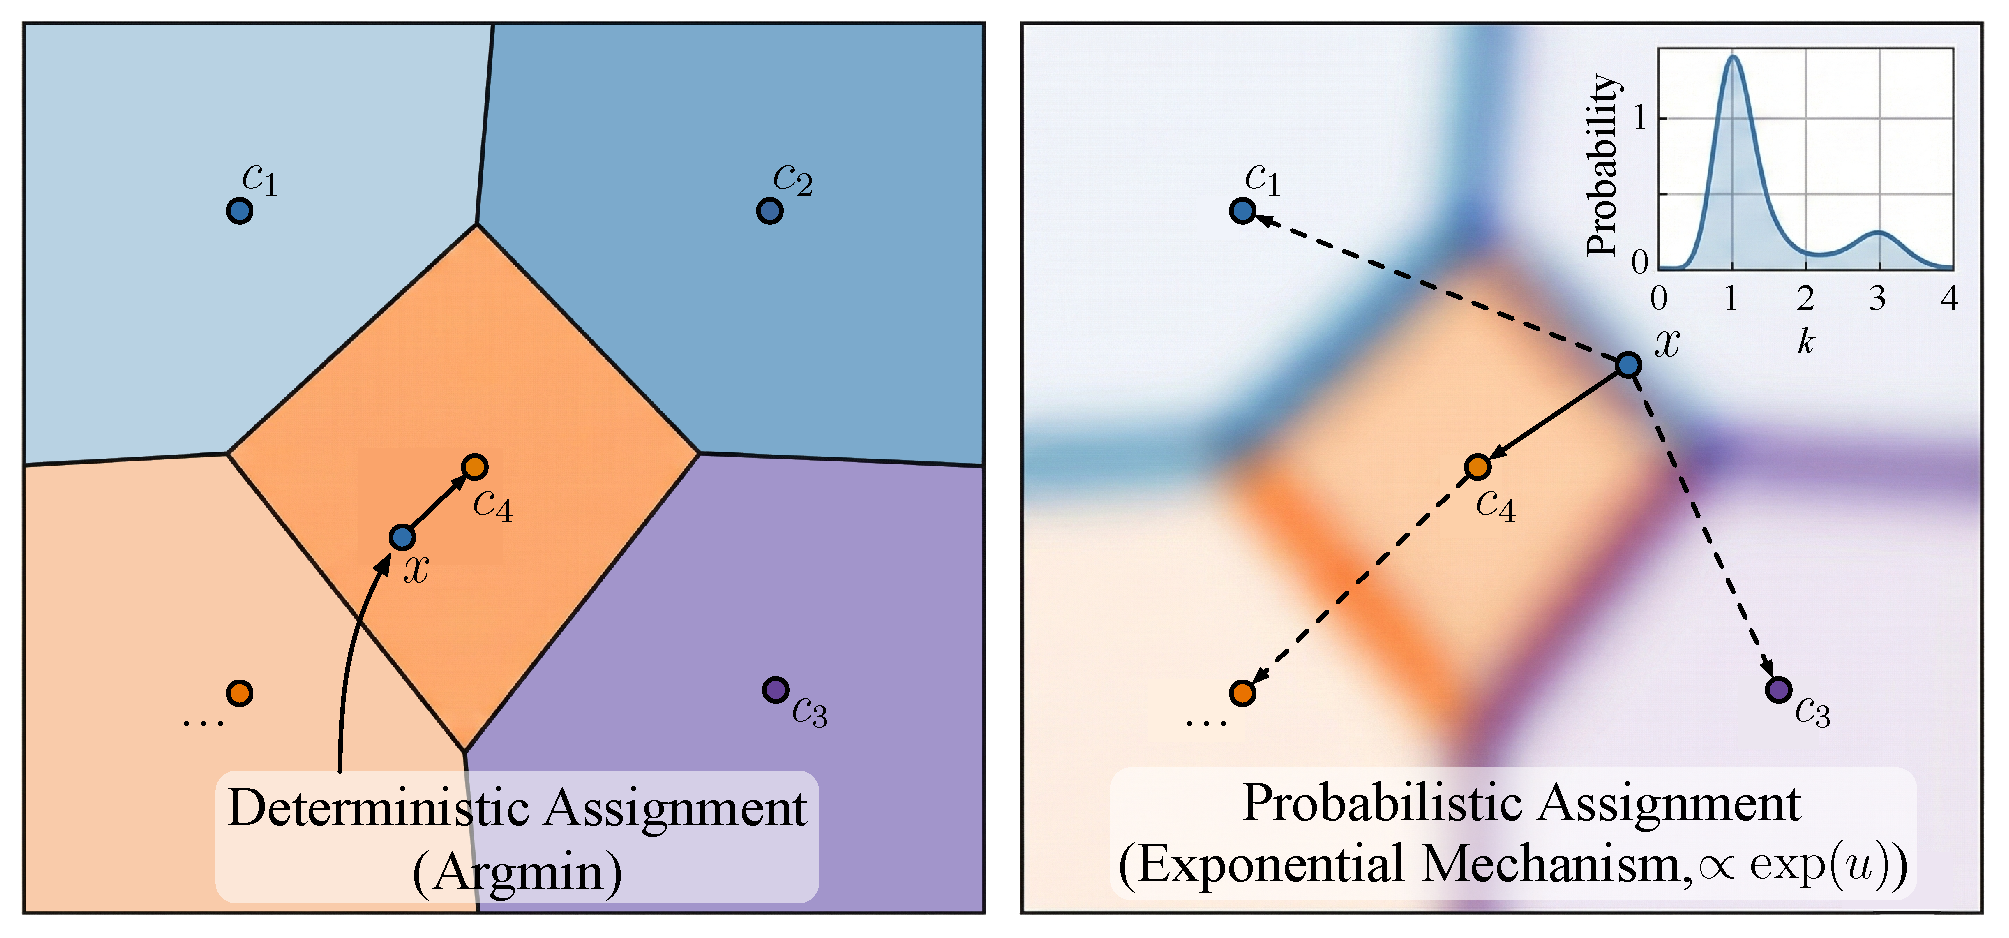
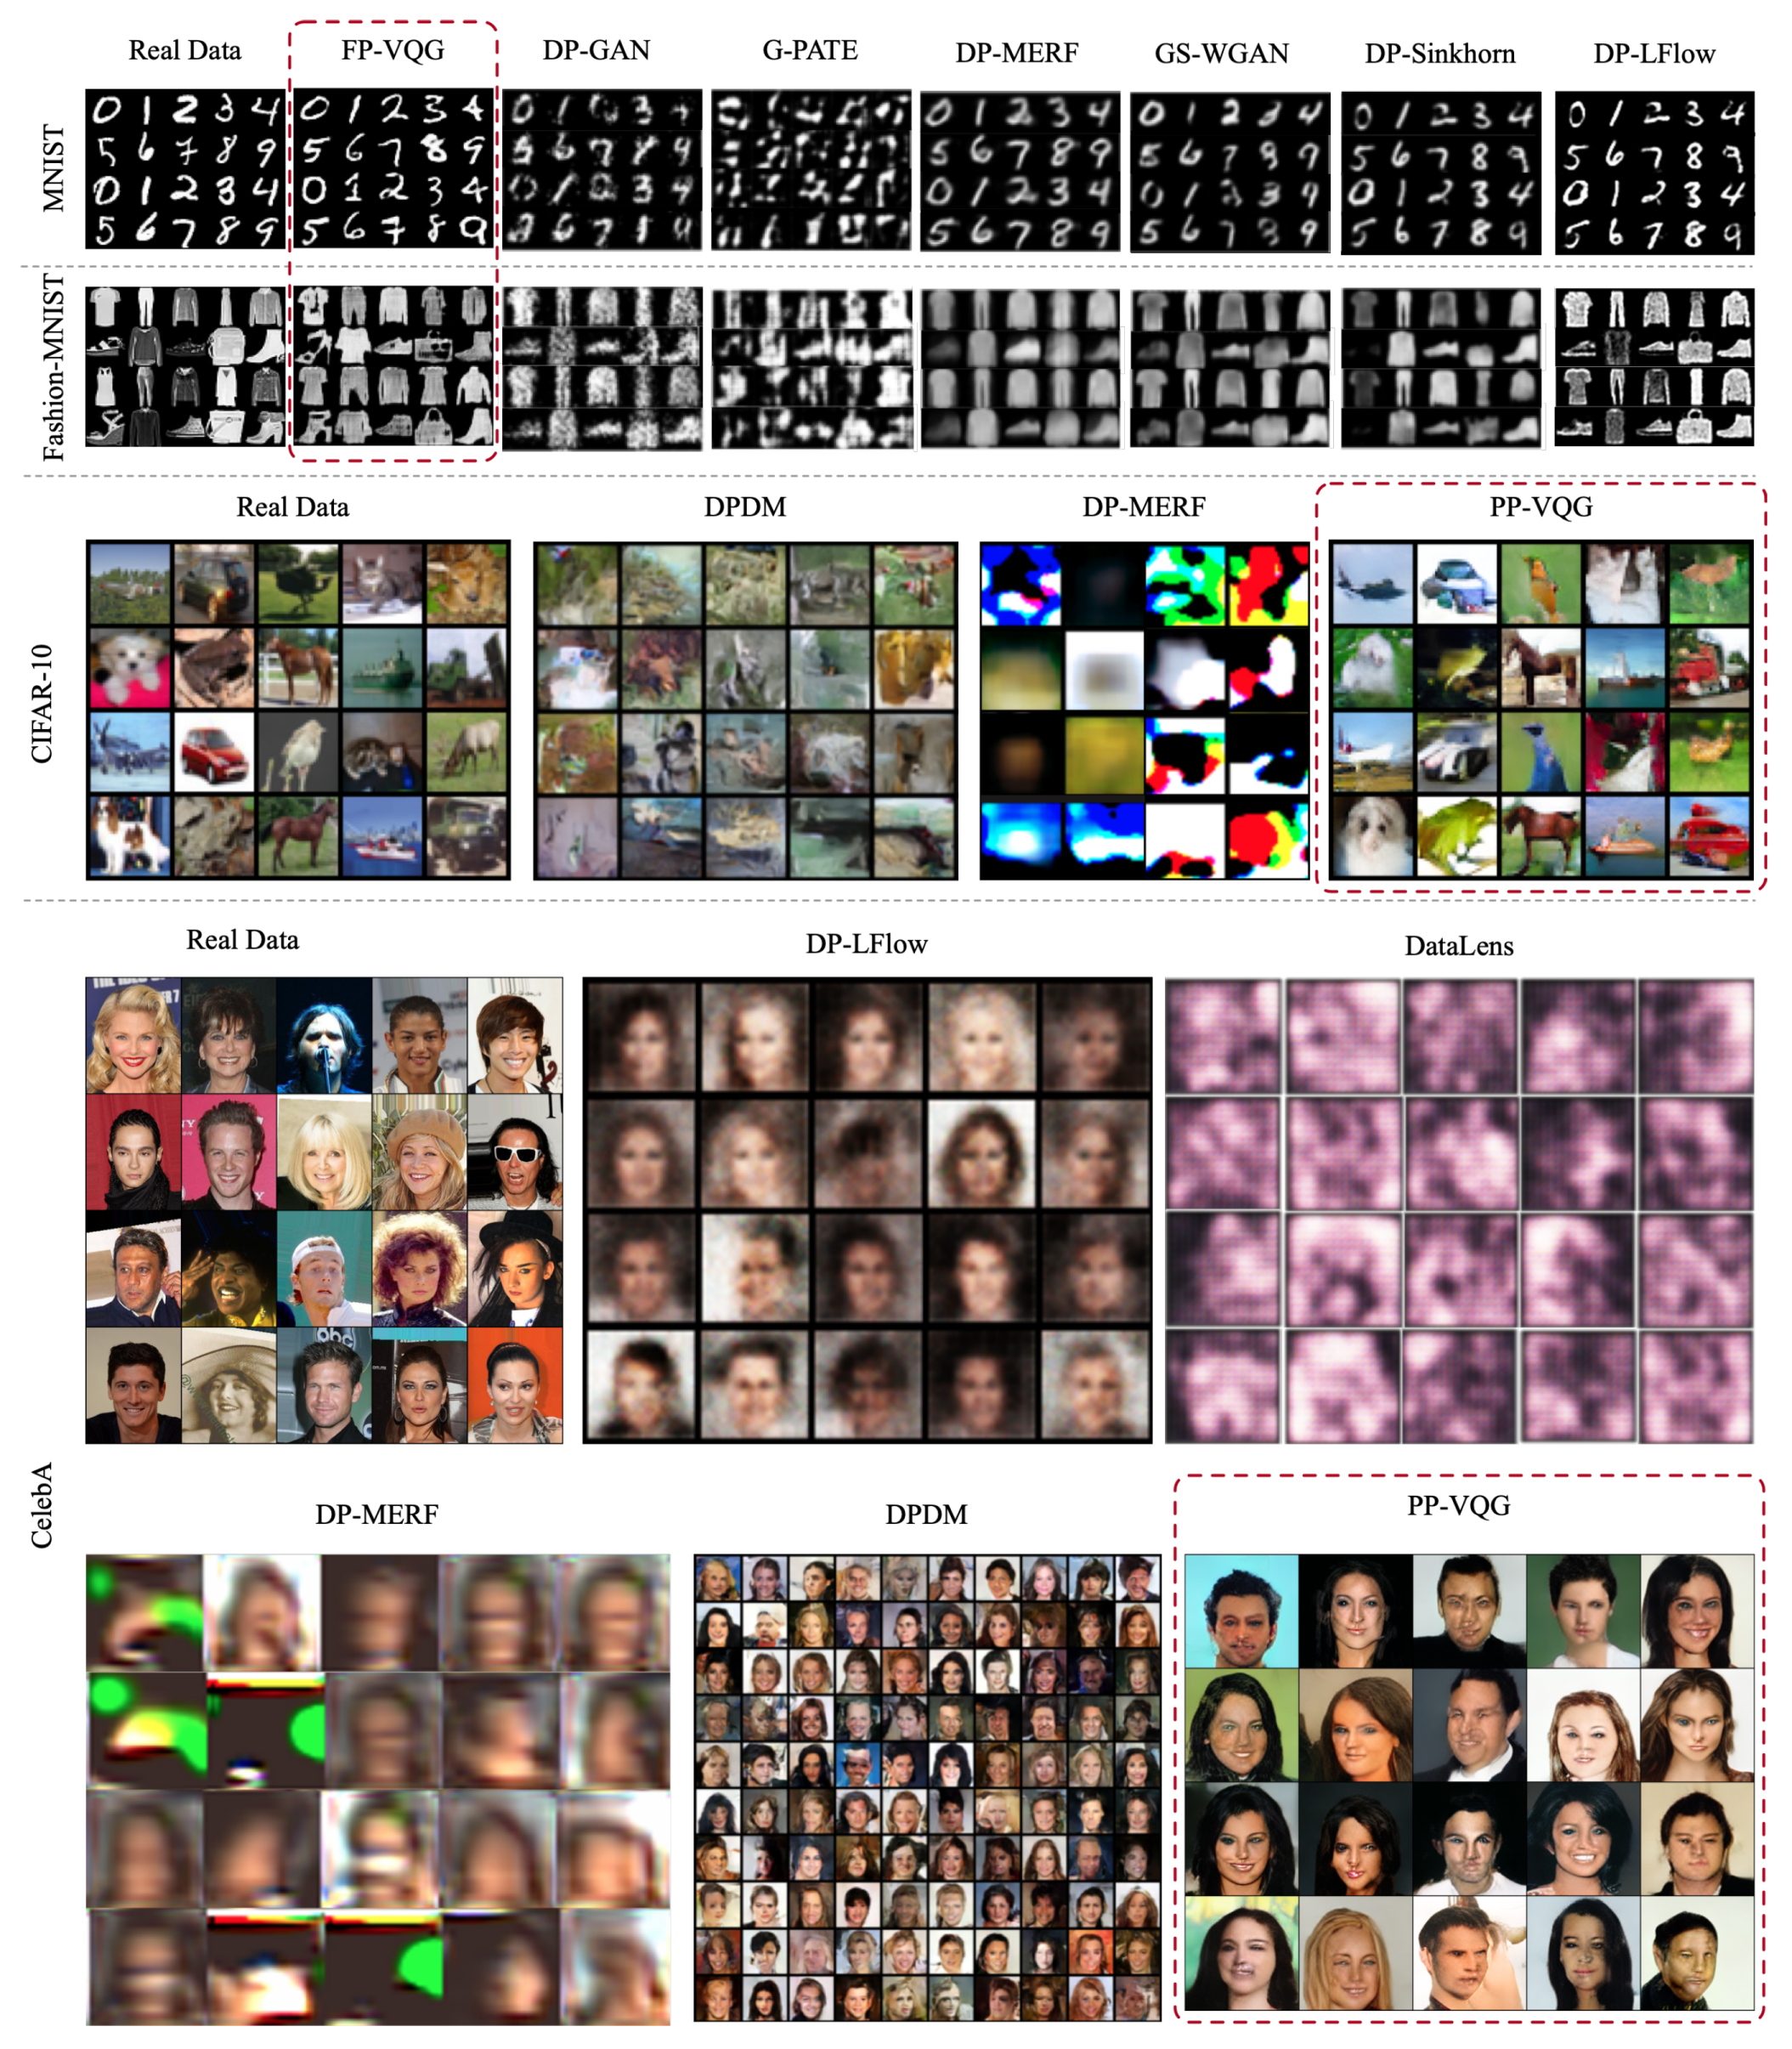
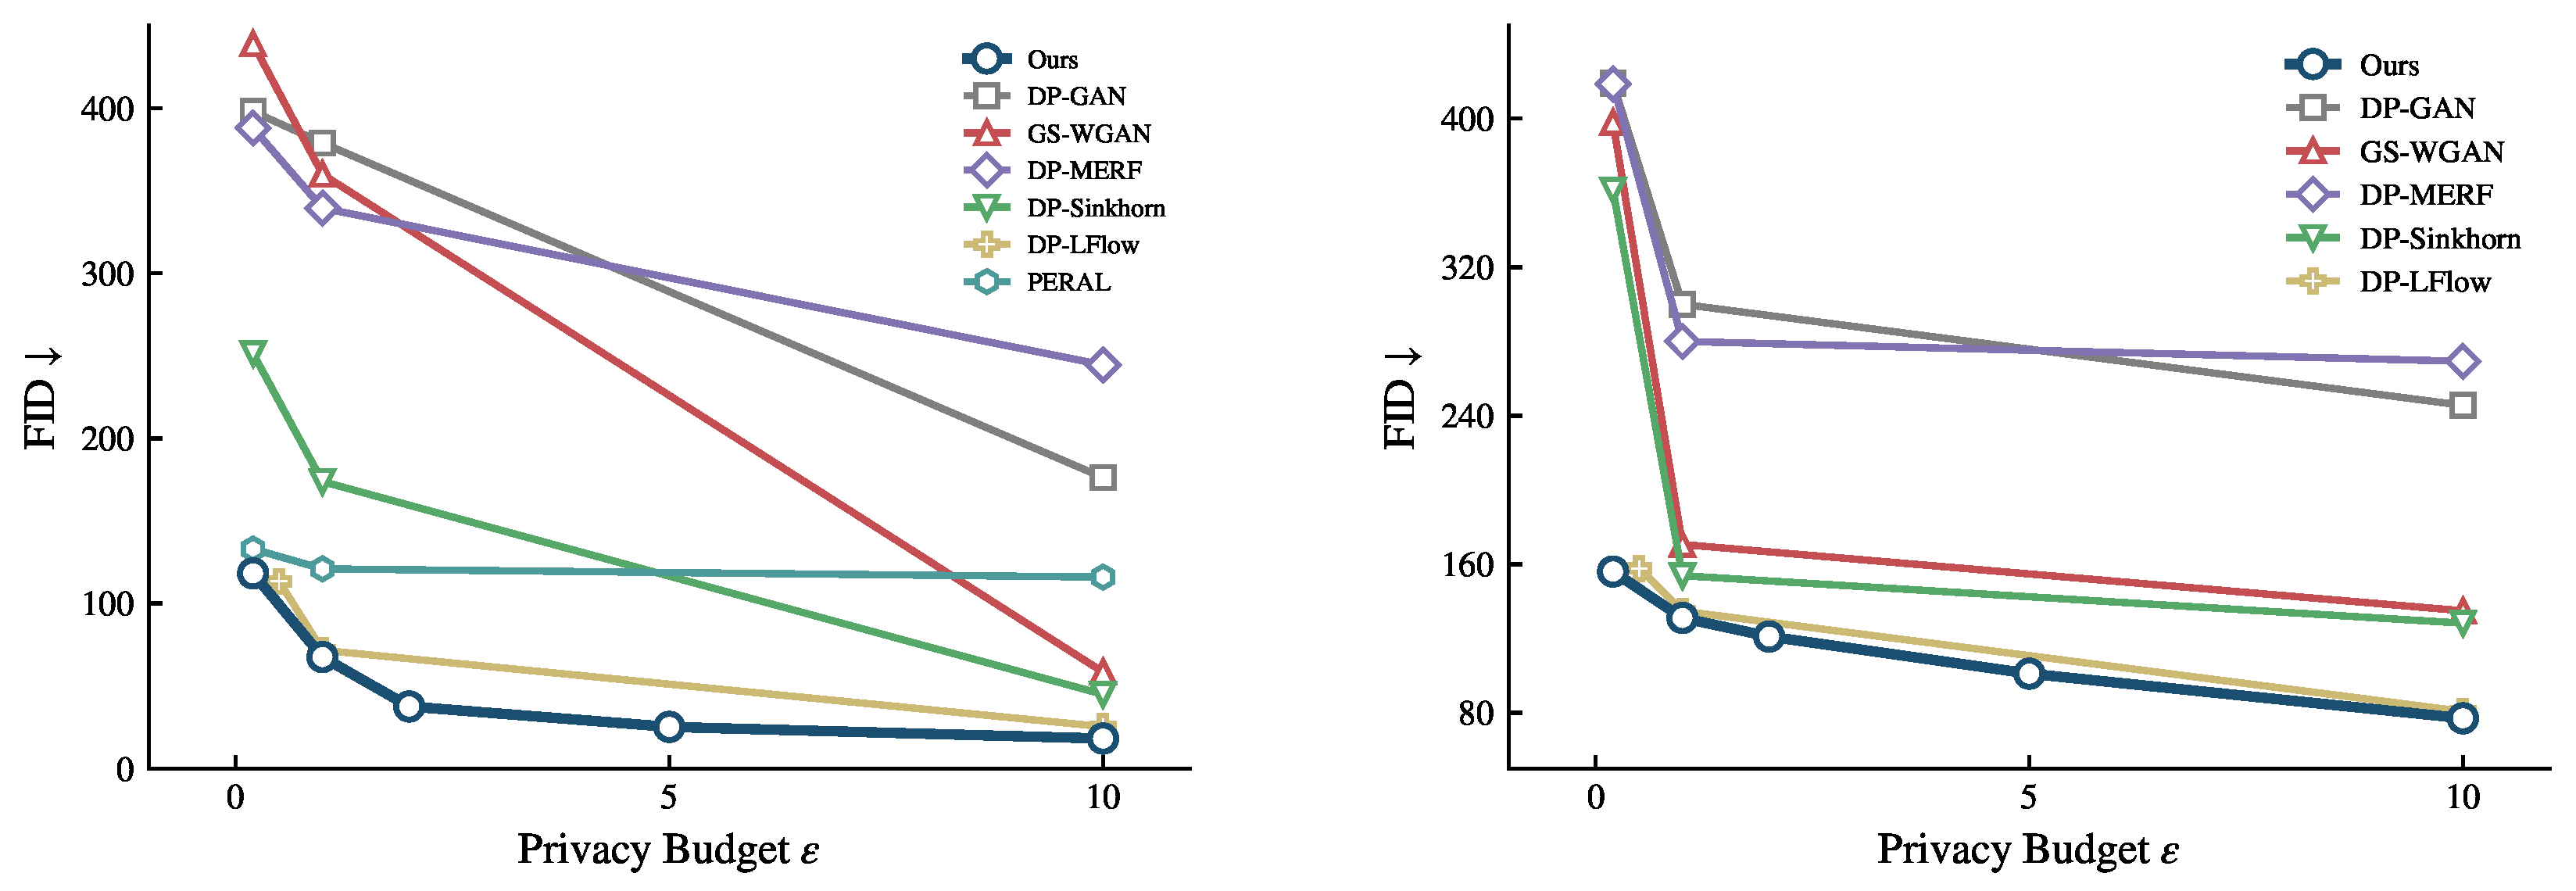
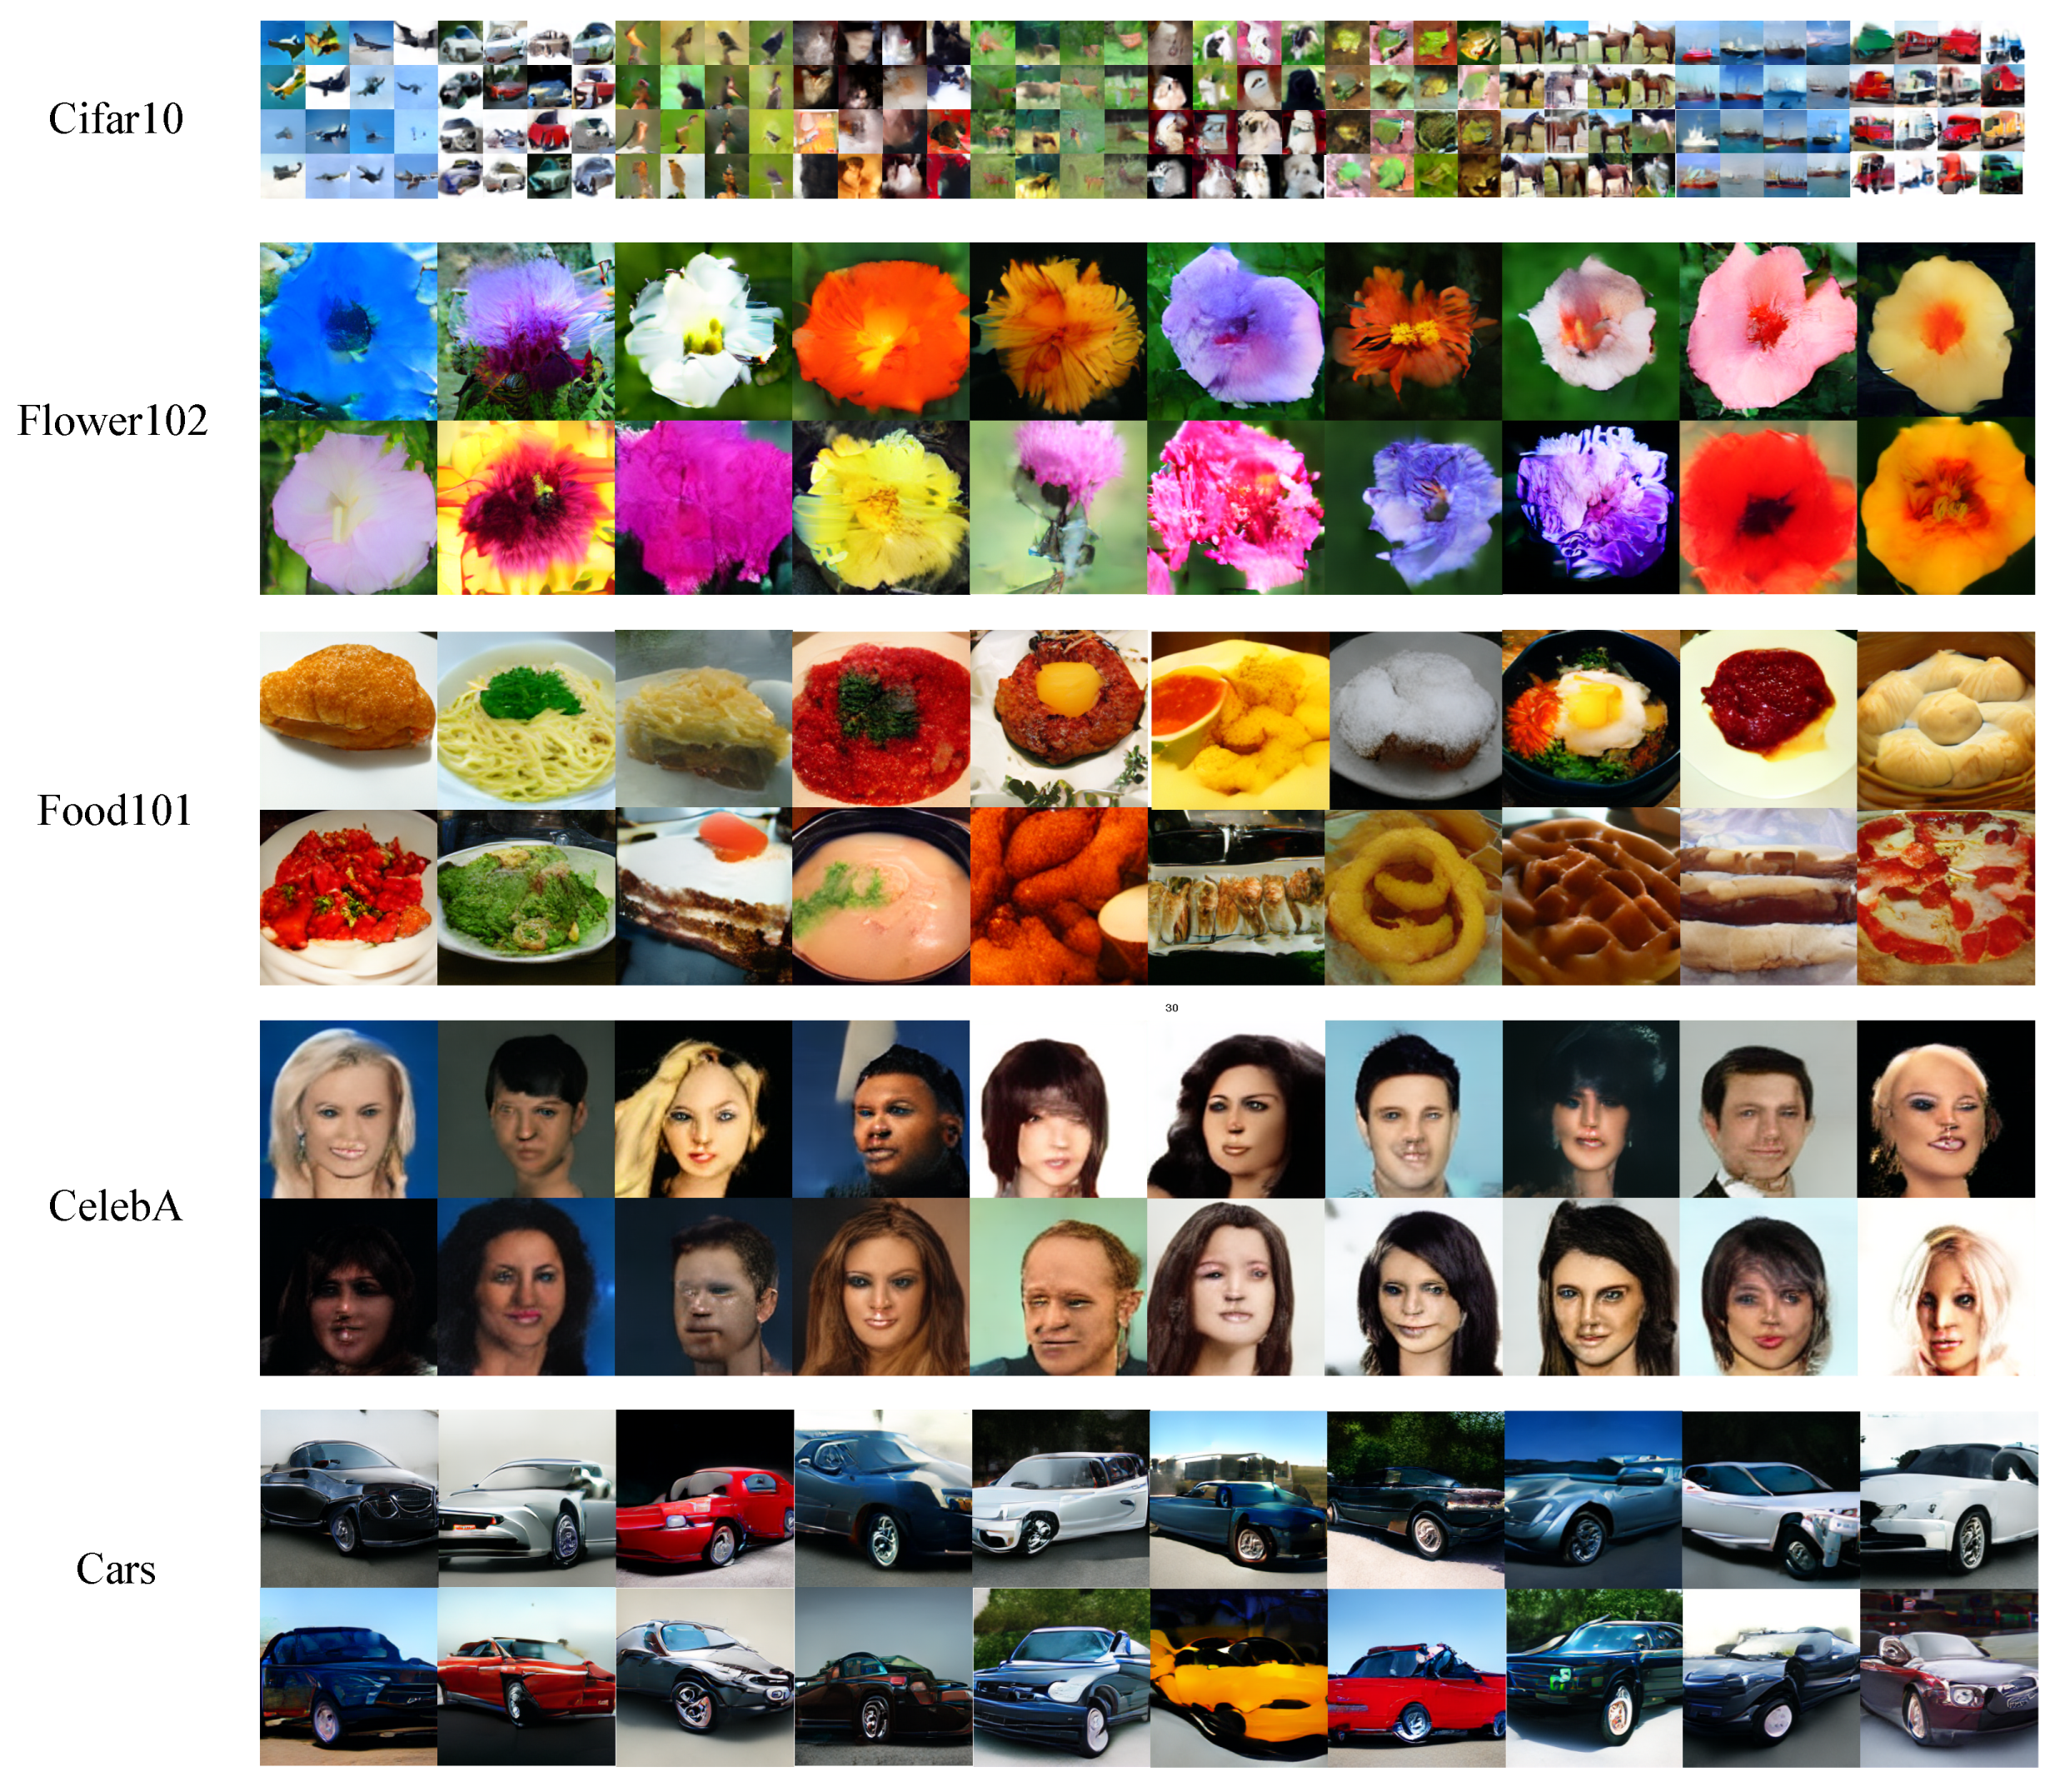
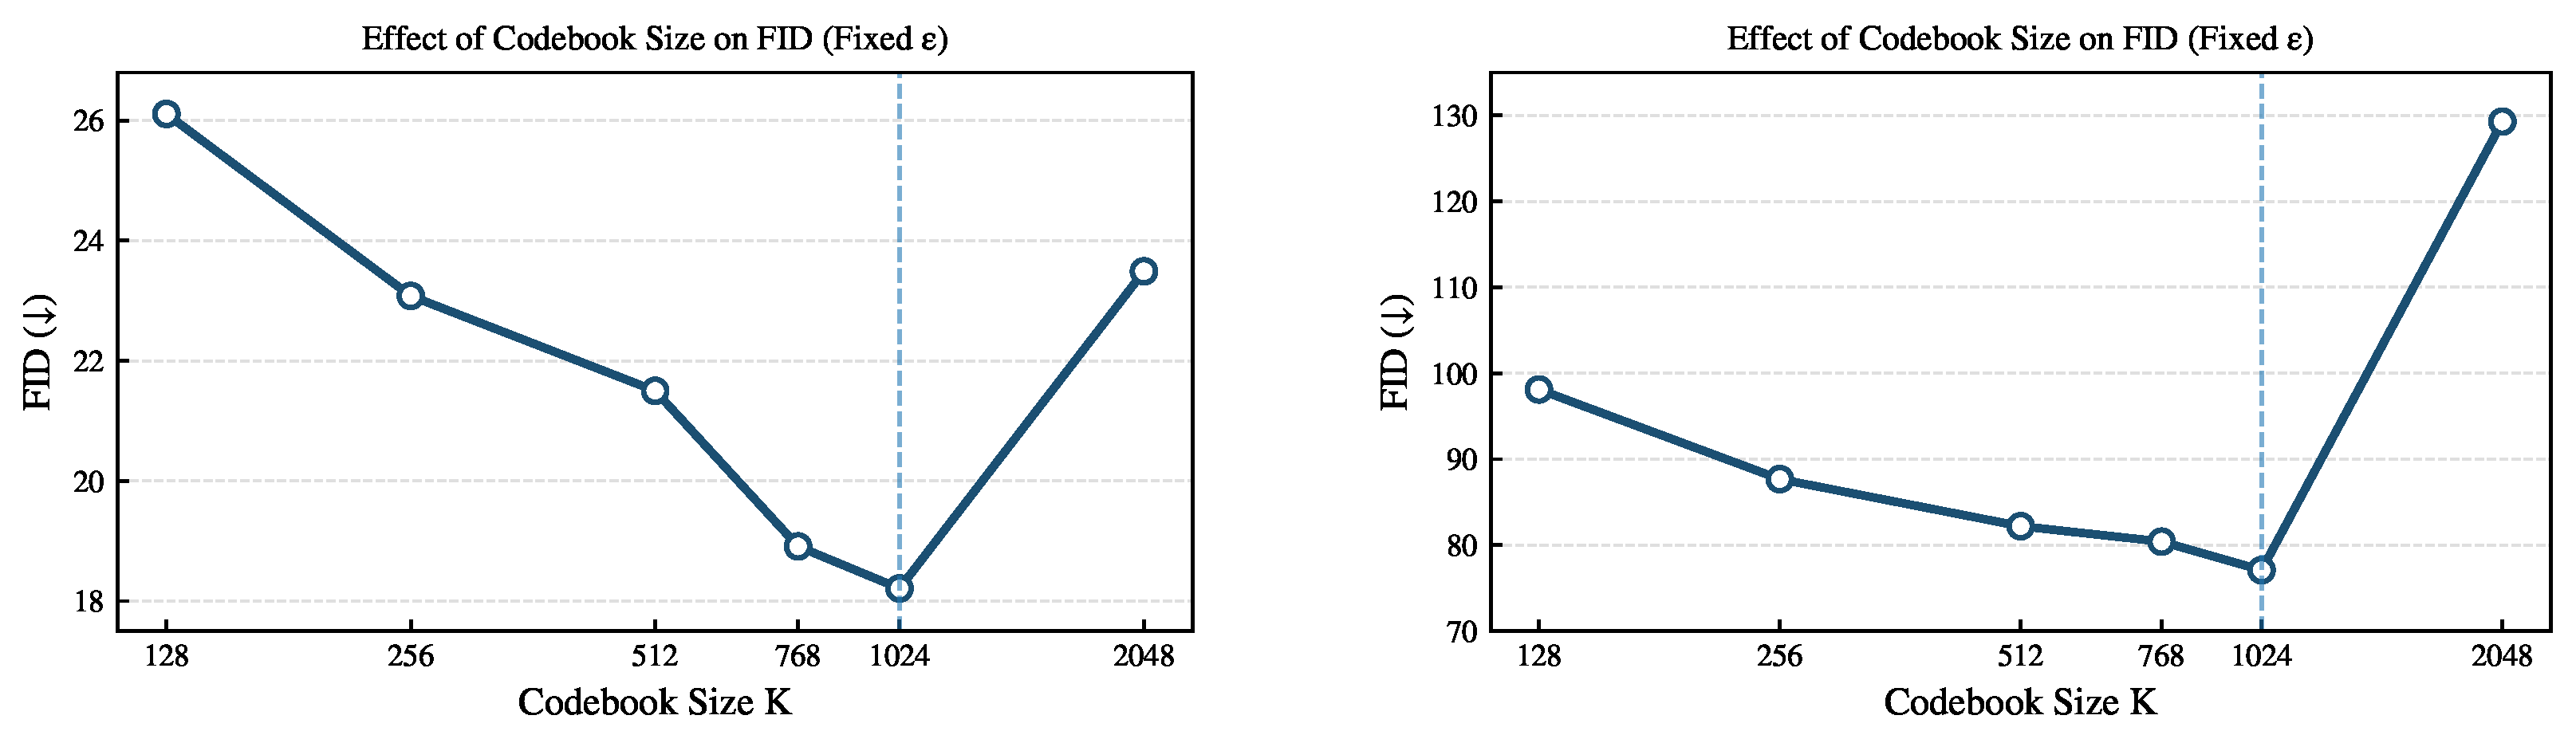
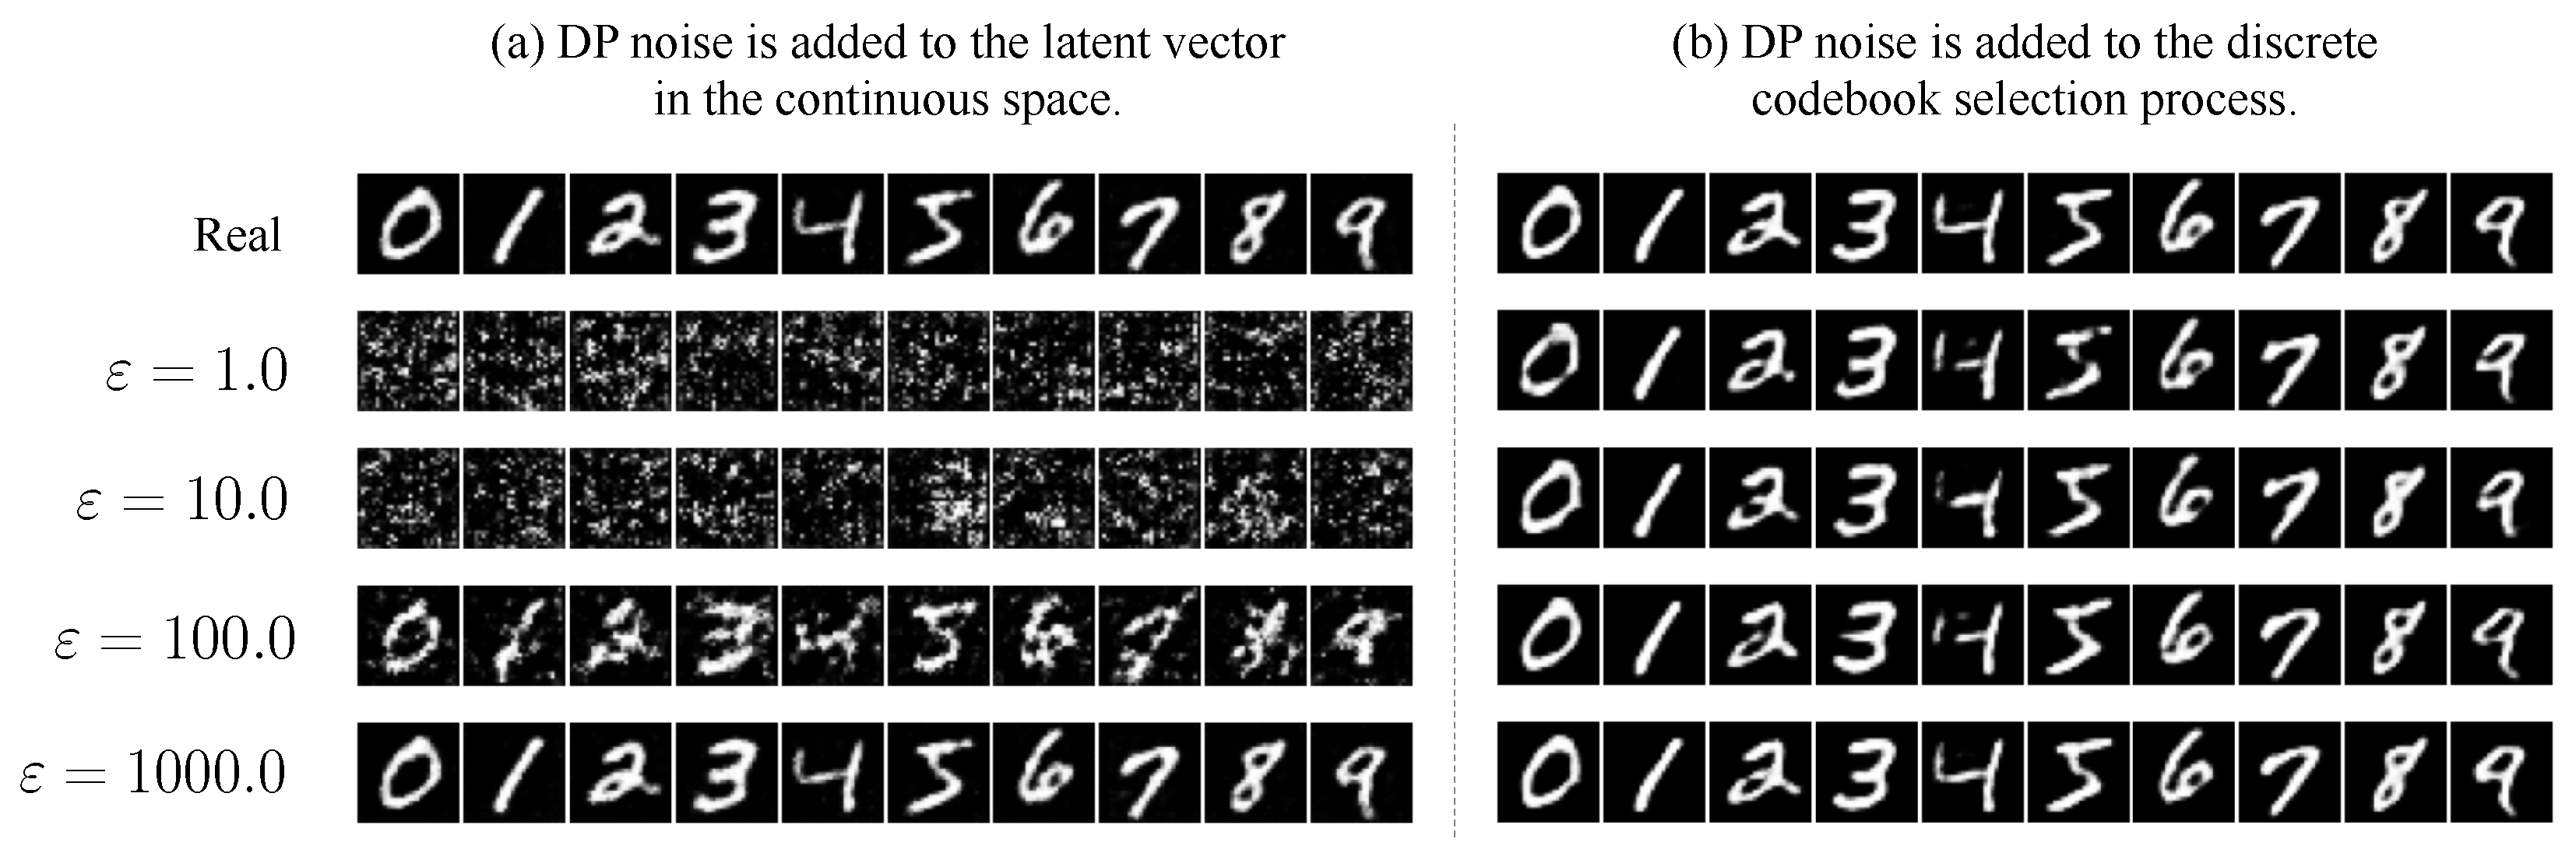

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.