


Abstract
Robot semantic navigation has received significant attention recently, as it aims to achieve reliable mapping and navigation accuracy. Object detection tasks are vital in this endeavor, as a mobile robot needs to detect and recognize the objects in the area of interest to build an effective semantic map. To achieve this goal, this paper classifies and discusses recently developed object detection approaches and then presents the available vision datasets that can be employed in robot semantic navigation applications. In addition, this paper discusses several experimental studies that have validated the efficiency of object detection algorithms, including Faster R-CNN, YOLO v5, and YOLO v8. These studies also utilized a vision dataset to design and develop efficient robot semantic navigation systems, which is also discussed. According to several experiments conducted in a Fablab area, the YOLO v8 object classification model achieved the best results in terms of classification accuracy and processing speed.
1. Introduction
Autonomous robot navigation is considered one of the most challenging problems in robotics. It aims to provide a robot with the ability to inspect the area of interest, travel independently, avoid obstacles, and plan a path to the destination point. Autonomous robot navigation involves different functions, from examining the environment and planning paths to building a map of the area of interest [1].
To achieve these tasks, existing robot navigation systems can be separated into two main categories: geometric and semantic navigation systems. The former employs range-finder methods to build a geometry map. In contrast, the latter adopts complicated sensing units, including vision systems, to construct a semantic map with rich information about the area of interest [2].
Robot semantic navigation is complicated because it involves adopting computer vision and deep learning techniques for understanding and navigating the environment based on semantic information, where the goal is to go beyond basic obstacle avoidance and enable robots to recognize and interpret the meanings of objects and structures in their surroundings [3].
World representation is considered one of the most significant issues in the robotics literature. Its importance stems from the necessity of developing an intelligent robot system that can understand the environment to allow the robot to plan, reason, and execute tasks [4].
Recently, robot semantic navigation systems have received considerable attention. Researchers are driven to create a robot platform that understands the navigation environment and acts accordingly. Existing semantic navigation systems gather semantic information via two different systems: LiDAR-based approaches and vision-based systems [5].
The importance of employing a semantic navigation system stems from the requirement of employing mobile robots in complicated environments. Mainly, robot semantic navigation depends on vision systems for the purpose of performing object detection and classification. Therefore, it is important to review, analyze, and assess the efficiency of the recently developed object detection algorithms that have been employed in robot semantic navigation approaches.
Hence, this paper presents an investigation and analysis on the existing vision-based systems that can be employed in robot semantic navigation systems. In addition, it presents experimental studies using the COCO vision dataset to validate the efficiency of different object detection methods in robot semantic navigation applications. It offers reliable guidance for developing an efficient robot semantic navigation system. The main contributions of this paper lie in the following aspects:
- It reviews object detection algorithms that have been employed in robot semantic navigation systems.
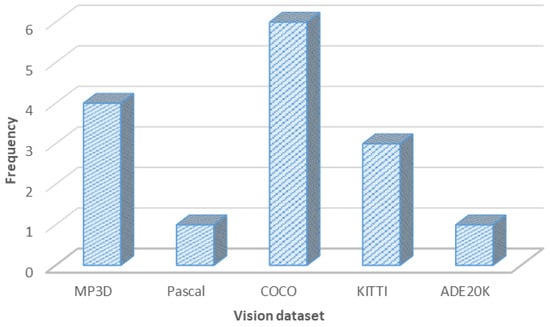
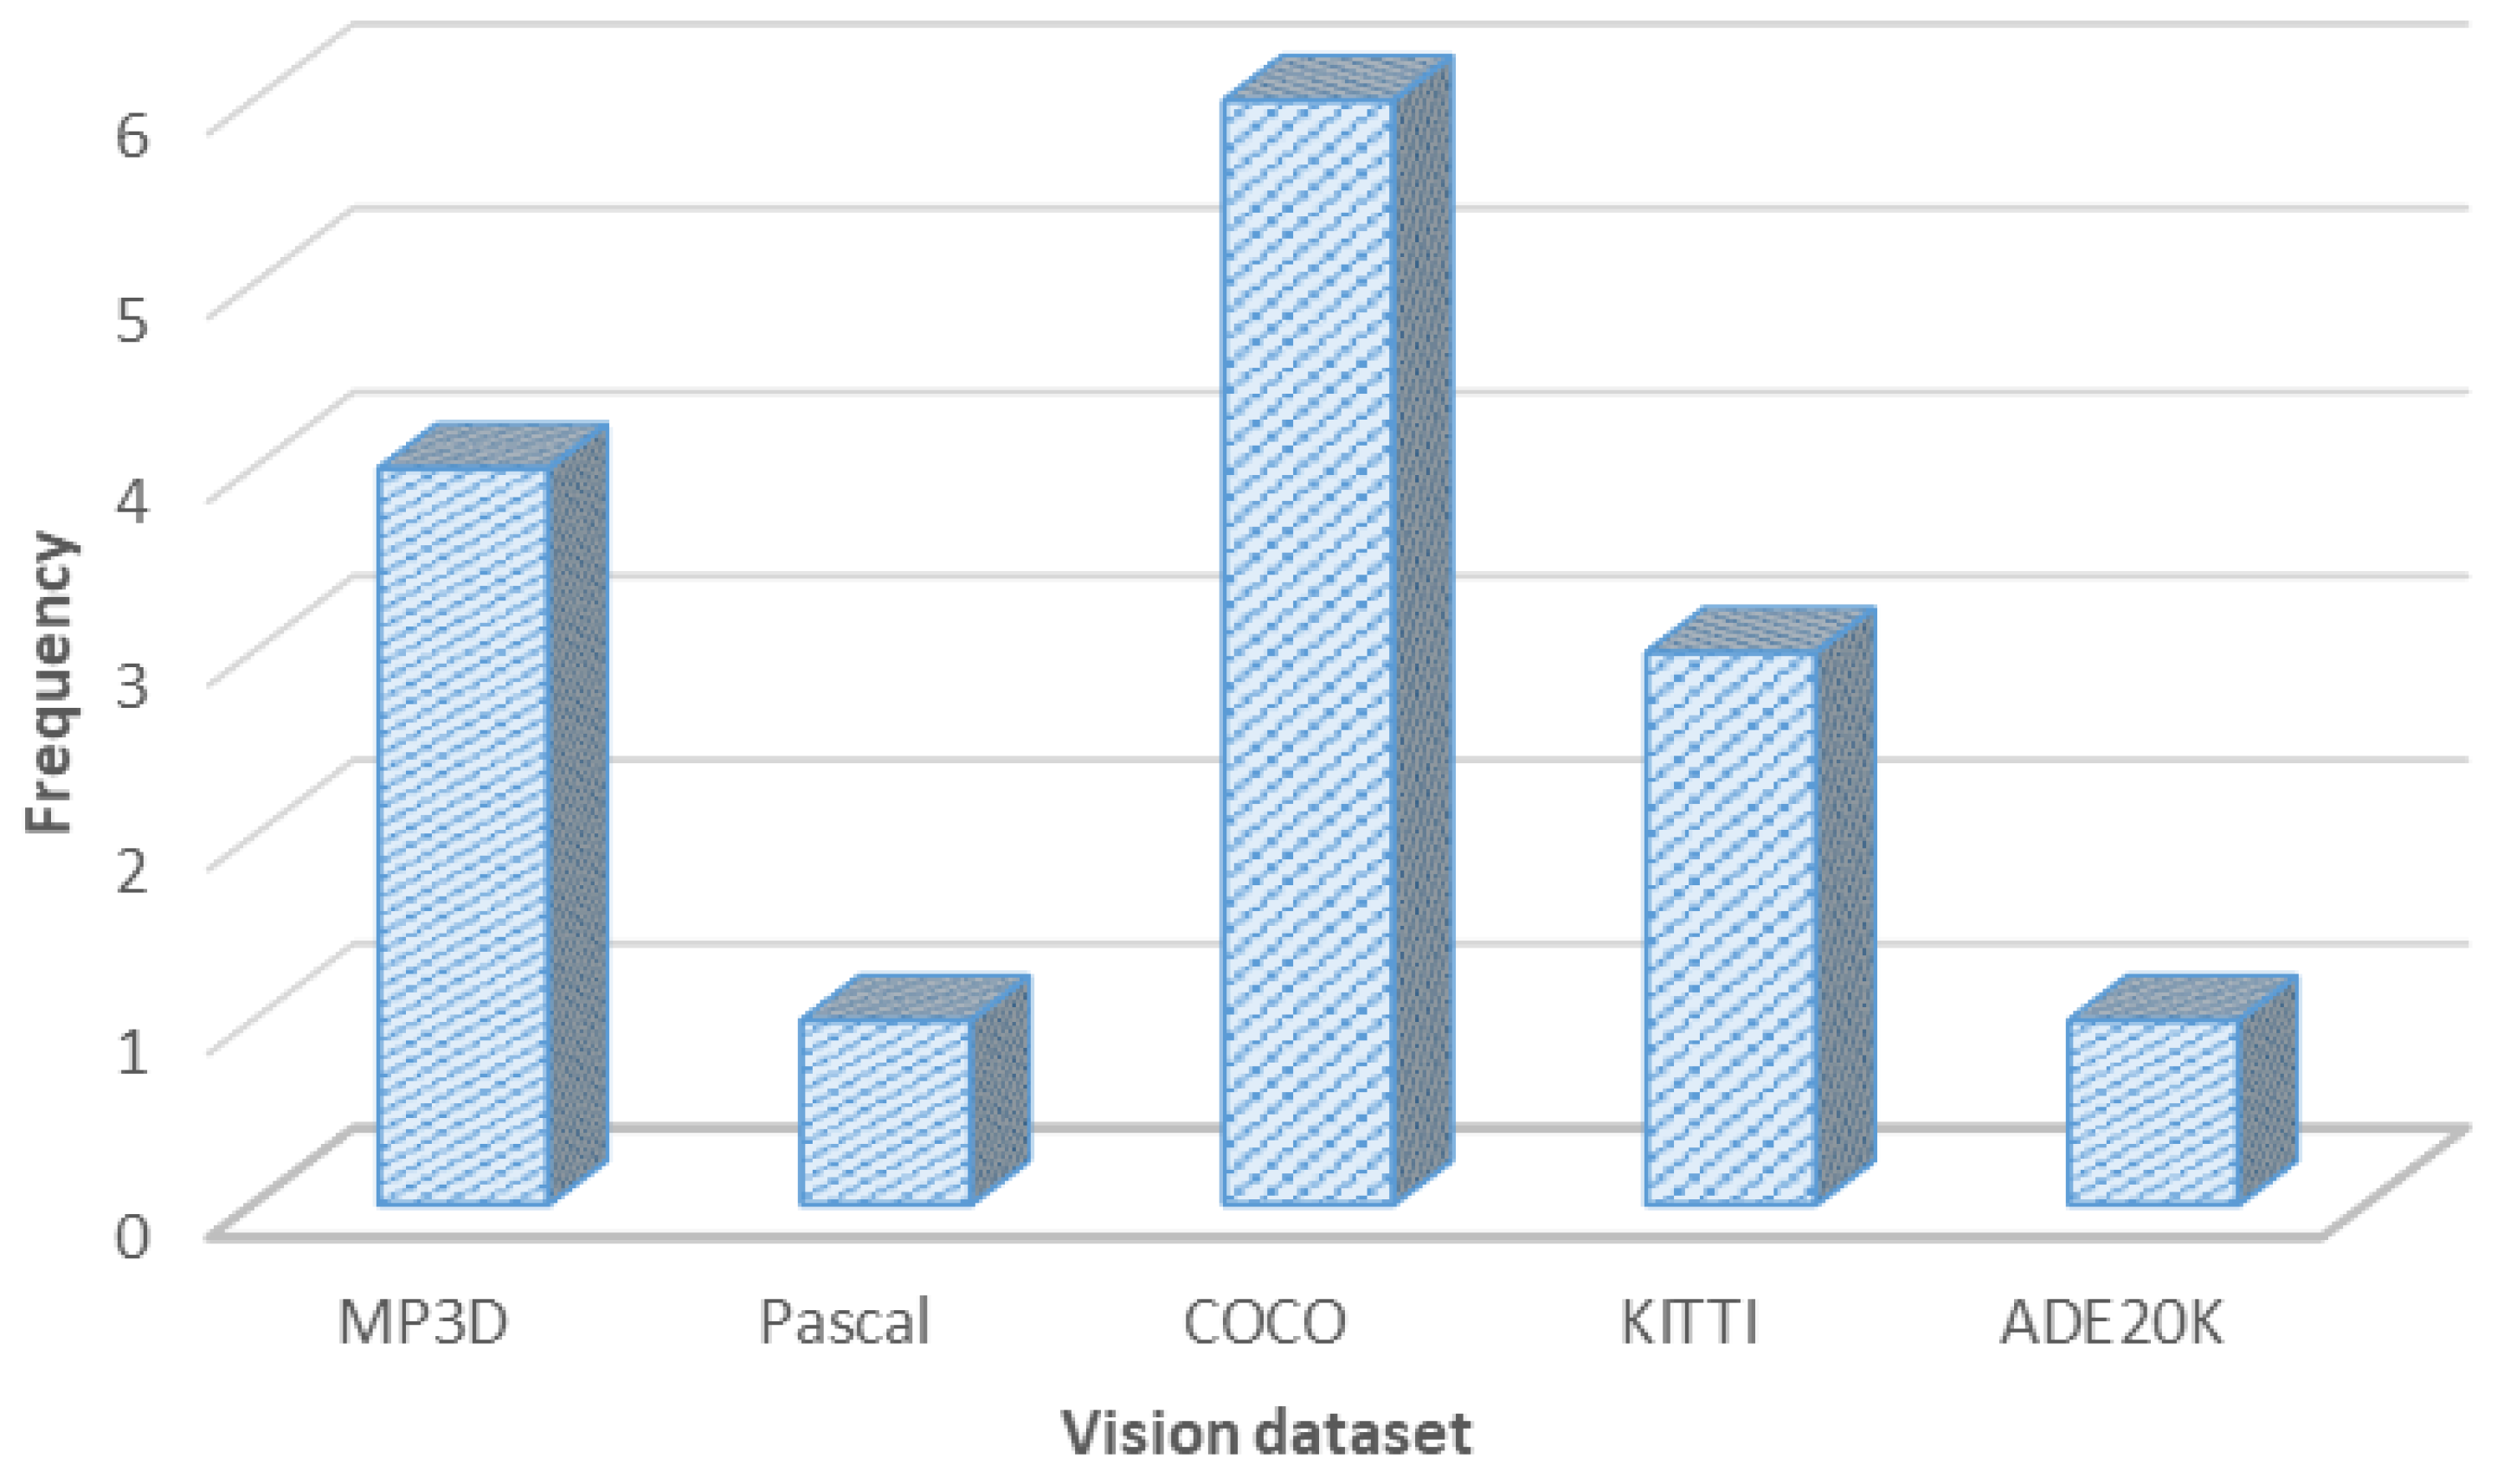
- It discusses and analyzes existing vision datasets for indoor robot semantic navigation systems.
- It validates the efficiency of several object detection algorithms along with an object detection dataset through several experiments conducted in indoor environments.
The remainder of this paper is organized as follows: Section 2 discusses recently developed object detection algorithms that have been employed for robot semantic navigation systems. Section 3 discusses different vision datasets, whereas Section 4 presents several experimental studies to assess the efficiency of three different object detection systems. Section 5 discusses the obtained results, and finally, Section 6 concludes the paper.
4. Experimental Study
This section discusses the experimental studies that were conducted to assess the efficiency of various object detection algorithms in robot semantic navigation systems. In addition, it discusses the robot platform designed to validate the efficiency of three object detection algorithms in the experimental environment.
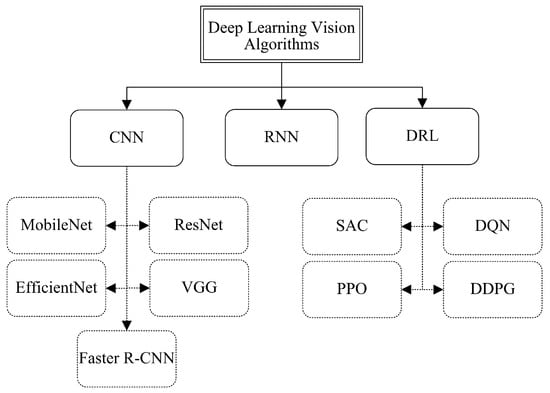
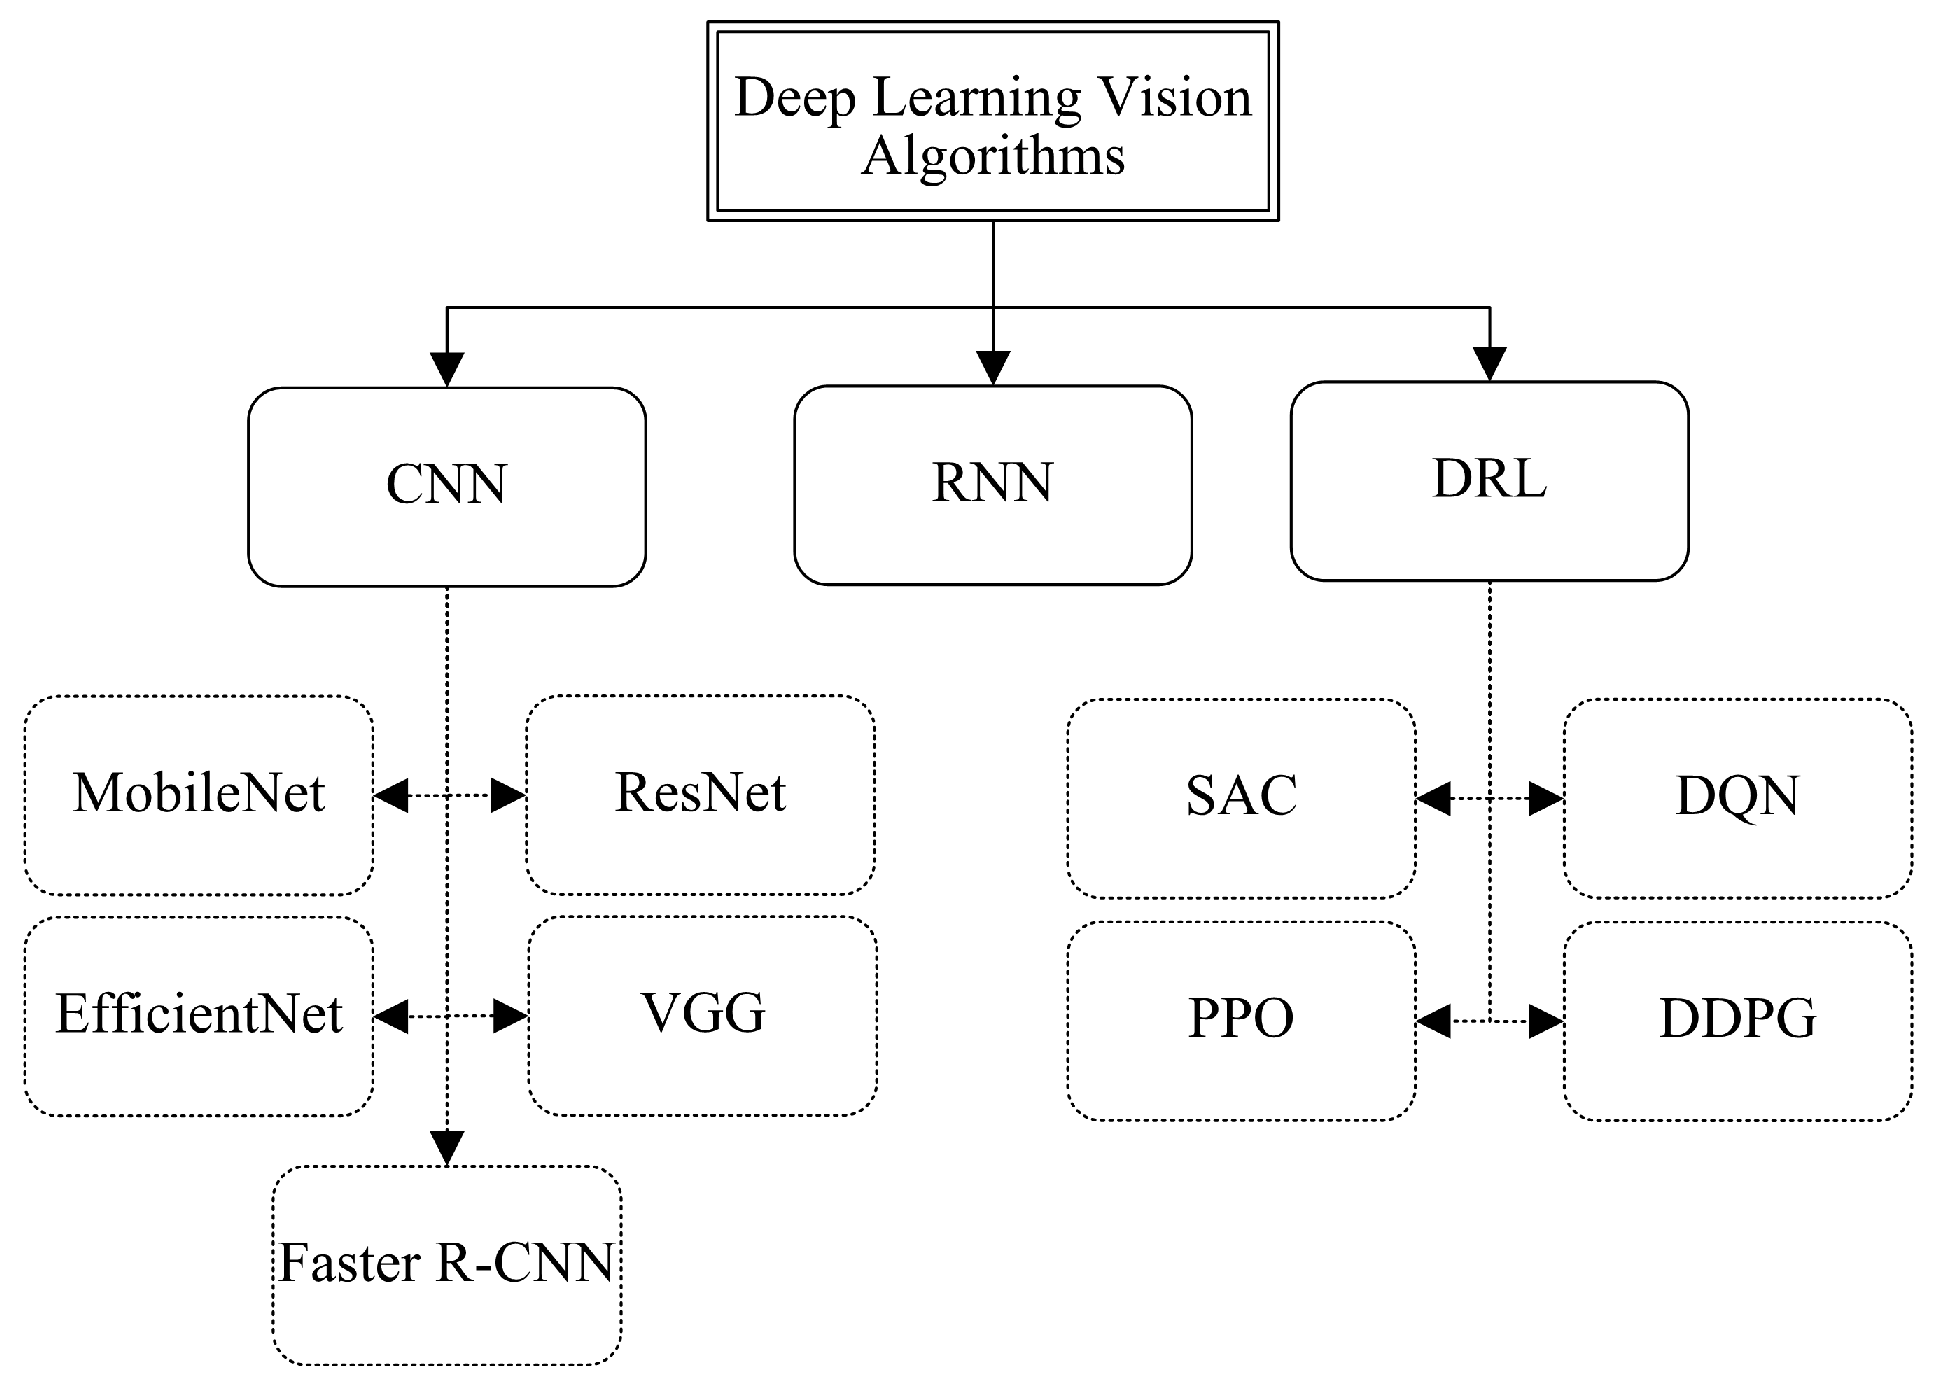
As outlined earlier in Section 2 (Object Detection Algorithms for Robot Semantic Navigation), recent developments in robot semantic navigation have predominantly emphasized CNN-based methodologies. This emphasis is often attributed to the ability of CNNs to effectively process spatial information, making them well suited for tasks such as scene understanding and environment perception in navigation scenarios.
While RNNs excel in capturing sequential dependencies and RL models in learning through interaction with environments, the specific demands of robot semantic navigation, which heavily rely on spatial data processing and real-time decision making, align more closely with the strengths of CNN architectures. This specialization allows for efficient feature extraction and mapping, crucial for successful navigation tasks.
Given these considerations and the current landscape of research in robot semantic navigation, we opted to concentrate on CNNs for our experimental evaluation to provide a focused and relevant analysis within the context of this study.
4.1. Environment Development
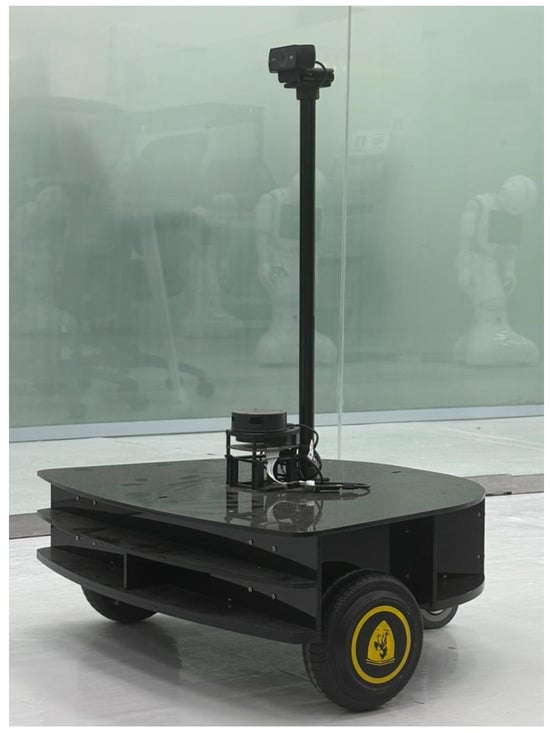
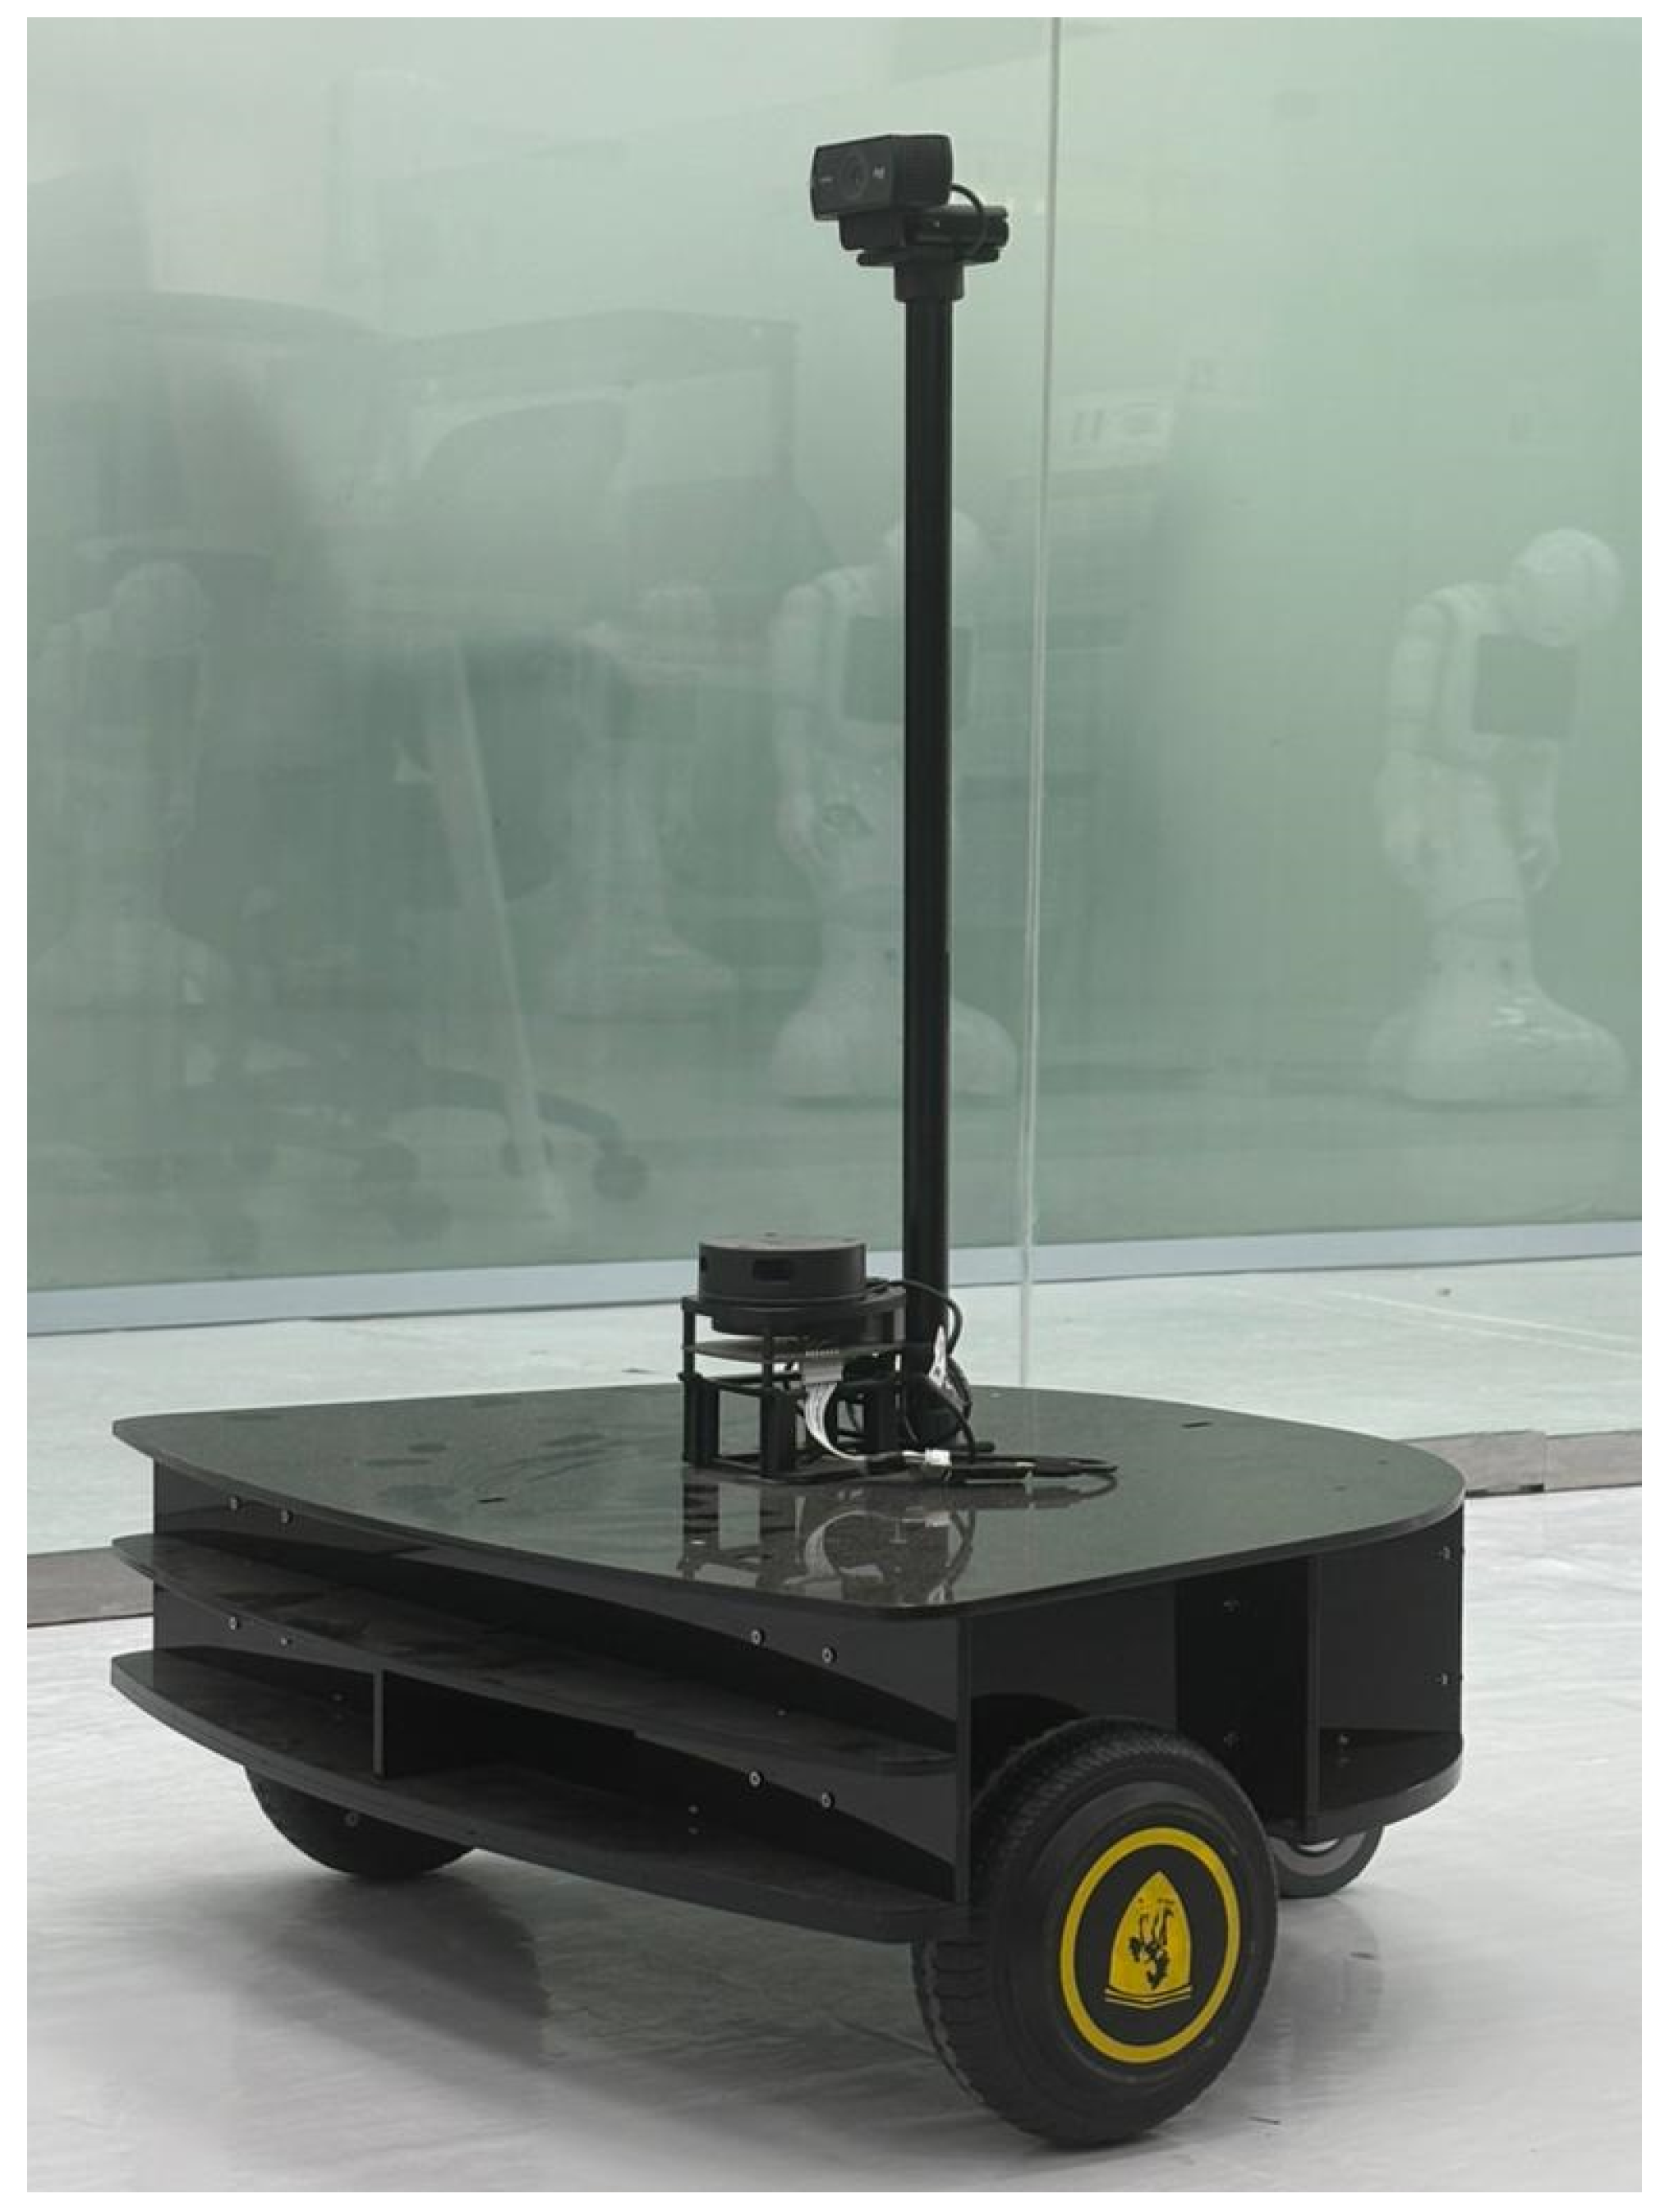
This subsection delves into the details of the robot platform and the experimental environment used in this study. To ensure the validity of our results, this research utilized a two-wheel drive robot platform as depicted in Figure 4. This platform was built using a Raspberry Pi 4 computer [75] and incorporates essential components for comprehensive environmental sensing and perception.
Figure 4.
The employed robot platform.
One crucial component is the RPLiDAR A1 unit [76], which plays a vital role in the robot’s environmental sensing capabilities. The RPLiDAR A1 is a LiDAR sensor that utilizes laser technology to precisely measure distances and generate a detailed 2D point cloud map of the surroundings. This enables the robot to perceive its environment accurately and create a representation of nearby objects, obstacles, and the overall spatial layout.
By leveraging the RPLiDAR A1’s scanning capabilities, the developed robot platform can navigate and avoid obstacles in real time, ensuring safe and efficient operation. The generated point cloud data can be processed and analyzed to extract valuable information for various applications, such as mapping, localization, and object recognition.
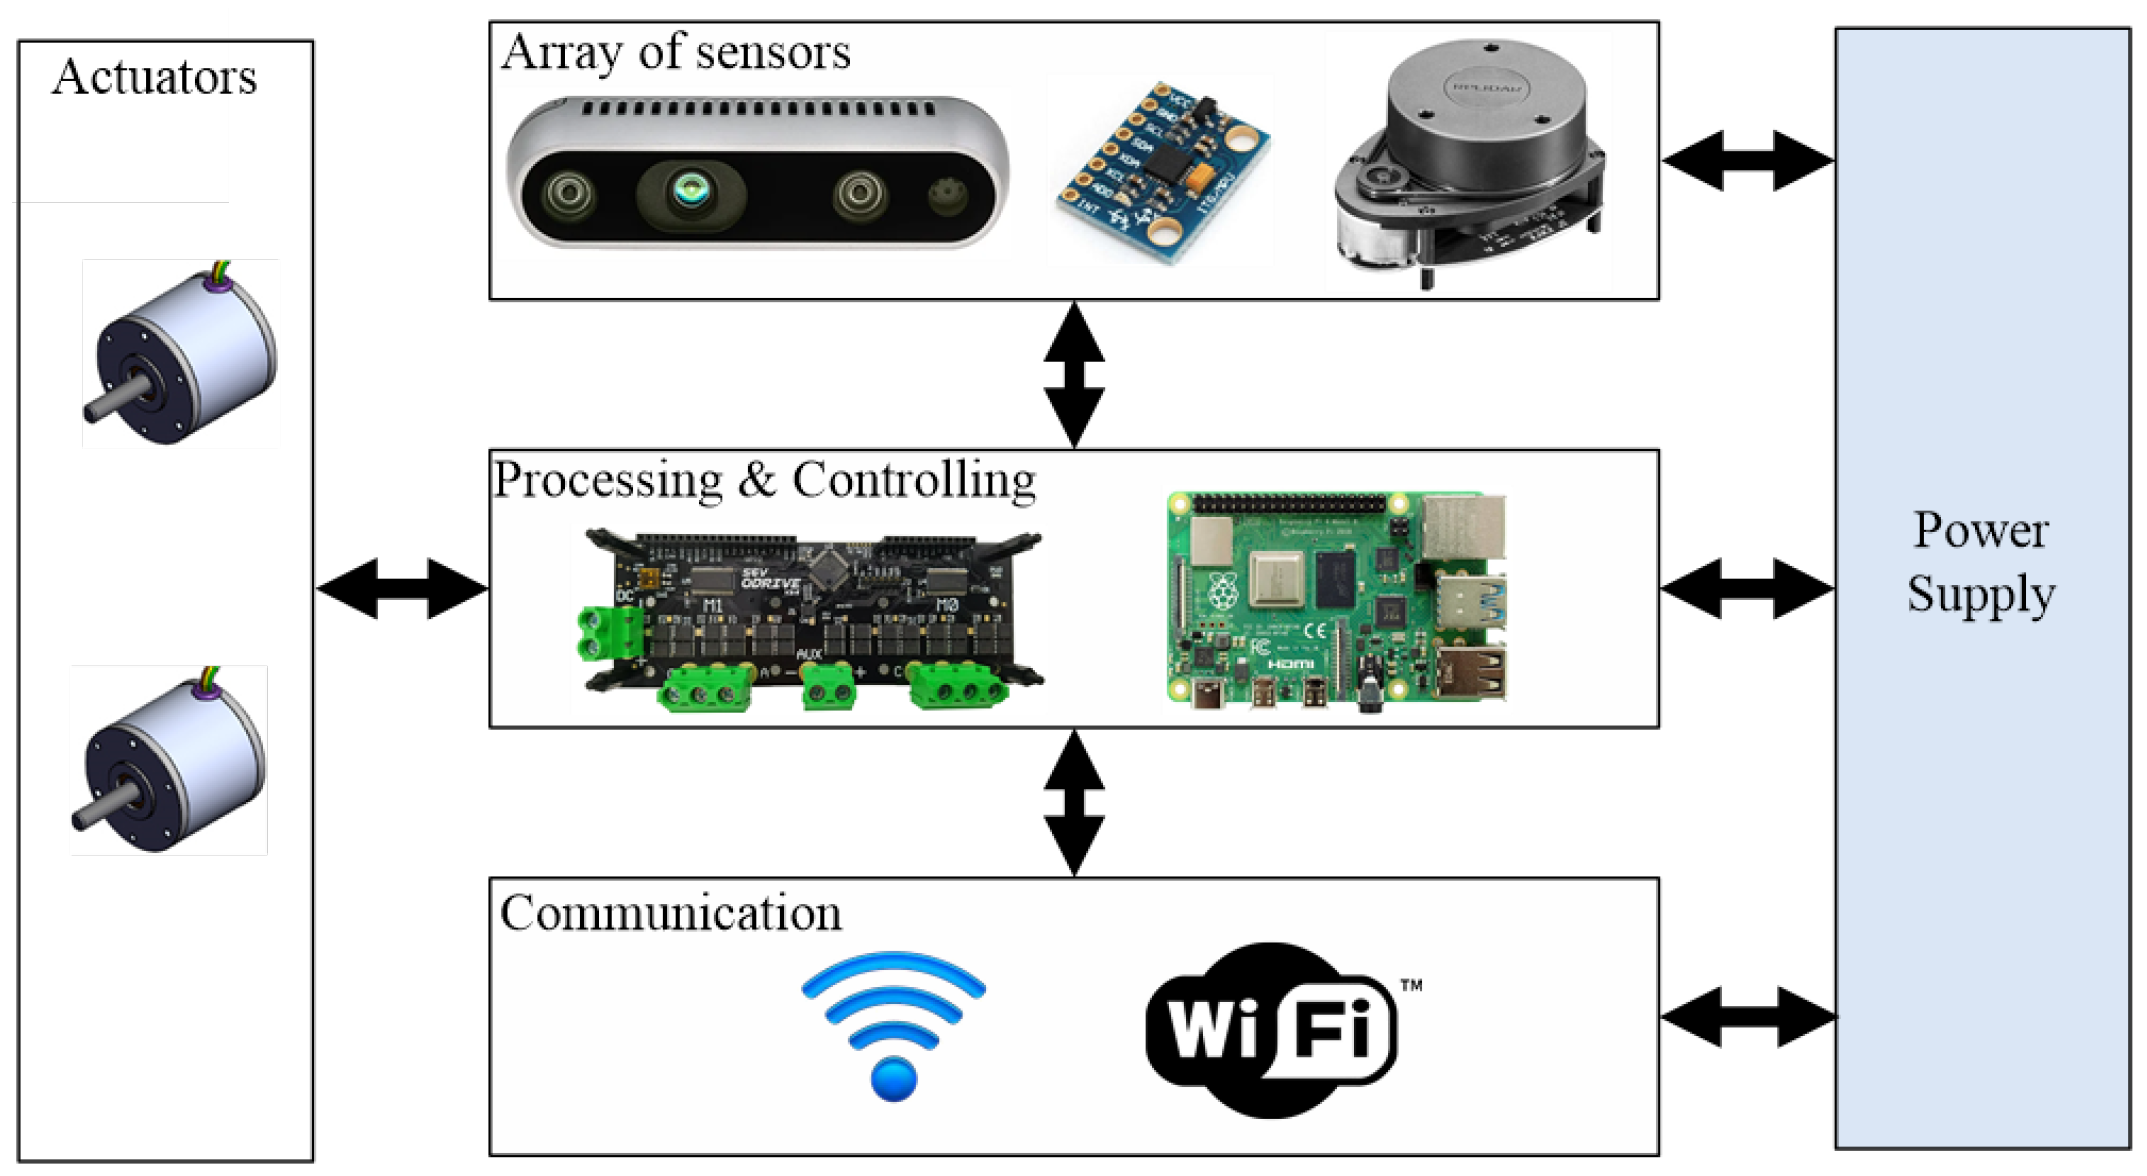
In addition to the RPLiDAR A1, the proposed robot platform also incorporates a Logitech Webcam for visual perception [77], allowing for the capture of real-time video footage. These visual data, combined with the LiDAR-based point cloud information, enable a more comprehensive understanding of the robot’s surroundings, facilitating tasks such as object detection, tracking, and scene understanding. To provide a comprehensive understanding of the robot’s capabilities, its specifications are detailed in Table 2, outlining key parameters such as its dimensions, weight, power supply, and communication interfaces. Moreover, the robot architecture is presented in Figure 5, which involves the main units of the employed robot platform.
Table 2.
The specifications of the developed mobile robot.
Figure 5.
The robot architecture in terms of employed hardware units.
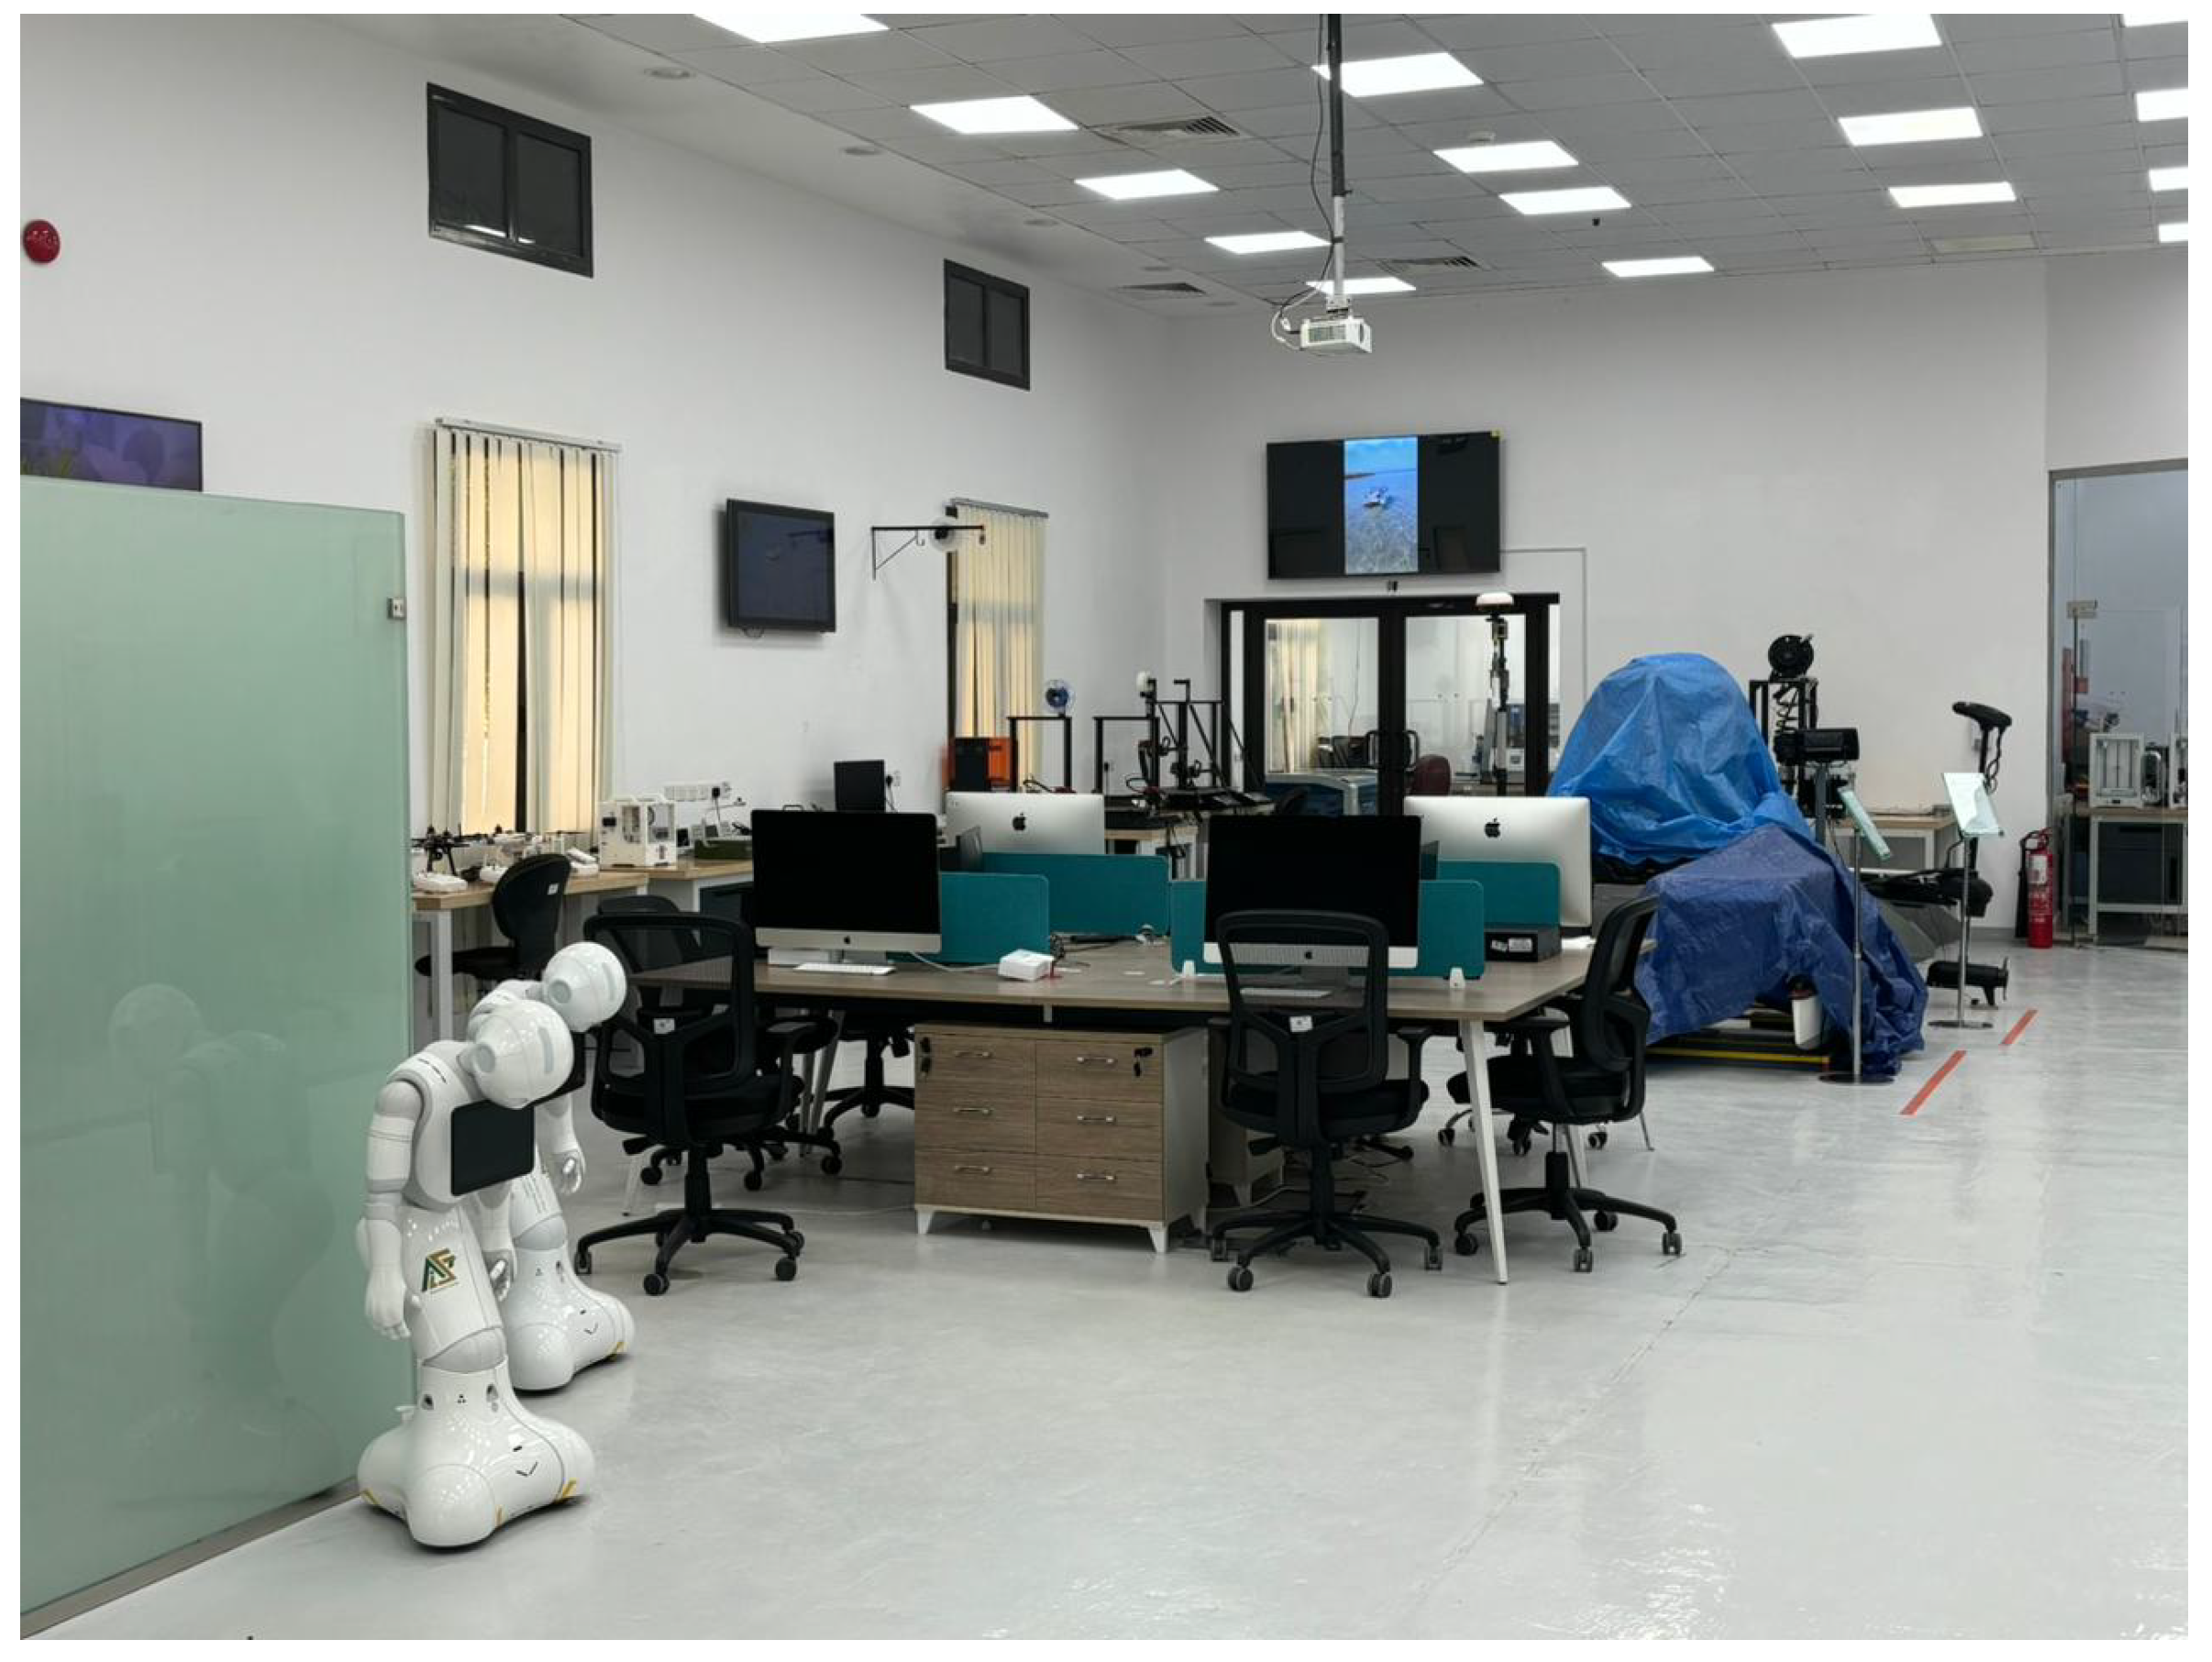
The experimental studies were conducted at the state-of-the-art Artificial Intelligence and Sensing Technologies (AIST) research center at the University of Tabuk. This facility provided an ideal setting for our research, equipped with a diverse range of components including a pepper robot, fish tank, 3D printer, whiteboards, computers, furniture, plants, TV, and various other items. The center’s environment, though challenging for robot navigation due to its crowded nature, offers a compact testing area of approximately 2000 ft2, as depicted in Figure 6.
Figure 6.
The Artificial Intelligence and Sensing Technologies (AIST) research center—experimental testbed.
For a comprehensive evaluation, this study meticulously assessed the efficiency and performance of three state-of-the-art object detection algorithms: YOLO v5, YOLO v8, and Faster R-CNN. These algorithms were selected based on their proven effectiveness and widespread use in a variety of robot applications, exemplifying their suitability for these evaluation objectives.
To ensure a robust evaluation, this research employed the widely recognized COCO dataset in its experimental studies. The COCO dataset is renowned for its extensive collection of annotated images, encompassing a diverse range of indoor objects. By leveraging this dataset, the researchers were able to evaluate the algorithms’ capabilities in detecting and recognizing various objects commonly encountered in indoor environments.
In utilizing the COCO dataset, the proposed evaluation encompassed a wide array of object categories, ensuring a comprehensive analysis of the algorithms’ performance. This dataset provided a solid foundation for assessing the algorithms’ accuracy, generalization, and suitability for real-world robot applications.
Through a rigorous evaluation process, this study aimed to provide valuable insights into the strengths and limitations of the YOLO v5, YOLO v8, and Faster R-CNN algorithms, enabling informed decisions regarding their adoption and utilization in robotic systems.
4.2. Experimental Results
The obtained results are discussed in this subsection, where the employed object detection models are assessed by analyzing three different validation metrics, object detection rate, object detection accuracy, and processing time, which are defined as follows:
- Object detection rate (ODR): This refers to the total number of objects that were successfully detected (true positive detections) using the employed object detection model, denoted as ‘’ in Equation (1), compared to the total number of existing objects in the environment, and referred to as ‘’ in the following equation:
- Object detection accuracy: This refers to the classification accuracy of the object detection model. In our study, we utilized the mean Average Precision metric to evaluate the model’s performance comprehensively. The aggregates precision scores across classes. Here is how it can be mathematically described.Let
- represent the Average Precision value for class i;
- N be the total number of classes.
The is calculated by averaging the across all classes, as follows:In this equation, the for each class is calculated individually, and then the mean of these values is calculated to obtain the score. To get to this point, we have to calculate the for class i, as shown in the following equation:where is the precision at recall level r, and is the change in recall from the previous recall level.The for a given class i is calculated by adding the precision values at various recall levels and weighting them by calculating the change in the recall. This technique aids in assessing how well the model detects objects of a certain class at varying confidence levels.The following is how to calculate both and in the average precision:- (a)
- Finding at a Specific Recall Level r:
- To calculate precision at a specific recall level r, we need to consider the precision value associated with the highest recall that is less than or equal to r, as follows:
- The precision at a specific recall level is the maximum precision value for all detections with a recall greater than or equal to that recall level.
- (b)
- Determining (change in the Recall):
- represents the change in recall from the previous recall level to the current recall level in the precision–recall curve, and it is calculated as follows:
- For each recall level, can be calculated as the difference between the current recall level and the previous recall level.
By computing precision at different recall levels and measuring the change in recall from one level to the next, we can effectively determine the precision–recall curve and subsequently calculate the for a specific class in object detection tasks.Finally, to determine the recall and precision for each class, we used the following equations:Precision:Recall:where- True Positives : Instances that the model correctly identifies as positive.
- False Positives : Instances that the model wrongly classifies as positive.
- False Negatives : Instances that the model wrongly classifies as negative but are positive.
- Processing time for the object detection model: This refers to the total time required for the model to process the input frames obtained from the vision unit and perform the detection task. The processing time for the object detection model can be calculated as the difference between the end time and the start time of the processing task, formulated as follows:
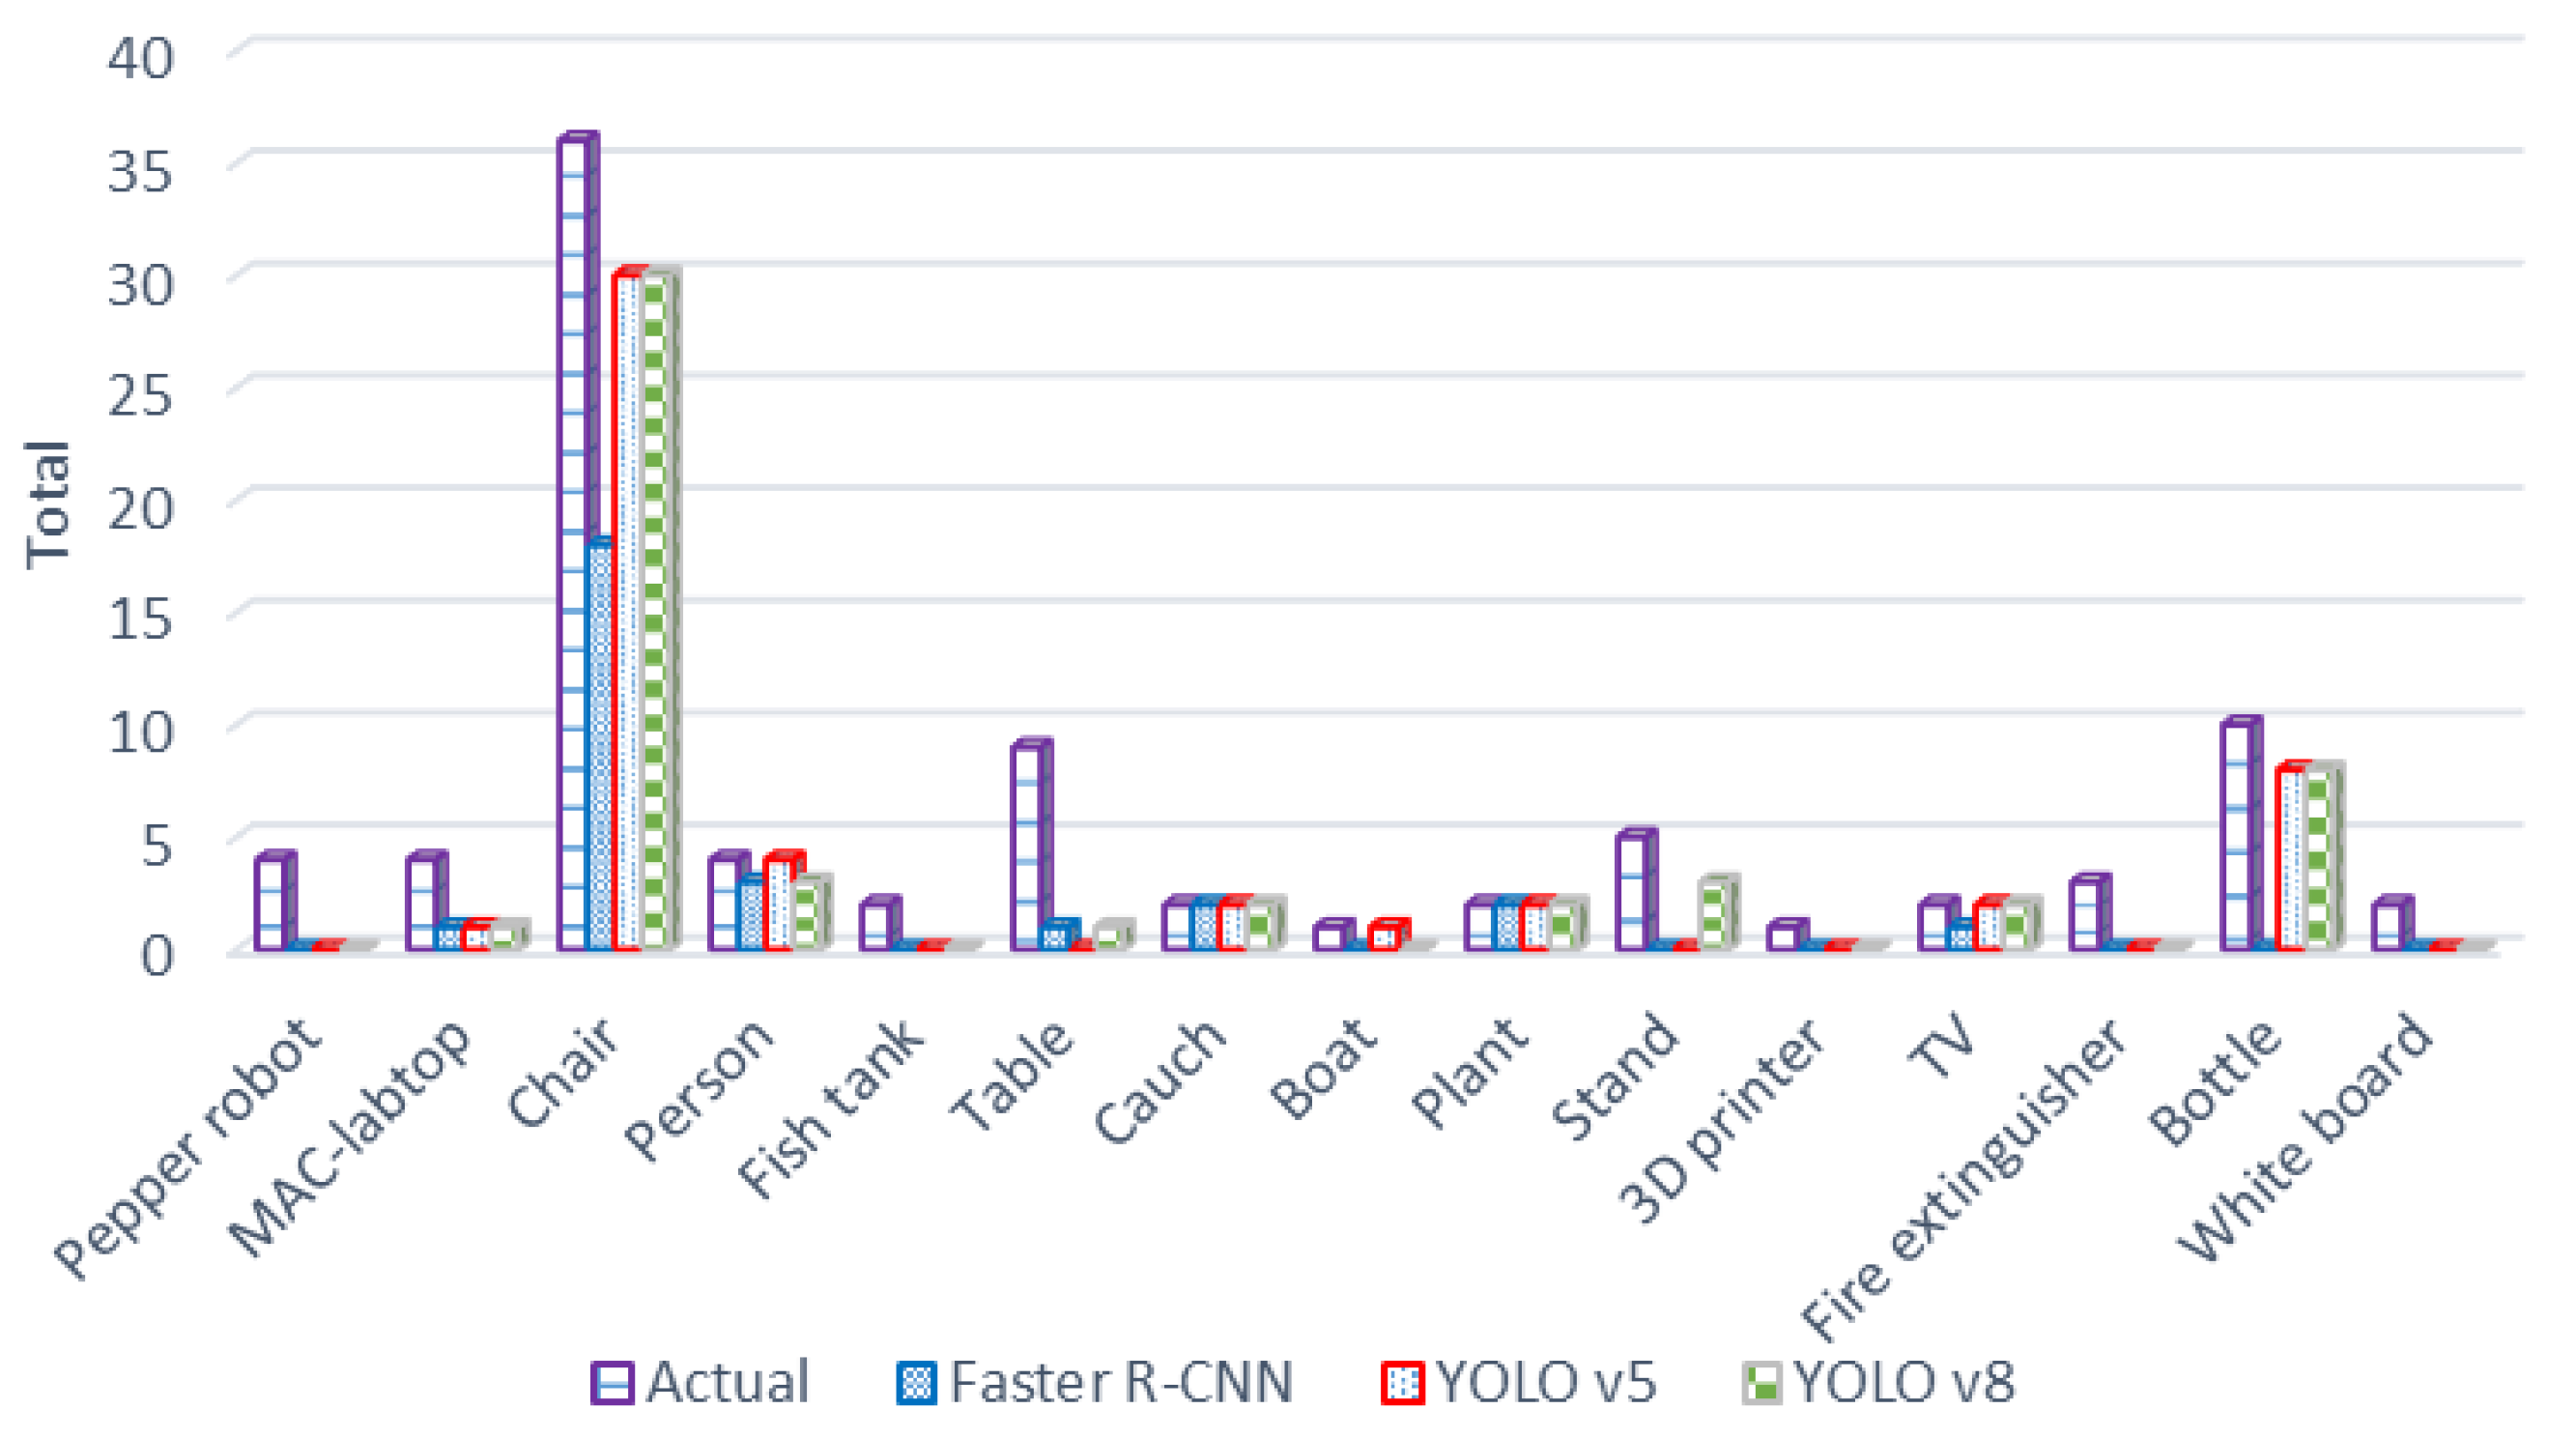
In Figure 7, the object detection rate for the three object detection models is depicted. As presented, YOLO v5 and v8 achieved almost the same object detection rate of 60.91% and 57.47%, respectively. However, the Faster R-CNN model offers the lowest object detection rate across almost all the existing classes, with an average of 32.18%. The main reason for this is the complexity of the Faster R-CNN model, which leads to the slow processing of frames from the RGB camera.
Figure 7.
Object detection rate for 16 classes using three object detection models.
In addition, the object detection rate for all three models was almost zero for a few classes, including the pepper robot, fish tank, 3D printer, and whiteboards, even though the webcam was able to capture the whole scene reliably. However, the COCO dataset does not contain the aforementioned classes. Table 3 presents the object detection rate for each object in the experimental testbed, using the three object detection models.
Table 3.
The object detection of each object in the experimental testbed.
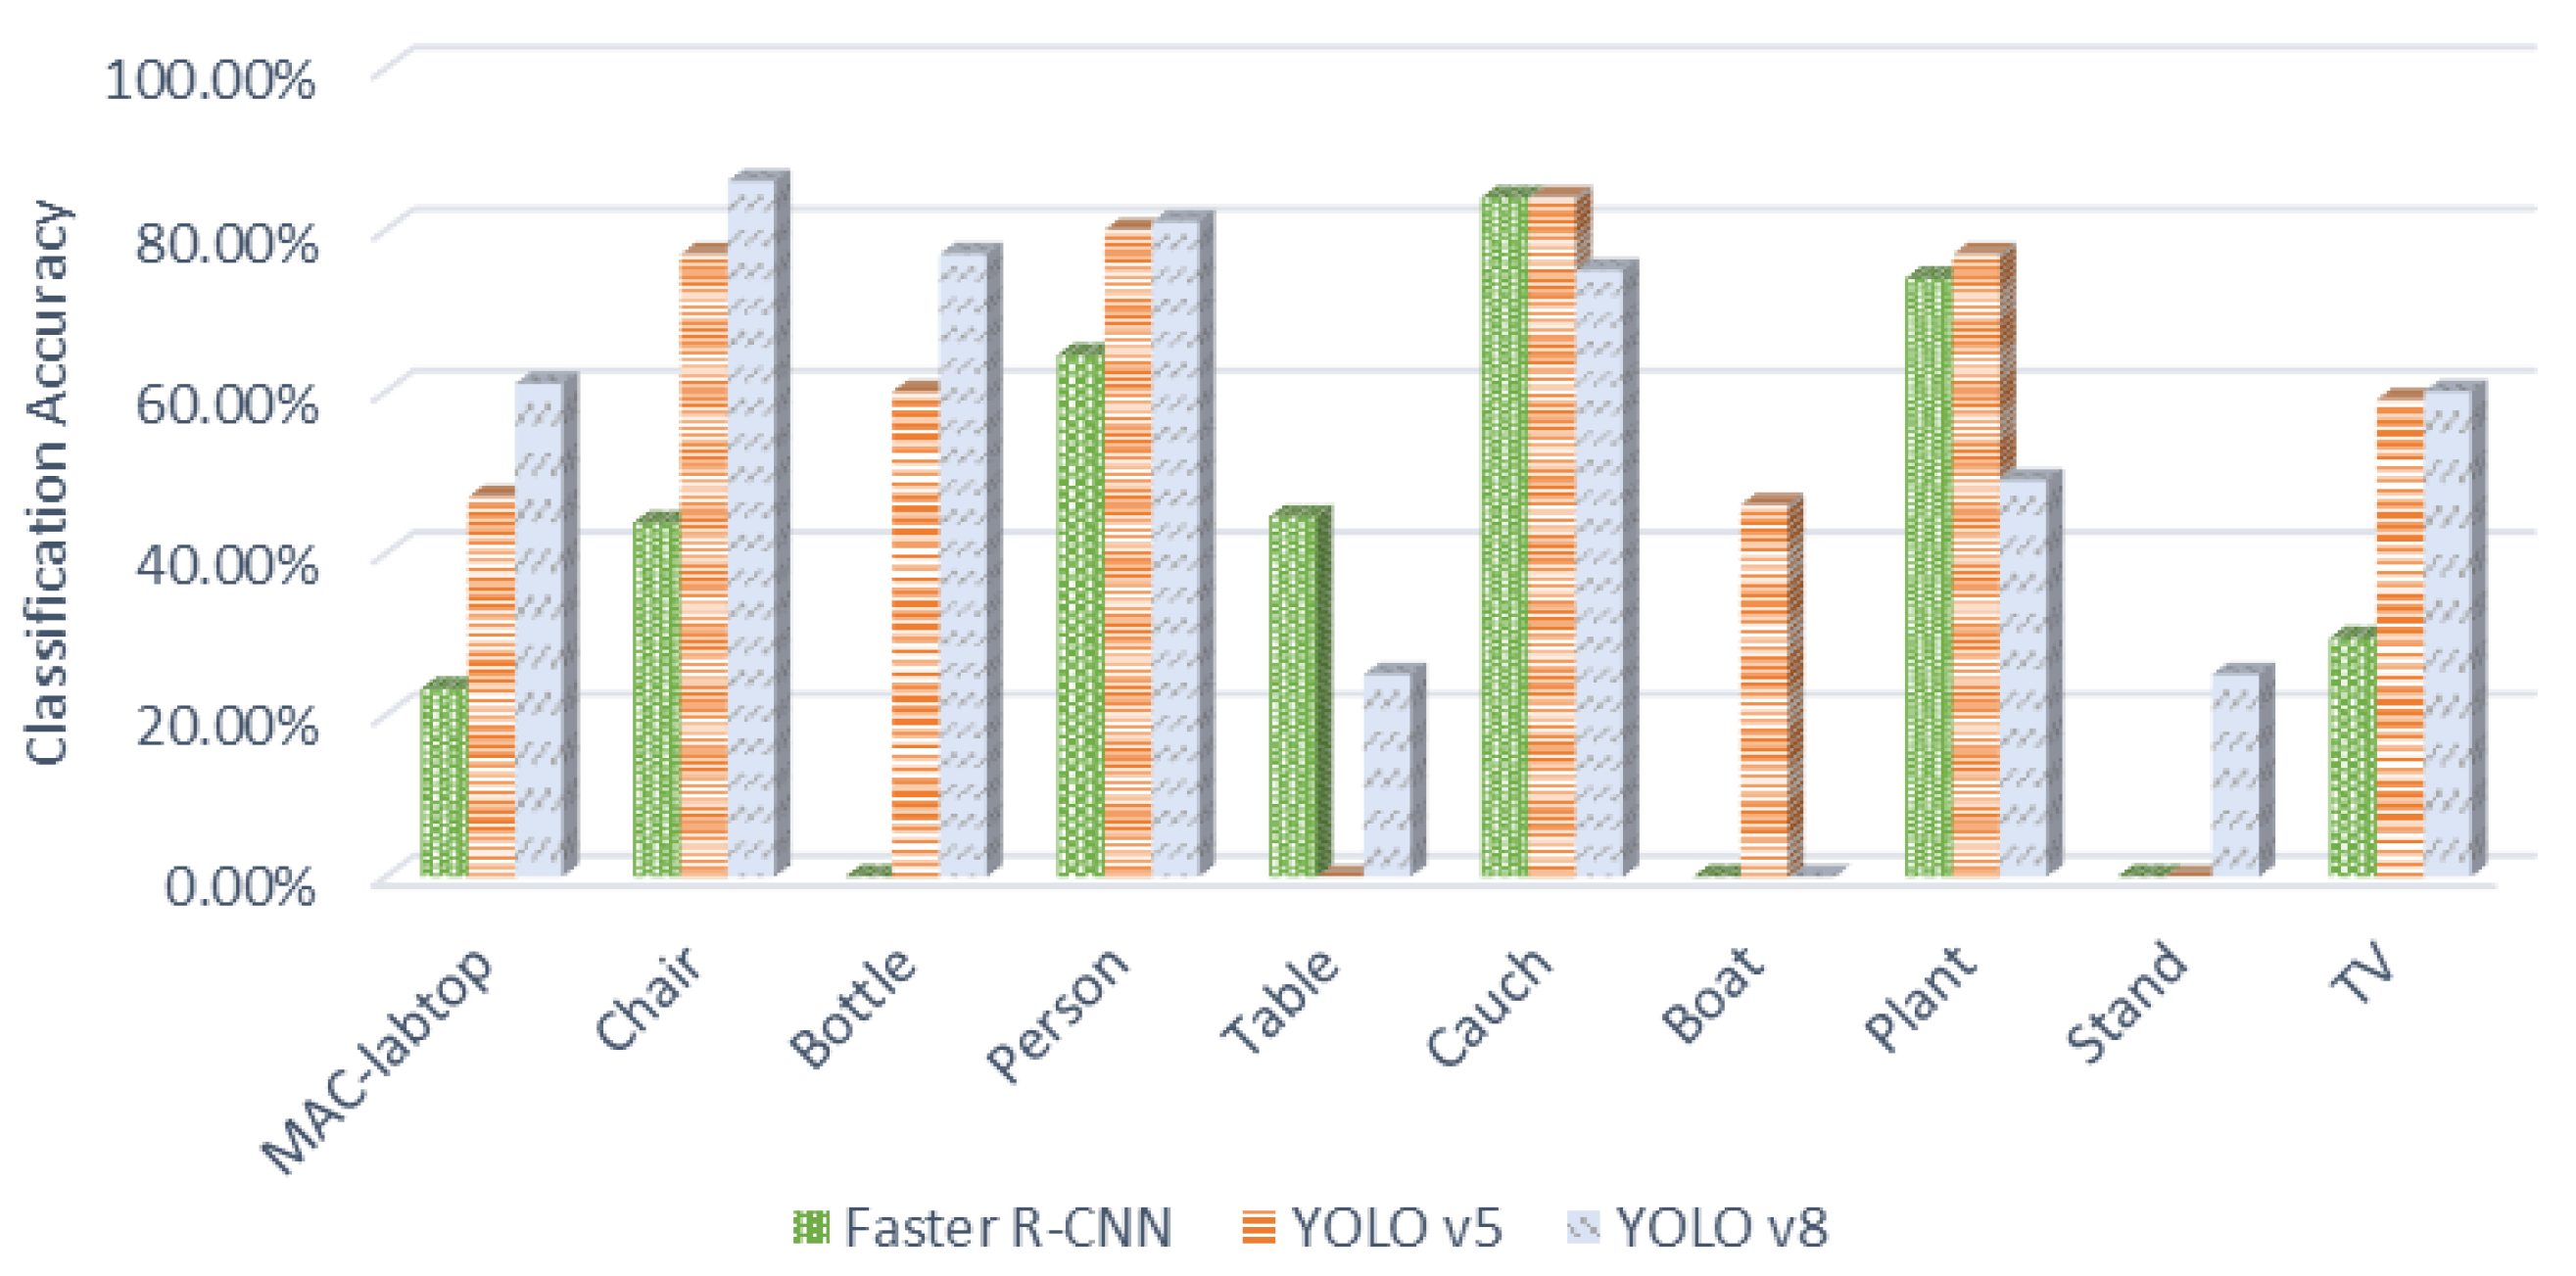
Figure 8 presents the average object detection accuracy for each class by vision detection system. For all the object detection models, the object classification accuracy was estimated. For instance, the average object classification accuracy for YOLO v5 and v8 is 53.90%, and 53.00%, respectively, whereas the Faster R-CNN model achieved the worst object classification accuracy with a percentage of 36.35%. Table 4 presents the classification accuracy for each object in the experiment testbed using the three object detection models.
Figure 8.
Object classification accuracy for three object detection models.
Table 4.
The object classification accuracy for each object in the experimental testbed using three classifiers.
In examining the experimental outcomes, the discrepancies in object detection performance among the models, as evidenced by Figure 8, underscore the nuanced impact of the model architecture and training data on detection capabilities. For instance, the failure of YOLOv5 to detect tables while successfully identifying a boat raises questions about the models’ inherent design choices and the diversity of objects in the training data. This discrepancy prompts a deeper exploration into how the specific architectural features of each model influence their detection prowess in varied scenarios. Moreover, understanding the cases or environments wherein each model excels is crucial for optimizing their applicability. Given the nuances of the COCO dataset, which includes ‘dining tables’ but not explicitly ‘tables’, and features ‘boat’ objects, the detection capabilities of YOLOv5 can be further contextualized. The presence of ‘dining tables’ in the dataset, although slightly different from generic ‘tables’, may explain YOLOv5’s failure to detect tables in our experimental setup. This discrepancy underscores the importance of precise object class definitions within the training data and their impact on model performance.
Conversely, the successful detection of boat instances by YOLOv5 aligns with the model’s exposure to boat objects in the COCO dataset. The dataset’s inclusion of boat annotations likely contributed to YOLOv5’s ability to identify boat objects in our experiments accurately. This highlights the significance of training data composition in shaping a model’s detection capabilities, emphasizing the need for datasets that encompass a diverse range of object classes relevant to the target application scenarios. Understanding these dataset-specific intricacies is essential in interpreting the performance variations observed among object detection models. By considering the subtleties of object class definitions and dataset contents, we can gain insights into how training data characteristics influence model behavior and detection outcomes in real-world environments. This underscores the importance of dataset curation and annotation precision in enhancing the effectiveness of object detection models like YOLOv5 across varied object categories and environmental conditions. Further investigation is warranted to discern the strengths and limitations of each model type, delineating their optimal use cases based on factors such as object complexity, scene clutter, and dataset diversity. By delving into these nuances, we can elucidate the interplay between model architectures, training data composition, and their respective performance in object detection tasks across different environmental contexts.
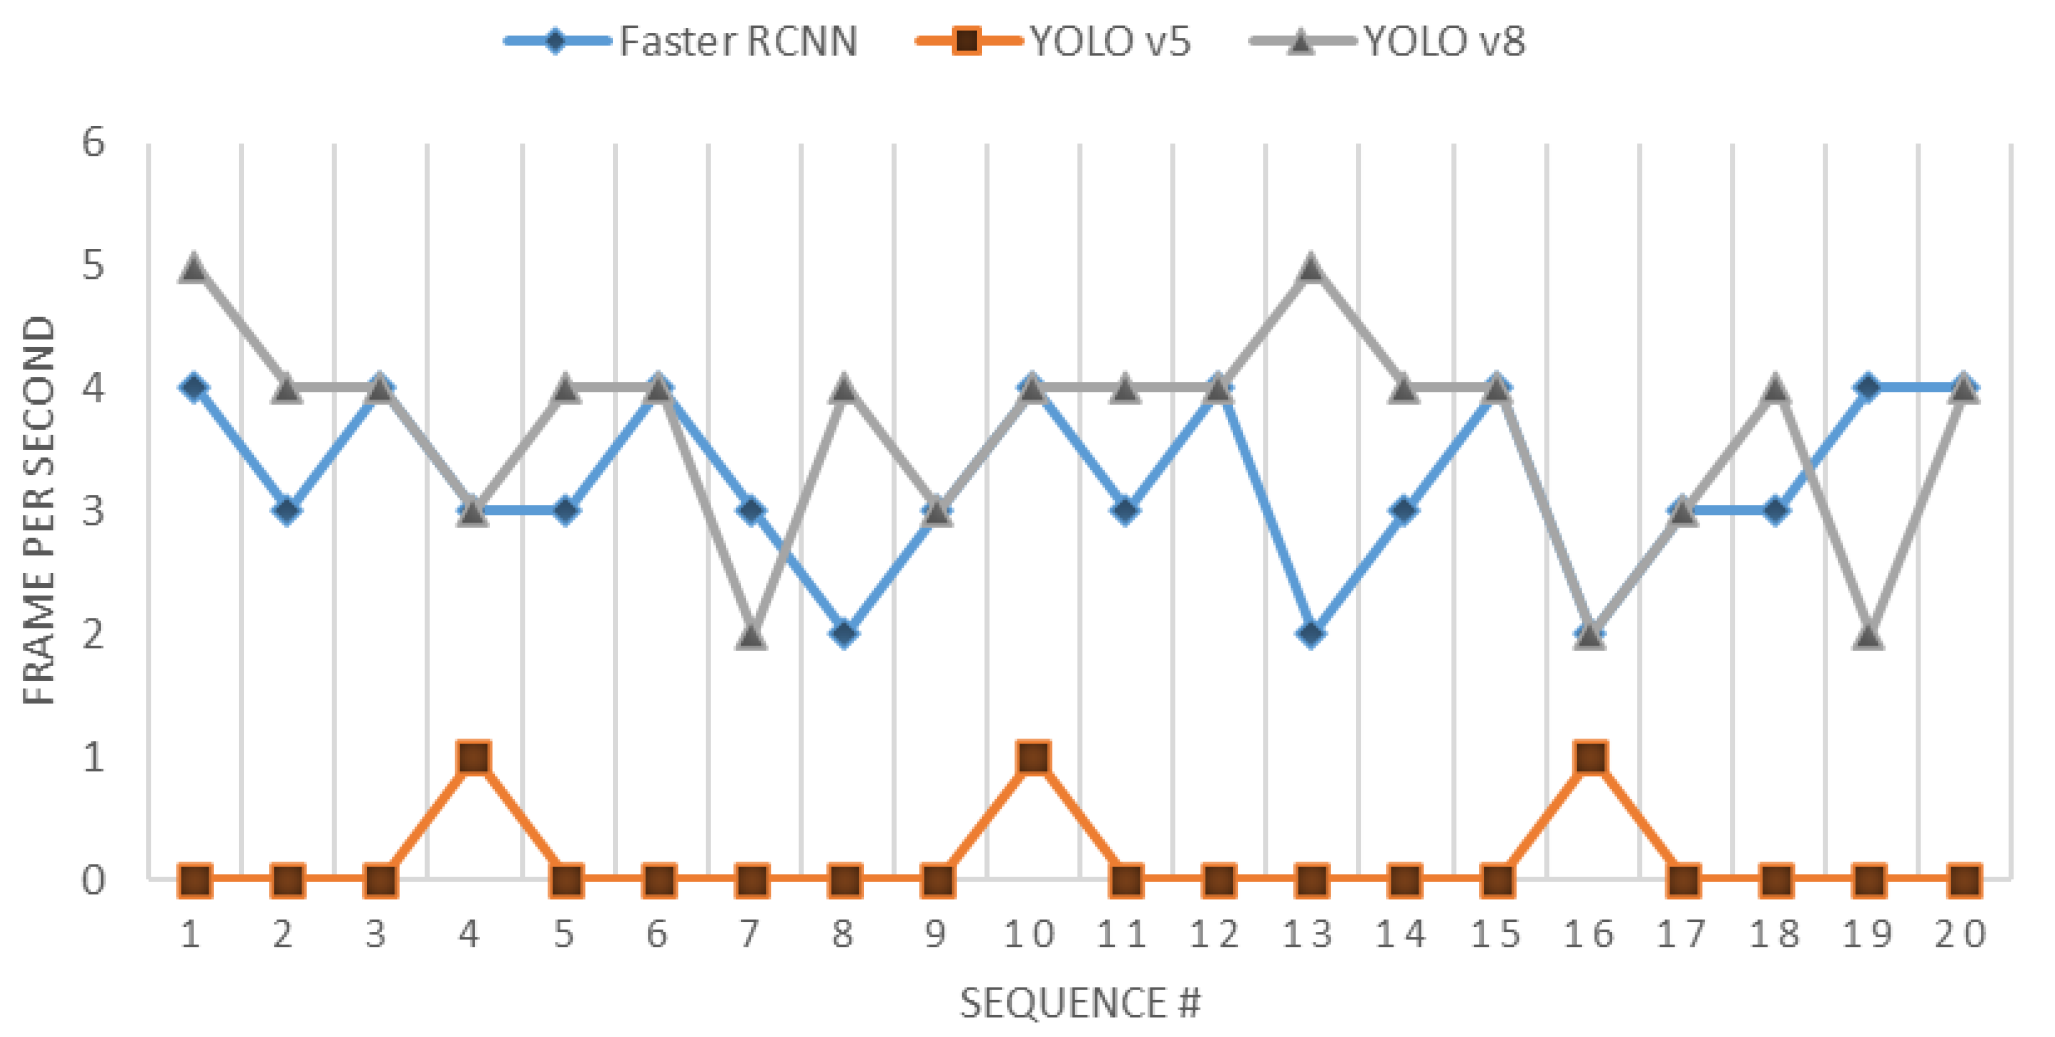
The processing time for the object detection models is essential for real-time applications; therefore, it was important to investigate the processing time for each object detection algorithm. As presented in Figure 9, the YOLO v5 and YOLO v8 algorithms processed almost four to five frames per second using the Raspberry Pi 4 computer. However, the Faster R-CNN algorithm processed almost one frame every four seconds on average.
Figure 9.
Processing time for the three object detection models.
Based on the evaluation results obtained, the YOLO v5 and YOLO v8 algorithms demonstrated superior performance in real-time object detection for robot systems compared to the Faster R-CNN algorithm.
5. Discussion
The importance of deep learning in semantic navigation stems from its capacity to provide robots with spatial awareness and contextual comprehension, where semantic navigation enables accurate navigation, object identification, and scene interpretation by determining the semantic properties of objects and situations. The deep learning approach is a cornerstone of semantic navigation, providing a thorough grasp of spatial contexts and object interactions. Its applications across varied datasets, together with continuous developments and prospects, highlight its critical role in defining the course of computer vision, autonomous systems, and human–machine interaction. As semantic navigation advances, the influence of deep learning will increase, ushering in a new era of intelligent and context-aware computers [1].
Based on the obtained results, it is evident that the Faster R-CNN model exhibits a slower processing speed compared to the YOLO models, making it unsuitable for real-time environments such as robot navigation systems. Furthermore, the Faster R-CNN model demonstrates inferior performance in terms of both detection and accuracy rates when compared to the YOLO models.
Both YOLO v5 and YOLO v8 are efficient object detection models that are capable of processing real-time images. However, YOLO v8 is a better choice for applications that necessitate real-time object detection.
As presented above, several object detection models have been employed in robot semantic navigation with diverse object detection accuracy, complexity, and processing time. However, according to the obtained results, the YOLO object detection model achieves the best object detection accuracy and offers minimum processing time.
The employment of the COCO dataset in robot semantic navigation supports the robot’s exploration and understanding of various indoor and outdoor settings, allowing deep learning models to understand item interactions, spatial layouts, and contextual relationships. This capacity has applications in robotics, augmented reality, and human–computer interaction, among other areas. While the set of 80 classes in the COCO dataset proves suitable for numerous applications, these research experiments indicate the need to incorporate additional class groups to accommodate other common object types. Therefore, it is crucial to expand and enhance the COCO dataset to meet the requirements for developing deep learning applications based on these models.
Semantic navigation is poised for further improvement and development, with an emphasis on improving interpretability, generalization, and adaptation across varied situations. The combination of reinforcement learning, continuous learning, and multi-modal perception has the potential to improve the capabilities of semantic navigation systems, allowing them to traverse complicated, dynamic, and previously unexplored settings.
6. Conclusions
One of the most important aspects of robotics is semantic navigation, which emphasizes how important it is for robots to understand the semantics of their environment in order to make intelligent decisions. In this paper, common vision models for robot semantic navigation systems were examined, and the robot vision datasets that are currently available were investigated. This study clarified the relative performance of three different object detection models by means of an empirical analysis that sought to determine each model’s effectiveness using the COCO vision dataset. The results show that, out of all the algorithms tested, the YOLO v8 object identification model performed the best in terms of classification rates, accuracy, and processing times, making it the best option for real-time robot semantic navigation systems. In the future, further research should be conducted to understand better the effects of using different object identification models in various case studies. This will help to develop a more thorough understanding of the models’ applicability and performance subtleties in the context of robot semantic navigation. This extended analysis not only synthesizes the existing literature but also opens the door to improved approaches and future developments in robotic semantic navigation systems. Additionally, it is desirable to look into the robustness and adaptability of object detection models in a variety of dynamic environments, as it is crucial to evaluate these models’ performance in a variety of lighting, weather, and cluttered scenarios to improve the dependability of semantic navigation systems.
Author Contributions
A.B., L.D., H.A. and A.A. surveyed and analyzed the recent developed robot semantic navigation systems that employed vision subsystems. T.A., A.A. and H.A. implemented three vision systems and performed several real experiments. O.M.A. validated the obtained results and contributed in writing the final manuscript. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Informed Consent Statement
Not applicable.
Data Availability Statement
This study employed the MS-COCO vision dataset to perform semantic classification, where MS-COCO dataset can be accessed through https://cocodataset.org/#home.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Alenzi, Z.; Alenzi, E.; Alqasir, M.; Alruwaili, M.; Alhmiedat, T.; Alia, O.M. A semantic classification approach for indoor robot navigation. Electronics 2022, 11, 2063. [Google Scholar] [CrossRef] [Scilit]
- Alhmiedat, T.; Marei, A.M.; Messoudi, W.; Albelwi, S.; Bushnag, A.; Bassfar, Z.; Alnajjar, F.; Elfaki, A.O. A SLAM-based localization and navigation system for social robots: The pepper robot case. Machines 2023, 11, 158. [Google Scholar] [CrossRef] [Scilit]
- Bhatt, D.; Patel, C.; Talsania, H.; Patel, J.; Vaghela, R.; Pandya, S.; Modi, K.; Ghayvat, H. CNN Variants for Computer Vision: History, Architecture, Application, Challenges and Future Scope. Electronics 2021, 10, 2470. [Google Scholar] [CrossRef] [Scilit]
- Alamri, S.; Alamri, H.; Alshehri, W.; Alshehri, S.; Alaklabi, A.; Alhmiedat, T. An autonomous maze-solving robotic system based on an enhanced wall-follower approach. Machines 2023, 11, 249. [Google Scholar] [CrossRef] [Scilit]
- Alqobali, R.; Alshmrani, M.; Alnasser, R.; Rashidi, A.; Alhmiedat, T.; Alia, O.M. A Survey on Robot Semantic Navigation Systems for Indoor Environments. Appl. Sci. 2023, 14, 89. [Google Scholar] [CrossRef] [Scilit]
- Uçar, A.; Demir, Y.; Güzeliş, C. Object recognition and detection with deep learning for autonomous driving applications. Simulation 2017, 93, 759–769. [Google Scholar] [CrossRef] [Scilit]
- Hernández, A.C.; Gómez, C.; Crespo, J.; Barber, R. Object Detection Applied to Indoor Environments for Mobile Robot Navigation. Sensors 2016, 16, 1180. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Krizhevsky, A.; Sutskever, I.; Hinton, G.E. Imagenet classification with deep convolutional neural networks. In Proceedings of the Advances in Neural Information Processing Systems 25, Lake Tahoe, NV, USA, 3–6 December 2012. [Google Scholar]
- Li, Z.; Liu, F.; Yang, W.; Peng, S.; Zhou, J. A Survey of Convolutional Neural Networks: Analysis, Applications, and Prospects. IEEE Trans. Neural Netw. Learn. Syst. 2022, 33, 6999–7019. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Ni, J.; Gong, T.; Gu, Y.; Zhu, J.; Fan, X. An improved deep residual network-based semantic simultaneous localization and mapping method for monocular vision robot. Comput. Intell. Neurosci. 2020, 2020, 7490840. [Google Scholar] [CrossRef] [Scilit]
- Mousavian, A.; Toshev, A.; Fišer, M.; Košecká, J.; Wahid, A.; Davidson, J. Visual representations for semantic target driven navigation. In Proceedings of the 2019 International Conference on Robotics and Automation (ICRA), Montreal, QC, Canada, 20–24 May 2019; pp. 8846–8852. [Google Scholar]
- Teso-Fz-Betoño, D.; Zulueta, E.; Sánchez-Chica, A.; Fernandez-Gamiz, U.; Saenz-Aguirre, A. Semantic segmentation to develop an indoor navigation system for an autonomous mobile robot. Mathematics 2020, 8, 855. [Google Scholar] [CrossRef] [Scilit]
- Simonyan, K.; Zisserman, A. Very deep convolutional networks for large-scale image recognition. arXiv 2014, arXiv:1409.1556. [Google Scholar]
- Dang, T.V.; Bui, N.T. Multi-scale fully convolutional network-based semantic segmentation for mobile robot navigation. Electronics 2023, 12, 533. [Google Scholar] [CrossRef] [Scilit]
- Kim, W.; Seok, J. Indoor semantic segmentation for robot navigating on mobile. In Proceedings of the 2018 Tenth International Conference on Ubiquitous and Future Networks (ICUFN), Prague, Czech Republic, 3–6 July 2018; pp. 22–25. [Google Scholar]
- Dang, T.V.; Tran, D.M.C.; Tan, P.X. IRDC-Net: Lightweight Semantic Segmentation Network Based on Monocular Camera for Mobile Robot Navigation. Sensors 2023, 23, 6907. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wei, Y.; Wei, W.; Zhang, Y. EfferDeepNet: An Efficient Semantic Segmentation Method for Outdoor Terrain. Machines 2023, 11, 256. [Google Scholar] [CrossRef] [Scilit]
- Liu, W.; Anguelov, D.; Erhan, D.; Szegedy, C.; Reed, S.; Fu, C.Y.; Berg, A.C. SSD: Single Shot MultiBox Detector. In Lecture Notes in Computer Science; Springer International Publishing: Berlin/Heidelberg, Germany, 2016; pp. 21–37. [Google Scholar] [CrossRef] [Scilit]
- Bersan, D.; Martins, R.; Campos, M.; Nascimento, E.R. Semantic map augmentation for robot navigation: A learning approach based on visual and depth data. In Proceedings of the 2018 Latin American Robotic Symposium, 2018 Brazilian Symposium on Robotics (SBR) and 2018 Workshop on Robotics in Education (WRE), João Pessoa, Brazil, 6–10 November 2018; pp. 45–50. [Google Scholar]
- Martins, R.; Bersan, D.; Campos, M.F.; Nascimento, E.R. Extending maps with semantic and contextual object information for robot navigation: A learning-based framework using visual and depth cues. J. Intell. Robot. Syst. 2020, 99, 555–569. [Google Scholar] [CrossRef] [Scilit]
- Dos Reis, D.H.; Welfer, D.; De Souza Leite Cuadros, M.A.; Gamarra, D.F.T. Mobile robot navigation using an object recognition software with RGBD images and the YOLO algorithm. Appl. Artif. Intell. 2019, 33, 1290–1305. [Google Scholar] [CrossRef] [Scilit]
- Wang, L.; Li, R.; Sun, J.; Zhao, L.; Shi, H.; Seah, H.S.; Tandianus, B. Object-Aware Hybrid Map for Indoor Robot Visual Semantic Navigation. In Proceedings of the 2019 IEEE International Conference on Robotics and Biomimetics (ROBIO), Dali, China, 6–8 December 2019; pp. 1166–1172. [Google Scholar]
- Anebarassane, Y.; Kumar, D.; Chandru, A.; Adithya, P.; Sathiyamurthy, K. Enhancing ORB-SLAM3 with YOLO-based Semantic Segmentation in Robotic Navigation. In Proceedings of the 2023 IEEE World Conference on Applied Intelligence and Computing (AIC), Sonbhadra, India, 29–30 July 2023; pp. 874–879. [Google Scholar]
- Mengcong, X.; Li, M. Object semantic annotation based on visual SLAM. In Proceedings of the 2021 Asia-Pacific Conference on Communications Technology and Computer Science (ACCTCS), Shenyang, China, 22–24 January 2021; pp. 197–201. [Google Scholar]
- Miyamoto, R.; Adachi, M.; Nakamura, Y.; Nakajima, T.; Ishida, H.; Kobayashi, S. Accuracy improvement of semantic segmentation using appropriate datasets for robot navigation. In Proceedings of the 2019 6th International Conference on Control, Decision and Information Technologies (CoDIT), Paris, France, 23–26 April 2019; pp. 1610–1615. [Google Scholar]
- Henke dos Reis, D.; Welfer, D.; de Souza Leite Cuadros, M.A.; Tello Gamarra, D.F. Object Recognition Software Using RGBD Kinect Images and the YOLO Algorithm for Mobile Robot Navigation. In Intelligent Systems Design and Applications: 19th International Conference on Intelligent Systems Design and Applications (ISDA 2019) held December 3–5, 2019; Springer: Berlin/Heidelberg, Germany, 2021; pp. 255–263. [Google Scholar]
- Xia, X.; Zhang, P.; Sun, J. YOLO-Based Semantic Segmentation for Dynamic Removal in Visual-Inertial SLAM. In Proceedings of the 2023 Chinese Intelligent Systems Conference; Springer: Berlin/Heidelberg, Germany, 2023; pp. 377–389. [Google Scholar]
- Truong, P.H.; You, S.; Ji, S. Object detection-based semantic map building for a semantic visual SLAM system. In Proceedings of the 2020 20th International Conference on Control, Automation and Systems (ICCAS), Busan, Republic of Korea, 13–16 October 2020; pp. 1198–1201. [Google Scholar]
- Liu, X.; Muise, C. A Neural-Symbolic Approach for Object Navigation. In Proceedings of the 2nd Embodied AI Workshop (CVPR 2021), Virtual, 20 June 2021; pp. 19–25. [Google Scholar]
- Chaves, D.; Ruiz-Sarmiento, J.R.; Petkov, N.; Gonzalez-Jimenez, J. Integration of CNN into a robotic architecture to build semantic maps of indoor environments. In Advances in Computational Intelligence: 15th International Work-Conference on Artificial Neural Networks, IWANN 2019, Gran Canaria, Spain, June 12–14, 2019, Proceedings, Part II 15; Springer: Berlin/Heidelberg, Germany, 2019; pp. 313–324. [Google Scholar]
- Joo, S.H.; Manzoor, S.; Rocha, Y.G.; Bae, S.H.; Lee, K.H.; Kuc, T.Y.; Kim, M. Autonomous navigation framework for intelligent robots based on a semantic environment modeling. Appl. Sci. 2020, 10, 3219. [Google Scholar] [CrossRef] [Scilit]
- Qiu, H.; Lin, Z.; Li, J. Semantic Map Construction via Multi-sensor Fusion. In Proceedings of the 2021 36th Youth Academic Annual Conference of Chinese Association of Automation (YAC), Nanchang, China, 28–30 May 2021; pp. 495–500. [Google Scholar]
- Fernandes, J.C.d.C.S. Semantic Mapping with a Mobile Robot Using a RGB-D Camera. Master’s Thesis, Laboratório de Robótica Móvel, Instituto de Sistemas e Robótica-Universidade de Coimbra, Coimbra, Portugal, 2019. [Google Scholar]
- Xu, X.; Liu, L.I.; Xiong, R.; Jiang, L. Real-time instance-aware semantic mapping. J. Phys. Conf. Ser. 2020, 1507, 052013. [Google Scholar] [CrossRef] [Scilit]
- Liu, X.; Wen, S.; Pan, Z.; Xu, C.; Hu, J.; Meng, H. Vision-IMU multi-sensor fusion semantic topological map based on RatSLAM. Measurement 2023, 220, 113335. [Google Scholar] [CrossRef] [Scilit]
- Xie, Z.; Li, Z.; Zhang, Y.; Zhang, J.; Liu, F.; Chen, W. A multi-sensory guidance system for the visually impaired using YOLO and ORB-SLAM. Information 2022, 13, 343. [Google Scholar] [CrossRef] [Scilit]
- Qi, X.; Wang, W.; Liao, Z.; Zhang, X.; Yang, D.; Wei, R. Object semantic grid mapping with 2D LiDAR and RGB-D camera for domestic robot navigation. Appl. Sci. 2020, 10, 5782. [Google Scholar] [CrossRef] [Scilit]
- Sun, H.; Meng, Z.; Ang, M.H. Semantic mapping and semantics-boosted navigation with path creation on a mobile robot. In Proceedings of the 2017 IEEE International Conference on Cybernetics and Intelligent Systems (CIS) and IEEE Conference on Robotics, Automation and Mechatronics (RAM), Ningbo, China, 19–21 November 2017; pp. 207–212. [Google Scholar]
- Shao, C.; Zhang, L.; Pan, W. Faster R-CNN learning-based semantic filter for geometry estimation and its application in vSLAM systems. IEEE Trans. Intell. Transp. Syst. 2021, 23, 5257–5266. [Google Scholar] [CrossRef] [Scilit]
- Sevugan, A.; Karthikeyan, P.; Sarveshwaran, V.; Manoharan, R. Optimized navigation of mobile robots based on Faster R-CNN in wireless sensor network. Int. J. Sens. Wirel. Commun. Control 2022, 12, 440–448. [Google Scholar] [CrossRef] [Scilit]
- Sun, Y.; Su, T.; Tu, Z. Faster R-CNN based autonomous navigation for vehicles in warehouse. In Proceedings of the 2017 IEEE International Conference on Advanced Intelligent Mechatronics (AIM), Munich, Germany, 3–7 July 2017; pp. 1639–1644. [Google Scholar]
- Zhang, Z.; Zhang, J.; Tang, Q. Mask R-CNN based semantic RGB-D SLAM for dynamic scenes. In Proceedings of the 2019 IEEE/ASME International Conference on Advanced Intelligent Mechatronics (AIM), Hong Kong, China, 8–12 July 2019; pp. 1151–1156. [Google Scholar]
- Sinha, R.K.; Pandey, R.; Pattnaik, R. Deep Learning For Computer Vision Tasks: A review. arXiv 2018, arXiv:1804.03928. [Google Scholar]
- Cheng, J.; Sun, Y.; Meng, M.Q.H. A dense semantic mapping system based on CRF-RNN network. In Proceedings of the 2017 18th International Conference on Advanced Robotics (ICAR), Hong Kong, China, 10–12 July 2017; pp. 589–594. [Google Scholar]
- Xiang, Y.; Fox, D. DA-RNN: Semantic mapping with data associated recurrent neural networks. arXiv 2017, arXiv:1703.03098. [Google Scholar]
- Zubair Irshad, M.; Chowdhury Mithun, N.; Seymour, Z.; Chiu, H.P.; Samarasekera, S.; Kumar, R. SASRA: Semantically-aware Spatio-temporal Reasoning Agent for Vision-and-Language Navigation in Continuous Environments. In Proceedings of the 2022 26th International Conference on Pattern Recognition (ICPR), Montreal, QC, Canada, 21–25 August 2022. [Google Scholar]
- Zhang, Y.; Feng, Z. Crowd-Aware Mobile Robot Navigation Based on Improved Decentralized Structured RNN via Deep Reinforcement Learning. Sensors 2023, 23, 1810. [Google Scholar] [CrossRef] [Scilit]
- Ondruska, P.; Dequaire, J.; Wang, D.Z.; Posner, I. End-to-end tracking and semantic segmentation using recurrent neural networks. arXiv 2016, arXiv:1604.05091. [Google Scholar]
- Le, N.; Rathour, V.S.; Yamazaki, K.; Luu, K.; Savvides, M. Deep Reinforcement Learning in Computer Vision: A Comprehensive Survey. arXiv 2021, arXiv:2108.11510. [Google Scholar] [CrossRef] [Scilit]
- Zhou, S.; Liu, X.; Xu, Y.; Guo, J. A deep Q-network (DQN) based path planning method for mobile robots. In Proceedings of the 2018 IEEE International Conference on Information and Automation (ICIA), Wuyishan, China, 11–13 August 2018; pp. 366–371. [Google Scholar]
- Reddy, D.R.; Chella, C.; Teja, K.B.R.; Baby, H.R.; Kodali, P. Autonomous Vehicle Based on Deep Q-Learning and YOLOv3 with Data Augmentation. In Proceedings of the 2021 International Conference on Communication, Control and Information Sciences (ICCISc), Idukki, India, 16–18 June 2021; Volume 1, pp. 1–7. [Google Scholar]
- Zeng, F.; Wang, C.; Ge, S.S. A survey on visual navigation for artificial agents with deep reinforcement learning. IEEE Access 2020, 8, 135426–135442. [Google Scholar] [CrossRef] [Scilit]
- Dai, Y.; Yang, S.; Lee, K. Sensing and Navigation for Multiple Mobile Robots Based on Deep Q-Network. Remote Sens. 2023, 15, 4757. [Google Scholar] [CrossRef] [Scilit]
- Vuong, T.A.T.; Takada, S. Semantic Analysis for Deep Q-Network in Android GUI Testing. In Proceedings of the SEKE, Lisbon, Portugal, 10–12 July 2019; pp. 123–170. [Google Scholar]
- Kästner, L.; Marx, C.; Lambrecht, J. Deep-reinforcement-learning-based semantic navigation of mobile robots in dynamic environments. In Proceedings of the 2020 IEEE 16th International Conference on Automation Science and Engineering (CASE), Hong Kong, China, 20–21 August 2020; pp. 1110–1115. [Google Scholar]
- Xu, J.; Zhang, H.; Qiu, J. A deep deterministic policy gradient algorithm based on averaged state-action estimation. Comput. Electr. Eng. 2022, 101, 108015. [Google Scholar] [CrossRef] [Scilit]
- Zhu, K.; Zhang, T. Deep reinforcement learning based mobile robot navigation: A review. Tsinghua Sci. Technol. 2021, 26, 674–691. [Google Scholar] [CrossRef] [Scilit]
- Haarnoja, T.; Zhou, A.; Hartikainen, K.; Tucker, G.; Ha, S.; Tan, J.; Kumar, V.; Zhu, H.; Gupta, A.; Abbeel, P.; et al. Soft actor-critic algorithms and applications. arXiv 2018, arXiv:1812.05905. [Google Scholar]
- Sharma, S. SAC-RL: Continuous Control of Wheeled Mobile Robot for Navigation in a Dynamic Environment. Ph.D. Thesis, Indian Institute of Technology Patna, Patna, India, 2020. [Google Scholar]
- Wahid, A.; Stone, A.; Chen, K.; Ichter, B.; Toshev, A. Learning object-conditioned exploration using distributed soft actor critic. Proc. Conf. Robot. Learn. PMLR 2021, 155, 1684–1695. [Google Scholar]
- Schulman, J.; Wolski, F.; Dhariwal, P.; Radford, A.; Klimov, O. Proximal Policy Optimization Algorithms. arXiv 2017, arXiv:1707.06347. [Google Scholar]
- Lin, T.Y.; Maire, M.; Belongie, S.; Bourdev, L.; Girshick, R.; Hays, J.; Perona, P.; Ramanan, D.; Zitnick, C.L.; Dollár, P. Microsoft COCO: Common Objects in Context. arXiv 2015, arXiv:1405.0312. [Google Scholar]
- Pereira, R.; Gonçalves, N.; Garrote, L.; Barros, T.; Lopes, A.; Nunes, U.J. Deep-learning based global and semantic feature fusion for indoor scene classification. In Proceedings of the 2020 IEEE International Conference on Autonomous Robot Systems and Competitions (ICARSC), Ponta Delgada, Portugal, 15–17 April 2020; pp. 67–73. [Google Scholar]
- Georgakis, G.; Bucher, B.; Schmeckpeper, K.; Singh, S.; Daniilidis, K. Learning to map for active semantic goal navigation. arXiv 2021, arXiv:2106.15648. [Google Scholar]
- Yu, D.; Khatri, C.; Papangelis, A.; Namazifar, M.; Madotto, A.; Zheng, H.; Tur, G. Common sense and Semantic-Guided Navigation via Language in Embodied Environments. In Proceedings of the International Conference on Learning Representations ICLR 2020, Addis Ababa, Ethiopia, 30 April 2020. [Google Scholar]
- Krantz, J. Semantic Embodied Navigation: Developing Agents That Navigate from Language and Vision. Ph.D. Thesis, Oregon State University, Corvallis, OR, USA, 2023. [Google Scholar]
- Narasimhan, M.; Wijmans, E.; Chen, X.; Darrell, T.; Batra, D.; Parikh, D.; Singh, A. Seeing the un-scene: Learning amodal semantic maps for room navigation. In Computer Vision—ECCV 2020: 16th European Conference, Glasgow, UK, August 23–28, 2020, Proceedings, Part XVIII 16; Springer: Berlin/Heidelberg, Germany, 2020; pp. 513–529. [Google Scholar]
- Vicente, S.; Carreira, J.; Agapito, L.; Batista, J. Reconstructing PASCAL VOC. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Columbus, OH, USA, 23–28 June 2014. [Google Scholar]
- Geiger, A.; Lenz, P.; Stiller, C.; Urtasun, R. Vision meets robotics: The KITTI dataset. Int. J. Robot. Res. 2013, 32, 1231–1237. [Google Scholar] [CrossRef] [Scilit]
- Behley, J.; Garbade, M.; Milioto, A.; Quenzel, J.; Behnke, S.; Stachniss, C.; Gall, J. Semantickitti: A dataset for semantic scene understanding of lidar sequences. In Proceedings of the IEEE/CVF International Conference on Computer Vision, Seoul, Republic of Korea, 27 October–2 November 2019; pp. 9297–9307. [Google Scholar]
- Behley, J.; Garbade, M.; Milioto, A.; Quenzel, J.; Behnke, S.; Gall, J.; Stachniss, C. Towards 3D LiDAR-based semantic scene understanding of 3D point cloud sequences: The SemanticKITTI Dataset. Int. J. Robot. Res. 2021, 40, 959–967. [Google Scholar] [CrossRef] [Scilit]
- Kostavelis, I.; Gasteratos, A. Semantic mapping for mobile robotics tasks: A survey. Robot. Auton. Syst. 2015, 66, 86–103. [Google Scholar] [CrossRef] [Scilit]
- Zhou, B.; Zhao, H.; Puig, X.; Fidler, S.; Barriuso, A.; Torralba, A. Scene Parsing through ADE20K Dataset. In Proceedings of the 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Honolulu, HI, USA, 21–26 July 2017; pp. 5122–5130. [Google Scholar] [CrossRef] [Scilit]
- Zhang, C.; Yang, Z.; Xue, B.; Zhuo, H.; Liao, L.; Yang, X.; Zhu, Z. Perceiving like a Bat: Hierarchical 3D Geometric and ndash;Semantic Scene Understanding Inspired by a Biomimetic Mechanism. Biomimetics 2023, 8, 436. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Raspberry Pi 4 2024. Available online: http://www.raspberrypi.com/products/raspberry-pi-4-model-b/ (accessed on 21 August 2024).
- RPLiDAR A1 2024. Available online: http://www.slamtec.ai/product/slamtec-rplidar-a1/ (accessed on 21 August 2024).
- Logitech Webcam 2024. Available online: https://www.logitech.com/en-sa/products/webcams/c920-pro-hd-webcam.960-001055.html (accessed on 21 August 2024).

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2024 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).