


Abstract
Contrastive learning improves model performance by differentiating between positive and negative sample pairs. However, its application is primarily confined to classification tasks, facing challenges with complex recognition tasks such as object detection and segmentation due to its limited capacity to capture spatial relationships and fine-grained features. To address this limitation, we propose LossTransform, a novel approach that redefines positive sample pairs and establishes a novel contrastive loss paradigm. LossTransform advances contrastive learning to the instance level, departing from the traditional sample level. Empirical evaluations on ImageNet, CIFAR, and object detection benchmarks indicate that LossTransform improves accuracy by +2.73% on CIFAR, +2.52% on ImageNet, and up to +5.2% in average precision on detection tasks, while maintaining efficiency. These results illustrate that LossTransform is compatible with large-scale training pipelines and exhibits robust performance across diverse and complex datasets. By optimizing model performance and significantly reducing training time, this research enables more efficient and accessible solutions for societal applications.
1. Introduction
Contrastive learning is instrumental in interpretable artificial intelligence as it enhances model performance by distinguishing between positive and negative pairs of samples. However, its practical applicability is limited. It performs well primarily in basic classification tasks on small datasets but struggles with more complex recognition tasks on larger datasets. Additionally, current studies [1,2] show that contrastive learning methods are not user-friendly, as they often require modifications to the original data pipeline, model architecture, and training recipe, instead of being directly applicable to existing models.
The application of contrastive learning is mainly limited to classification tasks due to its fundamental mechanism, which relies on unsupervised clustering, which brings positive sample pairs closer in the projection space while simultaneously maximizing the feature distance between negative sample pairs. Conventionally, the determination of whether two samples from a positive pair is based on two criteria: whether they originate from distinct augmentations of the same sample or whether they are separate sharing the same class label. However, this paradigm encounters challenges in more complex visual tasks such as object detection and semantic segmentation. These tasks not only involve category classification but also require the model to accurately localize objects spatially and capture fine-grained pixel-level information. The limitations of contrastive learning in these tasks arise from its inability to effectively manage multiple object instances and leverage local feature information.
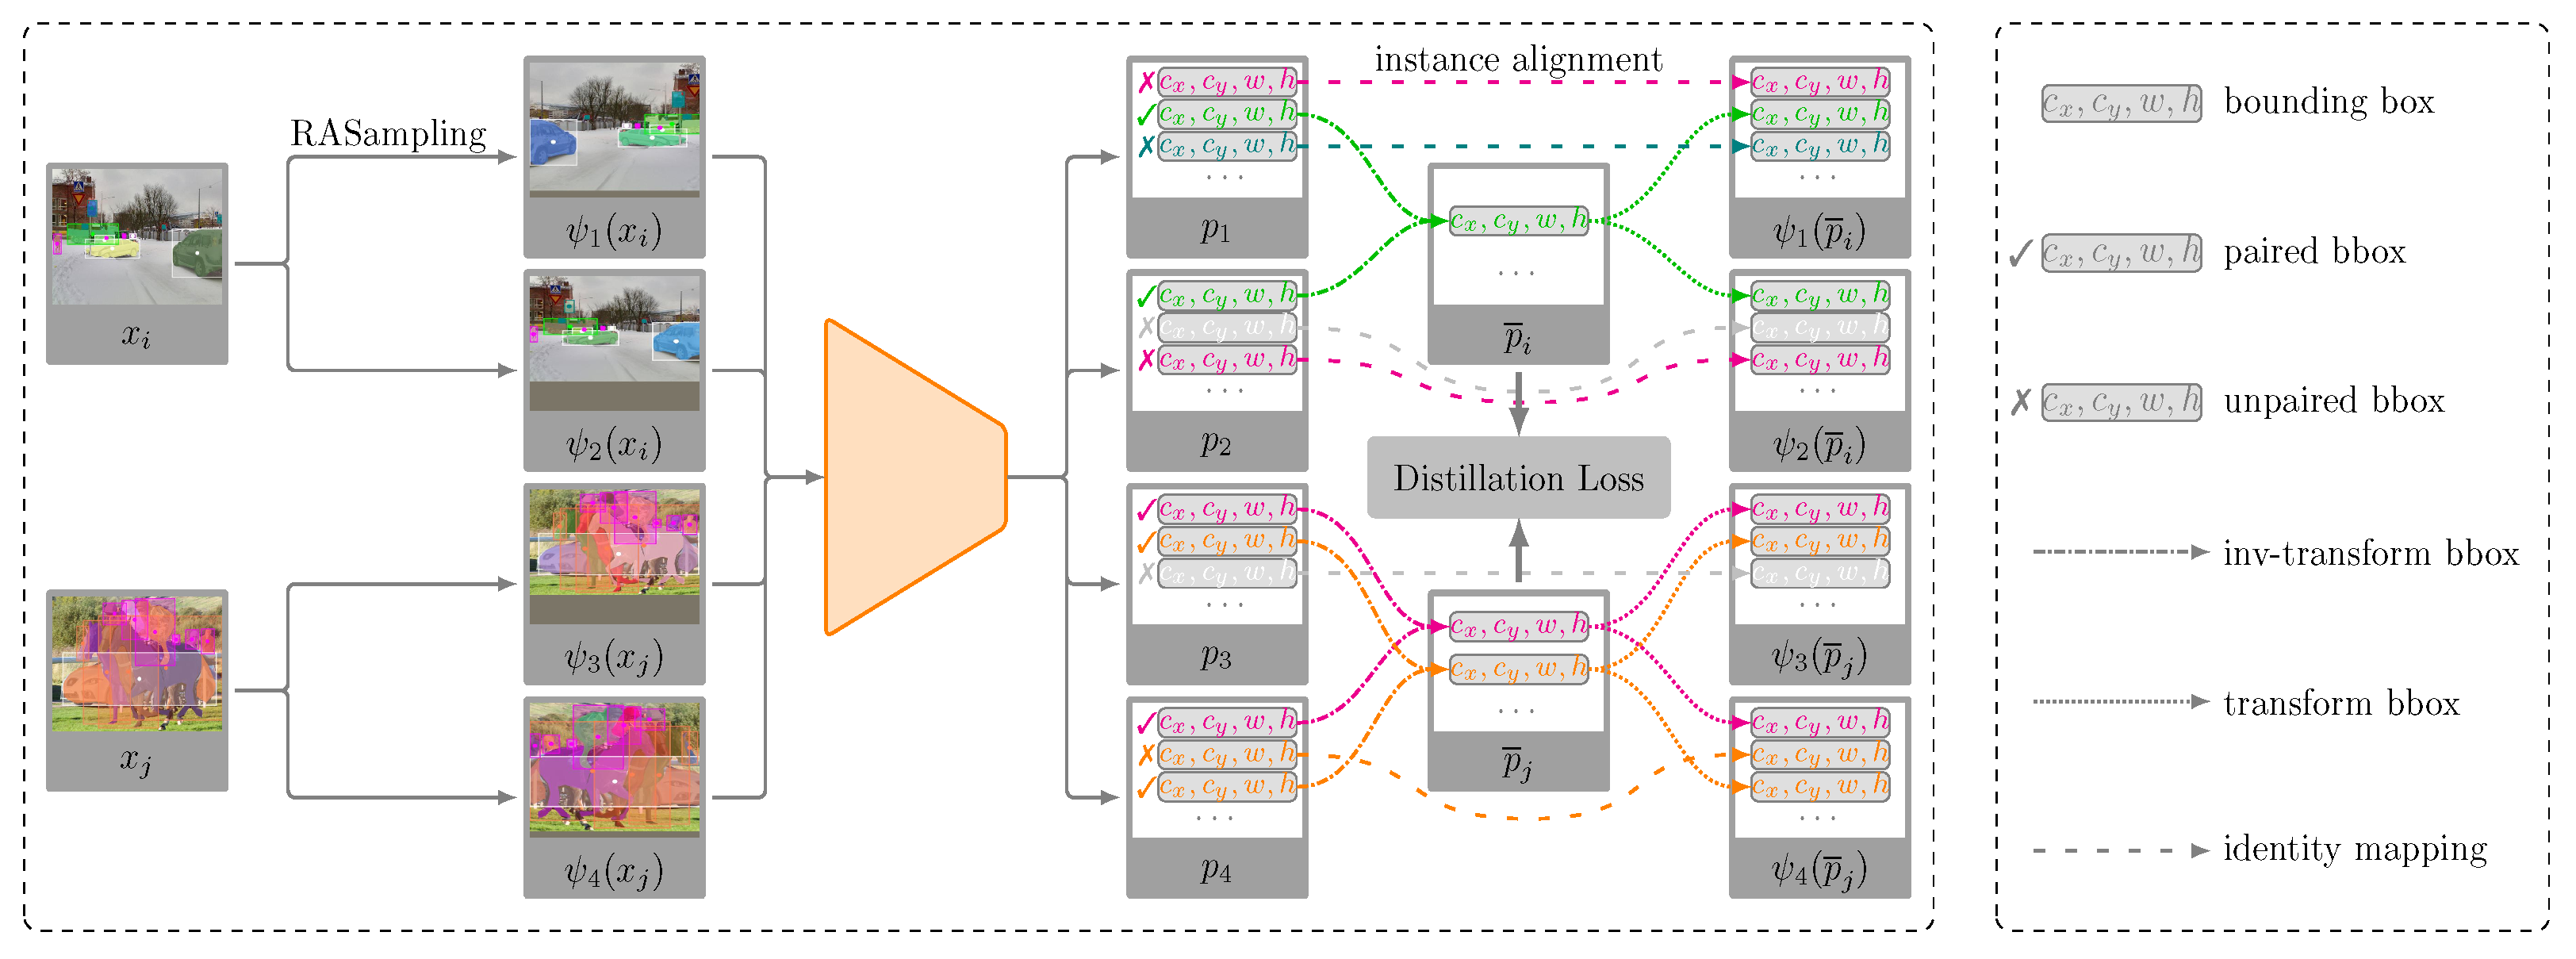
To effectively apply contrastive learning in general recognition tasks, we have redefined the concept of positive sample pairs and designed a novel contrastive loss paradigm. Specifically, in object detection applications, our approach extends contrastive learning to facilitate object pairing at the instance level (in this context, a “sample” refers to a single input data point in general recognition tasks, while an “instance” is a term specific to object detection, where a sample image may contain multiple instances, each defined by a bounding box, label, and polygon boundary or masked area), thereby diverging from the conventional use of positive/negative image pairs. As shown in Figure 1, an image undergoes independent random data augmentations (e.g., flipping, translation, and cropping), resulting in multiple replicas. These replicas contain both common instances and potentially unique instances. The feature representation of an instance’s bounding box is subject to change after data augmentation. To align these common instances, we first apply an inverse data augmentation to restore these features to a unified space. Based on a self-supervised alignment mechanism, we use a greedy matching algorithm to subsequently select high-confidence positive instance pairs from the multiple image replicas. Finally, we minimize the Kullback–Leibler divergence to constrain the distance between these positive instance pairs, thereby ensuring that the representations of identical instances from different image replicas become more compact within the projection space.
Figure 1.
Contrastive learning applied to object detection. Image replicas are generated through Random Augmentation Sampling (RASping, see Section 2.3), where each replica produces a series of bounding box via predictions. Inverse transformations (see Section 3.1) are applied to these boxes to estimate the model’s predictions on the original image. Geometric and statistical methods are used to align instances and match positive pairs of boxes (a bounding box labeled “✓” indicates that the instance can be paired with a bounding box in another image; unpaired bounding boxes are labeled “✗”, see Section 3.2), followed by the computation of an anchor box by averaging the corresponding box pairs. The KL divergence is minimized to reduce the distance between each predicted box and its anchor (see Section 3.3). Finally, anchor boxes are transformed and concatenated with unpaired bounding boxes to obtain the optimized box predictions as .
In this study, we conduct extensive evaluations of LossTransform on various datasets, model architectures, and recognition tasks. Our ablation studies show that LossTransform enables models to achieve improvements during testing: a +2.73% accuracy increase on CIFAR [3] and a +2.52% accuracy increase on ImageNet [4]. Experiments using the multi-task loss functions of Faster R-CNN [5] and Mask R-CNN [6] produce similar results, with a +5.2% Average Precision (AP) improvement on PennFudanPed [7], a +0.8% mean Average Precision (mAP) increase on PASCAL VOC 2012 [8], and a +0.4% mAP increase on MS COCO [9].
2. Related Work
2.1. Test-Time Augmentation
The ensemble learning method [10] and test time augmentation (TTA) technique [11] are often used in evaluating neural networks for image classification [12,13,14]. These methods aggregate outputs from various models or data augmentations and compute the average predicted results as the final prediction. From the perspective of knowledge distillation [15], both methods serve as strategies for generating soft labels [16]. TTA is inherently more versatile than other ensemble voting methods in a production environment because it does not require multiple models during the prediction phase. Recently, researchers applied this method to post-processing the prediction and retraining models [15,17,18]. We have incorporated this method in the training process to minimize the gap between predictions and the anchor prediction.
2.2. Semi-Supervised Learning
Different from data augmentation techniques, Semi-Supervised Learning (SSL) extends the cardinality of a training dataset by using a large amount of extra unlabelled data and subsequently generating pseudo labels through clustering algorithms [1,19]. In the SSL framework, the model can estimate the data-generating distribution and construct decision boundaries more precisely. An important concept in SSL is providing pseudo-labels to unlabeled data [20]. Building on this idea, in our method, if any images are successfully matched, they are collectively treated as positive samples of an unknown anchor sample. There is no requirement to identify the label of this unknown anchor sample; rather, we compute the average of the labels of all positive samples to serve as the pseudo-label for this anchor sample.
2.3. Random Augmentation Sampler
RASampler [21] is designed to limit data loading to a subset of the dataset for distribution purposes, incorporating repeated augmentation. For example, consider a dataset with five samples. To increase training data diversity, each sample can be augmented multiple times—here, three times per sample. The process typically involves
- Shuffling: Shuffling the original dataset indices (e.g., [0, 1, 2, 3, 4]) to create a randomized order (e.g., [3, 1, 4, 0, 2]).
- Repetition: Repeating each index based on the augmentation count (e.g., three times) results in [3, 3, 3, 1, 1, 1, 4, 4, 4, 0, 0, 0, 2, 2, 2].
- Subsampling: Splitting the indices to create a subset (e.g., [3, 3, 1, 4, 4]).
We use RAsamper in LossTransform to ensure that examples are repeated multiple times in each iteration while the total number of examples seen by the model in each epoch remains unchanged.
2.4. Sample Pairing in Object Detection
Sample pairing is a key issue when applying contrastive learning to object detection. Different works have proposed distinct strategies, but each of them comes with specific limitations.
2.4.1. Contrastive Learning for Object Detection
In this work, an image is augmented twice independently with random transformations, where random cropping plays a central role. The authors name this process TwoCropTransform [22]. It is important to note that this does not mean cropping out individual objects, but rather applying random cropping twice to generate two augmented views as a positive pair. This strategy may cause a mismatch in annotations: for example, when one crop removes objects on the left edge and the other crop removes objects on the right edge, the two augmented views will not share the same set of objects, resulting in unpaired labels and bounding boxes. In addition, the official code applies random horizontal flipping but does not introduce a corresponding alignment step in the loss function, which further increases the risk of annotation mismatch. Different from this work, our method does not rely on image-to-image positive pairs, but instead defines a pairing process at the object-to-object level.
2.4.2. DetCo: Unsupervised Contrastive Learning for Object Detection
DetCo [23] extends the previous idea by introducing two extra components. Besides random cropping, it generates small patches from the original image and further designs a global-to-global, global-to-local, and local-to-local pairing strategy. The final loss function is the weighted sum of these three terms. However, DetCo may face a similar issue as the first work. The paper does not clarify whether the crops are applied to the whole image or to detected objects. If the crops are image-level, the same annotation mismatch problem can still happen. Moreover, the released code only supports testing with pretrained models, making it difficult to confirm how sample pairing is implemented during training.
2.4.3. Contrastive Learning-Based Robust Object Detection Under Smoky Conditions
This work addresses detection in smoky images and builds a new architecture trained with a contrastive loss [24]. Unlike the previous two methods, sample pairing here does not suffer from annotation mismatch. This is because, under the smoky condition setting, the authors avoid using random cropping, image translation, or horizontal flipping. All augmented images share exactly the same annotations, naturally forming valid positive pairs. However, in general object detection tasks, random cropping, shifting, and flipping are critical for improving robustness. Therefore, this method may not generalize well beyond the smoky condition scenario.
2.5. Object Detection Loss Functions
Loss functions are a fundamental component in object detection, as they directly influence both classification and localization accuracy. A recent survey [25] provides a comprehensive review of detection losses, underscoring the role of carefully designed objectives in enhancing discriminative power. Our work follows a similar perspective from the lens of contrastive learning: by redefining positive sample pairs and proposing a novel contrastive loss, we contribute to the broader discussion on loss design. In particular, our instance-level contrastive paradigm complements detection-oriented loss formulations, highlighting the importance of loss functions as a unifying mechanism across recognition tasks.
3. Methods
Previous studies have relied heavily on minimizing the distance between positive pairs while maximizing the distance between negative pairs to improve model performance. This study demonstrates that substantial improvements in model performance can be achieved by employing LossTransform without the need to maximize the distance between negative pairs. In the following sections, we will take the task of object detection as an example: (1) defining the inverse transform for predicting the bounding box prediction; (2) explaining the instance alignment algorithm, which identifies all positive instance pairs through a greedy algorithm; and (3) presenting LossTransform, which redefines the loss function in contrastive learning and extends its application to non-classification tasks, while maintaining efficacy in classification tasks.
3.1. Inverse Transform
While data augmentation methods do not change the category of an instance, they can significantly impact its bounding box specifically; when performing a horizontal flip (hflip) or translation on an image, the transformation of the bounding box follows these steps:
where and are the center coordinates, are the width and height, respectively, are the image width and height, are the translation offsets along the horizontal (x-axis) and vertical (y-axis) directions, respectively, and is the rotation angle. Note that, for the object detection task, arbitrary-angle image rotation is not feasible because bounding boxes cannot be accurately computed unless the rotation angle . The inverse transformation is straightforward, as follows:
3.2. Instance Alignment
In our method, we use random data augmentation to generate multiple replicas. Given an image with raw annotations , generate m augmented replicas by applying a random data augmentation to the raw image, producing corresponding predictions
We align the predicted bounding boxes for positive instances by sorting them according to
Now, the averaged prediction is defined as . The aligned bounding boxes of instances are given by (see Figure A2 for visualization)
Additionally, for classification tasks, the ground-truth label is not affected by data augmentation. Thus, we do not need to consider inverse data augmentation or alignment. In our experiments, we used horizontal flipping and translation as image augmentations. However, some augmentation methods, such as “Simple Copy–Paste”, can completely change the instance class in images, which conflicts with contrastive learning and is not suitable for overuse in our method.
3.3. Loss Transform
Given a loss function L, we propose LossTransform by incorporating an additional regularization component. For a mini-batch of predictions with corresponding targets , the model parameters are optimized by minimizing the following objective function:
where we chose as the default setting because it provides a stable trade-off across different tasks and datasets, and represents the average prediction over all instances positively paired with . consists of two components: the traditional mini-batch loss on the left, and the distillation loss on the right, which is computed as the average of m Kullback–Leibler (KL) divergences.
4. Results
In this section, we start by evaluating the effectiveness of LossTransform in enhancing the generalizability of classifiers. Our experiments are primarily conducted on the CIFAR-10/100 and ImageNet-1K datasets. Initially, we investigate the factors that affect the performance of LossTransform. Subsequently, we demonstrate that models trained with LossTransform yield more stable predictions. Additionally, we employ LossTransform methods on various datasets and classifiers for comparison with baselines. We then explore the applications of LossTransform in the fine-tuning process.
Next, we analyze the memory limitations of the LossTransform method. Due to the increased computational demand of duplicating sample replicas for data augmentation, training large models on datasets with large-scale images requires additional computational resources. To address this limitation, LossTransform-v1 is introduced, employing subsampling of Repeated Augment Sampling, thereby not increasing the computational resources required for model training. Consequently, it offers a feasible solution to the limitations of LossTransform. Experiments on ImageNet and Microsoft COCO reveal that fine-tuning pre-trained models with LossTransform-v1 can yield better evaluations than state-of-the-art baselines.
In our experiments, we adhere to the original training recipes of all benchmark models, including their optimizers, batch sizes, epochs, and learning rate schedules.
4.1. Training Benefits from LossTransform
4.1.1. Suitability for Complex Augmentation
Here, we verify that the LossTransform of Categorical Cross Entropy (CCE) works well across all data augmentation schemes. Table 1 presents a performance comparison between LossTransform applied to Categorical Cross Entropy and the traditional CCE. For each combination of data augmentation schemes, we follow the official training recipe in the ResNet paper and apply CCE and for model training. All experiments are repeated five times with result variation under 0.3%.
Table 1.
Test error rates (%) of plain/LossTransform-trained models on CIFAR-10. The affine transformation [26] and horizontal flipping schemes are used by default. Cutout [27], CutMix [28], and mixup [29] are optional. The number of repetitions for Repeated Augmentation Sampling is set to 32. To emphasize general patterns, the best test error rates are highlighted in bold.
The last column of Table 1 demonstrates that is efficient for all hybrid data augmentation schemes. Empirically, while the traditional CCE-trained model shows improvement with a single data augmentation scheme, it fails under hybrid schemes due to the ambiguities introduced by mixed data augmentations. overcomes this limitation to work for all data augmentation combinations and improve the model performance.
4.1.2. Faster Convergence
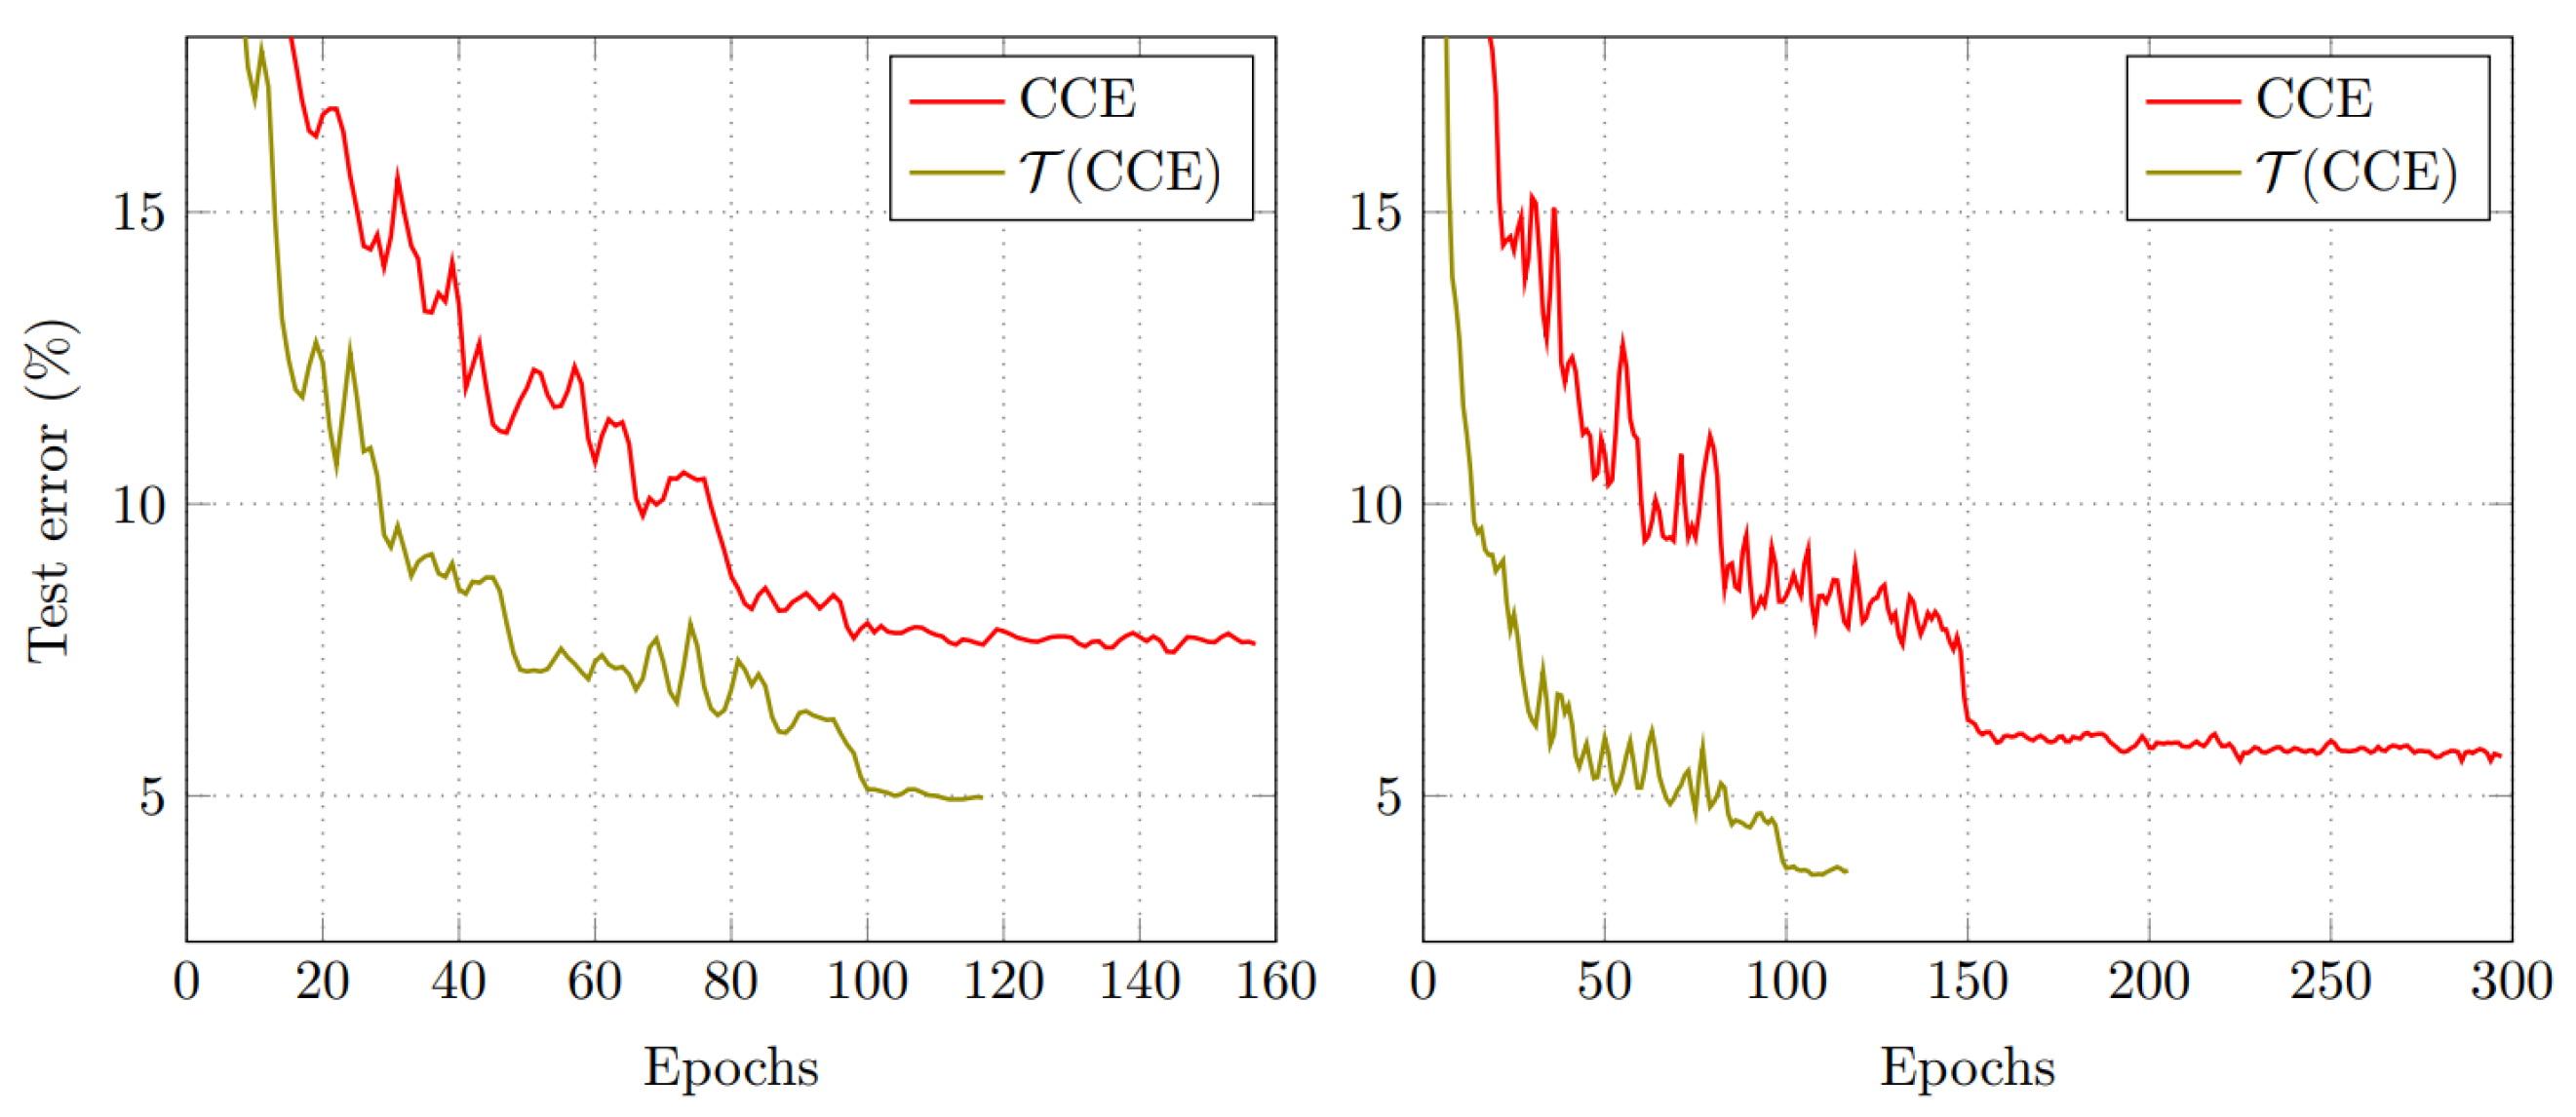
A loss function that converges to lower local minima reflects enhanced model performance, while faster convergence reduces computational resources, improving training efficiency. The LossTransform converts a loss function into a better form, thereby increasing the training speed and improving better model performance. Figure 2 shows a typical example of the CCE loss function, where models gain additional performance from the faster training on .
Figure 2.
Test error of ResNet-20 and DenseNet-40 on CIFAR-10 dataset. The model trained with LossTransform effectively gains lower test errors and accelerates the training process.
Based on CCE and the official training recipe, the top-1 validation accuracy of DenseNet has stopped improving after 300 epochs. However, our loss function converges faster with 120 epochs. Figure 2 (left) illustrates the test error (%) of CCE-trained ResNet and -trained ResNet, respectively, where saves 25% training iteration steps. Figure 2 (right) shows the same performance on DenseNet where saves 60% training iteration steps.
4.1.3. Stable Predictions
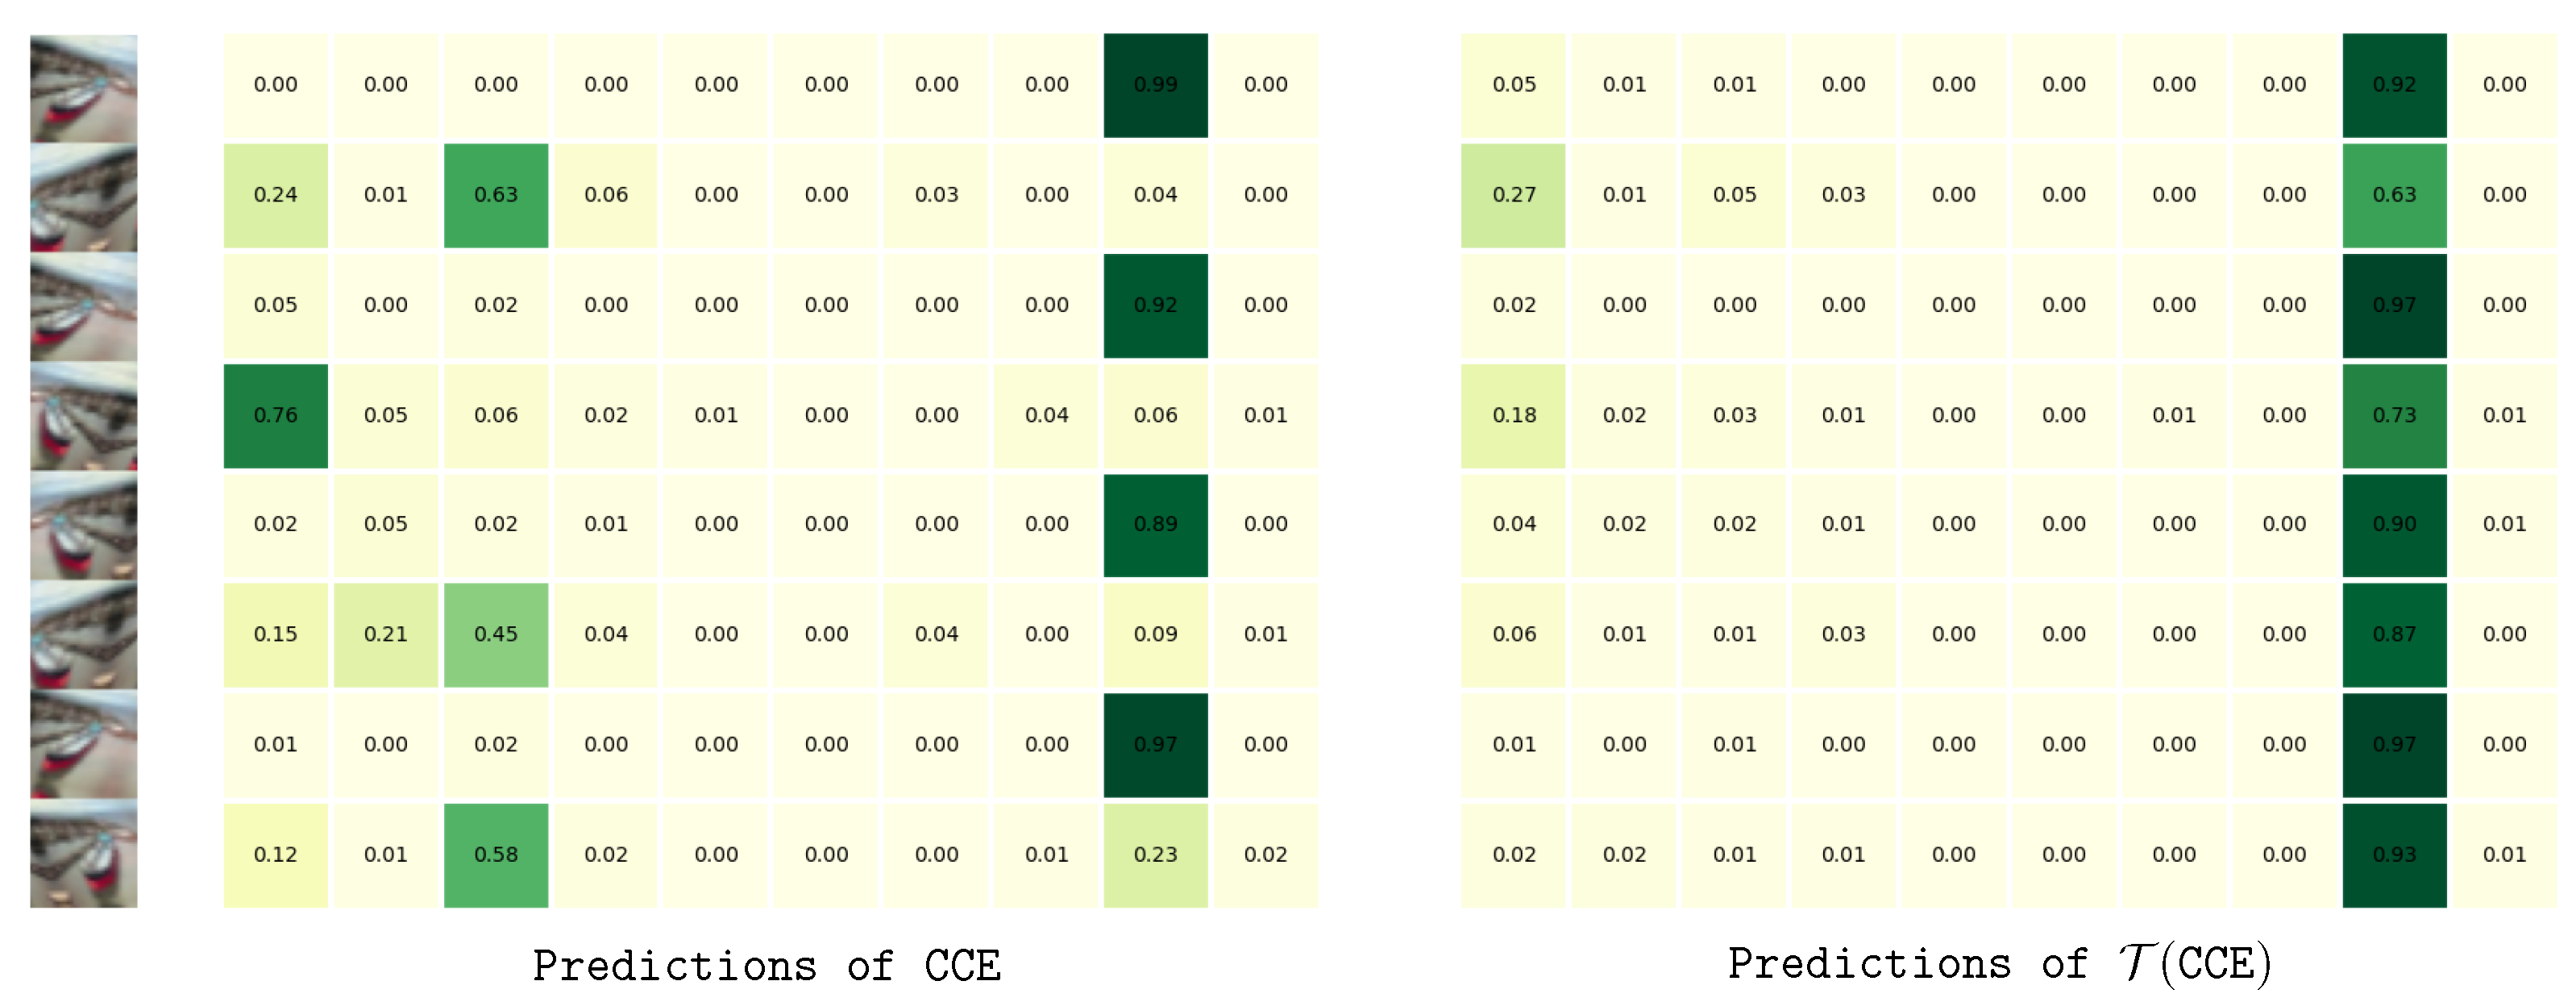
We demonstrate that classifiers trained using LossTransform have a significant change in predictive behaviour. Figure 3 shows the difference between a standard-trained model and a LossTransform-trained model.
Figure 3.
The predicted probabilities of eight augmented images. The left matrix corresponds to the predicted probabilities of a ResNet-20 model trained with CCE loss. The right matrix corresponds to the predicted probabilities of a LossTransform-trained ResNet-20 model. We color the probability background with its value; the higher the value, the deeper the square.
The standard-trained model tends to assign inconsistent predicted probabilities across different augmented images; therefore, the predicted results are easily affected by data augmentation (see Figure 3, left). On the contrary, when we apply LossTransform, the model outputs almost identical prediction probabilities to different augmented images (see Figure 3, right). To the image classification task, we now introduce a concrete variance metric to measure the stability of predictions:
where are the prediction probability vectors of an image under m different augmentations. Figure 3 shows that the model trained with LossTransform has stable output and is minimally influenced by noise and data augmentation.
4.1.4. The Number of Repetitions for REPEATED Augmentation
To evaluate the impact of the number of repetitions m on model training, four distinct data augmentation techniques are used, including affine transformation, horizontal flipping, CutMix, and mixup, with different values of m during training. For other training settings in our experiments, we follow the configurations outlined in the ResNet and DenseNet papers.
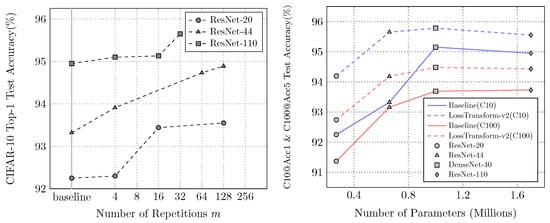
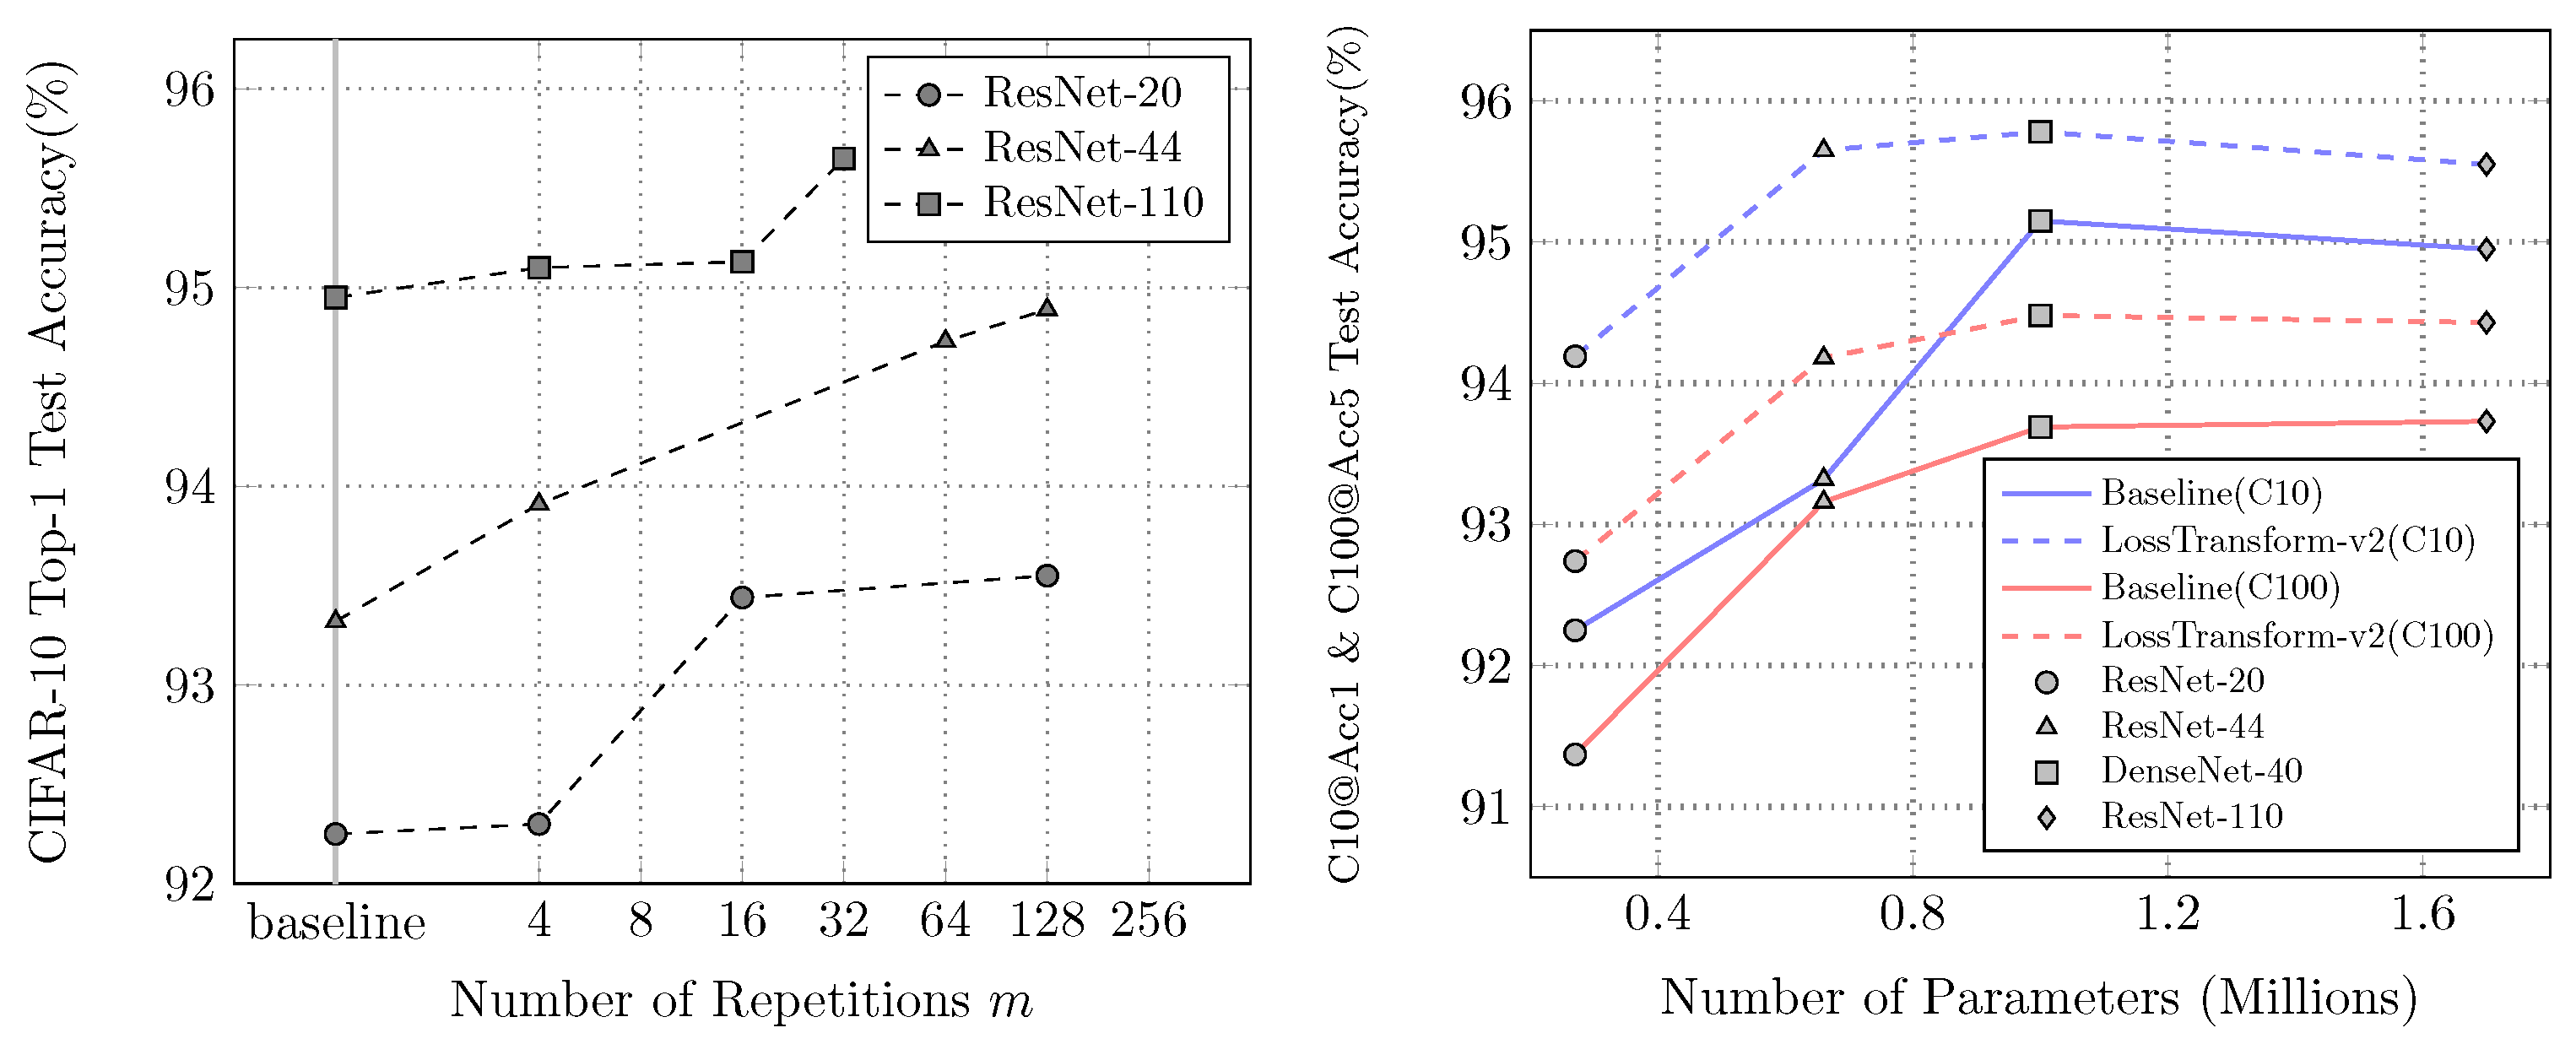
Figure 4 illustrates that the test accuracy reward of models is positively correlated with m. The model trained with tends to yield consistent improvement in accuracy with the growing m. Another factor that affects performance is the network complexity. The model with fewer parameters gains higher test accuracy improvement when training with the loss function. In Appendix B, we also present ablation and sensitivity analyses for both parameters and m.
Figure 4.
Left: All networks tend to gain more performance improvement with the growing number of repetitions m. Right: Small models gain more improvement in CIFAR-10@Acc1 and CIFAR-100@Acc5 tests.
4.1.5. Comparison with Other Loss Functions
Table 2 presents the comparison between the LossTransform and other methods when training models from scratch. We achieve better accuracies on all mini-size ResNet and DenseNet models without using extra training data or pre-trained models.
Table 2.
Test error rates on CIFAR-10 and CIFAR-100 datasets. Comparisons with default CCE (baseline) and Supervised Contrastive Learning (SupCon). The best rates are highlighted in bold.
We also list in Table 2 the results of the large-scale ImageNet model (ResNet-50 with 25.6 million parameters) on the CIFAR dataset [2], the experiments of comparing cross-entropy training, SimCLR [1], maxi-margin classifiers [30], and SupCon [2]. In comparison, we achieve better results on smaller models, and our loss function only requires 120 epochs for training, while other methods are much more complicated (≈1000 epochs).
LossTransform is also suitable for fine-tuning. We conduct experiments using pre-trained MobileNet-V2 [31], NASNetMobile [32], and EfficientNet-B0 [33] models on the ImageNet-1K dataset. In these experiments, we still use the aforementioned simple data augmentation schemes for fair comparison. All models are trained end-to-end by SGD with a momentum of 0.9, a constant learning rate of 0.001, and 30 epochs. We use a batch size of 128 and set m for up to 4.
Table 3 shows the fine-tuning results of for deeper networks. The top-1 and top-5 accuracy refer to the model’s performance on the ImageNet-1K validation dataset. Remarkably, all the pre-trained models are downloaded from the TensorFlow platform. The real validation accuracy (without using any TTA and ensemble methods) of these pre-trained models is much lower. The validation accuracies (MobileNet-V2: 71.3%; NASNetMobile: 74.4%; EfficientNet-B0: 77.1%) shown on the TensorFlow webpage and in corresponding papers are the results of ensemble and multi-crop models [34]) (MobileNetV2: 67.59%; NASNetMobile: 72.11%; EfficientNet-B0: 76.22%).
Table 3.
Comparison among the pre-trained models and fine-tuned models on the ImageNet-1K validation set.
4.1.6. Object Detection and Instance Segmentation
Unlike image classification, object detection and instance segmentation are advanced tasks in computer vision. More specifically, object detection is a hybrid task of regression and classification that requires detecting objects of interest in unknown numbers. Instance segmentation needs to classify each pixel in the image to provide more fine analysis results. To date, most learning algorithms are still evaluated on benchmarks of classification tasks, so building a generalized algorithm that can traverse AI fields is an important challenge.
We investigate the application of LossTransform on PennFudanPed object detection and instance segmentation task. Table 4 shows the evaluation of models on the test set. We get significant improvements by using LossTransform applied to the multi-task loss function , where is the plain multi-task loss function in Mask R-CNN. In this table, every pair of experiments uses the same training configurations, in which each model is trained by two different loss functions, respectively. So the precision gain of models is entirely due to the LossTransform method.
Table 4.
Comparison with the multi-task loss function of Mask R-CNN on PennFudanPed object detection and instance segmentation. Horizontal flipping, random cropping, and simple copy–paste data augmentations are used, and all models are trained from scratch. Mask R- is initialized with a MS COCO pre-trained model and fine-tuned on the new dataset.
In the first experiments, we replace the feature pyramid network (as of v0.14, TorchVision offers the model architectures for ImageNet, and we extract their backbone with a feature pyramid network (FPN) on top of Mask R-CNN) [35] of Mask R-CNN architecture with different structures and retrain the whole model from scratch. For DenseNet121- [14], GoogLeNet- [36], ResNet-50-, and WideResNet50-based [37] FPNs, we set anchors to ((32,), (64,), (128,), (256,), (512,)) which means there are five levels/groups with one anchor size. For ConvNeXt-tiny- [38], EfficientNetB4- [33], InceptionV3- [39], MNASNet1_0- [40], and ShuffleNetV2-based [41] FPNs, we set anchors to ((32, 64, 128, 256, 512), (32, 64, 128, 256, 512)). These models are trained with a mini-batch size of 4 and a total of 18 epochs, with the learning rate divided by factor 10 at epochs 12 and 16. For DensNet121, EfficientNetB4, GoogLeNet, ResNet50, ShuffleNetV2, and WideResNet50, we start training with an initial learning rate of 0.01. Other models start with 0.0025.
In the last two experiments, we freeze the FPN and region proposal network [5] of the pre-trained Mask R-CNN model and then fine-tune it on the new dataset. The learning rate starts at 0.005.
We further investigate the PASCAL VOC 2012 dataset. In order to train the Mask R-CNN with LossTransfrom on this dataset, we need to convert the VOC to a dataset that can conduct the instance segmentation task. Here, we preprocess the dataset by using the algorithm [11,42] to split distinct individual instances from multiple objects of the same class. Then, we freeze the ResNet50-FPN and the region proposal network (RPN) of Mask-RCNN and use transfer learning to retrain the RoI heads. Finally, we achieve 73.5% mAP on the object detection task by training the model with , which gains an extra +0.8% mAP than using .
4.2. Fine-Tuning Benefits from LossTransform-v1
From Figure 1, it can be seen that the reformulated loss function in LossTransform consumes multiple times more memory during computation. For example, a mini-batch of images , after repetition and data augmentation, results in the actual training input , leading to a data throughput during optimization that is three times greater than in the standard training phase. This implies that LossTransform can effectively train large models on large-scale image datasets only if sufficient GPU memory is available.
To address this memory limitation, we apply RASampler in LossTransform. RASampler includes a shuffling and subsampling process. For instance, after sequentially applying shuffling, subsampling, and data augmentation, the actual mini-batch images become , ensuring that the number of examples the model learns from in each iteration remains unchanged.
We investigate the application of LossTransform-v1 on the ImageNet-1K classification (see Table 5) and MS COCO object detection (see Table 6) tasks. In our fine-tuning experiments, TorchVision provides multi-version pre-trained weights for each model architecture [43]. For fair ablation studies, we use the “V1 pre-trained weights” as the default since the corresponding training recipes for “V1 pre-trained weights” are not specifically tailored to each model architecture. We only keep the learning rate as the value from the last epoch in recipes. We empirically find that, when using LossTransform-v1, the model typically achieves performance improvement within 20 training epochs. Our experiments show that LossTransform is effective even for complex models like ViT [44].
Table 5.
Comparison among the pre-trained and fine-tuned models on the ImageNet-1K validation set.
Table 6.
Comparison among the pre-trained and fine-tuned models on MS COCO object detection task. Horizontal flipping data augmentation is used, and all model heads are trained from scratch.
5. Discussion
It is important to acknowledge the limitations of our method. Currently, we focus exclusively on image classification and object detection tasks. However, other recognition or generation tasks, such as text classification and causal language modeling, are also fundamental classification problems. This suggests that our method may be applicable beyond the vision domain, though empirical validation is needed in future work.
In addition, our approach duplicates input data multiple times within each mini-batch to perform diverse data augmentations; while this strategy improves training dynamics, as shown in Section 4, it inevitably increases GPU memory consumption. Nonetheless, we observe that our method accelerates model convergence compared to standard training, which may offset the additional memory overhead over the course of training.
Recent advances in contrastive learning, such as MoCo v3 [45] and DINO [46], have demonstrated strong performance in classification and object detection tasks. Although MoCo v3 and DINO achieve better results in some scenarios, MoCo v3 requires dual encoders for contrastive loss, and DINO relies on an additional teacher network for distillation. Both approaches introduce additional trainable parameters and increase model size. In contrast, LossTransform is a novel loss function paradigm that requires no architectural modifications and can be applied to any model using cross-entropy or multi-loss frameworks.
Finally, our method has not yet been applied to causal language modeling or text classification: (1) LossTransform relies on multiple parallel stochastic augmentations of the same input, which conflicts with causal language modeling. Despite both image classification and causal language modeling using cross-entropy as a loss function, for supervised fine-tuning (SFT) [47] in large language models (e.g., Gemma [48], Qwen [49], DeepSeek [50]), data augmentation is usually prohibited. (2) Perspectively, our method remains applicable to downstream text classification tasks (and other discriminative language tasks), where data augmentation strategies (e.g., back-translation, synonym replacement) are commonly used. In this scenario, the output port of the text classification model is identical to the image classification model, both using cross-entropy loss for optimization, with data augmentation allowed.
6. Conclusions
In this paper, we propose the LossTransform method for training neural networks. This method represents a more generalized approach to contrastive learning, which can be easily implemented through the reformulation of the loss function. It has proved to be effective across various data augmentation schemes, recognition tasks, and neural network architectures. The core principle of LossTransform is to minimize the distances between positive samples or pull together positive samples to their center.
LossTransform does not require the modification of data pipelines, model architectures, and training recipes. Therefore, it will not increase the computational resources requirement for image classification/object detection models. Any model that can be deployed on resource-constrained environments (smartphones or edge devices) can also benefit from LossTransform after training/fine-tuning on servers. This method is user-friendly with a plug-and-play implementation, as it upgrades only the loss function in practical scenarios. It is applicable for either training from scratch and fine-tuning.
For model training, LossTransform contributes to improving the stability of model inference, boosting the convergence speed, and enhancing the efficiency of utilizing data augmentation. LossTransform-v1 addresses the shortcomings of LossTransform regarding memory constraints. In the case of challenging recognition tasks, LossTransform-v1 can continue to yield better evaluation than state-of-the-art baselines.
Author Contributions
Conceptualization, Z.L. and J.C.; methodology, Z.L.; software, Z.L.; validation, Z.L., J.C. and H.H.G.; formal analysis, Z.L.; investigation, Z.L.; resources, Z.L.; data curation, Z.L.; writing—original draft preparation, Z.L.; writing—review and editing, J.C. and H.H.G.; visualization, Z.L.; supervision, J.C. and H.H.G.; project administration, Z.L. All authors have read and agreed to the published version of the manuscript.
Funding
This work is partially supported by the National Science Foundation Grants CNS-2120350 and III-2311598.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
All datasets used in this study are publicly available. The CIFAR-10 and CIFAR-100 datasets are available at: https://www.cs.toronto.edu/~kriz/cifar.html [3], accessed on 18 May 2023. The ImageNet dataset is available at: https://www.image-net.org/ [4], accessed on 18 May 2023. The Microsoft COCO dataset is available at: https://cocodataset.org/ [9], accessed on 18 May 2023. The experimental data, source code, and detailed training logs that were used to generate all figures and tables in this manuscript are publicly available at https://github.com/LizhengMathAi/LossTransform (accessed on 29 November 2025). Identical copies of the figures and tables shown in this paper can be found in the repository to ensure full reproducibility.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| AP | Average Precision |
| CCE | Categorical Cross Entropy |
| hflip | Horizontal Flip |
| mAP | Mean Average Precision |
| RA | Random Augmentation |
| RASampler | Random Augmentation Sampler |
| RPN | region proposal network |
| SSL | Semi-Supervised Learning |
| TTA | Test Time Augmentation |
Appendix A
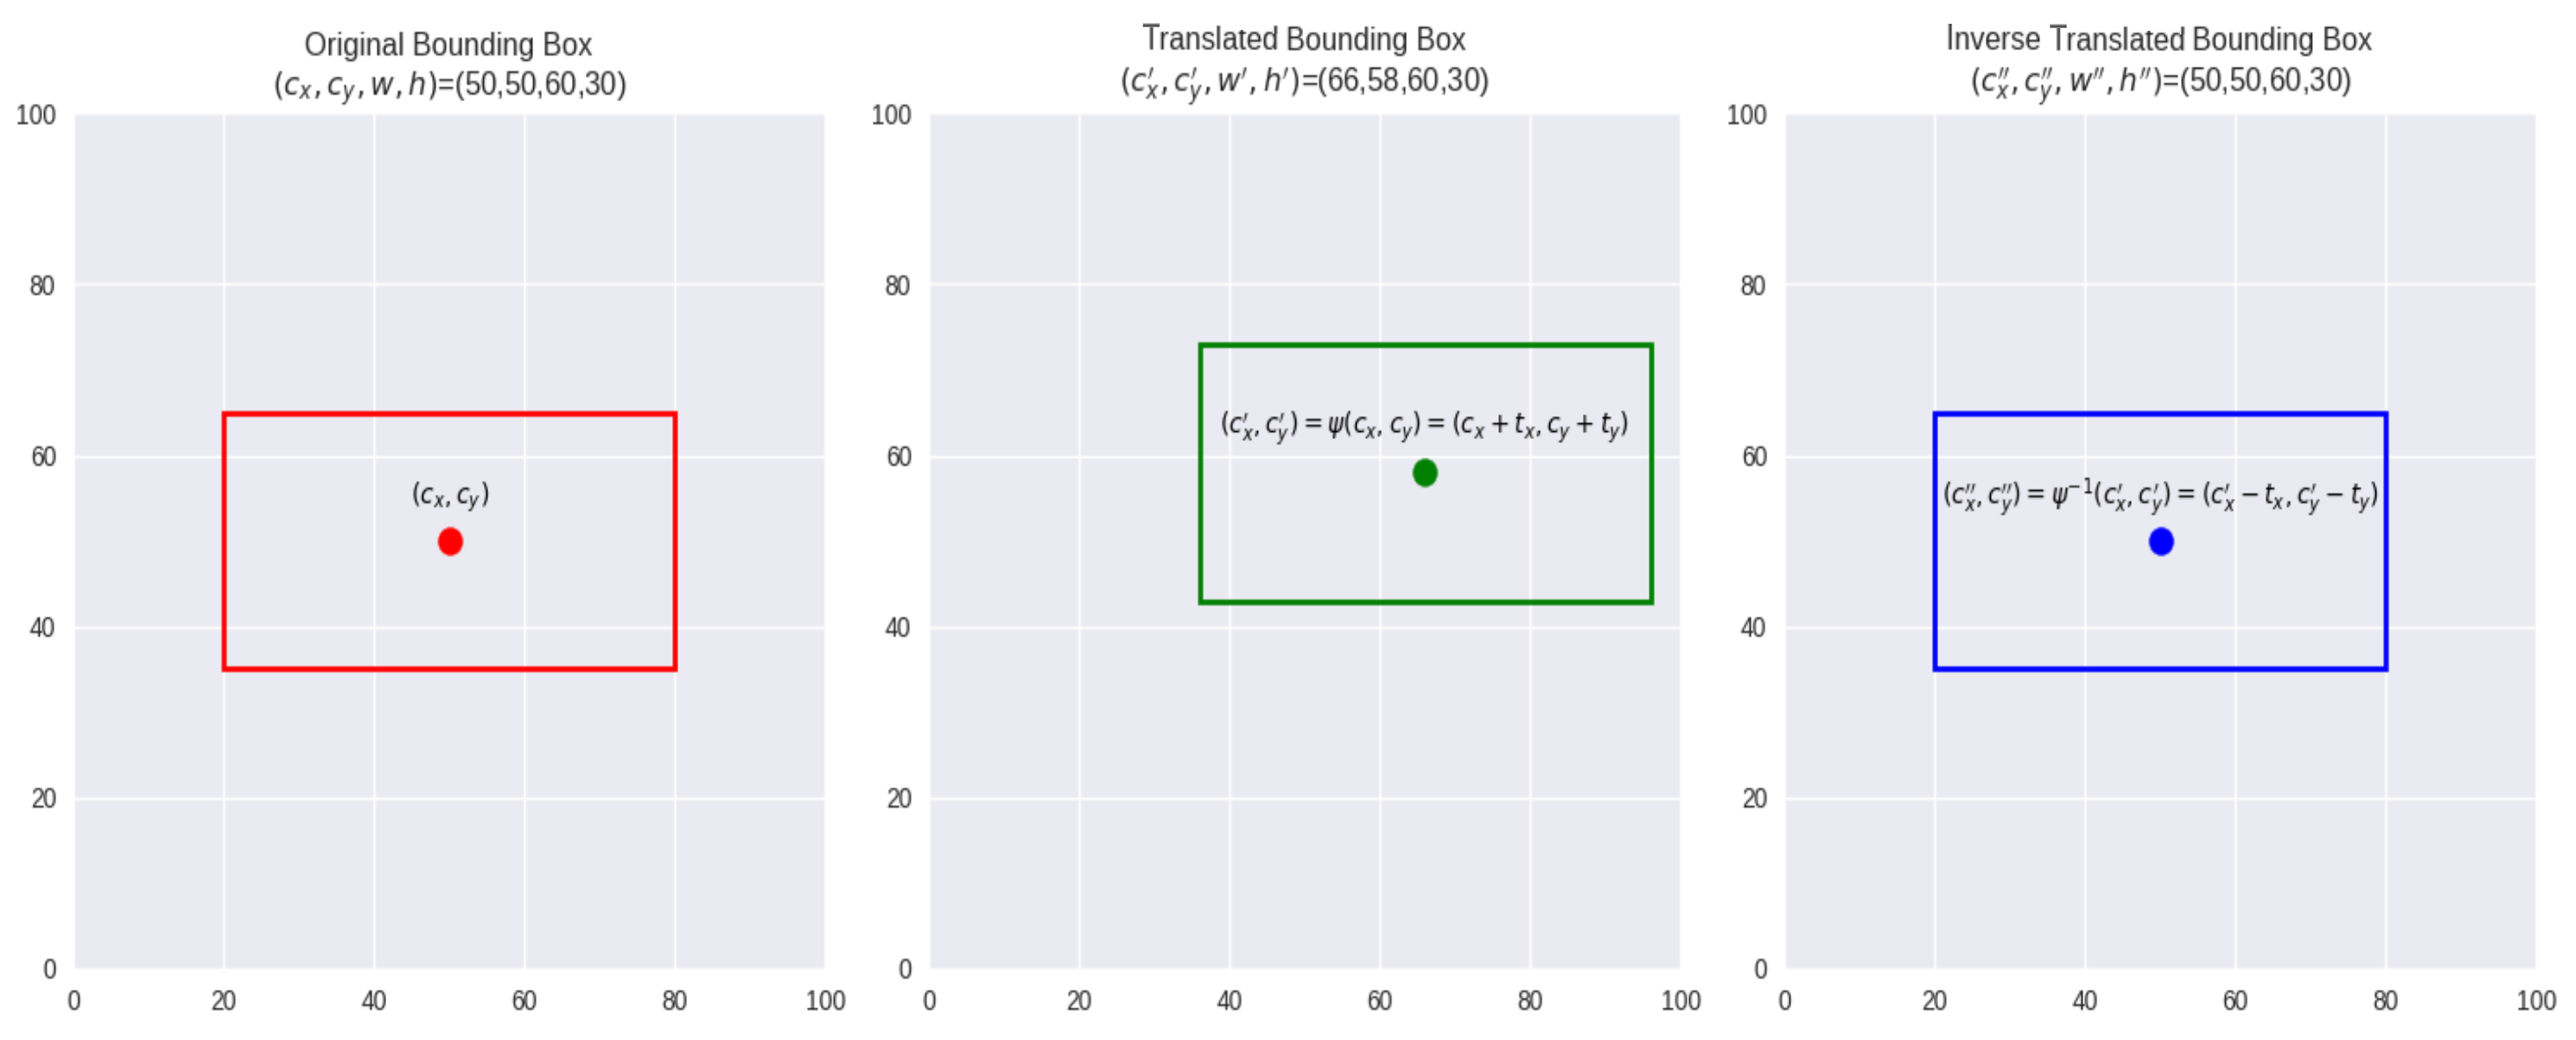
In this section, we visualize the translation transform applied to a bounding box within an image. The translation shifts the center of the bounding box while keeping its dimensions (height and width) unchanged. In this example, Equations (2) and (6) are
Figure A1.
Illustration of bounding box translation and its inverse. The left panel shows the original bounding box (red) with a center at , width , and height . The middle panel depicts the translated bounding box (green) after applying with and , resulting in a new center at . The right panel shows the result after applying the inverse transform (blue), recovering the original bounding box center at .
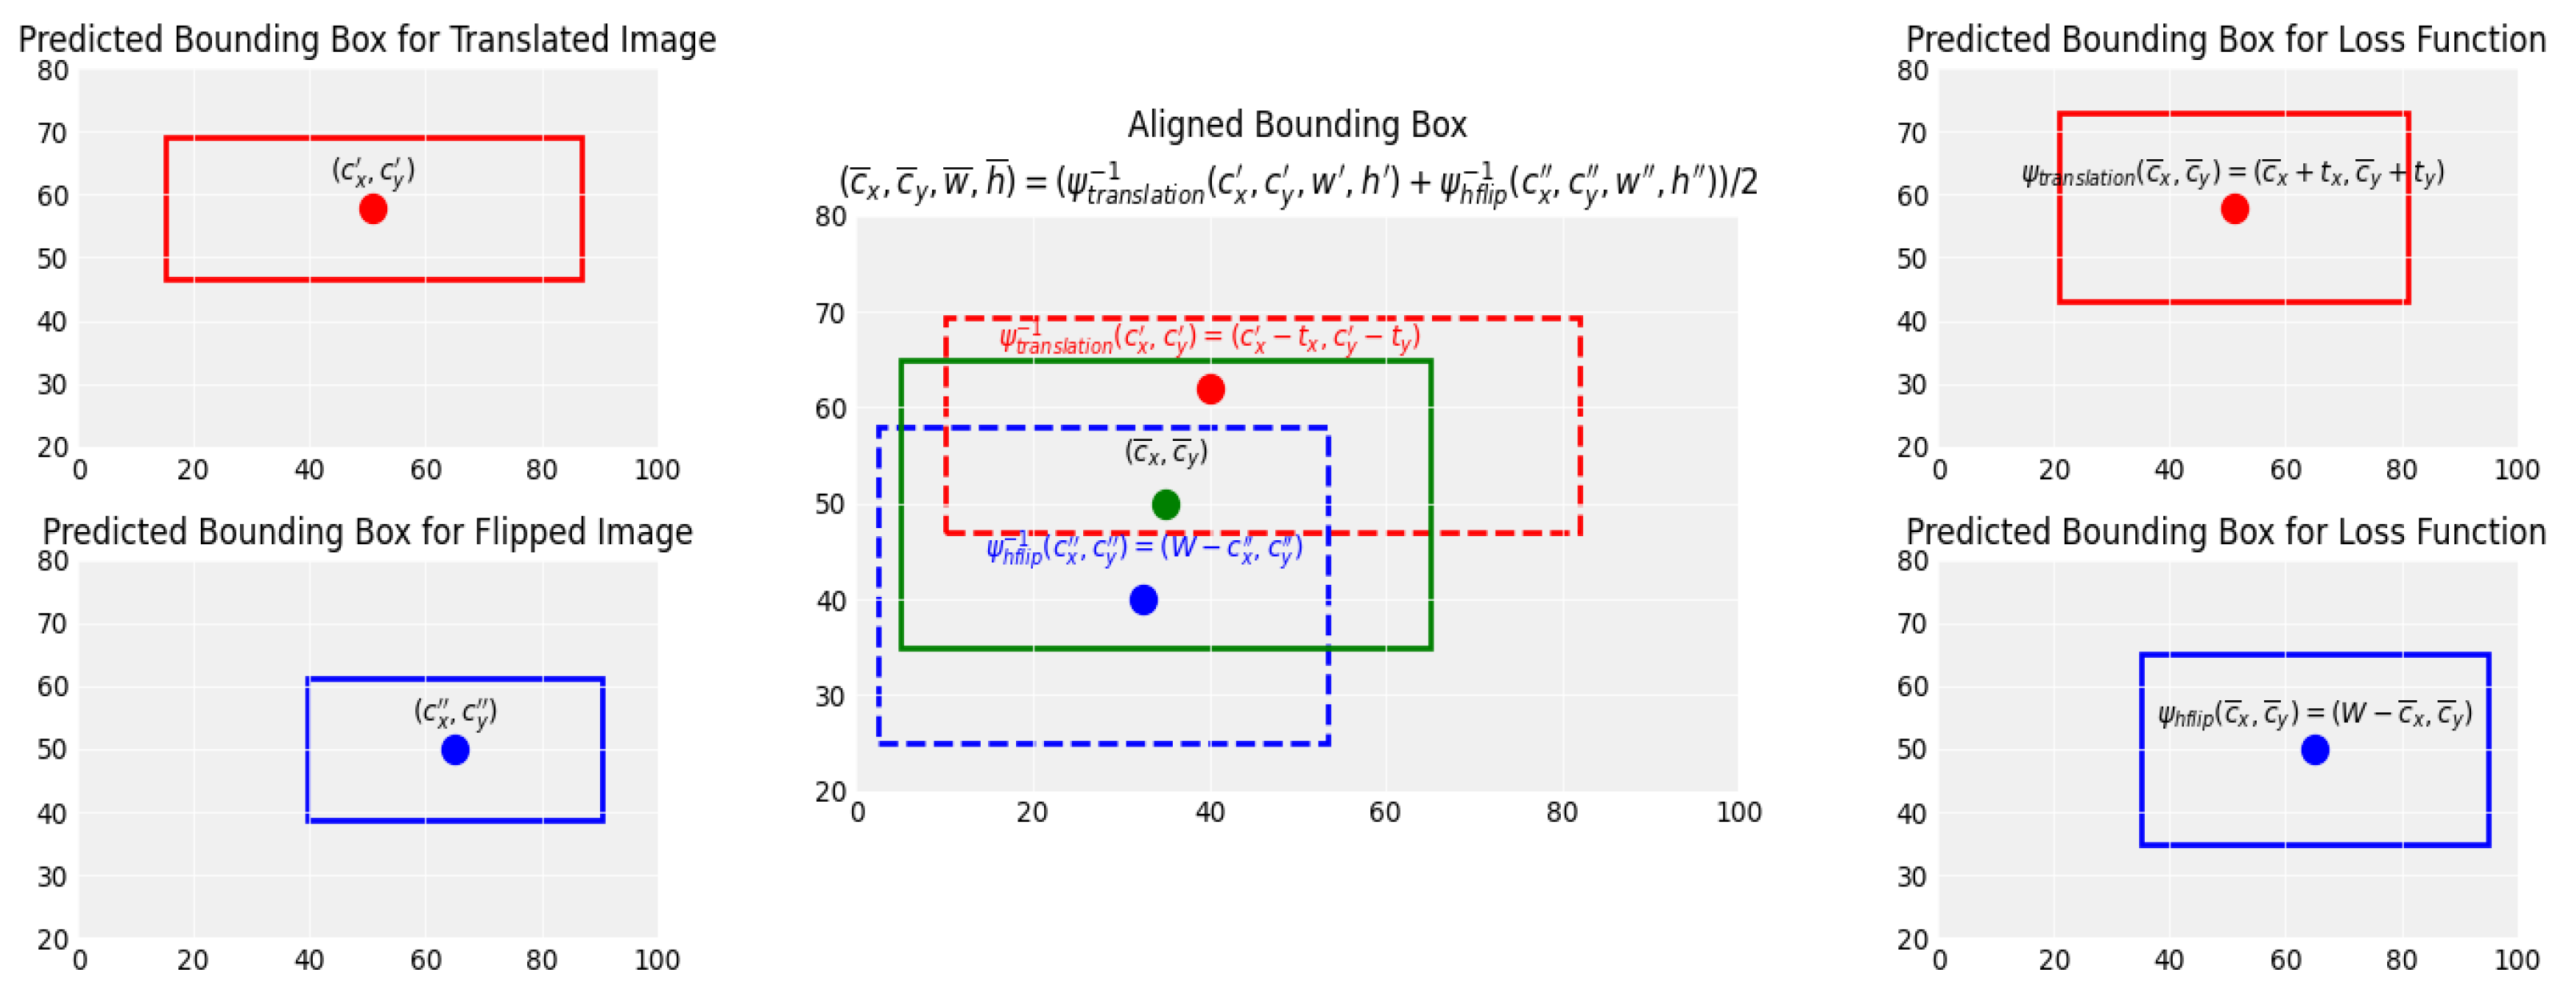
In this section, we also visualize the instance alignment process. In this example, the image is augmented by translation and horizontal flip (hflip), respectively. For the first replica image, the predicted bounding box (red solid) has a center . For the second replica image, the predicted bounding box (blue solid) has a center . After applying the inverse transforms, they are converted to the dashed boxes:
If their predicted classes are the same and the overlap area is greater than a threshold, they are considered a positive pair. Next, we compute the average bounding box (green solid):
with center for the KL divergence. Finally, we apply the original translation and hflip transforms to this average bounding box to obtain the fixed predicted bounding boxes (red solid and blue solid) for the outputs.
Figure A2.
Illustration of bounding box translation and its inverse. The left panel shows the original bounding box (red) with a center at , width , and height . The middle panel depicts the translated bounding box (green) after applying with and , resulting in a new center at . The right panel shows the result after applying the inverse transform (blue), recovering the original bounding box center at .
Appendix B
Our method introduces two hyperparameters, and m. We chose () as the default setting because it provides a stable trade-off across different tasks and datasets. However, the optimal varies by scenario. From the ablation studies in Table A1 and Table A2, we observed that
- Increasing m consistently improves performance up to a saturation point (e.g., 32), while larger values incur diminishing returns due to additional computation.
- Smaller values (e.g., 0.2) work better for high-accuracy image classification models, where the raw prediction confidence is reliable.
- Larger values (e.g., 2.0) benefit object detection or lower-accuracy models, where stronger distillation regularization is needed.
Table A1.
Model performance results on MS COCO object detection task. Horizontal flipping data augmentation and fixed is used, and all model heads are trained from scratch. All networks tend to gain more performance improvement with the growing number of .
Table A2.
Model performance results on CIFAR-10. Experiments applied with the same model are grouped together for test error rate (%) comparison. All networks tend to gain more performance improvement with the growing number of m and decreasing value of . The best test error rates are highlighted in bold.
Appendix C
In deep learning and reinforcement learning, all current loss functions can be viewed as combinations of cross-entropy (CE) and norms, where CE measures the divergence between probability distributions and norms quantify differences in continuous spaces. This perspective highlights the foundational role these components play across various tasks. Below, we provide examples illustrating this composition:
- In image classification and text classification tasks, the loss function is typically the negative log likelihood (NLL), which is the hard-label version of cross-entropy. This encourages the model to assign high probability to the correct class while minimizing probabilities for incorrect ones.
- For Variational Autoencoders (VAEs) and diffusion models, the loss function includes the Kullback–Leibler (KL) divergence, a variant of the soft-label version of cross-entropy. KL divergence measures the difference between the approximate posterior and the prior, and it can be decomposed as , directly linking it to cross-entropy.
- In object detection tasks, particularly for two-stage models like Faster R-CNN, the loss function is a linear combination of cross-entropy for classification and smooth loss for bounding box regression. The smooth loss is a hybrid of and norms, providing robustness to outliers by behaving like for small errors and for large ones.
- For large language models (LLMs), during pre-training from scratch or supervised fine-tuning, the task is causal language modeling, where the loss function is cross-entropy over next-token predictions. In the post-training phase, such as during reinforcement learning from human feedback (RLHF), the policy optimization loss can be separated into multiple cross-entropies (e.g., for policy and value functions) and norms (e.g., for regularization or value estimation).
To extend this to reinforcement learning more broadly, policy gradient methods like REINFORCE use a loss akin to weighted cross-entropy, where the log-probability of actions is multiplied by advantages, while value-based methods like Deep Q-Networks employ mean squared error (an norm) for temporal difference learning. These examples underscore how CE and norms form the building blocks of optimization objectives in modern AI systems.
References
- Chen, T.; Kornblith, S.; Norouzi, M.; Hinton, G. A simple framework for contrastive learning of visual representations. In Proceedings of the International Conference on Machine Learning PMLR, Virtual, 13–18 July 2020; pp. 1597–1607. [Google Scholar]
- Khosla, P.; Teterwak, P.; Wang, C.; Sarna, A.; Tian, Y.; Isola, P.; Maschinot, A.; Liu, C.; Krishnan, D. Supervised contrastive learning. Adv. Neural Inf. Process. Syst. 2020, 33, 18661–18673. [Google Scholar]
- Krizhevsky, A. Learning Multiple Layers of Features from Tiny Images; Technical Report, University of Toronto. 2009. Available online: https://www.cs.toronto.edu/~kriz/cifar.html (accessed on 29 November 2025).
- Russakovsky, O.; Deng, J.; Su, H.; Krause, J.; Satheesh, S.; Ma, S.; Huang, Z.; Karpathy, A.; Khosla, A.; Bernstein, M.; et al. Imagenet large scale visual recognition challenge. Int. J. Comput. Vis. 2015, 115, 211–252. [Google Scholar] [CrossRef] [Scilit]
- Ren, S.; He, K.; Girshick, R.; Sun, J. Faster r-cnn: Towards real-time object detection with region proposal networks. In Proceedings of the 29th International Conference on Neural Information Processing Systems—Volume 1, Montreal, QC, Canada, 7–12 December 2015. [Google Scholar]
- He, K.; Gkioxari, G.; Dollár, P.; Girshick, R. Mask r-cnn. In Proceedings of the IEEE International Conference on Computer Vision, Venice, Italy, 22–29 October 2017; pp. 2961–2969. [Google Scholar]
- Wang, L.; Shi, J.; Song, G.; Shen, I.-f. Penn-Fudan Database for Pedestrian Detection and Tracking. 2007. Available online: https://www.cis.upenn.edu/~jshi/ped_html/ (accessed on 9 August 2024).
- Everingham, M.; Van Gool, L.; Williams, C.K.; Winn, J.; Zisserman, A. The pascal visual object classes (voc) challenge. Int. J. Comput. Vis. 2010, 88, 303–338. [Google Scholar] [CrossRef] [Scilit]
- Lin, T.Y.; Maire, M.; Belongie, S.; Hays, J.; Perona, P.; Ramanan, D.; Dollár, P.; Zitnick, C.L. Microsoft coco: Common objects in context. In Proceedings of the Computer Vision–ECCV 2014: 13th European Conference, Zurich, Switzerland, 6–12 September 2014; Proceedings, Part V 13. Springer: Cham, Switzerland, 2014; pp. 740–755. [Google Scholar]
- Dong, X.; Yu, Z.; Cao, W.; Shi, Y.; Ma, Q. A survey on ensemble learning. Front. Comput. Sci. 2020, 14, 241–258. [Google Scholar] [CrossRef] [Scilit]
- Shanmugam, D.; Blalock, D.; Balakrishnan, G.; Guttag, J. Better aggregation in test-time augmentation. In Proceedings of the IEEE/CVF International Conference on Computer Vision, Montreal, QC, Canada, 10–17 October 2021; pp. 1214–1223. [Google Scholar]
- Simonyan, K.; Zisserman, A. Very deep convolutional networks for large-scale image recognition. arXiv 2014, arXiv:1409.1556. [Google Scholar]
- He, K.; Zhang, X.; Ren, S.; Sun, J. Deep residual learning for image recognition. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Las Vegas, NV, USA, 27–30 June 2016; pp. 770–778. [Google Scholar]
- Huang, G.; Liu, Z.; Van Der Maaten, L.; Weinberger, K.Q. Densely connected convolutional networks. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Honolulu, HI, USA, 21–26 July 2017; pp. 4700–4708. [Google Scholar]
- Gou, J.; Yu, B.; Maybank, S.J.; Tao, D. Knowledge distillation: A survey. Int. J. Comput. Vis. 2021, 129, 1789–1819. [Google Scholar] [CrossRef] [Scilit]
- Galstyan, A.; Cohen, P.R. Empirical comparison of “hard” and “soft” label propagation for relational classification. In Proceedings of the International Conference on Inductive Logic Programming, Corvallis, OR, USA, 19–21 June 2007; Springer: Berlin/Heidelberg, Germany, 2007; pp. 98–111. [Google Scholar]
- Hinton, G.; Vinyals, O.; Dean, J. Distilling the knowledge in a neural network. arXiv 2015, arXiv:1503.02531. [Google Scholar] [CrossRef] [Scilit]
- Kim, I.; Kim, Y.; Kim, S. Learning loss for test-time augmentation. Adv. Neural Inf. Process. Syst. 2020, 33, 4163–4174. [Google Scholar]
- Zbontar, J.; Jing, L.; Misra, I.; LeCun, Y.; Deny, S. Barlow twins: Self-supervised learning via redundancy reduction. In Proceedings of the International Conference on Machine Learning PMLR, Virtual, 18–24 July 2021; pp. 12310–12320. [Google Scholar]
- Athiwaratkun, B.; Finzi, M.; Izmailov, P.; Wilson, A.G. There are many consistent explanations of unlabeled data: Why you should average. arXiv 2018, arXiv:1806.05594. [Google Scholar]
- Touvron, H.; Cord, M.; Douze, M.; Massa, F.; Sablayrolles, A.; Jégou, H. Training data-efficient image transformers & distillation through attention. In Proceedings of the International Conference on Machine Learning PMLR, Virtual, 18–24 July 2021; pp. 10347–10357. [Google Scholar]
- Balasubramanian, R.; Rathore, K. Contrastive learning for object detection. arXiv 2022, arXiv:2208.06412. [Google Scholar] [CrossRef] [Scilit]
- Xie, E.; Ding, J.; Wang, W.; Zhan, X.; Xu, H.; Sun, P.; Li, Z.; Luo, P. Detco: Unsupervised contrastive learning for object detection. In Proceedings of the IEEE/CVF International Conference on Computer Vision, Montreal, QC, Canada, 10–17 October 2021; pp. 8392–8401. [Google Scholar]
- Wu, W.; Chang, H.; Zheng, Y.; Li, Z.; Chen, Z.; Zhang, Z. Contrastive learning-based robust object detection under smoky conditions. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, New Orleans, LA, USA, 18–24 June 2022; pp. 4295–4302. [Google Scholar]
- Terven, J.; Cordova-Esparza, D.M.; Ramirez-Pedraza, A.; Chavez-Urbiola, E.A.; Romero-Gonzalez, J.A. Loss functions and metrics in deep learning. arXiv 2023, arXiv:2307.02694. [Google Scholar] [CrossRef] [Scilit]
- Cubuk, E.D.; Zoph, B.; Shlens, J.; Le, Q.V. Randaugment: Practical automated data augmentation with a reduced search space. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops, Seattle, WA, USA, 14–19 June 2020; pp. 702–703. [Google Scholar]
- DeVries, T.; Taylor, G.W. Improved regularization of convolutional neural networks with cutout. arXiv 2017, arXiv:1708.04552. [Google Scholar] [CrossRef] [Scilit]
- Yun, S.; Han, D.; Oh, S.J.; Chun, S.; Choe, J.; Yoo, Y. Cutmix: Regularization strategy to train strong classifiers with localizable features. In Proceedings of the IEEE/CVF International Conference on Computer Vision, Seoul, Republic of Korea, 27 October–2 November 2019; pp. 6023–6032. [Google Scholar]
- Zhang, H.; Cisse, M.; Dauphin, Y.N.; Lopez-Paz, D. mixup: Beyond empirical risk minimization. arXiv 2017, arXiv:1710.09412. [Google Scholar]
- Liu, W.; Wen, Y.; Yu, Z.; Yang, M. Large-margin softmax loss for convolutional neural networks. arXiv 2016, arXiv:1612.02295. [Google Scholar]
- Howard, A.G.; Zhu, M.; Chen, B.; Kalenichenko, D.; Wang, W.; Weyand, T.; Andreetto, M.; Adam, H. Mobilenets: Efficient convolutional neural networks for mobile vision applications. arXiv 2017, arXiv:1704.04861. [Google Scholar] [CrossRef] [Scilit]
- Zoph, B.; Vasudevan, V.; Shlens, J.; Le, Q.V. Learning transferable architectures for scalable image recognition. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Salt Lake City, UT, USA, 18–23 June 2018; pp. 8697–8710. [Google Scholar]
- Tan, M.; Le, Q. Efficientnet: Rethinking model scaling for convolutional neural networks. In Proceedings of the International Conference on Machine Learning PMLR, Long Beach, CA, USA, 9–15 June 2019; pp. 6105–6114. [Google Scholar]
- Huang, Y.; Cheng, Y.; Bapna, A.; Firat, O.; Chen, D.; Chen, M.; Lee, H.; Ngiam, J.; Le, Q.V.; Wu, Y.; et al. Gpipe: Efficient training of giant neural networks using pipeline parallelism. In Proceedings of the 33rd International Conference on Neural Information Processing Systems, Vancouver, BC, Canada, 8–14 December 2019. [Google Scholar]
- Lin, T.Y.; Dollár, P.; Girshick, R.; He, K.; Hariharan, B.; Belongie, S. Feature pyramid networks for object detection. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Honolulu, HI, USA, 21–26 July 2017; pp. 2117–2125. [Google Scholar]
- Szegedy, C.; Liu, W.; Jia, Y.; Sermanet, P.; Reed, S.; Anguelov, D.; Erhan, D.; Vanhoucke, V.; Rabinovich, A. Going deeper with convolutions. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Boston, MA, USA, 7–12 June 2015; pp. 1–9. [Google Scholar]
- Zagoruyko, S.; Komodakis, N. Wide residual networks. arXiv 2016, arXiv:1605.07146. [Google Scholar]
- Liu, Z.; Mao, H.; Wu, C.Y.; Feichtenhofer, C.; Darrell, T.; Xie, S. A convnet for the 2020s. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Denver, CO, USA, 3–7 June 2022; pp. 11976–11986. [Google Scholar]
- Szegedy, C.; Vanhoucke, V.; Ioffe, S.; Shlens, J.; Wojna, Z. Rethinking the inception architecture for computer vision. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Las Vegas, NV, USA, 27–30 June 2016; pp. 2818–2826. [Google Scholar]
- Tan, M.; Chen, B.; Pang, R.; Vasudevan, V.; Sandler, M.; Howard, A.; Le, Q.V. Mnasnet: Platform-aware neural architecture search for mobile. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Long Beach, CA, USA, 15–20 June 2019; pp. 2820–2828. [Google Scholar]
- Zhang, X.; Zhou, X.; Lin, M.; Sun, J. Shufflenet: An extremely efficient convolutional neural network for mobile devices. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Salt Lake City, UT, USA, 18–23 June 2018; pp. 6848–6856. [Google Scholar]
- Fiorio, C.; Gustedt, J. Two linear time union-find strategies for image processing. Theor. Comput. Sci. 1996, 154, 165–181. [Google Scholar] [CrossRef] [Scilit]
- TorchVision Contributors. TorchVision Models. 2024. Available online: https://pytorch.org/vision/master/models.html (accessed on 9 August 2024).
- Dosovitskiy, A.; Beyer, L.; Kolesnikov, A.; Weissenborn, D.; Zhai, X.; Unterthiner, T.; Dehghani, M.; Minderer, M.; Heigold, G.; Gelly, S.; et al. An image is worth 16x16 words: Transformers for image recognition at scale. arXiv 2020, arXiv:2010.11929. [Google Scholar]
- Chen, X.; Xie, S.; He, K. An empirical study of training self-supervised vision transformers. In Proceedings of the IEEE/CVF International Conference on Computer Vision, Montreal, QC, Canada, 10–17 October 2021; pp. 9640–9649. [Google Scholar]
- Zhang, H.; Li, F.; Liu, S.; Zhang, L.; Su, H.; Zhu, J.; Ni, L.M.; Shum, H.Y. Dino: Detr with improved denoising anchor boxes for end-to-end object detection. arXiv 2022, arXiv:2203.03605. [Google Scholar]
- Sheng, G.; Zhang, C.; Ye, Z.; Wu, X.; Zhang, W.; Zhang, R.; Peng, Y.; Lin, H.; Wu, C. Hybridflow: A flexible and efficient rlhf framework. In Proceedings of the Twentieth European Conference on Computer Systems, Rotterdam, The Netherlands, 30 March–3 April 2025; pp. 1279–1297. [Google Scholar]
- Team, G.; Mesnard, T.; Hardin, C.; Dadashi, R.; Bhupatiraju, S.; Pathak, S.; Sifre, L.; Rivière, M.; Kale, M.S.; Love, J.; et al. Gemma: Open models based on gemini research and technology. arXiv 2024, arXiv:2403.08295. [Google Scholar] [CrossRef] [Scilit]
- Bai, J.; Bai, S.; Chu, Y.; Cui, Z.; Dang, K.; Deng, X.; Fan, Y.; Ge, W.; Han, Y.; Huang, F.; et al. Qwen technical report. arXiv 2023, arXiv:2309.16609. [Google Scholar] [CrossRef] [Scilit]
- Liu, A.; Feng, B.; Xue, B.; Wang, B.; Wu, B.; Lu, C.; Zhao, C.; Deng, C.; Zhang, C.; Ruan, C.; et al. Deepseek-v3 technical report. arXiv 2024, arXiv:2412.19437. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).