


Abstract
With the rapid development of ubiquitous data collection and data analysis, data privacy in a recommended system is facing more and more challenges. Differential privacy technology can provide strict privacy protection while reducing the risk of privacy leakage, but it also introduces unwanted noise, which makes the performance of the recommender system worsen. Among different users, the degree of their sensitivity to privacy is usually different. Thus, through considering the impact of users’ personalized requirements, the collaborative filtering algorithm can be designed to reduce the amount of unwanted noise. Taking the above assertions into account, we propose a collaborative filtering algorithm based on personalized privacy protection. First, it locally classifies ratings by privacy sensitivity on the user side, then utilizes the random flip mechanism to protect the privacy-sensitive ratings. Then, after the server catches the perturbed rating data, we reconstruct the joint item-item distribution through the Bayesian estimation method. Experimental results show that our proposed algorithm can significantly improve the recommendation performance of recommendation systems while protecting users’ privacy.
1. Introduction
Recommendation systems are widely used in real-life recommendation tasks as an effective method to solve the issue of information overload.
Collaborative filtering algorithm is the most classic and commonly used in the field of recommendation system. The basic idea of collaborative filtering algorithm is to recommend items to users based on their previous preferences and the choices of other users with similar interests, that is, based on users’ historical behavioral data to discover users’ preferences and to predict the items that users may like. It does not rely on any items’ additional information (e.g., their own characteristics) or any users’ additional information (e.g., age, gender, etc.). Currently, the most widely used collaborative filtering algorithm is the neighborhood-based method, which includes two main types of algorithms. One type is the user-based collaborative filtering algorithm (UserCF), which recommends products to users according to others has the similar interests as them, the other is the item-based collaborative filtering algorithm (ItemCF), which recommends items which are similar to their previously preferred items. Additionally, recommender systems usually need to collect users’ personal information and interaction records to train models and perform high-quality product recommendations [1,2]. Traditional recommender systems assume that platform parties and users are completely trustworthy with each other. However, the reality is often not as ideal as we think, there often exists the risk of privacy leakage in real scenarios, and this risk exists in multiple ways, including between users and platforms, between users and users, and between platforms and platforms. This leads to the risk of leakage of users’ private information. Collaborative filtering algorithms are widely applied in various fields; however, these algorithms extensively use users’ historical information in the process of preference calculation, which may lead to the risk of privacy leakage [3,4,5]. Therefore, privacy protection in recommendation algorithms is of great concern to users. To address the issue of privacy leakage during recommendation, many studies have tried to bring the differential privacy-preserving strategy into collaborative filtering algorithms [6]. Some typical algorithms include one designed by Zhu et al. [7], which is an item-based differential privacy recommendation algorithm and a user-based differential privacy recommendation algorithm, which can effectively solve the issue of privacy leakage of collaborative filtering algorithms, but due to its neglect of the sensitivity of user rating data, a large amount of noise data is introduced, resulting in unsatisfactory algorithm efficiency, and at the same time, the user-based strategy and the project-based strategy are independent to each other, so advantages of algorithms are not fully released. Wang et al. [8] combined the Bhattacharyya similarity with the K-medoids clustering to improve the accuracy of the similarity measure of the differential privacy-based collaborative filtering algorithms. Meanwhile, the differential privacy mechanism also introduces a lot of noise data that impairs the performance of the recommendation system. How to trade-off between algorithmic performance and the privacy security has become one of the hot spots in the field of differential privacy-preserving recommendation algorithms.
To better protect users’ privacy security, many scholars have tried to introduce the method of data reconstruction, which is an evaluation algorithm based on the probabilistic perturbation mechanism. Traditional evaluation algorithms can only reconstruct the distribution of a single vector; thus, Rade et al. [9] proposed a joint cardinality estimation method to reconstruct the joint distribution of multiple vectors. Then, Chen et al. [10] introduced the joint cardinality estimation method into the neighbor-based collaborative filtering algorithm, which effectively improved the performance of the recommendation system while protecting the security of users’ privacy. Guo et al. [11,12] proposed a joint frequency estimation algorithm based on the random response mechanism, and applied it to the neighbor-based collaborative filtering algorithm to protect the security of users’ privacy. However, the estimation results of these joint estimation algorithms mentioned above are sometimes negative, which can seriously affect the accuracy of the distribution of rating prediction. Furthermore, Ren et al. [13] proposed a distributed reconstruction method for the high-dimensional crowdsourced data based on the random response mechanism, which could greatly improve the release accuracy of the high-dimensional crowdsourced data. However, there exists great differences in structure between the crowdsourced data and the rating data, resulting in the reconstruction method based on high-dimensional crowdsourced data cannot be directly applied to the recommendation system. In addition, different users have different sensitivity to privacy, and ignoring differences between users not only does not meet the user’s personalized privacy requirements, but also introduces additional noise into the data, thereby reducing the performance of the recommendation system.
To address the issue of user privacy leakage, this paper proposes a collaborative filtering algorithm based on personalized privacy protection. Our main contributions include: (1) providing a personalized privacy sensitivity classification and coding method, which can effectively reduce the noise added by the privacy protection; and (2) propose a Bayesian joint distribution estimation method through creatively applying the Bayesian algorithm to the similarity calculation of recommendation systems.
2. Collaborative Filtering Algorithm Based on Personalized Privacy Protection
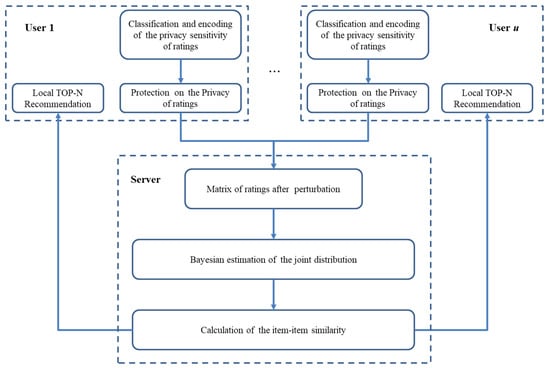
To better protect the security of users’ privacy, while reducing the impact of noise on the performances of the recommendation algorithms, this paper proposes a personalized collaborative filtering-based recommendation algorithm with the differential privacy protection, and the algorithmic architecture is shown in Figure 1.
Figure 1.
Overview of Algorithmic architecture.
From Figure 1, each user locally classifies the privacy sensitivity of ratings and encodes it, then perturbs the ratings and sends the vector of perturbed ratings to the server. According to all the perturbed ratings, the server first utilizes the Bayesian estimation to reconstruct the joint distribution of items, then calculates the item-item similarity and sends the results to users. Finally, it locally completes the high-quality, personalized recommendation.
2.1. Evaluation and Encoding of the Privacy Sensitivity of User Ratings
For recommendation systems, malicious attackers often rely on users’ rating data to infer and obtain user privacy. Numerous studies [14,15,16] have proved that there exists a certain correlation between the size of the ratings and user privacy, and too high and too low ratings tend to be more favorable for malicious attackers to infer users’ private information, such as user preferences. On the other side, from the user’s perspective, both users’ rating habits and the degree of the sensitivity to privacy protection are different. Based on the above two factors, the classification rules of the privacy sensitivity towards users’ ratings are proposed as follows:
where and represent the maximum and minimum values specified by the rating rules, respectively; denotes the average score of user u; is an adjustable variable to adjust the range of intervals classified.
Depending on the sensitivity type of ratings, the encoding function E is
where , , and are 1, 0, and −1, respectively, that is, the encoding function encodes the high-sensitivity score as 1, the low-sensitivity score as −1, and the weakly sensitive score as 0.
The rating of u constitutes the rating vector of . According to the function E, is encoded to be the sensitive rating vector and weakly sensitive rating vector
where represents the collection of items corresponding to the sensitive rating, and represents the collection of items corresponding to the weakly sensitive rating. Additionally,.
2.2. Differential Privacy Protection for Rating Data
To protect the security of the encoded rating data, users need to locally perturb them. Based on the random flip mechanism, the perturbation function for the sensitive ratings is shown below:
where , , and represents the privacy budget, respectively, and represents one random number evenly distributed within [0, 1]. The variable is the result of the inverse operation on . is the output of being perturbed. In the perturbation function of ∅, flips with the probability of p and does not flip with the probability of q, i.e.,
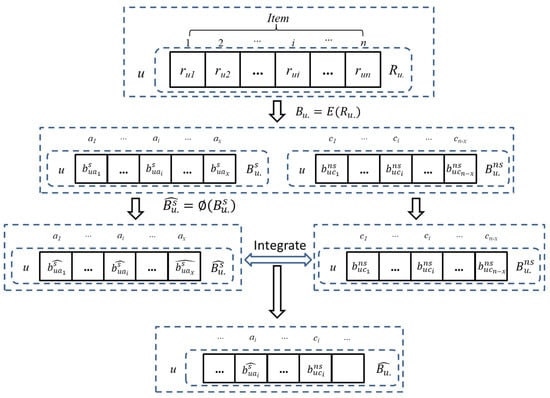
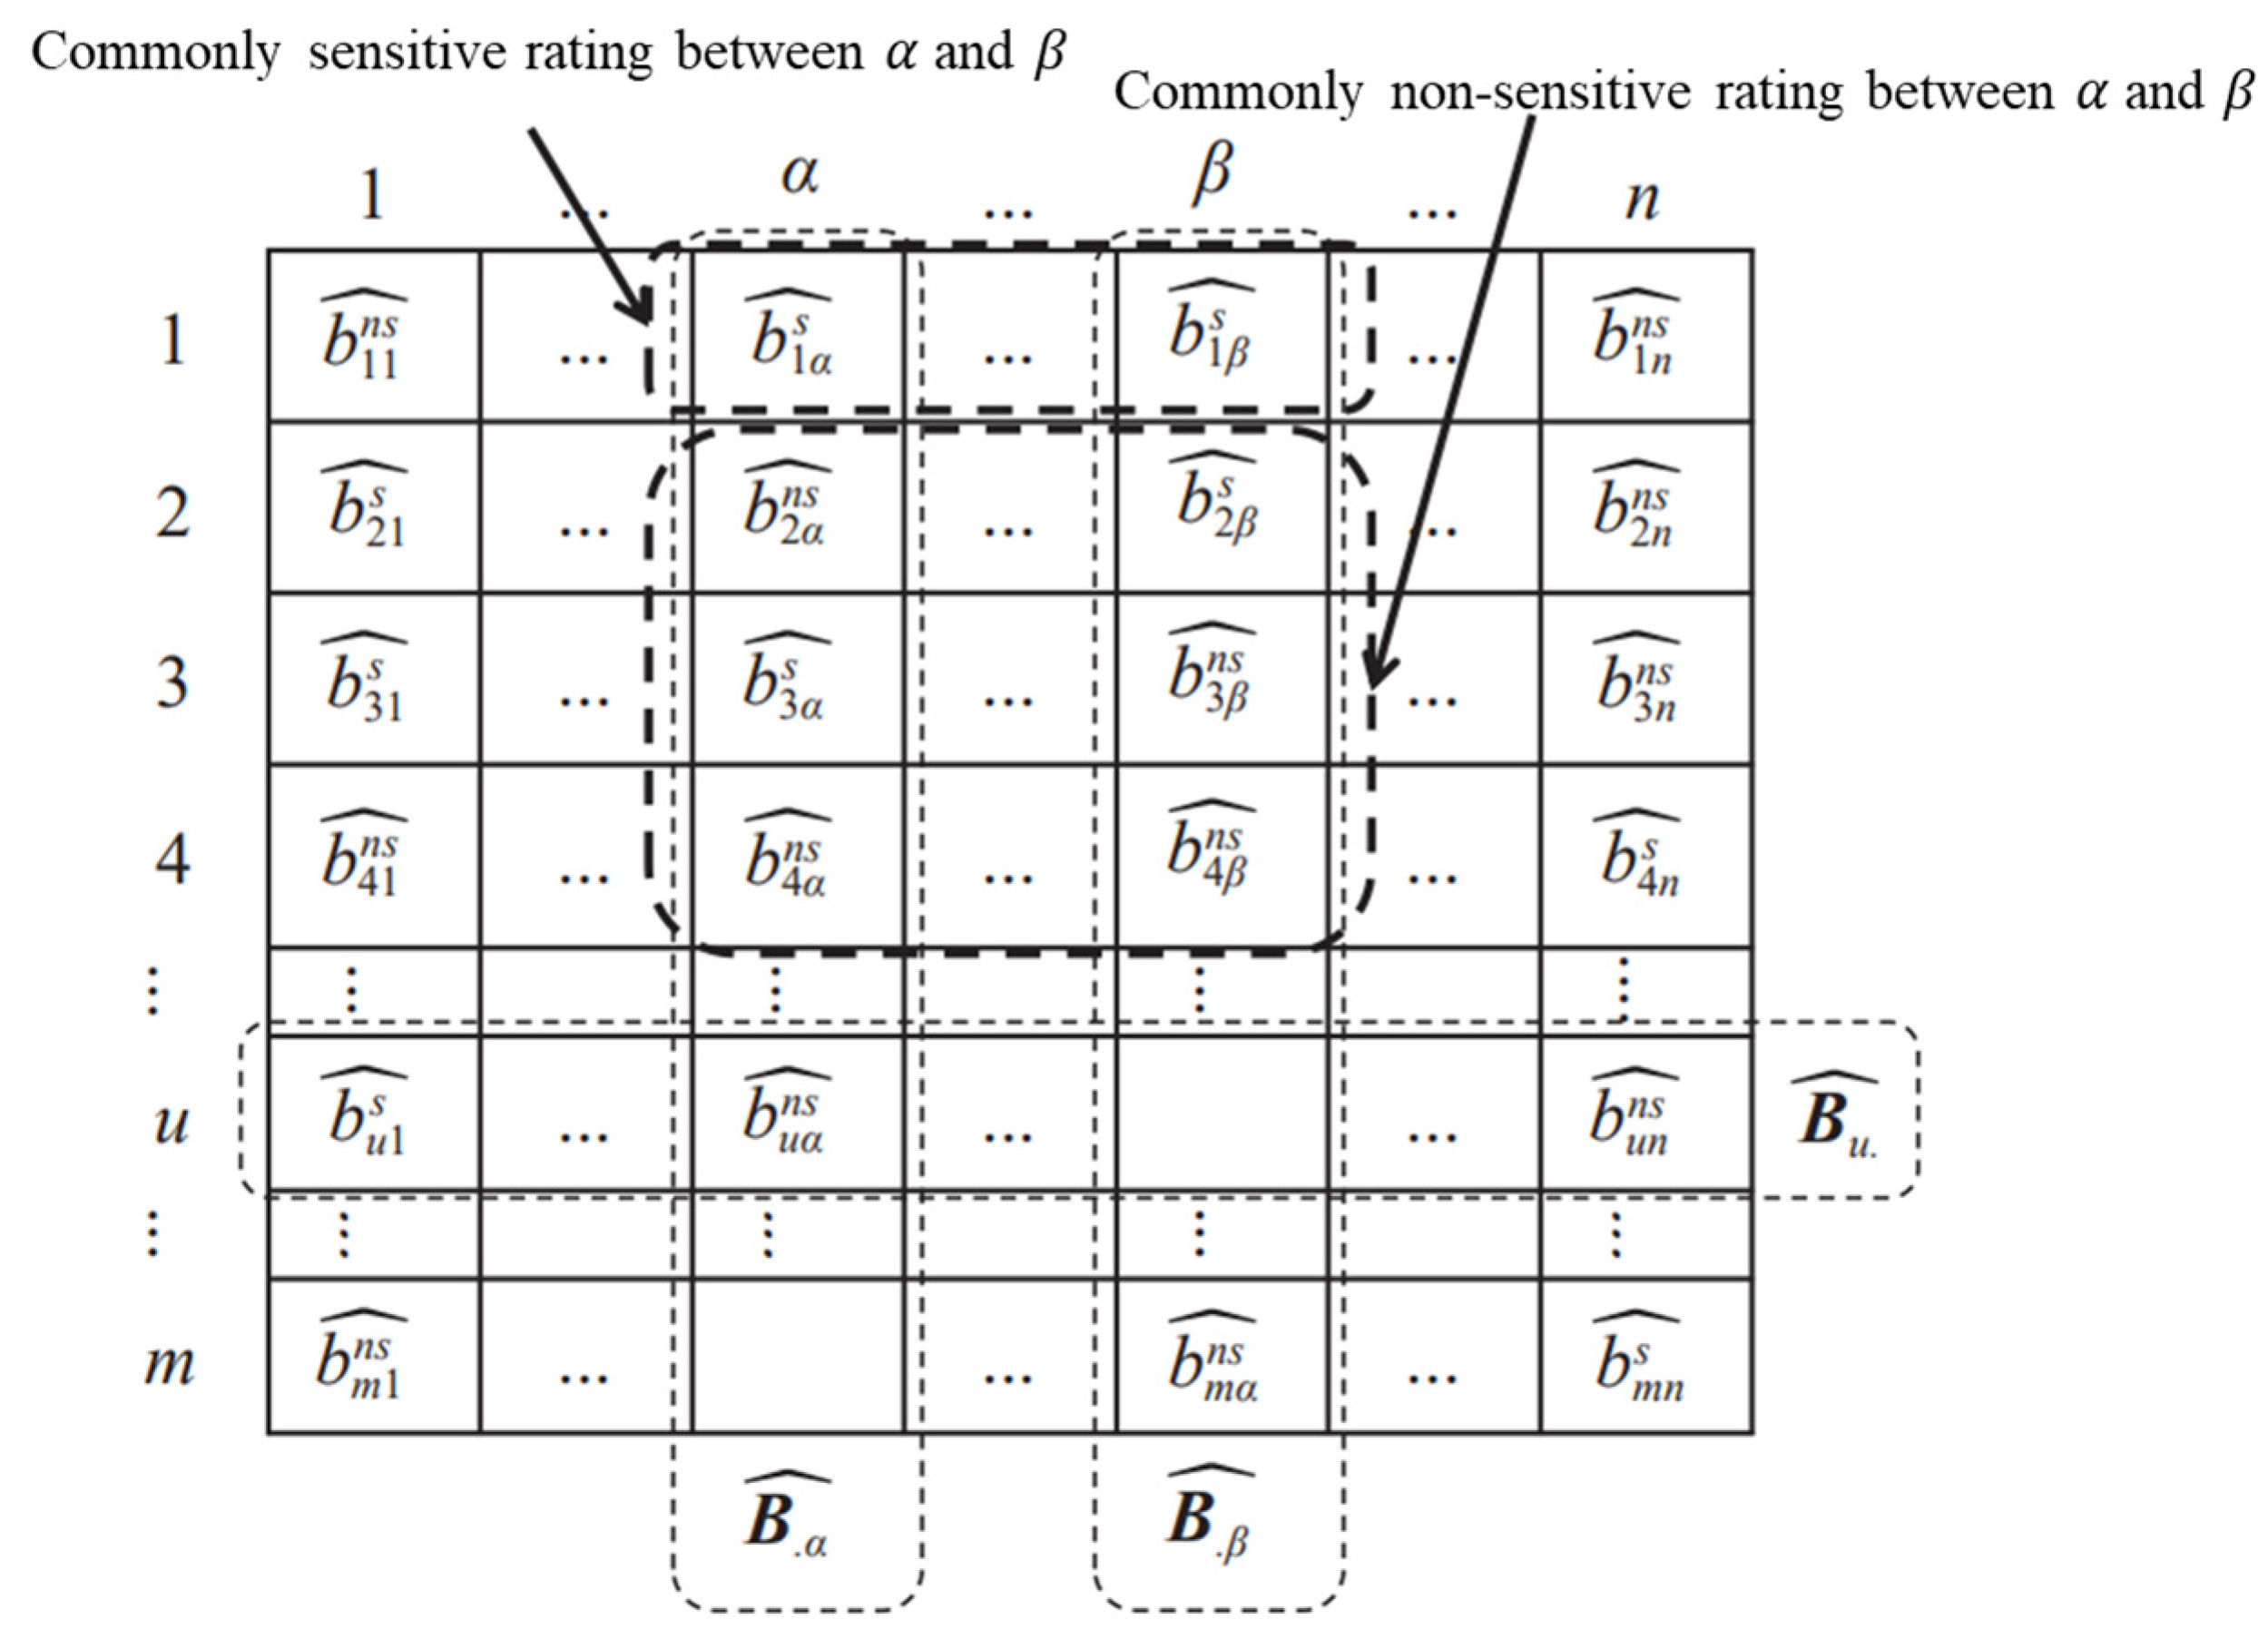
Based on the encoding function and the perturbation function , Figure 2 shows the privacy protection operation for the local rating data. First, encode the rating vector of user to be and through the function . Second, use the perturbation function to perturb each element within to get the perturbed sensitive rating vector . Finally, stitch and into , and send to the server.
Figure 2.
Privacy protection on rating data.
2.3. Item-Item Similarity
After the server receives the perturbed rating data from each user, the perturbation matrix of ratings can be obtained as shown in Figure 3. and represent the perturbation rating vectors for item and item , respectively. According to the type of common ratings stemming from item and item , divide the common ratings into the collection including all the sensitive rating pairs and the collection , including all the weakly sensitive rating pairs, where
Figure 3.
Perturbation matrix .
Furthermore, and represent the collections of users corresponding to and , respectively, then calculate the similarity of each rating pair, then obtain the item-item similarity between and with the weighted sum, i.e.,
where represents the similarity of the sensitive rating pair; represents the similarity of the weakly sensitive rating pair; the parameter denotes the weight coefficient.
2.3.1. Similarity of the Sensitive Rating Pair
To improve the performance of the recommendation system, we use the Bayesian algorithm to reconstruct the joint distribution of the sensitive rating pair within . For and , and represent the collection of pre-perturbation sensitive rating pairs and the collection of post-perturbation sensitive rating pairs.
The joint distribution estimation algorithm based on Bayesian algorithm is shown as follows.
First, initialize the rating pairs in to be uniformly distributed, then calculate the prior probability through Bayesian method, i.e.,
where and represent the random flip probability, respectively; denotes the number of elements in the collection of ; , and represent the i-th element in the collections of and , respectively.
Furthermore, iteratively update the value of the posterior probability estimation for , i.e.,
where represents the times of iterations. In addition, the algorithm stops iterating under the following condition, i.e.,
where is used to control the number of iterations. Finally, Algorithm 1 outputs the Bayesian estimation distribution . According to , the similarity of the sensitive rating pair can be obtained as follows, i.e.,
| Algorithm 1: Joint distribution estimation algorithm based on Bayesian method |
| Input: p,q;,;;,; |
| Output: |
| 1. Initialize ; |
| 2. for in |
| 3. for in |
| 4. Calculate the prior probability according to Formula 5; |
| 5. end for |
| 6. end for |
| 7. Initialize ;//The number of iteration executions |
| 8. while () |
| 9. for in |
| 10. for in |
| 11. Calculate the posteriori probability according to Formula 6; |
| 12. end for |
| 13. end for |
| 14. Calculate according to Formula 7; |
| 15. Update ; |
| 16. return ;//Return after the while loop ends |
2.3.2. Similarity of the Weakly Sensitive Rating Pair
The weakly sensitive rating pair remains the same in similarity as the original rating pair, and the detailed theoretical analysis can be seen in Section 3.1. The similarity of the weakly sensitive rating pair can be calculated by:
where .
2.4. Local Top-N Recommendation
Users can obtain the collection of item neighbors according to the similarity results in the server. The local prediction formula for the user ’s rating of the item α is shown below.
where denotes the original rating of item from user, , and is an element of the collection of . Finally, the top items with the highest predicted ratings are recommended to users.
3. Algorithmic Analysis
3.1. Analysis on Efficiency
In this paper, we mainly use the following two methods to ensure the validity of the rating data, reducing the impact stemming from the privacy noise on the recommendation process.
First, controlling the impact of privacy protection noise on recommendation results through classifying rating data according to its sensitivity. Specifically, for the weakly sensitive rating pair, its similarity is the same as the similarity when the rating data is not perturbed. This is because when encoding the rating data, the weakly sensitive rating is encoded as 0 and the sensitive score is ±1. The difference between the sensitive rating and the weakly sensitive rating, whether before or after the random flip operation, is always 1. Therefore, the sensitivity classification and the encoding strategy adopted in this paper can effectively reduce the influence of noise on the similarity calculation, thus substantially improving the accuracy of the recommendation system.
Second, for the sensitive scoring pair, we utilize the Bayesian algorithm to reconstruct its distribution. Given the distribution of the random flip probability and the distribution of the rating pairs having been randomly flipped, the distribution of the original rating pair can be estimated. The accuracy of the estimation result obtained by Algorithm 1 is affected by the initial value of and the iteration times of . In this paper, initialize the original distribution be the uniform distribution, and through adjusting the times of iterations to ensure the accuracy of the estimation results. Reconstructing the distribution of the sensitive rating pair can reduce the impact of noisy data on the similarity calculation results of the sensitive rating pair, thereby further improving the performance of the recommendation system.
3.2. Analysis on Security
The proposed algorithm uses the random flip mechanism to perturb the encoded privacy-sensitive ratings and accomplish differential privacy protection for the sensitive rating. The proof that the proposed algorithm can satisfy the differential privacy security is as follows.
Assume and be two different collections of neighbor data for user, , and there exists one different sensitive rating element between the two collections, i.e.,
represents the random flip operation. Assume denote the random output of . Then,
Therefore, it can be proved that the proposed algorithm can satisfy the requirements of the ε-differential privacy.
4. Experimental Analysis
In this paper, the analysis of performance is carried out on the publicly available datasets MovieLens 1M and Yahoo Music, and the details of the two datasets are shown in Table 1. To better observe the experimental effect, MovieLens 1M and Yahoo Music are both divided into the training set and the test set in the ratio of 8:2.
Table 1.
Basic information on datasets.
Here, we use the mean absolute error (MAE) and the root mean square error (RMSE) as the evaluation indicators, and detailed definitions of MAE and RMSE are:
where and represent the real rating and the predictive rating of user, , on item, , respectively. and represent the collection of users and the collection of items, respectively.
4.1. Algorithms for Comparison
To further illustrate the performance of the algorithm in this paper, the following mainstream algorithms are selected.
(1) IBCF-DS [1], which is a collaborative filtering algorithm based on item similarity. Similar to PPPCF, it also adopts the rating encoding method [12] to ensure the consistency of the comparison. However, IBCF-DS does not adopt any data privacy protection measures, so it can be used as a baseline for the performance comparison.
(2) PNCF [7], which is an item-based collaborative filtering algorithm. It brings the exponential mechanism and the Laplace mechanism to protect the privacy of data [13,14,15,16], and introduces the recommendation perception sensitivity and truncated similarity to improve the utility of the algorithm.
(3) DPLCF [10], which is a distributed recommendation algorithm. Similar to PPPCF, it uses the random flip mechanism to locally protect the privacy security of the implicit data on the user side, then uses the cardinality estimation mechanism [17,18] on the server side to reconstruct the joint cardinality between items and through reducing the Jekaard similarity error between projects to optimize the accuracy of recommendations.
(4) LDP item-base CF [11], which uses the UE encoding strategy to flip data with a certain probability to locally protect the privacy of data on the user side. On the server side, it uses the frequency estimation and the joint frequency estimation [19,20,21,22] to reconstruct data to reduce the error of privacy noise on similarity and ensure the accuracy of recommendations.
(5) Truncated PPPCE, which is constructed through removing the Bayesian estimation module from PPPCF, in order to illustrate the influence of the Bayesian estimation module on PPPCE.
4.2. Parameter Settings
In this paper, assign 0.05 to the iteration threshold of the Bayesian estimation, and assign 0.2 to the similarity adjustment parameter . However, assign 0.5 to the similarity adjustment parameter in Equation 2 and Equation 3, and refer to the literature [11], assign 0.5 to the parameter of conditional probability similarity in the LDP item-base CF algorithm. To observe the algorithm performance under different privacy budgets, the range of the privacy budget is assigned to [0.1, 1] with the step size of 0.1. To observe the effect of the number of neighbors on the algorithm, the number of neighbors of items is assigned to [20, 100] with the step size of 20.
4.3. Parameter Settings
4.3.1. Effect of N on Experimental Results
Assign 1 to the privacy budget , and Table 2 shows the performance of each algorithm with different numbers of neighbors, i.e., N.
Table 2.
Comparison of the algorithm performance with different values of N.
Table 2 shows that with the increasing value of N, both MAE and RMSE of each algorithm continue to decrease, indicating that the increase in the number of neighbors will improve the accuracy of the recommendation system. PNCF performed poorly because it did not have the data reconstruction module. Among these differential privacy protection-based algorithms, PPPCE performed best in terms of MAE and RMSE, which were closest to the baseline algorithm IBCF-DS. Meanwhile, comparing with Truncated PPPCE, the average MAE of PPPCE is reduced by 8.2% (0.07) and the average RMSE of PPPCE is reduced by 8.3% (0.09) on the dataset of MovieLens 1M; the average MAE of PPPCE is reduced by 8.2% (0.07) and the average RMSE of PPPCE is reduced by 8.3% (0.09) on the dataset of Yahoo Music, indicating that the Bayesian estimation module has a good reconstruction effect on the perturbated data and can effectively improve the performance of the recommendation algorithm. Additionally, seen from Table 2, PPPCE outperforms DPLCF and LDP item-base CF on the two datasets, indicating that the Bayesian estimation method and the data sensitivity division method adopted in PPPCE perform better than the cardinality estimation method and frequency estimation method used in those two algorithms in terms of the data reconstruction.
4.3.2. Effect of on Experimental Results
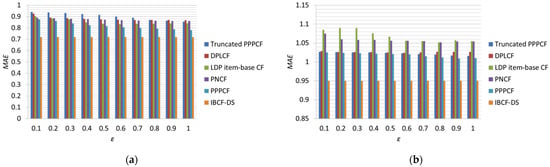
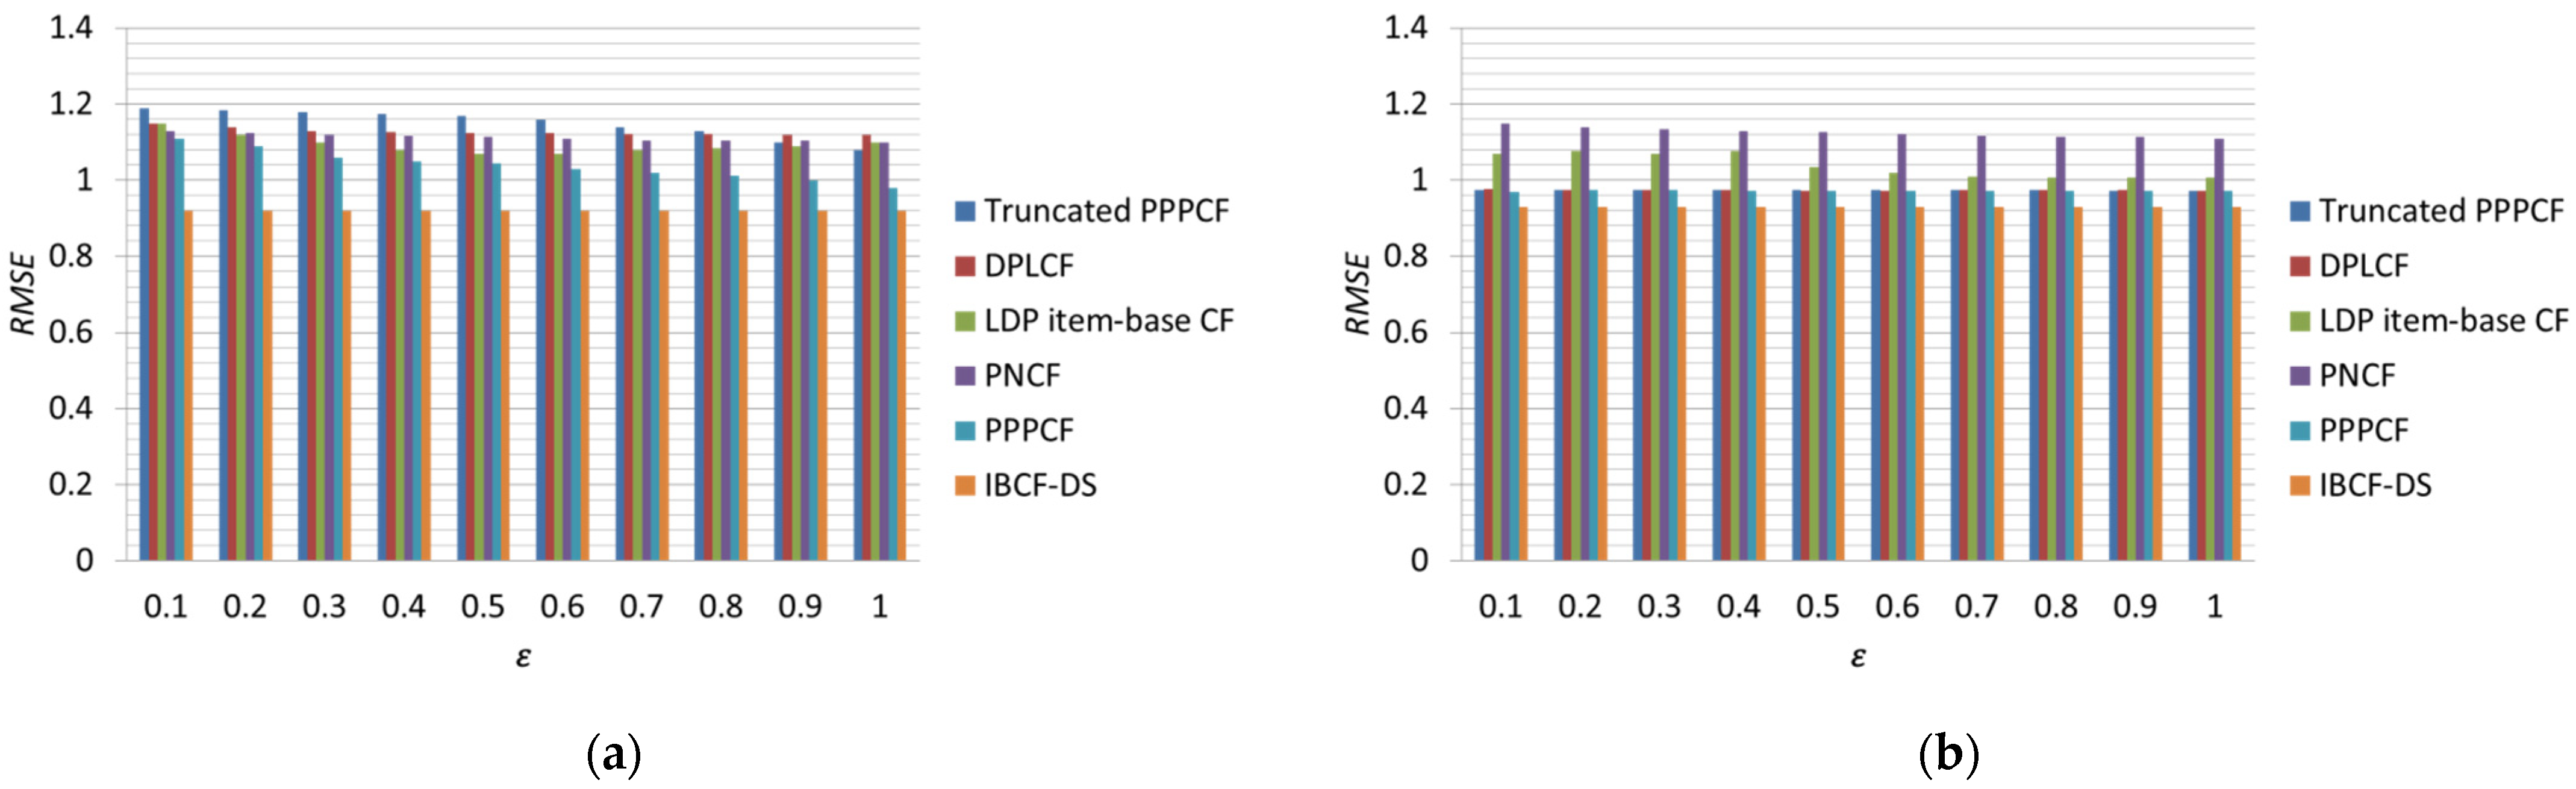
To ensure the effectiveness of privacy protection, we set the value of the privacy budget to be in the range of [0.1,1]. Figure 4 and Figure 5, respectively show the changes of MAE and RMSE on the dataset as the value of changes. Due to the lack of the differential privacy protection mechanism, the curve of IBCF-DS remains unchanged.
Figure 4.
MAE of each algorithm with different privacy budgets . (a) Movielens 1M; (b) Yahoo Music.
Figure 5.
Figure 5.RMSE of each algorithm with different privacy budgets . (a) Movielens 1M; (b) Yahoo Music.
With the increase in ε of the two datasets, both MAE and RMSE show a downward trend. This is because as ε increases, the noise of data decreases and the availability of data increases. Seen from the above figures that PPPCF outperforms other algorithms except IBCF-DS on both datasets. First, each algorithm performs in terms of MAE on the dataset of MovieLens 1M, PPPCF is 9.2% (0.083) less than the Truncated PPPCE, 9.7% (0.089) less than DPLCF, 3.3% (0.028) less than LDP item-base CF, and 5.1% (0.044) less than PNCF. Then, each algorithm performs in terms of RMSE on the dataset of MovieLens 1M, PPPCF is 9.3% (0.106) less than the Truncated PPPCE, 10.6% (0.123) less than DPLCF, 4.2% (0.046) less than LDP item-base CF, and 5.7% (0.063) less than PNCF. Second, due to the data on the dataset of Yahoo Music is sparser, causing the effect of the Bayesian estimation mechanism, the cardinality estimation mechanism, and the frequency estimation mechanism is not obvious, but compared with PNCF without the data reconstruction module, these three data reconstruction algorithms can still bring obvious improvement in utility. Among the three algorithms with data reconstruction, the prediction error of PPPCF still performs best, indicating that PPPCF can indeed improve the accuracy of the recommendation algorithm.
4.3.3. Algorithmic Efficiency
PPPCF mainly consists of three operations: local data processing, similarity calculation, and rating prediction. The local data processing operation can be further divided into two parts, one is the classification and encoding of ratings, the other is the differential privacy protection for ratings. As the local operation needs to traverse all the user-rating vectors in the dataset, its time complexity is .
The item-item similarity calculation includes the similarity calculation of the sensitive rating pairs and the similarity calculation for the weakly sensitive rating pairs. Assuming that the number of sensitive rating pairs is , according to the execution process of BBBCF, when calculating the similarity of an item-item pair, it should traverse the weakly sensitive rating pairs once and the sensitive rating pairs iter times, so the time complexity is , and the time complexity of the similarity calculation on the server side is . From Equation (11), the time complexity of the user’s local prediction for all items is. Choose the DPLCF and LDP item-based CF algorithms, which also apply the localized differential privacy frameworks, for the comparative analysis. According to the calculation process of these two algorithms, the time complexity of their local data processing is also , and the time complexity of the similarity calculation is . Additionally, since the rating prediction model used in the comparison algorithms is the same as PPPCF, so their time complexities of the rating prediction are . Compared with all the comparison algorithms, the time complexity of the local data processing section and the rating prediction section of PPPCF is the same as others, but in the similarity calculation section, the time complexity of PPPCF is higher due to the need to iteratively reconstruct the distribution of rating data. However, since and , it is still in the same range as all the comparison algorithms.
To further verify the results of the complexity analysis, taking the Movielens 1M and Yahoo Music datasets for example, assign and be 1, 100, then evaluate the time overhead of each algorithm on the two datasets, experimental results are shown in Table 3. Each algorithm spends about the same amount of time on local data processing operations, with the PPCF algorithm having the least time overhead. This is because the PPPCF algorithm classifies the data sensitivity before perturbing the data, which greatly reduces the amount of data that needs to be perturbed.
Table 3.
Comparison of the time overhead.
In the process of the similarity calculation, PPPCF is affected by (i.e., number of the sensitive rating pairs) and iter (i.e., times of iterations), so multiple iterations are required to ensure a lower prediction error, causing its time overhead for the similarity calculation is greater than the other comparison algorithms. Meanwhile, the benefit of high time overhead is that its prediction error is lower than others.
Additionally, PPPCF utilizes the Hamming distance to measure the similarity, and in the actual operation process, the Hamming distance between vectors can be obtained through XOR operation, which can improve the operation efficiency of PPPCF algorithm. This is confirmed by the fact that the Truncated PPPCE has a smaller time overhead in calculating similarity in Table 3. For the recommendation algorithm, the efficiency of the rating prediction calculation is particularly important, and the time taken to predict ratings for a single user on the Yahoo Music and Movielens 1M datasets is 6~7 ms and 78~81 ms, respectively, which can meet the actual needs.
In summary, although the PPPCF increases the time overhead caused by the similarity calculation on the server side, it does not affect the efficiency of the rating prediction, and the recommendation error of PPPCF is superior to other algorithms for comparison on datasets of different sparsity. This shows that under the interaction of the privacy sensitivity classification module and the Bayesian data reconstruction module, the similarity calculation is less affected by the perturbed data to achieve higher data availability and recommendation accuracy.
5. Conclusions
Based on the random flip mechanism, this paper proposes a collaborative filtering algorithm with differential privacy-preserving protection. In order to trade off the relationship between privacy protection and performance of recommendation, it classifies ratings into privacy-sensitive and weakly sensitive privacy ratings according to user’s personalized needs for privacy. Then, it brings a coding rule for ratings to effectively reduce unwanted noise resulting from privacy protection. Furthermore, it reconstructs the distribution of the perturbated data through the Bayesian joint estimation model. Experimental results on two public datasets verify that the proposed algorithm has better performance in trading off between the performance of recommendation system and the security of privacy, and it is of certain practical value. Due to the privacy protection reduces the recommendation efficiency of the system to a certain extent, in our future work, we will focus on the data pre-processing strategies, such as cleaning and classification of rating data to further reduce time consumption. Additionally, we will also consider doing some exploration in hybrid recommendation algorithms.
Author Contributions
Conceptualization and methodology, B.C. and W.L.; software, X.Z.; validation, B.C., X.Q. and P.C.; formal analysis, P.C.; investigation, X.Q.; writing—original draft preparation, B.C. and K.F.; writing—review and editing, B.C. and W.L.; funding acquisition, B.C. and X.Q. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by MILITARY PROJECT from PLA EQUIPMENT DEVELOPMENT DEPARTMENT, grant numbers are NO. JK2021A030450 and NO. JK20211A010443, and also funded by the Key-Area Research and Development Program of Guangzhou City from GUANGZHOU SCIENCE AND TECHNOLOGY DEPARTMENT, grant number is NO. 202206030009.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
In order to prevent the data from being abused, we open our data based on reasonable requests. Please contact authors with a formal application form to access the data from liuwei_bit@126.com.
Conflicts of Interest
The authors declare no conflict of interest.
References
- Wei, S.; Ye, N.; Zhang, S.; Huang, X.; Zhu, J. Item-Based Collaborative Filtering Recommendation Algorithm Combining Item Category with Interestingness Measure. In Proceedings of the 2012 International Conference on Computer Science and Service System, Nanjing, China, 11–13 August 2012; pp. 2038–2041. [Google Scholar]
- Su, X.; Khoshgoftaar, T.M. A Survey of Collaborative Filtering Techniques. Adv. Artif. Intell. 2009, 2009, 421425. [Google Scholar] [CrossRef] [Scilit]
- Kenthapadi, K.; Mironov, I.; Thakurta, A.G. Privacy-preserving Data Mining in Industry. In Proceedings of the Twelfth ACM International Conference on Web Search and Data Mining, Melbourne, VIC, Australia, 11–15 February 2019; pp. 840–841. [Google Scholar]
- Zhang, F.; Xue, E.; Guo, R.; Qu, G.; Zhao, G.; Zomaya, A.Y. DS-ADMM++: A Novel Distributed Quantized ADMM to Speed up Differentially Private Matrix Factorization. IEEE Trans. Parallel Distrib. Syst. 2022, 33, 1289–1302. [Google Scholar] [CrossRef] [Scilit]
- Chen, C.; Wu, H.; Su, J.; Lyu, L.; Zheng, X.; Wang, L. Differential Private Knowledge Transfer for Privacy-Preserving Cross-Domain Recommendation. In Proceedings of the ACM Web Conference 2022, Virtual Event, Lyon, France, 25–29 April 2022; pp. 1455–1465. [Google Scholar]
- Zhao, Y.; Chen, J. A Survey on Differential Privacy for Unstructured Data Content. ACM Comput. Surv. 2022, 54, 207. [Google Scholar] [CrossRef] [Scilit]
- Zhu, X.; Sun, Y. Differential Privacy for Collaborative Filtering Recommender Algorithm. In Proceedings of the 2016 ACM on International Workshop on Security And Privacy Analytics, New Orleans, LA, USA, 11 March 2016; pp. 9–16. [Google Scholar]
- Ran, X.; Yin, E.; Wang, Y. Differential Privacy-Preserving Recommendation Algorithm Based on Bhattacharyya Coefficient Clustering. J. Beijing Univ. Posts Telecommun. 2021, 44, 81–88. [Google Scholar] [CrossRef]
- Fenske, E.; Mani, A.; Johnson, A.; Sherr, M. Accountable Private Set Cardinality for Distributed Measurement. ACM Trans. Priv. Secur. 2022, 25, 25. [Google Scholar] [CrossRef] [Scilit]
- Gao, C.; Huang, C.; Lin, D.; Jin, D.; Li, Y. DPLCF: Differentially Private Local Collaborative Filtering. In Proceedings of the 43rd International ACM SIGIR Conference on Research and Development in Information Retrieval, Xi’an, China, 25–30 July 2020; pp. 961–970. [Google Scholar]
- Guo, T.; Luo, J.; Dong, K.; Yang, M. Locally differentially private item-based collaborative filtering. Inf. Sci. 2019, 502, 229–246. [Google Scholar] [CrossRef] [Scilit]
- Wang, T.; Zhang, X.; Feng, J.; Yang, X. A Comprehensive Survey on Local Differential Privacy toward Data Statistics and Analysis. Sensors 2020, 20, 7030. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wu, C.; Wu, F.; Lyu, L.; Huang, Y.; Xie, X. FedCTR: Federated Native Ad CTR Prediction with Cross-platform User Behavior Data. ACM Trans. Intell. Syst. Technol. 2022, 13, 62. [Google Scholar] [CrossRef] [Scilit]
- Knijnenburg, B.P.; Berkovsky, S. Privacy for Recommender Systems: Tutorial Abstract. In Proceedings of the Eleventh ACM Conference on Recommender Systems, Como, Italy, 27–31 August 2017; pp. 394–395. [Google Scholar]
- Chen, C.; Liu, Z.; Zhao, P.; Zhou, J.; Li, X. Privacy preserving point-of-interest recommendation using decentralized matrix factorization. In Proceedings of the AAAI Conference on Artificial Intelligence, New Orleans, LA, USA, 2–7 February 2018. [Google Scholar]
- Meng, X.; Wang, S.; Shu, K.; Li, J.; Chen, B.; Liu, H.; Zhang, Y. Personalized privacy-preserving social recommendation. In Proceedings of the AAAI Conference on Artificial Intelligence, New Orleans, LA, USA, 2–7 February 2018. [Google Scholar]
- Jalili, M.; Ahmadian, S.; Izadi, M.; Moradi, P.; Salehi, M. Evaluating collaborative filtering recommender algorithms: A survey. IEEE Access 2018, 6, 74003–74024. [Google Scholar] [CrossRef] [Scilit]
- Alhijawi, B.; Kilani, Y. A collaborative filtering recommender system using genetic algorithm. Inf. Process. Manag. 2020, 57, 102310. [Google Scholar] [CrossRef] [Scilit]
- Herlocker, J.L.; Konstan, J.A.; Riedl, J. Explaining collaborative filtering recommendations. In Proceedings of the 2000 ACM Conference on Computer Supported Cooperative Work, Philadelphia, PA, USA, 2–6 December 2000; pp. 241–250. [Google Scholar]
- Koren, Y.; Rendle, S.; Bell, R. Advances in collaborative filtering. In Recommender Systems Handbook; Springer: New York, NY, USA, 2021; pp. 91–142. [Google Scholar]
- Miyahara, K.; Pazzani, M.J. Collaborative Filtering with the Simple Bayesian Classifier. In Proceedings of the PRICAI 2000 Topics in Artificial Intelligence, Melbourne, Australia, 28 August–1 September 2000; pp. 679–689. [Google Scholar]
- Wang, W.; Duan, L.-Y.; Jiang, H.; Jing, P.; Song, X.; Nie, L. Market2Dish: Health-aware food recommendation. ACM Trans. Multimed. Comput. Commun. Appl. 2021, 17, 33. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2023 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).