


Abstract
For the problem of online real-time prediction of copper particle content in the lubricating oil of the main spindle-bearing system of mining equipment, the traditional direct detection method is costly and has insufficient real-time performance. To this end, this paper proposes an indirect prediction method based on data-driven neural networks. The proposal of this method is based on a core assumption: during the stable wear stage of the equipment, there exists a modelable statistical correlation between the copper particle content in the oil and the total amount of non-ferromagnetic particles that are easy to measure online. Based on this, a neural network prediction model was constructed, with the online metal abrasive particle sensor signal (non-ferromagnetic particle content) as the input and the copper particle content as the output. The experimental data are derived from 100 real oil samples collected on-site from the lubrication system of the main shaft bearing of a certain mine mill. To enhance the model’s performance in the case of small samples, data augmentation techniques were adopted in the study. The verification results show that the average prediction accuracy of the proposed neural network model reaches 95.66%, the coefficient of determination (R2) is 0.91, and the average absolute error (MAE) is 0.3398. Its performance is significantly superior to that of the linear regression model used as the benchmark (with an average accuracy of approximately 80%, R2 = 0.71, and the mean absolute error (MAE) = 1.5628). This comparison result not only preliminarily verified the validity of the relevant hypotheses of non-ferromagnetic particles and copper particles in specific scenarios, but also revealed the nonlinear nature of the relationship between them. This research explores and preliminarily validates a low-cost technical path for the online prediction of copper particle content in the stable wear stage of the main shaft bearing system, suggesting its potential for engineering application within specific, well-defined scenarios.
1. Introduction
This paper studies the problem of online real-time prediction of copper particle content in lubricating oil in the main spore-bearing system of mining equipment. During the long-term operation of mining equipment, the main spindle-bearing system will produce copper particle impurities due to wear. The size and quantity of these impurities have a significant impact on the operational performance of the mill [1]. In mining equipment, the spindle-bearing system often adopts a friction pair structure of copper-based alloy-bearing shells paired with hardened steel journal shafts. Under the typical working conditions of heavy load, low speed, and continuous operation of this type of equipment, the interface of the friction pair is often in a state of boundary lubrication or mixed lubrication. The main wear mechanisms are adhesive wear and fatigue wear, which cause copper alloy materials to peel off from the surface of the bearing bush in the form of particles and enter the lubricating oil. Therefore, the content of copper particles in lubricating oil can be used as a key specific indicator to characterize the wear state of this copper friction pair. The accumulation of its content not only directly aggravates the deterioration of lubrication performance and accelerates the wear process, but also may cause abnormal system temperature rise, vibration, and even sudden faults, seriously threatening the reliable operation and safe production of equipment [2]. Therefore, real-time and accurate prediction of copper particle content in oil is of crucial engineering value for achieving intelligent maintenance based on state, extending the service life of equipment, and ensuring continuous safe production.
At present, the detection technologies for copper particles are mainly divided into offline and online categories. Although offline methods such as ferrography analysis, combined with energy spectrometers [3,4] or spectral analysis methods [5,6,7], can achieve accurate identification and quantification, their processes are cumbersome and time-consuming, and they cannot meet the urgent need for real-time prediction and early warning of equipment status. In terms of online detection technology, various sensing mechanisms such as inductive [8,9,10], capacitive [11,12,13], and optical sensing [14] have achieved significant development. Among them, typical representatives include the three-coil eddy current sensor proposed by Gu et al. [15] and the twin-solenoid inductive sensor developed by Ma et al. [16]. These devices can achieve online monitoring of abrasive contaminants in hydraulic oil and have the basic classification function of ferromagnetic particles and non-ferromagnetic particles. However, these techniques generally share a common limitation: they can detect the presence of particles and basic ferromagnetic classification, but are restricted in further distinguishing the specific material composition of non-ferrous metal particles (for example, copper and aluminum) [17,18,19]. This leads to a technical gap in the real-time and specific quantitative prediction of the wear status of copper components in systems such as spindle-bearings, which limits the level of refinement in fault diagnosis.
In recent years, with the development of intelligent manufacturing and industrial Internet, the research paradigm in the fields of reliability engineering and intelligent fault diagnosis is accelerating its transformation from traditional threshold alarms and regular maintenance to data-driven predictive maintenance [20,21,22]. Deep learning technology has demonstrated great potential in mining equipment health status information from multi-source sensing data such as vibration, acoustics, and oil [23]. The current research frontier focuses on the use of data-driven models to achieve precise identification and quantitative assessment of early weak faults and specific fault modes. However, for highly specialized diagnostic tasks such as quantitative prediction of wear particles of specific materials, there are still two prominent challenges: (1) The “small sample” predicament: High-value equipment pursues high reliability, resulting in a natural scarcity and high acquisition cost of effective sample data for specific failure modes (such as copper wear), which seriously restricts the training and generalization capabilities of data-driven models. (2) “High cost” constraint: Many high-precision diagnostic solutions rely on multi-source heterogeneous sensor fusion or precise offline analysis equipment, which face bottlenecks in terms of cost, real-time performance, and the ease of industrial field deployment. Although existing studies have explored ways to enhance the performance of models under data scarcity by integrating physical knowledge with deep learning [24], these methods typically require relatively clear physical mechanisms or additional physical parameter inputs. It is extremely difficult to construct an accurate physical model for the quantitative prediction of specific wear particles in lubricating oil, and obtaining additional physical parameters will increase costs and complexity.
Therefore, exploring a technical path that can effectively overcome the limitation of the initial sample size and achieve real-time prediction of specific wear components based solely on a single, mature, and low-cost online sensor signal holds significant theoretical and engineering value.
In view of this, this study proposes an online prediction method for copper particle content in lubricating oil based on neural networks and data augmentation technology. The core idea is as follows: Utilize the potential statistical relationship that may exist between the total amount of non-ferromagnetic particles and the content of copper particles in the oil during the stable wear stage of mining equipment [25], and using the widely applied online sensor signal of metal abrasive particles as input, a nonlinear mapping model from easily measurable parameters to difficult-to-measure parameters is established through the construction and training of a neural network model. The main purpose of this study is as follows: (1) Construct and verify the feasibility of this prediction model; (2) introduce data augmentation strategies to alleviate the small sample constraints and enhance the model’s robustness; (3) design an online prediction solution.
The arrangement of this article is as follows: Section 2 introduces the establishment method of the online prediction model for copper particle content. Firstly, the overall idea of establishing an online prediction model was expounded. The data augmentation method is presented, and the establishment process of the prediction model based on neural network technology is described in detail. In Section 3, a case study was conducted. Firstly, a hydraulic pipeline system for online detection of non-ferromagnetic particles based on metal abrasive particle sensors was established. Combined with the offline copper particle detection method, a database of copper particle content and non-ferromagnetic particle content was obtained. On this basis, through data augmentation methods and neural network technology, an online prediction model for copper particle content based on non-ferromagnetic particle content was trained, and the accuracy of the prediction model was verified. Section 4 summarizes the key conclusions, limitations and future development directions of this study.
2. Establishment of an Online Prediction Model for Copper Particle Content
2.1. The Overall Idea for Establishing an Online Prediction Model
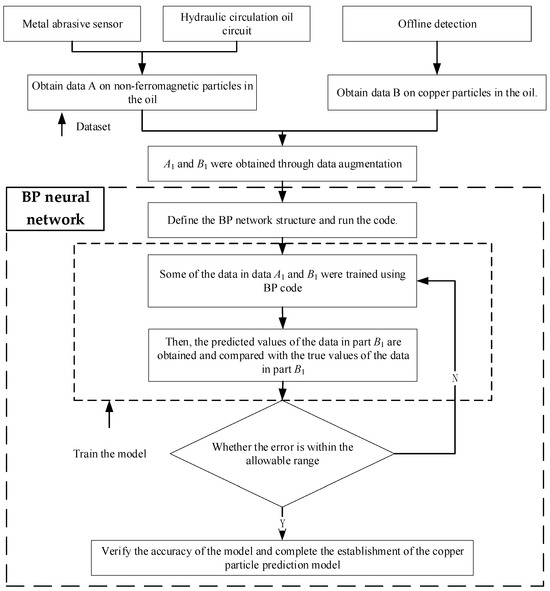
The overall idea of the online prediction model constructed in this paper is shown in Figure 1. The specific steps for constructing an online prediction model are as follows: Firstly, an offline detection method is adopted, combined with oil filtration and separation technology as well as inductively coupled plasma atomic emission spectrometry or mass spectrometry, to obtain the content of copper particles in the oil. Secondly, a hydraulic circulation system including a metal abrasive particle sensor and a lubricating oil pump should be established to predict the content of non-ferromagnetic particles in the oil in real time. Due to the difficulty in the oil sampling and the small amount of data, the accuracy of the prediction model will be affected. Therefore, methods such as feature space linear interpolation, principal component perturbation, and data transformation are adopted to conduct data augmentation on N groups of data composed of non-ferromagnetic particle data A and copper particle data B to expand the data volume. The expanded data consists of N1 groups (comprising non-ferromagnetic particle data A1 and copper particle data B1). Based on the above data, write the BP neural network program(MATLAB R2020a), define the network structure, and initialize the parameters. The network input is the content of non-ferromagnetic particles, and the output is the content of copper particles. The network is trained through the backpropagation algorithm to establish the statistical relationship between the two. The content of copper particles is predicted based on the content of non-ferromagnetic particles. The error between the predicted result and the true value is adjusted through multiple iterative training until the accuracy requirements are met.
Figure 1.
Overall idea of establishing an online prediction model of copper particles.
Ultimately, an online prediction model for copper particles was constructed based on the statistical relationship between A1 and B1 to achieve real-time prediction of the copper particle content in the oil.
Software and Implementation: All the computational analyses, data preprocessing, construction of neural network models, training and evaluation in this study were carried out in the MATLAB R2020a environment. All schematics and flowcharts were drafted using Microsoft Visio 2016 (Version 16.0), while all data-driven plots and analysis charts were generated within the MATLAB R2020a environment.
2.2. Data Augmentation Method
Data augmentation is a widely applied technique in model training. It artificially creates new and additional training samples based on existing data through a series of random but reasonable transformations, thereby expanding the scale and diversity of the dataset. The core idea is to make full use of existing data without collecting additional new data, and to enable the model to learn more robust and generalized features by creating new data.
Due to the difficulty in sampling oil products and the small amount of copper particle data in the oil products, the accuracy of the prediction model will be affected. Therefore, the method combining feature space linear interpolation, principal component perturbation and data transformation is adopted for the data of copper particles in oil. Due to the difficulty of oil sampling and the small amount of data on copper particles in oil, it will affect the accuracy of the prediction model. Therefore, a method combining feature space linear interpolation, principal component perturbation and data transformation is adopted to enhance the data of copper particles and non-ferromagnetic particles in the oil.
At present, there is no clear theoretical or empirical model regarding the quantitative relationship between the content of non-ferromagnetic particles and copper particles in lubricating oil. In the absence of prior knowledge, data augmentation relies on reasonable assumptions about the data generation process. This study is based on the following observation: During the stable wear stage, the wear particles produced by the same friction pair may show a continuous and smooth changing trend in terms of composition and quantity. Therefore, in the feature space composed of the number of non-ferromagnetic particles (A) and the number of copper particles (B), linear interpolation between similar samples can be regarded as a reasonable approximation of the continuous change in the wear state. To enhance the diversity and rationality of the generated data, we further introduced a slight perturbation based on principal component analysis (PCA) after interpolation to simulate the minute fluctuations existing in the real data, thereby avoiding the generation of overly idealized or repetitive samples.
The core idea of the feature space linear interpolation method is as follows: directly connect two real data points in the space jointly formed by “features and targets”, and “sample” new data points on this connection line. It can be expressed as
where and are random non-ferromagnetic particle content data in N groups of oil particle detection data, and are random copper magnetic particle content data (ii and jj are randomly selected dissimilar data indexes); is the interpolation coefficient; represents the newly generated data group through interpolation. This method can strictly maintain the joint distribution characteristics of the original data. Any newly generated points are located within the convex hull formed by the original data points, fully adhering to the statistical relationship presented by the data itself.
To ensure that the data generated by interpolation conforms to the physical continuity of the wear process, the selection of interpolation points and is not completely random. This study adopts a distance-based screening strategy: interpolation is only performed when the Euclidean distance between two points in the feature-target joint space is less than the threshold D_max. D_max is set to 1.2 times the average distance of all the original data in this space to ensure that interpolation occurs in the local neighborhood with a similar wear mechanism. The interpolation coefficient is randomly sampled from the uniform distribution U (0, 1) to ensure that the new data points are uniformly distributed along the selected line segments. This strategy strikes a balance between data diversity and physical rationality.
After the data is enhanced by interpolation through the feature space linear interpolation method, the principal component perturbation method is adopted for supplementary data enhancement to increase the density and smoothness of the data distribution. The core idea is to transform the data from its original coordinate axes to its “natural” coordinate axes, and then add noise to the main variation directions indicated by these new coordinate axes (based on the assumption that the direction with the greatest data variation is the most important direction, while the direction with the least variation is the direction of noise or secondary features). Among them, the existing data group can be expressed as matrix :
then the data matrix is decomposed by PCA. PCA will find a new set of orthogonal bases (principal components), among which, the first principal component is the direction with the largest variance of the data, and the second principal component is the direction orthogonal to and with the second-largest variance. This is achieved through Singular Value Decomposition (SVD):
where is the left singular vector matrix, which is the eigenvector of ; is the right singular vector matrix, which is the eigenvector of ; is a 2 x 2 matrix, and its columns are the principal components and ; is a singular value matrix, and the elements on its diagonal are singular values , which are proportional to the standard deviation of the principal components.
Furthermore, for any original data point , generating a new data point can be expressed as
where is an original and unstandardized data point; and are the estimates of the standard deviations in the first and second principal component directions, respectively, which can be expressed as ; and represent the random noise figures sampled from the normal distribution, that is, , where c is used to control the amplitude of the disturbance.
To ensure that the generated perturbation data is both diverse and does not deviate from the actual physical distribution, the setting of the perturbation amplitude parameter c in this study is associated with the standard deviation of each principal component direction. Specifically, take , that is, add Gaussian noise with a standard deviation of 15% in each principal component direction. This proportion was determined through a preliminary sensitivity analysis: when c is within the range of to , augmented data can effectively enhance the model’s generalization ability without introducing obvious abnormal samples. Finally, is selected as the robust value for balancing data diversity and distribution fidelity.
In addition, data transformation can be carried out within the local neighborhood (assuming that the data is linear within the local domain), which can be expressed as
where and are data within the neighborhood; and are similar small random values. Among them, the random coefficients and are sampled from the normal distribution N(1, 2) with a mean of 1 and a standard deviation of to simulate the possible minor measurement fluctuations or operating condition disturbances in actual predictions. In this study, was set to 0.08 through experiments. After all the data augmentation steps are completed, the original data and the augmentation data are projected into a two-dimensional space through t-SNE visualization for qualitative inspection. It is confirmed that the augmentation data points closely surround the original data clusters, and no obvious distribution drift or abnormal aggregation occurs.
In summary, by expanding the data on the content of N groups of non-ferromagnetic particles and copper particles measured in the experiment, and combining different data augmentation methods (MATLAB R2020a), N1 groups of oil particle detection data (consisting of non-ferromagnetic particle data A1 and copper particle data B1) can be obtained.
2.3. Establishment of a Prediction Model Based on Neural Network Technology
BP neural network is a multi-layer feedforward neural network, and its learning process consists of two processes: the forward propagation of signals and the backward propagation of errors. Through the backpropagation algorithm, the weights and thresholds of the network are constantly adjusted, causing the output error of the network to change in a decreasing direction until the expected accuracy is achieved. Its structure typically consists of an input layer, a hidden layer, and an output layer, and it has a powerful nonlinear mapping capability. It performs well in simple data prediction and is suitable for establishing predictive models.
The design process of the BP neural network prediction model mainly includes the following steps: data collection, network construction, network setup, initialization of weights and biases, network training, network validation (including performance analysis after training), and application of the model.
As can be seen from Section 2.2, N groups of data have been expanded to N1 groups based on the data augmentation method. It is known that they consist of non-ferromagnetic particle data A1 and copper particle data B1.
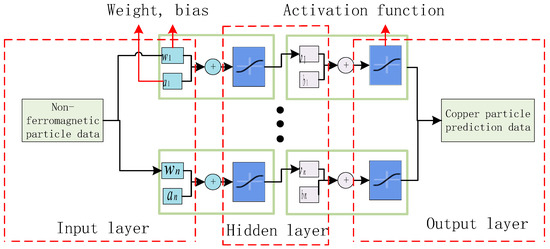
Furthermore, a multi-layer feedforward neural network is constructed, the input is the quantity of non-ferromagnetic particles ranging from 150 to 200 µm in the oil (unit: number of particles), and the output is the quantity of copper particles in the corresponding oil sample (unit: number of particles). The input layer is configured with one neuron to receive a single input variable A1, representing each input variable (1 < I < m) with xi, and the output layer is configured with one neuron to output the prediction result B1, representing each input variable (1 < I < m) with yiyu and the actual value of each output variable with yi. The p group of data in the m group is used as the training set for establishing the prediction model, and the q group of data is used as the validation set. Among them, the validation set is an independent dataset used during the model training process to monitor performance, adjust hyperparameters, and prevent overfitting. It does not participate in parameter updates and is a key tool for evaluating the generalization ability of the model before the final test. The m-p-q group data was used as the test set for establishing the prediction model. The number of neurons n set in the hidden layer was obtained through the 5-fold cross-validation method to enhance the nonlinear fitting ability of the network. The topological structure of this network follows a multi-layer feedforward architecture, as shown in Figure 2. Data is transmitted layer by layer from the input layer through the hidden layer and finally reaches the output layer, achieving the forward propagation of information.
Figure 2.
Neural network model diagram.
Before model training, the original data is first subjected to normalization preprocessing. This step helps to reduce the sensitivity of the initial distribution of weights to network training and enhance the numerical stability during the gradient descent process. The mathematical expression of the normalization transformation is as follows:
where is represents the original data, is the normalized data, i takes the value of (1, m), and i is an integer.
The mathematical expression of its neural network can generally be expressed as
where is the input variable for each layer; n is the number of layers of the neural network; f1 and f2 are activation functions; yi is the output variable; a and b are bias terms; w and v denote the weight matrices of the input and hidden layers, respectively; C is the output vector obtained by applying an activation function to the weighted sum of inputs.
The hidden layer uses a sigmoid activation function (f1), while the output layer uses a linear function (f2).
After obtaining the output result, since the normalization processing of the input data has begun, to ensure the uniformity of the data, it is necessary to perform reverse normalization processing on the output layer data here, which can be expressed as
where is represents the predicted value of copper particle content obtained by performing reverse normalization processing on the output layer data . represents the maximum value of all output values in the training set; represents the minimum value of all output values in the training set.
After calculating the predicted output value, compare it with the actual value of the output variable to calculate the Mean Squared Error (MSE). MSE is an important statistical indicator for measuring the difference between the predicted value and the true value, also known as the loss function. The smaller the value, the higher the accuracy of the model’s prediction results.
where is the predicted value of the output variable; q represents the number of groups in the training set; E represents the mean square error value (loss function) between the expected value and the actual value of the output variable.
To further prevent overfitting, an L2 regularization term is introduced into the loss function. L2 regularization penalizes overly large weight values by adding a term of the sum of squares of the weights of the network ownership to the loss function, thereby prompting the model to learn a smoother and simpler mapping function. The total loss function L after introducing regularization is defined as
where represents the regularization intensity coefficient, which is a hyperparameter that needs to be optimized. The regularization intensity coefficient is optimized through a grid search and 5-fold cross-validation system: within the preset log-scale candidate value range, cross-validation is performed on each candidate value to obtain the average validation performance, and finally, the value with the best validation performance is selected.
The training process adopts the validation set loss as the core monitoring indicator and implements a dual anti-overfitting strategy: L2 regularization constrains the weight amplitude each time the parameters are updated, while the early stop mechanism continuously tracks the validation loss. When this indicator fails to break the minimum record for 10 consecutive training rounds, the training is immediately terminated and automatically rolled back to the network state with the best validation performance. This monitoring mechanism ensures that the model can fully learn the data patterns while promptly avoiding the decline in generalization ability caused by overtraining, ultimately obtaining a stable and reliable prediction model.
If the mean square error value is significant, the deviation between the model’s prediction result and the actual value is substantial. The backpropagation algorithm must optimize and adjust each neural network layer’s weights and bias parameters. Subsequently, the forward propagation operation of Equation (6) is re-executed to calculate the new mean square error value.
The error from the output layer to the hidden layer of backpropagation can generally be expressed as
where is represents the error from the output layer to the hidden layer.
Then, an iteration can be completed by obtaining the variation in parameters such as weights and biases. According to the processing method of the optimal gradient descent, b and v descend the fastest along the negative gradient direction and can be expressed as
where is the learning rate of the BP neural network, represents the weight change in the output layer, and represents the bias change in the output layer.
Furthermore, the error from the hidden layer to the input layer of backpropagation can be expressed as
where is the error from the hidden layer to the input layer.
Variable parameters such as weight and bias can be obtained to complete one iteration. According to the processing method of the optimal gradient descent, we decline the fastest along the negative gradient direction, which can be expressed as
where is the change in the weight of the hidden layer; represents the offset variation in the hidden layer.
Through multiple cyclic iterations of this process, the mean square error value of Equation (7) is reduced to a sufficiently small size and meets the model’s accuracy requirements, thereby completing the training and optimization of the model.
The N1 group of oil sample data, including A1 and B1, was selected to further verify the performance of the constructed neural network prediction model. The neural network prediction model trained above was used to predict the copper particle content, and the prediction results were compared and analyzed with the actual measured values. The model’s prediction accuracy is evaluated by calculating the Mean Squared Error (MSE) and the Coefficient of Determination (R2). Mean square error (MSE) is the average of the squares of the prediction errors, used to measure the difference between the predicted values of the model and the actual values. The smaller the MSE value, the higher the model’s prediction accuracy. The coefficient of determination (R2) reflects the model’s ability to interpret data variation. The closer its value is to 1, the better the model’s fit.
Further, the new data of A can be imported into the prediction model to predict the data of B.
Furthermore, considering that the number of copper particles and non-ferromagnetic particles has a certain linear correlation trend under the same wear mechanism, a baseline model for predicting oil particles was constructed based on linear regression. By evaluating its goodness of fit and generalization error on an independent test set and conducting a comparative analysis with the BP neural network prediction model, this demonstrates the necessity and superiority of the intelligent prediction model proposed in this paper in improving prediction accuracy and generalization ability. Since this study is a single independent variable and a single dependent variable, the baseline function for its fitting is
where is represents the predicted number of copper particles; represents the number of non-ferromagnetic particles; B represents the intercept term; represents the regression coefficient.
3. Experimental Studies
3.1. Experimental Platform Construction
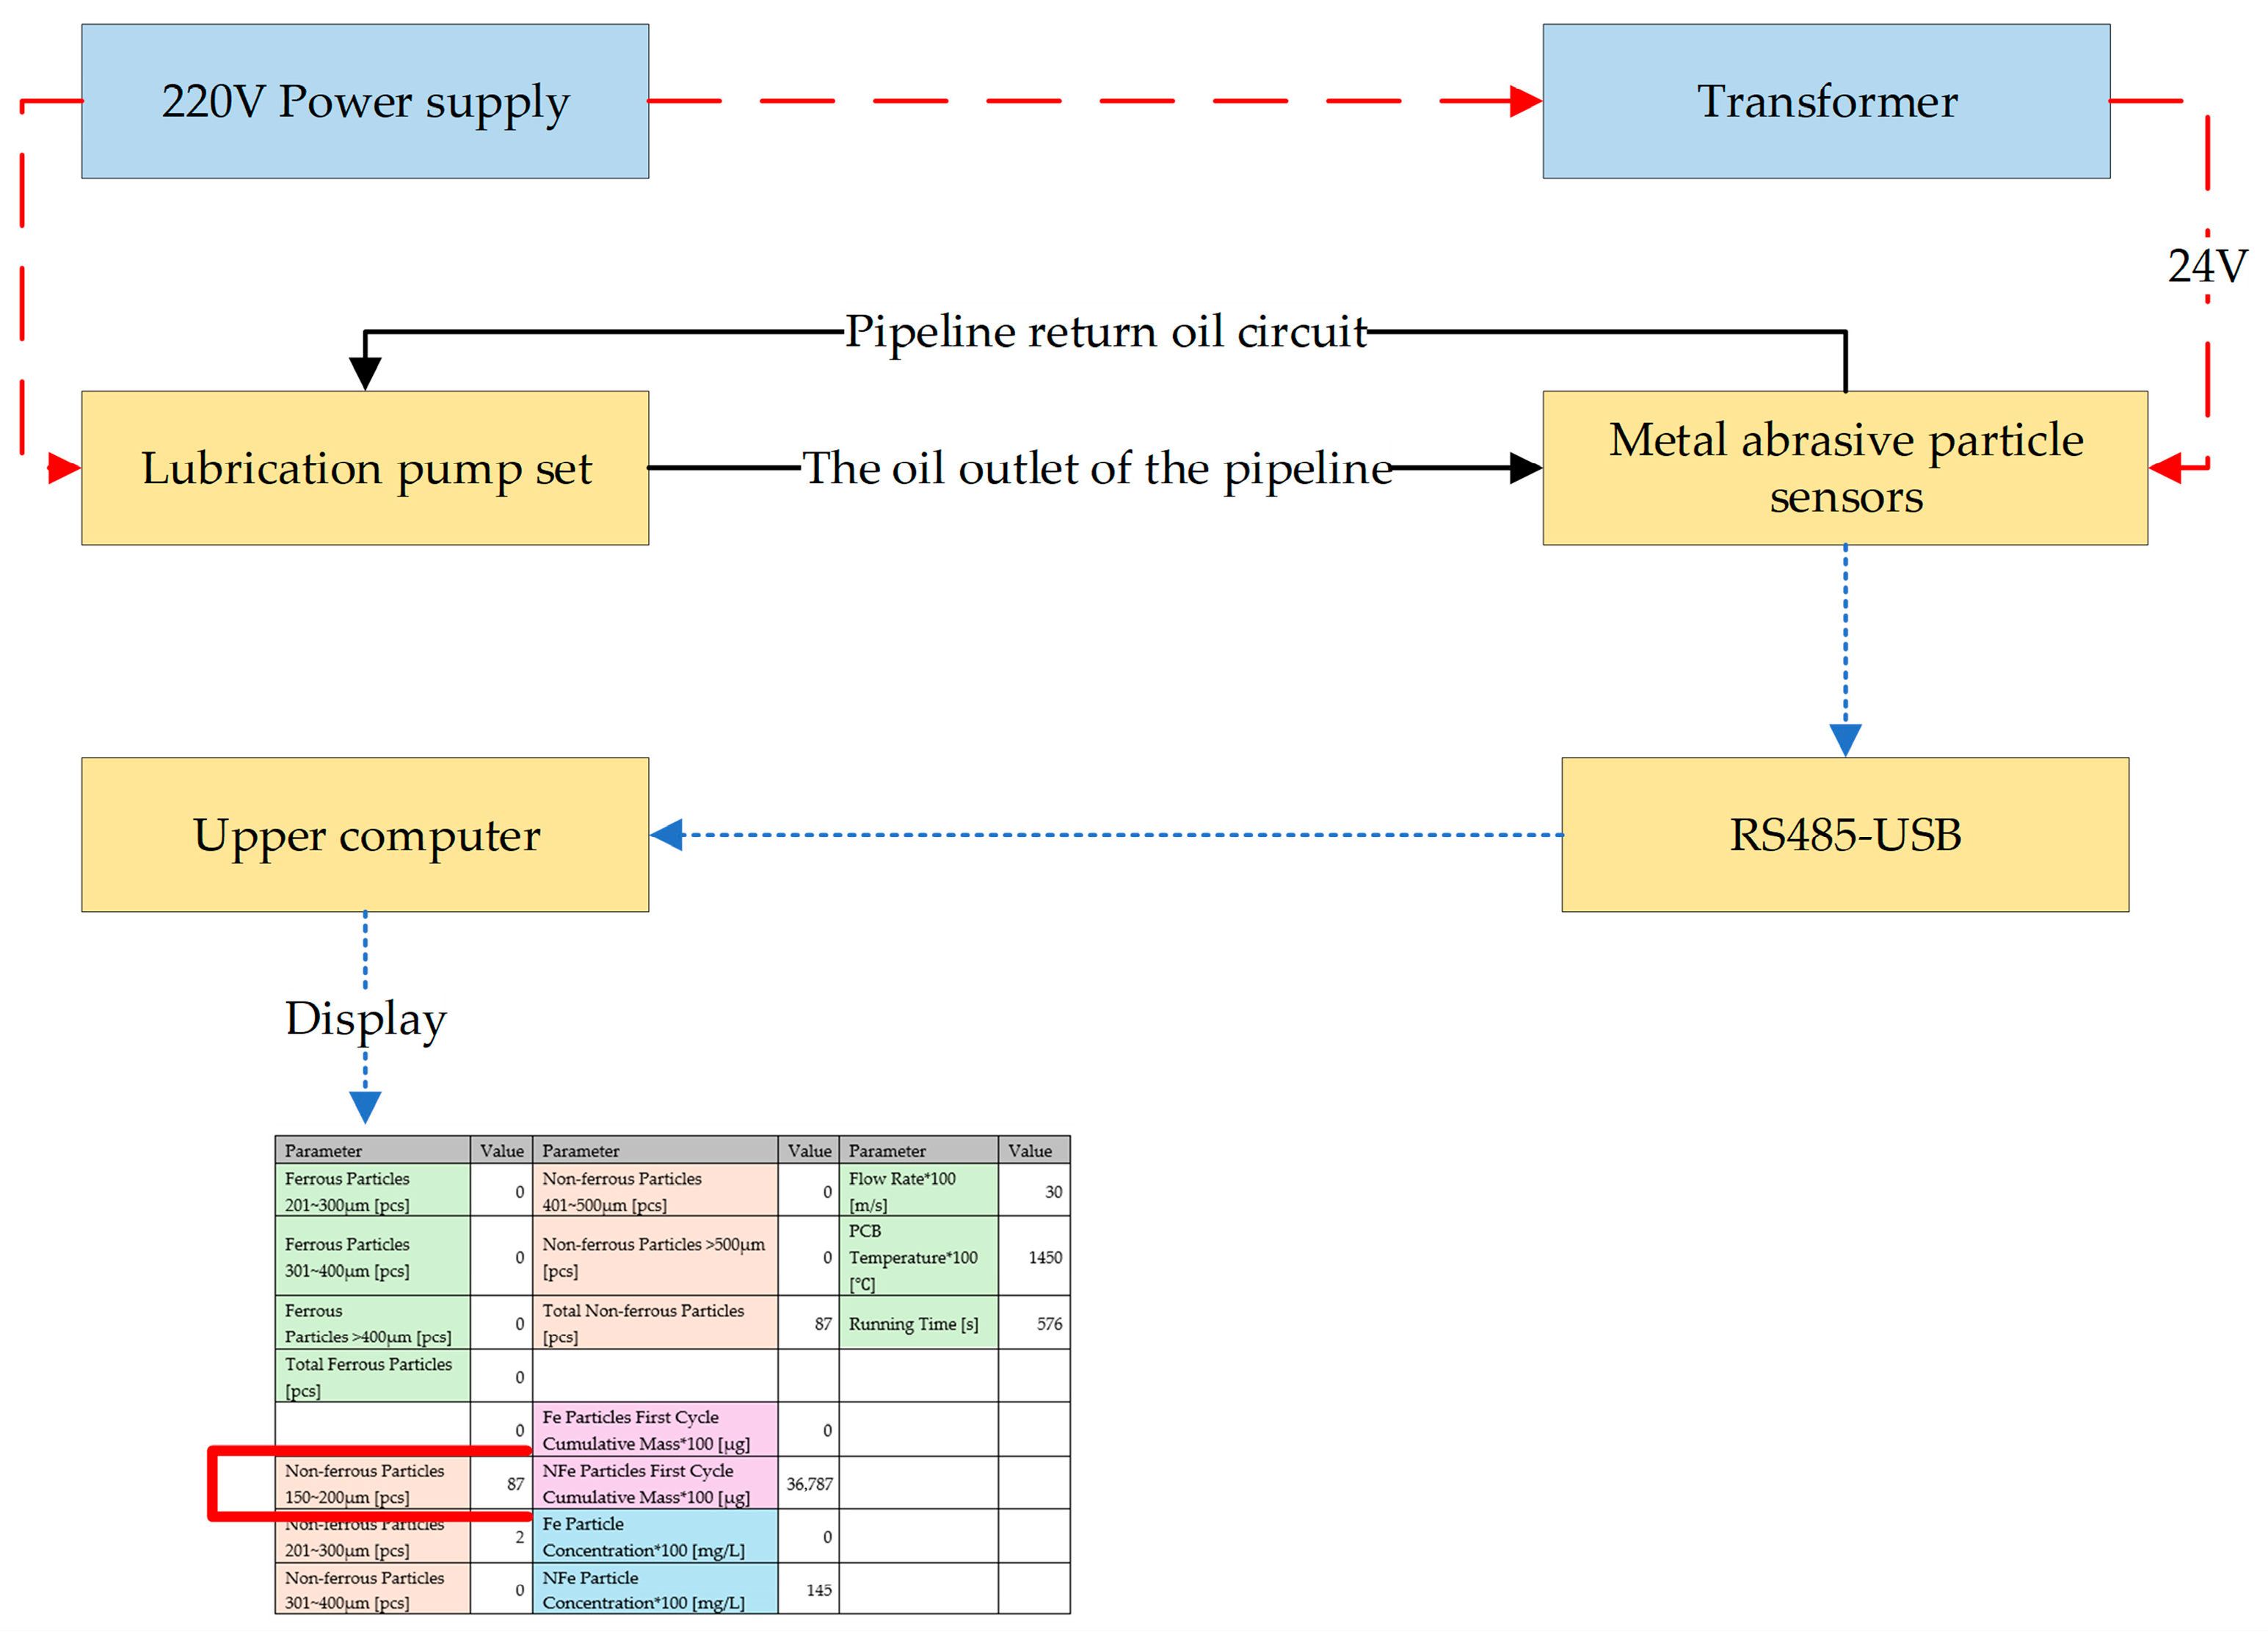
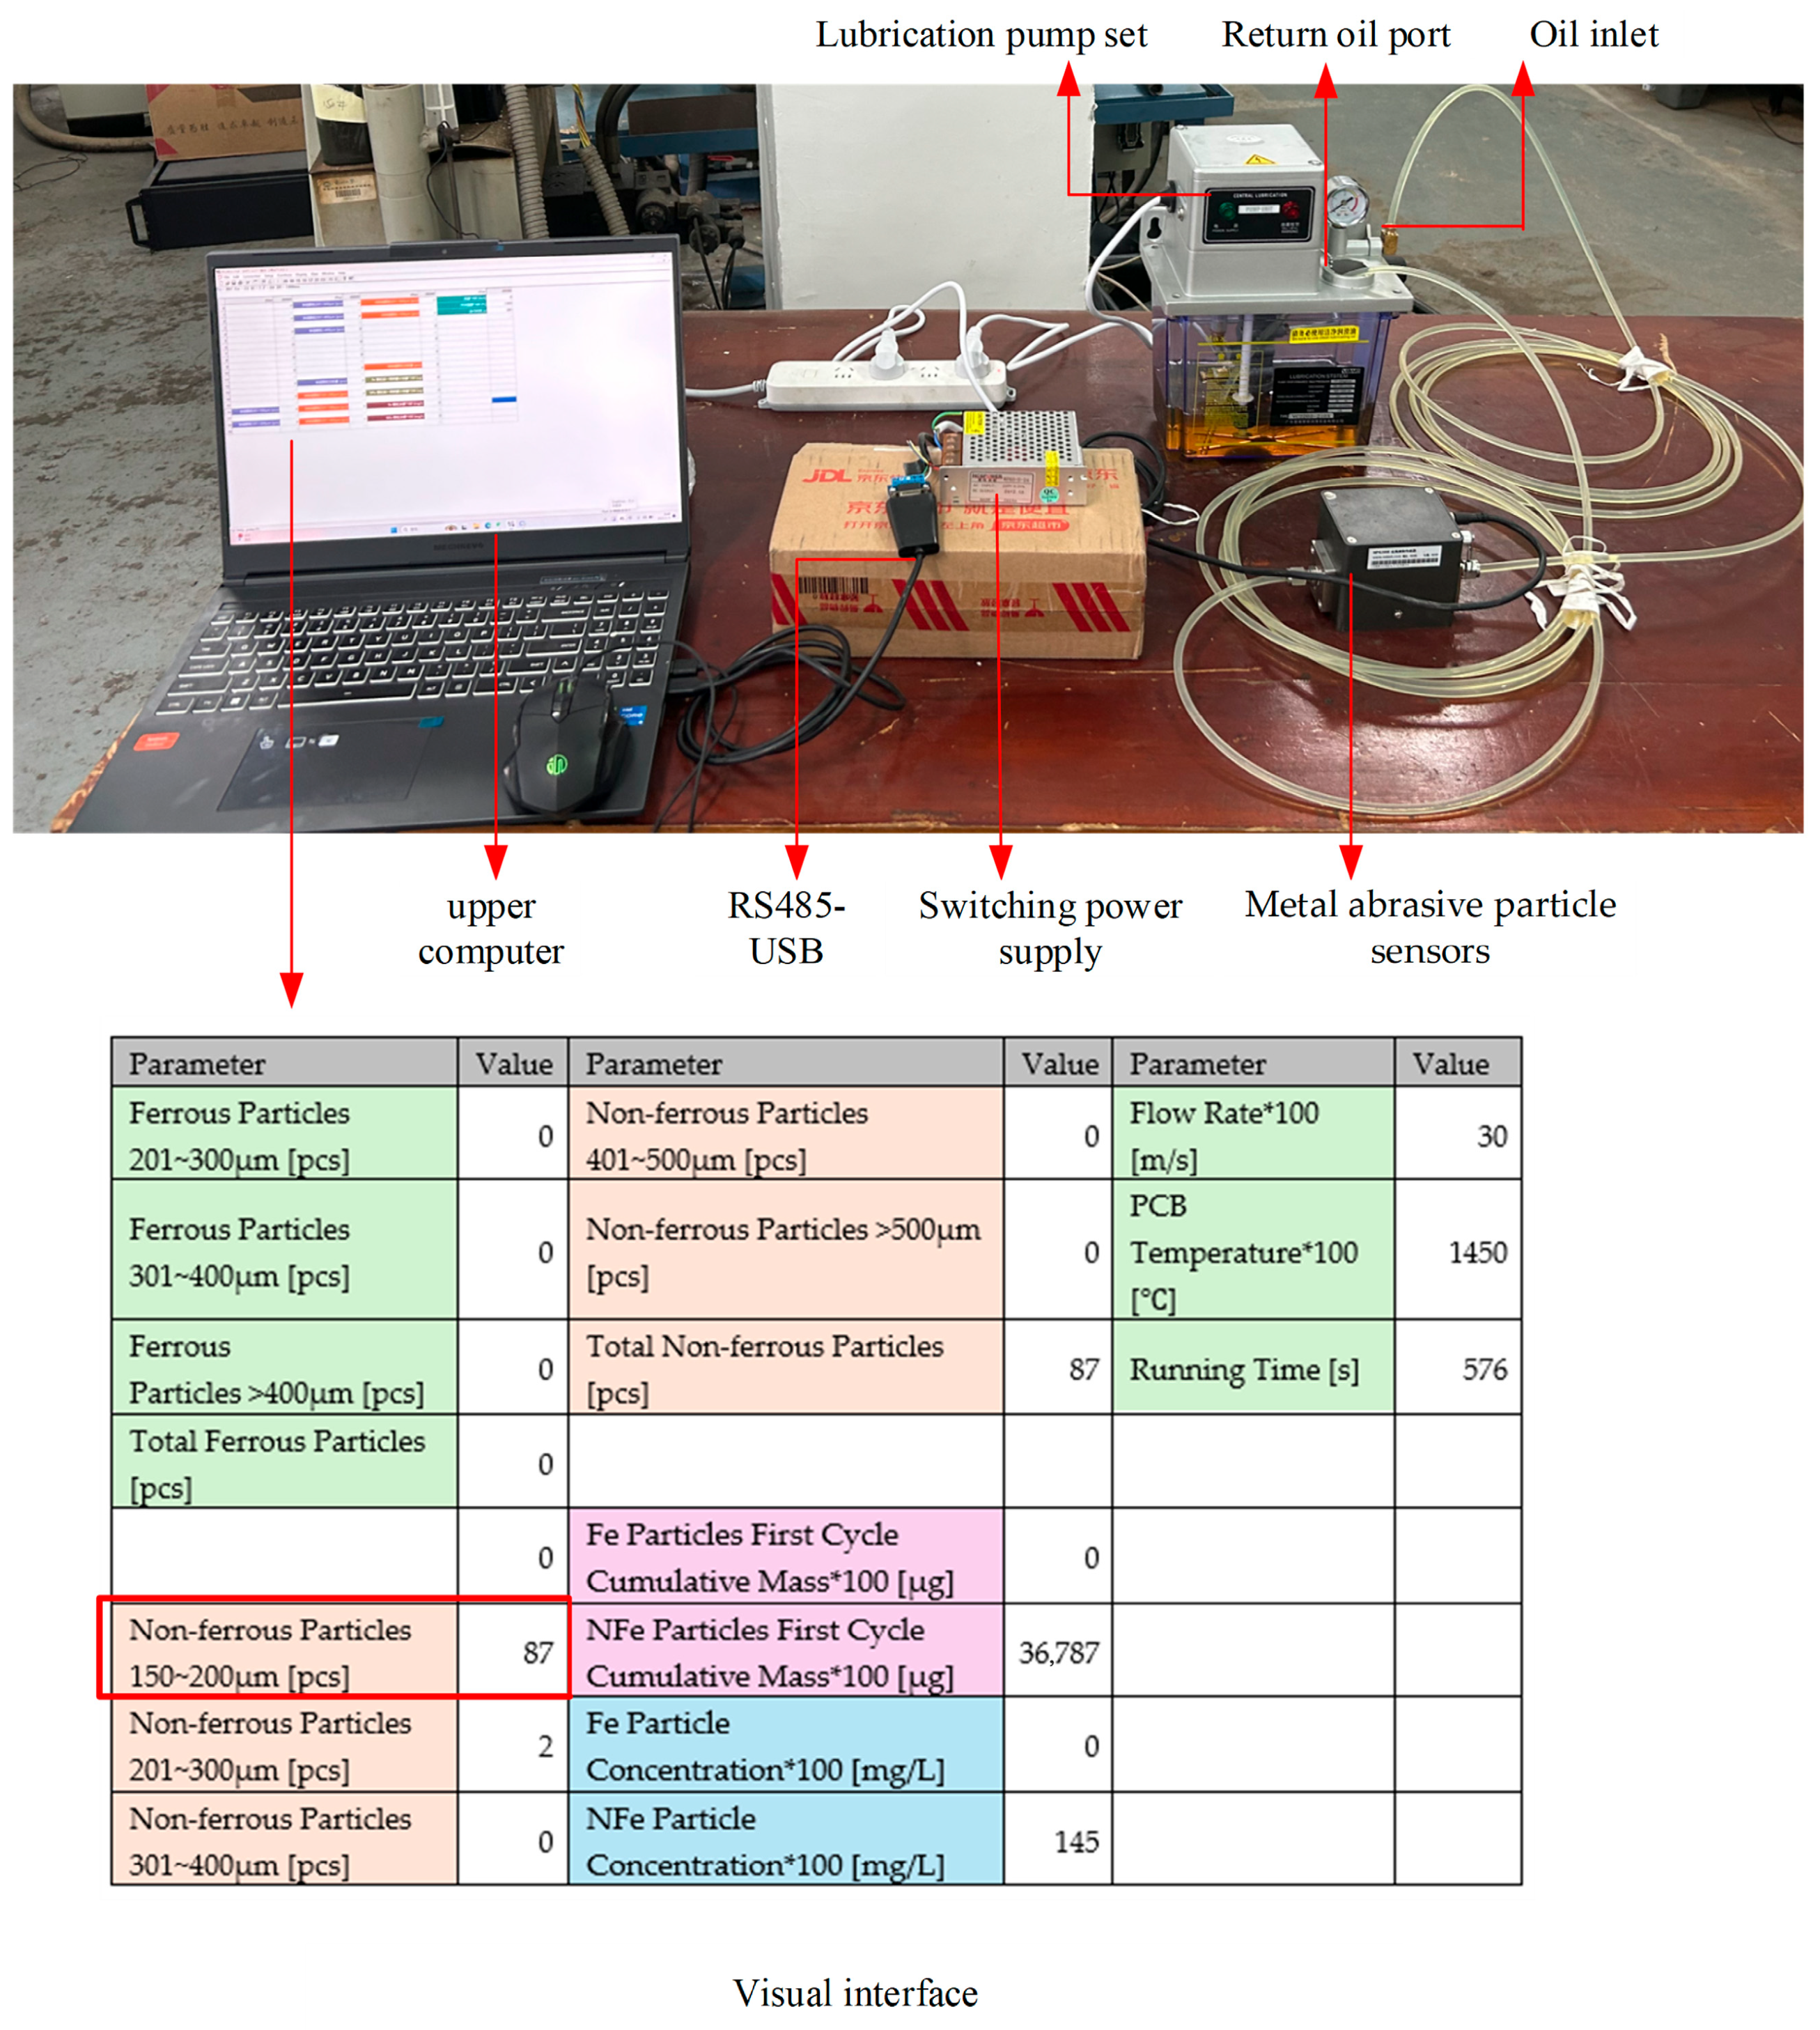
The experimental system is designed based on the relevant theoretical knowledge of hydraulic transmission and fluid mechanics to reflect the flow state of the oil under real working conditions as much as possible, thereby obtaining data on non-ferromagnetic particles in the oil. It should be noted that this experimental platform is a hydraulic circulation testing system. Its main purpose is to accurately simulate the working state of online metal abrasive sensors (such as oil flow rate and flow field characteristics) in a laboratory environment and obtain sensor readings that match the offline laboratory test data. The system itself does not contain any wearing parts. All the wear particles detected are derived from oil samples independently collected from the actual operating equipment. Therefore, this experiment aims to verify the feasibility of the statistical relationship modeling method based on historical wear data, rather than simulating the dynamic wear generation process. First, a hydraulic circulation system is set up to detect the content of non-ferromagnetic particles in the oil. The testing principle of the hydraulic system is shown in Figure 3, and the physical structure of the hydraulic testing system is shown in Figure 4. This system mainly comprises metal abrasive particle sensors, lubrication pump sets, Teflon transparent tubes, RS485-USB converters, transformers 220 V to 24 V, upper computers, etc. The lubrication pump set is connected to the metal abrasive particle sensor through a transparent Teflon tube to predict the content of non-ferromagnetic particles in the oil. After the oil flows through the metal abrasive particle sensor, based on the principle of electromagnetic induction, the sensor detects the concentration and size distribution of metal particles in the oil in real time. The detection data is transmitted to the upper computer through the RS485-USB converter for real-time display, recording, processing, and data analysis.
Figure 3.
Schematic diagram of the hydraulic system.
Figure 4.
Schematic diagram of the experimental system.
Due to the limitations of offline detection technology for copper particles in the oil, currently only sample data of copper particle content larger than 100 µm can be collected. Metal abrasive particle sensors also have a fixed detection range. Therefore, sample data of non-ferromagnetic particles ranging from 150 to 200 µm in the oil was selected to match the copper particle data size range.
The red-highlighted area in Figure 4 corresponds to the target parameter of this study: the content of non-ferromagnetic particles. This parameter was the primary metric obtained from the experimental measurements.
3.2. Experimental Test Results
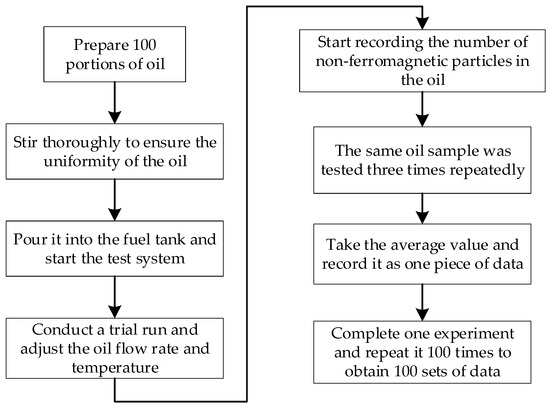
To ensure the engineering representativeness of the experimental data and the reliability of the method verification, all the oil samples used in this study were derived from the spindle-bearing lubrication system of a certain mine mill. This equipment operates under typical heavy-load and low-speed conditions, and its lubrication system is a forced circulation oil circuit. Oil samples were collected regularly and in equal quantities through the sampling port on the main return oil pipeline during the continuous operation of the equipment to ensure that the obtained wear particles truly reflect the wear behavior of the friction pair under actual working conditions. A total of 100 samples were taken. In order to obtain the data on the content of non-ferromagnetic particles in the oil, the oil samples were injected into the oil tank of the lubrication pump set in sequence. The parameter settings of the metal abrasive sensor (MPS v2.0.1) were adjusted, and the flow rate of the oil through the sensor was set to 0.3 m/s. The experimental operation temperature was at room temperature, and the single measurement operation time was approximately 20 s. To ensure the reliability of data collection and avoid accidental errors, this study continuously collected the non-ferromagnetic particle content signals output by the metal abrasive sensor through the upper computer system. For each oil sample, three independent repeated measurements were conducted, and the arithmetic mean was taken as the final observed value of the sample to enhance the statistical stability of the data and the reproducibility of the measurements. This strategy effectively suppressed the influence of random fluctuations on the experimental results. Based on this, a total of 100 sets of high-quality, non-ferromagnetic particle content data were obtained. The experimental operation steps are shown in Figure 5.
Figure 5.
Test operation procedure diagram.
Subsequently, the 100 samples of the tested oil were analyzed offline. The offline detection method was used to obtain 100 sets of data on the copper particle content in the oil. For details, please refer to the Appendix A. A total of 100 tests were conducted, and some of the measured data are shown in Table 1. The complete data can be found in the Appendix A.
Table 1.
Shows the measured data in part.
3.3. Model Prediction Results
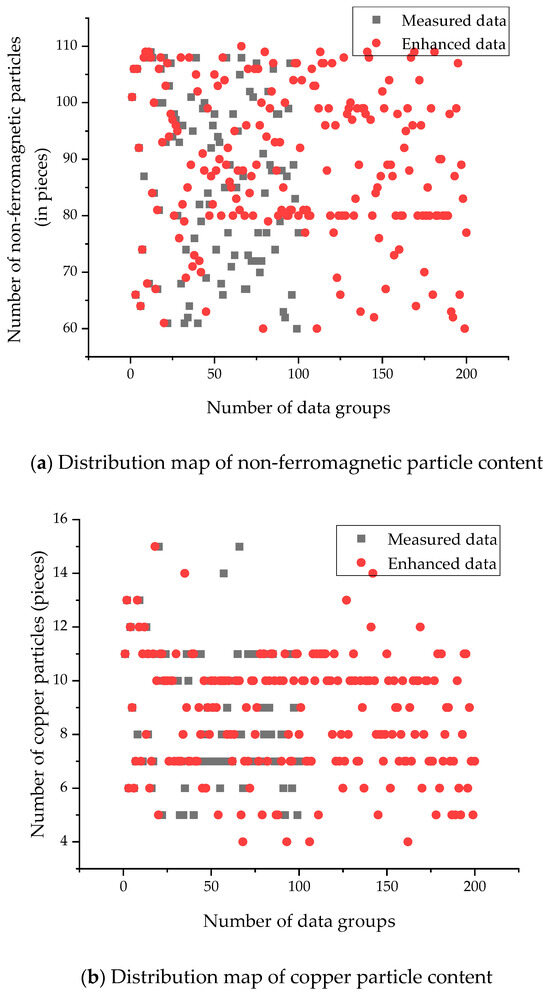
Based on Section 2, an online prediction model was established. To ensure the objectivity and reliability of the generalization ability assessment of the model, this study adopts the hold-out method to divide the training set and the test set. Specifically, 20 groups were randomly selected from 100 groups of original oil samples as the test set, and the remaining 80 groups were used as the training set. To verify the stability of the partitioning, this study conducted three different random partitions and trained the models, respectively, for performance evaluation (R2, MAE, average accuracy). The results show that the fluctuation range of the evaluation indicators in the three experiments are all less than ±2%, indicating that the model is not sensitive to the way the dataset is divided and has good stability. It should be particularly noted that all data augmentation operations (including feature space interpolation, principal component perturbation, and data transformation) are only applied to the training set data. The test set data should always remain in its original state to avoid information leakage and ensure the fairness and reproducibility of the evaluation results. Therefore, among the 100 sets of data on the content of non-ferromagnetic particles and copper particles in oil samples obtained through experiments and offline detection, 80 sets were enhanced through interpolation and other methods. The remaining 20 sets of measured data are used to verify the accuracy of the prediction model. First, substitute 60 groups of data from the 80 groups into Equation (1), and then expand 120 groups of data through the feature space linear interpolation method. Then, Equations (2)–(4) were substituted in, and the 120 sets of data were processed through the principal component perturbation method, increasing the data to 140 sets. Substitute the remaining 20 groups of data into Equation (5) and enhance it to 40 groups of data through the data transformation method. During the process of enhancing data generation, the noise amplitude parameter c of PCA perturbation is set to 15% of the standard deviation of each principal component (i.e., ). This value was determined based on the preliminary sensitivity analysis of grid search: We conducted experiments within the range of – with a step size of 0.05. By observing the distribution density and dispersion of the enhanced data in the original feature space and verifying its influence on the convergence of the initial training loss of the subsequent neural network under different c values, was ultimately selected as the optimal parameter. This setting can effectively expand the diversity of data distribution while strictly maintaining the inherent statistical laws of the original data, providing high-quality and physically meaningful training samples for subsequent model training. A total of 180 sets of oil data after enhancement were used as the training set for establishing the prediction model. The training set was supplemented with 20 sets of measured data for verifying the accuracy of the prediction model, totaling 200 sets of data. The distribution comparison of the data before and after enhancement is shown in Figure 6. Analysis shows that the joint distribution characteristics of the enhanced data processed by feature space interpolation and principal component perturbation are effectively maintained within the convex hull range of the original dataset, and no abnormal samples beyond the original distribution boundary are introduced. This verifies the distribution fidelity and physical interpretability of the enhancement process, ensuring the statistical consistency of the enhanced data and the reliability of the enhancement algorithm. For details, please refer to the Appendix A.
Figure 6.
Data distribution map after data augmentation.
To construct a robust prediction model for copper particle content, this study designed and optimized the structure and training parameters of the BP neural network based on 180 sets of augmented data. The network adopts a single hidden layer feedforward architecture. Each input layer and output layer is equipped with one neuron, which is, respectively, used to receive the data of non-ferromagnetic particle content and output the predicted value of copper particle content. The number of neurons in the hidden layer (candidate set: 5, 8, 10, 12, 15) was systematically evaluated through 5-fold cross-validation. The mean square error of the average validation was used as the selection criterion, and the optimal structure was finally determined as 1–10–1. At the network implementation level, the hidden layer adopts the Sigmoid activation function, and the output layer adopts the linear activation function. The weights are initialized through the Xavier method: The training adopts the gradient descent algorithm with driving force (learning rate 0.01, momentum coefficient 0.9). The loss function is defined as the mean square error and an L2 regularization term is introduced. The regularization coefficient is optimized through a 5-fold cross-validation grid search and is finally determined to be 0.001. This value achieves the best balance on the validation set: it can effectively suppress overfitting (with a small gap between training and validation losses), while maintaining a high level of prediction accuracy. During the training process, the maximum number of iteration rounds is set to 1000, and overfitting is controlled based on an early stop mechanism (terminating if the validation loss does not decrease for 10 consecutive rounds) to ensure that the model has reliable generalization performance on an independent test set.
Furthermore, the content of non-ferromagnetic particles in the oil is first imported into Equation (6) for data normalization processing. Then, the normalized content of non-ferromagnetic particles (training set) is imported into Equation (7), and initial values are assigned to the weights and offsets in Equation (7). The content of copper particles in the oil is gradually calculated. Then, the content of copper particles in the oil is imported into Equation (8) for reverse normalization processing. The predicted value of copper particle content calculated and the content of copper particles in the oil obtained through offline detection are imported into Equations (9) and (10) to calculate the mean square error value. If the mean square error is too large, it indicates that there is a significant difference between the predicted value and the true value of copper particles in the oil, and the accuracy of the model’s prediction result is lower.
Furthermore, it is necessary to optimize and adjust the weights and bias parameters of each layer of the neural network through the backpropagation algorithm. First, calculate the error from the output layer to the hidden layer of the backpropagation by referring to Equation (11), and then substitute the error obtained by Equation (11) into Equation (12) to obtain the variation in parameters such as weights and biases within the output layer. Complete an update iteration of the weights and biases of the output layer. Similarly, substitute the error obtained from Equation (11) into Equation (13) to calculate the error from the hidden layer to the input layer of backpropagation. Then, substitute the error obtained from Equation (13) into Equation (14) to obtain the variation in parameters such as weights and biases within the hidden layer, completing one update and iteration of the weights and biases of the hidden layer.
Then, the newly obtained weights, offsets and other parameters of the hidden layer and output layer are re-substituted into Equations (6)–(8) to obtain the new content values of copper particles in the oil. Subsequently, the calculated content of copper particles and the content of copper particles in the oil obtained through offline detection are substituted into Equations (9) and (10) to calculate the mean square error. This iterative training process was repeated until the coefficient of determination tended to 1 and the mean square error stabilized. At this point, the online prediction model for copper particles in the oil was completed.
In this paper, the coefficient of determination (R2) and the mean absolute error (MAE) are adopted as the core indicators for evaluating the model performance, and the prediction accuracy is introduced as an auxiliary evaluation criterion to comprehensively measure the prediction accuracy and goodness of fit of the model.
Further, the data of non-ferromagnetic particle content in the test set was substituted into the prediction model to calculate the predicted value of copper particle content in the oil. An accuracy formula was defined to calculate the accuracy of the online prediction model for copper particles, achieving online prediction of copper particle oil. Compared with the offline detection results of the same oil sample, the accuracy was ≥ 80%. The results are shown in Table 2.
Table 2.
Verification data (After data enhancement).
Further, calculate the average absolute error of the test set, which can be expressed as
where is represents the true data of the content of the copper particle in the test set; represents the predicted data of the content of the copper particle in the test set; represents the total number of samples in the test set, which is 20 here.
Substituting the test set data shown in Table 2 into the model constructed by Equation (13), it was calculated that the mean absolute error (MAE) of the model trained with enhanced data was approximately 0.3398.
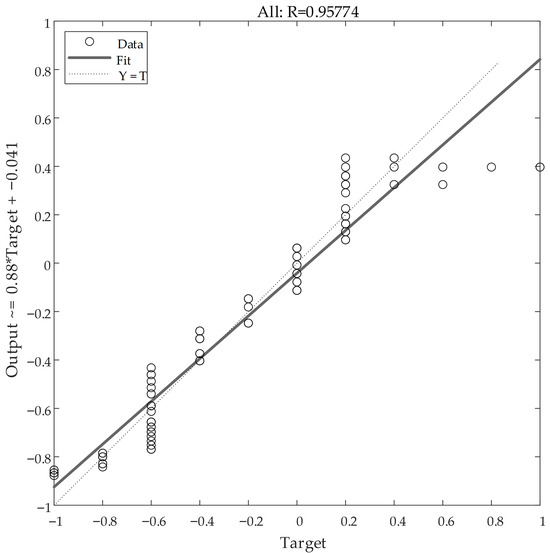
The constructed copper particle content prediction model was verified by 20 independent samples. The results showed that the prediction accuracy of all samples was above 80%, with an average accuracy of 95.66% and the lowest accuracy of 85.7%. The coefficient of determination (R2) of the model is 0.91 (Figure 7), and the mean absolute error (MAE) is 0.3398, indicating a highly linear correlation between the predicted values and the true values, and the overall fitting effect of the model is good.
Figure 7.
Comprehensive evaluation of the coefficient of determination for model training after data augmentation.
Furthermore, the original oil data without data augmentation was substituted into the training model for data training. The accuracy was calculated based on the same test set data, as shown in Table 3.
Table 3.
Verification data (Before data augmentation).
Then, by substituting the test set data shown in Table 3 into the model constructed by Equation (13), the mean absolute error (MAE) of the model before training with the augmented data was calculated to be approximately 0.8235.
The copper particle content prediction model based on the original oil data was verified by 20 independent samples. Its performance in terms of accuracy, goodness of fit, and prediction deviation is as follows: The average prediction accuracy is 84.07% (the lowest is 66.6%), the coefficient of determination (R2) reaches 0.725 (Figure 8), and the mean absolute error (MAE) is 1.1235.
Figure 8.
Comprehensive evaluation of the model training determination coefficient before data augmentation.
Furthermore, it can be obtained that the absolute coefficient (R2), mean absolute error (MAE), and accuracy calculated by the model trained after data augmentation for the test set have all improved compared to the model trained before data augmentation. Specifically, the coefficient of determination (R2) has increased from 0.725 to 0.91. The mean absolute error (MAE) of the test set decreased from 1.1235 to 0.3398. The average accuracy of the test set has increased from 84.07% to 95.66%.
This study simultaneously introduces linear regression as the benchmark model to conduct systematic modeling and comparative analysis of oil prediction data. Specifically, first, a linear regression model is constructed based on the training set data to solve for the optimal regression coefficient. Subsequently, the test set data is substituted into the obtained regression equation for prediction, and parameters such as the accuracy of the test set are calculated to evaluate the prediction accuracy and generalization performance of the model.
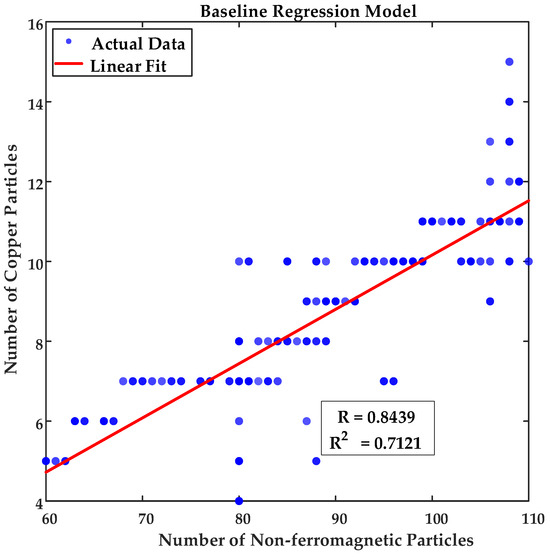
The results show that the average prediction accuracy of the linear regression model on the test set is approximately 80%, which is significantly lower than 95.66% of the BP neural network model. Meanwhile, its coefficient of determination (R2) is 0.7121 (Figure 9), indicating that the model’s ability to interpret data variation is limited and its goodness of fit is relatively low. After calculation, the mean absolute error (MAE) of the linear regression model is 1.5628 particles, further confirming that there is a significant deviation in its prediction.
Figure 9.
Evaluation of the determination coefficient of the baseline function.
In summary, the results of this case study suggest that the following: First, under the constraint of limited samples, the employed data augmentation strategy appears effective in enhancing model performance in a laboratory setting. Second, for the studied task, the neural network-based prediction method exhibits a notable performance advantage over the traditional linear regression baseline. These findings collectively indicate the potential of integrating data augmentation with neural networks for modeling the nonlinear relationship between non-ferromagnetic and copper particle counts within the context of the specific equipment and wear stage investigated.
4. Conclusions
Copper particles, as a key indicator of the wear of copper-based friction pairs in mining equipment, play an important role in indicating the reliability of the equipment through their content changes. To achieve low-cost and real-time online prediction of this wear component, this paper proposes and verifies an indirect prediction method based on neural networks and data augmentation techniques. The main conclusions are summarized as follows:
- This paper constructs a BP neural network prediction model integrating data augmentation strategies. This model takes the content of non-ferromagnetic particles that can be measured online as input and the content of copper particles that are difficult to measure offline as output, and it establishes the statistical relationship between the two. The introduction of data augmentation technology has effectively alleviated the problem of insufficient training samples caused by the high cost of offline detection, providing a feasible path for modeling under the condition of small samples.
- Based on the independently built hydraulic testing platform, the matching data of non-ferromagnetic particles and copper particles within the particle size range of 150–200 μm in 100 sets of oil were obtained. Through enhancement methods such as feature space interpolation and principal component perturbation, the 80 training samples were expanded to 180, and 20 independent test samples were used for verification, providing a reliable data basis for model training and evaluation.
- Experimental verification on the independent test set shows that the average prediction accuracy in the test set is 95.66%, the minimum prediction accuracy is 85.7%, and the coefficient of determination (R2) and the mean absolute error (MAE) in the main evaluation indicators of the model are 0.91 and 0.3398. These results indicate that, for the test samples and under specified conditions, the proposed method can predict the copper particle content based on the signals of conventional non-ferromagnetic particle sensors within the size range of 150–200 µm, achieving a very good level of accuracy. This provides a potential low-cost indirect monitoring method for assessing the wear state of specific mining equipment during stable operation. However, it must be emphasized that these findings come from a specific case study. Their generalization as a robust engineering solution requires further verification.
This study has clear preliminary nature and case-specific characteristics. The conclusion is derived from the analysis of data obtained from a single type of equipment during the stable wear stage under controlled laboratory conditions, and the current model has not yet incorporated complex factors in actual working conditions such as oil aging, multi-source contamination, load fluctuations, and coupling of multiple wear mechanisms. Furthermore, the research verification relies on the test results of historical oil samples in the simulation loop. What the model learns is the statistical relationship of the target equipment within a specific sampling period. It is particularly worth noting that the data augmentation technique adopted is a mathematical expansion of the statistical space of the existing training samples. Although it helps to improve the training stability and test performance under small samples, it does not introduce new independent tribological information. Its effect partly stems from the smooth fitting of the existing data distribution. Therefore, the engineering practicality and real generalization ability of this method–especially the accurate prediction ability for newly generated and unseen wear particles on real equipment–have not yet been finally confirmed. Future work is of vital importance. It is necessary to deploy sensors on real equipment for long-term on-site monitoring, collect independent and real-time multi-condition data streams, and rigorously evaluate their actual robustness. Meanwhile, it is possible to explore the extension of this method framework to other oil analysis tasks (such as distinguishing different ferromagnetic particles or contaminants) to test its broader application potential.
Author Contributions
Conceptualization, L.Y. (Long Yuan), Z.D., X.G., Y.Z. and J.L.; Methodology, L.Y. (Long Yuan), Z.D., X.G., Y.Z. and L.Y. (Liusong Yang); Software, Z.D., Y.Z., L.Y. (Liusong Yang) and Y.W.; Validation, X.G., Y.Z., L.Y. (Liusong Yang), Y.W. and J.L.; Investigation, L.Y. (Long Yuan), Y.W. and J.L.; Resources, J.L. All authors have read and agreed to the published version of the manuscript.
Funding
This work is supported by the Henan Province Major Science and Technology Special Project (Grant No. 241100220300).
Data Availability Statement
The data presented in this study are available on request from the corresponding author.
Conflicts of Interest
Authors Long Yuan, Zibin Du, Xun Gao, Liusong Yang and Yuehui Wang were employed by the companies Citic Heavy Industries Co., Ltd. and Luoyang Mining Machinery Engineering Design and Research Institute Co., Ltd. The remaining authors declare that the research was conducted in the absence of any commercial or financial relationships that could be construed as a potential conflict of interest.
Appendix A
Table A1.
Experimental test data (100 groups).
Table A2.
Data for training after data enhancement (180 groups).
Table A3.
Data used to verify the training model (20 groups).
References
- Wang, Z.; Xue, X.; Yin, H.; Jiang, Z.; Li, Y. Research progress on monitoring and separating suspension particles for lubricating oil. Complexity 2018, 2018, 9356451. [Google Scholar] [CrossRef] [Scilit]
- Huang, X.; Bao, S.; Dong, H.; Xu, J. Cummins Marine Diesel Engine Wear Analysis Based on the Oil Ferrography Analysis Technology. In Proceedings of the International Forum on Energy, Environment Science and Materials (IFEESM 2015), Shenzhen, China, 25–26 September 2015; pp. 710–713. [Google Scholar]
- More, P.P.; Jaybhaye, M.D. Wear Particle Classification Using Ferrographic Analysis in Gearbox System Considering Area and Perimeter. J. Fail. Anal. Prev. 2023, 23, 1967–1978. [Google Scholar] [CrossRef] [Scilit]
- Murata, Y.; Moronaga, T.; Egami, M.; Hayashi, K.; Nanba, S.; Hara, T.; Ohnuma, I.; Ohmura, T. Accurate measurement of solute profile segregated at steel grain boundary by scanning transmission electron microscope with energy dispersive X-ray spectroscopy. Micron 2025, 198, 103887. [Google Scholar] [CrossRef] [Scilit]
- Zhou, X.; Zhang, Z.; Yang, C.; Wang, H.; Li, L. Qualitative and quantitative analysis of bio-oil/biochar in asphalt using a novel method based on infrared spectroscopy and microstructure. Constr. Build. Mater. 2025, 501, 144280. [Google Scholar] [CrossRef] [Scilit]
- Sun, H.; Li, T.; Zhang, L. Matrix separation-inductively coupled plasma atomic emission spectroscopy for the determination of impurity elements in tungsten-copper alloys. J. Phys. Conf. Ser. 2025, 3030, 012014. [Google Scholar] [CrossRef] [Scilit]
- Yu, B.; Cao, N.; Zhang, T. A novel signature extracting approach for inductive oil debris sensors based on symplectic geometry mode decomposition. Measurement 2021, 185, 110056. [Google Scholar] [CrossRef] [Scilit]
- Shi, H.; Zhang, H.; Ma, L.; Zeng, L. A multi-function sensor for online detection of contaminants in hydraulic oil. Tribol. Int. 2019, 138, 196–203. [Google Scholar] [CrossRef] [Scilit]
- Sun, J.; Wang, L.; Li, J.; Li, F.; Li, J.; Lu, H. Online oil debris monitoring of rotating machinery: A detailed review of more than three decades. Mech. Syst. Signal Process. 2021, 149, 107341. [Google Scholar] [CrossRef] [Scilit]
- Zhang, S.; Zhang, Z.; Bai, C.; Hu, S.; Wang, J.; Wang, C.; Zhang, H. Characterization of Abrasive Grain Signal of Oil Detection Sensor Based on LC Resonance Wireless Transmission. J. Mar. Sci. Eng. 2024, 12, 1704. [Google Scholar] [CrossRef] [Scilit]
- Raadnui, S.; Kleesuwan, S. Low-cost condition monitoring sensor for used oil analysis. Wear 2005, 259, 1502–1506. [Google Scholar] [CrossRef] [Scilit]
- Murali, S.; Xia, X.; Jagtiani, A.V.; Carletta, J.; Zhe, J. Capacitive Coulter counting: Detection of metal wear particles in lubricant using a microfluidic device. Smart Mater. Struct. 2009, 18, 037001. [Google Scholar] [CrossRef] [Scilit]
- Kshetri, S.; Steward, B.L.; Birrell, S.J. Dielectric spectroscopic sensor for particle contaminant detection in hydraulic fluids. Int. J. Fluid Power 2014, 7, 5196–5202. [Google Scholar]
- Jourdainne, L.; Boumbimba, R.M.; Triki, B.; Bouquey, M.; Muller, R.; Hébraud, P.; Pfeiffer, P. Compact and flexible optical sensor designed for online monitoring. Int. J. Mater. Form. 2012, 5, 1–9. [Google Scholar]
- Gu, C.; Zhang, Z.; Zhang, S.; Zhao, H.; Hu, S.; Zhang, W.; Bai, C.; Zhang, H.; Wang, C. Design and detection performance of metal contaminant sensor with triple coil structure. J. Mar. Sci. Eng. 2025, 13, 59. [Google Scholar]
- Ma, L.; Shi, H.; Zhang, H.; Li, G.; Shen, Y.; Zeng, N. High-sensitivity distinguishing and detection method for wear debris in oil of marine machinery. Ocean Eng. 2020, 215, 107452. [Google Scholar] [CrossRef] [Scilit]
- Wu, T.; Wu, H.; Du, Y.; Peng, Z. Progress and trend of sensor technology for on-line oil monitoring. Sci. China Technol. Sci. 2013, 56, 2914–2926. [Google Scholar] [CrossRef] [Scilit]
- Xiao, H.; Wang, X.; Li, H.; Luo, J.; Feng, S. An inductive debris sensor for a large-diameter lubricating oil circuit based on a high-gradient magnetic field. Appl. Sci. 2019, 9, 1546. [Google Scholar]
- Markova, V.L. Increasing the Reliability of Real-Time Diagnostics of a Wear Particle Counter. J. Frict. Wear 2020, 41, 204–210. [Google Scholar] [CrossRef] [Scilit]
- Zhu, L.; Qin, S.; Hao, Y.; Yan, T.; Yang, Z.; Yong, J.; Shu, X. Knowledge-based intelligent ensemble monitoring method of grit wear in ultrasonic assisted grinding. Adv. Eng. Inform. 2025, 64, 103043. [Google Scholar]
- Jiang, T.; Yao, X.; Ma, M.; Yu, H.; Sun, J.; Liu, Y.; Hu, X.; Chen, C.; Lei, C.; Wang, X. Multiphase-based predictive framework construction of abrasive wear performance in C–V–Cr–Mo alloys. J. Mater. Res. Technol. 2025, 39, 1927–1942. [Google Scholar] [CrossRef] [Scilit]
- Russel, E.; Madhu, S.; Varuvel, E.G.; Santhi, G.B.; Suresh, G.; Josephin, J.F.; Albeshr, M.F.; Kiani, F. Advanced machine learning techniques for predicting wear performance in graphene oxide particulate interpenetrating polymer network composites. Eng. Appl. Artif. Intell. 2025, 161, 112252. [Google Scholar] [CrossRef] [Scilit]
- Sheth, F.; Mathur, P.; Shaikh, H.; Kumar, D.; Mishra, S.; Gupta, A.K. Learning heat: High-fidelity experimental and Koo-Kleinstreuer–Li thermal conductivity predictions in nanofluids via advanced data augmentation and metaheuristic search. Int. Commun. Heat Mass Transf. 2026, 171, 110022. [Google Scholar] [CrossRef] [Scilit]
- He, Z.; Wang, S.; Shi, J.; Liu, D.; Duan, X.; Shang, Y. Physics-informed neural network supported wiener process for degradation modeling and reliability prediction. Reliab. Eng. Syst. Saf. 2025, 258, 110906. [Google Scholar] [CrossRef] [Scilit]
- Mei, J.; Hang, Y.; Cai, Z.; Yu, L.; Liu, Y.; Lin, X.; Zhao, W.; Zhu, G. Effect of cycle number on the fretting wear mechanism of 690TT heat transfer tubes/316L stainless steel caused by fibrous foreign objects. Tribology 2025. Available online: https://link.cnki.net/urlid/62.1224.O4.20251212.0841.008 (accessed on 13 November 2025).

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.