


Abstract
Industrial pumps are critical components in manufacturing and process plants, where early acoustic anomaly detection is essential for preventing unplanned downtime and reducing maintenance costs. In practice, however, strong background noise, severe class imbalance between rare faults and abundant normal data, and the limited computing resources of edge devices make reliable deployment challenging. In this work, a lightweight Audio Spectrogram Transformer (Tiny-AST) is proposed for robust pump anomaly detection under imbalanced supervision. Building on the Audio Spectrogram Transformer, the internal Transformer encoder is redesigned by jointly reducing the embedding dimension, depth, and number of attention heads, and combined with a class frequency-based balanced sampling strategy and time–frequency masking augmentation. Experiments on the pump subset of the MIMII dataset across three SNR levels (−6 dB, 0 dB, 6 dB) demonstrate that Tiny-AST achieves an effective trade-off between computational efficiency and noise robustness. With 1.01 M parameters and 1.68 GFLOPs, it maintains superior performance under heavy noise (−6 dB) compared to ultra-lightweight CNNs (MobileNetV3) and offers significantly lower computational cost than standard compact baselines (ResNet18, EfficientNet-B0). Furthermore, comparisons highlight the performance gains of this lightweight supervised approach over traditional unsupervised benchmarks (e.g., autoencoders, GANs) by effectively leveraging scarce fault samples. These results indicate that a carefully designed lightweight Transformer, together with appropriate sampling and augmentation, can provide competitive acoustic anomaly detection performance while remaining suitable for deployment on resource-constrained industrial edge devices.
1. Introduction
Industrial pumps are widely deployed in manufacturing, energy systems, chemical processing, and water supply networks, and their operational stability is crucial for ensuring production safety and reducing maintenance costs. Unexpected pump failures may result in hazardous operating conditions, production downtime, and substantial financial losses. Consequently, rapid and reliable fault detection has become a core component of modern predictive maintenance. With the increasing adoption of smart manufacturing and the Industrial Internet of Things (IIoT), equipment health monitoring is shifting from traditional reactive maintenance toward real-time, data-driven predictive strategies. Among various sensing modalities, acoustic monitoring has emerged as an attractive solution due to its non-contact nature, low deployment cost, and flexibility, making it well suited for pumps and other rotating machinery [1]. This modality is also increasingly applied across diverse manufacturing processes [2]. However, acoustic signals in industrial environments are often severely affected by background noise, reflections, and interference from nearby equipment, resulting in highly non-stationary and low-SNR (signal-to-noise ratio) patterns. In addition, faulty samples are typically scarce compared with abundant normal recordings, leading to pronounced class imbalance [3]. These factors make reliable acoustic fault detection in real-world industrial settings particularly challenging. In practice, industrial acoustic monitoring is typically deployed under two different data regimes. (i) In early-stage deployments, only normal-condition data may be available, and unsupervised one-class anomaly detection (UAD) is often adopted. (ii) In mature maintenance pipelines, historical fault recordings or maintenance logs are accumulated over time, enabling supervised fault classification.
Early research on pump anomaly detection relied heavily on handcrafted features such as Mel-frequency cepstral coefficients (MFCC), spectral statistics, and entropy-related measures. Akpudo et al. [4] proposed an MFCC-based approach for electromagnetic pump fault detection, while Zhou et al. [5] introduced a method based on sliding dispersion entropy (SDE) for diagnosing diaphragm pump anomalies. Although such methods provide interpretable representations grounded in signal-processing heuristics, their feature expressiveness is inherently limited and their performance is sensitive to noise, equipment variability, and non-stationary operating conditions. Moreover, the dependence on expert-driven feature engineering restricts their scalability and generalization in complex industrial environments.
To overcome these limitations, researchers have increasingly explored unsupervised and self-supervised learning methods, including autoencoders (AE), variational autoencoders (VAE), denoising autoencoders (DAE), and generative adversarial networks (GAN). An et al. [6] applied a VAE to model the latent distribution of normal sound profiles, enabling anomaly detection via reconstruction errors. Müller et al. [7] proposed a convolutional AE that exploits the spatial structure of spectrograms, and GAN-based approaches have been used to learn the distribution of normal acoustic patterns through adversarial training [8]. Despite these advances, reconstruction-based methods typically prioritize global structural fidelity, making them less sensitive to subtle local anomalies. Their reconstruction quality also tends to degrade under high-noise conditions, leading to unstable detection performance. We observe that these UAD methods are particularly suitable for scenarios where fault labels are unavailable. However, such approaches are generally limited to binary anomaly detection, i.e., determining whether a fault exists, and are unable to provide more fine-grained localization at the level of specific equipment or fault types.
With the availability of labeled datasets, supervised deep learning models—particularly convolutional neural networks (CNNs) [9] and recurrent neural networks (RNNs) [10]—have achieved notable success in industrial sound classification and fault detection. These methods not only achieve higher anomaly detection accuracy but also facilitate finer-grained fault partitioning in practical applications [11,12]. CNNs (e.g., VGG) excel at extracting local time–frequency patterns from spectrograms, while RNNs (e.g., LSTM, GRU) are effective at modeling sequential dependencies in machinery operation. e Souza et al. [13] applied a CNN-based classifier to centrifugal pump fault diagnosis, and Ma et al. [14] utilized LSTM models to estimate flow rates and evaluate pump performance. Hybrid architectures such as CNN–LSTM and VGG–LSTM further combine spatial feature extraction with temporal modeling and have demonstrated strong performance across various acoustic monitoring tasks [15,16]. Nevertheless, CNNs inherently struggle to model global dependencies due to limited receptive fields, whereas RNNs suffer from vanishing gradients when handling long sequences, which limits their effectiveness on long-duration spectrograms.
The emergence of the Transformer architecture has reshaped the landscape of sequence modeling. Its self-attention mechanism can capture long-range dependencies without recurrent structures, achieving state-of-the-art performance across speech and natural language processing tasks [17]. Vision Transformer (ViT) [18] extends this paradigm to the image domain by treating image patches as token sequences, demonstrating that attention-only architectures can match or surpass convolutional models. Building upon this foundation, the Audio Spectrogram Transformer (AST) [19] converts audio signals into spectrogram patches and applies Transformer blocks to jointly capture time–frequency dependencies, achieving leading performance on several audio classification benchmarks. These developments highlight the strong potential of attention-based architectures for acoustic modeling.
However, the original AST model was primarily designed for general-purpose acoustic event recognition and has not been tailored to industrial acoustic monitoring. Its large parameter count, high computational cost, and complex architecture hinder deployment in real-time or resource-constrained industrial scenarios. Furthermore, industrial acoustic signals differ markedly from typical environmental sounds: they exhibit strong periodicity, heavy and non-stationary background noise, equipment-specific characteristics, and severe class imbalance. These factors limit the performance and generalization of existing AST architectures when applied to pump fault detection. This work addresses the need for a lightweight Transformer model optimized for industrial constraints.
Accordingly, the main contributions of this work are summarized as follows:
- The Audio Spectrogram Transformer (AST) is systematically introduced into the domain of pump acoustic anomaly detection, and its effectiveness is demonstrated on the MIMII (Malfunctioning Industrial Machine Investigation and Inspection) [20] industrial sound dataset.
- A training framework explicitly tailored to severe class imbalance is developed, integrating class-balanced sampling and time–frequency masking augmentation to mitigate the performance degradation caused by scarce fault samples.
- A lightweight Tiny-AST architecture is proposed, in which the Transformer depth, embedding dimension, and attention complexity are reduced, thereby significantly decreasing the parameter count and inference cost while maintaining strong discriminative performance.
- Extensive experiments are conducted across multiple pump types and noise levels (0 dB, −6 dB, and 6 dB), illustrating the robustness and generalization ability of the proposed method under realistic noisy industrial conditions.
2. Methods
2.1. Overview of the Proposed Framework
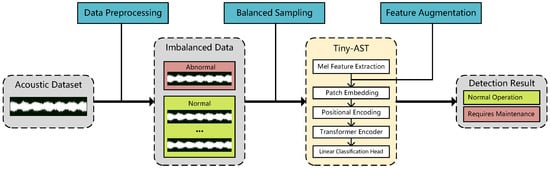
This section presents an overview of the proposed framework for acoustic anomaly detection in industrial pump systems. To cope with the low signal-to-noise ratios, complex background noise, and severe class imbalance commonly encountered in practice, an end-to-end pipeline is constructed in which class-balanced sampling, time–frequency domain feature augmentation, and a lightweight Transformer-based Tiny-AST module are integrated. The overall framework is illustrated in Figure 1.
Figure 1.
Workflow of the proposed Tiny-AST–based anomaly detection framework.
First, the raw audio waveform undergoes basic preprocessing, including amplitude normalization and length alignment. Given the strong imbalance between normal and abnormal samples, a class frequency–aware balanced sampling strategy is applied at the dataset level prior to training, so that minority (abnormal) classes are more frequently presented to the model without discarding information from the majority (normal) classes.
The waveform is then fed into the proposed Tiny-AST module, which begins with a non-trainable time–frequency front-end. Specifically, we compute 128-dimensional log-Mel filterbank features using a 25 ms Hamming window with a 10 ms hop, yielding a 2D log-Mel spectrogram that serves as a standardized acoustic representation for subsequent patch generation and Transformer-based modeling. At this stage, we incorporate time–frequency masking [21] as a data augmentation technique, randomly masking frequency bands and temporal segments to simulate partial signal loss and to improve robustness under noisy industrial conditions.
The augmented log-Mel spectrogram is further processed by the remaining learnable part of the Tiny-AST module, including patch tokenization and linear projection, followed by stacked Transformer encoder layers and an MLP classifier. The output is used as a compact representation for fault classification, yielding the final diagnostic decision.
2.2. Data Preprocessing, Class Balancing, and Augmentation
Acoustic data collected from industrial pumps first undergo basic preprocessing, in which z-score normalization [22] is incorporated into the processing pipeline. However, these data typically exhibit pronounced class imbalance: normal operating states are recorded far more frequently than faults, and abnormal samples are often unevenly distributed across machines and operating conditions. To improve generalization and strengthen the representation of rare faults, a unified preprocessing framework is adopted in which class-balanced sampling is combined with time–frequency masking augmentation on the log-Mel spectrograms used by the Tiny-AST module.
2.2.1. Class-Balanced Sampling Strategy
In a highly imbalanced dataset, naive random sampling tends to over-emphasize the majority (normal) class, which degrades the classifier’s sensitivity to rare abnormal patterns. Classical oversampling inflates the dataset and increases training cost, whereas undersampling discards a substantial portion of normal data. While recent research suggests that Virtual Sample Generation (VSG) [23] and Generative Adversarial Network (GAN) [24] techniques can alleviate data scarcity and class imbalance, such generative methods may introduce additional computational overhead and are less attractive for edge deployment. To avoid these drawbacks, a frequency-aware sampling strategy inspired by [25] is adopted, in which each training sample is assigned a weight inversely proportional to the frequency of its class.
Let denote the number of samples belonging to class k. For the i-th sample with label set , the sampling weight is defined as
The corresponding normalized sampling probability is
where N is the total number of training samples. In the original Pretraining, Sampling, Labeling, and Aggregation (PSLA) framework [25], this formulation is used for the multilabel AudioSet dataset, where each sample may belong to multiple classes.
In the MIMII pump subset considered in this work, each sample is associated with a single label out of eight classes (four pump IDs × two states). Thus, Equation (1) reduces to
and Equation (2) becomes a simple inverse-frequency weighting over classes. During training, we perform weighted random sampling with replacement in each epoch according to . Here, the epoch size is defined as the number of sampled training instances per epoch; in our implementation it is fixed to N draws (i.e., num_samples in WeightedRandomSampler). Therefore, each epoch contains the same number of training iterations as standard uniform sampling, but the sampling distribution is reweighted to increase the relative occurrence of minority (fault) classes.
2.2.2. Time–Frequency Masking Augmentation
Even with class-balanced sampling, rare abnormal samples are still revisited more frequently than normal samples, which may lead to overfitting to specific noise patterns or device conditions. To further enhance robustness and serve as an effective regularization technique, we adopt a SpecAugment-style time–frequency masking scheme, following the implementation used in the PSLA framework [25] and originally proposed in [26]. The masking is applied directly to the log-Mel spectrograms that are fed into Tiny-AST, and is designed to simulate partial signal dropouts along both the time and frequency axes so that the model learns to rely on more global and redundant cues rather than on a few highly localized features; specifically, it prevents the model from over-relying on specific frequency bands (e.g., RPM harmonics) which might not generalize to other pumps.
Let denote the log-Mel spectrogram of an input segment, where T and F are the numbers of time frames and Mel-frequency channels, respectively. We denote by the spectrogram after frequency masking and by the final spectrogram after time masking.
Frequency Masking
A contiguous band of Mel-frequency channels is randomly masked. Let be the maximum frequency-mask width. For each training sample, we draw an integer mask width and a starting index . The frequency-masked spectrogram is then defined element-wise as
Time Masking
Similarly, a contiguous block of time frames is randomly masked. Let be the maximum time-mask width. For each sample, we draw an integer mask width and a starting index . The time-masked spectrogram is obtained from as
In practice, the parameters and are sampled on-the-fly for each input at every epoch, as in [25]. This on-line, SpecAugment-style masking substantially increases the effective diversity of the training data and, as confirmed in our experiments, improves robustness particularly under the most challenging low-SNR conditions.
2.3. AST and the Proposed Tiny-AST
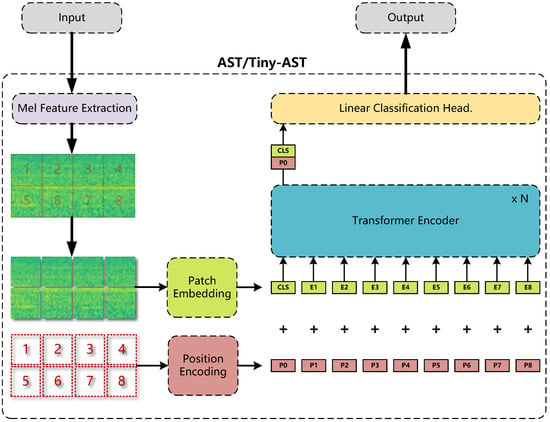
Audio Spectrogram Transformer (AST) [19] is one of the first modules to apply a pure Transformer architecture directly to audio classification. Its overall architecture comprises five key components: mel feature extraction, patch embedding, positional encoding, transformer encoder blocks, and a linear classification head. The architecture is illustrated in Figure 2.
Figure 2.
Architecture of the original AST and the proposed Tiny-AST.
First, the input waveform is processed by the Mel feature extraction front-end, where it is converted into 128-dimensional log-Mel filterbank features using a 25 ms Hamming window with a 10 ms hop, yielding a time–frequency representation of size for an audio clip of length t seconds. The resulting log-Mel spectrogram is then divided into fixed-size patches with overlap along both time and frequency. Each patch is flattened and mapped to a token embedding through a linear projection layer (patch embedding), forming a sequence that serves as input to the Transformer.
Since the Transformer architecture does not inherently encode positional information, AST adds a learnable positional embedding to each patch token. In addition, a learnable classification token (denoted as [CLS]) [27] is prepended to the sequence, and its output representation is used as a global summary of the input audio. The core Transformer encoder module adopts the standard Transformer architecture [17]. Specifically, the encoder is composed of a stack of 6 Transformer blocks using a Pre-Normalization structure, where Layer Normalization (LN) is applied before the Multi-Head Self-Attention (MSA) and the Feed-Forward Network (FFN). The MSA utilizes the standard scaled dot-product attention mechanism. The FFN consists of two linear layers with an expansion ratio of 4, separated by a GELU (Gaussian Error Linear Unit) activation function. In this work, the dropout rate is set to 0 for all layers, as the compact model size and the time–frequency masking augmentation effectively prevent overfitting. Because a mature implementation is already available in PyTorch [28], the model is easy to implement and extend. This attention-based architecture enables the model to capture long-range dependencies across the entire time–frequency plane. Compared with convolutional networks that rely on local receptive fields, AST leverages global attention to directly model interactions between any pair of time–frequency tokens, which is particularly beneficial in complex acoustic environments. Finally, the representation associated with the [CLS] token is normalized by a final Layer Normalization step and projected by a linear classification head to the 8 target classes (Pump IDs × states).
Building on this architecture, a lightweight variant tailored to industrial pump acoustics, referred to as Tiny-AST, is introduced. Tiny-AST preserves the core design of AST—including patch-wise tokenization, learnable positional encoding, a purely attention-based encoder, and a [CLS]-based classification mechanism—but incorporates a set of systematic architectural simplifications to improve efficiency and deployability under industrial constraints.
Concretely, the internal Transformer backbone is reconfigured with a reduced embedding dimension, fewer attention heads, a narrower feed-forward network, and a shallower encoder depth. These changes are not a simple uniform downscaling of the original model; rather, they are guided by the characteristics of industrial pump sounds, which typically exhibit strong periodicity, relatively narrow-band structures, and low signal-to-noise ratios. The resulting lightweight architecture helps mitigate overfitting on limited data, reduces computational cost, and enables deployment on resource-constrained edge devices while maintaining strong discriminative performance.
A detailed comparison between the original AST and the proposed Tiny-AST—including parameter counts, depth, embedding dimensions, and computational complexity—is provided in Section 4.1.
3. Experiment
3.1. Dataset Description
This study employs the MIMII dataset [20] as the primary data source for experiments. The dataset contains sound recordings from various industrial machines under both normal and multiple anomalous operating conditions. The covered machine types include pumps, fans, valves, and sliders, which represent common equipment in industrial environments.
The MIMII dataset features several types of machine faults, including but not limited to rotational imbalance, leakage, internal contamination, and structural wear. Each audio segment is labeled as either normal or abnormal, making the dataset well suited for benchmarking acoustic anomaly detection algorithms.
Audio recordings were collected using a circular microphone array equipped with eight independent microphones, positioned approximately 500 mm from the target machine. To simulate real-world conditions, the dataset incorporates background noise recorded from several actual factories. These noises include sounds from other operating machines, environmental disturbances, and reverberation effects caused by complex spatial structures. Such characteristics render MIMII one of the most challenging and representative public datasets for industrial acoustic anomaly detection.
In this work, we focus specifically on the pump subset of MIMII for model training and evaluation. Table 1 summarizes the detailed composition of the pump data, including machine IDs, the number of normal and abnormal samples, and the noise conditions. The noise level is represented by the SNR, where a lower SNR indicates stronger background interference. For each pump ID and SNR condition, the segments are randomly divided into training, validation, and test sets with a ratio of 7:2:1, ensuring that there is no overlap between the three splits.
Table 1.
Statistics of the pump subset in the MIMII dataset under three SNR conditions (−6 dB, 0 dB, and 6 dB). Since the sample counts remain identical across SNR levels, they are listed only once.
3.2. Evaluation Metrics
To comprehensively evaluate the performance of the proposed method on industrial pump anomaly detection, two widely used metrics are adopted: the area under the receiver operating characteristic (ROC) curve (AUC) [29] and classification accuracy (ACC). These metrics together provide a balanced assessment of the model under the severe class imbalance inherent in industrial acoustic datasets.
In this work, anomaly detection performance is evaluated at the segment level using the area under the ROC curve (AUC). Let and denote the numbers of normal and abnormal test segments, respectively. We denote by and the sets of normal and abnormal segments. The anomaly score for a target failure class k is defined as the model’s confidence that sample x belongs to that specific abnormal class (represented by the output probability of the softmax layer). The AUC for class k can then be written as
where denotes the Heaviside step function, which returns 1 if its argument is greater than 0 and 0 otherwise.
This definition can be interpreted as the probability that a randomly chosen abnormal segment is assigned a higher anomaly score than a randomly chosen normal segment, and thus summarizes the classifier’s performance over all possible decision thresholds. This probabilistic definition applies to both binary and multi-class scenarios. In our experiments, for multi-class tasks, anomaly detection is evaluated in a one-vs-rest manner, and the final performance is reported as the macro-averaged AUC, obtained by averaging the class-wise over all classes.
In addition to AUC, we report the classification accuracy (ACC) as an intuitive measure of the overall prediction performance. Let , , , and denote the numbers of true positives, true negatives, false positives, and false negatives at a given decision threshold, respectively. The accuracy is defined as
Although ACC is easy to interpret, it may be biased toward the majority class when the dataset is highly imbalanced. Therefore, in this work ACC is used as a complementary metric to AUC, providing an additional perspective on the overall behavior of the classifier.
3.3. Experimental Environment and Settings
All experiments are conducted on a workstation equipped with an Intel Core i7-14700KF CPU, 32 GB of RAM, and an NVIDIA GeForce RTX 4070 Ti SUPER GPU, using the PyTorch (version 1.8.1+cu111) deep learning framework. The initial learning rate is set to , and a warm-up schedule is adopted: the learning rate is linearly increased during the first 10 epochs and subsequently decayed by a factor of 0.9 every 2 epochs. The binary cross-entropy (BCE) loss is used as the objective function, and all models are optimized with the Adam optimizer and a weight decay of . Unless otherwise stated, each model is trained for 30 epochs.
The validation set described in Section 3.1 plays a critical role in the training process. Specifically, it is utilized for model selection and hyperparameter tuning. At the end of each training epoch, the model is evaluated on the validation set, and the checkpoint achieving the lowest validation loss is saved as the optimal model for final testing. Additionally, key hyperparameters, including the initial learning rate and the weight decay, were determined based on the model’s performance on the validation set.
In line with the research objectives, four groups of experiments are designed:
- 1.
- Model simplification black and redundancy analysis: to quantify the architectural redundancy in the original AST backbone and determine the minimal capacity required for pump signals.
- 2.
- Ablation study on balanced sampling and data augmentation: to decouple and validate the individual and combined contributions of the proposed class-balanced sampling and time–frequency masking scheme.
- 3.
- Robustness evaluation and comparison with CNN baselines: to compare Tiny-AST with representative convolutional architectures across different SNR conditions in terms of both noise robustness and computational efficiency.
- 4.
- Performance analysis under different supervision regimes: to assess the value of supervised learning by comparing Tiny-AST against unsupervised MIMII baselines, particularly under high-noise conditions.
The corresponding results and discussions are presented in Section 4.
4. Results and Discussion
4.1. Model Simplification Experiments
It is widely recognized in the audio domain that industrial machinery sounds differ fundamentally from general environmental audio (e.g., AudioSet [30]). Pump signals are typically stationary, periodic, and possess lower spectral complexity compared to the diverse and transient events found in large-scale audio datasets. Consequently, standard Transformer architectures like the original AST (equipped with the base384 backbone), which are designed for high-capacity general audio tagging, are likely substantially over-parameterized for this specific task.
To systematically analyze this redundancy and identify the minimal architectural capacity required for effective pump anomaly detection, we conduct a series of model reduction experiments. The original AST model serves not as a baseline to be “beaten”, but as a performance upper bound or reference point. We assume that its massive capacity is sufficient to capture all relevant features, albeit inefficiently. By progressively reducing the embedding dimension, encoder depth, and number of heads, we aim to determine the “breaking point” where the model size aligns with the intrinsic complexity of the pump signals without sacrificing discriminative performance.
Unless otherwise stated, all experiments in this subsection are performed on the pump subset of the MIMII dataset under the SNR = −6 dB condition. This setting corresponds to the most adverse noise environment and thus provides a stringent test of robustness in realistic industrial scenarios. The task is formulated as an 8-class classification problem: the model is required to distinguish four pump units (Pump ID 00, 02, 04, and 06), each with two operating states (normal and abnormal). The input is a raw audio segment from a pump, and the output is the corresponding “Pump ID + operating state” label.
As a first step, the original base384 backbone is replaced with a more compact ViT variant, while the overall AST pipeline is kept unchanged. Following the nomenclature in Vision Transformer (ViT) [18] and DeiT [31], the original AST adopts the base configuration (denoted as base384), characterized by embed_dim = 768, depth = 12, and num_heads = 12. We substitute this with a tiny configuration (denoted as tiny224), reducing the hyperparameters to embed_dim = 192, depth = 12, and num_heads = 3. Apart from this change in backbone capacity, all other training settings (data preprocessing, optimizer, and learning rate schedule) are kept identical to ensure a fair comparison. Table 2 reports the parameter (Params) counts and anomaly detection performance. The results indicate that the model size is substantially reduced after introducing tiny224, while the AUC and ACC under the −6 dB condition exhibit only marginal degradation. This result confirms our hypothesis regarding the redundancy of the original architecture: the base384 scale is indeed unnecessary for characterizing simple pump mechanics, and the model can be significantly compressed.
Table 2.
Comparison between the original AST (base384) and the AST variant with the tiny224 backbone on the pump subset of MIMII (SNR = −6 dB). The base384 model serves as a performance upper bound to demonstrate architectural redundancy.
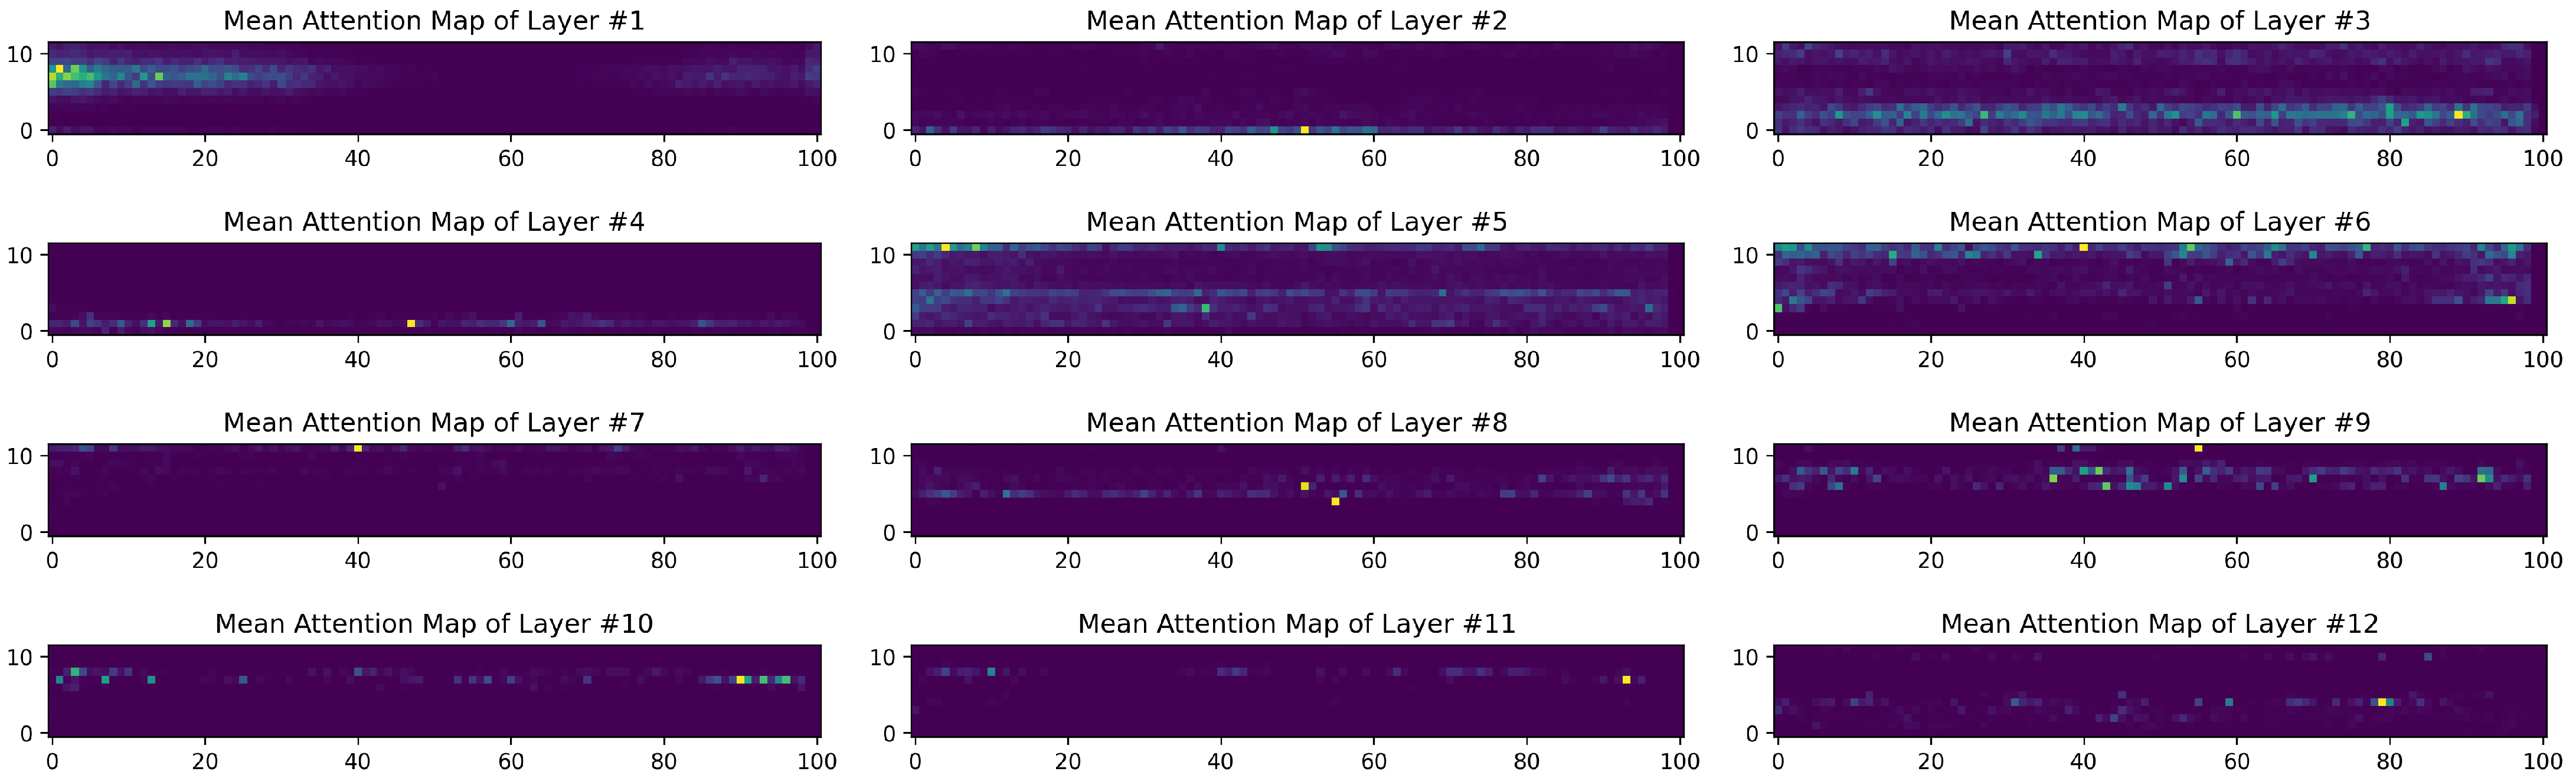
Building on this result, further reductions in network complexity are pursued to improve deployability on edge devices. To guide this process effectively, it is essential to understand how the encoder utilizes its representational capacity. As emphasized in recent industrial AI studies, “opening the black box” of deep networks via explainable AI(XAI) techniques—such as SHAP, Grad-CAM, or attention visualization—is critical for revealing physically meaningful patterns and ensuring reliability in manufacturing systems [2]. Motivated by this, attention-based visualization is performed on the AST model equipped with the tiny224 backbone to gain insights into the contribution of different encoder layers. For each Transformer encoder layer, the multi-head self-attention outputs are first averaged over all attention heads. Then, for the first sample in the batch, the attention weights associated with the token [CLS] are computed. Only the components corresponding to the time–frequency patches are retained, and these attention scores are rearranged into a two-dimensional grid of size along the frequency and time axes. Figure 3 illustrates, under this visualization scheme, the mean attention maps of each encoder layer, i.e., the average attention from the [CLS] token to all time–frequency patches.
Figure 3.
Visualization of mean attention layers 1–12 for the AST-tiny224 configuration.For each layer, the attention weights are averaged over all attention heads and over the batch.The x-axis and y-axis correspond to the time and frequency patch indices, respectively, each representing a local region in the input time–frequency plane. Brighter colors indicate higher attention weights.
As shown in Figure 3, the attention distributions in several encoder layers are relatively sparse. In some layers (e.g., the 2nd, 4th, 7th, and 11th layers), only a small number of time–frequency regions receive substantial attention, while most regions exhibit near-zero responses. This observation suggests that the current network depth and capacity exceed the actual modeling requirements of the task, and that the representational power of certain encoder layers is not fully exploited. Consequently, there is clear potential for further structural simplification.
Motivated by this analysis, the Transformer encoder structure is systematically pruned and adjusted, and multiple combinations of embed_dim, depth, and num_heads are explored under identical experimental settings. To comprehensively evaluate the model efficiency, we report both the number of Params and the floating-point operations (GFLOPs). The resulting metrics, AUC, and ACC for the different configurations are summarized in Table 3. The results indicate that overly aggressive compression (for example, simultaneously reducing both the embedding dimension and the number of layers to very small values) leads to a pronounced drop in detection performance. However, within a moderate range of model sizes, it is possible to retain performance comparable to that of the larger models while significantly reducing both the parameter count and the computational cost.
Table 3.
Model size–performance trade-off of AST under different Transformer encoder configurations on the MIMII pump subset (SNR = −6 dB). GFLOPs are calculated based on an input size of . The proposed Tiny-AST corresponds to the AST-d6h3-96 configuration. Bold values indicate the best performance across different configurations.
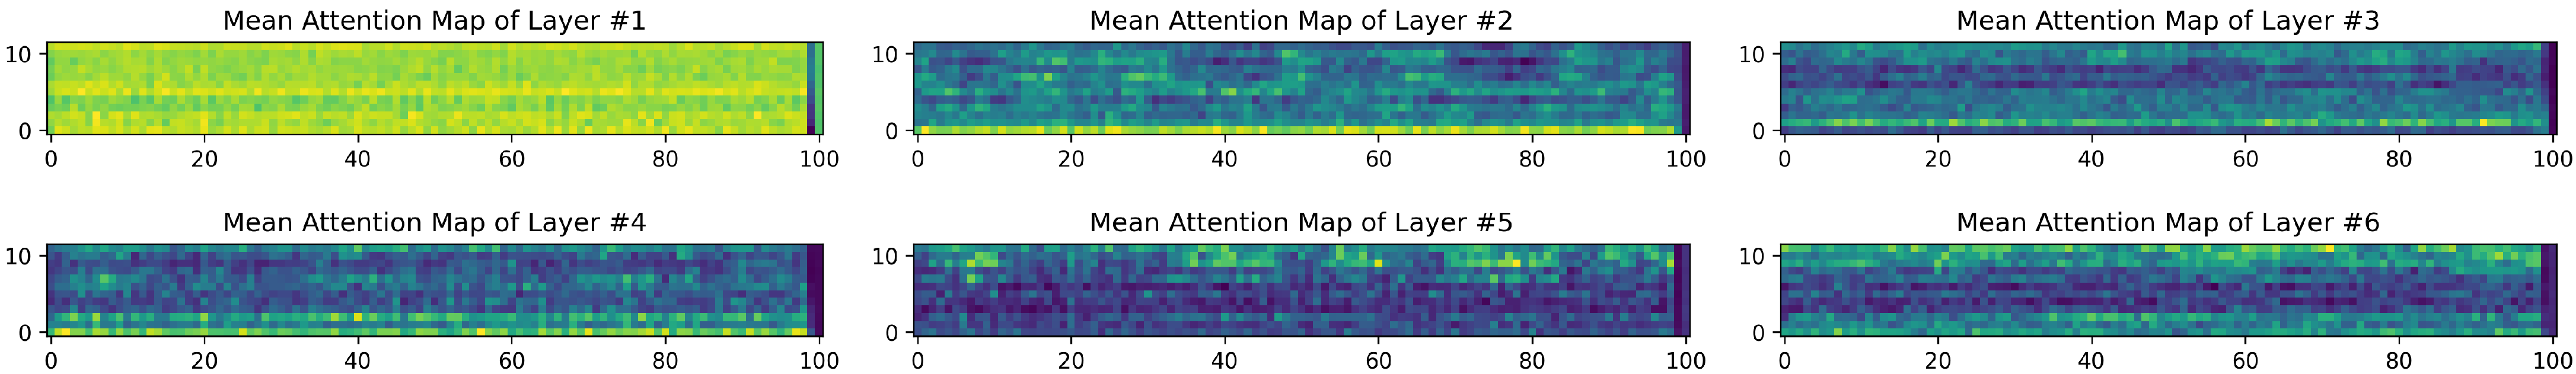
Taking into account the trade-off between compactness, computational efficiency, and accuracy, a configuration with embed_dim = 96, depth = 6, and num_heads = 3 is ultimately adopted as the internal Transformer encoder of the proposed Tiny-AST. Under this configuration, the total number of parameters is only 1.008 M and the computational complexity is strictly limited to 1.683 GFLOPs, while the AUC and ACC under the −6 dB condition reach 0.994595 and 0.943529, respectively. This configuration achieves a favorable balance between model size, inference cost, and detection performance. Figure 4 shows the attention distributions of Tiny-AST obtained using the same visualization procedure. Compared with the tiny224-based model in Figure 3, the attention from the [CLS] token to the time–frequency patches is more concentrated and dense across layers, and a larger number of encoder layers consistently focus on time–frequency regions associated with pump faults. This indicates a more efficient utilization of the encoder’s representational capacity after structural simplification and further demonstrates that the proposed model reduction strategy can enhance efficiency and edge deployability without materially compromising anomaly detection performance.
Figure 4.
Visualization of attention layers 1–6 for the AST-d6h3-96 (Tiny-AST) configuration. The x-axis and y-axis correspond to the time and frequency patch indices, respectively, each representing a local region in the input time–frequency plane. Brighter colors indicate higher attention weights.
4.2. Validation of Balanced Sampling and Data Augmentation Strategies
In practical industrial environments, equipment operates in a healthy state for the vast majority of time, and abnormal conditions occur only sporadically. As a result, anomalous samples are typically scarce, and industrial datasets often exhibit severe class imbalance. For the MIMII dataset used in this study, for example, the number of normal and abnormal samples in the pump subset is approximately in a 10:1 ratio (see Table 1). Such an imbalanced distribution tends to bias the model toward the majority (normal) class during training and weakens its ability to represent minority abnormal patterns. This issue is further exacerbated under strong noise conditions, which make anomaly detection even more challenging.
To alleviate these problems, Section 2.2 introduced a data processing pipeline that combines class-balanced sampling with time–frequency masking-based data augmentation. In this subsection, the effectiveness of this strategy is systematically evaluated. Following the setup of the model simplification experiments in Section 4.1, the focus is again placed on the pump subset of the MIMII dataset with SNR = −6 dB, which emulates a typical high-noise industrial scenario and thus provides a stringent test of robustness. The task is formulated as an 8-class classification problem corresponding to four pumps (Pump ID 00, 02, 04, and 06), each with two operating states (normal/abnormal). This setting enables a comprehensive assessment of the proposed sampling and augmentation strategies across multiple machines and operating conditions.
Regarding the model architecture, the detector is fixed to the Tiny-AST configuration identified in Section 4.1, and only the data processing strategy is varied. Table 4 summarizes the experimental results under different settings. The baseline Tiny-AST (without balancing or augmentation) achieves an AUC of 0.977681 and an ACC of 0.905882. Introducing the class-balanced sampling strategy alone significantly improves the Accuracy to 0.931765 (+2.59%), confirming that mitigating the dominance of normal samples helps the model better identify the minority fault class. On the other hand, applying time–frequency masking augmentation alone yields an AUC of 0.979421 and an ACC of 0.927059, offering a moderate improvement over the baseline by increasing feature diversity. However, the highest performance is achieved when both strategies are combined, yielding an AUC of 0.994595 and an ACC of 0.943529. This demonstrates that balanced sampling and feature augmentation are complementary: the former addresses the label bias, while the latter prevents overfitting to specific noise patterns, jointly enabling robust anomaly detection under low-SNR conditions.
Table 4.
Ablation study of balanced sampling and time–frequency masking on Tiny-AST performance (SNR = −6 dB). The symbol ‘✓’ indicates the component is applied. Bold values indicate the best performance among different combinations.
4.3. Robustness Evaluation and Comparison with CNN Baselines
To assess the robustness of the proposed Tiny-AST model under mismatched noise conditions and to benchmark it against lightweight convolutional architectures, a cross-SNR generalization experiment is conducted. Specifically, all models are trained exclusively on the pump subset of the MIMII dataset with SNR = 0 dB and then evaluated on test sets with SNR levels of 0 dB, −6 dB, and 6 dB. This setting mimics a realistic industrial scenario in which the acoustic environment at deployment time may differ from that observed during training. As in the previous experiments, the task is formulated as an 8-class classification problem corresponding to four pumps (Pump IDs 00, 02, 04, and 06), each in either a normal or an abnormal operating state.
In addition to Tiny-AST, three representative lightweight CNN architectures are adopted as baseline models: ResNet18 [32], EfficientNet-B0 [33], and MobileNetV3 [34]. These networks are widely used in resource-constrained vision applications and are characterized by relatively small parameter counts and computational costs. To ensure a fair comparison, all models share the same input representation (log-Mel spectrograms), training data (0 dB training set), and optimization hyperparameters; only the network architecture differs across methods. The evaluation metrics include the AUC for discrimination performance, as well as the number of Params and GFLOPs to measure model complexity. The GFLOPs are calculated based on the input size of the log-Mel spectrograms, which is , in order to quantify the theoretical computational cost.
Table 5 summarizes the complexity metrics and test AUCs of all models. In terms of computational cost, MobileNetV3 achieves the lowest GFLOPs (0.32), reflecting its design focus on extreme efficiency via depthwise separable convolutions. However, Tiny-AST (1.68 GFLOPs) is still highly efficient, requiring approximately 18% of the computational cost of ResNet18 (9.53 GFLOPs) and is lower than EfficientNet-B0 (2.15 GFLOPs). Notably, Tiny-AST achieves the smallest parameter footprint (1.01 M) among all compared methods, which is advantageous for reducing storage requirements on edge devices.
Table 5.
Comparison of Tiny-AST and lightweight CNN baselines on the MIMII pump subset under different SNR conditions. All models are trained on the 0 dB training set. GFLOPs are calculated to measure computational complexity. Bold values indicate the best performance across different models.
Regarding detection performance, at 0 dB and 6 dB, all methods achieve near-perfect performance (AUCs close to 1). However, when the SNR is reduced to −6 dB, the limitations of the compact CNN baselines become apparent. The AUCs of ResNet18, EfficientNet-B0, and MobileNetV3 drop to 0.907, 0.876, and 0.867, respectively. MobileNetV3, despite its low latency, suffers the most significant performance degradation under heavy noise. In contrast, Tiny-AST maintains the highest AUC of 0.913 under the same condition.
These results demonstrate a critical trade-off: while MobileNetV3 offers the lowest theoretical calculation count, it lacks the representational robustness required for high-noise industrial environments. Tiny-AST effectively bridges this gap, offering a lightweight architecture (smallest Params, low GFLOPs comparable to or better than EfficientNet) while delivering superior cross-noise generalization capability thanks to the global attention mechanism.
4.4. Comparison with Existing MIMII-Based Methods
To further assess the overall effectiveness of the proposed Tiny-AST on industrial acoustic anomaly detection, we compare it with a set of representative methods that have been evaluated on the MIMII dataset. The competing approaches include the official MIMII baseline (MIMII) [20], reconstruction-based autoencoder models (AE, VAE, CAE, CVAE) [35], generative adversarial network variants (GAN, EDGAN) [36], and the recently proposed GRLNet [37].
It is important to note the methodological distinction in this comparison: most baseline methods adopt an unsupervised anomaly detection paradigm, where models are trained exclusively on normal data. In contrast, Tiny-AST adopts an imbalanced supervised learning paradigm, leveraging both normal data and a limited number of historical fault recordings (as discussed in the introduction). Therefore, this comparison aims to quantify the performance benefits of supervision when scarce fault labels are available, particularly under challenging noise conditions, rather than comparing network architectures under identical constraints.
To ensure a consistent evaluation benchmark, we align our test settings with the experimental protocol used in the original MIMII studies. For each SNR level (−6 dB, 0 dB, and 6 dB) and each pump (Pump IDs 00, 02, 04, and 06), an independent binary classification task is defined. The AUC is used as the sole evaluation metric. While baseline methods are trained on normal data only, Tiny-AST is trained on the imbalanced training set containing both classes. The test data splits remain identical for all methods to ensure that reported metrics reflect detection performance on the same acoustic events.
Table 6 summarizes the AUC scores of all methods. To clearly distinguish the experimental protocols, methods are grouped into unsupervised baselines (trained on normal data only) and the proposed supervised approach (trained on normal and limited fault data). In the most challenging −6 dB setting, the traditional reconstruction-based methods exhibit limited performance. The MIMII baseline achieves AUCs in the range of approximately 0.52–0.93. AE, VAE, CAE, CVAE, GAN, GRLNet, and EDGAN generally improve upon the baseline, but for several pumps (e.g., ID 02 and 06), their AUCs remain around or below 0.8. This performance drop indicates that without explicit knowledge of fault patterns, unsupervised models struggle to distinguish subtle anomalies from heavy background noise. In contrast, by learning from the limited fault samples, Tiny-AST attains AUCs of about 0.857, 0.998, and 1.000 on Pump IDs 00, 02, and 04, respectively. Although EDGAN slightly surpasses Tiny-AST on Pump ID 06, Tiny-AST maintains a stable AUC above 0.83. This comparison highlights that supervised learning, even with imbalanced data, offers significantly better robustness in low-SNR environments than pure unsupervised approaches. This observation aligns with recent findings in industrial AI, where deep supervised architectures capable of modeling complex dependencies—such as ResNet-based methods for geometric feature classification—have demonstrated superior resilience against process variability compared to shallower or unsupervised alternatives [38].
Table 6.
AUC comparison between Tiny-AST and existing MIMII-based methods. Methods are grouped by their training data requirements to distinguish between unsupervised baselines and the proposed supervised approach. Bold values indicate the best performance across different models.
Under the 0 dB condition, all methods exhibit improved performance. Tiny-AST reaches AUCs of approximately 0.969, 0.990, and 1.000 on Pump IDs 00, 02, and 04, respectively, demonstrating that the proposed balanced sampling strategy effectively utilizes the minority class data. On Pump ID 06, EDGAN attains a slightly higher AUC (around 0.96) than Tiny-AST (around 0.92). These results suggest that when the noise level is moderate and the anomaly patterns are relatively regular, reconstruction-based methods can be competitive. However, the discriminative nature of Tiny-AST provides a more consistent performance guarantee across different machines without requiring the careful threshold tuning often needed for reconstruction error distributions.
In the high-SNR setting of 6 dB, nearly all methods achieve AUCs close to 1, showing that when background interference is weak, a variety of modeling paradigms can reliably distinguish between normal and abnormal states. In this scenario, Tiny-AST achieves AUCs of about 0.970, 0.997, and 1.000 on Pump IDs 00, 02, and 04, respectively. This indicates that the “supervised” advantage diminishes when the signal is clean, as the normal data distribution is distinct enough for UAD methods to work effectively.
Considering all three SNR levels, the value of the proposed method lies in its “worst-case” performance. First, in the −6 dB scenario, Tiny-AST substantially outperforms reconstruction-based unsupervised methods on the majority of pumps. Second, at 0 dB and 6 dB, it remains on par with the state-of-the-art. While strict comparisons are constrained by the different training data regimes, these results empirically validate that in “mature” industrial pipelines where historical fault logs exist, deploying a lightweight supervised model like Tiny-AST is a more robust strategy than relying solely on normal-data-based anomaly detection.
5. Conclusions
This paper has presented a lightweight Audio Spectrogram Transformer (Tiny-AST) for robust acoustic anomaly detection in industrial pump systems, specifically designed for imbalanced supervised learning scenarios. By systematically simplifying the original AST architecture, the resulting Tiny-AST contains only 1.01 M parameters and requires just 1.68 GFLOPs, achieving a competitive balance between model complexity and performance. Model simplification experiments confirmed that the original AST backbone was substantially over-parameterized for this task, and attention map visualizations revealed that the streamlined encoder utilizes its representational capacity more effectively.
Our training strategy, combining class frequency-based balanced sampling with time–frequency masking augmentation, proved highly effective. Ablation studies demonstrated that this approach significantly improves both AUC and ACC under the most challenging −6 dB noise condition, confirming its vital role in enhancing detection stability when faced with severe class imbalance and strong background interference.
The robustness of Tiny-AST was benchmarked against both lightweight CNNs and existing unsupervised MIMII-based methods, yielding two key insights. First, compared to CNNs, Tiny-AST offers a superior trade-off between efficiency and robustness. While being significantly more computationally efficient than baselines like ResNet18, it provides substantially better noise resilience than ultra-lightweight models such as MobileNetV3. Second, the comparison with unsupervised methods (e.g., autoencoders, GANs) quantifies the value of supervision in high-noise environments. While unsupervised methods are effective in clean conditions, their performance degrades sharply at −6 dB. In contrast, by leveraging even scarce fault labels, Tiny-AST maintains high reliability, demonstrating a critical performance gain for “mature” industrial pipelines with available historical data.
Despite these advantages, we acknowledge that as a supervised model, Tiny-AST is primarily designed to recognize known fault types and may not generalize to entirely novel anomalies. This makes it most suitable for “brownfield” environments where the primary failure modes are recurrent and documented. Future work will focus on extending Tiny-AST to other machine types, incorporating self-supervised pretraining to leverage large unlabeled datasets, and developing hybrid models that combine supervised precision with unsupervised novelty detection capabilities.
Author Contributions
Conceptualization, H.Z. and Y.-H.L.; methodology, H.Z. and Y.-H.L.; software, H.Z.; validation, H.Z. and Y.-H.L.; formal analysis, Y.-H.L. investigation, H.Z.; resources, Y.-H.L.; data curation, H.Z.; writing—original draft preparation, H.Z.; writing—review and editing, H.Z. and Y.-H.L.; visualization, H.Z.; supervision, Y.-H.L.; project administration, Y.-H.L.; funding acquisition, Y.-H.L. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by ZZ2025JH08.
Data Availability Statement
This study is based on the publicly available MIMII dataset, which can be accessed at the MIMII project repository (accessed on 15 September 2025). (https://zenodo.org/record/3384388). No new raw data were created in this work. The preprocessing steps and the use of the dataset for training and evaluation are described in Section 3 and Section 4.
Conflicts of Interest
The authors declare no conflict of interest. The funders had no role in the design of the study; in the collection, analyses, or interpretation of data; in the writing of the manuscript; or in the decision to publish the results.
References
- Yang, Y.; Ding, L.; Xiao, J.; Fang, G.; Li, J. Current status and applications for hydraulic pump fault diagnosis: A review. Sensors 2022, 22, 9714. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wu, M.; Yao, Z.; Verbeke, M.; Karsmakers, P.; Gorissen, B.; Reynaerts, D. Data-driven models with physical interpretability for real-time cavity profile prediction in electrochemical machining processes. Eng. Appl. Artif. Intell. 2025, 160, 111807. [Google Scholar] [CrossRef] [Scilit]
- Tang, S.; Yuan, S.; Zhu, Y. Deep learning-based intelligent fault diagnosis methods toward rotating machinery. IEEE Access 2019, 8, 9335–9346. [Google Scholar] [CrossRef] [Scilit]
- Akpudo, U.E.; Hur, J.W. A cost-efficient MFCC-based fault detection and isolation technology for electromagnetic pumps. Electronics 2021, 10, 439. [Google Scholar] [CrossRef] [Scilit]
- Zhou, C.; Jia, Y.; Bai, H.; Xing, L.; Yang, Y. Sliding dispersion entropy-based fault state detection for diaphragm pump parts. Coatings 2021, 11, 1536. [Google Scholar] [CrossRef] [Scilit]
- An, J.; Cho, S. Variational autoencoder based anomaly detection using reconstruction probability. Spec. Lect. IE 2015, 2, 1–18. [Google Scholar]
- Müller, R.; Ritz, F.; Illium, S.; Linnhoff-Popien, C. Acoustic Anomaly Detection for Machine Sounds based on Image Transfer Learning. In Proceedings of the 13th International Conference on Agents and Artificial Intelligence (ICAART 2021), Online, 4–6 February 2021; SciTePress: Setúbal, Portugal, 2021; Volume 2, pp. 49–56. [Google Scholar] [CrossRef] [Scilit]
- Xia, X.; Pan, X.; Li, N.; He, X.; Ma, L.; Zhang, X.; Ding, N. GAN-based anomaly detection: A review. Neurocomputing 2022, 493, 497–535. [Google Scholar] [CrossRef] [Scilit]
- Kim, Y. Convolutional Neural Networks for Sentence Classification. In Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP), Doha, Qatar, 25–29 October 2014; pp. 1746–1751. [Google Scholar]
- Elman, J.L. Finding structure in time. Cogn. Sci. 1990, 14, 179–211. [Google Scholar] [CrossRef]
- Chen, B.; Zha, J.; Cai, Z.; Wu, M. Predictive modelling of surface roughness in precision grinding based on hybrid algorithm. CIRP J. Manuf. Sci. Technol. 2025, 59, 1–17. [Google Scholar] [CrossRef] [Scilit]
- Wu, M.; Arshad, M.H.; Saxena, K.K.; Qian, J.; Reynaerts, D. Profile prediction in ECM using machine learning. Procedia CIRP 2022, 113, 410–416. [Google Scholar] [CrossRef] [Scilit]
- e Souza, A.C.O.; de Souza, M.B., Jr.; da Silva, F.V. Development of a CNN-based fault detection system for a real water injection centrifugal pump. Expert Syst. Appl. 2024, 244, 122947. [Google Scholar] [CrossRef] [Scilit]
- Ma, J.; Wang, Y.; Wen, J.; Zhang, B.; Li, W. Early Anomaly Detection in Hydraulic Pumps Based on LSTM Traffic Prediction Model. In International Conference on Intelligent Information Processing; Springer: Cham, Switzerland, 2024; pp. 3–15. [Google Scholar]
- Wang, P.; Zhang, Y.; Linjama, M.; Zhao, L.; Yao, J. Fault identification and localization for the fast switching valve in the equal-coded digital hydraulic system based on hybrid CNN-LSTM model. Mech. Syst. Signal Process. 2025, 224, 112201. [Google Scholar] [CrossRef] [Scilit]
- Zhu, Y.; Su, H.; Tang, S.; Zhang, S.; Zhou, T.; Wang, J. A novel fault diagnosis method based on SWT and VGG-LSTM model for hydraulic axial piston pump. J. Mar. Sci. Eng. 2023, 11, 594. [Google Scholar] [CrossRef] [Scilit]
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A.N.; Kaiser, Ł.; Polosukhin, I. Attention is all you need. Adv. Neural Inf. Process. Syst. 2017, 30, 5998–6008. [Google Scholar]
- Dosovitskiy, A.; Beyer, L.; Kolesnikov, A.; Weissenborn, D.; Zhai, X.; Unterthiner, T.; Dehghani, M.; Minderer, M.; Heigold, G.; Gelly, S.; et al. An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale. arXiv 2020, arXiv:2010.11929. [Google Scholar]
- Gong, Y.; Chung, Y.A.; Glass, J. AST: Audio Spectrogram Transformer. arXiv 2021, arXiv:2104.01778. [Google Scholar]
- Purohit, H.; Tanabe, R.; Ichige, K.; Endo, T.; Nikaido, Y.; Suefusa, K.; Kawaguchi, Y. MIMII Dataset: Sound Dataset for Malfunctioning Industrial Machine Investigation and Inspection. In Proceedings of the 4th Workshop on Detection and Classification of Acoustic Scenes and Events (DCASE2019), New York, NY, USA, 25–26 October 2019; pp. 209–213. [Google Scholar] [CrossRef] [Scilit]
- Kong, Q.; Cao, Y.; Iqbal, T.; Wang, Y.; Wang, W.; Plumbley, M.D. Panns: Large-scale pretrained audio neural networks for audio pattern recognition. IEEE/ACM Trans. Audio Speech Lang. Process. 2020, 28, 2880–2894. [Google Scholar] [CrossRef] [Scilit]
- Al Shalabi, L.; Shaaban, Z.; Kasasbeh, B. Data mining: A preprocessing engine. J. Comput. Sci. 2006, 2, 735–739. [Google Scholar] [CrossRef] [Scilit]
- Ge, J.; Yao, Z.; Wu, M.; Almeida, J.H.S., Jr.; Jin, Y.; Sun, D. Tackling data scarcity in machine learning-based CFRP drilling performance prediction through a Broad Learning System with Virtual Sample Generation (BLS-VSG). Compos. Part B Eng. 2025, 305, 112701. [Google Scholar] [CrossRef] [Scilit]
- Zhang, H.; Lai, Y.H. Improving State-of-Health Estimation for Lithium-Ion Batteries Based on a Generative Adversarial Network and Partial Discharge Profiles. World Electr. Veh. J. 2025, 16, 277. [Google Scholar] [CrossRef] [Scilit]
- Gong, Y.; Chung, Y.A.; Glass, J. Psla: Improving audio tagging with pretraining, sampling, labeling, and aggregation. IEEE/ACM Trans. Audio Speech Lang. Process. 2021, 29, 3292–3306. [Google Scholar] [CrossRef] [Scilit]
- Park, D.S.; Chan, W.; Zhang, Y.; Chiu, C.C.; Zoph, B.; Cubuk, E.D.; Le, Q.V. SpecAugment: A Simple Data Augmentation Method for Automatic Speech Recognition. arXiv 2019, arXiv:1904.08779. [Google Scholar]
- Devlin, J.; Chang, M.W.; Lee, K.; Toutanova, K. Bert: Pre-training of deep bidirectional transformers for language understanding. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers); Association for Computational Linguistics: Stroudsburg, PA, USA, 2019; pp. 4171–4186. [Google Scholar]
- Paszke, A.; Gross, S.; Massa, F.; Lerer, A.; Bradbury, J.; Chanan, G.; Killeen, T.; Lin, Z.; Gimelshein, N.; Antiga, L.; et al. PyTorch: An Imperative Style, High-Performance Deep Learning Library. Adv. Neural Inf. Process. Syst. 2019, 32, 8024–8035. [Google Scholar]
- Koizumi, Y.; Kawaguchi, Y.; Imoto, K.; Nakamura, T.; Nikaido, Y.; Tanabe, R.; Purohit, H.; Suefusa, K.; Endo, T.; Yasuda, M.; et al. Description and Discussion on DCASE2020 Challenge Task2: Unsupervised Anomalous Sound Detection for Machine Condition Monitoring. arXiv 2020, arXiv:2006.05822. [Google Scholar]
- Gemmeke, J.F.; Ellis, D.P.; Freedman, D.; Jansen, A.; Lawrence, W.; Moore, R.C.; Plakal, M.; Ritter, M. Audio set: An ontology and human-labeled dataset for audio events. In Proceedings of the 2017 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), New Orleans, LA, USA, 5–9 March 2017; pp. 776–780. [Google Scholar]
- Touvron, H.; Cord, M.; Douze, M.; Massa, F.; Sablayrolles, A.; Jégou, H. Training data-efficient image transformers & distillation through attention. In Proceedings of the International Conference on Machine Learning, Virtual, 18–24 July 2021; pp. 10347–10357. [Google Scholar]
- He, K.; Zhang, X.; Ren, S.; Sun, J. Deep residual learning for image recognition. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Las Vegas, NV, USA, 27–30 June 2016; pp. 770–778. [Google Scholar]
- Tan, M.; Le, Q. Efficientnet: Rethinking model scaling for convolutional neural networks. In Proceedings of the International Conference on Machine Learning, Long Beach, CA, USA, 9–15 June 2019; pp. 6105–6114. [Google Scholar]
- Howard, A.; Sandler, M.; Chu, G.; Chen, L.C.; Pang, R.; Vasudevan, V. Searching for MobileNetV3. In Proceedings of the 2019 IEEE/CVF International Conference on Computer Vision (ICCV), Seoul, Republic of Korea, 27 October–2 November 2019. [Google Scholar]
- Nguyen, M.H.; Nguyen, D.Q.; Nguyen, D.Q.; Pham, C.N.; Bui, D.; Han, H.D. Deep convolutional variational autoencoder for anomalous sound detection. In Proceedings of the 2020 IEEE Eighth International Conference on Communications and Electronics (ICCE), Phu Quoc Island, Vietnam, 13–15 January 2021; pp. 313–318. [Google Scholar]
- Liu, S.; Li, J.; Ke, W.; Yin, H. Multi-attention enhanced discriminator for gan-based anomalous sound detection. In Proceedings of the ICASSP 2024-2024 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Seoul, Republic of Korea, 14–19 April 2024; pp. 6715–6719. [Google Scholar]
- Sha, Y.; Gou, S.; Faber, J.; Liu, B.; Li, W.; Schramm, S.; Stoecker, H.; Steckenreiter, T.; Vnucec, D.; Wetzstein, N.; et al. Regional-local adversarially learned one-class classifier anomalous sound detection in global long-term space. In Proceedings of the 28th ACM SIGKDD Conference on Knowledge Discovery and Data Mining, New York, NY, USA, 14–18 August 2022; pp. 3858–3868. [Google Scholar]
- Wu, M.; Yao, Z.; Ye, L.; Verbeke, M.; Karsmakers, P.; Reynaerts, D. Geometrical Feature Classification in Electrical Discharge Machining Using In-Process Monitoring and Machine Learning. Procedia CIRP 2025, 137, 462–467. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.