


Abstract
This paper investigates the estimation of the value at risk (VaR) across various probability levels for the log-returns of a comprehensive dataset comprising four thousand crypto-assets. Employing four recently introduced adaptive conformal inference (ACI) algorithms, we aim to provide robust uncertainty estimates crucial for effective risk management in financial markets. We contrast the performance of these ACI algorithms with that of traditional benchmark models, including GARCH models and daily range models. Despite the substantial volatility observed in the majority of crypto-assets, our findings indicate that ACI algorithms exhibit notable efficacy. In contrast, daily range models, and to a lesser extent, GARCH models, encounter challenges related to numerical convergence issues and structural breaks. Among the ACI algorithms, Fully Adaptive Conformal Inference (FACI) and Scale-Free Online Gradient Descent (SF-OGD) stand out for their ability to provide precise VaR estimates across all quantiles examined. Conversely, Aggregated Adaptive Conformal Inference (AgACI) and Strongly Adaptive Online Conformal Prediction (SAOCP) demonstrate proficiency in estimating VaR for extreme quantiles but tend to be overly conservative for higher probability levels. These conclusions withstand robustness checks encompassing the market capitalization of crypto-assets, time-series size, and different forecasting methods for asset log-returns. This study underscores the promise of ACI algorithms in enhancing risk assessment practices in the context of volatile and dynamic crypto-asset markets.
1. Introduction
In the realm of predictive modeling and decision making, accurately quantifying uncertainty is as crucial as making accurate predictions themselves. This need for robust uncertainty estimation becomes particularly pronounced in high-stakes scenarios, where the consequences of erroneous decisions can be significant. One widely accepted approach for quantifying uncertainty is through the utilization of prediction sets, which associate each prediction with a range of potential outcomes, thereby providing a measure of the model’s confidence in its predictions.
Conformal inference, introduced by Vovk et al. (2005) and Shafer and Vovk (2008), offers a powerful framework for enhancing predictive models by constructing valid prediction sets with coverage guarantees. Unlike traditional methods that rely heavily on specific assumptions about data distributions, conformal prediction imposes minimal assumptions, primarily requiring exchangeability of the data; see Angelopoulos and Bates (2023) for a recent survey. However, in many real-world scenarios, such as time-series data or instances of distributional shift, the assumption of exchangeability may not hold, necessitating the development of adaptive techniques to handle such complexities.
Recent advancements in conformal inference have led to the emergence of adaptive conformal inference (ACI) algorithms, designed explicitly to address scenarios where data arrive sequentially, without assuming exchangeability. These algorithms dynamically adjust the width of prediction intervals in response to observed data, thereby providing adaptive and accurate uncertainty quantification. Notably, ACI algorithms have been shown to be effective in various domains, including financial forecasting, epidemiology, and image classification.
Motivated by the success of ACI algorithms in handling sequential data, we turn our attention to the task of forecasting the value at risk (VaR) using adaptive conformal inference techniques. The VaR, a measure of the maximum potential loss that an investment portfolio may face over a specified time horizon, is of paramount importance in risk management across financial institutions and investment firms. Moreover, Emmer et al. (2015) and Kratz et al. (2018) showed that the expected shortfall (ES)1 can be backtested through the approximation of several VaR estimates computed at different probability levels using a multinomial test. Accurate risk estimation is critical for ensuring financial stability and making informed investment decisions.
In this paper, we explore an innovative application of adaptive conformal inference (ACI) methods, traditionally employed for generating prediction intervals in machine learning, to the domain of financial risk management, specifically for estimating value-at-risk (VaR) measures. While ACI methods have been predominantly used to construct robust confidence intervals around mean predictions, we adapt these methods to provide precise point estimates for tail quantiles. This adaptation leverages the ability of ACI to dynamically adjust prediction intervals based on the observed data, which is particularly useful in capturing the extreme quantiles necessary for accurate VaR estimation.
The conventional use of ACI methods involves creating prediction intervals for a given mean prediction model, adjusting the interval widths based on whether recent predictions have been included or excluded within these intervals. This adaptive mechanism ensures that the prediction intervals remain reliable over time, even as the underlying data distribution shifts. In our work, we repurpose this adaptive mechanism to estimate the quantiles of the prediction errors, which are then combined with point forecasts from a simple mean prediction model. This approach allows us to accurately predict the tail quantiles, which correspond to the VaR measures. By clearly delineating this novel application of ACI methods, we provide a fresh perspective on how these techniques can be utilized beyond their traditional scope. Our main interest lies not in constructing prediction intervals around mean forecasts, but in obtaining accurate point estimates for tail quantiles directly. This focus on quantile estimation for VaR calculation is crucial for effective financial risk management, where understanding the behavior of extreme values is more relevant than the central tendency. Thus, our work bridges the gap between robust prediction interval methodologies and the specific needs of financial risk estimation, offering a valuable contribution to the field.
Specifically, we explore the application of various ACI algorithms, including Aggregated ACI by Zaffran et al. (2022), Fully Adaptive Conformal Inference by Gibbs and Candès (2022), Scale-Free Online Gradient Descent by Bhatnagar et al. (2023), and Strongly Adaptive Online Conformal Prediction by Bhatnagar et al. (2023), in the context of VaR prediction. These algorithms offer different approaches to adaptively adjusting prediction intervals, thereby catering to diverse modeling requirements and data characteristics.
The primary objectives in this study are twofold. First, we aim to conduct a comprehensive empirical evaluation to assess the performance and applicability of the proposed ACI algorithms in VaR prediction tasks, to evaluate whether these methodologies can ensure accurate and reliable estimation of uncertainty in financial risk assessment. Secondly, we perform a wide range of robustness checks to verify that the results for the baseline case also hold in different settings. Therefore, we perform a series of checks considering the market capitalization of crypto-assets, time-series size, and different forecasting methods for asset log-returns.
In the rapidly evolving landscape of cryptocurrencies, understanding risk measures is crucial for both investors and regulators. Previous empirical works have often focused on the most capitalized cryptocurrencies, such as Bitcoin and Ethereum, due to their high liquidity and significant market impact. However, the cryptocurrency market is highly diverse, encompassing assets with varying degrees of liquidity, capitalization, and investor profiles. It is for this reason that this paper aims to address this diversity by analyzing a comprehensive dataset of 4000 cryptocurrencies. This broad scope allows us to capture a wide range of market behaviors and dynamics, providing a more holistic view of risk measures across the entire cryptocurrency spectrum. By including assets with different characteristics, we can derive more robust and generalizable conclusions about the effectiveness of adaptive conformal inference (ACI) methods for computing market risk measures.
The remainder of this paper is organized as follows. In Section 2, we review the literature devoted to adaptive conformal inference algorithms, while Section 3 presents a description of the ACI algorithms under consideration, highlighting their key features and theoretical properties. Subsequently, in Section 4, we conduct extensive empirical evaluations with four thousand crypto-assets to compare the performance of these algorithms in VaR forecasting tasks, together with robustness checks. Finally, Section 5 summarizes our findings and outlines directions for future research in this domain.
2. Literature Review
Conformal inference (CI), originally proposed by Vovk et al. (1999) and Vovk et al. (2005), has emerged as a versatile framework for constructing prediction intervals around point predictions, facilitating robust uncertainty quantification across various domains (Angelopoulos and Bates 2023). It has garnered significant attention for its utility in uncertainty quantification in regression and classification tasks; see Papadopoulos (2008), Lei et al. (2013), Lei and Wasserman (2014), Vovk et al. (2018), Romano et al. (2019, 2020), Cauchois et al. (2021), and Barber et al. (2021) for several examples and detailed discussions.
However, traditional CI methods operate under the assumption of data exchangeability, wherein the joint distribution of observations remains invariant to their order. However, real-world datasets often deviate from this assumption, particularly in scenarios involving temporal dependence, such as time-series data; see Gibbs and Candès (2021, 2022), Zaffran et al. (2022), and Bhatnagar et al. (2023). In this regard, several extensions of conformal prediction techniques have addressed challenges related to distribution shift, employing methods such as reweighting and distributionally robust optimization to maintain approximately valid coverage; see Tibshirani et al. (2019), Podkopaev and Ramdas (2021), Yang et al. (2022), and Barber et al. (2023).
A recent line of research within the CI framework focuses on adaptive conformal inference (ACI) algorithms, designed to handle non-exchangeable data by dynamically adjusting prediction intervals based on observed data (Gibbs and Candès 2021). The original ACI algorithm introduces a learning rate parameter to control the rate of adaptation, with subsequent research exploring meta-algorithms to optimize this parameter. Notable ACI algorithms include the Aggregated ACI by Zaffran et al. (2022), the Fully Adaptive Conformal Inference by Gibbs and Candès (2022), the Scale-Free Online Gradient Descent by Bhatnagar et al. (2023), and the Strongly Adaptive Online Conformal Prediction by Bhatnagar et al. (2023).
Alternative lines of research have also started to explore the application of conformal prediction to time-series data by using randomization, ensembles, and other meta-algorithms to produce valid prediction sets (Chernozhukov et al. 2018; Sousa et al. 2022; Xu and Xie 2021). Other approaches include simply using vanilla conformal prediction for time series without theoretical guarantees or resorting to weaker notions of exchangeability; see Dashevskiy and Luo (2008), Wisniewski et al. (2020), Stankeviciute et al. (2021), and Kath and Ziel (2021). To keep track of the latest developments in conformal prediction, the reader may want to see the Awesome Conformal Prediction repository by Manokhin (2024).
Overall, the literature on adaptive conformal inference algorithms underscores their significance in addressing the complexities of non-exchangeable data, offering the most promising avenues for robust uncertainty quantification in diverse application domains. It is for these reasons that we will use these methodologies to compute robust market risk measures with crypto-assets.
We remark that Wisniewski et al. (2020) and Kath and Ziel (2021) are the only authors who employed (vanilla) conformal prediction to generate prediction intervals and rigorously tested their validity using unconditional and conditional coverage tests. However, their primary focus was on obtaining valid prediction intervals rather than on the tails of the distribution, which are critical for financial risk management. Wisniewski et al. (2020) evaluated their models using 19 different confidence levels, ranging from 5% to 95%, while Kath and Ziel (2021) focused on 50% and 90% prediction intervals. Despite their thorough examination, the quantiles they considered do not align with the requirements of financial risk management. Regulatory frameworks such as the Basel II agreement mandate the use of value at risk (VaR) at the 1% probability level, while Basel III suggests using expected shortfall at the 2.5% probability level. The higher quantiles examined by Wisniewski et al. (2020) and Kath and Ziel (2021) are less relevant for these purposes. Moreover, both studies revealed that although several models passed the unconditional coverage tests, almost none succeeded in the conditional coverage tests across all significance levels (see table 2 in both papers). Such results highlight the limitations of existing models in providing reliable risk measures that are crucial for serious risk management applications. In contrast to these prior works, our study pioneers the application of ACI methods specifically for estimating tail quantiles relevant to financial risk management and that are robust to distributional shifts. By focusing on quantile estimation for VaR, we address a critical gap in the literature. Our approach not only leverages the adaptive nature of ACI to dynamically adjust prediction intervals but also repurposes these intervals to provide precise point estimates for the tail quantiles. This innovative use of ACI methods extends their applicability beyond traditional prediction interval construction, offering significant benefits for the accurate estimation of risk measures. To our knowledge, this alternative use of ACI for direct quantile estimation in the context of financial risk management has not been explicitly considered in the previous literature. Thus, our work not only builds on the previous studies of Wisniewski et al. (2020) and Kath and Ziel (2021) but also introduces a novel application that enhances the toolkit available for risk managers.
3. Materials and Methods
The aim of this study is to compare the performance of four ACI algorithms with traditional volatility models for daily data, such as GARCH models and daily range models, in computing the value at risk (VaR) at various probability levels for a large set of crypto-assets. Additionally, this comparison indirectly assesses the quality of the models’ expected shortfall (ES), as proposed by Kratz et al. (2018). The ES represents the average of the worst p losses, where p is the percentile of the returns distribution. Although Gneiting (2011) demonstrated that the ES lacks a mathematical property known as elicitability and cannot be directly backtested, Emmer et al. (2015) showed that the ES becomes elicitable when conditioned on the VaR and can be backtested by approximating multiple VaR levels. This concept was further refined by Kratz et al. (2018), who introduced a multinomial test of VaR violations across multiple levels as a means of backtesting the ES.
Before presenting the outcomes of our extensive empirical evaluations, we first discuss the general structure of adaptive conformal inference, the four specific ACI algorithms used in our analysis, the benchmark volatility models for daily data, and backtesting procedures for market risk measures.
3.1. Adaptive Conformal Inference: The General Structure
We delve into an online learning scenario where we have a sequential stream of crypto-assets’ log-returns , one at a time; see Cesa-Bianchi and Lugosi (2006) for a detailed discussion of online learning theory. Supposing that is our desired empirical coverage of prediction intervals, our objective is to produce, at each time step t, a prediction interval for the upcoming log-return . This interval is generated using an interval construction function denoted as , that takes a parameter and produces a closed prediction interval . It is essential that the interval construction function be nested, so that if , then must be a subset of , thus indicating wider prediction intervals for larger values of . is indexed by t to highlight its potential dependence on other information available at each time point, such as a point prediction . In addition, let be the radius at time t, i.e., the smallest ensuring that the prediction interval covers the log-return , and be the indicator function. A critical assumption used for the theoretical analysis of several ACI algorithms is the boundedness of these radii, so there exists a constant such that for all t.
A straightforward approach to build prediction intervals involves directly employing the parameter to determine the interval width. Given the point prediction at each time t, we can create a symmetric prediction interval around this point estimate as . This method is known as the linear interval constructor and, in this setup, the radius is given by the absolute residual . The original work on adaptive conformal inference (ACI) by Gibbs and Candès (2021) proposed constructing intervals based on past observed residuals. Assume we have a function S, known as a “nonconformity score”, where a common choice is given by the absolute residual . Moreover, if we denote with the nonconformity score of the t-th log-return, then the quantile interval constructor is formulated as follows:
where Quantile is the empirical -quantile of the elements in set M. It is easy to verify that is nested within because the quantile function is non-decreasing in . The linear interval constructor is used with Scale-Free Online Gradient Descent by Bhatnagar et al. (2023) and Strongly Adaptive Online Conformal Prediction by Bhatnagar et al. (2023), whereas the quantile interval constructor is used with Aggregated ACI by Zaffran et al. (2022) and Fully Adaptive Conformal Inference by Gibbs and Candès (2022).
In this framework, the lower quantile of the interval constructor corresponds to the 1-day-ahead value at risk (VaR) at the probability level , denoted as . Conversely, the upper quantile of the interval constructor corresponds to the 1-day-ahead value at risk (VaR) at the probability level , denoted as .
In general, the ACI algorithms’ interactions with the data and the computations of losses follow a similar pattern, which is repeated sequentially for each time step :
- Predict and build the prediction interval ;
- Observe the true outcome and compute the radius ;
- Verify whether is not included in the prediction interval, ;
- Compute the so-called pinball loss , defined as follows:
This iterative process forms the foundation of the theoretical framework of online learning, from which theoretical results are then derived for each ACI algorithm.
The original adaptive conformal inference (ACI) algorithm proposed by Gibbs and Candès (2021) dynamically adjusts the width of prediction intervals based on observed data. Their algorithm is outlined in pseudo-code format in Appendix A. It is possible to show that the updating mechanism for the estimated radius can be derived as an online subgradient descent scheme, using the subgradient of the pinball loss function. In simple terms, if the log-return falls outside the prediction interval at time t (), the next interval widens . Conversely, if falls within the interval , the next interval narrows . The learning rate governs the speed at which the interval width adapts to the data and is the primary tuning parameter. Theoretical considerations on coverage error bounds suggest a larger to expedite coverage error decay over time. However, in practice, overly large values lead to intervals exhibiting significant oscillations. Conversely, overly small values result in intervals that adapt too slowly to distribution shifts. Hence, selecting an appropriate value is crucial. This issue has spurred the development of ACI algorithms that are robust to the choice of this parameter. The theoretical guarantees concerning the performance of the ACI algorithm remain unaffected by the selection of the initial value . Therefore, in practical applications any value can be chosen. Over time, the influence of the initial choice of diminishes proportionally to the chosen learning rate. Following Susmann et al. (2023), we set when employing the quantile interval predictor, and otherwise.
Finally, we remark that in the evaluation of adaptive conformal inference (ACI) algorithms, traditional metrics such as the empirical coverage and the regret provide valuable insights into the overall performance of prediction intervals2. However, in the context of financial risk management, particularly concerning the estimation of risk measures in the tails of log-returns distributions, a more nuanced approach is required. Specifically, the focus is often directed towards assessing the quality of the estimated (tail) risk measures, such as quantiles (e.g., value at risk) or more comprehensive measures like the expected shortfall. Given the critical importance of accurately estimating tail risk, it is important to employ specialized evaluation techniques tailored to market risk measures. Consequently, backtesting procedures designed specifically for assessing the adequacy of these risk measures offer a more appropriate and rigorous means of evaluation in our case than the empirical coverage and the regret. An overview of the backtesting procedures employed in our empirical analysis is provided in Section 3.4.
3.2. ACI Algorithms: AgACI, FACI, SF-OGD, SAOCP
Aggregated ACI (AgACI) by Zaffran et al. (2022) resolves the challenge of selecting a suitable learning rate for ACI by executing multiple instances of the algorithm with varying learning rates. Subsequently, it combines the lower and upper interval bounds separately using an online aggregation-of-experts algorithm. Specifically, one aggregation algorithm aims to estimate the lower quantile, while the other targets the upper quantile. Zaffran et al. (2022) explored several online aggregation algorithms and observed similar outcomes. Therefore, we adopt their recommendation and utilize the Bernstein Online Aggregation (BOA) algorithm, implemented in the opera R package (Gaillard et al. 2023; Wintenberger 2017). BOA operates as an online algorithm, deriving predictions for the lower (or upper) prediction interval bound through a weighted average of candidate ACI prediction interval bounds, with weights determined by each candidate’s past performance concerning the quantile loss. Therefore, the prediction intervals produced by AgACI may not be symmetric around the point prediction, given the separate weights assigned to the lower and upper bounds. The primary parameter to tune in AgACI is the set of candidate learning rates . Susmann et al. (2023) suggest using the following learning rates: . Additionally, each candidate ACI algorithm requires a starting value for , which can be arbitrarily set to , as previously discussed. The AgACI algorithm is outlined in pseudo-code format in Appendix B, and it is implemented in the AdaptiveConformal R package; see Susmann et al. (2023) for more details. Finite sample bounds on the coverage error and the regret do not exist for the AgACI algorithm. Zaffran et al. (2022) performed a wide range of experiments on synthetic time series with different time dependence structures, showcasing the robustness of the AgACI algorithm and its superior performance compared to baseline methods. However, they noted at the conclusion of their paper that future research would involve a theoretical analysis of the aggregation algorithm, particularly to determine if the experimentally observed asymptotic validity holds.
Fully Adaptive Conformal Inference (FACI) by Gibbs and Candès (2022) was developed by the creators of the original ACI algorithm, in part to address the challenge of selecting the learning rate parameter . In this regard, FACI shares a similar objective with the AgACI algorithm, although it employs a slightly different approach. FACI also aggregates predictions from multiple instances of ACI, each executed with different learning rates. However, it differs in that it directly combines the estimated radii produced by each algorithm based on their pinball loss, employing an exponential reweighting scheme (Gradu et al. 2023). Unlike AgACI, FACI does not separately aggregate the upper and lower bounds of the intervals, and this enables the development of theoretical guarantees regarding the algorithm’s performance in a more straightforward manner. The FACI algorithm is outlined in pseudo-code format in Appendix C, and it is implemented in the AdaptiveConformal R package; see Susmann et al. (2023) for more details. The process of tuning hyperparameters involves selecting a time interval length to control the pinball loss, which can be arbitrarily chosen. For the hyperparameter , Gibbs and Candès (2022) advocate for the optimal choice . Determining the third hyperparameter poses a greater challenge. In the absence of distribution shifts, the optimal choice for is
where K is the number of multiple copies of the ACI algorithm with different learning rates. We remark that this solution is optimal only for the quantile interval constructor, where represents a quantile of previous nonconformity scores. Alternatively, Gibbs and Candès (2022) suggest learning in an online manner using the following update rule:
Both approaches for selecting yielded similar results in the empirical studies reported by Gibbs and Candès (2022). Following Susmann et al. (2023), we employed the former approach when the quantile interval construction function was selected, while we employed the latter approach for the linear interval construction function. Similar to AgACI, the grid for the learning parameter consists of values from the set . To establish a bound on the coverage error, Gibbs and Candès (2022) examined a slightly modified version of FACI in which is chosen randomly from the candidate with weights given by , instead of taking a weighted average. They ensure that this randomized version of FACI yields results very similar to the deterministic version. The coverage error result also assumes that hyperparameters can change over time, meaning and are specific to each time t, rather than being fixed. The authors demonstrate that the coverage error has the following specific bound, where and represent the smallest and largest learning rates in the grid, respectively:
Therefore, if both and converge to zero as , the coverage error will also converge to zero. Additionally, under mild distributional assumptions, they provide a type of short-term coverage error bound for arbitrary time spans, along with several regret bounds. For more details, we refer to Gibbs and Candès (2022).
Scale-Free Online Gradient Descent (SF-OGD) is a versatile algorithm for online learning, initially proposed by Orabona and Pál (2018). This algorithm involves updating through a gradient descent step, with the learning rate adapting to the scale of previously observed gradients. While SF-OGD was initially introduced within the context of adaptive conformal inference (ACI) as a sub-algorithm for SAOCP (outlined below), it has demonstrated strong performance on its own in real-world applications; see Bhatnagar et al. (2023). The SF-OGD algorithm is outlined in pseudo-code format in Appendix D, and it is implemented in the AdaptiveConformal R package; see Susmann et al. (2023) for more details. It is possible to show that the optimal selection for the learning rate is , where D represents the maximum possible radius. In cases where D is unknown, it can be estimated by employing an initial subset of the time series as a calibration set. D can then be estimated as the maximum of the absolute residuals between the observed log-returns and the corresponding forecasts (Bhatnagar et al. 2023; Orabona and Pál 2018). Bhatnagar et al. (2023) found a bound for the coverage error of this algorithm by showing that for any learning rate (where is optimal) and any starting value , then it holds that for any ,
We remark that the coverage bounds for SF-OGD and SAOCP below (which is a generalization of SF-OGD) are distribution-free; see Theorems 4.2 and 4.3 and their proofs in Bhatnagar et al. (2023) for the full details.
The Strongly Adaptive Online Conformal Prediction (SAOCP) algorithm by Bhatnagar et al. (2023) was introduced as an enhancement over existing ACI algorithms, offering more robust theoretical guarantees. SAOCP operates similarly to AgACI and FACI, using a set of candidate online learning algorithms to generate prediction intervals, which are subsequently aggregated using a meta-algorithm. While SF-OGD was chosen as the candidate algorithm, any algorithm with anytime regret guarantees can be employed. Unlike AgACI and FACI, where each candidate employs a distinct learning rate but contributes consistently to the final prediction intervals, SAOCP assigns identical learning rates to all candidates. However, each candidate is allocated positive weight over a specific time interval. To address rapid distribution shifts, new candidate algorithms are continuously introduced, ensuring swift adaptation and positive weighting for the most recent candidates. In essence, SAOCP functions as a meta-algorithm overseeing multiple experts, with each expert constituting an independent online learning algorithm responsible for its own active interval with a finite lifetime. At each time point t, a new expert is created, active over a finite “lifetime” that is defined as
where is a multiplier for the lifetime of each expert. Experts are weighted based on their empirical performance relative to the pinball loss function, resulting in intervals with robust regret guarantees. The SAOCP algorithm is outlined in pseudo-code format in Appendix E, and it is implemented in the AdaptiveConformal R package; see Susmann et al. (2023) for more details. The primary tuning parameter for SAOCP is the learning rate of the SF-OGD sub-algorithms, with the optimal choice established as , as discussed earlier. Bhatnagar et al. (2023) typically determine D by selecting the maximum residual from a calibration set. The second tuning parameter, which is the lifetime multiplier g, governs the duration of each expert’s lifetime. Following Bhatnagar et al. (2023), we set . Bhatnagar et al. (2023)—theorem 4.3—showed that a bound on the coverage error of SAOCP is given by
for any , and where is a technical measure of the smoothness of the cumulative gradients and expert weights for each of the candidate experts. For example, if there exists , then for some , and the previous bound becomes . Finally, we remark that the previous bound is distribution-free, and mild regularity assumptions on the distributions of the data are only required if we need to achieve approximately valid coverage on sub-interval of time. For more details, see theorem C.3 in Bhatnagar et al. (2023).
3.3. Benchmark Volatility Models for Daily Data
The GARCH(1,1) model remains a prominent benchmark model for computing market risk measures with daily data for several reasons. Firstly, it captures essential characteristics of financial time series, such as volatility clustering and time-varying volatility, which are commonly observed in real-world financial markets. Secondly, the GARCH(1,1) model is relatively parsimonious compared to other volatility models, requiring only a small number of parameters for estimation. Given its widespread use in academic research and industry practice, the GARCH(1,1) model serves as a natural reference competitor when evaluating the performance of alternative market risk models. Its inclusion as a benchmark ensures that the proposed models undergo rigorous comparison against a well-established and widely recognized standard, thus enhancing the robustness and credibility of the assessment process in risk management applications. Specifically, a simple GARCH(1,1) with constant mean and standardized errors following a symmetric Student’s t-distribution with degrees of freedom was used in this work to model the conditional variance of the log-returns :
More complex model specifications and error distributions were discarded because they resulted in much higher rates of numerical convergence failures; see Fantazzini (2022) and Fantazzini (2023) for similar evidence with crypto-assets. The complexity of estimating GARCH models and the necessity for sizable samples have been extensively documented in the literature. The seminal work by Fiorentini et al. (1996) highlighted the issues involved in GARCH model estimation, emphasizing the demand for large datasets. Furthermore, comprehensive simulation studies conducted by Hwang and Valls Pereira (2006), Fantazzini (2009), and Bianchi et al. (2011) underscored the requirement of a sample size ranging from 250 to 500 observations for obtaining reliable model estimates of basic GARCH models. For scenarios involving more complex data generating processes, even larger sample sizes were necessary to ensure robust estimation. For GARCH models with Student’s t errors, the calculation of the 1-day-ahead value at risk (VaR) at the probability level p using information up to time is as follows:
Here, represents the 1-day-ahead forecast of the conditional mean, denotes the 1-day-ahead forecast of the conditional variance, and denotes the inverse function of the Student’s t-distribution with estimated degrees of freedom at the probability level p. The term represents the scale parameter of the Student’s t-distribution.
The second benchmark volatility model that we consider in our analysis employs the daily range to estimate the daily conditional variance of the log-returns . The idea of using the price range has a rich history in both the academic and professional literature, starting from the 19th century; see Nison (1994) and references therein. Notably, volatility measures derived from the daily range emerged as efficient alternatives to return-based volatility estimators, as demonstrated by several authors, beginning with Parkinson (1980). Recent research has reignited interest in range-based estimators employing the open, high, low, and close (OHLC) prices for estimating daily volatility; see Patton (2011), Molnár (2012), Chou et al. (2015), and Fiszeder et al. (2019). Intriguingly, high-frequency volatility models have shown superior performance over low-frequency models using range-based estimators for short-term forecasts, typically one day ahead (Lyócsa et al. 2021). However, for longer forecast horizons, such as up to one month, the difference in forecast accuracy diminishes, particularly for most market indices. Moreover, Fantazzini (2023) conducted a comprehensive analysis on a dataset of over 2000 crypto-assets, evaluating their credit risk by computing their probability of “death”, and found that ZPP-based models using range-based volatility estimators were a better choice for long-term forecasts up to 1 year ahead (which is the standard horizon for credit risk management). Building on Molnár (2012) and Fantazzini (2023), we will adopt the Garman–Klass volatility estimator (Garman and Klass (1980)). This estimator has been shown to produce standardized returns that are normally distributed and yields estimates comparable to those obtained from high-frequency data. The Garman–Klass estimator assumes a Brownian motion with zero drift and no opening jumps. Nonetheless, for cases involving opening jumps, as seen with illiquid assets, the jump-adjusted Garman–Klass volatility estimator described in Molnár (2012) will be employed. The formula for the jump-adjusted Garman–Klass (GK) volatility estimator for the daily conditional variance of the log-returns is presented below:
To forecast the dynamics of range-based daily volatilities , we employed the heterogeneous autoregressive (HAR) model proposed by Corsi (2009), which posits that the daily volatility is influenced by past volatility over different time periods:
where , , and denote the daily, weekly, and monthly volatility components, respectively. We adjusted the time periods for weekly and monthly volatilities to 7 and 30 days, respectively, instead of the usual 5 and 22 days, to accommodate the continuous trading in cryptocurrency exchanges. We set the conditional mean of the log-returns to zero when using the Garman–Klass volatility estimator. Therefore, in the case of the HAR model with daily range data, the 1-day-ahead VaR can be computed as follows:
where denotes the inverse function of the normal distribution at the probability level p.
3.4. Backtesting Methods for Market Risk Measures
The assessment of different value-at-risk (VaR) models’ forecasting performance entails comparing the forecast VaR values against actual returns for each day. Initially, the process involves tallying the number of violations when the forecast VaR is lower than the actual losses, with , where denotes the absence of VaR violations. The unconditional coverage test developed by Kupiec (1995) verifies whether the fraction of actual violations, , is statistically significantly different from p%, so the null hypothesis is given by . This test employs the following likelihood ratio test statistic for the null hypothesis (Kupiec 1995):
The conditional coverage test by Christoffersen (1998) tests the joint null hypothesis concerning the accuracy of the average number of VaR violations and the independence of violations. This test can identify models forecasting an excessive or insufficient number of clustered violations, but it requires at least several hundred observations for accuracy. The test statistic is presented as follows:
where is the number of observations with value i followed by j for and denotes the corresponding probabilities.
In addition to the count of VaR violations, financial regulators are concerned with their magnitude. Thus, the asymmetric quantile loss (QL) function proposed by González-Rivera et al. (2004) was computed in our analysis:
where is the indicator function for the VaR exceedances. This function penalizes realized losses below the p-th quantile level more heavily, facilitating cost comparison among different choices.
The previous asymmetric quantile loss functions are then used by the model confidence set (MCS) by Hansen et al. (2011) to select the best VaR forecasting models at a specified confidence level. Given the differences between the QLs of models i and j at time t (expressed as ), the MCS approach is employed to evaluate the hypothesis of equal predictive capability, denoted as , for all in M, where M represents the set of forecasting models. The initial step involves the computation of the following t-statistics:
where is the simple loss of the i-th model relative to the average losses across models in the set M, measures the sample loss differential between models i and j, while is a bootstrapped estimate of . Subsequently, the T-max statistic is calculated as follows: . This statistic has a non-standard distribution, hence its distribution under the null hypothesis is determined via bootstrap methods involving 1000 replications. If the null hypothesis is rejected, one model is eliminated from the analysis, restarting the testing procedure anew; see Hansen et al. (2011) for more details.
Building upon an idea introduced by Emmer et al. (2015), Kratz et al. (2018) introduced a multinomial value-at-risk (VaR) test that implicitly evaluates the expected shortfall (ES) by approximating it with various VaR levels. Their approximation is defined as
where . A similar but more convenient approximation for the ES at the 2.5% level, as adopted by Basel III, was proposed by Wimmerstedt (2015) and Fantazzini and Shangina (2019):
Kratz et al. (2018) suggested using several VaR probability levels , where for , starting from a given level p. If represents the usual indicator function for a VaR violation at level and , then the sequence counts the number of VaR violations at level . Now, define as a multinomial distribution with T trials, each of which may result in one of outcomes with probabilities that sum to one, while the observed cell counts are defined by . Then, under the assumptions of unconditional coverage and independence, as in Christoffersen (1998), it can be shown that the random vector follows the multinomial distribution . Supposing that the estimated multinomial distribution is , where are the estimated distribution parameters, Kratz et al. (2018) consider the following null and alternative hypotheses:
The null hypothesis can be tested using various test statistics. We refer to Cai and Krishnamoorthy (2006) for a comprehensive simulation study on the exact size and power properties of five possible tests, three of which were later employed by Kratz et al. (2018). In our empirical analysis, we utilized the exact method, the fifth test statistic reviewed by Cai and Krishnamoorthy (2006), which computes the probability of a given outcome under the null hypothesis using the multinomial probability distribution itself:
Cai and Krishnamoorthy (2006) concluded that while the exact method performs well, it can be time-consuming for large numbers of cells N and sample sizes T. In such cases, simulation methods are preferable. For a comprehensive discussion on these backtesting methods and others, we refer to Fantazzini (2019), chap. 11.
3.5. Structure of the Empirical Analysis
In this study, we conduct a comprehensive empirical analysis to evaluate the performance and robustness of various methods for estimating market risk measures across a diverse set of cryptocurrencies. Our analysis consists of a baseline case that considers all assets, as well as a series of robustness checks to verify that the results for the baseline case also hold in different settings. It is structured as follows:
- Baseline case: All 4000 assets. In the baseline analysis, we included all 4000 cryptocurrencies in our dataset to provide a broad assessment of the methods under study. This diverse dataset allows us to capture a wide range of market behaviors and characteristics.
- Robustness check 1: Market capitalization of crypto-assets. We conducted a robustness check based on the market capitalization of the assets. Our dataset included daily market capitalization data for 2310 out of the 4000 assets. The remaining assets lacked these data, which may indicate transparency issues regarding their circulating supply. For a comprehensive analysis, we divided these 2310 assets into four groups of approximately equal size based on their market capitalization. The first group consists of assets with the highest market capitalization, while the fourth group includes those with the lowest capitalization.
- Robustness check 2: Time-series size. To examine the impact of time-series length on our results, we divided the assets into four groups according to the number of daily data points available. Each group contains approximately the same number of assets. The first group includes assets with the longest time series (ranging from 1613 to 4939 daily data points), and the fourth group includes assets with the shortest time series (ranging from 731 to 836 daily data points).
- Robustness check 3: Different forecasting methods. In the baseline case, we used a simple AR(1) model due to its ease of estimation and the generally weak mean dependence in crypto-assets’ log-returns. As a third robustness check, we evaluated the impact of using a more complex model specification with a robust estimation method. Specifically, we employed a single-hidden-layer neural network, utilizing seven lagged daily log-returns as inputs and three hidden units:Feed-forward neural networks with a single hidden layer are implemented in the nnet R package, and we refer to Venables and Ripley (2002), chapter 8, for the full theoretical details and the software implementation.
- Robustness check 4: Comparison with methods that predict quantiles directly. Engle and Manganelli (2004) proposed an alternative approach to quantile estimation that focuses on modeling the quantile directly rather than the entire distribution. They introduced a class of semi-parametric conditional autoregressive quantile models, known as CAViaR, which utilize quantile regression and mild distributional assumptions. These models have a structure similar to GARCH models and are formally defined as follows:where represents the p-quantile function associated with the conditional distribution of returns , , and and are the model parameters. The asymmetric slope model is specifically designed to capture the asymmetric leverage effect, which is the tendency for volatility to be higher following a negative return than a positive return of equal magnitude. The indirect GARCH(1,1) CAViaR model is correctly specified if the underlying data are generated by a GARCH(1,1) model with an independent and identically distributed innovation process. The adaptive specification adjusts to past errors to minimize the probability of consecutively underestimating the VaR. The CAViaR parameters are estimated using the quantile regression minimization technique introduced by Koenker and Bassett (1978):where is the vector of parameters to be estimated, while I is the indicator function. When the quantile model is linear, this minimization can be formulated as a linear programming problem, for which the dual problem is conveniently solved. For this reason, and due to past empirical evidence, such as that provided by Abad et al. (2014) and references therein, we will use only the symmetric absolute value (SAV) model3. Moreover, given the computational burden of estimating the model for each quantile, we will limit our analysis to a selected group of crypto-assets: the two most capitalized assets (Bitcoin and Ethereum) and the two least capitalized assets (Bubble and Litecoin-Token) for which all models achieved numerical convergence.
The aim of this structure is to ensure that our empirical analysis is thorough and considers various factors that may influence the performance of the risk estimation methods.
4. Results
4.1. Data
Our study analyzed a dataset comprising 4000 crypto-assets spanning from July 2010 to January 2024. We obtained all assets, freely available from https://coinmarketcap.com/, in January 2024, ensuring that each had a time series consisting of at least 730 daily data points. We made this selection to ensure that all models used in our analysis had a minimum of one year’s worth of data for initial training and calibration. The dataset included daily open, high, low, and close prices, as well as traded volume and market capitalization. Initially, we downloaded a dataset comprising 4003 assets. However, three assets were excluded due to their close prices remaining at zero throughout the entire time span, rendering them unusable. Additionally, approximately a dozen assets exhibited unusual reported prices in the weeks preceding their delisting from coinmarketcap.com. These anomalous trading days were excluded from our analysis to maintain its integrity. The names of the 4000 crypto assets used in our analysis are listed in Table A1, Table A2, Table A3, Table A4, Table A5, Table A6, Table A7 and Table A8 in Appendix F.
The first 365 daily observations were used to initialize the estimation of the GARCH model, with log-returns computed using the closing prices. For the HAR model, the daily range was estimated using the open, high, low, and close prices. Similarly, for the training and calibration of ACI models, log-returns were computed using the closing prices. An expanding window approach was then employed for the GARCH and HAR models, where one day of data was added incrementally to the initial sample. The models were re-estimated with the expanded dataset, and the value at risk (VaR) for the next day was computed. The ACI models were trained incrementally, one data point at a time, as detailed in the algorithms provided in Appendix B, Appendix C, Appendix D and Appendix E.
In our study, we utilize a dataset comprising 4000 cryptocurrencies, covering a wide range of market conditions and asset characteristics. This extensive dataset includes not only the most capitalized cryptocurrencies, like Bitcoin and Ethereum, but also those with lower capitalization and liquidity. The rationale behind this comprehensive approach is twofold. First, it allows us to assess the performance of ACI methods across a diverse set of assets, which is essential for understanding the general applicability and robustness of these methods. Second, by including a wide variety of cryptocurrencies, we can identify specific challenges and opportunities associated with different types of assets. This approach enables us to draw more nuanced and actionable insights that are relevant to a broader audience, including investors, portfolio managers, and regulators. Our analysis thus provides a detailed examination of market risk measures across the full spectrum of the cryptocurrency market, ensuring that our conclusions are both robust and broadly applicable.
As outlined in the previous section, we calculated the value at risk (VaR) across five probability levels (, , , , ) for the log-returns of each asset. This enabled us to conduct an approximate backtesting of the expected shortfall (ES) at the 2.5% level, a metric included in the Basel III agreement. While our primary focus was on the left tail of the distribution, given its significance in financial risk management, we also computed five quantiles for the right tail (, , , , ) to ensure comprehensiveness and generality.
For the ACI models, we opted to employ a simple AR(1) model to capture the dynamics of the crypto-assets’ log-returns. Although we initially attempted to utilize the Hyndman and Khandakar Hyndman and Khandakar (2008) algorithm for automatic selection of the optimal ARIMA model4, this approach encountered challenges, particularly with extremely volatile crypto-assets possessing relatively short time series (fewer than 1000 observations). Consequently, we reverted to employing a straightforward AR(1) model. In this regard, it is worth noting that the mean dependence of crypto-assets’ log-returns is generally weak. Nevertheless, as part of our robustness checks, we will examine the impact on our results when employing a more complex model specification with a robust estimation method.
4.2. Baseline Case: All 4000 Assets
In this section, we present the results of our comprehensive evaluation of value-at-risk (VaR) forecasting models applied to a dataset comprising 4000 crypto assets. Our analysis includes four adaptive conformal inference (ACI) models, one generalized autoregressive conditional heteroskedasticity (GARCH) model, and one heterogeneous autoregressive (HAR) model using daily range volatilities.
Our evaluation begins with an examination of the performance of each model using the Kupiec (1995) test, the Christoffersen (1998) test, and the multinomial VaR test by Kratz et al. (2018); see Table 1. Across all quantiles, we observed that the ACI models generally performed well, with FACI and SF-OGD emerging as the most effective models. However, AgACI and SAOCP, while providing accurate estimates for extreme quantiles ( and ), were too conservative when estimating quantiles between 1% and 2.5%, with less violations than expected. In the right tail of the distribution, AgACI demonstrated better results, in line with the FACI and SF-OGD algorithms. According to the multinomial VaR test, FACI and SF-OGD were able to properly model the left and right tails of the distribution for the vast majority of crypto-assets (approximately 90% of assets), followed by AgACI (approximately 80%), while SAOCP had the worst performance among ACI algorithms, with only approximately 50% of assets where the multinomial VaR test was not rejected at the 5% probability level.
Table 1.
Average number of violations in % across all assets for each quantile; % of times the Christoffersen conditional coverage (CC) test was not rejected at the 5% probability level across all assets for each quantile; % of times the Kupiec unconditional coverage (UC) test was not rejected at the 5% probability level across all assets for each quantile. The last column shows the % of times the multinomial VaR test by Kratz et al. (2018) was not rejected at the 5% probability level across all assets, for the five quantiles in the left tail (ES_2.5_test) and in the right tail (ES_97.5_test), respectively. The results for the GARCH and HAR models only include assets for which numerical convergence was achieved.
Differently from the ACI algorithms, the GARCH and HAR models faced challenges in achieving numerical convergence for approximately 2.5% of assets (96 and 104 assets, respectively), particularly those with extreme variability and/or relatively small datasets (). Despite this, GARCH served as a reliable benchmark model, slightly underestimating VaR for the most extreme quantiles () while maintaining accuracy for the other quantiles. Instead, the HAR model with daily range volatilities proved to be the least effective, underestimating lower quantiles up to , and severely overestimating higher quantiles. Similar problems emerged also for the right tail of the distribution. According to the multinomial VaR test, the GARCH model was able to model the left and right tails of the distribution for approximately 70% of assets, whereas for the HAR model this was approximately 20% of assets, thus confirming the previous problems with the tests for the single quantiles.
To identify the best VaR forecasting models, we utilized the asymmetric quantile loss (QL) function proposed by González-Rivera et al. (2004) and employed the model confidence set (MCS) method by Hansen et al. (2011); see Table 2 and Table 3. Notably, we considered only assets for which all six models reached numerical convergence. Such a choice clearly penalized ACI models, which were able to estimate quantiles for all assets, whereas this was not the case for GARCH and HAR models. Nevertheless, given that financial regulators are concerned not only with the number of VaR violations but also with their magnitude, we also compared the models using the asymmetric quantile loss and the MCS.
Table 2.
Average rank of the models across all assets for each quantile based on the asymmetric quantile loss (QL) function proposed by González-Rivera et al. (2004).
Table 3.
Number of times (in %) when the model was included into the model confidence set (MCS) at the 10% confidence level across all assets.
Our analysis reveals that the GARCH model consistently emerged as the top-ranked model for the majority of assets and was almost always included in the MCS. This underscores the enduring relevance of the GARCH(1,1) model with a Student’s t-distribution in finance when using daily data, even nearly four decades after it was originally proposed.
While ACI models demonstrated proficiency in estimating quantiles for most assets, they exhibited challenges in estimating the most extreme quantiles ( and ), particularly the AgACI and FACI models that showed rather large asymmetric losses and lower ranking. However, the SF-OGD and SAOCP models displayed greater precision with smaller losses. These findings have significant implications for financial risk management: while a traditional benchmark like the GARCH model remains relevant, newer approaches such as ACI models offer promising alternatives, particularly for assets with complex dynamics such as crypto-assets, albeit with some caveats in extreme quantile estimation. Given that ACI models are more precise in terms of VaR violations, while GARCH models are better in terms of asymmetric quantile losses, forecasting combinations are a possibility. We leave this interesting issue as an avenue for further research.
4.3. Robustness Check 1: Market Capitalization of Crypto-Assets
In this section, we examined the 2310 assets with daily market capitalization data and categorized them into four groups, each containing approximately the same number of assets. The first group comprises assets with the highest market capitalization in dollars, while the fourth group consists of assets with the lowest capitalization.
We computed the Kupiec (1995) test, the Christoffersen (1998) test, and the multinomial VaR test by Kratz et al. (2018) for each group, with the results presented in Table 4 and Table 5.
Table 4.
Backtesting results based on market capitalization (first 2 groups): Average number of violations in % across all assets for each quantile; % of times the Christoffersen conditional coverage (CC) test was not rejected at the 5% probability level across all assets for each quantile; % of times the Kupiec unconditional coverage (UC) test was not rejected at the 5% probability level across all assets for each quantile. The last column shows the % of times the multinomial VaR test by Kratz et al. (2018) was not rejected at the 5% probability level across all assets, for the five quantiles in the left tail (ES_2.5_test) and in the right tail (ES_97.5_test), respectively.
Table 5.
Backtesting results based on market capitalization (last 2 groups): Average number of violations in % across all assets for each quantile; % of times the Christoffersen conditional coverage (CC) test was not rejected at the 5% probability level across all assets for each quantile; % of times the Kupiec unconditional coverage (UC) test was not rejected at the 5% probability level across all assets for each quantile. The last column shows the % of times the multinomial VaR test by Kratz et al. (2018) was not rejected at the 5% probability level across all assets, for the five quantiles in the left tail (ES_2.5_test) and in the right tail (ES_97.5_test), respectively.
The empirical analysis broadly confirms the findings of the baseline case. However, it reveals that the performance of the GARCH model and, to a lesser extent, the SAOCP algorithm deteriorated significantly when focusing on assets with the lowest market capitalization. It appears that the extreme volatility of this asset class strongly impacted the numerical stability of these models. As a result, the GARCH model exhibited too many VaR violations, while the SAOCP model demonstrated too few.
It is well known that crypto-assets with lower market capitalization tend to experience higher levels of volatility. This heightened volatility can pose challenges for several modeling approaches, which may struggle to adequately capture and predict extreme movements in these assets’ prices. As such, future research could explore alternative modeling techniques specifically tailored to address the unique characteristics and dynamics of lower-capitalization crypto-assets, potentially enhancing the accuracy and robustness of risk management strategies in this segment of the market.
4.4. Robustness Check 2: Time-Series Size
As a second robustness check, we divided our assets into four groups based on the size of their time series, with each group containing approximately the same number of assets. The first group encompasses assets with the longest time series, ranging from 1613 daily data points to 4939 daily data points, while the fourth group comprises assets with the shortest time series, ranging from 731 daily data points to 836 daily data points.
We computed the Kupiec (1995) test, the Christoffersen (1998) test, and the multinomial VaR test by Kratz et al. (2018) for each group, with the results presented in Table 6 and Table 7.
Table 6.
Backtesting results based on time-series size (first 2 groups): Average number of violations in % across all assets for each quantile; % of times the Christoffersen conditional coverage (CC) test was not rejected at the 5% probability level across all assets for each quantile; % of times the Kupiec unconditional coverage (UC) test was not rejected at the 5% probability level across all assets for each quantile. The last column shows the % of times the multinomial VaR test by Kratz et al. (2018) was not rejected at the 5% probability level across all assets, for the five quantiles in the left tail (ES_2.5_test) and in the right tail (ES_97.5_test), respectively.
Table 7.
Backtesting results based on time-series size (last 2 groups): Average number of violations in % across all assets for each quantile; % of times the Christoffersen conditional coverage (CC) test was not rejected at the 5% probability level across all assets for each quantile; % of times the Kupiec unconditional coverage (UC) test was not rejected at the 5% probability level across all assets for each quantile. The last column shows the % of times the multinomial VaR test by Kratz et al. (2018) was not rejected at the 5% probability level across all assets, for the five quantiles in the left tail (ES_2.5_test) and in the right tail (ES_97.5_test), respectively.
The empirical analysis broadly confirms the findings of the baseline case. However, it unveils some intriguing trends: AgACI, FACI, and SF-OGD exhibit consistent performances across time series of varying lengths. Instead, GARCH models seem to perform best with time series close to 1000 observations. Assets with longer time series exhibit a higher number of VaR exceedances than expected, particularly in the extreme left tail, likely attributed to significant structural breaks. Conversely, shorter time series exhibit slightly inferior performance, likely due to relatively small datasets that are insufficient for accurate parameter estimation.
SAOCP and the HAR model with daily range data perform notably better with time series containing fewer than 1000 observations compared to longer time series. It appears that these methods are more sensitive to structural breaks, which occur more frequently in assets with longer time series. This evidence indirectly corroborates the simulation studies conducted by Susmann et al. (2023), which demonstrated that SAOCP (and to some extent, SF-OGD) tend to underestimate the quantiles when faced with a distributional shift. A notable departure from the findings of Susmann et al. (2023) is that the simple SF-OGD model turned out to be pretty robust across all time samples: despite showing slightly inferior performances compared to the FACI algorithm for very long time series, these differences were mostly statistically insignificant in terms of quantile losses (not reported). Moreover, SF-OGD emerged as the top-performing model for the shortest time series.
This evidence underscores the importance of considering both the length of the time series and the model’s sensitivity to structural breaks when selecting appropriate risk forecasting methods. Future research could delve deeper into understanding the mechanisms underlying these performance disparities and explore potential refinements to enhance the accuracy and robustness of risk predictions across diverse time-series lengths.
4.5. Robustness Check 3: Different Forecasting Methods
As a third robustness check, we wanted to assess the impact on our results by employing a more complex model specification than an AR(1) model, namely, a single-hidden-layer neural network using seven lagged daily log-returns as inputs and three hidden units.
We computed the Kupiec (1995) test, the Christoffersen (1998) test, and the multinomial VaR test by Kratz et al. (2018) for the four ACI algorithms using the neural network as the forecasting model, and the results are presented in Table 8. We also computed the asymmetric QL function proposed by González-Rivera et al. (2004) and employed the MCS method by Hansen et al. (2011); see Table 9 and Table 10. Similarly to the baseline case, we considered only assets for which all six models reached numerical convergence.
Table 8.
Average number of violations in % across all assets for each quantile using a neural network; % of times the Christoffersen conditional coverage (CC) test was not rejected at the 5% probability level across all assets for each quantile; % of times the Kupiec unconditional coverage (UC) test was not rejected at the 5% probability level across all assets for each quantile. The last column shows the % of times the multinomial VaR test by Kratz et al. (2018) was not rejected at the 5% probability level across all assets, for the five quantiles in the left tail (ES_2.5_test) and in the right tail (ES_97.5_test), respectively.
Table 9.
Average rank of the models across all assets for each quantile based on the asymmetric quantile loss (QL) function proposed by González-Rivera et al. (2004). ACI algorithms use a neural network.
Table 10.
Number of times (in %) when the model was included into the model confidence set (MCS) at the 10% confidence level across all assets. ACI algorithms use a neural network.
In terms of VaR violations, there are no notable differences among the models, except for SAOCP, where the number of instances where the Christoffersen test, the Kupiec test, and the multinomial VaR test did not reject the null hypothesis was 5–12% lower than the baseline case. This evidence suggests that the more volatile mean forecasts computed using a neural network penalized this algorithm. A similar phenomenon, albeit on a smaller scale (3–5% lower), was also observed for the AgACI algorithm.
Regarding quantile loss functions, all four ACI algorithms were strongly penalized in terms of average ranking, with SAOCP exhibiting the largest decline in ranking across all competing models. Likewise, all four ACI algorithms demonstrated a decrease in the percentage of times the models were included in the model confidence set (20–30% lower), particularly affecting the left tail of the distribution.
In general, employing a more complex forecasting model for the mean of the assets’ log-returns with ACI algorithms did not result in more precise risk estimates. This outcome can probably be attributed to the lower model bias being outweighed by the higher variance in the model estimates. These findings underscore the intricate trade-offs involved in selecting forecasting models for risk management purposes, highlighting the importance of considering both model complexity and estimation accuracy in decision-making processes.
4.6. A Comparison with Methods That Predict Quantiles Directly
As a fourth robustness check, we employed the symmetric absolute value (SAV)-CAViaR model with a selected group of crypto-assets: the two most capitalized assets (Bitcoin and Ethereum) and the two least capitalized assets (Bubble and Litecoin-Token) for which all models achieved numerical convergence. The plots of the prices of these four crypto-assets are reported in Figure 1, while the main descriptive statistics of their log-returns are shown in Table 11.
Figure 1.
Plots of the prices of four crypto-assets: Bitcoin, Ethereum, Bubble, Litecoin-Token.
Table 11.
Log-returns’ main descriptive statistics: Bitcoin, Ethereum, Bubble, Litecoin-Token.
We computed the Kupiec (1995) test, the Christoffersen (1998) test, and the multinomial VaR test by Kratz et al. (2018) for the four ACI algorithms using the AR(1) as the forecasting model, for the GARCH model with Student’s t errors, for the HAR model with the daily range, and for the CAViaR-SAV model. We also computed the asymmetric QL function proposed by González-Rivera et al. (2004) and employed the MCS method by Hansen et al. (2011). The results for Bitcoin and Ethereum are presented in Table 12, while for Bubble and Litecoin-Token they are presented in Table 13.
Table 12.
Number of VaR violations in % across Bitcoin and Ethereum for each quantile and model; p-values in % for the Christoffersen conditional coverage (CC) test; p-values in % for the Kupiec unconditional coverage (UC) test; asymmetric quantile loss (QL) function by González-Rivera et al. (2004); the model was included in the model confidence set (MCS): yes or no; p-values in % for the multinomial VaR test by Kratz et al. (2018), for the five quantiles in the left tail (ES_2.5_test) and in the right tail (ES_97.5_test), respectively.
Table 13.
Number of VaR violations in % across Bubble and Litecoin-Token for each quantile and model; p-values in % for the Christoffersen conditional coverage (CC) test; p-values in % for the Kupiec unconditional coverage (UC) test; asymmetric quantile loss (QL) function by González-Rivera et al. (2004); the model was included in the model confidence set (MCS): yes or no; p-values in % for the multinomial VaR test by Kratz et al. (2018), for the five quantiles in the left tail (ES_2.5_test) and in the right tail (ES_97.5_test), respectively.
In terms of VaR violations, all four ACI algorithms were able to properly model both the left and right tails of the return distributions, with the exception of SAOCP, which continued to show issues when modeling the right tail of the distribution. The GARCH model worked well with Ethereum but was unable to correctly estimate the quantiles for Bitcoin and the assets with the lowest capitalization. The HAR model performed the worst across all assets, while the CAViaR model passed all coverage tests for the left tail of the assets with the highest market capitalization but failed the tests for the right tail and for the assets with the lowest capitalization.
Regarding quantile loss functions, the GARCH model generally exhibited the lowest asymmetric loss functions for Bitcoin and Ethereum, followed by the CAViaR model and the ACI models. However, the GARCH model showed the worst losses (along with the HAR model) for the assets with the lowest market capitalization, whereas the ACI methods performed the best. This confirms that the extreme volatility of these types of assets strongly impacts their numerical stability. Interestingly, the CAViaR model demonstrated remarkably low losses across all assets, indicating its greater computational robustness compared to the GARCH and HAR models. It is important to note that in most instances, the differences between the models’ losses were not statistically significant, resulting in the vast majority of the considered models being included in the model confidence set.
In summary, while traditional models like GARCH and HAR exhibit strengths and weaknesses across different assets, the adaptive nature of ACI methods, particularly their robustness in highly volatile markets, highlights their potential as valuable tools in financial risk management. The CAViaR model’s consistent performance across various assets further underscores its reliability, making it an interesting alternative to more conventional approaches.
5. Discussion and Conclusions
This paper compared the performance of four adaptive conformal inference (ACI) algorithms with traditional volatility models for daily data, such as GARCH models and daily range models, in computing the value at risk (VaR) at various probability levels for 4000 crypto-assets observed between 2010 and 2024. Additionally, this comparison indirectly assessed the quality of the models’ expected shortfall (ES) by using a multinomial test of VaR violations across multiple levels as a means of backtesting the ES, as proposed by Kratz et al. (2018).
To achieve this objective, we employed four ACI algorithms, including Aggregated ACI by Zaffran et al. (2022), Fully Adaptive Conformal Inference by Gibbs and Candès (2022), Scale-Free Online Gradient Descent by Bhatnagar et al. (2023), and Strongly Adaptive Online Conformal Prediction by Bhatnagar et al. (2023). These algorithms, explicitly designed to address scenarios where data arrive sequentially, dynamically adjust the width of prediction intervals in response to observed data, thereby providing adaptive and accurate uncertainty quantification. As benchmark models for daily data, we used the GARCH(1,1) model with a symmetric Student’s t-distribution for the standardized errors and the daily range volatilities computed using the Garman–Klass estimator together with an HAR model.
In terms of VaR violations across all quantiles, FACI and SF-OGD were able to properly model the left and right tails of the distribution for the vast majority of crypto-assets, followed by AgACI, while SAOCP exhibited the poorest performance among the ACI algorithms. Conversely, the GARCH and HAR models faced challenges in achieving numerical convergence for approximately 2.5% of assets, particularly those with extreme variability and/or relatively small datasets (). Despite this, GARCH served as a reliable benchmark model, slightly underestimating the VaR for the most extreme quantiles () while maintaining accuracy for the other quantiles. In contrast, the HAR model with daily range volatilities proved to be the least effective, underestimating lower quantiles by up to and severely overestimating higher quantiles. Similar issues emerged for the right tail of the distribution.
Regarding asymmetric quantile loss functions, our analysis revealed that the GARCH model consistently emerged as the top-ranked model for the majority of assets and was almost always included in the model confidence set. While ACI models demonstrated proficiency in estimating quantiles for most assets, they exhibited challenges in estimating the most extreme quantiles ( and ), particularly the AgACI and FACI models, which showed rather large asymmetric losses and lower rankings. However, the SF-OGD and SAOCP models displayed greater precision with smaller losses.
These findings have significant implications for financial risk management: while a traditional benchmark like the GARCH model remains relevant, newer approaches such as ACI models offer promising alternatives, particularly for assets with complex dynamics such as crypto-assets, albeit with some caveats in extreme quantile estimation. Given that ACI models are more precise in terms of VaR violations, while GARCH models are better in terms of asymmetric quantile losses, forecasting combinations are a possibility, and we leave this issue as an avenue for further research.
Finally, we performed a set of robustness checks to verify that our results also held with different settings. In terms of market capitalization of crypto-assets, the results were similar to the baseline case. However, we found that the performance of the GARCH model and, to a lesser extent, the SAOCP algorithm deteriorated significantly when focusing on assets with the lowest market capitalization. It is well known that crypto-assets with lower market capitalization tend to experience higher levels of volatility. This heightened volatility can pose challenges for several modeling approaches, which may struggle to adequately capture and predict extreme movements in these assets’ prices. As such, future research could explore alternative modeling techniques specifically tailored to address the unique characteristics and dynamics of lower-capitalization crypto-assets, potentially enhancing the accuracy and robustness of risk management strategies in this segment of the market.
As a second robustness check, we divided our assets into four groups based on the size of their time series: AgACI, FACI, and SF-OGD exhibited consistent performances across time series of varying lengths. Instead, GARCH models seemed to perform best with time series close to 1000 observations. SAOCP and the HAR model with daily range data performed notably better with time series containing fewer than 1000 observations compared to longer time series. It appears that these methods are more sensitive to structural breaks, which occur more frequently in assets with longer time series. This evidence indirectly corroborates the simulation studies conducted by Susmann et al. (2023), which demonstrated that SAOCP tends to underestimate the quantiles when faced with a distributional shift. This evidence underscores the importance of considering both the length of the time series and the model’s sensitivity to structural breaks when selecting appropriate risk forecasting methods. Future research could delve deeper into understanding the mechanisms underlying these performance disparities and explore potential refinements to enhance the accuracy and robustness of risk predictions across diverse time-series lengths.
As a third robustness check, we assessed the impact on our results of employing a single-hidden-layer neural network instead of a simple AR(1) like in the baseline case. In terms of VaR violations, there are no notable differences among the models (except for SAOCP), while regarding quantile loss functions all four ACI algorithms were strongly penalized in terms of average ranking, with SAOCP exhibiting the largest decline in ranking across all competing models. In general, employing a more complex forecasting model for the mean of the assets’ log-returns with ACI algorithms did not result in more precise risk estimates. This outcome can probably be attributed to the lower model bias being outweighed by the higher variance in the model estimates. These findings underscore the intricate trade-offs involved in selecting forecasting models for risk management purposes, highlighting the importance of considering both model complexity and estimation accuracy in decision-making processes.
As a fourth robustness check, we tested the symmetric absolute value (SAV)-CAViaR model with four crypto-assets, including the most and least capitalized. The ACI algorithms effectively modeled both tails of the return distributions, except for SAOCP on the right tail. The GARCH model performed well for Ethereum but struggled with Bitcoin and low-capitalization assets. The HAR model performed the worst, while the CAViaR model passed coverage tests for the left tail of high-capitalization assets but failed for the right tail and low-capitalization assets. The GARCH model had the lowest asymmetric losses for Bitcoin and Ethereum but performed poorly for low-capitalization assets, where the ACI methods excelled. Overall, the ACI methods demonstrated robustness in highly volatile markets, and the CAViaR model showed consistent performance, making it a reliable alternative to traditional approaches.
The general recommendation for investors that emerges from our analysis is to utilize the Fully Adaptive Conformal Inference (FACI) and the Scale-Free Online Gradient Descent (SF-OGD) algorithms. These algorithms exhibit remarkable precision in providing VaR estimates across all examined quantiles, applicable to various types of crypto-assets and different market conditions. The risk estimates offered by these ACI algorithms can then be compared or even combined with those from traditional GARCH models, especially considering the latter’s proficiency in offering small asymmetric quantile losses, provided a large dataset is available. We leave this issue as an avenue for future research. We note that while GARCH(1,1) is a parsimonious and analytically appealing model, its performance is highly dependent on the size and characteristics of the data sample. Our study found that GARCH(1,1) faces computational difficulties and often fails to achieve numerical convergence for smaller datasets (fewer than 1000 observations). Furthermore, for longer datasets, the model struggles with structural breaks, leading to suboptimal performance, particularly in the extreme parts of the left tail of the distribution, as observed with Bitcoin. In contrast, the ACI algorithms offer several advantages. They are computationally more efficient and robust across a wider range of dataset sizes, from small to medium. This makes them particularly suitable for crypto-assets, which often have limited historical data or exhibit high volatility. The ACI models dynamically adjust to new data, providing more accurate and adaptive risk estimates without the computational burdens associated with GARCH models. Additionally, the simplicity and speed of ACI models enhance their tractability, making them more practical for real-time risk management and forecasting in the fast-evolving cryptocurrency market. While GARCH(1,1) remains valuable for its analytical properties and its capacity to support further financial modeling, such as deriving explicit asset valuation formulas, the ACI models fill an important gap by offering robust performance and computational efficiency across various market conditions and data constraints. Therefore, incorporating ACI models into risk management frameworks provides a complementary approach, leveraging their strengths in scenarios where traditional models like GARCH may falter.
An important limitation of this paper is the reliance on time series consisting of at least 730 daily data points, ensuring each model had a minimum of one year’s worth of data for initial training and calibration. This condition inevitably excluded a significant number of young crypto-assets, thereby restricting the depth of our analysis. One potential solution could involve utilizing high-frequency data if available, although alternative approaches should also be explored. Further research endeavors could address these limitations by incorporating additional data sources, exploring alternative model specifications, and examining the performance of forecasting models across varying time horizons and market conditions. This would enhance the robustness and applicability of risk management strategies in the dynamic landscape of crypto-assets.
As a final note, we wish to underscore that our findings align with the existing literature, highlighting the necessity of robust risk management frameworks for crypto-assets. For instance, Liu et al. (2020) emphasize the challenges and rewards of investing in cryptocurrencies, suggesting that value-at-risk (VaR) forecasting can benefit from parsimonious models. Although they discuss models under the generalized autoregressive score (GAS) framework, our study similarly finds that simpler models, such as GARCH, remain highly relevant and effective for VaR forecasting in specific scenarios. This resonates with Liu et al. (2020)’s assertion that more elaborate models do not always outperform simpler alternatives, particularly when considering the varying dynamics of crypto-assets. Trucíos and Taylor (2023) further contribute to the discourse by comparing various advanced risk forecasting methods, including long-memory processes and quantile regression-based models, and highlighting the efficacy of certain models for specific cryptocurrencies. Their exploration of the robustness of these models during turbulent periods, such as the COVID-19 pandemic, parallels our findings that no single model universally outperforms others. Additionally, their investigation into forecast combination strategies aligns with our suggestion that combining traditional models like GARCH with ACI approaches could enhance predictive performance. Müller et al. (2022) introduce the concept of range value at risk (RVaR) and demonstrate that GARCH models with various error distributions can effectively forecast RVaR for major cryptocurrencies. Our study corroborates their observation that non-normal distributions are often more suitable for VaR and expected shortfall (ES) predictions, reinforcing the notion that the choice of model and distribution significantly impacts the accuracy of risk measures and that simple volatility models, such as GARCH with a Student’s t-distribution, can produce accurate risk forecasts. Alexander and Dakos (2023) provide one of the most comprehensive reviews of the cryptocurrency risk forecasting literature, advocating for the practical application of relatively simple models over more complex alternatives. Their extensive backtesting with hourly and daily data reveals that models capturing asymmetric volatility and heavy-tailed distributions are just as effective as more sophisticated models. Our results echo this sentiment, demonstrating that models like FACI and SF-OGD can achieve reliable forecasts for crypto-assets without the need for overly computationally complex specifications, thus addressing the practical constraints faced by investors.
In conclusion, our study situates itself within the broader context of the cryptocurrency risk forecasting literature, aligning with key findings from Liu et al. (2020), Müller et al. (2022), Trucíos and Taylor (2023), and Alexander and Dakos (2023). By validating the efficacy of newer ACI models and recognizing the conditions under which they excel, our research contributes to a nuanced understanding of risk management in the cryptocurrency market. Future research should continue to explore the interplay between model complexity, data availability, and forecasting accuracy to develop robust risk management strategies that can withstand the unique challenges posed by crypto-assets.
Funding
This research received no external funding.
Data Availability Statement
The original data presented in the study were downloaded from the website https://coinmarketcap.com. However, the free web API used for this task is not longer available since early 2024, and a registration is required.
Conflicts of Interest
The author declares no conflicts of interest.
Appendix A. The Original Adaptive Conformal Inference (ACI) Algorithm
| Input: starting value , user-specified learning rate . for do Output: prediction interval . Observe . Evaluate . Update . end for |
Appendix B. The Aggregated Adaptive Conformal Inference (AgACI) Algorithm
| Input: candidate learning rates , starting value . Initialize lower and upper BOA algorithms: . for do Initialize ACI = ACI . end for for do for do Retrieve candidate prediction interval from . end for Compute aggregated lower bound . Compute aggregated upper bound . Output: prediction interval . Observe . for do Update with log-return . end for Update with observed log-return . Update with observed log-return . end for |
Appendix C. The Fully Adaptive Conformal Inference (FACI) Algorithm
| Input: starting value , candidate learning rates , parameters . for do Initialize expert = ACI ). end for for do Define the probabilities , for all . Set . Output: prediction interval . Observe the log-return and compute . , for all . Set for do Update ACI with and obtain end for end for |
Appendix D. The Scale-Free Online Gradient Descent (SF-OGD) Algorithm
| Input: starting value , learning rate . for do Output: prediction interval Observe the log-return and compute Update end for |
Appendix E. The Strongly Adaptive Online Conformal Prediction (SAOCP) Algorithm
| Input: initial value , learning rate . for do Initialize expert = SF-OGD , set weight Compute active set Active(t) (see below for definition of ), Compute prior probability Active. Compute un-normalized probability for all Normalize if , else . Set (for ), and for Output: prediction set . Observe log-return and compute . for Active(t) do Update expert with and obtain Compute Update expert weight end for end for |
Appendix F. List of Crypto-Assets’ IDs and Names
Table A1.
Names and crypto-assets’ coinmarketcap.com IDs: 1–500.
Table A2.
Names and crypto-assets’ coinmarketcap.com IDs: 501–1000.
Table A3.
Names and crypto-assets’ coinmarketcap.com IDs: 1001–1500.
Table A4.
Names and crypto-assets’ coinmarketcap.com IDs: 1501–2000.
Table A5.
Names and crypto-assets’ coinmarketcap.com IDs: 2001–2500.
Table A6.
Names and crypto-assets’ coinmarketcap.com IDs: 2501–3000.
Table A7.
Names and crypto-assets’ coinmarketcap.com IDs: 3001–3500.
Table A8.
Names and crypto-assets’ coinmarketcap.com IDs: 3501–4000.
Notes
| 1 | The ES is the average of the worst p losses, where p is the percentile of the returns distribution. |
| 2 | The empirical coverage is the proportion of log-returns that fell within the corresponding prediction intervals, while the regret is the difference between the cumulative pinball loss given by a sequence versus the cumulative loss of the best possible fixed choice. Gibbs and Candès (2021) demonstrated that for all , the ACI algorithm has the following finite sample bound on the coverage error (i.e., the difference between the empirical coverage and the nominal coverage): . This indicates that the coverage error is guaranteed to converge to zero for any choice of as T increases. Additionally, a similar bound exists for the regret, providing further insights into the algorithm’s performance. For more comprehensive details, we refer to Gibbs and Candès (2021). |
| 3 | The R code using optimized C++ routines to estimate the CAViaR model can be found at https://github.com/Buczman/CaviaR (accessed on 15 April 2024). |
| 4 | The algorithm is implemented in the R (version 4.3.1) package forecast (version 8.22.0). |
References
- Abad, Pilar, Sonia Benito, and Carmen López. 2014. A comprehensive review of value at risk methodologies. The Spanish Review of Financial Economics 12: 15–32. [Google Scholar] [CrossRef] [Scilit]
- Alexander, Carol, and Michael Dakos. 2023. Assessing the accuracy of exponentially weighted moving average models for value-at-risk and expected shortfall of crypto portfolios. Quantitative Finance 23: 393–427. [Google Scholar] [CrossRef] [Scilit]
- Angelopoulos, Anastasios, and Stephen Bates. 2023. Conformal prediction: A gentle introduction. Foundations and Trends in Machine Learning 16: 494–591. [Google Scholar] [CrossRef] [Scilit]
- Barber, Rina Foygel, Emmanuel J. Candès, Aaditya Ramdas, and Ryan J. Tibshirani. 2021. Predictive inference with the jackknife+. The Annals of Statistics 49: 486–507. [Google Scholar] [CrossRef] [Scilit]
- Barber, Rina Foygel, Emmanuel J. Candes, Aaditya Ramdas, and Ryan J. Tibshirani. 2023. Conformal prediction beyond exchangeability. The Annals of Statistics 51: 816–45. [Google Scholar] [CrossRef] [Scilit]
- Bhatnagar, Aadyot, Huan Wang, Caiming Xiong, and Yu Bai. 2023. Improved online conformal prediction via strongly adaptive online learning. Paper presented at 40th International Conference on Machine Learning, Honolulu, HI, USA, July 23–29. [Google Scholar]
- Bianchi, Carluccio, Maria Elena De Giuli, Dean Fantazzini, and Mario Maggi. 2011. Small sample properties of copula-GARCH modelling: A Monte Carlo study. Applied Financial Economics 21: 1587–97. [Google Scholar] [CrossRef] [Scilit]
- Cai, Yong, and Kalimuthu Krishnamoorthy. 2006. Exact size and power properties of five tests for multinomial proportions. Communications in Statistics: Simulation and Computation 35: 149–60. [Google Scholar] [CrossRef] [Scilit]
- Cauchois, Maxime, Suyash Gupta, and John C. Duchi. 2021. Knowing what you know: Valid and validated confidence sets in multiclass and multilabel prediction. The Journal of Machine Learning Research 22: 3681–722. [Google Scholar]
- Cesa-Bianchi, Nicolo, and Gábor Lugosi. 2006. Prediction, Learning, and Games. Cambridge: Cambridge University Press. [Google Scholar]
- Chernozhukov, Victor, Kaspar Wüthrich, and Yinchu Zhu. 2018. Exact and robust conformal inference methods for predictive machine learning with dependent data. Paper presented at Conference On Learning Theory, Stockholm, Sweden, July 6–9; pp. 732–49. [Google Scholar]
- Chou, Ray Yeutien, Hengchih Chou, and Nathan Liu. 2015. Range Volatility: A Review of Models and Empirical Studies. New York: Springer, pp. 2029–50. [Google Scholar]
- Christoffersen, Peter F. 1998. Evaluating interval forecasts. International Economic Review 39: 841–62. [Google Scholar] [CrossRef] [Scilit]
- Corsi, Fulvio. 2009. A simple approximate long-memory model of realized volatility. Journal of Financial Econometrics 7: 174–96. [Google Scholar] [CrossRef] [Scilit]
- Dashevskiy, Mikhail, and Zhiyuan Luo. 2008. Network traffic demand prediction with confidence. Paper presented at IEEE GLOBECOM 2008—2008 IEEE Global Telecommunications Conference, New Orleans, LA, USA, November 30–December 4; pp. 1–5. [Google Scholar]
- Emmer, Susanne, Marie Kratz, and Dirk Tasche. 2015. What is the best risk measure in practice? A comparison of standard measures. Journal of Risk 18: 31–60. [Google Scholar] [CrossRef] [Scilit]
- Engle, Robert F., and Simone Manganelli. 2004. Caviar: Conditional autoregressive value at risk by regression quantiles. Journal of Business & Economic Statistics 22: 367–81. [Google Scholar]
- Fantazzini, Dean. 2009. The effects of misspecified marginals and copulas on computing the Value-at-Risk: A Monte Carlo study. Computational Statistics & Data Analysis 53: 2168–88. [Google Scholar]
- Fantazzini, Dean. 2019. Quantitative Finance with R and Cryptocurrencies. Chicago: Independently Publisher, ISBN-13: 978-1090685315. [Google Scholar]
- Fantazzini, Dean. 2022. Crypto-coins and credit risk: Modelling and forecasting their probability of death. Journal of Risk and Financial Management 15: 304. [Google Scholar] [CrossRef] [Scilit]
- Fantazzini, Dean. 2023. Assessing the credit risk of crypto-assets using daily range volatility models. Information 14: 254. [Google Scholar] [CrossRef] [Scilit]
- Fantazzini, Dean, and Tamara Shangina. 2019. The importance of being informed: Forecasting market risk measures for the Russian RTS index future using online data and implied volatility over two decades. Applied Econometrics 55: 5–31. [Google Scholar]
- Fiorentini, Gabriele, Giorgio Calzolari, and Lorenzo Panattoni. 1996. Analytic derivatives and the computation of GARCH estimates. Journal of Applied Econometrics 11: 399–417. [Google Scholar] [CrossRef] [Scilit]
- Fiszeder, Piotr, Marcin Fałdziński, and Peter Molnár. 2019. Range-based dcc models for covariance and value-at-risk forecasting. Journal of Empirical Finance 54: 58–76. [Google Scholar] [CrossRef] [Scilit]
- Gaillard, Pierre, Goude Yannig, Plagne Laurent, Dubois Thibaut, and Thieurmel Benoit. 2023. Opera: Online Prediction by Expert Aggregation. Available online: https://pierre.gaillard.me/opera.html (accessed on 1 June 2024).
- Garman, Mark B., and Michael J. Klass. 1980. On the estimation of security price volatilities from historical data. Journal of Business 53: 67–78. [Google Scholar] [CrossRef] [Scilit]
- Gibbs, Isaac, and Emmanuel Candès. 2021. Adaptive conformal inference under distribution shift. Advances in Neural Information Processing Systems 34: 1660–72. [Google Scholar]
- Gibbs, Isaac, and Emmanuel Candès. 2022. Conformal inference for online prediction with arbitrary distribution shifts. arXiv arXiv:2208.08401. [Google Scholar]
- Gneiting, Tilmann. 2011. Making and evaluating point forecasts. Journal of the American Statistical Association 106: 746–62. [Google Scholar] [CrossRef] [Scilit]
- González-Rivera, Gloria, Tae-Hwy Lee, and Santosh Mishra. 2004. Forecasting volatility: A reality check based on option pricing, utility function, value-at-risk, and predictive likelihood. International Journal of Forecasting 20: 629–45. [Google Scholar] [CrossRef] [Scilit]
- Gradu, Paula, Elad Hazan, and Edgar Minasyan. 2023. Adaptive regret for control of time-varying dynamics. Paper presented at Learning for Dynamics and Control Conference, Philadelphia, PA, USA, June 15–16; pp. 560–72. [Google Scholar]
- Hansen, Peter, Asger Lunde, and James Nason. 2011. The model confidence set. Econometrica 79: 453–97. [Google Scholar] [CrossRef] [Scilit]
- Hwang, Soosung, and Pedro Valls Pereira. 2006. Small sample properties of GARCH estimates and persistence. The European Journal of Finance 12: 473–94. [Google Scholar] [CrossRef] [Scilit]
- Hyndman, Rob, and Yeasmin Khandakar. 2008. Automatic time series forecasting: The forecast package for R. Journal of Statistical Software 27: 1–22. [Google Scholar] [CrossRef] [Scilit]
- Kath, Christopher, and Florian Ziel. 2021. Conformal prediction interval estimation and applications to day-ahead and intraday power markets. International Journal of Forecasting 37: 777–99. [Google Scholar] [CrossRef] [Scilit]
- Koenker, Roger, and Gilbert Bassett, Jr. 1978. Regression quantiles. Econometrica: Journal of the Econometric Society 46: 33–50. [Google Scholar] [CrossRef] [Scilit]
- Kratz, Marie, Yen H. Lok, and Alexander J. McNeil. 2018. Multinomial var backtests: A simple implicit approach to backtesting expected shortfall. Journal of Banking & Finance 88: 393–407. [Google Scholar]
- Kupiec, Paul H. 1995. Techniques for verifying the accuracy of risk measurement models. The Journal of Derivatives 3: 73–84. [Google Scholar] [CrossRef] [Scilit]
- Lei, Jing, and Larry Wasserman. 2014. Distribution-free prediction bands for non-parametric regression. Journal of the Royal Statistical Society Series B: Statistical Methodology 76: 71–96. [Google Scholar] [CrossRef] [Scilit]
- Lei, Jing, James Robins, and Larry Wasserman. 2013. Distribution-free prediction sets. Journal of the American Statistical Association 108: 278–87. [Google Scholar] [CrossRef] [Scilit]
- Liu, Wei, Artur Semeyutin, Chi Keung Marco Lau, and Giray Gozgor. 2020. Forecasting value-at-risk of cryptocurrencies with riskmetrics type models. Research in International Business and Finance 54: 101259. [Google Scholar] [CrossRef] [Scilit]
- Lyócsa, Štefan, Peter Molnár, and Tomáš Vỳrost. 2021. Stock market volatility forecasting: Do we need high-frequency data? International Journal of Forecasting 37: 1092–10. [Google Scholar] [CrossRef] [Scilit]
- Manokhin, Valery. 2024. Awesome Conformal Prediction. Available online: https://zenodo.org/records/6467205 (accessed on 1 June 2024).
- Molnár, Peter. 2012. Properties of range-based volatility estimators. International Review of Financial Analysis 23: 20–29. [Google Scholar] [CrossRef] [Scilit]
- Müller, Fernanda Maria, Samuel Solgon Santos, Thalles Weber Gössling, and Marcelo Brutti Righi. 2022. Comparison of risk forecasts for cryptocurrencies: A focus on range value at risk. Finance Research Letters 48: 102916. [Google Scholar] [CrossRef] [Scilit]
- Nison, Steve. 1994. Beyond Candlesticks: New Japanese Charting Techniques Revealed. Hoboken: John Wiley & Sons, vol. 56. [Google Scholar]
- Orabona, Francesco, and Dávid Pál. 2018. Scale-free online learning. Theoretical Computer Science 716: 50–69. [Google Scholar] [CrossRef] [Scilit]
- Papadopoulos, Harris. 2008. Inductive conformal prediction: Theory and application to neural networks. In Tools in Artificial Intelligence. Rijeka: IntechOpen. [Google Scholar]
- Parkinson, Michael. 1980. The extreme value method for estimating the variance of the rate of return. Journal of Business 53: 61–65. [Google Scholar] [CrossRef] [Scilit]
- Patton, Andrew J. 2011. Volatility forecast comparison using imperfect volatility proxies. Journal of Econometrics 160: 246–56. [Google Scholar] [CrossRef] [Scilit]
- Podkopaev, Aleksandr, and Aaditya Ramdas. 2021. Distribution-free uncertainty quantification for classification under label shift. Paper presented at Uncertainty in Artificial Intelligence, Online, July 27–30; pp. 844–53. [Google Scholar]
- Romano, Yaniv, Evan Patterson, and Emmanuel J Candès. 2019. Conformalized quantile regression. Paper presented at 33rd International Conference on Neural Information Processing Systems, Vancouver, BC, Canada, December 8–14; pp. 3543–53. [Google Scholar]
- Romano, Yaniv, Matteo Sesia, and Emmanuel Candes. 2020. Classification with valid and adaptive coverage. Advances in Neural Information Processing Systems 33: 3581–91. [Google Scholar]
- Shafer, Glenn, and Vladimir Vovk. 2008. A tutorial on conformal prediction. Journal of Machine Learning Research 9: 371–421. [Google Scholar]
- Sousa, Martim, Ana Maria Tomé, and José Moreira. 2022. A general framework for multi-step ahead adaptive conformal heteroscedastic time-series forecasting. arXiv arXiv:2207.14219. [Google Scholar]
- Stankeviciute, Kamile, Ahmed M Alaa, and Mihaela van der Schaar. 2021. Conformal time-series forecasting. Advances in Neural Information Processing Systems 34: 6216–28. [Google Scholar]
- Susmann, Herbert, Antoine Chambaz, and Julie Josse. 2023. Adaptiveconformal: An r package for adaptive conformal inference. arXiv arXiv:2312.00448. [Google Scholar]
- Tibshirani, Ryan J., Rina Foygel Barber, Emmanuel J. Candès, and Aaditya Ramdas. 2019. Conformal prediction under covariate shift. Paper presented at 33rd International Conference on Neural Information Processing Systems, Vancouver, BC, Canada, December 8–14; pp. 2530–40. [Google Scholar]
- Trucíos, Carlos, and James W. Taylor. 2023. A comparison of methods for forecasting value at risk and expected shortfall of cryptocurrencies. Journal of Forecasting 42: 989–1007. [Google Scholar] [CrossRef] [Scilit]
- Venables, William N., and Brian D. Ripley. 2002. Modern Applied Statistics with S-PLUS. Berlin: Springer Science & Business Media. [Google Scholar]
- Vovk, Vladimir, Alexander Gammerman, and Glenn Shafer. 2005. Algorithmic Learning in a Random World. Berlin: Springer, vol. 29. [Google Scholar]
- Vovk, Vladimir, Ilia Nouretdinov, Valery Manokhin, and Alexander Gammerman. 2018. Cross-conformal predictive distributions. Paper presented at Conformal and Probabilistic Prediction and Applications, Maastricht, The Netherlands, June 1–13; pp. 37–51. [Google Scholar]
- Vovk, Volodya, Alexander Gammerman, and Craig Saunders. 1999. Machine-learning applications of algorithmic randomness. Paper presented at Sixteenth International Conference on Machine Learning, Bled, Slovenia, June 27–30; pp. 444–53. [Google Scholar]
- Wimmerstedt, Lisa. 2015. Backtesting Expected Shortfall: The Design and Implementation of Different Backtests. Technical Report. Stockholm: Swedish Royal Institute of Technology. [Google Scholar]
- Wintenberger, Olivier. 2017. Optimal learning with bernstein online aggregation. Machine Learning 106: 119–41. [Google Scholar] [CrossRef] [Scilit]
- Wisniewski, Wojciech, David Lindsay, and Sian Lindsay. 2020. Application of conformal prediction interval estimations to market makers’ net positions. Paper presented at Conformal and Probabilistic Prediction and Applications, Online, September 9–11; pp. 285–301. [Google Scholar]
- Xu, Chen, and Yao Xie. 2021. Conformal prediction interval for dynamic time-series. Paper presented at International Conference on Machine Learning, Virtual, July 18–24; pp. 11559–69. [Google Scholar]
- Yang, Yachong, Arun Kumar Kuchibhotla, and Eric Tchetgen Tchetgen. 2022. Doubly robust calibration of prediction sets under covariate shift. arXiv arXiv:2203.01761. [Google Scholar] [CrossRef] [Scilit]
- Zaffran, Margaux, Olivier Féron, Yannig Goude, Julie Josse, and Aymeric Dieuleveut. 2022. Adaptive conformal predictions for time-series. Paper presented at International Conference on Machine Learning, Baltimore, MD, USA, July 17–23; pp. 25834–66. [Google Scholar]
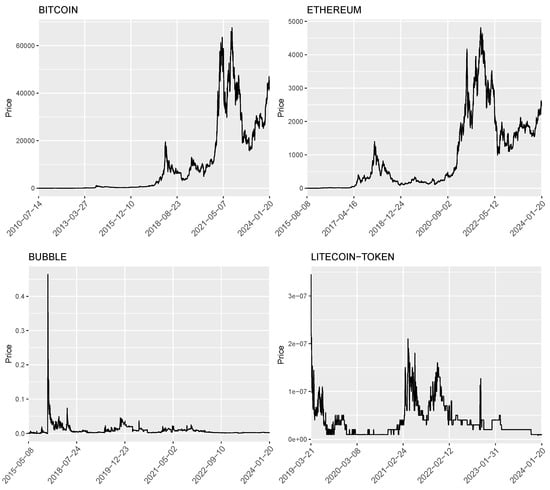


Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2024 by the author. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).