Article

Multi-Modal Enhancement Transformer Network for Skeleton-Based Human Interaction Recognition
School of Microelectronics and Communication Engineering, Chongqing University, Chongqing 400044, China
*
Author to whom correspondence should be addressed.
This work was done as an intern at the Institute of Science on Brain Inspired Intelligence, Chongqing University.
Biomimetics 2024, 9(3), 123; https://doi.org/10.3390/biomimetics9030123

Submission received: 15 January 2024 / Revised: 11 February 2024 / Accepted: 16 February 2024 / Published: 20 February 2024
(This article belongs to the Special Issue Biologically Inspired Vision and Image Processing)

Abstract

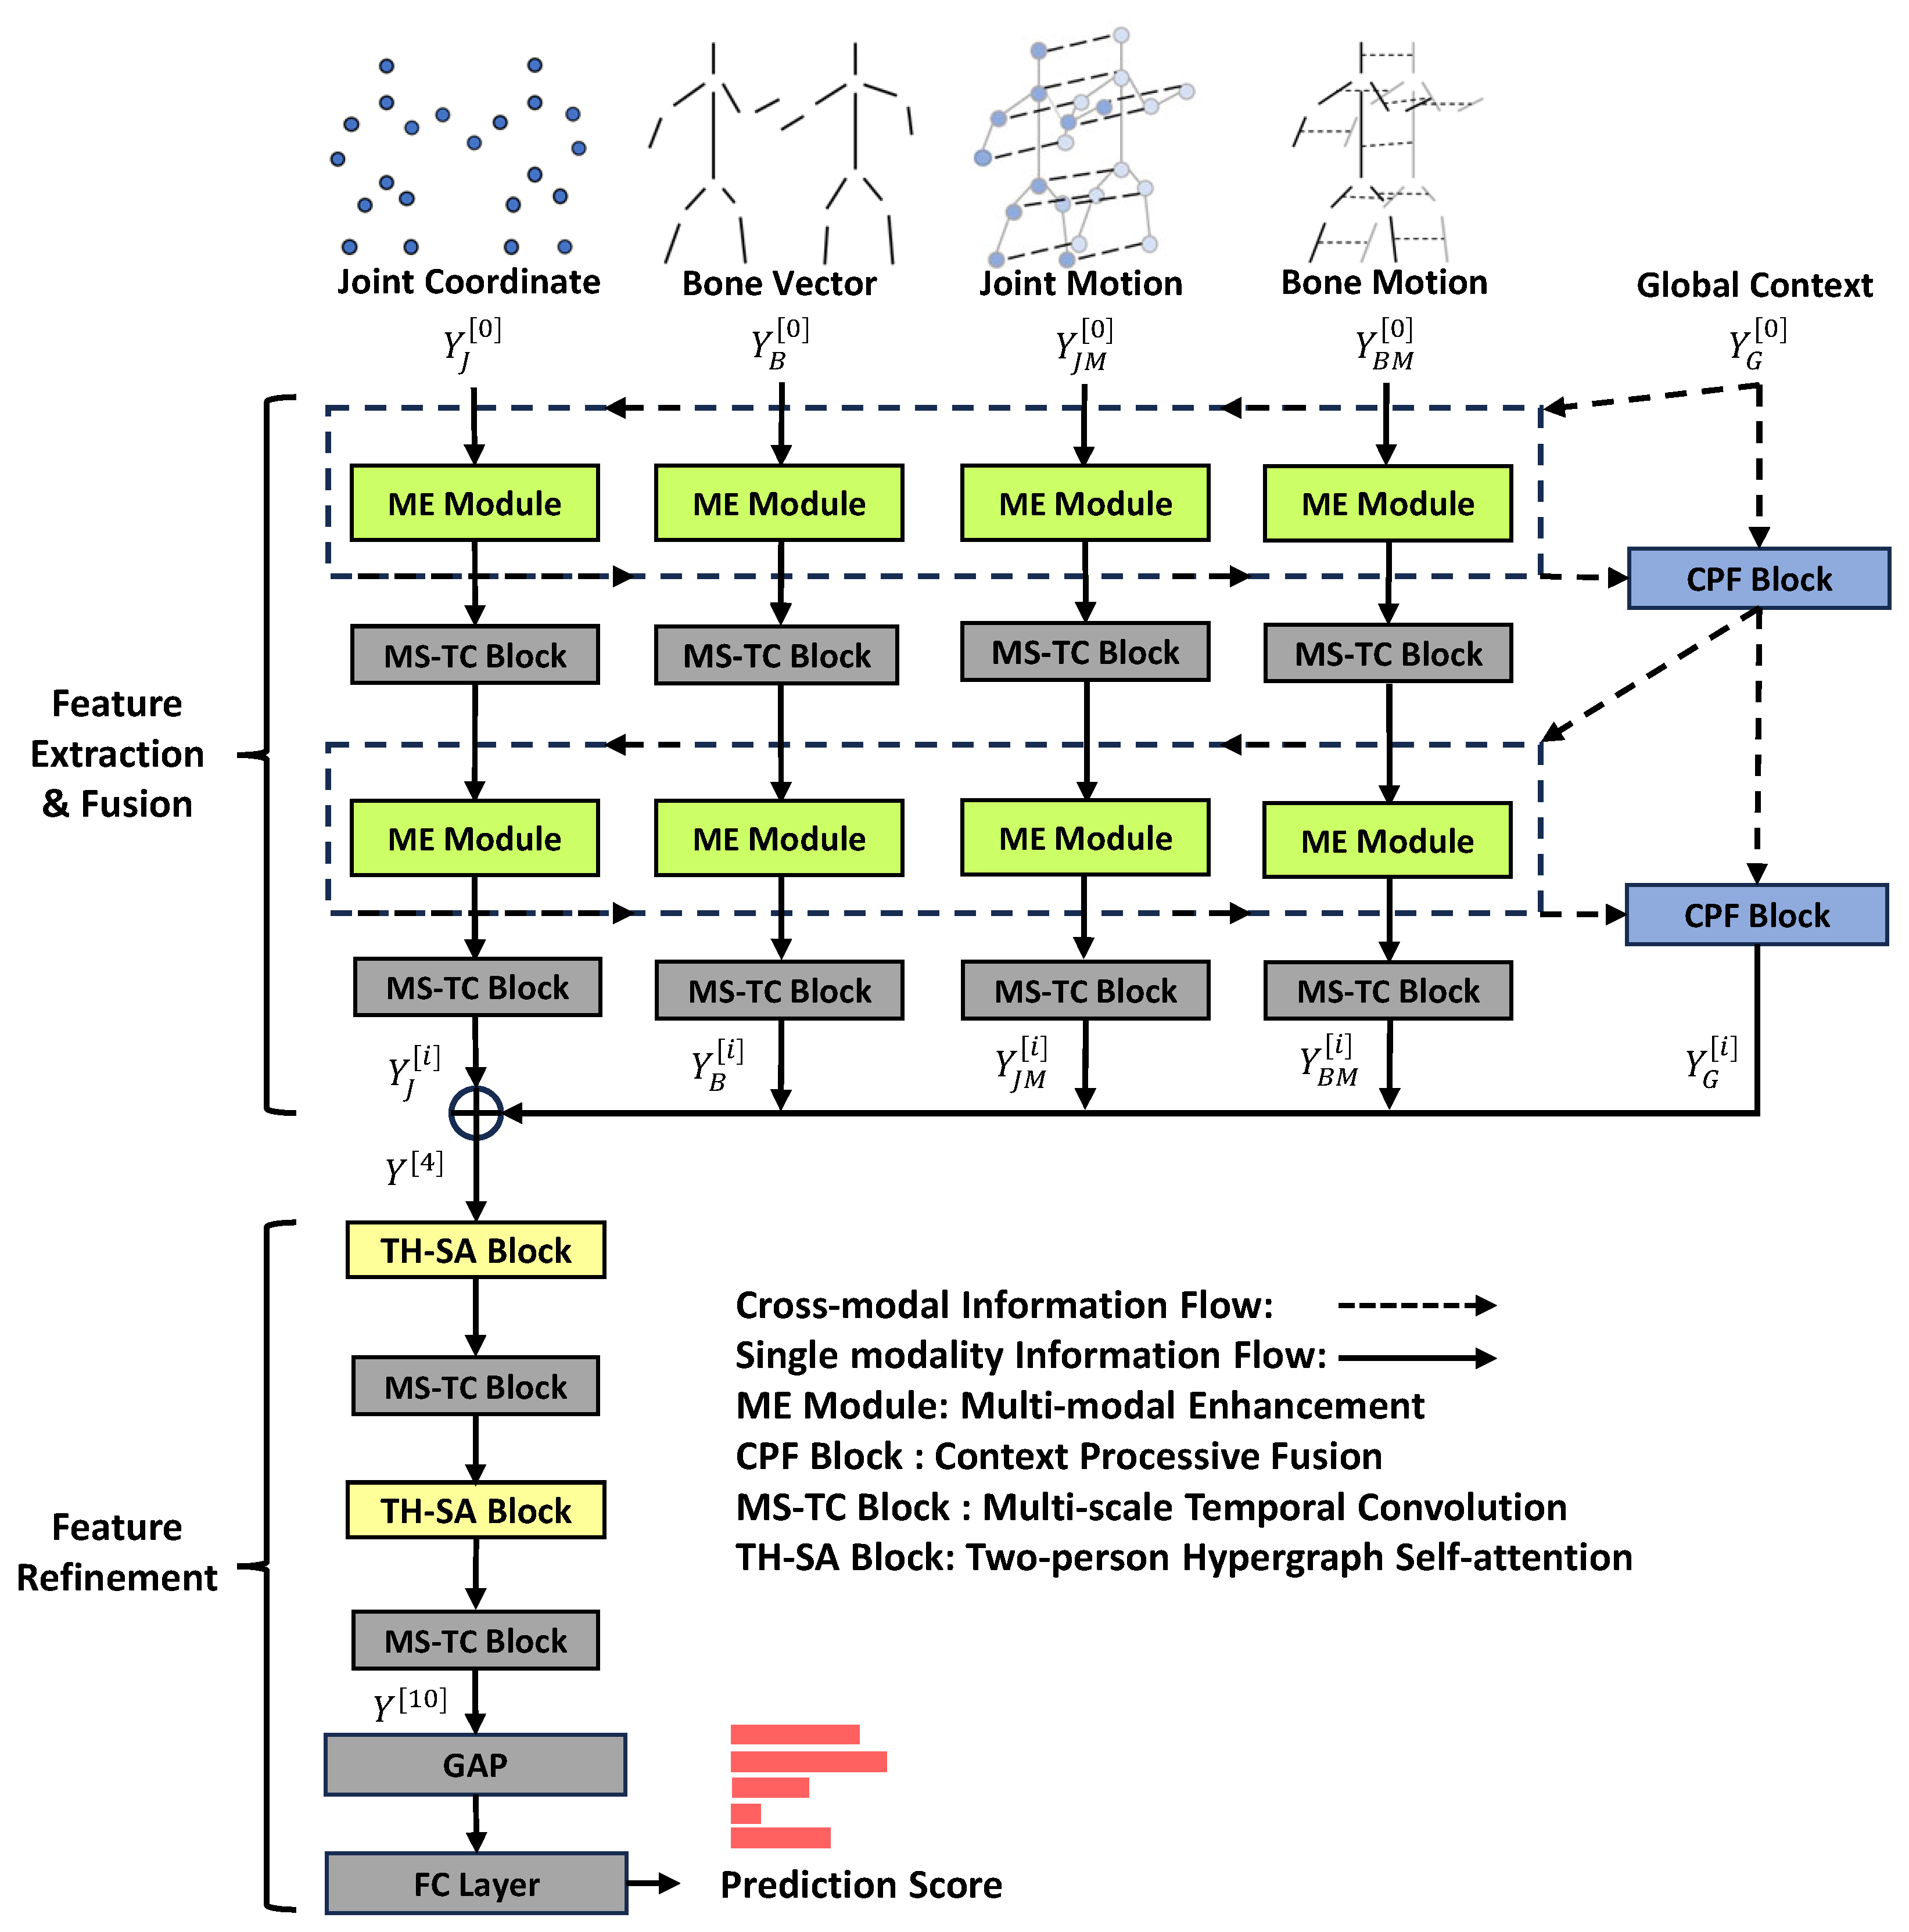
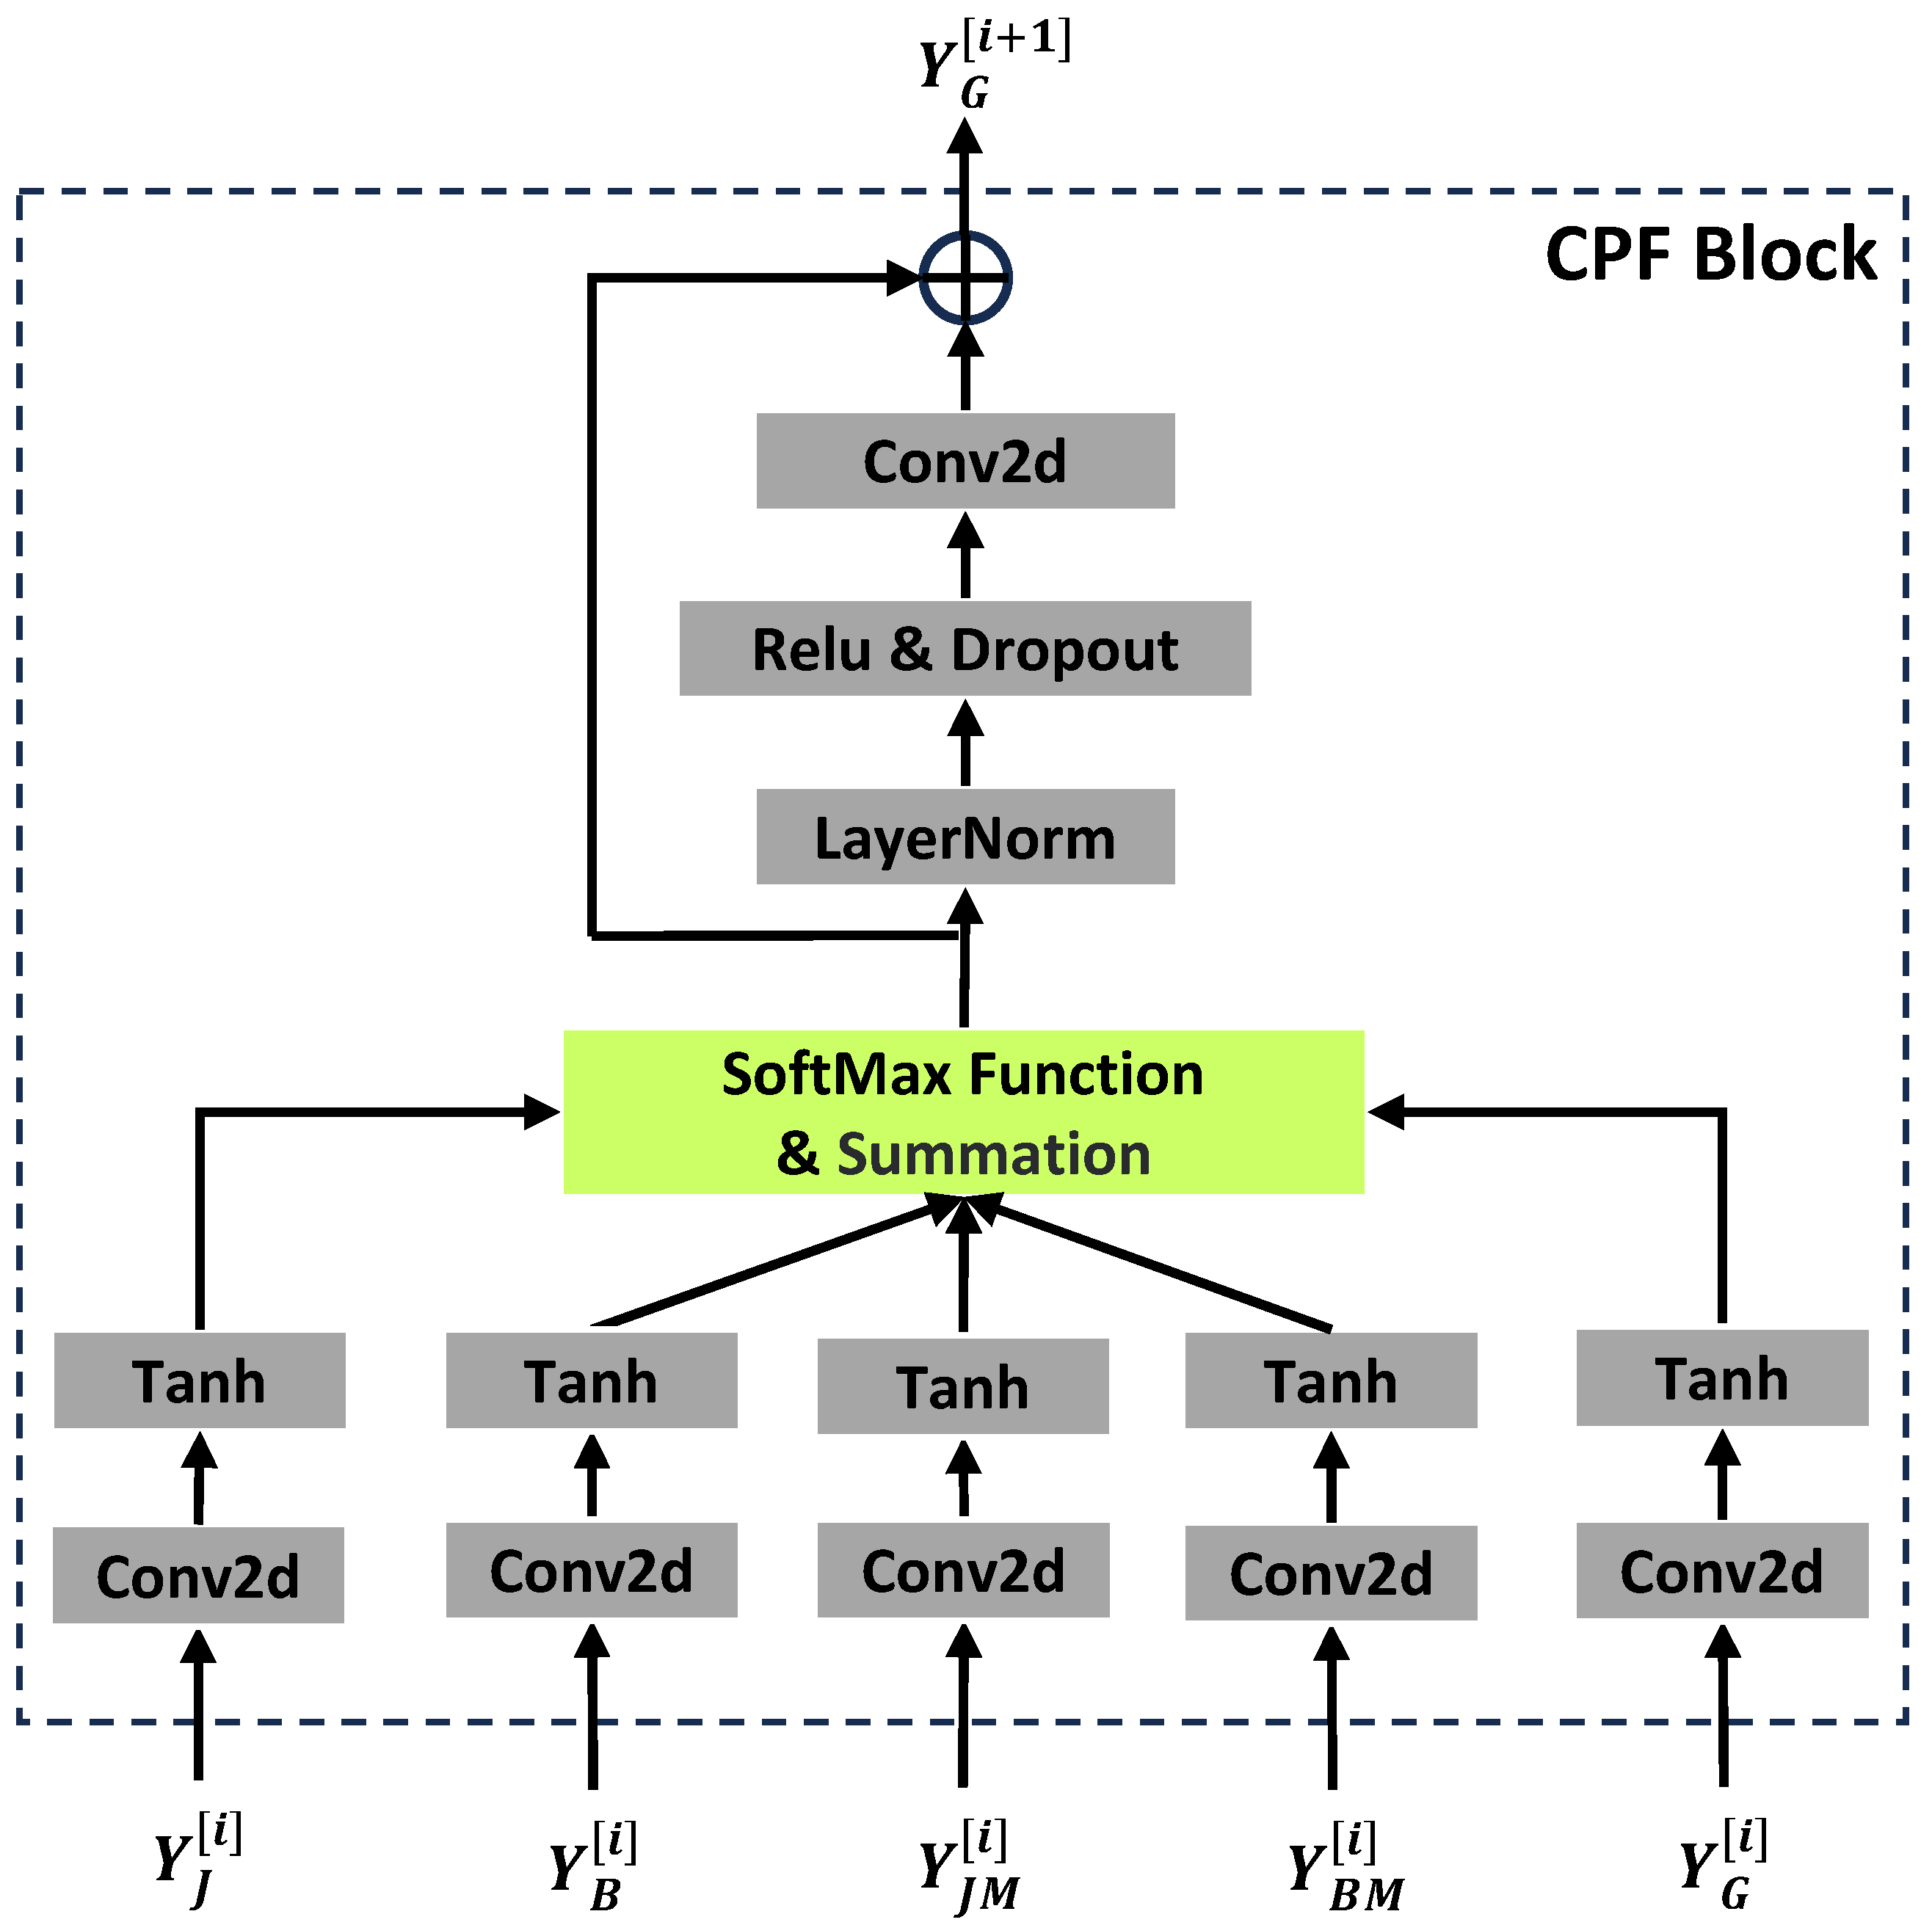
Skeleton-based human interaction recognition is a challenging task in the field of vision and image processing. Graph Convolutional Networks (GCNs) achieved remarkable performance by modeling the human skeleton as a topology. However, existing GCN-based methods have two problems: (1) Existing frameworks cannot effectively take advantage of the complementary features of different skeletal modalities. There is no information transfer channel between various specific modalities. (2) Limited by the structure of the skeleton topology, it is hard to capture and learn the information about two-person interactions. To solve these problems, inspired by the human visual neural network, we propose a multi-modal enhancement transformer (ME-Former) network for skeleton-based human interaction recognition. ME-Former includes a multi-modal enhancement module (ME) and a context progressive fusion block (CPF). More specifically, each ME module consists of a multi-head cross-modal attention block (MH-CA) and a two-person hypergraph self-attention block (TH-SA), which are responsible for enhancing the skeleton features of a specific modality from other skeletal modalities and modeling spatial dependencies between joints using the specific modality, respectively. In addition, we propose a two-person skeleton topology and a two-person hypergraph representation. The TH-SA block can embed their structural information into the self-attention to better learn two-person interaction. The CPF block is capable of progressively transforming the features of different skeletal modalities from low-level features to higher-order global contexts, making the enhancement process more efficient. Extensive experiments on benchmark NTU-RGB+D 60 and NTU-RGB+D 120 datasets consistently verify the effectiveness of our proposed ME-Former by outperforming state-of-the-art methods.
Keywords: transformer; skeleton data; human interaction recognition; hypergraph representation transformer; skeleton data; human interaction recognition; hypergraph representation