


Abstract
The combustion optimization problem of the circulation fluidized bed boiler is regarded as a difficult multi-objective optimization problem that requires simultaneously improving the boiler thermal efficiency and reducing the NOx emissions concentration. In order to solve the above-mentioned problem, a new multi-objective optimization framework that incorporates an interpretable CatBoost model and modified slime mould algorithm is proposed. Firstly, the interpretable CatBoost model combined with TreeSHAP is applied to model the boiler thermal efficiency and NOx emissions concentration. Simultaneously, data correlation analysis is conducted based on the established models. Finally, a kind of modified slime mould algorithm is proposed and used to optimize the adjustable operation parameters of one 330 MW circulation fluidized bed boiler. The experimental results show that the proposed framework can effectively improve the boiler thermal efficiency and reduce the NOx emissions concentration, where the average optimization ratio for thermal efficiency reaches +0.68%, the average optimization ratio for NOx emission concentration reaches −37.55%, and the average optimization time is 6.40 s. In addition, the superiority of the proposed method is demonstrated by ten benchmark testing functions and two constrained optimization problems. Therefore, the proposed framework is an effective artificial intelligence approach for the modeling and optimization of complex systems.
1. Introduction
1.1. Background
At present, thermal power generation still dominates the supply of electric energy, and coal is the main thermal power supply resource. However, as a kind of non-renewable energy source, coal is becoming more and more scarce with the massive consumption of thermal power generation. And the combustion process will be accompanied by large amounts of pollutants discharged into the atmosphere, such as NOx and SO2, which seriously affect the atmospheric environment and human living. Therefore, it is an urgent problem to improve boiler’s thermal efficiency and reduce NOx emissions for thermal power generation.
The above-mentioned problem is regarded as a multi-objective optimization problem, which is called a boiler combustion optimization problem, and it is also an important research direction [1]. It is widely known that the boiler combustion system has complex characteristics with non-linearity, strong coupling and large hysteresis, making it difficult to be optimized by traditional mathematical and statistical methods. To address this problem, many researchers commonly used artificial neural networks to build the thermal efficiency model or a NOx emissions model based on the boiler’s historical operation data [2,3,4,5]. And based on the established model, all kinds of optimization algorithms were applied to adjust the running parameters for improving the thermal efficiency and reducing NOx emissions. In addition, solving the optimization problem of the boiler combustion process is beneficial to the ecological modernization of power plants [6,7].
For modeling, Zhou et al. [8,9,10] applied artificial neural networks (ANNs) and support vector machine (SVM) variants to develop the prediction models for thermal efficiency and NOx emission concentration. The experimental results showed that ANNs or SVM variants can obtain good prediction results. These research results had an important impact on the subsequent research on the boiler combustion optimization problem. Si et al. [11] applied an improved SVM to achieve a dynamic adaptive model of NOx emission concentration, which provided a new idea for online modeling. Li et al. applied the extreme learning machine (ELM) and fast learning network (FLN) to model thermal efficiency and NOx emission [12,13,14]. The experimental results showed that the ELM and FLN can obtain higher accuracy and faster computing speed than ANNs and SVMs. Ma et al. [15] proposed a hyper-parameter self-optimized broad learning system to model the thermal efficiency and emission concentrations of Nox and SO2.
For optimization, researchers were keen on applying meta-heuristic optimization algorithms to solve the boiler combustion optimization problem [16,17,18]. Rahat et al. [19] applied a kind of novel multi-objective optimization algorithm to solve the contradiction between thermal efficiency and NOx emission concentration. Wang et al. [20] combined random forest (RF) with an improved flower pollination algorithm to build a NOx emission concentration model and reduce NOx emissions, separately. Hu et al. [21] used a deep neural network and multi-objective optimization algorithm to balance boiler thermal efficiency and NOx emission concentration. Three years ago, Xu et al. proposed several methods to solve the boiler combustion optimization problem, including the ICFAR-IPSO-LSTM-IMOPSO model [22], CIPSODM-LSTM algorithm framework [23], data-driven evolutionary optimization and online retrieval method [24]. In our group, Li and Ma et al. [25,26,27] used an improved artificial bee colony (ABC) and teaching and learning optimization (TLBO) to enhance the thermal efficiency and reduce the NOx emission concentration. In summary, artificial neural networks and meta-heuristic optimization algorithms can effectively solve the boiler combustion optimization problem.
1.2. Motivation
In this paper, a new multi-objective optimization framework is proposed to solve the boiler combustion optimization problem. The proposed framework combines the interpretable CatBoost model by TreeSHAP and a modified slime mould algorithm (MSMA). The interpretable CatBoost model is firstly used to build the synthetic model of boiler thermal efficiency and NOx emissions based on the historical operation data of one 330 MW circulation fluidized bed boiler (CFBB). Based on the established synthetic model, the modified slime mould algorithm is used to optimize the CFBB’s adjustment operation parameters for improved thermal efficiency and reduced NOx emissions. The experimental results show that the interpretable CatBoost model can obtain better model performance than RF [28,29], SVMs [30,31] and MLP [32,33,34], and the MSMA can improve boiler thermal efficiency and reduce NOx emissions.
Now, the new proposed framework needs to be explained. For the model method, CatBoost [35,36,37] is a kind of novel ensemble learning model that was first proposed by Yandex in 2017, and TreeSHAP [38,39] is an interpretable method for black box models that was proposed by Lundberg in 2017. Combining CatBoost with TreeSHAP can enhance its interpretability, which is called the interpretable CatBoost model in this paper. For the optimization algorithm, a slime mould algorithm (SMA) [40] is a kind of novel meta-heuristic algorithm that was first proposed by Lee et al. in 2020, which mainly simulates the changes of behavior and morphology of slime mould in nature during foraging. The SMA has several advantages, including a simple principle, few parameters and good global search capability. In order to further enhance the convergence accuracy and convergence speed of the original SMA, two mechanisms are proposed and introduced in the SMA. Firstly, iterative chaotic mapping with infinite collapse (ICMIC) [41] is used to initialize the population individuals for increasing population diversity and enhancing global search capability. Secondly, a reverse interpolation strategy (RIS) is proposed on the basis of opposition-based learning (OBL) [42,43] to update the positions of the population individuals obtained from each iteration, which helps to improve the quality of the solution and strengthen the local search ability. Compared with five other state-of-the-art meta-heuristic algorithms (including the butterfly optimization algorithm (BOA) [44], whale optimization algorithm (WOA) [45], seagull optimization algorithm (SOA) [46] and sparrow search algorithm (SSA) [47]) on 10 benchmark testing functions and two classical constrained optimization problems, the proposed MSMA outperforms on most testing functions. Moreover, compared to the original SMA, the MSMA is able to obtain better or equivalent convergence accuracy with less convergence time without increasing the calculation burden.
1.3. Contributions
In order to solve the boiler combustion optimization problem, a new multi-objective optimization framework is firstly designed in this paper. The contributions of this paper are summarized as follows:
- A kind of novel multi-objective optimization framework is proposed, which combines interpretable CatBoost by TreeSHAP and a modified slime mould algorithm. Particularly, this framework has model interpretability and adaptivity.
- A kind of modified slime mould algorithm is proposed to solve benchmark testing functions and constrained optimization problems.
The structure of this paper is as follows: the study object and basic methods are introduced in Section 2; the modified SMA is presented in Section 3; Section 4 contains the application of the proposed framework to the boiler combustion optimization problem; and the conclusions are presented in Section 5.
2. Related Work
2.1. Study Object
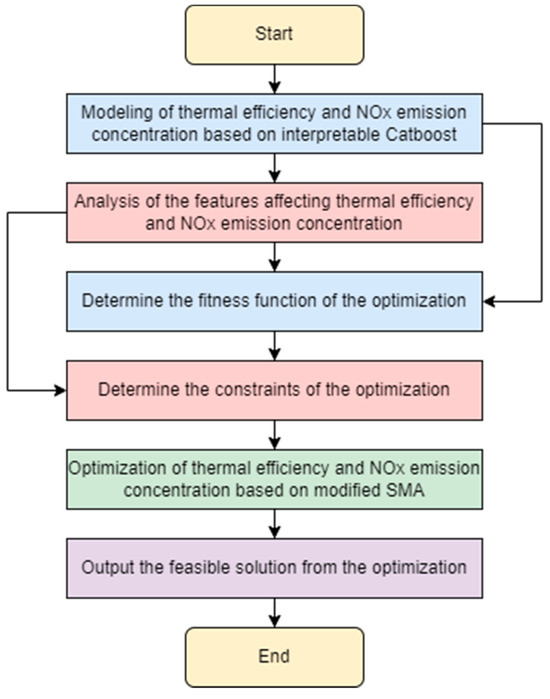
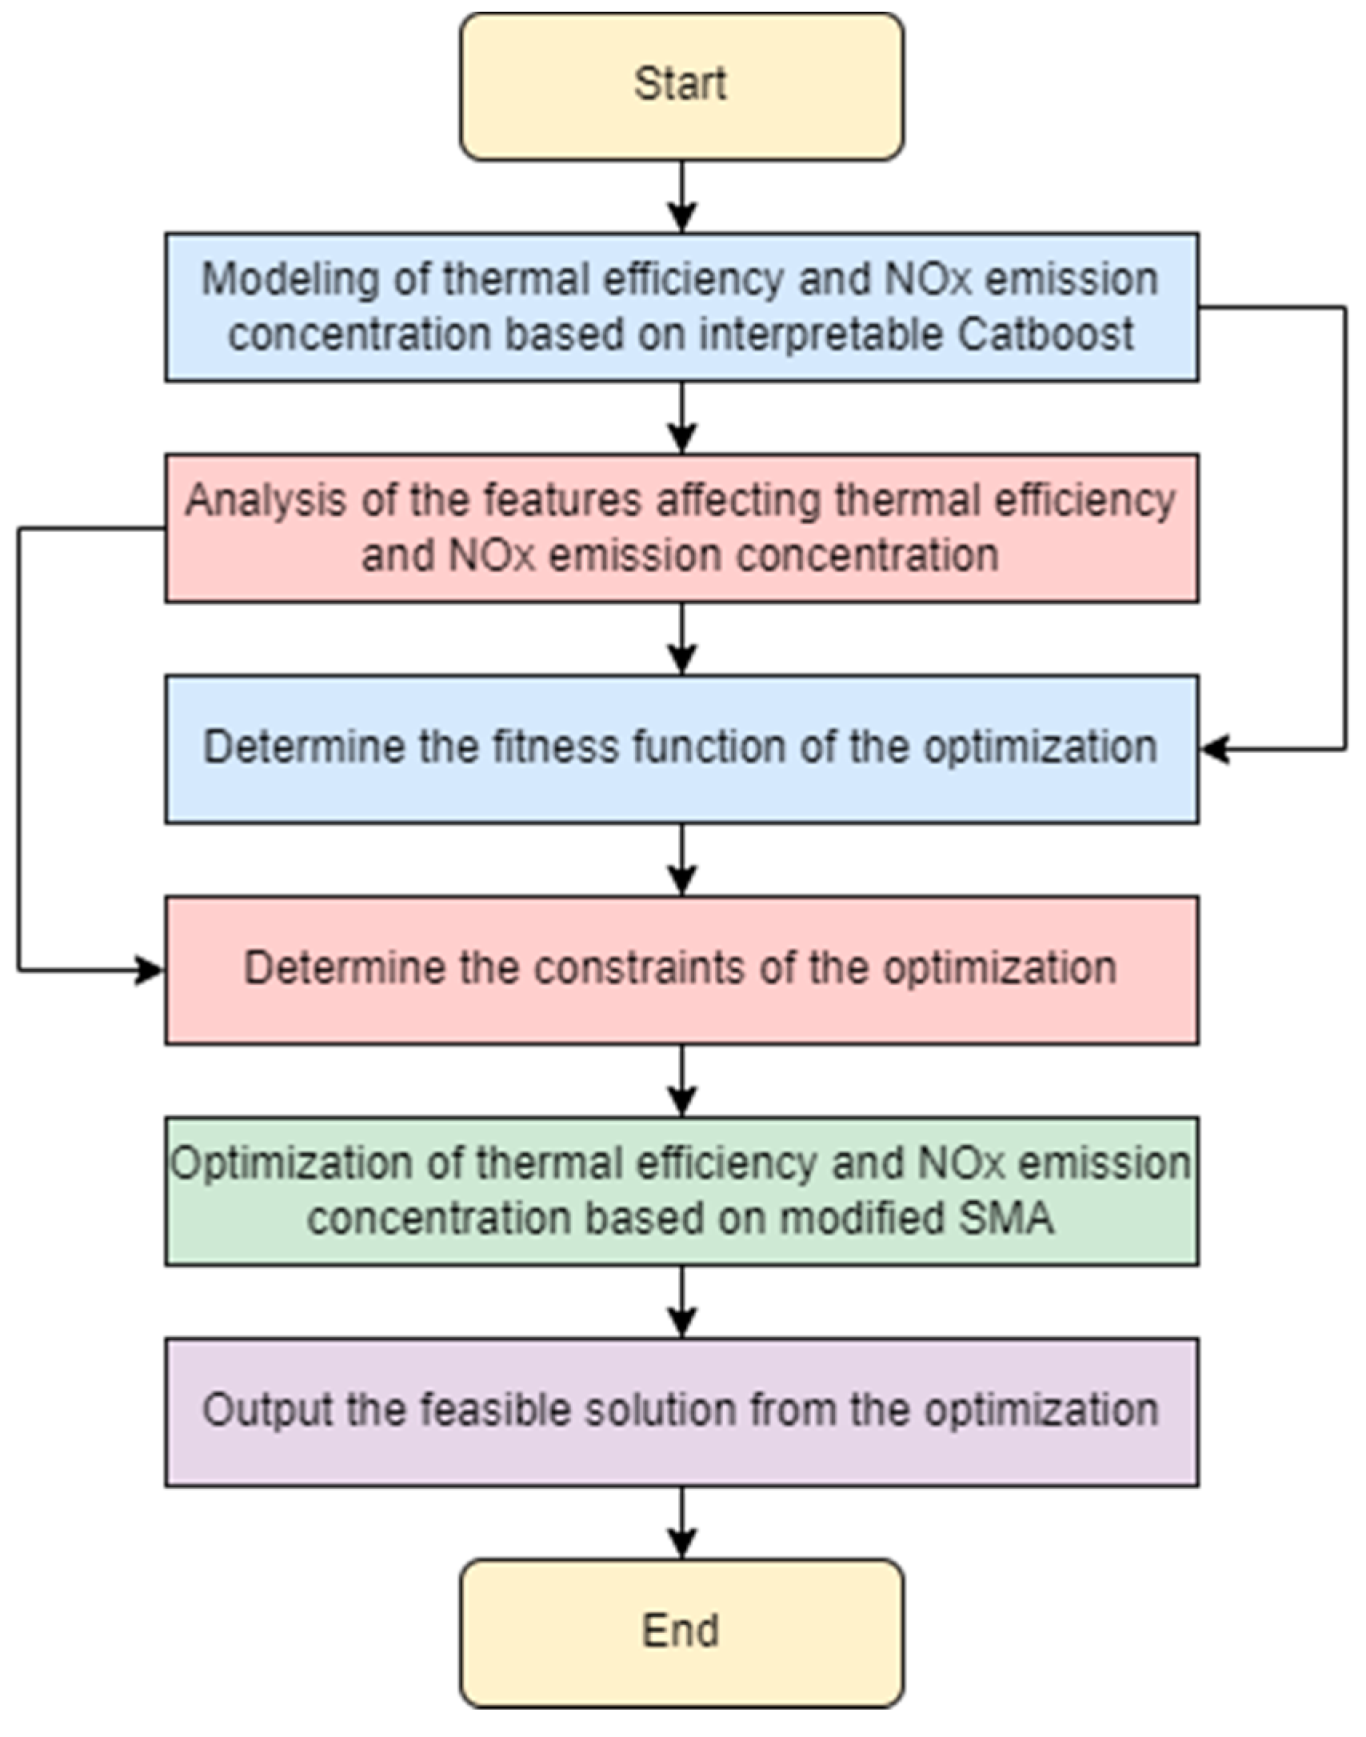
The study object of this paper is a 330 MW circulating fluidized bed boiler (CFBB). The main study focus of this paper is to maximize the thermal efficiency (TE) while minimizing the NOx emissions concentration of the CFBB. To achieve the optimization goal, a kind of new multi-objective optimization framework integrating the interpretable CatBoost model and MSMA is proposed in this paper. The flow chart of the proposed framework is shown in Figure 1, and the core steps are summarized as follows:
Figure 1.
The flow chart of the proposed framework.
Step 1. The interpretable CatBoost model combined with TreeSHAP is used to build the synthetic model of boiler thermal efficiency and NOx emissions based on historical operation data. Note that the detailed descriptions of the interpretable CatBoost and TreeSHAP are given in the literature [35,36,37,38,39], separately.
Step 2. Based on the established model in step 1, the value ranges of adjustable parameters of the CFBB with positive impact on thermal efficiency and negative impact on NOx emissions are obtained by further analyzing the features affecting the thermal efficiency and NOx emission concentration.
Step 3. Based on the established model and selected parameter features, the boiler’s adjustment parameters are optimized by a modified SMA with the fitness function of maximizing the thermal efficiency and minimizing the NOx emission concentration of the CFBB. And the constraints for the value ranges of the adjustable parameters of the CFBB are obtained in step 2.
2.2. Slime Mould Algorithm (SMA)
In this subsection, a detailed descriptions of the slime mould algorithm is given. The specific content of the SMA is explained below. In order to understand the following method, the symbols used in this section are explained in Table 1.
Table 1.
The symbol explanation of SMA and modified SMA.
The slime mould algorithm (SMA) is a kind of novel meta-heuristic algorithm that was first proposed by Lee et al. in 2020, which is inspired by foraging behavior and the morphology of slime mould. Slime mould is a eukaryotic organism that lives in a humid and cold environment and takes its nutrients mainly from external organic matter. When slime mould approaches its food source, its bio-oscillator generates a propagation wave through the vein to increase the flow of cytoplasm. The higher the concentration of food, the stronger the propagation wave generated by the bio-oscillator and the faster the cytoplasmic flow. The SMA has a simple principle, few adjustment parameters and strong global search capability. Therefore, the SMA is used to solve the boiler combustion optimization problem. Its basic principle is as follows.
(1) The stage of approaching food
In the approaching food phase, the slime mould approaches the food through the odor in the air, and the expression of its approaching behavior is shown in Equation (1).
where and are the positions of the slime mould individuals at the th and th iterations, respectively; is the best position of the slime mould individual at the th iteration; and are the two randomly selected slime mould individuals at the th iteration; the range of is , , is the current number of iterations and is the total number of iterations; the range of is from 1 linearly decreasing to 0; is a random value between 0 and 1; ,, is the fitness value of the th slime mould individual; is the optimal fitness value in all iterations; is the population size of the slime mould individuals; and is the weight of a slime mould individual, and its expression is shown in Equation (2).
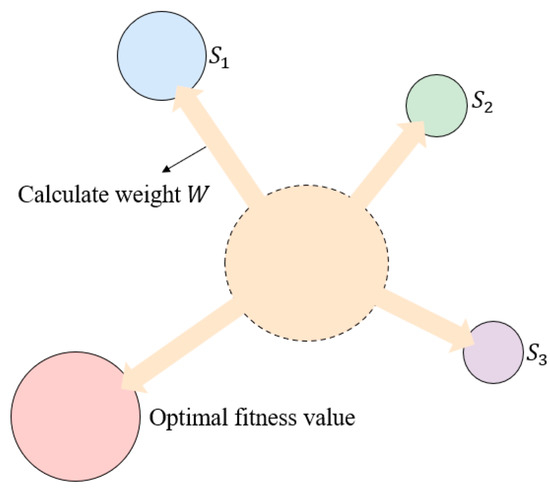
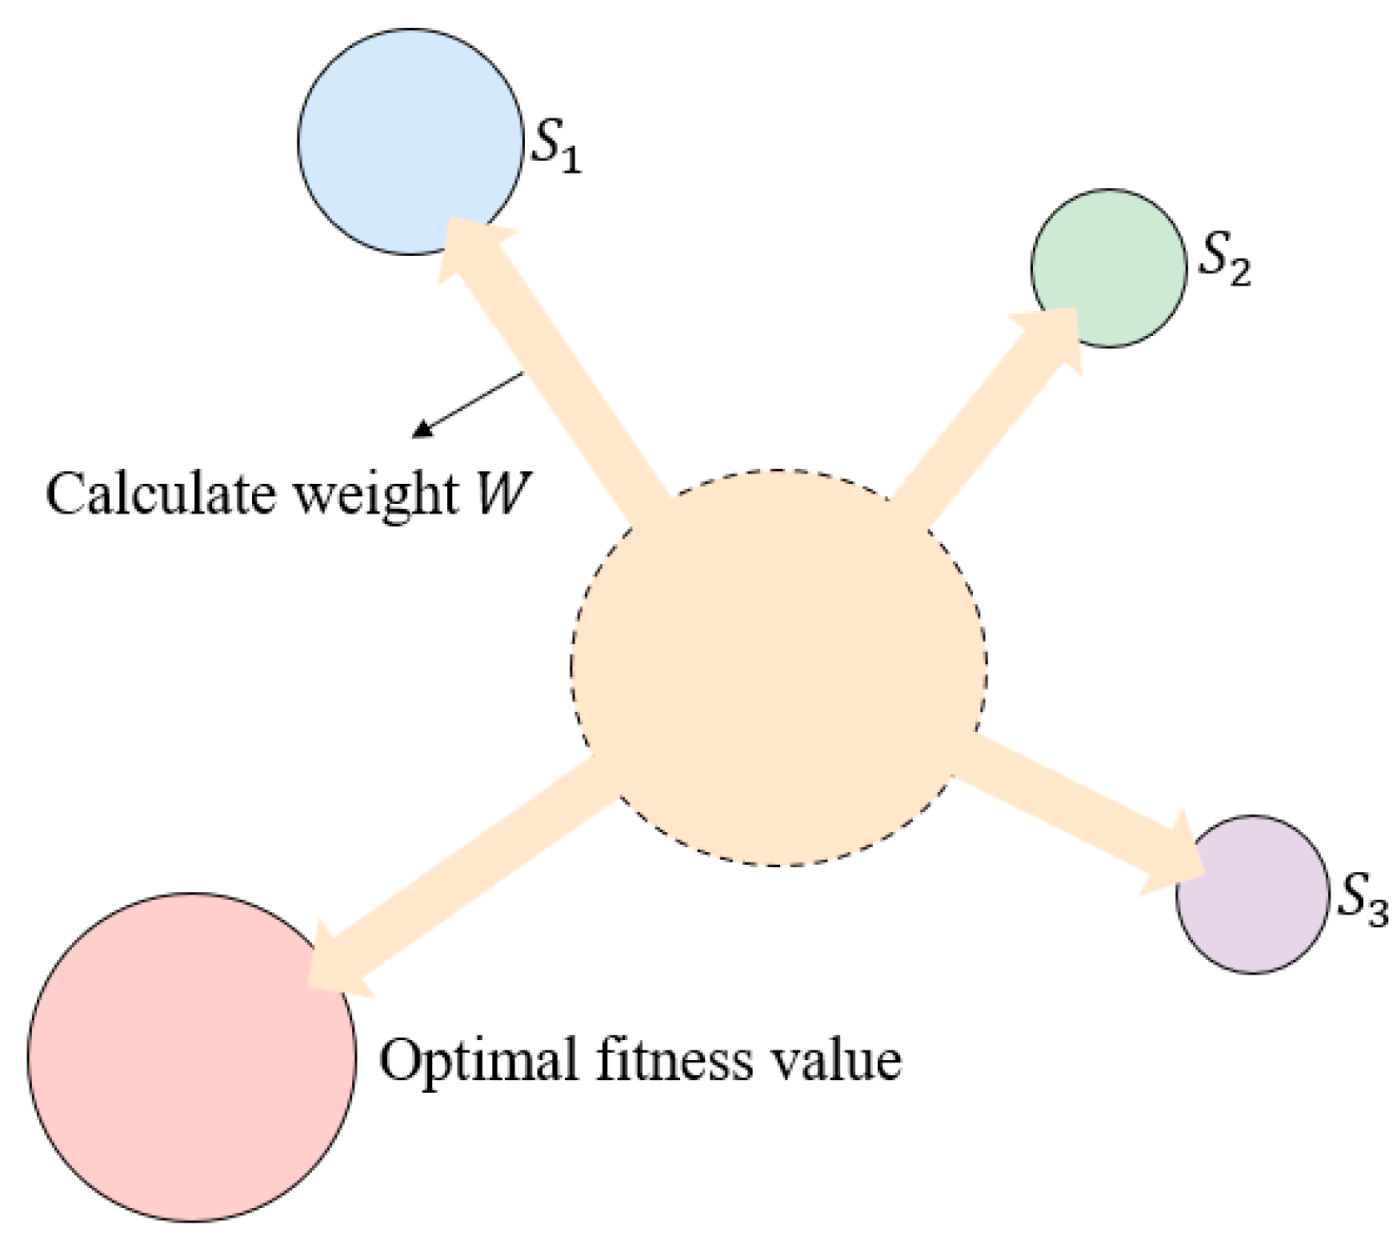
where is the top half of the population individual in terms of fitness value; and are the best and worst fitness value at the current iteration, respectively; is the sequence of sorted fitness values; is used to slow down the rate of change in the values and stabilize the change in the contraction frequency; and are used to explain the process of slime mould adjusting its position according to the food concentration, where the higher the food concentration, the greater the weight of slime mould near the area; if the food concentration is low, slime mould will turn to search for other areas, and the weight of slime mould in the area will become smaller. The fitness value evaluation graph of slime mould is shown in Figure 2.
Figure 2.
The fitness value evaluation graph of slime mould.
The approaching food stage simulates the positive and negative feedback process between the weight of slime mould and the food concentration. Equation (10) updates the individual positions according to the change in the optimal position and the fine tuning of , and . The role of is to form a search vector at any angle, i.e., to search the solution space in any direction, thus increasing the possibility of finding the optimal solution and better simulating the circular and fan-shaped structural motion of the slime mould as it approaches the food.
(2) The stage of enveloping food
The enveloping food phase simulates the contraction pattern of the slime mould venous tissue. The higher the concentration of food in contact with the venous tissue, the stronger the propagation wave generated by the bio-oscillator and the faster the cytoplasmic flow; the lower the concentration of food in contact with the venous tissue, the weaker the propagating waves generated by the biological oscillator and the slower the cytoplasmic flow. Based on the above principle, the expression of its enveloping behavior is shown in Equation (3).
where is the random value generated within 0 to 1; and are the upper and lower bounds of the search space, respectively; and is the proportion of randomly distributed slime mould individuals, and it is used to switch between the global search phase and the local search phase.
(3) The stage of grabbing food
During the food grasping phase, the slime mould uses the propagation waves generated by the bio-oscillator to change the velocity of cytoplasmic flow in the venous tissue, simulating the variation of the width of the venous tissue of slime mould with the variation of the oscillation frequency of the bio-oscillator by , and . The slime mould approaches the food more slowly when the food concentration is low and more quickly when it finds good quality food. This stage is actually the update of the , and .
3. Modified Slime Mould Algorithm (MSMA)
In order to further improve the convergence accuracy and convergence speed of the original SMA, a kind of modified slime mould algorithm (MSMA) is proposed by introducing two mechanisms. The detailed description of the two mechanisms is given in Section 3.1. In addition, ten benchmark testing functions and two classical constraint optimization problems are used to verify the performance of the MSMA in Section 3.2.
3.1. Improved Mechanism
(1) Iterative chaotic mapping with infinite collapse (ICMIC)
In swarm intelligence optimization algorithms, the quality of the initial population individuals has a large impact on the algorithm performance. A good initial population is conducive to obtaining a global optimal solution. The original SMA uses a random initialization method to initialize the population without a priori knowledge, which may easily lead to the population diversity missing. Logistic and tent chaotic mapping functions are commonly utilized to initialize population individuals for enhancing the population diversity. However, compared with these two chaotic mapping methods, the ICMIC chaotic mapping method has better uniform traversal and faster convergence. Therefore, the ICMIC chaos mapping method is introduced to generate population individuals.
The expression of the ICMIC chaotic mapping is shown in Equation (4).
where is a random value that follows the normal distribution in the interval .
Next, the chaotic sequence individual is converted to the real solution space, and the conversion formula is shown in Equation (5).
where and are the upper and lower bounds of the search space, respectively; and is the generated chaotic sequence.
(2) Reverse interpolation strategy (RIS)
In order to further enhance the local exploration capability of the original SMA, a reverse interpolation strategy (RIS) is proposed, which combines elite opposition-based learning and quadratic interpolation. The RIS makes it easy for population individuals to jump out of local optimal solutions.
Opposition-based learning (OBL) is an optimization mechanism that was first proposed by Tizhoosh in 2005 whose main principle is to compute and evaluate the inverse solution simultaneously for the current feasible solution and select the better solution as the next generation individual. Elite opposition-based learning (EOBL) expands the search space based on the former by exploiting the fact that elite individuals include richer effective information than general individuals.
Assuming that the elite individual of the slime mould population at the th iterations (i.e., the current optimal solution) is , where is the dimension of the search space, the expression of its elite opposition solution is shown in Equation (6).
where is the random value that follows the normal distribution in the interval [0, 1]; and are the upper and lower bounds of the search space, respectively.
When the generated elite inverse solution exceeds the maximum boundary range of the search space, the out-of-bounds reset is performed using the random generation method, whose expression is shown in Equation (7).
In order to further enhance the utility of EOBL and improve the global search capability of the algorithm, the quadratic interpolation method is introduced to further update the elite solutions obtained by EOBL.
Assuming that and are the two randomly selected slime mould individuals at the th iteration and different from and , then the fitness values of , and elite opposition solution are , and . The expression of the solution after the quadratic interpolation is shown in Equation (8).
When the generated solution after quadratic interpolation is not as good as the elite inverse solution, it is selected according to the expression shown in Equation (9).
(3) Overview of MSMA
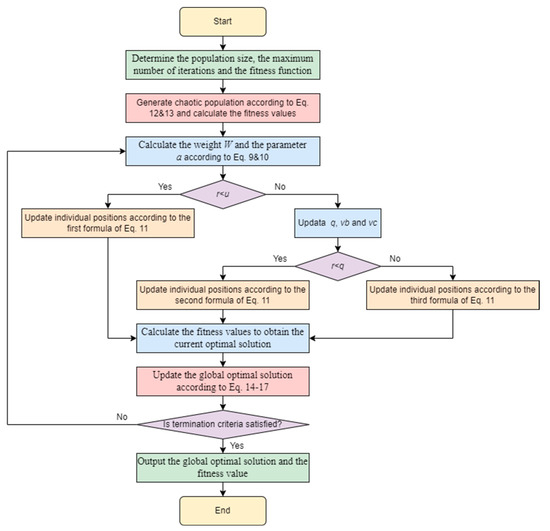
The flow chart of the MSMA is shown in Figure 3, and the specific steps are summarized as follows.
Figure 3.
The flow chart of MSMA.
Step 1: Determine the population size, the maximum number of iterations and the fitness function.
Step 2: Generate chaotic initialized population individuals according to Equations (4) and (5) and calculate the fitness values.
Step 3: Calculate the weight and the parameter according to Equations (1) and (2).
Step 4: Generate random number , and then judge the size of random value and parameter ; if , then update the individual position according to the first formula of Equation (3); otherwise, update parameters , , . Judge the size of and parameter ; if , then update the individual position according to the second formula of Equation (3); otherwise, update the individual position according to the third formula of Equation (3).
Step 5: Calculate the fitness values to obtain the current optimal solution.
Step 6: Update the global optimal solution according to Equations (6)–(9).
Step 7: Determine whether the end condition is satisfied, and if so, output the global optimal solution and the fitness value; otherwise, repeat steps 2–6.
3.2. Experiments
In order to demonstrate the performance of the MSMA, ten benchmark testing functions are chosen from the CEC-2005 functions, and two classical constrained optimization problems are employed in this subsection. All the experiments including those in Section 4 are implemented on 11th Gen Intel(R) Core (TM) i7-11800H @ 2.30 GHz 2.30 GHz Processor and 32 GB RAM. All algorithms are coded and carried out in Python version 3.9 and Windows 11 Professional.
3.2.1. Benchmark Testing Functions
The ten benchmark testing functions are shown in Table 2, where F1–F5 are single-peak testing functions and F6–F10 are multi-peak testing functions. The single-peak testing function has only one global optimal solution, which is mainly used to test the convergence speed and exploitation capability of the optimization algorithm. The multi-peak testing function has not only one global optimal solution, but also several local optimal solutions, which are mainly used to test the ability to jump out of the local optimal solution and the exploration capability of the optimization algorithm. In addition, five meta-heuristic algorithms are used to compare with the MSMA, including the original SMA [40], butterfly optimization algorithm (BOA) [44], whale optimization algorithm (WOA) [45], seagull optimization algorithm (SOA) [46] and sparrow search algorithm (SSA) [47]. According to references [40,44,45,46,47], parameters of the five algorithms are given in Table 3. For each testing function, the optimization algorithm runs independently 30 times. Three metrics are used to test the performance of the MSMA and other algorithms in terms of the mean, standard deviation (S.D.) and running time. The mean is the average of thirty optimum fitness values, and the running time is the average running time of thirty experiments. The population size of every algorithm is 50, and the maximum iteration number is 500. These testing functions are set to 30, 50 and 100 dimensions, separately. The experimental results are denoted from Table 4, Table 5 and Table 6.
Table 2.
The description of ten benchmark testing functions.
Table 3.
Parameters setting of six optimization algorithms.
Table 4.
The comparison metrics for six algorithms on 30 dimensional functions.
Table 5.
The comparison metrics for six algorithms on 50 dimensional functions.
Table 6.
The comparison metrics for six algorithms on 100 dimensional functions.
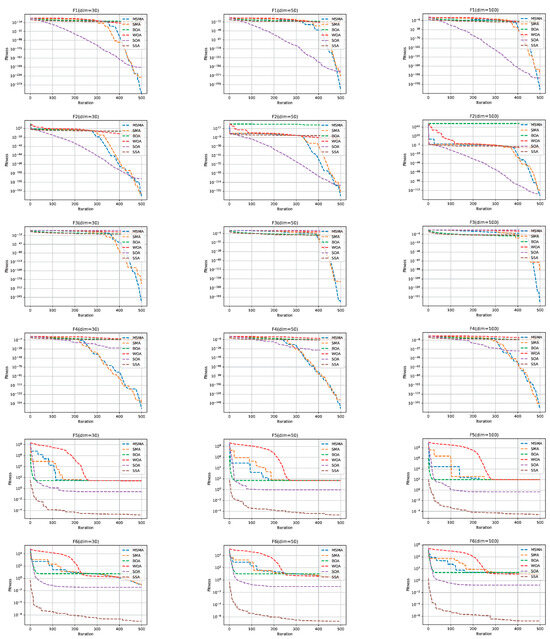
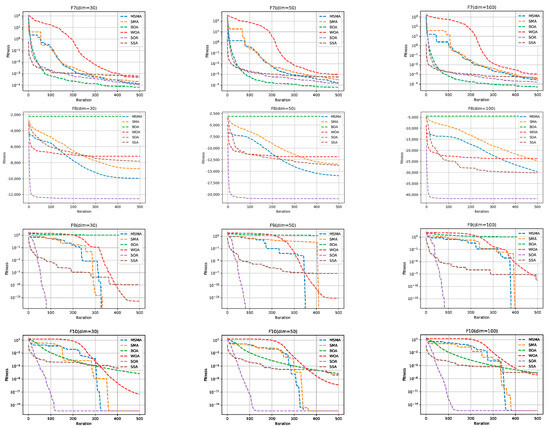
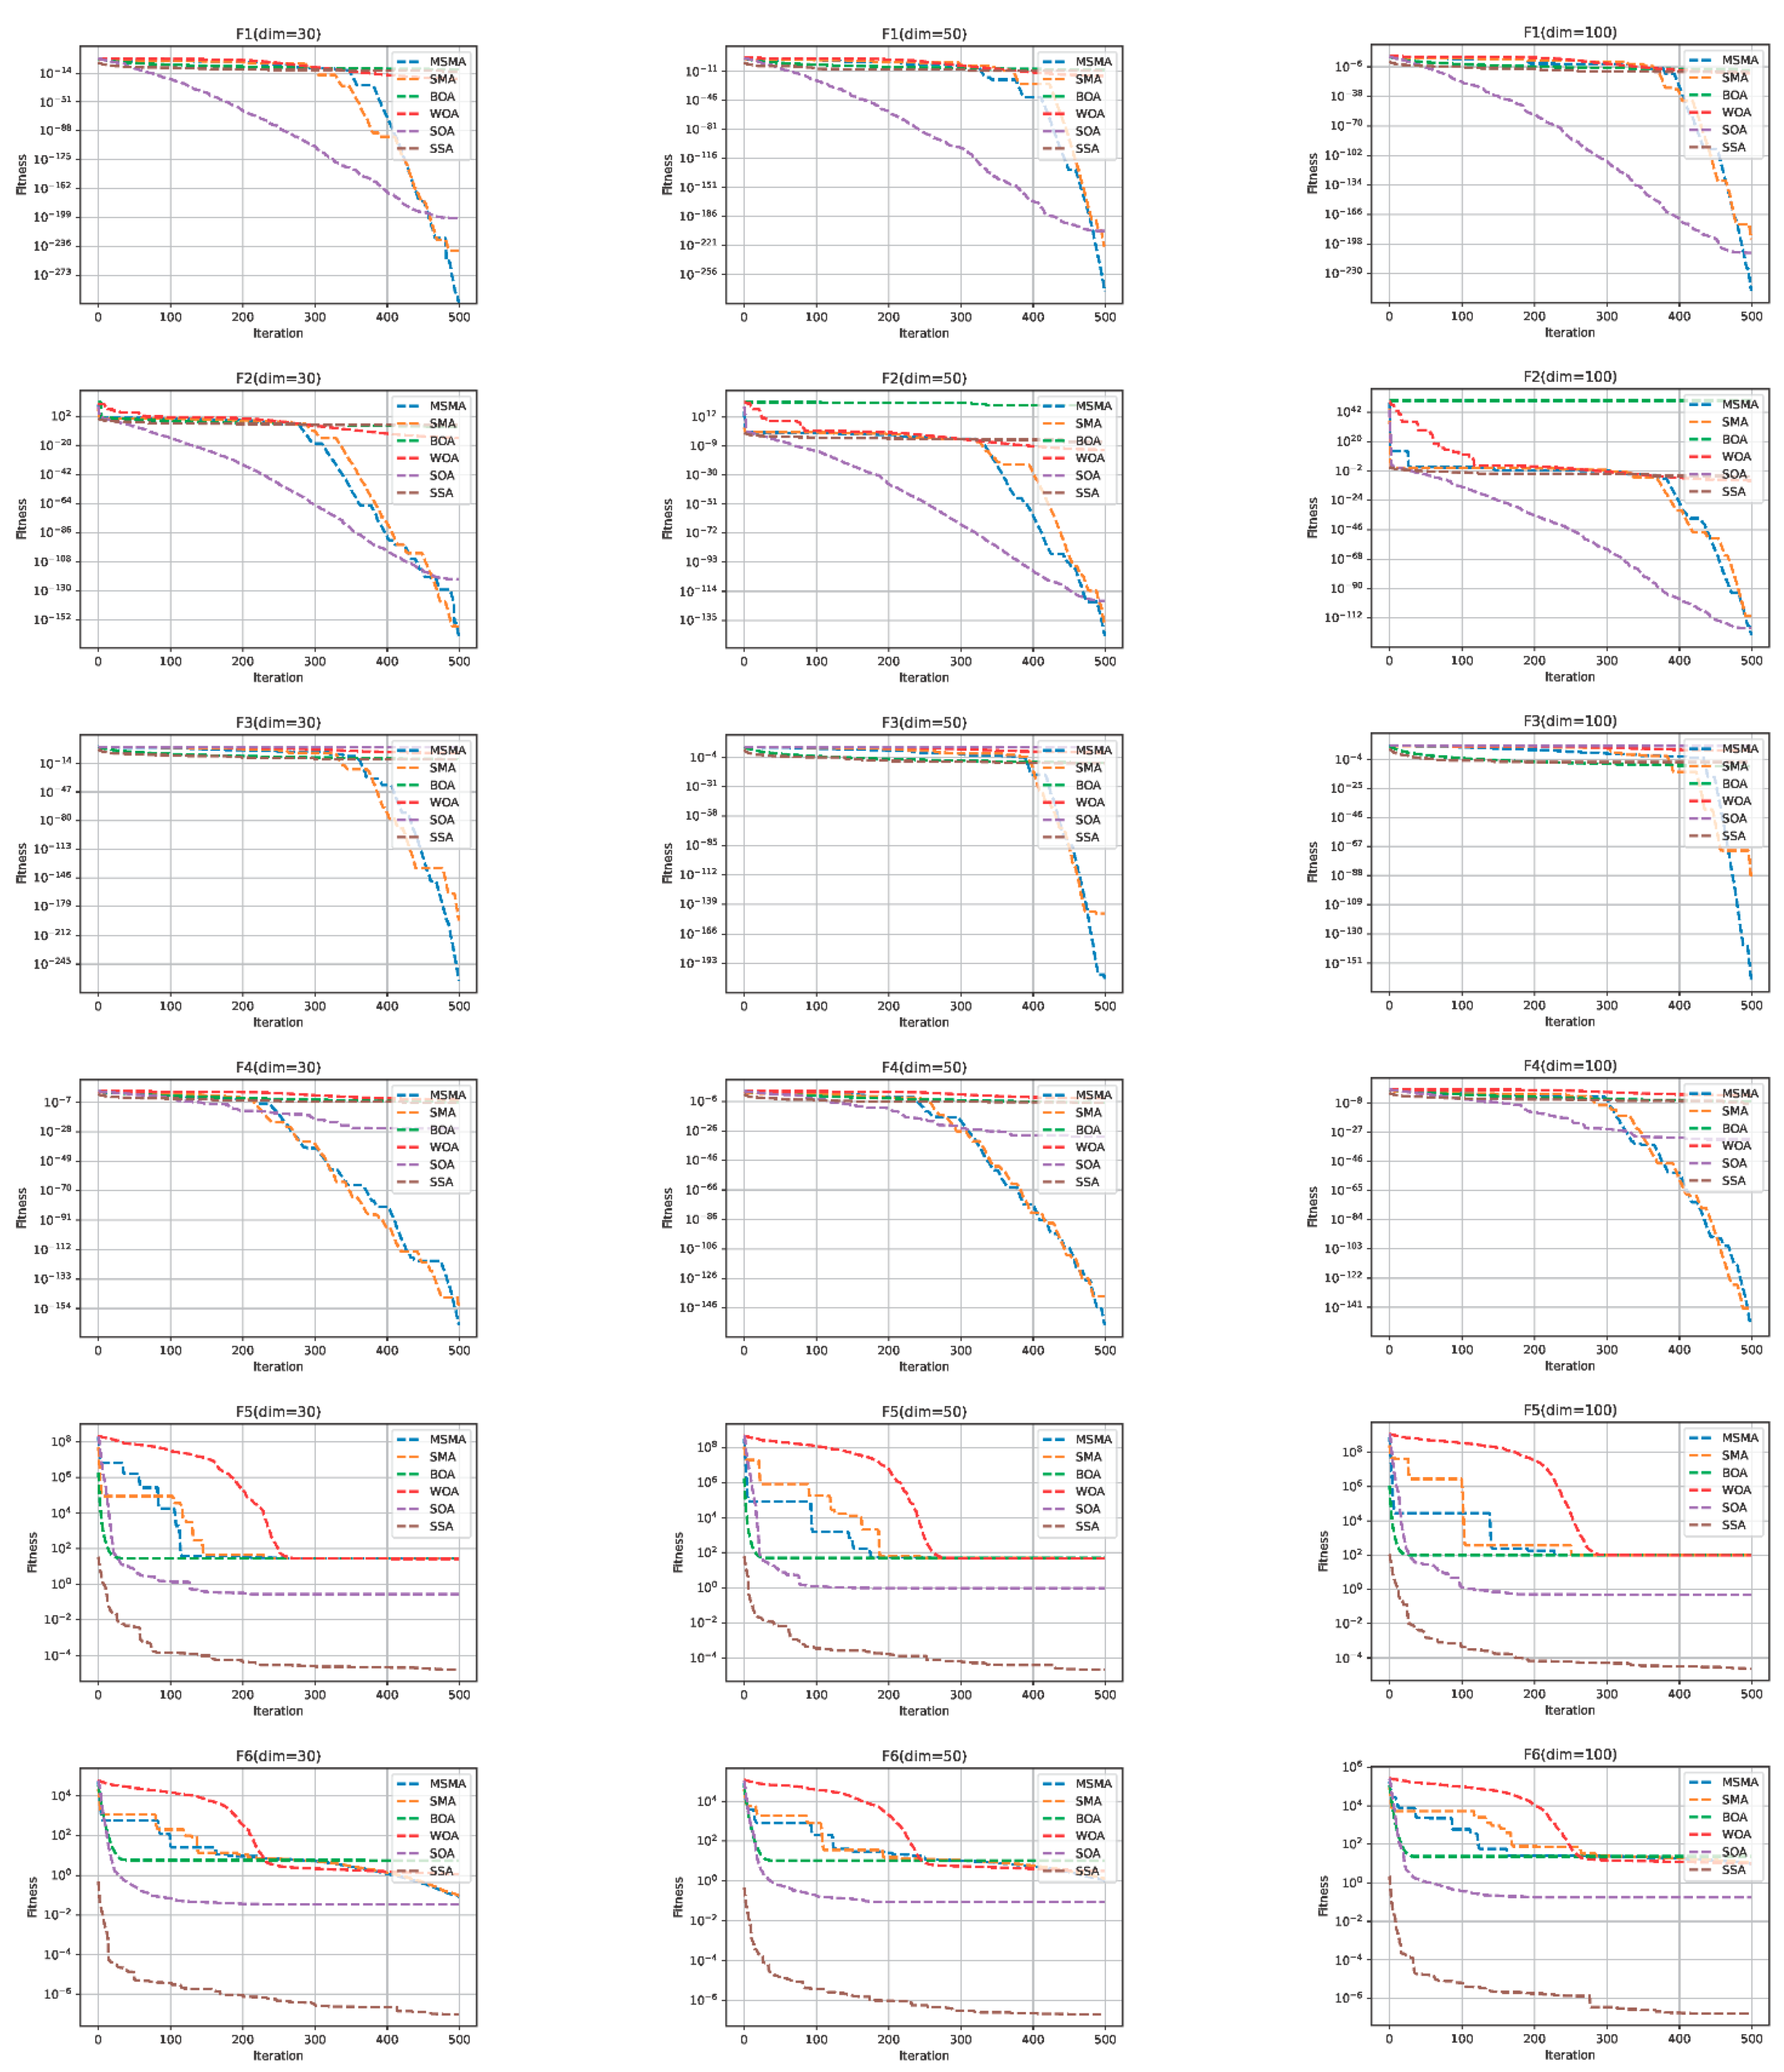
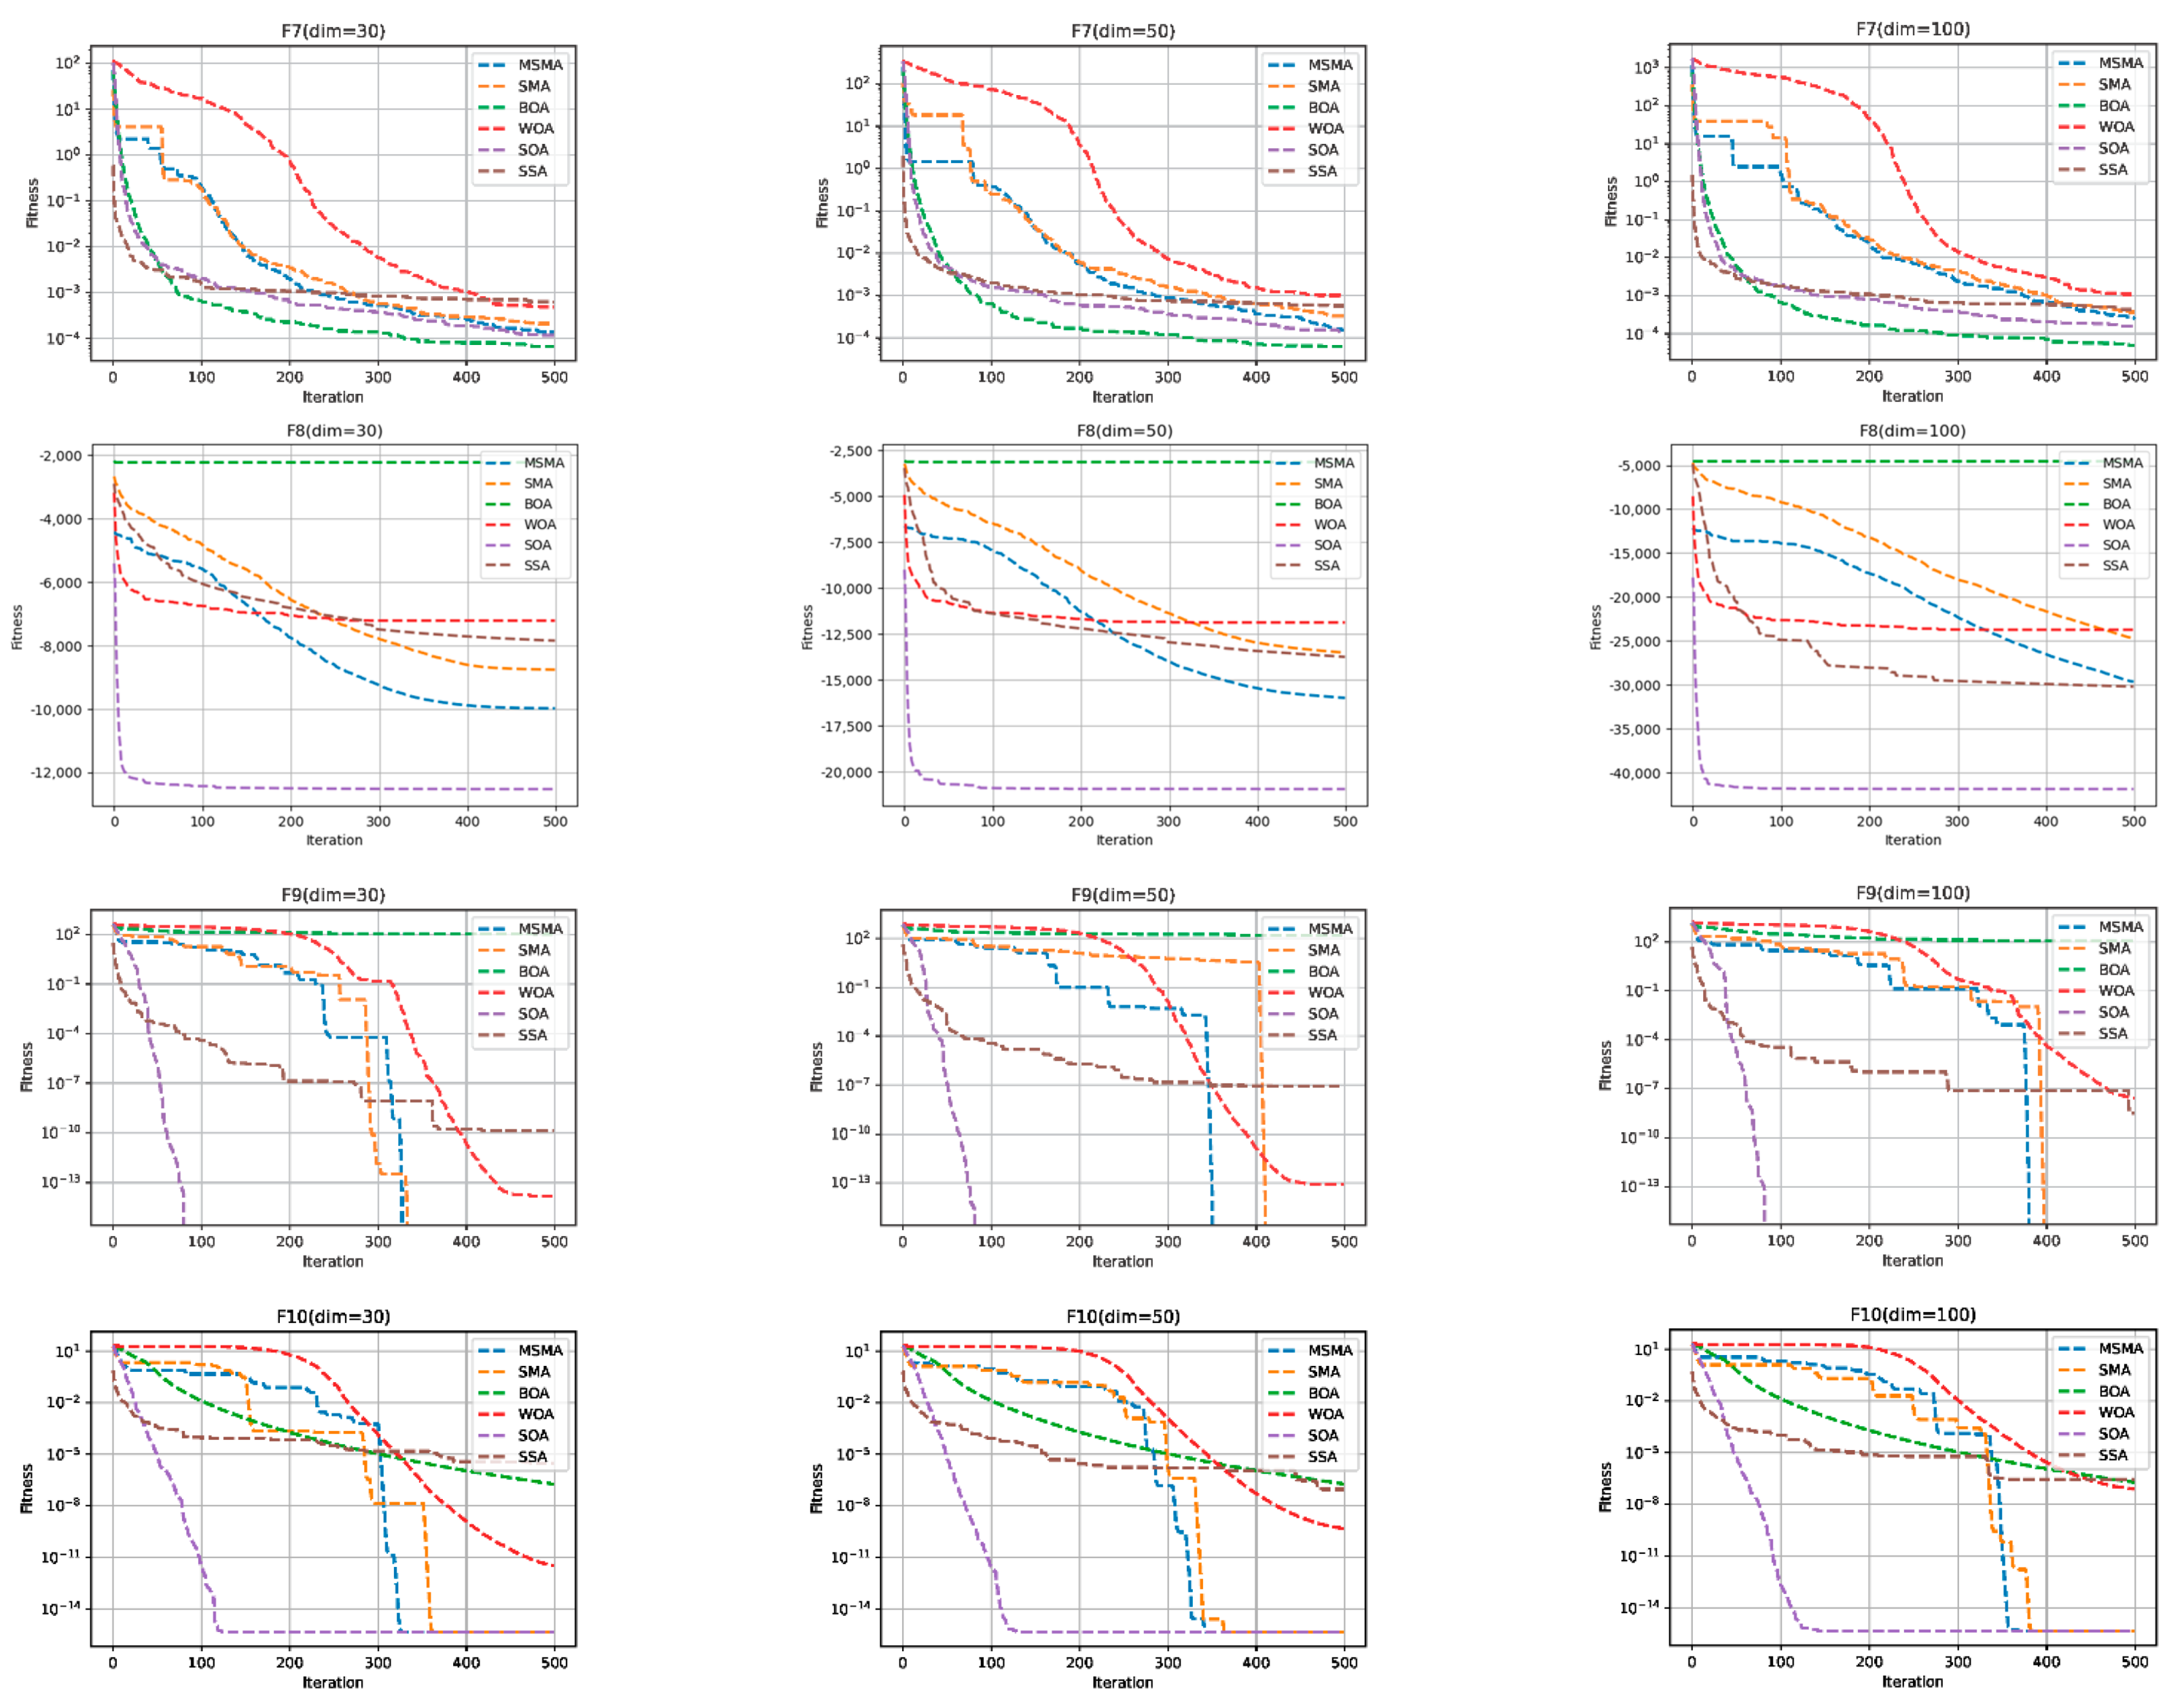
The best optimal solutions in terms of the mean, standard deviation and running time are shown in boldface. And it is noted that the smaller the value of these statistics metrics, the better the performance of the optimization algorithm. In addition, the convergence curves of the MSMA and other algorithms are shown in Figure 4.
Figure 4.
The convergence curves of six algorithms on 30, 50 and 100 dimensional functions.
As can be seen from Table 4, Table 5 and Table 6 and Figure 4, the MSMA has the lowest mean and lowest standard deviation of all the methods on functions F1, F2, F3, F4, F9 and F10. The SSA has the smallest mean and standard deviation for functions F5 and F6. The BOA has the smallest mean and standard deviation for function F7. The SOA has the smallest mean and standard deviation for function F8. And the SOA has the shortest calculation time of all the algorithms for all functions. For the functions F5, F6, F7 and F8, although the MSMA does not obtain the best model performance, it outperforms the original SMA in both mean and standard deviation.
3.2.2. Constrained Optimization Problem
(1) Optimal design of three-bar truss problem
In the optimal design of the three-bar truss problem, the variables , and are the cross-sectional areas of the three bars, respectively, and by symmetry . And the objective of the optimal design of the three-bar truss is to minimize the volume of the three-bar truss by adjusting the cross-sectional area . This optimal design problem has a nonlinear fitness function, three nonlinear inequality constraints and two continuous decision variables, as shown in Equations (10)–(15).
Fitness function:
Constraints:
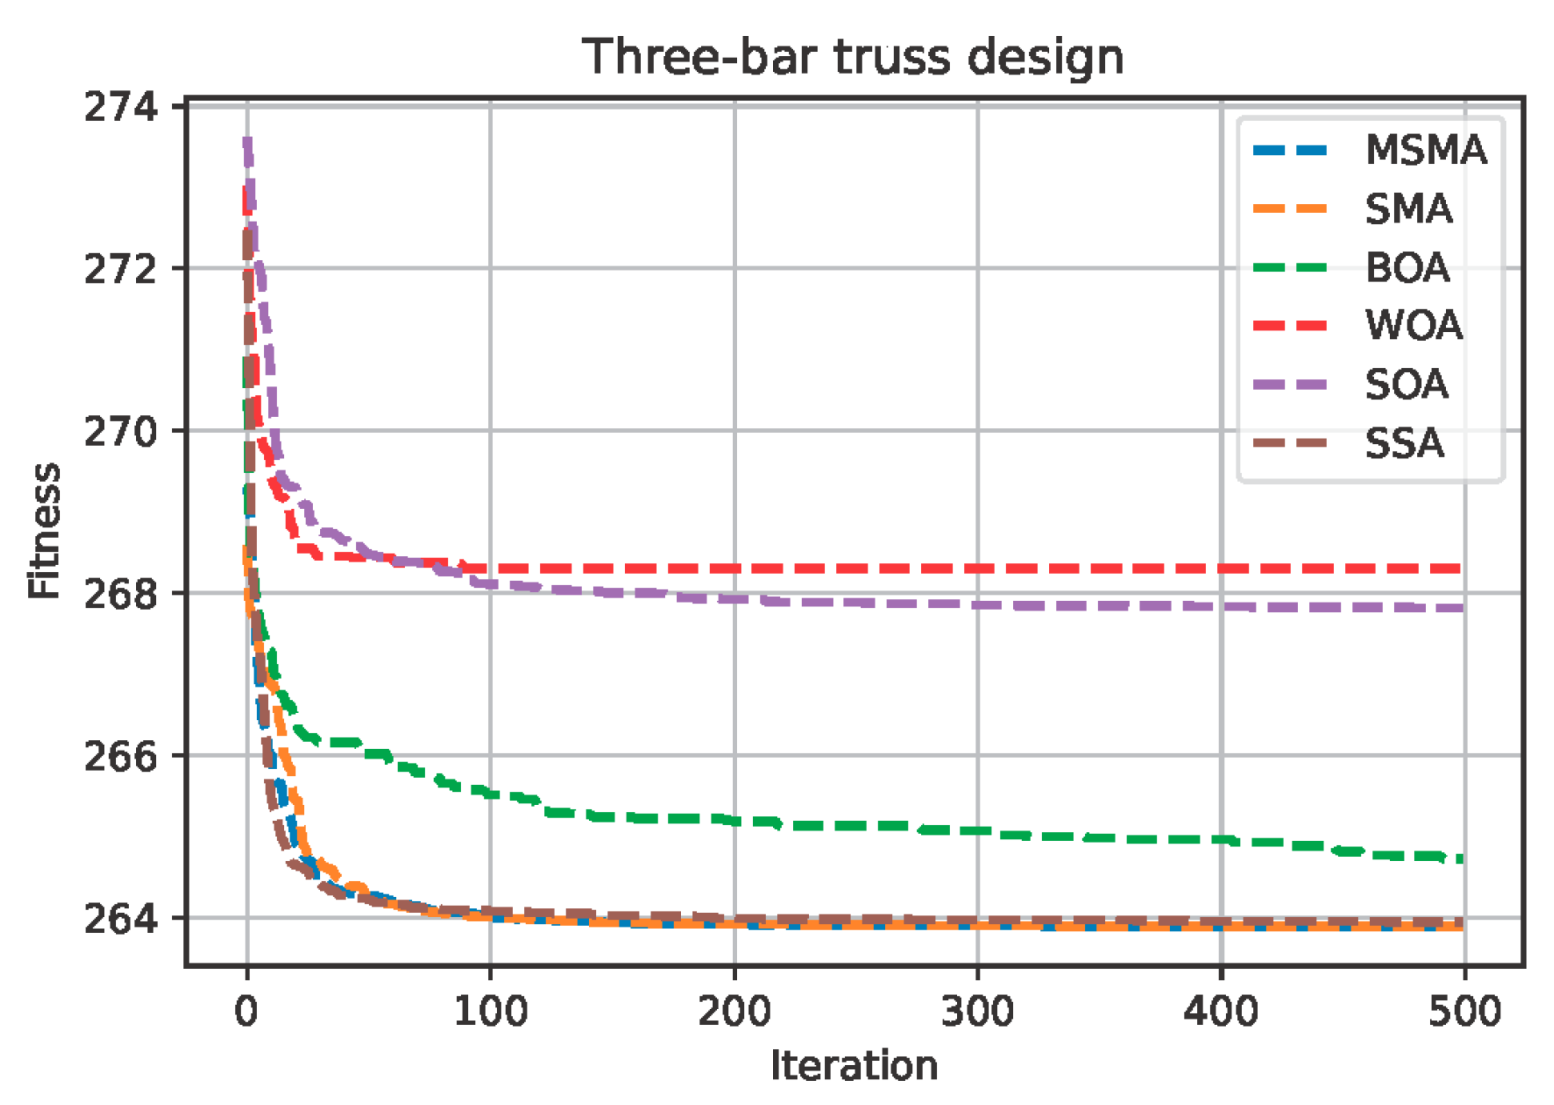
The optimal solutions of the MSMA and the other algorithms used for comparison on the optimal design of the three-bar truss problem are shown in Table 7, and the convergence curve of six algorithms on this optimal design problem is shown in Figure 5.
Table 7.
The comparison of model performance for six algorithms on the optimal design of three-bar truss problem.
Figure 5.
The convergence curve of six algorithms on the optimal design of three-bar truss problem.
As can be seen from Table 7 and Figure 5, the MSMA has the lowest mean and standard deviation of all the methods, and the WOA has the shortest running time.
(2) Optimal design of tension–compression spring problem
In the optimal design of the tension–compression spring problem, the variables , and are the spring coil diameter, spring coil diameter and number of coils wound, respectively. The objective of the optimal design of the tension–compression spring is to minimize the weight of the tension–compression spring while meeting the minimum deflection, vibration frequency and shear stress. This optimal design problem has a nonlinear fitness function, four nonlinear inequality constraints and three continuous decision variables, as shown in Equations (16)–(23).
Fitness function:
Constraints:
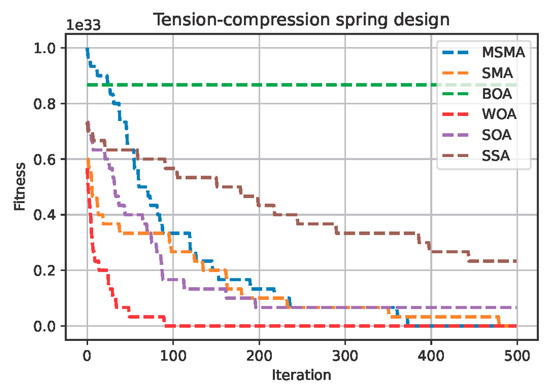
The optimal solutions of the MSMA and the other algorithms used for comparison on the optimal design of the tension–compression spring problem are shown in Table 8. And the convergence curves of six algorithms on this optimal design problem are shown in Figure 6.
Table 8.
The comparison of model performance for six algorithms on the optimal design of tension–compression spring problem.
Figure 6.
The convergence curve of six algorithms on the optimal design of tension–compression spring problem.
As can be seen from Table 8 and Figure 6, the WOA has the lowest mean, lowest standard deviation and shortest calculation time of all the methods for this optimal design problem. Although the MSMA did not obtain the best model performance for this optimal design problem, it outperforms the original SMA on both the mean and standard deviation.
3.3. Discussion and Analysis
By solving the ten benchmark testing functions and two constrained optimization problems, the experimental results reveal that the MSMA is an effective meta-heuristic algorithm. The MSMA is good at handling the single-peaked function extremum problems, because it can obtain the optimal solution on four single-peaked functions F1, F2, F3 and F4. The MSMA needs to be further enhanced in handling multi-peaked function extremum problems because it can only obtain the optimum solution on two multi-peaked functions, F9 and F10. Although the MSMA did not obtain the optimal solution on functions F5, F6, F7, and F8, it outperformed the original SMA for all four functions. In addition, the MSMA also showed good performance on two constrained optimization problems.
The time complexity of calculating the SMA depends on the following aspects: population initialization of slime mould, evaluation and ranking of fitness values, weight update, and position update of slime mould individuals. Since the slime mould population size is , the research problem dimension is , and the maximum number of iterations is , the time complexity of the original SMA is according to the description of the SMA and the operation rules of time complexity. For the MSMA, the time complexity of ICMIC chaotic mapping to initialize the slime mould population is , the time complexity of the fitness evaluation and ranking is , the time complexity of the weight update is , the time complexity of the position update of slime mould individuals is , and the reverse interpolation strategy to generate new positions is ; then, the overall time complexity of the MSMA is . The time complexity of the MSMA is the same as that of the original SMA, indicating that the improved algorithm does not increase the computational burden.
Overall, the MSMA is more effective than the original SMA, and it can obtain better or equivalent convergence accuracy with fewer convergence times without adding much calculation time.
4. Boiler Combustion Optimization
In this section, the proposed multi-objective optimization framework is used to solve the boiler combustion optimization problem. Firstly, the description of boiler operation data is given in Section 4.1. Secondly, the interpretable CatBoost is applied to model the boiler thermal efficiency and NOx emissions concentration in Section 4.2. Based on the established model, data correlation analysis is conducted, determining the range of the parameters to be optimized. In Section 4.4, the proposed MSMA is used to optimize these adjustment parameters for improving thermal efficiency and reducing NOx emission concentration at the same time.
4.1. The Source and Description of Boiler Data
There are mainly 26 input data samples that affect the thermal efficiency (TE) and nitrogen oxide (NOx) emission concentration of the CFBB, including the boiler load, coal feed rate, average bed temperature, air flow, air temperature, etc. The symbols and descriptions of each sample are shown in Table 9. A total of 2880 sets of data were collected from the DCS of the CFBB. Some of these data are shown in Table 10.
Table 9.
Description of feature symbols.
Table 10.
The operation conditions of circulation fluidized bed boiler.
4.2. Modeled by Interpretable CatBoost
In this subsection, the interpretable CatBoost model is used to build a comprehensive model of the boiler thermal efficiency and NOx emissions concentration. In order to evaluate the model superiority of the interpretable CatBoost model, three state-of-the-art methods are employed to compare the model accuracy and generalization capability, including random forest (RF), support vector machine (SVM), and multi-layer perceptron (MLP). The parameter settings of each method are given in Table 11. Four metrics are used to verify the performance of each method, such as root mean square error (RMSE), mean absolute error (MAE), mean absolute percentage error (MAPE) and goodness of fit (R2) of ten-fold cross-validation. For training data, the smaller the parameters (RMSE, MAE and MAPE) and the closer the R2 value is to one, the higher the model accuracy. For testing data, the smaller the parameters (RMSE, MAE and MAPE) and the closer the R2 value is to one, the better the generalization capability.
Table 11.
Parameter settings of four methods.
The data shown in Table 10 were normalized. Then, the total 2880 sets of data were divided into training data and testing data in a ratio of 7:3 according to the rule of ten-fold cross-validation. The experimental results are shown in Table 12.
Table 12.
The experimental results of four models on two objectives.
As shown in Table 12, compared with RF, SVM and MLP, the interpretable CatBoost model can obtain better model accuracy and adequate generalization capability in the feature models established for the thermal efficiency and NOx emissions concentration of the CFBB both on the training set and testing set.
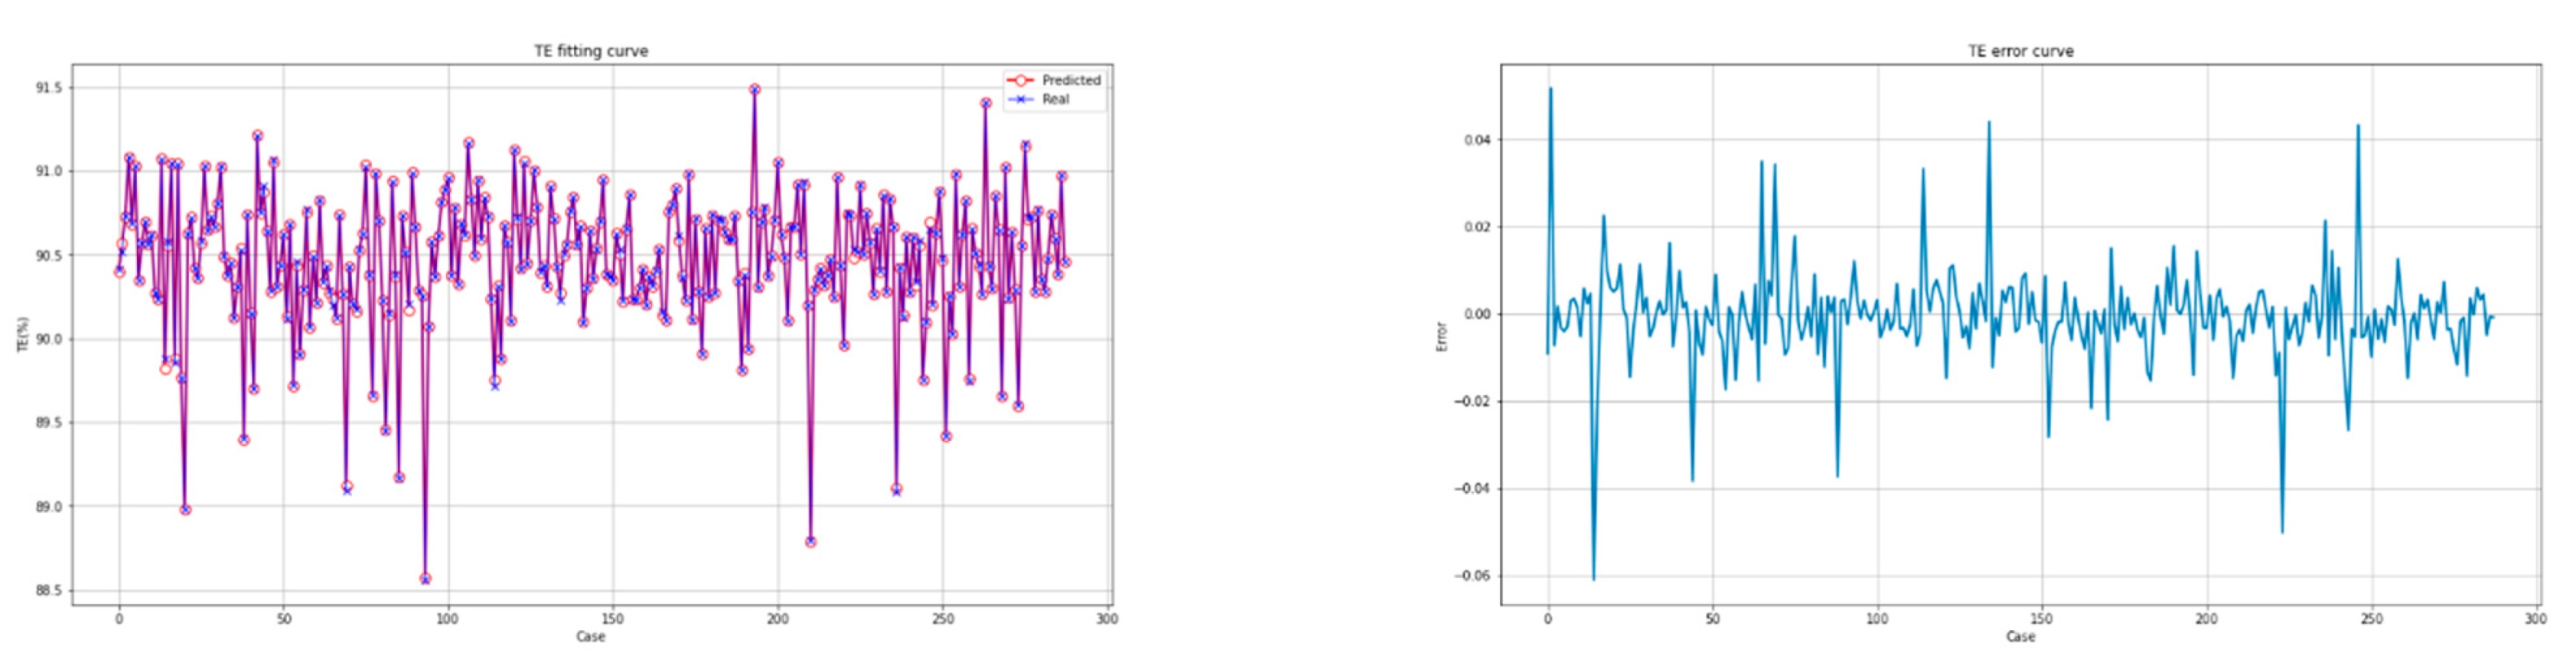
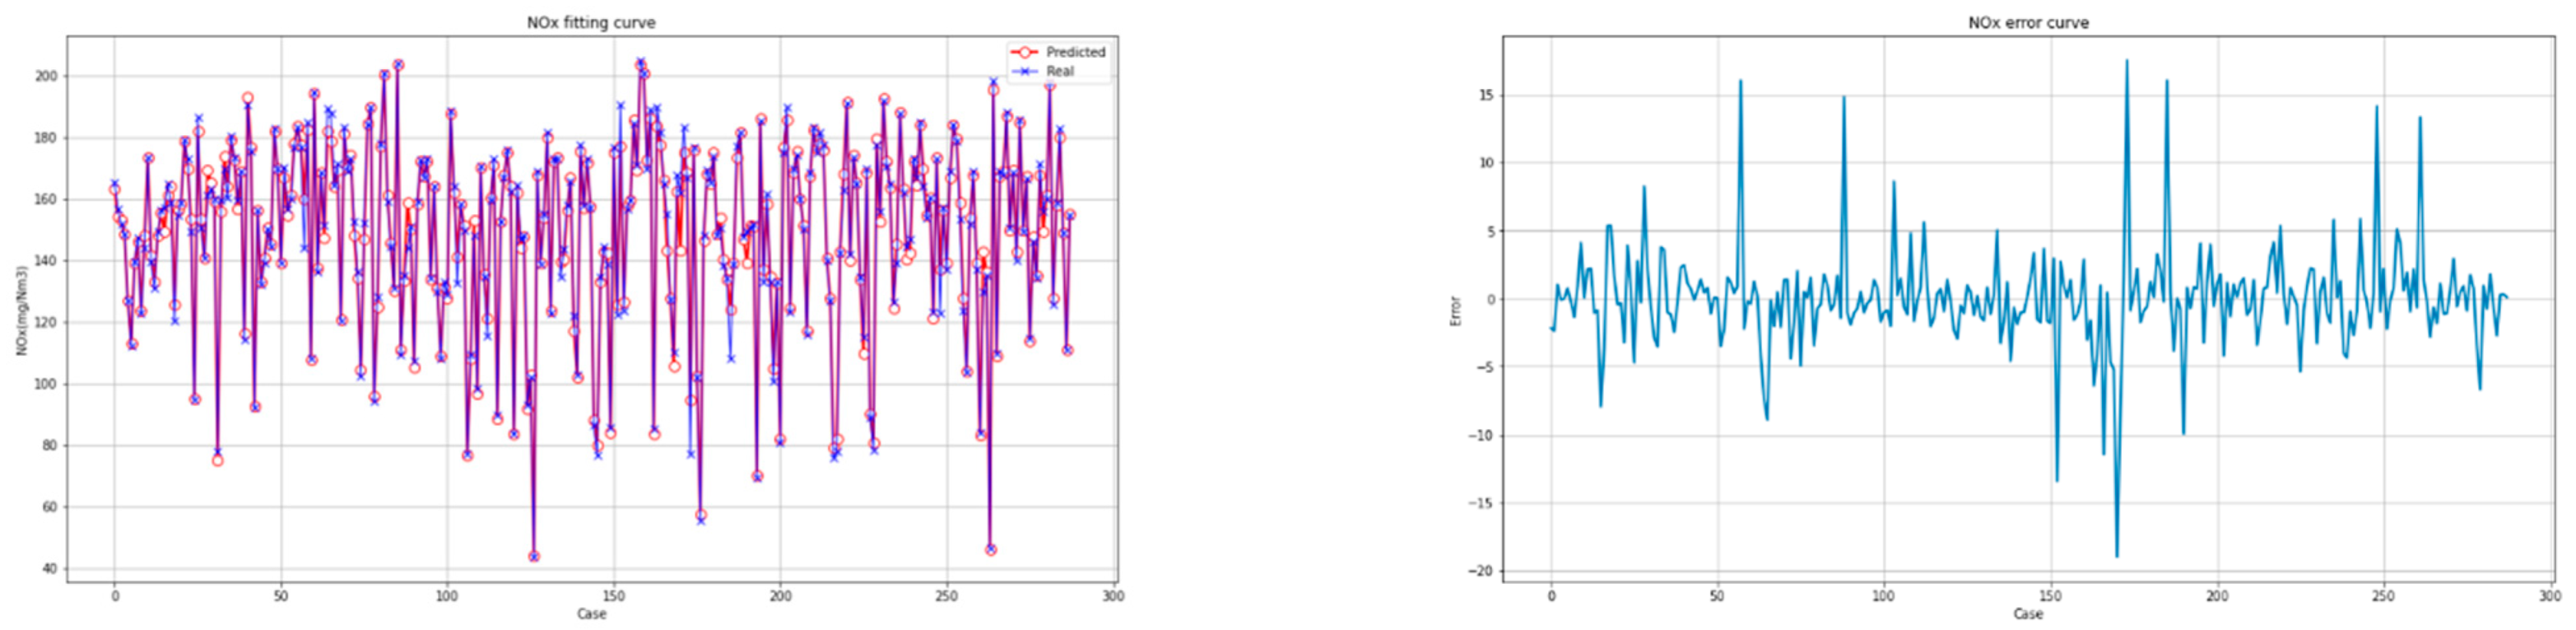
The fitting diagrams and error diagrams of the interpretable CatBoost model for modeling the two objectives of the CFBB on the partial testing set are shown in Figure 7 and Figure 8, where the red line and the blue line in the fitting diagram indicate the predicted values and real values of the partial testing set, and the light blue line in the error diagram represents the error of the predicted values compared to the real values for the partial testing set.
Figure 7.
The fitting diagram and error diagram of the interpretable CatBoost model for modeling the thermal efficiency.
Figure 8.
The fitting diagram and error diagram of the interpretable CatBoost model for modeling the NOx emissions concentration.
4.3. Data Feature Analysis
In response to the weak interpretation of CatBoost, an interpretable method combined TreeSHAP is applied to investigate the effect of the combustion condition of the CFBB on the thermal efficiency and NOx emission concentration.
The feature analysis importance diagram and summary diagram of thermal efficiency are shown in Figure 9.
Figure 9.
The feature analysis importance diagram and summary diagram of thermal efficiency.
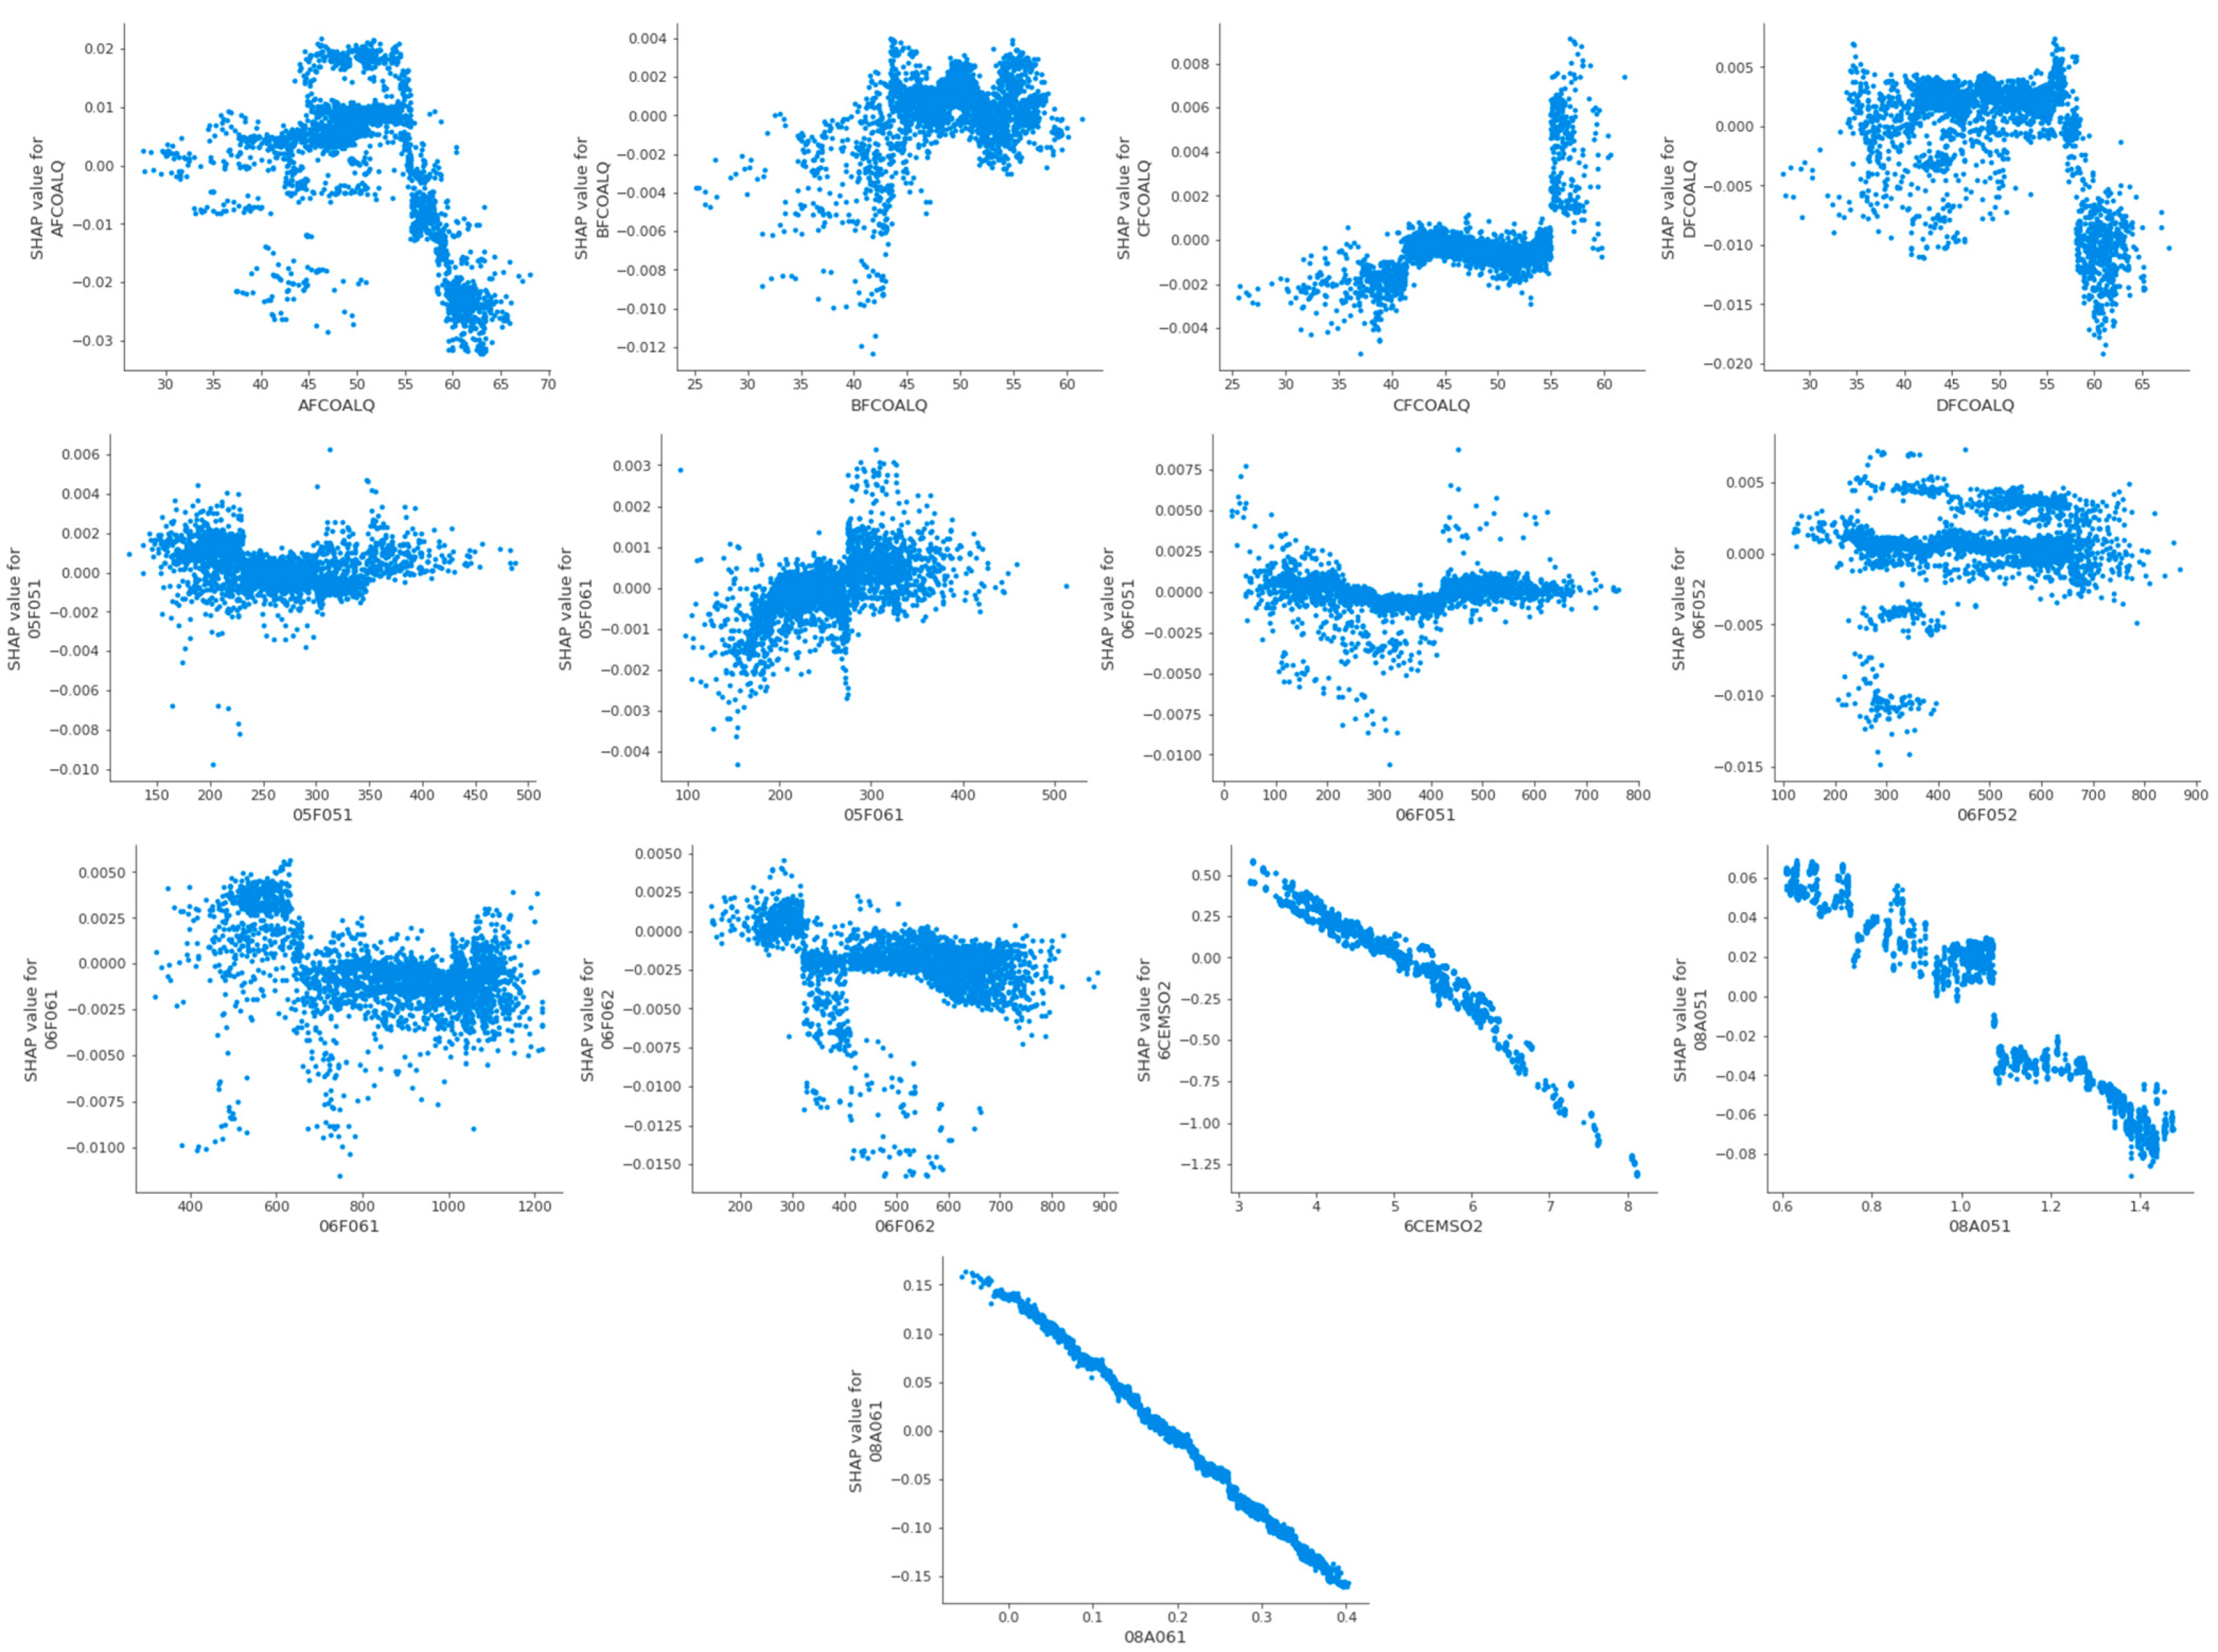
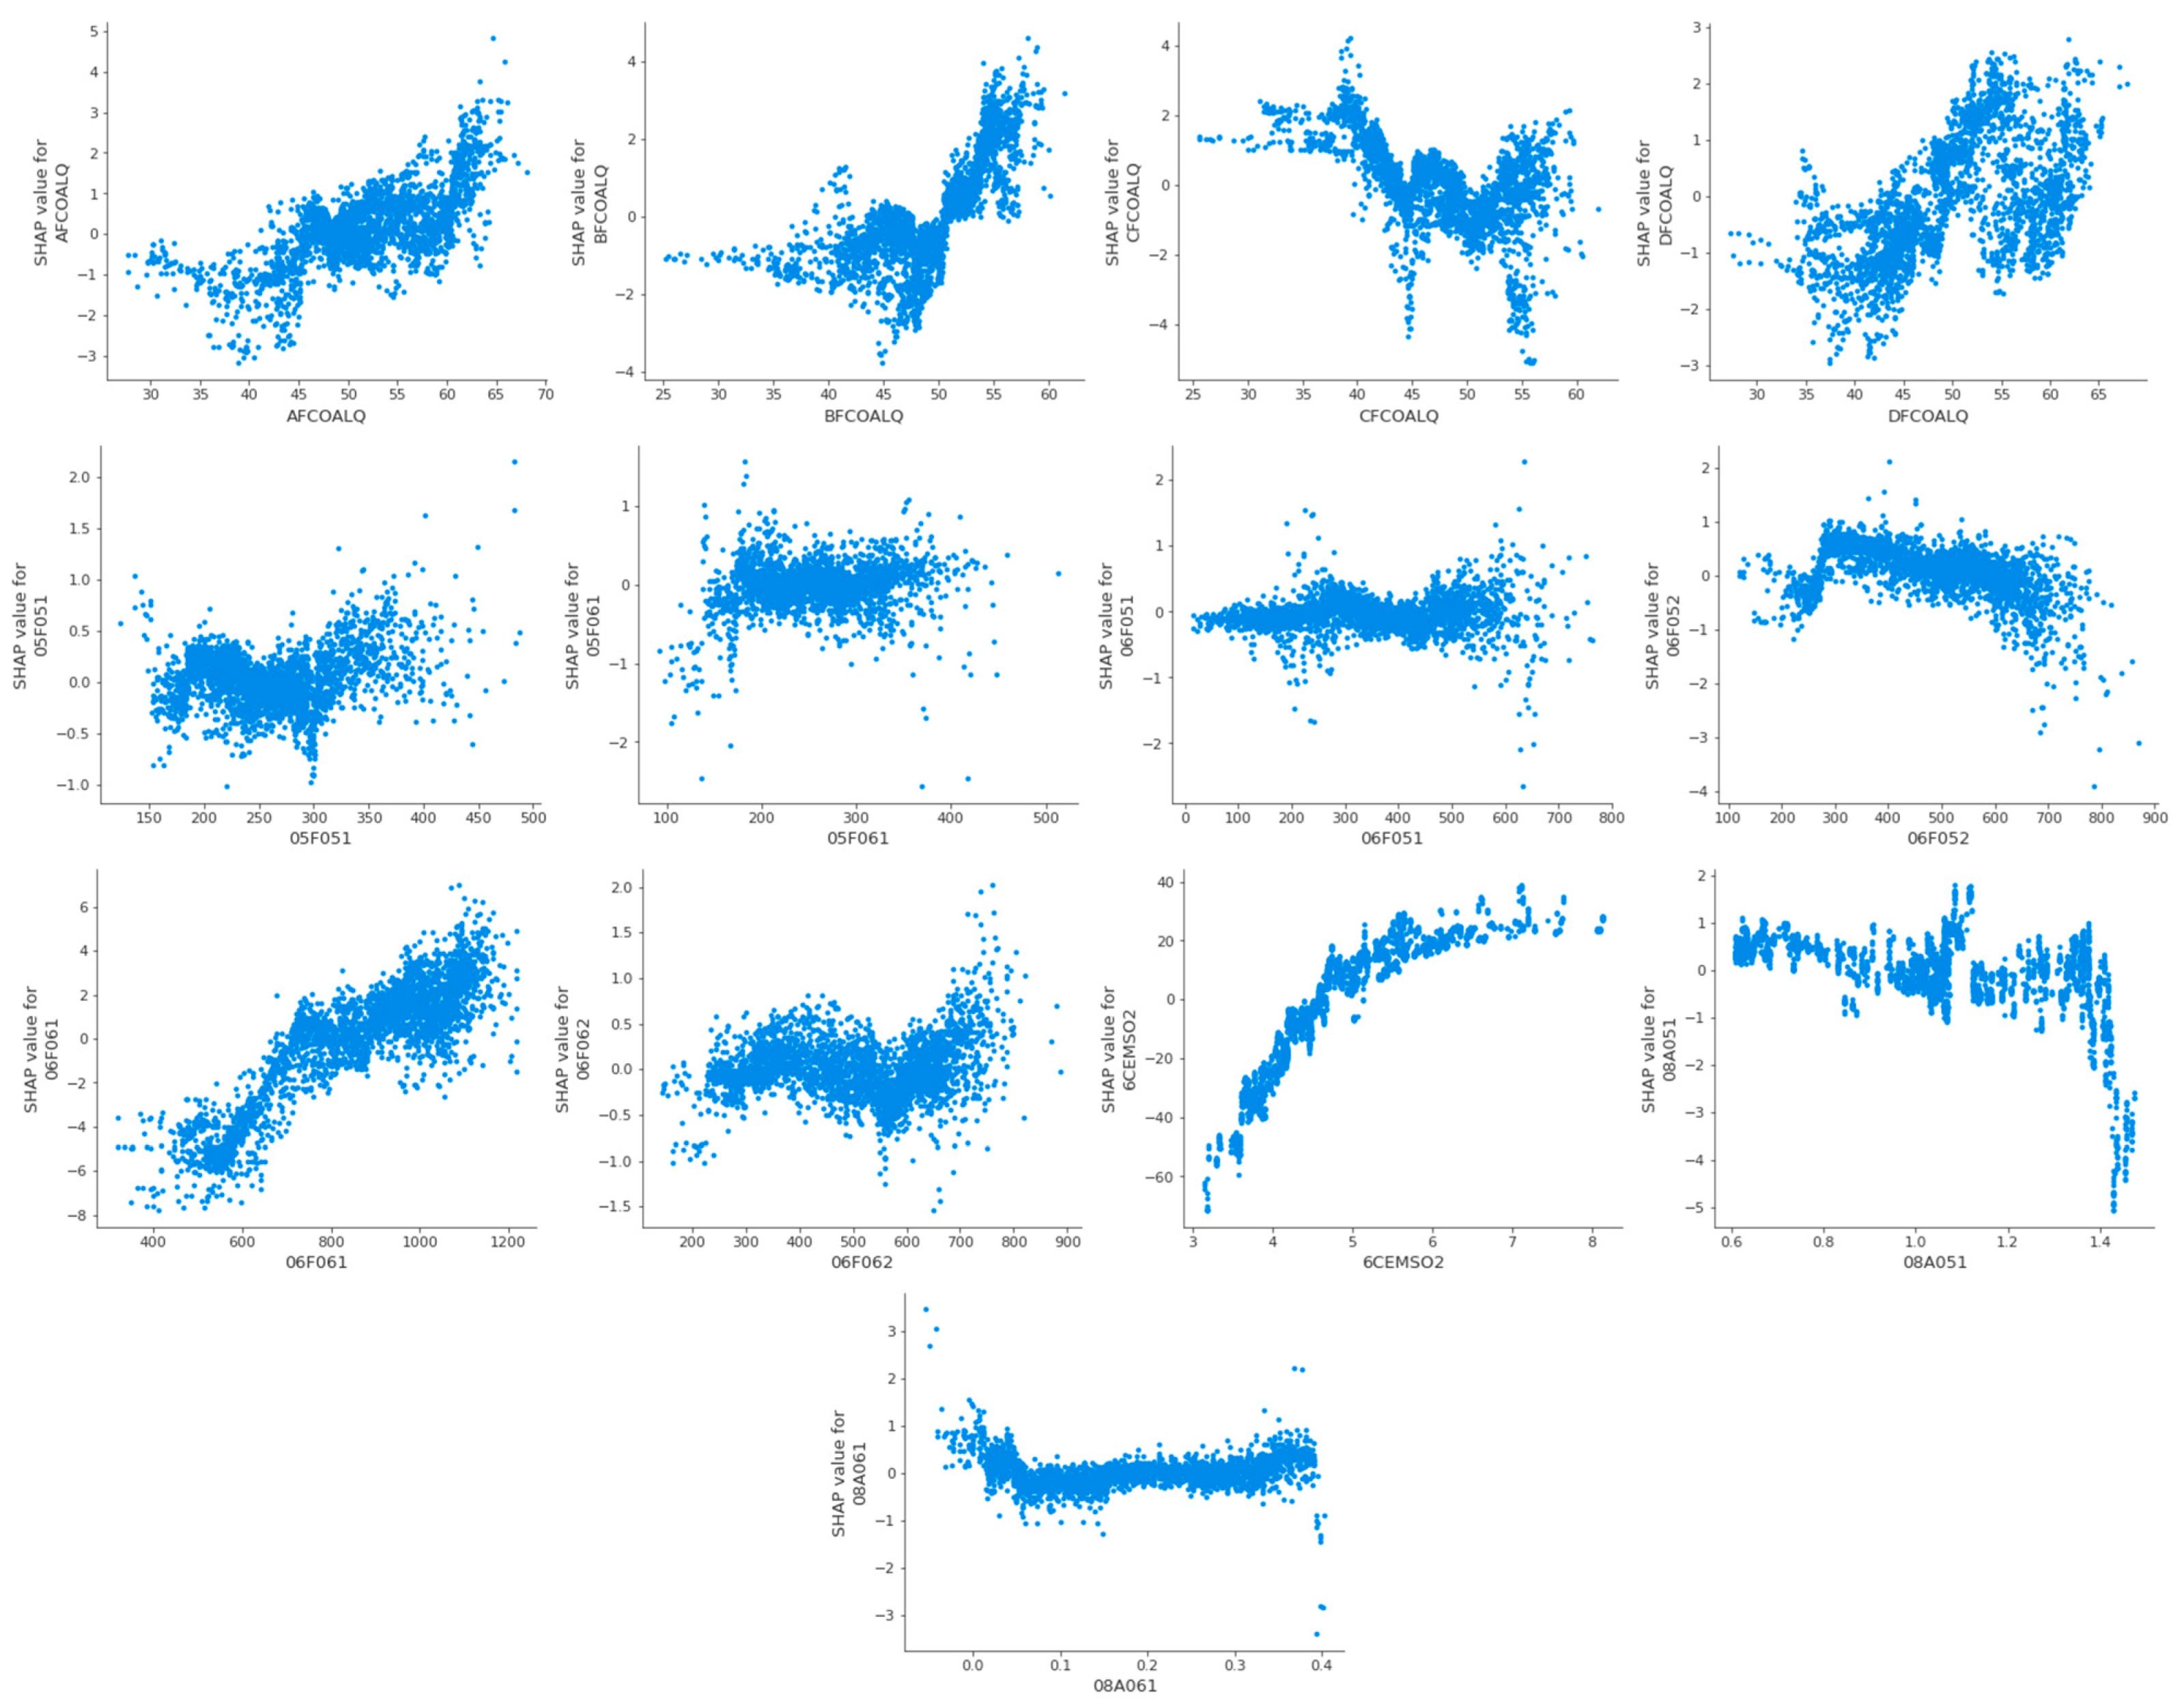
The feature analysis dependency diagram of thermal efficiency is shown in Figure 10.
Figure 10.
The feature analysis dependency diagram of thermal efficiency.
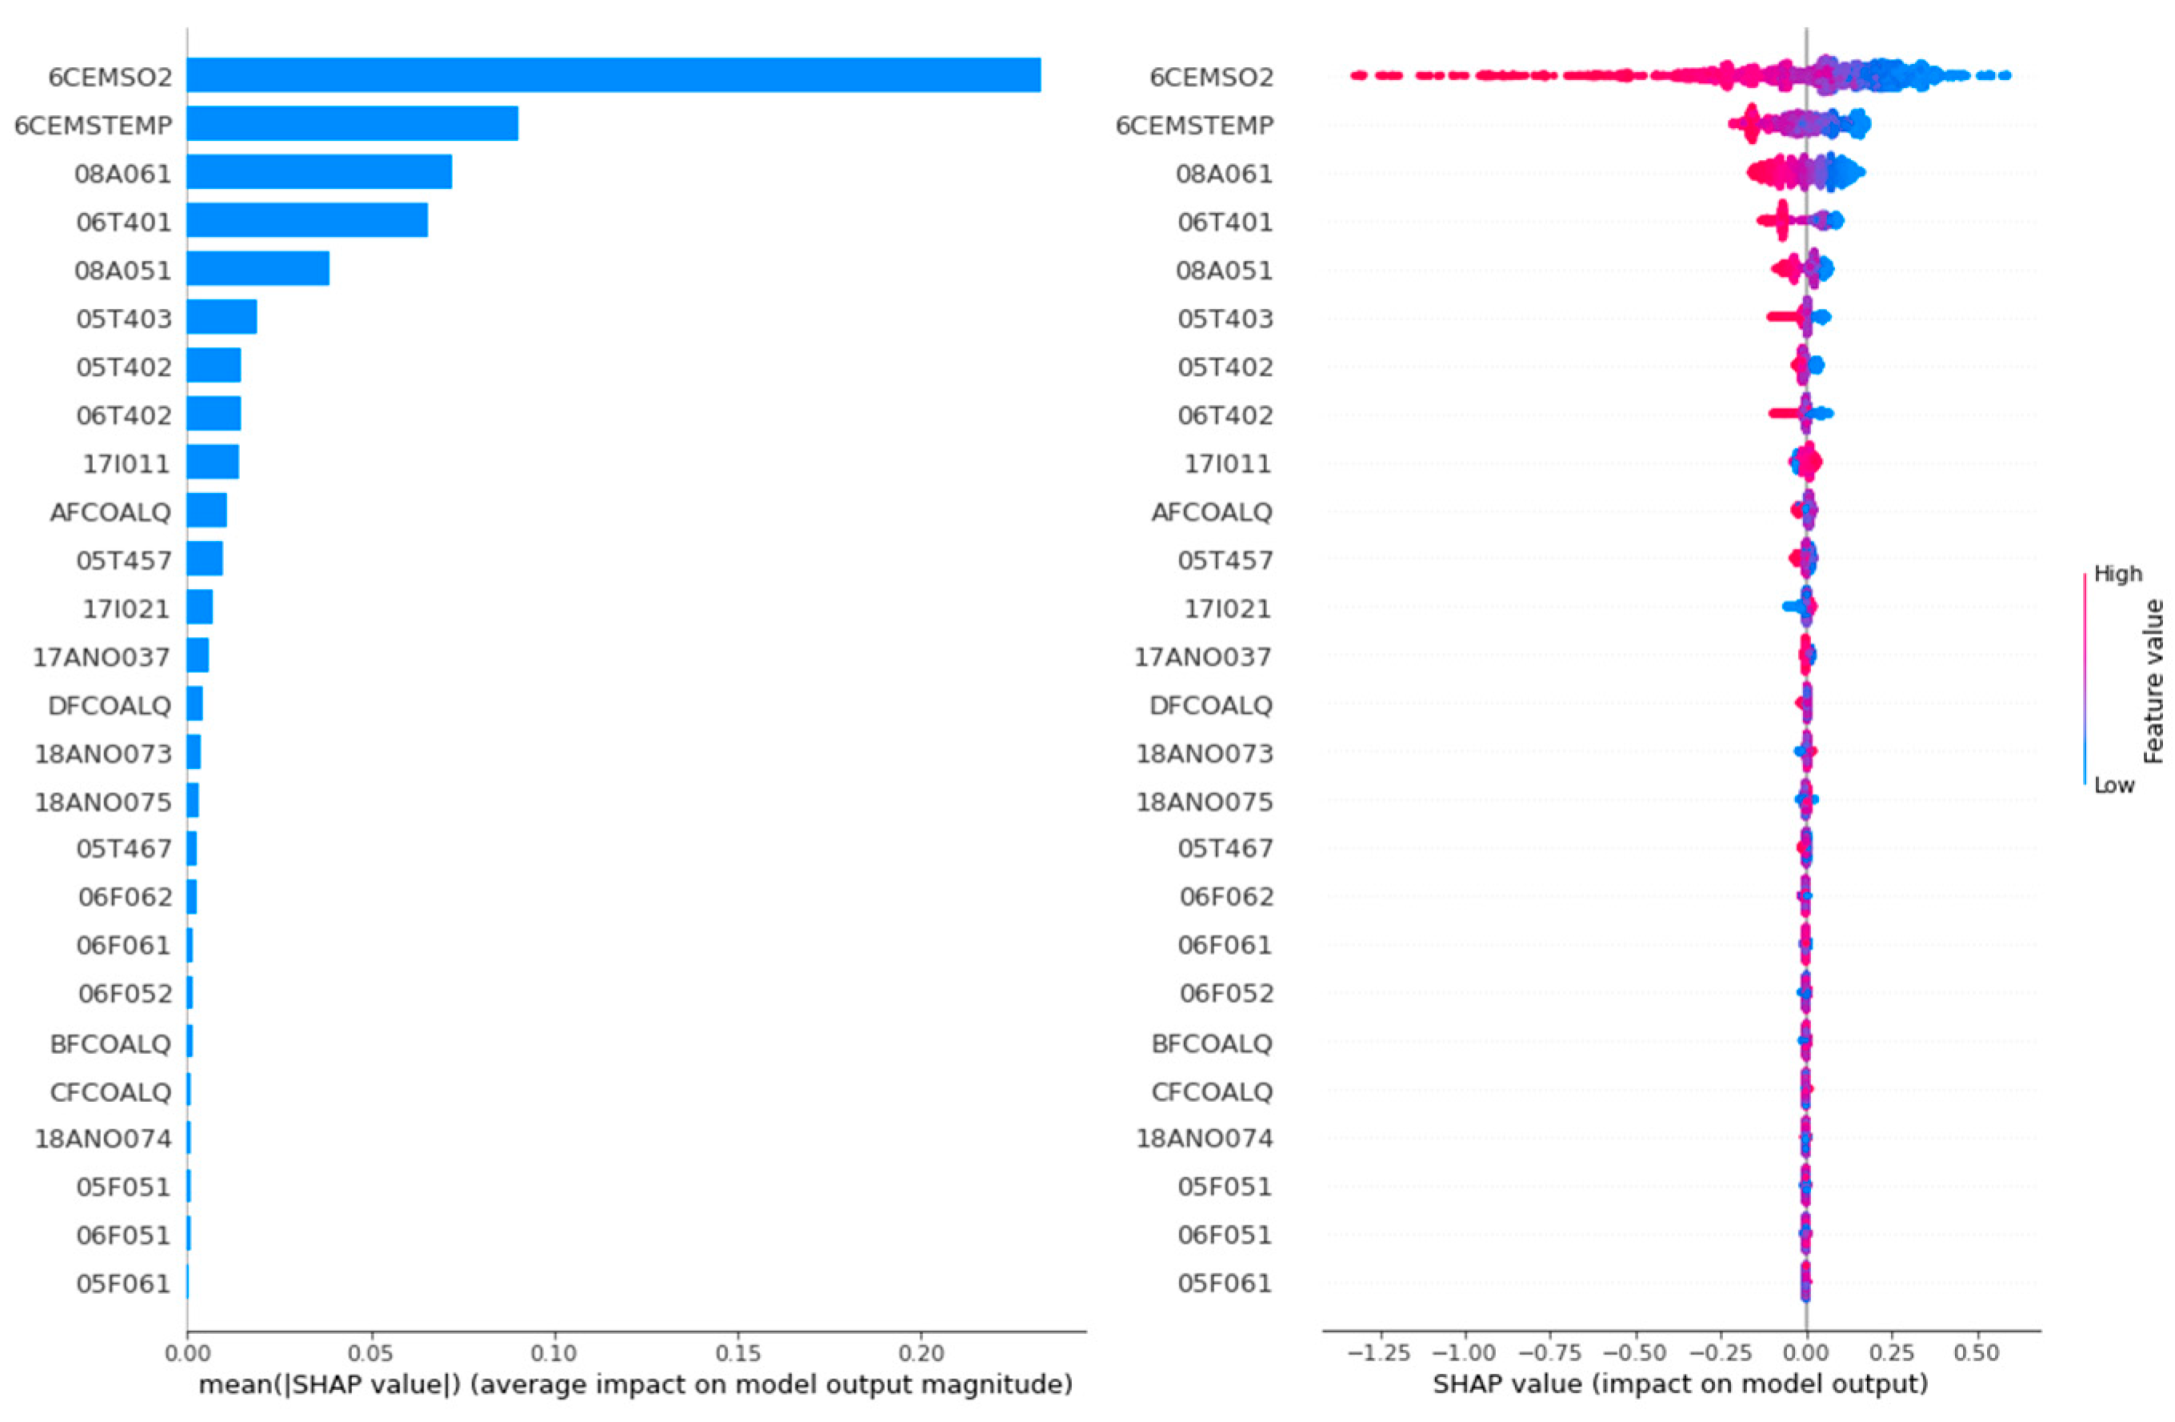
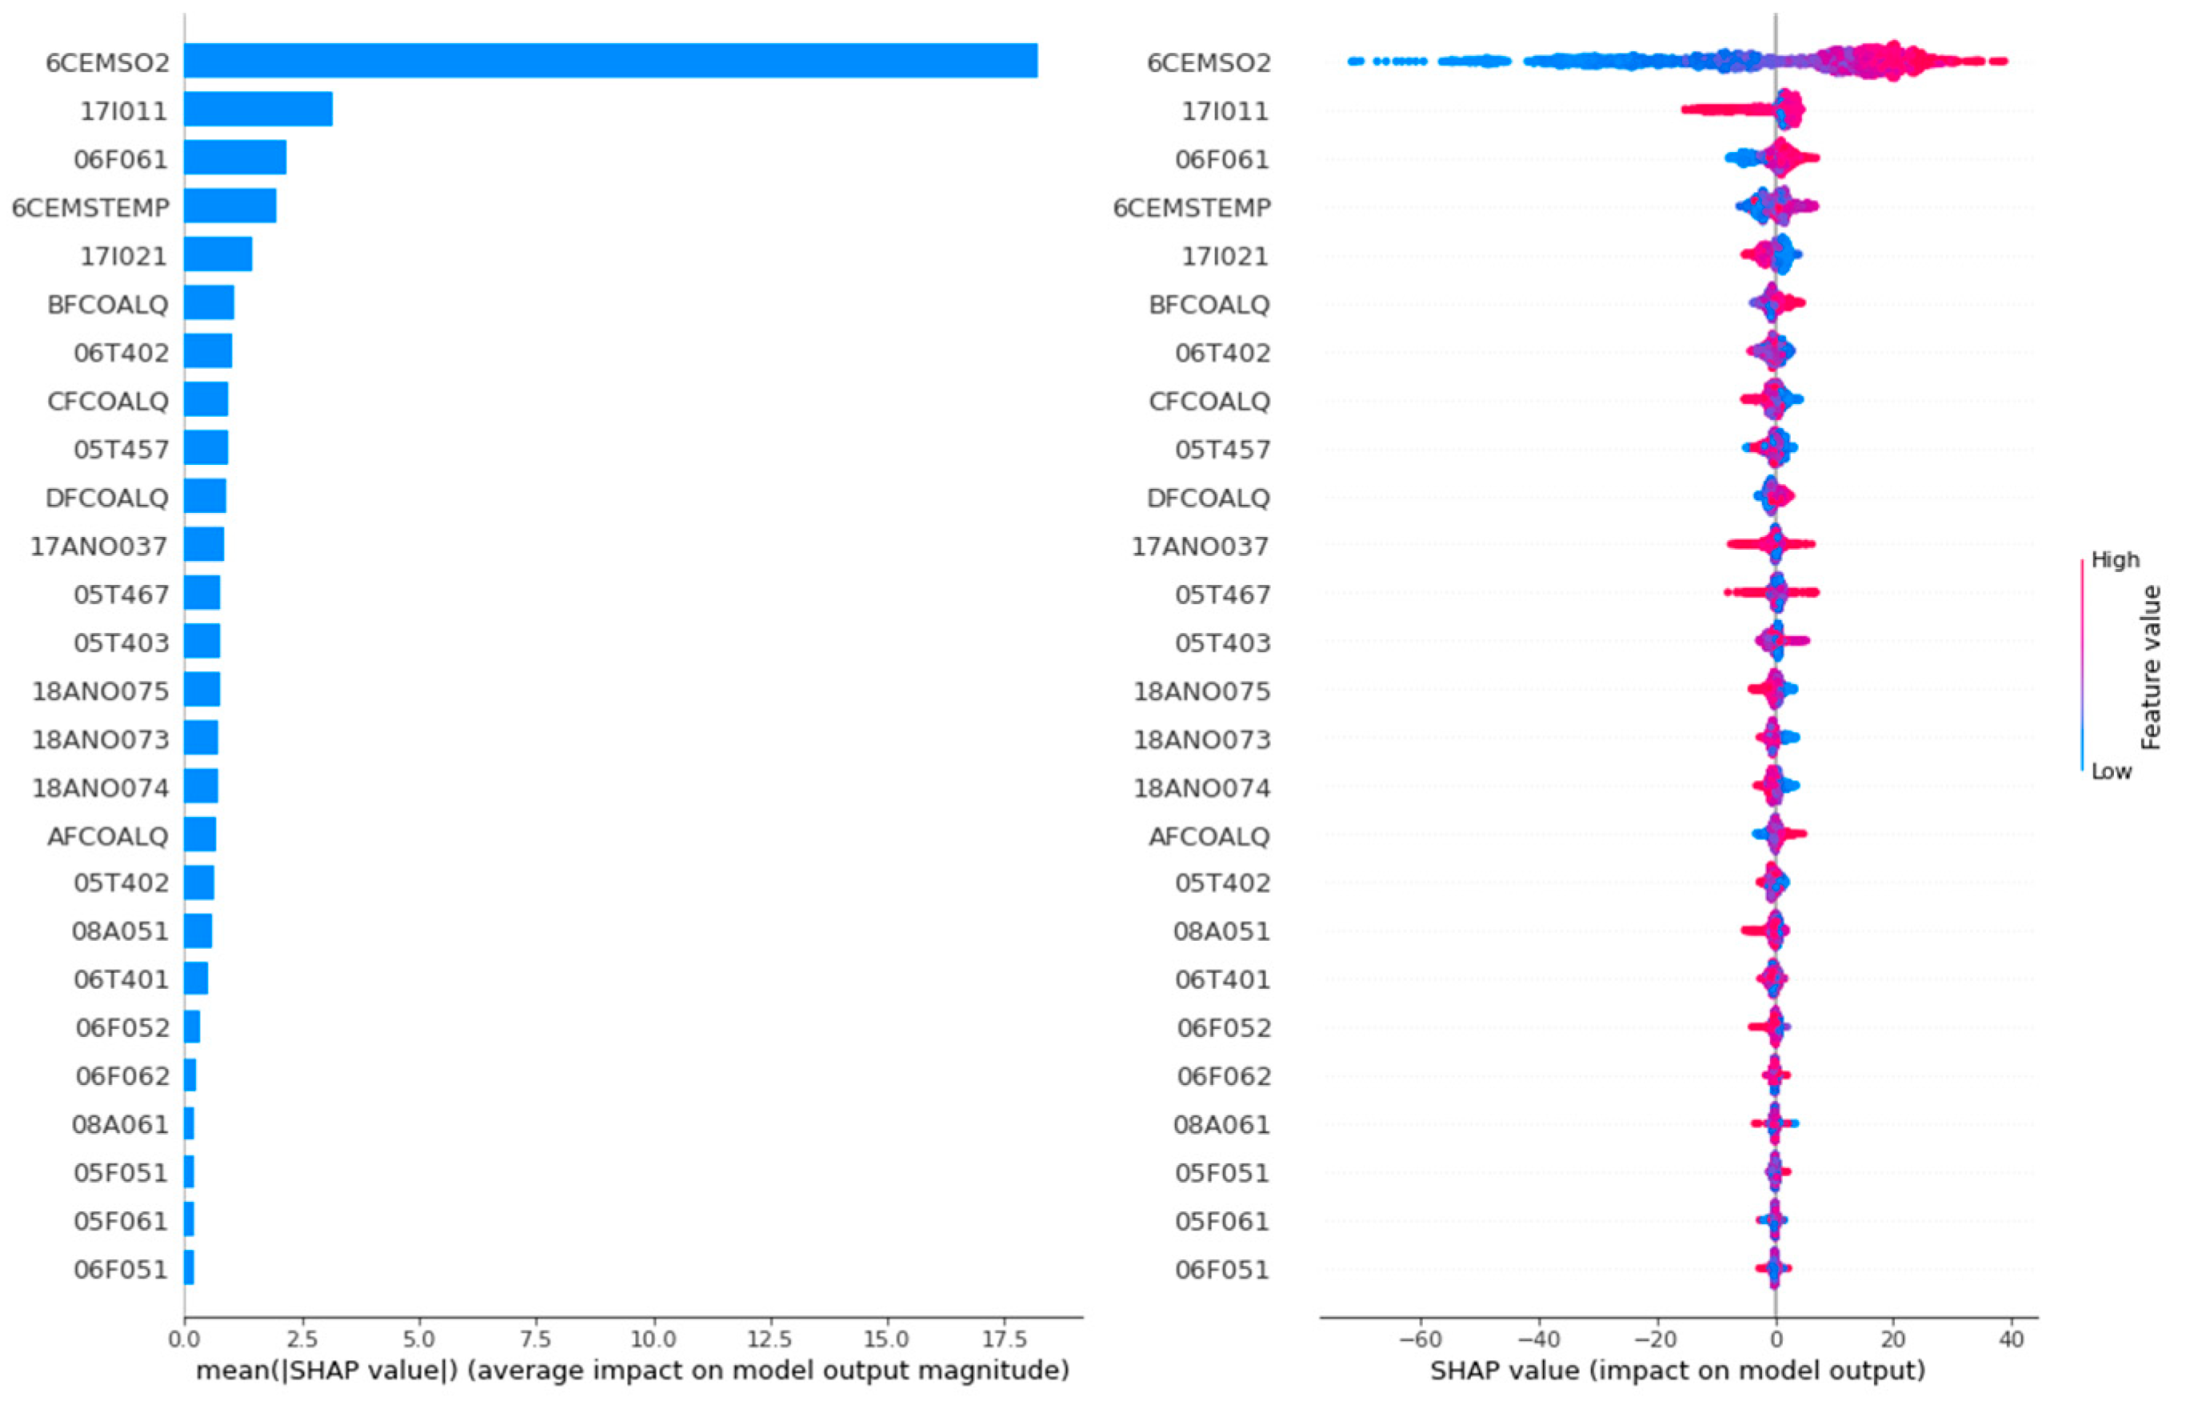
The feature analysis importance diagram and summary diagram of NOx emission concentration is shown in Figure 11.
Figure 11.
The feature analysis importance diagram and summary diagram of NOx emission concentration.
The feature analysis dependency diagram of thermal efficiency is shown in Figure 12.
Figure 12.
The feature analysis dependency diagram of thermal efficiency.
In the feature analysis importance diagrams of Figure 9 and Figure 11, the horizontal coordinate represents the Shapley value. The larger the Shapley value, the greater the feature importance. As can be seen in Figure 9, the top five features that have the greatest impact on the thermal efficiency of the CFBB are 6CEMSO2, 6CEMSTEMP, 08A061, 06T401 and 08A051. As can be seen in Figure 11, the top five features that have the greatest effect on the NOx emission concentration of the CFBB are 6CEMSO2, 17I011, 06F061, 6CEMSTEMP and 17I021.
In the feature analysis summary diagrams of Figure 9 and Figure 11, each feature point represents the corresponding feature sample, the change in color from blue to red indicates the change in the value of the feature sample from small to large, and the positive and negative Shapley values indicate the positive and negative effects of the feature sample with the target. In order to explore more visually the positive and negative effects of different values of each feature on the target, the feature analysis dependency diagrams shown in Figure 10 and Figure 12 are more important.
Taking the first subgraph in Figure 10 and Figure 12 as an example, for the feature AFCOALQ, its original value range is [27.67, 68.12]. When it has a positive impact on the thermal efficiency of the CFBB, its value range is [27.67, 60.40], and when it has a negative impact on the NOx emission concentration of the CFBB, its value range is [27.67, 63.86], so it can be obtained that the value range when its impact on thermal efficiency is positive and its impact on NOx emission concentration is negative is [27.67, 56.90]. And the value ranges of the other adjustable parameters of the combustion system of the CFBB are shown in Table 13.
Table 13.
The value range of adjustable parameters of the combustion system of the CFBB.
4.4. Parameters Optimized by MSMA
In this subsection, the MSMA is applied to optimize the boiler thermal efficiency and NOx emissions concentration based on the established models. The objective function is shown in Equation (24), where is a vector containing 13 adjustable operation parameters, i.e., AFCOALQ (), BFCOALQ (), CFCOALQ (), DFCOALQ (), 05F051 (), 05F061 (), 06F051 (), 06F052 (), 06F061 (), 06F062 (), 6CEMSO2 (), 08A051 () and 08A061 (). and are the function value of boiler thermal efficiency and NOx emission concentration, respectively. The constraints are shown in Equations (26)–(38), i.e., the range of adjustable operation parameters.
Objective function:
Constraints:
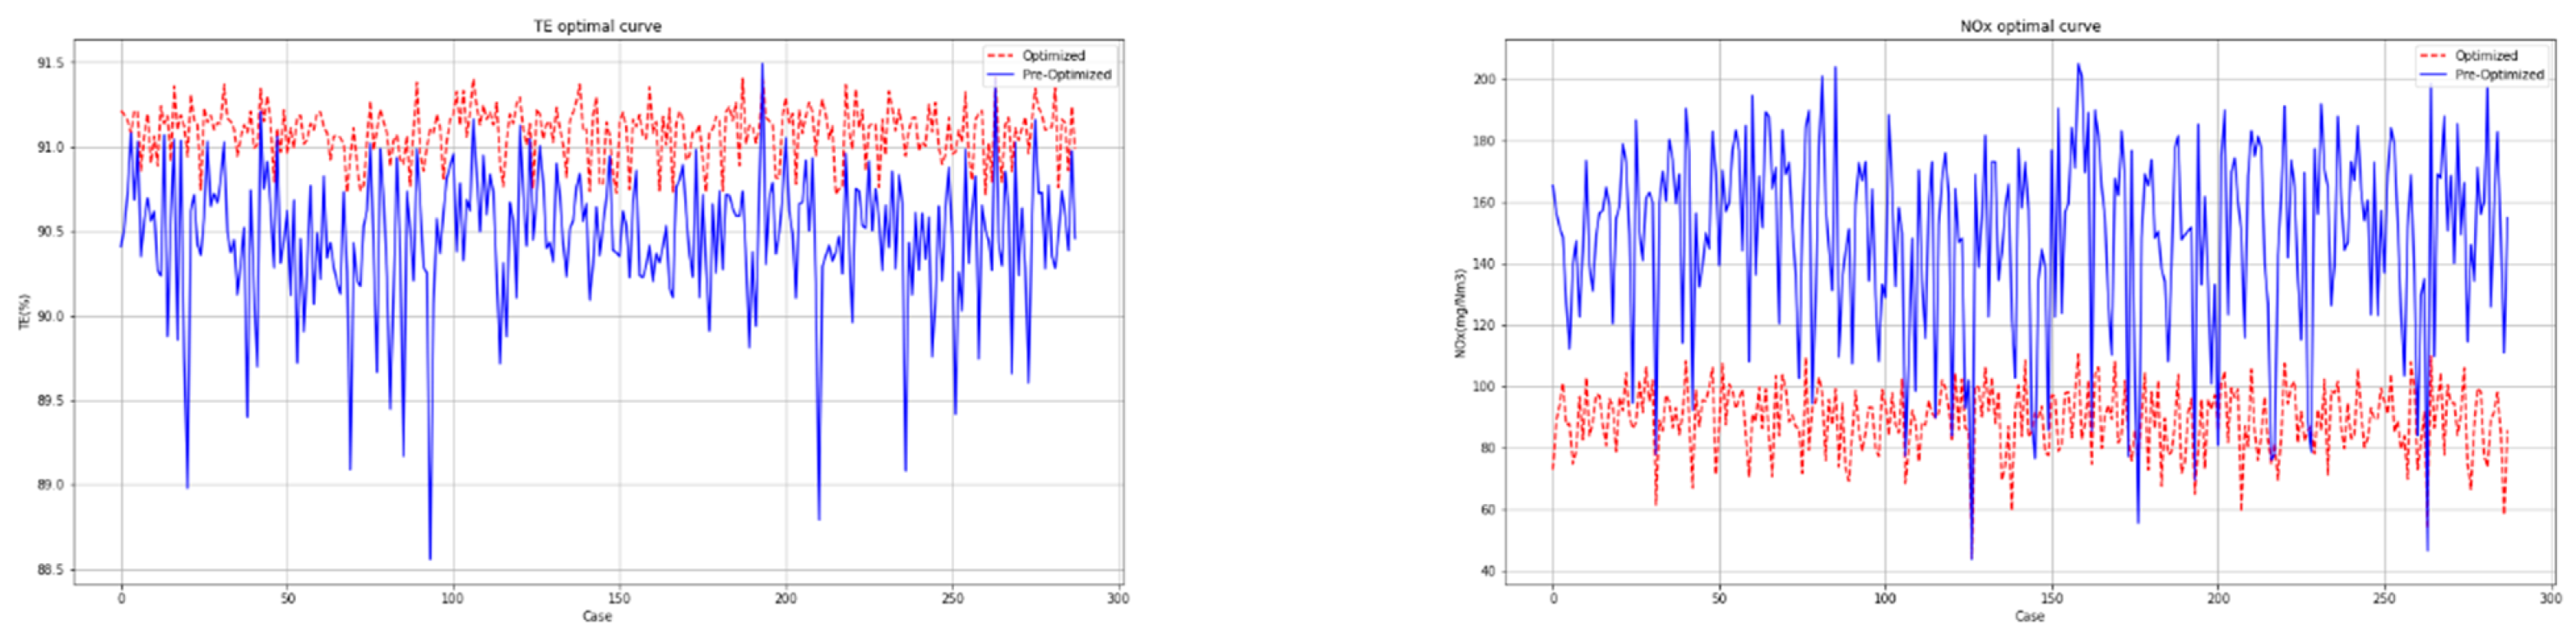
The population size and the maximum number of iterations of the MSMA are set to 40 and 50, respectively. Overall, 10% of the operation data shown in Table 10 were randomly selected to be optimized. The partial optimization results of the MSMA are recorded in Table 13. And the optimization curves of the MSMA for boiler thermal efficiency and NOx emission concentration are shown in Figure 13.
Figure 13.
The optimization curves of MSMA for thermal efficiency and NOx emission concentration.
As can be seen in Table 14 and Figure 13, the MSMA can effectively optimize the combustion system of the CFBB, which is able to reduce the NOx emission concentration while ensuring a high thermal efficiency. Among them, the average optimization ratio for thermal efficiency reaches +0.68%, the average optimization ratio for NOx emission concentration reaches −37.55%, and the average optimization time is 6.40 s, which is much less than the time for each interval sampling, so the actual industrial demand can be met.
Table 14.
The optimization results of MSMA for thermal efficiency and NOx emission concentration.
5. Conclusions
This paper designs a new multi-objective optimization framework to solve the boiler combustion optimization problem. The proposed framework has several functions, such as modeling, data correlation analysis and optimization. Actually, the framework integrates the interpretable CatBoost model and a modified slime mould algorithm. The framework is used to improve the thermal efficiency and reduce the NOx emissions of one 330 MW CFBB. The experimental results show that the proposed framework can on average improve the boiler thermal efficiency by 0.68% while reducing the NOx emission concentration by 37.55%, and the optimized adjustment operation parameters can meet the actual industrial demand. In addition, a kind of modified slime mould algorithm is proposed to improve the convergence accuracy of the original SMA. Through the benchmark functions test, the MSMA outperforms the original SMA.
In future research, we are planning to use the proposed framework to solve modeling and optimization problems for different types of complex systems. Moreover, we will further enhance the convergence accuracy of the MSMA through several mechanisms and design more efficient multi-objective algorithms based on the MSMA.
Author Contributions
Conceptualization, S.G. and Y.M.; methodology, S.G.; software, S.G.; validation, Y.M.; formal analysis, S.G.; investigation, Y.M.; resources, Y.M.; data curation, Y.M.; writing—original draft preparation, S.G. and Y.M.; writing—review and editing, S.G. and Y.M.; visualization, S.G.; supervision, Y.M.; project administration, Y.M.; funding acquisition, Y.M. All authors have read and agreed to the published version of the manuscript.
Funding
This work is supported by the National Natural Science Foundation of China (Grant No. 62203332) and the Natural Science Foundation of Tianjin (Grant No. 20JCQNJC00430).
Institutional Review Board Statement
Not applicable.
Data Availability Statement
This manuscript does not report data generation or analysis.
Conflicts of Interest
The authors declare no conflict of interest.
References
- Zhou, H. Study on Some Key Issues in NOx Control and Combustion Optimization of Large Power Plant Boilers. Doctoral Dissertation, Zhejiang University, Hangzhou, China, 2004. [Google Scholar]
- Zhou, H.; Zhao, J.; Zheng, L.; Wang, C.; Cen, K. Modeling NOx emissions from coal-fired utility boilers using support vector regression with ant colony optimization. Eng. Appl. Artif. Intell. 2012, 25, 147–158. [Google Scholar] [CrossRef] [Scilit]
- Zhou, H.; Cen, K. Combining Neural Network or Support Vector Machine with Optimization Algorithms to Optimize the Combustion. In Combustion Optimization Based on Computational Intelligence; Advanced Topics in Science and Technology in China; Springer: Singapore, 2018. [Google Scholar] [CrossRef] [Scilit]
- Yao, Z.; Romero, C.; Baltrusaitis, J. Combustion optimization of a coal-fired power plant boiler using artificial intelligence neural networks. Fuel 2023, 344, 128145. [Google Scholar] [CrossRef] [Scilit]
- Li, G.; Niu, P.; Wang, H.; Liu, Y. Least Square Fast Learning Network for modeling the combustion efficiency of a 300 WM coal-fired boiler. Neural Netw. Off. J. Int. Neural Netw. Soc. 2014, 51, 57–66. [Google Scholar]
- Akopov, A.S.; Beklaryan, L.A.; Saghatelyan, A.K. Agent-based modelling for ecological economics: A case study of the Republic of Armenia. Ecol. Model. 2017, 346, 99–118. [Google Scholar] [CrossRef] [Scilit]
- Cappelletti, F.; Manuguerra, L.; Rossi, M.; Germani, M.; Sartini, M. Design optimization for environmental sustainability: A framework to select the best eco-design strategy. Proc. Des. Soc. 2023, 3, 1297–1306. [Google Scholar] [CrossRef] [Scilit]
- Zheng, L.; Zhou, H.; Cen, K.; Wang, C. A comparative study of optimization algorithms for low NOx combustion modification at a coal-fired utility boiler. Expert Syst. Appl. 2009, 36, 2780–2793. [Google Scholar] [CrossRef] [Scilit]
- Wu, F.; Zhou, H.; Ren, T.; Zheng, L.; Cen, K. Combining support vector regression and cellular genetic algorithm for multi-objective optimization of coal-fired utility boilers. Fuel 2009, 88, 1864–1870. [Google Scholar] [CrossRef] [Scilit]
- Zhou, H.; Zheng, L.; Cen, K. Computational intelligence approach for NOx emissions minimization in a coal-fired utility boiler. Energy Convers. Manag. 2010, 51, 580–586. [Google Scholar] [CrossRef] [Scilit]
- Si, F.; Romero, C.E.; Yao, Z.; Xu, Z.; Morey, R.L.; Liebowitz, B.N. A new approach for function approximation in boiler combustion optimization based on modified structural AOSVR. Expert Syst. Appl. 2009, 36, 8691–8704. [Google Scholar] [CrossRef] [Scilit]
- Li, G.; Niu, P.; Duan, X.; Zhang, X. Fast learning network: A kind of novel artificial neural network with a fast learning speed. Neural Comput. Appl. 2014, 24, 1683–1695. [Google Scholar] [CrossRef] [Scilit]
- Niu, P.; Ma, Y.; Li, G. Model NOx emission and thermal efficiency of CFBB based on an ameliorated extreme learning machine. Soft Comput. 2018, 22, 4685–4701. [Google Scholar] [CrossRef] [Scilit]
- Li, X.; Niu, P.; Li, G.; Liu, J. An Adaptive Extreme Learning Machine for Modeling NOx Emission of a 300 MW Circulating Fluidized Bed Boiler. Neural Process. Lett. 2017, 46, 643–662. [Google Scholar] [CrossRef] [Scilit]
- Ma, Y.; Niu, P.; Yan, S.; Li, G. A modified online sequential extreme learning machine for building circulation fluidized bed boiler’s NOx emission model. Appl. Math. Comput. 2018, 334, 214–226. [Google Scholar] [CrossRef] [Scilit]
- Ma, Y.; Xu, C.; Wang, H.; Wang, R.; Liu, S.G.; Gu, X. Model NOx, SO2 Emissions Concentration and Thermal Efficiency of CFBB Based on a Hyper-Parameter Self-Optimized Broad Learning System. Energies 2022, 15, 7700. [Google Scholar] [CrossRef] [Scilit]
- Fan, Y.; Liu, X.; Zhang, C.; Li, C.; Li, X.; Wang, H. Dynamic prediction of boiler NOx emission with graph convolutional gated recurrent unit model optimized by genetic algorithm. Energy 2024, 294, 130957. [Google Scholar] [CrossRef] [Scilit]
- Xi, H.; Liao, P.; Wu, X. Simultaneous parametric optimization for design and operation of solvent-based post-combustion carbon capture using particle swarm optimization. Appl. Therm. Eng. 2020, 184, 116287. [Google Scholar] [CrossRef] [Scilit]
- Rahat, A.A.; Wang, C.; Everson, R.M.; Fieldsend, J.E. Data-driven multi-objective optimisation of coal-fired boiler combustion systems. Appl. Energy 2018, 229, 446–458. [Google Scholar] [CrossRef] [Scilit]
- Wang, F.; Ma, S.; Wang, H.; Li, Y.H.; Qin, Z.; Zhang, J. A hybrid model integrating improved flower pollination algorithm-based feature selection and improved random forest for NOx emission estimation of coal-fired power plants. Measurement 2018, 125, 303–312. [Google Scholar] [CrossRef] [Scilit]
- Hu, X.; Niu, P.; Wang, J.; Zhang, X. Multi-objective prediction of coal-fired boiler with a deep hybrid neural networks. Atmos. Pollut. Res. 2020, 11, 1084–1090. [Google Scholar] [CrossRef] [Scilit]
- Xu, W.; Huang, Y.; Song, S.; Chen, B.; Qi, X. A novel online combustion optimization method for boiler combining dynamic modeling, multi-objective optimization and improved case-based reasoning. Fuel 2023, 337, 126854. [Google Scholar] [CrossRef] [Scilit]
- Xu, W.; Huang, Y.; Song, S. On-line combustion optimization framework for coal-fired boiler combining improved cultural algorithm, deep learning, multi-objective evolutionary algorithm with improved case-based reasoning technology. Fuel 2024, 358, 130225. [Google Scholar] [CrossRef] [Scilit]
- Xu, W.; Poh, K.; Song, S.; Huang, Y. Research on reducing pollutant, improving efficiency and enhancing running safety for 1000 MW coal-fired boiler based on data-driven evolutionary optimization and online retrieval method. Appl. Energy 2025, 377, 123958. [Google Scholar] [CrossRef] [Scilit]
- Li, G.; Niu, P.; Ma, Y.; Wang, H.; Zhang, W. Tuning extreme learning machine by an improved artificial bee colony to model and optimize the boiler efficiency. Knowl. Based Syst. 2014, 67, 278–289. [Google Scholar] [CrossRef] [Scilit]
- Ma, Y.; Zhang, X.; Song, J.; Chen, L. A modified teaching-learning-based optimization algorithm for solving optimization problem. Knowl. Based Syst. 2020, 212, 106599. [Google Scholar] [CrossRef] [Scilit]
- Ma, Y.; Wang, H.; Zhang, X.; Hou, L.; Song, J. Three-objective optimization of boiler combustion process based on multi-objective teaching–learning based optimization algorithm and ameliorated extreme learning machine. Mach. Learn. Appl. 2021, 5, 100082. [Google Scholar] [CrossRef] [Scilit]
- Biau, G.; Scornet, E. A random forest guided tour. TEST 2015, 25, 197–227. [Google Scholar] [CrossRef] [Scilit]
- Couronné, R.; Probst, P.; Boulesteix, A. Random forest versus logistic regression: A large-scale benchmark experiment. BMC Bioinform. 2018, 19, 270. [Google Scholar] [CrossRef] [Scilit]
- Cristianini, N.; Shawe-Taylor, J. An Introduction to Support Vector Machines and Other Kernel-based Learning Methods; Cambridge University Press: Cambridge, MA, USA, 2000. [Google Scholar]
- Steinwart, I.; Christmann, A. Support Vector Machines; Springer: New York, NY, USA, 2008. [Google Scholar]
- Huang, G.; Zhu, Q.; Siew, C.K. Extreme learning machine: A new learning scheme of feedforward neural networks. In Proceedings of the 2004 IEEE International Joint Conference on Neural Networks (IEEE Cat. No.04CH37541), Budapest, Hungary, 25–29 July 2004; Volume 2, pp. 985–990. [Google Scholar]
- Huang, G.; Zhu, Q.; Siew, C.K. Extreme learning machine: Theory and applications. Neurocomputing 2006, 70, 489–501. [Google Scholar] [CrossRef] [Scilit]
- Huang, G.; Zhou, H.; Ding, X.; Zhang, R. Extreme Learning Machine for Regression and Multiclass Classification. IEEE Trans. Syst. Man Cybern. Part B (Cybern.) 2012, 42, 513–529. [Google Scholar] [CrossRef] [Scilit]
- Prokhorenkova, L.; Gusev, G.; Vorobev, A.; Dorogush, A.V.; Gulin, A. CatBoost: Unbiased boosting with categorical features. arXiv 2017. [Google Scholar] [CrossRef] [Scilit]
- Hancock, J.T.; Khoshgoftaar, T.M. CatBoost for big data: An interdisciplinary review. J. Big Data 2020, 7, 94. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Dorogush, A.V.; Ershov, V.; Gulin, A. CatBoost: Gradient boosting with categorical features support. arXiv 2018, arXiv:1810.11363. [Google Scholar]
- Lundberg, S.M.; Erion, G.G.; Lee, S. Consistent Individualized Feature Attribution for Tree Ensembles. arXiv 2018, arXiv:1802.03888. [Google Scholar]
- Lundberg, S.M.; Lee, S. A Unified Approach to Interpreting Model Predictions. In Proceedings of the NIPS’17: Proceedings of the 31st International Conference on Neural Information Processing Systems, Long Beach, CA, USA, 4–9 December 2017. [Google Scholar]
- Li, S.; Chen, H.; Wang, M.; Heidari, A.; Mirjalili, S.M. Slime mould algorithm: A new method for stochastic optimization. Future Generarion Comput. Syst. 2020, 111, 300–323. [Google Scholar] [CrossRef] [Scilit]
- He, D.; He, C.; Jiang, L.; Zhu, H.; Hu, G. Chaotic characteristics of a one-dimensional iterative map with infinite collapses. IEEE Trans. Circuits Syst. I-Regul. Pap. 2001, 48, 900–906. [Google Scholar]
- Tizhoosh, H.R. Opposition-Based Learning: A New Scheme for Machine Intelligence. In Proceedings of the International Conference on Computational Intelligence for Modelling, Control and Automation and International Conference on Intelligent Agents, Web Technologies and Internet Commerce (CIMCA-IAWTIC’06), Vienna, Austria, 28–30 November 2005; Volume 1, pp. 695–701. [Google Scholar]
- Seif, Z.; Ahmadi, M.B. An opposition-based algorithm for function optimization. Eng. Appl. Artif. Intell. 2015, 37, 293–306. [Google Scholar] [CrossRef] [Scilit]
- Arora, S.; Singh, S. Butterfly optimization algorithm: A kind of novel approach for global optimization. Soft Comput. 2019, 23, 715–734. [Google Scholar] [CrossRef] [Scilit]
- Mirjalili, S.M.; Lewis, A. The Whale Optimization Algorithm. Adv. Eng. Softw. 2016, 95, 51–67. [Google Scholar] [CrossRef] [Scilit]
- Dhiman, G.; Kumar, V. Seagull optimization algorithm: Theory and its applications for large-scale industrial engineering problems. Knowl. Based Syst. 2019, 165, 169–196. [Google Scholar] [CrossRef] [Scilit]
- Xue, J.; Shen, B. A kind of novel swarm intelligence optimization approach: Sparrow search algorithm. Syst. Sci. Control Eng. 2020, 8, 22–34. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2024 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).