


Abstract
Artificial neural networks (ANNs) have achieved great success in performing machine learning tasks, including classification, regression, prediction, image processing, image recognition, etc., due to their outstanding training, learning, and organizing of data. Conventionally, a gradient-based algorithm known as backpropagation (BP) is frequently used to train the parameters’ value of ANN. However, this method has inherent drawbacks of slow convergence speed, sensitivity to initial solutions, and high tendency to be trapped into local optima. This paper proposes a modified particle swarm optimization (PSO) variant with two-level learning phases to train ANN for image classification. A multi-swarm approach and a social learning scheme are designed into the primary learning phase to enhance the population diversity and the solution quality, respectively. Two modified search operators with different search characteristics are incorporated into the secondary learning phase to improve the algorithm’s robustness in handling various optimization problems. Finally, the proposed algorithm is formulated as a training algorithm of ANN to optimize its neuron weights, biases, and selection of activation function based on the given classification dataset. The ANN model trained by the proposed algorithm is reported to outperform those trained by existing PSO variants in terms of classification accuracy when solving the majority of selected datasets, suggesting its potential applications in challenging real-world problems, such as intelligent condition monitoring of complex industrial systems.
1. Introduction
The human nervous system inspires an artificial neural network (ANN), and many artificial neurons act as interconnected processing elements in ANN to emulate the cerebral cortex of brain structure. In contrast to other conventional machine learning methods, ANNs demonstrate outstanding capabilities in generalizing, organizing, and learning the nonlinear data that are commonly observed in real-world scenarios [1]. Due to these appealing features, ANNs have been widely implemented to solve various real-world application, including intelligent condition monitoring [2], speech recognition [3], fault diagnosis [4], pothole classification [5], etc. Generally, ANN structure can be separated into three parts: the input layer, the hidden layer, and the output layer. Information flows in a single direction within an ANN model, i.e., from the input layer to the hidden layer, followed by the output layer [6]. Each neuron of the layers is incorporated with an activation function to convert the summed weighted input received by each neuron into the nonlinear output. This nonlinear characteristic serves as the cornerstone for ANN to have competitive performance in tackling various challenging machine learning tasks, such as the learning of complex data, functions approximation, and predictions [7].
Before deploying an ANN model to solve machine learning tasks, a training process is performed to determine the optimal combinations of weight and bias values for all neurons that can achieve minimum error. A gradient-based algorithm known as the backpropagation (BP) method is conventionally used to train ANN models [7]. At the beginning stage of ANN training, the initial weight and bias values of neurons are randomly generated, and the actual output values of the network are determined. The error signals between the desired and actual outputs are then calculated and backpropagated to the network to adjust the weight and bias values of each neuron. Despite its popularity, some drawbacks were reported when using the classical BP method to train ANN models, especially when solving complex nonlinear problems. For instance, the BP method has a high tendency to be trapped in local optima and fail to reach global optimum when dealing with solution regions with complex characteristics. The performance of the ANN model when solving complex problems can be significantly degraded due to suboptimal weight and bias values assigned to all neurons [7]. The convergence characteristic of the classical BP method in ANN training is also sensitive to the initial values of weight, bias, and network parameters (e.g., activation function). There might be scenarios where the classical BP method produces poor initial weight and bias values for ANN during the training process, leading to compromised network performances [7]. These limitations of classical BP methods have motivated researchers to seek robust alternatives that can address ANN training problems more efficiently and effectively.
In recent years, metaheuristic search algorithms (MSAs) have emerged as promising solutions to tackle complex optimization problems, such as those reported in [8,9,10,11,12,13]. The excellent global search ability and stochastic characteristic of these MSAs can also be harnessed for training ANN models to solve classification or regression problems. Particle swarm optimization (PSO) is one of the most popular MSAs, and it is motivated by the collective behavior of bird flocks in locating food sources [14]. Each PSO particle can memorize its previous best searching experiences, and this unique feature distinguishes PSO from other MSAs [15]. The search trajectory of each PSO particle is adjusted based on its previous best experience and the best experience achieved by the entire population during the optimization process. Since the inception of the original PSO in 1995, many new variants have been proposed to solve various real-world optimization problems. Despite its appealing features, such as simplicity in implementation and fast convergence speed, the capability of original PSO to solve complex optimization problems such as ANN training remain questionable due to its high tendency to suffer from premature convergence issues when solving complex problems with high-dimensional search space. Therefore, more robust search mechanisms must be incorporated into the original PSO to balance the algorithm’s exploration and exploitation searches.
1.1. Research Motivations
A PSO variant known as particle swarm optimization without velocity (PSOWV) was proposed in [16] by discarding the velocity component of each particle during the search process. PSOWV has demonstrated more competitive performance than the conventional PSO by solving simple benchmark problems with better accuracy in fewer iteration numbers. Despite its promising performance, PSOWV still suffers from some inherent drawbacks that might restrict its feasibility to solve more challenging optimization problems, such as the training of ANN models for classification or regression tasks.
Similar to most MSAs, PSOWV employs a conventional initialization scheme to randomly generate the initial population of particles during the search process. This conventional initialization scheme produces the initial position of each particle using uniform distribution without considering the characteristics or fitness landscapes of given optimization problems [17]. When particles are mistakenly initialized in local optima, it may lead to premature convergence issues and poor solution accuracy. In contrary, the convergence speed of the algorithm can be significantly deteriorated if particles are initialized at solution regions far away from the global optimum. It is more desirable to have a robust initialization scheme that can generate the initial position of each particle more systematically to ensure the initial population has a better solution quality.
When carefully inspecting the search operator of PSOWV, the new position of each particle is directly affected by the directional information of historical best positions, i.e., the personal best position of the particle itself and the global best position of the population. While these historical best positions are beneficial to accelerate the convergence speed of PSOWV at the early stage of optimization, they are less frequently updated at the latter stages [18]. When both personal and global best positions are overemphasized during the search process of PSOWV, the entrapment of these historical best positions into local optima at the early stage of the search process could misguide the remaining particles converging towards the inferior solution regions and lead to premature convergence. To prevent these undesirable scenarios, it is necessary for PSOWV to be incorporated with a more robust diversity preservation scheme when dealing with complex problems. The directional information offered by other non-historical best positions should be leveraged during the search process to prevent the potential negative impacts brought by personal and global best positions.
Finally, it is observed that PSOWV has limited ability to achieve proper trade-off between exploration and exploitation searches because only one search operator is used to perform the search process. Hence, PSOWV can only perform well in certain types of optimization problems (i.e., unimodal problem), and it exhibits poor optimization performance in other problem categories. When solving optimization problems with different complexity levels as governed by the characteristics of fitness landscapes, it is crucial for an algorithm to intelligently regulate its exploration and exploitation strength to locate the global optima [19]. The incorporation of multiple search operators with different levels of exploration and exploitation strengths can be envisioned as an alternative to enhance the robustness of the algorithm to solve different complex optimization problems competitively.
1.2. Research Contributions
To address the shortcomings of PSOWV in solving complex optimization problems such as the ANN model training, an enhanced variant known as multi-swarm-based particle swarm optimization with two-level learning phases (MSPSOTLP) is proposed. Apart from optimizing the weight and bias values of ANN models during the training process, the proposed MSPSOTLP can also determine the optimal activation function of an ANN model to solve the given classification problem. The main modifications introduced into MSPSOTLP to highlight its research contributions are summarized as follows:
- A modified initialization scheme is incorporated into MSPSOTLP to generate an initial population with better robustness and diversity by leveraging the benefits of the chaotic system (CS) and oppositional-based learning (OBL).
- In the primary learning phase of MSPSOTLP, both the multi-swarm concept and social learning concept are incorporated to promote rapid convergence of the population towards the optimal regions by enabling particles to learn from other superior population members while preserving the diversity level of population.
- In the secondary learning phase of MSPSOTLP, two modified search operators with different characteristics are designed for each particle to perform searching with different levels of exploration and exploitation strengths, hence enabling the proposed algorithm to solve different types of optimization problems more competitively.
- The performance of MSPSOTLP in solving global optimization problems is investigated using CEC 2014 benchmark functions. The classification performances of ANN models trained using MSPSOTLP are also evaluated with 16 datasets selected from UCI Machine Learning Repository. The proposed MSPSOTLP is proven more competitive than its peer algorithms at solving the benchmark functions and ANN training.
The remaining sections of this article are organized as follows. Related works of this study are explained in Section 2. The detailed search mechanisms of MSPSOTLP are described in Section 3. Extensive simulation studies performed to investigate the performance of MSPSOTLP in solving global optimization problems and its capability to train ANN models in solving classification problems are presented in Section 4. Finally, Section 5 concludes the research findings and future works.
2. Related Works
2.1. Particle Swarm Optimization (PSO)
PSO is inspired by the collective behavior of bird flocking or fish schooling to search for food sources [14]. Suppose that N is the population size and D is the dimensional size of an optimization problem. Each PSO particle is a potential solution to solve an optimization problem represented with a velocity vector of and a position vector of , where and refer to the population index and dimension index, respectively. Unlike other MSAs, each PSO particle can memorize its previous best experience and the best experience achieved by the population, denoted as personal best position of and global best position of , respectively. During the t-th iteration of the search process, the new velocity of each n-th particle in any d-th dimension is adjusted based on the corresponding dimensional components of the personal best position (i.e., self-cognitive component) and global best position (i.e., social component) as follows:
where is an inertia weight; and are acceleration coefficients; are two random numbers generated from a uniform distribution. Referring to , the new position of each n-th particle in every d-th dimension is updated as:
The fitness of every n-th particle with updated position is evaluated as and compared with those of the personal best position and global best position denoted as and , respectively. Both of and will be updated as if the latter solution is superior. The search process of PSO using Equations (1) and (2) is iterated until the predefined termination criteria are satisfied.
2.2. Particle Swarm Optimization without Velocity (PSOWV)
PSOWV is a velocity-discarded version of PSO proposed in [16], aiming to enhance the ability of PSO to locate the global optimum of a given problem with a lesser iteration number. During the search process, the d-th dimension of position for every n-th PSOWV particle (i.e., ) can be updated based on the random linear combination between its personal best position (i.e., ) and the global best position (i.e., ) of the population in the same dimensional component as follows:
The fitness evaluation and procedure to update historically best positions (i.e., and ) of PSOWV are similar to those of the original PSO. Although PSOWV can solve the simple benchmark functions with a faster convergence speed than the original PSO, its feasibility to solve more challenging real-world optimization problems, such as training ANN models, remains unexplored. Furthermore, preliminary studies also revealed the high tendency of PSOWV to suffer premature convergence issues because its search behavior is governed by a single search operator that highly relies on the directional information provided by historically best positions.
2.3. PSO Variants
Despite appealing characteristics, such as rapid convergence speed and simplistic implementation, the original PSO tends to suffer from rapid loss of population diversity and premature convergence issues when solving more complex optimization problems. Proper balancing of exploration and exploitation searches is considered a fundamental cornerstone for MSAs such as PSO to solve different optimization problems competitively. Therefore, various modification schemes were proposed by researchers over the years to address the demerits of the original PSO.
Parameter adaptation is a popular enhancement strategy of PSO by determining the proper combination of control parameters that can govern its search trajectories. The control parameters to be adjusted include inertia weight, constriction factor, acceleration coefficients, and a variety of these parameters. Some notable PSO variants that were proposed with parameter adaptation approaches are reported in [20,21,22,23]. Neighborhood structure modification is another promising technique of PSO because it governs the broadcast rate of information between population members. Particularly, the fully connected population topology tends to be more exploitative, whereas the partially connected one has stronger exploitation strengths. PSO variants reported in [19,24,25,26,27,28] can achieve proper tradeoffs between the exploration and exploitation searches by varying their population topology with time or based on current search environments. Apart from modifying the neighborhood structure, it is also feasible to introduce single or multiple modified learning strategies into PSO for achieving performance enhancements such as those proposed in [29,30,31,32,33,34,35,36]. To alleviate potential negative impacts brought by the historically best solution (e.g., personal and global best positions), novel exemplars might be constructed by these modified learning strategies from the non-fittest solutions to guide the search process of particles more effectively while preserving the population diversity. Finally, the PSO’s robustness in solving high-complexity real-world problems can be enhanced using the hybridization approach, such as those reported in [37,38,39,40]. Different hybridization frameworks [41] can be designed to leverage the strengths of search operators incorporated in other MSAs for compensating the drawbacks of PSO in solving certain problem classes. The strengths and limitations of selected PSO variants are analyzed and summarized in Table 1.
Table 1.
Strengths and limitations of selected PSO variants.
2.4. Application of MSAs in Training ANN Models
Given the drawbacks of the conventional BP method, numerous MSAs were designed as promising alternatives to train ANN models with more robust network performances [42]. A two-layer PSO (PSO-PSO) algorithm was proposed in [43] to train a multilayer perceptron (MLP) neural network by interleaving two PSO algorithms. The first layer of PSO was used to optimize the number of perceptrons in the network architecture, whereas the second layer of PSO optimized the weight and bias values based on the network architecture obtained by the first layer. Nevertheless, simulation studies revealed that the ANN models optimized by PSO-PSO did not significantly outperform their peers when solving the classification benchmark datasets. A hybridized PSO and gravitational search algorithm (PSOGSA) was proposed [44] to optimize the weights and biases of the ANN model by leveraging the unique searching behaviors of PSO and GSA. When training the ANN model, PSO was incorporated to alleviate the inherent drawbacks of GSA, i.e., low convergence rate and high tendency to be trapped in local optima. A hybrid improved opposition-based PSO with a backpropagation algorithm (IOPSO-BPA) [45] was introduced to optimize the weight values of ANNs. Both oppositional-based learning and mutation schemes were incorporated as diversity preservation schemes of IOPSO-BPA.
Furthermore, the concepts of time-varying parameters were introduced to improve the convergence characteristic of the algorithm in optimizing the weights of ANN models. Kandasamy and Rajendran [46] proposed a hybrid algorithm to overcome the drawbacks of the conventional BP methods overfitting and entrapment in local optima when training ANN models. PSO was firstly employed to search for the optimal combination of trainable weights of the ANN model by minimizing the classification error function. Subsequently, the steepest descent method was applied to fine tune the near-optimal weight values encoded in the global best position to further improve classification accuracy. In [47], a self-adaptive and strategy-based PSO (SPS-PSO) was designed to solve the large-scale feature selection and ANN training problems for large-scale datasets. Five search operators with different characteristics were introduced in SPS-PSO, and an adaptive mechanism was used to assign a suitable operator for each particle to ensure it can perform searching with balanced exploration and exploitation strengths. A comprehensive adaptive PSO (ACPSO) was designed in [48] to tackle the denoising issue of ultrasound images by optimizing the functional-link neural network (FLNN). The velocity of the ACPSO was only dependent on the global best position, and its controlling parameters were adaptively adjusted based on the personal and global best positions. To mitigate the flooding issue, an ANN model was trained using PSO in [49] to formulate river flow modelling based on the weather and meteorological data. It was revealed that the river flow strongly correlates with selected variables, such as temperature, evaporation, and rainfall. In [50], hybrid intelligent modeling was developed using PSO and ANN (PSO-ANN) to predict the soil matric sanction, i.e., a useful metric to indicate the soil shear strength in addressing sudden landslides issue, with improved prediction accuracy.
The genetic algorithm (GA) [51] is another popular MSA used to train ANN models. A hybrid model of ANN and GA (ANN-GA) was proposed in [52] to optimize the weights and biases of the ANN model used for modeling the slump of ready-mix concrete. The initial weights and biases of ANN-GA were determined using GA and fine-tuned with the BP algorithm. ANN-GA was reported to outperform its peers by leveraging the benefits of GA and BP to promote its global and local search abilities, respectively. In [53], GABPNN was proposed by integrating GA into a BP-trained ANN to optimize the thickness of blow-molded polypropylene bellows. In GABPNN, the BP algorithm was first applied to train the weights of the ANN model using lesser learning samples, and these weights were further evolved in the feasible solution regions using GA. Contrary to ANN-GA, GA promoted the local search behavior of GABPNN by adopting an elitist strategy and a simulated annealing algorithm. GABPNN demonstrated its effectiveness and competitive performance in solving blow molding problems. A hybrid MLP ANN and GA approach (MLPANN-GA) was introduced in [54] to predict sludge bulking for water treatment plants. GA was incorporated to train the weights, activation functions, and thresholds of the MLPANN model. Simulation studies reported that the incorporation of GA to train MLPANN can increase the accuracy of the ANN model in estimating the sludge volume index.
In addition to GA, teaching-learning-based optimization (TLBO) [55] is another popular MSA widely used for ANN optimization. A TLBO-based ANN (TLBOANN) was proposed in [56] to estimate the energy consumption in Turkey. TLBO was applied to search for the optimal weights and biases of the ANN model by minimizing the error function based on the input data provided, i.e., gross domestic product, population, and import and export data in Turkey. An improved hybrid TLBO and ANN (iTLBO-ANN) was proposed in [57] to solve real-world building energy consumption forecasting problems. Three modifications, known as feedback stage, accuracy factor, and worst solution elimination, were introduced to improve the performance of TLBO in optimizing the weights and thresholds of the ANN model within a shorter time. The iTLBO-ANN outperformed other ANN models trained by GA and PSO by predicting building energy consumption with better accuracy and computational speed. Another TLBO-optimized ANN [58] was proposed to improve the performance in predicting the axial capacity of pile foundations. TLBO was used to train the weights of the ANN model by minimizing the mean square error produced when predicting the ultimate capacity of both driven and drilled shaft piles embedded in uncemented soils. The ANN model trained by TLBO outperformed that trained by BP by producing better variance accounted for and determination coefficient. A new TLBO variant known as TLBO-MLPs was used to train ANN model for data classification [59]. Additional mechanisms were introduced in both the teacher and learner phases of TLBO-MLPs to achieve realistic emulation of classroom teaching and learning that can lead to performance gain in solving complex optimization problems [60].
3. Proposed Methodology
3.1. Formulation of ANN Training as an Optimization Problem
An ANN model to be optimized in this study consists of a three-layer structure with P input neurons, Q hidden neurons, and R output neurons in input, hidden, and output layers, respectively, as illustrated in Figure 1. The neurons in each layer are considered a set of processing elements that are connected by weights with other layers. Suppose that refers to the value of -th neuron at the input layer, represents the value of -th neuron at the hidden layer, and is the r-th neuron at the output layer, where ,, and . Denote as the connection weight between and ; as the connection weight between and ; and as the biases of and , respectively. The values of each q-th hidden neuron and r-th output neuron can be produced by computing the sum of input weight with the presence of biases, followed by the non-linearization process of this weighted summation with an activation function of expressed as follows:
Figure 1.
The network architecture of an ANN model with three-layer structure.
Contrary to the majority of existing ANN training algorithms that only focus on searching optimal weights and biases, this study also considers the optimal selection of the activation function used to solve a given classification task. The decision variables to be optimized by the proposed MSPSOTLP when training the ANN model include: (a) weights , (b) biases , and (c) index that refer to the candidate activation functions, where Binary Step, Sigmoid [7], Hyperbolic Tangent (Tanh) [7], Inverse Tangent (ATan), and Rectified Linear Unit (ReLU) [61] functions are assigned with indices of 1, 2, 3, 4, and 5, respectively. The mathematical formulation of the candidate activation functions considered in this study is presented in Table 2.
Table 2.
The mathematical formulation of the considered activation functions.
The decision variables to be optimized by the proposed MSPSOTLP in ANN training are encoded into the position vector X of each particle as follows:
Referring to Equation (6), the ANN training considered in the current study can be formulated as an optimization problem with a dimensional size of D, where
In this study, the fitness of each MSPSOTLP particle when it is used to train the ANN model can be evaluated by measuring the mean square error between the predicted and expected output values. Given a dataset with a total of data samples, the predicted output of g-th data sample produced by an ANN model trained by MSPSOTLP and its corresponding expected outcome stored in the dataset are indicated as and , respectively, where . The mean square error produced by an ANN model constructed using the decision variables stored in the position vector X of the particle is calculated as the fitness value as follows:
Based on Equation (8), the ANN training is considered a minimization problem because it is more desirable to produce an ANN model with a minor error, implying its high classification accuracy in solving a given dataset.
3.2. Proposed MSPSOTLP Algorithm
In this study, a new PSO variant known as MSPSOTLP is proposed to solve challenging optimization problems, including the ANN training problem formulated in Equation (8), with improved performances. For the latter problem, the proposed MSPSOTLP is used to optimize the weights, biases, and selection of activation functions of the ANN model when solving the given datasets. The essential modifications introduced to enhance the search performance of MSPSOTLP are described in the following subsections.
3.2.1. Modified Initialization Scheme of MSPSOTLP
Population initialization is considered a crucial process to develop robust MSAs because the quality of initial candidate solutions can influence the algorithm’s convergence rate and searching accuracy [17]. Most PSO variants employed random initialization to generate the initial population without considering any meaningful information about the search environment [17]. The stochastic behavior of the random initialization scheme might produce particles at inferior solution regions at the beginning stage of optimization. This undesirable scenario can prevent the algorithm’s convergence towards the global optimum, thus compromising the algorithm’s overall performance.
In this study, a modified initialization scheme incorporated with the chaotic system (CS) and oppositional-based learning (OBL), namely the CSOBL initialization scheme, is designed for the proposed MSPSOTLP to overcome the drawbacks of the conventional initialization scheme. Unlike a random system that demonstrates completely unpredictable behaviors, CS is considered a more powerful initialization scheme that can produce an initial swarm with better diversity by leveraging its ergodicity and non-repetition natures. Denote as the initial condition of a chaotic variable that is randomly generated in each independent run. refers to the value of the chaotic variable in z-th iteration with , where represents the maximum sequence number. Given the bifurcation coefficient of , the chaotic sequence is updated using a chaotic sine map [62] as:
Let and be the upper and lower limits of the decision variable in each d-th dimension, respectively, where . Given the chaotic variable produced in the final iteration of Z, the d-th dimension of each n-th chaotic swarm member can be initialized as:
Referring to Equation (10), a chaotic population with a swarm size of N can be produced and represented as a population set of .
Despite the benefits of the chaotic map in enhancing population diversity, these chaotic swarm members can be initialized in solution regions far away from the global optimum, leading to the low convergence rate of the algorithm. To overcome this drawback, a solution set opposite with is generated by leveraging the OBL concept [63]. For every d-th dimension of n-th chaotic swarm member represented as , the corresponding opposite swarm member is calculated using OBL strategy [17,64] as follows:
Similarly, an opposite population with a swarm size of N can be generated using Equation (11) and represented as another population set of .
To produce an initial population with better fitness and wider coverage in the solution space, both of and are merged as a combined population set of with a swarm size of 2N as follows:
Subsequently, the fitness of all solution members in are evaluated, and a sorting operator of is then applied to rearrange these solution members from the best to worst based on their fitness to produce a sorted population set of , where
Finally, a truncation operator is applied to select the top N solution members of on to construct the initial population of MSPSOTLP, i.e., , where
The pseudocode used to describe the CSOBL initialization scheme of MSPSOTLP is presented in Algorithm 1.
| Algorithm 1. Pseudocode of CSOBL initialization scheme for MSPSOTLP | ||||
| Input: , , , , | ||||
| 01: | Initialize and ; | |||
| 02: | for each n-th particle do | |||
| 03: | for each d-th dimension do | |||
| 04: | Randomly generate initial chaotic variable ; | |||
| 05: | Initialize the chaotic sequence as ; | |||
| 06: | while is smaller than do | |||
| 07: | Update chaotic variable using Equation (9); | |||
| 08: | end while | |||
| 09: | Compute using Equation (10); | |||
| 10: | Compute using Equation (11); | |||
| 11: | end for | |||
| 12: | ;/* Store new chaotic swarm member */ | |||
| 13: | ;/* Store new opposite swarm member */ | |||
| 14: | end for | |||
| 15: | Construct using Equation (12); | |||
| 16: | Evaluate the fitness of all solution members in ; | |||
| 17: | Sort all solution members of from the best to worst using Equation (13); | |||
| 18: | Produce the initial population using Equation (14); | |||
| Output: | ||||
3.2.2. Primary Learning Phase of MSPSOTLP
Most PSO variants, including PSOWV, rely on the global best position to adjust the search trajectories of particles during the optimization process without considering the useful information of other non-fittest particles in the population. Although the directional information of the global best position might be useful to solve simple unimodal problems, it might not necessarily be the best option to handle complex problems with multiple numbers of local optima due to the possibility of the global best position being trapped at the local optima in an earlier stage of optimization. Without a proper diversity preservation scheme, other population members tend to be attracted by misleading information about the global best position and converge towards the inferior region, leading to premature convergence and poor optimization results.
To address the aforementioned issues, several modifications are incorporated into the primary learning phase of MSPSOTLP to achieve a proper balancing of exploration and exploitation searches. The multiswarm concept is first introduced as a diversity preservation scheme at the beginning stage of the primary learning phase by randomly dividing the main population of into S subswarms. Each s-th subswarm is denoted by consists of particles, where . To produce each s-th subswarm from the main population , a reference point of is randomly generated in search space. The normalized Euclidean distance between the reference point and personal best position of each n-th particle, i.e., are measured as , i.e.,
Referring to the values computed for all N particles, the particles with the nearest distances from are identified as the members of s-th subswarm and stored in before they are discarded from the main population . From Algorithm 2, the reference-point-based population division scheme used to generate the multiswarm for the primary learning phase of MSPSOTLP is repeated until all subswarms are generated.
| Algorithm 2. Pseudocode of reference-point-based population division scheme used to generate the multiswarm for the primary learning phase of MSPSOTLP | |||
| Input: , , , , , , | |||
| 01: | Initialize ; | ||
| 02: | while main population is not empty do | ||
| 03: | Randomly generate in search space; | ||
| 04: | for each n-th particle do | ||
| 05: | Calculate using Equation (15); | ||
| 06: | end for | ||
| 07: | Select particles with the nearest from to construct ; | ||
| 08: | Eliminate the members of from ; | ||
| 09: | ; /* Update the index of subswarm*/ | ||
| 10: | end while | ||
| Output: where | |||
Define as the personal best fitness of each n-th particle stored in the s-th subswarm , where and . All particles stored in each s-th subswarm are then sorted from the worst to best based on their personal best fitness values, as shown in Figure 2. Accordingly, any k-th particle stored in the sorted is considered to have better or equally good personal best fitness than that of n-th particle if the condition of is satisfied. Referring to Figure 2, it is notable that the first particle stored in has the worst personal best fitness, whereas the final particle stored in has the most competitive personal best fitness after the sorting process. Therefore, the personal best position of the final particle is also considered as the subswarm best position of represented as for .
Figure 2.
Graphical illustration of sorting all particles stored in each subswarm based on their personal best fitness values.
For each s-th sorted subswarm, define as a set variable used to store the personal best position of all solution members that are superior to that of n-th solution member for . Notably, the set variable is not constructed for the final solution member because none of the solution members stored in has better personal best fitness than or . Referring to the solution members stored in each , a unique mean position denoted as is then specifically constructed to guide the search process of every n-th solution member in the s-th subswarm, where:
Apart from , a social exemplar that plays crucial roles to adjust the search trajectory of each n-th particle stored in is also formulated. In contrary to global best position, the social exemplar constructed for each n-th particle is unique and it can guide the search process with better diversity by fully utilizing the promising directional information of other particles stored in with better personal best fitness values. Specifically, each d-th dimension of n-th social learning exemplar for s-th subswarm, i.e., , can be contributed by the same dimensional component of any randomly selected solution members of . The procedures used to construct the social exemplar for each n-th particle stored in are described in Algorithm 3, where refers to a random integer generated between the indices of and .
| Algorithm 3. Pseudocode used to generate the social exemplar for each non-fittest solution member in each subswarm | ||
| Input: , , , | ||
| 01: | for each d-th dimension do | |
| 02: | Randomly generate an integer between indices of and ; | |
| 03: | Extract the associated component of from ; | |
| 04: | ; | |
| 05: | end for | |
| Output: | ||
Given the subswarm best position , mean position and social exemplar , the new position of each n-th non-fittest solution member stored in the s-th subswarm, where and , is updated as follows:
where , and represent the acceleration coefficients; are random numbers generated from uniform distributions. Referring to Equation (17), the directional information contributed by and are unique for each n-th non-fittest solution member of because the better solution members are stored in every set variable are different for . The social learning concept incorporated in Equation (17) also ensures that only the useful information brought by better-performing solutions is used to guide the search process of each n-th particle to accelerate the algorithm’s convergence rate. Furthermore, this learning strategy does not consider the global best position in updating the new position of each n-th particle; therefore, it has better robustness against premature convergence issues.
On the other hand, different approaches are proposed to generate the mean position and social exemplar used for guiding the search process of the final particle stored in every n-th subswarm because none of the solution members of can have better personal best fitness than that of . Define as a set variable used to store the subswarm best position of any b-th subswarm if is better than , i.e.,
where is a set containing the indices of all subswarms that have better subswarm best fitness than that of s-th subswarm; refers to the size of set in the range of 0 to . Obviously, is the subswarm best position of s-th subswarm is the same as the global best position of population, therefore the empty sets of are obtained under this circumstance.
The subswarm consists of , the unique mean position used to guide the search process of the final particle stored in each s-th subswarm based on are calculated as follows:
Similarly, a social exemplar of is also derived from adjusting the search trajectory of the final particle stored in each s-th subswarm except for the one consisting of . As shown in Algorithm 4, each d-th dimension of the social exemplar is assigned to the final particle of s-th subswarm , i.e., , is contributed by the same dimensional component of any subswarm best position randomly selected from , where b refers to a subswarm index randomly selected from .
| Algorithm 4. Social Exemplar Scheme for the Best Particle in Each Subswarm | ||
| Input: , , , | ||
| 01: | for each d-th dimension do | |
| 02: | Randomly generated a subswarm index of ; | |
| 03: | Extract the corresponding component of from ; | |
| 04: | ; | |
| 05: | end for | |
| Output: | ||
Except for the subswarm consisting of with , the position of final particle stored in each s-th subswarm can be updated as follows:
where are random numbers generated from a uniform distribution. Similarly, the directional information provided by and are unique for each final particle in each s-th subswarm because the solution members stored in each set are different. Contrary to Equation (17), the social learning concept introduced in Equation (20) allows each subswarm to converge towards the promising solution regions without experiencing rapid loss of population diversity by facilitating the information exchanges between different subswarms. In addition, the employment of in Equation (20) is expected to improve the convergence rate of MSPSOTLP.
The overall procedures of the primary learning phase proposed for MSPSOTLP is described in Algorithm 5. For each new position obtained from Equations (17) or (20), boundary checking is first performed to ensure all decision variables’ upper and lower limits are not violated. The fitness value corresponding to the updated for each particle in s-th subswarm is then evaluated as and compared with those of its personal best position and global best position denoted as and , respectively. Both and are replaced by the updated if the latter solution is proven to be superior to the latter two solutions.
| Algorithm 5. Pseudocode of primary learning phase for MSPSOTLP | |||||
| Input: , , , , , , , | |||||
| 01: | Divide main population into multiple subswarm using Algorithm 2; | ||||
| 02: | Sort the solution members of from the worst to best based on their personal best fitness values and create for each s-th subswarm; | ||||
| 03: | Identify the subswarm best position of each s-th subswarm and create for the final particle in all S subswarms using Equation (18); | ||||
| 04: | Determine and for the final particle of all S subswarms based on ; | ||||
| 05: | for each s-th subswarm do | ||||
| 06: | for each n-th particle do | ||||
| 07: | if then | ||||
| 08: | Calculate based on using Equation (16); | ||||
| 09: | Generate based on using Algorithm 3; | ||||
| 10: | Update using Equation (17); | ||||
| 11: | else if then | ||||
| 12: | if then | ||||
| 13: | Calculate based on using Equation (19); | ||||
| 14: | Generate based on using Algorithm 4; | ||||
| 15: | Update using Equation (20); | ||||
| 16: | end if | ||||
| 17: | end if | ||||
| 18: | Evaluate of the updated ; | ||||
| 19: | if is better than then | ||||
| 20: | ; | ||||
| 21: | if is better than then | ||||
| 22: | ; | ||||
| 23: | end if | ||||
| 24: | end if | ||||
| 25: | end for | ||||
| 26: | end for | ||||
| Output: | |||||
3.2.3. Secondary Learning Phase of MSPSOTLP
Substantial studies [19,65] reported that most PSO variants employed single search operators that can only solve specific optimization problems with good results, but fail to perform well in the remaining problems due to the limited variations of exploration and exploitation strengths. For some challenging optimization problems, the fitness landscapes contained in different subregions of search space can be significantly different. Therefore, the particles need to adjust their exploration and exploitation strengths dynamically when searching in different regions of the solution space to locate global optimum and deliver good optimization results.
Motivated by these findings, a secondary phase is designed as an alternative framework of MSPSOTLP, where two search operators with different search characteristics are incorporated to guide the search process of particles with varying levels of exploration and exploitation strengths. Unlike the primary learning phase, both search operators assigned in the secondary learning phase aim to further refine those already found promising regions by searching around the personal best positions of all MSPSOTLP particles. Before initiating the secondary learning phase, all S subswarms constructed during the primary learning phase, i.e., for , are merged to form the main population with N particles as shown below:
To assign a search operator for each n-th particle during the secondary learning phase of MSPSOTLP, a randomly selected particle with a population index of e is randomly generated, where and . Define as the personal best position of this randomly selected e-th particle and its personal best fitness is evaluated as . If the e-th particle has better personal best fitness than that of , the new personal best position of latter particle can be updated as , where
where are random numbers generated from a uniform distribution. The search operator of Equation (22) can attract of n-th particle towards the promising solution regions covered by the e-th peer particle, hence it behaves more exploratively.
For the case, if e-th particle has more inferior personal best fitness than that of n-th particle, the former solution is discarded. Another four distinct particles with population indices of w, x, y and z are randomly selected instead, where and . Denote , , and as the d-th dimension of the personal best position for the w-th, x-th, y-th and z-th particles, respectively. Let be the same d-th dimension of the global best position. For every n-th particle, each of the d-th dimension of its new personal best position can be calculated as:
where are random numbers generated from a uniform distribution. From Equation (23), there is a probability for each to inherit its original information from or to perform searching around the nearby region of with small perturbations based on the information of , , and . Hence, the search operator of Equation (23) is considered more exploitative than that of Equation (22). The procedures used to implement the secondary learning phase of MSPSOTLP is shown in Algorithm 6. For each new obtained from Equations (22) or (23), boundary checking is performed. For each n-th particle, the fitness value of its updated is obtained as and compared with and . If is better than and , the latter two solutions are replaced by the former one.
| Algorithm 6. Pseudocode of secondary learning phase for MSPSOTLP | ||||
| Input: for , | ||||
| 01: | Reconstruct main population using Equation (21); | |||
| 02: | for each n-th particle do | |||
| 03: | Randomly select e-th particle from with and ; | |||
| 04: | if is better than then | |||
| 05: | Calculate using Equation (22); | |||
| 06: | else if is not better than then | |||
| 07: | for each d-th dimension do | |||
| 09: | Calculate using Equation (23); | |||
| 10: | end for | |||
| 11: | end if | |||
| 12: | Evaluate ; | |||
| 13: | if is better than then | |||
| 14: | ; | |||
| 15: | if is better than then | |||
| 16: | ; | |||
| 17: | end if | |||
| 18: | end if | |||
| 19: | end for | |||
| Output: , , , | ||||
3.2.4. Overall Framework of MSPSOTLP
The overall framework of MSPSOTLP is described in Algorithm 7. The initial population of MSPSOTLP is first generated using the CSOBL initialization scheme, where the chaotic map and oppositional-based learning concepts are incorporated to enhance the quality and coverage of the initial solutions in the search space, respectively. The primary learning phase is performed to update the positions of particles by leveraging the benefits of the multiswarm and social learning concepts. The secondary learning phase is then executed to fine-tune the personal best position of each particle based on two newly proposed search operators with different search characteristics. These iterative search processes are repeated until the termination criterion of is satisfied, where is a counter used to record the fitness evaluation number consumed by MSPSOTLP and is a predefined maximum fitness evaluation number. At the end of the optimization process, is returned as the best-optimized result found by the proposed algorithm. If MSPSOTLP is used to train the ANN model, then can be decoded as the optimal combination of weights, biases, and activation functions used by an ANN model to solve a given dataset.
| Algorithm 7 (Main Algorithm). MSPSOTLP | |||
| Input: , , , , | |||
| 01: | Initialize as an empty vector and ; | ||
| 02: | Initialize ; | ||
| 03: | Generate the initial population using Algorithm 1; | ||
| 04: | ; | ||
| 05: | for each n-th particle do | ||
| 06: | ; | ||
| 07: | If is better than then | ||
| 08: | ; | ||
| 09: | end if | ||
| 10: | end for | ||
| 11: | while do | ||
| 12: | Perform the primary learning phase using Algorithm 5; | ||
| 13: | ; | ||
| 14: | Perform the secondary learning phase using Algorithm 6; | ||
| 15: | ; | ||
| 16: | end while | ||
| Output: , | |||
4. Performance Analysis of MSPSOTLP
The performance of the proposed MSPSOTLP in solving various types of challenging optimization problems is investigated and compared with well-established PSO variants. This includes the performance of MSPSOTLP in solving CEC 2014 benchmark functions, followed by its performance in optimizing the weights, biases, and activation functions of ANN models for solving classification problems.
4.1. Performance Evaluation of MSPSOTLP in Solving Global Optimization Problems
4.1.1. CEC 2014 Benchmark Functions
The optimization performance of the proposed MSPSOTLP is evaluated using 30 benchmark functions of CEC 2014 [66]. As described in Table 3, the benchmark functions with different fitness landscape characteristics can be classified into four categories, known as (i) unimodal functions (F1–F3), (ii) simple multimodal functions (F4–F16), (iii) hybrid functions (F17–F22) and (iv) composition functions (F23–F30). For all benchmark functions in CEC 2014 with D dimensions, the search range X of each decision variable is constrained between −100 to 100. Furthermore, the fitness value of theoretical global optimum of each function is presented in Table 3.
Table 3.
CEC 2014 benchmark functions and its fitness value of theoretical global optimum.
4.1.2. Performance Metrics for Solving Benchmark Functions
Performances of all compared algorithms are measured using the mean fitness and standard deviation SD. Specifically, is the mean error between the fitness of the best solution produced by an algorithm and the actual global optimum of a benchmark function in multiple runs. At the same time, the SD value measures the consistency of an algorithm in solving a given problem. Smaller Fmean and SD imply the capability of an algorithm to solve a function with better accuracy and consistency, respectively.
A set of non-parametric statistical analysis procedures [67,68] are applied to analyze the performance of the proposed MSPSOTLP and its competitors from a statistical point of view. The Wilcoxon signed rank test [68] is applied to conduct a pairwise comparison between the proposed MSPSOTLP and each competitor at a significance level of . The results generated by the Wilcoxon signed rank test are presented in terms of , , p, and h values. and summarize the sum of ranks where MSPSOTLP outperforms or underperforms its peer algorithm, respectively. The p-value indicates the minimum significance level required to identify the performance deviations between the two algorithms. If the p-value is smaller than , the better result achieved by an algorithm is considered statistically significant. Based on the obtained p-value and predefined , the corresponding h value is concluded to be significantly better (i.e., h = “+”), statistically insignificant (i.e., h = “=”), or significantly worse (i.e., h = “-”).
Multiple comparisons among the proposed MSPSOTLP and its competitors is also conducted using the Friedman test [67]. The Friedman test first produces the average ranking of each algorithm. The p-value obtained from the Friedman test measures the global differences among all compared algorithms at a significance level of . If significant global differences are observed, three post-hoc analyses [67], known as Bonferroni-Dunn, Holm, and Hochberg, are performed to analyze the substantial differences among all compared algorithms based on the adjusted p-values (APVs).
4.1.3. Parameter Settings for Solving Benchmark Functions
The performance of the proposed MSPSOTLP in solving CEC 2014 benchmark functions is compared with seven well-established PSO variants. The selected PSO variants include the conventional PSO (PSO) [14], PSO without velocity (PSOWV) [16], unconstrained version of multi-swarm PSO without velocity (MPSOWV) [15], competitive swarm optimizer (CSO) [69], social learning PSO (SLPSO) [18], hybridized PSO with gravitational search algorithm (PSOGSA) [44], and accelerated PSO (APSO) [70].
The parameter settings of all of the compared algorithms are set with the recommended values in their respective literature and presented in Table 4. All compared algorithms are configured with a population size of to solve each benchmark function at for 30 independent times. The maximum fitness evaluation numbers of all algorithms are set as . All compared algorithms are simulated using Matlab 2019b on a personal computer with Intel ® Core i7-7500 CPU @ 2.70 GHz.
Table 4.
Parameter settings of all compared algorithms.
4.1.4. Performance Comparison in Solving CEC 2014 Benchmark Functions
The simulation results of Fmean and SD produced by the proposed MSPSOTLP and other selected PSO variants in solving the CEC 2014 benchmark functions are presented in Table 5. The algorithms’ best and second-best Fmean obtained are indicated in boldface and underlined, respectively. Moreover, the performance comparison between the proposed MSPSOTLP and selected PSO variants is summarized in #BMF and w/t/l. Specifically, #BMF indicates the number of best Fmean obtained by an algorithm in solving all function, while w/t/l reports that the proposed MSPSOTLP has better performance in w function, similar performance in t function, and worse performance in l function as compared to the particular compared algorithm.
Table 5.
Fmean and SD values produced by the proposed MSPSOTLP and other PSO variants in solving CEC 2014 benchmark functions.
For unimodal functions (i.e., F1–F3), the proposed MSPSOTLP has the most dominating search performance by producing the best Fmean values to solve these three functions. MSPSOTLP is also the only PSO variant to locate the global and near-global optimum solutions of F2 and F3, respectively. Apart from MSPSOTLP, both PSO and PSOGSA are considered to have relatively better search performance than the rest of the algorithms in solving unimodal functions by producing one second-best Fmean. Meanwhile, PSOWV, MPSOWV and APSO have inferior search performance by producing Fmean values that are generally larger than those of the other algorithms.
For simple multimodal functions (i.e., F4-F16), the proposed MSPSOTLP has the most competitive performance in solving these 13 functions with the seven best Fmean (i.e., F4, F7, F10, F13, and F14) and three second-best Fmean (i.e., F5, F8, and F9). MSPSOTLP is also the only algorithm that successfully locates the global optimum of function F7. Contrary to unimodal functions, CSO and SLPSO have exhibited relatively better performance in solving several simple multimodal functions, such as F6, F8, F9, and F11. Although PSO and PSOGSA have good performance in solving unimodal functions, their performances in solving F4, F6, F7, F8, F9, F10, F11, F13, F15, and F16 are relatively inferior. The performance degradations of PSO and PSOGSA reflect the limitation of both algorithms in tackling optimization problems with multiple local optima. Meanwhile, APSO shows relatively better search performance at solving F5, F12, and F14 than PSOWV and MPSOWV.
The excellent optimization performance of the proposed MSPSOTLP is also demonstrated in the hybrid function category (i.e., F17–F22) by solving all six functions with the best Fmean values. PSOGSA follows this, producing three second-best Fmean values for F17, F18, and F21. However, the performance of PSOGSA in solving hybrid functions is not consistent, as shown by its relatively inferior results in F19 and F22. A similar scenario is observed from PSO, CSO, and SLPSO, producing mediocre performance in solving most hybrid functions. Specifically, PSO can solve F20 and F21 with relatively good performance, but it performs poorly in F17, F18, F19, and F22. Meanwhile, CSO is reported to solve F19 and F22 with competitive performance, but delivers poor results for F17, F18, F20, and F21. On the other hand, APSO, PSOWV, and MPSOWV are reported to have inferior search performance in solving all hybrid functions with higher complexity levels.
In the category of composition function (i.e., F23–F30), PSOGSA shows its competitive performance in dealing with these more complex functions, followed by the proposed MSPSOTLP. PSAGSA can solve all eight composite functions with the best Fmean values, while MSPSOTLP produces two best Fmean (i.e., F25 and F26) and five second-best Fmean (i.e., F23, F24, F28, F29, and F30). Although PSOGSA performs better than MSPSOTLP when solving composite functions, PSOGSA performs more inferiorly than MSPSOTLP in three other problem categories. CSO produces one best Fmean (i.e., F26) and three second-best Fmean (i.e., F23, F25, and F27), implying its competitive performance in solving composite functions. Meanwhile, SLPSO is observed to have relatively good performance in solving F23 and F25, but mediocre performance in the remaining composite functions.
Overall, the proposed MSPSOTLP has demonstrated the best search accuracy among all compared PSO variants by producing 18 best Fmean values in solving 30 functions, implying that the search mechanisms incorporated are sufficiently robust to handle optimization problems with different levels of complexity as compared to most of its peer algorithms. This is followed by PSOGSA and CSO, which are reported to have 10 and 5 best Fmean values, respectively. On the other hand, PSOWV is identified as the worst algorithm by producing 26 worst Fmean values in solving 30 CEC 2014, implying its limitations in solving the benchmark functions with simple fitness landscapes.
4.1.5. Non-Parametric Statistical Analyses
Based on the reported Fmean values, Wilcoxon signed rank test [68] is applied to perform a pairwise comparison between the proposed MSPSOTLP and the selected PSO variants. The results in terms of , , p, and h values, are presented in Table 6. Accordingly, MSPSOTLP performs significantly better than all other PSO variants at a significance level of as indicated by the h value of “+”. Notably, the proposed MSPSOTLP completely dominates PSO, PSOWV, and PSOWV to solve CEC 2014 benchmark functions based on the promising , , p and h values reported.
Table 6.
Pairwise comparisons by Wilcoxon signed rank test between MSPSOTLP and each peer algorithm.
The Friedman test [67] is further conducted for multiple comparisons between the proposed MSPSOTLP and selected PSO variants based on their Fmean values. The results, in terms of average ranking, chi-square statistics, and p-value, are reported in Table 7. The Friedman test reports that MSPSOTLP has the best performance by scoring an average rank of 1.6833, followed by CSPSO, PSOGSA, SLPSO, PSO, APSO, MPSOWV, and PSOWV with average ranks of 3.0500, 3.0667, 3.7667, 4.4167, 5.6500, 6.6500, and 7.7167, respectively. The p-value determined by the Friedman test through chi-square statistics is smaller than the predefined significance level of . Therefore, significant global performance deviations among all compared algorithms are observed.
Table 7.
Average ranking and p-value produced by Friedman test.
Given the global performance difference observed from the Friedman test, three post-hoc statistical analyses [67], known as Bonferroni-Dunn, Holm, and Hochberg, are utilized to identify other concrete performance differences between the proposed MSPSOTLP and different PSO variants. The results, in terms of z values, unadjusted p values, and adjusted p values (APVs), produced by three procedures are reported in Table 8. All post-hoc procedures confirm the significant performance enhancement of MSPSOTLP against PSOWV, MPSOWV, APSO, SLPSO, and PSO at . The Hochberg procedure has higher sensitivity to detect the significant performance difference between MSPSOTLP, CSO, and PSAGSA. Notably, the Holm procedure can detect the significant performance improvement of MSPSOTLP against CSO and PSOGSA if the threshold level is adjusted to .
Table 8.
Adjusted p values produced by each algorithm through three post-hoc analysis procedures.
4.1.6. Performance Analysis of Proposed Improvement Strategies
A further performance analysis is conducted in this subsection to investigate the contribution brought by each improvement strategy introduced into MSPSOTLP, i.e., modified initialization scheme (i.e., chaotic map and oppositional based learning), primary learning phase (i.e., multiswarm concept and construction of social exemplar), and secondary learning phase (i.e., two search operators with different search characteristic). The original PSOWV is chosen as the baseline method to be compared in this subsection. Another three variants of MSPSOTLP, i.e., MSPSOTLP-1, MSPSOTLP-2 and MSPSOTLP-3, are also introduced to analyze the performance gains brought by the modified initialization scheme, primary learning phase, and secondary learning phase, respectively. Particularly, MSPSOTLP-1 refers to the PSOWV enhanced with the CSOBL initialization scheme. Meanwhile, MSPSOTLP-2 refers to PSOWV enhanced with the CSOBL initialization scheme and primary learning phase. Finally, MSPSOTLP-3 refers to PSOWV enhanced with the CSOBL initialization scheme and secondary learning phase, where its primary phase is replaced with the original search operator of PSOWV. The performance gain achieved by each MSPSOTLP variants against the original PSOWV when solving every benchmark function is measured as as follow:
Referring to Equation (24), it is evident that a positive value of can be obtained if a particular MSPSOTLP variant can solve the benchmark functions with better Fmean value than that of PSOWV and vice versa.
The simulation results in terms of Fmean and obtained by PSOWV and all MSPSOTLP variants when solving all CEC 2014 benchmark functions are presented in Table 9. Accordingly, all MSPSOTLP variants have successfully solved the majority of CEC 2014 benchmark functions with different degrees of performance gains. MPSOTLP-1 is observed to outperform PSOWV in the majority of CEC 2014 benchmark functions except for F1, F5, F6, F11, F12, F16, F17, F21, F29, and F30. Although the CSOBL can produce an initial population with better solution quality in terms of fitness and diversity that can lead to performance gain of algorithm, it is not sufficient to solve the complex problem because CSOBL is only executed once during the search process. Some interesting findings can be observed when both variants of MSPSOTLP-2 and MSPSOTLP-3 are used to solve CEC 2014 benchmark functions. Particularly, MSPSOTLP-2 can perform better than MSPSOTLP-3 when solving the unimodal (i.e., F1 to F3), simple multimodal (i.e., F4 to F16) and hybrid (i.e., F17 to F22) functions. Meanwhile, MSPSOTLP-3 is revealed to be more competitive than MSPSOTLP-2 in dealing with the most complex composition function. The performance differences between MSPSOTLP-2 and MSPSOTLP03 can be justified based on their inherent search mechanisms. For MSPSOTLP-2, the primary learning phase is incorporated with multiswarm and social learning concepts used to accelerate the convergence characteristic of the algorithm without compromising its population diversity. When dealing with optimization functions with less complex fitness landscapes (i.e., unimodal, simple multimodal, and hybrid functions), the benefits brought by both the multiswarm and social learning concepts can still suppress the potential negative drawbacks of the historically best position (i.e., global best position in this case). When the fitness landscapes of the optimization problems are increased further, such as those in composition functions, the numbers of local optima in the solution space have increased exponentially. Under this circumstance, the diversity maintenance scheme introduced in the primary learning phase of MSPSOTLP-2 is not sufficient to curb the high tendency of historically best positions to be trapped in these local optima. On the other hand, the secondary learning phase of MSPSOTLP-3 can leverage the useful directional information of other non-fittest solutions to perform searching with greater exploration strengths; thus, it has a higher chance to escape from the inferior regions of the solution space. Finally, the complete MSPSOTLP has exhibited the best performance when solving all CEC 2014 benchmark functions with 26 best and 4 s-best Fmean values. The simulation results reported in Table 9 have verified that each improvement strategy incorporated into MSPSOTLP indeed has different contributions to enhancing the search performance of the proposed algorithm.
Table 9.
Simulation results of Fmean and obtained by PSOWV and all MSPSOTLP variants when solving CEC 2014 benchmark functions.
4.2. Performance Evaluation of MSPSOTLP in Training ANN Models
4.2.1. Classification Datasets for Training ANN Models
Apart from general optimization performance, the capability of the proposed MSPSOTLP in training ANN models for data classification tasks is also evaluated using sixteen standard datasets extracted from the University of California Irvine (UCI) machine learning repository [71]. The sixteen datasets selected for performance evaluation include Iris, Liver Disorder, Blood Transfusion, Statlog Heart, Hepatitis, Wine, Breast Cancer, Seeds, Australian Credit Approval, Haberman’s Survival, New Thyroid, Glass, Balance Scale, Dermatology, Landsat and Bank Note. The properties of each dataset are summarized in Table 10. Each selected dataset is separated into two parts, known as 70% of training samples and 30% of testing samples. Specifically, the training samples are used by MSPSOTLP and other PSO variants to optimize the parameters of ANN models (i.e., weights, biases, and activation function). In contrast, the testing samples are used to evaluate the generalization performance of ANN models trained by all compared algorithms.
Table 10.
Properties of datasets selected for ANN model training.
4.2.2. Performance Metrics for ANN Training
Classification accuracy is a popular performance metric used to measure the classification performance of an ANN model. Suppose that refers to the number of correctly classified data samples by the ANN model, while represents the total number of data samples in each dataset. The value is calculated as follow:
An ANN model with a larger value of is more desirable because it can produce better results in terms of classification accuracy. In addition, the ANN model produces a larger value when solving the testing samples s also considered to have better generalization performance due to its excellent capability to accurately classify unseen data in different classes with its understanding of the existing data. Furthermore, the standard deviation SD values are also recorded to observe the consistency of ANN models trained by compared PSO variants in solving classification datasets.
4.2.3. Parameter Settings for ANN Training
Similar to the global optimization, the performance of the ANN model trained by the proposed MSPSOTLP in solving sixteen datasets extracted from the UCI machine learning repository is compared with the seven PSO variants reported in Section 4.1.3. The parameters of all compared algorithms are configured as reported in Table 3 as recommended in their original literature. The same values of and are also configured for all compared PSO variants in solving ANN training problems, where the value of D is calculated based on Equation (7). The ANN model to be trained in this study is constructed by an input layer, a hidden layer, and an output layer. The number of input and output neurons of each ANN model are configured based on the number of attributes and classes of a given dataset, respectively, as presented in Table 8. Meanwhile, the number of neurons in the hidden layer is 15. Similarly, all compared algorithms in training ANN model are simulated using Matlab 2019b on a personal computer with Intel ® Core i7-7500 CPU @ 2.70GHz.
4.2.4. Performance Comparison in Training ANN Models
The and SD values produced by the ANN models optimized by all compared PSO variants when classifying the training and testing samples are presented in Table 11 and Table 12, respectively. Similarly, the best and second best values produced by the compared methods in each dataset are indicated in boldface and underlined, respectively. The comparative studies between the ANN models trained by MSPSOTLP and other PSO variants are summarized in and w/t/l as similar to those in Table 5. Specifically, records the number of best values produced by each algorithm in training the ANN models for 16 datasets extracted from UCI machine learning repository.
Table 11.
The and SD values produced by ANN models trained by the proposed MSPSOTLP and other PSO variants when solving the training samples.
Table 12.
The and SD values produced by ANN models trained by the proposed MSPSOTLP and other PSO variants when solving the testing samples.
According to Table 11, ANN models trained by the proposed MSPSOTLP are reported to have the best performance for being able to solve 12 out of 16 sets of training samples with the best values. Specifically, MSPSOTLP emerges as the best training algorithm for ANN models in dealing with datasets of Iris, Statlog Hearts, Hepatitis, Wine, Seeds, Australian Credit Approval, New Thyroid, Glass, Balance Scale, Dermatology, Landsat, and Bank Note. It is also noteworthy that the proposed MSPSOTLP is the only algorithm that has successfully trained ANN models with 100% of values to classify the training sets of Wine and Bank Note. The ANN models trained by PSO and PSAGSA can occasionally deliver good performances by producing two best values in solving training samples. Although the values produced by ANN models trained by the proposed MSPSOSLP in classifying training samples of Liver Disorder, Blood Transfusion, Breast Cancer, and Haberman’s Survival are slightly lower than PSO and PSOGSA, the performance differences between these algorithms are marginal and not more than 1%. On the other hand, the ANN models trained by MSPSOTLP are reported to have more notable performance differences than PSO and PSOGSA in terms of values when classifying the training samples of Iris, Statlog Heart, Hepatitis, Seeds, New Thyroid, Glass, and Landsat. The ANN models trained by PSOWV are reported to have the most inferior performance by producing eight worst and seven second-worst values when solving all 16 classification datasets except for Landsat.
In addition to training samples, 30% of datasets are extracted as testing samples to evaluate the generalization performances of ANN models optimized by all compared PSO variants. According to Table 12, ANN models trained by the proposed MSPSOTLP are reported to have the best generalization performance for being able to produce 12 best and 2 s-best values when classifying the testing samples of 16 selected datasets. Specifically, ANN models trained by MSPSOTLP successfully produce the best in solving the testing samples of Iris, Statlog Heart, Hepatitis, Wine, Breast Cancer, Seeds, Haberman’s Survival, New Thyroid, Glass, Balance Scale, Landsat, and Bank Note. Moreover, MSPSOTLP is also reported to be the only algorithm that can train ANN models to solve the testing samples of Iris and Seeds with 100% of . On the other hand, the ANN models trained by PSO, MPSOWV, SLPSO, and APSO are reported to produce the best values when classifying the testing samples of Dermatology, Blood Transfusion, Australian Credit Approval, and Liver Disorder, respectively. Although ANN models trained by MSPSOTLP are observed to produce relatively inferior values in solving the testing samples of these four datasets, some performance differences are insignificant. On the contrary, ANN models trained by MSPSOTLP produce much better values than PSO, MPSOWV, SLPSO, and APSO in solving the testing samples of certain datasets, such as Hepatitis, Wine, Seeds, New Thyroid, etc. The ANN models trained by PSOWV perform the worst by producing seven lowest values (i.e., testing samples of Liver Disorder, Breast Cancer, Seeds, Australian Credit Approval, New Thyroid, Glass, and Balance Scale) and eight second-worst values (i.e., testing samples of Iris, Statlog Heart, Hepatitis, Wine, Haberman’s Survival, Dermatology, Landsat, and Bank Note).
4.2.5. Non-Parametric Statistical Analyses
Similar to those reported in Section 4.1.5, the Wilcoxon signed rank test [68] is applied to perform a pairwise comparison between the proposed MSPSOTLP and the selected PSO variants based on the reported values. The , , p, and h values produced by ANN models trained by the compared algorithms in classifying the training and testing samples are presented in Table 13 and Table 14, respectively. From Table 13, ANN models trained by the proposed MSPSOTLP have significantly better performance than those of other PSO variants at a significance level of , as indicated by the h value of “+”. Notably, the ANN model optimized by the proposed MSPSOTLP can completely dominate those of PSOWV, CSO, SLPSO, and APSO when solving the training samples of selected datasets. Similarly, ANN models trained by MSPSOTLP are observed to perform significantly better than other PSO variants in solving all testing samples of datasets chosen, as indicated by the h values of “+” in Table 14. These pairwise comparison results imply the excellent generalization ability of ANN model trained by MSPSOTLP due to its ability to handle unseen data of testing samples effectively.
Table 13.
Wilcoxon signed rank test as a pairwise comparison between the ANN models optimized by MSPSOTLP and each PSO variant when classifying the training samples.
Table 14.
Wilcoxon signed rank test as pairwise comparison between the ANN models optimized by MSPSOTLP and each PSO variant when classifying the testing samples.
Apart from pairwise comparison, multiple comparisons among the ANN models trained by all compared algorithms are also conducted by Friedman Test [67]. The average ranking values produced by the ANN models trained by all compared algorithms in solving training and testing samples are reported in Table 15 and Table 16, respectively. Table 15 shows that the ANN models trained by MSPSOTLP score the best average ranking when classifying the training datasets, followed by PSOGSA, PSO, MPSOWV, CSO, SLPSO, APSO, and PSOWV. Although Table 7 reports that MPSOWV has a relatively poor ranking in solving CEC 2014 benchmark functions, it performs relatively well in training ANN models in solving training samples. Conversely, CSO does not perform well in training the ANN model despite producing relatively competitive performance in solving CEC 2014 benchmark functions. Table 16 reveals that the ANN model trained by MSPSOTLP has the best average ranking value in classifying the testing samples, followed by MPSOWV, PSO, PSOGSA, SLPSO, CSO, APSO, and PSOWV. Similarly, MPSOWV shows its competitive performance in training the ANN model, despite having inferior performance in solving CEC 2014 benchmark functions. Although the ANN model trained by PSOGSA has the second-best average ranking in solving training samples, as reported in Table 15, it does not perform well in solving testing samples, as reported in Table 16, implying the tendency of PSAGSA to produce the ANN models that suffer with overfitting issues and have poor generalization performance to handle unseen data.
Table 15.
The average ranking values of ANN models are trained by all compared algorithms in solving training samples.
Table 16.
The average ranking values of ANN models are trained by all compared algorithms in solving testing samples.
Referring to the p values reported in Table 15 and Table 16, significant global performance differences among the ANN models trained by all compared algorithms to solve training and testing samples are observed at a significance level of . The concrete differences between the ANN models trained by MSPSOTLP and other PSO variants in classifying the training and testing samples are further analyzed using the Bonferroni-Dunn, Holm, and Hochberg procedures, as shown in Table 17 and Table 18, respectively. According to the APVs for solving training samples, as reported in Table 17, all post-hoc procedures confirm the significant performance improvement of ANN models trained by MSPSOTLP against those of PSOWV, APSO, SLPSO, and CPSO at . On the other hand, all post-hoc procedures can detect the significant performance improvement of ANN models trained by MSPSOTLP against those of PSOWV, APSO, CSO, SLPSO, and PSOGSA in solving testing samples, as indicated by the APVs values in Table 18.
Table 17.
Adjusted p values produced by trained ANN models in solving training samples through three post-hoc analysis procedures.
Table 18.
Adjusted p values produced by trained ANN models in solving testing samples through three post-hoc analysis procedures.
5. Conclusions
This study proposes a new PSO variant known as multi-swarm-based particle swarm optimization with two-level learning phases (MSPSOTLP) to address the potential drawbacks of PSOWV. Three significant modifications are introduced into the proposed MSPSOTLP to ensure that proper balancing of the exploration and exploitation searches of the algorithm can be achieved in handling more challenging optimization problems, including the training process of the ANN model. A new population initialization scheme, the CSOBL initialization scheme, is incorporated to replace the conventional random initialization scheme in generating initial solutions with better diversity and broader coverage in the solution space. Both multiswarm and social learning concepts are incorporated into the primary learning phase of MSPSOTLP to guide the search process of particles more effectively without losing population diversity by leveraging the directional information contributed by other non-fittest particles in the population. Additionally, a secondary learning phase is introduced with the adoption of two search operators with different levels of exploration and exploitation strengths, aiming to address the limitations of a single search operator adopted by many existing PSO variants. Extensive simulation studies report that the proposed MSPSOTLP outperforms the selected seven PSO variants in solving benchmark problems from CEC 2014 by producing 18 best mean fitness values out of 30 functions. Moreover, the training process of the ANN model is also formulated as an optimization problem, where the objective is to produce the optimal values of weights and biases and the selection of activation functions. The proposed MSPSOTLP is reported to have the best overall performance in training ANN models to solve classification datasets extracted from the UCI machine learning repository.
While MSPSOTLP has demonstrated competitive performances to solve the CEC 2014 benchmark functions and train ANN model for classifying UCI machine learning datasets, the proposed work still has room for improvement in terms of its search mechanisms and potential real-world applications. First, the main population of MSPSOTLP is divided by the reference-point-based population division scheme into a predefined number of subswarms during the primary learning phase. It is nontrivial to determine the optimal subswarm numbers for optimization problems with different types of fitness landscapes. Second, the solution update process of MSPSOTLP is performed by comparing the fitness values of current and new particles. It is noteworthy that such a greedy selection scheme tends to suppress the survival of novel particles that might have temporary poor performances at the earlier stage of search process, but can contribute for long-term success if given sufficient iteration numbers. Third, the performance of the ANN optimized by MSPSOTLP is currently evaluated using the datasets obtained from a public database. Despite exhibiting promising classification accuracy in most selected datasets, the feasibility of the proposed method to solve more challenging real-world classification and regression problems remains unexplored. Some potential future works are then suggested to address these aforementioned limitations. First, the population division scheme of MSPSOTLBP can be further enhanced such that the optimal subswarm numbers can be determined adaptively based on the types of fitness landscapes encountered by the population. Second, other criteria, such as the fitness improvement rate and population diversity, should be considered by MSPSOTLP during the solution update process to preserve the novel particles that can bring long-term success for the algorithm. Finally, it is worth it to investigate the feasibility of ANN optimized by MSPSOTLP to address challenging issues encountered in the intelligent condition monitoring of complex industrial systems [2], such as the remaining useful life prediction of gear pumps [72], the time series prognosis of fuel cells [73], and predictive maintenance of renewable energy systems [74].
Author Contributions
Conceptualization, W.H.L., S.S.T. and E.-S.M.E.-K.; methodology, K.M.A., W.H.L. and E.-S.M.E.-K.; software, K.M.A., C.E.C., A.A.A. and A.I.; validation, K.M.A., C.E.C., F.K.K. and D.S.K.; formal analysis, K.M.A., S.S.T. and W.H.L.; investigation, K.M.A., W.H.L. and E.-S.M.E.-K.; resources, E.-S.M.E.-K., C.E.C., F.K.K. and D.S.K.; data curation, K.M.A., C.E.C., A.A.A., A.I. and F.K.K.; writing—original draft preparation, K.M.A., C.E.C., A.A.A., A.I. and F.K.K.; writing—review and editing, W.H.L., S.S.T. and E.-S.M.E.-K.; visualization, K.M.A., C.E.C. and D.S.K.; supervision, W.H.L., S.S.T. and E.-S.M.E.-K.; project administration, W.H.L. and E.-S.M.E.-K.; funding acquisition, E.-S.M.E.-K. and D.S.K. All authors have read and agreed to the published version of the manuscript.
Funding
Princess Nourah bint Abdulrahman University Researchers Supporting Project number (PNURSP2022R300), Princess Nourah bint Abdulrahman University, Riyadh, Saudi Arabia.
Data Availability Statement
The data will be provided upon reasonable request.
Acknowledgments
Princess Nourah bint Abdulrahman University Researchers Supporting Project number (PNURSP2022R300), Princess Nourah bint Abdulrahman University, Riyadh, Saudi Arabia.
Conflicts of Interest
The authors declare no conflict of interest.
References
- Khashei, M.; Bijari, M. An artificial neural network (p, d, q) model for timeseries forecasting. Expert Syst. Appl. 2010, 37, 479–489. [Google Scholar] [CrossRef] [Scilit]
- Berghout, T.; Benbouzid, M. A Systematic Guide for Predicting Remaining Useful Life with Machine Learning. Electronics 2022, 11, 1125. [Google Scholar] [CrossRef] [Scilit]
- Abdelhamid, A.A.; El-Kenawy, E.-S.M.; Alotaibi, B.; Amer, G.M.; Abdelkader, M.Y.; Ibrahim, A.; Eid, M.M. Robust Speech Emotion Recognition Using CNN+ LSTM Based on Stochastic Fractal Search Optimization Algorithm. IEEE Access 2022, 10, 49265–49284. [Google Scholar] [CrossRef] [Scilit]
- El-kenawy, E.-S.M.; Albalawi, F.; Ward, S.A.; Ghoneim, S.S.; Eid, M.M.; Abdelhamid, A.A.; Bailek, N.; Ibrahim, A. Feature selection and classification of transformer faults based on novel meta-heuristic algorithm. Mathematics 2022, 10, 3144. [Google Scholar] [CrossRef] [Scilit]
- Alhussan, A.A.; Khafaga, D.S.; El-Kenawy, E.-S.M.; Ibrahim, A.; Eid, M.M.; Abdelhamid, A.A. Pothole and Plain Road Classification Using Adaptive Mutation Dipper Throated Optimization and Transfer Learning for Self Driving Cars. IEEE Access 2022, 10, 84188–84211. [Google Scholar] [CrossRef] [Scilit]
- Wu, H.; Zhou, Y.; Luo, Q.; Basset, M.A. Training feedforward neural networks using symbiotic organisms search algorithm. Comput. Intell. Neurosci. 2016, 2016, 9063065. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Feng, J.; Lu, S. Performance analysis of various activation functions in artificial neural networks. J. Phys. Conf. Ser. 2019, 1237, 022030. [Google Scholar] [CrossRef] [Scilit]
- Abu-Shams, M.; Ramadan, S.; Al-Dahidi, S.; Abdallah, A. Scheduling Large-Size Identical Parallel Machines with Single Server Using a Novel Heuristic-Guided Genetic Algorithm (DAS/GA) Approach. Processes 2022, 10, 2071. [Google Scholar] [CrossRef] [Scilit]
- Sharma, A.; Khan, R.A.; Sharma, A.; Kashyap, D.; Rajput, S. A Novel Opposition-Based Arithmetic Optimization Algorithm for Parameter Extraction of PEM Fuel Cell. Electronics 2021, 10, 2834. [Google Scholar] [CrossRef] [Scilit]
- Singh, A.; Sharma, A.; Rajput, S.; Mondal, A.K.; Bose, A.; Ram, M. Parameter Extraction of Solar Module Using the Sooty Tern Optimization Algorithm. Electronics 2022, 11, 564. [Google Scholar] [CrossRef] [Scilit]
- El-Kenawy, E.-S.M.; Mirjalili, S.; Abdelhamid, A.A.; Ibrahim, A.; Khodadadi, N.; Eid, M.M. Meta-heuristic optimization and keystroke dynamics for authentication of smartphone users. Mathematics 2022, 10, 2912. [Google Scholar] [CrossRef] [Scilit]
- Khafaga, D.S.; Alhussan, A.A.; El-Kenawy, E.-S.M.; Ibrahim, A.; Eid, M.M.; Abdelhamid, A.A. Solving Optimization Problems of Metamaterial and Double T-Shape Antennas Using Advanced Meta-Heuristics Algorithms. IEEE Access 2022, 10, 74449–74471. [Google Scholar] [CrossRef] [Scilit]
- El-Kenawy, E.-S.M.; Mirjalili, S.; Alassery, F.; Zhang, Y.-D.; Eid, M.M.; El-Mashad, S.Y.; Aloyaydi, B.A.; Ibrahim, A.; Abdelhamid, A.A. Novel Meta-Heuristic Algorithm for Feature Selection, Unconstrained Functions and Engineering Problems. IEEE Access 2022, 10, 40536–40555. [Google Scholar] [CrossRef] [Scilit]
- Kennedy, J.; Eberhart, R. Particle swarm optimization. In Proceedings of the ICNN’95—International Conference on Neural Networks, Perth, Australia, 27 November–1 December 1995; Volume 1944, pp. 1942–1948. [Google Scholar]
- Ang, K.M.; Lim, W.H.; Isa, N.A.M.; Tiang, S.S.; Wong, C.H. A constrained multi-swarm particle swarm optimization without velocity for constrained optimization problems. Expert Syst. Appl. 2020, 140, 112882. [Google Scholar] [CrossRef] [Scilit]
- El-Sherbiny, M.M. Particle swarm inspired optimization algorithm without velocity equation. Egypt. Inform. J. 2011, 12, 1–8. [Google Scholar] [CrossRef] [Scilit]
- Tian, D.; Zhao, X.; Shi, Z. DMPSO: Diversity-guided multi-mutation particle swarm optimizer. IEEE Access 2019, 7, 124008–124025. [Google Scholar] [CrossRef] [Scilit]
- Cheng, R.; Jin, Y. A social learning particle swarm optimization algorithm for scalable optimization. Inf. Sci. 2015, 291, 43–60. [Google Scholar] [CrossRef] [Scilit]
- Lim, W.H.; Isa, N.A.M.; Tiang, S.S.; Tan, T.H.; Natarajan, E.; Wong, C.H.; Tang, J.R. A self-adaptive topologically connected-based particle swarm optimization. IEEE Access 2018, 6, 65347–65366. [Google Scholar] [CrossRef] [Scilit]
- Isiet, M.; Gadala, M. Self-adapting control parameters in particle swarm optimization. Appl. Soft Comput. 2019, 83, 105653. [Google Scholar] [CrossRef] [Scilit]
- Li, M.; Chen, H.; Wang, X.; Zhong, N.; Lu, S. An improved particle swarm optimization algorithm with adaptive inertia weights. Int. J. Inf. Technol. Decis. Mak. 2019, 18, 833–866. [Google Scholar] [CrossRef] [Scilit]
- Ghasemi, M.; Akbari, E.; Rahimnejad, A.; Razavi, S.E.; Ghavidel, S.; Li, L. Phasor particle swarm optimization: A simple and efficient variant of PSO. Soft Comput. 2019, 23, 9701–9718. [Google Scholar] [CrossRef] [Scilit]
- Liu, W.; Wang, Z.; Zeng, N.; Yuan, Y.; Alsaadi, F.E.; Liu, X. A novel randomised particle swarm optimizer. Int. J. Mach. Learn. Cybern. 2021, 12, 529–540. [Google Scholar] [CrossRef] [Scilit]
- Ang, K.M.; Juhari, M.R.M.; Cheng, W.-L.; Lim, W.H.; Tiang, S.S.; Wong, C.H.; Rahman, H.; Pan, L. New Particle Swarm Optimization Variant with Modified Neighborhood Structure. In Proceedings of the 2022 International Conference on Artificial Life and Robotics (ICAROB2022), Oita, Japan, 20–23 January 2022. [Google Scholar] [CrossRef] [Scilit]
- Wu, D.; Jiang, N.; Du, W.; Tang, K.; Cao, X. Particle swarm optimization with moving particles on scale-free networks. IEEE Trans. Netw. Sci. Eng. 2018, 7, 497–506. [Google Scholar] [CrossRef] [Scilit]
- Xu, Y.; Pi, D. A reinforcement learning-based communication topology in particle swarm optimization. Neural Comput. Appl. 2020, 32, 10007–10032. [Google Scholar] [CrossRef] [Scilit]
- Chen, K.; Xue, B.; Zhang, M.; Zhou, F. Novel chaotic grouping particle swarm optimization with a dynamic regrouping strategy for solving numerical optimization tasks. Knowl. Based Syst. 2020, 194, 105568. [Google Scholar] [CrossRef] [Scilit]
- Roshanzamir, M.; Balafar, M.A.; Razavi, S.N. A new hierarchical multi group particle swarm optimization with different task allocations inspired by holonic multi agent systems. Expert Syst. Appl. 2020, 149, 113292. [Google Scholar] [CrossRef] [Scilit]
- Yang, Q.; Chen, W.-N.; Da Deng, J.; Li, Y.; Gu, T.; Zhang, J. A level-based learning swarm optimizer for large-scale optimization. IEEE Trans. Evol. Comput. 2017, 22, 578–594. [Google Scholar] [CrossRef] [Scilit]
- Li, W.; Meng, X.; Huang, Y.; Fu, Z.-H. Multipopulation cooperative particle swarm optimization with a mixed mutation strategy. Inf. Sci. 2020, 529, 179–196. [Google Scholar] [CrossRef] [Scilit]
- Liu, H.; Zhang, X.-W.; Tu, L.-P. A modified particle swarm optimization using adaptive strategy. Expert Syst. Appl. 2020, 152, 113353. [Google Scholar] [CrossRef] [Scilit]
- Xia, X.; Gui, L.; He, G.; Wei, B.; Zhang, Y.; Yu, F.; Wu, H.; Zhan, Z.-H. An expanded particle swarm optimization based on multi-exemplar and forgetting ability. Inf. Sci. 2020, 508, 105–120. [Google Scholar] [CrossRef] [Scilit]
- Xu, G.; Cui, Q.; Shi, X.; Ge, H.; Zhan, Z.-H.; Lee, H.P.; Liang, Y.; Tai, R.; Wu, C. Particle swarm optimization based on dimensional learning strategy. Swarm Evol. Comput. 2019, 45, 33–51. [Google Scholar] [CrossRef] [Scilit]
- Wang, C.; Song, W. A modified particle swarm optimization algorithm based on velocity updating mechanism. Ain Shams Eng. J. 2019, 10, 847–866. [Google Scholar] [CrossRef] [Scilit]
- Karim, A.A.; Isa, N.A.M.; Lim, W.H. Modified particle swarm optimization with effective guides. IEEE Access 2020, 8, 188699–188725. [Google Scholar] [CrossRef] [Scilit]
- Karim, A.A.; Isa, N.A.M.; Lim, W.H. Hovering Swarm Particle Swarm Optimization. IEEE Access 2021, 9, 115719–115749. [Google Scholar] [CrossRef] [Scilit]
- Wei, B.; Zhang, W.; Xia, X.; Zhang, Y.; Yu, F.; Zhu, Z. Efficient feature selection algorithm based on particle swarm optimization with learning memory. IEEE Access 2019, 7, 166066–166078. [Google Scholar] [CrossRef] [Scilit]
- Şenel, F.A.; Gökçe, F.; Yüksel, A.S.; Yiğit, T. A novel hybrid PSO–GWO algorithm for optimization problems. Eng. Comput. 2019, 35, 1359–1373. [Google Scholar] [CrossRef] [Scilit]
- Zhang, M.; Long, D.; Qin, T.; Yang, J. A chaotic hybrid butterfly optimization algorithm with particle swarm optimization for high-dimensional optimization problems. Symmetry 2020, 12, 1800. [Google Scholar] [CrossRef] [Scilit]
- Ang, K.M.; Juhari, M.R.M.; Lim, W.H.; Tiang, S.S.; Ang, C.K.; Hussin, E.E.; Pan, L.; Chong, T.H. New Hybridization Algorithm of Differential Evolution and Particle Swarm Optimization for Efficient Feature Selection. In Proceedings of the 2022 International Conference on Artificial Life and Robotics (ICAROB2022), Oita, Japan, 20–23 January 2022; Volume 27, p. 5. [Google Scholar] [CrossRef] [Scilit]
- Grosan, C.; Abraham, A. Hybrid evolutionary algorithms: Methodologies, architectures, and reviews. In Hybrid Evolutionary Algorithms; Springer: Berlin/Heidelberg, Germany, 2007; pp. 1–17. [Google Scholar]
- Abdolrasol, M.G.; Hussain, S.S.; Ustun, T.S.; Sarker, M.R.; Hannan, M.A.; Mohamed, R.; Ali, J.A.; Mekhilef, S.; Milad, A. Artificial neural networks based optimization techniques: A review. Electronics 2021, 10, 2689. [Google Scholar] [CrossRef] [Scilit]
- Carvalho, M.; Ludermir, T.B. Particle swarm optimization of neural network architectures andweights. In Proceedings of the 7th International Conference on Hybrid Intelligent Systems (HIS 2007), Kaiserslautern, Germany, 17–19 September 2007; pp. 336–339. [Google Scholar]
- Mirjalili, S.; Hashim, S.Z.M.; Sardroudi, H.M. Training feedforward neural networks using hybrid particle swarm optimization and gravitational search algorithm. Appl. Math. Comput. 2012, 218, 11125–11137. [Google Scholar] [CrossRef] [Scilit]
- Yaghini, M.; Khoshraftar, M.M.; Fallahi, M. A hybrid algorithm for artificial neural network training. Eng. Appl. Artif. Intell. 2013, 26, 293–301. [Google Scholar] [CrossRef] [Scilit]
- Kandasamy, T.; Rajendran, R. Hybrid algorithm with variants for feed forward neural network. Int. Arab J. Inf. Technol. 2018, 15, 240–245. [Google Scholar]
- Xue, Y.; Tang, T.; Liu, A.X. Large-scale feedforward neural network optimization by a self-adaptive strategy and parameter based particle swarm optimization. IEEE Access 2019, 7, 52473–52483. [Google Scholar] [CrossRef] [Scilit]
- Kumar, M.; Mishra, S.K.; Joseph, J.; Jangir, S.K.; Goyal, D. Adaptive comprehensive particle swarm optimisation-based functional-link neural network filtre model for denoising ultrasound images. IET Image Process. 2021, 15, 1232–1246. [Google Scholar] [CrossRef] [Scilit]
- Hayder, G.; Solihin, M.I.; Mustafa, H.M. Modelling of river flow using particle swarm optimized cascade-forward neural networks: A case study of Kelantan River in Malaysia. Appl. Sci. 2020, 10, 8670. [Google Scholar] [CrossRef] [Scilit]
- Davar, S.; Nobahar, M.; Khan, M.S.; Amini, F. The Development of PSO-ANN and BOA-ANN Models for Predicting Matric Suction in Expansive Clay Soil. Mathematics 2022, 10, 2825. [Google Scholar] [CrossRef] [Scilit]
- Melanie, M. An Introduction to Genetic Algorithms; Massachusetts Institute of Technology: Cambridge, MA, USA, 1996; p. 158. [Google Scholar]
- Chandwani, V.; Agrawal, V.; Nagar, R. Modeling slump of ready mix concrete using genetic algorithms assisted training of Artificial Neural Networks. Expert Syst. Appl. 2015, 42, 885–893. [Google Scholar] [CrossRef] [Scilit]
- Huang, H.-X.; Li, J.-C.; Xiao, C.-L. A proposed iteration optimization approach integrating backpropagation neural network with genetic algorithm. Expert Syst. Appl. 2015, 42, 146–155. [Google Scholar] [CrossRef] [Scilit]
- Bagheri, M.; Mirbagheri, S.A.; Bagheri, Z.; Kamarkhani, A.M. Modeling and optimization of activated sludge bulking for a real wastewater treatment plant using hybrid artificial neural networks-genetic algorithm approach. Process Saf. Environ. Prot. 2015, 95, 12–25. [Google Scholar] [CrossRef] [Scilit]
- Rao, R.V.; Savsani, V.J.; Vakharia, D.P. Teaching–learning-based optimization: A novel method for constrained mechanical design optimization problems. Comput.-Aided Des. 2011, 43, 303–315. [Google Scholar] [CrossRef] [Scilit]
- Uzlu, E.; Kankal, M.; Akpınar, A.; Dede, T. Estimates of energy consumption in Turkey using neural networks with the teaching–learning-based optimization algorithm. Energy 2014, 75, 295–303. [Google Scholar] [CrossRef] [Scilit]
- Li, K.; Xie, X.; Xue, W.; Dai, X.; Chen, X.; Yang, X. A hybrid teaching-learning artificial neural network for building electrical energy consumption prediction. Energy Build. 2018, 174, 323–334. [Google Scholar] [CrossRef] [Scilit]
- Benali, A.; Hachama, M.; Bounif, A.; Nechnech, A.; Karray, M. A TLBO-optimized artificial neural network for modeling axial capacity of pile foundations. Eng. Comput. 2021, 37, 675–684. [Google Scholar] [CrossRef] [Scilit]
- Ang, K.M.; Lim, W.H.; Tiang, S.S.; Ang, C.K.; Natarajan, E.; Ahamed Khan, M. Optimal Training of Feedforward Neural Networks Using Teaching-Learning-Based Optimization with Modified Learning Phases. In Proceedings of the 12th National Technical Seminar on Unmanned System Technology 2020; Springer: Singapore, 2022; pp. 867–887. [Google Scholar]
- Chong, O.T.; Lim, W.H.; Isa, N.A.M.; Ang, K.M.; Tiang, S.S.; Ang, C.K. A Teaching-Learning-Based Optimization with Modified Learning Phases for Continuous Optimization. In Science and Information Conference; Springer: Cham, Switzerland, 2020; pp. 103–124. [Google Scholar]
- Lin, G.; Shen, W. Research on convolutional neural network based on improved Relu piecewise activation function. Procedia Comput. Sci. 2018, 131, 977–984. [Google Scholar] [CrossRef] [Scilit]
- Gao, W.; Liu, S.; Huang, L. A global best artificial bee colony algorithm for global optimization. J. Comput. Appl. Math. 2012, 236, 2741–2753. [Google Scholar] [CrossRef] [Scilit]
- Tizhoosh, H.R. Opposition-based learning: A new scheme for machine intelligence. In Proceedings of the International Conference on Computational Intelligence for Modelling, Control and Automation and International Conference on Intelligent Agents, Web Technologies and Internet Commerce (CIMCA-IAWTIC’06), Vienna, Austria, 28–30 November 2005; pp. 695–701. [Google Scholar]
- Dong, N.; Wu, C.-H.; Ip, W.-H.; Chen, Z.-Q.; Chan, C.-Y.; Yung, K.-L. An opposition-based chaotic GA/PSO hybrid algorithm and its application in circle detection. Comput. Math. Appl. 2012, 64, 1886–1902. [Google Scholar] [CrossRef] [Scilit]
- Vrugt, J.A.; Robinson, B.A.; Hyman, J.M. Self-adaptive multimethod search for global optimization in real-parameter spaces. IEEE Trans. Evol. Comput. 2008, 13, 243–259. [Google Scholar] [CrossRef] [Scilit]
- Liang, J.J.; Qu, B.Y.; Suganthan, P.N. Problem Definitions and Evaluation Criteria for the CEC 2014 Special Session and Competition on Single Objective Real-Parameter Numerical Optimization. In Technical Report 201311, Computational Intelligence Laboratory, Zhengzhou University, Zhengzhou China and Technical Report; Nanyang Technological University: Singapore, 2013. [Google Scholar]
- Derrac, J.; García, S.; Molina, D.; Herrera, F. A practical tutorial on the use of nonparametric statistical tests as a methodology for comparing evolutionary and swarm intelligence algorithms. Swarm Evol. Comput. 2011, 1, 3–18. [Google Scholar] [CrossRef] [Scilit]
- García, S.; Molina, D.; Lozano, M.; Herrera, F. A study on the use of non-parametric tests for analyzing the evolutionary algorithms’ behaviour: A case study on the CEC’2005 special session on real parameter optimization. J. Heuristics 2009, 15, 617–644. [Google Scholar] [CrossRef] [Scilit]
- Cheng, R.; Jin, Y. A competitive swarm optimizer for large scale optimization. IEEE Trans. Cybern. 2014, 45, 191–204. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Yang, X.-S.; Deb, S.; Fong, S. Accelerated particle swarm optimization and support vector machine for business optimization and applications. In International Conference on Networked Digital Technologies; Springer: Berlin/Heidelberg, Germany, 2011; pp. 53–66. [Google Scholar]
- Lichman, M. UCI Machine Learning Repository. 2013. Available online: https://archive.ics.uci.edu/ml/index.php (accessed on 3 June 2022).
- Zhang, P.; Jiang, W.; Shi, X.; Zhang, S. Remaining Useful Life Prediction of Gear Pump Based on Deep Sparse Autoencoders and Multilayer Bidirectional Long ands Short Term Memory Network. Processes 2022, 10, 2500. [Google Scholar] [CrossRef] [Scilit]
- Wang, P.; Liu, H.; Hou, M.; Zheng, L.; Yang, Y.; Geng, J.; Song, W.; Shao, Z. Estimating the Remaining Useful Life of Proton Exchange Membrane Fuel Cells under Variable Loading Conditions Online. Processes 2021, 9, 1459. [Google Scholar] [CrossRef] [Scilit]
- Benbouzid, M.; Berghout, T.; Sarma, N.; Djurović, S.; Wu, Y.; Ma, X. Intelligent Condition Monitoring of Wind Power Systems: State of the Art Review. Energies 2021, 14, 5967. [Google Scholar] [CrossRef] [Scilit]
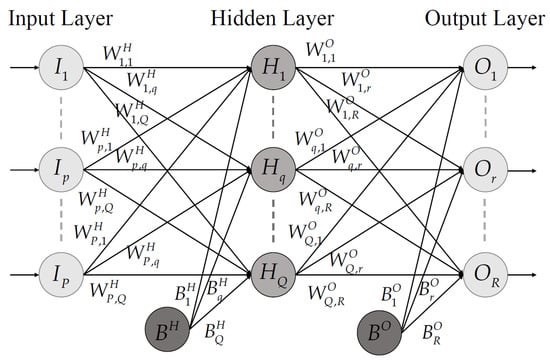
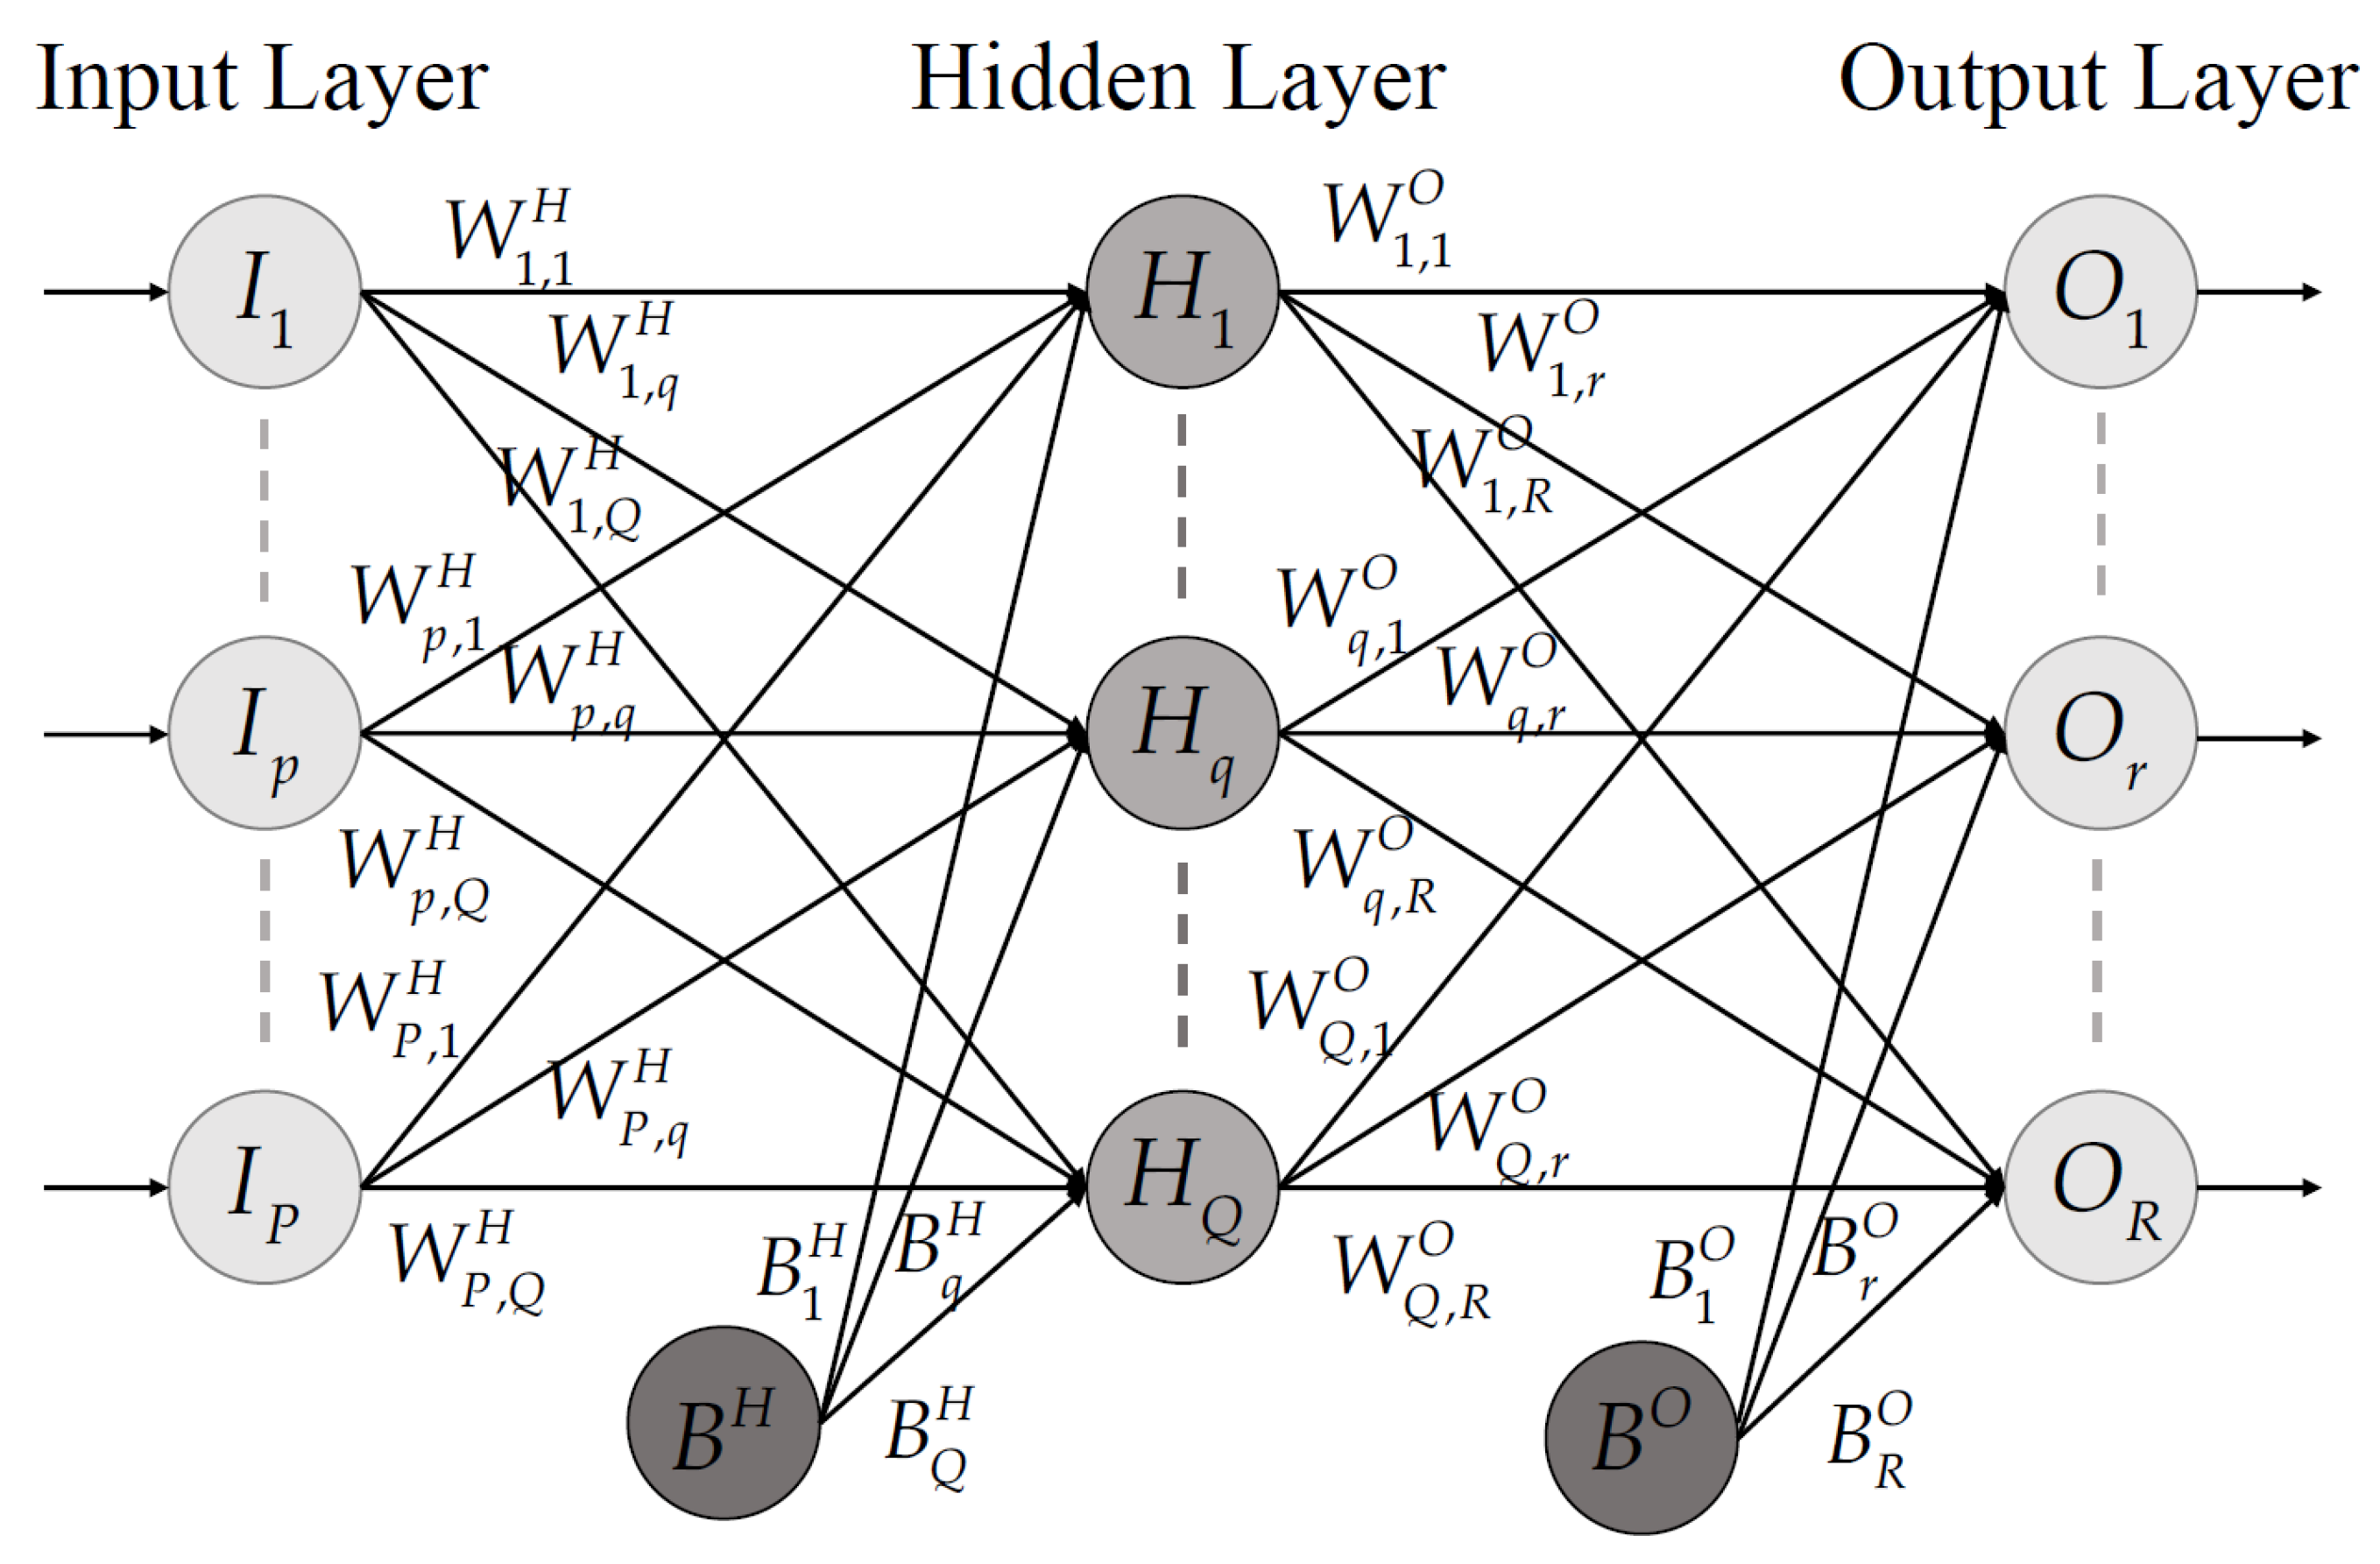
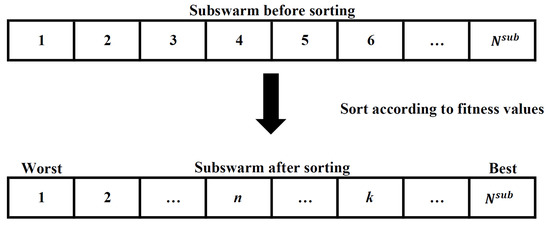
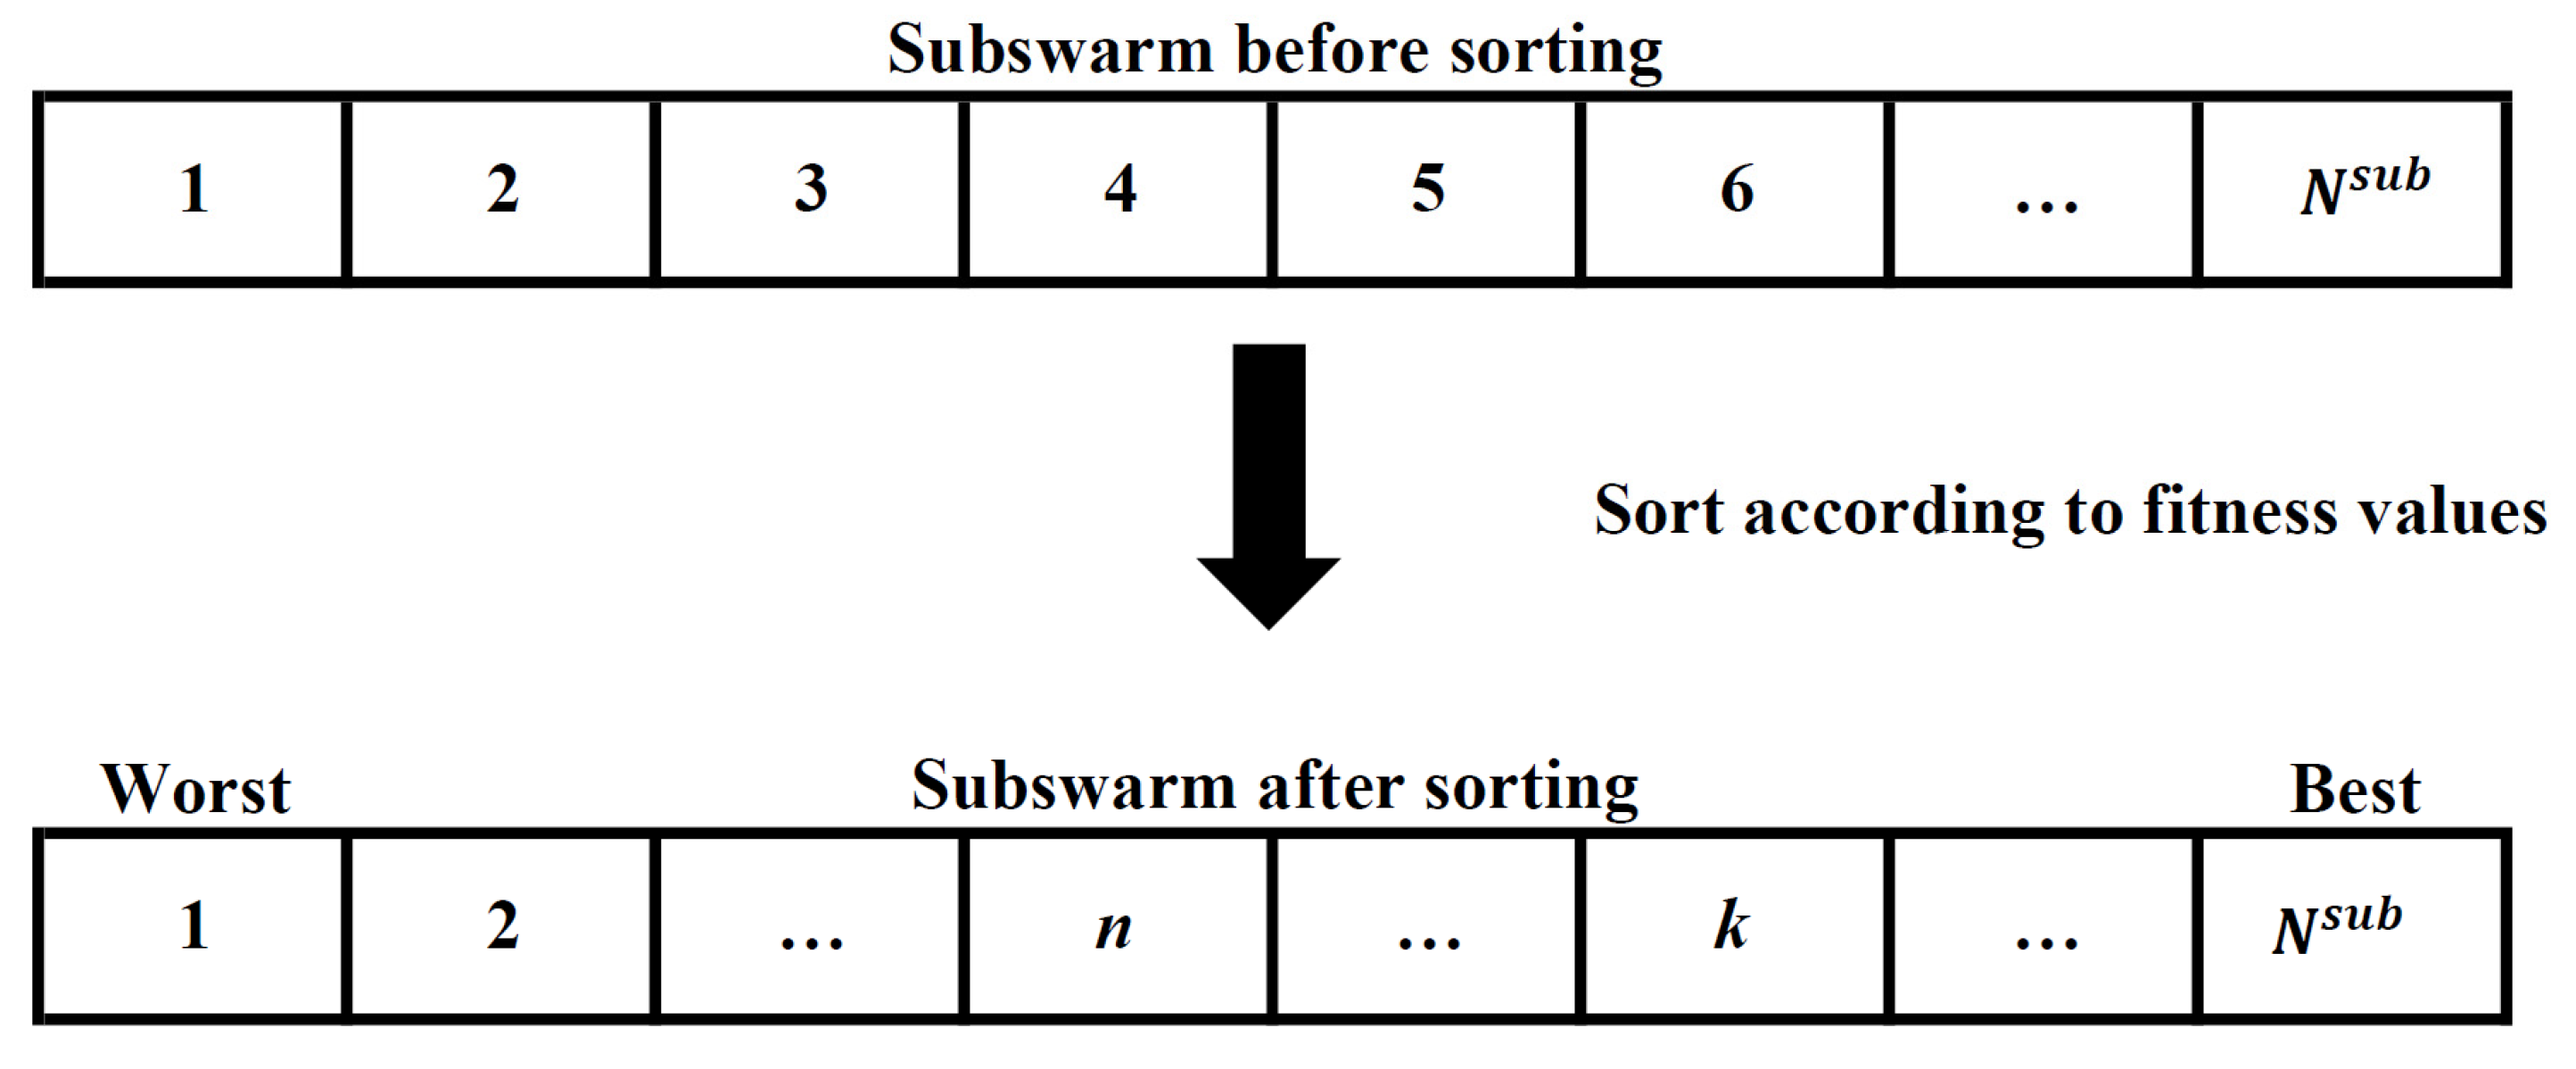

Publisher’s Note: MDPI stays neutral with regard to jurisdictional claims in published maps and institutional affiliations. |
© 2022 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).