


Abstract
In this paper we analyze the bias in a general linear least-squares parameter estimation problem, when it is caused by deterministic variables that have not been included in the model. We propose a method to substantially reduce this bias, under the hypothesis that some a-priori information on the magnitude of the modelled and unmodelled components of the model is known. We call this method Unbiased Least-Squares (ULS) parameter estimation and present here its essential properties and some numerical results on an applied example.
1. Introduction
The well known least-squares problem [1], very often used to estimate the parameters of a mathematical model, assumes an equivalence between a matrix-vector product on the left, and a vector b on the right hand side: the matrix A is produced by the true model equations, evaluated at some operating conditions, the vector x contains the unknown parameters and the vector b are measurements, corrupted by white, Gaussian noise. This equivalence cannot be satisfied exactly, but the least-squares solution yields a minimum variance, maximum likelihood estimate of the parameters x, with a nice geometric interpretation: the resulting predictions are at the minimum Euclidean distance from the true measurements b and the vector of residuals is orthogonal w.r.t. the subspace of all possible predictions.
Unfortunately, each violation of these assumptions produces in general a bias in the estimates. Various modifications have been introduced in the literature to cope with some of them: mainly, colored noise on b and/or A due to model error and/or colored measurement noise. The model error is often assumed as an additive stochastic term in the model, e.g., error-in-variables [2,3], with consequent solution methods like Total Least-Squares [4] and Extended Least-Squares [5], to cite a few. All these techniques let the model to be modified to describe, in some sense, the model error.
Here, instead, we assume that the model error depends from deterministic variables in a way that has not been included in the model, i.e., we suppose to use a reduced model of the real system, as it is often the case in applications. In this paper we propose a method to cope with the bias in the parameter estimates of the approximate model by exploiting the geometric properties of least-squares and using small additional a-priori information about the norm of the modelled and un-modelled components of the system response, available with some approximation in most applications. To eliminate the bias on the parameter estimates we perturb the right-hand-side without modifying the reduced model, since we assume it describes accurately one part of the true model.
2. Model Problem
In applied mathematics, physical models are often available, usually rather precise at describing quantitatively the main phenomena, but not satisfactory at the level of detail required by the application at hand. Here we refer to models described by differential equations, with ordinary and/or partial derivatives, commonly used in engineering and applied sciences. We assume, therefore, that there are two models at hand: a true, unknown model and an approximate, known model . These models are usually parametric and they must be tuned to describe a specific physical system, using a-priori knowledge about the application and experimental measurements. Model tuning, and in particular parameter estimation, is usually done with a prediction error minimization criterion that makes the model response to be a good approximation of the dynamics shown by the measured variables used in the estimation process. Assuming that the true model is linear in the parameters that must be estimated, the application of this criterion brings to a linear least-squares problem:
where, from here on, is the Euclidean norm, is supposed full rank , , , are the model response values and is the vector of experimental measurements. Usually the measured data contain noise, i.e., we measure , with a certain kind of additive noise (e.g., white Gaussian). Since we are interested here in algebraic and geometric aspects of the problem, we suppose and set . Moreover, we assume ideally that holds exactly. Let us consider also the estimation problem for the approximate model :
where , , with . The choice of the notation for is to remind that the least-squares solution satisfies where is the orthogonal projection of on the subspace generated by , and the residual is orthogonal to this subspace. Let us suppose that corresponds to the first columns of A, which means that the approximate model is exactly one part of the true model , i.e., and so the solution of (1) can be decomposed in two parts such that
This means that the model error corresponds to an additive term in the estimation problem.
Note that the columns of are linearly independent since A is supposed to be of full rank. We do not consider the case in which is rank-deficient, because it would mean that the model is not well parametrized. Moreover, some noise in the data is sufficient to determine a full rank matrix.
For brevity, we will call the subspace generated by the columns of A and , the subspaces generated by the columns of , respectively. Note that if and were orthogonal, decomposition (3) would be orthogonal. However, in the following we will consider the case in which the two subspaces are not orthogonal, as it commonly happens in practice. Oblique projections, even if not as common as orthogonal ones, have a large literature, e.g., [6,7].
Now, it is well known and easy to demonstrate that, when we solve problem (2) and is not orthogonal to , we get a biased solution, i.e., :
Lemma 1.
Given with and , and given , call x the least-squares solution of (2) and the solution of (1) decomposed as in (3). Then
- (i)
- if then
- (ii)
- if then
Proof.
The least-squares problem boils down to finding x such that Let us consider the unique decomposition of f on and as with and . Call the decomposition on and , hence there exist two vectors such that and . If then the two decompositions are the same, hence and so . Otherwise, for the definition of orthogonal projection ([6], third point of Def at page 429), it must hold . □
3. Analysis of the Parameter Estimation Error
The aim of this paper is to propose a method to decrease substantially the bias of the solution of the approximated problem (2), with the smallest additional information about the norms of the model error and of the modelled part responses.
In this section we will introduce sufficient conditions to remove the bias and retrieve the true solution in a unique way, as summarized in Lemma 4. Let us start with a definition.
Definition 1
(Intensity Ratio). The intensity ratio between modelled and un-modelled dynamics is defined as
In the following we assume that a good approximation of this intensity ratio is available and that its magnitude is sufficiently big, i.e., we have an approximate model that is quite accurate. This information about the model error will be used to reduce the bias, as shown in the following sections. Moreover we will consider also the norm (or, equivalently, the norm ).
3.1. The Case of Exact Knowledge about and
Here we assume, initially, to know the exact values of and , i.e.,
This ideal setting is important to figure out the problem also with more practical assumptions. First of all, let us show a nice geometric property that relates and under a condition like (4).
Lemma 2.
The problem of finding the set of that give a constant, prescribed value for and is equivalent to that of finding the set of of the decomposition (see the proof of Lemma 1) lying on the intersection of and the boundaries of two n-dimensional balls in . In fact, it holds:
Proof.
Given and , we call the feasible set of accurate model responses all the that satisfy the relations (5). Now we will see that Lemma 2 allows us to reformulate problem (2) in the problem of finding a feasible that, replaced to in (2), gives as solution an unbiased estimate of . Indeed, it is easy to note that belongs to this feasible set. Moreover, since , we can reduce the dimensionality of the problem and work on the subspace which has dimension , instead of the global space of dimension n. To this aim, let us consider the matrix of the SVD decomposition of , , and complete its columns to an orthonormal basis of to obtain a matrix U. Since the vectors belong to the subspace , the vectors defined such that and must have zeros on the last components. Since U has orthonormal columns, it preserves the norms and so and . If we call the first components of the vectors (which have again the same norms of the full vectors in ) respectively, we have
In this way the problem depends only on the dimension of the known subspace, i.e., the value of , and does not depend on the dimensions and . From (8) we can deduce the equation of the -dimensional boundary of an -ball to which the vector must belong. In the following we discuss the various cases.
3.1.1. Case
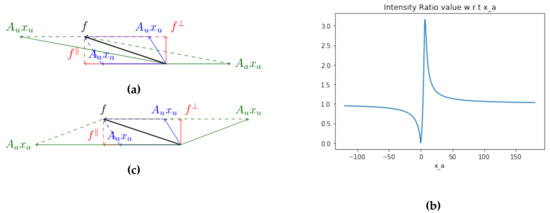
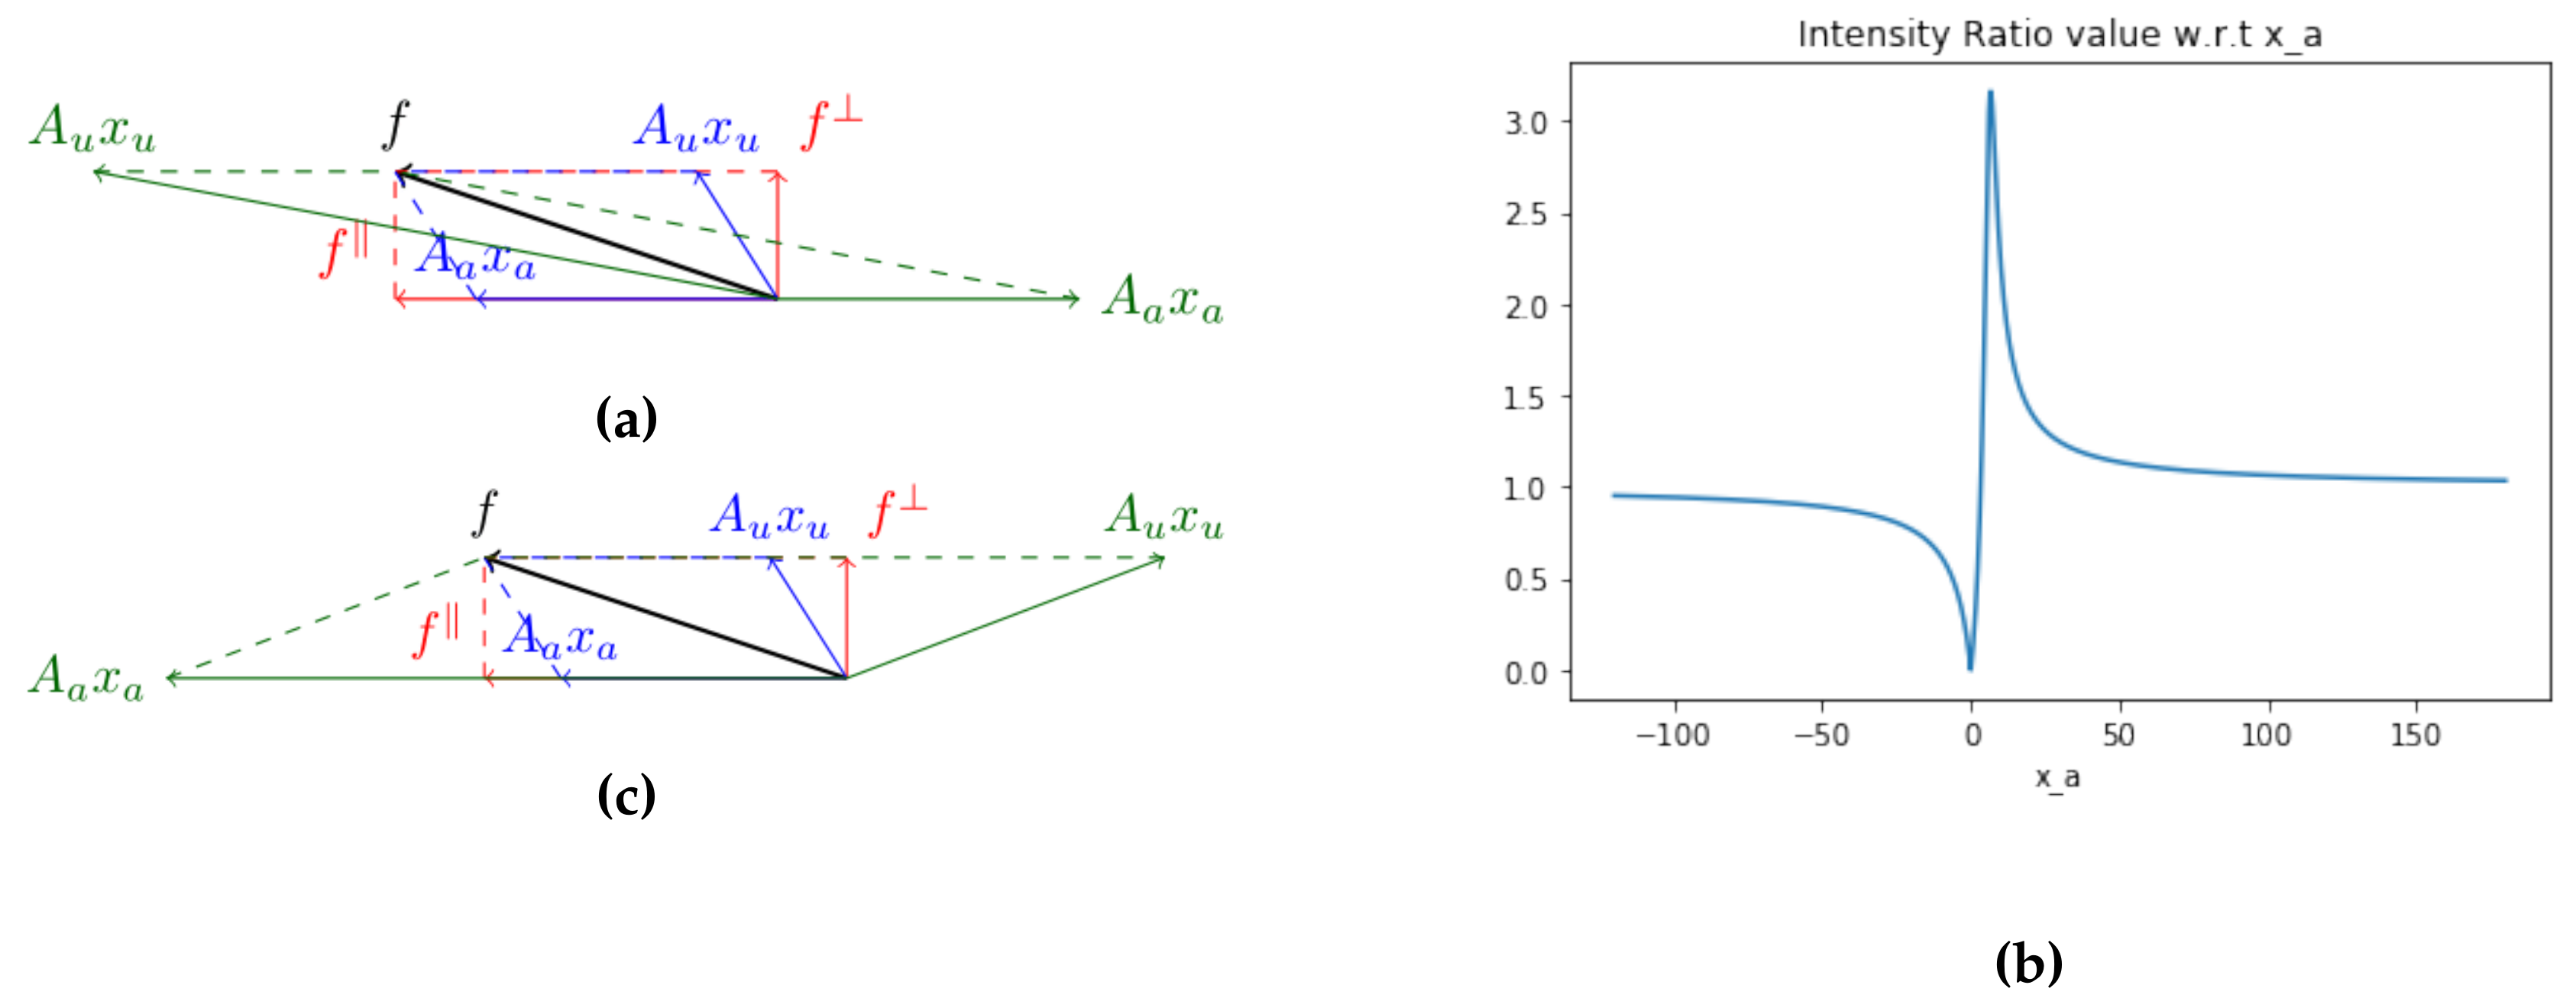
In this case, we have one unique solution when both conditions on and are imposed. When only one of these two is imposed, two solutions are found, shown in Figure 1a,c. Figure 1b shows the intensity ratio .
Figure 1.
Case . (a): Case , . Solutions with the condition on . In the figure: the true decomposition obtained imposing both the conditions (blue), the orthogonal decomposition (red), another possible decomposition (green) that satisfy the same norm condition , but different ; (b): Case . Intensity Ratio value w.r.t the norm of the vector : given a fixed value of Intensity Ratio there can be two solution, i.e. two possible decomposition of f as sum of two vectors with the same Intensity Ratio; (c): Case , . Solutions with the condition on . In the figure: the true decomposition obtained imposing both the conditions (blue), the orthogonal decomposition (red), another possible decomposition (green) with the same intensity ratio , but different .
3.1.2. Case
Consider the vectors as defined previously, in particular we are looking for . Hence, conditions (8) can be written as
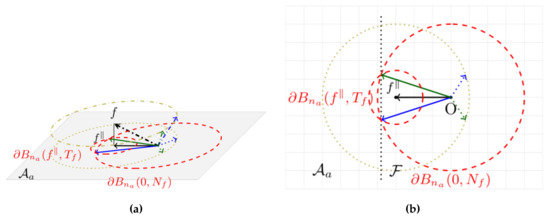
where the right equation is the -dimensional subspace (line) obtained subtracting the first equation to the second. This subspace has to be intersected with one of the beginning circumferences to obtain the feasible vectors , as can be seen in Figure 2a and its projection on in Figure 2b. The intersection of the two circumferences (5) can have different solutions depending on the value of . When this value is strictly positive there are zero solutions, this means that the estimates of and are not correct: we are not interested in this case because we suppose the two values to be sufficiently well estimated. When the value is strictly negative there are two solutions, that coincide when the value is zero.
Figure 2.
Case . (a): Case , , with . In the figure: the true decomposition (blue), the orthogonal decomposition (red), another possible decomposition of the infinite ones (green); (b): Case , . Projection of the two circumferences on the subspace , and projections of the possible decompositions of f (red, blue and green).
When there are two solutions, we have no sufficient information to determine which one of the two solutions is the true one, i.e., the one that gives : we cannot choose the one that has minimum residual, neither the vector that has the minimum angle with f, because both solutions have the same values of these two quantities. However, since we are supposing the linear system to be originated by an input/output system, where the matrix is a function also of the input and f are the measurements of the output, we can take two tests with different inputs. Since all the solution sets contain the true parameter vector, we can determine the true solution from their intersection, unless the solutions of the two tests are coincident. The condition for coincidence is expressed in Lemma 3.
Let us call the matrix of the test , to which correspond a vector . The line on which lie the two feasible vectors of the same test i is and is the line through the two solution points. To have two tests with non-coincident solutions, we need that these two lines do not have more than one common point, that in the case is equivalent to , i.e., , i.e., . We represent the lines by means of their orthogonal vector from the origin We introduce the matrices such that , , and such that .
Lemma 3.
Consider two tests from the same system with with the above notation. Then it holds if and only if .
Proof.
From the relation , we have
It holds hence we will show this second equivalence. We note that and calculate
Now let us call the vector such that , then, using the fact that we obtain
Hence we have □
3.1.3. Case
More generally, for the case , consider the vectors as defined previously, in particular we are looking for . Conditions (8) can be written as
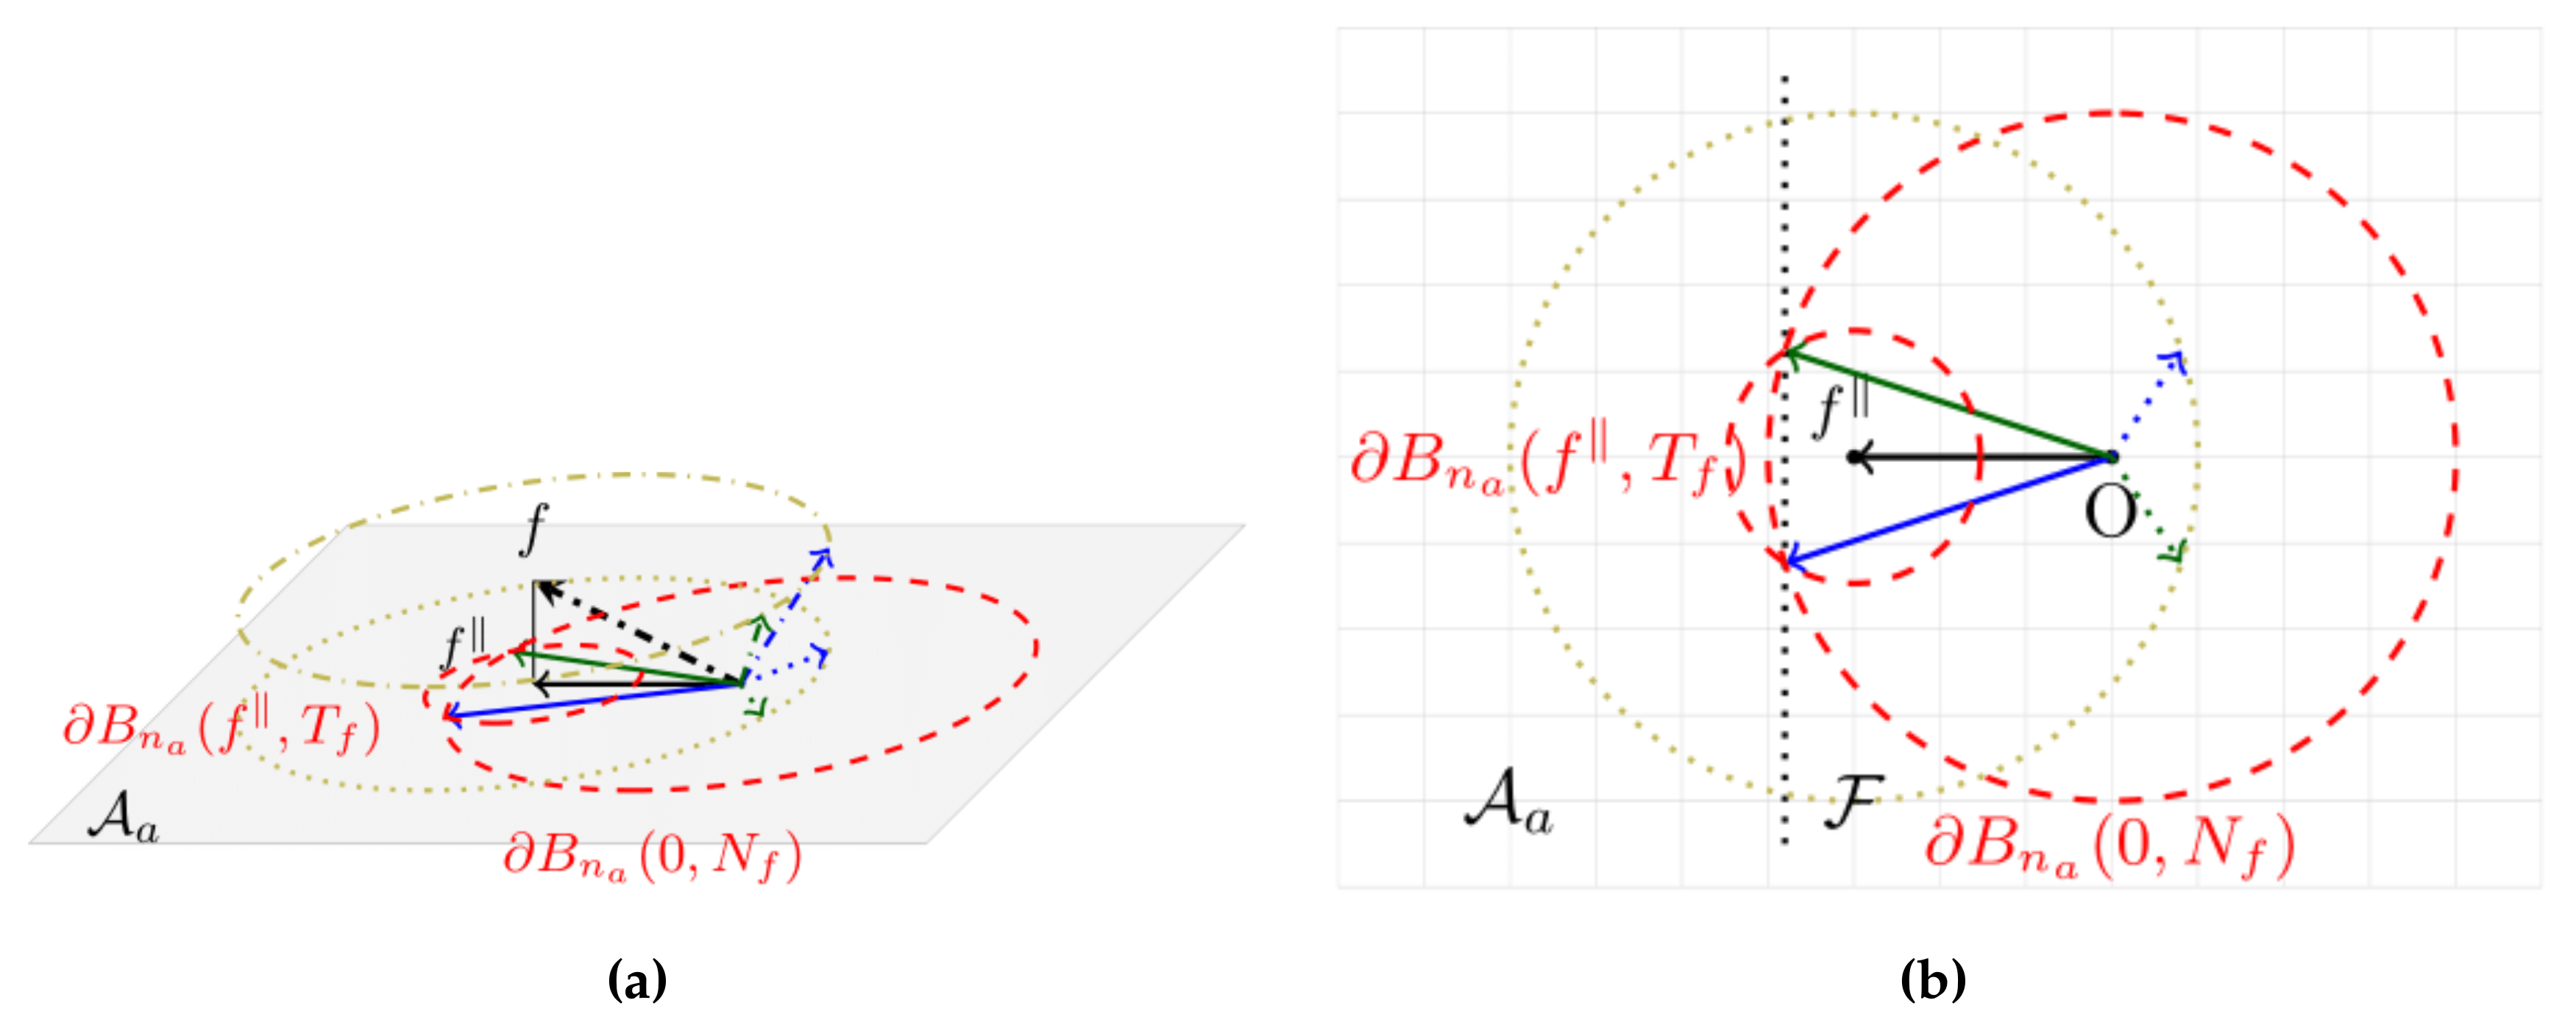
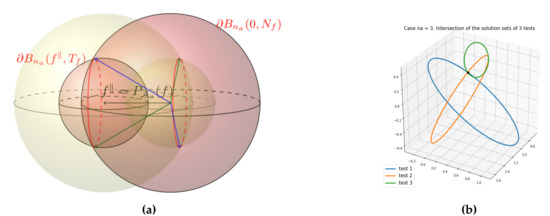
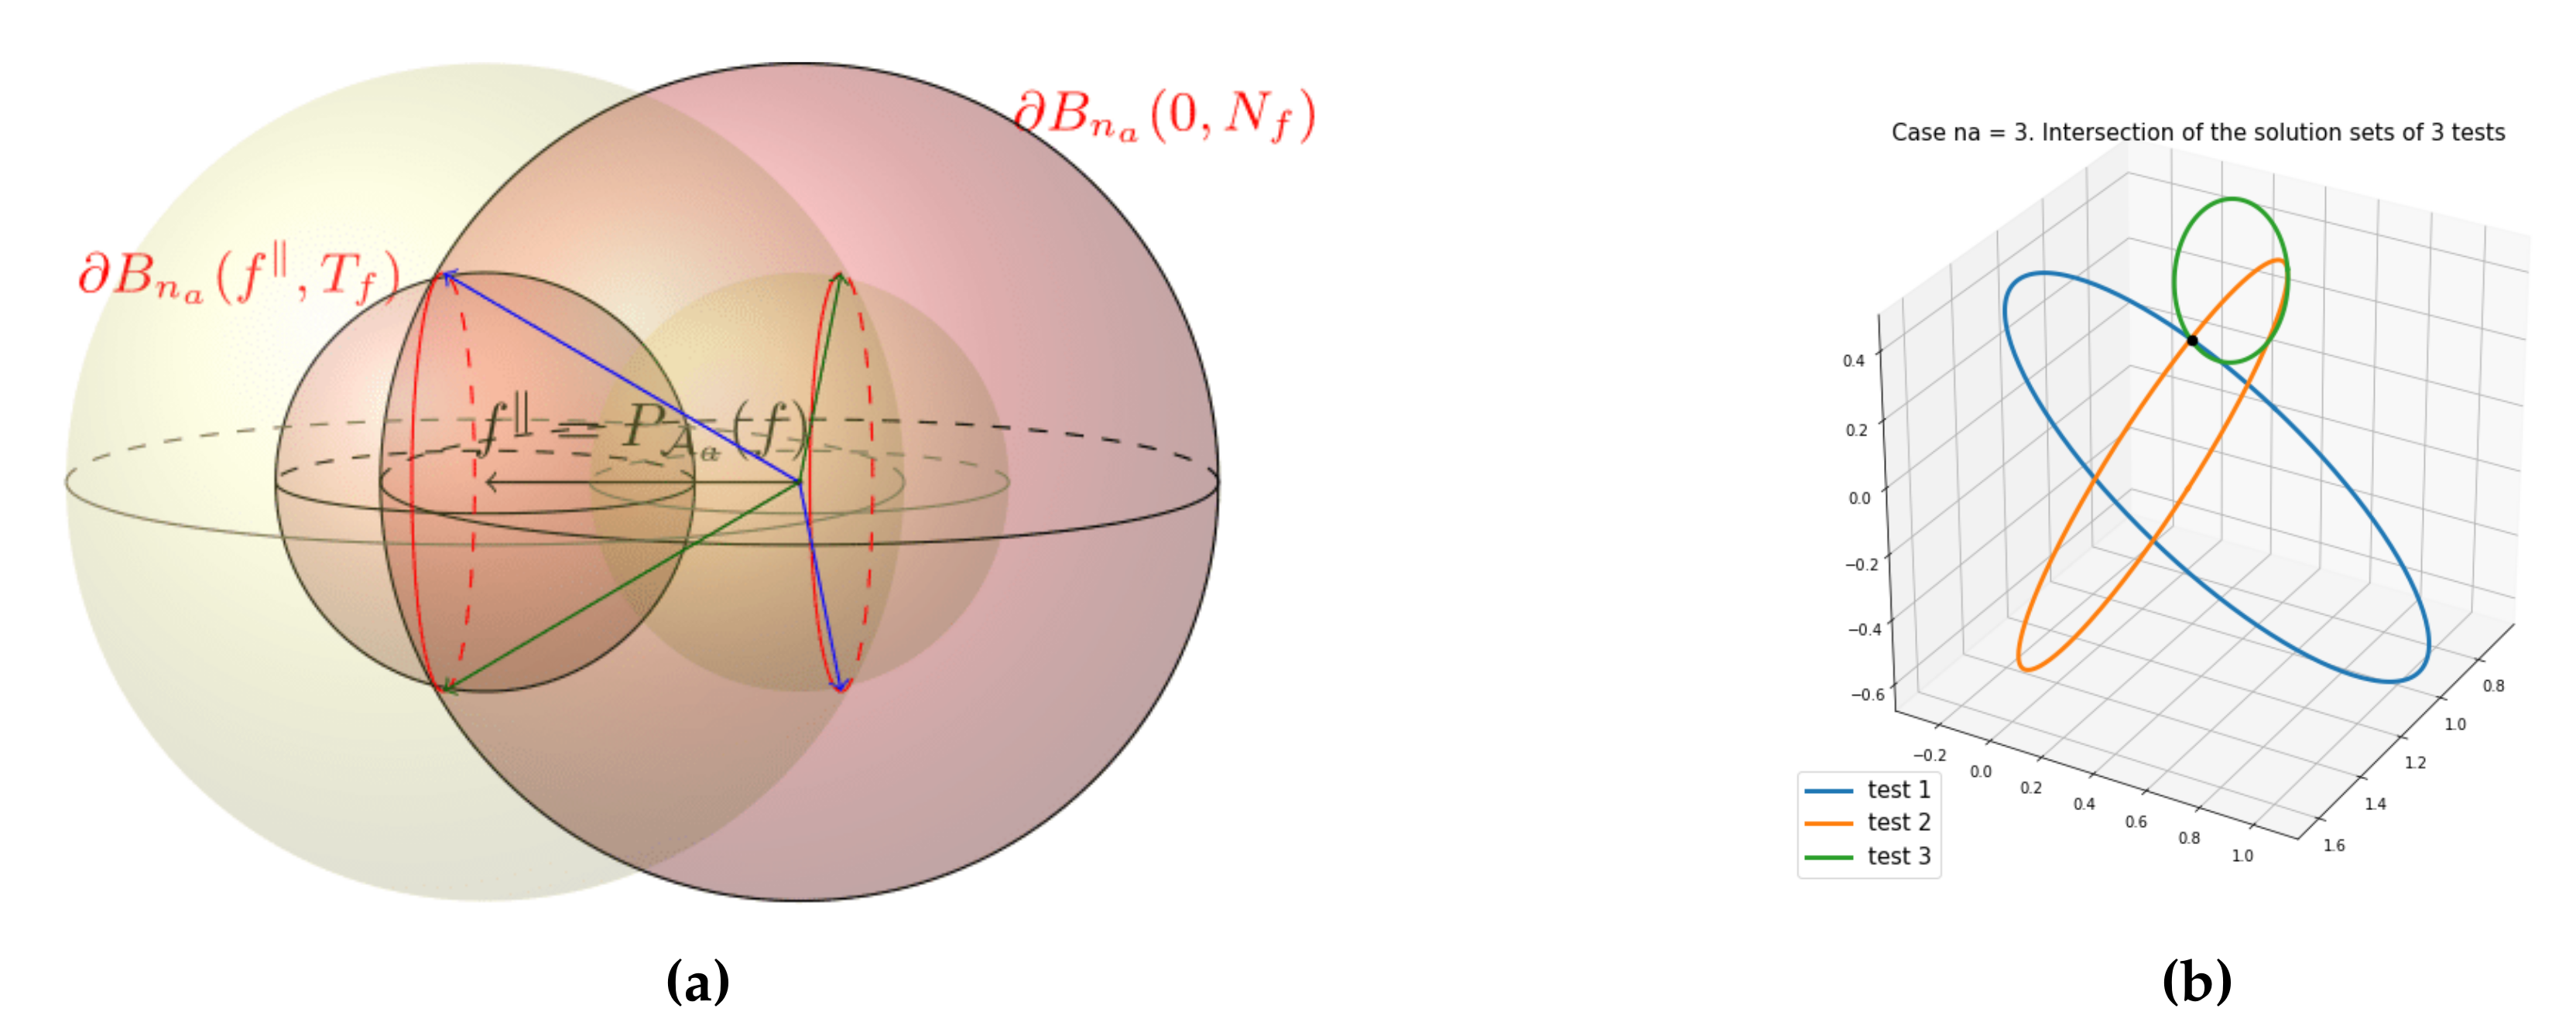
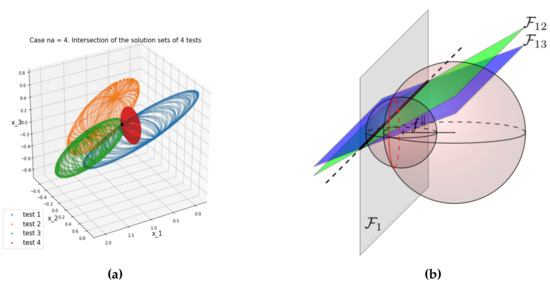
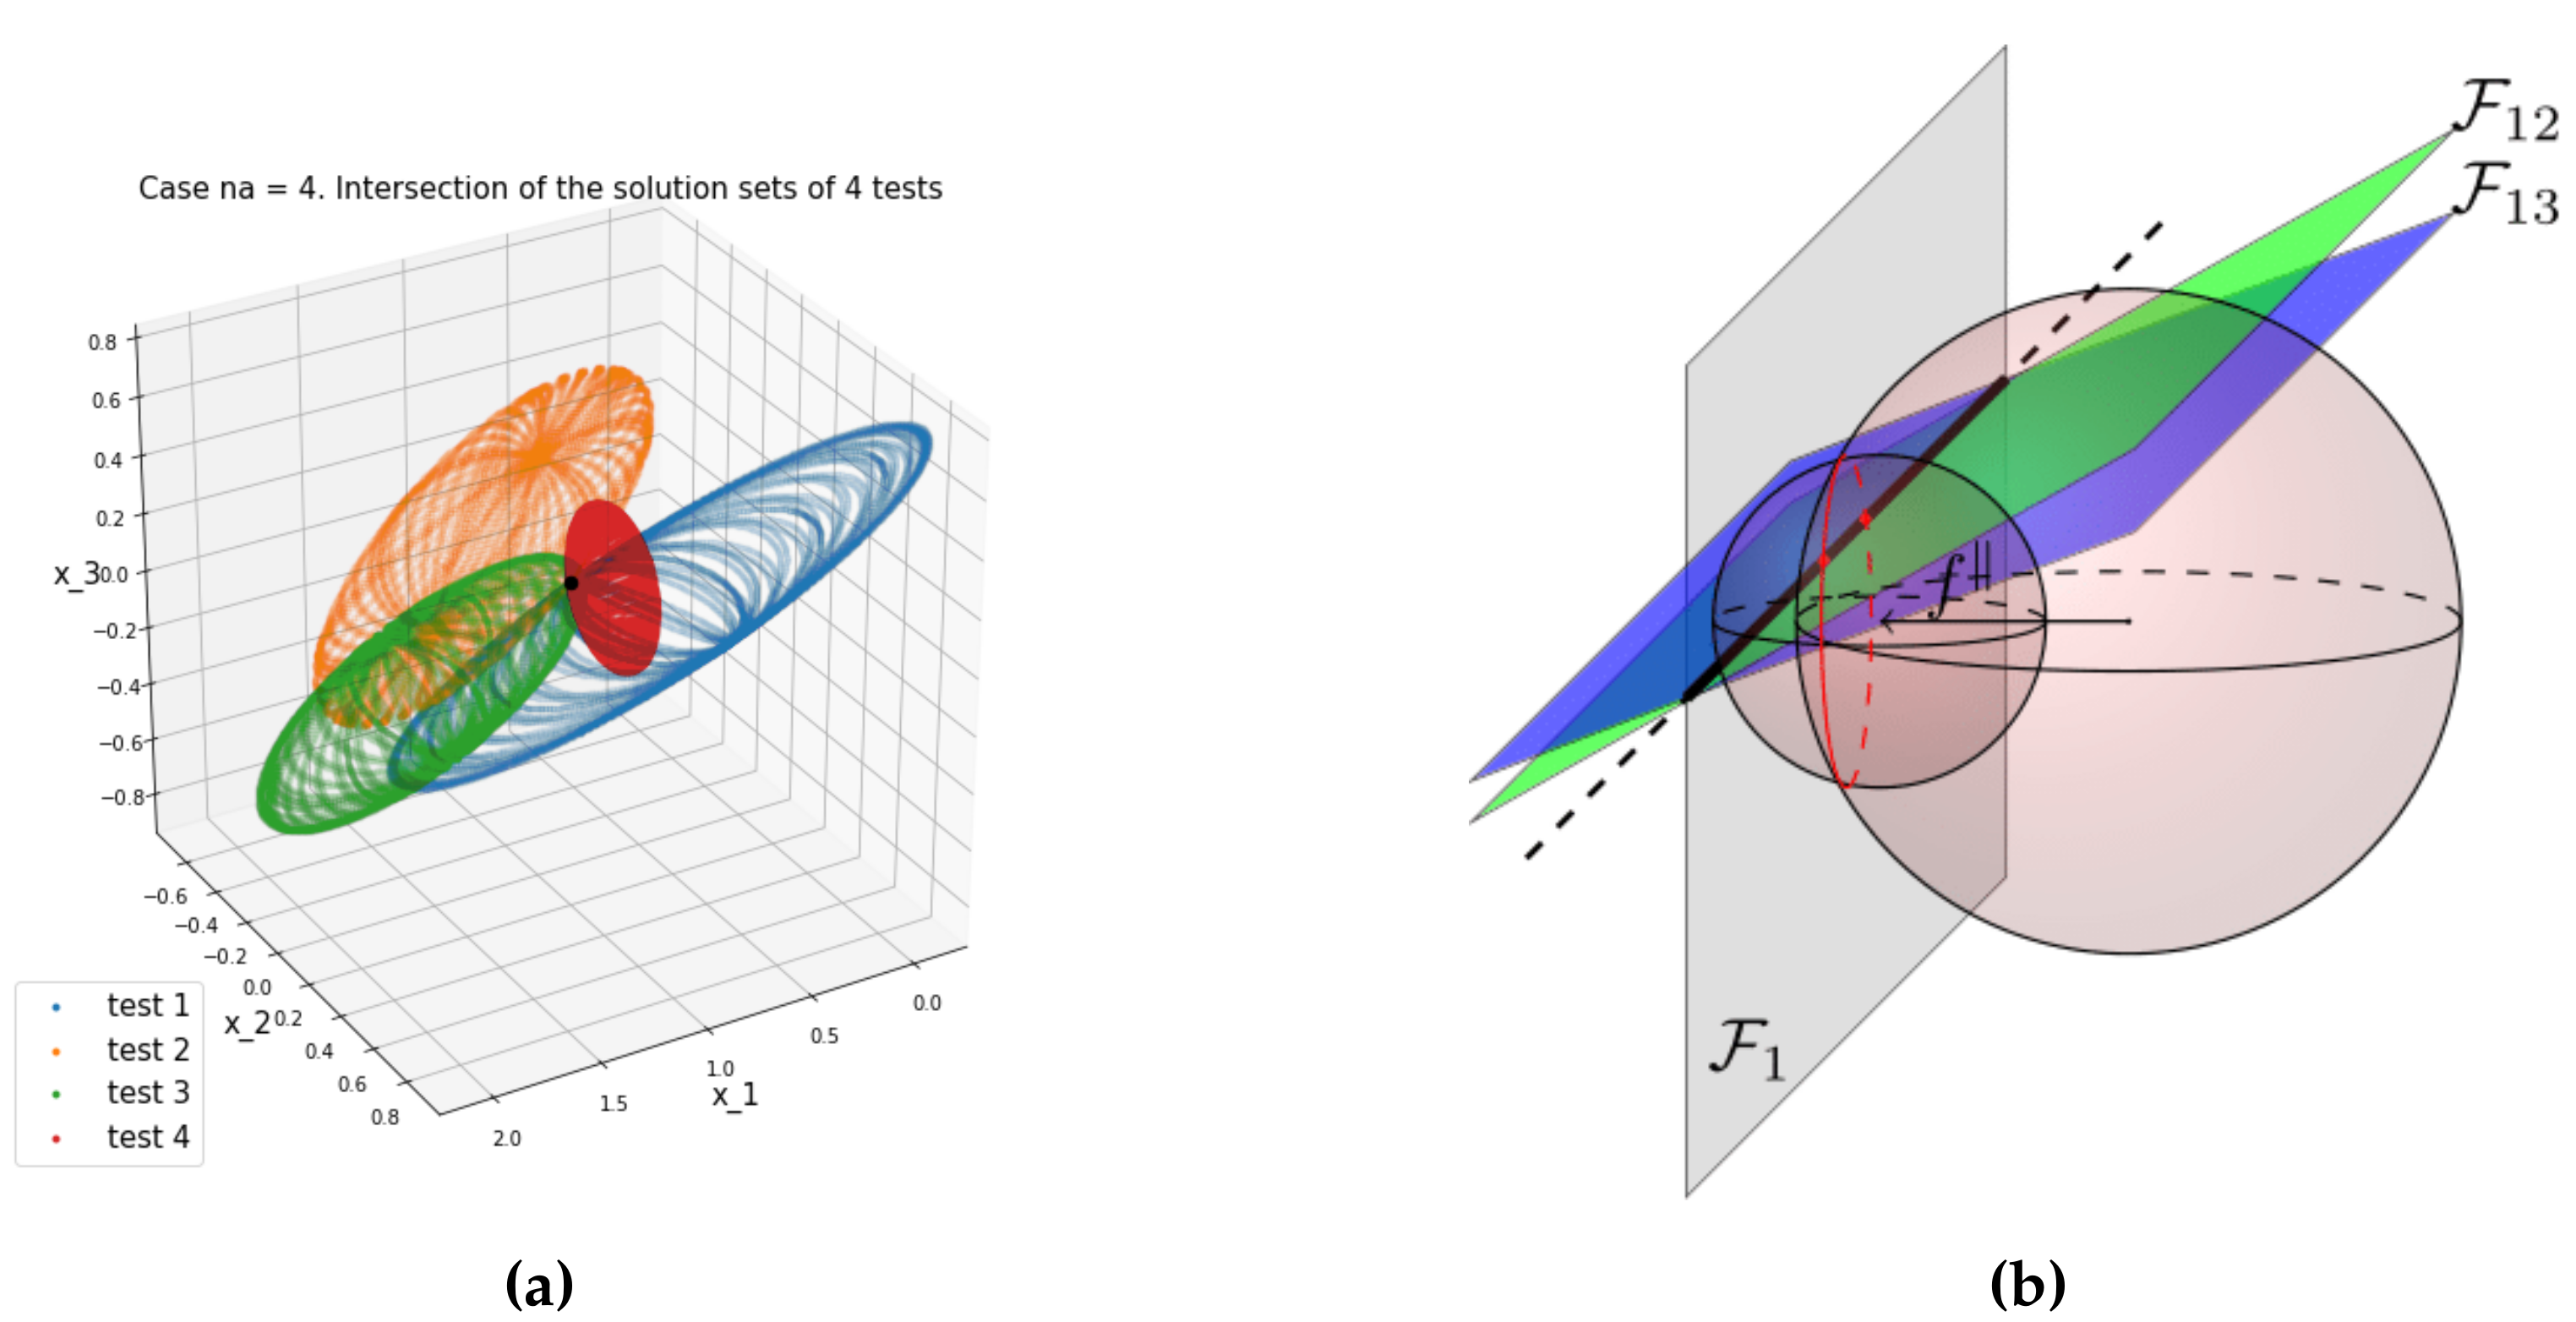
where the two equations on the left are two -spheres, i.e., the boundaries of two -dimensional balls. Analogously to the case , the intersection of these equations can be empty, one point or the boundary of a -dimensional ball (with the same conditions on ). The equation on the right of (13) is the -dimensional subspace on which lies the boundary of the -dimensional ball of the feasible vectors , and is obtained subtracting the first equation to the second one. In Figure 3a the graphical representation of the decomposition for the case is shown, and in Figure 3b the solution ellipsoids of 3 tests whose intersection is one point. Figure 4a shows the solution hyperellipsoids of 4 tests whose intersection is one point, in the case .
Figure 3.
Case . (a): Case , , : in the picture , i.e., the projection of f on . The decompositions that satisfies the conditions on and are the ones with that lies on the red circumference on the left. The spheres determined by the conditions are shown in yellow for the vector and in blue for the vector . Two feasible decompositions are shown in blue and green; (b): Case . Intersection of three hyperellipsoids, set of the solutions of three different tests, in the space .
Figure 4.
Case . (a): Case . Intersection of four hyperellipsoids, set of the solutions of four different tests, in the space ; (b): Case . Example of three tests for which the solution has an intersection bigger than one single point. The three -dimensional subspaces in the space generated by intersect in a line and their three orthogonal vectors are not linearly independent.
We note that, to obtain one unique solution we must intersect the solutions of at least two tests. Let us give a more precise idea of what happens in general. Given tests we call, as in the previous case, the vector orthogonal to the -dimensional subspace that contains the feasible , and . We project this subspace on and obtain that we describe through its orthogonal vector . If the vectors are linearly independent, it means that the -dimensional subspaces intersect themselves in one point. In Figure 4b it is shown an example in which, in the case the vectors are not linearly independent. The three solution sets of this example will intersect in two points, hence, for , three tests are not always sufficient to determine a unique solution.
Lemma 4.
For all , the condition that, given tests, the hyperplanes previously defined have linearly independent normal vectors is sufficient to determine one unique intersection, i.e., one unique solution vector , that satisfies the system of conditions (4) for each test.
Proof.
The intersection of independent hyperplanes in is a point. Given a test i and the affine subspace of that test
where is the normal vector of the linear subspace and the translation with respect to the origin.
The conditions on relative to tests correspond to a linear system , where is the i-th row of A and each component of the vector b given by . The matrix A has full rank because of the linear independence condition of the vectors , hence the solution of the linear system is unique.
The unique intersection is due to the hypothesis of full column rank of the matrices : this condition implies that the matrices map the surfaces to hyperplanes . □
For example, with (Lemma 3) this condition is equal to considering two tests with non-coincident lines , i.e., two non-coincident .
3.2. The Case of Approximate Knowledge of and Values
Let us consider N tests and call and the values as defined in Lemma 2, relative to test i. Since the system of conditions
is equivalent, as shown in Lemma 2, we will take into account the system on the right for its simplicity: the equation on represents an hyperellipsoid, translated with respect to the origin.
In a real application, we can assume to know only an interval in which the true values of is contained and, analogously, an interval for values. Supposing we know the bounds on and , then the bounds on can be easily computed. Let us call these extreme values , we will assume it always holds
for each i-th test of the considered set .
Condition (4) is now relaxed as follows: the true solution satisfies
for each i-th test of the considered set .
Assuming the extremes to be non-coincident ( and ), these conditions do not define a single point, i.e., the unique solution (as in (4) of Section 3.1), but an entire closed region of the space that may be even not connected, and contains infinite possible solutions x different from .
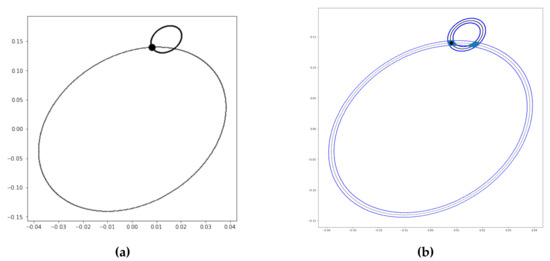
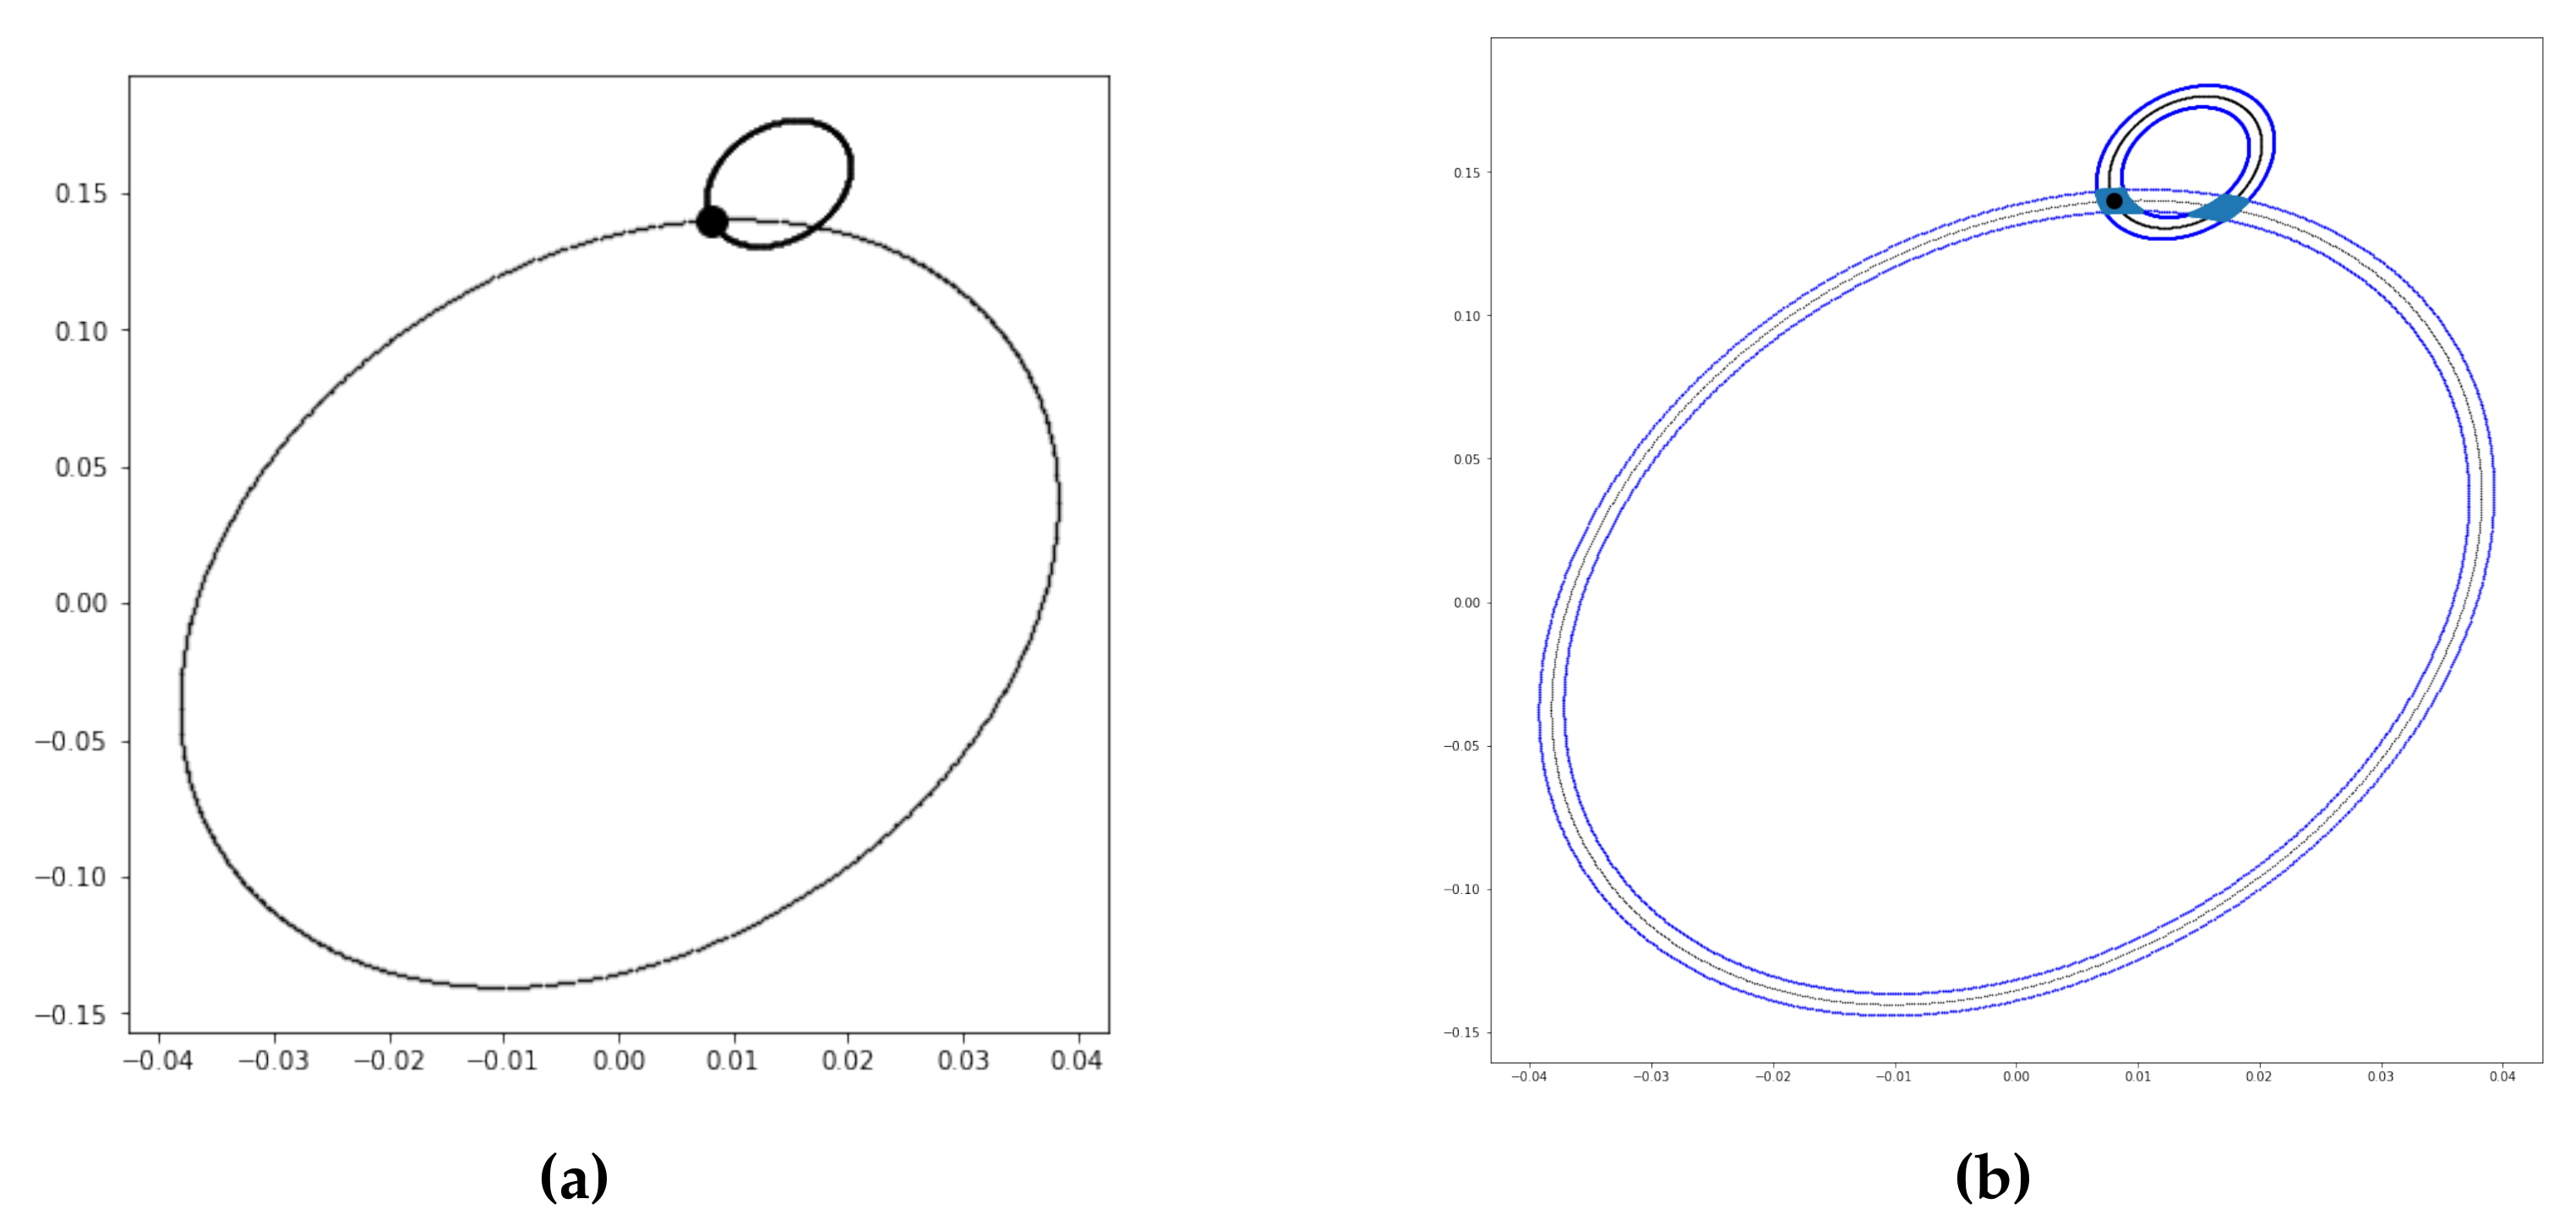
In Figure 5 two examples, with , of the conditions for a single test are shown: on the left in the case of exact knowledge of the and values, and on the right with the knowledge of two intervals containing the right values.
Figure 5.
Examples of the exact and approximated conditions on a test with . In the left equation the two black ellipsoids are the two constraints of the right system of (14), while in the right figure the two couples of concentric ellipsoids are the borders of the thick ellipsoids defined by (16) and the blue region is the intersection of (18) and (19). The black dot in both the figures is the true solution. (a): Exact conditions on and ; (b): Approximated conditions on and .
Given a single test, the conditions (16) on a point x can be easily characterized. Given the condition
we write with the vectors of the orthogonal basis, given by the columns V of the SVD decomposition . Then
Since the norm condition holds, then we obtain the equation of the hyperellipsoid for as:
The bounded conditions hence gives the region inside the two hyperellipsoids centered in the origin:
Analogously for the condition, the region inside the two translated hyperellipsoids:
Given a test i, each of the conditions (18) and (19), constrain to lie inside a thick hyperellipsoid, i.e., the region between the two concentric hyperellipsoids. The intersection of these two conditions for test i is a zero-residual region that we call
It is easy to verify that if is equal to the assumed or , or is equal to the assumed or , the true solution will be on a border of the region , and if it holds for both and it will lie on a vertex.
When more tests are put together, we have to consider the points that belong to the intersection of all these regions , i.e.,
These points minimize, with zero residual, the following optimization problem:
It is also easy to verify that, if the true solution lies on an edge/vertex of one of the regions , it will lie on an edge/vertex of their intersection.
The intersected region tends to monotonically shrink in a way that depends from the properties of the added tests. We are interested to study the conditions that make it reduce to a point, or at least to a small region. A sufficient condition to obtain a point is given in Theorem 1.
Let us first consider the function that, given a point in the space , returns the squared norm of its image through the matrix :
where are the columns of V and .
The direction of maximum increase of this function is given by its gradient
Analogously, define the function as
with gradient
Definition 2.
(Upward/Downward Outgoing Gradients) Take a test i, and the functions and as in (23) and (25), with the formulas of the gradient vectors of these two functions as in (24) and (26). Given the two extreme values and for each test, let us define
- the downward outgoing gradients as the set of gradients calculated on the points on the minimum hyperellipsoidthey point inward to the region of the thick hyperellipsoid.
- the Upward Outgoing Gradients as the set of negative gradients of points on the maximum hyperellipsoidthey point outward the region.
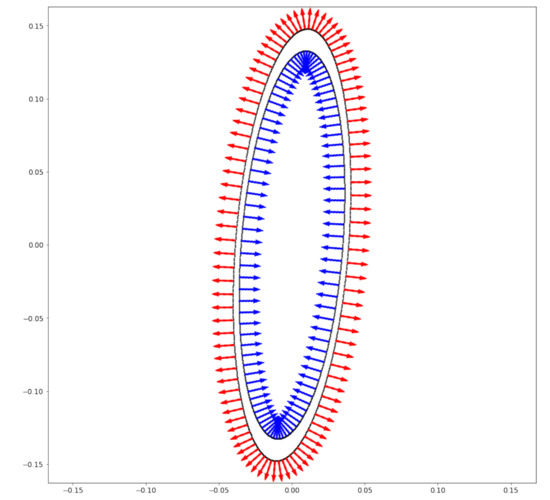
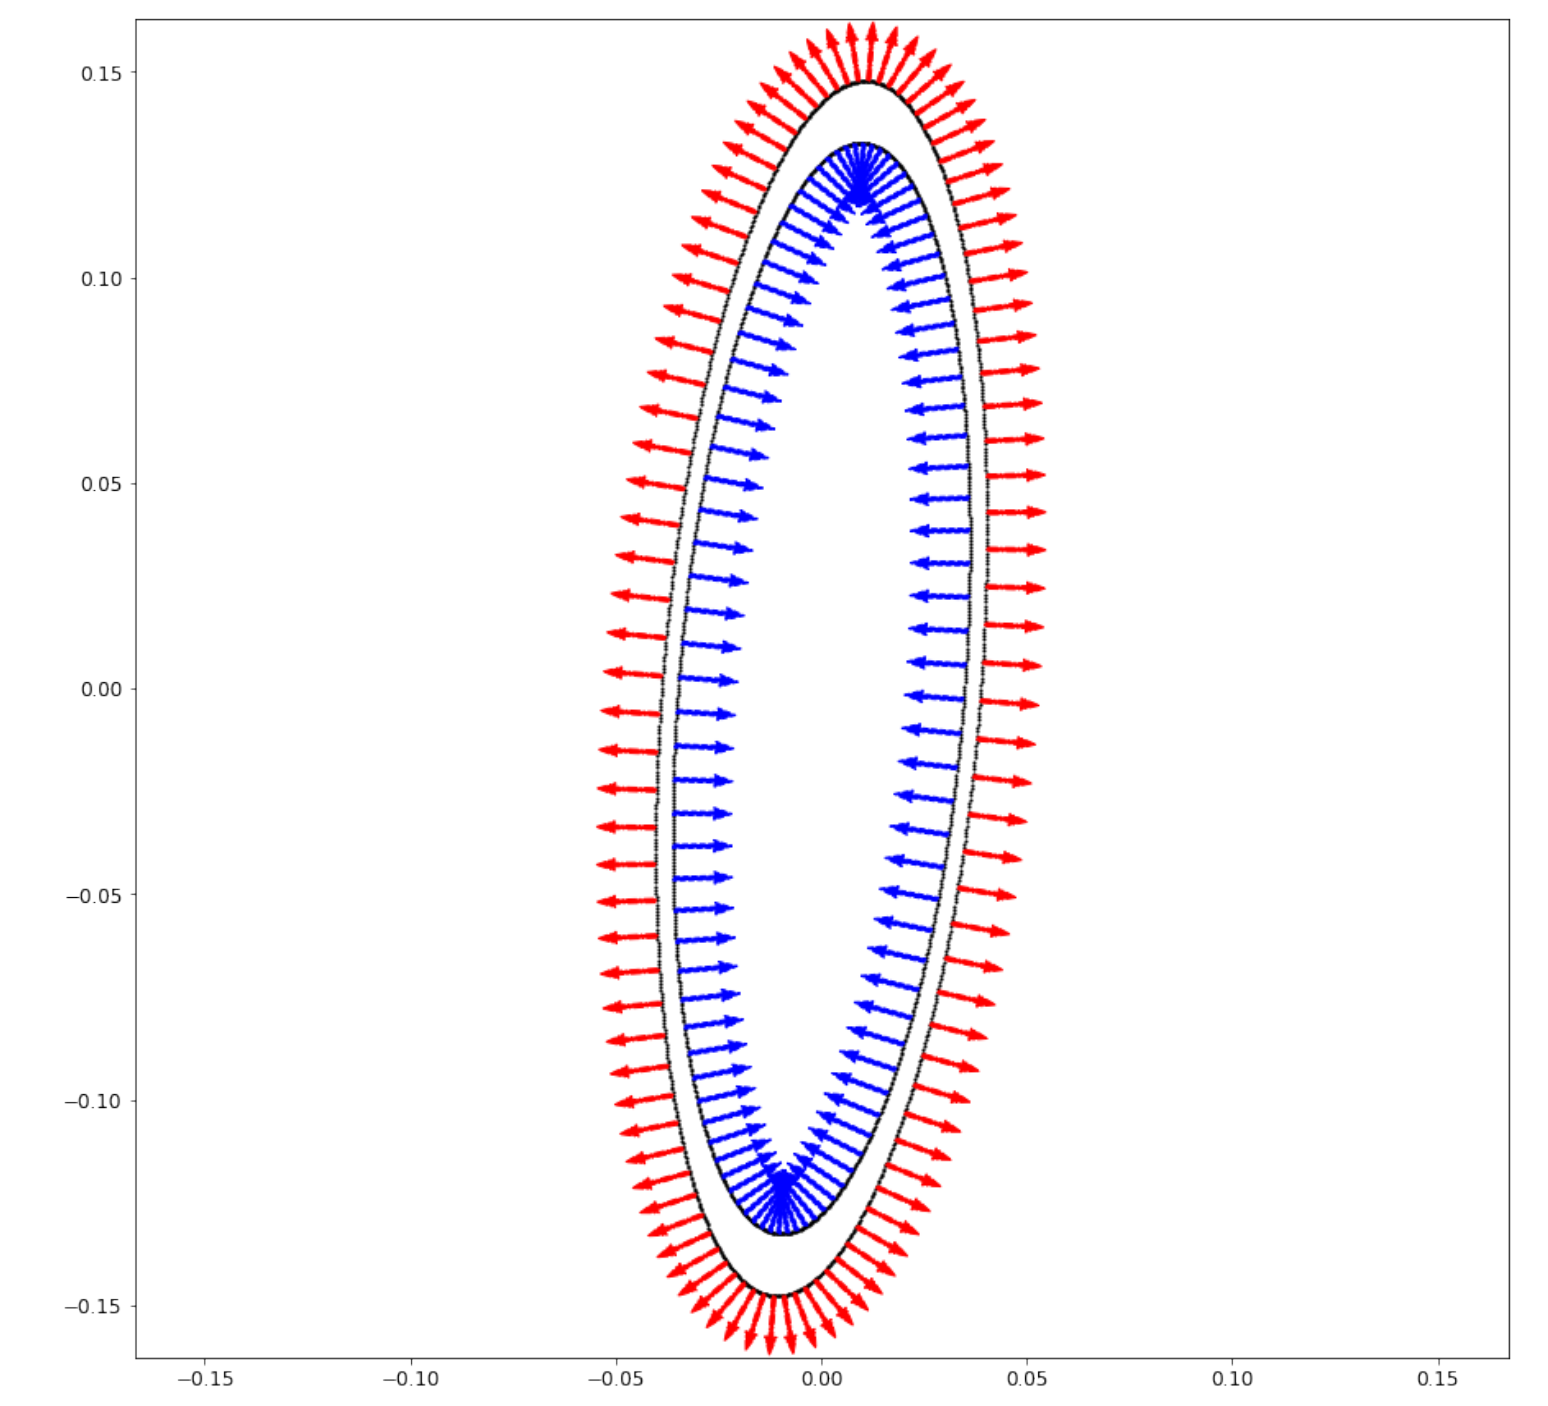
Note that the upward/downward outgoing gradient of function (or ) on point x is the normal vector to the tangent plane on the hyperellipsoid on which the point lies. Moreover, these vectors point outward the region defined by Equation (18) (and (19) respectively). In Figure 6, an example of some upward/downward outgoing gradients of function is shown.
Figure 6.
In the figure some upward/downward outgoing gradients are shown: the blue internal ones are downward outgoing gradients calculated on points x on the internal ellipsoid with , while the external red ones are upward outgoing gradients calculated on points x on the external ellipsoid with .
Theorem 1.
Given N tests with values and in the closed intervals and , take the set of all the upward/downward outgoing gradients of functions and calculated in the true solution , i.e.,
If there is at least one outgoing gradient of this set in each orthant of , then the intersection region of Equation (21) reduces to a point.
Proof.
What we want to show is that given any perturbation of the real solution , there exists at least one condition among (18) and (19) that is not satisfied by the new perturbed point .
Any sufficiently small perturbation in an orthant in which lies an upward/downward outgoing gradient (from now on "Gradient"), determines an increase/decrease in the value of the hyperellipsoid function relative to that Gradient, that makes the relative condition to be unsatisfied.
Hence, if the Gradient in the orthant considered is upward, it satisfies (or analogously with ) and for each perturbation in the same orthant we obtain
(or analogously with ). In the same way, if the Gradient is downward we obtain
(or analogously with ).
When in one orthant there are more than one Gradient, it means that more than one condition will be unsatisfied by the perturbed point for a sufficiently small in that orthant. □
4. Problem Solution
The theory previously presented allows us to build a solution algorithm that can deal with different a-priori information. We will start in Section 4.1 with the ideal case, i.e., with exact knowledge of and . Then, we generalize to a more practical setting, where we suppose to know an interval that contains the values of all the experiments considered and an interval for the values. Hence, the estimate solution will satisfy Equations (18) and (19). In this case we describe an algorithm for computing an estimate of the solution, that we will test in Section 5 against a toy model.
4.1. Exact Knowledge of and
When the information about and is exact, with the minimum amount of experiments indicated in Section 3 we can find the unbiased parameter estimate as the intersection of the zero-residual sets corresponding to each experiment. In principle this could be done also following the proof of Lemma 4, but the computation of the vectors is quite cumbersome. Since this is an ideal case, we solve it by simply imposing the satisfaction of the various and conditions (Equation (14)) as an optimization problem:
The solution of this problem is unique when the tests are in a sufficient number and satisfies the conditions of Lemma 4.
This nonlinear least-squares problem can be solved using a general nonlinear optimization algorithm, like Gauss–Newton method or Levenberg–Marquardt [8].
4.2. Approximate Knowledge of and
In practice, as already pointed out in Section 3.2, it is more realistic to know the two intervals that contain all the and values for each test i. Then, we know that within the region there is also the exact unbiased parameter solution , that we want at least to approximate. We introduce here an Unbiased Least-Squares (ULS) Algorithm 1 for the computation of this estimate.
| Algorithm 1 An Unbiased Least-Squares (ULS) algorithm. |
|
In general, the zero-residual region of each test contains the true point of the parameters vector, while the estimated iterates with the local optimization usually start from a point outside this region and converge to a point on the boundary of the region.
The ULS estimate can converge to the true solution in two cases:
- the true solution lies on the border of the region and the estimate reach the border on that point;
- the region reduces to a dimension smaller than the required accuracy, or reduces to a point.
The size of the intersection set , of the zero-residual regions , is estimated in the following way.
Let us define an index, that we call region shrinkage estimate, as follows:
where we used in the experiments below, and is the Dirac function of the set .
5. Numerical Examples
Let us consider a classical application example, the equations of a DC motor with a mechanical load, where the electrical variables are governed by the following ordinary differential equation
where I is the motor current, the motor angular speed, V the applied voltage, and a possible unmodelled component
where is the number of poles of the motor, i.e., the number of windings or magnets [9], the magnitude of the error model and the angle, given by the system
Note that the unknown component of this example can be seen as a difference in the potential that is not described by the approximated model. We are interested in the estimation of parameters . In our test the true values were constant values .
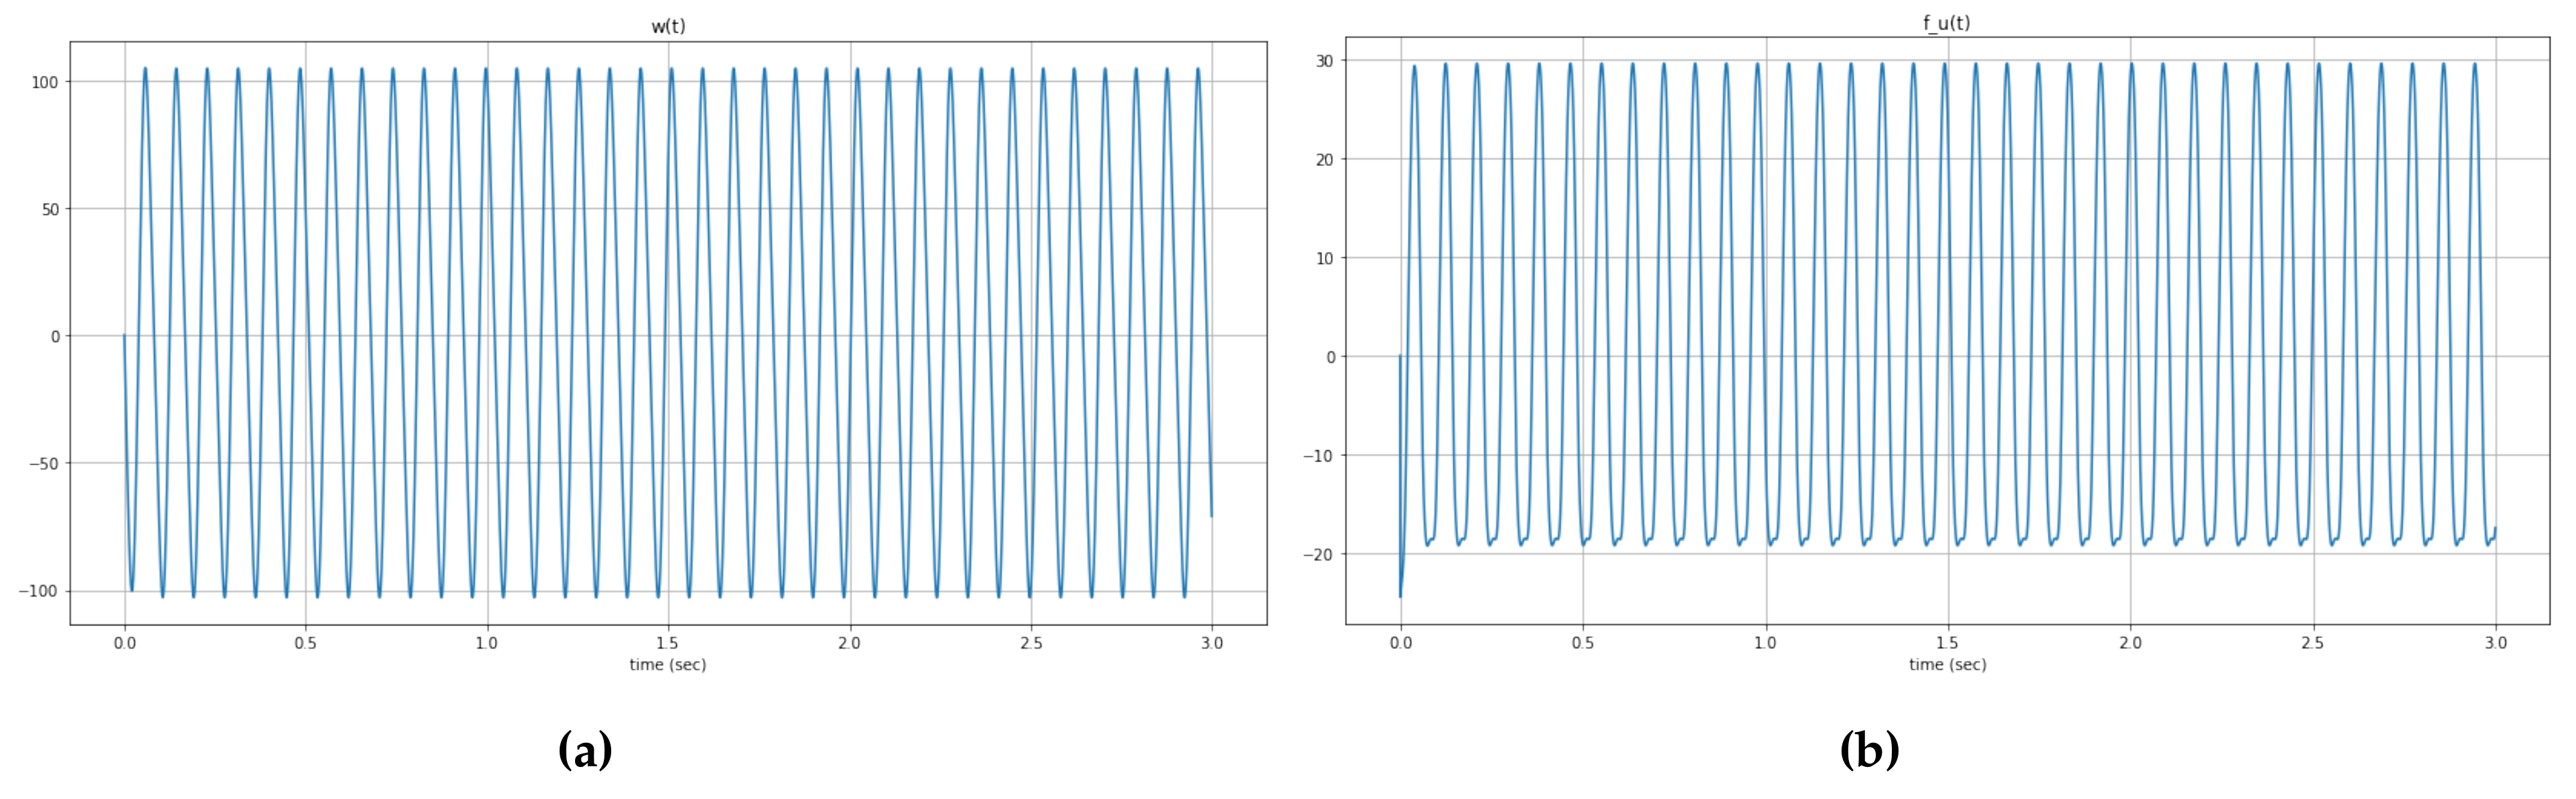
We suppose to know the measurements of I and at equally spaced times with step h, such that , and . In Figure 7 we see the plots of the motor speed and of the unknown component for this experiment.
Figure 7.
The plots of (a) and (b) in the experiment.
We compute the approximation of the derivative of the current signal with the forward finite difference formula of order one
with a step . The applied voltage is held constant to the value .
To obtain a more accurate estimate, or to allow the possibility of using higher step size values h, finite differences of higher order can be used, for example the fourth order difference formula
With the choice of the finite difference formula, we obtain the discretized equations
We will show a possible implementation of the method explained in the previous sections, and the results we get with this toy-model example. The comparison is made against the standard least-squares. In particular, we will show that when the information about and is exact, we have an exact removal of the bias. In case this information is only approximate, which is common in a real application, we will show how the bias asymptotically disappears when the number of experiments increases.
We build each test taking the Equation (35) for n samples in the range , obtaining the linear system
so that the first matrix in the equation is with , the number of parameters to be estimated.
To measure the estimation relative error we will use the following formula, where is the parameter estimate:
Note that the tests that we built in the numerical experiments below are simply small chunks of consecutive data, taken from one single simulation for each experiment.
The results have been obtained with a Python code developed by the authors, using NumPy for linear algebra computations and scipy.optimize for the nonlinear least-squares optimization.
5.1. Exact Knowledge of and
As analyzed in Section 4.1, the solution of the minimization problem (30) is computed with a local optimization algorithm.
Here the obtained results show an error with an order of magnitude of in every test we made. Note that it is also possible to construct geometrically the solution, with exact results.
5.2. Approximate Knowledge of and
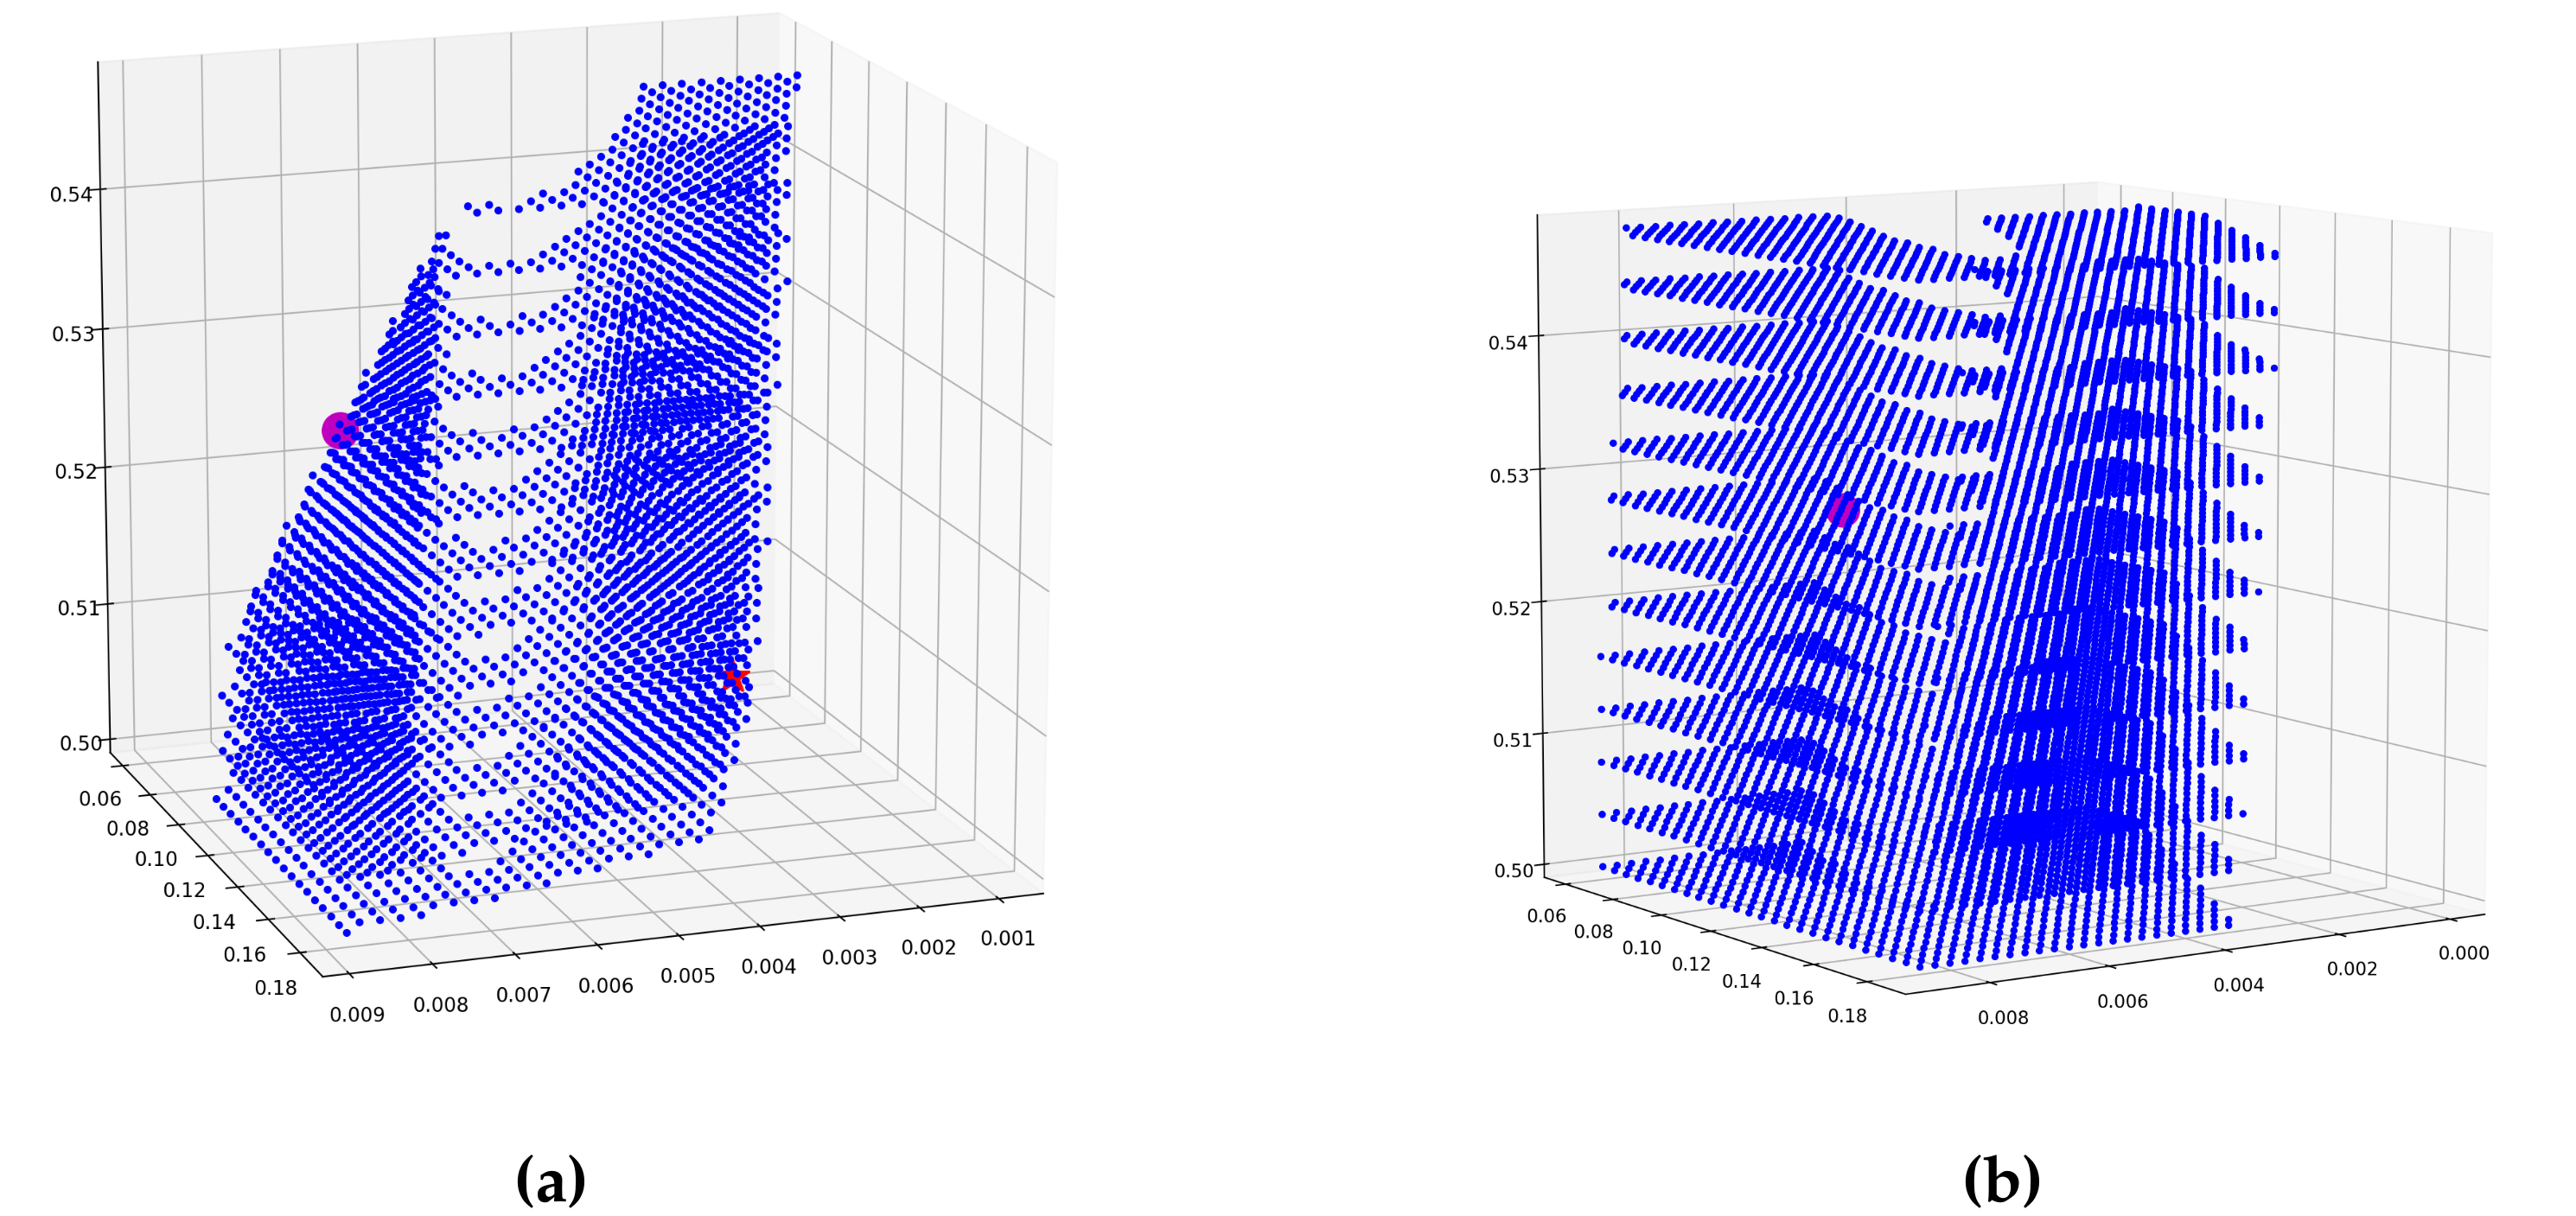
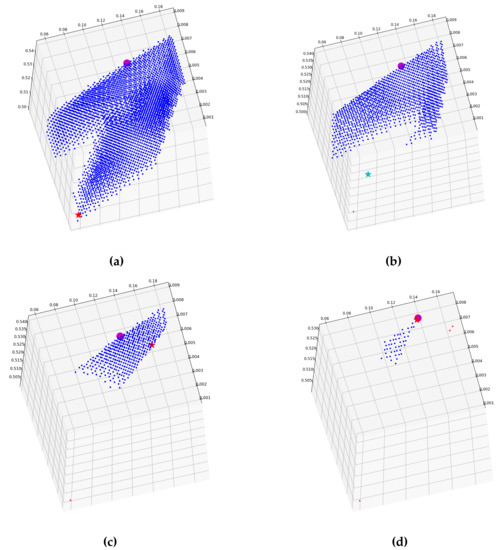
When and are known only approximately, i.e., we know only an interval that contains all the values and an interval that contains all the values, we lose the unique intersection of Lemma 4, that would require only tests. Moreover, with a finite number of tests we cannot guarantee in general to satisfy the exact hypotheses of Theorem 1. As a consequence, various issues open up. Let’s start by showing in Figure 8 that when all the four conditions of (15) hold with equality, the true solution lies on the boundary of the region as already mentioned in Section 3.2. If this happens, then with the conditions of Theorem 1 on the upward/downward outgoing gradients, the region is a point. When all the four conditions of (15) hold with strict inequalities, the true solution lies inside the region (Figure 8b). From a theoretical point of view this distinction has a big importance, since it means that the zero-residual region can or cannot be reduced to a single point. From a practical point of view it becomes less important, for the moment, since we cannot guarantee that the available tests will reduce exactly to a single point and we will arrive most of the times to an approximate estimate. This can be more or less accurate, but this depends on the specific application, and this is out of the scope of the present work.
Figure 8.
Two examples of (zero-residual) intersection regions with different location of the true solution: inside the region or on its border. For graphical reasons the region has been discretized and the dots are the grid nodes; the bigger ball (thick point) is the true solution. (a): The true solution (ball) is on the border of ; (b): The true solution (ball) is internal to .
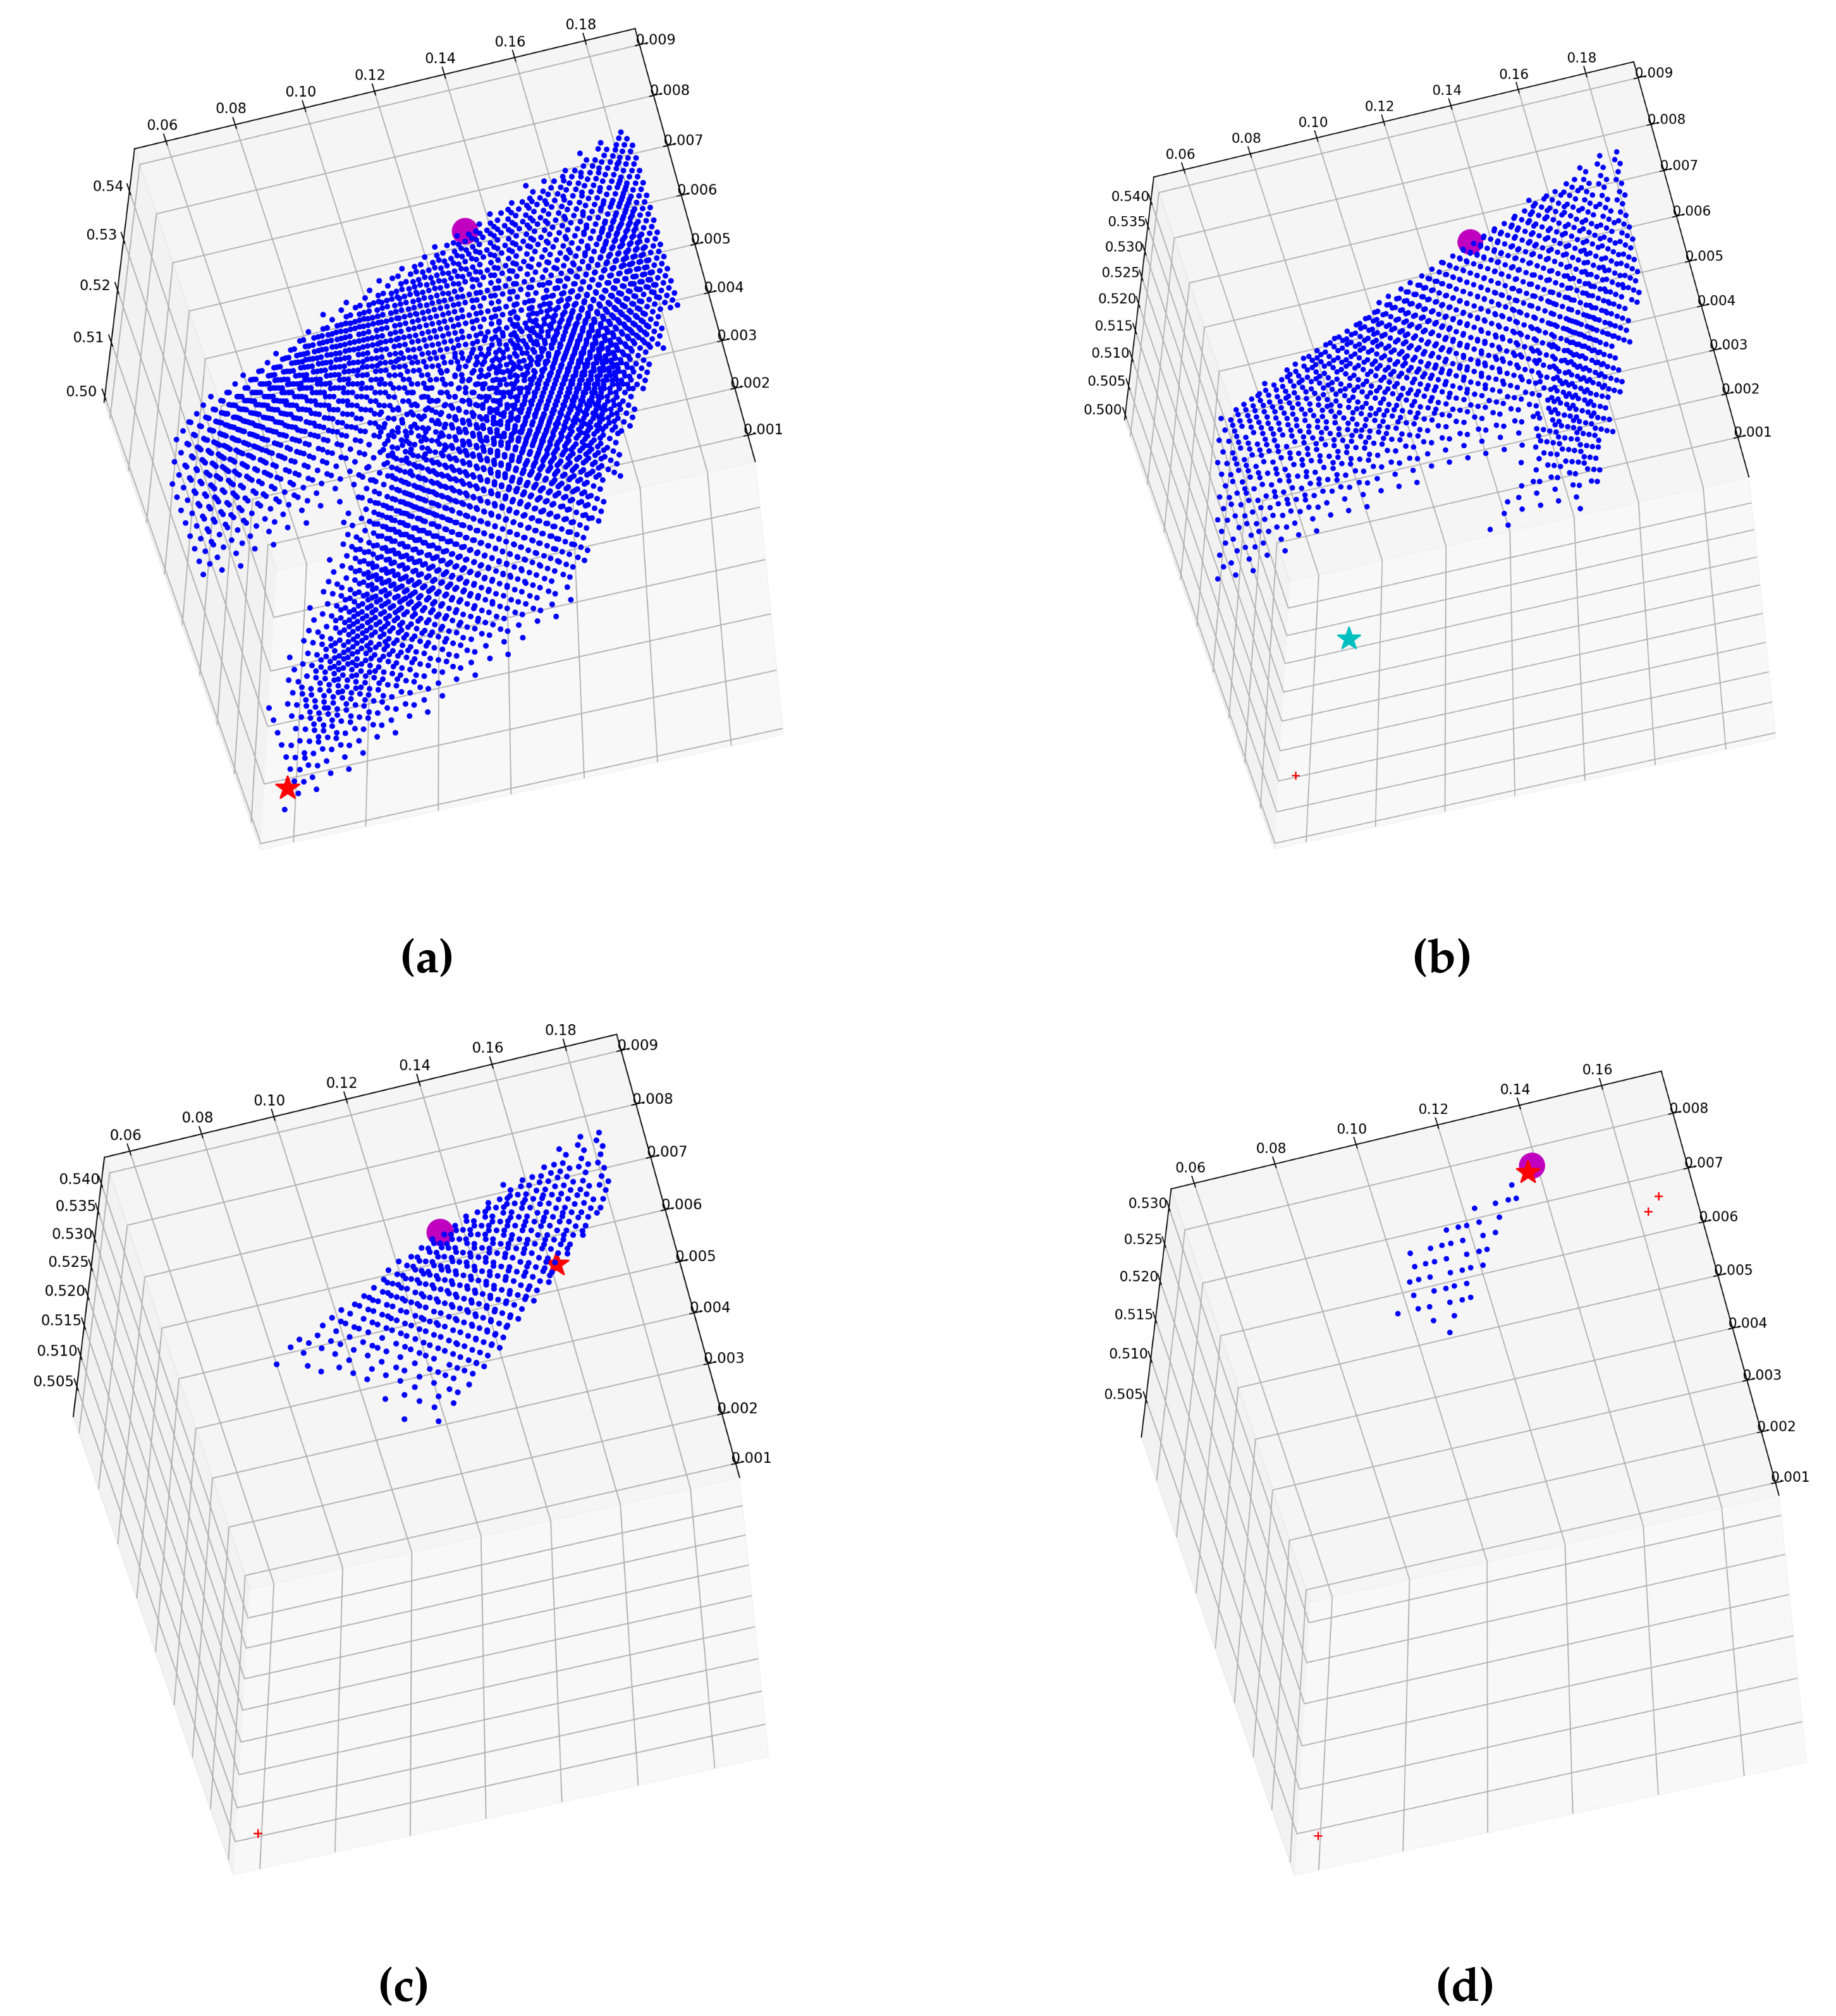
To be more precise, when the conditions of Theorem 1 are not satisfied, there is an entire region of the parameters space which satisfies exactly problem (30), but only one point of this region is the true solution . As more tests are added and intersected together, the zero-residual region tends to reduce, simply because it must satisfy an increasing number of inequalities. In Figure 9 we can see four iterations taken from an example, precisely with 3, 5, 9 and 20 tests intersected and . With only three tests (Figure 9a), there is a big region (described by the mesh of small dots), and here we see that the true solution (thick point) and the current estimate (star) stay on opposite sides of the region, as accidentally happens. With five tests (Figure 9a) the region has shrunk considerably and the estimate is reaching the boundary (in the plot it is still half-way), and even more with nine tests (Figure 9c). The convergence arrives here before the region collapses to a single point, because accidentally the estimate has approached the region boundary at the same point where the true solution is located.
Figure 9.
The intersection region at different number of tests involved. For graphical reasons the region has been discretized and the dots are the grid nodes; the bigger ball is the true solution and the star is the current estimate in the experiment. (a) 3 tests; (b) 5 tests; (c) 9 tests; (d) 20 tests.
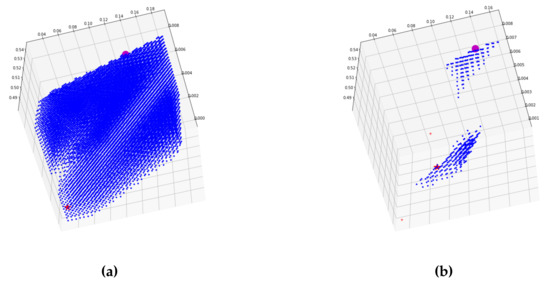
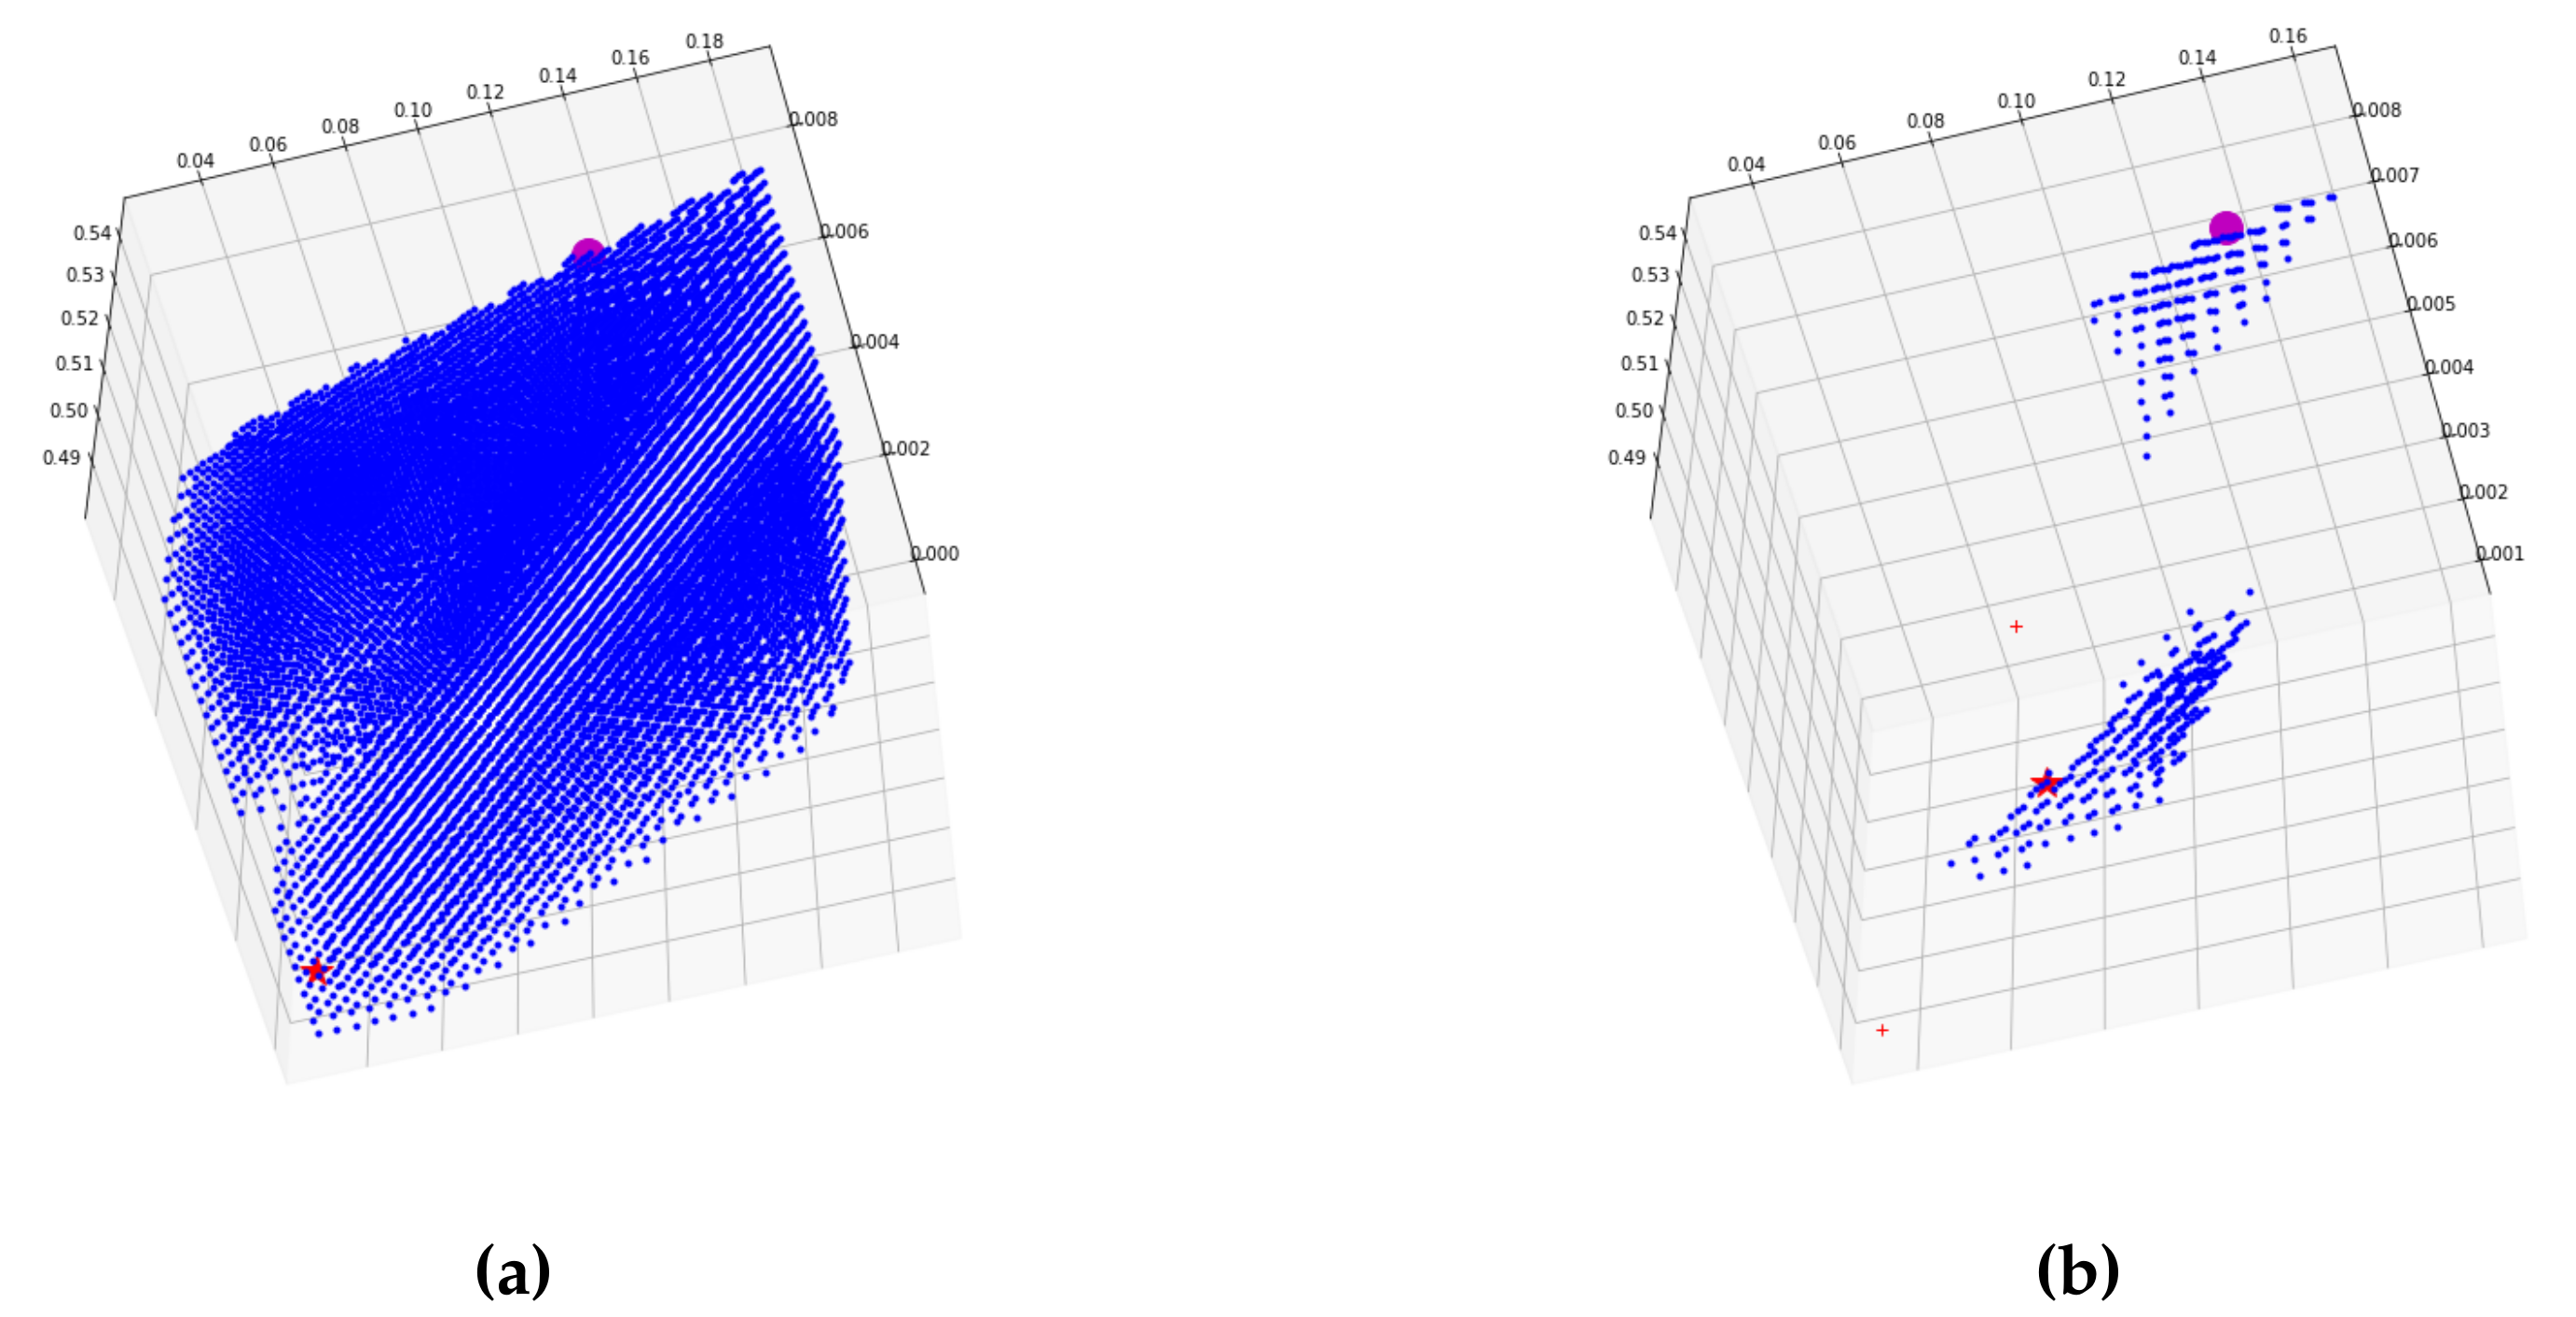
In general, the zero-residual region (20) of each test contains the true solution, while the estimate arrives from outside the region and stops when it bumps the border of the intersection region (21). For this reason we have convergence when the region that contains the true solution is reduced to a single point, and the current estimate does not lie in a disconnected sub-region of different from the one in which the true solution lies. Figure 10 shows an example of an intersection region which is the union of two closed disconnected regions: this case creates a local minimum in problem (30).
Figure 10.
The intersection region at different number of tests involved. On the left a few tests have created a single connected region while, on the right, adding more tests have splitted it into two subregions. For graphical reasons the region has been discretized and the dots are the grid nodes; the bigger ball is the true solution and the star is the current estimate in the experiment. (a) A (portion of a) connected region ; (b) A region split into two not connected sub regions.
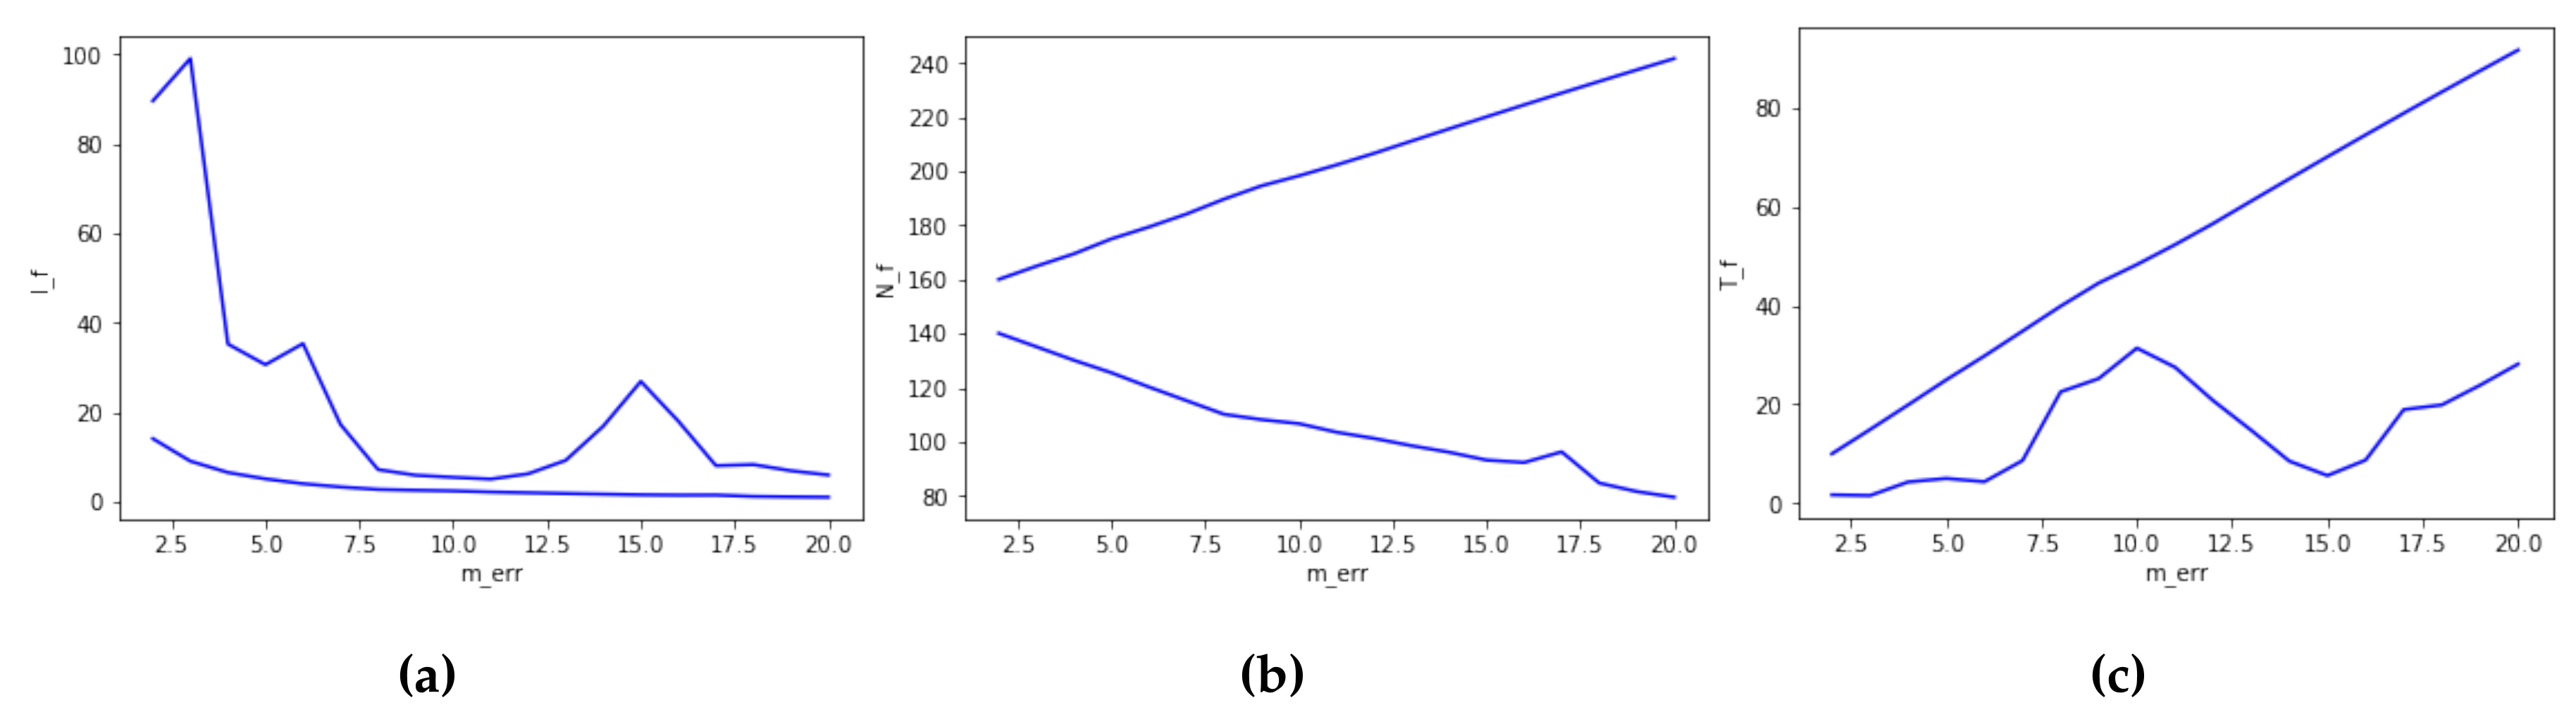
In Figure 11 we see the differences and vs. . The differences are bigger for higher values of the model error. It seems that this is the cause of a more frequent creation of local minima.
Figure 11.
The three plots show the values assumed by the extreme values (15) as a function of . (a): ; (b): ; (c).
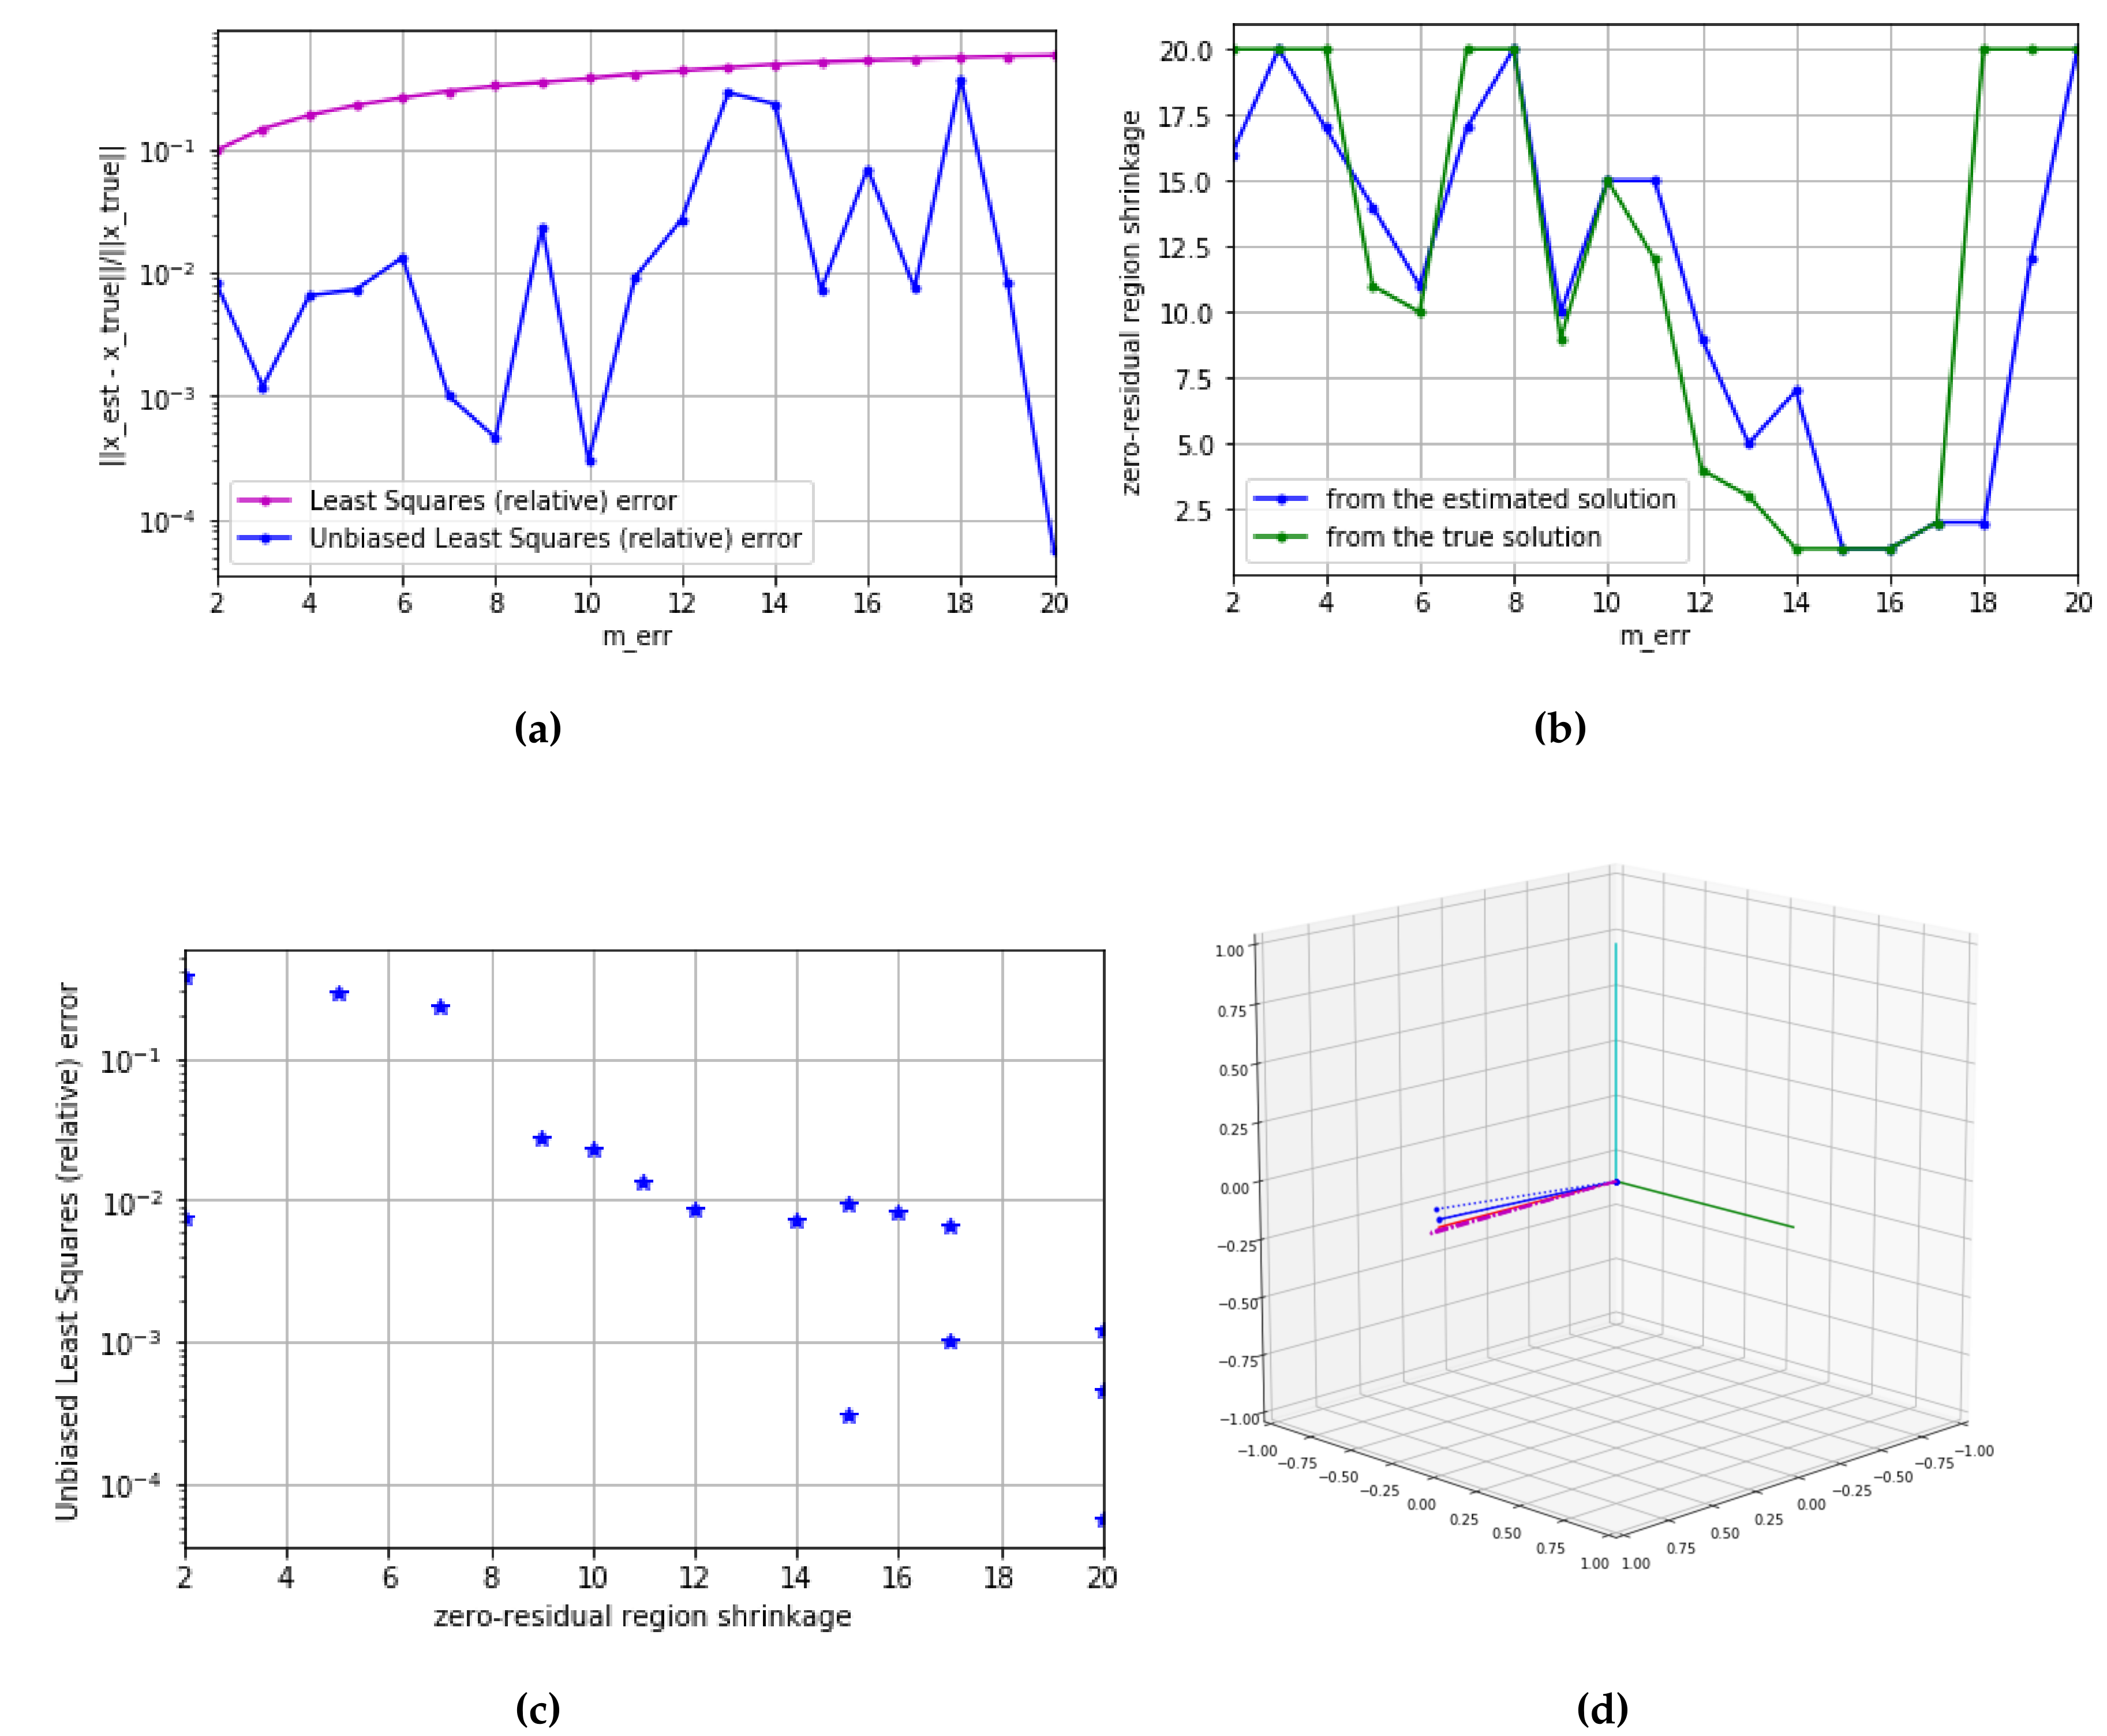
Figure 12 synthesizes the main results that we have experienced with this new approach. Globally it shows a great reduction of the bias contained in the standard least-squares estimates; indeed, we had to use the logarithmic scale to enhance the differences in the behaviour of the proposed method while varying . In particular,
Figure 12.
The plots summarize the results obtained by the ULS approach to parameter estimation no the model problem explained at the beginning of this section. (a): The relative estimation error (37) vs. ; (b): The region shrinkage estimate (31) vs. ; (c): The relative estimation error (37) vs. the estimate of the region shrinkage, considering the experiments with ; (d): A three dimensional view of the Outgoing Gradients at the last iteration of the experiment with .
- with considerable levels of modelling error, let us say between 2 and 12, the parameter estimation error is at least one order of magnitude smaller that that of least-squares; this is accompanied by high levels of shrinkage of the zero-residual region (Figure 12b);
- with higher levels of , we see a low shrinkage of the zero-residual region and consequently an estimate whose error is highly oscillating, depending on where the optimization algorithm has brought it to get in contact with the zero-residual region;
- at we see the presence of a local minimum, due to the falling to pieces of the zero-residual region as in Figure 10: the shrinkage at the true solution is estimated to be very high, while at the estimated solution it is quite low, since it is attached to a disconnected, wider sub-region.
- the shrinking of the zero-residual region is related to the distribution of the outgoing gradients, as stated by Theorem 1: in Figure 12d we see that in the experiment with they occupy only three of eight orthants, while in the best results of the other experiments the gradients distribute themselves in almost all orthants (not shown).
It is evident from these results that for lower values of modelling error , it is much easier to produce tests that reduce the zero-residual region to a quite small interval of , while for high values of it is much more difficult and the region can even fall to pieces, thus creating local minima. It is also evident that a simple estimate of the region size, like (31), can reliably assess the quality of the estimate produced by the approach here proposed, as summarized in Figure 12c.
6. Conclusions
In this paper we have analyzed the bias commonly arising in parameter estimation problems where the model is lacking some deterministic part of the system. This result is useful in applications where an accurate estimation of parameters is important, e.g., in physical (grey-box) modelling typically arising in the model-based design of multi-physical systems, see e.g., the motivations that the authors did experience in the design of digital twins of controlled systems [10,11,12] for virtual prototyping, among an actually huge literature.
At this point, the method should be tested in a variety of applications, since the ULS approach here proposed is not applicable black-box as Least-Squares are. Indeed, it requires some additional a priori information. Moreover, since the computational complexity of the method here presented is relevant, efficient computational methods must be considered and will be a major issue in future investigations.
Another aspect that is even worth to deepen is also the possibility to design tests that contribute optimally to the reduction of the zero-residual region.
Author Contributions
Conceptualization, methodology, validation, formal analysis, investigation, software, resources, data curation, writing—original draft preparation, writing—review and editing, visualization: M.G. and F.M.; supervision, project administration, funding acquisition: F.M. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by the project DOR1983079/19 from the University of Padova and by the doctoral grant “Calcolo ad alte prestazioni per il Model Based Design" from Electrolux Italia s.p.a.
Conflicts of Interest
The authors declare no conflict of interest.
References
- Björck, A. Numerical Methods for Least Squares Problems; Society for Industrial and Applied Mathematics: Philadelphia, PA, USA, 1996. [Google Scholar] [CrossRef] [Scilit]
- Huffel, S.V.; Markovsky, I.; Vaccaro, R.J.; Söderström, T. Total least squares and errors-in-variables modeling. Signal Process. 2007, 87, 2281–2282. [Google Scholar] [CrossRef] [Scilit]
- Söderström, T.; Soverini, U.; Mahata, K. Perspectives on errors-in-variables estimation for dynamic systems. Signal Process. 2002, 82, 1139–1154. [Google Scholar] [CrossRef] [Scilit]
- Van Huffel, S.; Vandewalle, J. The Total Least Squares Problem: Computational Aspects and Analysis; Frontiers in Applied Mathematics (Book 9); Society for Industrial and Applied Mathematics: Philadelphia, PA, USA, 1991. [Google Scholar]
- Peck, C.C.; Beal, S.L.; Sheiner, L.B.; Nichols, A.I. Extended least squares nonlinear regression: A possible solution to the “choice of weights” problem in analysis of individual pharmacokinetic data. J. Pharmacokinet. Biopharm. 1984, 12, 545–558. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Meyer, C.D. Matrix Analysis and Applied Linear Algebra; Society for Industrial and Applied Mathematics: Philadelphia, PA, USA, 2000. [Google Scholar]
- Hansen, P.C. Oblique projections and standard-form transformations for discrete inverse problems. Numer. Linear Algebra Appl. 2013, 20, 250–258. [Google Scholar] [CrossRef] [Scilit]
- Nocedal, J.; Wright, S. Numerical Optimization; Springer: Berlin, Germany, 1999. [Google Scholar]
- Krause, P.C. Analysis of Electric Machinery; McGraw Hill: New York, NY, USA, 1986. [Google Scholar]
- Beghi, A.; Marcuzzi, F.; Rampazzo, M.; Virgulin, M. Enhancing the Simulation-Centric Design of Cyber-Physical and Multi-physics Systems through Co-simulation. In Proceedings of the 2014 17th Euromicro Conference on Digital System Design, Verona, Italy, 27–29 August 2014; pp. 687–690. [Google Scholar] [CrossRef] [Scilit]
- Beghi, A.; Marcuzzi, F.; Rampazzo, M. A Virtual Laboratory for the Prototyping of Cyber-Physical Systems. IFAC-PapersOnLine 2016, 49, 63–68. [Google Scholar] [CrossRef] [Scilit]
- Beghi, A.; Marcuzzi, F.; Martin, P.; Tinazzi, F.; Zigliotto, M. Virtual prototyping of embedded control software in mechatronic systems: A case study. Mechatronics 2017, 43, 99–111. [Google Scholar] [CrossRef] [Scilit]
© 2020 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).