Journal Description
Machine Learning and Knowledge Extraction
is an international, peer-reviewed, open access, monthly journal on machine learning and applications, see our video on YouTube explaining the MAKE journal concept.
- Open Access— free for readers, with article processing charges (APC) paid by authors or their institutions.
- High Visibility: indexed within Scopus, ESCI (Web of Science), dblp, and other databases.
- Rapid Publication: manuscripts are peer-reviewed and a first decision is provided to authors approximately 18.7 days after submission; acceptance to publication is undertaken in 3.8 days (median values for papers published in this journal in the first half of 2026).
- Journal Rank: JCR - Q1 (Engineering, Electrical and Electronic) / CiteScore - Q1 (Engineering (miscellaneous))
- Recognition of Reviewers: Reviewers whose reports are timely and of high quality receive an APC discount voucher for a future publication in an MDPI journal. Become a reviewer.
- Journal Cluster of Artificial Intelligence: AI, AI in Medicine, Algorithms, BDCC, MAKE, MTI, Stats, Virtual Worlds, Computers and Journal of Superintelligence.
Impact Factor:
8.4 (2025);
5-Year Impact Factor:
7.4 (2025)
Latest Articles
Geometry-Aware 1D Residual CNN-BiLSTM Network for Automated Vertebral Localization and Scoliosis Classification
Mach. Learn. Knowl. Extr. 2026, 8(9), 286; https://doi.org/10.3390/make8090286 - 15 Sep 2026
Abstract
Accurate localization of the upper end vertebra (UEV), lower end vertebra (LEV), and apex vertebra (AV) is essential for automated scoliosis assessment and Cobb angle measurement. This study proposes a geometry-aware, multi-task sequence learning framework for vertebral landmark localization and scoliosis type classification.
[...] Read more.
Accurate localization of the upper end vertebra (UEV), lower end vertebra (LEV), and apex vertebra (AV) is essential for automated scoliosis assessment and Cobb angle measurement. This study proposes a geometry-aware, multi-task sequence learning framework for vertebral landmark localization and scoliosis type classification. The framework integrates YOLOv8-OBB-based feature extraction with a 1D Residual CNN-BiLSTM architecture and a displacement-guided regularization term, termed Geometric Loss (GeoLoss). Images and reference annotations were obtained from the open-source Spinal-AI2024 dataset, and a development set of 550 radiographs was used for model development and internal evaluation. Vertebral detections were transformed into 12-dimensional geometric sequences encoding orientation, displacement, shape, confidence, and curvature. Robustness was assessed using four train–validation–test partitioning strategies with repeated experiments and five-fold cross-validation, with the 75/15/10 partition showing the strongest mean internal performance. On a disjoint held-out set of 58 unseen images from the same dataset, the model achieved a Type Accuracy, EV Accuracy (±1), and EV Accuracy (±2) of 96.55%, 86.63%, and 94.19%, respectively, with an EV mean absolute error of 0.559 vertebral levels. These findings support geometry-aware sequence modeling as an effective approach for automated vertebral landmark localization and scoliosis assessment.
Full article
(This article belongs to the Topic Applications of Image and Video Processing in Medical Imaging)
Open AccessArticle
Recurrent Graph Attention over Longitudinal Brain Networks Predicts Conversion from Mild Cognitive Impairment to Alzheimer’s Disease
by
Medet Ashimgaliyev, Ainur Zhumadillayeva, Miras Mussabek, Nurbek Saparkhojayev, Peiwu Qin and Dusmat Zhamangarin
Mach. Learn. Knowl. Extr. 2026, 8(9), 285; https://doi.org/10.3390/make8090285 - 15 Sep 2026
Abstract
Predicting progression from mild cognitive impairment (MCI) to Alzheimer’s disease (AD) requires models that represent both regional brain abnormalities and their evolution across repeated examinations. We developed a longitudinal graph neural network that integrates structural magnetic resonance imaging, FDG-PET, regional imaging biomarkers, and
[...] Read more.
Predicting progression from mild cognitive impairment (MCI) to Alzheimer’s disease (AD) requires models that represent both regional brain abnormalities and their evolution across repeated examinations. We developed a longitudinal graph neural network that integrates structural magnetic resonance imaging, FDG-PET, regional imaging biomarkers, and clinical covariates across irregular follow-up visits. The study included 614 participants with baseline MCI from the Alzheimer’s Disease Neuroimaging Initiative: 218 converters to AD within five years and 396 non-converters, with 2438 eligible longitudinal visits. Each visit was represented as an 82-node brain graph based on the Desikan–Killiany atlas. Node features combined a 128-dimensional multimodal convolutional embedding with four regional biomarkers. Graph-attention layers modelled spatial dependencies, a node-wise gated recurrent unit modelled longitudinal dependencies, and masked temporal self-attention aggregated variable-length visit sequences. Participants were divided at the subject level into development and held-out test sets, and hyperparameters were selected by five-fold cross-validation within the development set. On the held-out test set of 123 participants, the model reached an area under the receiver operating characteristic curve of 0.859 (95% CI 0.795–0.915), balanced accuracy of 0.805 (95% CI 0.736–0.862), sensitivity of 0.781, and specificity of 0.832. The AUC was numerically higher than that of the strongest baseline, a CNN–GRU sequence model, which reached 0.832 (95% CI 0.758–0.894); the paired AUC difference was 0.027 (95% CI 0.009–0.098), the unadjusted DeLong p-value was 0.026, and the Holm-adjusted p-value was 0.052, which was not significant at the conventional 0.05 threshold after correction for multiple comparisons. In ablation experiments, removing temporal modelling reduced the AUC to 0.818, and removing the spatial graph structure reduced it to 0.808, the two largest reductions observed. Integrated-gradient analysis placed the highest importance on hippocampal and entorhinal regions. Combining graph-based spatial modelling with recurrent longitudinal reasoning was associated with higher discrimination than sequence modelling alone, though this difference was not statistically significant after correction for multiple comparisons. Validation was restricted to a single research cohort (ADNI), and no independent external dataset was used; prospective external validation on an independent cohort is required before the model can be considered for clinical use Because FDG-PET was unavailable for 19.3% of visits, we report the headline result separately from a sensitivity analysis restricted to participants with complete FDG-PET at every visit (development set cross-validated AUC 0.891 vs. 0.874 for the full cohort with masked missing FDG-PET); multimodal performance should be read as cohort-dependent rather than as a single unconditional figure.
Full article
(This article belongs to the Special Issue Selected Papers from the International Conference on Advances in Artificial Intelligence and Machine Learning (AAIML 2026))
Open AccessArticle
Context-Aware LLM-Guided Neighbourhood Search for Simulation-Based Production Scheduling
by
Róbert Skapinyecz
Mach. Learn. Knowl. Extr. 2026, 8(9), 284; https://doi.org/10.3390/make8090284 - 15 Sep 2026
Abstract
The paper presents a novel large language model-based neighbourhood search method for production scheduling using discrete-event simulation (DES) as the modelling and evaluation engine. The combination of large language models (LLMs) and DES represents a relatively new area of research with significant potential.
[...] Read more.
The paper presents a novel large language model-based neighbourhood search method for production scheduling using discrete-event simulation (DES) as the modelling and evaluation engine. The combination of large language models (LLMs) and DES represents a relatively new area of research with significant potential. The current study aims to demonstrate the applicability of LLMs for the automated closed-loop optimisation of production systems, using the DES environment as a configurable modelling tool and an evaluation engine at the same time, from which the results and the related contextual information are extracted at the end of each simulation run to provide feedback and context for the LLM in its autonomous search for improved solutions. The architecture was implemented with the use of Mistral Small 3.2 (24B) as the LLM and Siemens Tecnomatix Plant Simulation as the DES environment. The results from the proposed approach were compared with those of a genetic algorithm (GA) native to the applied DES environment, and with those achieved using simulated annealing (SA). While the proposed method was generally outperformed by the GA and the SA in terms of final solution quality and computational cost, it demonstrated advantages in terms of simulation demand while also providing a highly adaptable optimisation framework with significant potential for improvement and wider generalisation in the future.
Full article
(This article belongs to the Section Learning)
Open AccessArticle
Functional Kolmogorov-Arnold Network: A Hilbert-Space Perspective on Spatial Representation Learning for Medical Image Segmentation
by
Maksim Penkin and Andrey Krylov
Mach. Learn. Knowl. Extr. 2026, 8(9), 283; https://doi.org/10.3390/make8090283 - 15 Sep 2026
Abstract
Medical image segmentation requires spatial transformations that remain effective across heterogeneous image statistics and boundary conditions. We introduce FunKAN, a KAN-inspired operator that acts directly on spatial feature maps: analytical Hermite basis maps are evaluated on an input-conditioned deformed grid, scored against learned
[...] Read more.
Medical image segmentation requires spatial transformations that remain effective across heterogeneous image statistics and boundary conditions. We introduce FunKAN, a KAN-inspired operator that acts directly on spatial feature maps: analytical Hermite basis maps are evaluated on an input-conditioned deformed grid, scored against learned channel-wise templates, mixed by a softmax over modes, and aggregated across channels. A Hilbert-space functional approximation result motivates the function-space viewpoint, while the exact finite FunKAN operator is treated separately and is not claimed to inherit a universal-approximation theorem. We embed FunKAN in a U-shaped architecture (U-FunKAN) and evaluate it under the validation-only selection protocol on BUSI, GlaS, and CVC-ClinicDB. The frozen model is tested once per seed after three-seed training. U-FunKAN improves mean test IoU over a same-protocol U-Net by 6.35 percentage points on BUSI and 1.85 points on CVC-ClinicDB, while GlaS performance is comparable, with U-FunKAN 0.50 points lower. U-FunKAN uses fewer parameters than the retrained U-Net (15.95 M vs. 31.03 M) but is substantially slower in measured GPU latency, so we do not claim universal computational efficiency. The results support dataset-dependent gains from functional spatial parameterization rather than uniform dominance.
Full article
(This article belongs to the Topic Applications of Image and Video Processing in Medical Imaging)
Open AccessArticle
A Gradient-Level Diagnosis of Extreme Class Imbalance in Multiple Instance Learning via q-Calculus
by
Arif Ali Rehman, Enrique Nava Baro and Pablo Otero
Mach. Learn. Knowl. Extr. 2026, 8(9), 282; https://doi.org/10.3390/make8090282 - 14 Sep 2026
Abstract
Training under extreme class imbalance (>1:100) remains an open problem in weakly supervised learning. The standard remedy—loss-level reweighting (focal loss, asymmetric loss, class-balanced loss)—is widely adopted, yet its behavior at extreme ratios in Multiple Instance Learning (MIL) is poorly understood. On digital breast
[...] Read more.
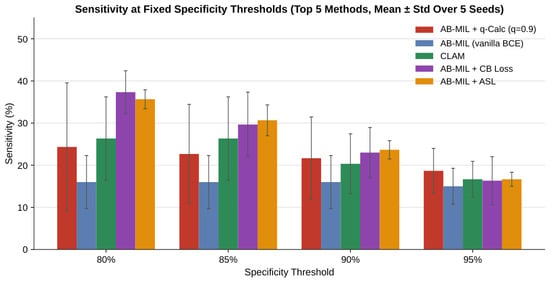
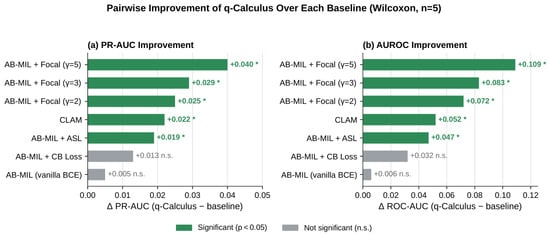
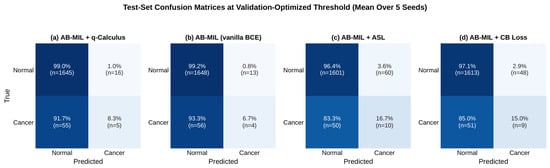
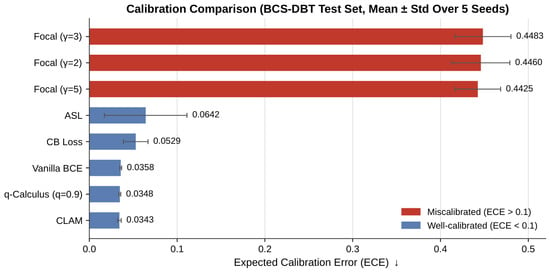
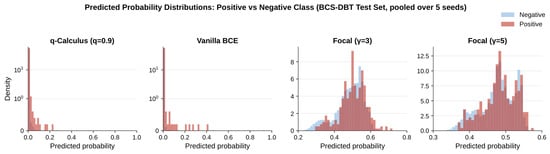
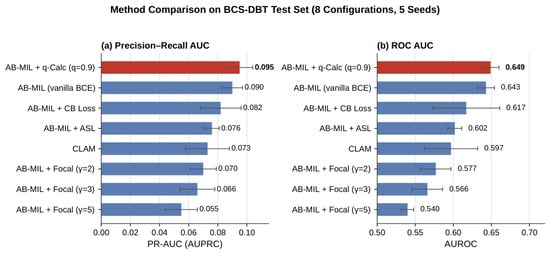
Training under extreme class imbalance (>1:100) remains an open problem in weakly supervised learning. The standard remedy—loss-level reweighting (focal loss, asymmetric loss, class-balanced loss)—is widely adopted, yet its behavior at extreme ratios in Multiple Instance Learning (MIL) is poorly understood. On digital breast tomosynthesis (attention-based pooling over frozen EfficientNet-B3 features), we study the optimization bounds under extreme bag-level MIL imbalance (1:251), intervening at two levels: the loss surface (via reweighting) and the gradient dynamics (via a novel q-calculus gradient modification using the Jackson q-derivative). All three reweighting strategies degrade classification relative to unweighted binary cross-entropy (BCE), monotonically, eliminating the loss surface as the bottleneck. Extended evaluation ( seeds) shows q-calculus gradient smoothing matches vanilla BCE ( , Cohen’s ) despite provably reducing gradient variance, establishing an empirical ceiling on the optimization-achievable area under the precision-recall curve (AUPRC) of 0.0912; loss reweighting defines the floor at 0.055. Focal loss is additionally catastrophically miscalibrated (ECE > 0.44 vs. 0.036 for vanilla BCE), a collapse that persists under adaptive binning. In this regime, exceeding the ceiling points to the data-representation level, not the optimizer. We further identify ratio-invariant safety—non-degradation at any imbalance ratio, satisfied by vanilla BCE and q-calculus but violated by all reweighting methods—and give recommendations spanning moderate to extreme imbalance.
Full article
(This article belongs to the Section Learning)
►▼
Show Figures

Figure 1
Open AccessSystematic Review
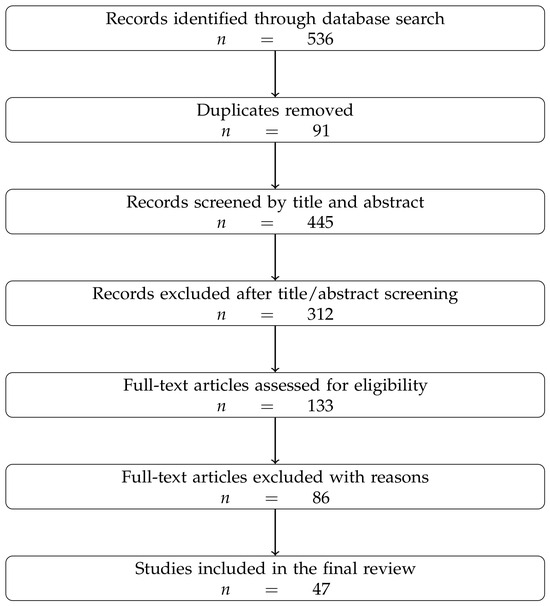
Bridging Knowledge and Learning: A Multi-Axis Analytical Survey for Neurosymbolic Artificial Intelligence
by
Sotiris Zikas, Katerina Gkirtzou, Theodor Panagiotakopoulos and Yiannis Kiouvrekis
Mach. Learn. Knowl. Extr. 2026, 8(9), 281; https://doi.org/10.3390/make8090281 - 14 Sep 2026
Abstract
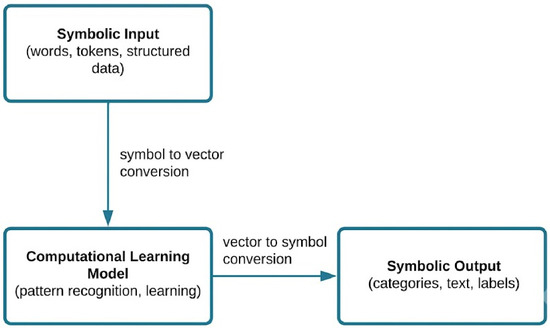
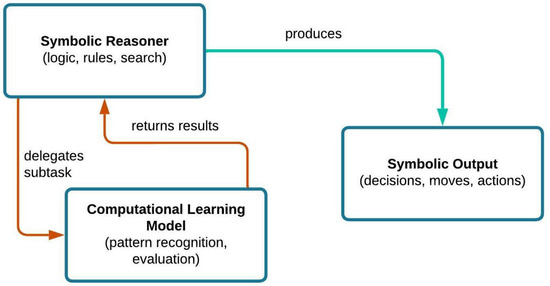
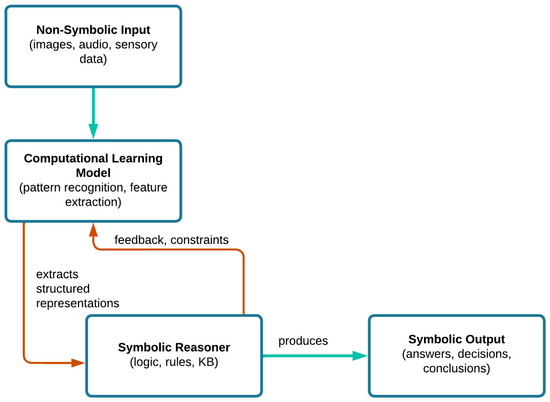
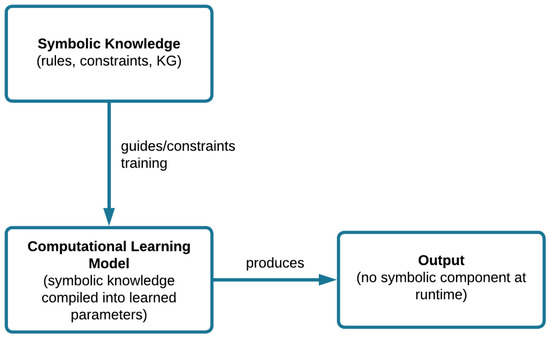
Neurosymbolic AI (NeSy AI) seeks to integrate the strengths of symbolic reasoning with computational learning methods, addressing fundamental challenges of each paradigm in isolation. Existing surveys have primarily organized this growing body of research by architecture. The systematic evaluation of NeSy systems against
[...] Read more.
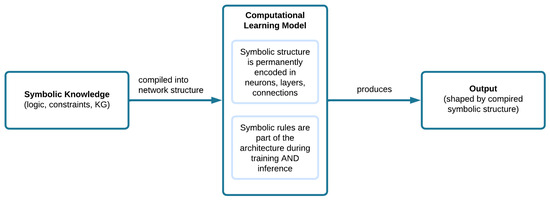
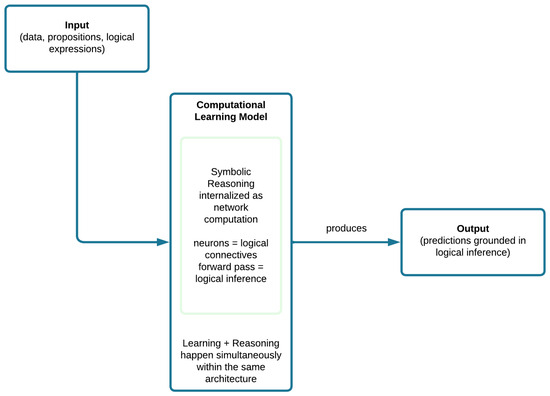
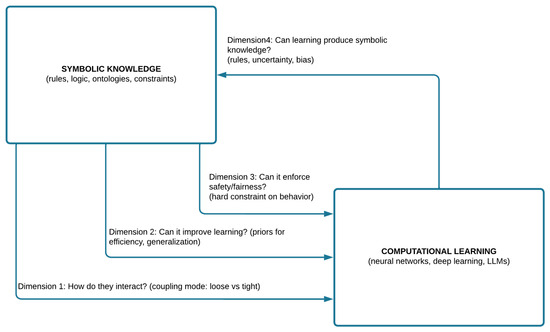
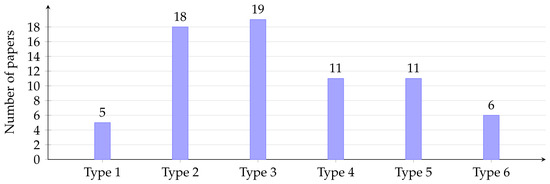
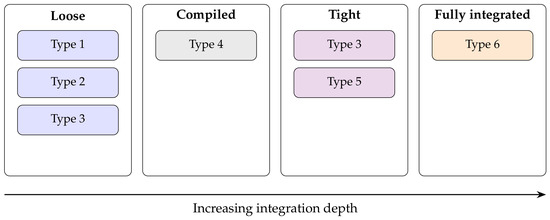
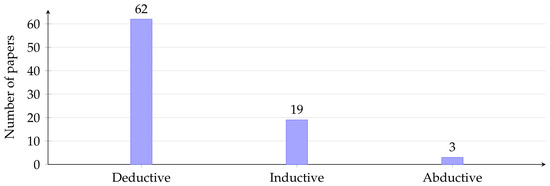
Neurosymbolic AI (NeSy AI) seeks to integrate the strengths of symbolic reasoning with computational learning methods, addressing fundamental challenges of each paradigm in isolation. Existing surveys have primarily organized this growing body of research by architecture. The systematic evaluation of NeSy systems against the foundational questions about knowledge–learning interaction raised in the literature has received far less attention. This paper introduces a multi-axis analytical framework that combines the six-type taxonomy proposed by Kautz with four foundational dimensions derived from the open questions raised by van Harmelen: the mode of integration between symbolic and computational learning components, the use of symbolic priors for learning, the enforcement of symbolic constraints for safety and bias prevention, and the production of symbolic knowledge from learning. Complemented by a systematic reasoning categorization (deductive, inductive, abductive), this framework is applied to categorize and analyze 70 NeSy papers. The analysis reveals that while symbolic priors for learning are widely adopted in the surveyed corpus, symbolic constraints for safety and fairness remain significantly underexplored despite being among the most frequently cited motivations for NeSy research. Task-level abductive reasoning is virtually absent, appearing in only three of the 70 systems, all but one from 2026. Fully integrated architectures (Kautz Type 6) remain scarce and largely theoretical, and bidirectional knowledge–learning interaction is rare. Six concrete gaps are identified, providing specific directions for future research in neurosymbolic AI.
Full article
(This article belongs to the Special Issue Trustworthy AI: Integrating Knowledge, Retrieval, and Reasoning)
►▼
Show Figures

Figure 1
Open AccessArticle
Cross-Domain Input, Mutual Exclusivity, and Inferential Reasoning: When LLMs Learn Words Like Humans
by
Veronica Mendoza, Ekaitz Zulueta, Xabier Basogain, Javier Peña-Ceballos and Julen Carasa-Castaño
Mach. Learn. Knowl. Extr. 2026, 8(9), 280; https://doi.org/10.3390/make8090280 - 11 Sep 2026
Abstract
Humans acquire meaningful language by storing perceptual categories, category-word mappings, and conditional IF–THEN rules in rich, cross-domain, multimodal contexts. Crucially, structured cross-domain input that pairs visual context and language (text) appears to be fundamental to this process, enabling individuals to acquire, for example,
[...] Read more.
Humans acquire meaningful language by storing perceptual categories, category-word mappings, and conditional IF–THEN rules in rich, cross-domain, multimodal contexts. Crucially, structured cross-domain input that pairs visual context and language (text) appears to be fundamental to this process, enabling individuals to acquire, for example, the lexicon. The present study investigates whether Large Language Models (LLMs) can learn words when trained on structured cross-domain input rather than text-only exposure. This paper incorporates a controlled Fictitious-Animal Paradigm featuring 32 creatures and 32 pseudowords, divided into two phases: single-animal and dual-animal scenes. Single-animal contexts entailed storing categories and mappings, while dual-animal environments involved storing logical constraints and performing inference. The authors propose a computational model centred on four capacities for context-based word learning: storing perceptual categories, category-word mappings, and the Mutual Exclusivity rule (formalised as a conditional IF-THEN statement), and retrieving stored information to assign novel labels through inference. The evaluation demonstrates that structured cross-domain input enables LLMs to exhibit behaviour consistent with conditional IF–THEN rules, allowing them to infer and acquire novel words based on current visual contexts. These findings suggest that, with this input that integrates context and text, LLMs display adaptive, real-time human-like inferential reasoning in word learning.
Full article
(This article belongs to the Section Learning)
►▼
Show Figures

Figure 1
Open AccessArticle
AnExplainable AI Engineering Framework for Claims-Only First-Stage Provider Audit Triage Using SHAP-Guided Hybrid Retrieval-Augmented Generation
by
Danni Huang, Litong Song, Yue Chen, Shuangjiang He, Ruiqi Wang, Hongyu Shen and Weishen Chu
Mach. Learn. Knowl. Extr. 2026, 8(9), 279; https://doi.org/10.3390/make8090279 - 10 Sep 2026
Abstract
This study proposes an explainable artificial intelligence (XAI) engineering workflow for provider-level healthcare claim audit prioritization using SHAP-guided hybrid retrieval-augmented generation (RAG). The framework integrates provider-level claim aggregation, tree-based risk screening, SHAP explanation, exploratory group-level SHAP clustering, policy concept retrieval, and constrained large
[...] Read more.
This study proposes an explainable artificial intelligence (XAI) engineering workflow for provider-level healthcare claim audit prioritization using SHAP-guided hybrid retrieval-augmented generation (RAG). The framework integrates provider-level claim aggregation, tree-based risk screening, SHAP explanation, exploratory group-level SHAP clustering, policy concept retrieval, and constrained large language model audit narrative generation. Experiments on a public Medicare provider fraud dataset use the dataset-provided PotentialFraud label as a weak audit prioritization label rather than a legal determination of fraud. The results show that reimbursement exposure, utilization duration, claim repetition, deductible patterns, and beneficiary case mix contribute to provider-level risk scores. Additional cross-validation, calibration, threshold, and scale-confounding analyses indicate that provider size and financial exposure are important confounders, while non-scale and contextual features also retain predictive information. Beyond prediction, the framework organizes local SHAP drivers into exploratory provider archetypes and maps explanation patterns to audit-relevant policy concepts. Compared with pure embedding retrieval, the SHAP-guided hybrid retriever increases policy concept diversity and explanation alignment, although these retrieval metrics do not replace independent expert audit validation. Because the public dataset does not include referral pathways, inter-facility transfers, provider–network relationships, or care-coordination records, the framework cannot determine whether utilization patterns are explained by clinically appropriate referrals, regional access constraints, or multi-level care pathways. Its current applicability is therefore limited to provider-level audit prioritization using the available claims and beneficiary variables. The proposed system is positioned as a reproducible engineering prototype for cautious, human-reviewed audit support rather than a comprehensive or automated fraud determination system.
Full article
(This article belongs to the Special Issue Trustworthy AI: Integrating Knowledge, Retrieval, and Reasoning)
►▼
Show Figures

Figure 1
Open AccessArticle
Neural Probabilistic Relational Games (N-PRG): Learning Influence Coalitions from Cascade Data via Gradient Descent
by
Duc Nghia Vu, Thanh Huy Nguyen, Duc Thi Vu and Janos Demetrovics
Mach. Learn. Knowl. Extr. 2026, 8(9), 278; https://doi.org/10.3390/make8090278 - 9 Sep 2026
Abstract
Influence maximisation traditionally assumes that each activated neighbour contributes independently to the likelihood of a user adopting information, ignoring conjunctive synergies where a set of users must be active simultaneously to trigger another. Relational games provide a formal language for such coalitional dependencies,
[...] Read more.
Influence maximisation traditionally assumes that each activated neighbour contributes independently to the likelihood of a user adopting information, ignoring conjunctive synergies where a set of users must be active simultaneously to trigger another. Relational games provide a formal language for such coalitional dependencies, but the necessary influence hypergraph must be hand-crafted by domain experts, making them infeasible for large, dynamic social networks. We introduce the Neural Probabilistic Relational Game (N-PRG), a data-driven framework that automatically learns a probabilistic hypergraph of influence coalitions from cascade traces. A feed-forward neural network, trained via gradient descent to predict user activation, is interpreted using Deep SHAP to extract important set-level triggers. These are calibrated into a stochastic cascade model, the Probabilistic Relational Game (PRG), which generalises the Independent Cascade to set-based activation. We define the Minimal Reliable Seed Set problem, prove its NP-hardness even in the deterministic case, and establish that the expected influence function is monotone. We further demonstrate that, unlike the Independent Cascade model, the influence function under conjunctive (AND-type) hyperedges is in general not submodular, which precludes constant-factor approximation guarantees and motivates the use of greedy heuristics. Extensive experiments on synthetic data confirm that N-PRG successfully identifies coalitional interactions of size greater than one and achieves targeted out-of-sample coverage. Semi-synthetic experiments on Digg and Twitter network topologies demonstrate that N-PRG discovers seed sets up to 45% smaller than Independent Cascade baselines, while providing interpretable coalition pathways invisible to black-box methods. N-PRG thus unites the flexibility of gradient-descent learning with the structural rigour of relational games for influence analysis.
Full article
(This article belongs to the Section Network)
►▼
Show Figures

Figure 1
Open AccessReview
A Cross-Layer Review of Intelligent, Secure, and Privacy-Preserving Internet of Vehicles
by
Mohanad Alayedi and Ahmad M. Jaradat
Mach. Learn. Knowl. Extr. 2026, 8(9), 277; https://doi.org/10.3390/make8090277 - 9 Sep 2026
Abstract
The Internet of Vehicles (IoV) is revolutionizing intelligent transportation systems by ubiquitous connectivity of vehicles, roadside infrastructure, pedestrians, edge/cloud platforms, and smart-city services. With the IoV evolving towards highly connected, autonomous and data-driven mobility ecosystems, it needs to meet challenging requirements for low
[...] Read more.
The Internet of Vehicles (IoV) is revolutionizing intelligent transportation systems by ubiquitous connectivity of vehicles, roadside infrastructure, pedestrians, edge/cloud platforms, and smart-city services. With the IoV evolving towards highly connected, autonomous and data-driven mobility ecosystems, it needs to meet challenging requirements for low latency, scalability, interoperability, security, privacy and trust. This paper presents a comprehensive cross-layer approach for intelligent, secure and privacy-preserving IoV systems. It is built upon an analytical framework and systematically studies the perception, communication, edge/cloud computing, blockchain-enabled trust and application layers of IoV technologies. In addition, the paper presents an in-depth review of the enabling techniques such as machine learning (ML), deep learning (DL), reinforcement learning (RL), federated learning (FL), blockchain, cybersecurity mechanisms, digital twins, edge computing, 6G integration, and resource allocation. Moreover, it discusses the interplay and trade-offs between intelligence, security, privacy, computation, latency, and scalability. The survey also covers other significant challenges like intrusion detection, decentralized authentication, privacy-preserving learning, blockchain overhead, semantic interoperability, post-quantum security, and standardized datasets. This study is intended to serve as a structured reference for the development of scalable, trustworthy, and intelligent IoV systems by highlighting state-of-the-art techniques, open research gaps, and future directions.
Full article
(This article belongs to the Section Network)
►▼
Show Figures

Figure 1
Open AccessArticle
Reality Gap Analysis in Physics-Informed ICS Anomaly Detection: From Synthetic Validation to HAI 23.05 Real-World Testbed Evaluation
by
Dalibor Radovanovic, Dusan Markovic, Petar Kresoja, Aleksandar Sandro Cvetkovic, Vesna Radojcic, Marko Sarac and Nikola Savanovic
Mach. Learn. Knowl. Extr. 2026, 8(9), 276; https://doi.org/10.3390/make8090276 - 9 Sep 2026
Abstract
Physics-informed anomaly detection for industrial control systems (ICSs) is usually validated on synthetic data. How much of that performance survives on real hardware-in-the-loop (HIL) data is an open question. We re-implement PhySec-Edge, a hybrid BiLSTM/β-VAE/GAT/Kalman pipeline, as a full architecture and evaluate it
[...] Read more.
Physics-informed anomaly detection for industrial control systems (ICSs) is usually validated on synthetic data. How much of that performance survives on real hardware-in-the-loop (HIL) data is an open question. We re-implement PhySec-Edge, a hybrid BiLSTM/β-VAE/GAT/Kalman pipeline, as a full architecture and evaluate it on HAI 23.05. The gap is consistent across five seeds. AI-only F1 falls from 0.774 (synthetic) to 0.525 (HAI); the full hybrid falls from 0.798 to 0.512. The components diverge. PVE residual sharing transfers but weakens on real data (ΔF1 = +0.010 ± 0.008 across five seeds against +0.017 synthetic; ΔMCC = +0.013, positive in every seed). The PVE NIS decision score fails outright (raw FPR = 0.482; a correction brings it to 0.013, but detection does not recover). Under the retrospective fixed-FPR comparison, the preferred configuration is GNN+BiLSTM (F1 = 0.530 ± 0.002), outperforming full-EADE fusion (0.512 ± 0.003). From this split we derive the information-vs-decision pathway distinction, a way to reason about component-level generalization in hybrid architectures. We then set out what it means for physics-informed ICS detector design and edge deployment.
Full article
(This article belongs to the Special Issue From Experimental AI to Industrial Decision Systems)
►▼
Show Figures

Graphical abstract
Open AccessArticle
One Reflex, Two Answers: Model Judges Weakly Discriminate Localized from Distributed Causes in Agent Failure Attribution
by
Brian Scavotto
Mach. Learn. Knowl. Extr. 2026, 8(9), 275; https://doi.org/10.3390/make8090275 - 8 Sep 2026
Abstract
When an autonomous language-model agent fails, a growing body of work hands the diagnosis to a large language model (LLM) that reads the trace and names the responsible step. We ask whether this attribution separates two causes, a localized corruption from one bad
[...] Read more.
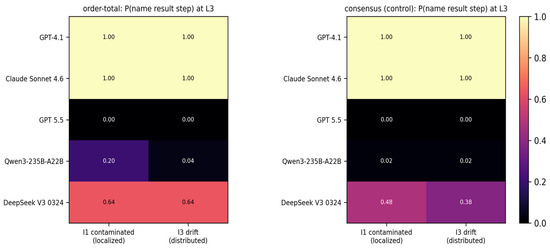
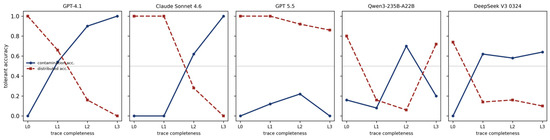
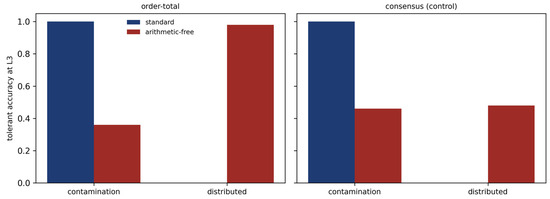
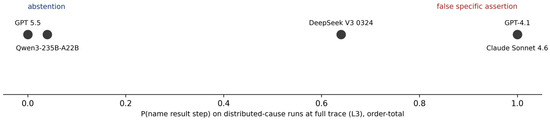
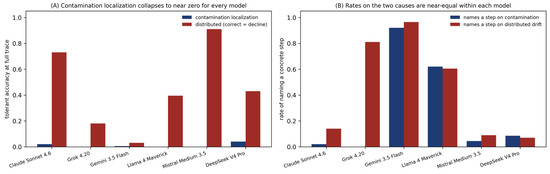
When an autonomous language-model agent fails, a growing body of work hands the diagnosis to a large language model (LLM) that reads the trace and names the responsible step. We ask whether this attribution separates two causes, a localized corruption from one bad input and a distributed degradation across many steps. Using controlled fault injection across two agent tasks, four trace-completeness levels and ten judges, we find discrimination weak wherever the causes are demonstrably identifiable from the trace. Most judges apply one propensity, naming the step that produced the result, so their two per-class accuracies become readouts of one number whose margin stays near zero. Two frontier models produce results consistent with opposite ends of that axis, one asserting an inconsistency the trace does not contain, the other abstaining. On the realistic task four of six judges invert, naming a concrete step more often on the distributed cause than on the localized one. The limit is not incapacity. Where contradicting the trace takes only a comparison the same judge localizes the fault in fifty of fifty runs, against one of fifty where it would take arithmetic and zero of fifty where the trace is consistent, and a 2500-fold sweep of fault magnitude leaves the margin unchanged. A deterministic non-model rule separates the causes on the main-panel traces, where no judge under the standard prompt exceeds 0.16 at full detail; one prompt intervention lifts the margin to 0.34. We read this as a reliability caution for LLM-as-judge attribution across the models, prompts, and constructed tasks evaluated here.
Full article
(This article belongs to the Section Learning)
►▼
Show Figures

Figure 1
Open AccessArticle
Accelerated LLM: A Fuzzy-Logic-Augmented Router Architecture for Efficient Multi-Domain Query Processing via Specialised Small Language Models
by
Kushagra Agrawal, Deshmukh Nirmiti Akshay, Palak Kaushik, Shaveta Jain, Ganga Sharma and Sumendra Yogarayan
Mach. Learn. Knowl. Extr. 2026, 8(9), 274; https://doi.org/10.3390/make8090274 - 7 Sep 2026
Abstract
Large language models (LLMs) incur prohibitive computational costs when deployed as monolithic systems for multi-domain query processing. This paper proposes Accelerated LLM, a modular architecture that replaces a single general-purpose LLM with an ensemble of task-specialised small language models (SLMs) governed by a
[...] Read more.
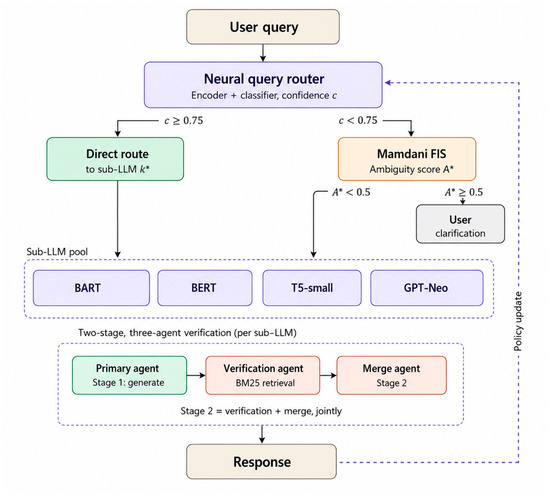
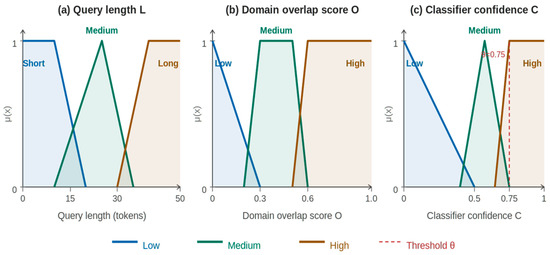
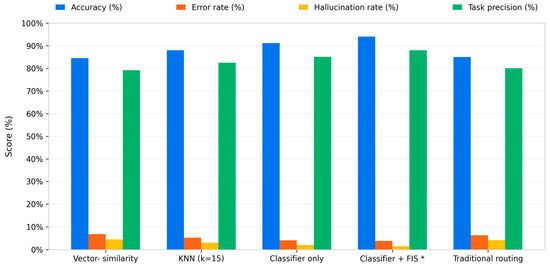
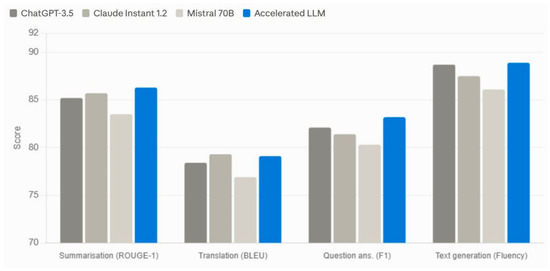
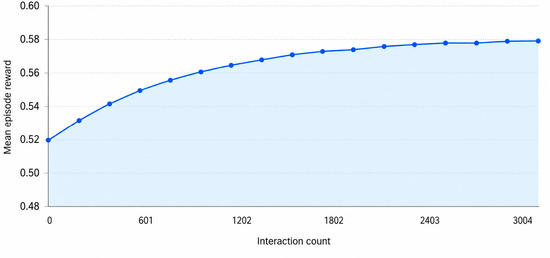
Large language models (LLMs) incur prohibitive computational costs when deployed as monolithic systems for multi-domain query processing. This paper proposes Accelerated LLM, a modular architecture that replaces a single general-purpose LLM with an ensemble of task-specialised small language models (SLMs) governed by a neural query router and a Mamdani fuzzy inference system. The router embeds each user query using a frozen sentence encoder and classifies it across four task domains—summarisation, translation, question answering, and text generation—routing confident queries directly to the corresponding SLM. Ambiguous queries are escalated to a three-input fuzzy logic system operating on Query Length, inter-Domain Overlap Score, and Classifier Confidence, enabling principled handling of imprecise inputs. A reinforcement-learning feedback loop, validated through a controlled pilot deployment, continuously refines the routing policy. The complete pipeline, including the sentence encoder, totals approximately 2.14 billion parameters—a 98.8% reduction relative to GPT-3.5 (175 B). The integration of fuzzy logic into the routing stage raises classification accuracy from 91.5% to 94.3% and reduces the hallucination rate to 9.8% (minor) and 6.4% (major). Evaluated on healthcare-augmented benchmarks against ChatGPT-3.5, Claude, Mistral 70B, and two contemporary compact models (GPT-4o-mini and Llama 3.1-8B-Instruct), Accelerated LLM achieves competitive or superior task-specific performance at a fraction of the parameter count. A small-scale pilot evaluation in the legal domain indicates that the routing and fuzzy logic components retain partial effectiveness beyond the primary healthcare setting, though full multi-domain validation remains future work.
Full article
(This article belongs to the Topic Applications of NLP, AI, and ML in Software Engineering)
►▼
Show Figures

Figure 1
Open AccessArticle
A Multi-Scale Fractal Feature Extraction Method for CNN-Based Plant Disease Classification
by
Egor Savchenko and Anna Maslovskaya
Mach. Learn. Knowl. Extr. 2026, 8(9), 273; https://doi.org/10.3390/make8090273 - 7 Sep 2026
Abstract
Plant diseases, being a subject of interdisciplinary research, significantly reduce crop yield, quality, and economic returns, while the misidentification of pathogens often leads to ineffective treatments and may harm beneficial organisms and ecosystems. This work develops an approach for robust visual classification of
[...] Read more.
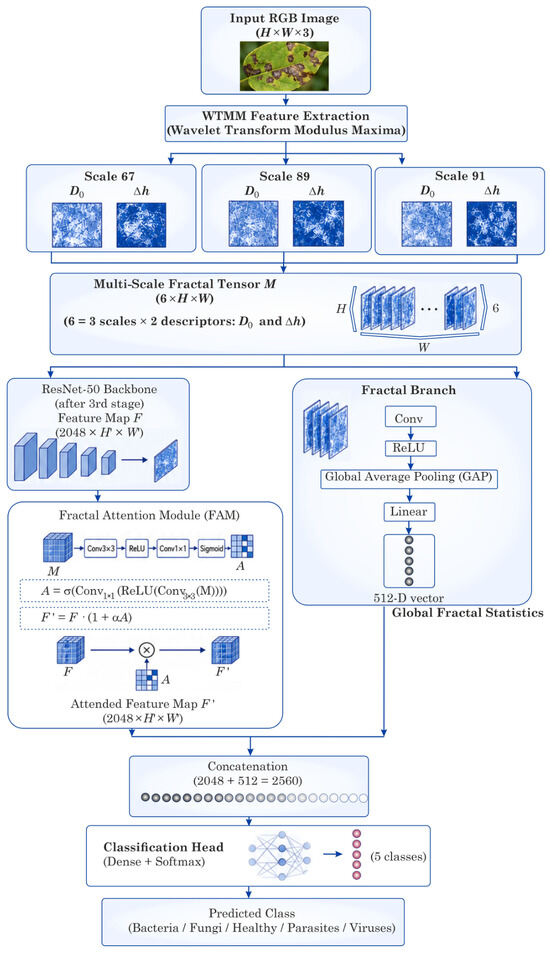
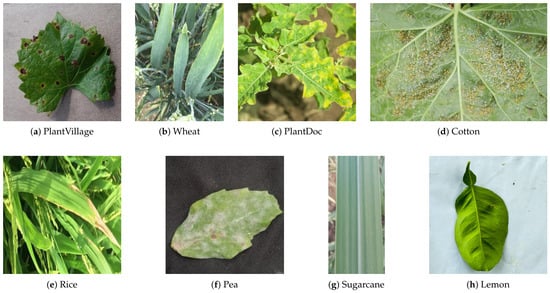
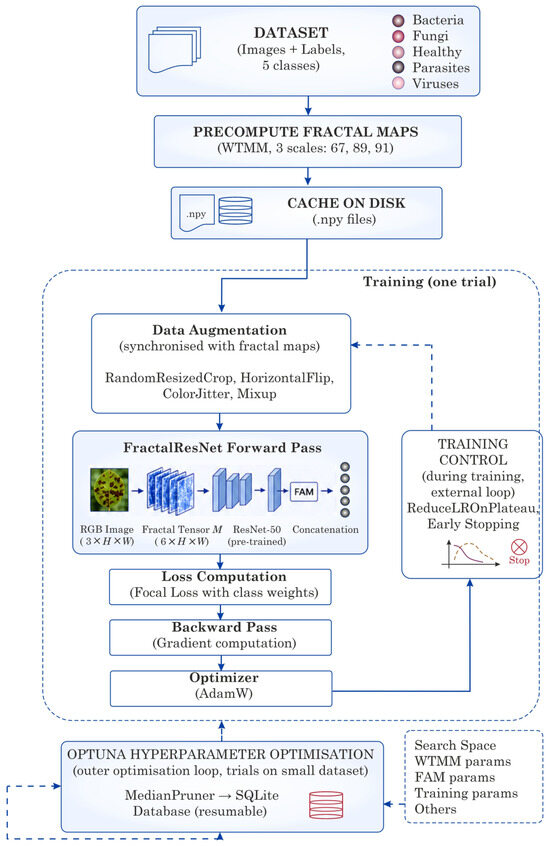
Plant diseases, being a subject of interdisciplinary research, significantly reduce crop yield, quality, and economic returns, while the misidentification of pathogens often leads to ineffective treatments and may harm beneficial organisms and ecosystems. This work develops an approach for robust visual classification of plant diseases under limited and heterogeneous data based on multi-scale fractal texture descriptors integrated into a convolutional neural network. The proposed method employs wavelet transform modulus maxima to extract two complementary fractal characteristics, local fractal dimension and singularity spectrum width, from leaf images at several spatial scales. These descriptors form multi-channel fractal maps fed into a fractal attention module (FAM) inserted after the third stage of a ResNet-50 architecture. The FAM learns to emphasize spatial regions where fractal properties are most discriminative, while a parallel branch encodes global fractal statistics into an auxiliary vector combined with backbone features at the final classification layer. Experiments are conducted on a large heterogeneous collection of 11 public plant disease datasets under 5-shot, 50-shot, and full-scale training regimes. The fractal-augmented model raises classification accuracy from 57.06% to 67.73% on 5 shots and from 80.81% to 86.11% on 50 shots, red outperforming the plain ResNet-50 in these settings, converges within 1–2 epochs versus 25–40, and shows markedly better resilience to color distortions, random occlusions, and grayscale conversion in most cases. The generated attention maps provide spatially explicit explanations of the model’s decisions, increasing transparency for practical use. The proposed approach demonstrates that fractal analysis, embedded as a modulating signal inside a deep network, can serve as an efficient and interpretable inductive bias, which is particularly valuable under data scarcity and noisy agricultural imagery.
Full article
(This article belongs to the Special Issue Artificial Intelligence for Signal, Image, and Multimodal Data Processing: Algorithms, Models, and Knowledge Extraction)
►▼
Show Figures

Figure 1
Open AccessArticle
Algorithmic Diffusion on YouTube: A Machine Learning Analysis of Channel-Level Information Spread and Its Cross-Platform Generalisability
by
Dana Tyulemissova, Aigul Shaikhanova, Oleksandr Kuznetsov, Aigerim Sambetova, Kainizhamal Iklassova and Aisanim Sarsenbayeva
Mach. Learn. Knowl. Extr. 2026, 8(9), 272; https://doi.org/10.3390/make8090272 - 6 Sep 2026
Abstract
(1) Background: Information diffusion models developed for graph-based platforms such as Reddit and broadcast architectures such as Telegram identify temporal features—particularly the timing of peak spread—as dominant predictors of coverage. Whether these predictors generalise to platforms where content is distributed through algorithmic recommendation
[...] Read more.
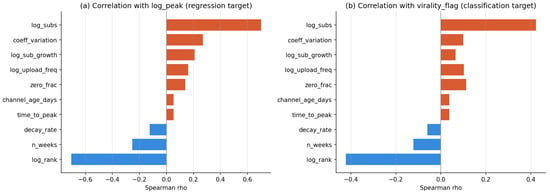
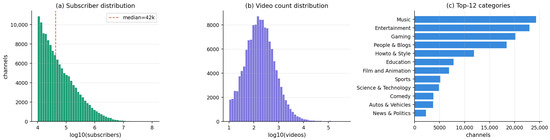
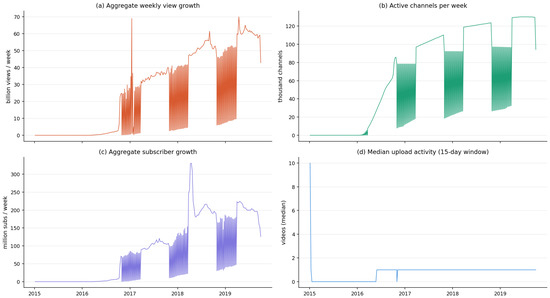
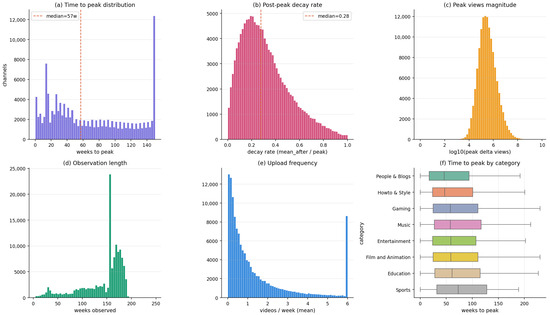
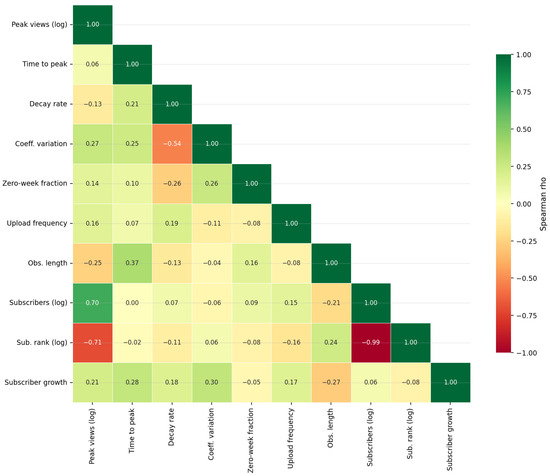
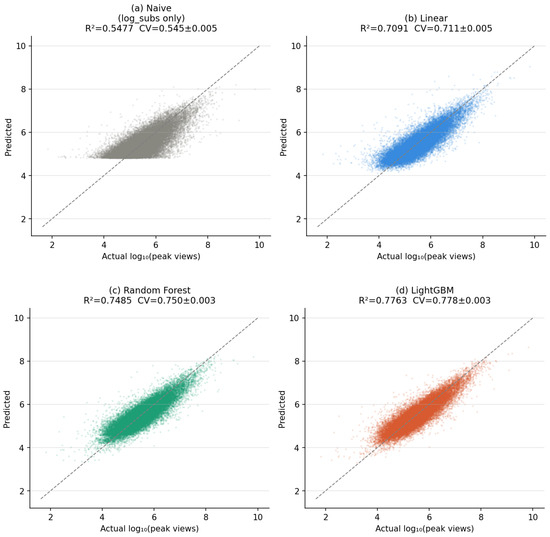
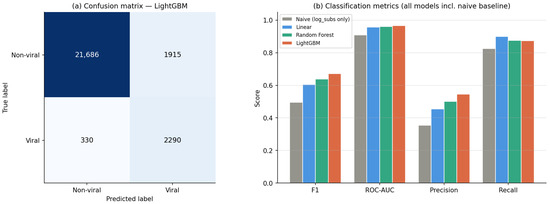
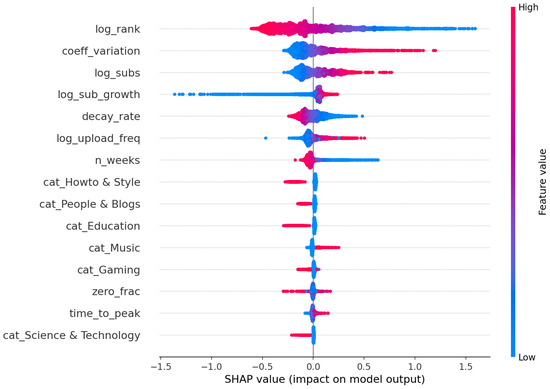
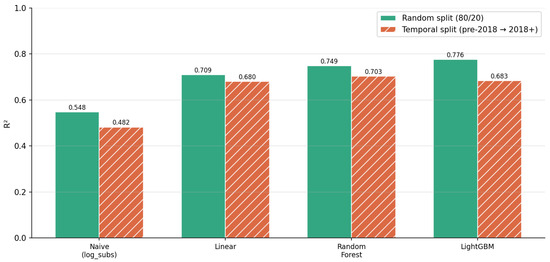
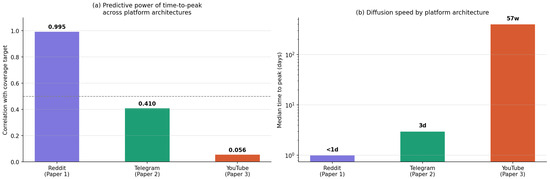
(1) Background: Information diffusion models developed for graph-based platforms such as Reddit and broadcast architectures such as Telegram identify temporal features—particularly the timing of peak spread—as dominant predictors of coverage. Whether these predictors generalise to platforms where content is distributed through algorithmic recommendation rather than social-graph contagion remains an open question. (2) Methods: We analyse the YouNiverse dataset, comprising 133,364 English-language YouTube channels observed weekly from January 2015 to September 2019 (18.9 million observations). We derive channel-level diffusion features—including time-to-peak, post-peak decay rate, diffusion volatility, and upload frequency—and train three machine learning models (Linear Regression, Random Forest, and LightGBM) on two tasks: predicting peak weekly view growth (regression) and identifying viral channels (classification). A single-feature naive baseline (subscriber count alone) establishes the marginal contribution of the broader feature set beyond subscriber count alone, and a temporal split experiment (training on channels peaking before 2018, testing on 2018–2019) assesses cross-temporal stability. Because subscriber count and subscriber rank are measured at the October 2019 crawl, this is a retrospective characterisation rather than a strict real-time forecasting design. (3) Results: LightGBM achieves (5-fold CV: ) compared with for the naive baseline, a net gain of . Because subscriber rank and subscriber count are near-perfectly collinear, we interpret them jointly as a channel-size dimension (42.2% of total mean absolute SHAP attribution), rather than as independent effects. Time-to-peak ranks fourteenth (1.1%), in contrast to its dominant role on Reddit ( , rank #1). For virality classification, LightGBM achieves ROC-AUC . Under the temporal split, Random Forest ( ) outperforms LightGBM ( ), showing greater cross-temporal stability within this retrospective split. (4) Conclusions: Within the 2015–2019 data, the results are consistent with algorithmic recommendation weakening the relationship between temporal diffusion dynamics and coverage magnitude at the channel level. Time-to-peak is weakly informative in this setting, while generalisation to the current recommendation system requires validation on newer data.
Full article
(This article belongs to the Section Learning)
►▼
Show Figures

Figure 1
Open AccessReview
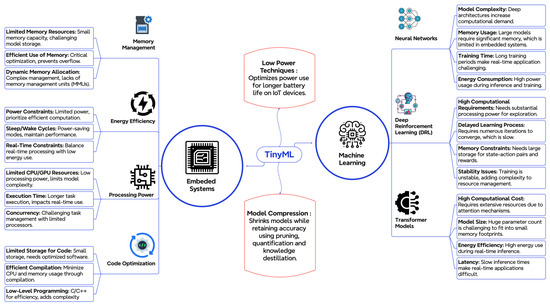
A Review of TinyML for Human Activity Recognition on Edge Devices
by
Ismail Lamaakal, Chaymae Yahyati, Yassine Maleh, Khalid El Makkaoui and Ibrahim Ouahbi
Mach. Learn. Knowl. Extr. 2026, 8(9), 271; https://doi.org/10.3390/make8090271 - 5 Sep 2026
Abstract
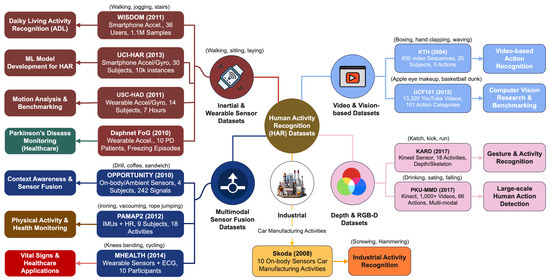
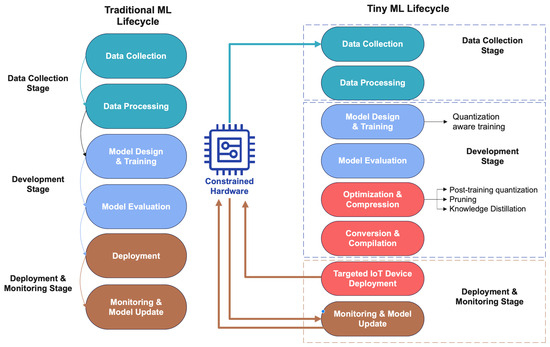
The integration of Tiny Machine Learning (TinyML) into human activity recognition (HAR) represents a paradigm shift in artificial intelligence, enabling real-time, efficient, and privacy-preserving analysis on resource-constrained edge devices. This paper presents a comprehensive review of TinyML for HAR, covering foundational concepts, methodologies,
[...] Read more.
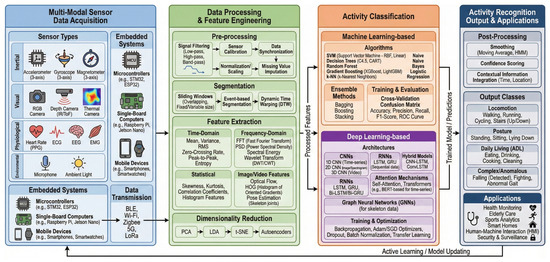
The integration of Tiny Machine Learning (TinyML) into human activity recognition (HAR) represents a paradigm shift in artificial intelligence, enabling real-time, efficient, and privacy-preserving analysis on resource-constrained edge devices. This paper presents a comprehensive review of TinyML for HAR, covering foundational concepts, methodologies, and applications. the review examines the state of the art of existing works and approaches that combine TinyML and HAR, providing a detailed review and comparison of models, algorithms, and frameworks. This comparison sheds light on the effectiveness and limitations of different methodologies. Key contributions include a systematic taxonomy of HAR systems leveraging TinyML, a detailed analysis of optimization techniques like pruning, quantization, and knowledge distillation, and insights into state-of-the-art frameworks and datasets. Challenges such as scalability, energy efficiency, and generalization to diverse environments are critically examined, alongside solutions like federated learning, multimodal data fusion, the integration of generative AI, neuromorphic hardware, 5G/6G and Internet Of Things (IoT) connectivity, which are highlighted as transformative enablers for advancing HAR applications. This review serves as a foundational resource for researchers and practitioners aiming to harness TinyML’s potential in activity recognition systems.
Full article
(This article belongs to the Section Safety, Security, Privacy, and Cyber Resilience)
►▼
Show Figures

Figure 1
Open AccessArticle
Hallucinations in Structured Extraction: A Case Study on Prompt-Based Semantic Role Labeling
by
Ioannis Kazlaris, Konstantinos Diamantaras, Efstathios Antoniou and Charalampos Bratsas
Mach. Learn. Knowl. Extr. 2026, 8(9), 270; https://doi.org/10.3390/make8090270 - 4 Sep 2026
Abstract
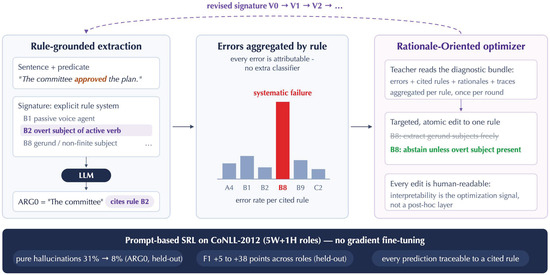
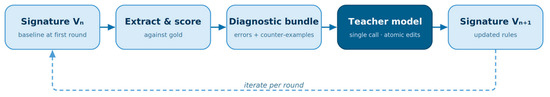
This paper studies hallucinations in structured extraction using prompt-based Semantic Role Labeling (SRL) as a controlled case study. We implement a DSPy-based pipeline in which each prediction includes a generated rationale and a citation to a governing rule, allowing extraction errors to be
[...] Read more.
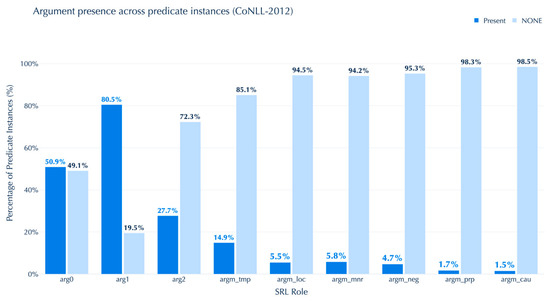
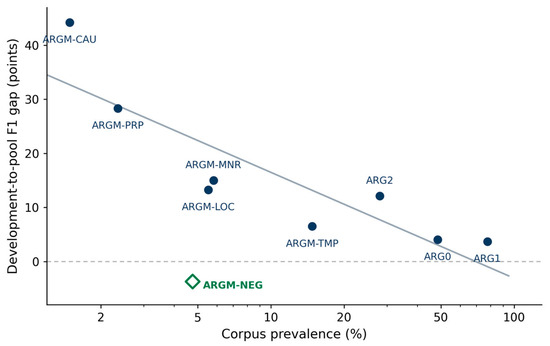
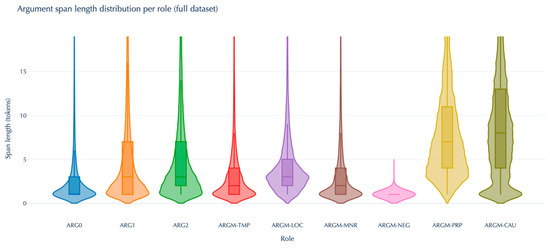
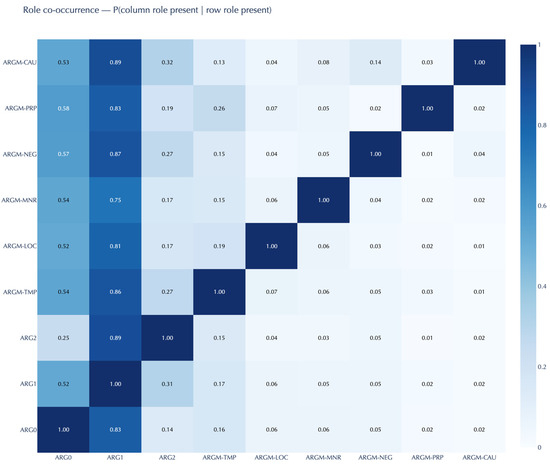
This paper studies hallucinations in structured extraction using prompt-based Semantic Role Labeling (SRL) as a controlled case study. We implement a DSPy-based pipeline in which each prediction includes a generated rationale and a citation to a governing rule, allowing extraction errors to be aggregated by attributed rule. This diagnostic signal is used by a Rationale-Oriented (RO) optimizer to perform targeted, human-readable signature revisions. Experiments use a representative 1000-sentence pool drawn from the CoNLL-2012 test split, with a nested 200-sentence development subset used for optimization and the remaining 800 sentences reserved as an unseen subset. After signature selection, the role-specific signatures are fixed; on the disjoint unseen subset, they improve over their corresponding unoptimized baselines for all nine evaluated 5W + 1H-aligned roles, although the magnitude of improvement and the development-to-held-out gap vary substantially by role, with the sparse ARGM-PRP and ARGM-CAU roles generalizing markedly less well than their development scores suggest. Across the full 1000-sentence pool, the selected-role, gold-predicate aggregate reaches 67.04% strict micro-F1; this is a within-study summary and not a full CoNLL SRL score. In the held-out ARG0 analysis, extraction outcomes are non-uniformly associated with cited rules, while signature perturbations show that rule citations are better interpreted as observable diagnostic proxies than as faithful per-instance causal explanations. Compared against MIPROv2 on the same extraction model, RO reaches a comparably low commission-error operating point without the recall collapse MIPROv2 incurs. Two further ablations locate the source of the effect: a full nine-role cross-model transfer to Phi-4-reasoning shows RO signatures carrying across model families unevenly, with gains concentrated on the weak, sparse roles and negligible-to-slightly-negative where the target model is already competent, and with transferred precision capped by its coarser span-boundary behavior; and a matched same-model self-critique ablation, in which Qwen3-14B supplies its own diagnostic feedback across the same nine roles, tests how much of the refinement effect can be recovered without a stronger external critic. Seen together, these ablations separate cross-model signature portability from teacher-capacity effects and clarify which parts of RO depend on the diagnostic structure itself versus the critic used to revise the signatures. The primary condition retains a design-time dependence on a proprietary teacher, and signature optimization is centered on a single open-weight extraction model, Qwen3-14B.
Full article
(This article belongs to the Special Issue Trustworthy AI: Integrating Knowledge, Retrieval, and Reasoning)
►▼
Show Figures

Graphical abstract
Open AccessArticle
STRATA-HeadQuotient: Functional Localization of One Quarter of Global KV Heads with Typed Predicate-Graph Computation at 8192-Token Context
by
Nurgali Kadyrbek and Madina Mansurova
Mach. Learn. Knowl. Extr. 2026, 8(9), 269; https://doi.org/10.3390/make8090269 - 4 Sep 2026
Abstract
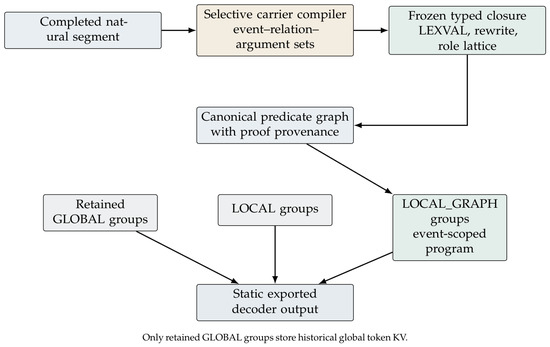
Global attention combines long-range lexical access with semantic-relation retrieval, making whole-layer replacement lossy. We present Strata-HeadQuotient, which statically assigns each key–value (KV) head to full-history attention (GLOBAL), 1024-token attention (LOCAL), or local attention plus an event-scoped typed graph read (LOCAL_GRAPH).
[...] Read more.
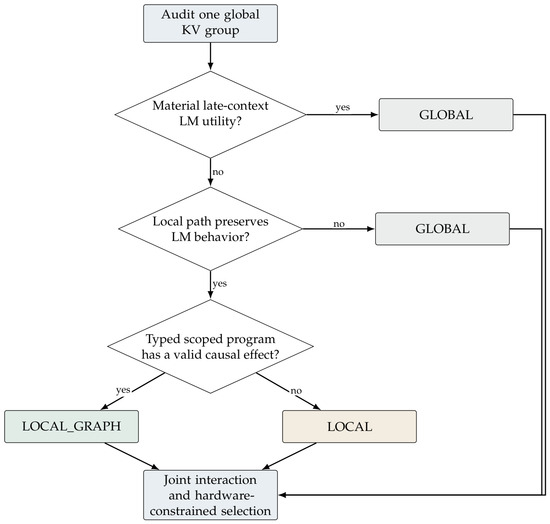
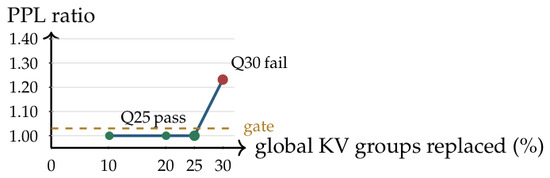
Global attention combines long-range lexical access with semantic-relation retrieval, making whole-layer replacement lossy. We present Strata-HeadQuotient, which statically assigns each key–value (KV) head to full-history attention (GLOBAL), 1024-token attention (LOCAL), or local attention plus an event-scoped typed graph read (LOCAL_GRAPH). For a 24-layer, 16-head decoder, we audited 384 heads and all 6903 pairs among 118 candidates before constrained subset selection. The Q25 export localized 96/384 heads: 81 were LOCAL and 15 were LOCAL_GRAPH. On 470 document-disjoint 8192-token windows (3.85 million tokens), graph-disabled Q25 perplexity was 1.00146× dense (95% document-bootstrap interval: 1.00131–1.00161); the 4096–8191-token ratio was 1.00201. On an untouched 2000-case semantic test, typed execution was 1998/2000, versus 374/2000 for a capacity-matched untyped graph. Two fresh adaptation/selection runs reproduced both directions, although every matched-capacity marginal graph-effect interval included zero. Q25 retained 78.125% of token-KV bytes and 98.44% of dense full-sequence throughput; a tested Q30 export failed. Thus, interaction-aware localization preserved 8192-token language-model quality, while a separate typed path controlled event-role behavior. The experiment does not establish that graph computation caused perplexity preservation.
Full article
(This article belongs to the Special Issue Trustworthy AI: Integrating Knowledge, Retrieval, and Reasoning)
►▼
Show Figures

Figure 1
Open AccessArticle
Queue-Scheduled Multi-Fidelity Bayesian Optimisation with Cross-Fidelity Anomaly Resolution for Laboratory Deployment
by
Kishan Kartha and Alex James
Mach. Learn. Knowl. Extr. 2026, 8(9), 268; https://doi.org/10.3390/make8090268 - 3 Sep 2026
Abstract
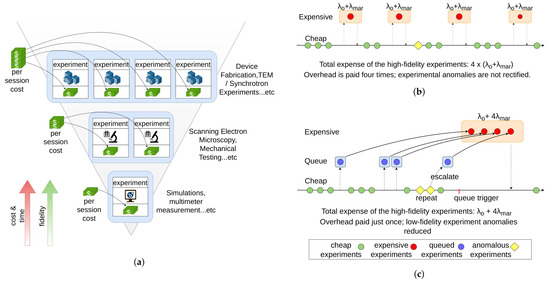
Laboratory experimentation is shaped by practical constraints, so computational frameworks built for offline settings do not transfer cleanly to an online laboratory routine. Two mismatches dominate. First, they assume on-demand access to high-fidelity facilities, whereas characterisation, fabrication, and testing are rarely economical one
[...] Read more.
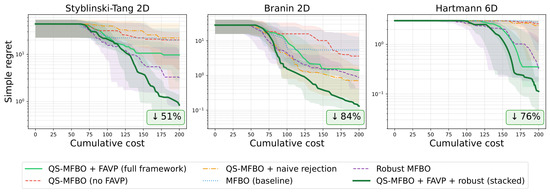
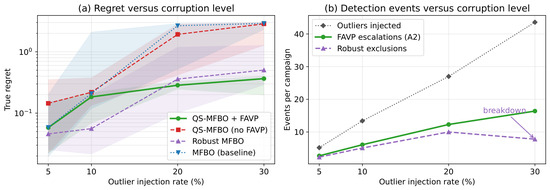
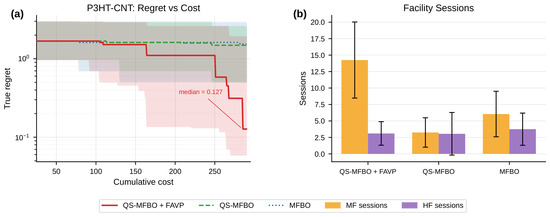
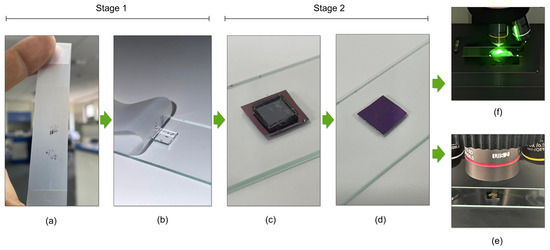
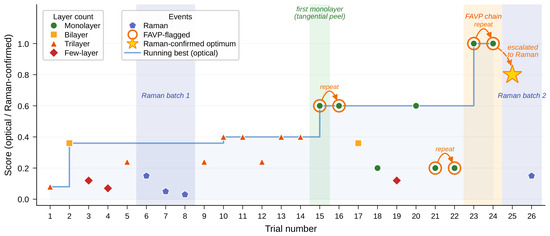
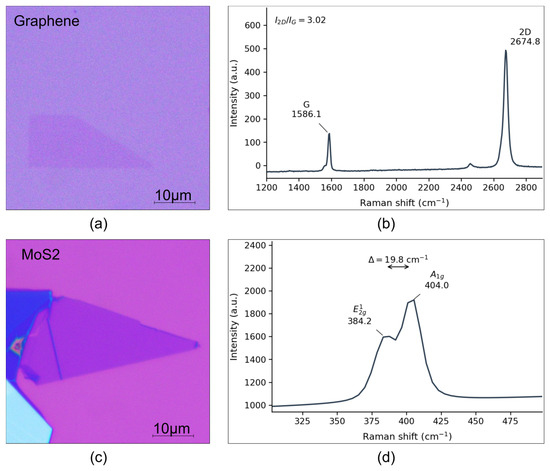
Laboratory experimentation is shaped by practical constraints, so computational frameworks built for offline settings do not transfer cleanly to an online laboratory routine. Two mismatches dominate. First, they assume on-demand access to high-fidelity facilities, whereas characterisation, fabrication, and testing are rarely economical one sample at a time. Second, experiments produce occasional catastrophic, non-Gaussian errors that a fixed noise model handles poorly. Here, we introduce a coupled scheduling-and-verification layer that wraps a multi-fidelity optimiser. A queue scheduler models per-session overheads and batches expensive measurements to amortise them; a Fidelity-Aware Verification Protocol repeats suspect observations and escalates unresolved ones to a higher fidelity. The two share the same cost-amortised queue, so a verification escalation is dispatched as just another queued sample, and anomaly handling reinforces batching rather than competing with it. On synthetic functions, the layer reduces overhead-incurring sessions by 28–43% and, under catastrophic outliers, cuts regret by 51–84%. On a real three-fidelity materials dataset, it improves cost-efficiency and robustness. In a live deployment on polydimethylsiloxane-mediated 2D material transfer, it reached Raman-confirmed monolayer graphene in 26 trials using only two Raman sessions, and those discovered parameters transferred another 2D material, monolayer molybdenum disulphide, on the first attempt.
Full article
(This article belongs to the Topic AI and Computational Methods for Modelling, Simulations and Optimizing of Advanced Systems: Innovations in Complexity, 2nd Edition)
►▼
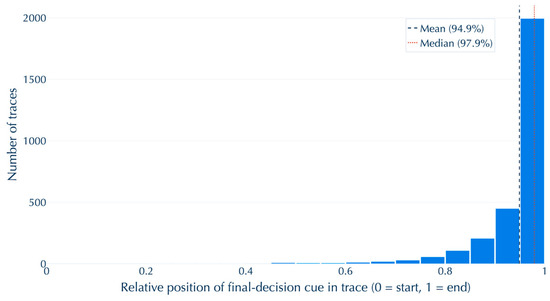
Show Figures

Figure 1
Open AccessArticle
Physics Structure-Informed Neural Networks in the TinyML Pipeline: Antisymmetry Preservation, Deployment Accounting, and Training-Budget Sensitivity
by
Sorin Liviu Jurj
Mach. Learn. Knowl. Extr. 2026, 8(9), 267; https://doi.org/10.3390/make8090267 - 1 Sep 2026
Abstract
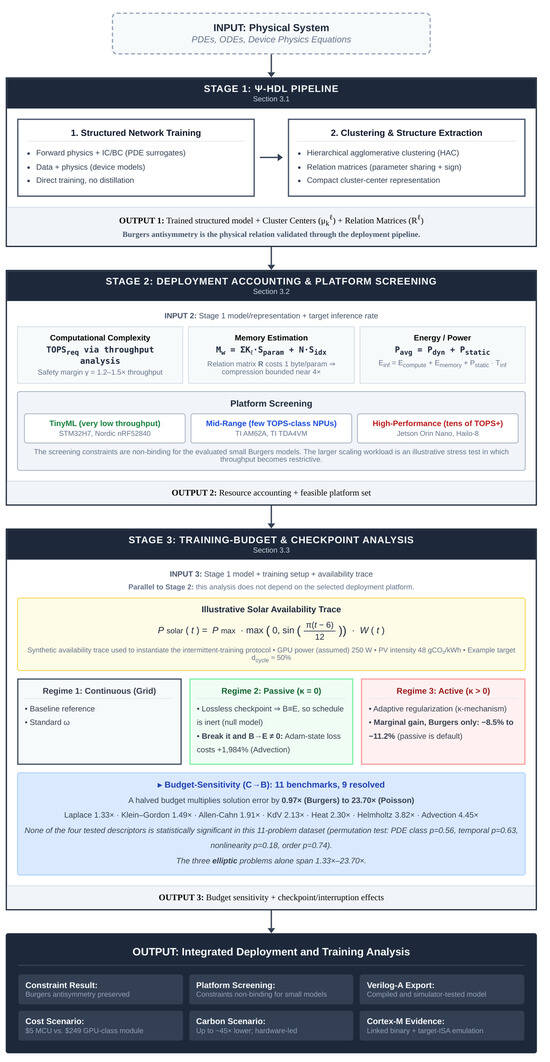
Physics structure-informed neural networks ( -NN) promise to carry known physical relations into compact models, but tiny machine learning (TinyML) deployment adds compression, finite precision, compilation, and hardware constraints that can change how those benefits appear in practice. We study this end
[...] Read more.
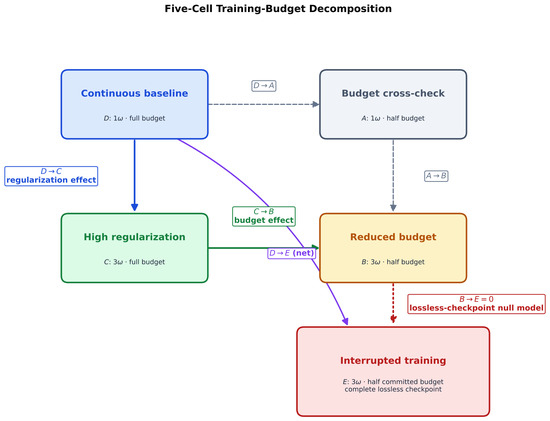
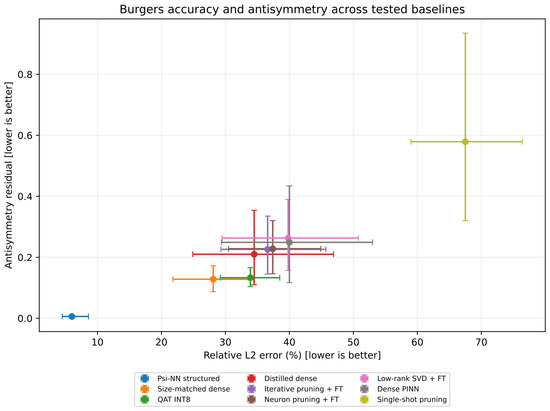
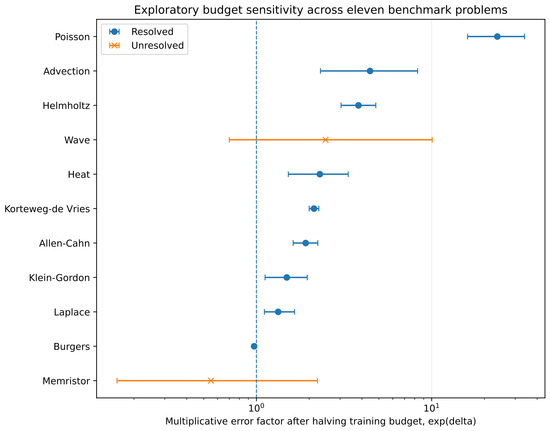
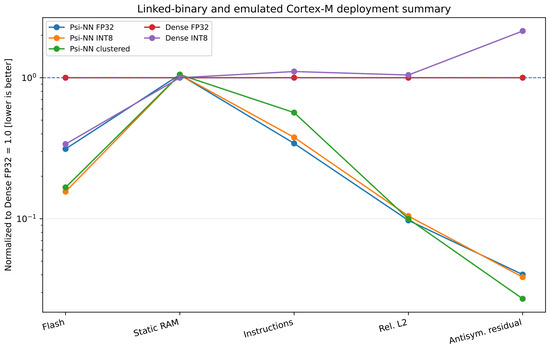
Physics structure-informed neural networks ( -NN) promise to carry known physical relations into compact models, but tiny machine learning (TinyML) deployment adds compression, finite precision, compilation, and hardware constraints that can change how those benefits appear in practice. We study this end to end for Burgers odd-in-x antisymmetry. A -NN preserves the encoded relation through clustering, 8-bit integer (INT8) quantization, compilation, and Cortex-M target-instruction-set emulation, achieving 6.0% relative error and an antisymmetry residual of 0.006; none of seven evaluated compression baselines matches both under the common protocol. Deployment accounting reveals a complementary result. Centroid count is not deployable memory because the relation/index table must also be stored, limiting 32-bit floating-point (FP32) weight-memory reduction to about under one-byte indexing. At matched parameter count, structured and dense models have comparable flash and instruction requirements, so structure improves Burgers accuracy and antisymmetry at a given footprint rather than automatically shrinking hardware requirements. Under complete lossless checkpointing, interruption timing has no independent effect, while budget loss and checkpoint degradation govern robustness. In the eleven-problem dataset, none of four tested descriptors reaches statistical significance for budget sensitivity. These results separate what physics structure preserves from what TinyML deployment must measure explicitly.
Full article
(This article belongs to the Special Issue Next-Generation TinyML: Innovations in Models, Security, and Applications for Constrained Intelligent Systems)
►▼
Show Figures

Figure 1
Highly Accessed Articles
Latest Books
E-Mail Alert
News
10 September 2026
The 2026 3rd International Conference on Digital Media, Communication and Information Systems (DMCIS 2026), 23–25 October 2026, Busan, South Korea
9 September 2026
Meet Us at the 2026 2nd International Conference on Medical Robotics and Artificial Intelligence (CMRAI 2026), 16–18 October 2026, Chengdu, China
Topics
Topic in
AI, MAKE, Robotics, Sensors, Electronics
Deep Visual Recognition: Methods, and Applications
Topic Editors: Min Young Kim, Francisco Gomez-DonosoDeadline: 30 October 2026
Topic in
Entropy, IJMS, International Journal of Topology, MAKE, Mathematics, Quantum Reports, Symmetry
Topological, Quantum, and Molecular Information Approaches to Computation and Intelligence
Topic Editors: Michel Planat, Edward A. RietmanDeadline: 31 December 2026
Topic in
AI, Computers, Electronics, Information, MAKE, Signals
Recent Advances in Label Distribution Learning
Topic Editors: Xin Geng, Ning Xu, Liangxiao JiangDeadline: 31 January 2027
Topic in
Electronics, MAKE, Sensors, Applied Sciences, J. Imaging
Applied Computer Vision and Pattern Recognition: 3rd Edition
Topic Editors: Antonio Fernández-Caballero, Byung-Gyu KimDeadline: 28 February 2027
Conferences
Special Issues
Special Issue in
MAKE
Clinically Robust and Transparent AI-Assisted Medical Diagnostics: From Learning Dynamics to Real-World Deployment
Guest Editors: Milan Toma, Constantinos PattichisDeadline: 30 September 2026
Special Issue in
MAKE
Selected Papers from the International Conference on Advances in Artificial Intelligence and Machine Learning (AAIML 2026)
Guest Editors: Naoyuki Ishimura, Irena SpasićDeadline: 30 September 2026
Special Issue in
MAKE
Artificial Intelligence for Signal, Image, and Multimodal Data Processing: Algorithms, Models, and Knowledge Extraction
Guest Editors: Omneya Attallah, Sahar Selim, Lobna A. SaidDeadline: 15 October 2026
Special Issue in
MAKE
Knowledge Discovery and Extraction with Large Language Models, Retrieval-Augmented Generation, and Autonomous Agents: Methods, Architectures, and Applications
Guest Editors: Shaheen Khatoon, Azhar Mahmood, Marek SikoraDeadline: 31 December 2026
Topical Collections
Topical Collection in
MAKE
Extravaganza Feature Papers on Hot Topics in Machine Learning and Knowledge Extraction
Collection Editor: Andreas Holzinger
Topical Collection in
MAKE
Feature Papers in Safety, Security, Privacy, and Cyber Resilience
Collection Editor: Simon Tjoa
Topical Collection in
MAKE
Robust and Uncertainty-Aware Learning from Real-World Data
Collection Editors: Federico Cabitza, Andrea Campagner