1. Introduction
Genomic research has long been anchored to a single linear reference genome as the cornerstone for understanding a species’ genetic makeup. While this method has significantly advanced our comprehension of genetic variation and function, it has limitations, particularly when studying species with significant structural variation, diverse populations, or non-model organisms. By its very nature, the linear reference favors the person or individuals from where it originated and cannot fully reflect the range of genetic variability within a species. This insight has led to a paradigm change in pangenomics, which aims to fully characterize and evaluate a species’ or clade’s whole genetic repertoire [
1]. The pangenome concept, initially introduced in microbiology, refers to the complete set of genes present across all individuals of a species [
2]. It includes core genes shared by all individuals, accessory genes found in some individuals, and unique genes present in only one or a few individuals. This model has since expanded beyond gene-level content to include structural and copy-number variation, as well as coding elements at the nucleotide level. For instance, pangenome graphs have been successfully applied to resolve complex structural variations in the human HLA region [
3] and to characterize the extensive accessory genomes in bacterial species like Streptococcus [
4]. However, representing this complex diversity in a meaningful, computationally tractable format poses significant challenges. Pangenome graphs have emerged as a potent solution to this challenge. Unlike linear references, these graphs encode multiple genome sequences as paths through a graph structure. Nodes in the graph typically represent sequences or variants, and edges encode connections between them, capturing alternative alleles, rearrangements, and insertions in a unified framework. This unique approach not only unlocks the potential for unbiased read mapping, more accurate variant discovery, and deeper insights into evolutionary dynamics but also holds the promise of revolutionizing genomics research in the future.
In the past five years, advances in long-read sequencing technologies, high-quality genome assemblies, and efficient graph algorithms have enabled the widespread adoption of graph-based pangenomics. These advancements have been made possible by significant collaborative efforts such as the Human Pangenome Reference Consortium (HPRC) [
5], Vertebrate Genomes Project (VGP) [
6], and Earth BioGenome Project (EBP) [
7]. These initiatives have accelerated the generation of high-contiguity, phased genome assemblies, reflecting the collective efforts of the scientific community in advancing pangenome research.
At the same time, the bioinformatics community has observed a rapidly expanding ecosystem of tools for creating, querying, visualizing, and evaluating pangenome graphs. These tools frequently use contemporary data structures, cloud computing, and graph theory and are always changing to accommodate the large volume and complexity of new data in big data ecosystems. This dynamic environment, characterized by constant innovation and adaptation, is a testament to the excitement and progress in the field, keeping researchers engaged and excited about the future of pangenome research.
This review provides a comprehensive overview of recent pangenome graph research and development trends. We summarize the theoretical underpinnings of pangenome graphs, review the current landscape of software tools, and highlight emerging applications across evolutionary biology, medical genetics, and population genomics. We also discuss the field’s key challenges and open problems, and we outline promising future research and tool development directions.
Scope and Review Methodology
The main objective of this review is to synthesize the rapidly expanding ecosystem of graph-based pangenomics, focusing on the transition from linear reference models to multidimensional graph architectures. To ensure a systematic and detailed review of the field, the following scope and methodology were applied.
The selection of the literature, software, and biological applications for this review was governed by three primary criteria:
Temporal Scope: This review prioritizes advancements made within the past five years (2020–2025), a period distinguished by a marked escalation in high-quality genome assemblies and long-read sequencing technologies.
Tool Selection: We focus on high-performance, scalable bioinformatics toolkits that have achieved extensive adoption or represent significant methodological shifts. These include construction pipelines (e.g., Minigraph–Cactus, PGGB), indexing solutions (GBWT, ODGI), and graph-aware mappers (VG Giraffe, GraphAligner).
Dataset and Initiative Benchmarks: The review emphasizes data and workflows derived from major international pangenome initiatives, including the Human Pangenome Reference Consortium (HPRC), the Vertebrate Genomes Project (VGP), and the Earth BioGenome Project (EBP).
To evaluate the current state of pangenome graph bioinformatics, we introduce four distinct analytical dimensions used to categorize the reviewed content:
- 1.
Computational Effectiveness and Scalability: We assess tools based on their runtime, memory overhead (RAM usage), and scalability to population-level datasets (e.g., 50+ human genomes).
- 2.
Structural Resolution and Accuracy: This dimension examines the compromises between “reference-guided” approaches, which offer faster construction, and “reference-free” or high-resolution methods that depict fine-grained structural variation and complex rearrangements.
- 3.
Interoperability and Standardization: We analyze the current landscape for data formats—such as GFA, VG, and ODGI—and the tools that enable translation between them to support reproducible workflows.
- 4.
Domain-Specific Utility: We evaluate the practical application of pangenome graphs throughout diverse biological domains, specifically human genomics (variant calling and clinical diagnostics), microbial genomics (horizontal gene transfer and resistance tracking), and plant genomics (handling polyploidy and repetitive content).
The following table summarizes the technical characteristics of the primary pangenome tool chains reviewed in this study. The main objective of this review is to synthesize the rapidly expanding ecosystem of graph-based pangenomics. To ensure a systematic and unbiased selection of the literature and software, we conducted a structured search across PubMed, Google Scholar, and bioRxiv using keywords: “pangenome graph,” “genome graph,” “variation graph,” “pangenome construction,” and “graph mapping.”
Tool Selection and Inclusion Criteria:
The selection of the software toolkits listed in
Table 1 was governed by a multi-stage screening process.
Initial Identification: Our search identified 42 individual tools or pipelines for graph-based genomic analysis.
Temporal and Performance Filtering: We prioritized advancements made within the past five years (2020–2025). Tools were further evaluated for their computational effectiveness and scalability to population-level datasets (e.g., 50+ human genomes).
Adoption and Integration: We focused on high-performance toolkits that have achieved extensive adoption or are central to major international pangenome initiatives, such as the Human Pangenome Reference Consortium (HPRC).
Final Selection: The toolkits listed in
Table 1 (PGGB, Minigraph–Cactus, VG Giraffe, GraphAligner, Gramtools, and ODGI) were selected because they represent distinct, non-redundant categories of the pangenome workflow—ranging from de novo construction to clinical genotyping and topological visualization.
2. Background
2.1. From Linear Genomes to Pangenomes
For decades, genomic analyses have been anchored to linear reference genomes, single contiguous assemblies typically derived from a single or a few individuals. While these references have served as invaluable resources (e.g., GRCh38 for humans), they fail to capture the complete genomic variation within a species. This variation includes substantial structural variation (inversions or translocations), gene presence/absence variation, and population-specific sequences. As more individuals were sequenced, it became evident that these variations were excluded from the reference. This realization has driven the move toward pangenomics, a more inclusive framework that holds great promise for the future of genomic analysis.
- (a)
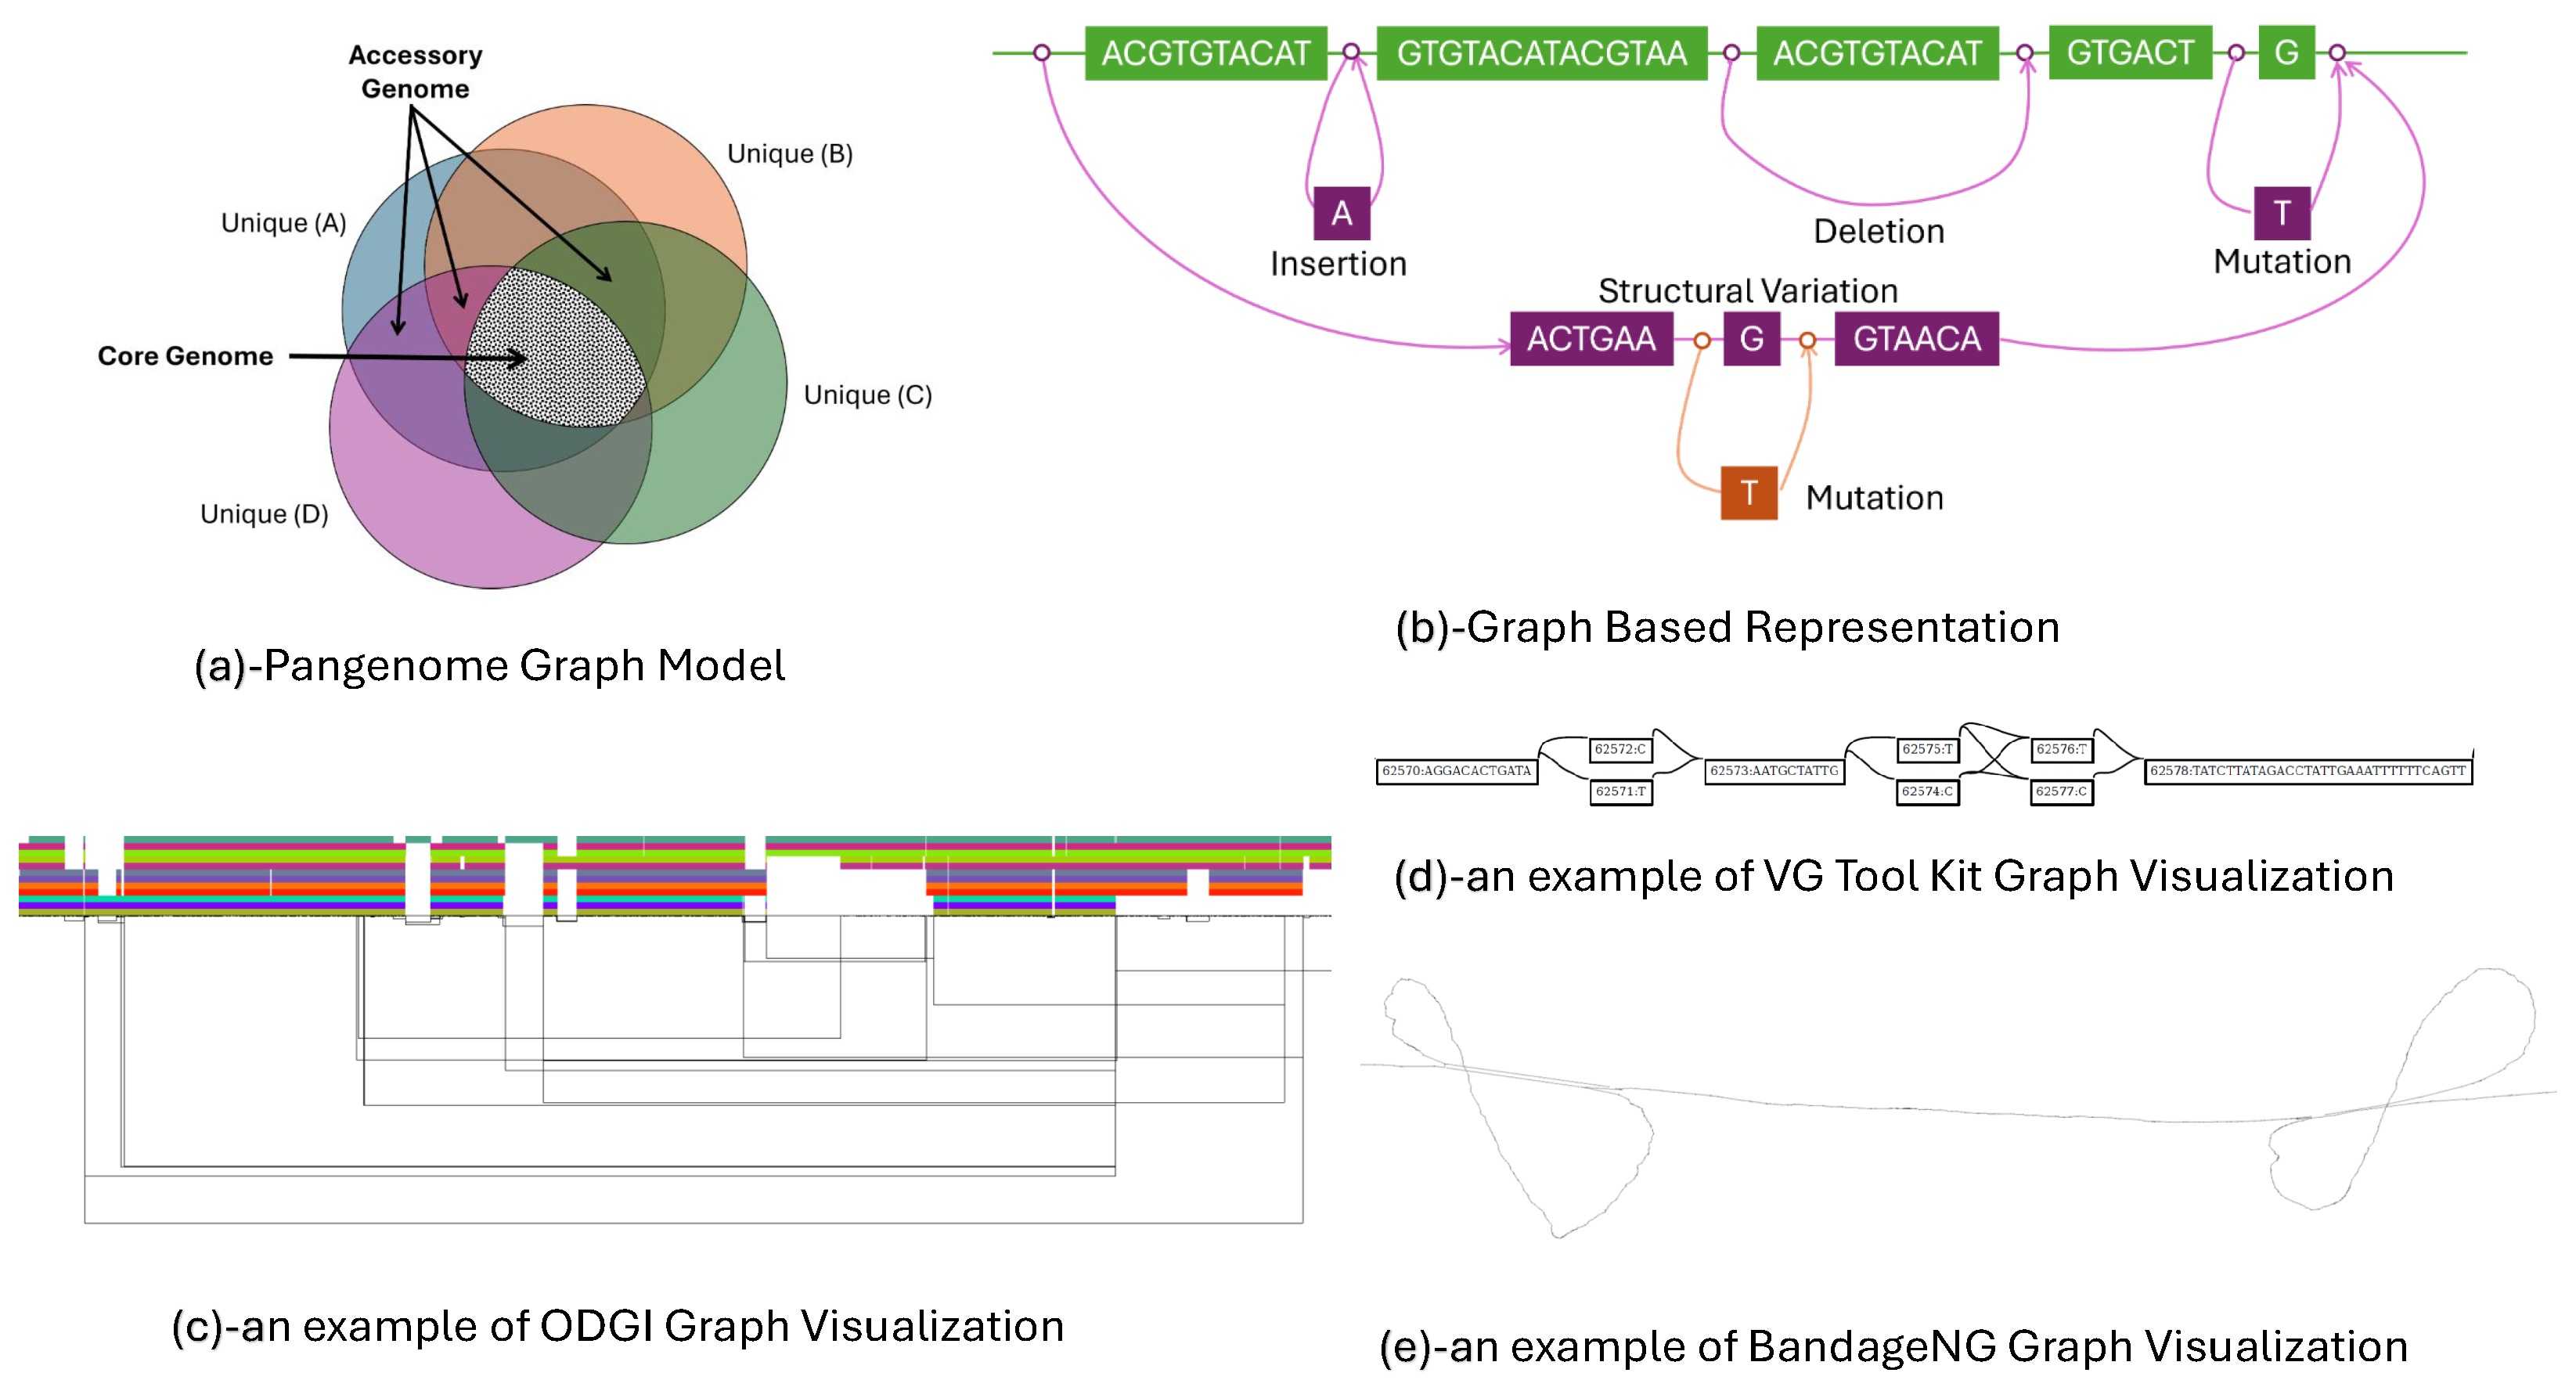
Pangenome Graph Model: A Venn diagram shows the main components of a pangenome. The core genome, shared by all, is at the center, surrounded by the accessory genome present in some but not all individuals, and unique (A–D) sequences found only in specific or a few individuals.The pangenome of a species refers to the union of all genomic sequences across its individuals, encompassing:
- –
Core genome: sequences shared across all individuals.
- –
Accessory genome: sequences present in some but not all individuals.
- –
Private/unique genome: sequences found in a single individual or a few.
This model enables a more comprehensive understanding of variation, evolutionary pressures, and genotype–phenotype relationships.
- (b)
Graph-Based Representation: A schematic encodes multiple genomes as paths through a graph. This approach captures genetic variations—insertions, deletions, mutations, and structural variation—in a single framework, avoiding linear reference bias.
- (c)
ODGI Graph Visualization: The ODGI toolkit visualizes the graph’s topology and sequence paths, offering a high-level, compressed view useful for large-scale analyses and quality control.
- (d)
VG Tool Kit Graph Visualization: The VG toolkit provides a detailed look at nodes and variations, helping researchers analyze complex genomic regions.
- (e)
BandageNG Graph Visualization: BandageNG displays large assembly and variation graphs in GFA format, aiding interpretation of connectivity and structural complexity in pangenome data.
2.2. Pangenome Graphs: Concepts and Data Structures
In order to computationally model the pangenome, graph-based representations (
Figure 1b) have become central. Pangenome graphs encode multiple genomes simultaneously, avoiding the biases of linear reference alignments.
2.2.1. Graph Definitions
Pangenome graphs can be categorized into distinct models, each differing in construction strategy and biological applicability.
Several graph-based models are used to represent genomic data, each offering unique advantages. Sequence graphs, such as de Bruijn graphs [
14], represent genomic sequences as nodes (nucleotides, kmers, or contigs) with edges indicating valid adjacencies between them. Variation graphs are designed to encode haplotype diversity, enabling multiple paths that reflect the genomes of different individuals. Cactus graphs, which are constructed from multiple sequence alignments, preserve syntenic relationships and genomic rearrangements [
15]. Each of these graph structures supports a different balance of complexity, scalability, and biological interpretability.
2.2.2. Graph Model Architectures in Pangenomics
The structural representation of a pangenome is fundamentally determined by its underlying graph models, as shown in
Table 2. While various implementations exist, three primary architectures dominate the current landscape: de Bruijn graphs (dBG), variation graphs (VG), and Cactus graphs.
De Bruijn graphs are optimized for assembly by decomposing sequences into overlapping k-mers, but they often lack explicit haplotype representation. In contrast, variation graphs encode allelic diversity by representing sequences as nodes and variations as alternate paths, making them better suited for read mapping and variant inference. Cactus graphs provide a hierarchical decomposition that excels at representing large-scale structural rearrangements and maintaining synteny across diverse species.
2.2.3. Representation Standards
Key formats for graph genomes include the following.
Several formats and toolkits have been developed to facilitate the storage, exchange, and analysis of genome graphs. The Graphical Fragment Assembly (GFA) format provides a standardized, textual way to represent assembly graphs, promoting interoperability between different tools and platforms [
16]. The Variation Graphs (VGs) format, used by the VG toolkit, offers a binary representation specifically tailored for encoding and processing variation graphs [
17]. Additionally, the Optimized Dynamic Genome/graph Implementation (ODGI) is an advanced toolkit designed for the succinct and efficient manipulation of genome graphs, enabling large-scale analyses with improved speed and memory usage [
13]. These formats and tools are essential for advancing graph-based genomics workflows.
2.3. Analytical Advantages of Pangenome Graphs
Pangenome graphs are now applied to a variety of computational genomics tasks.
Graph-based genome representations enable a wide range of powerful downstream analyses in genomics. For read mapping, tools such as vg map, GraphAligner, and Giraffe leverage graph structures to achieve more accurate alignments, particularly in regions with high genetic variability. In variant calling, graph-aware methods can more sensitively detect single-nucleotide polymorphisms (SNPs) and significant structural variants by accounting for known alternative alleles and complex rearrangements. Comparative genomics also benefits, as graphs naturally capture rearrangements, insertions, and deletions, enabling detailed structural comparisons between individuals or species. In functional genomics, graph-based approaches help associate structural variations with regulatory regions or genes that may be absent from traditional reference genomes. Finally, in population genomics, the richer representation of haplotype diversity provided by genome graphs supports improved inference of ancestry and natural selection patterns across populations.
2.4. Major Initiatives Driving Pangenome Graph Construction
Several global efforts have been instrumental in developing large-scale pangenome graphs. Major international initiatives are leveraging genome graph technologies to construct comprehensive genomic references. The Human Pangenome Reference Consortium (HPRC) seeks to replace the traditional linear human reference genome with a pangenome reference built from hundreds of individuals representing diverse ancestries [
5]. The 1000 Genomes Project has expanded its efforts by constructing variation graphs from phased variant calls across thousands of human genomes, thereby enhancing representation of global genetic diversity [
18]. Meanwhile, the Vertebrate Genomes Project (VGP) and Earth BioGenome Project (EBP) are generating reference-quality assemblies for a wide range of species, laying the groundwork for multi-species pangenome graphs [
18]. These projects collectively exemplify the shift toward graph-based models in genomics, aiming for more inclusive and accurate representations of genetic variation.
3. Recent Advances in Pangenome Graph Tooling
Recent advances in creating scalable, effective, and medically appropriate pangenome graph technologies are of significant importance. These tools not only significantly advance our discipline but also cover every facet of pangenomics activities, such as downstream analysis, visualization, and graph construction. This section, which is arranged according to functionality, ensures you are up to date on the most significant current innovations in pangenome graph technology, keeping you informed and up-to-date in your field.
3.1. Graph Construction
Despite significant progress, building precise and effective pangenome graphs remains a critical challenge in genomics. There is a growing demand for tools that can integrate multiple genomes, resolve complex structural variations, and represent genetic diversity without unnecessary redundancy. Minigraph–Cactus addresses these needs by combining the speed of Minigraph for constructing graph backbones from reference-quality assemblies with the fine-grained alignment capabilities of Cactus; this approach is a key component of the Human Pangenome Reference Consortium (HPRC) pipeline [
9]. The PanGenome Graph Builder (pggb) further advances the field by automating high-resolution pangenome graph construction using tools like wfmash, seqwish, and smoothxg, preserving long-range alignments and yielding topologically clean graphs [
1]. The VG toolkit provides robust computational methods for constructing and manipulating genome-variation graphs, reducing reference bias and improving read-mapping accuracy [
17]. Collectively, these tools support the integration of both linear and graph-based references and are increasingly adopting reference-free strategies to further minimize reference bias.
3.2. Graph Indexing and Optimization
Pangenome graphs necessitate compact indexing and optimized traversal strategies to enable real-time queries and scalable genomic analyses. Tools such as ODGI offer efficient manipulation, visualization, and analytics for genome graphs, providing memory-efficient storage solutions and supporting parallel graph operations [
13]. Within the VG toolkit, Giraffe stands out as an ultra-fast mapper that leverages GBWT (Graph Burrows–Wheeler Transform) indexes to achieve rapid read alignment at the population scale [
10]. The GBWT itself is a succinct index designed for haplotype-aware queries and is central to high-performance, graph-based mapping and phasing [
19]. These indexing solutions—ODGI, Giraffe, and GBWT—are vital for enabling interactive graph queries, efficient mapping, and sensitive variant discovery across expansive pangenome datasets, thereby facilitating scalable, responsive operations on complex genome graphs.
3.3. Graph-Aware Mapping and Variant Discovery
Graph-aware mappers and variant callers have greatly enhanced sensitivity and reduced reference bias, particularly in structurally variable and underrepresented regions of the genome. Mapping aligns sequencing reads to a reference genome or graph, while variant calling identifies sequence differences (variants) based on these alignments. Tool selection depends on experimental goals and the characteristics of sequencing data. For example, GraphAligner enables accurate alignment of spliced and long-read sequencing data to genome graphs, making it especially valuable for transcriptome analyses and handling error-prone long reads [
11]. Giraffe, part of the VG toolkit, is optimized for short-read data and is designed to scale to population-level pangenomes, delivering near-linear mapping speeds while maintaining high sensitivity [
10]. Gramtools is well-suited for genotyping nested and multiscale variants using a graph genome model, with notable applications in microbial genomics where complex variation is common [
12]. In summary, GraphAligner is ideal for long-read and transcriptomic data, Giraffe for high-throughput short-read population studies, and Gramtools for scenarios involving complex structural variation and microbial genomes. Collectively, these tools are key to transforming pangenome graphs from static representations into functional references, enabling their effective use with real-world sequencing data.
3.4. Visualization and Interpretation
Visualizing pangenome graphs poses significant challenges due to their inherent non-linearity and structural complexity, yet recent advancements have greatly improved interpretability. Tools like ODGI Viz provide both topological and linearized views, enabling users to interactively explore graph structures and sequence paths (
Figure 1c) [
13]. Within the VG toolkit, vg view and vg vis facilitate path-, node-, and variation-level visual inspection, helping researchers dissect complex regions (
Figure 1d). BandageNG, a modern and actively maintained fork of Bandage, supports visualization of large assembly and variation graphs in the widely used GFA format (
Figure 1e) [
20]. Interactive visualization is critical for quality control, interpretation of structural variation, and the curation of assemblies in graph-based genome projects, empowering researchers to better understand and validate complex genomic data.
3.5. Standards and Interoperability
The rapid proliferation of graph-based tools in genomics has made standardization and interoperability increasingly vital. Far from being mere technicalities, these efforts are central to enabling reproducible science and seamless cross-platform integration within bioinformatics workflows. GFA1 and GFA2 have become widely adopted standards for representing sequence graphs, with extensions to accommodate genomic variation and path information. In parallel, RDF-based models are emerging to link pangenome graphs with broader knowledge graphs, enabling richer annotation and semantic integration. Interchange frameworks and tools—such as vg convert, odgi view, and gfaffix—facilitate translation between popular formats like VG, GFA, and ODGI, promoting robust interoperability across diverse graph toolchains. Collectively, these standardization initiatives are essential for ensuring the long-term progress, reproducibility, and collaborative potential of graph-based genomics.
4. Applications and Use Cases
Pangenome graphs are powerful tools in genomics. They provide a comprehensive representation of genomic diversity and facilitate inaccessible discoveries through linear reference-based analyzes. This section explores key application areas where pangenome graphs have shown transformative potential.
4.1. Human Genomics
4.1.1. Improved Variant Calling and Genotyping
Traditional reference-based pipelines are prone to reference bias, particularly in regions with structural variation or in populations underrepresented in the reference genome. Pangenome graphs reduce this bias by incorporating multiple haplotypes and structural variants into a unified reference framework. Graph-based pipelines demonstrated a 20–30% increase in SV detection sensitivity in segmental duplication regions compared to GRCh38-based pipelines.
The Human Pangenome Reference Consortium (HPRC), a leading organization, has demonstrated that graph-based variant calling improves sensitivity in segmental duplications, centromeric regions, and large insertions/deletions.
Tools like VG Giraffe and Gramtools have been deployed for genotyping complex loci (e.g., HLA, CYP genes), revealing population-specific haplotypes with high accuracy.
4.1.2. Population-Scale Analysis
Pangenome graphs provide an efficient framework for analyzing thousands of haplotypes simultaneously, greatly enhancing large-scale genomic studies. This capability is particularly valuable for pangenome-wide association studies (pan-GWAS), where graph-based genotyping increases the power to detect causal variants that may be missed by traditional linear approaches [
21]. Additionally, structural variation catalogs, such as those produced by the Human Structural Variation Consortium (HGSVC), leverage pangenome graphs to anchor the discovery and annotation of large-scale structural variants, offering a comprehensive view of genetic diversity across populations. These applications underscore the transformative impact of pangenome graphs on both association studies and structural variation research.
4.2. Microbial Genomics
In microbial genomics, pangenome graphs provide a powerful framework for capturing the extensive genetic diversity driven by horizontal gene transfer, gene presence/absence variation, and pan-structural changes within populations. Graph-based tools such as PANX [
22] and Panaroo [
23] are widely used to model both core and accessory genomes in bacterial communities. These graph representations enable effective tracking of antimicrobial resistance genes, mapping of virulence factors, and conducting pangenome-wide association studies (pan-GWAS), particularly in pathogenic microbes. Such approaches have become invaluable for infectious disease surveillance, resistance monitoring, and evolutionary analyzes, offering a comprehensive perspective on microbial diversity and adaptation [
8].
4.3. Plant and Agricultural Genomics
The inherent complexity of plant genomes—stemming from polyploidy, extensive repetitive content, and large structural variants—makes them particularly well-suited for graph-based genomic representations. Initiatives such as the MaizeGDB pangenome [
24], the Brassica pangenome [
25], and multiple rice genome projects [
26] have adopted graph-based methods to capture and integrate structural diversity across diverse accessions. These graph models facilitate haplotype-based breeding, trait mapping, and genomic selection, empowering plant breeders to harness allelic diversity that is often overlooked by traditional single-reference approaches [
27]. As a result, graph-based genomics is becoming an increasingly valuable tool for crop improvement and the study of plant diversity.
Plant genomes pose significant challenges due to their large size, repetitive sequences, and complex evolutionary histories. Pangenome graphs provide a comprehensive framework for addressing these issues, thereby supporting advances in crop improvement and evolutionary research.
Polyploidy and Genome Duplication
Numerous ecologically and economically important plants, including wheat (Triticum aestivum) and cotton (Gossypium), are polyploid and contain multiple chromosome sets originating from distinct ancestral species [
28]. Linear reference genomes often merge these subgenomes, leading to ambiguous read mapping and inaccurate variant identification. Pangenome graphs explicitly represent homeologous sequences, allowing for precise differentiation between subgenomes and detailed tracking of the evolutionary divergence of duplicated genes.
Transposable Elements (TEs) and Repetitive Sequences
Transposable elements frequently dominate plant genomes, comprising over 80% of the total DNA in species such as maize [
29]. These elements are a primary source of structural variation and changes in genome size. Graph-based models effectively capture the movement of transposable elements within populations. By representing these elements as alternative paths or loops, graph models clarify the role of repetitive sequences in phenotypic diversity and gene regulation, aspects that are often obscured in linear genome alignments.
Presence/Absence Variation (PAV)
A considerable fraction of the plant species’ gene pool is not present in every individual. Presence/absence variations frequently involve genes associated with resistance to biotic and abiotic stresses [
30]. A single linear reference representing the pangenome core does not capture shell or cloud genes specific to individual cultivars. Pangenome graphs incorporate these dispensable genes as auxiliary paths, ensuring that critical agronomic traits, such as drought tolerance or pest resistance, are detectable during sequence analysis.
Introgression and wild relatives. Contemporary crop breeding frequently utilizes introgression, the transfer of genetic material from wild relatives into elite cultivars to introduce advantageous traits. Introgressed genomic segments are often highly divergent from domesticated references. Graph-based reference genomes can integrate the genomes of wild ancestors with those of modern varieties, enabling breeders to accurately map introgressed segments and monitor linkage drag, where undesirable wild traits are retained alongside target genes.
Why Plant Genomes Need Pangenomes
Early crop genome assemblies, such as the rice reference published in 2005 [
31], dramatically accelerated gene discovery and trait mapping by providing a standardized genomic framework for plant genetics. However, these reference genomes were typically derived from a single individual or elite cultivar and, therefore, captured only a narrow fraction of the genetic diversity present within a species. As sequencing technologies matured and multiple high-quality plant genomes became available, it became increasingly evident that single-reference models fail to represent the extensive sequence and structural variation observed across accessions, landraces, and wild progenitors.
4.4. Functional Genomics and Transcriptomics
Beyond representing DNA sequence variation, graphs are increasingly applied to model the complexity of splicing events, transcriptional isoforms, and functional genomic elements. Splice and variation graphs designed for transcriptomic data—such as those used in GraphAligner and VG RNA—enable accurate read alignment and quantification across a wide range of isoforms and alleles [
32]. These approaches support advanced applications, including eQTL (expression quantitative trait loci) mapping, allele-specific expression analysis, and the investigation of alternative splicing in both humans and model organisms [
33]. By extending the utility of graph-based genomics into transcriptomics and functional annotation, researchers can achieve a more comprehensive understanding of gene regulation and expression diversity.
4.5. Methodology for Resolving Plant Genomic Complexity
The structural architecture of plant genomes is defined by high repeat density, recursive polyploidy, and nested transposable elements (TEs). These features pose significant challenges for linear reference-based alignment. Traditional mapping often fails to capture the full spectrum of presence–absence variations (PAVs). PAVs frequently underlie agronomically vital traits such as stress resistance and yield.
To overcome these limitations, graph-based pan-assembly methodologies use iterative construction toolkits, such as Minigraph–Cactus. These tools integrate multiple de novo assemblies into a singular coordinate system. This approach uses a “base-graph” strategy. Structural variations are represented as alternate paths. As a result, multi-layered alignment of nested TEs becomes possible. These TEs would otherwise be collapsed or misaligned in linear models. By leveraging these graph-aware algorithms, researchers can precisely quantify PAV frequency and identify introgression events across diverse cultivars. This transforms the plant pangenome from a conceptual inventory into a functional tool for marker-assisted selection.
4.6. Transitioning to Clinical Implementation and Precision Medicine
While plant genomics focus on capturing broad structural diversity, the application of pangenome graphs in clinical genomics is shifting. The focus is now on enhancing the resolution of pathogenic loci. The core methodology replaces the single-line reference with a multi-haplotype framework. This shift minimizes reference bias. Reference bias is a primary source of false negatives in clinical screening.
Recent clinical implementation pipelines have begun using the VG toolkit and ODGI. These tools improve the detection of pathogenic structural variants (SVs) in medically relevant regions, such as segmental duplications and centromeric repeats. In multi-center studies of rare genetic disorders, these graph-based alignments increase diagnostic sensitivity for SVs by 25%. This is compared to traditional GRCh38-aligned pipelines [
34].
In pharmacogenomics, the methodology has shifted toward graph-based genotyping of highly polymorphic loci. For example, using Gramtools to genotype CYP2D6 alleles within a graph model enables detection of population-specific haplotypes. Traditional linear callers often overlook these haplotypes. By resolving these complex, multiscale variants, graph-based approaches directly inform drug-metabolism phenotypes. They provide high-fidelity genetic insights that are required for effective personalized therapy and precision medicine [
35].
4.7. Evolutionary and Comparative Genomics
Pangenome graphs offer a powerful means for representing and analyzing evolutionary relationships by capturing both structural and sequence diversity across species or populations. In evolutionary genomics, the topology of these graphs provides a flexible framework to identify lineage-specific variants, introgression events, and patterns of adaptive evolution. Researchers are increasingly leveraging graph-based approaches to reconstruct ancestral genomes and visualize synteny—the conservation of gene order—across multiple species [
36]. These capabilities make pangenome graphs especially valuable for unraveling the complexities of genome evolution and for studying the genetic basis of adaptation and diversification.
Multi-Species Comparative Pangenomics Pangenome graphs facilitate not only the analysis of intra-species variation but also the alignment and comparison of multiple related species. In contrast to linear alignments, which often result in significant sequence loss within divergent regions, graph-based comparative genomics preserves the evolutionary context of both conserved core regions and lineage-specific accessory elements.
Synteny Preservation: Graph-based structures, such as Cactus, enable hierarchical alignment of multiple genomes and maintain long-range synteny, even when large-scale chromosomal rearrangements are present.
Interspecies Phylogenomics: Threading multiple species through a unified graph enables the identification of “orthologous paths,” which provide higher-resolution estimates of evolutionary distance compared to traditional single-copy ortholog approaches.
Case Study Utility: This framework is essential for projects, such as the Vertebrate Genomes Project (VGP), as it facilitates the investigation of accelerated evolution within specific clades by mapping divergence directly onto the graph topology.
Microbial Pangenomics: From Description to Methodological Inference Traditional microbial pangenomics primarily described “core” and “accessory” genomes. In contrast, current graph-based methodologies enable more comprehensive functional and clinical inference through detailed structural analysis.
Mobile Genetic Element (MGE) Tracking: Instead of merely recording the presence of plasmids or transposons, graph models explicitly represent the insertion sites and structural context of MGEs [
37]. This explicit representation is critical for mapping the transmission of Antimicrobial Resistance (AMR) genes across diverse bacterial strains.
High-Resolution Genotyping: Pangenome graphs enable “k-mer aware” variant calling in highly recombinant species [
38], such as Streptococcus pneumoniae. Tools such as PanSN-spec or McCortex facilitate the inference of recombination events that are often obscured by reference-guided mapping.
Strain-Level Resolution in [
39]: Graph-based references are increasingly employed to deconvolve complex metagenomic samples. Aligning short-read data to a pre-constructed microbial pangenome graph enables strain-level identification and facilitates the tracking of clonal evolution within a host over time.
4.8. Pangenome Analysis for Anaplasmataceae Bacteria
Anaplasmataceae primarily infect vertebrates and are typically transmitted by arthropod vectors such as ticks [
40]. The family includes several important genera, including Anaplasma and Ehrlichia, which cause diseases such as anaplasmosis and ehrlichiosis in both humans and animals. These bacteria often target white blood cells. Anaplasmataceae is a family of bacteria within the order Rickettsiales. Members of this family are obligate intracellular pathogens, meaning they must live and multiply inside the cells of their host organisms. Anaplasma blood cells, leading to symptoms such as fever, malaise, and, in severe cases, organ dysfunction. Diagnosis usually involves blood tests and molecular techniques, while treatment typically requires antibiotics like doxycycline. Ongoing research continues to improve understanding of their biology, epidemiology, and effective prevention strategies.
Pangenomes provide a powerful approach to studying Anaplasmataceae by analysing the complete set of genes present within all strains of the family or its genera. By comparing the core genome (genes shared by all strains) and the accessory genome (genes present in some but not all strains), researchers can identify genetic diversity, understand evolutionary relationships, and uncover genes linked to virulence, antibiotic resistance, and host adaptation. This information helps reveal how different species and strains adapt to various hosts or environments, and can inform the development of diagnostic tools, vaccines, and targeted treatments. Pangenomic analysis also facilitates the discovery of novel genes that may contribute to the unique biology of Anaplasmataceae.
In recent studies, 121 Anaplasmataceae genomes were processed using the PGAP (Prokaryotic Genome Annotation Pipeline), yielding 9024 gene clusters in the pangenome. This large number of clusters highlights the family’s extensive genetic diversity. Such a comprehensive pangenome enables in-depth comparative analyzes, helping pinpoint essential genes conserved across all strains, as well as strain-specific genes that could serve as targets for further research into pathoicity, host interactions, and potential therapeutics [
41].
Based on the pangenome analysis of the Anaplasmataceae family—which includes key genera like Anaplasma, Ehrlichia, and Wolbachia—the results typically reveal a highly specialized genomic structure adapted for obligate intracellular survival. The pangenome of this family is generally characterized as open but shows significant conservation within specific lineages. For instance, in Anaplasma phagocytophilum, a significant portion of the genome is core (consistently present across strains), often exceeding 90% of any single genome’s content, while the accessory genome remains relatively small but critical for niche adaptation. These accessory elements frequently include genes for type IV effectors (T4Es), ankyrin repeat proteins (Anks), and outer membrane proteins (OMPs), such as the p44/Msp2 paralogs, which are instrumental in host cell invasion and immune evasion. The presence–absence matrix often shows that, while core metabolic pathways are streamlined and reductive due to host dependency, the diversity in the shell and cloud genomes drives the specific host–vector tropism observed among ruminant-, canine-, and human-infecting strains. Core genome can be highly conserved and takes up a high percentage of the total genome (e.g., >1.4 Mbp in A. phagocytophilum), including genes with housekeeping functions, DNA replication, and basic metabolism. Accessory genome is a smaller fraction (often 5–15%); it contains variable gene clusters, like virulence factors, niche adaptation, and host-specific interactions. Key variable genes are the T4SS effectors, Ankyrin-repeat proteins, and polymorphic membrane proteins, which have a role in facilitating intracellular survival and manipulating host cell signaling.
5. Challenges and Limitations
Despite their transformative potential, pangenome graphs are not without challenges. The development, adoption, and practical utility of these data structures are limited by both computational and biological complexities. This section discusses the key obstacles impeding widespread implementation of pangenome graphs across genomic research and clinical applications.
5.1. Computational Scalability
Graph-based representations are inherently more complex than linear genomes, and this complexity increases with the number of genomes incorporated.
Graph construction becomes computationally intensive as the number of input genomes grows, particularly when preserving complex variation such as nested structural variants and repeats.
Performing a read alignment to graphs is significantly more expensive than to linear references. Even with recent advancements like VG Giraffe and GraphAligner, graph-based mappers require more memory and CPU time than BWA [
42] or minimap2 [
43].
Graph indexing and storage are another bottleneck. Succinct data structures (e.g., GCSA2, GBWT) reduce memory usage, but trade-offs exist between compression, query time, and updateability.
The computational performance of pangenome graph tools varies significantly, with trade-offs in different aspects. For example, PGGB provides high-resolution graph construction but at the cost of high memory usage (>100 GB RAM for 50+ human genomes) and extended runtime (several days on 32-core systems) [
1]. Conversely, Minigraph–Cactus offers faster initial graph construction by leveraging reference-guided assembly but sacrifices fine-grained structural resolution [
5]. Understanding these trade-offs is crucial for making informed choices.
minimap2 is a linear aligner commonly used as a baseline comparator rather than a graph-native tool, with their consistent runtime of approximately 10–20 min for 30× human WGS in read mapping, stand as a testament to the efficiency that can be achieved in pangenome analysis. VG Giraffe, while expanding to population-level references, usually requires 3–5× greater memory and 2× CPU time. GraphAligner, on the other hand, exhibits higher overhead when used on big transcriptomic graphs, yet it is very effective for lengthy readings.
On the indexing front, GBWT provides fast haplotype-aware queries but requires precomputation and incurs high disk storage costs for complex populations. Tools like ODGI are optimized for memory and parallelism, allowing scalable graph manipulation on HPC or cloud-native infrastructures.
Given the trade-offs in computational performance, the strategic choice of toolchains becomes a crucial part of the research process. Depending on the goals of the study, the size of the genome, and the computing power available, researchers must carefully select the most suitable toolchains. A comparative overview of the main computational characteristics of popular tools is provided in
Table 3 below, engaging researchers in this strategic decision-making process.
5.2. Standardization and Interoperability
In contrast to the well-established ecosystem surrounding linear genome representations, graph-based bioinformatics currently lacks mature and universally adopted standards for data formats, interfaces, and APIs. The coexistence of multiple graph formats—including GFA, VG, ODGI, rGFA, and GBZ—has led to tool fragmentation and significant challenges in integrating graph-based workflows. This lack of interoperability, coupled with the absence of a comprehensive toolkit similar to samtools or GATK in the linear genome world, results in steep learning curves for both new users and developers. Furthermore, inconsistent and underdeveloped support for annotation representation—such as genes and transcripts—across different graph platforms hinders the broader adoption of graph approaches in functional genomics and downstream analyzes.
5.3. Biological Interpretation and Visualization
While graph structures offer significant power for representing genomic diversity, they often pose interpretability challenges, particularly for users accustomed to traditional linear reference models. Visualizations of genome graphs can quickly become complex and overwhelming, especially when representing large genomes or intricate, deeply nested structural variants. This complexity underscores the need for more intuitive, user-friendly visualization tools that enable multi-scale exploration, from gene-level details to chromosome-wide perspectives, while clearly illustrating structural and haplotypic diversity. Furthermore, biological concepts such as “gene,” “allele,” or “haplotype” become less clearly defined and more ambiguous within the graph context, highlighting the need for standardization and clear definitions to facilitate effective communication and analysis.
5.4. Reference Coordinate Systems and Compatibility
Many downstream analyzes and legacy genomics pipelines are built around linear coordinate systems, such as GRCh38 or GENCODE, which underpin data formats and tools across the field. Moving to graph-based reference systems disrupts these longstanding assumptions, necessitating the development of coordinate translation mechanisms to project graph alignments onto familiar linear paths. While tools like VG offer solutions for translating between graph and linear coordinates, these processes can be lossy and error-prone, particularly in regions of high structural complexity. As graph-based genomics continues to advance, improving the accuracy and reliability of coordinate translation will be essential to ensure compatibility with existing resources and workflows.
While tools like VG offer solutions for translating between graph and linear coordinates, these processes can be lossy and error-prone, particularly in regions of high structural complexity. As graph-based genomics continues to advance, improving the accuracy and reliability of coordinate translation will be essential to ensure compatibility with existing resources and workflows.
5.5. Data Integration and Annotation
Integrating functional data—such as epigenomic marks, gene expression levels, and regulatory elements—into pangenome graphs remains an emerging and technically challenging area. Traditionally, most functional datasets are mapped to linear reference genomes, and remapping these annotations onto graph-based references is complex and prone to errors, particularly in repetitive or structurally variable genomic regions. The task of annotation liftover is further complicated by the limitations of existing formats like GTF and BED, which are not designed for the non-linear nature of graph genomes. As a result, there is a growing need for new annotation paradigms and tools specifically tailored to the representation and integration of functional data within pangenome graphs.
5.6. Adoption in Clinical and Regulatory Settings
Despite their promise, graph-based genomic methods face significant hurdles in clinical adoption. Clinical pipelines demand high standards of reproducibility, interpretability, and regulatory compliance—areas in which current graph-based tools still have notable gaps. The validation of graph-based variant calls for clinical use remains limited, and to date, regulatory bodies have not endorsed graph genomes for routine diagnostic applications. Furthermore, the absence of clinical-grade, thoroughly documented software and established best-practice pipelines for graph genomics continues to impede their integration into translational research and clinical diagnostics. Addressing these challenges will be essential for realizing the full potential of graph genomics in precision medicine [
44].
6. Future Directions
The field of pangenome graph research is rapidly evolving, propelled by advances in sequencing technologies, algorithm design, and large-scale genome initiatives. This section outlines key areas where further innovation and development are expected to drive the next generation of graph-based genomics.
6.1. Towards Scalable and Dynamic Graph Construction
With the rapid increase in high-quality genome assemblies, particularly from initiatives like the Human Pangenome Reference Consortium (HPRC), computational methods must adapt to efficiently accommodate this expanding data landscape. Dynamic graph augmentation is becoming essential, enabling algorithms to incrementally add new genomes to existing graphs while preserving crucial topological features and haplotype paths, rather than necessitating complete graph reconstruction. The ability to construct and update graphs in a streaming and distributed manner is also critical for handling population-scale datasets in real time, making scalable, cloud-native infrastructure increasingly important. Furthermore, as graph complexity grows, strategies for graph simplification—such as selective pruning and abstraction—will be necessary to tailor analyzes for specific domains, whether for targeted investigations or comprehensive whole-genome exploration.
6.2. Enhanced Read Mapping and Variant Calling
Ongoing research in graph genomics is expected to yield increasingly efficient and accurate methods for read alignment and variant inference. Innovations in indexing, such as succinct de Bruijn graph variants and compressed path indexes, are emerging to better balance memory usage, query speed, and the ability to update graphs dynamically. Machine learning-enhanced mappers, particularly those leveraging transformer-based architectures, are poised to advance the modeling of complex graph contexts, leading to more precise alignments. In parallel, the development of graph-aware variant callers that operate natively on graph alignments will enable robust multi-sample and population-aware variant discovery. Together, these advances will further empower graph genomics to handle large-scale and diverse datasets with improved accuracy and scalability.
6.3. Graph-Based Genome Annotation
Functional annotation within graph genomes remains an underdeveloped but essential frontier for genomics. To fully realize the potential of pangenome graphs, graph-native gene models are needed that can accurately represent complex splicing patterns and gene structures across diverse haplotypes and structural backgrounds. Emerging tools such as PanSNAP and Spliced Graphs are paving the way for transcript annotation and isoform discovery within a graph-based framework, offering new opportunities to characterize transcript diversity. Moreover, standardizing annotation schemes and formats across tools will be vital for integrating diverse expression, methylation, and regulatory datasets, ultimately enabling more comprehensive and biologically meaningful analyses.
6.4. Visualization and User Accessibility
The accessibility of pangenome graphs to wider research and clinical communities will depend on the development of new, intuitive interfaces. Multi-scale visualization platforms that integrate genetic variation, annotation, and expression data into interactive and responsive views will empower users to explore complex genomic structures with ease. Web-native tools such as JBrowse 3 and MoMI-G enable direct interaction with graph-based representations in a browser, eliminating the need for specialized local infrastructure. Looking ahead, natural language interfaces and explainable AI systems hold promise for enabling non-specialists to query, explore, and interpret graph-based genomic variation, further democratizing the use of pangenome graphs in both research and clinical settings.
6.5. Graph-Based Genome-Wide Association Studies (GWAS)
Traditional linear reference genomes introduce reference bias in genome-wide association studies (GWAS) and often fail to capture non-reference alleles, particularly in diverse or underrepresented populations. Graph genomes address these limitations by enabling improved variant discovery and imputation across a broader spectrum of genetic diversity. They also support graph-aware association models that can analyze not only single-nucleotide variants but also structural variation, pan-alleles, and complex haplotype paths. Furthermore, integrating epigenomic and regulatory data within a graph framework allows for more comprehensive interpretation of trait associations, paving the way for deeper insights into the genetic architecture of complex traits and diseases.
6.6. Standards, Interoperability, and FAIR Graphs
Establishing consensus around graph data structures, metadata conventions, and APIs will be pivotal for advancing the field of graph genomics. There is a growing need for the development of graph-aware standards analogous to established formats like VCF, GTF, and SAM/BAM [
45], providing uniform approaches for representing variant calls, annotations, and alignments within graph-based frameworks. Adhering to FAIR (Findable, Accessible, Interoperable, Reusable) principles will further enhance reproducibility and facilitate data sharing within the genomics community. To drive these efforts, community-driven governance models are essential, fostering collaboration among tool developers, researchers, and consortia, and ensuring that emerging standards address the practical needs of diverse stakeholders.
6.7. Clinical Translation and Regulatory Integration
For graph-based genomic methods to transition from research to clinical practice, they must meet rigorous clinical-grade standards. This requires the development of robust benchmarking datasets specifically designed to validate graph-based variant calling, with a focus on medically significant genomic regions. Additionally, interpretability frameworks must be established to ensure that graph-based genotype information can be readily understood and applied in clinical decision-making. Close collaboration with regulatory bodies is also essential for evaluating and certifying graph-based analysis pipelines, particularly as they are integrated into precision medicine initiatives. Meeting these requirements will be critical for establishing the reliability, transparency, and clinical utility of graph genomics in healthcare.
6.8. Toward a Unified Containerized Toolkit for Pangenome Graphs
As the landscape of pangenome research continues to evolve, the complexity of deploying and integrating diverse tools for graph construction, alignment, variant calling, and visualization presents a significant barrier to entry for many researchers [
46]. Developing a containerized solution similar in spirit to the “Mars” [
47,
48] toolkit can greatly alleviate these challenges. Such a platform would encapsulate widely used pangenome graph tools (e.g., VG toolkit, ODGI, minimap2) within a reproducible and portable environment, streamlining installation and configuration.
Moreover, by incorporating modular workflows that guide users through end-to-end processes—from input genome preparation and graph construction to read alignment and variant interpretation this toolkit would significantly reduce the technical burden associated with pipeline assembly. Integrating flexible configuration options and standardized I/O handling would empower researchers to experiment with different toolchains, track performance metrics, and adapt workflows to suit specific research questions in microbial, human, and metagenomic pangenome contexts. The development of such a unified system represents a promising direction to democratize pangenome analysis and accelerate innovation in graph-based genomics.
6.9. Improving Pangenome Sequences Using Transformer-Based Models
Although pangenome approaches mitigate the reference bias inherent in single linear genomes, they introduce new computational challenges, including sequence fragmentation, graph complexity, alignment ambiguity, and error propagation during assembly and variant integration. A prominent example of these challenges is the frequent miscall of structural variants, such as deletions and duplications, which can significantly impact disease association studies by linking incorrect genomic variants to conditions. Recent advances in transformer-based deep learning models offer a promising paradigm for addressing these challenges by learning long-range dependencies, contextual sequence representations, and structural regularities directly from large-scale genomic data [
49].
Transformer Architectures for Genomic Sequences Transformers rely on self-attention mechanisms to model global contextual relationships within sequences. In genomics, nucleotide sequences are tokenized into k-mers, or subsequences, enabling models to capture motifs, repeats, and long-range regulatory patterns. Unlike recurrent or convolutional architectures, transformers scale more effectively with sequence length and allow parallelized training, which is critical for pangenome-scale datasets [
50,
51].
Genomic transformer models, such as DNABERT and the Nucleotide Transformer, have demonstrated strong performance in tasks including variant effect prediction, genome annotation, and sequence reconstruction [
50,
52]. These models provide a foundation for extending transformer-based learning to pangenomic improvement tasks.
Transformer-Based Enhancement of Pangenome Sequences Error Correction and Sequence Refinement Self-supervised transformers trained using masked language modeling can identify improbable nucleotide contexts within pangenome sequences and graph nodes. By leveraging learned sequence distributions across diverse haplotypes, the model can propose corrections for sequencing or assembly errors, particularly in repetitive or low-complexity regions [
52].
Gap Filling and Missing Variant Inference Pangenome graphs often contain gaps owing to incomplete assemblies or population sampling bias. Transformers can infer missing sequence segments by conditioning on the flanking graph paths and homologous contexts across samples. This is analogous to sequence inpainting and has been shown to be effective in long-context biological language models [
50]. To enhance trust in these imputations, our approach incorporates confidence scores for the inferred segments, allowing users to make informed decisions on the reliability of these inferences. Calibration strategies such as Monte Carlo dropout are utilized to provide probabilistic assessments of the imputed sequences, thus supporting practical deployment.
Graph-Aware Contextual Embeddings By integrating positional encodings derived from variation graphs (e.g., node connectivity, path frequency, or topological order), transformer embeddings can encode both the linear sequence context and graph structure. These embeddings enable improved downstream tasks, such as read mapping, variant normalization, and haplotype-aware alignment [
1].
Transformer-based models offer a powerful and flexible framework for improving pangenome sequences through error correction, gap inference, and context-aware representation learning. By leveraging large-scale self-supervised training and integrating graph-derived context, these models have the potential to substantially enhance the accuracy, completeness, and usability of pangenome resources for genomic research.
7. Conclusions
The switch to graph based pangenomes from linear reference genomes is a groundbreaking advancement in genomics with a promising future. Pangenome graphs provide a comprehensive, equitable, and structurally sound framework for depicting genomic variation across populations, species, and evolutionary time. These graphs overcome the long-standing drawbacks of single-reference methods by capturing a variety of haplotypes, structural rearrangements, and non reference sequences, opening the door to more precise read mapping, variant calling, and functional interpretation.
This paper reviews the latest developments in graph construction algorithms, data structures, read mapping, variant inference, and downstream applications. We highlight key tools, platforms, and challenges encountered in building, analyzing, and visualizing pangenome graphs at scale. From population-scale human references to complex plant and microbial assemblies, graph methods are essential for decoding genomic diversity.
Despite the tremendous advancements, we must still be dedicated to solving the existing problems. Scalability, interoperability, annotation, and accessibility present opportunities and challenges for properly utilizing pangenome graphs. In particular, efforts to integrate functional genomics, epigenomic signals, and phenotypic traits into graph-based models will be crucial for biological discovery and translational impact. As graph genomes transition into clinical and public health applications, considerations around standardization, benchmarking, and regulatory approval will become increasingly important.
The convergence of long-read sequencing, distributed computing, AI-driven analysis, and collaborative data sharing will accelerate the maturation of pangenome graph ecosystems. These technologies, together with community-driven initiatives such as the Human Pangenome Reference Consortium and the Earth BioGenome Project, will redefine reference standards and democratize genomics across ancestries, organisms, and research communities.
In summary, pangenome graphs are no longer a conceptual future—they are becoming foundational to how we represent, analyze, and understand genomes. Continued interdisciplinary collaboration among algorithm developers, genome scientists, clinicians, and policymakers is not only beneficial, but essential to ensure that graph-based pangenomics achieves its full potential in both research and medicine.
Author Contributions
Conceptualization, F.N.I., S.A. and A.S.; methodology, F.N.I., S.A. and A.S.; software, F.N.I., S.A. and A.S.; validation, F.N.I., S.A. and A.S.; formal analysis, F.N.I., S.A. and A.S.; investigation, F.N.I., S.A. and A.S.; resources, F.N.I., S.A. and A.S.; data curation, F.N.I., S.A. and A.S.; writing—original draft preparation, F.N.I., S.A. and A.S.; writing—review and editing, F.N.I., S.A. and A.S.; visualization, F.N.I., S.A. and A.S.; supervision, F.N.I., S.A. and A.S.; project administration, F.N.I., S.A. and A.S. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
No new data were created or analyzed in this study. Data sharing is not applicable to this article.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Garrison, E.; Guarracino, A.; Heumos, S.; Villani, F.; Bao, Z.; Tattini, L.; Hagmann, J.; Vorbrugg, S.; Marco-Sola, S.; Kubica, C.; et al. Building pangenome graphs. Nat. Methods 2024, 21, 2008–2012. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Medini, D.; Donati, C.; Tettelin, H.; Masignani, V.; Rappuoli, R. The microbial pan-genome. Curr. Opin. Genet. Dev. 2005, 15, 589–594. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Bodmer, W. The HLA system: Structure and function. J. Clin. Pathol. 1987, 40, 948–958. [Google Scholar] [CrossRef] [Scilit]
- Weiser, J.N.; Ferreira, D.M.; Paton, J.C. Streptococcus pneumoniae: Transmission, colonization and invasion. Nat. Rev. Microbiol. 2018, 16, 355–367. [Google Scholar] [CrossRef] [Scilit]
- Liao, W.W.; Asri, M.; Ebler, J.; Doerr, D.; Haukness, M.; Hickey, G.; Lu, S.; Lucas, J.K.; Monlong, J.; Abel, H.J.; et al. A draft human pangenome reference. Nature 2023, 617, 312–324. [Google Scholar] [CrossRef] [Scilit]
- Rhie, A.; McCarthy, S.A.; Fedrigo, O.; Damas, J.; Formenti, G.; Koren, S.; Uliano-Silva, M.; Chow, W.; Fungtammasan, A.; Kim, J.; et al. Towards complete and error-free genome assemblies of all vertebrate species. Nature 2021, 592, 737–746. [Google Scholar] [CrossRef] [Scilit]
- Lewin, H.A.; Robinson, G.E.; Kress, W.J.; Baker, W.J.; Coddington, J.; Crandall, K.A.; Durbin, R.; Edwards, S.V.; Forest, F.; Gilbert, M.T.P.; et al. Earth BioGenome Project: Sequencing life for the future of life. Proc. Natl. Acad. Sci. USA 2018, 115, 4325–4333. [Google Scholar] [CrossRef] [Scilit]
- Yang, Z.; Guarracino, A.; Biggs, P.J.; Black, M.A.; Ismail, N.; Wold, J.R.; Merriman, T.R.; Prins, P.; Garrison, E.; de Ligt, J. Pangenome graphs in infectious disease: A comprehensive genetic variation analysis of Neisseria meningitidis leveraging Oxford Nanopore long reads. Front. Genet. 2023, 14, 1225248. [Google Scholar] [CrossRef] [Scilit]
- Hickey, G.; Monlong, J.; Ebler, J.; Novak, A.M.; Eizenga, J.M.; Gao, Y.; Marschall, T.; Li, H.; Paten, B. Pangenome graph construction from genome alignments with Minigraph-Cactus. Nat. Biotechnol. 2024, 42, 663–673. [Google Scholar] [CrossRef] [Scilit]
- Sirén, J.; Monlong, J.; Chang, X.; Novak, A.M.; Eizenga, J.M.; Markello, C.; Sibbesen, J.A.; Hickey, G.; Chang, P.C.; Carroll, A.; et al. Pangenomics enables genotyping of known structural variants in 5202 diverse genomes. Science 2021, 374, abg8871. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Rautiainen, M.; Marschall, T. GraphAligner: Rapid and versatile sequence-to-graph alignment. Genome Biol. 2020, 21, 253. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Letcher, B.; Hunt, M.; Iqbal, Z. Gramtools enables multiscale variation analysis with genome graphs. Genome Biol. 2021, 22, 259. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Guarracino, A.; Heumos, S.; Nahnsen, S.; Prins, P.; Garrison, E. ODGI: Understanding pangenome graphs. Bioinformatics 2022, 38, 3319–3326. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Etzion, T. Sequences and the de Bruijn Graph: Properties, Constructions, and Applications; Elsevier: Amsterdam, The Netherlands, 2024. [Google Scholar]
- Paten, B.; Diekhans, M.; Earl, D.; John, J.S.; Ma, J.; Suh, B.; Haussler, D. Cactus graphs for genome comparisons. J. Comput. Biol. 2011, 18, 469–481. [Google Scholar] [CrossRef] [Scilit]
- Gonnella, G.; Kurtz, S. RGFA: Powerful and convenient handling of assembly graphs. PeerJ 2016, 4, e2681. [Google Scholar] [CrossRef] [Scilit]
- Garrison, E.; Sirén, J.; Novak, A.M.; Hickey, G.; Eizenga, J.M.; Dawson, E.T.; Jones, W.; Garg, S.; Markello, C.; Lin, M.F.; et al. Variation graph toolkit improves read mapping by representing genetic variation in the reference. Nat. Biotechnol. 2018, 36, 875–879. [Google Scholar] [CrossRef] [Scilit]
- Wang, T.; Antonacci-Fulton, L.; Howe, K.; Lawson, H.A.; Lucas, J.K.; Phillippy, A.M.; Popejoy, A.B.; Asri, M.; Carson, C.; Chaisson, M.J.; et al. The Human Pangenome Project: A global resource to map genomic diversity. Nature 2022, 604, 437–446. [Google Scholar] [CrossRef] [Scilit]
- Novak, A.M.; Garrison, E.; Paten, B. A graph extension of the positional Burrows–Wheeler transform and its applications. Algorithms Mol. Biol. 2017, 12, 18. [Google Scholar] [CrossRef] [Scilit]
- Heumos, S.; Guarracino, A.; Schmelzle, J.N.M.; Li, J.; Zhang, Z.; Hagmann, J.; Nahnsen, S.; Prins, P.; Garrison, E. Pangenome graph layout by path-guided stochastic gradient descent. Bioinformatics 2024, 40, btae363. [Google Scholar] [CrossRef] [Scilit]
- Manuweera, B.; Mudge, J.; Kahanda, I.; Mumey, B.; Ramaraj, T.; Cleary, A. Pangenome-wide association studies with frequented regions. In Proceedings of the 10th ACM International Conference on Bioinformatics, Computational Biology and Health Informatics, Niagara Falls, NY, USA, 7–10 September 2019; ACM: New York, NY, USA, 2019; pp. 627–632. [Google Scholar]
- Ding, W.; Baumdicker, F.; Neher, R.A. panX: Pan-genome analysis and exploration. Nucleic Acids Res. 2018, 46, e5. [Google Scholar] [CrossRef] [Scilit]
- Tonkin-Hill, G.; MacAlasdair, N.; Ruis, C.; Weimann, A.; Horesh, G.; Lees, J.A.; Gladstone, R.A.; Lo, S.; Beaudoin, C.; Floto, R.A.; et al. Producing polished prokaryotic pangenomes with the Panaroo pipeline. Genome Biol. 2020, 21, 180. [Google Scholar] [CrossRef] [Scilit]
- Woodhouse, M.R.; Cannon, E.K.; Portwood, J.L.; Harper, L.C.; Gardiner, J.M.; Schaeffer, M.L.; Andorf, C.M. A pan-genomic approach to genome databases using maize as a model system. BMC Plant Biol. 2021, 21, 385. [Google Scholar] [CrossRef] [Scilit]
- MacNish, T.R.; Al-Mamun, H.A.; Bayer, P.E.; McPhan, C.; Fernandez, C.G.T.; Upadhyaya, S.R.; Liu, S.; Batley, J.; Parkin, I.A.; Sharpe, A.G.; et al. Brassica Panache: A multi-species graph pangenome representing presence absence variation across forty-one Brassica genomes. Plant Genome 2025, 18, e20535. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Hamilton, J.P.; Li, C.; Buell, C.R. The rice genome annotation project: An updated database for mining the rice genome. Nucleic Acids Res. 2025, 53, D1614–D1622. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Kim, M.; Cha, I.T.; Lee, K.E.; Li, M.; Park, S.J. Pangenome analysis provides insights into the genetic diversity, metabolic versatility, and evolution of the genus Flavobacterium. Microbiol. Spectr. 2023, 11, e01003-23. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wendel, J.F.; Cronn, R.C. Polyploidy and the evolutionary history of cotton. Adv. Agron. 2003, 87, 139–186. [Google Scholar]
- Zattera, M.L.; Bruschi, D.P. Transposable elements as a source of novel repetitive DNA in the eukaryote genome. Cells 2022, 11, 3373. [Google Scholar] [CrossRef] [Scilit]
- Springer, N.M.; Ying, K.; Fu, Y.; Ji, T.; Yeh, C.T.; Jia, Y.; Wu, W.; Richmond, T.; Kitzman, J.; Rosenbaum, H.; et al. Maize inbreds exhibit high levels of copy number variation (CNV) and presence/absence variation (PAV) in genome content. PLoS Genet. 2009, 5, e1000734. [Google Scholar] [CrossRef] [Scilit]
- Sasaki, T.; Burr, B. International Rice Genome Sequencing Project: The effort to completely sequence the rice genome. Curr. Opin. Plant Biol. 2000, 3, 138–142. [Google Scholar] [CrossRef] [Scilit]
- Sibbesen, J.A.; Eizenga, J.M.; Novak, A.M.; Sirén, J.; Chang, X.; Garrison, E.; Paten, B. Haplotype-aware pantranscriptome analyses using spliced pangenome graphs. Nat. Methods 2023, 20, 239–247. [Google Scholar] [CrossRef] [Scilit]
- He, X.; Qi, Z.; Liu, Z.; Chang, X.; Zhang, X.; Li, J.; Wang, M. Pangenome analysis reveals transposon-driven genome evolution in cotton. BMC Biol. 2024, 22, 92. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Downing, T. Approaches to studying virus pangenome variation graphs. Genom. Proteom. Bioinform. 2026, qzag003. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Kane, M. CYP2D6 overview: Allele and phenotype frequencies. In Medical Genetics Summaries [Internet]; National Center for Biotechnology Information: Bethesda, MD, USA, 2025. [Google Scholar]
- Zhao, K.; Xue, H.; Li, G.; Chitikineni, A.; Fan, Y.; Cao, Z.; Dong, X.; Lu, H.; Zhao, K.; Zhang, L.; et al. Pangenome analysis reveals structural variation associated with seed size and weight traits in peanut. Nat. Genet. 2025, 57, 1250–1261. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Johansson, M.H.; Bortolaia, V.; Tansirichaiya, S.; Aarestrup, F.M.; Roberts, A.P.; Petersen, T.N. Detection of mobile genetic elements associated with antibiotic resistance in Salmonella enterica using a newly developed web tool: MobileElementFinder. J. Antimicrob. Chemother. 2021, 76, 101–109. [Google Scholar] [CrossRef] [Scilit]
- Ebler, J.; Ebert, P.; Clarke, W.E.; Rausch, T.; Audano, P.A.; Houwaart, T.; Mao, Y.; Korbel, J.O.; Eichler, E.E.; Zody, M.C.; et al. Pangenome-based genome inference allows efficient and accurate genotyping across a wide spectrum of variant classes. Nat. Genet. 2022, 54, 518–525. [Google Scholar] [CrossRef] [Scilit]
- Snipen, L.; Angell, I.L.; Rognes, T.; Rudi, K. Reduced metagenome sequencing for strain-resolution taxonomic profiles. Microbiome 2021, 9, 79. [Google Scholar] [CrossRef] [Scilit]
- Brouqui, P.; Matsumoto, K. Bacteriology and phylogeny of Anaplasmataceae. Ricketts. Dis. 2007, 191–210. [Google Scholar]
- Dereeper, A.; Summo, M.; Meyer, D.F. PanExplorer: A web-based tool for exploratory analysis and visualization of bacterial pan-genomes. Bioinformatics 2022, 38, 4412–4414. [Google Scholar] [CrossRef] [Scilit]
- Li, H.; Durbin, R. Fast and accurate short read alignment with Burrows-Wheeler transform. Bioinformatics 2009, 25, 1754–1760. [Google Scholar] [CrossRef] [Scilit]
- Li, H. Minimap2: Pairwise alignment for nucleotide sequences. Bioinformatics 2018, 34, 3094–3100. [Google Scholar] [CrossRef] [Scilit]
- Sengupta, A.; Ismail, F.N. Software as a Medical Device: Design and Compliance. In Proceedings of the 2025 17th International Conference on Computer and Automation Engineering (ICCAE), Perth, Australia, 20–22 March 2025; IEEE: Piscataway, NJ, USA, 2025; pp. 321–325. [Google Scholar]
- Danecek, P.; Bonfield, J.K.; Liddle, J.; Marshall, J.; Ohan, V.; Pollard, M.O.; Whitwham, A.; Keane, T.; McCarthy, S.A.; Davies, R.M.; et al. Twelve years of SAMtools and BCFtools. GigaScience 2021, 10, giab008. [Google Scholar] [CrossRef] [Scilit]
- Ismail, F.N.; Sengupta, A. Revolutionizing Bacterial Genomics: Graph-Based Strategies for Improved Variant Identification In Proceedings of the Applied Computing for Software and Smart Systems; Chaki, R., Cortesi, A., Saeed, K., Chaki, N., Deb, N., Eds.; Springer: Cham, Switzerland, 2026; pp. 107–122. [Google Scholar]
- Ismail, F.N.; Amarasoma, S. Mars: Simplifying Bioinformatics Workflows Through a Containerized Approach to Tool Integration and Management. Bioinform. Adv. 2025, 5, vbaf074. [Google Scholar] [CrossRef] [Scilit]
- Ismail, F.N.; Amarasoma, S. An Integrated Genomics Workflow Tool: Simulating Reads, Evaluating Read Alignments, and Optimizing Variant Calling Algorithms. In Proceedings of the 2024 12th International Conference on Bioinformatics and Computational Biology (ICBCB), Tokyo, Japan, 18–21 March 2024; IEEE: Piscataway, NJ, USA, 2024; pp. 49–56. [Google Scholar]
- Chen, Z. Attention is not all you need anymore. arXiv 2023, arXiv:2308.07661. [Google Scholar] [CrossRef] [Scilit]
- Ji, Y.; Zhou, Z.; Liu, H.; Davuluri, R.V. DNABERT: Pre-trained Bidirectional Encoder Representations from Transformers model for DNA-language in genome. Bioinformatics 2021, 37, 2112–2120. [Google Scholar] [CrossRef] [Scilit]
- Ismail, F.N.; Sengupta, A.; Amarasoma, S. Deep Learning for Regulatory Genomics: A Survey of Models, Challenges, and Applications. Bioinform. Adv. 2025, vbaf271. [Google Scholar] [CrossRef] [Scilit]
- Dalla-Torre, H.; Gonzalez, L.; Mendoza-Revilla, J.; Lopez Carranza, N.; Grzywaczewski, A.H.; Oteri, F.; Dallago, C.; Trop, E.; de Almeida, B.P.; Sirelkhatim, H.; et al. Nucleotide Transformer: Building and evaluating robust foundation models for human genomics. Nat. Methods 2025, 22, 287–297. [Google Scholar] [CrossRef] [Scilit]
| Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |