1. Introduction
In recent years, impressive progress has been made regarding the digitalization of the banking sector, transforming the way financial transactions are conducted. As a result, customers can be efficiently served, but at the same time, the risk of exposing institutions to increasingly sophisticated fraud schemes is being posed. In fact, the electronic transaction systems provided by banks can produce large volumes of transactions in a short period of time, thus creating a data-rich environment, which may, however, involve the possibility of the simultaneous existence of malicious activity that is difficult to detect.
Consequently, a new challenge has arisen for conventional fraud detection systems, since they are mainly based on static rules and predefined thresholds, which do not always lead to successful fraud detection. Simple rules can detect common anomalies, such as transactions exceeding a fixed threshold. However, they are likely to be inadequate for ever-evolving fraud tactics, potentially generating a large number of false positives [
1]. Thus, to address these limitations, the research community is turning to the examination of anomaly detection techniques based on machine learning. While supervised classification methods need labeled instances of fraud, anomaly detection techniques model the usual behavior of accounts, users, or systems and identify statistically significant deviations as potential threats. This can help detect fraud in cases where fraudulent transactions are rare and dynamic, or in cases where future attack strategies may not resemble previous incidents [
2,
3]. In the literature, we find a variety of methods for anomaly detection, such as statistical profiling, clustering, Bayesian inference, and the use of neural networks, many of which succeed in detecting financial fraud [
4,
5].
Recent studies have proposed hybrid and ensemble models that can combine multiple algorithms in order to improve accuracy and reduce false positives [
6]. Moreover, Wu and Wang [
7] show that locally interpretable anomaly detection approaches can improve transparency and, as a result, trust in financial institutions. Furthermore, Hashemi et al. [
8] support that machine learning techniques are pivotal for large-scale banking fraud detection, advocating for algorithmic approaches that scale with growing transaction databases. The study indicates that by implementing machine learning, banks can streamline operations while proactively minimizing their exposure to fraudulent activities. Moreover, fraud detection in the banking sector has been significantly enhanced by advances in neural network-based models, which enable automated analysis of large-scale transactional data. Recent research shows that neural network-driven frameworks can improve efficacy in large-scale banking environments, which are often characterized by evolving fraud tactics and noisy transaction data [
9,
10]. Unlike traditional rule-based systems, deep learning models, such as recurrent neural networks, multilayer perceptrons, and hybrid architectures, are able to identify complex, non-linear transaction patterns [
11,
12]. Such systems can continuously learn the behavioral profiles of accounts and adapt to concept drift, thus enabling financial institutions to proactively mitigate fraud risks and to maintain efficient, automated transaction-monitoring processes.
Despite these advancements, the majority of the existing literature examines supervised or model-centric frameworks, with fewer studies exploring the operational behavior of industrial, unsupervised anomaly detection platforms that are deployed under real-world banking constraints—a gap that the present study seeks to address. It should also be noted that, in addition to the literature directly related to transaction fraud detection methods, there exist recent studies that focus on the importance of analyzing extreme events and behaviors that are located in the tails of the distribution. For instance, Ul-Durar et al. [
13] highlight that significant but unusual economic phenomena are not always adequately captured by average-based approaches. Although this approach is econometric, the same conceptual issue is also examined by our study, but from an operational perspective, by evaluating an industrial, unsupervised system that uses machine learning for the efficient real-time detection of extreme and abnormal transaction behaviors in the banking sector.
Recently, several approaches have been developed in the industry that apply these concepts at scale, such as Elastic Machine Learning (Elastic ML), an unsupervised anomaly detection framework integrated into the Elastic Stack. Elastic ML constructs probabilistic models based on historical data, accounts for seasonal and trend variations in time-series, and evaluates incoming observations against these expected patterns to generate anomaly scores (see the Elastic Documentation, version 8, for an explicit analysis. The Elastic Documentation can be found here:
https://www.elastic.co/docs/explore-analyze/machine-learning/anomaly-detection/ml-getting-started (accessed on 22 June 2025)). By disaggregating analyses by entity, such as account identifiers, personalized profiles can be developed, resulting in increased fraud detection accuracy due to a reduction in false positives. Operational teams can be further supported through the use of powerful visualization tools, such as swim lanes and anomaly explorers, thus having a good visualization of statistical results as interpretable information.
Despite the extensive utilization of Elastic ML in production environments, its behavior, limitations and applicability to financial fraud scenarios remain largely unexplored in the academic literature. In the present study, the first evaluation of Elastic Machine Learning (Elastic ML) in the context of banking transaction fraud detection is presented. Our study advances the existing literature by providing a methodological system-level evaluation of an industrial, unsupervised anomaly detection platform under heterogeneous fraud archetypes that simulate realistic banking scenarios. Specifically, through the systematic examination of anomaly score behavior and the isolation of distinct statistical deviation dimensions, the present study contributes to a deeper understanding of how probabilistic anomaly detection mechanisms operate in real-world banking systems (In real banking environments, the timely and correct detection of fraud is crucial. Thus, our work focuses on a structured methodology (i.e., Elastic ML) instead of a new algorithm that may have problems in scalability. Often, new academic algorithms are computationally intensive when processing millions of transactions in real-time, while structured methodological frameworks, such as Elastic ML, are already optimized for this high-velocity environment. Furthermore, our work provides an empirical baseline for future researchers or practitioners to improve the algorithm behind Elastic ML). The evaluation was conducted across three heterogeneous fraud typologies within a unified framework to: (i) detect suspicious accounts using multiple IPs to perform banking transactions, (ii) detect suspicious transactions originating from multiple countries in short time intervals, (iii) detect unusually high transaction amounts relative to the account history. Our methodological analysis demonstrates how a single unsupervised framework can adapt to different behavioral dimensions without requiring labeled fraud data to detect suspicious transactions. The results indicate that the proposed application effectively captures anomalies in the dataset, thereby assisting financial institutions and banks in enhancing their cybersecurity measures.
The rest of this paper is structured as follows.
Section 2 describes the simulated datasets that were created and the implemented methodology.
Section 3 presents the application of Elastic ML in three different use cases, based on the simulated datasets, and analyzes the results. Finally,
Section 4 summarizes the contributions of this study.
2. Data and Methodology
In order to detect any existing anomalies in financial transactions, a methodological framework that can be both adaptive and scalable is required. Traditional systems that are usually based on thresholds, such as the existence of a maximum allowed price or a restriction on the geographical locations, can detect simple cases of fraudulent transactions but often lead to excessive false positives. As a result, they are not effective in detecting and capturing evolving fraud methods.
To overcome these obstacles, we examine the use of unsupervised anomaly detection platforms and the adoption of machine learning techniques for detecting heterogeneous forms of fraud in realistic banking environments. In particular, in our study, we aim to evaluate the operational behavior of an unsupervised anomaly detection system (i.e., Elastic ML) under different categories of statistical deviation. For this purpose, three fraud scenarios were constructed, each of which isolates a distinct statistical deviation dimension.
These three specific scenarios were not chosen arbitrarily. On the contrary, they reflect realistic fraud-related patterns that are extensively observed both in the banking sector and cybercrime investigations. Moreover, each scenario approaches fraud from a different statistical perspective: behavioral/network-based, spatial and magnitude-based.
This methodological design allows us to examine each type of anomaly separately and analyze how the unsupervised system responds to different anomaly categories within a unified framework. This controlled isolation enhances the analytical transparency, interpretability and reproducibility of the experimental process. At the same time, the three scenarios can be seen as modular components of a broader detection framework, which, in real banking environments, can operate simultaneously and across multiple behavioral dimensions in parallel.
In order to detect anomalies, Elastic ML uses a statistical method based on probability. It starts by “learning” the normal profile of data and then checks each new observation to see how likely it is to occur. If data changes over time, and in order to be able to distinguish what is expected from what is not expected, the system takes into account the general trend and seasonality. Also, to be able to detect both sudden peaks and persistent deviations, it performs analysis both at individual time intervals and over a longer period. Finally, each observation is given an anomaly score from 0 to 100: the higher the score, the more likely the event is to be indicative of suspicious or irregular behavior, and therefore the more important the observation is considered for further investigation in cases of fraud detection.
The key to the whole process is, of course, the use of appropriate data. In order to evaluate the operational behavior of an unsupervised, behavior-based anomaly detection framework under realistic conditions, Elastic was supplied with AI-generated datasets that simulate realistic banking transactions involving potential fraud scenarios, a deliberate methodological choice that was driven by the strict privacy, regulatory, and security constraints that limit access to real-world banking data (No primary data were collected or processed in the context of this study, as such activities would conflict with privacy and data protection requirements. In particular, the collection and processing of original personal data fall under the scope of the General Data Protection Regulation (GDPR) (Regulation (EU) 2016/679), which establishes a strict legal framework for the protection of personal data). For example, several accounts were matched to typical patterns of stable transactions, while others showed unusual IP activity, cross-border transactions or extreme fluctuations in transaction values. This data was then imported into Elastic, where it was stored to create the appropriate anomaly detection jobs. To construct jobs that would investigate the existence of anomalies, their appropriate initial parameterization was required, i.e., the definition of how the model would interpret the data. Thus, we proceeded to define the function to be applied, the time period of the transactions to be monitored, and the entities to be monitored. Appropriate detection functions were used, such as high_distinct_count and high_mean, so that the entities’ behavior could be examined. Also, to determine the sensitivity of the model to sudden spikes, we used appropriate bucket spans that defined the time window for the collection of the observations (e.g., five minutes or fifteen minutes). In addition, account_id was assigned as a partition field, so that accounts could be modeled independently, while the use of influencers allowed for the direct attribution of anomalies to specific entities.
It should be noted that the parameterization of Elastic ML in this study was designed to align the analysis with the dynamics of the examined bank fraud scenarios, so as to realistically simulate common fraud tactics in banking transactions rather than explicitly optimize detection accuracy. The selection of the bucket span and the detector functions determines the temporal and behavioral scale on which deviations are evaluated regarding their normal behavior. For instance, sudden IP bursts may manifest within shorter time windows, whereas more persistent deviations require larger aggregation periods.
We also used Kibana’s visualization suite that offers advanced visual representations, in order to interpret statistical results and translate them into patterns of potential fraud. In particular, to precisely inspect when and where deviations occurred, we used the Swim Lane and Anomaly Explorer views, which demonstrate a timeline of anomalies across accounts. Furthermore, to make a specific comparison of actual versus typical values for a single account along with the corresponding anomaly score, we used the Single Metric Viewer. Finally, to make cross-account comparisons and isolate outliers, we used aggregated dashboards.
Overall, Elastic ML maintained a consistent methodological foundation based on statistical profiling and anomaly scoring, although it was adapted to three different types of fraudulent behaviors. Thus, this methodological framework clearly demonstrates how anomaly detection can overcome the obstacles that may exist in rigid threshold systems and proceed to a more dynamic, data-driven model.
3. Empirical Results and Interpretation
In the current study, we examined three different scenarios of simulated fraud detection in banking transactions, and it was thus demonstrated that Elastic ML is able to inspect diverse types of cyber fraud in the banking sector. Specifically, we explored three heterogeneous fraud typologies within a unified framework.
- -
In Use Case 1, we analyzed the number of distinct IP addresses related to each account at five-minute time intervals.
- -
In Use Case 2, we analyzed the geographical diversity in transactions over fifteen-minute time intervals.
- -
In Use Case 3, we analyzed unusually high transaction amounts at fifteen-minute time intervals.
3.1. Anomaly Detection in Account Activity: Identifying Multiple IP Access Patterns
Firstly, to investigate the effectiveness of machine learning tools in the detection of unusual patterns in the banking sector, we created a set of 1500 simulated transactions which included diverse user accounts, a wide range of IP addresses and transaction timestamps spanning eight hours (from 1 January 2023 00:00:00 to 1 January 2023 08:00:00). The objective was to provide a realistic test environment for detecting transactions by combining physical activity with intentionally suspicious scenarios.
The Elastic Machine Learning framework was then used, where the data was initially inserted. Afterwards, we created and configured an appropriate job, with the detector set to high_distinct_count (ip_address) and the partition field to account_id, so that each account would be modeled independently. The influencer field was also set to account_id so that anomalies would be attributed directly to the accounts involved. Also, the bucket span was set to five minutes so that the system could create a baseline of typical behavior over short periods of time. The main goal was to identify anomalies, i.e., cases where the number of unique IP addresses from a single account significantly exceeded its historical norm. After the job was run, the Anomaly Explorer feature clearly indicated an anomaly in account acc_47 on 1 January 2023, between 07:15 and 07:20. The swim lane representation was used to better visualize the results, where a sharp spike isolated to acc_47 was indicated. On the contrary, for the remaining accounts, there was no spike indicated as they seemed to remain within expected ranges (
Figure 1).
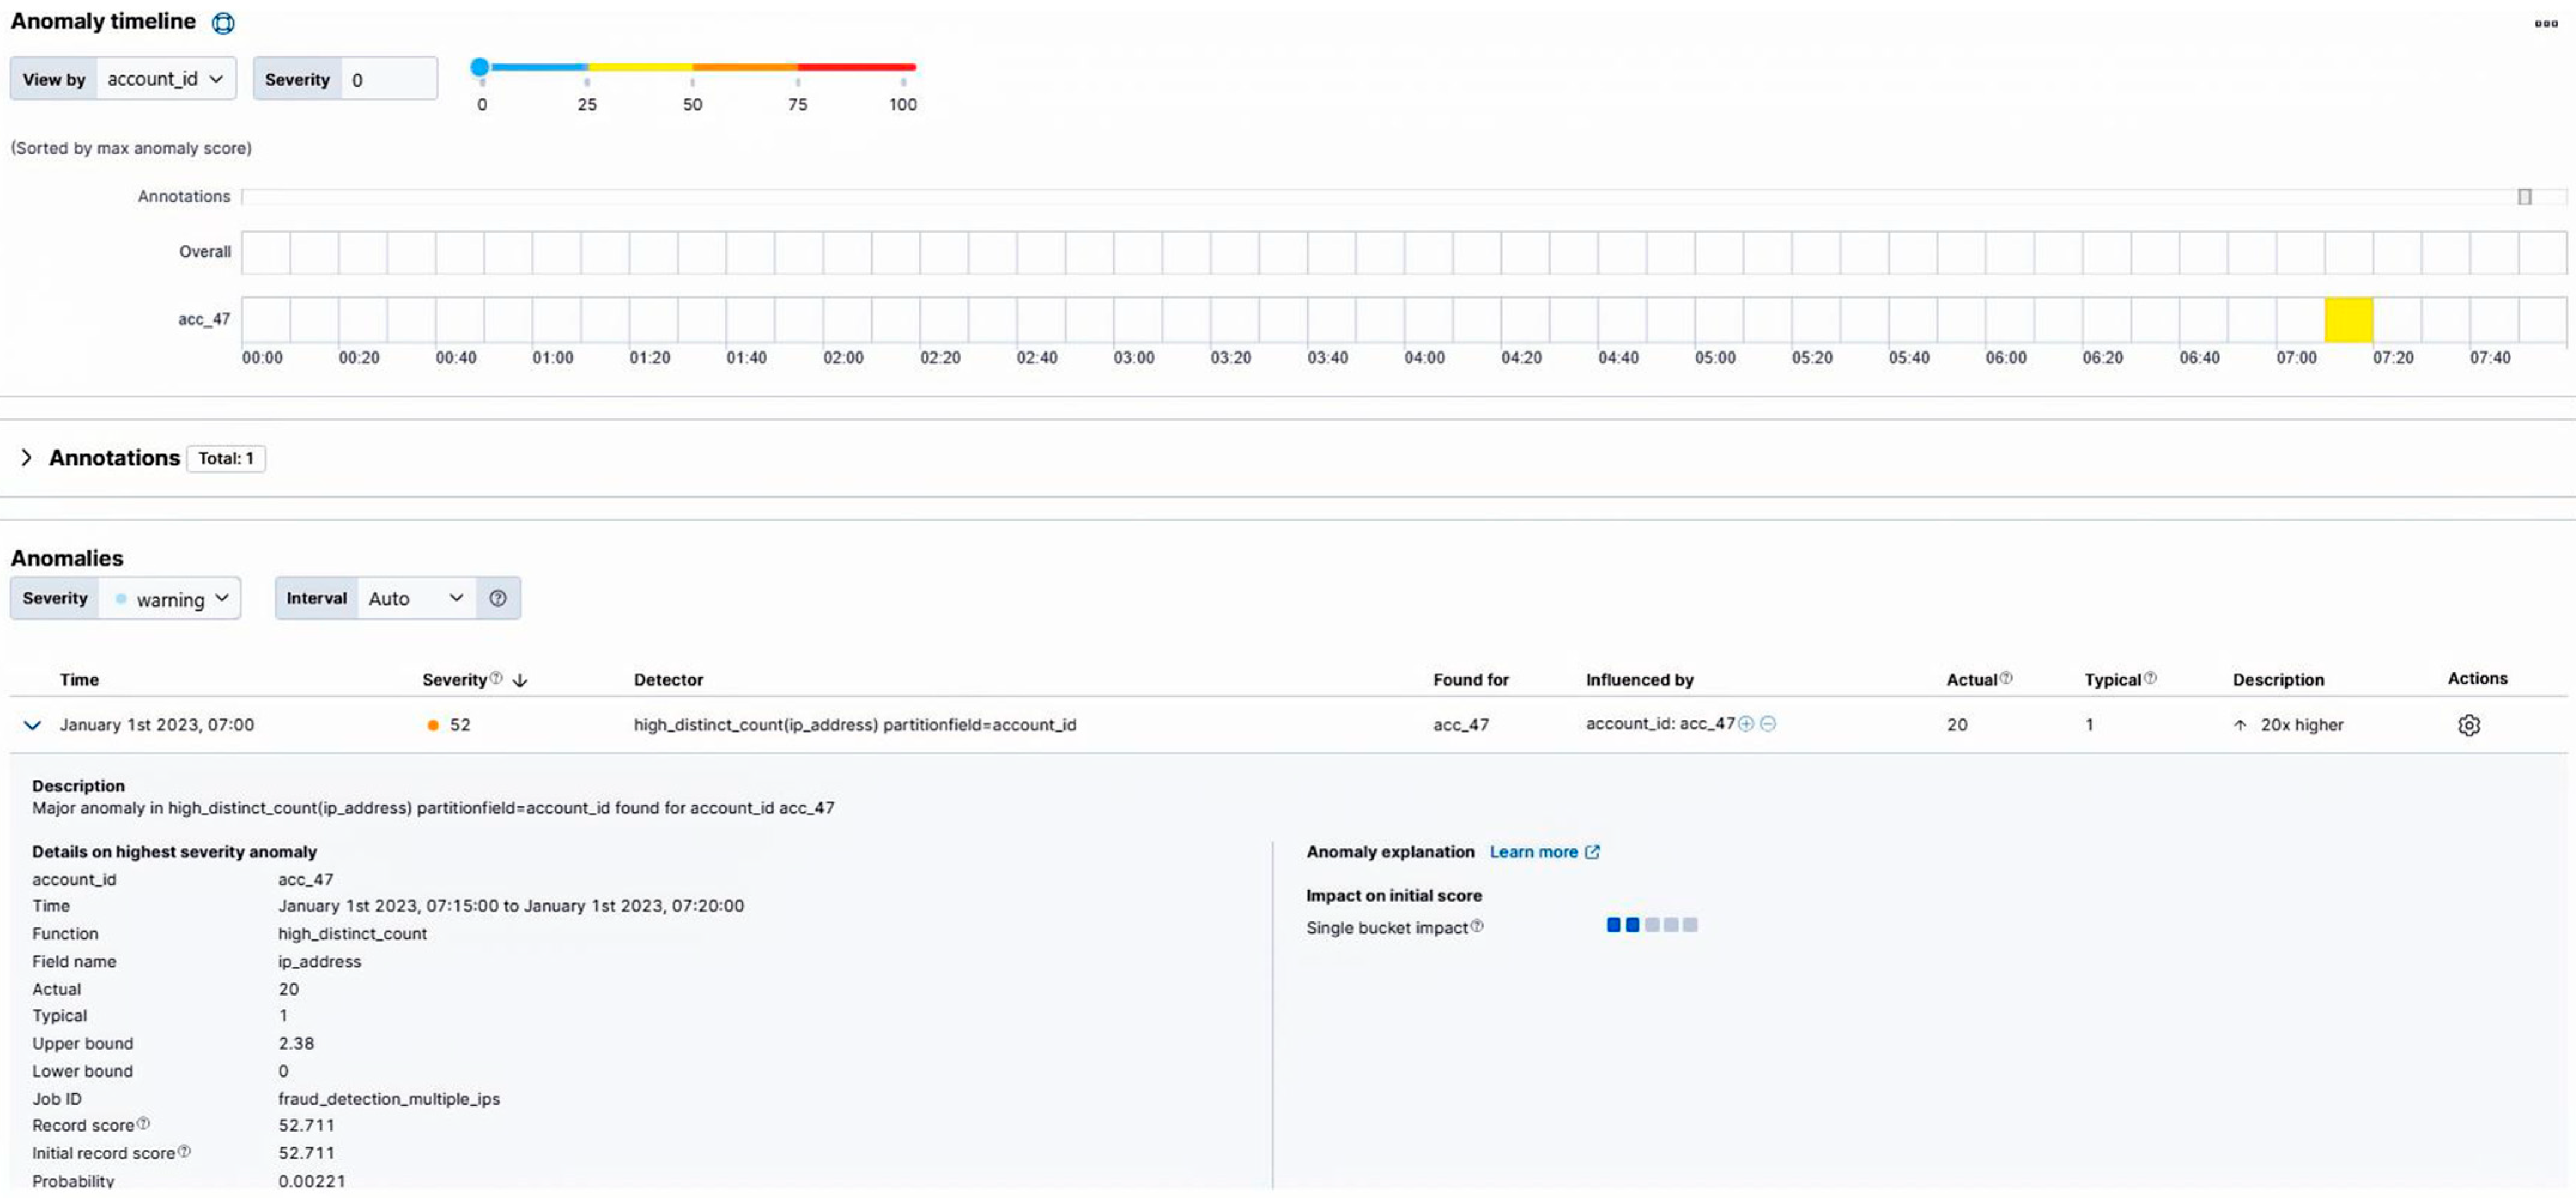
In order to provide a better interpretation of the results, we used the Single Metric Viewer, where it was found that during the above interval, the account was accessed from 20 distinct IP addresses, while it was usually accessed from single IP addresses in historical data. This sudden twenty-fold increase could indicate a clear deviation from the normal activity. Thus, it was placed in the category of high-severity findings, and the anomaly was assigned a score of 52 (
Figure 2).
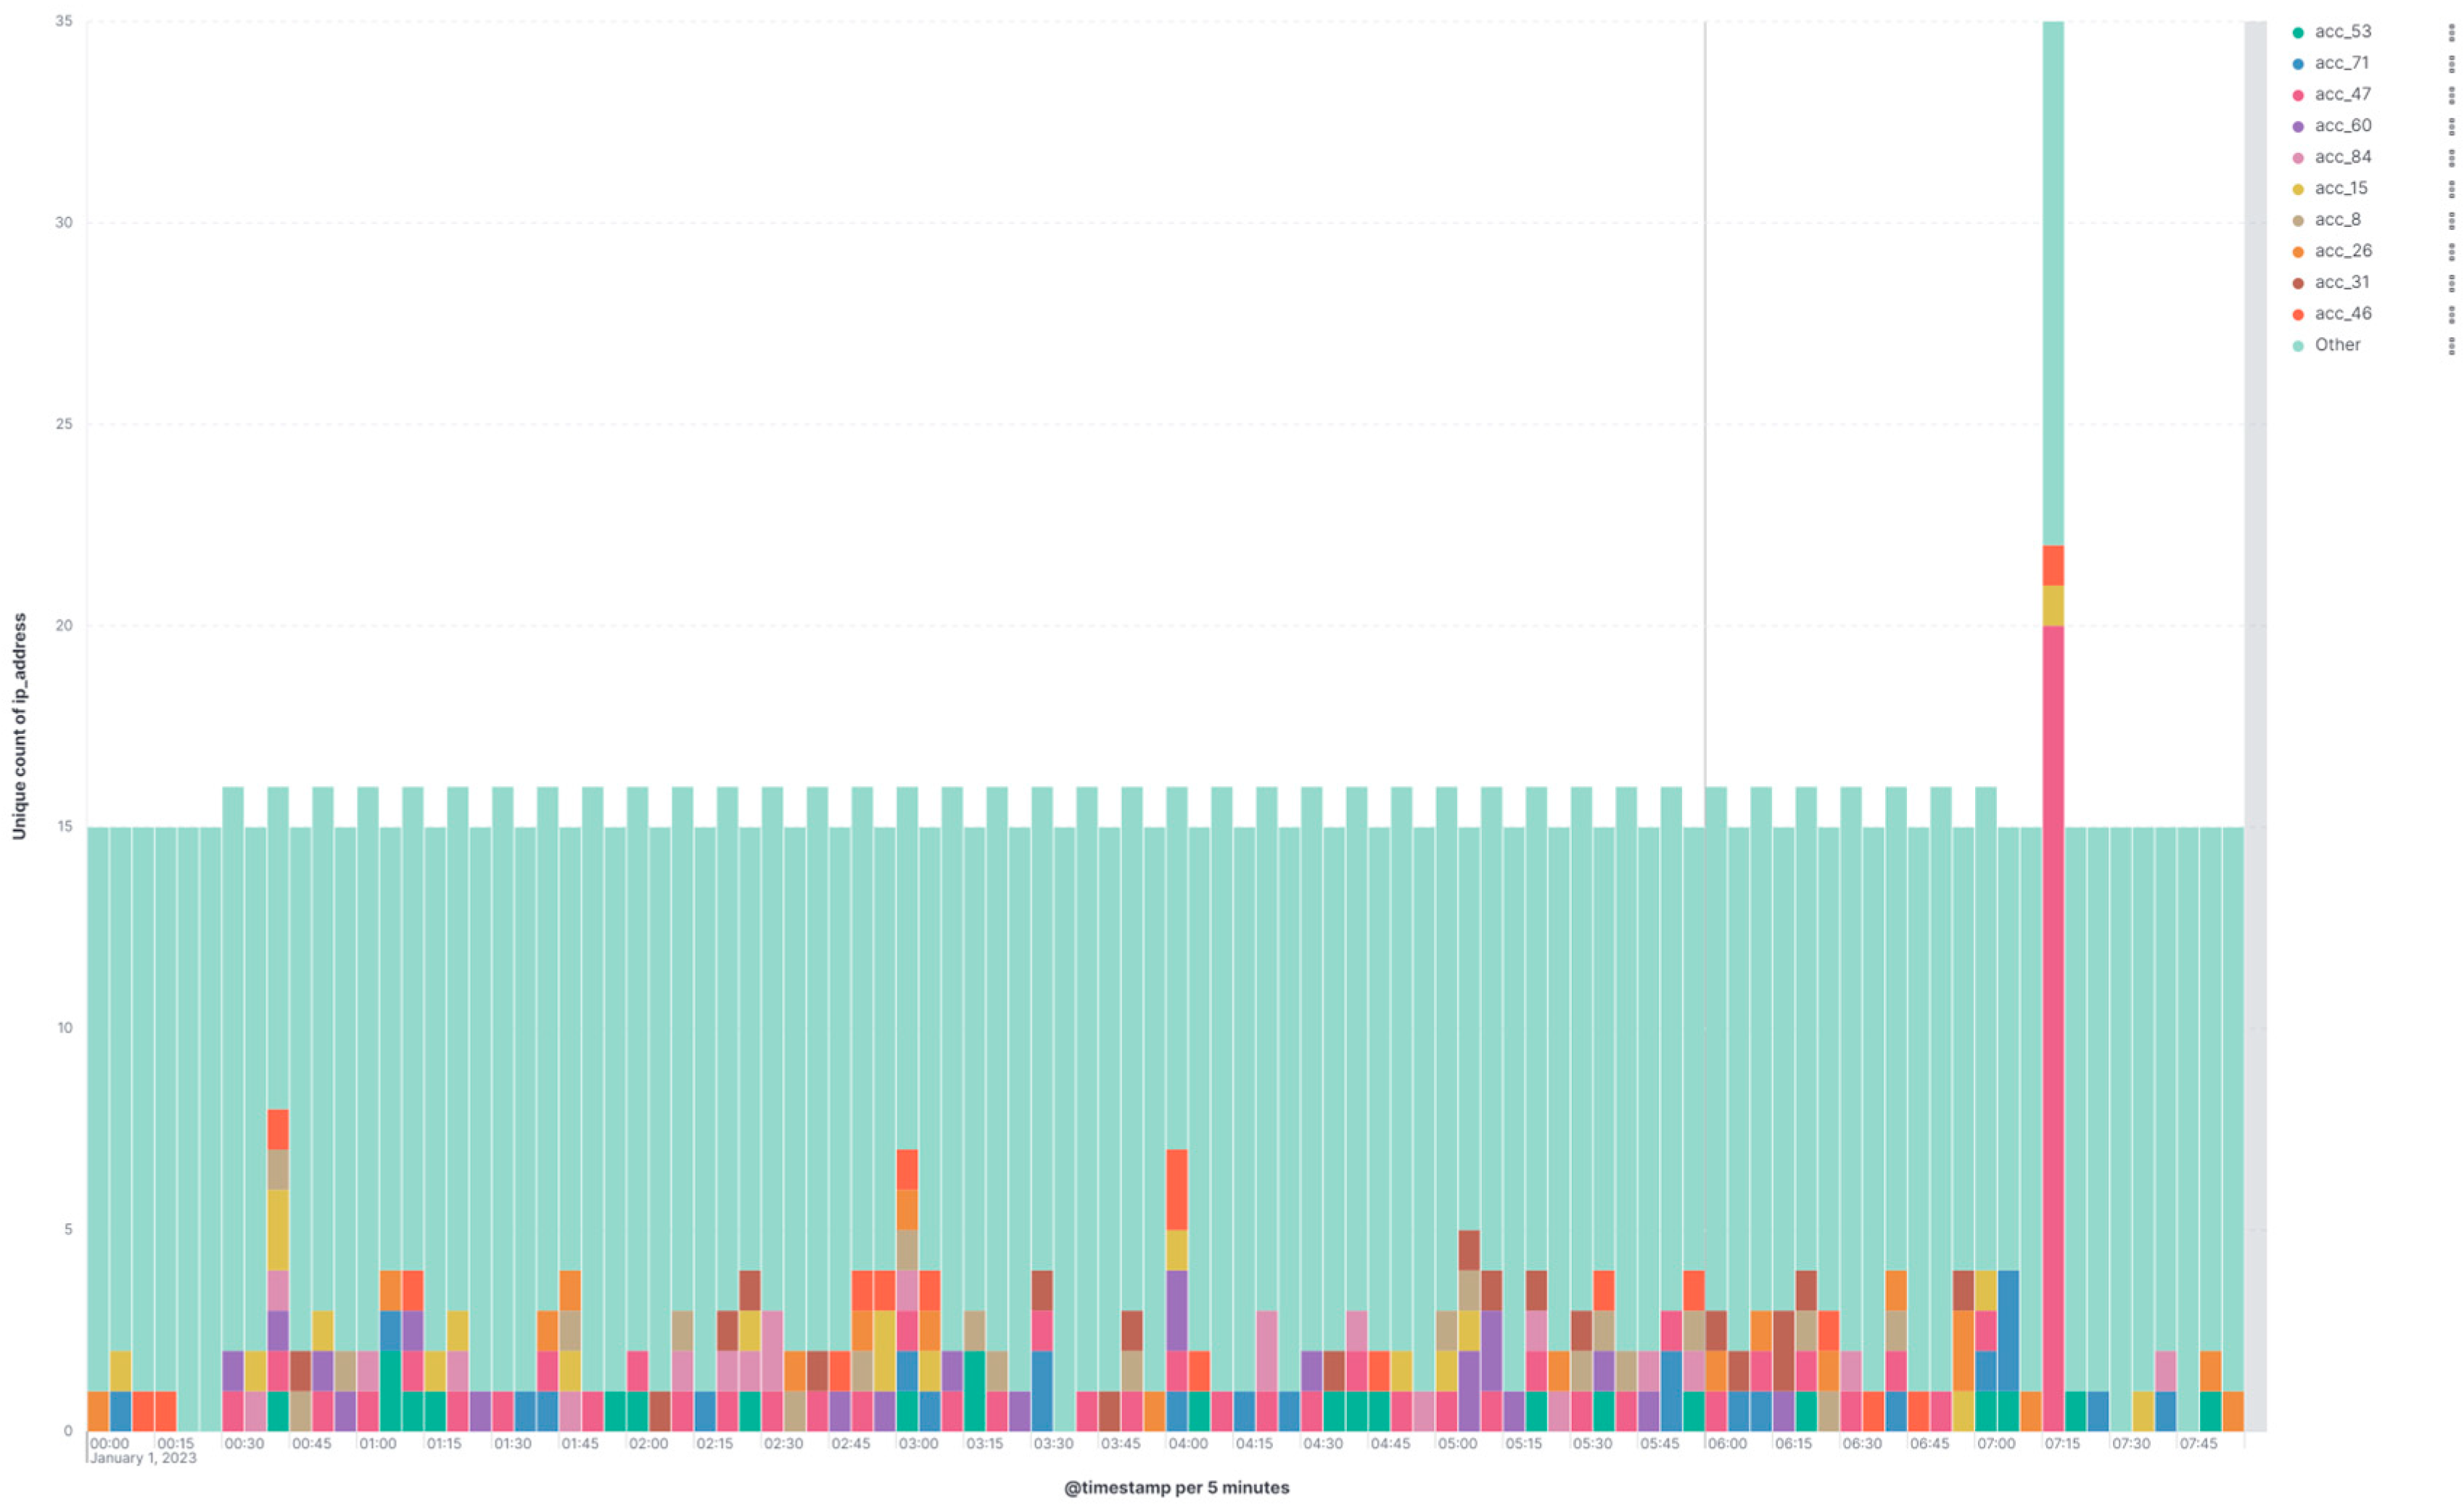
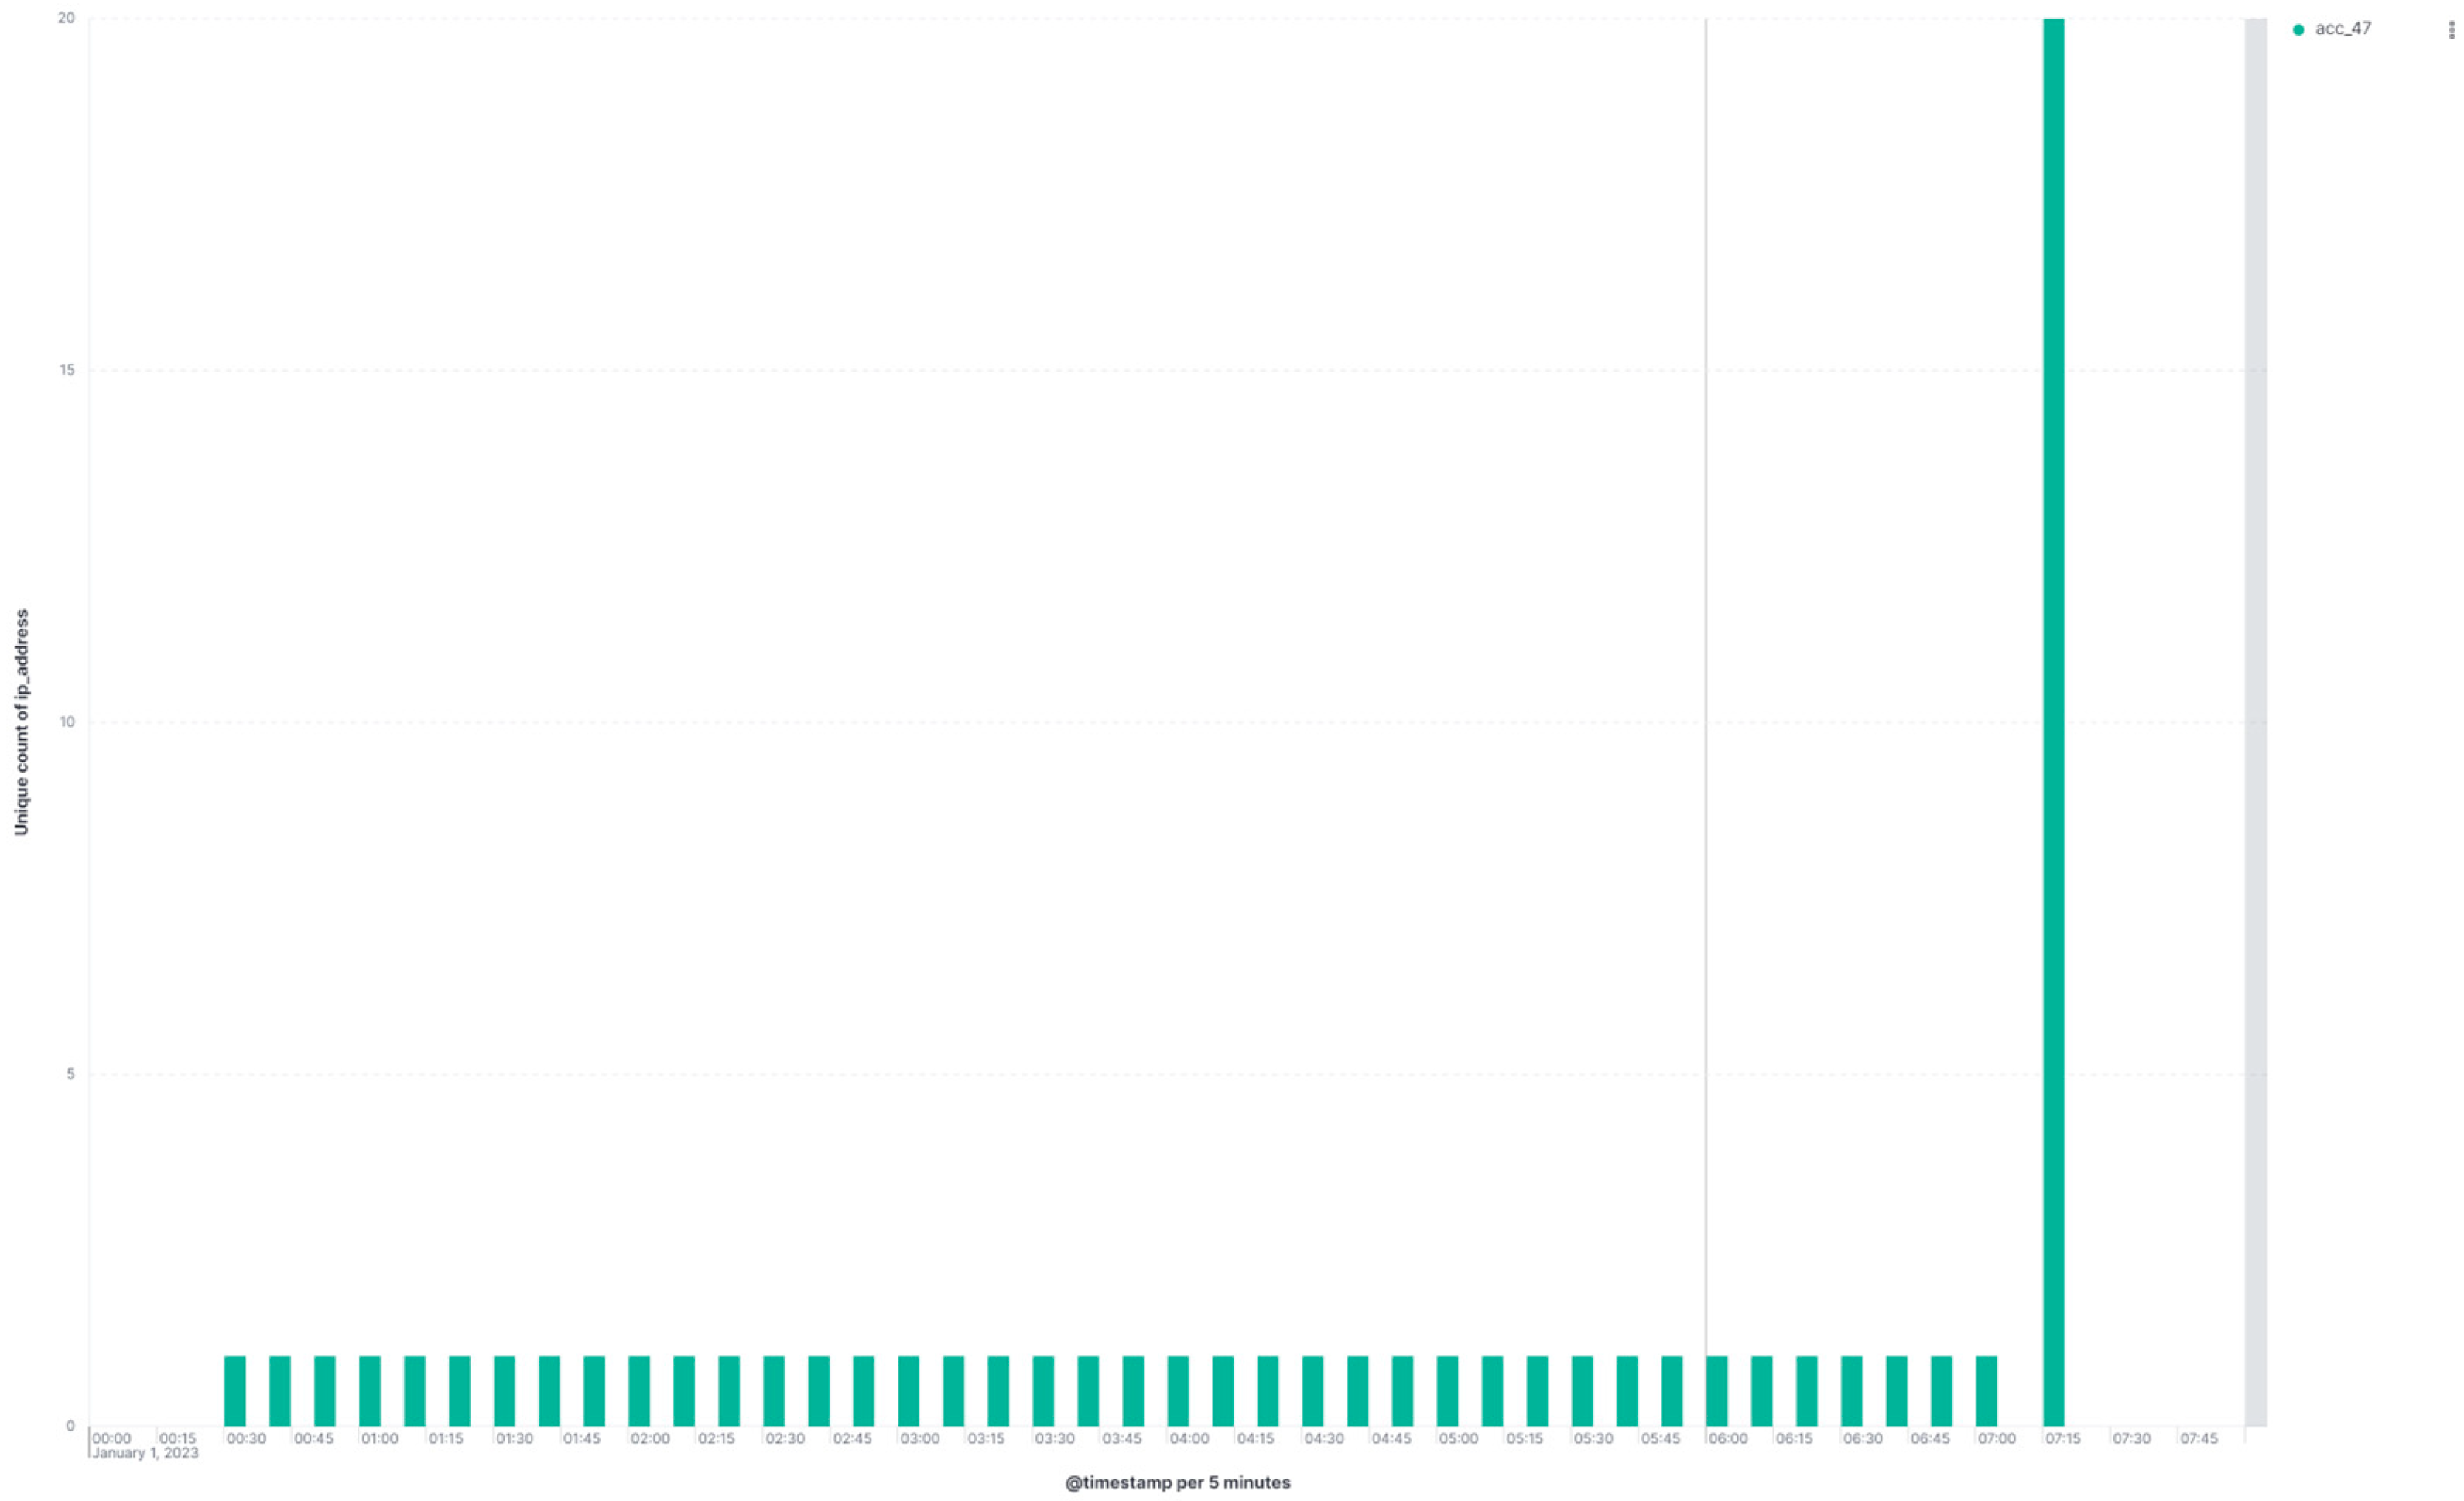
Similarly, a bar chart aggregating all accounts highlighted the unusual spike, which could be traced exclusively to acc_47 (see
Figure 3).
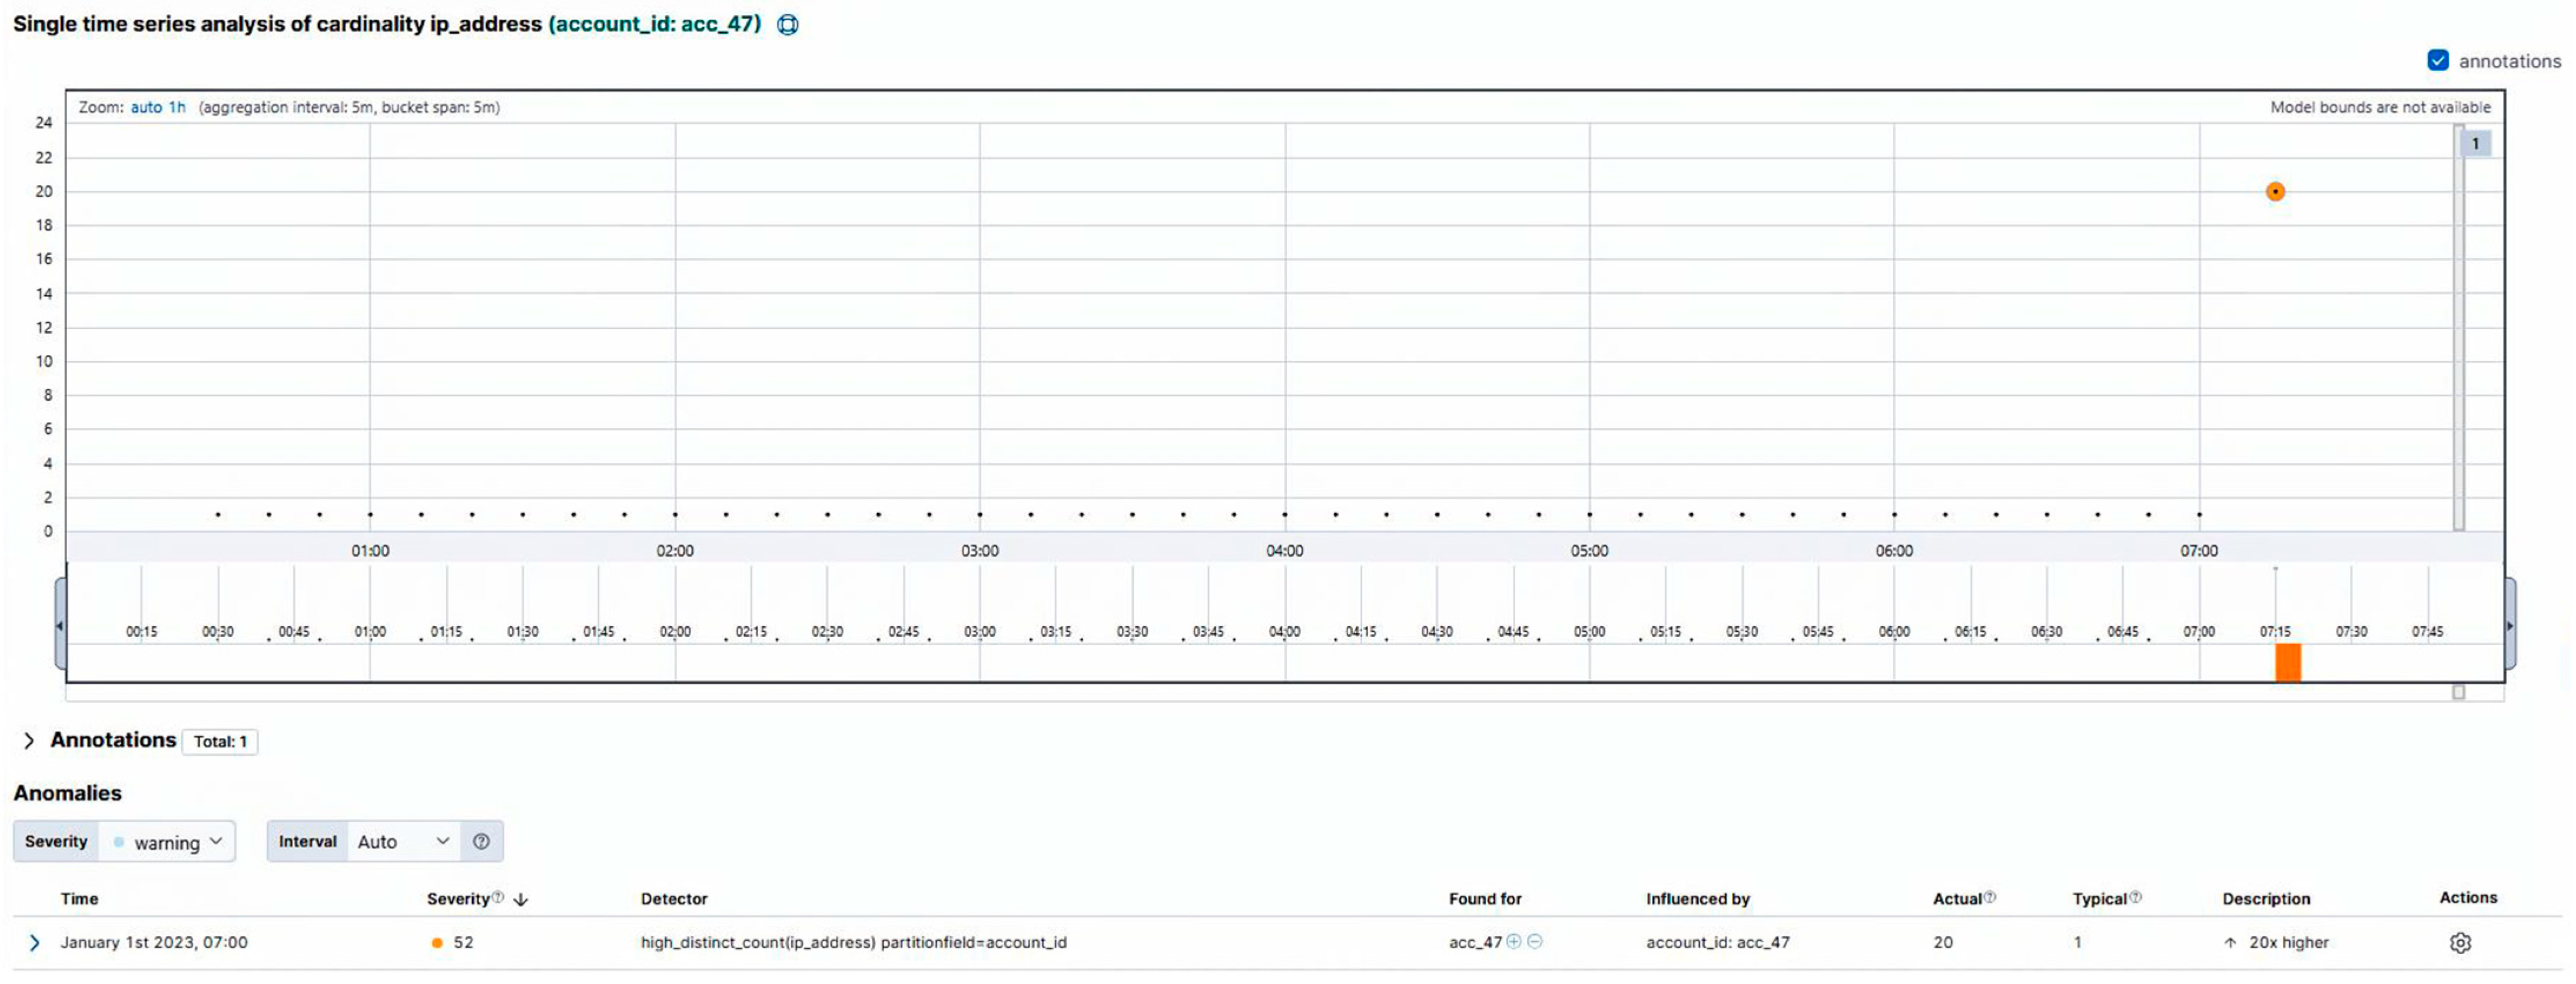
Also, if we examine only the behavior of account acc_47, we can get the visualization in
Figure 4, where it is clearly indicated that multiple IPs were recorded for this account only in the anomaly bucket (see
Figure 4).
From an operational point of view, this sudden increase in the number of IPs associated with an account during a short-term interval could indicate several suspicious activities, such as account takeover attempts, automated attacks (botnet-driven credential stuffing), use of rotating proxies or VPNs to cover traces, or simultaneous account usage by multiple individuals.
Overall, the detection of multiple IPs for a single account in a short 5 min time interval constitutes a strong deviation from the account’s normal behavior and could indicate fraudulent behavior. What is more, the optical representation of the results, together with the statistical data (Anomaly Score), gives us a strong indication for further investigation. Finally, the methodology that was used can ensure both the reproducibility of the results and applicability to real-world fraud detection scenarios.
3.2. Detecting Suspicious Transactions from Multiple Countries
In online banking fraud, investigating the geographical origin plays a crucial role. Case studies where, in a short period of time and for a single account, transactions originating from many different countries are conducted can be considered highly unusual. They usually indicate account takeover, VPN or proxy usage, or even mule-account activity. In order to investigate this scenario, a simulated banking data set was created, and Elastic Machine Learning anomaly detection was applied.
Initially, a suitable dataset of approximately 1000 transactions was created, including fields such as account ID, country of origin, timestamp, IP address, and transaction amount, spanning 21 h (from 1 January 2023 00:00:00 to 1 January 2023 20:30:00). Most transactions originated from a single country to reflect normal behavior. However, several accounts were appropriately configured. The objective was to inspect accounts that made transactions originating from an unusually large number of countries in short periods of time.
To analyze this data, an appropriate job was configured in Elastic ML with the detector set to high_distinct_count (country), the bucket span to fifteen minutes, and the partition field to account_id so that each account would be modeled separately. In addition, the influencer field was also set to account_id so that anomalies would be attributed directly to the accounts involved. The objective was to identify spikes in the number of countries that were associated with an account during these 15 min intervals.
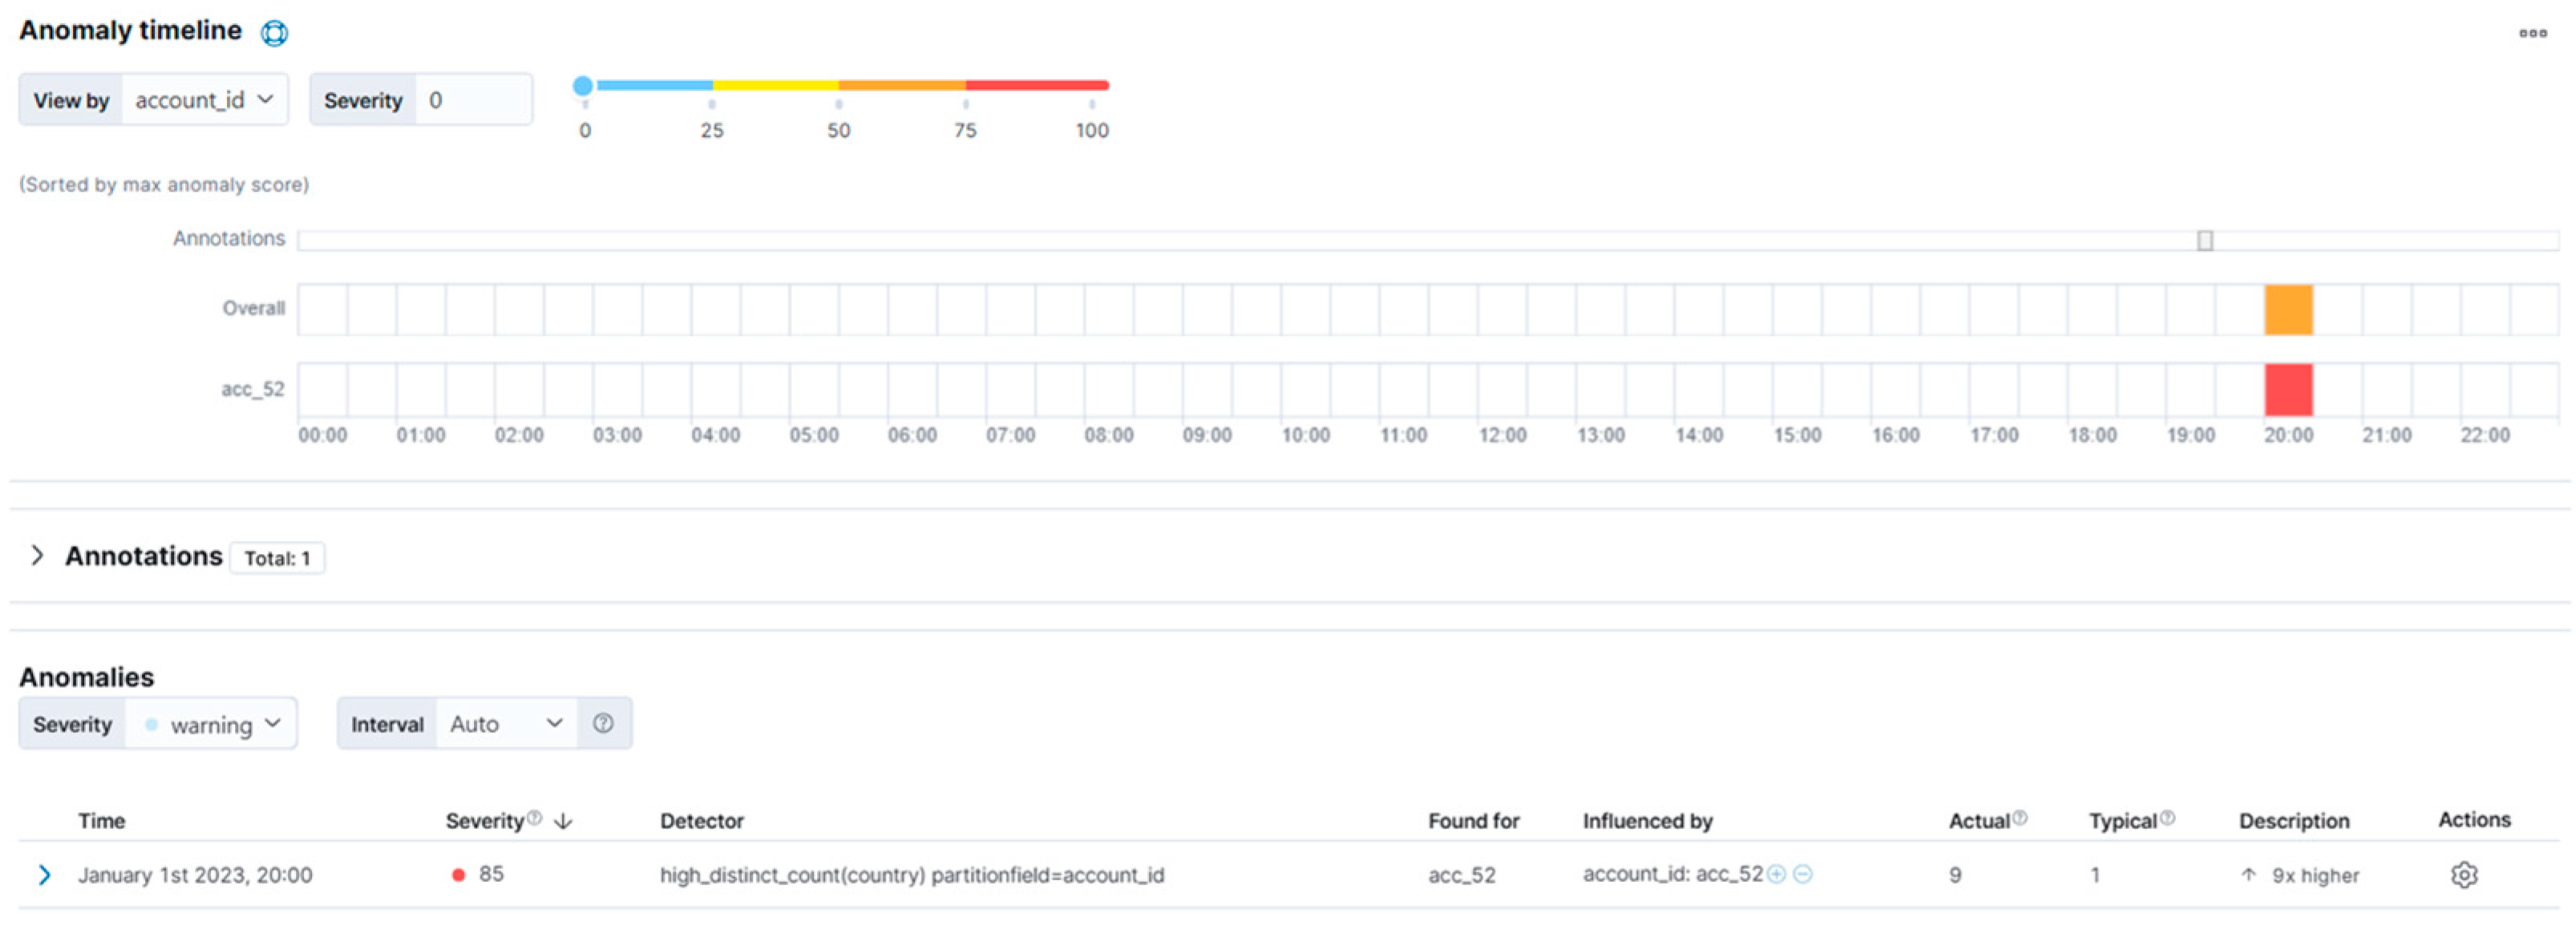
After the job was run, the Anomaly Explorer feature clearly indicated a significant anomaly in account acc_52 at 20:00. During this interval (from 20:00 to 20:15), transactions were found from nine distinct countries related to this account, much higher than the typical pattern of only one or two. This deviation was characterized as a high-severity anomaly, represented thus with red color in the Elastic Anomaly Explorer interface. The Actual vs. Typical comparison table reported a value of nine countries against a baseline of one, confirming a sharp departure from normal activity (see
Figure 5).
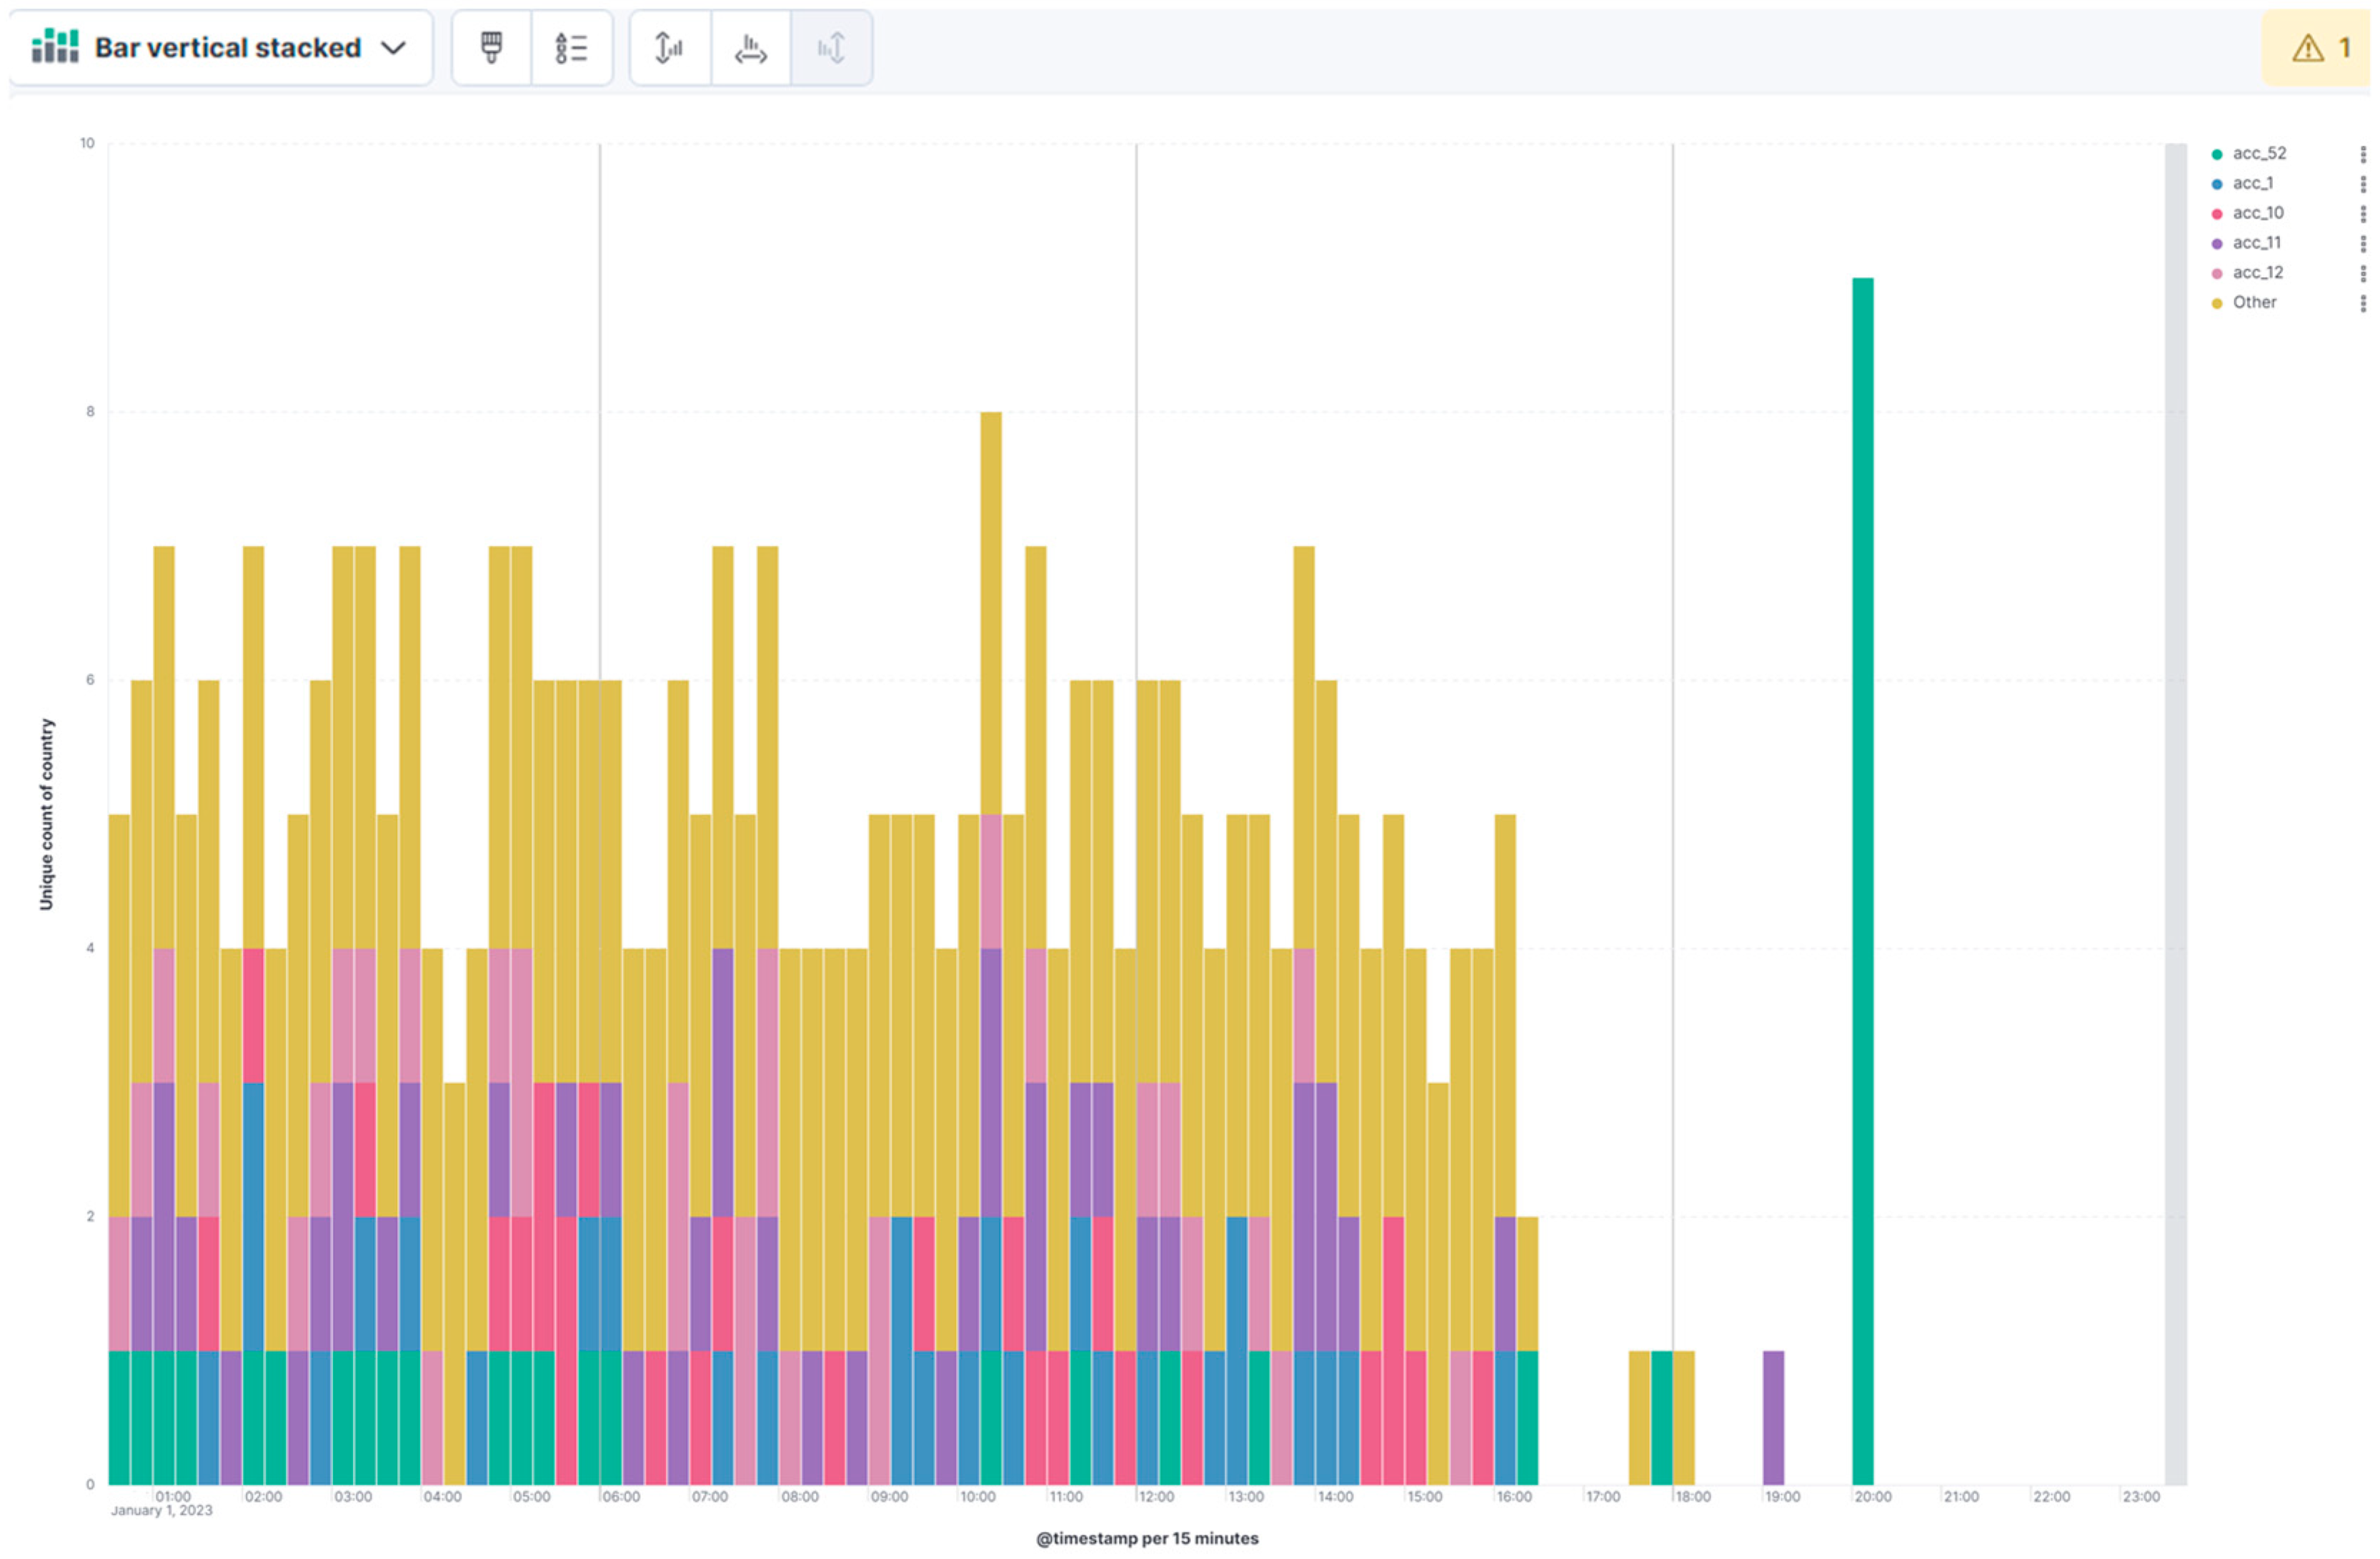
To further analyze this case, we used appropriate visualization tools on the Elastic framework, which provided further insight into the anomaly. A stacked bar chart across accounts was created, where it is clearly shown that the unusual behavior was associated only with acc_52, while other accounts maintained their usual behavior (see
Figure 6).
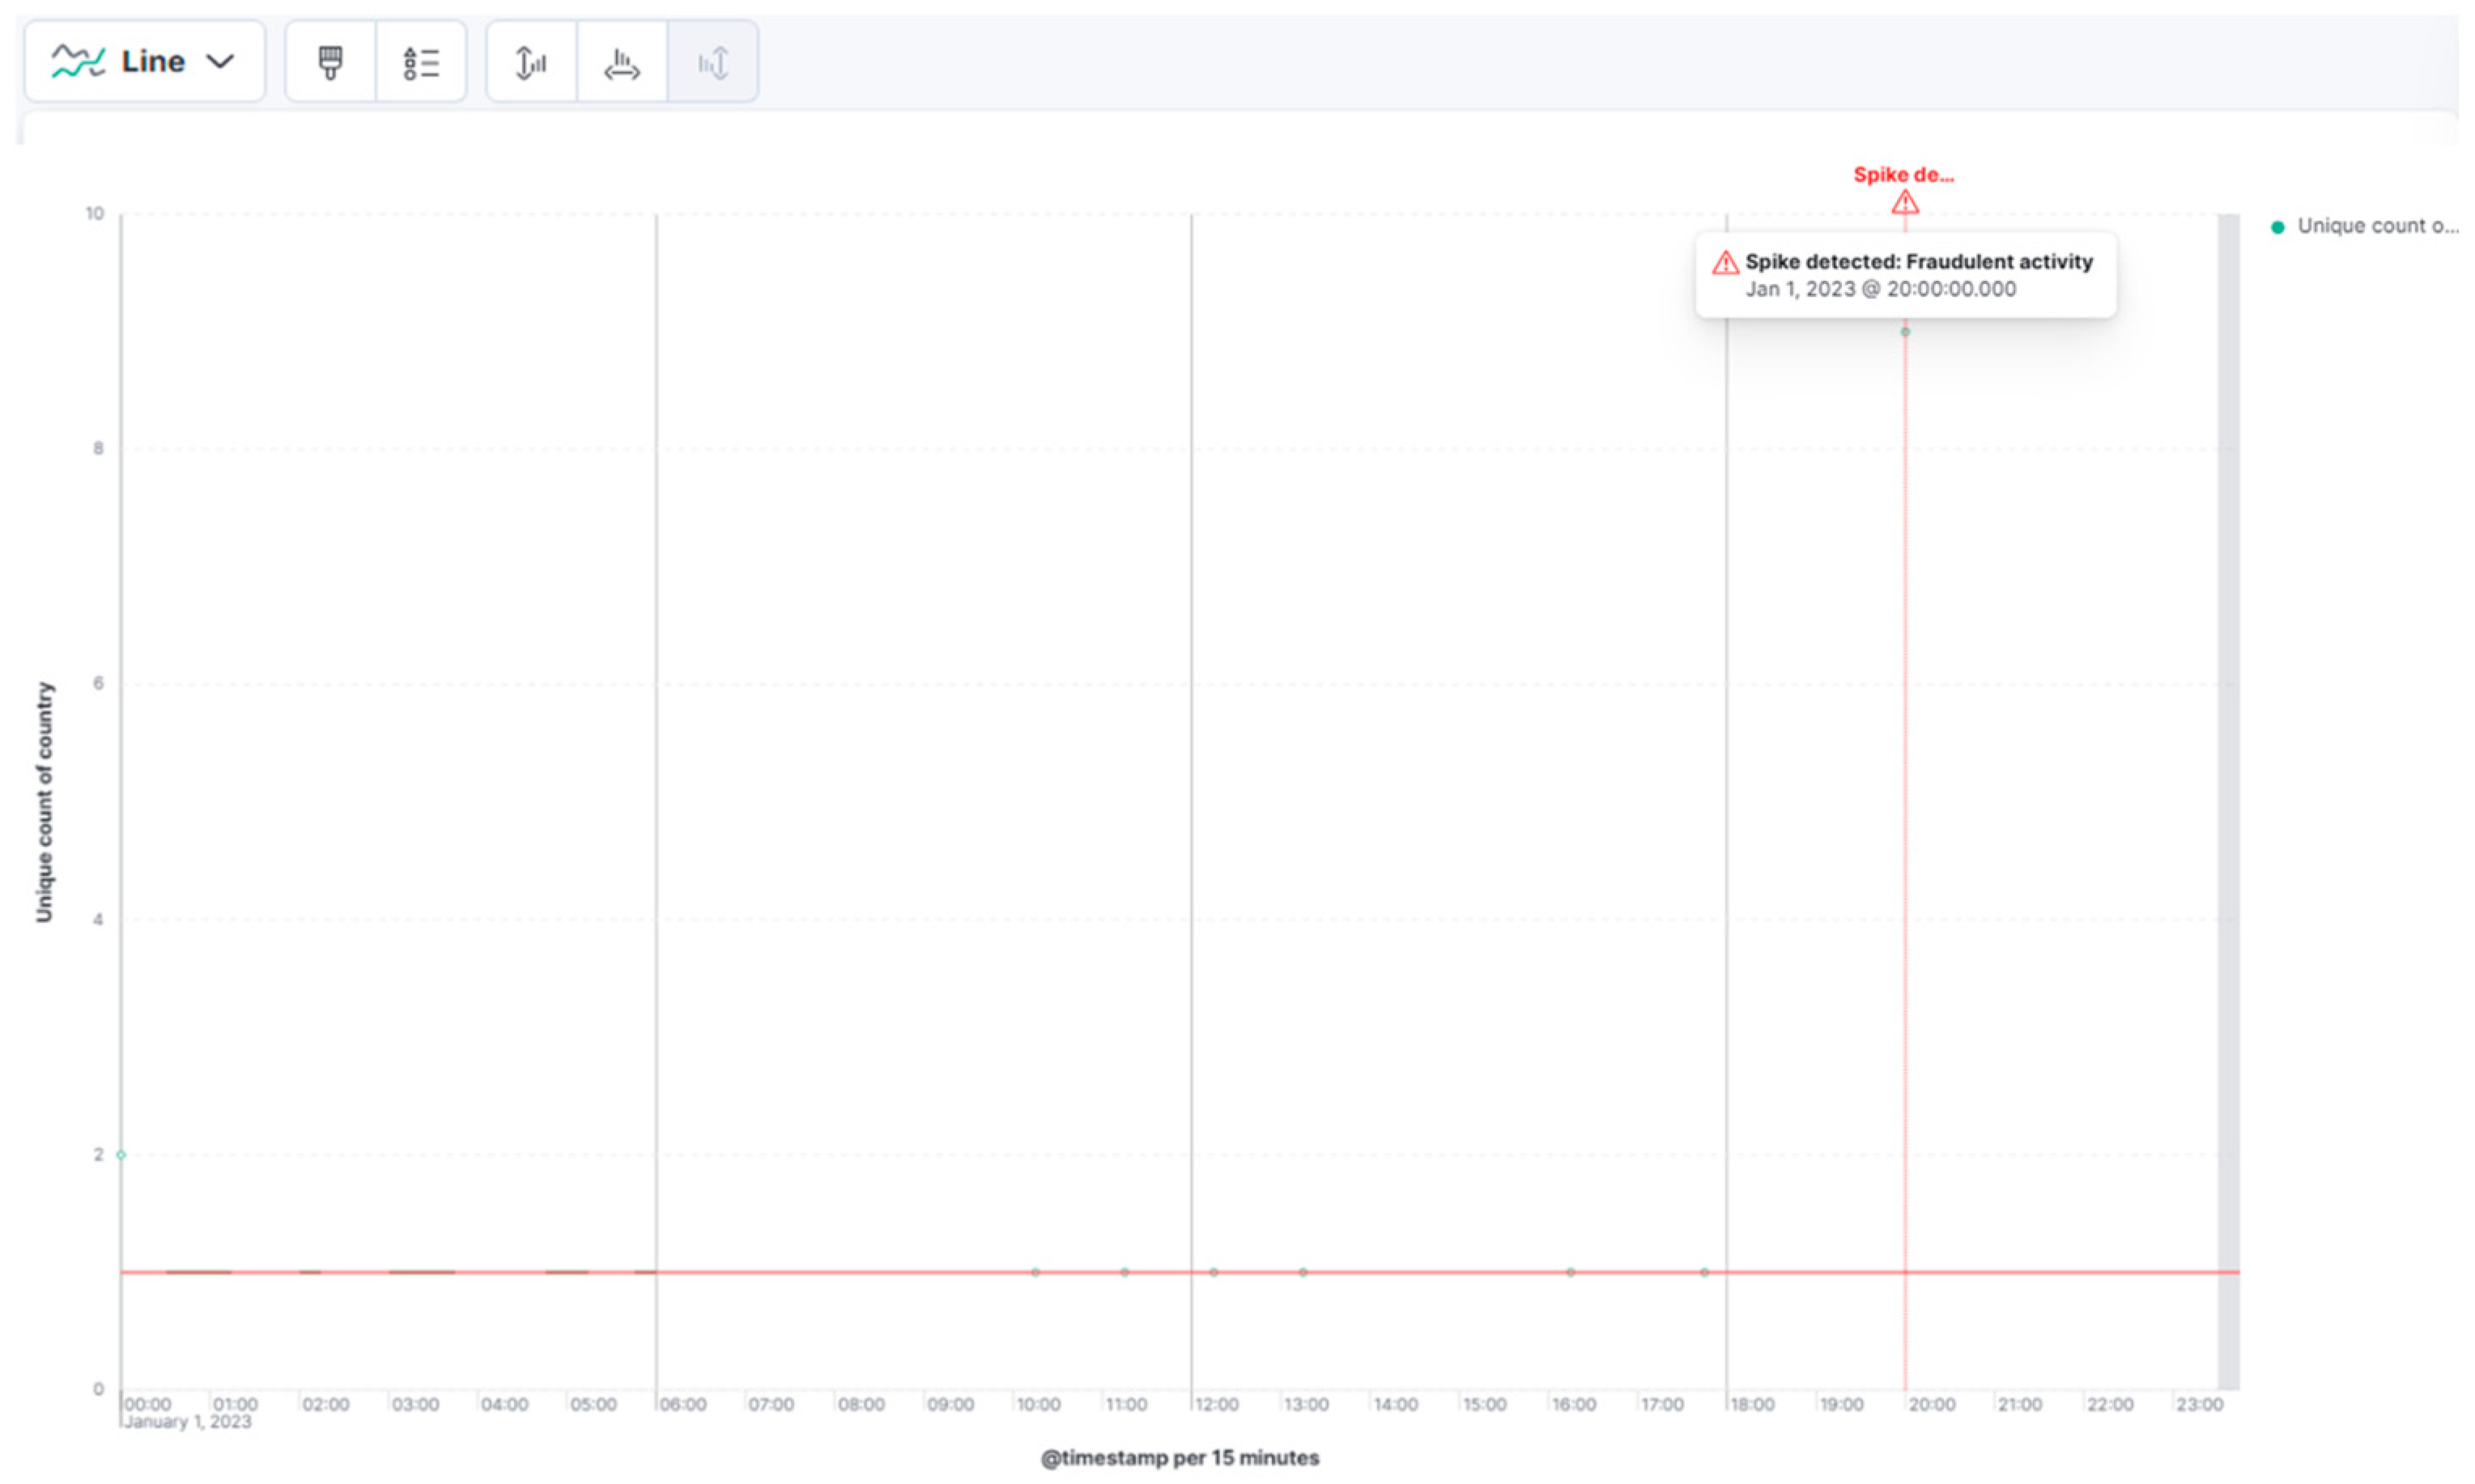
Also, in the time-series line chart, which tracks the evolution of the number of countries per account, a sharp spike for acc_52 during the 20:00 interval was confirmed, followed by a return to typical levels (see
Figure 7).
By applying such techniques, we can detect highly fraudulent activities, as it is rare, if not impossible, for a genuine, trusted customer to conduct banking transactions from many different countries within a few minutes. A possible interpretation could be the use of mule accounts to carry out coordinated fraud, the concealment of location through the use of proxy or VPN infrastructures, and the use of cross-directory credentials from different regions that have been compromised.
In conclusion, Elastic ML clearly identified the “multi-country fraud” scenario. The method is based on the difference between the actual and typical values calculated by the model. The system was able to identify a significant deviation from typical behavior, assigning it a high anomaly score, so that it could be further investigated. The finding can be used either for alerting (real-time detection) or for fraud investigation cases. From the financial institution’s perspective, detecting such a pattern could lead to an immediate transaction freeze or a manual review by the fraud team.
3.3. Detecting Anomalous High-Value Transactions by Account
In the third scenario, we analyzed simulated banking transactions to detect anomalies related to unusually high transaction amounts. As the usual activity of an account regarding transaction size follows a consistent pattern, possible sudden deviations are likely to be detected as an indication of fraud or money laundering. The main objective was to inspect accounts with unusual activity compared to their historical data.
A set of approximately 1000 simulated bank transactions over one month (January 2023) was created, with fields such as account ID, timestamp and transaction amount. In the majority of the accounts, stable transaction values were recorded, whereas in individual accounts, there were high transaction amounts recorded, which were different from the usual pattern.
To further examine the data, an anomaly detection job was appropriately configured in Elastic ML, with the detector set to high_mean (amount) and the split field defined as account_id. Also, the bucket span was set to fifteen minutes so that deviations in short time intervals could be captured. The main aim was to initially generate the behavioral profile for each account by calculating their typical transaction averages, and then detect possible deviations.
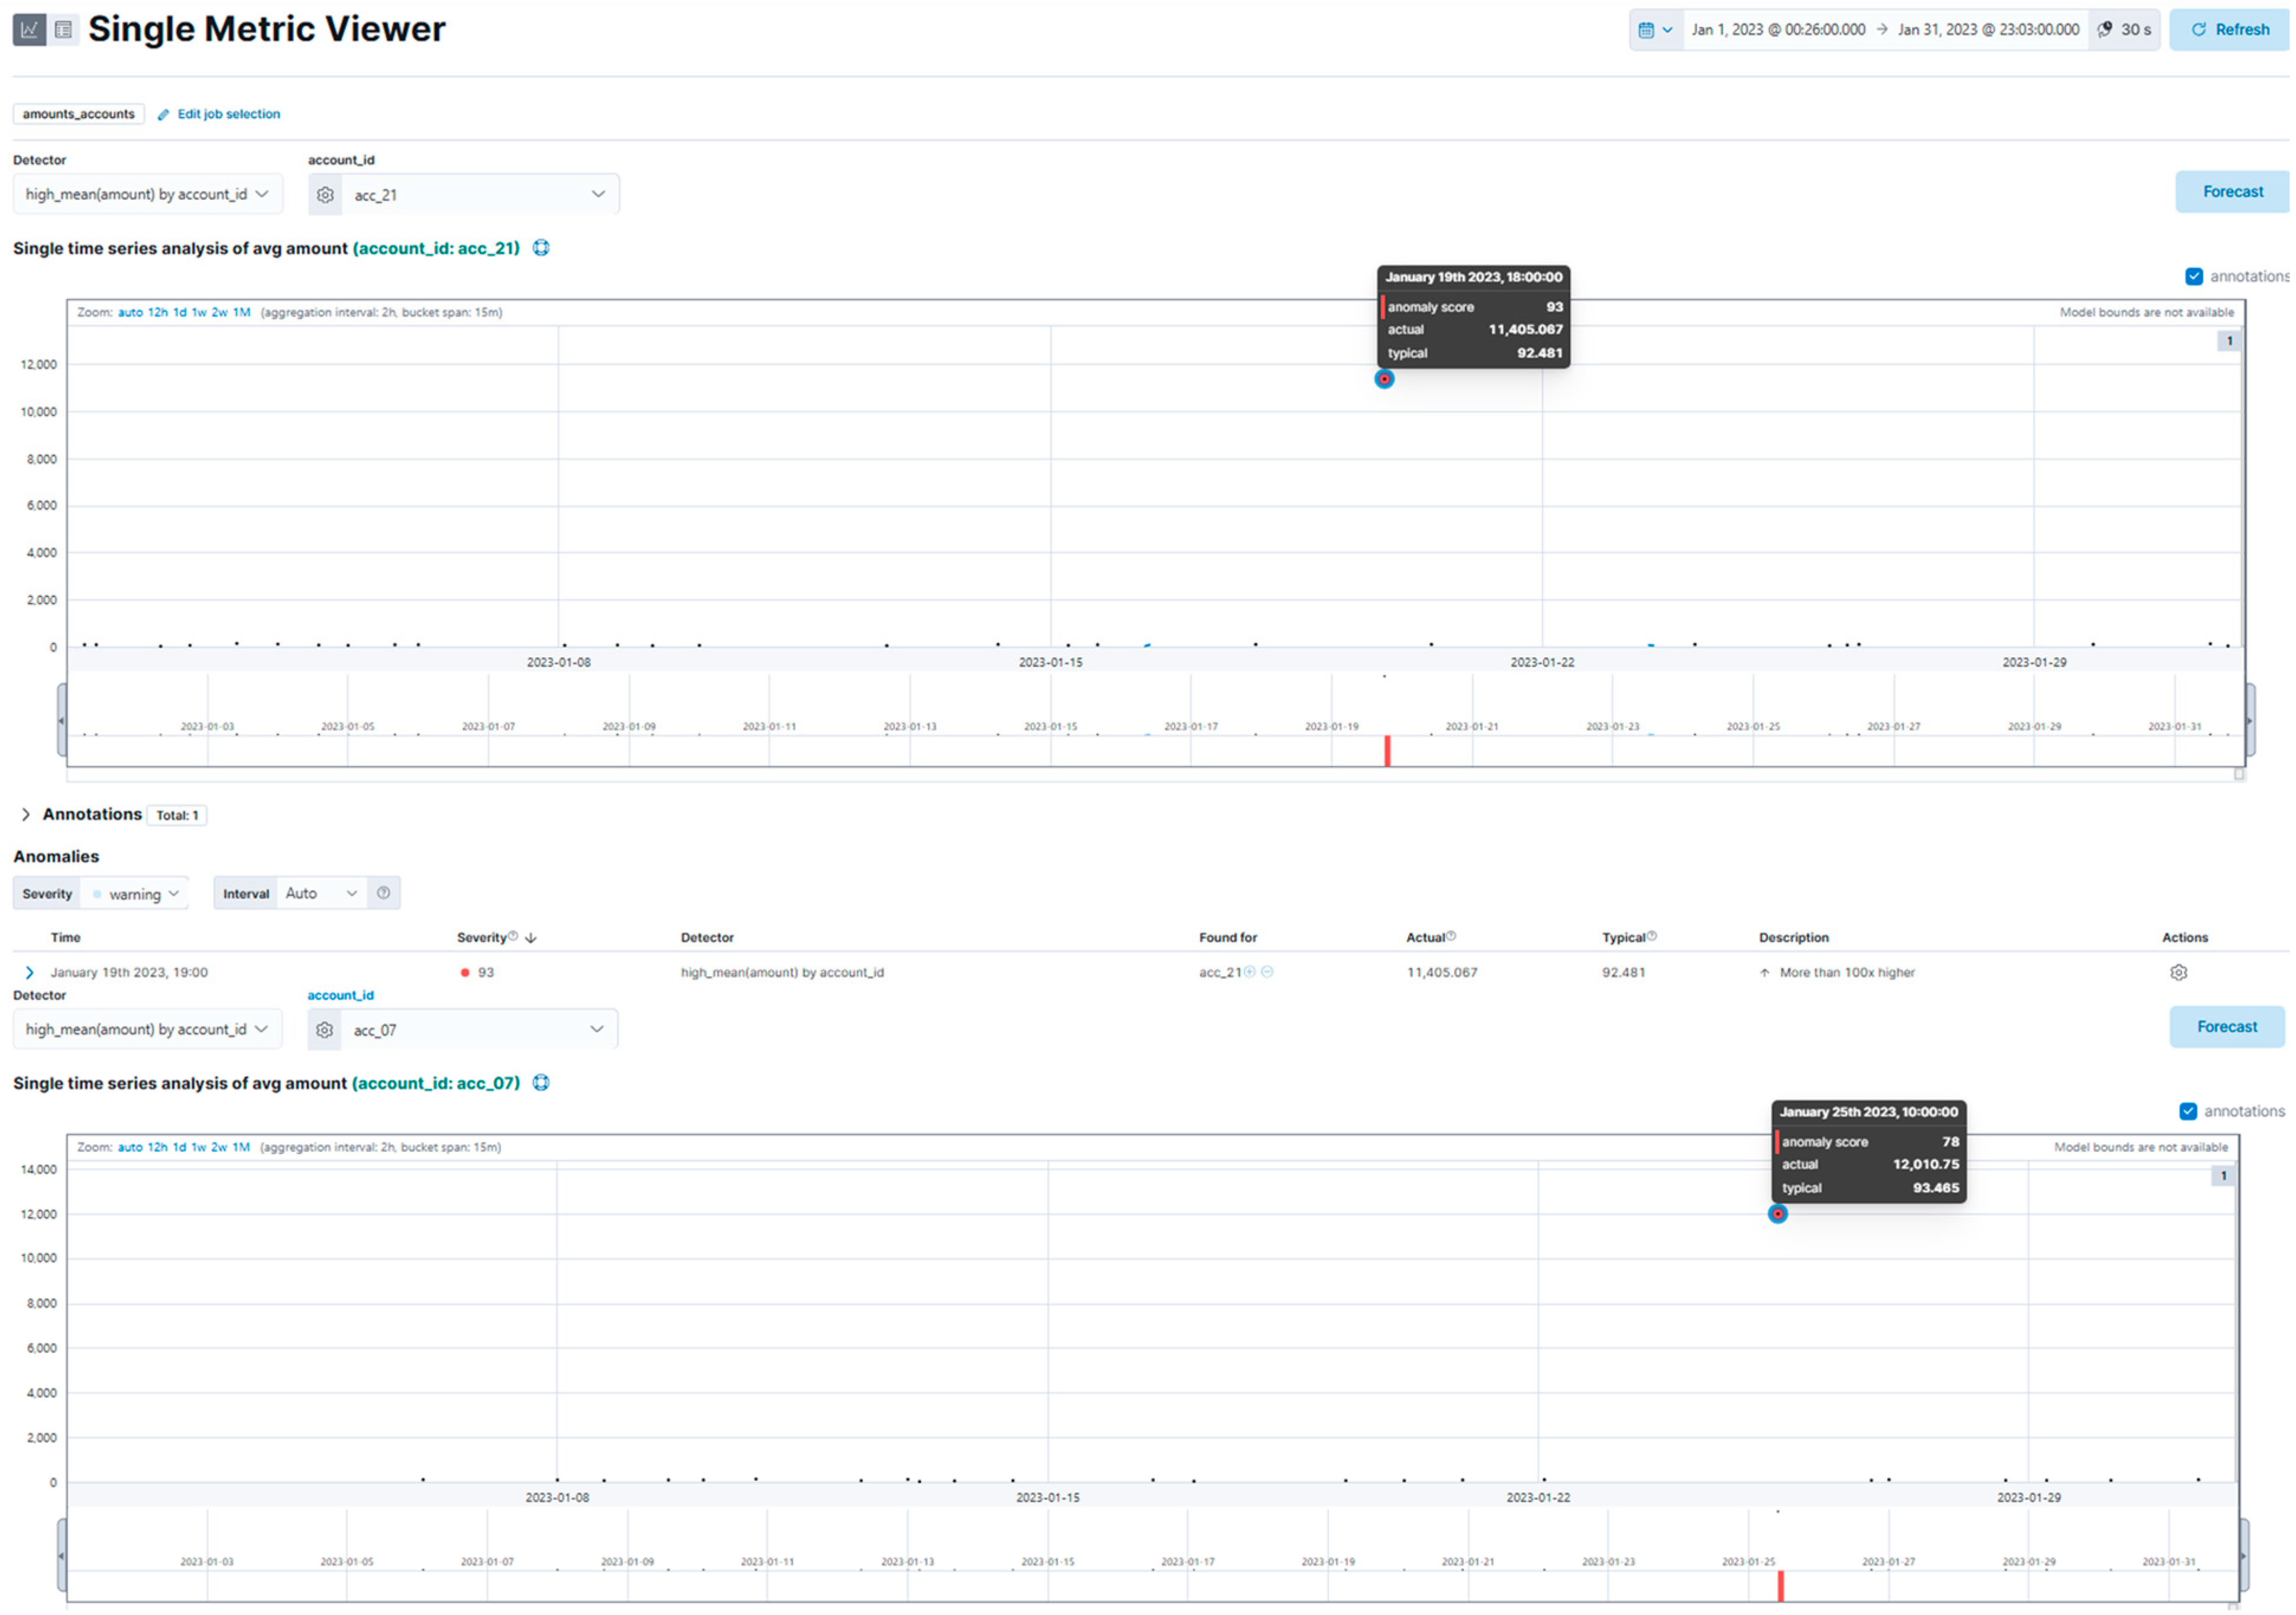
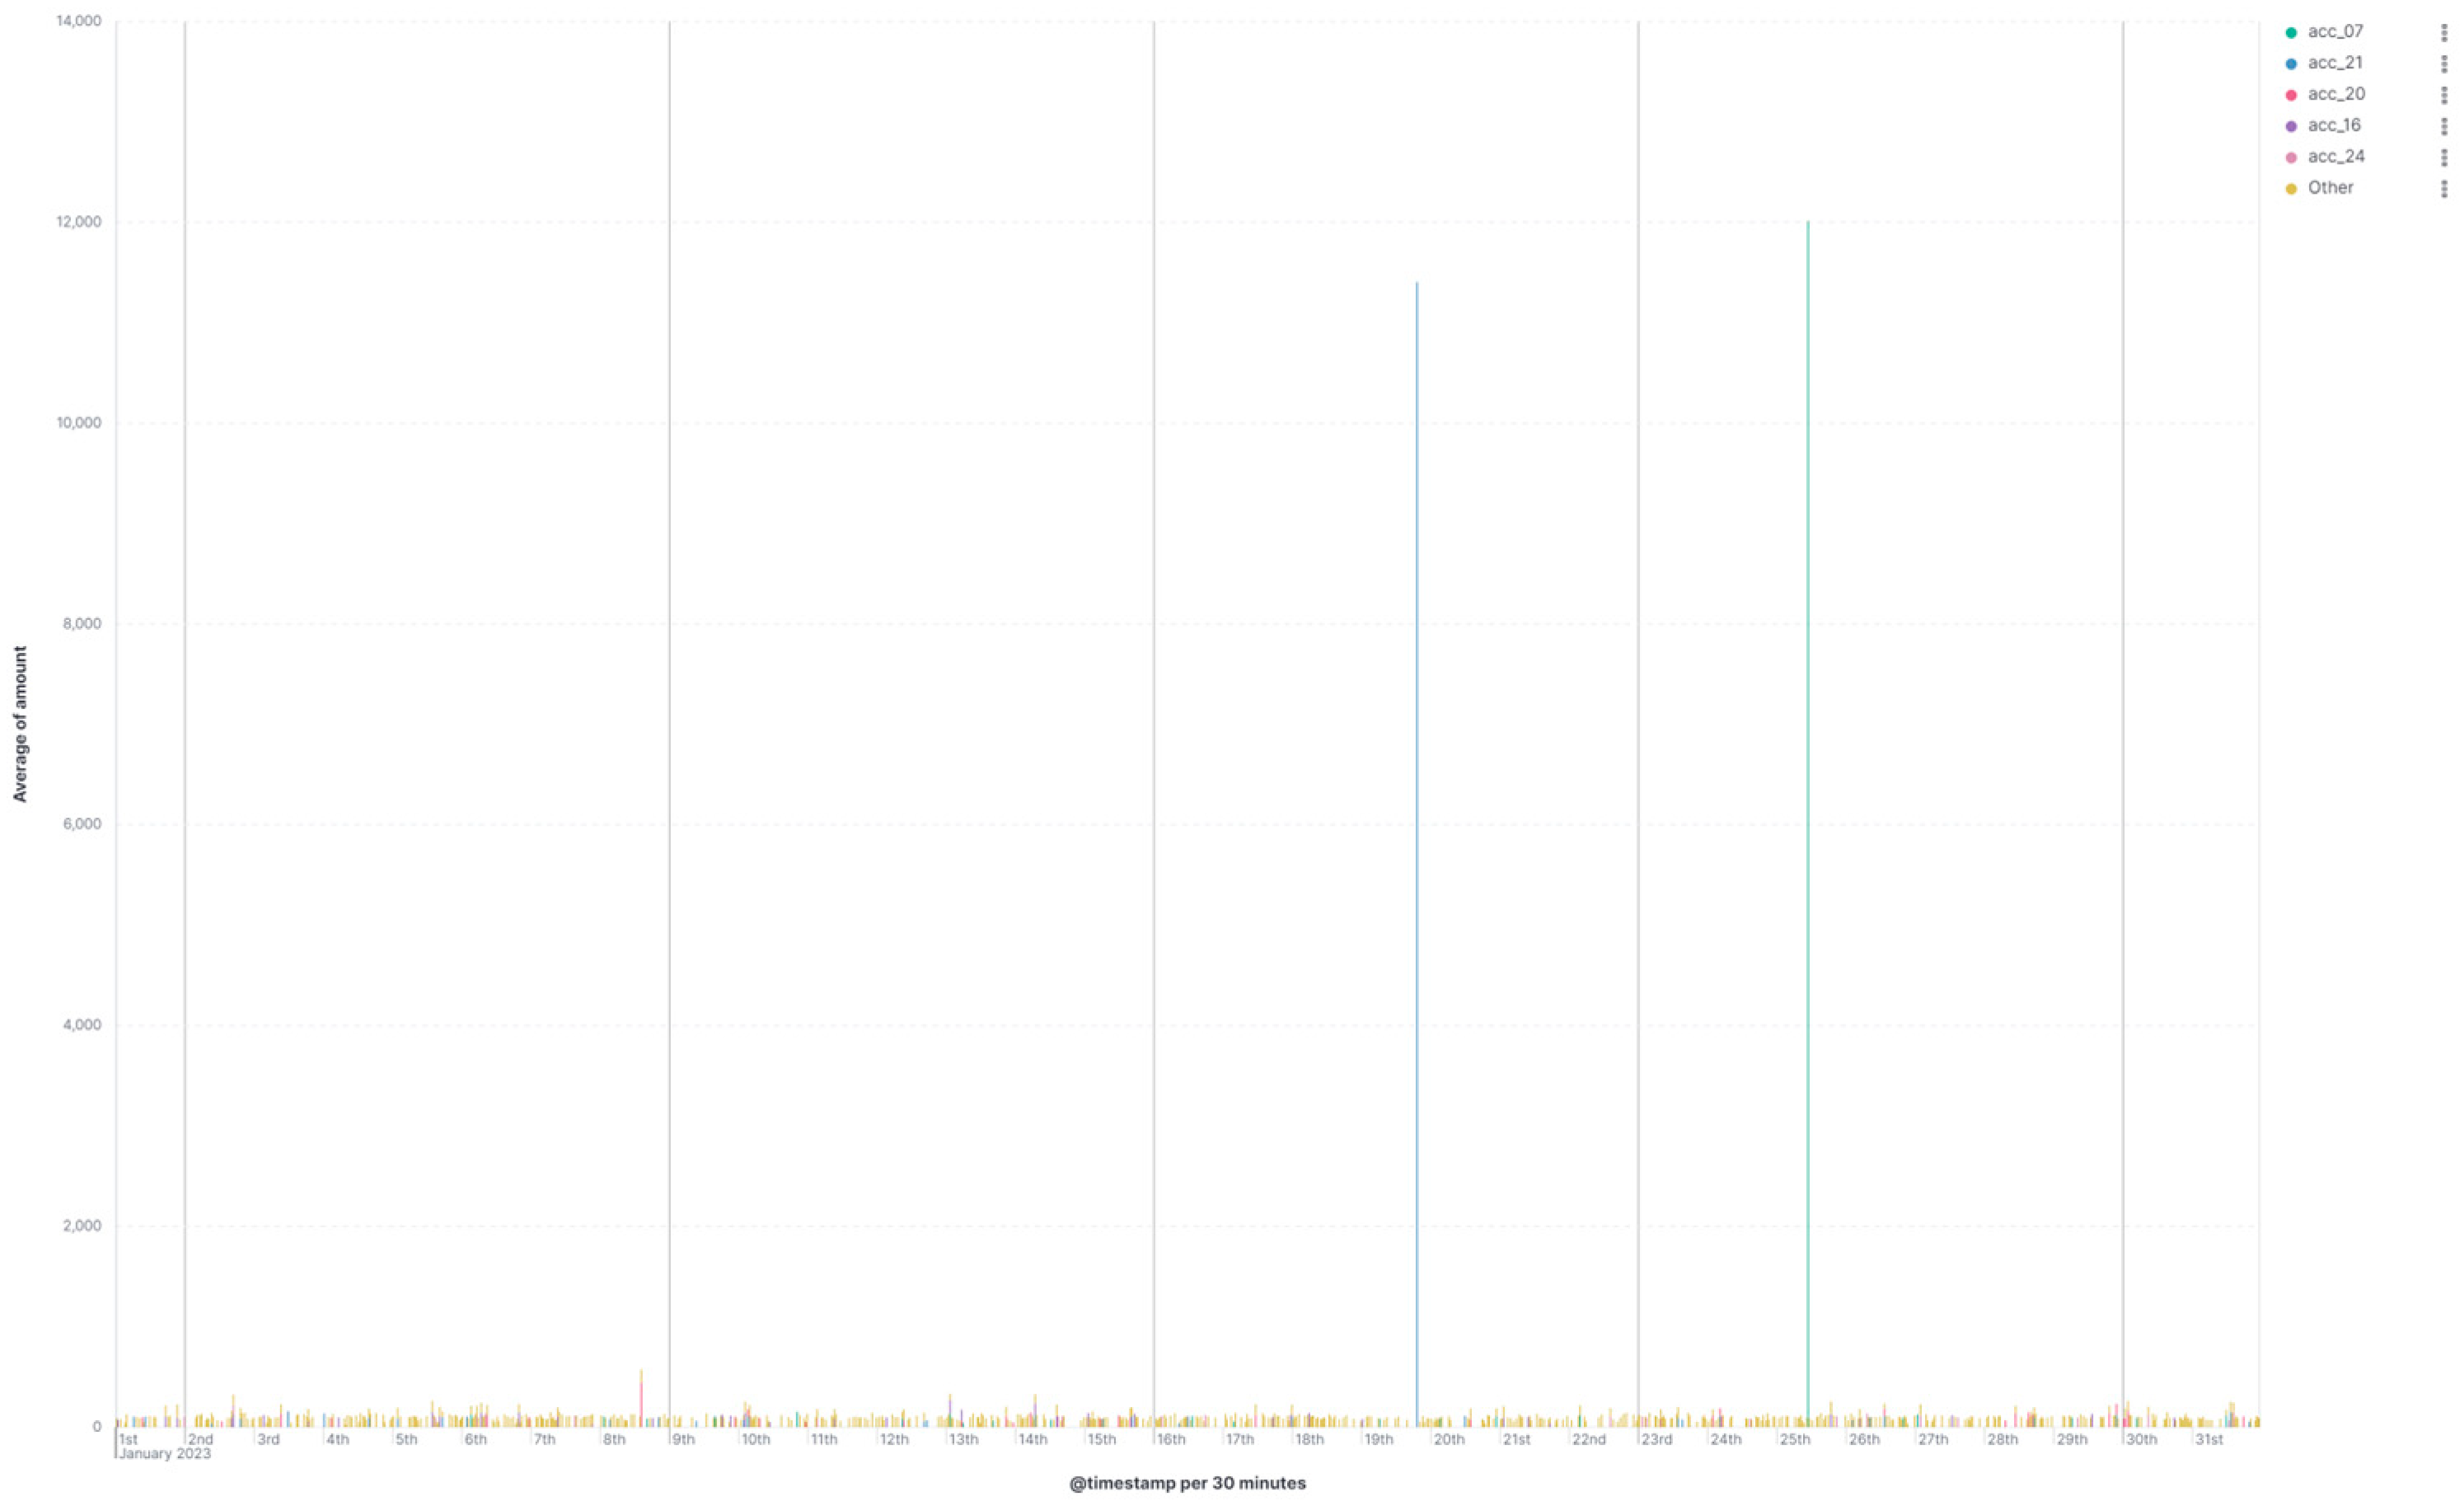
After the job was run, we proceeded with data visualization, both overall and per account. In the dashboard, most accounts showed stable average transaction amounts within expected statistical limits. However, two specific accounts, acc_07 and acc_21, showed sharp increases well above their historical profiles (see
Figure 8).
What is more, with the use of Single Metric Viewer, we observed that, for account acc_21, a transaction of approximately €11,405 was detected, while the expected average was near €92. This anomaly was considered critical and assigned a severity score of 93. Moreover, for account acc_07, a transaction of approximately €12,010 was detected, while the expected average was only ~€93. This deviation was also considered critical and therefore assigned a severity score of 78. (see
Figure 9).
It was clearly demonstrated that these two accounts exceeded their typical values by more than 100 times, and were therefore considered suspicious, while all other accounts remained within their expected ranges. Thus, it was confirmed that the model could isolate only the suspicious accounts.
Overall, we support that this approach could enhance the detection of banking fraud, as it provides the possibility of early detection of transactions that are drastically different from the usual activity of an account. Also, as this model is not based on general thresholds but takes into consideration the accounts’ statistical behavior, a reduction in false positives could be achieved. What is more, it could support Anti-Money Laundering (AML)/Fraud Investigation teams so that they could concentrate on transactions with high anomaly scores, thus ensuring both efficiency and effectiveness. Finally, it could contribute to regulatory compliance (Anti-Money Laundering Directive (AMLD) in the European Union, Bank Secrecy Act/Anti-Money Laundering (BSA/AML) framework in the United States), thus supporting the banking sector to build a comprehensive early warning system and enhance the protection of customers and organizations against fraud or money laundering.
In conclusion, the Elastic Machine Learning framework could be properly used to detect anomalies and inspect fraudulent behaviors at an early stage in the banking sector. Combining data analysis with appropriate result visualization could lead to increased protection for both customers and organizations from fraud, money laundering and other malicious financial activities.
4. Conclusions
This paper empirically investigates the performance of the Elastic Machine Learning (ML) tool in anomaly detection in banking transactions. To the best of our knowledge, this is the first study in the literature that systematically examines the operational behavior of an industrial, unsupervised anomaly detection platform across three distinct fraud-related scenarios in the banking sector. In doing so, it bridges the gap between theoretical anomaly detection principles and their practical implementation in scalable banking systems. The constructed scenarios focused on the examination of abnormal patterns related to a single account that was suddenly associated with a large number of IP addresses, on transactions originating from multiple countries within a short time window, and on unusually high transaction values relative to an account’s historical behavior.
Our findings indicate that Elastic ML successfully identified deviations from expected behavior across all examined scenarios. Also, it managed to inspect heterogeneous anomalies under a unified, unsupervised learning framework. In contrast to traditional approaches based on rigid thresholds, our proposed framework (i.e., Elastic ML) demonstrates great flexibility in adapting to evolving behavioral patterns. Furthermore, the visualization capabilities of Elastic ML enhanced the interpretability of anomaly detection outputs, thereby supporting their integration into automated fraud detection and Anti-Money Laundering (AML) systems. Finally, by decreasing and preventing fraud within the banking sector, this framework contributes indirectly to broader financial stability by enhancing the integrity and trust of the financial system (i.e., banks, consumers and investors) as a whole. Specifically, this tool can enhance the resilience of financial institutions by limiting the accumulation of fraud-related losses, reducing reputational and legal risks, and preventing sudden disruptions to balance sheets. At a systemic level, confidence in the banking system is enhanced by reducing the likelihood that localized incidents of delinquency could develop into broader episodes of systemic stress.
From an operational perspective, the proposed framework could be upscaled to real banking systems, with the examined scenarios serving as modular components of a scalable, unified, real-time framework that detects fraud in banking transactions. Specifically, they could operate in parallel at the account level, dynamically investigating different behaviors according to the needs, risk policies and regulatory requirements of each banking institution.
The adoption of this framework in real banking systems may introduce practical challenges, such as the management of a large number of fraud signals or false positives. The occurrence of false positives presents an inherent trade-off in unsupervised anomaly detection systems, which is linked to parameter choices and the natural variability of normal behavior. Since the present study uses AI-generated data to simulate realistic fraud scenarios, a systematic empirical assessment of false positives could be more appropriately conducted with the use of real-world banking data, presenting a natural direction for future work. Overall, integrating this framework with more advanced explainable AI techniques would support its responsible deployment, showing the way for more transparent, reliable, and operationally robust fraud detection systems in real-world banking environments.