Article

Statevector-to-Hardware Reconstruction of a Four-Qubit ZZ Quantum Kernel: A Single-Backend Case Study of Three Execution Jobs

by
Rostyslav Sipakov
Department of Environmental Protection and Occupational Safety Technologies, Kyiv National University of Construction and Architecture, Povitrianykh Syl, 31, 03037 Kyiv, Ukraine
Quantum Rep. 2026, 8(3), 93; https://doi.org/10.3390/quantum8030093
Submission received: 24 July 2026 / Revised: 6 September 2026 / Accepted: 8 September 2026 / Published: 9 September 2026
(This article belongs to the Topic Quantum Computing: Latest Advances and Prospects)

Abstract

Hardware noise and finite sampling perturb the fidelity estimates forming a quantum-kernel Gram matrix. We measured how far three hardware-reconstructed Gram matrices depart from an exact statevector reference for one frozen four-qubit ZZ feature map on N = 24 observation windows from an indoor air-quality time series. The corresponding circuits were executed on ibm_fez at 1024 shots per circuit in three separate, non-interleaved jobs—one per configuration: baseline, dynamical decoupling alone, and gate twirling alone. All were complete, finite, and positive-semidefinite. Off-diagonal root-mean-squared error (RMSE) against the reference was 0.0878, 0.0864, and 0.0427; full-matrix centered kernel alignment (CKA) ranged from 0.933 to 0.989, and the post hoc diagonal-excluded (U-centered) CKA ranged from 0.816 to 0.986. The gate-twirled job deviated least on every reported geometry axis; its baseline contrasts are deletion-stable for the Spearman, mean-absolute-error, RMSE, and full-matrix CKA diagnostics, while the Pearson and diagonal-excluded contrasts fall just below that convention. Dynamical decoupling was not separated from the baseline. The observed error exceeded both finite-shot reference scales, so under those sampling-only models, sampling does not explain it. Centered kernel–target alignment did not track reconstruction fidelity and stayed at or below each label-permutation reference: implementation fidelity and task relevance are distinct diagnostic axes. All configuration-level statements describe three realized jobs on one backend; no mitigation-efficacy, classifier-superiority, forecasting, or quantum-advantage claim is made.

Graphical Abstract

1. Introduction

1.1. Background and Motivation

A quantum feature map embeds a classical input (x) into a quantum state, x ↦ | ϕ ( x ) 〉 , and the associated quantum kernel measures similarity through a squared overlap, i.e.,
K ( x i , x j ) ⁠ = 〈 ϕ ( x i ) ∣ ϕ ( x j ) 〉 2 ,
so that the kernel (Gram) matrix encodes the feature-map-induced pairwise-similarity structure of the dataset [1,2,3]. Every downstream kernel method sees the data only through this matrix, so the fidelity of the matrix, itself, is a precondition for any learning claim built on it. On near-term hardware, finite sampling and device noise perturb the estimated overlaps, driving kernel entries toward a common background and flattening the matrix relative to its intended form [4,5,6].
Our data come from indoor air-quality (IAQ) monitoring with low-cost duplicate sensors, whose noisy, partially redundant multivariate streams make a difficult real-world test case for similarity-based learning [7,8]. The broader monitoring project concerns redundancy- and missingness-aware (RMA) sensor modeling; the present hardware experiment is deliberately restricted to a single fixed, four-qubit ZZ feature map (ZZ4) and does not execute any RMA kernel on hardware. This paper does not ask whether a quantum computer improves indoor air-quality prediction. It asks the logically prior question: can the statevector ZZ4 kernel be reconstructed on real IBM Quantum hardware with interpretable, bounded distortion? Characterizing how a designed kernel is changed by execution is a prerequisite for and distinct from any later claim of quantum advantage [9,10,11,12].

1.2. Related Work

The ZZ-type feature map and the squared-overlap quantum kernel originate in supervised learning with quantum-enhanced feature spaces [1], with supervised quantum models later identified as kernel methods [2,3]. Benchmarking shows that quantum-kernel behavior hinges on encoding, bandwidth, and concentration rather than on the mere use of a quantum device [13,14]: without the right inductive bias, generalization can degrade [15], kernel values can concentrate toward a constant [4], and sufficient classical data can erase the advantage [12]. Concentration is therefore not only a hardware-noise phenomenon: data-scaling (bandwidth-type) hyperparameters control the noiseless spectrum and inductive bias of the kernel itself [16], and the usefulness of a quantum kernel is a question separate from its faithful execution [17]. These results motivate the treatment of the statevector kernel, not the hardware kernel, as the intended object and the question of how faithfully it is reconstructed in execution.
On noisy hardware, quantum-kernel classifiers have been demonstrated at the 17–27-qubit scale [9,11], and embedding kernels have been trained directly on devices [10], but finite-shot estimation, noise, and compilation all degrade the estimated kernel [4,6], decoherence reduces its effective rank [5], and the realized benefit of mitigation depends jointly on the device and compilation [18,19]. The execution configurations compared here—dynamical decoupling [20,21] and gate (Pauli) twirling [22]—are standard runtime-selectable mitigation strategies within this toolbox [23,24,25]. The closest hardware-fidelity neighbor validates a quantum-kernel support vector machine on the same backend family and reports high statevector-to-hardware fidelity correlation with overly flat quantum eigenspectra [26] (preprint); studies that combine mitigations and judge them by downstream accuracy [27] answer a different question than kernel-geometry reconstruction [28].
We measure reconstruction fidelity with representation-similarity and alignment tools: centered kernel alignment (CKA) between two kernels [29], centered (Cortes-type) kernel–target alignment (KTA) between a kernel and the label Gram matrix [10,30], entropy-based effective rank [5,31], and positive-semidefinite (PSD) diagnostics [32]. Both CKA and centered KTA are invariant to affine (scale-and-shift) changes of a kernel, so a purely depolarizing-type contraction cannot move them; a recent kernel-level comparison instead reads depolarizing noise as increasing quantum–classical CKA [33] (preprint). This sets up the central tension of the study: alignment with the statevector geometry and alignment with the labels need not move in the same direction.

1.3. Research Gap and Contribution

Quantum kernels have been executed on hardware, and the individual mitigation strategies and geometry diagnostics are each well established. What is comparatively underexplored is their combination on a single, fixed kernel: a fixed-protocol, statevector-referenced measurement of reconstruction fidelity for one frozen kernel on a real device, compared across execution configurations and read against an explicit finite-shot reference scale [6,34]. Neither CKA nor KTA is new to this work. The contribution is their paired, statevector-referenced use as separate implementation-fidelity and task-relevance axes within an artifact-grounded hardware-kernel diagnostic case study: entrywise error and CKA answer how faithfully the designed Gram matrix was reconstructed, centered KTA against a permutation reference answers whether the kernel’s structure is aligned with the task, a finite-shot reference scale bounds what sampling alone can explain, and none of these answers substitutes for the others or for downstream accuracy. Concretely, we (i) execute the fixed ZZ4 kernel on IBM Quantum hardware for a frozen subset of N = 24 IAQ windows; (ii) compare baseline, dynamical-decoupling, and gate-twirling configurations, each submitted as a single non-interleaved job; (iii) report rank-order, linear, entrywise, alignment (full-matrix and diagonal-excluded CKA; centered KTA), spectral, and PSD diagnostics against the statevector reference; (iv) document a CKA/KTA tension in which the most faithful reconstruction does not carry the highest label alignment; and (v) compare the observed off-diagonal root-mean-squared error (RMSE) with conservative global and entry-resolved finite-shot reference scales. These contributions are diagnostic: the single-job design supports descriptive comparison, not causal mitigation-efficacy estimates, and the fixed N = 24 subset supports reconstruction-fidelity claims, not predictive ones.

1.4. Research Questions and Scope

This work is a fixed-subset, single-backend hardware-kernel case study of three execution jobs (ibm_fez, 1024 shots per circuit), designated Wave 1 in the project’s decision record. It does not estimate general mitigation efficacy and does not test IAQ forecasting accuracy, quantum advantage, or hardware-classifier superiority. “Survival” is reported as a continuous, multi-metric description; no binary pass/fail threshold was pre-specified. Directional expectations recorded alongside the research questions were not independently timestamped before the hardware results were available and are not treated as confirmatory hypotheses (Supplementary Note S1). We address four research questions.
RQ1 (geometry survival). To what extent is the geometry of the fixed four-qubit ZZ4 statevector kernel preserved when reconstructed on IBM Quantum hardware for the frozen N = 24 subset, as measured by rank-order (Spearman), linear (Pearson), entrywise (mean, root-mean-squared, and maximum absolute error), and centered full-matrix (CKA) agreement with the statevector reference?
RQ2 (configuration differences). What descriptive differences in centered-geometry preservation and off-diagonal entrywise distortion are observed among the three configurations (baseline, dynamical decoupling alone, and gate twirling alone), each submitted as a single non-interleaved job?
RQ3 (finite-shot reference scale). How does the observed off-diagonal hardware-versus-statevector RMSE compare with a conservative global and an entry-resolved finite-shot reference scale under the Wave 1 reconstruction?
RQ4 (label alignment as a distortion diagnostic). Does the intended ZZ4 statevector kernel align with the frozen event-onset labels beyond a random-label permutation reference on this subset, and should any CKA/KTA divergence be interpreted as a distortion diagnostic rather than as evidence of supervised predictive improvement?
Throughout, statevector and hardware quantities are kept distinct, and all alignment and spectral changes are treated as diagnostics of hardware distortion. Section 2 specifies the data, kernel, hardware protocol, and metrics; Section 3 reports the results; Section 4 discusses implications; Section 5 consolidates limitations; and Section 6 concludes the paper. The full protocol, derivation, and extended diagnostic detail are relocated to the Supplementary Methods (location map in Table SM.0) and Supplementary Notes S1–S3.

2. Materials and Methods

2.1. Data and Frozen Subset

The data are real indoor air-quality duplicate-sensor records organized as a forecasting dataset (30-min window stride, one-hour horizon). The binary target (y_event_onset_next_1h) indicates whether a new air-quality event starts within the next hour; windows with already-active events or invalid future labels were excluded from the eligible set. The feature set (F_quantum_4) comprises four one-hour pollutant summaries (pm25_mean_last_1h, pm10_mean_last_1h, hcho_mean_last_1h, and tvoc_mean_last_1h), imputed from training data and min–max scaled to [ 0 , π ] under a train-only policy, with out-of-range values clipped to that range.
A subset of N = 24 observation windows (16 for training and 8 for testing; 12 event-onset and 12 non-onset) was selected and frozen before hardware execution was authorized, with dated, checksum-locked freeze artifacts preceding job creation. The windows span 22 December 2024 to 20 April 2026, with median spacing of ≈4.7 days (per-window ledger in Supplementary Table S2.9). The frozen subset yields N ( N + 1 ) / 2 = 300 unordered kernel evaluations (276 unique off-diagonal pairs), enumerated in a fixed, label-blind pair inventory (Supplementary Methods A1). The governing decision record states (STOP_AFTER_WAVE1_REPORT_RESULTS): the subset is not an adjustable analysis input, and no window was added, removed, or reweighted after authorization (Supplementary Methods A1–A4). The public Wave 1 reproducibility package at a fixed commit (github.com/rsipakov/iaq-quantum-kernel-wave1-reproducibility, release v1.2-wave1-manuscript; Zenodo DOI 10.5281/zenodo.21332398) contains the frozen subset, the statevector reference, the raw and reconstructed hardware artifacts, and the analysis scripts; Supplementary Note S1 maps every reported quantity to its artifact.

2.2. ZZ4 Feature Map, Statevector Reference, and Hardware Estimator

ZZ4 is Qiskit’s ZZFeatureMap on four qubits (one per feature): two repetitions of a Hadamard layer followed by a data-encoding layer of single- and two-qubit Z rotations, with linear (nearest-neighbor) entanglement and the default scaling of α = 2 [1]. The configuration was fixed before execution and never re-tuned. The statevector reference is the exact squared-fidelity kernel of this map, i.e.,
K SV ( i , j ) ⁠ = 〈 ϕ ( x ˜ i ) ∣ ϕ ( x ˜ j ) 〉 2 ,
computed for all 24 windows; its diagonal equals unity by construction. Each hardware entry was estimated with a compute–uncompute fidelity circuit, i.e., U ZZ 4 ( x ˜ j ) † U ZZ 4 ( x ˜ i ) applied to | 0 〉 ⊗ 4 , whose all-zero outcome probability equals K SV ( i , j ) in the noiseless limit. On hardware, the entry is the finite-shot estimator, i.e.,
K ^ r ( i , j ) ⁠ = n 0 4 , r ( i , j ) N r ( i , j ) ,
with n 0 4 , r representing the observed all-zero count and N r = 1024 denoting the observed shots for regime r ∈ { H 0 , H 1 , H 2 } . Symmetrization mirrors the measured upper triangle; the measured diagonal is retained rather than forced to one (mean ≈ 0.94 ; diagonal circuits reduce to measurement-only bodies, so these entries mainly reflect preparation, readout, and finite-shot effects). All three reconstructed matrices are complete (576 finite entries) and already positive-semidefinite (uncorrected λ min = 0.429 , 0.462 , and 0.232 ; statevector 0.0565 ), so no reported metric depends on PSD replacement (audit in Supplementary Methods A4).

2.3. Hardware Protocol and Execution Configurations

The pilot ran on the 156-qubit IBM Quantum backend ibm_fez with the SamplerV2 primitive [35] (Qiskit 2.4.1, qiskit-ibm-runtime 0.46.1) in backend job mode, with one job per configuration, each covering all 300 pair circuits: d7vf6n3ack5s73bfc0eg (H0, baseline), d7vf8ocinasc738u1bhg (H1, dynamical decoupling only, XX sequence), and d7vfbsfmrars73d84u20 (H2, gate twirling only, active-accum, resolved to 16 randomizations per circuit). All three jobs completed (DONE) with 300 retrieved PUB results each and no retrieval failure, and they ran sequentially within one ≈13.3-minute window on 9 May 2026 (UTC); the persisted job manifest records their submission at 08:42:05, 08:46:26, and 08:53:05 UTC (H0, H1, and H2, in that order) for 921 , 600 observed shots and 244 billed QPU seconds in total. The 300 logical circuit bodies are shared across regimes; the regimes differ only in Sampler-level runtime options (SHA-256-locked records). Compiled depth was at most 102, with at most 22 two-qubit gates (cz) at optimization_level=1; the physical-qubit layout, transpilation seed, and a contemporaneous calibration table were not persisted. The manuscript refers to the artifact regimes H0/H1/H2 as configurations M0/M1/M2 where convenient; the alias is notational only (Supplementary Methods A3). Shots were budget-safe at 1024 per circuit (planned: 4096). For H2, the 1024 shots are pooled across the 16 twirling randomizations; per-randomization counts were not persisted, so between-randomization variability cannot be estimated from the recorded data (Supplementary Methods A2). No combined decoupling-plus-twirling configuration was executed.

2.4. Geometry and Task-Alignment Metrics

Scalar agreement and entrywise-error metrics are evaluated on the off-diagonal domain, i.e., Ω = { ( i , j ) : i ≠ j } ( | Ω | = 552 directed entries; equivalent to the 276 unordered pairs by symmetry): Spearman and Pearson correlations with the statevector entries and mean, root-mean-squared, median, and maximum absolute error. Matrix-level metrics retain the full symmetric matrix, including the measured diagonal: the centered kernel alignment, i.e.,
CKA ( K m , K SV ) ⁠ = 〈 H K m H , H K SV H 〉 F ∥ H K m H ∥ F ∥ H K SV H ∥ F , H = I N − 1 N 1 1 ⊤ ;
the centered kernel–target alignment ( KTA c ( K m , y ) = CKA ( K m , y y ⊤ ) ) with balanced signed labels ( y i ∈ { − 1 , + 1 } ), and the entropy effective rank of the zero-clipped spectrum. Both centered functionals are invariant to the affine map, i.e., K ↦ a K + b 1 1 ⊤ ( a > 0 ), so a purely depolarizing contraction cannot move them; any positive hardware KTA uplift certifies a non-affine distortion component, without, by itself, identifying a mechanism (Supplementary Methods A5–A8). Because the shared near-unit diagonal inflates the full-matrix CKA, a post hoc diagonal-excluded (U-centered) CKA computed from the HSIC ⁠ 1 estimator [36] is reported alongside it (Supplementary Table S2.5). Statevector-referenced tension quantities are the CKA loss ( L CKA , r = 1 − CKA ( K hw ( r ) , K SV ) ) and the label uplift ( Δ KTA , r = KTA c ( K hw ( r ) , y ) − KTA c ( K SV , y ) ).

2.5. Statistical Policy and Reference Scales

The statistical unit is the frozen observation window: kernel entries sharing a window are dependent, so the 552 directed entries are deterministic summary domains, not sampling units, and no entrywise correlation-test p-values or bootstrap intervals are used. Uncertainty statements are limited to leave-one-window-out jackknife standard errors [37] and paired contrasts preserving within-window covariance; the descriptive ratio ( z desc = Δ / SE ^ JK ( Δ ) ) is a scale-free stability diagnostic, not a test statistic, and is not converted into p-values. For brevity, a contrast is called deletion-stable when | z desc | ≥ 2 ; this is a readability convention conditional on the three realized jobs, not a significance threshold, and it measures sensitivity to deletion of frozen windows, not hardware run-to-run uncertainty. Non-resolution is not equivalence. The persisted jackknife covers Spearman, Pearson, MAE, full-matrix CKA, and centered KTA; deletion probes for RMSE, U-centered CKA, and Δ KTA were added at revision under the same reading (Supplementary Methods A10).
Two finite-shot reference scales are defined at the executed S = 1024 shots: the deliberately conservative global scale ( σ ref , global = 1 / 2 S ≈ 0.022097 ) and the entry-resolved, matrix-aware scale ( σ shot , matrix , r ) (root mean square of the per-entry binomial plug-ins over Ω , ≈ 0.0083 ). Both are diagnostic reference scales, not uncertainty models or physical noise-model decompositions, and for H2, they use the pooled 1024-shot probabilities (Supplementary Methods A9). Label alignment is referenced to fixed-seed label-permutation nulls ( B = 5000 ; statevector, with per-regime nulls added at revision), a split-preserving permutation variant, a count-level finite-shot resampling null ( 20 , 000 replicates), and two classical comparator kernels; the revision additions are deterministic or fixed-seed recomputations from the frozen v1.2 artifacts and explicitly post hoc, and none is a confirmatory test (Supplementary Methods A10). The directional expectations (E1–E4) recorded alongside the research questions were not independently timestamped before the hardware results were available; are not treated as confirmatory; and are reproduced verbatim, along with their provenance status, in Supplementary Note S1 (Section S1.5). All statistical outputs are fixed-subset, post-reconstruction diagnostics; they support kernel-geometry and distortion statements, not classifier accuracy, hardware superiority, or quantum advantage.
Generative AI tools were used during preparation (figure-script review, readability editing, reference verification, and an independent audit of the public package); they were not used to design the study, execute jobs, choose methodology, or produce any reported quantity, and all reported quantities regenerate from the persisted pipeline (Data Availability Statement).

3. Results

3.1. Execution and Reconstruction

All three configurations completed as single backend-mode jobs on ibm_fez at 1024 shots per circuit, with 300 retrieved PUB results per regime; no retrieval failure; and complete, finite, positive-semidefinite 24 × 24 reconstructions under the measured-diagonal policy (Section 2.2; job identifiers in Section 2.3; full execution ledger, resource accounting, and PSD audit in Supplementary Methods B1 and A4). Every frozen quantity below traces to a versioned, checksum-registered artifact of the public package; the revision-added diagnostics are fixed-seed recomputations from those artifacts, registered in release v1.3-revision-diagnostics (Supplementary Notes S1 and S2).

3.2. Reconstruction Fidelity and Configuration Contrasts (RQ1 and RQ2)

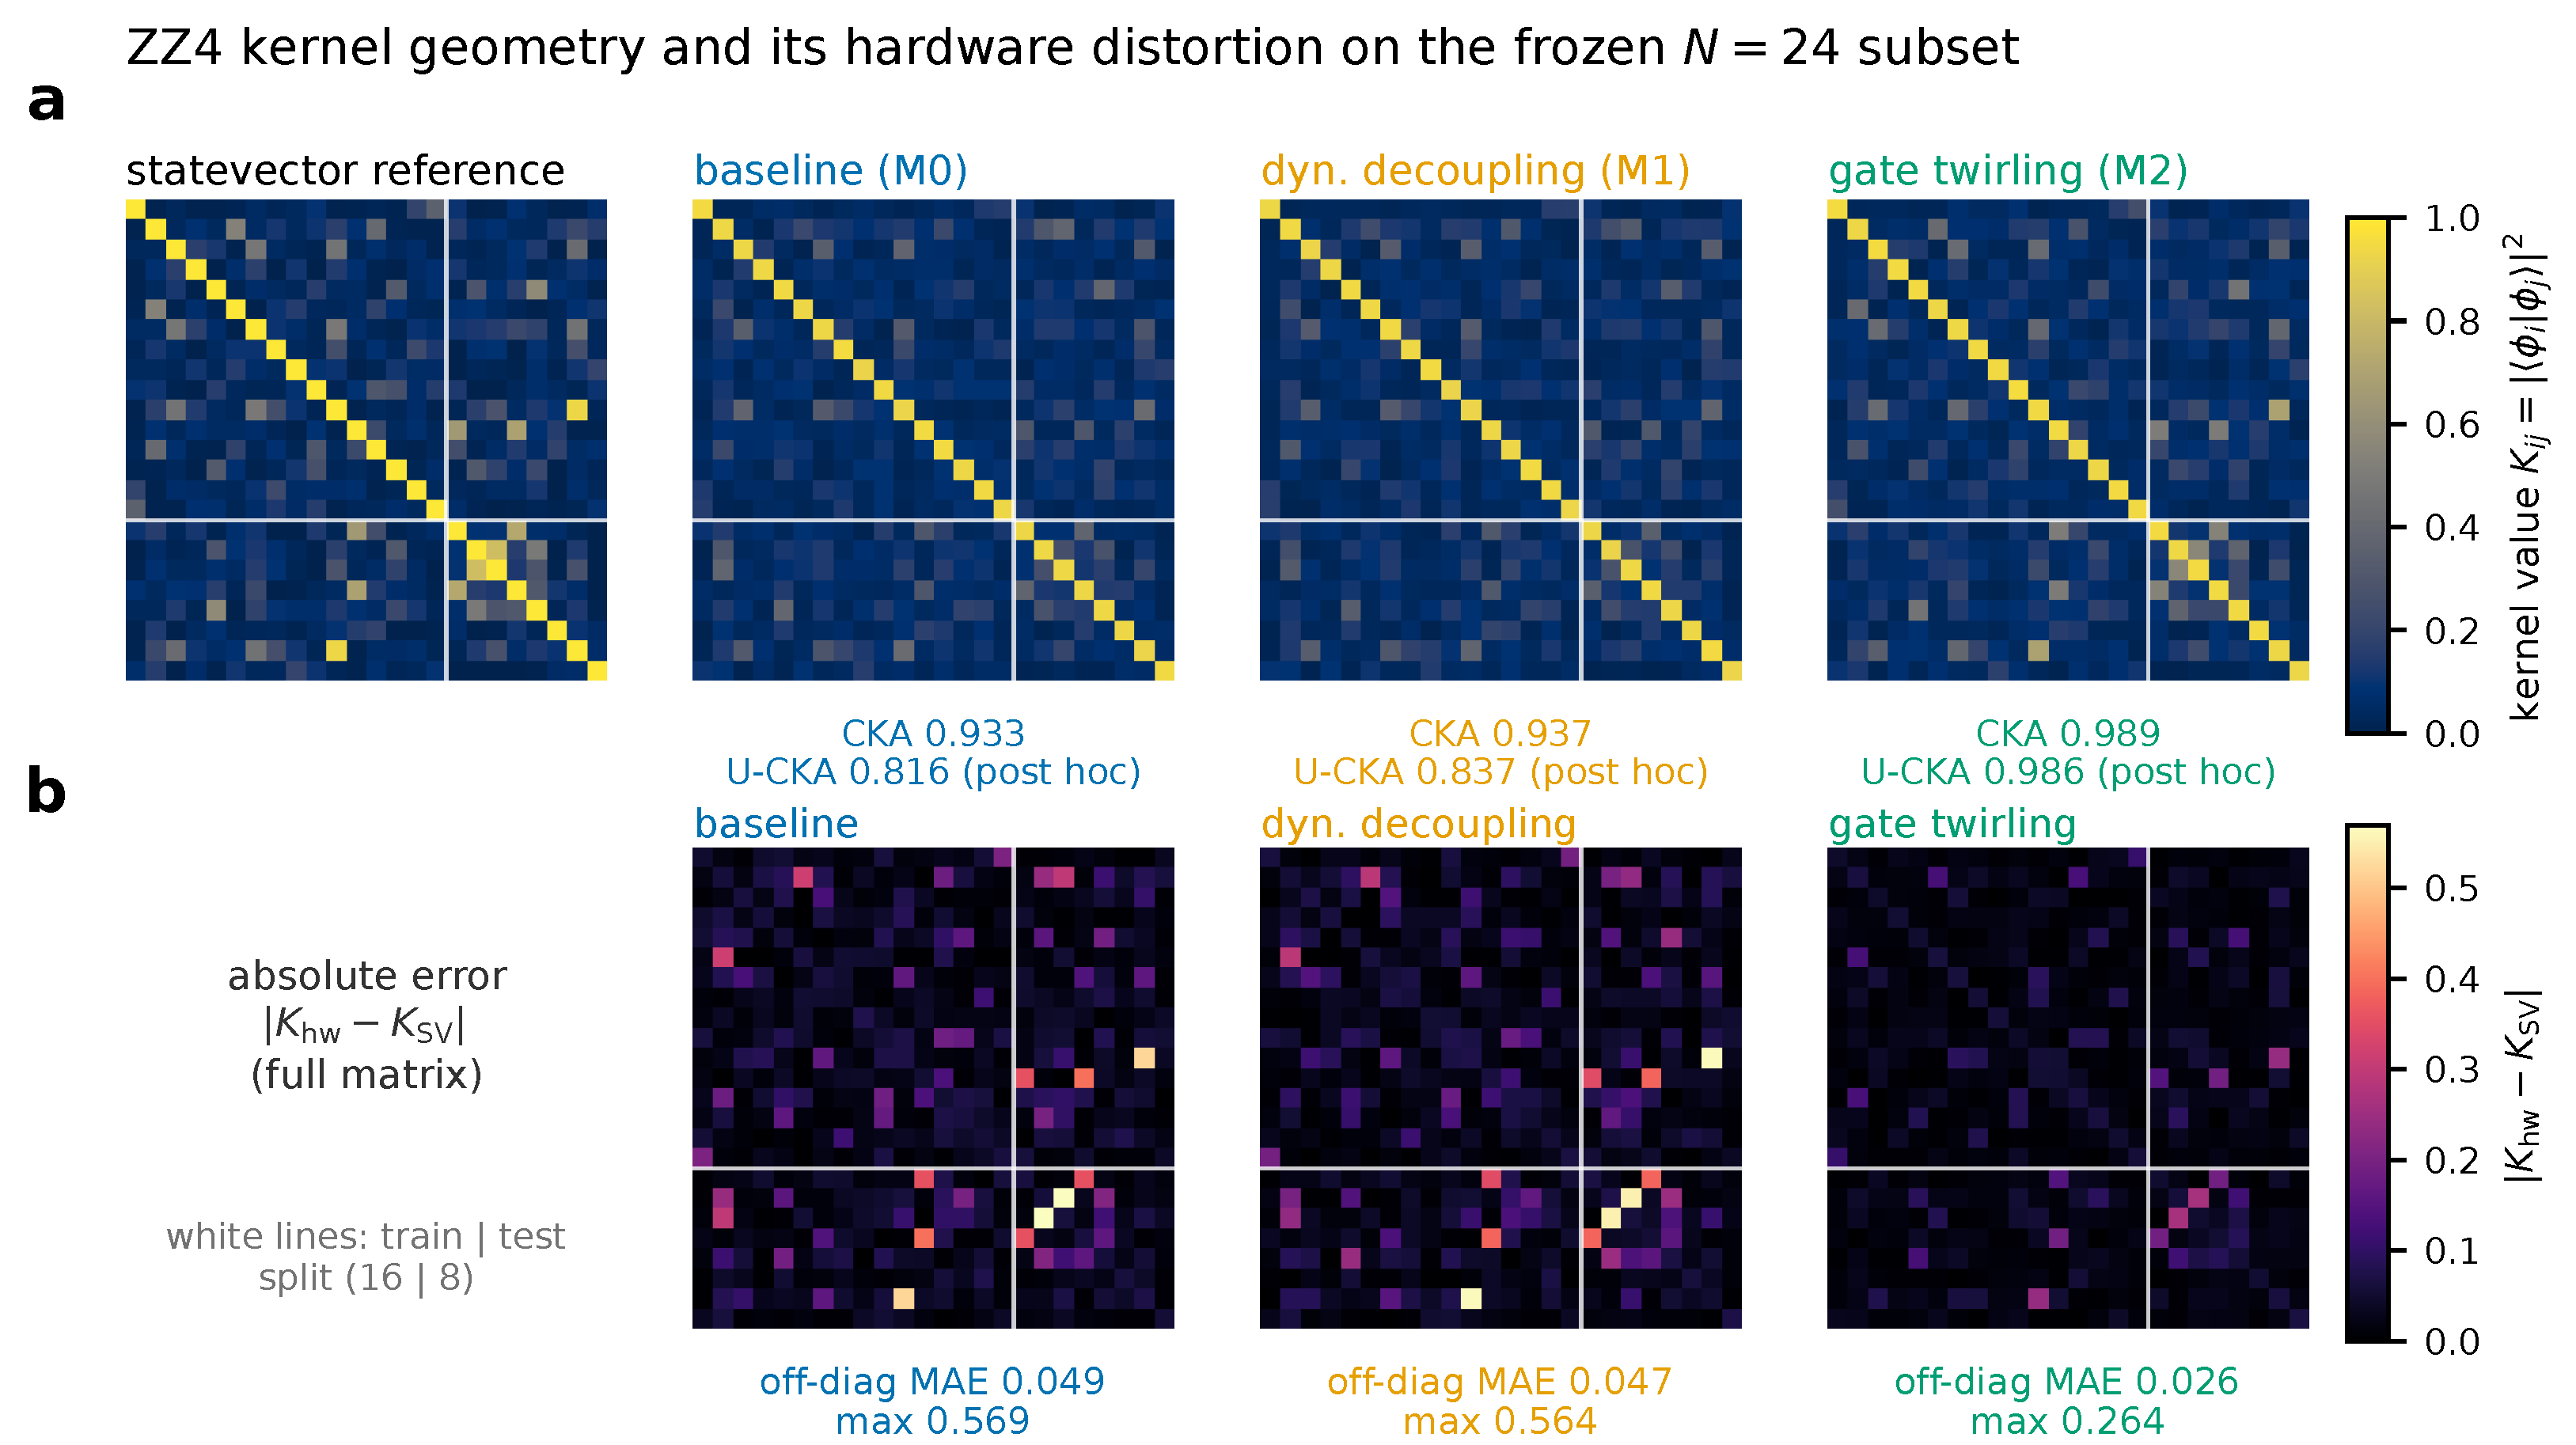
Table 1 reports the headline distortion metrics; Figure 1 shows the four Gram matrices and their entrywise errors.
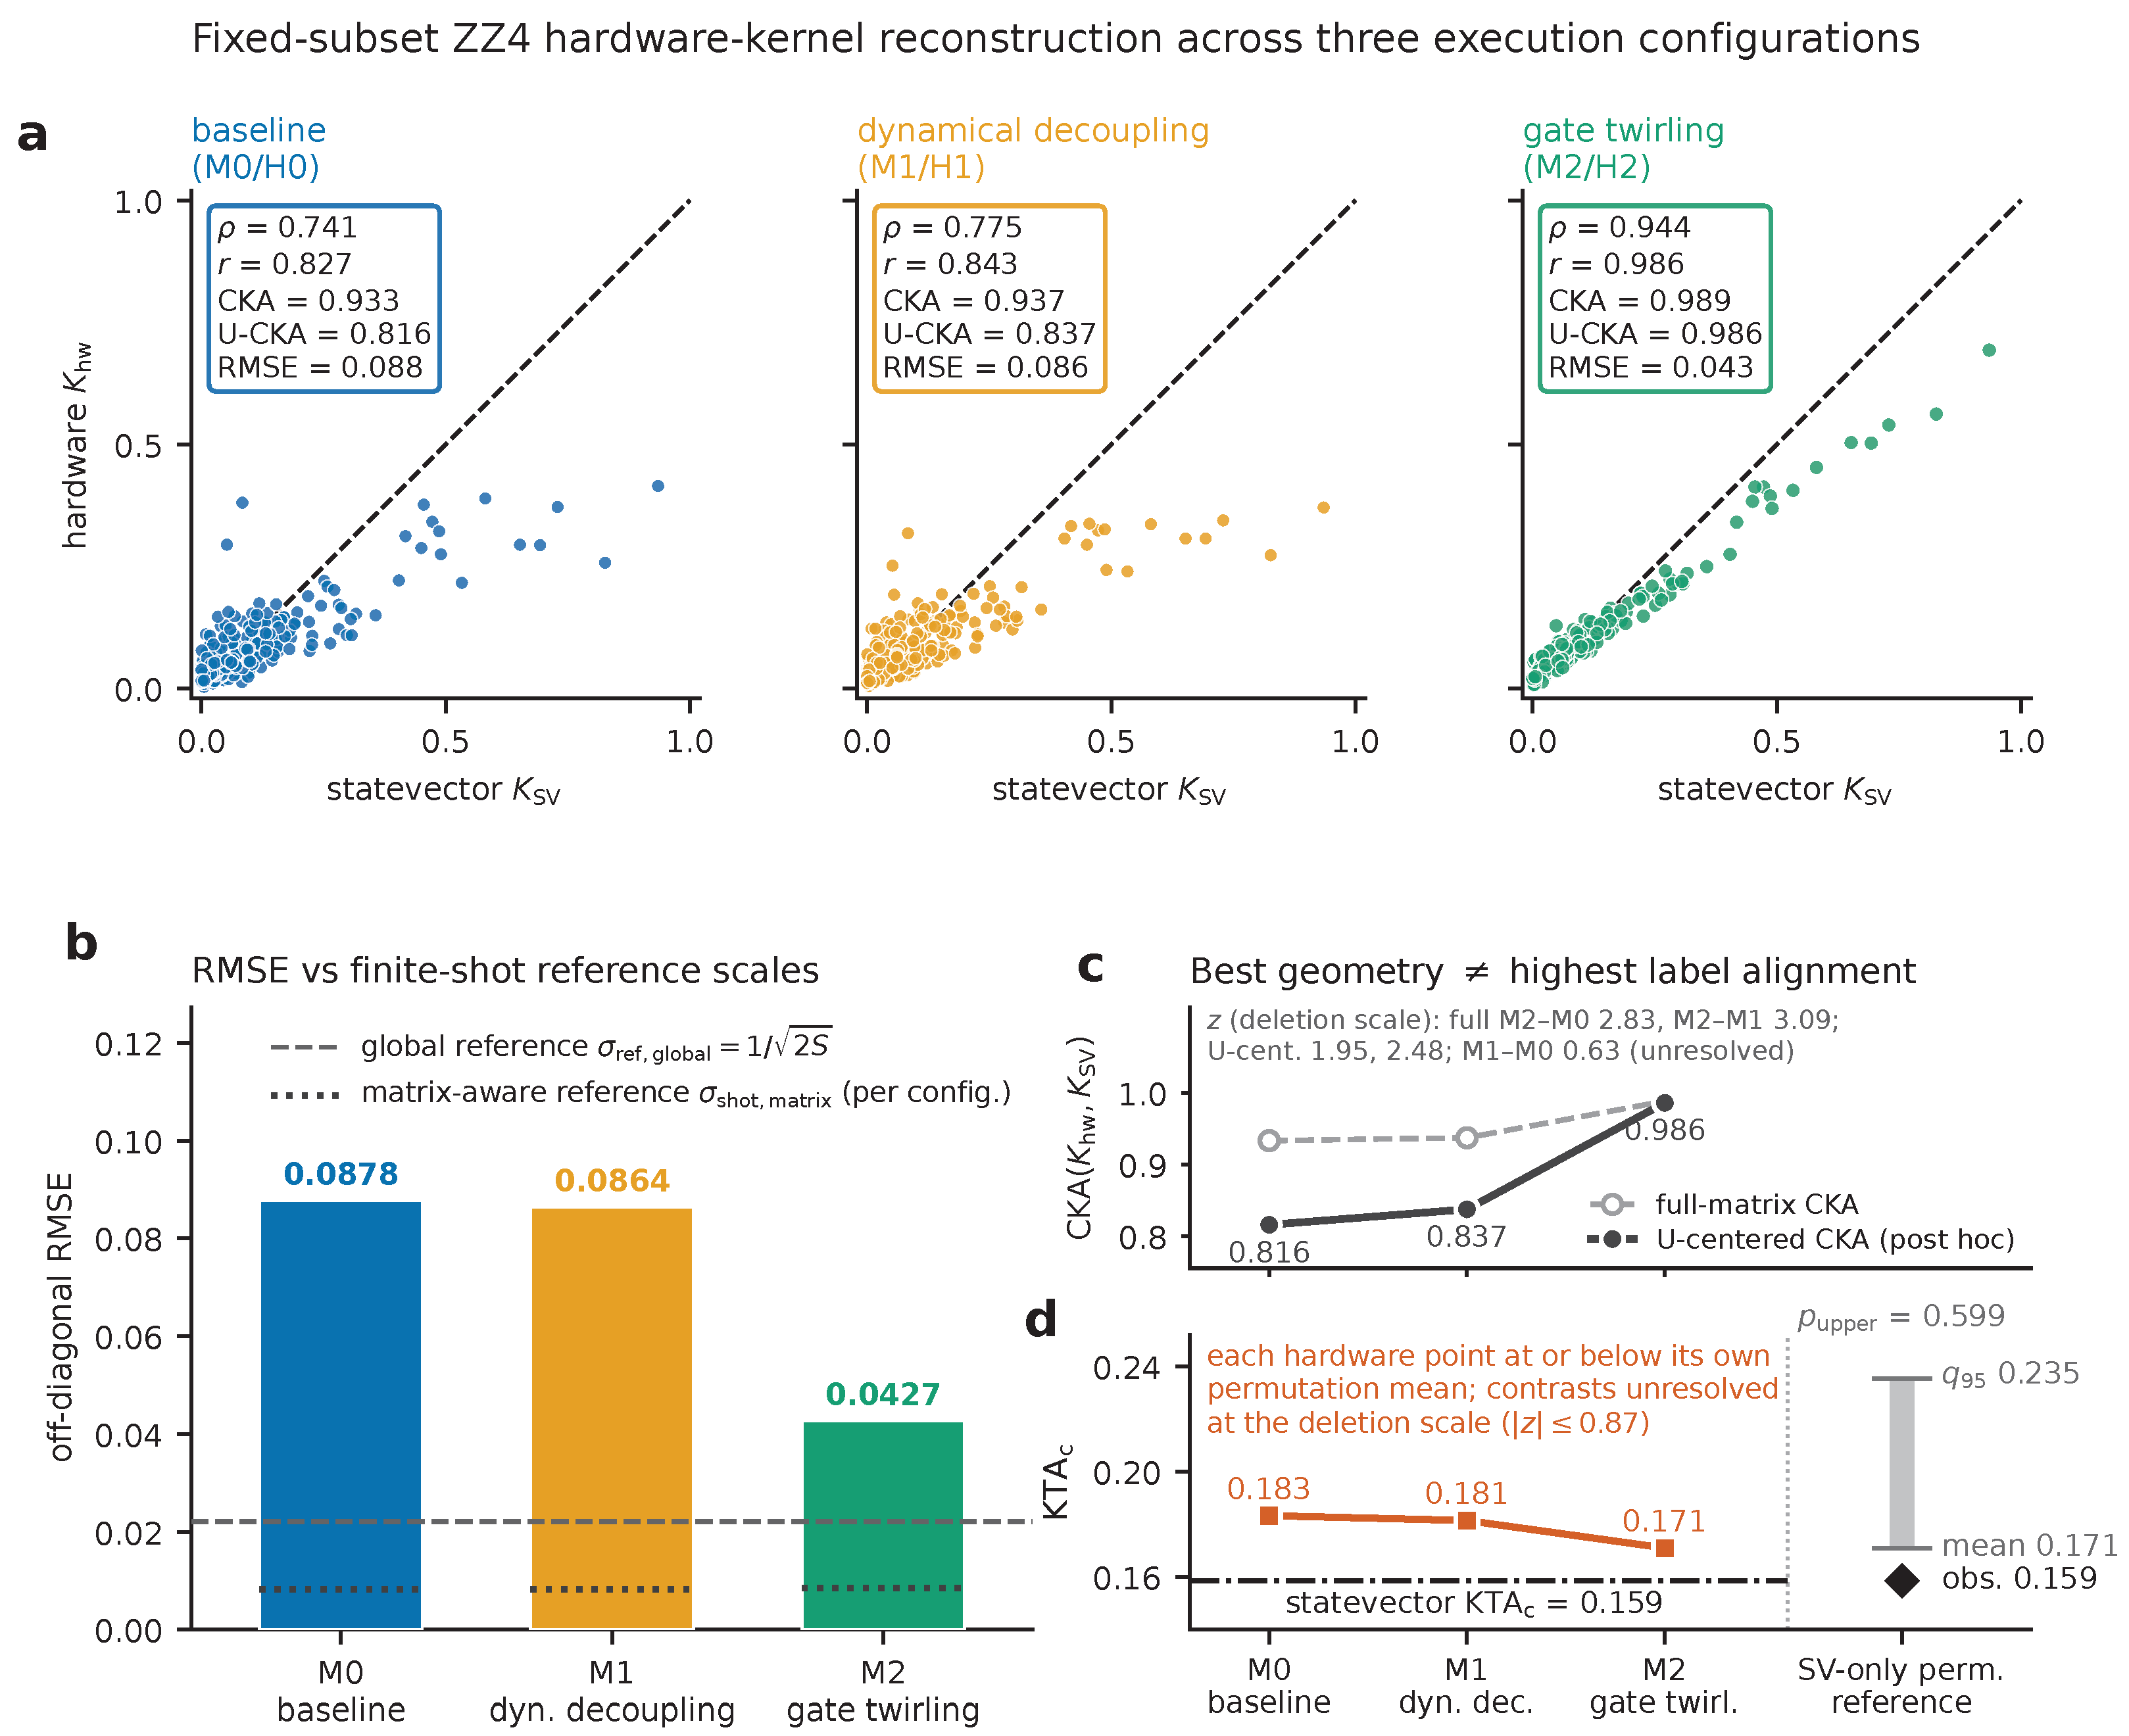
Reconstruction fidelity (RQ1). All three reconstructions preserve the intended ZZ4 structure to a substantial descriptive degree. Even the unmitigated baseline retains positive rank-order and linear agreement ( ρ = 0.741 , r = 0.827 ) and high full-matrix centered alignment ( 0.933 ; diagonal-excluded 0.816 ). Preservation is incomplete everywhere. The hardware kernels reduce the off-diagonal variance to 28.9 % , 28.3 % , and 52.3 % of the statevector off-diagonal variance ( 0.01866 ), a change in the direction expected when noise concentrates overlaps toward a common value [4]. The worst-case entrywise error reaches 0.569 (H0) and 0.564 (H1)—more than half the kernel range—against 0.264 for H2.
Configuration contrasts (RQ2). On every agreement metric, the observed ordering is gate twirling first, then dynamical decoupling, then baseline. Relative to baseline, the gate-twirled job shows a 47.5 % lower off-diagonal MAE, 51.3 % lower RMSE, and a centered-alignment loss ( 1 − CKA ) of 0.0113 versus 0.0666 ; on the diagonal-excluded variant, the point separation widens ( 0.9863 versus 0.8156 ), while its deletion contrast weakens ( z desc = 1.95 versus 2.83 full matrix). The baseline-to-decoupling differences are small and not deletion-stable on any persisted metric. Effective rank is inflated on hardware ( 21.18 , 21.22 , 19.79 versus 17.97 ), least under twirling; this is an uncentered point-estimate diagnostic of spectral flattening, complementary to the centered metrics (spectra in Supplementary Figure S3.2; detail in Supplementary Methods B5). Among the three observed jobs, the gate-twirled job is therefore the most faithful reconstruction, and this is a descriptive statement about these jobs on this backend, not a causal mitigation-efficacy estimate.

3.3. Task Alignment and the CKA/KTA Tension (RQ4)

The statevector ZZ4 kernel does not align with the frozen event-onset labels beyond a random-label reference: its centered alignment of 0.1585 lies below the permutation-null mean ( 0.1710 ) with p upper - tail = 0.5988 ( B = 5000 ; seed-stable across a 16-seed envelope, [ 0.587 , 0.608 ] ), and a split-preserving permutation variant agrees ( 0.562 ). Two post hoc classical comparators on the same inputs (linear and median-bandwidth RBF kernels) likewise show no above-chance alignment ( 0.0076 and 0.0680 ; p = 0.796 and 0.589 ; Supplementary Table S2.8), consistent with the weak alignment being a property of the frozen subset and target at this scale rather than of ZZ4 specifically. This is an absence-of-evidence statement at N = 24 , not an equivalence claim, and it rules out any IAQ forecasting claim from this pilot.
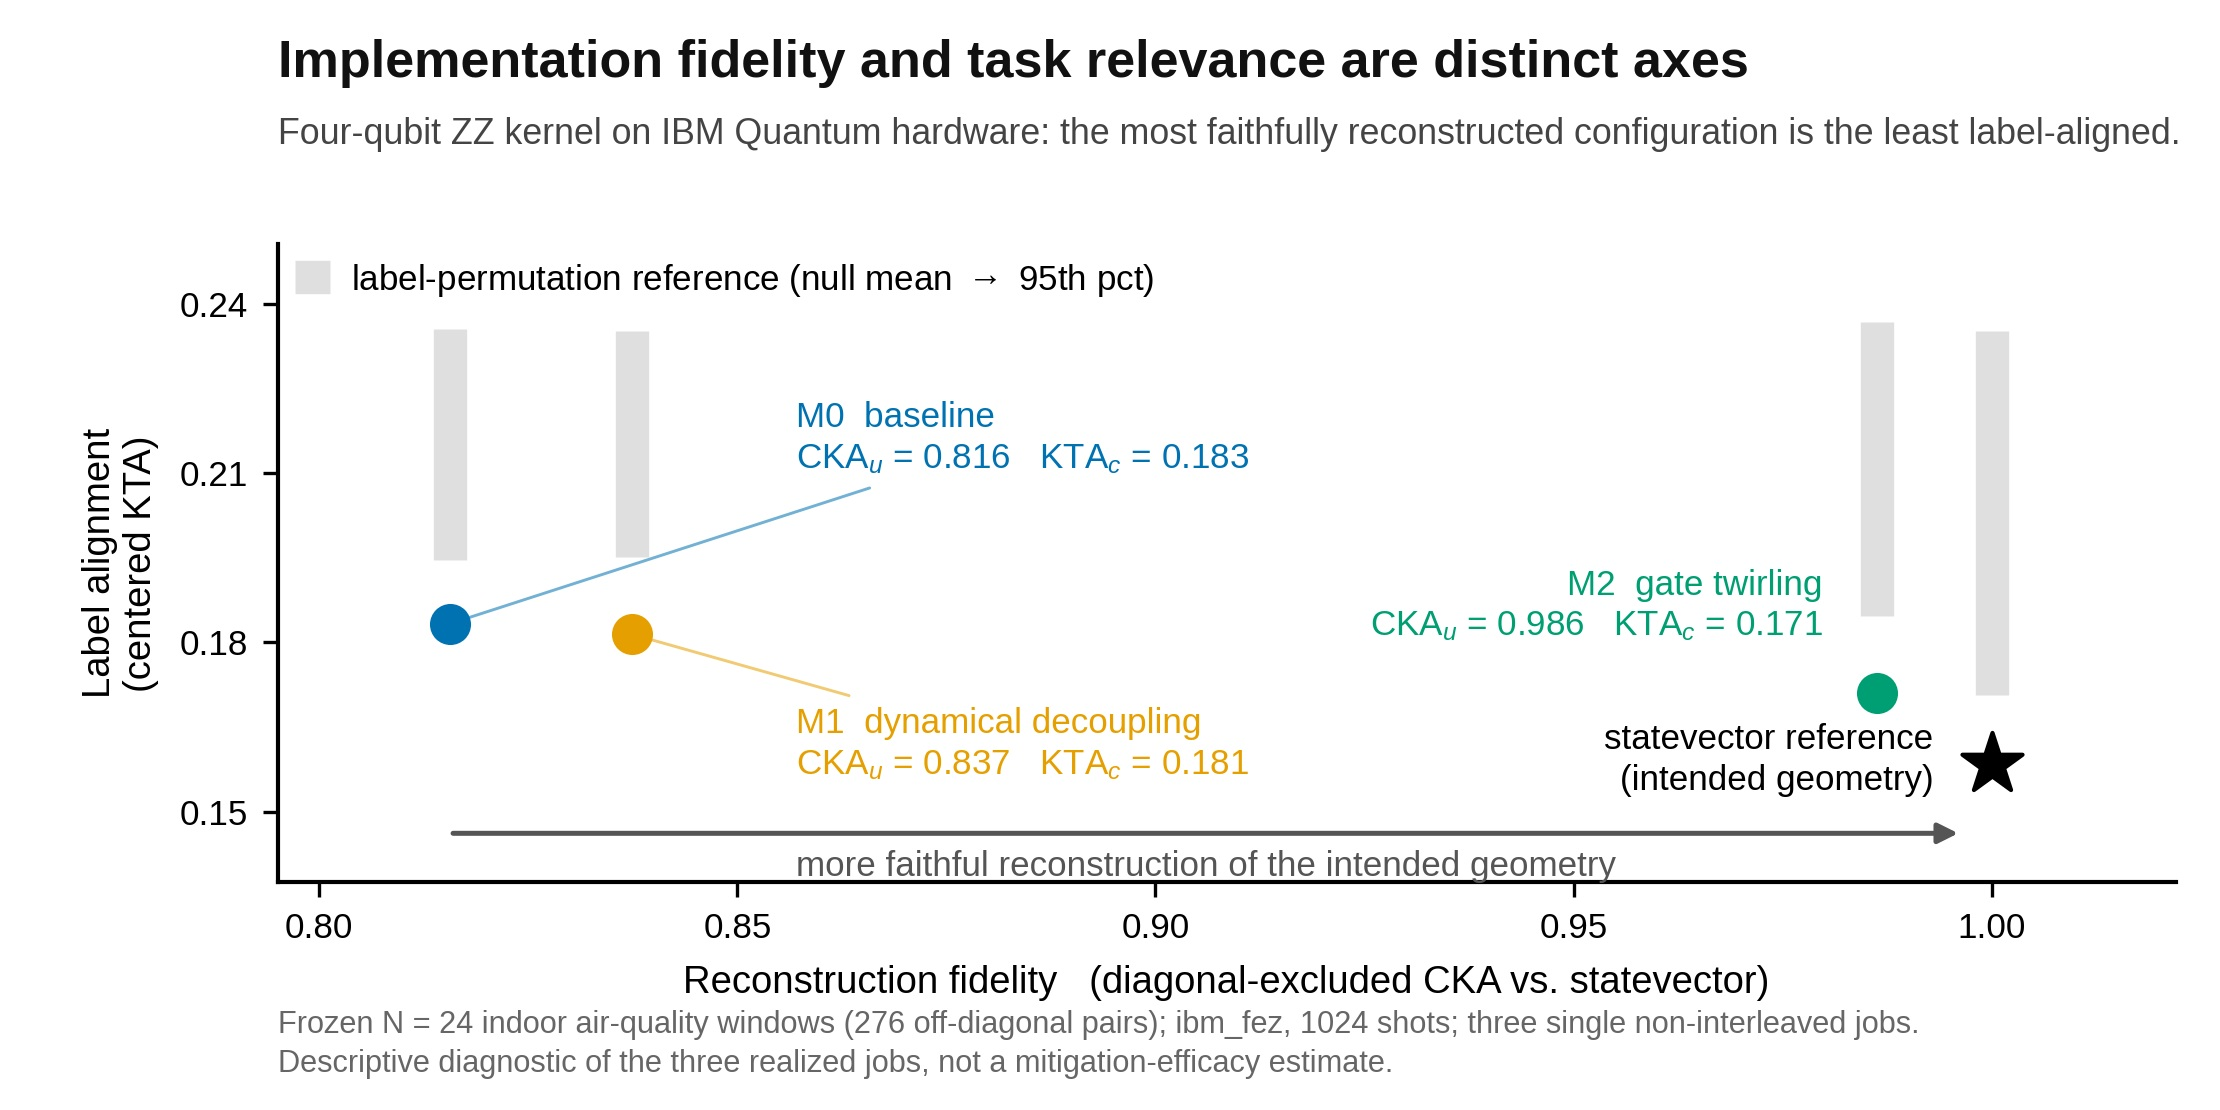
Against this reference, the hardware kernels show a small, centered-KTA uplift ( Δ KTA = + 0.0248 , + 0.0230 , + 0.0125 for H0, H1, H2), ordered opposite to geometric fidelity: the most faithful job carries the lowest absolute hardware KTA ( 0.1710 ), closest to the statevector value. Three revision references bound its reading (Supplementary Table S2.6). First, the uplift lies outside a count-level finite-shot resampling null around the statevector probabilities ( 0 / 20 , 000 replicates reach any observed uplift; null SD of 0.0022 ), so it is not attributable to finite-shot sampling under that reference. Second, every hardware kernel sits at or below its own label-permutation mean ( p upper - tail = 0.670 , 0.711 , 0.639 ), so the uplift cannot be read as captured label signal. Third, a numerator–denominator attribution locates it arithmetically: the label-directed numerator ( y ⊤ K y ) decreases on hardware in every configuration ( − 3.5 % to − 5.6 % , carried mainly by measured-diagonal deflation), while the centered kernel norm decreases substantially more ( − 16.6 % , − 16.8 % , − 12.5 % ), so the normalized alignment rises. Because the centered functionals annihilate affine (depolarizing-type) contractions (Section 2.4), the uplift certifies a non-affine distortion component whose action is normalization-associated; it identifies an arithmetic locus, not a physical mechanism. The absolute centered-KTA contrasts between configurations are not deletion-stable ( | z desc | ≤ 0.87 ), and the uplift deletion probe is likewise unresolved ( z desc ≈ 1.1 – 1.2 ): the robust statement is the fidelity ordering; the KTA ordering is a point-estimate pattern. We make no claim that hardware improves supervised performance.

3.4. Finite-Shot Reference Scales (RQ3) and Synthesis

The observed off-diagonal RMSE exceeds both finite-shot reference scales in every configuration: 0.0878 , 0.0864 , and 0.0427 against the conservative global scale of σ ref , global ≈ 0.0221 (about 4.0 , 3.9 , and 1.9 global reference scales) and the matrix-aware scale of ≈0.0083 (about 10.6 , 10.5 , and 5.0 matrix-aware scales). A direct reference simulation supports the same conclusion: sampling-only reconstruction of the statevector matrix at the executed shot count yields RMSE ≈ 0.0082 , on average (99th percentile, ≈0.0094), and full-matrix CKA  ≈ 0.9994 . The simulated RMSE is far below the observed RMSE, whereas the simulated CKA is far above the observed CKA. Under the stated sampling-only reference models, finite-shot sampling alone therefore cannot explain the observed hardware–statevector discrepancy. The margin over the reference scales is narrowest for the gate-twirled job, whose observed discrepancy is the smallest of the three; this is the regime in which the originally planned 4096-shot budget would have mattered most (the full quadrature bookkeeping, the fixed-RMSE projection, and the dimensionless transforms are reported in Supplementary Methods A9 and B3–B4; the matrix-aware quantities for H2 are pooled-binomial references that do not capture between-randomization variability). The synthesis across RQ1–RQ4 is then direct (Figure 2): the configuration that best matched the intended statevector geometry did not show the largest observed hardware label alignment; the fidelity leg of this cross-over is deletion-stable for the Spearman, MAE, RMSE, and full-matrix CKA contrasts (on the diagonal-excluded variant, the M2–M0 contrast sits just below the convention, at z desc = 1.95 , while the M2–M1 contrast at 2.48 passes it), while the KTA leg is not resolved at all; the observed discrepancy on which both legs act exceeds the stated sampling-only reference scales in every configuration.

4. Discussion

4.1. What the Case Study Establishes

The ZZ4 kernel was reconstructed on hardware in a limited, well-defined sense: three complete, finite, already positive-semidefinite Gram reconstructions, each retaining substantial rank-order, linear, and centered agreement with the statevector reference and each compressing the off-diagonal spread as concentration theory anticipates [4]. Among the three observed jobs, the gate-twirled job was the most faithful on every reported axis, with contrasts against both other jobs that are deletion-stable for Spearman, MAE, RMSE, and full-matrix CKA (the Pearson M2–M0 and diagonal-excluded M2–M0 contrasts fall just below the convention); dynamical decoupling alone was not separated from baseline. Because the configurations ran as single non-interleaved jobs on one backend, the ordering is descriptive of these jobs: job-to-job variation and calibration drift are confounded with configuration, and no causal mitigation-efficacy estimate is made [18,20,22].

4.2. Fidelity and Task Relevance Are Distinct Axes

The central lesson is the CKA/KTA tension: the reconstruction most faithful to the designed kernel carried the lowest hardware label alignment. The resolution is that the designed kernel was not aligned with the task to begin with: its statevector alignment sits at or below the random-label reference, as do the classical comparators. Greater observed fidelity to the intended structure therefore did not coincide with higher observed task alignment on this subset. The small uplift of the noisier jobs is normalization-associated (stronger contraction of the centered kernel norm than of the label-directed numerator); it lies outside the finite-shot null while remaining below each kernel’s own permutation reference. It is a property of the distortion, not captured signal. Implementation fidelity is necessary to realize a designed quantum model, but it does not confer task relevance; on real data, the two axes need not coincide [12,15], echoing the classical observation that similarity indices with different invariances need not track task-grounded measures [29,38,39]. Hardware QML studies should report both axes; reporting either alone invites overclaiming in one direction or the other.

4.3. Relation to Concentration, Spectral Alignment, and Kernel Design

Three strands of recent work bear on these results. First, kernel concentration does not require hardware noise: the noiseless spectrum and inductive bias of an embedding kernel are governed in part by data-scaling (bandwidth-type) hyperparameters and by feature-map architecture [14,16], and in ZZ4, the scaling of α = 2 and the architecture (two repetitions, linear entanglement) were fixed rather than tuned. The hardware contraction measured here is therefore an additional distortion on top of whatever intrinsic concentration the fixed map carries, and usefulness of the kernel is a separate question again [17]. Second, scalar centered KTA and spectral task–model alignment are complementary, not interchangeable: with K c = V Λ V ⊤ , the KTA numerator ( y ⊤ K c y = ∑ j λ j ( v j ⊤ y ) 2 ) collapses the eigenvalue-weighted label projection into one number, whereas the spectral profile of Canatar, Bordelon, and Pehlevan [40] resolves where target power lies across eigenmodes and connects it to kernel-regression generalization. Neither substitutes for statevector-referenced CKA, which measures hardware-to-reference agreement rather than task alignment; a quantitative spectral profile is beyond the frozen scope of this case study, and kernel-regression generalization was not part of the design. Third, an alternative to reproducing a fixed map more faithfully is to adapt or discover the map itself [41]; within this study, the map is deliberately frozen, and any selection on the same 24 windows would be circular; a future design would select on training data, freeze, and validate independently on hardware. Shot-budget-aware acquisition [42] is a further complementary direction for the sampling side; it does not bear on the physical attribution of the residual discrepancy, which this study deliberately leaves as a reference-scale comparison.

5. Limitations

5.1. Fixed Subset and Descriptive Resolution

All results rest on one pre-authorized frozen subset of 24 windows from one duplicate-sensor IAQ dataset and one binary target; the analysis supports reconstruction-fidelity statements, not predictive ones. Uncertainty is assessed only by leave-one-window-out deletion sensitivity; z desc is not a significance test, non-resolution is not equivalence, and median/maximum error, off-diagonal variance, and effective rank carry no deletion probe at all. Nothing here licenses extrapolation beyond this subset.

5.2. Single Backend, Single Non-Interleaved Jobs

Each configuration was executed once, non-interleaved, on ibm_fez under one pre-submission live backend-metadata snapshot (per-qubit calibration tables were not persisted; Section 2.3), so the configuration comparison is confounded with job-to-job variation and calibration drift. Because the three jobs were submitted in a fixed order, with successive submission intervals of roughly four and seven minutes and an overall span of about eleven minutes (Section 2.3), any drift in device conditions over that interval is a competing explanation for the observed ordering that the recorded data cannot exclude; the window-level jackknife quantifies deletion sensitivity within a job, not variation between jobs. This is the most consequential limit: the ordering is descriptive of these three jobs, and no general mitigation-efficacy conclusion follows [18].

5.3. Budget-Safe Shots and Pooled Twirling

Execution used 1024 shots per circuit rather than the planned 4096; the reference-scale conclusions hold under both budgets (Supplementary Methods B3–B4), at the cost of precision, where distortion is smallest. For H2, shots are pooled across 16 twirling randomizations; per-randomization counts were not persisted, so between-randomization variability is unestimated, and the binomial plug-in is a magnitude reference only. The quadrature decompositions are deterministic bookkeeping identities, not fitted noise models.

5.4. Stopped Revision-Validation Attempt

A separate prospectively specified technical validation attempt not included in the Wave 1 results stopped at its mandatory H2 acceptance gate because the tested runtime result representation (ibm_fez) did not expose separately addressable data for the 16 requested twirling randomizations. No validation block was submitted, and no primary endpoint was computed; consequently, the attempt provides no replication evidence, and the Wave 1 H2 between-randomization variability remains unestimated. This operational finding is specific to the tested software stack and result-access path.

5.5. One Fixed Map; No Downstream Evaluation; Post Hoc Additions

No alternative encoding, bandwidth, or entanglement structure was explored, and no classifier was trained: the endpoints are reconstruction fidelity and distortion, not task performance [27]. The revision-added references (per-regime permutation nulls, resampling null, attribution, U-centered CKA, deletion probes, and comparators) are deterministic or fixed-seed recomputations from the frozen artifacts, added post hoc and marked as such; they supply reference context, not configuration-level resolution.

6. Conclusions

This case study reported a fixed-protocol, statevector-referenced measurement of how faithfully one frozen four-qubit ZZ4 quantum kernel is reconstructed on a single IBM Quantum backend under three execution configurations, each a single non-interleaved job. The intended structure was reconstructed with characterizable, configuration-dependent distortion: among the three observed jobs, the gate-twirled job was the most faithful on every reported axis (deletion-stable against the baseline for Spearman, MAE, RMSE, and full-matrix CKA and just below that convention for the Pearson and diagonal-excluded variants), while dynamical decoupling alone was not separated from the baseline. The observed off-diagonal RMSE exceeds both finite-shot reference scales in every configuration, so under the stated sampling-only reference models, finite-shot sampling alone does not explain the discrepancy. The most faithful reconstruction did not carry the highest label alignment because the designed kernel was not task-aligned to begin with; the small hardware-alignment uplift is a normalization property of the non-affine distortion, not captured signal. Implementation fidelity and task relevance are distinct axes, and hardware quantum machine-learning studies should report both. These findings are descriptive and bounded to one kernel, one backend, three jobs, and a frozen N = 24 subset; they support no claim of improved prediction, hardware classifier superiority, or quantum advantage. Converting them into causal and predictive statements is deferred to future work under a new decision record, including interleaved and replicated jobs, cross-device execution, per-randomization count persistence, downstream classifier tests, and larger subsets. A future validation study would require a separately amended acquisition protocol that preserves per-randomization observations, validated by a new technical sentinel and followed by replicated time-bounded blocks; such an acquisition design would not be assumed equivalent to the historical server-side gate-twirling treatment.   

Supplementary Materials

The following supporting information can be downloaded at https://www.mdpi.com/article/10.3390/quantum8030093/s1, Supplementary Note S1 (Artifact grounding and reproducibility map), Supplementary Note S2 (Extended statistical and diagnostic tables), Supplementary Note S3 (Extended figures), and a Supplementary Methods document (Extended methods, protocol, and diagnostic detail, relocated from the main text at revision) accompany the online version of this article. Supplementary Note S1 provides the consolidated section-to-artifact correspondence for the Methods and Results, recorded against the round-0 section numbering (the mapping to the revised structure is given in Supplementary Methods Table SM.0); it documents the file paths, scripts, and checksum coverage that link each frozen reported quantity to the persisted artifacts of the public Wave 1 reproducibility package, and its Section S1.5 reproduces the directional expectations (E1–E4) verbatim with their provenance status. Supplementary Note S2 provides the full versions of the statistical and diagnostic tables, together with the revision-added diagnostic tables (Supplementary Tables S2.5–S2.9, each carrying its own provenance note referencing package release v1.3-revision-diagnostics). Supplementary Note S3 provides the extended figures: the finite-shot reference-scale figure (Supplementary Figure S3.1) and the spectral-flattening figure relocated from the main text (Supplementary Figure S3.2). The Supplementary Methods document contains the relocated protocol, derivation, and extended diagnostic material (Parts A1–A10 and B1–B6, with the location map in Table SM.0). References [5,10,20,22,29,30,35,36,37] are cited in the Supplementary Materials.

Funding

This research received no external funding.

Data Availability Statement

The frozen ZZ4 hardware subset, the statevector reference kernel, and the raw and reconstructed IBM Quantum result artifacts that support the findings of this study are publicly available in the Wave 1 reproducibility repository at a fixed commit (github.com/rsipakov/iaq-quantum-kernel-wave1-reproducibility, commit 6d14bca984486509b40850372f373c3499843dbc, release tag v1.2-wave1-manuscript) and are archived at Zenodo (DOI: 10.5281/zenodo.21332398). This is an artifact-level reproducibility package for the frozen ZZ4 hardware analysis. It does not reproduce the full upstream indoor air-quality dataset construction. The audit and analysis scripts used to reproduce the reported reconstruction, distortion, uncertainty, and shot-noise diagnostics are openly available in the same repository and archival snapshot (github.com/rsipakov/iaq-quantum-kernel-wave1-reproducibility, commit 6d14bca984486509b40850372f373c3499843dbc, release tag v1.2-wave1-manuscript; Zenodo DOI: 10.5281/zenodo.21332398), released under the MIT license. The revision-added diagnostics of Section 2.5 are reproduced by the scripts/09k_revision_diagnostics.py and scripts/verify_statevector_regeneration.py fixed-seed scripts, which are included in package release v1.3-revision-diagnostics of the same repository (Zenodo DOI: 10.5281/zenodo.21438523), together with their persisted output (hardware_analysis/zz4_wave1_revision_diagnostics.json). These scripts consume only artifacts byte-identical to the v1.2-wave1-manuscript release, which remains the provenance reference for all frozen quantities. The original numbered execution scripts retained in the repository are archival records from the source execution environment. They are not the supported reproduction path for the flat public package.

Acknowledgments

The author acknowledges the use of IBM Quantum services for this work. The views expressed are those of the author and do not reflect the official policy or position of IBM or the IBM Quantum team. During the preparation of this manuscript, the author used Claude (Anthropic) for the purposes of figure preparation, code-quality review, readability editing, and proofreading; Perplexity for literature and reference verification; and OpenAI Codex for an independent audit of the reproducibility package. The author has reviewed and edited the output of these tools and takes full responsibility for the content of this publication.

Conflicts of Interest

The author declares no competing interests.

References

  1. Havlíček, V.; Córcoles, A.D.; Temme, K.; Harrow, A.W.; Kandala, A.; Chow, J.M.; Gambetta, J.M. Supervised Learning with Quantum-Enhanced Feature Spaces. Nature 2019, 567, 209–212. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  2. Schuld, M.; Killoran, N. Quantum Machine Learning in Feature Hilbert Spaces. Phys. Rev. Lett. 2019, 122, 040504. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  3. Schuld, M. Supervised Quantum Machine Learning Models Are Kernel Methods. arXiv 2021, arXiv:2101.11020. [Google Scholar] [CrossRef] [Scilit]
  4. Thanasilp, S.; Wang, S.; Cerezo, M.; Holmes, Z. Exponential Concentration in Quantum Kernel Methods. Nat. Commun. 2024, 15, 5200. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  5. Heyraud, V.; Li, Z.; Denis, Z.; Le Boité, A.; Ciuti, C. Noisy Quantum Kernel Machines. Phys. Rev. A 2022, 106, 052421. [Google Scholar] [CrossRef] [Scilit]
  6. Wang, X.; Du, Y.; Luo, Y.; Tao, D. Towards Understanding the Power of Quantum Kernels in the NISQ Era. Quantum 2021, 5, 531. [Google Scholar] [CrossRef] [Scilit]
  7. Morawska, L.; Thai, P.K.; Liu, X.; Asumadu-Sakyi, A.; Ayoko, G.; Bartonova, A.; Bedini, A.; Chai, F.; Christensen, B.; Dunbabin, M.; et al. Applications of Low-Cost Sensing Technologies for Air Quality Monitoring and Exposure Assessment: How Far Have They Gone? Environ. Int. 2018, 116, 286–299. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  8. Karagulian, F.; Barbiere, M.; Kotsev, A.; Spinelle, L.; Gerboles, M.; Lagler, F.; Redon, N.; Crunaire, S.; Borowiak, A. Review of the Performance of Low-Cost Sensors for Air Quality Monitoring. Atmosphere 2019, 10, 506. [Google Scholar] [CrossRef] [Scilit]
  9. Peters, E.; Caldeira, J.; Ho, A.; Leichenauer, S.; Mohseni, M.; Neven, H.; Spentzouris, P.; Strain, D.; Perdue, G.N. Machine Learning of High Dimensional Data on a Noisy Quantum Processor. npj Quantum Inf. 2021, 7, 161. [Google Scholar] [CrossRef] [Scilit]
  10. Hubregtsen, T.; Wierichs, D.; Gil-Fuster, E.; Derks, P.J.H.S.; Faehrmann, P.K.; Meyer, J.J. Training Quantum Embedding Kernels on Near-Term Quantum Computers. Phys. Rev. A 2022, 106, 042431. [Google Scholar] [CrossRef] [Scilit]
  11. Glick, J.R.; Gujarati, T.P.; Córcoles, A.D.; Kim, Y.; Kandala, A.; Gambetta, J.M.; Temme, K. Covariant Quantum Kernels for Data with Group Structure. Nat. Phys. 2024, 20, 479–483. [Google Scholar] [CrossRef] [Scilit]
  12. Huang, H.Y.; Broughton, M.; Mohseni, M.; Babbush, R.; Boixo, S.; Neven, H.; McClean, J.R. Power of Data in Quantum Machine Learning. Nat. Commun. 2021, 12, 2631. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  13. Schnabel, J.; Roth, M. Quantum Kernel Methods Under Scrutiny: A Benchmarking Study. Quantum Mach. Intell. 2025, 7, 58. [Google Scholar] [CrossRef] [Scilit]
  14. Gil-Fuster, E.; Eisert, J.; Dunjko, V. On the Expressivity of Embedding Quantum Kernels. Mach. Learn. Sci. Technol. 2024, 5, 025003. [Google Scholar] [CrossRef] [Scilit]
  15. Kübler, J.M.; Buchholz, S.; Schölkopf, B. The Inductive Bias of Quantum Kernels. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), Online, 6–14 December 2021; Volume 34, pp. 12661–12673. Available online: https://proceedings.neurips.cc/paper/2021/hash/69adc1e107f7f7d035d7baf04342e1ca-Abstract.html (accessed on 6 September 2026).
  16. Canatar, A.; Peters, E.; Pehlevan, C.; Wild, S.M.; Shaydulin, R. Bandwidth Enables Generalization in Quantum Kernel Models. Trans. Mach. Learn. Res. 2023. Available online: https://openreview.net/forum?id=A1N2qp4yAq (accessed on 6 September 2026).
  17. Incudini, M.; Martini, F.; Di Pierro, A. Toward useful quantum kernels. Adv. Quantum Technol. 2025, 8, 2300298. [Google Scholar] [CrossRef] [Scilit]
  18. Ji, Y.; Polian, I. Synergistic Dynamical Decoupling and Circuit Design for Enhanced Algorithm Performance on Near-Term Quantum Devices. Entropy 2024, 26, 586. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  19. Cai, Z.; Babbush, R.; Benjamin, S.C.; Endo, S.; Huggins, W.J.; Li, Y.; McClean, J.R.; O’Brien, T.E. Quantum Error Mitigation. Rev. Mod. Phys. 2023, 95, 045005. [Google Scholar] [CrossRef] [Scilit]
  20. Viola, L.; Knill, E.; Lloyd, S. Dynamical Decoupling of Open Quantum Systems. Phys. Rev. Lett. 1999, 82, 2417–2421. [Google Scholar] [CrossRef] [Scilit]
  21. Ezzell, N.; Pokharel, B.; Tewala, L.; Quiroz, G.; Lidar, D.A. Dynamical Decoupling for Superconducting Qubits: A Performance Survey. Phys. Rev. Appl. 2023, 20, 064027. [Google Scholar] [CrossRef] [Scilit]
  22. Wallman, J.J.; Emerson, J. Noise Tailoring for Scalable Quantum Computation via Randomized Compiling. Phys. Rev. A 2016, 94, 052325. [Google Scholar] [CrossRef] [Scilit]
  23. Temme, K.; Bravyi, S.; Gambetta, J.M. Error Mitigation for Short-Depth Quantum Circuits. Phys. Rev. Lett. 2017, 119, 180509. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  24. Hicks, R.; Kobrin, B.; Bauer, C.W.; Nachman, B. Active Readout-Error Mitigation. Phys. Rev. A 2022, 105, 012419. [Google Scholar] [CrossRef] [Scilit]
  25. Smith, A.W.R.; Khosla, K.E.; Self, C.N.; Kim, M.S. Qubit Readout Error Mitigation with Bit-Flip Averaging. Sci. Adv. 2021, 7, eabi8009. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  26. Kakavand, S.; Strohmeyer, C.; Schlotter, M. Benchmarking Quantum Kernel Support Vector Machines Against Classical Baselines on Tabular Data: A Rigorous Empirical Study with Hardware Validation. arXiv 2026, arXiv:2604.18837. [Google Scholar] [CrossRef] [Scilit]
  27. Singh, G.; Jin, H.; Merz, K.M., Jr. Benchmarking MedMNIST Dataset on Real Quantum Hardware. Sci. Rep. 2026, 16, 9017. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  28. Cerezo, M.; Verdon, G.; Huang, H.Y.; Cincio, Ł.; Coles, P.J. Challenges and Opportunities in Quantum Machine Learning. Nat. Comput. Sci. 2022, 2, 567–576. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  29. Kornblith, S.; Norouzi, M.; Lee, H.; Hinton, G. Similarity of Neural Network Representations Revisited. In Proceedings of the 36th International Conference on Machine Learning (ICML) PMLR, Long Beach, CA, USA, 9–15 June 2019; Volume 97, pp. 3519–3529. Available online: https://proceedings.mlr.press/v97/kornblith19a.html (accessed on 6 September 2026).
  30. Cortes, C.; Mohri, M.; Rostamizadeh, A. Algorithms for Learning Kernels Based on Centered Alignment. J. Mach. Learn. Res. 2012, 13, 795–828. Available online: https://www.jmlr.org/papers/v13/cortes12a.html (accessed on 6 September 2026).
  31. Roy, O.; Vetterli, M. The Effective Rank: A Measure of Effective Dimensionality. In Proceedings of the 2007 15th European Signal Processing Conference (EUSIPCO), Poznan, Poland, 3–7 September 2007; pp. 606–610. [Google Scholar] [CrossRef] [Scilit]
  32. Higham, N.J. Computing a Nearest Symmetric Positive Semidefinite Matrix. Linear Algebra Appl. 1988, 103, 103–118. [Google Scholar] [CrossRef] [Scilit]
  33. Rza, S. Beyond Accuracy: A Kernel-Level Comparative Analysis of Quantum and Classical Support Vector Machines; Research Square: Durham, NC, USA, 2026; Preprint. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  34. Shastry, A.; Jayakumar, A.; Patel, A.D.; Bhattacharyya, C. Shot-Frugal and Robust Quantum Kernel Classifiers. arXiv 2022, arXiv:2210.06971. [Google Scholar] [CrossRef] [Scilit]
  35. Javadi-Abhari, A.; Treinish, M.; Krsulich, K.; Wood, C.J.; Lishman, J.; Gacon, J.; Martiel, S.; Nation, P.D.; Bishop, L.S.; Cross, A.W.; et al. Quantum Computing with Qiskit. arXiv 2024, arXiv:2405.08810. [Google Scholar] [CrossRef] [Scilit]
  36. Song, L.; Smola, A.; Gretton, A.; Bedo, J.; Borgwardt, K. Feature Selection via Dependence Maximization. J. Mach. Learn. Res. 2012, 13, 1393–1434. Available online: https://www.jmlr.org/papers/v13/song12a.html (accessed on 6 September 2026).
  37. Efron, B.; Stein, C. The Jackknife Estimate of Variance. Ann. Stat. 1981, 9, 586–596. [Google Scholar] [CrossRef] [Scilit]
  38. Raghu, M.; Gilmer, J.; Yosinski, J.; Sohl-Dickstein, J. SVCCA: Singular Vector Canonical Correlation Analysis for Deep Learning Dynamics and Interpretability. In Proceedings of the Advances in Neural Information Processing Systems, Long Beach, CA, USA, 4–9 December 2017; Volume 30. [Google Scholar] [CrossRef] [Scilit]
  39. Ding, F.; Denain, J.S.; Steinhardt, J. Grounding Representation Similarity Through Statistical Testing. In Proceedings of the Advances in Neural Information Processing Systems, Online, 6–14 December 2021; Volume 34. Available online: https://openreview.net/forum?id=_kwj6V53ZqB (accessed on 6 September 2026).
  40. Canatar, A.; Bordelon, B.; Pehlevan, C. Spectral bias and task-model alignment explain generalization in kernel regression and infinitely wide neural networks. Nat. Commun. 2021, 12, 2914. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  41. Incudini, M.; Lizzio Bosco, D.; Martini, F.; Grossi, M.; Serra, G.; Di Pierro, A. Automatic and Effective Discovery of Quantum Kernels. IEEE Trans. Emerg. Top. Comput. Intell. 2026, 10, 2210–2219. [Google Scholar] [CrossRef] [Scilit]
  42. Xu, J.; Li, C.; Zeng, D.; Paisley, J.; Zhao, Q. AQKA: Active quantum kernel acquisition under a shot budget. arXiv 2026, arXiv:2605.14672. [Google Scholar] [CrossRef] [Scilit]
Figure 1. ZZ4 kernel geometry and its hardware distortion on the frozen N = 24 subset. (a) The statevector Gram matrix and its three hardware reconstructions on a shared [ 0 , 1 ] scale; the bright diagonal (mean ≈ 0.94 ) is the measured hardware diagonal and is not, itself, evidence of reconstruction fidelity. (b) Entrywise absolute error | K hw − K SV | ; error concentrates in a subset of window pairs under baseline and dynamical decoupling and is markedly smaller in the gate-twirled job. White lines mark the fixed 16 | 8 train/test split. Descriptive diagnostic: single non-interleaved jobs on ibm_fez at 1024 shots.
Quantumrep 08 00093 g001
Figure 2. Fixed-subset ZZ4 hardware-kernel reconstruction across three execution configurations. (a) Off-diagonal kernel entries (276 unordered pairs) against the statevector reference; compression toward a common background is strongest for baseline and weakest for gate twirling. (b) Observed off-diagonal error against the global and matrix-aware finite-shot reference scales; the observed RMSE exceeds both in every configuration (quadrature bookkeeping, not a physical noise-model decomposition). (c) Centered geometric fidelity (full-matrix CKA) rises from M0 to M2; the full-matrix M2 contrasts are deletion-stable ( z desc = 2.83 , 3.09 ), the diagonal-excluded M2–M0 contrast sits just below the convention ( 1.95 ) while M2–M1 passes it ( 2.48 ), and the M1–M0 contrast is unresolved ( 0.63 ). (d) Absolute hardware–label alignment ( KTA c , point estimates; contrasts unresolved, | z | ≤ 0.87 ) falls as fidelity rises; the gray interval is the statevector label-permutation reference (null mean to q 95 ; Supplementary Table S2.3), and each hardware point sits at or below its own random-label mean (Supplementary Table S2.6). Descriptive diagnostic on the frozen N = 24 subset; single non-interleaved jobs on ibm_fez at 1024 shots.
Quantumrep 08 00093 g002
Table 1. Headline statevector-to-hardware ZZ4 distortion metrics for the three observed jobs. Statevector references: KTA c ( K SV , y ) = 0.1585 ; erank ( K SV ) = 17.97 (hardware 21.18 , 21.22 , and 19.79 ). Pearson correlations are 0.827 , 0.843 , and 0.986 ; median/maximum absolute errors are 0.0262 / 0.569 , 0.0261 / 0.564 , and 0.0162 / 0.264 . The U-centered CKA is the post hoc diagonal-excluded (HSIC ⁠ 1 ) variant, reported because the shared near-unit measured diagonal (mean ≈ 0.94 ) inflates the full-matrix value. Uncertainty status (deletion scale, Supplementary Methods B2): the M2 contrasts against M0 and M1 are deletion-stable for Spearman, MAE, RMSE, and full-matrix CKA ( | z desc | ≈ 2.8 –5); the U-centered M2-M0 contrast is weaker ( z desc = 1.95 ; M2-M1 2.48 ); Pearson M2-M0 is borderline ( 1.92 ); no M1-M0 contrast is deletion-stable ( | z desc | ≤ 1.96 ); all centered-KTA contrasts are unresolved ( | z desc | ≤ 0.87 ). All values are point estimates on the frozen N = 24 subset; no formal significance test or mitigation-efficacy estimate is implied. Full and unsplit tables: Supplementary Tables S2.1 and S2.2 and Supplementary Methods B2.
ConfigurationArtifact RegimeSpearmanMAERMSECKA (Full)U-CKA (Post Hoc) KTA c
M0 baselineH0 0.741 0.0490 0.0878 0.933 0.8156 0.1833
M1 dynamical decouplingH1 0.775 0.0473 0.0864 0.937 0.8373 0.1815
M2 gate twirlingH2 0.944 0.0257 0.0427 0.989 0.9863 0.1710
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.