Article

A Deep Learning-Driven Binocular Vision Path Detection Approach for Orchard Robots

College of Mechanical Engineering, Shenyang Ligong University, No. 6, Nanping Middle Road, Hunnan District, Shenyang 110159, China
*
Author to whom correspondence should be addressed.
AgriEngineering 2026, 8(9), 369; https://doi.org/10.3390/agriengineering8090369
Submission received: 27 April 2026 / Revised: 7 August 2026 / Accepted: 31 August 2026 / Published: 2 September 2026

Abstract

Autonomous driving relying on visual navigation plays a vital role in promoting automation within the jujube industry. Conventional visual navigation strategies fail to satisfy the demands of straddle-type jujube harvesters owing to their unique row-straddling configuration and complex orchard environments. Accordingly, this paper proposes a novel binocular vision-based path detection algorithm for autonomous jujube harvesters. In the proposed method, target trunks detected from binocular images are used to generate a navigation path that better aligns with the operating trajectory of harvester. A Single Shot MultiBox Detector (SSD) deep learning model is employed to detect trunk bounding boxes. To mitigate interference induced by false detections from the deep learning model, a curve-fitting-based path calibration strategy is implemented. Experimental results demonstrate that the proposed algorithm achieves a detection speed of 14.38 fps with a false detection rate of 3.64%, satisfying the operational demands for autonomous driving of jujube harvesters. Furthermore, this algorithm can be extended to other orchard mobile robots that execute row-straddling operations similar to jujube harvesters.

1. Introduction

The development of orchard mobile robots offers promising opportunities for improving automation, efficiency, and sustainability in fruit production [1]. To improve the automation level of the jujube industry and promote industrial transformation, a straddle-type jujube harvester was designed and developed by the laboratory at Shihezi University. The harvester adopts a row-straddling operating configuration, allowing it to straddle jujube tree rows and navigate along tree trunks during harvesting operations. To further reduce operational costs and improve the level of automation, developing an autonomous navigation system for the harvester has become a critical requirement. Furthermore, effective navigation path planning is essential for achieving autonomous operation of the jujube harvester [2]. However, conventional navigation methods are unsuitable for jujube harvesters due to the complex orchard environment and their unique row-straddling operating configuration. Therefore, this paper proposes a novel navigation path detection algorithm to enable autonomous operation of the jujube harvester.
Existing navigation path detection methods for orchard mobile robots can be broadly classified into three categories based on sensing technologies: GNSS (Global Navigation Satellite System)-based methods, LiDAR (Light Detection And Ranging)-based methods, and Computer Vision-based methods [3].
With the availability of GNSS for civilian applications, agricultural production has been significantly advanced, particularly in the field of precision agriculture [4]. Currently, RTK-DGP-based navigation systems can achieve centimeter-level positioning accuracy and have been successfully implemented in agricultural fields, such as sugar beet production [5]. However, the reliability of GNSS-based navigation is significantly affected in orchard environments, where satellite signals may become unstable, unavailable, or inaccurate due to obstructions caused by tree canopies and complex terrain conditions [6,7,8].
To overcome the limitations of GNSS-based navigation in orchard environments, LiDAR has been widely investigated as a local perception sensor for autonomous navigation due to its ability to extract geometric features from surrounding scenes [9]. Several studies have explored LiDAR-based navigation methods for orchard mobile robots. A navigation method equipped with a 2D LiDAR scanner was developed by integrating Particle filter and Kalman filter algorithms [10]. Furthermore, a line feature extraction-based navigation approach was proposed using the PEARL algorithm on 2D point clouds [11]. Nevertheless, LiDAR-based navigation still faces challenges in complex orchard environments because sufficient and distinctive geometric features or reliable landmarks are difficult to identify [3]. Moreover, the relatively high cost of LiDAR sensors limits their widespread application in agricultural robotic systems [12].
With the rapid development of digital image processing technologies, computer vision has been widely adopted in agricultural production due to its intuitive perception capability and high accuracy [13]. In recent years, vision-based navigation of orchard mobile robots has attracted considerable research interest [14,15]. According to the number of cameras employed, existing visual navigation approaches can generally be categorized into monocular vision-based and stereo vision-based methods.
Monocular vision-based navigation approaches mainly rely on detecting navigation paths from in-row regions [16,17,18] or tree canopies [19]. Nevertheless, their performance is often affected by illumination variations and occlusions, resulting in limited navigation accuracy [20]. In addition, the canopy characteristics of jujube trees during the harvesting season are relatively inconspicuous and highly similar to the surrounding ground background, which increases the difficulty of image segmentation. More importantly, since jujube harvesters perform row-straddling operations and require navigation according to trunk positions, monocular vision-based approaches are inadequate for autonomous navigation because canopy information cannot reliably represent the spatial distribution of tree trunks.
Compared with monocular vision, stereo vision, especially binocular vision, exhibits superior performance in complex environments with uneven illumination and low contrast and has been widely used for terrain mapping and environmental perception [21,22]. In general, binocular vision systems estimate depth information by constructing disparity maps from the correspondence between left and right images, which enables 3D reconstruction and provides reliable information for navigation path generation [12,23,24,25]. Furthermore, binocular vision is particularly suitable for orchard mobile robots with limited payload and power capacity due to its passive sensing capability and relatively low hardware cost [20,26]. However, conventional binocular vision-based navigation approaches cannot meet the requirements of jujube harvesters because the fixed installation configuration of stereo cameras makes it difficult to directly obtain the trunk-related position navigation information required for row-straddling operations.
Based on the aforementioned analysis, this paper proposes a novel binocular vision-based navigation path detection algorithm for autonomous jujube harvesters. The proposed method employs deep learning techniques to estimate the positions of target trunks on both sides of the harvester and generate the corresponding navigation path. Experimental results demonstrate that the proposed algorithm can accurately determine navigation paths for jujube harvesters and meet practical operational requirements. This study provides a theoretical foundation for implementing autonomous navigation in jujube harvesting systems. The main contribution of this work is the development of a trunk-guided navigation path detection algorithm based on a specially designed binocular vision system, which addresses the unique requirements of straddle-type jujube harvesters.

2. Materials and Methods

2.1. Experimental Platform and Equipment

The objective of this study is to develop a binocular vision-based navigation path detection algorithm for autonomous navigation of the jujube harvester based on tree trunk detection. The experimental platform and equipment, including the jujube harvester and binocular cameras, are described in the following sections.

2.1.1. Jujube Harvester

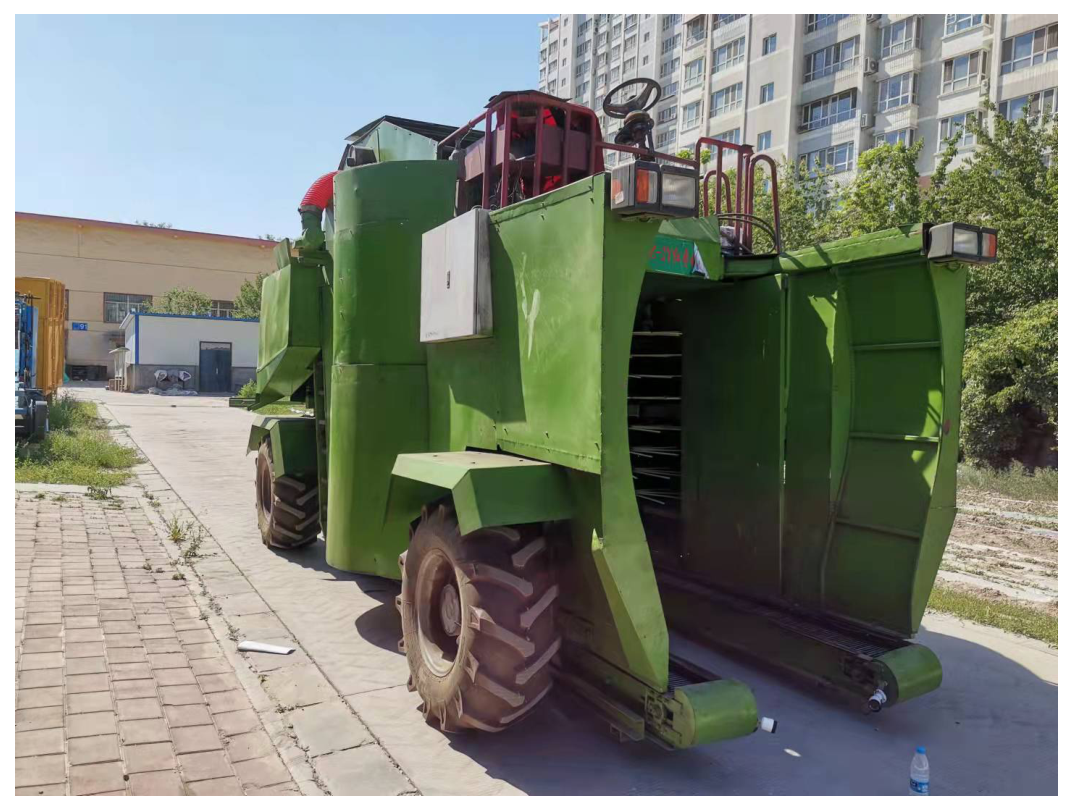
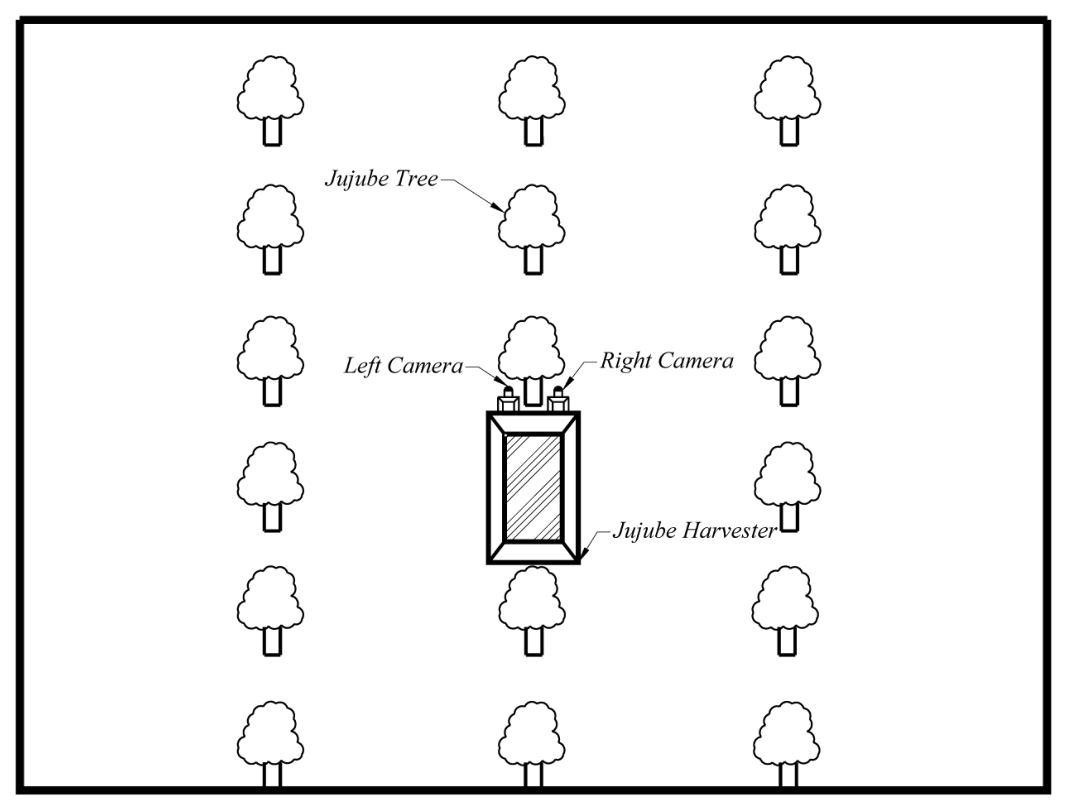
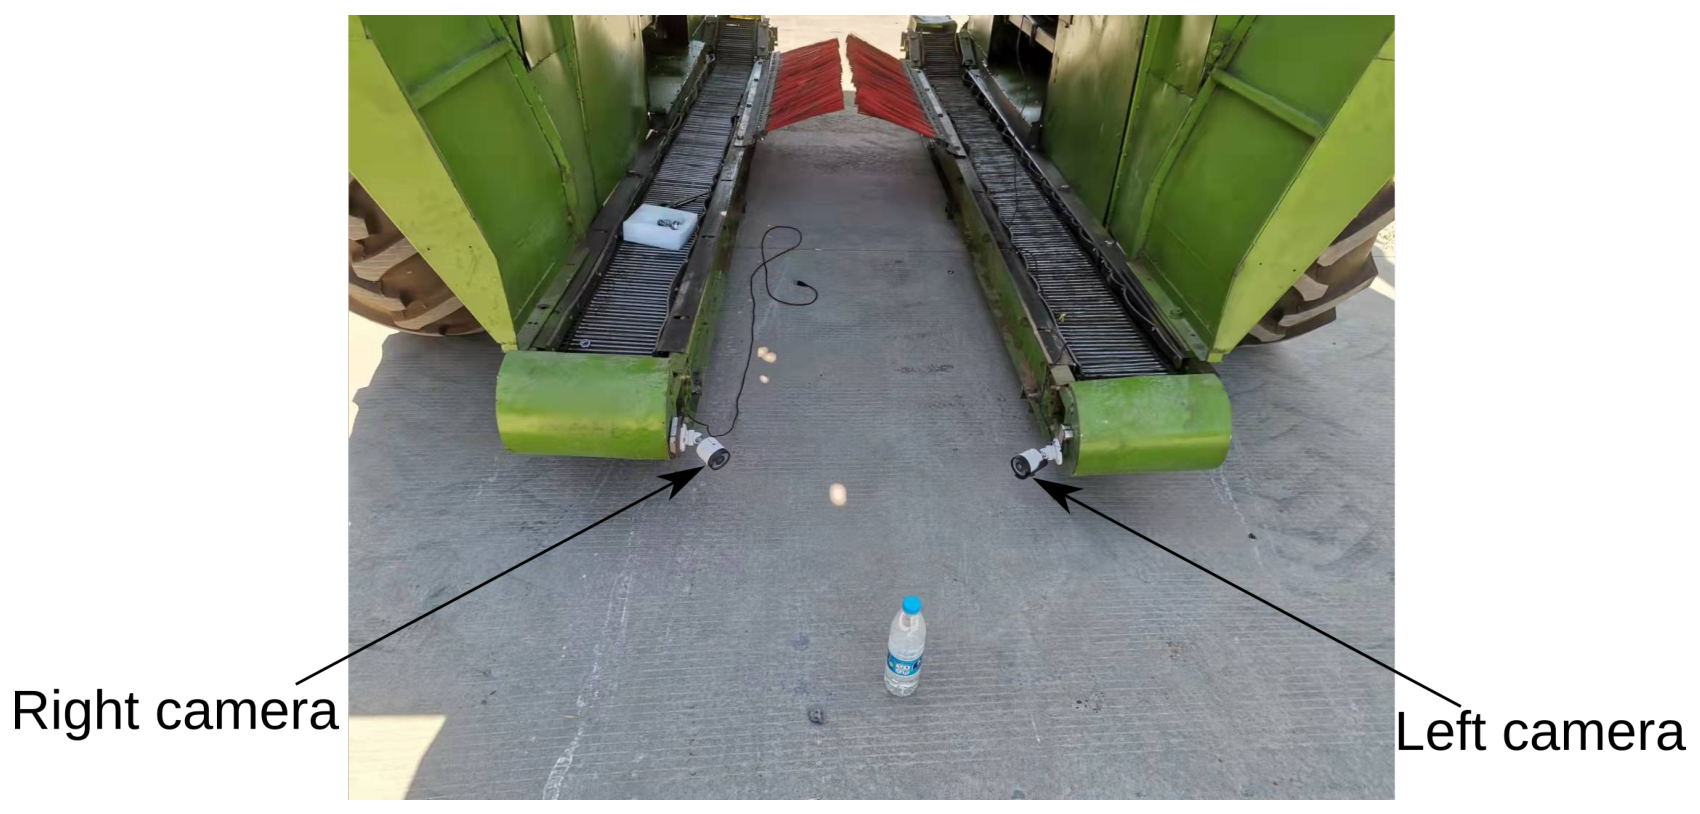
The proposed method was developed on the jujube harvester shown in Figure 1, which was independently designed and manufactured by Shihezi University. The harvester achieves automatic jujube harvesting by shaking tree branches and collecting the falling fruits. Figure 2 presents the top-view schematic of the jujube harvester during its row-straddling operation. The harvester moves along the tree row while straddling the jujube trees, and the binocular cameras are mounted on the lower left and lower right sides of the machine, respectively.

2.1.2. Binocular Cameras

Figure 3 illustrates the binocular camera configuration on the jujube harvester. The cameras are symmetrically mounted on the left and right transmission devices, with a height of 40 cm above the ground and a baseline distance of 50 cm. The optical axes are oriented at 45° to the forward direction of the harvester. The main camera specifications are provided in Table 1.
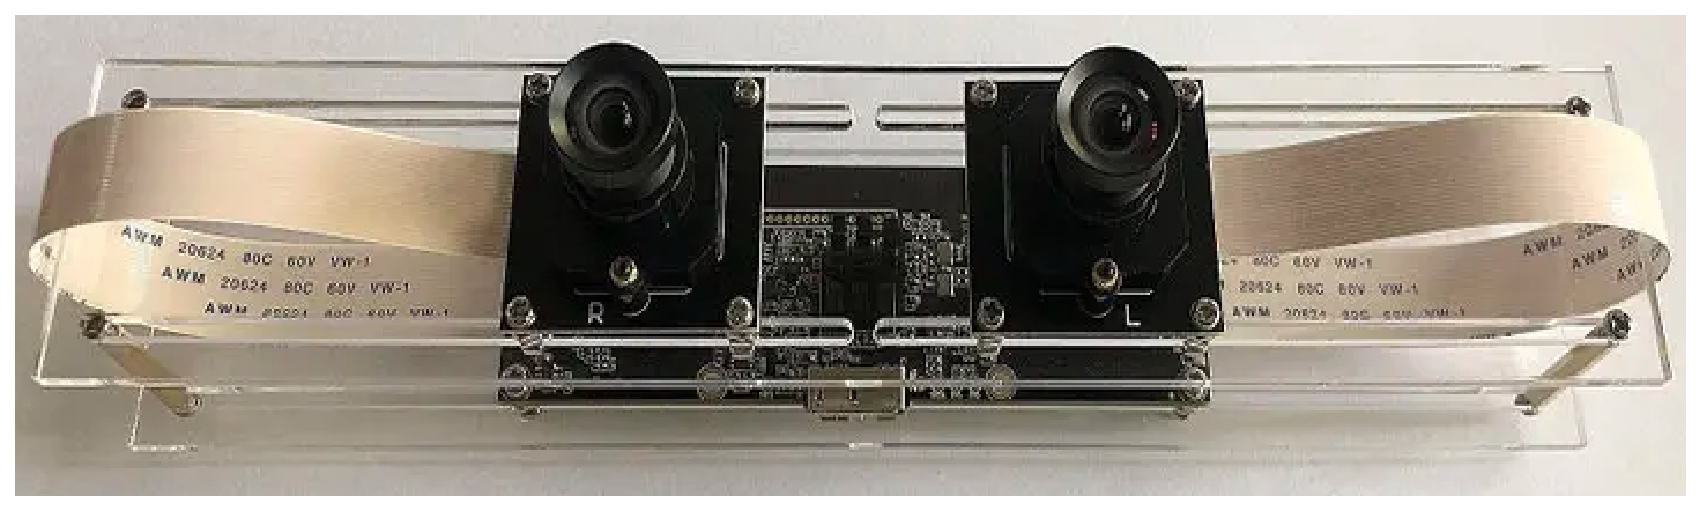
Existing navigation path estimation methods cannot be directly applied to the jujube harvester due to its unique binocular camera configuration. Unlike conventional binocular systems with closely spaced cameras (Figure 4), the proposed system adopts a wider camera baseline, resulting in the following challenges:
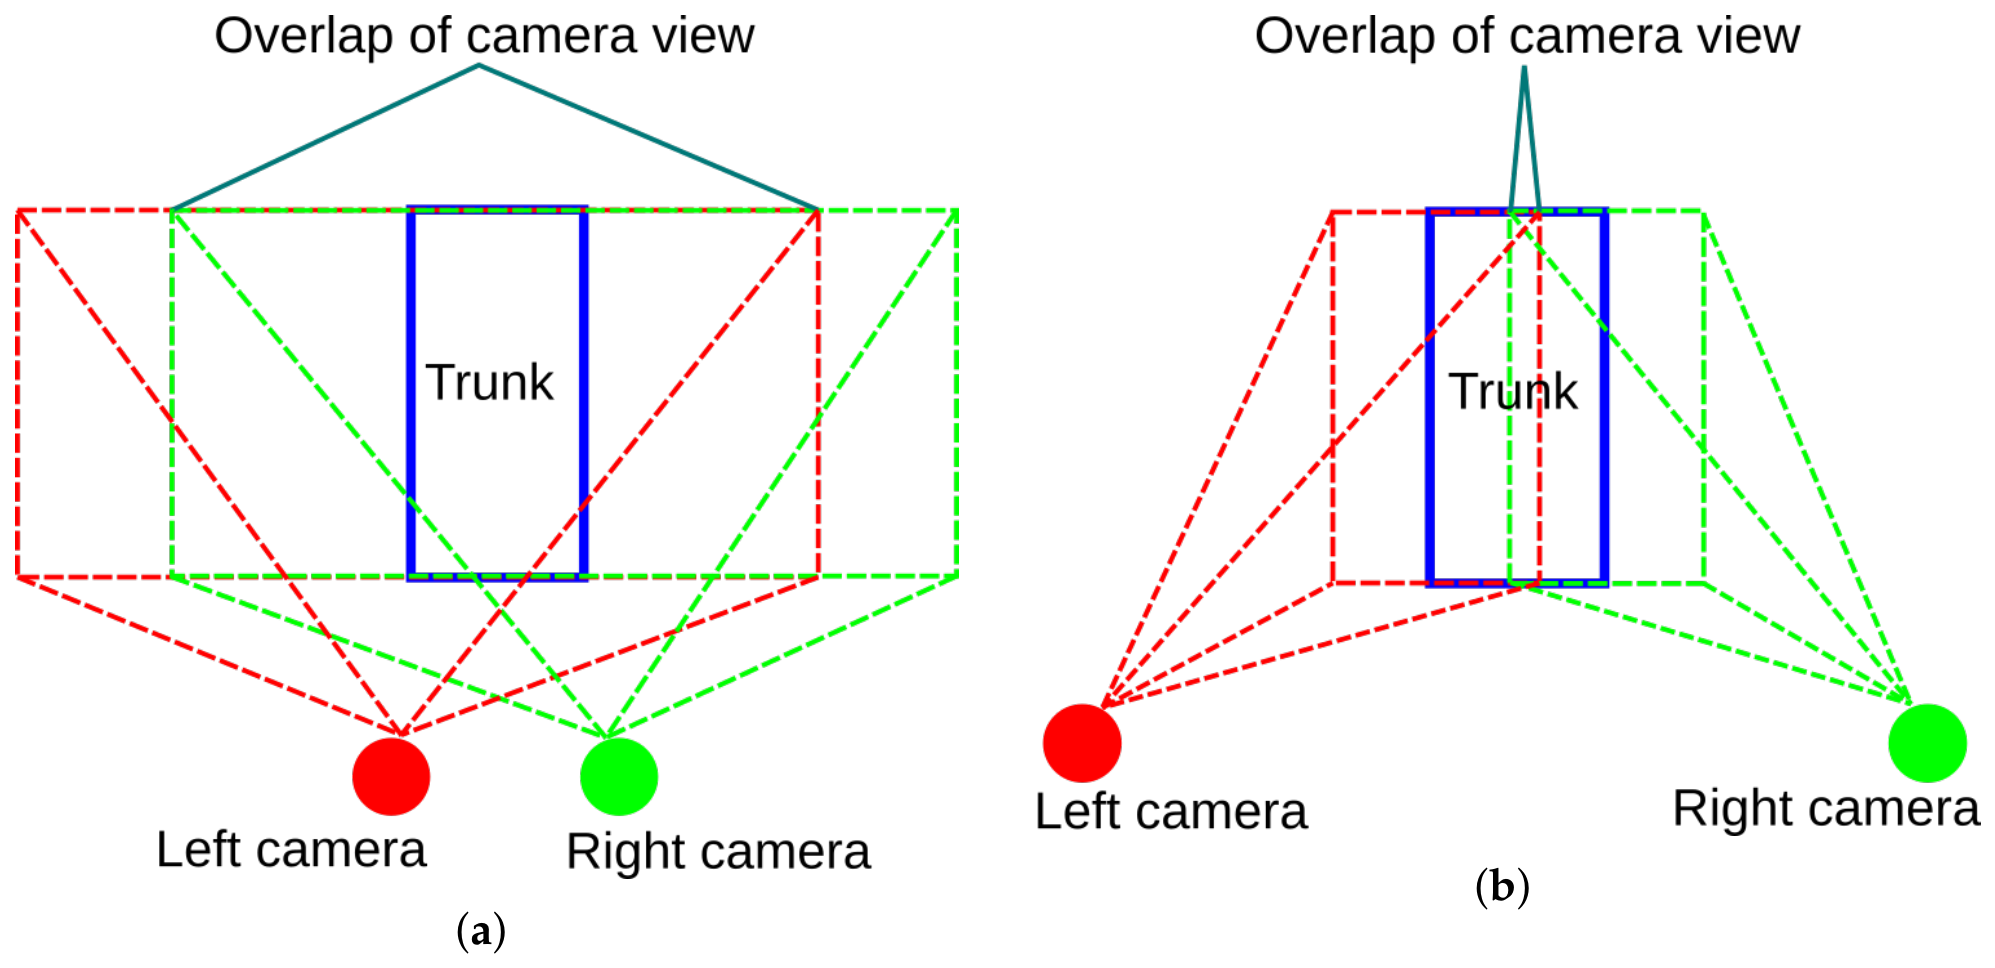
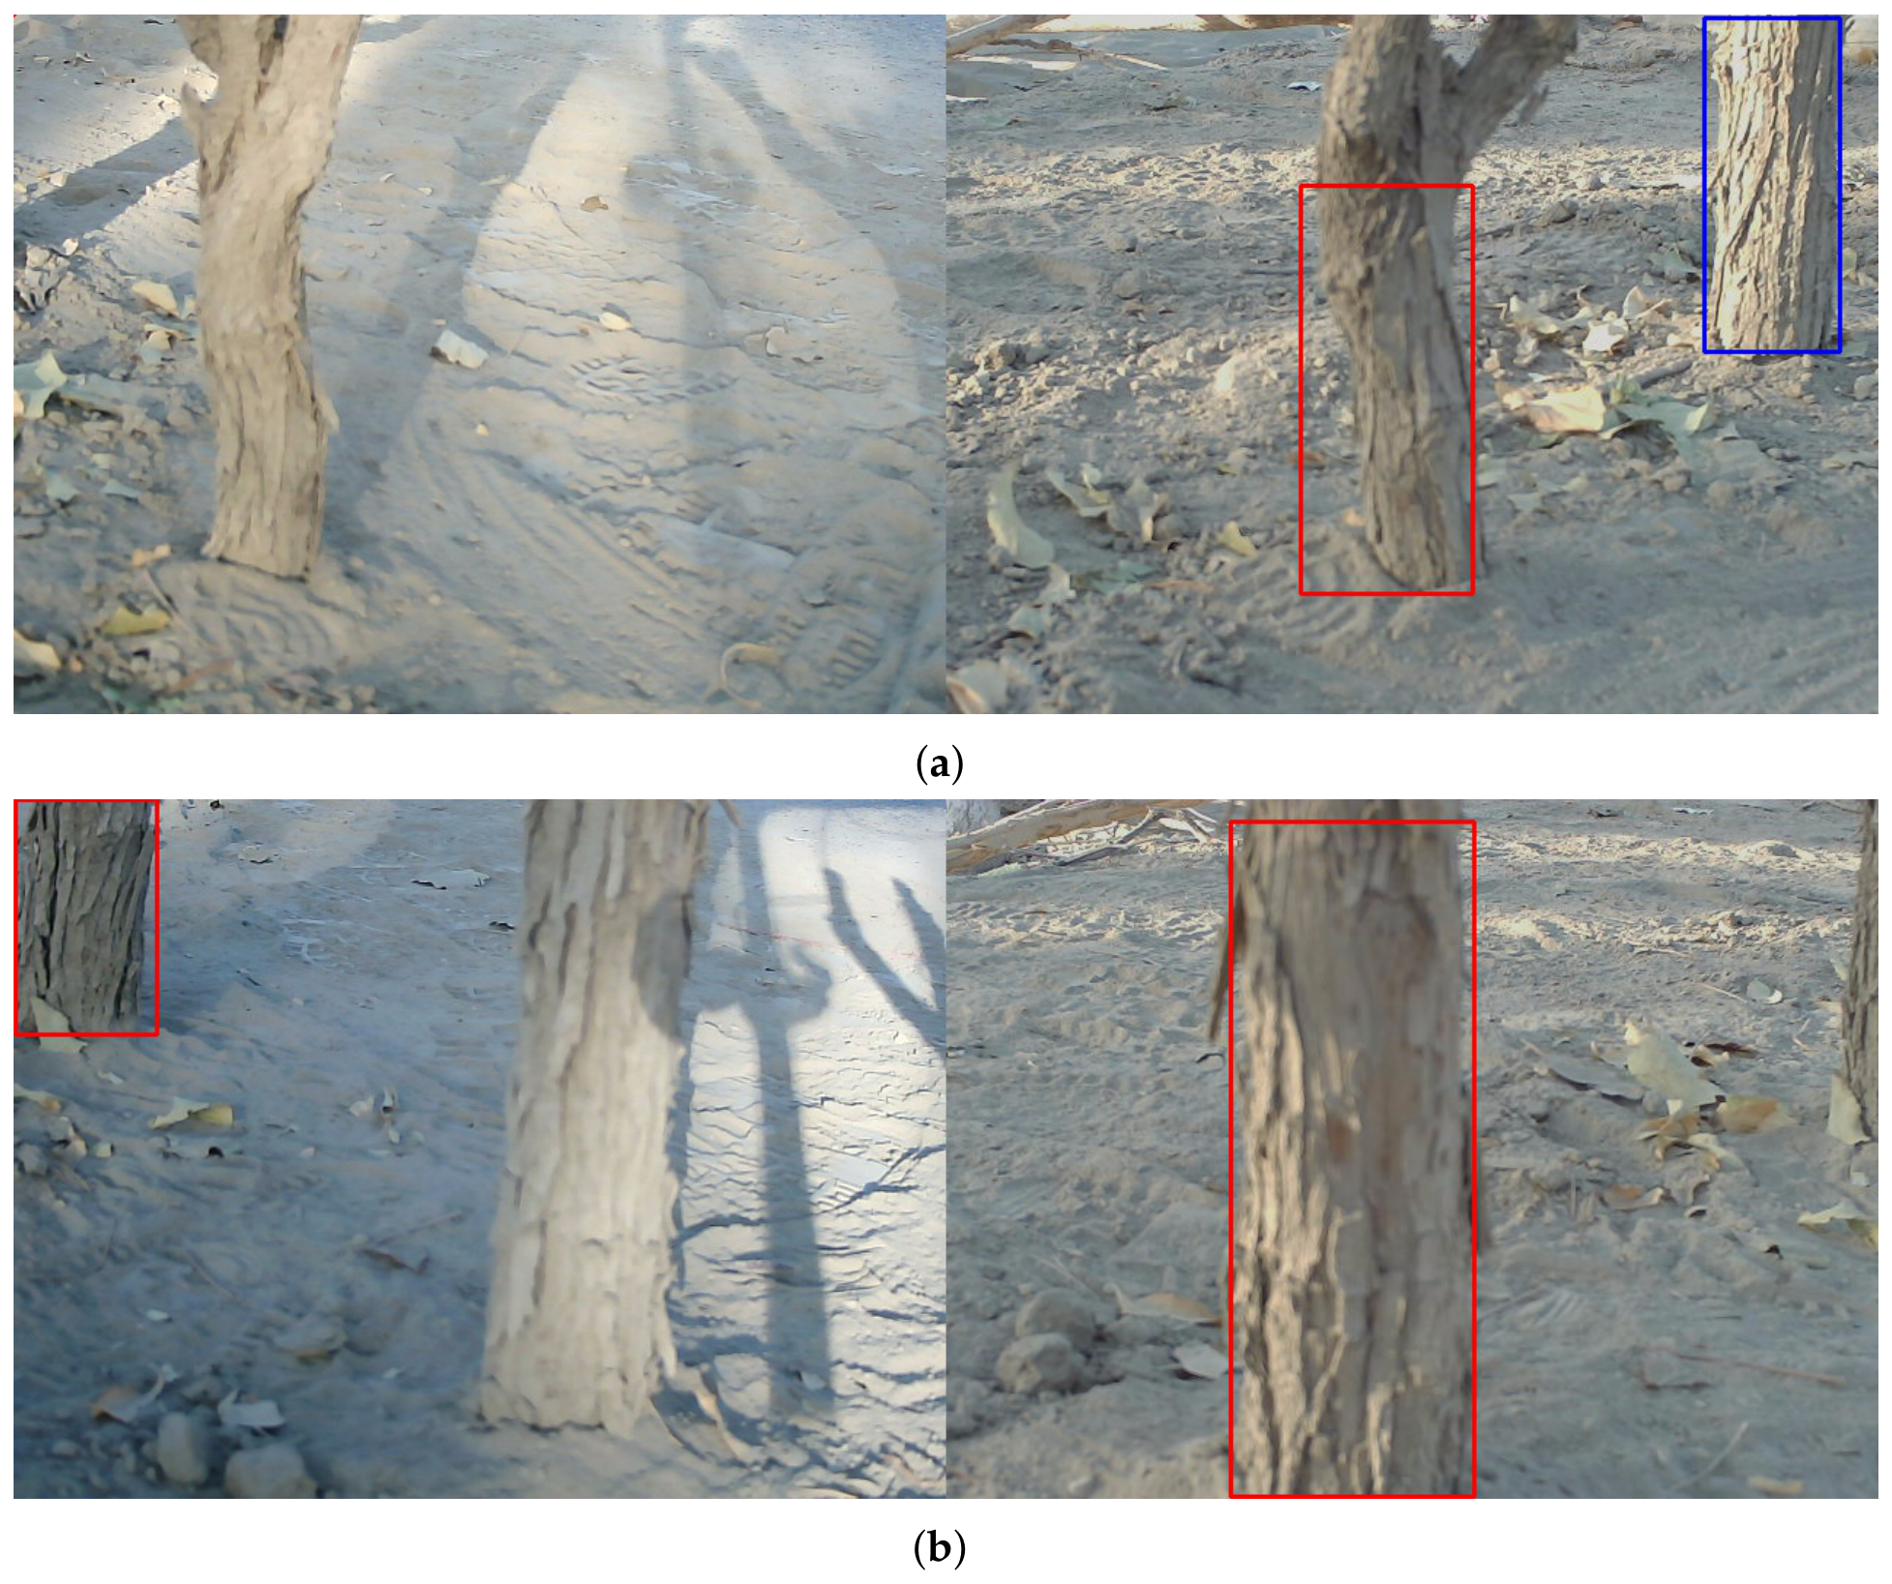
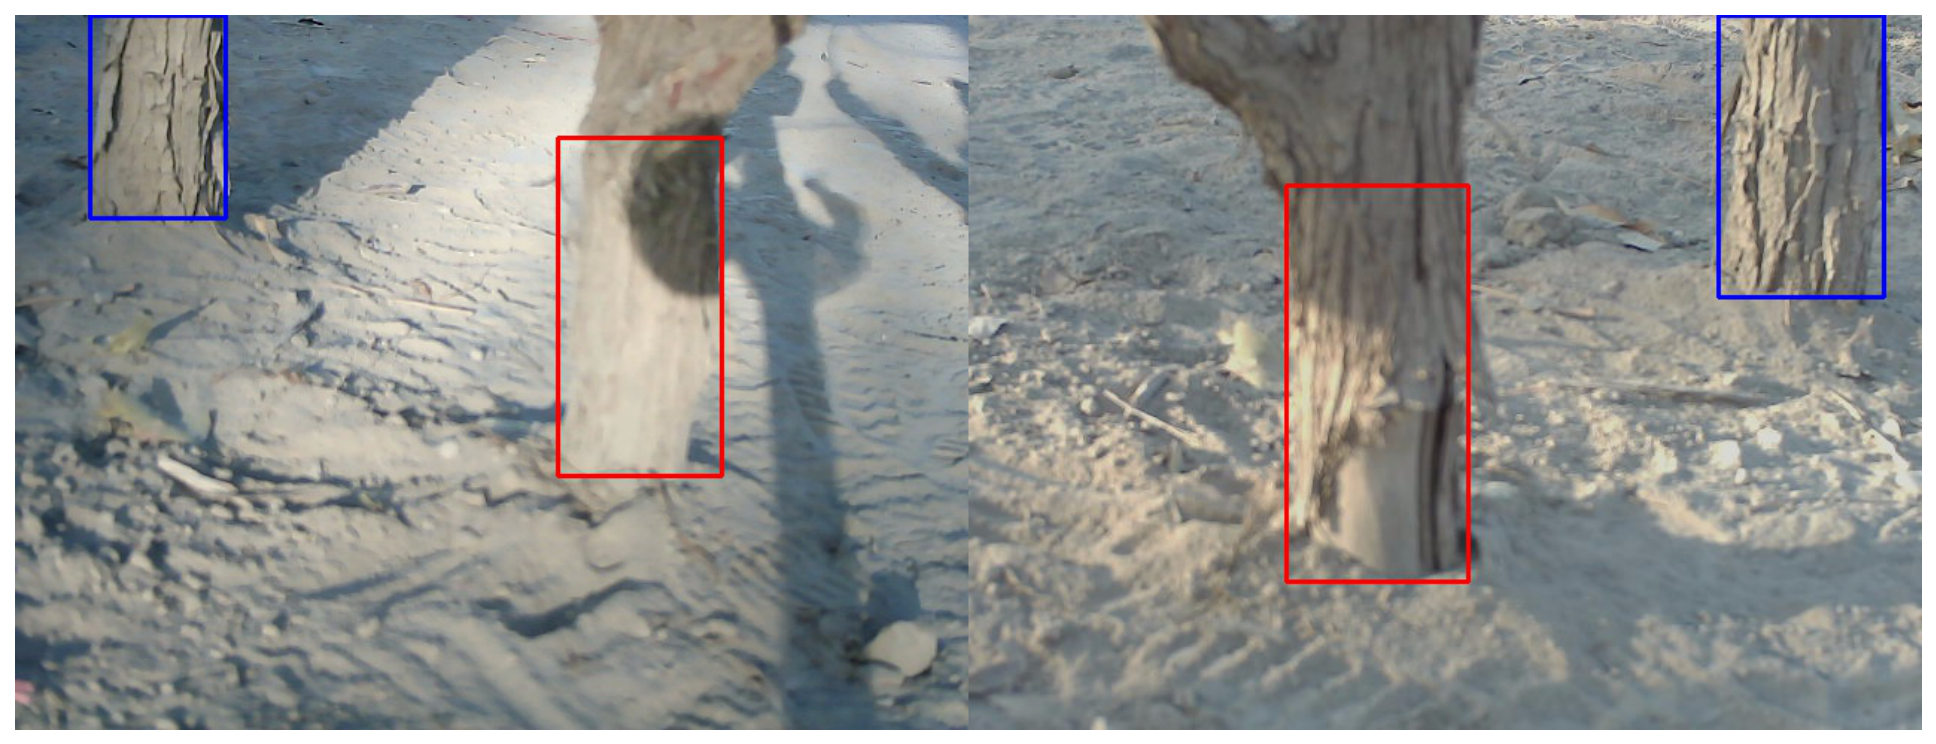
First, Figure 5 presents the binocular images acquired by the cameras mounted on the jujube harvester. Rectangular boxes with identical colors denote the same trunk in both views. As shown in Figure 6b, the overlapping field of view between the cameras is limited and changes during harvesting. Conventional stereo vision methods require stable camera geometry and epipolar constraints, which are difficult to preserve under field conditions. Although the cameras are rigidly mounted on the chassis, harvesting-induced vibrations continuously alter their relative pose and invalidate the calibrated epipolar geometry required by stereo matching algorithms such as ELAS (Efficient Large Scale Stereo Matching) [27]. Therefore, static calibration-based stereo methods cannot provide reliable trunk detection for jujube harvesting, motivating the proposed approach.

2.2. Image Acquisition

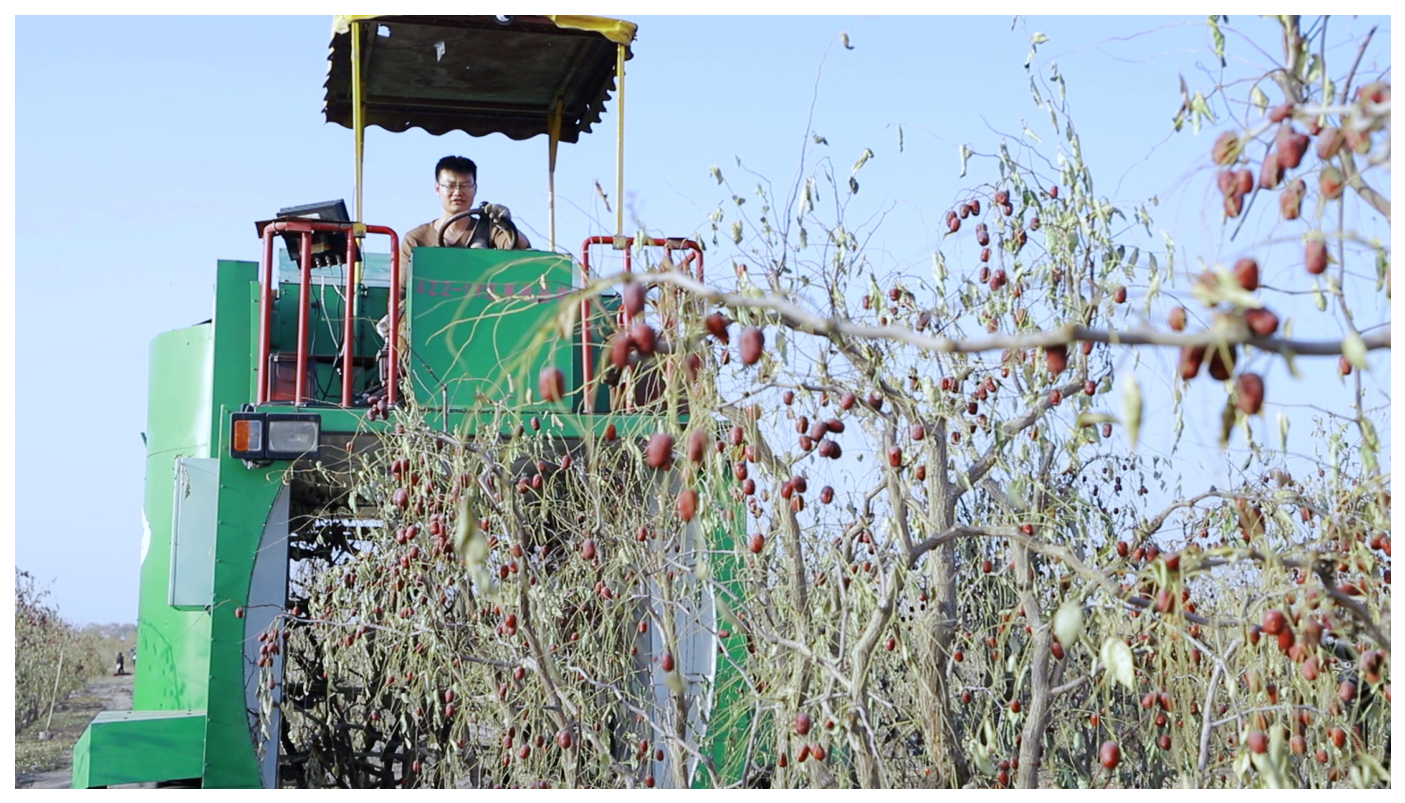
The video data were collected from 11 November 2021 to 1 December 2021, between 8:00 a.m. and 6:00 p.m. under clear weather conditions in a jujube orchard in A’er, Xinjiang, China. The cameras were installed according to the configuration described in Section 2.1.2. A worker manually drove the jujube harvester at an operating speed of 2.2 km/h to record the video sequences. Figure 7 shows the video acquisition process in the orchard, and the collected dataset is summarized in Table 2.

2.3. Navigation Path

The objective of this study is to develop a trunk-guided navigation path detection method for autonomous jujube harvesting. Considering the unique binocular camera configuration of the jujube harvester, a customized binocular vision-based approach is proposed to generate suitable navigation paths.
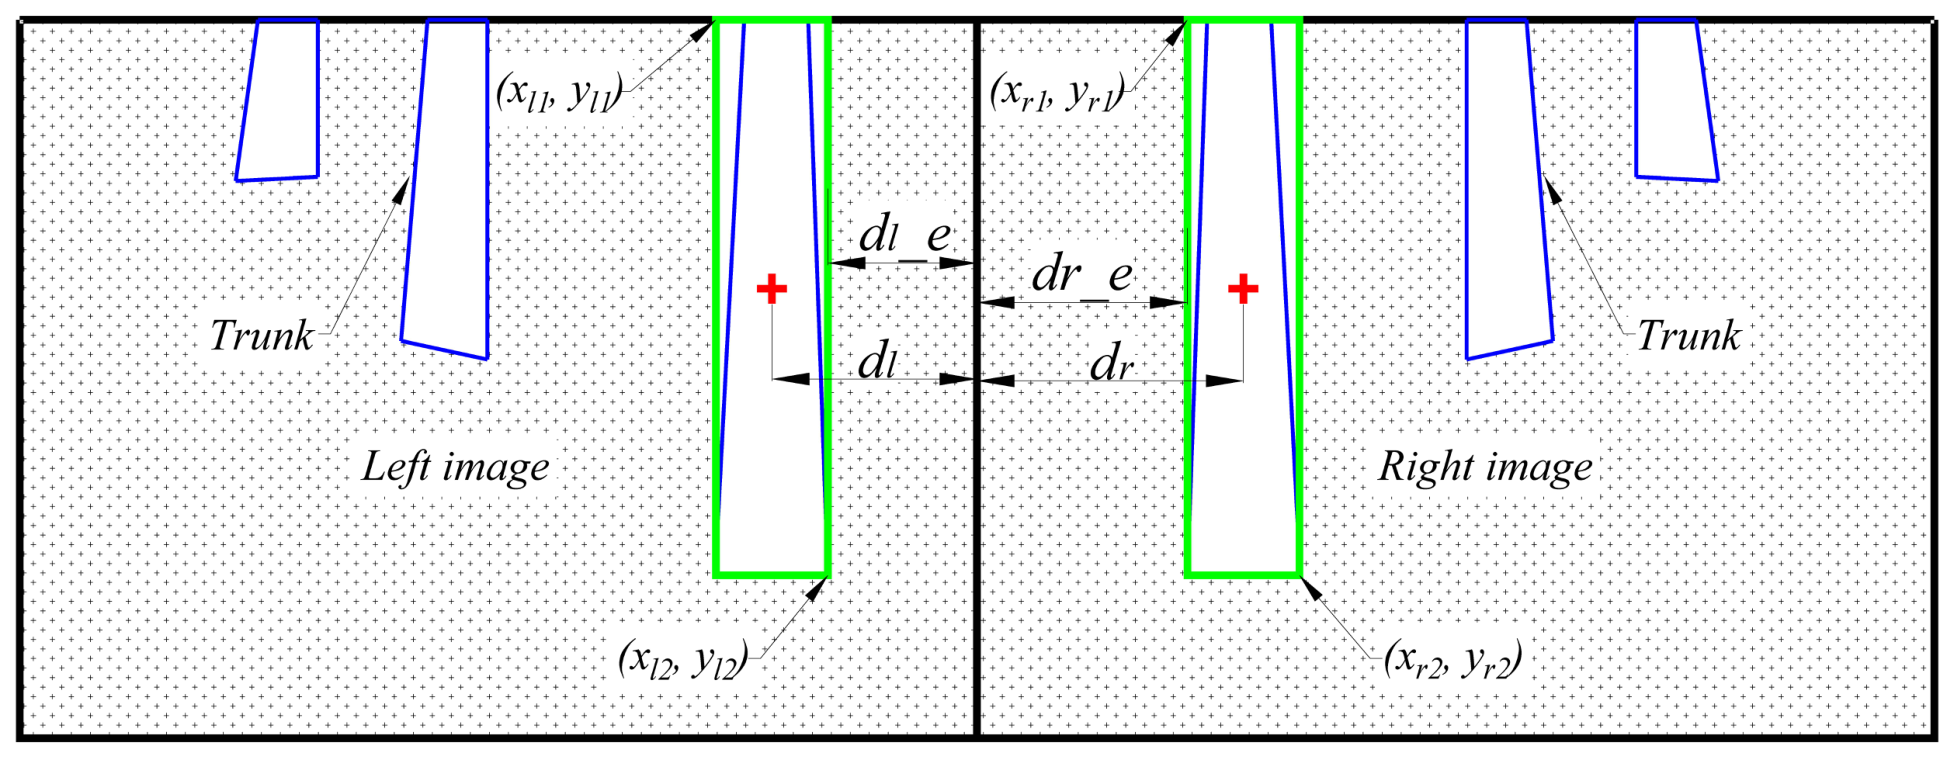
Figure 8 illustrates the image configuration used for navigation path calculation. The distances d l and d r between the center (red cross) of the target trunk bounding box (green rectangle) and the left and right image boundaries are used to calculate the navigation path C in Equation (1). The target trunk is selected as the closest trunk detected by the object detection model.
C = T u r n r i g h t d r > d l K e e p d r = d l T u r n l e f t d r < d l
Equation (2) defines the calculation of d l and d r . The coordinates ( x l 1 , y l 1 ) and ( x l 2 , y l 2 ) denote the top-left and bottom-right corners of the target trunk bounding box in the left image, while ( x r 1 , y r 1 ), ( x r 2 , y r 2 ) represent the corresponding corners in the right image. w is the width of the left image. The top-left corner is set as the coordinate origin, and the horizontal and vertical directions are defined as the x-axis and the y-axis, respectively.
d l = w x l 1 + x l 2 2 d r = x r 1 + x r 2 2
Additionally, d l _ e and d r _ e denote the distances between the target trunk bounding box edges and the image boundaries, as calculated in Equation (3). They are used to determine whether the trunk reaches the image boundary.
d l _ e = w x l 2 d r _ e = x r 1

2.4. Trunk Boxes Obtained

The first step of the proposed method is to detect jujube tree trunks from binocular images. A deep learning-based object detection model is employed to generate trunk bounding boxes due to its effectiveness in object detection tasks.

2.4.1. Dataset Generation

The dataset consists of 15,188 images collected from jujube orchards. A total of 3155 images were randomly selected and manually annotated using LabelImg (https://github.com/heartexlabs/labelImg (accessed on March 6 2022)). The annotated dataset was randomly divided into training, testing, and validation sets with ratios of 60%, 20%, and 20%, containing 1893, 631, and 631 images, respectively.

2.4.2. Model Selection Method

With the rapid advancement of deep learning technologies, deep learning-based visual navigation has attracted increasing attention in orchard mobile robot applications [28,29,30]. Deep learning enables computational models to learn hierarchical data representations through multiple layers [31].
Three representative detectors, Faster R-CNN, YOLO V3, and SSD, were selected for comparison, representing two-stage high-accuracy, single-stage high-speed, and balanced single-stage architectures, respectively. These models were chosen to evaluate the adaptability of classical object detection frameworks for jujube trunk recognition. Lightweight detectors such as YOLO V7 and YOLO V8 were not included because the embedded computing platform of the harvester lacks compatibility with their required operators and frameworks. Moreover, this study focuses on robust path calibration rather than network backbone improvement. The deployment of advanced lightweight detectors on agricultural robotic platforms will be explored in future work.
Furthermore, a study [32] demonstrated that Faster R-CNN [33] outperformed YOLO V3 [34] in trunk detection and was successfully applied to orchard robot navigation under varying illumination conditions using thermal images. The SSD model [35] provides a favorable trade-off between detection accuracy and speed and has been widely adopted in industrial applications. Therefore, Faster R-CNN, YOLO V3, and SSD were selected for comparative evaluation of jujube trunk detection.
The model selection strategy was developed based on [36]. K-fold cross validation was employed to evaluate model performance [37,38]. The mean Average Precision ( m A P ) was selected as the primary evaluation metric for object detection [39,40,41,42]. Considering the requirement for accurate trunk localization, the IoU threshold was set to 0.9, and m A P @ 0.9 was adopted for evaluation. Detection speed was also included due to its importance in practical operations. In addition, batch size and learning rate were optimized as critical hyperparameters affecting model performance [43]. The model selection procedure is described as follows.

2.4.3. Image Augmentation

Image augmentation is widely used in deep learning training to increase data diversity, improve model generalization, and reduce overfitting [44,45]. Traditional augmentation techniques include affine transformations and color modifications [46]. Since trunk position is essential for navigation, rotation augmentation was excluded in this study. The applied augmentation methods included RGB-HSV color conversion, random contrast, random brightness, random cropping, expansion, random mirroring, and random light noise addition [47].

2.4.4. Semi-Supervised Training

Manual annotation is labor-intensive and time-consuming [48]. To reduce annotation requirements, semi-supervised learning utilizes both labeled and unlabeled data during model training [49,50]. Self-training is a widely used semi-supervised strategy for object detection, where pseudo-labels generated by model predictions are used to expand the training set [49,51]. Following [52], a pseudo-label-based self-training method was adopted in this study. The initial model M was trained using labeled data, and the iterative procedure is described as follows.
1.
Generate pseudo labels for randomly selected unlabeled images using model M with confidence threshold c.
2.
Combine pseudo-labeled images with the original training data.
3.
Train a new model M using the updated dataset.
4.
Repeat Steps 2 to 3 until all unlabeled images are utilized.
5.
Select the model with the highest m A P @ 0.9 on the test dataset.

2.5. Finding Target Trunk Boxes

Since multiple trees may appear in a single image, multiple trunk bounding boxes can be detected simultaneously. The trunk closest to the jujube harvester is selected as the target trunk. According to Section 2.3, this trunk corresponds to the bounding box closest to the image boundary in each binocular image. Therefore, d l or d r is calculated for all detected trunk boxes, and the box with the minimum value is selected as the target trunk box.

2.6. Path Calibration Method

Since deep learning models may produce detection errors, abnormal predictions must be handled before generating navigation commands. A filtering strategy is applied to remove frames with abnormal d l or d r values, and the trunk position is subsequently estimated to maintain continuous and stable control.

2.6.1. Finding the False Frame

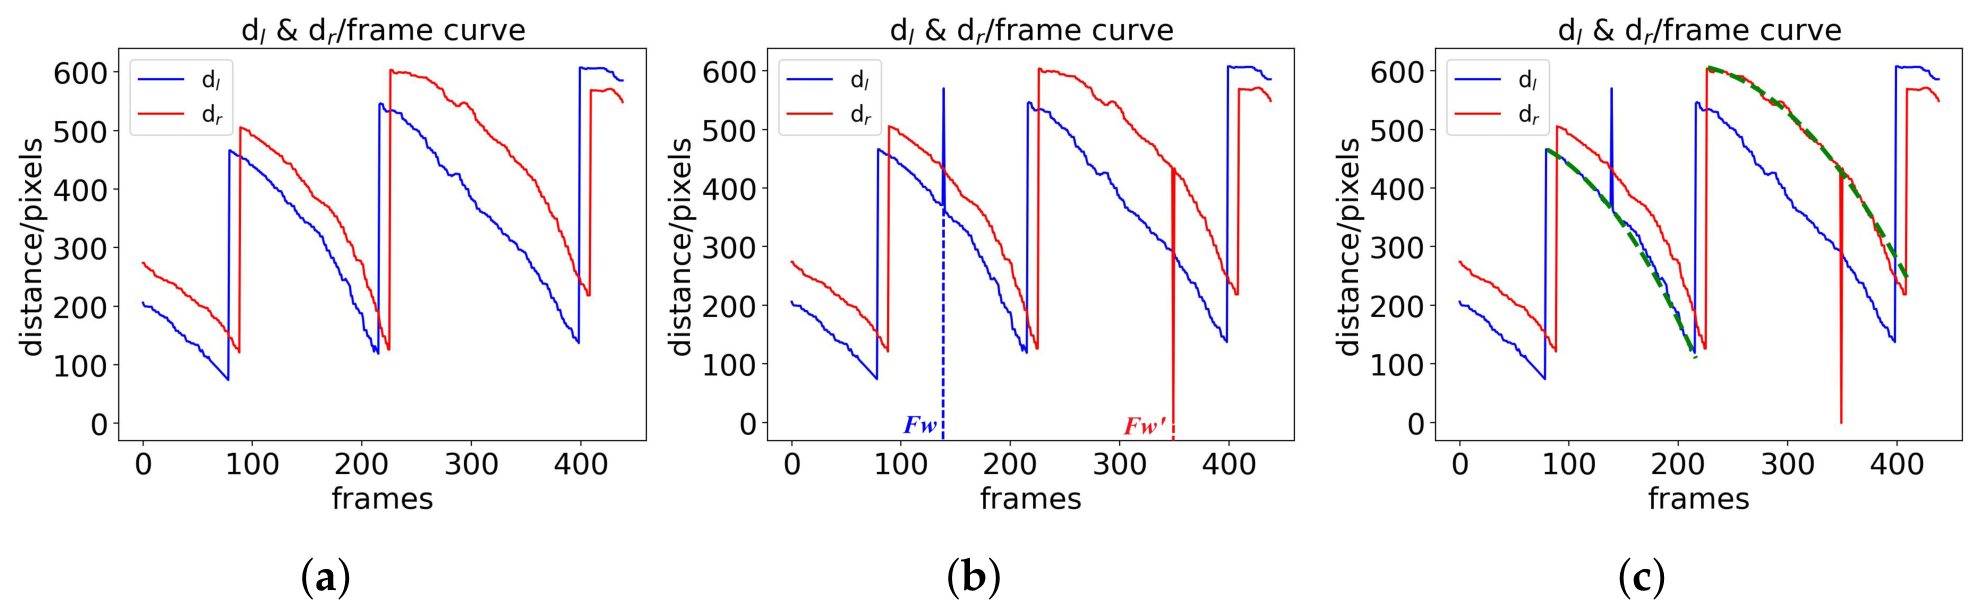
A false frame refers to a frame with an incorrect detection result from the deep learning model. Figure 9a illustrates the correctly estimated navigation path, which provides real-time steering commands for jujube harvester direction adjustment.
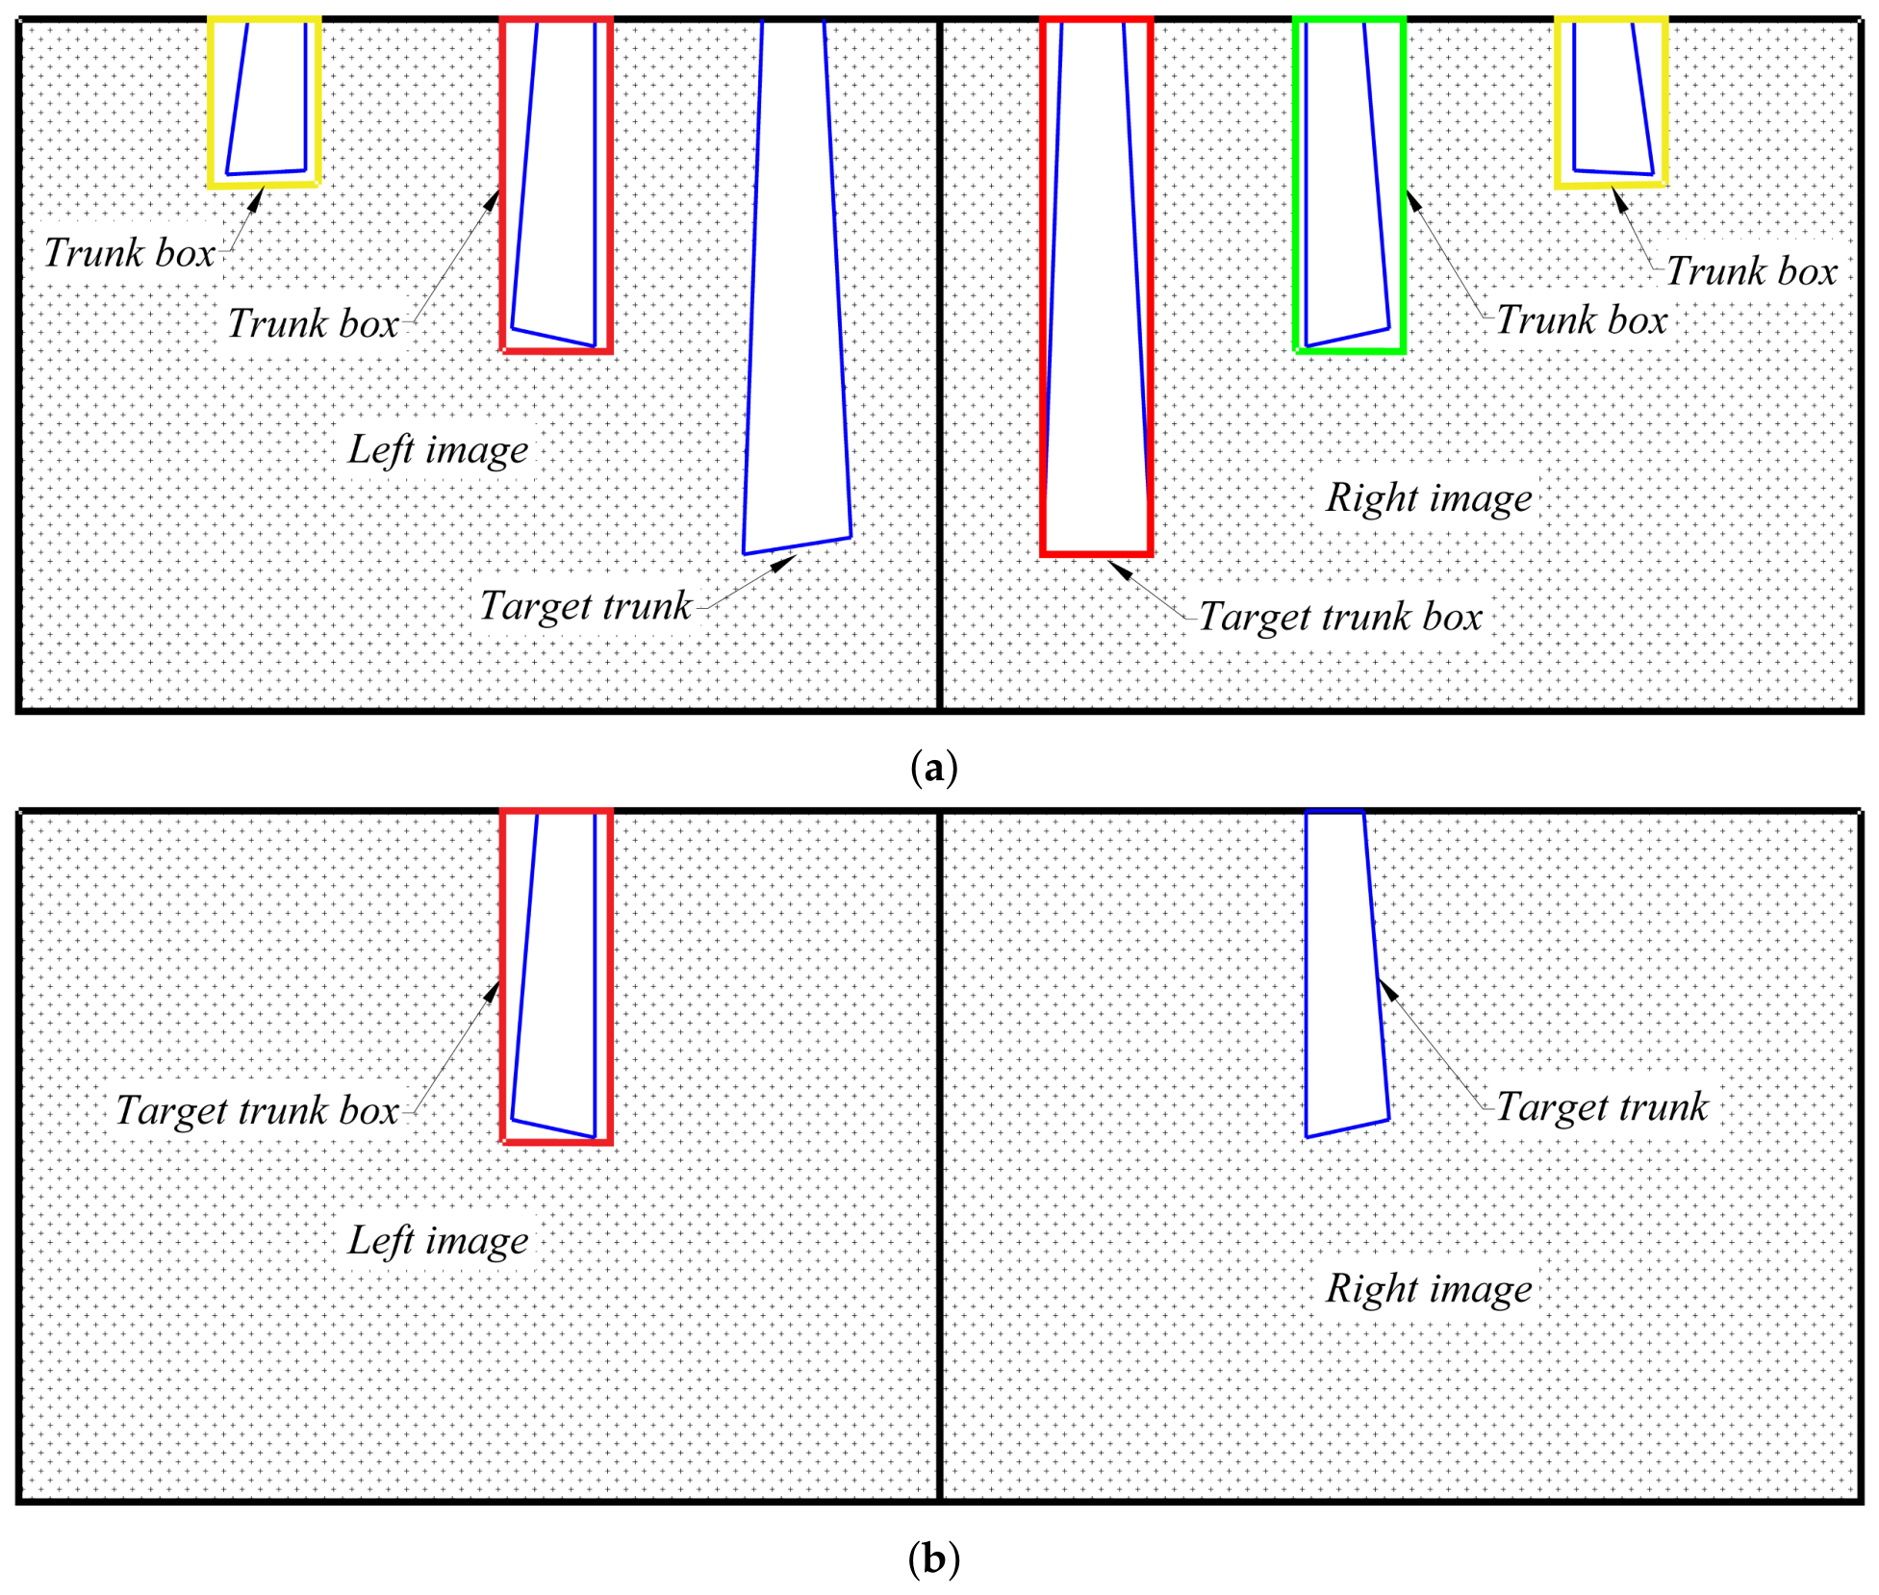
As shown in Figure 9b, false detections occur in the frame of F w , and F w . In frame F w , the target trunk is present but missed by the S S D model in the left image (Figure 10b). In frame F w , the target trunk is missed in the right image, resulting in no detected trunk bounding box (Figure 10a). Equation (4) defines the criterion for false frame identification, where L denotes the label of the current frame.
L = F a l s e d > p a n d d e < k T r u e b e s i d e s
where
d = d l a n d d e = d l _ e i n l e f t i m a g e d = d r a n d d e = d r _ e i n r i g h t i m a g e

2.6.2. Achieve the Estimated Value

After identifying false frames, the missing values are estimated to calculate the navigation path. The curve function of the interval containing F w or F w is defined in Equation (6), where each interval is approximated by a conic section. The coefficients a 0 , a 1 , and a 2 are obtained using the least squares method based on valid points before the false frame. The missing value d is then estimated by substituting F w or F w into Equation (6).
d = a 0 + a 1 · F 1 + a 2 · F 2
The fitted curve is plotted as the green dashed line in Figure 9. As illustrated, d l and d r defined under the F w and F w frames can be adopted to compute the navigation path after path calibration.
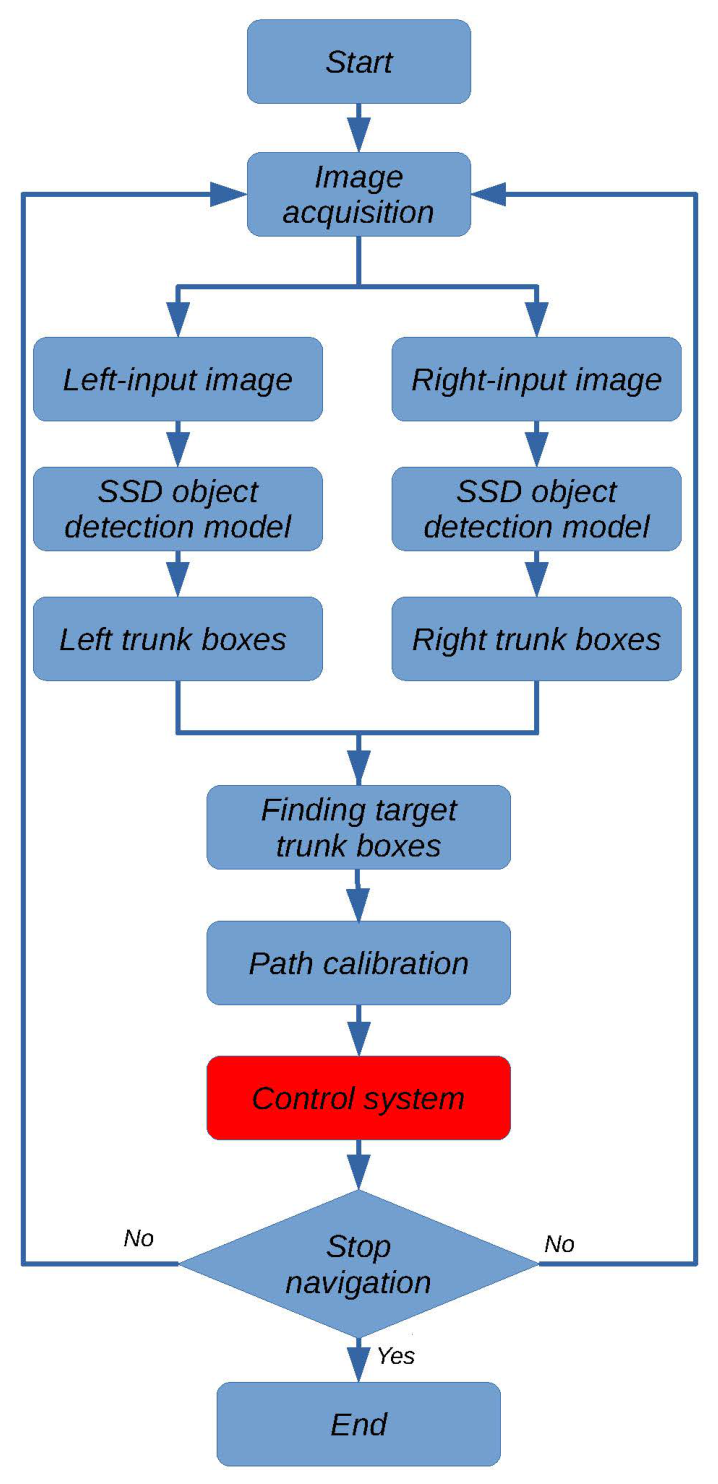
To summarize, the work flow of the navigation system is shown in Figure 11. And the c o n t r o l   s y s t e m part of them is not introduced in this paper.

3. Results

All algorithms and data processing were implemented on the L i n u x x 64 5.4 . 0 131 g e n e r i c system using V i s u a l S t u d i o C o d e ( V 1.72 . 2 ) and A n a c o n d a 3 . The host computer is equipped with an I n t e l ( R ) C o r e ( T M ) i 7 4770 C P U @ 3.40 G H z , 16 G B RAM, and a G e F o r c e R T X 2080 T i graphics card.

3.1. Deep Learning Model Selection

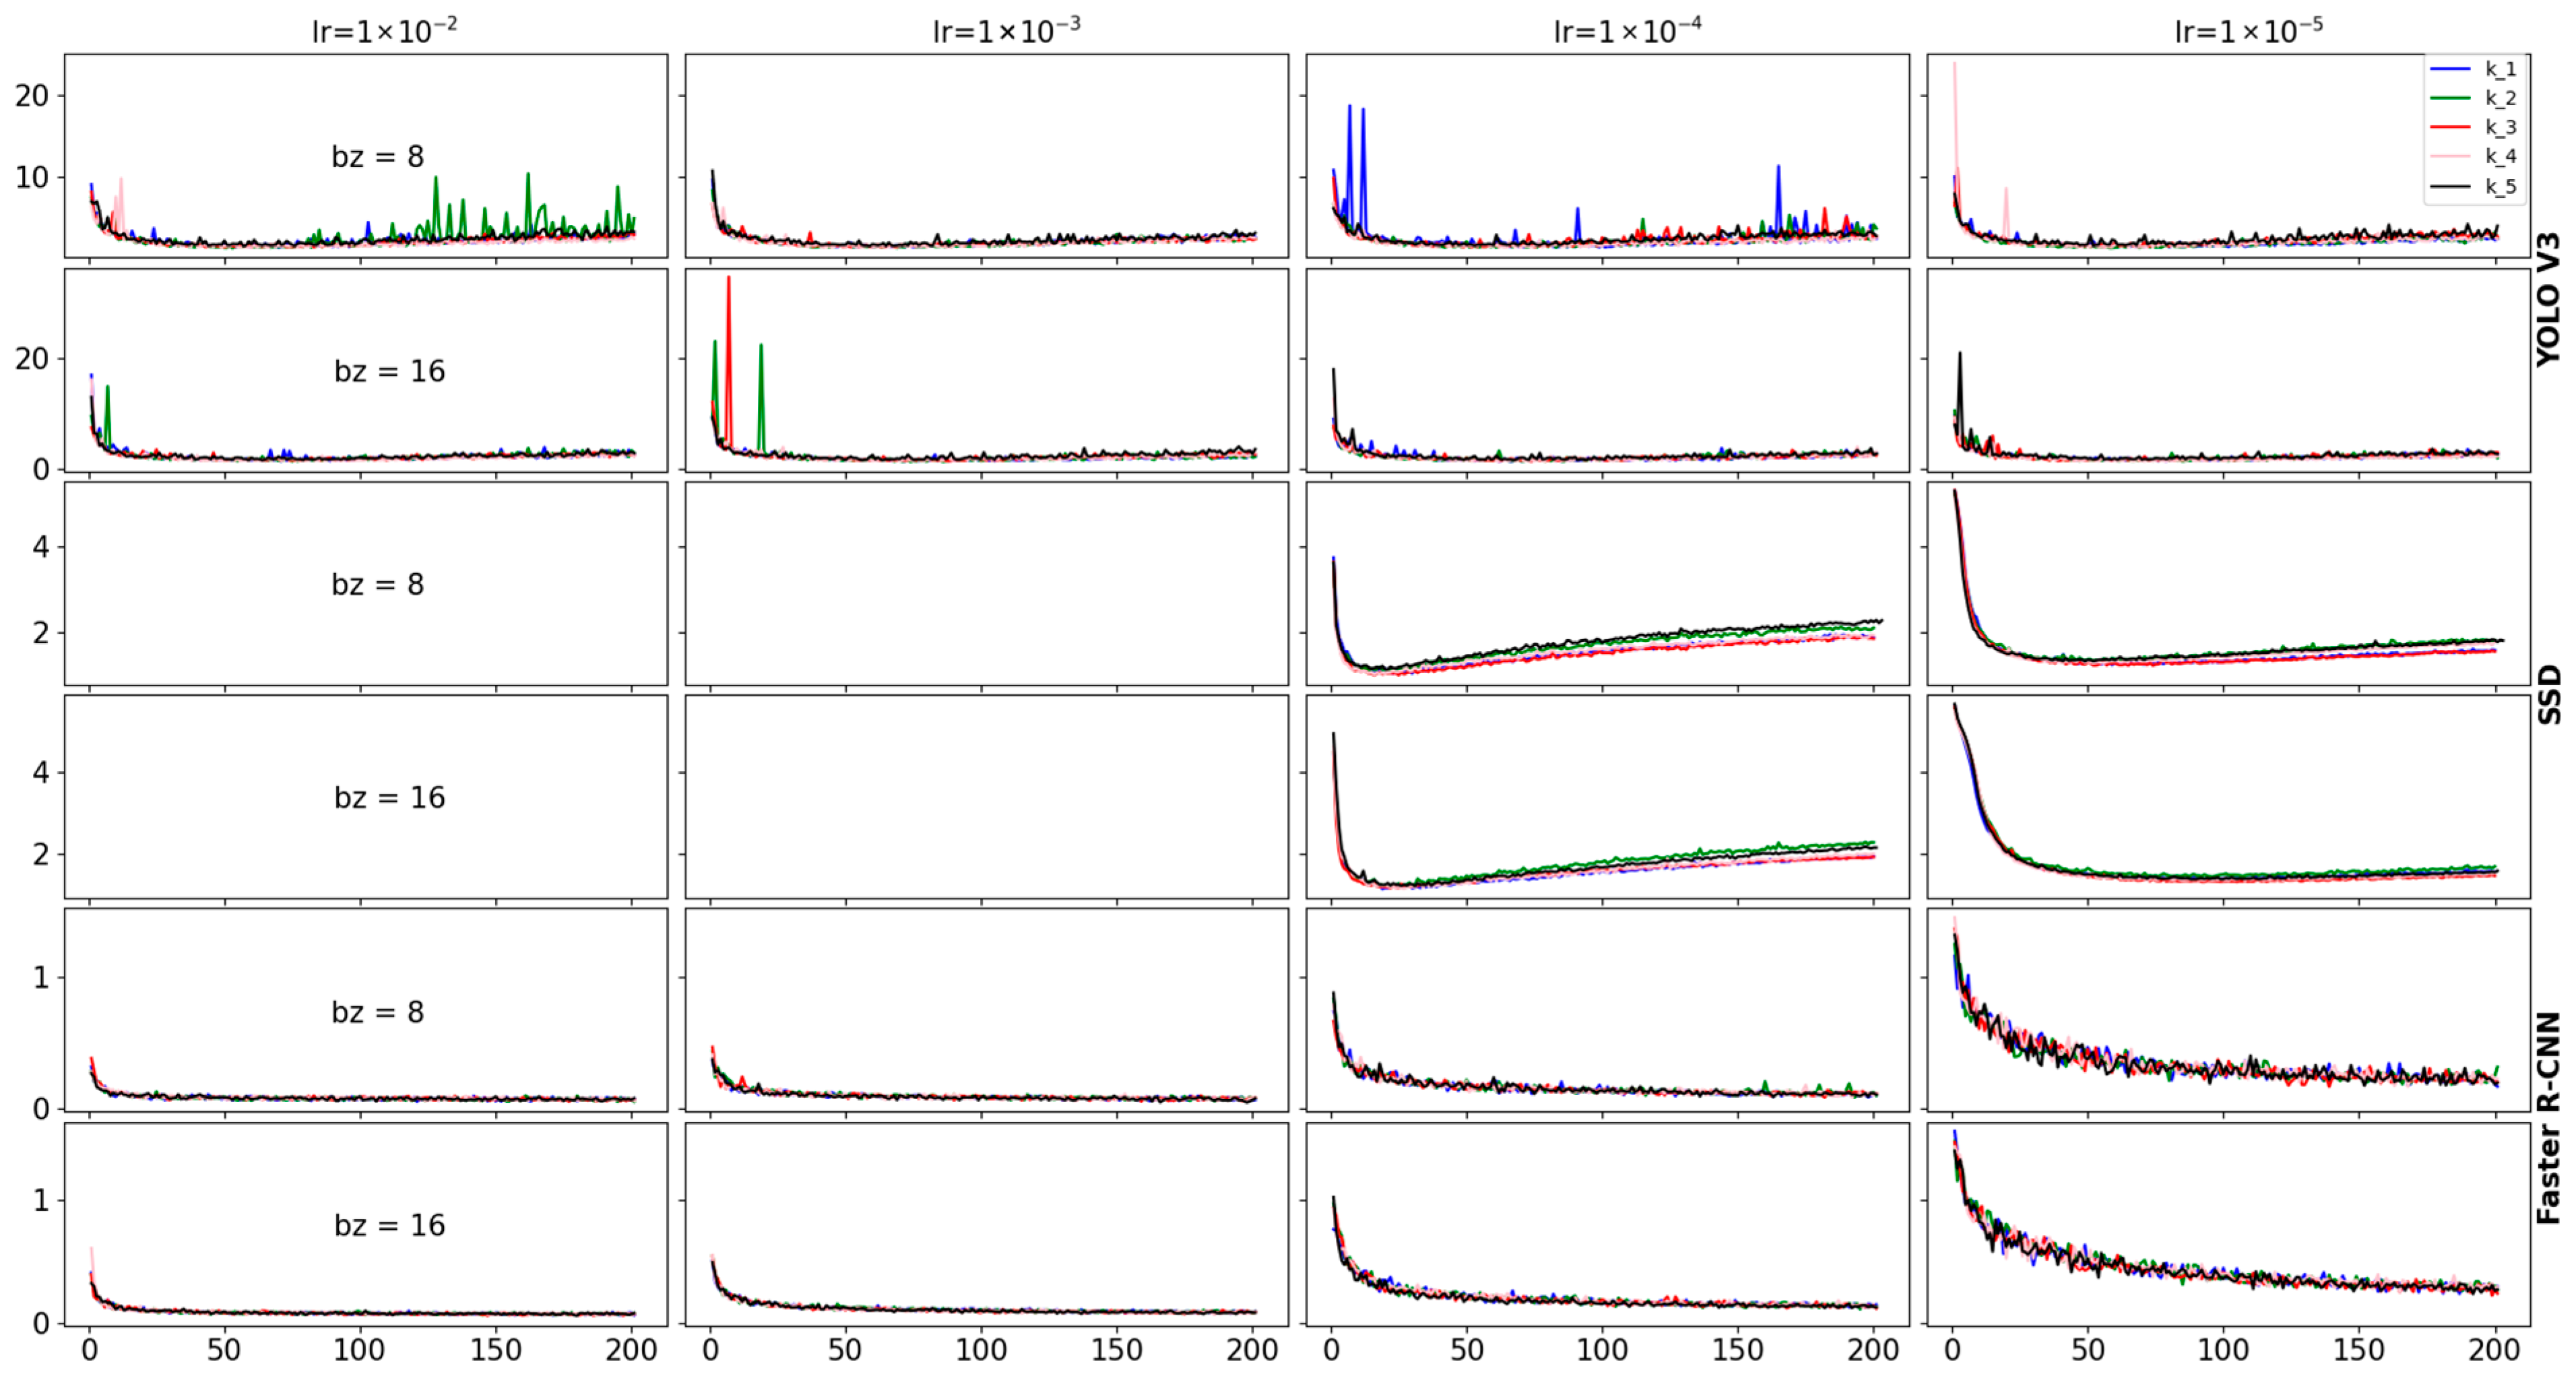
Figure 12 shows validation loss curves for models with varied hyperparameters trained using 5 f o l d c r o s s v a l i d a t i o n , where b z and l r represent batch size and learning rate. The SSD model trained at learning rates of 1 × 10⁻² and 1 × 10⁻³ cannot be applied to this study.
Table 3 summarizes the model evaluation metrics. Faster R-CNN obtains the optimal m A P @ 0.9 ( ( 24.93 ± 6.22 ) % ), yet its detection speed ( ( 10.13 ± 0.03 ) f p s ) fps cannot satisfy the task’s real-time demand. SSD outperforms YOLO V3 slightly in experiments and is therefore adopted as the deep learning backbone.

3.2. Semi-Supervised Learning

Two experiments were carried out to improve model performance using pseudo-labels. As a mature training scheme, Early Stopping frequently surpasses regularization methods and gains extensive application due to easy implementation [53]. The Early Stopping hyperparameters were configured with Patience of 20 and validation loss as the monitoring indicator.
The first experiment investigates the optimal quantity of pseudo-labeled samples for each training iteration. Experimental results are summarized in Table 4. As observed, the optimal pseudo-label count is 100, which yields the highest m A P @ 0.9 of 52.86% on the test set.
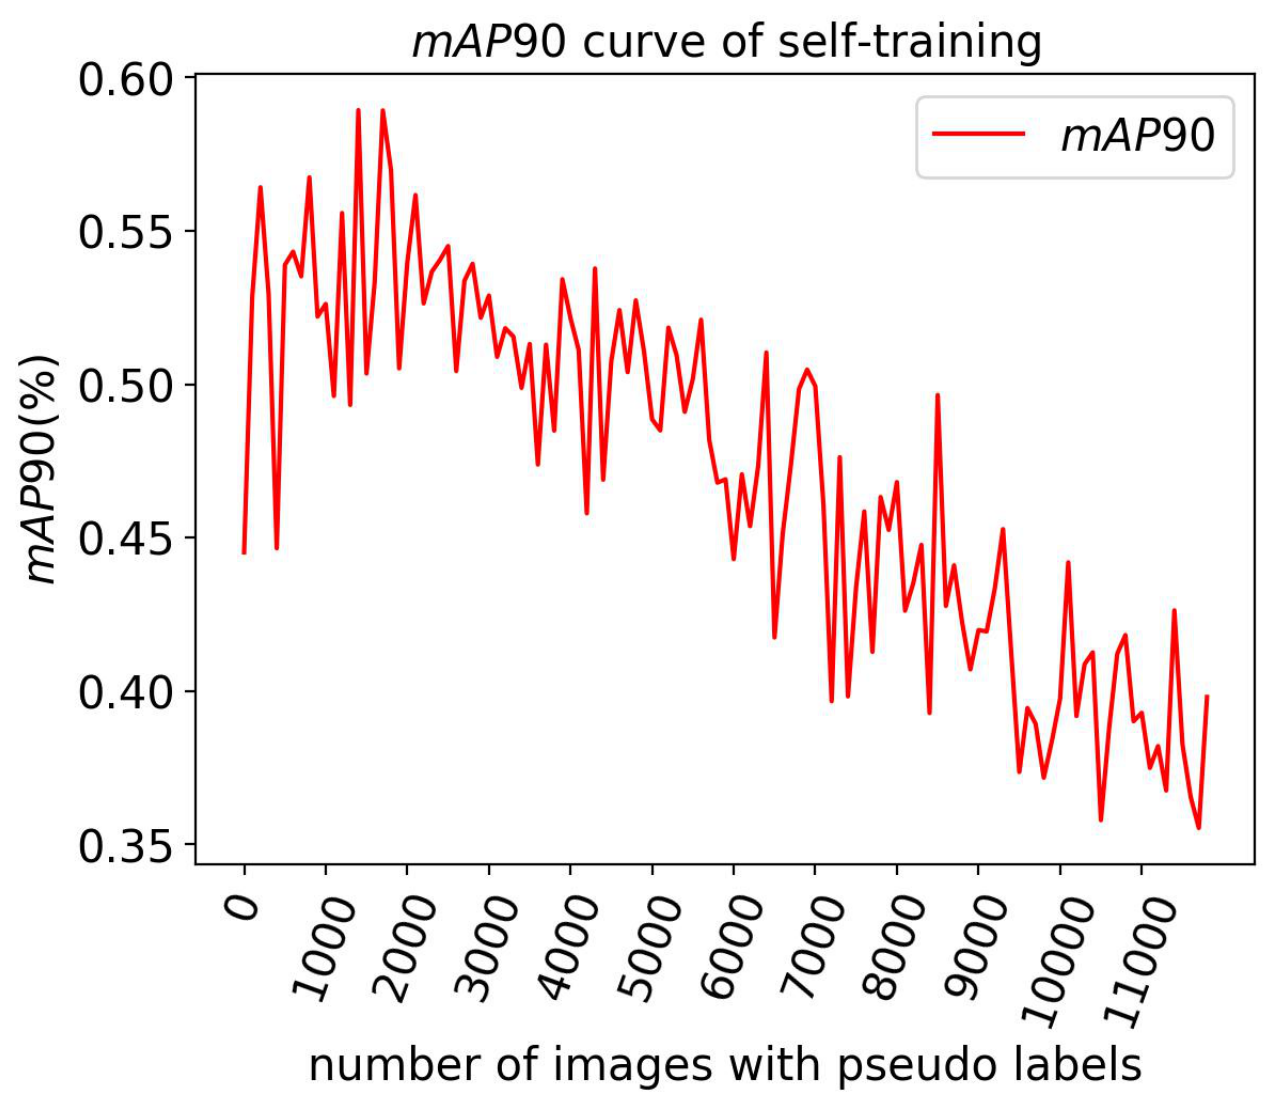
Second, as unlabeled data far outnumber labeled samples, we further explore the optimal quantity of pseudo-labeled images. Figure 13 indicates that the model trained with approximately 1400 pseudo-labeled images achieves the best performance, and this configuration is adopted for our final model.

3.3. Performance Improvement Result

Model performance after image augmentation and self-training is shown in Table 5. The m A P @ 0.9 metric rises by 20% with image augmentation and further improves by 14% via pseudo-label self-training. Accordingly, both image augmentation and pseudo-label self-training boost the S S D model performance in this task.
Although the m A P @ 0.9 of 58.93% is lower than that of dataset-oriented detectors, it meets the requirements of orchard navigation for three reasons:
1.
Under heavy orchard interference, our optimizations raise the SSD baseline from 23.98% by over 34 percentage points.
2.
Embedded path calibration reconstructs navigation paths during temporary detection failures discussed in Section 2.6.
3.
The low traveling speed of the harvester enables the control system to compensate occasional detection deviations.

3.4. False Detection Analysis

Typical detection failure cases are presented below. In all subsequent figures, red boxes denote detected target trunks in binocular image pairs. In Figure 14a, the S S D model fails to output trunk bounding boxes on the left image, producing no valid navigation path for this frame. In Figure 14b, the target trunk near the right edge of the left image is undetected, which yields an erroneous navigation path.
Furthermore, experiments on the navigation path false detection rate r d are carried out using randomly sampled video clips from the collected dataset. The metric r d is computed via Equation (7), where w f and t f denote the number of falsely detected frames and the total number of frames, respectively. Experimental results are summarized in Table 6.
r d = w f t f × 100 %
The false detection rate reaches 3.64% and the inference speed is 14.38 f p s , satisfying the autonomous navigation requirements of the jujube harvester.
Two frame-rate metrics must be differentiated in this work. High frame rates in the model comparison table denote pure single-image backbone inference, excluding preprocessing and post-processing. By contrast, the integrated system speed of 14.38 f p s covers the full binocular pipeline: dual-camera synchronous S S D inference, valid trunk target filtering, path calibration interpolation for detection missing, and navigation path command generation for the harvester control unit. This full-stack frame rate characterizes the practical real-time performance on the physical harvester.

3.5. Path Calibration

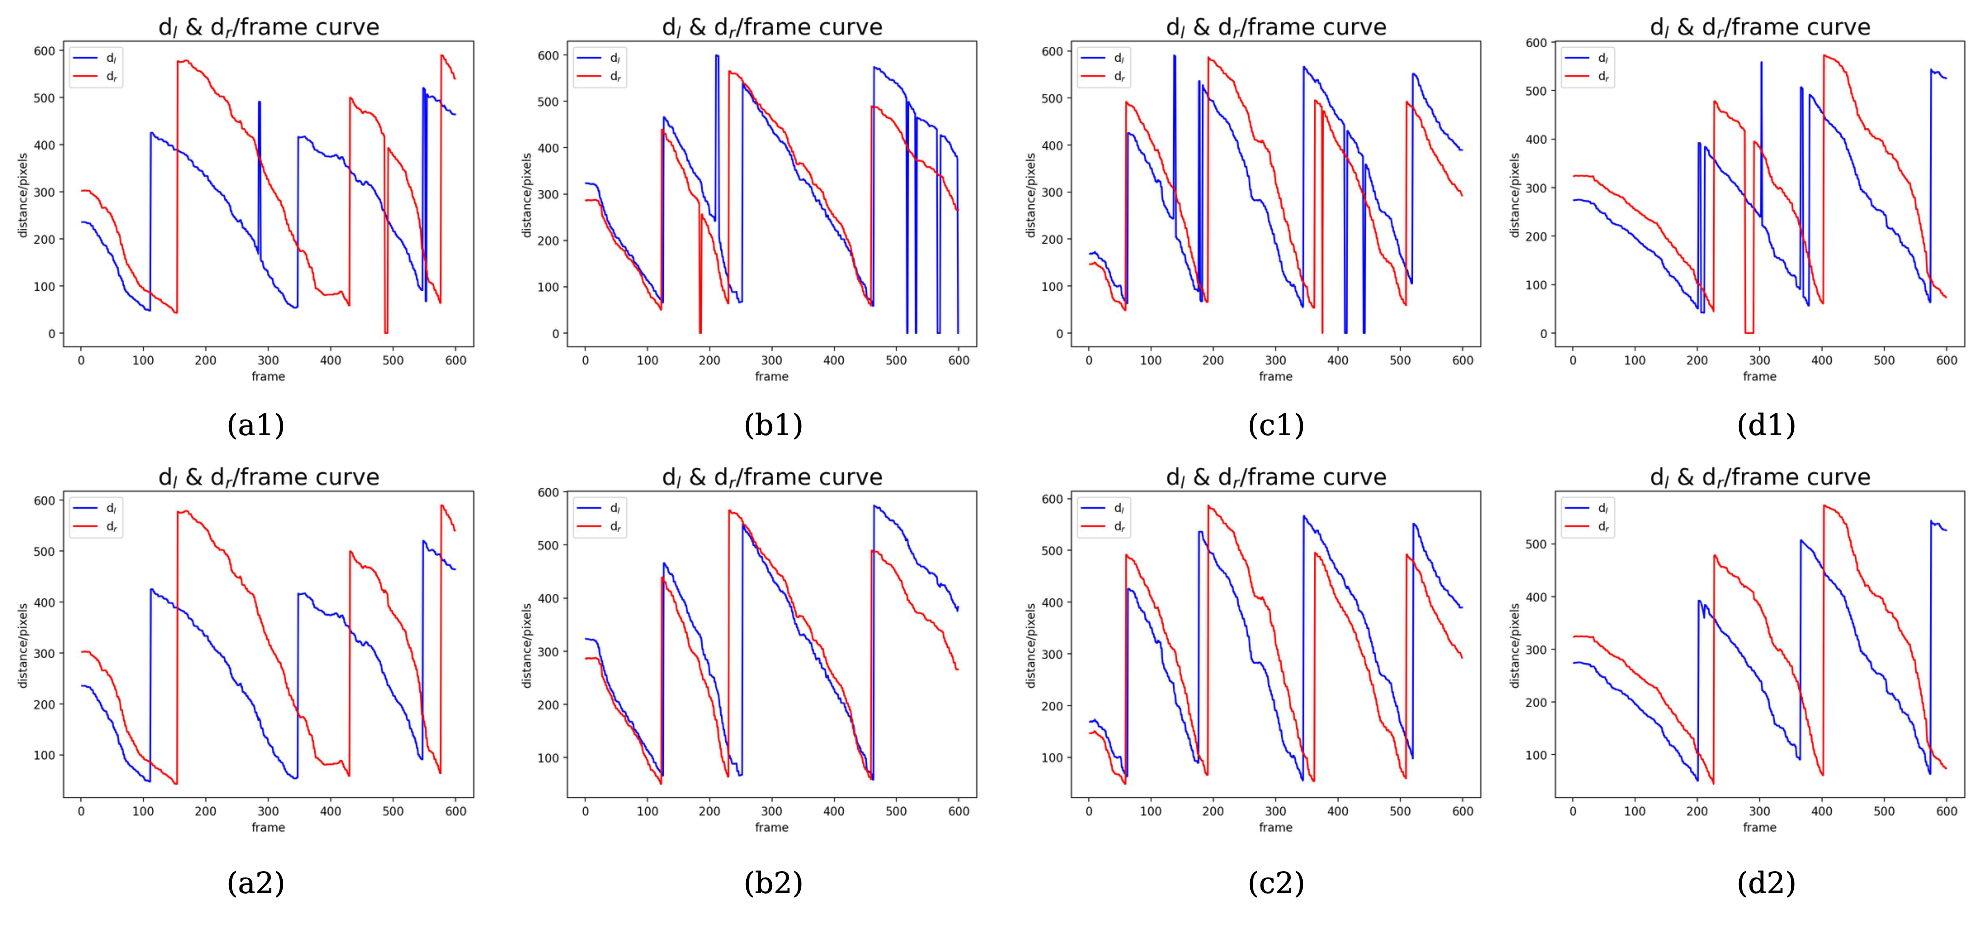
In Figure 15, the first row Figure 15(a1–d1) plots raw d l and d r curves without path calibration from test videos. The second row Figure 15(a2–d2) presents the corresponding curves with outliers corrected via path calibration.
As observed, calibrated d l and d r can serve as navigation paths for autonomous jujube harvester navigation amid false detections.
The proposed conic interpolation for missing detection compensation has inherent limitations. The lightweight single conic fitting suits jujube harvesters navigating slowly along straight or gently curved rows over mildly undulating terrain, where smooth trajectory assumptions are valid. Under extreme conditions including sharp steering and rough terrain, abrupt trajectory variations cannot be precisely represented by one quadratic curve and produce large path deviations. Future work will employ segmented piecewise curve fitting to adapt to varying trajectory curvatures.

3.6. Ablation Study

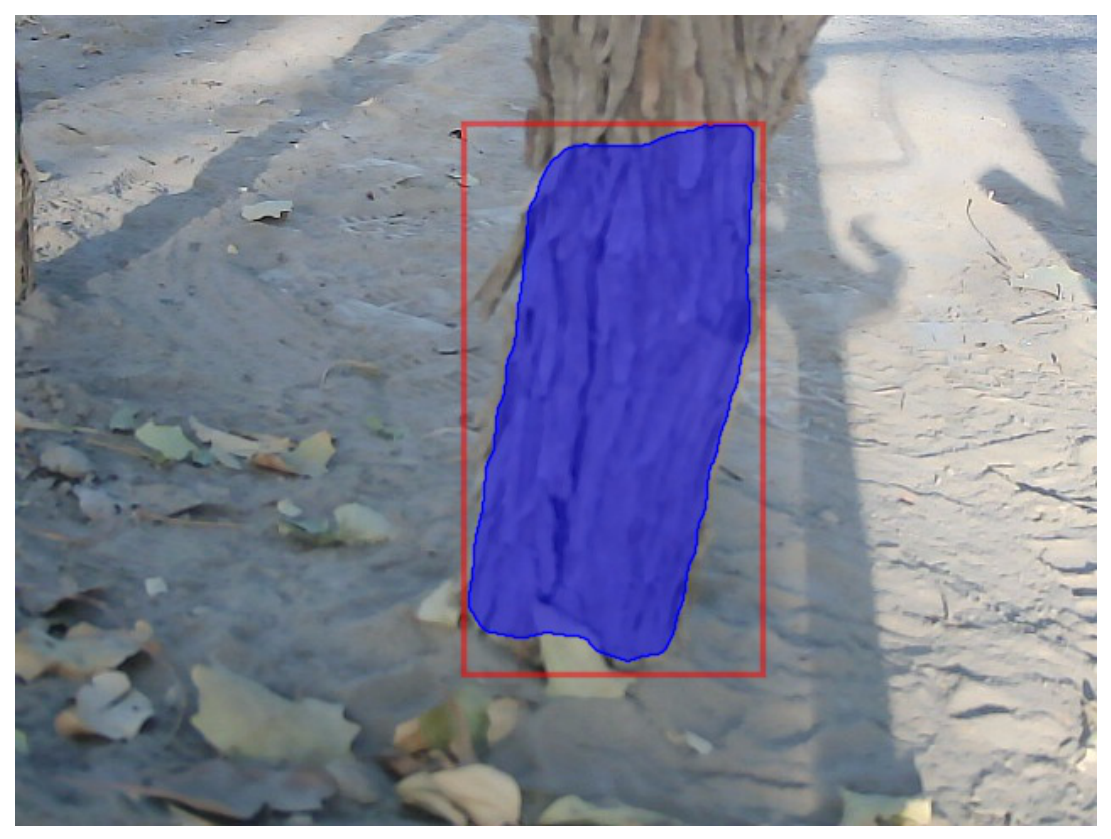
It should be emphasized that the following comparison between SSD and Detectron2 only conducts a relative consistency test of trunk mass center outputs, rather than an absolute positioning accuracy assessment against manually annotated ground truth. This group of experiments aims to verify whether lightweight SSD can generate trunk center coordinates consistent with the high-precision segmentation model Detectron2 [54], rather than quantifying the real geometric error of either model against actual trunk positions. Figure 16 displays the detection result leaned on the Detectron 2 deep learning model designed, which is one of the state-of-the-art instance segmentation models. In this picture, for the same trunk, the blue-connected area and the red rectangle box is generated from the Detectron 2 model.
Although instance segmentation delivers higher detection accuracy, its low inference speed limits deployment on the jujube harvester. To verify whether general object detection suits this scenario, we calculate the distance between the two mass centers.
Equation (8) computes the mass center ( c i _ x , c i _ y ) of the blue connected area; ( x k , y k ) is the coordinate of the k t h pixel and n is the total pixel count inside the region. Equation (9) yields the mass center ( c o _ x , c o _ y ) of the red bounding box, defined by its top-left ( x 1 , y 1 ) and bottom-right ( x 2 , y 2 ) corners. Errors are calculated via Equation (10), and results are listed in Table 7.
c i _ x = k = 1 n x k n c i _ y = k = 1 n y k n
c o _ x = x 1 + x 2 2 c o _ y = y 1 + y 2 2
d = | c i _ x c o _ x |
As listed in the table, the average error ranges from 2.5 to 2.7 pixels and stays within acceptable bounds. Thus, the object detection accuracy meets the autonomous navigation requirements of jujube harvester. Nevertheless, this comparative evaluation carries inherent limitations. The slight coordinate offset between SSD and Detectron2 merely proves prediction consistency between the two models, rather than the absolute deviation from the real trunk ground truth. Future work will adopt the manually annotated ground truth to measure absolute positioning error and further quantify the geometric precision of the lightweight SSD.

4. Limitations

The limitations of this work are illustrated via the d l and d r curves in Figure 15. Obvious discrepancies arise on the curves when detection switches from one target trunk to the next, accompanied by substantial divergence between d l and d r . This phenomenon mainly stems from inconsistent mounting heights and installation angles of the two cameras. In addition, the algorithm is validated only on collected datasets; further field experiments in jujube orchards will be conducted in future work.

5. Conclusions

This work develops a deep learning binocular vision navigation algorithm for autonomous jujube harvesters. Comparative and ablation experiments validate three key contributions: S S D surpasses Y O L O V 3 and F a s t e r R C N N for trunk detection under complex orchard conditions; pseudo-label self-training improves baseline S S D accuracy; and conic-section path calibration boosts system robustness against detection loss and false positives. The binocular vision system steadily outputs real-time navigation paths in natural orchards. This lightweight anti-interference framework supports orchard autonomous navigation and offers an algorithmic basis for unmanned jujube harvesters.
Future work covers two aspects. Algorithmically, we improve trunk detection accuracy and long-sequence stability for extreme orchard environments. For system integration, the vision module will connect to the vehicle controller for closed-loop field tests, with continuous in-row trials verifying real-time performance and practical reliability.
In conclusion, this paper constructs a full binocular vision pipeline adapted to vibration-disturbed jujube orchards. Comparative tests, pseudo-label self-training ablation studies and missing-path calibration confirm that the integrated algorithm reliably generates navigation trajectories for autonomous harvesters, delivering a viable visual perception scheme for unmanned orchard harvesting equipment.

Author Contributions

Conceptualization, X.Z.; methodology, X.Z.; software, X.Z.; validation, Z.Z.; formal analysis, X.Z. and Z.L.; investigation, X.Z.; data curation, Z.L. and Z.Z.; writing—original draft preparation, X.Z.; writing—review and editing, X.Z.; visualization, X.Z.; supervision, X.Z. All authors have read and agreed to the published version of the manuscript.

Funding

This work was supported by the National Key R & D Program of China (No. 2020YFB1711703 and No. 2020YFB2007700), the Key Projects of National Natural Science Foundation of China (No. 52035002), the National Natural Science Foundation of China (No. 62173356), and the Science and Technology Development Fund (FDCT) of Macau, China (No. 0019/2021/A).

Institutional Review Board Statement

Not applicable.

Informed Consent Statement

Not applicable.

Data Availability Statement

Data are not available for sensibility reasons.

Acknowledgments

The authors would like to thank the editor, associate editor and anonymous reviewers for their constructive comments and suggestions that significantly improve this paper.

Conflicts of Interest

The authors declare no conflicts of interest.

References

  1. Bayar, G.; Bergerman, M.; Koku, A.B.; ilhan Konukseven, E. Localization and control of an autonomous orchard vehicle. Comput. Electron. Agric. 2015, 115, 118–128. [Google Scholar] [CrossRef] [Scilit]
  2. Chen, J.; Wang, Z.; Long, T.; Wu, J.; Cai, G.; Zhang, H. Research on Navigation Line Extraction of Garden Mobile Robot Based on Edge Detection. J. Intell. Robot. Syst. 2022, 105, 27. [Google Scholar] [CrossRef] [Scilit]
  3. Li, X.; Qiu, Q. Autonomous Navigation for Orchard Mobile Robots: A Rough Review. In Proceedings of the 2021 36th Youth Academic Annual Conference of Chinese Association of Automation (YAC), Nanchang, China, 28–30 May 2021; pp. 552–557. [Google Scholar] [CrossRef] [Scilit]
  4. Rovira-Más, F.; Chatterjee, I.; Sáiz-Rubio, V. The role of GNSS in the navigation strategies of cost-effective agricultural robots. Comput. Electron. Agric. 2015, 112, 172–183. [Google Scholar] [CrossRef] [Scilit]
  5. Bakker, T.; van Asselt, K.; Bontsema, J.; Müller, J.; van Straten, G. Autonomous navigation using a robot platform in a sugar beet field. Biosyst. Eng. 2011, 109, 357–368. [Google Scholar] [CrossRef] [Scilit]
  6. Jones, M.H.; Bell, J.; Dredge, D.; Seabright, M.; Scarfe, A.; Duke, M.; MacDonald, B. Design and testing of a heavy-duty platform for autonomous navigation in kiwifruit orchards. Biosyst. Eng. 2019, 187, 129–146. [Google Scholar] [CrossRef] [Scilit]
  7. Gan, H.; Lee, W. Development of a Navigation System for a Smart Farm. IFAC-PapersOnLine 2018, 51, 1–4. [Google Scholar] [CrossRef] [Scilit]
  8. Aguiar, A.S.; dos Santos, F.N.; Cunha, J.B.; Sobreira, H.; Sousa, A.J. Localization and Mapping for Robots in Agriculture and Forestry: A Survey. Robotics 2020, 9, 97. [Google Scholar] [CrossRef] [Scilit]
  9. Nehme, H.; Aubry, C.; Solatges, T.; Savatier, X.; Rossi, R.; Boutteau, R. LiDAR-based Structure Tracking for Agricultural Robots: Application to Autonomous Navigation in Vineyards. J. Intell. Robot. Syst. 2021, 103, 61. [Google Scholar] [CrossRef] [Scilit]
  10. Blok, P.M.; van Boheemen, K.; van Evert, F.K.; IJsselmuiden, J.; Kim, G.H. Robot navigation in orchards with localization based on Particle filter and Kalman filter. Comput. Electron. Agric. 2019, 157, 261–269. [Google Scholar] [CrossRef] [Scilit]
  11. Malavazi, F.B.; Guyonneau, R.; Fasquel, J.B.; Lagrange, S.; Mercier, F. LiDAR-only based navigation algorithm for an autonomous agricultural robot. Comput. Electron. Agric. 2018, 154, 71–79. [Google Scholar] [CrossRef] [Scilit]
  12. Li, Y.; Wang, X.; Liu, D. 3D autonomous navigation line extraction for field roads based on binocular vision. J. Sens. 2019, 2019, 6832109. [Google Scholar] [CrossRef] [Scilit]
  13. Liu, S.; Wang, X.; Li, S.; Chen, X.; Zhang, X. Obstacle avoidance for orchard vehicle trinocular vision system based on coupling of geometric constraint and virtual force field method. Expert Syst. Appl. 2022, 190, 116216. [Google Scholar] [CrossRef] [Scilit]
  14. Zhou, J.; Geng, S.; Qiu, Q.; Shao, Y.; Zhang, M. A Deep-Learning Extraction Method for Orchard Visual Navigation Lines. Agriculture 2022, 12, 1650. [Google Scholar] [CrossRef] [Scilit]
  15. Opiyo, S.; Okinda, C.; Zhou, J.; Mwangi, E.; Makange, N. Medial axis-based machine-vision system for orchard robot navigation. Comput. Electron. Agric. 2021, 185, 106153. [Google Scholar] [CrossRef] [Scilit]
  16. Yang, Z.; Ouyang, L.; Zhang, Z.; Duan, J.; Yu, J.; Wang, H. Visual navigation path extraction of orchard hard pavement based on scanning method and neural network. Comput. Electron. Agric. 2022, 197, 106964. [Google Scholar] [CrossRef] [Scilit]
  17. Sharifi, M.; Chen, X. A novel vision based row guidance approach for navigation of agricultural mobile robots in orchards. In Proceedings of the 2015 6th International Conference on Automation, Robotics and Applications (ICARA); IEEE: New York, NY, USA, 2015; pp. 251–255. [Google Scholar] [CrossRef] [Scilit]
  18. Lyu, H.K.; Park, C.H.; Han, D.H.; Kwak, S.W.; Choi, B. Orchard Free Space and Center Line Estimation Using Naive Bayesian Classifier for Unmanned Ground Self-Driving Vehicle. Symmetry 2018, 10, 355. [Google Scholar] [CrossRef] [Scilit]
  19. Radcliffe, J.; Cox, J.; Bulanon, D.M. Machine vision for orchard navigation. Comput. Ind. 2018, 98, 165–171. [Google Scholar] [CrossRef] [Scilit]
  20. Du, Y.; Fan, B.; Han, J.; Tang, Y. Binocular Based Moving Target Tracking for Mobile Robot. In Proceedings of the Intelligent Robotics and Applications; Xie, M., Xiong, Y., Xiong, C., Liu, H., Hu, Z., Eds.; Springer: Berlin/Heidelberg, Germany, 2009; pp. 929–935. [Google Scholar] [CrossRef] [Scilit]
  21. Tang, Y.; Chen, M.; Wang, C.; Luo, L.; Li, J.; Lian, G.; Zou, X. Recognition and Localization Methods for Vision-Based Fruit Picking Robots: A Review. Front. Plant Sci. 2020, 11, 510. [Google Scholar] [CrossRef] [Scilit]
  22. Rovira-Más, F.; Zhang, Q.; Reid, J.F. Stereo vision three-dimensional terrain maps for precision agriculture. Comput. Electron. Agric. 2008, 60, 133–143. [Google Scholar] [CrossRef] [Scilit]
  23. Zhang, S.; Wang, Y.; Zhu, Z.; Li, Z.; Du, Y.; Mao, E. Tractor path tracking control based on binocular vision. Inf. Process. Agric. 2018, 5, 422–432. [Google Scholar] [CrossRef] [Scilit]
  24. Takahashi, T.; Zhang, S.; Fukuchi, H. Acquisition of 3-D information by binocular stereo vision for vehicle navigation through an orchard. In Automation Technology for Off-Road Equipment; American Society of Agricultural and Biological Engineers: St. Joseph, MI, USA, 2002; p. 337. [Google Scholar]
  25. Zhai, Z.; Zhu, Z.; Du, Y.; Song, Z.; Mao, E. Multi-crop-row detection algorithm based on binocular vision. Biosyst. Eng. 2016, 150, 89–103. [Google Scholar] [CrossRef] [Scilit]
  26. Hu, P.; Hao, X.; Li, J.; Cheng, C.; Wang, A. Design and implementation of binocular vision system with an adjustable baseline and high synchronization. In Proceedings of the 2018 IEEE 3rd International Conference on Image, Vision and Computing (ICIVC); IEEE: New York, NY, USA, 2018; pp. 566–570. [Google Scholar] [CrossRef] [Scilit]
  27. Geiger, A.; Roser, M.; Urtasun, R. Efficient Large-Scale Stereo Matching. In Proceedings of the Computer Vision—ACCV 2010; Kimmel, R., Klette, R., Sugimoto, A., Eds.; Springer: Berlin/Heidelberg, Germany, 2011; pp. 25–38. [Google Scholar] [CrossRef] [Scilit]
  28. Kim, W.S.; Lee, D.H.; Kim, Y.J.; Kim, T.; Lee, H.J. Path detection for autonomous traveling in orchards using patch-based CNN. Comput. Electron. Agric. 2020, 175, 105620. [Google Scholar] [CrossRef] [Scilit]
  29. Han, S.H.; Kang, K.M.; Choi, C.H.; Lee, D.H. Deep learning-based path detection in citrus orchard. In Proceedings of the 2020 ASABE Annual International Virtual Meeting; American Society of Agricultural and Biological Engineers: St. Joseph, MI, USA, 2020; p. 1. [Google Scholar] [CrossRef] [Scilit]
  30. Shang, G.; Liu, G.; Zhu, P.; Han, J.; Xia, C.; Jiang, K. A Deep Residual U-Type Network for Semantic Segmentation of Orchard Environments. Appl. Sci. 2021, 11, 322. [Google Scholar] [CrossRef] [Scilit]
  31. Pouyanfar, S.; Sadiq, S.; Yan, Y.; Tian, H.; Tao, Y.; Reyes, M.P.; Shyu, M.L.; Chen, S.C.; Iyengar, S.S. A survey on deep learning: Algorithms, techniques, and applications. ACM Comput. Surv. (CSUR) 2018, 51, 1–36. [Google Scholar] [CrossRef] [Scilit]
  32. Jiang, A.; Noguchi, R.; Ahamed, T. Tree Trunk Recognition in Orchard Autonomous Operations under Different Light Conditions Using a Thermal Camera and Faster R-CNN. Sensors 2022, 22, 2065. [Google Scholar] [CrossRef] [Scilit]
  33. Ren, S.; He, K.; Girshick, R.B.; Sun, J. Faster R-CNN: Towards Real-Time Object Detection with Region Proposal Networks. Adv. Neural Inf. Process. Syst. 2015, 28, 91–99. [Google Scholar]
  34. Redmon, J.; Farhadi, A. YOLOv3: An Incremental Improvement. arXiv 2018, arXiv:1804.02767. [Google Scholar] [CrossRef] [Scilit]
  35. Liu, W.; Anguelov, D.; Erhan, D.; Szegedy, C.; Reed, S.; Fu, C.Y.; Berg, A.C. SSD: Single Shot MultiBox Detector. In Proceedings of the Computer Vision—ECCV 2016; Leibe, B., Matas, J., Sebe, N., Welling, M., Eds.; Springer: Cham, Switzerland, 2016; pp. 21–37. [Google Scholar] [CrossRef] [Scilit]
  36. Xu, Y.; Goodacre, R. On splitting training and validation set: A comparative study of cross-validation, bootstrap and systematic sampling for estimating the generalization performance of supervised learning. J. Anal. Test. 2018, 2, 249–262. [Google Scholar] [CrossRef] [Scilit]
  37. Saud, S.; Jamil, B.; Upadhyay, Y.; Irshad, K. Performance improvement of empirical models for estimation of global solar radiation in India: A k-fold cross-validation approach. Sustain. Energy Technol. Assess. 2020, 40, 100768. [Google Scholar] [CrossRef] [Scilit]
  38. Wong, T.T.; Yeh, P.Y. Reliable accuracy estimates from k-fold cross validation. IEEE Trans. Knowl. Data Eng. 2019, 32, 1586–1594. [Google Scholar] [CrossRef] [Scilit]
  39. Everingham, M.; Van Gool, L.; Williams, C.K.; Winn, J.; Zisserman, A. The pascal visual object classes (voc) challenge. Int. J. Comput. Vis. 2010, 88, 303–338. [Google Scholar] [CrossRef] [Scilit]
  40. Everingham, M.; Eslami, S.; Van Gool, L.; Williams, C.K.; Winn, J.; Zisserman, A. The pascal visual object classes challenge: A retrospective. Int. J. Comput. Vis. 2015, 111, 98–136. [Google Scholar] [CrossRef] [Scilit]
  41. Russakovsky, O.; Deng, J.; Su, H.; Krause, J.; Satheesh, S.; Ma, S.; Fei-Fei, L. ImageNet large scale visual recognition. arXiv 2014, arXiv:1409.0575. [Google Scholar]
  42. Henderson, P.; Ferrari, V. End-to-End Training of Object Class Detectors for Mean Average Precision. In Proceedings of the Computer Vision—ACCV 2016; Lai, S.H., Lepetit, V., Nishino, K., Sato, Y., Eds.; Springer: Cham, Switzerland, 2017; pp. 198–213. [Google Scholar] [CrossRef] [Scilit]
  43. Kandel, I.; Castelli, M. The effect of batch size on the generalizability of the convolutional neural networks on a histopathology dataset. ICT Express 2020, 6, 312–315. [Google Scholar] [CrossRef] [Scilit]
  44. Shorten, C.; Khoshgoftaar, T.M. A survey on image data augmentation for deep learning. J. Big Data 2019, 6, 60. [Google Scholar] [CrossRef] [Scilit]
  45. Bloice, M.D.; Stocker, C.; Holzinger, A. Augmentor: An image augmentation library for machine learning. arXiv 2017, arXiv:1708.04680. [Google Scholar] [CrossRef] [Scilit]
  46. Mikołajczyk, A.; Grochowski, M. Data augmentation for improving deep learning in image classification problem. In Proceedings of the 2018 International Interdisciplinary PhD Workshop (IIPhDW), Świnoujście, Poland, 9–12 May 2018; pp. 117–122. [Google Scholar] [CrossRef] [Scilit]
  47. Khalifa, N.E.; Loey, M.; Mirjalili, S. A comprehensive survey of recent trends in deep learning for digital images augmentation. Artif. Intell. Rev. 2021, 55, 2351–2377. [Google Scholar] [CrossRef] [Scilit]
  48. Hu, N.; Dannenberg, R.B. A Bootstrap Method for Training an Accurate Audio Segmenter. In Proceedings of the ISMIR, London, UK, 11–15 September 2005; pp. 223–229. [Google Scholar]
  49. Rosenberg, C.; Hebert, M.; Schneiderman, H. Semi-supervised self-training of object detection models. In Proceedings of the 2005 Seventh IEEE Workshops on Applications of Computer Vision (WACV/MOTION’05), Breckenridge, CO, USA, 5–7 January 2005. [Google Scholar] [CrossRef] [Scilit]
  50. Albert, P.; Ortego, D.; Arazo, E.; O’Connor, N.; McGuinness, K. ReLaB: Reliable Label Bootstrapping for Semi-Supervised Learning. In Proceedings of the 2021 International Joint Conference on Neural Networks (IJCNN), Shenzhen, China, 18–22 July 2021; pp. 1–8. [Google Scholar] [CrossRef] [Scilit]
  51. Tanha, J.; Van Someren, M.; Afsarmanesh, H. Semi-supervised self-training for decision tree classifiers. Int. J. Mach. Learn. Cybern. 2017, 8, 355–370. [Google Scholar] [CrossRef] [Scilit]
  52. Lee, D.H. Pseudo-label: The simple and efficient semi-supervised learning method for deep neural networks. In Proceedings of the Workshop on Challenges in Representation Learning, ICML, Atlanta, GA, USA, 16–21 June 2013; Volume 3, p. 896. [Google Scholar]
  53. Prechelt, L. Automatic early stopping using cross validation: Quantifying the criteria. Neural Netw. 1998, 11, 761–767. [Google Scholar] [CrossRef] [Scilit]
  54. Wu, Y.; Kirillov, A.; Massa, F.; Lo, W.Y.; Girshick, R. Detectron2. 2019. Available online: https://github.com/facebookresearch/detectron2 (accessed on 23 April 2022).
Figure 1. The jujube harvester designed by Shihezi University.
Agriengineering 08 00369 g001
Figure 2. The top view diagram of the straddle-type jujube harvester operation.
Agriengineering 08 00369 g002
Figure 3. Binocular cameras installation in this paper.
Agriengineering 08 00369 g003
Figure 4. Conventional binocular cameras.
Agriengineering 08 00369 g004
Figure 5. The actual image from binocular cameras in this paper.
Agriengineering 08 00369 g005
Figure 6. The overlap of camera view from binocular cameras in this paper: (a) overlap of camera view from conventional binocular cameras; (b) overlap of camera view from binocular cameras in this paper.
Agriengineering 08 00369 g006
Figure 7. The scene of the jujube harvester collecting images in jujube orchards.
Agriengineering 08 00369 g007
Figure 8. The diagram of the navigation path.
Agriengineering 08 00369 g008
Figure 9. The diagram of path calibration: (a) The correct navigation path. (b) The false navigation path. (c) The navigation path after calibration.
Agriengineering 08 00369 g009
Figure 10. Diagrams of false frames: (a) F w frame. (b) F w frame.
Agriengineering 08 00369 g010
Figure 11. The work flow of the navigation system.
Agriengineering 08 00369 g011
Figure 12. The training and validation loss curve of different models with different parameters.
Agriengineering 08 00369 g012
Figure 13. The m A P @ 0.9 curve of self-training under different numbers of unlabeled images.
Agriengineering 08 00369 g013
Figure 14. The false detection caused by the SSD model.
Agriengineering 08 00369 g014
Figure 15. The curve before and after path calibration.
Agriengineering 08 00369 g015
Figure 16. Results of the instance segmentation and the object detection based on the Detectron 2 model.
Agriengineering 08 00369 g016
Table 1. Main parameters of the camera used for image acquisition.
ResolutionInterface TypeProduct ModelTemperature
640 × 480 VGA MJPEGUSB2.0 High SpeedRER-USBFHD01M-LS36 20 70 °C
Table 2. The information of videos collected in jujube orchards.
CameraVideo NumberFrame NumberFrame Rate
left24759415
right24759415
Table 3. The performance of different models trained by different hyperparameters.
ModelLearning RateBatch SizemAP90 (%)Speed (fps)Recall (%)Precision (%)F1-Score (%)
Yolo V31 × 10−2821.18 ± 5.0748.96 ± 2.1542.08 ± 5.4839.82 ± 5.4140.91 ± 5.44
1619.76 ± 6.1349.83 ± 0.4540.08 ± 5.7538.00 ± 5.8539.01 ± 5.80
1 × 10−3822.98 ± 3.8249.50 ± 0.6543.89 ± 3.8940.30 ± 4.5742.01 ± 4.26
1619.71 ± 5.1949.89 ± 0.5639.66 ± 5.1737.52 ± 5.3838.56 ± 5.29
1 × 10−4823.10 ± 7.0043.58 ± 0.3942.70 ± 7.3940.53 ± 7.1441.59 ± 7.26
1621.22 ± 9.0844.06 ± 1.0642.42 ± 9.7140.27 ± 9.3341.32 ± 9.51
1 × 10−5821.89 ± 4.178.73 ± 1.0942.38 ± 4.4939.61 ± 4.9640.94 ± 4.74
1620.00 ± 5.1542.70 ± 1.1840.50 ± 5.9638.12 ± 5.8839.28 ± 5.91
SSD1 × 10−28nannannannannan
16nannannannannan
1 × 10−38nannannannannan
16nannannannannan
1 × 10−4823.98 ± 2.7487.04 ± 4.7844.27 ± 2.1243.92 ± 1.9544.10 ± 2.03
1621.52 ± 3.2885.08 ± 1.1942.14 ± 3.1741.86 ± 2.9742.00 ± 3.07
1 × 10−5815.53 ± 1.5576.8 ± 4.8734.90 ± 1.9134.84 ± 1.8734.87 ± 1.88
1614.66 ± 1.4166.80 ± 5.6933.10 ± 1.8733.28 ± 1.6533.19 ± 1.76
Faster R-CNN1 × 10−2823.99 ± 7.3410.22 ± 0.1248.41 ± 7.4541.67 ± 6.4244.78 ± 6.90
1624.93 ± 6.2210.13 ± 0.0349.64 ± 6.7341.48 ± 5.3345.19 ± 5.94
1 × 10−3823.48 ± 2.7110.25 ± 0.0548.67 ± 3.2241.70 ± 2.9144.92 ± 3.06
16 19.89 ± 2.81 10.25 ± 0.09 43.89 ± 3.55 37.99 ± 3.16 40.72 ± 3.31
1 × 10−4819.03 ± 1.0010.21 ± 0.1142.52 ± 1.2836.74 ± 0.9639.42 ± 1.10
1616.67 ± 2.879.64 ± 1.1638.75 ± 3.2933.11 ± 2.7635.71 ± 3.00
1 × 10−5810.84 ±  1.0010.11 ± 0.0728.65 ± 1.5524.33 ± 1.6726.31 ± 1.63
167.36 ± 0.8810.13 ± 6.8622.94 ± 1.0119.14 ± 1.1220.87 ± 1.08
Table 4. The best number of pseudo-labels for every training set.
NumbermAP90 (%)
10052.86
20048.46
30047.76
40049.63
50047.03
60050.17
70051.72
80043.64
90044.68
100046.09
Table 5. The performance of models under different conditions.
ProcessingmAP90 (%)
without image augmentation23.98
with image augmentation44.52
self-training58.93
The 23.98% m A P @ 0.9 is the hyperparameter-optimized SSD from Table 3, serving as the unified baseline for all ablation tests in Table 5.
Table 6. Experimental results of the false detection rate.
Speed (fps)tf (Frames)wf (Frames)rd (%)
14.3811,5754223.64
Table 7. Distance between object detection and instance segmentation.
NumFrameInstances NumberTotal ErrorAverage Error (Pixels)
1100016704601.8662.755
2100016994511.2122.655
3100017474562.4632.611
4100016854337.0542.576
5100017134590.4702.679
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.