IRC-Bench: Recognizing Entities from Contextual Cues in First-Person Reminiscences
Abstract
1. Introduction
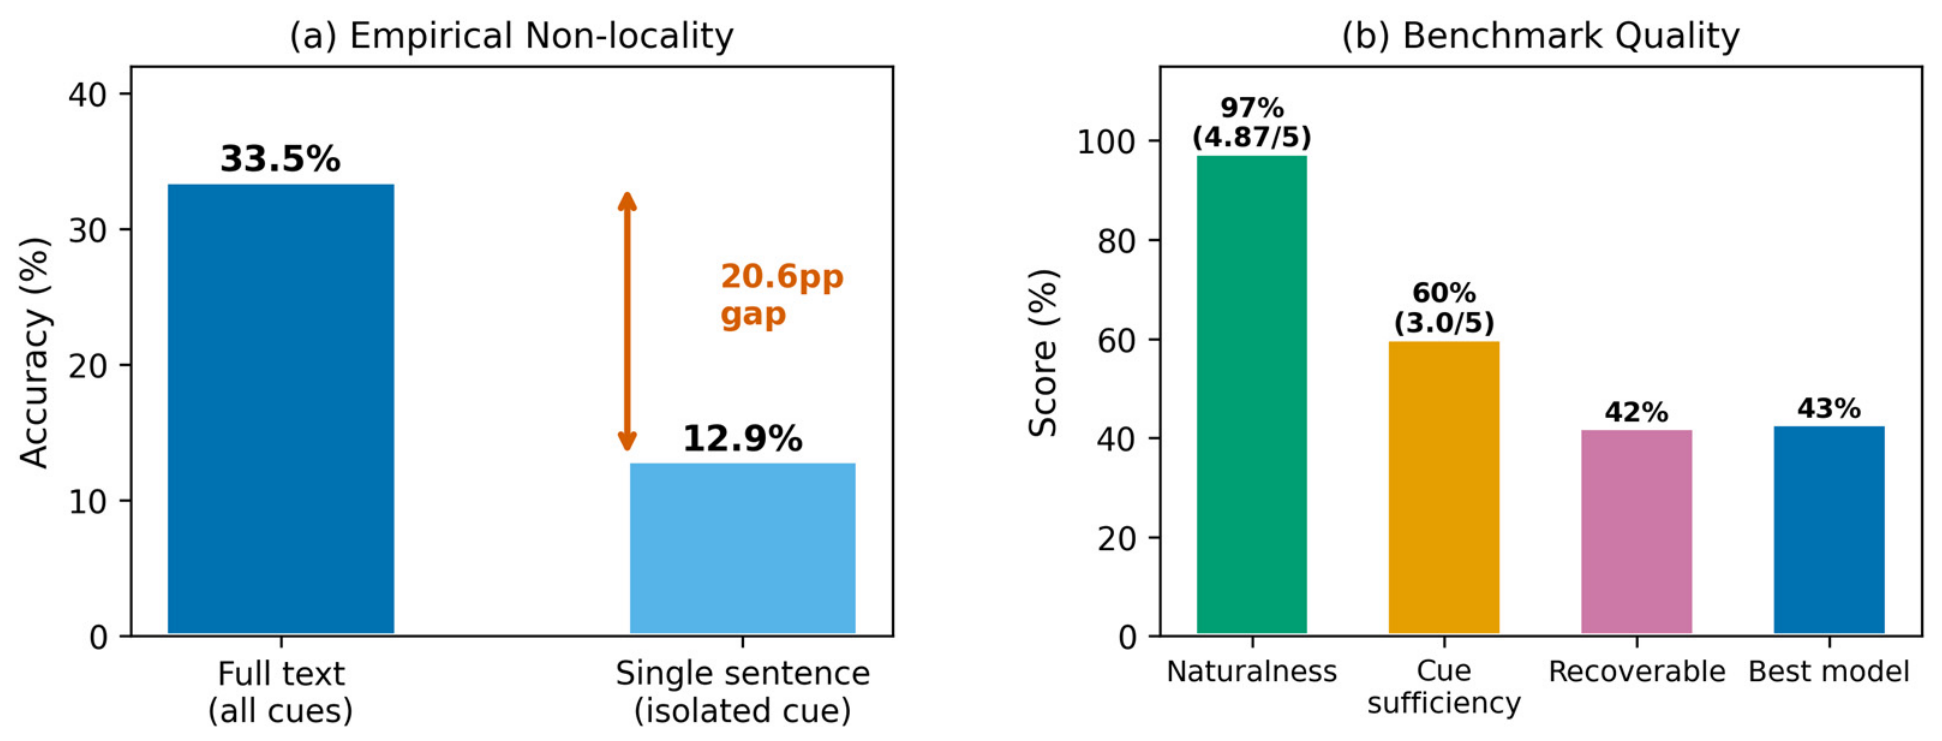
- Operationalizing non-locality at scale. IRC-Bench contributes a concrete operational formulation of non-locality for implicit entity recognition in reminiscence narratives. We define non-locality as a task setting in which the target entity is difficult to infer from any single contiguous passage span but becomes identifiable through the combination of multiple distributed contextual cues. We operationalize this property through a formal task definition, a sentence-ablation diagnostic, and benchmark-scale evaluation. In the diagnostic experiment, GPT-4o zero-shot accuracy drops from 33.5% with the full text to 12.9% with single-sentence context (n = 200), showing that entity recognition depends on integrating cues distributed across the narrative.
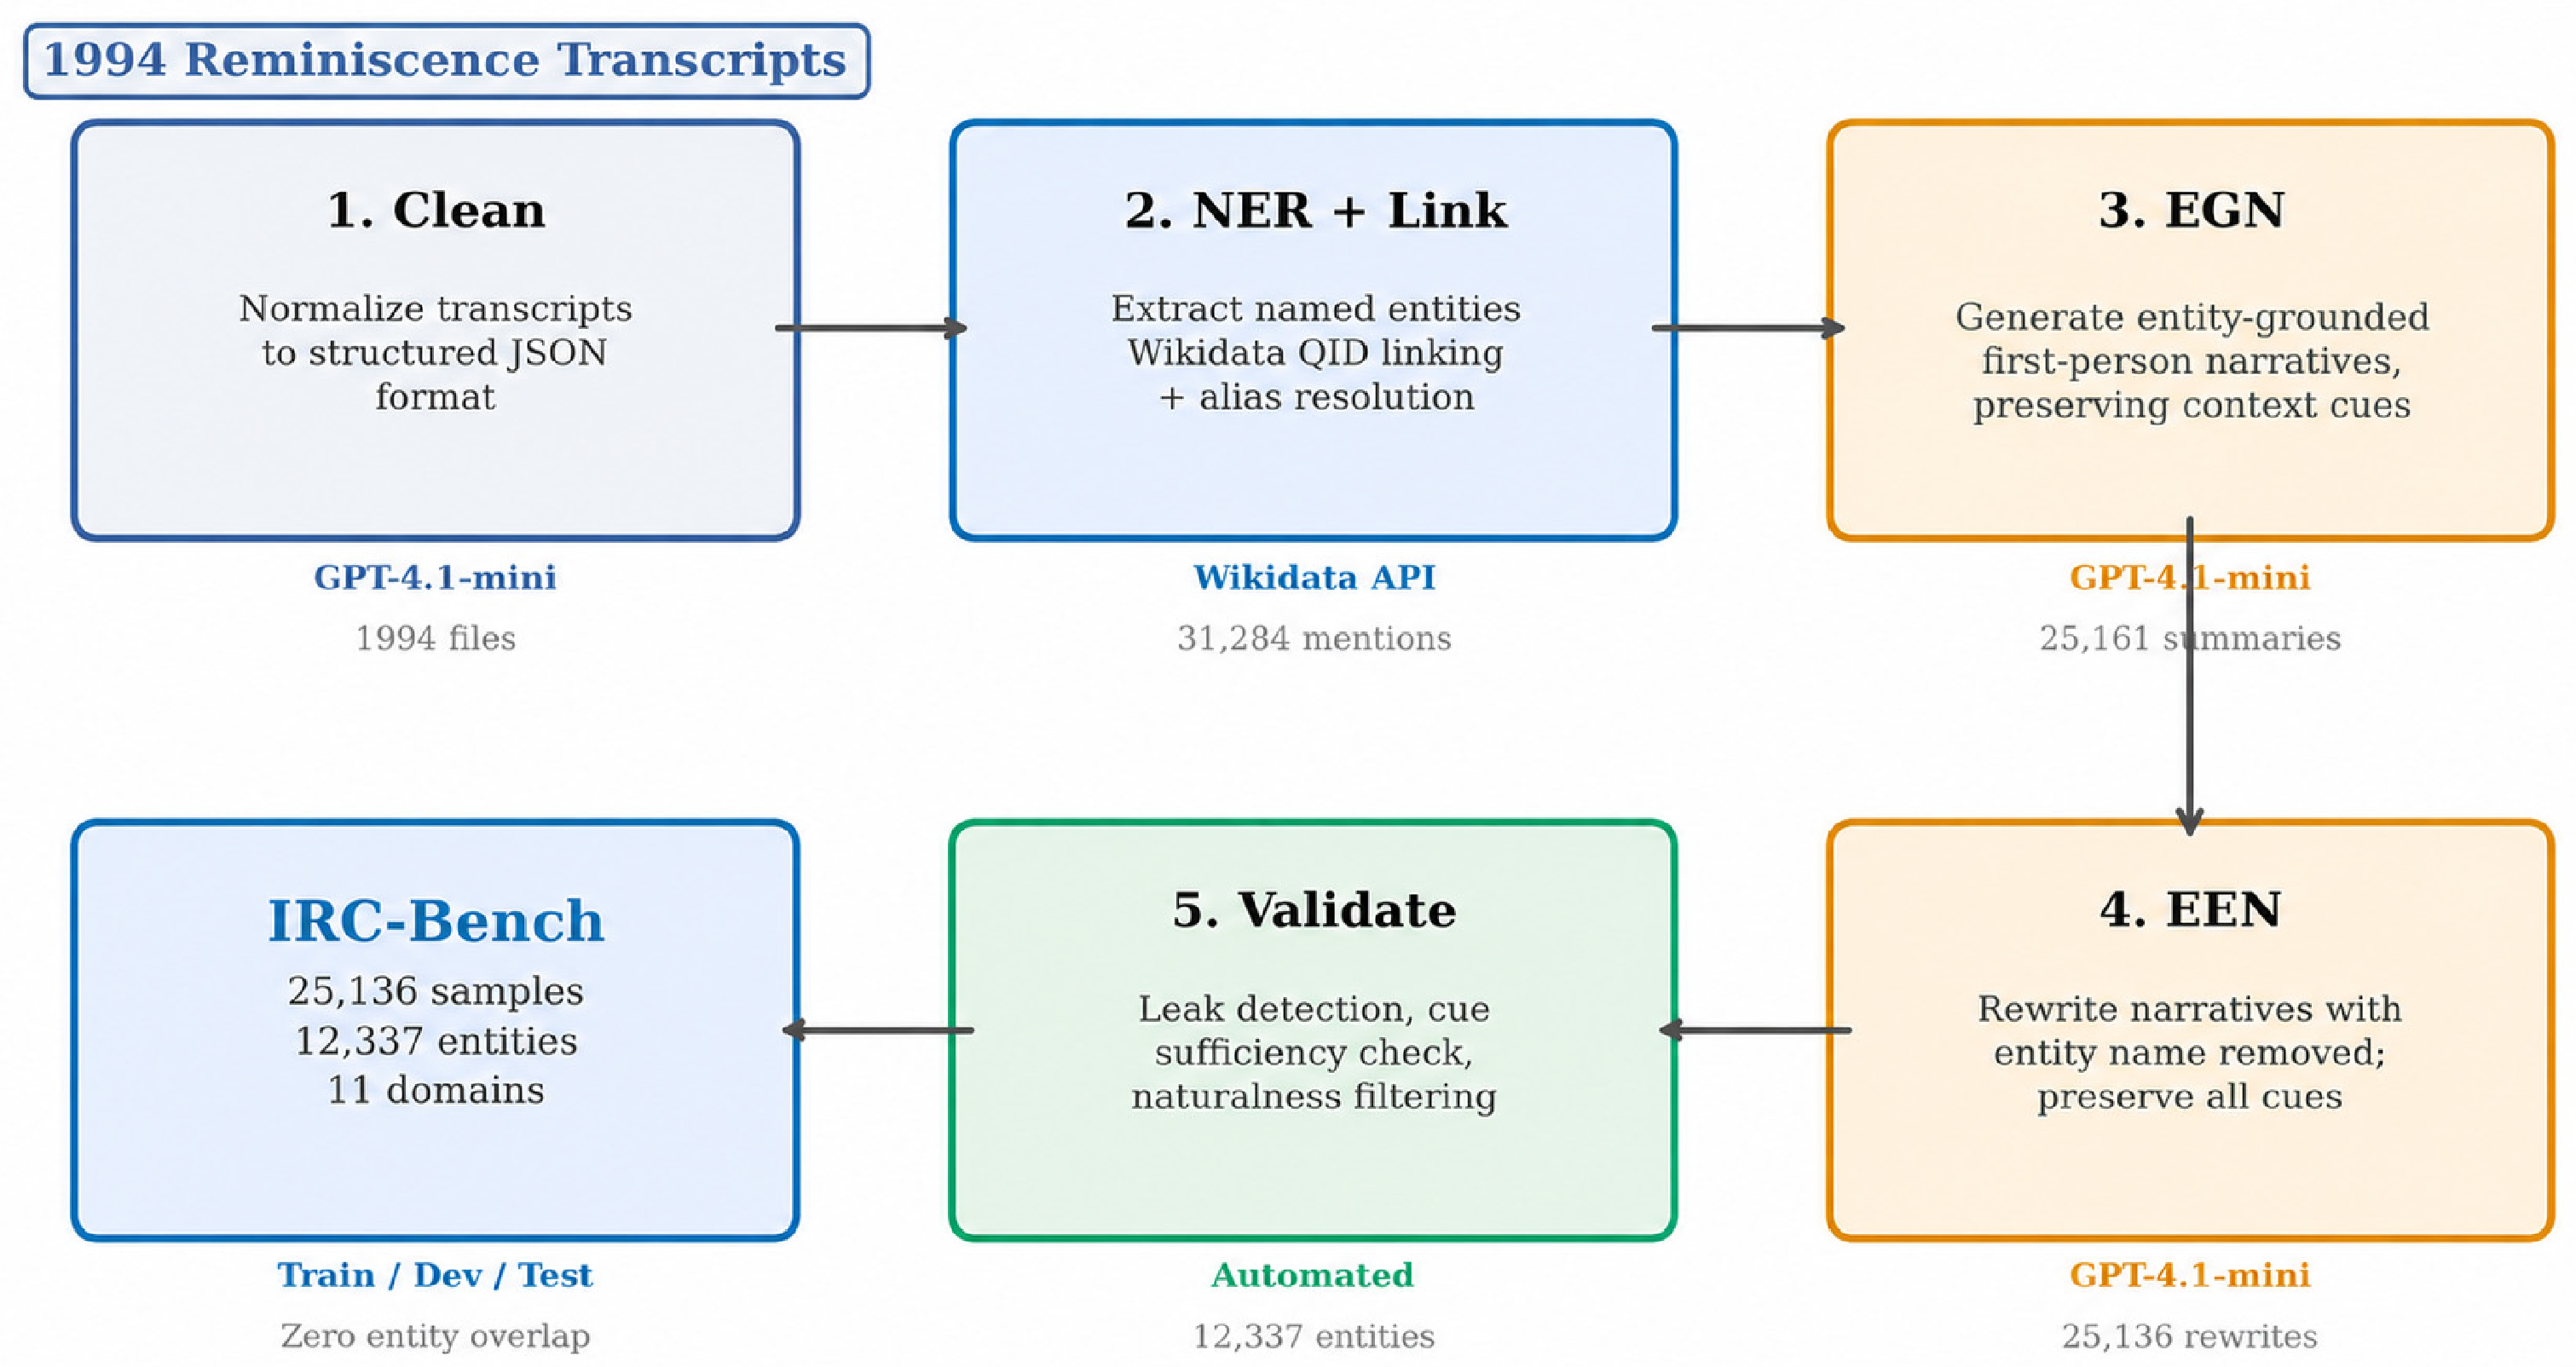
- IRC-Bench. We release IRC-Bench as a community evaluation resource: 25,136 implicit entity recognition samples derived from 12,337 unique Wikidata-linked entities sourced from 1994 reminiscence transcripts across 11 thematic domains, with entity-level train/dev/test splits ensuring zero entity overlap between partitions. Each sample includes both an EGN and an EEN, along with entity metadata (QID, aliases, Wikipedia description). The release follows the NeurIPS Datasets and Benchmarks track convention; contributions (1) and (3) stand independently of the dataset release.
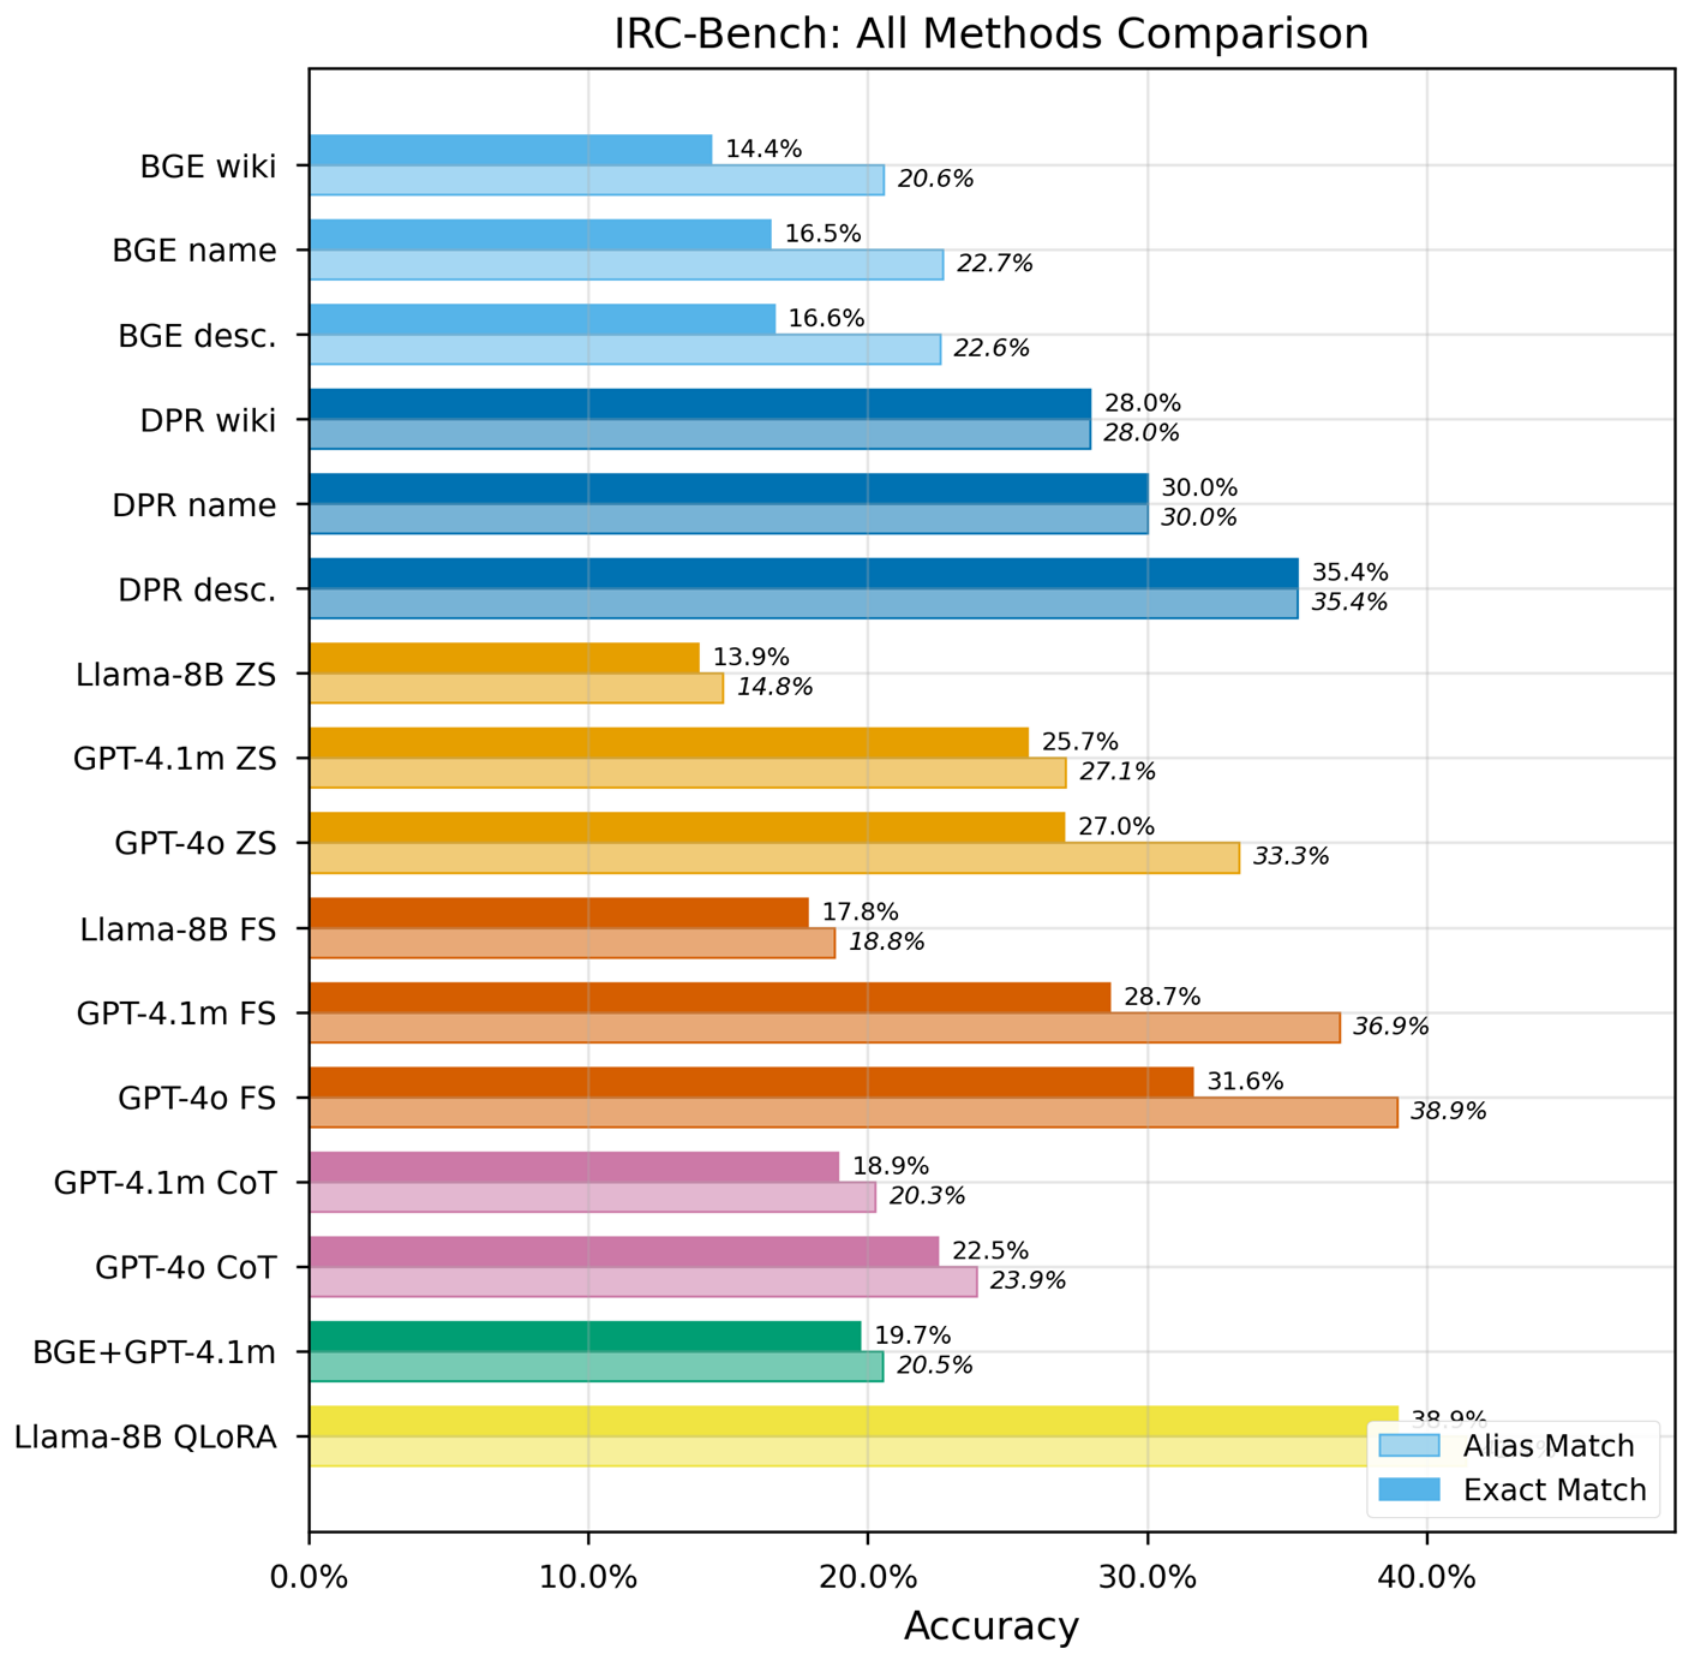
- Comprehensive evaluation. We systematically compare 19 experimental configurations spanning open-world LLM inference (zero-shot, few-shot, chain-of-thought, QLoRA fine-tuning), closed-world dense retrieval (off-the-shelf and DPR fine-tuned), and hybrid RAG, revealing that fine-tuning doubles performance in both paradigms, chain-of-thought reasoning degrades performance on this task, and model scale interacts strongly with prompting and adaptation strategy.
2. Related Work
2.1. Named Entity Recognition
2.2. Entity Linking
2.3. Reminiscence Analysis and NLP
2.4. Implicit and Zero-Mention Entities
2.5. Oral History NLP
2.6. Knowledge-Grounded Question Answering
2.7. Recent Developments
3. Dataset Construction
3.1. Overview
3.2. Source Collections
3.3. Pipeline Stages
3.4. Entity Knowledge Base
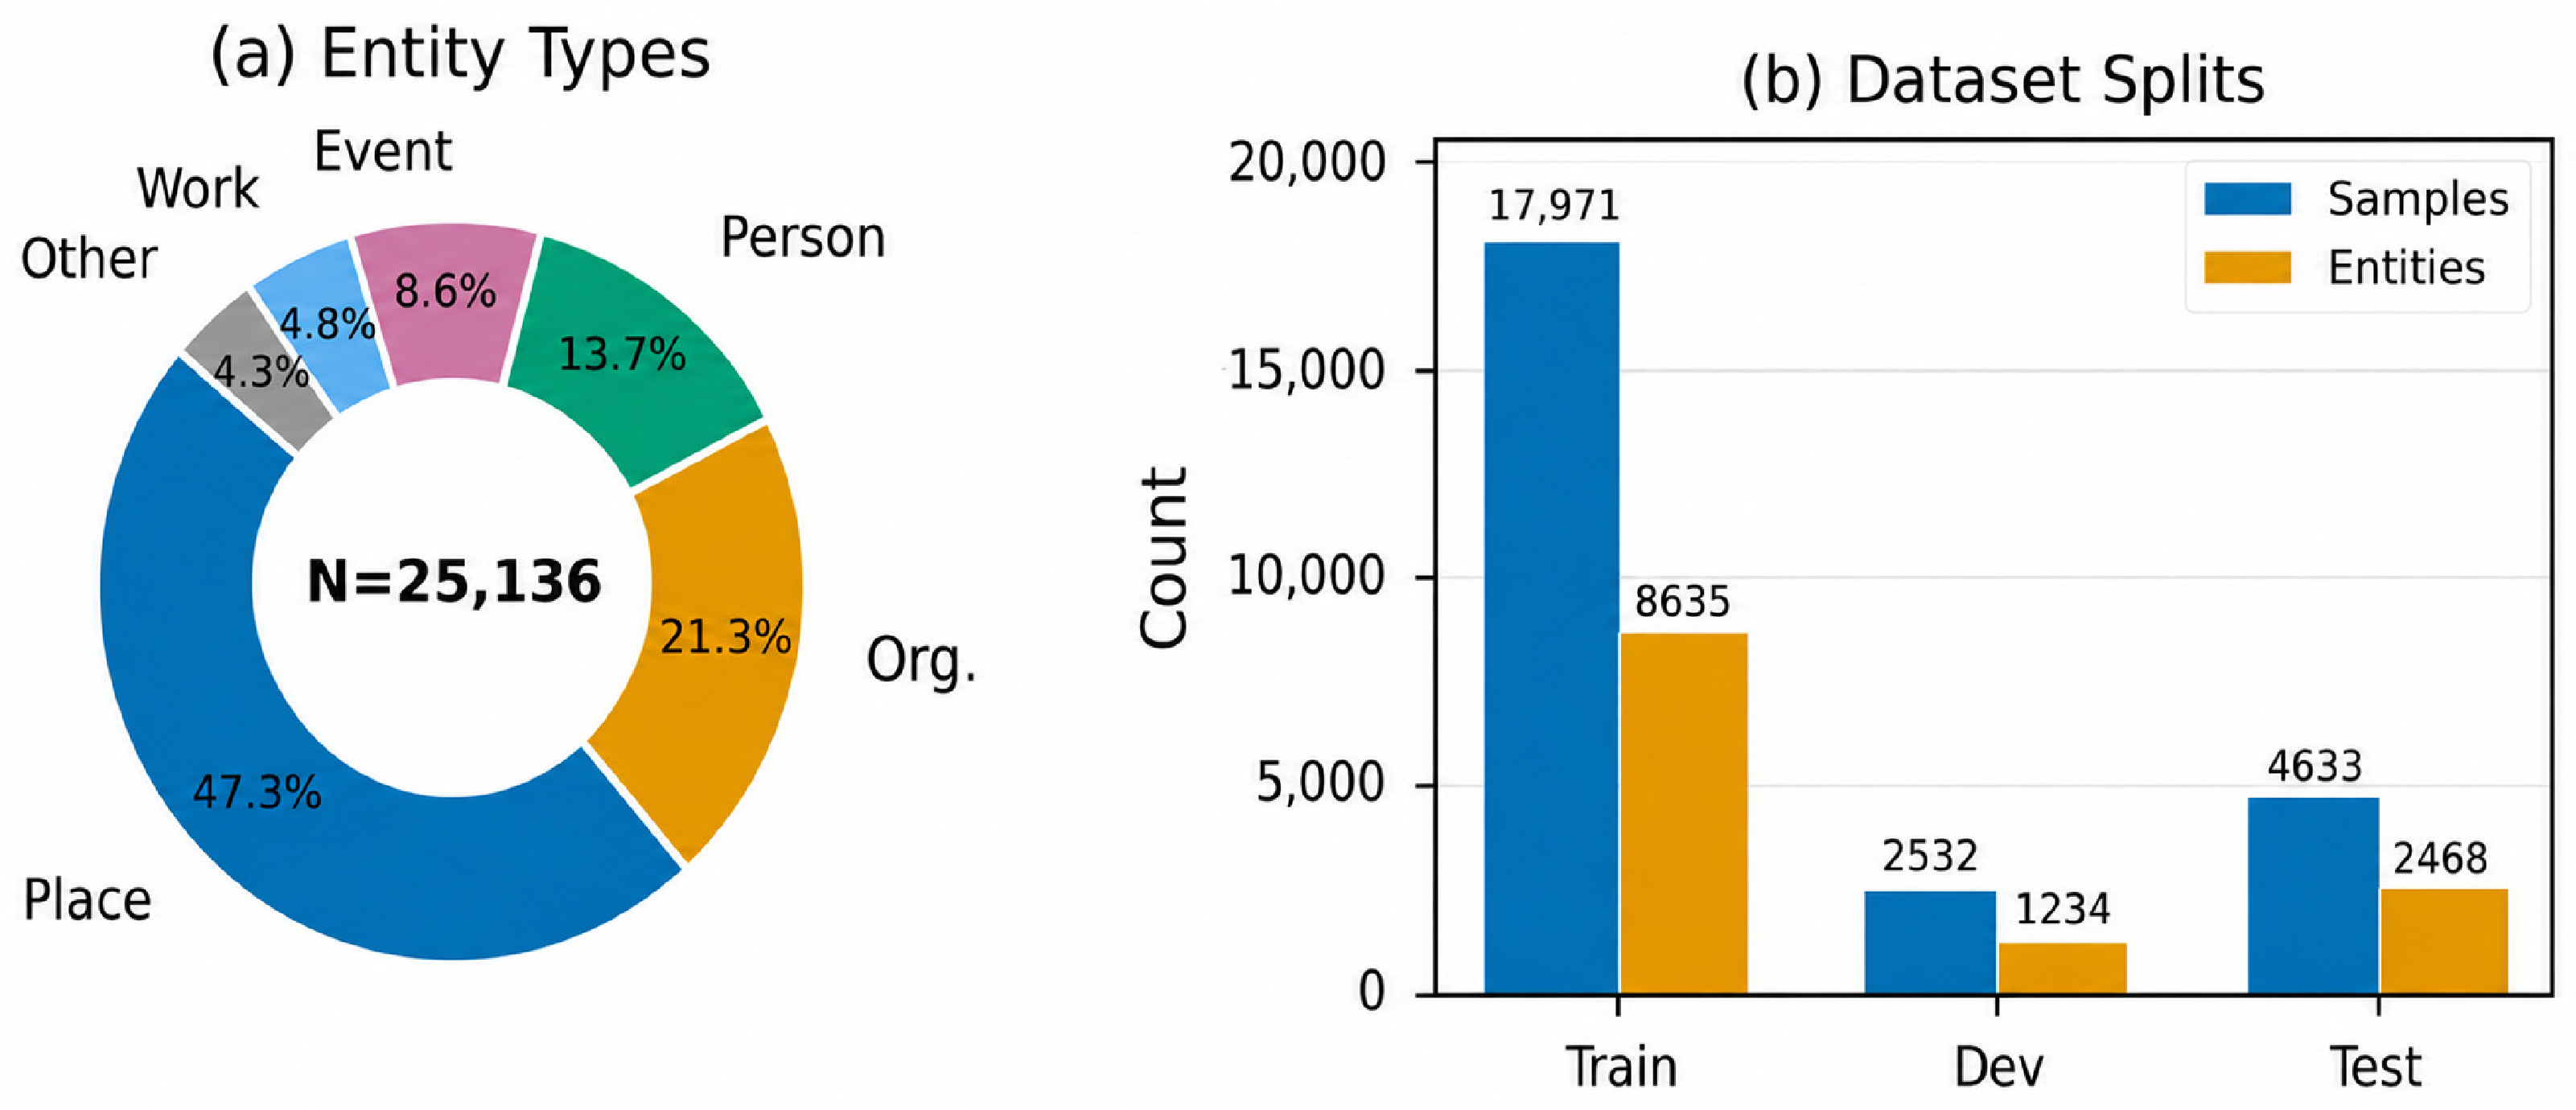
3.5. Entity-Level Train/Dev/Test Splitting
3.6. Entity Type Distribution
3.7. Example Samples
3.8. Pipeline Validation and Difficulty Calibration
4. Methodology
4.1. Task Formulation
4.2. The Non-Locality Property
4.3. Open-World Methods
4.3.1. LLM Generative Approach
4.3.2. Models
4.3.3. QLoRA Fine-Tuning (O10)
4.4. Closed-World Methods
4.4.1. BGE-Base Baseline (Closed-World Configurations C1, C2, C3)
4.4.2. DPR Fine-Tuning (Closed-World Configurations C4, C5, C6)
4.5. RAG Baseline (RAG Configuration 1; RAG1)
4.6. Leakage Prevention
5. Evaluation Protocol
5.1. Matching Hierarchy
5.2. Metrics
5.3. Statistical Significance
6. Results and Analysis
6.1. Open-World Performance
6.2. Closed-World Performance
6.3. Cross-Paradigm Comparison
6.4. Per-Entity-Type Analysis
6.5. Error Analysis
6.6. Key Findings Summary
6.7. Statistical Significance Results
7. Discussion
7.1. Implications for System Design
7.2. Generalization and Boundary Conditions
7.3. Application Areas
7.4. What IRC-Bench Measures That Prior Tasks Do Not
7.5. Threats to Validity
8. Conclusions
Author Contributions
Funding
Data Availability Statement
Conflicts of Interest
Abbreviations
| BAAI | Beijing Academy of Artificial Intelligence |
| BGE | BAAI General Embedding |
| BiLSTM-CRF | Bidirectional long short-term memory with conditional random fields |
| BLINK | Bi-encoder Linker |
| C1-C6 | Closed-world experimental configurations 1–6 |
| CoT | Chain-of-thought |
| DPR | Dense passage retrieval |
| EEN | Entity-elided narrative |
| EGN | Entity-grounded narrative |
| EL | Entity linking |
| FS | Few-shot |
| GENRE | Generative Entity Retrieval |
| IRC-Bench | Implicit Reminiscence Context Benchmark |
| LoRA | Low-Rank Adaptation |
| MNRL | Multiple Negatives Ranking Loss |
| MRR | Mean Reciprocal Rank |
| MTEB | Massive Text Embedding Benchmark |
| NER | Named Entity Recognition |
| NF4 | NormalFloat 4-bit |
| O1-O13 | Open-world experimental configurations 1–13 |
| QID | Wikidata identifier |
| QLoRA | Quantized Low-Rank Adaptation |
| RAG | Retrieval-augmented generation |
| W2NER | Word–word relation classification for named entity recognition |
| ZS | Zero-shot |
Appendix A. Prompt Templates
Appendix A.1. Zero-Shot Prompt
| You are an entity recognition expert. Given a text that implicitly references a named entity without mentioning it, identify what entity is being referenced. |
| What named entity is implicitly referenced in this text? The entity is never mentioned by name. Text: “{text}” Think about the contextual cues (dates, places, events, people, roles) and identify the specific named entity being referenced. Answer with ONLY the entity name (canonical Wikipedia name), nothing else. |
Appendix A.2. Few-Shot Prompt
| You are an entity recognition expert. Given a text that implicitly references a named entity without mentioning it, identify what entity is being referenced. |
| What named entity is implicitly referenced in this text? The entity is never mentioned by name. Examples: Text: “I remember that Sunday morning in December 41. We were listening to the radio when the news broke about the attack on the naval base in Hawaii. That’s when everything changed.” Entity: Attack on Pearl Harbor Text: “I enlisted right out of high school and went to boot camp in San Diego. As an aircraft mechanic, I was sent to the Pacific.” Entity: United States Marine Corps Text: “After the surrender, we flew into the main islands. I landed in the bay and spent six months there for the occupation. The capital was flattened by the B-29s.” Entity: Tokyo Text: “In late 1941, I was set to ship out from San Francisco. A friend ran up saying they’re bombing the base in Hawaii.” Entity: Attack on Pearl Harbor Text: “Growing up in that bustling metropolis with towering skyscrapers, I was immersed in a vibrant culture.” Entity: New York City Now identify the entity in this text: Text: “{text}” Answer with ONLY the entity name (canonical Wikipedia name), nothing else. |
Appendix A.3. Chain-of-Thought Prompt
| You are an entity recognition expert. Think step by step. |
| What named entity is implicitly referenced in this text? The entity is never mentioned by name. Text: “{text}” Think step by step: 1. What contextual cues are present? (dates, places, events, people, roles) 2. What type of entity do these cues suggest? (Person, Place, Organization, Event) 3. What specific named entity matches ALL these cues? Reasoning: [your step-by-step analysis] Entity: [canonical Wikipedia name] |
Appendix A.4. RAG Prompt
| This text implicitly references a named entity without naming it. Based on the contextual cues, which candidate is most likely? Text: “{text}” Candidates: 1. {candidate_1} − {description_1} 2. {candidate_2} − {description_2} 3. {candidate_3} − {description_3} 4. {candidate_4} − {description_4} 5. {candidate_5} − {description_5} If none match well, suggest a better entity. Answer: [number]. [entity name] |
Appendix A.5. QLoRA Fine-Tuning Prompt (O10)
| <|begin_of_text|> <|start_header_id|>system<|end_header_id|> You identify implicitly referenced entities.<|eot_id|> <|start_header_id|>user<|end_header_id|> What entity is implicitly referenced? Answer with only the entity name. Text: {implicit_text}<|eot_id|> <|start_header_id|>assistant<|end_header_id|> {entity}<|eot_id|> |
Appendix A.6. Pipeline Stage 2: NER + Wikidata-Title Prompt
| You are a named entity recognition expert. Output ONLY a valid JSON array. No markdown, no code fences, no explanation. |
| Extract ALL notable named entities from this oral history transcript. For each entity provide: -id: sequential number (1, 2, 3…) -entity: canonical name (as it appears on Wikipedia) -type: exactly one of: Person, Place, Organization, Event, Work, Military_Unit -surface_forms: array of exact text spans from the transcript that reference this entity (include all variations/mentions) -wikipedia_title: Wikipedia article title (best guess, use canonical English Wikipedia title) RULES: 1. Only include entities that would have a Wikipedia article 2. Include all notable: people, places, organizations, events, military units, cultural works 3. Do NOT include the interviewer or respondent themselves (unless they are a public figure being interviewed ABOUT their public role) 4. Do NOT include generic terms (army, soldier, war, city, country without specific name) 5. Include historical events with specific names (Pearl Harbor, D-Day, 9/11) 6. For places: include specific named locations (cities, bases, landmarks), not generic (“the beach”, “my house”) 7. Surface forms: list ALL different ways the entity is mentioned in the text Output ONLY a JSON array: [{“id”: 1, “entity”: “Pearl Harbor”, “type”: “Event”, “surface_forms”: [“Pearl Harbor”, “the attack on Pearl Harbor”], “wikipedia_title”: “Attack_on_Pearl_Harbor”}, {“id”: 2, “entity”: “United States Marine Corps”, “type”: “Organization”, “surface_forms”: [“the Marines”, “Marine Corps”, “USMC”], “wikipedia_title”: “United_States_Marine_Corps”}] Transcript: {text} |
Appendix A.7. Pipeline Stage 3: Entity-Grounded Summary Prompt
| You are a research assistant creating entity-focused summaries from oral history transcripts. Output ONLY valid JSON. No markdown, no code fences. |
| Given this oral history transcript and a list of entities found in it, generate a short first-person summary for EACH entity. Each summary should: 1. Be 3–5 sentences, written as if the respondent is telling the story 2. Mention the entity BY NAME naturally 3. Include contextual cues: dates, places, co-occurring events, roles, people 4. Capture the relationship between the respondent and the entity 5. Be factually grounded in the transcript (no invented details) Entities to summarize: {entities} Transcript: {text} Output a JSON array with one object per entity: [ { “entity_id”: 1, “entity”: “Pearl Harbor”, “summary”: “I remember when Pearl Harbor was attacked. It was 7 December 1941, and I was listening to the radio…”, “cues”: [“7 December 1941”, “radio”, “attack”, “Hawaii”] } ] Generate summaries for ALL entities listed above. Output ONLY the JSON array. |
Appendix A.8. Pipeline Stage 4: Entity Elision (Implicit Rewrite) Prompt
| You rewrite text to remove entity names while preserving style and content. Output ONLY valid JSON. No markdown, no code fences. |
| Rewrite each summary so the target entity is NEVER mentioned by name, abbreviation, or obvious synonym. RULES: 1. Remove ALL direct references to the entity name 2. Keep the first-person voice and speaking style 3. Keep all contextual cues: dates, places, co-occurring events, roles, people 4. Replace the entity name with natural contextual descriptions (not verbose) 5. Do NOT add or invent new information 6. Keep the same length (3–5 sentences) 7. The rewritten text should still allow a knowledgeable reader to identify the entity Summaries to rewrite: {summaries} Output a JSON array with the rewritten versions: [ { “entity_id”: 1, “entity”: “Pearl Harbor”, “implicit_text”: “I remember when it happened. It was 7 December 1941, and we were listening to a football game on the radio when the news broke about the attack on the naval base in Hawaii…” } ] Rewrite ALL summaries. Output ONLY the JSON array. |
Appendix B. Training Hyperparameters
Appendix B.1. QLoRA (O10) Fine-Tuning

| Base model | meta-llama/Llama-3.1-8B-Instruct |
| Model parameters | ~8B (base); ~6.5M trainable (LoRA) |
| Quantization | 4-bit NormalFloat (NF4) |
| Compute dtype | bfloat16 |
| LoRA rank (r) | 16 |
| LoRA alpha (α) | 32 |
| LoRA dropout | 0.05 |
| Target modules | q_proj, v_proj, k_proj, o_proj |
| Training examples | 17,971 |
| Epochs | 2 |
| Per-device batch size | 48 |
| Gradient accumulation | 1 (effective batch: 48) |
| Learning rate | 2 × 10⁻⁴ |
| Max sequence length | 192 tokens |
| Warmup steps | 50 |
| Precision | bfloat16 |
| Validation samples | 500 (subset of dev) |
| Framework | TRL SFTTrainer + PEFT |
Appendix B.2. DPR (Dense Passage Retrieval) Fine-Tuning
| Base model | BAAI/bge-base-en-v1.5 |
| Model parameters | ~110 M |
| Embedding dimension | 768 |
| Training examples | 17,971 |
| Epochs | 3 |
| Batch size | 48 |
| Learning rate | 2 × 10⁻⁵ |
| Warmup steps | 100 |
| Loss function | MultipleNegativesRankingLoss (MNRL) |
| Optimizer | AdamW |
| Mixed precision | FP16 (AMP) |
| Negatives | In-batch (47 negatives per sample) |
| Random seed | 42 |
Appendix B.3. Quality-Evaluation Judge Prompt
| You are evaluating the quality of an implicit entity recognition sample. A human narrator originally described an event/person/place by name (the Entity-Grounded Narrative). The entity name was then removed to create the Entity-Elided Narrative (EEN), preserving only contextual cues. Your task: evaluate the EEN quality on four dimensions. **Entity:** {entity_name} ({entity_type}) **EEN (entity name removed):** “{een_text}” **EGN (original with entity name):** “{egn_text}” Rate each dimension: 1. **Naturalness** (1–5): Does the EEN read like something a person would naturally say? (1 = very awkward/robotic, 5 = completely natural first-person speech) 2. **Leakage** (yes/no): Does the entity name (or an obvious alias) still appear verbatim in the EEN? 3. **Cue sufficiency** (1–5): Are there enough contextual cues in the EEN for a knowledgeable human to identify the entity? (1 = impossible, 3 = possible with expertise, 5 = obvious) 4. **Recoverability** (yes/probably/unlikely/no): Could you identify the entity from the EEN alone, without seeing the EGN? Respond in exactly this format: Naturalness: [1–5] Leakage: [yes/no] Cue sufficiency: [1–5] Recoverability: [yes/probably/unlikely/no] Brief explanation: [one sentence] |
Appendix C. Example Predictions
Appendix C.1. Correct Predictions (O2: GPT-4o Few-Shot)
| Correct Example 1 “I studied at a major public university in Northern California, where I was part of the Design Department. During my time there, I combined academic courses with art classes, focusing on three-dimensional design…” Gold: University of California, Berkeley|Prediction: University of California, Berkeley ✓ |
| Correct Example 2 “I was born in the capital city of Germany in the early 1930s. It was a turbulent time as the political climate was rapidly changing. My family decided to leave that city in 1938 to escape the dangers posed by the Nazi regime. That move shaped much of my early life and future.” Gold: Berlin|Prediction: Berlin ✓ |
| Correct Example 3 “When I first came to America, I worked in a Pacific island territory for eight months on a sugar plantation. I was only 15 years old and worked under a Chinese boss for $18 a month…” Gold: Hawaii|Prediction: Hawaii ✓ |
| Correct Example 4 “My grandfather was a teenager during the major 1950s political upheaval in our Caribbean homeland and once found a journal from someone fighting with the revolutionary leader. That period was filled with fear for my family and community. The uprising brought about communism, which had some positive effects like high literacy rates, but also caused extreme poverty and suffering. The memories of that era shape how older immigrants from that island view politics in the United States today.” Gold: Cuban Revolution|Prediction: Cuban Revolution ✓ |
| Correct Example 5 “He and I were close when he was Senate majority leader, and he was very cordial to me when I first came to the Senate. He gave me important committee assignments, including chairing the Calendar Committee and seats on the Agricultural and Finance Committees. He was probably the most able majority leader in history, knowing the Senate’s personalities and how to motivate them. As President, he overcommitted on social programs, which I believe contributed to the huge deficits we face today.” Gold: Lyndon B. Johnson|Prediction: Lyndon B. Johnson ✓ |
Appendix C.2. Incorrect Predictions (O2: GPT-4o Few-Shot)
| Incorrect Example 1: Wrong type “My great-grandfather left Lithuania in the early 1900s to escape oppression and seek a better life in America. He arrived before World War I and worked hard to establish himself, eventually sending for his family…” Gold: Solomon Goodman|Prediction: Lithuanian Jews ✗ The model predicted a group/category rather than the specific individual being described. |
| Incorrect Example 2: Wrong type “I once kept a newspaper clipping of a write-up about a historic estate by a famous 19th-century author, but unfortunately, I have misplaced it. The author’s writing gave me some insight into the estate…” Gold: Harriet Beecher Stowe|Prediction: Monticello ✗ The model focused on the “historic estate” cue rather than the “famous 19th-century author” cue. |
| Incorrect Example 3: Wrong type “The priest who taught me algebra and later became the bishop of a diocese in eastern Washington questioned my presence in his advanced algebra class because I lacked the necessary background…” Gold: Bishop of Spokane|Prediction: West Point ✗ The model produced a completely unrelated entity, likely confusing the religious context. |
| Incorrect Example 4: Same-type, related “Remote healthcare delivery became a critical part of how we provided care during the viral outbreak. Initially, we relied on phone calls, but within weeks, our organization quickly implemented video…” Gold: Telehealth|Prediction: COVID-19 pandemic ✗ The model identified the correct general domain but predicted the contextual event rather than the practice being described. |
| Incorrect Example 5: Same-type, near miss “He was my Ph.D. advisor at the California university starting in 1956. He was a brilliant economist who later won the Nobel Prize, and studying under him greatly influenced my academic development. His mentorship helped shape my approach to economics and game theory.” Gold: Kenneth Arrow|Prediction: John Forbes Nash Jr. ✗ The model predicted a Nobel laureate economist associated with game theory, but confused the advisor (Arrow, at Stanford) with another famous figure in the same field. |
References
- Subramaniam, P.; Woods, B. The impact of individual reminiscence therapy for people with dementia: Systematic review. Expert Rev. Neurother. 2012, 12, 545–555. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Woods, B.; O’Philbin, L.; Farrell, E.M.; Spector, A.E.; Orrell, M. Reminiscence therapy for dementia. Cochrane Database Syst. Rev. 2018, 2018, CD001120. [Google Scholar] [CrossRef] [Scilit]
- Boyd, D. Achieving the Promise of Oral History in a Digital Age. In The Oxford Handbook of Oral History, Oxford Handbooks; Ritchie, D.A., Ed.; Oxford Academic: Oxford, UK, 2012. [Google Scholar] [CrossRef] [Scilit]
- Nadeau, D.; Sekine, S. A survey of named entity recognition and classification. Lingvisticae Investig. 2007, 30, 3–26. [Google Scholar] [CrossRef] [Scilit]
- Li, J.; Sun, A.; Han, J.; Li, C. A survey on deep learning for named entity recognition. IEEE Trans. Knowl. Data Eng. 2020, 34, 50–70. [Google Scholar] [CrossRef] [Scilit]
- Ganea, O.E.; Hofmann, T. Deep joint entity disambiguation with local neural attention. In Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing, Copenhagen, Denmark, 9–11 September 2017; pp. 2619–2629. [Google Scholar]
- Kolitsas, N.; Ganea, O.E.; Hofmann, T. End-to-end neural entity linking. In Proceedings of the 22nd Conference on Computational Natural Language Learning, Brussels, Belgium, 31 October–1 November 2018; pp. 519–529. [Google Scholar]
- Lee, K.; He, L.; Lewis, M.; Zettlemoyer, L. End-to-end neural coreference resolution. In Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing, Copenhagen, Denmark, 9–11 September 2017; pp. 188–197. [Google Scholar]
- Hosseini, H. Implicit Entity Recognition and Linking in Tweets. Ph.D. Thesis, Toronto Metropolitan University, Toronto, ON, Canada, 2022. [Google Scholar]
- Hosseini, H.; Bagheri, E. Learning to rank implicit entities on Twitter. Inf. Process. Manag. 2021, 58, 102503. [Google Scholar] [CrossRef] [Scilit]
- Lample, G.; Ballesteros, M.; Subramanian, S.; Kawakami, K.; Dyer, C. Neural architectures for named entity recognition. In Proceedings of the 2016 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, San Diego, CA, USA, 12–17 June 2016; pp. 260–270. [Google Scholar]
- Devlin, J.; Chang, M.W.; Lee, K.; Toutanova, K. Bert: Pre-training of deep bidirectional transformers for language understanding. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers); Association for Computational Linguistics: Stroudsburg, PA, USA, 2019; pp. 4171–4186. [Google Scholar]
- Xie, T.; Li, Q.; Zhang, J.; Zhang, Y.; Liu, Z.; Wang, H. Empirical study of zero-shot NER with ChatGPT. In Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing; Association for Computational Linguistics: Singapore, 2023; pp. 7935–7956. [Google Scholar]
- Ashok, D.; Lipton, Z.C. Promptner: Prompting for named entity recognition. arXiv 2023, arXiv:2305.15444. [Google Scholar]
- Sang, E.T.K.; De Meulder, F. Introduction to the CoNLL-2003 shared task: Language-independent named entity recognition. In Proceedings of the Seventh Conference on Natural language Learning at HLT-NAACL, Edmonton, AB, Canada, 31 May–1 June 2003; pp. 142–147. [Google Scholar]
- Malmasi, S.; Fang, A.; Fetahu, B.; Kar, S.; Rokhlenko, O. MultiCoNER: A large-scale multilingual dataset for complex named entity recognition. In Proceedings of the 29th International Conference on Computational Linguistics, Gyeongju, Republic of Korea, 12–17 October 2022; pp. 3798–3809. [Google Scholar]
- Li, J.; Fei, H.; Liu, J.; Wu, S.; Zhang, M.; Teng, C.; Ji, D.; Li, F. Unified named entity recognition as word-word relation classification. In Proceedings of the AAAI Conference on Artificial Intelligence; Association for the Advancement of Artificial Intelligence: Washington, DC, USA, 2022; Volume 36, No. 10, pp. 10965–10973. [Google Scholar]
- Zhou, W.; Zhang, S.; Gu, Y.; Chen, M.; Poon, H. Universalner: Targeted distillation from large language models for open named entity recognition. arXiv 2023, arXiv:2308.03279. [Google Scholar]
- Wu, L.; Petroni, F.; Josifoski, M.; Riedel, S.; Zettlemoyer, L. Scalable zero-shot entity linking with dense entity retrieval. In Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP), Online, 8–12 November 2020; pp. 6397–6407. [Google Scholar]
- De Cao, N.; Izacard, G.; Riedel, S.; Petroni, F. Autoregressive Entity Retrieval. In Proceedings of the ICLR 2021-9th International Conference on Learning Representations, Virtual, Austria, 3–7 May 2021; Volume 2021. [Google Scholar]
- Ayoola, T.; Tyagi, S.; Fisher, J.; Christodoulopoulos, C.; Pierleoni, A. Refined: An efficient zero-shot-capable approach to end-to-end entity linking. In Proceedings of the 2022 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies: Industry Track, Seattle, WA, USA, 10–15 July 2022; pp. 209–220. [Google Scholar]
- Botha, J.A.; Shan, Z.; Gillick, D. Entity linking in 100 languages. In Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP); Association for Computational Linguistics: Stroudsburg, PA, USA, 2020; pp. 7833–7845. [Google Scholar]
- Butler, R.N. The life review: An interpretation of reminiscence in the aged. Psychiatry 1963, 26, 65–76. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Webster, J.D. Construction and validation of the Reminiscence Functions Scale. J. Gerontol. 1993, 48, P256–P262. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Nikitina, S.; Callaioli, S.; Baez, M. Smart conversational agents for reminiscence. In Proceedings of the 1st International Workshop on Software Engineering for Cognitive Services, Gothenburg, Sweden, 28–29 May 2018; pp. 52–57. [Google Scholar]
- Pessanha, F.; Salah, A.A. A computational look at oral history archives. J. Comput. Cult. Herit. 2021, 15, 1–16. [Google Scholar] [CrossRef] [Scilit]
- Perera, N.; Dehmer, M.; Emmert-Streib, F. Named entity recognition and relation detection for biomedical information extraction. Front. Cell Dev. Biol. 2020, 8, 673. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Hou, Y. Bridging anaphora resolution as question answering. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics; Association for Computational Linguistics: Stroudsburg, PA, USA, 2020; pp. 1428–1438. [Google Scholar]
- Poesio, M.; Stuckardt, R.; Versley, Y. Anaphora Resolution: Algorithms, Resources, and Applications; Springer: Berlin/Heidelberg, Germany, 2016. [Google Scholar]
- Treder, M.S.; Lee, S.; Tsvetanov, K.A. Introduction to Large Language Models (LLMs) for dementia care and research. Front. Dement. 2024, 3, 1385303. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Broadbent, E.; Stafford, R.; MacDonald, B. Acceptance of healthcare robots for the older population: Review and future directions. Int. J. Soc. Robot. 2009, 1, 319–330. [Google Scholar] [CrossRef] [Scilit]
- De Jager, A.; Fogarty, A.; Tewson, A.; Lenette, C.; Boydell, K. Digital storytelling in research: A systematic review. Qual. Rep. 2017, 22, 2548–2582. [Google Scholar] [CrossRef] [Scilit]
- Yang, Z.; Qi, P.; Zhang, S.; Bengio, Y.; Cohen, W.; Salakhutdinov, R.; Manning, C.D. HotpotQA: A dataset for diverse, explainable multi-hop question answering. In Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing; Association for Computational Linguistics: Stroudsburg, PA, USA, 2018; pp. 2369–2380. [Google Scholar]
- Petroni, F.; Rocktäschel, T.; Riedel, S.; Lewis, P.; Bakhtin, A.; Wu, Y.; Miller, A. Language models as knowledge bases? In Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP); Association for Computational Linguistics: Stroudsburg, PA, USA, 2019; pp. 2463–2473. [Google Scholar]
- Lewis, P.; Perez, E.; Piktus, A.; Petroni, F.; Karpukhin, V.; Goyal, N.; Küttler, H.; Lewis, M.; Yih, W.-T.; Rocktäschel, T.; et al. Retrieval-augmented generation for knowledge-intensive nlp tasks. Adv. Neural Inf. Process. Syst. 2020, 33, 9459–9474. [Google Scholar]
- Karpukhin, V.; Oguz, B.; Min, S.; Lewis, P.; Wu, L.; Edunov, S.; Chen, D.; Yih, W.-t. Dense passage retrieval for open-domain question answering. In Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP); Association for Computational Linguistics: Stroudsburg, PA, USA, 2020; pp. 6769–6781. [Google Scholar]
- Ding, Y.; Zeng, Q.; Weninger, T. Chatel: Entity linking with chatbots. In Proceedings of the 2024 Joint International Conference on Computational Linguistics, Language Resources and Evaluation (LREC-COLING 2024), Turin, Italy, 20–25 May 2024; pp. 3086–3097. [Google Scholar]
- Xin, A.; Qi, Y.; Yao, Z.; Zhu, F.; Zeng, K.; Xu, B.; Hou, B.; Li, J. Llmael: Large language models are good context augmenters for entity linking. In Proceedings of the 34th ACM International Conference on Information and Knowledge Management, Seoul, Republic of Korea, 10–14 November 2025; pp. 3550–3559. [Google Scholar]
- Kuratov, Y.; Bulatov, A.; Anokhin, P.; Rodkin, I.; Sorokin, D.; Sorokin, A.; Burtsev, M. Babilong: Testing the limits of llms with long context reasoning-in-a-haystack. Adv. Neural Inf. Process. Syst. 2024, 37, 106519–106554. [Google Scholar] [CrossRef] [Scilit]
- Hsieh, C.-P.; Sun, S.; Kriman, S.; Acharya, S.; Rekesh, D.; Jia, F.; Ginsburg, B. RULER: What’s the real context size of your long-context language models? arXiv 2024, arXiv:2404.06654. [Google Scholar]
- Modarressi, A.; Deilamsalehy, H.; Dernoncourt, F.; Bui, T.; Rossi, R.A.; Yoon, S.; Schütze, H. Nolima: Long-context evaluation beyond literal matching. arXiv 2025, arXiv:2502.05167. [Google Scholar]
- Žabokrtský, Z.; Konopík, M.; Nedoluzhko, A.; Novák, M.; Ogrodniczuk, M.; Popel, M.; Prazak, O.; Sido, J.; Zeman, D. Findings of the second shared task on multilingual coreference resolution. In Proceedings of the CRAC 2023 Shared Task on Multilingual Coreference Resolution; Association for Computational Linguistics: Stroudsburg, PA, USA, 2023; pp. 1–18. [Google Scholar]
- Draxler, C.; van den Heuvel, H.; van Hessen, A.; Ircing, P.; Lehečka, J. Speech technology services for oral history research. In Proceedings of the First Workshop on Holocaust Testimonies as Language Resources (HTRes)@ LREC-COLING 2024, Turin, Italy, 20–25 May 2024; pp. 38–43. [Google Scholar]
- Cherukuri, K.S.; Moses, P.A.; Sakata, A.; Chen, J.; Chen, H. Large language models for oral history understanding with text classification and sentiment analysis. arXiv 2025, arXiv:2508.06729. [Google Scholar]
- Hurst, A.; Lerer, A.; Goucher, A.P.; Perelman, A.; Ramesh, A.; Clark, A.; Ostrow, A.J.; Welihinda, A.; Hayes, A.; Radford, A.; et al. Gpt-4o system card. arXiv 2024, arXiv:2410.21276. [Google Scholar]
- Touvron, H.; Martin, L.; Stone, K.; Albert, P.; Almahairi, A.; Babaei, Y.; Bashlykov, N.; Batra, S.; Bhargava, P.; Bhosale, S.; et al. Llama 2: Open foundation and fine-tuned chat models. arXiv 2023, arXiv:2307.09288. [Google Scholar]
- Grattafiori, A.; Dubey, A.; Jauhri, A.; Pandey, A.; Kadian, A.; Al-Dahle, A.; Letman, A.; Mathur, A.; Schelten, A.; Vaughan, A.; et al. The llama 3 herd of models. arXiv 2024, arXiv:2407.21783. [Google Scholar]
- Hu, E.J.; Shen, Y.; Wallis, P.; Allen-Zhu, Z.; Li, Y.; Wang, S.; Wang, L.; Chen, W. Lora: Low-rank adaptation of large language models. arXiv 2022, arXiv:2106.09685v1. [Google Scholar]
- Dettmers, T.; Pagnoni, A.; Holtzman, A.; Zettlemoyer, L. Qlora: Efficient finetuning of quantized llms. Adv. Neural Inf. Process. Syst. 2023, 36, 10088–10115. [Google Scholar] [CrossRef] [Scilit]
- Xiao, S.; Liu, Z.; Zhang, P.; Muennighoff, N.; Lian, D.; Nie, J.Y. C-pack: Packed resources for general Chinese embeddings. In Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval; Association for Computing Machinery: New York, NY, USA, 2024; pp. 641–649. [Google Scholar]


| ENTITY-GROUNDED NARRATIVE (EGN) | “The attack on Pearl Harbor was the event that changed everything for Japanese Americans like me. After 7 December 1941, suspicion and hatred grew, and we were treated as enemy aliens despite being American citizens. It was because of Pearl Harbor that the government issued Executive Order 9066 and started the forced relocation.” |
| ENTITY-ELIDED NARRATIVE (EEN) | “The surprise attack on a naval base in Hawaii was the event that changed everything for Japanese Americans like me. After 7 December 1941, suspicion and hatred grew, and we were treated as enemy aliens despite being American citizens. It was because of that attack that the government issued an order and started the forced relocation.” Gold entity: Attack on Pearl Harbor (Q52418)|Type: Event|Cues: 7 December 1941; naval base in Hawaii; Executive Order 9066; forced relocation |
| Collection | Transcripts | Sources | Description |
|---|---|---|---|
| Veterans | 517 | Library of Congress VHP, Nevada WWII, Niles Library, Wisconsin Veterans Museum | Military service narratives |
| Immigration | 402 | University of Minnesota, Densho Digital Archive | Immigration and assimilation experiences |
| Regional | 314 | University of Nevada Reno, Kentucky Oral History Commission | Regional and community histories |
| Depression Era | 213 | Federal Writers’ Project (Library of Congress) | Great Depression oral histories |
| Japanese American | 156 | Densho Digital Archive | Japanese American internment and post-war |
| Academic | 153 | Columbia University Oral History, Smithsonian Archives of American Art | Academic and university histories |
| September 11 | 72 | National Park Service 9/11 Memorial | 9/11 experiences and aftermath |
| Civil Rights | 68 | Civil Rights History Project (Library of Congress) | Civil rights movement narratives |
| COVID-19 | 42 | Various oral history projects | Pandemic experiences |
| Labor | 30 | Labor Archives and Research Center | Labor movement histories |
| Refugee | 27 | Voices of Conscience, UNHCR collections | Refugee experiences |
| Total | 1994 | 11 thematic domains, 25+ institutional archives | |
| Partition | Samples | Entities |
|---|---|---|
| Train | 17,971 | 8635 |
| Dev | 2532 | 1234 |
| Test | 4633 | 2468 |
| Total | 25,136 | 12,337 |
| Entity Type | Samples | % of Total | Unique Entities |
|---|---|---|---|
| Place | 11,893 | 47.3% | 4821 |
| Organization | 5366 | 21.3% | 2894 |
| Person | 3450 | 13.7% | 2207 |
| Event | 2162 | 8.6% | 1102 |
| Work | 1195 | 4.8% | 743 |
| Military Unit | 537 | 2.1% | 312 |
| Other | 533 | 2.1% | 258 |
| Total | 25,136 | 100% | 12,337 |
| Entity Type | Example |
|---|---|
| Person | EGN: “Rosa Parks was arrested on 5 December 1955, in Montgomery, Alabama, for refusing to give up her bus seat, an act that sparked the Montgomery bus boycott. E. D. Nixon called me late that night to inform me of her arrest and to urge action.” EEN: “A woman was arrested on 5 December 1955, in Montgomery, Alabama, for refusing to give up her bus seat, an act that sparked the Montgomery bus boycott. A local leader called me late that night to inform me of her arrest and to urge action.” Gold: Rosa Parks (Q41921)|Cues: 5 December 1955, Montgomery Alabama, bus seat refusal, bus boycott |
| Event | EGN “I headed the relief committee during the disastrous Berkeley Fire of 1923, helping to coordinate aid and recovery efforts for the community. This was a challenging time for Berkeley, California, and I took an active role in organizing support to help residents rebuild.” EEN “I headed the relief committee during the disastrous fire of 1923 in a California city, helping to coordinate aid and recovery efforts for the community. This was a challenging time for the city, and I took an active role in organizing support to help residents rebuild.” Gold: Berkeley Fire of 1923 (Q4561337) |
| Organization | EGN “After leaving the Navy in 1966, I worked in the warehouse at Montgomery Ward in Redwood City. It was a non-union job and pretty low-key, just me and an older lady doing pricing and warehouse work.” EEN “After leaving the Navy in 1966, I worked in the warehouse at a national department store in Redwood City. It was a non-union job and pretty low-key, just me and an older lady doing pricing and warehouse work.” Gold: Montgomery Ward (Q3046)|Cues: Navy 1966, warehouse, national department store, Redwood City, non-union |
| ID | Model | Mode | Exact, % | Alias, % | Contain, % | Jaccard, % |
|---|---|---|---|---|---|---|
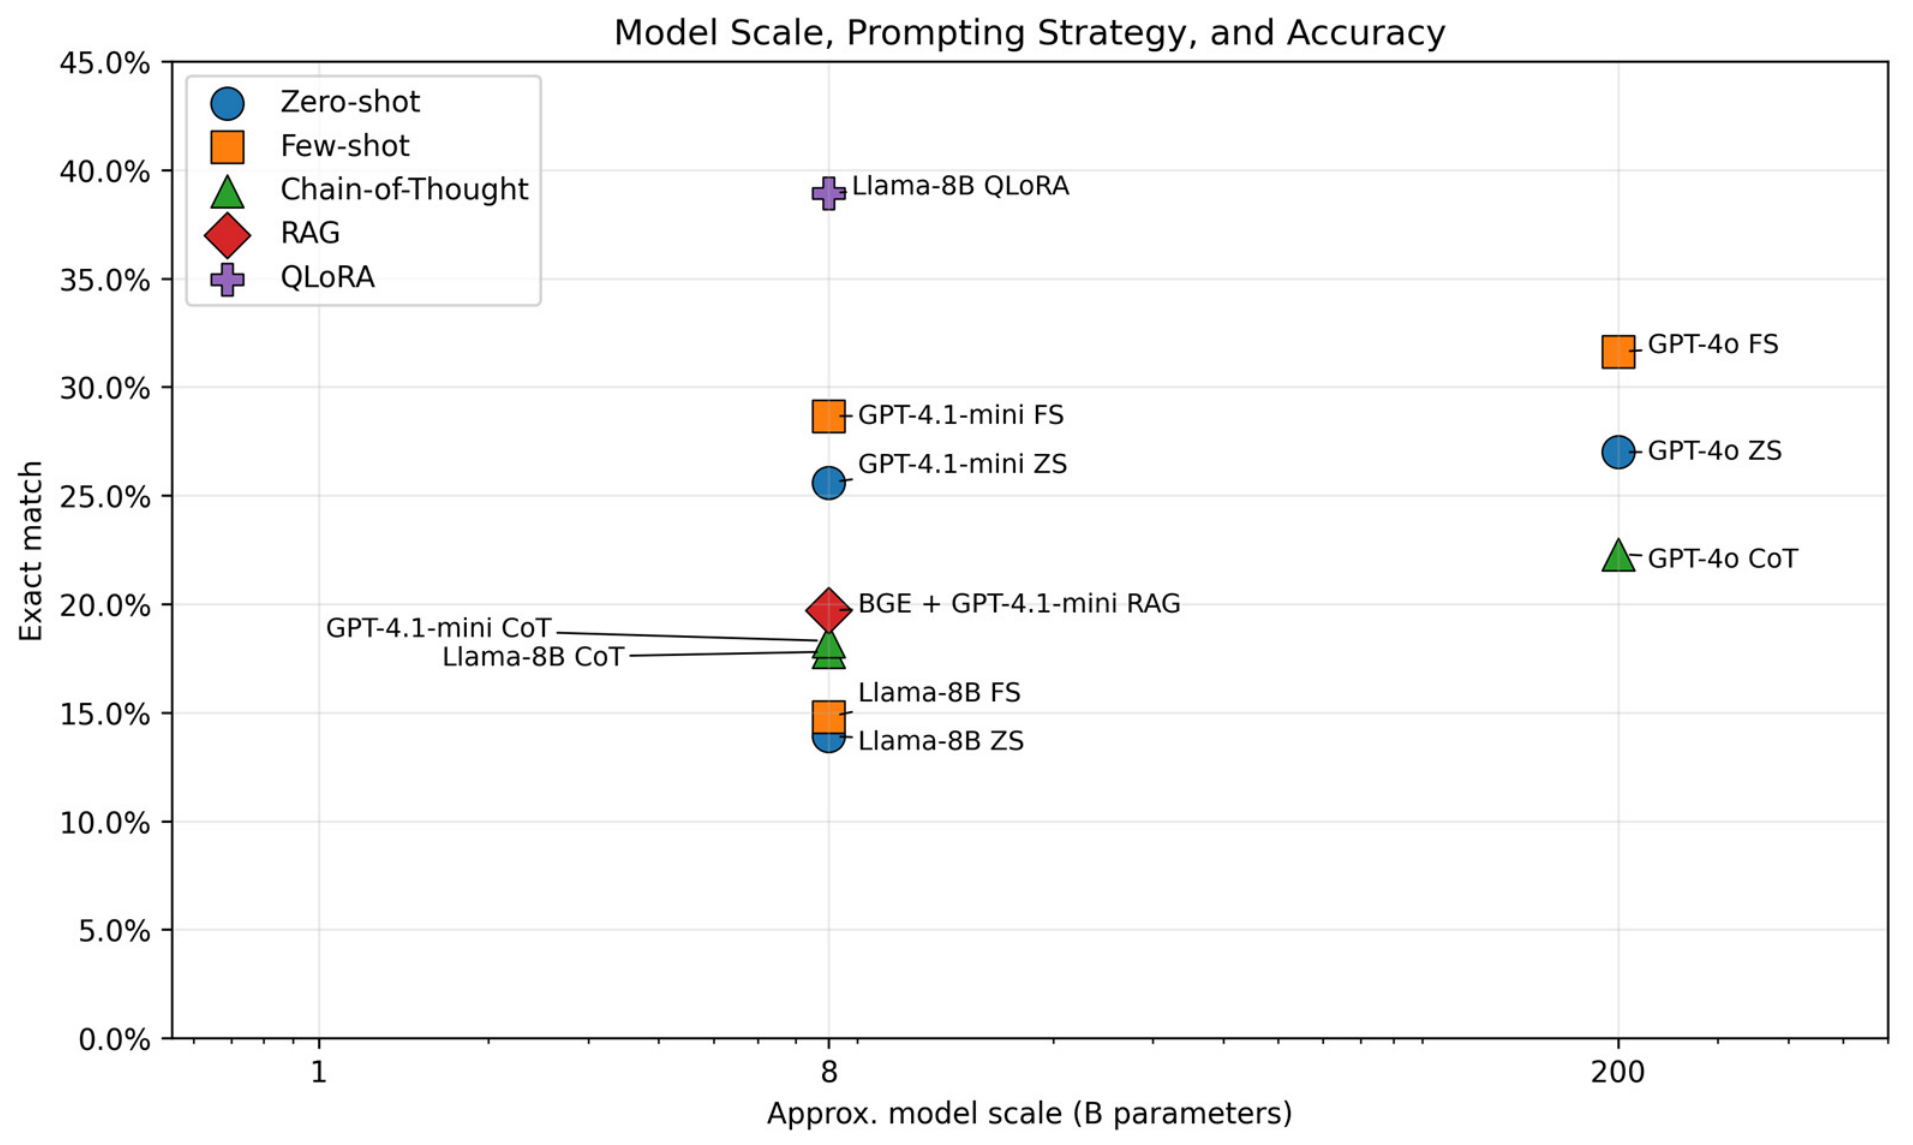
| O1 | GPT-4o | Zero-shot | 27.02 | 33.30 | 33.30 | 35.05 |
| O2 | GPT-4o | Few-shot | 31.62 | 38.94 | 38.94 | 41.10 |
| O3 | GPT-4.1-mini | Zero-shot | 25.71 | 27.09 | 33.50 | 35.94 |
| O4 | GPT-4.1-mini | Few-shot | 28.66 | 36.89 | 36.89 | 39.48 |
| O5 | Llama 3.1 8B | Zero-shot | 13.92 | 14.81 | 19.47 | 20.18 |
| O6 | Llama 3.1 8B | Few-shot | 17.83 | 18.80 | 24.61 | 25.66 |
| O10 | Llama 3.1 8B (QLoRA) | Fine-tuned | 38.94 | 41.42 | 47.90 | 51.59 |
| O11/b | GPT-4.1-mini CoT | t = 0.7/t = 0.0 | 18.93/19.44 | 20.27/20.76 | 26.48/26.87 | 27.69/28.10 |
| O12/b | GPT-4o CoT | t = 0.7/t = 0.0 | 22.51/25.57 | 23.89/33.54 | 30.91/37.21 | 32.33/38.92 |
| O13 | Llama 3.1 8B CoT | t = 0.7 | 6.22 | 6.69 | 11.72 | 12.24 |
| RAG1 | BGE + GPT-4.1-mini | RAG | 19.71 | 20.53 | 28.75 | 29.55 |
| ID | Retriever | Entity Repr. | Hit@1, % | Hit@3, % | Hit@5, % | Hit@10, % | MRR | Alias H@1, % |
|---|---|---|---|---|---|---|---|---|
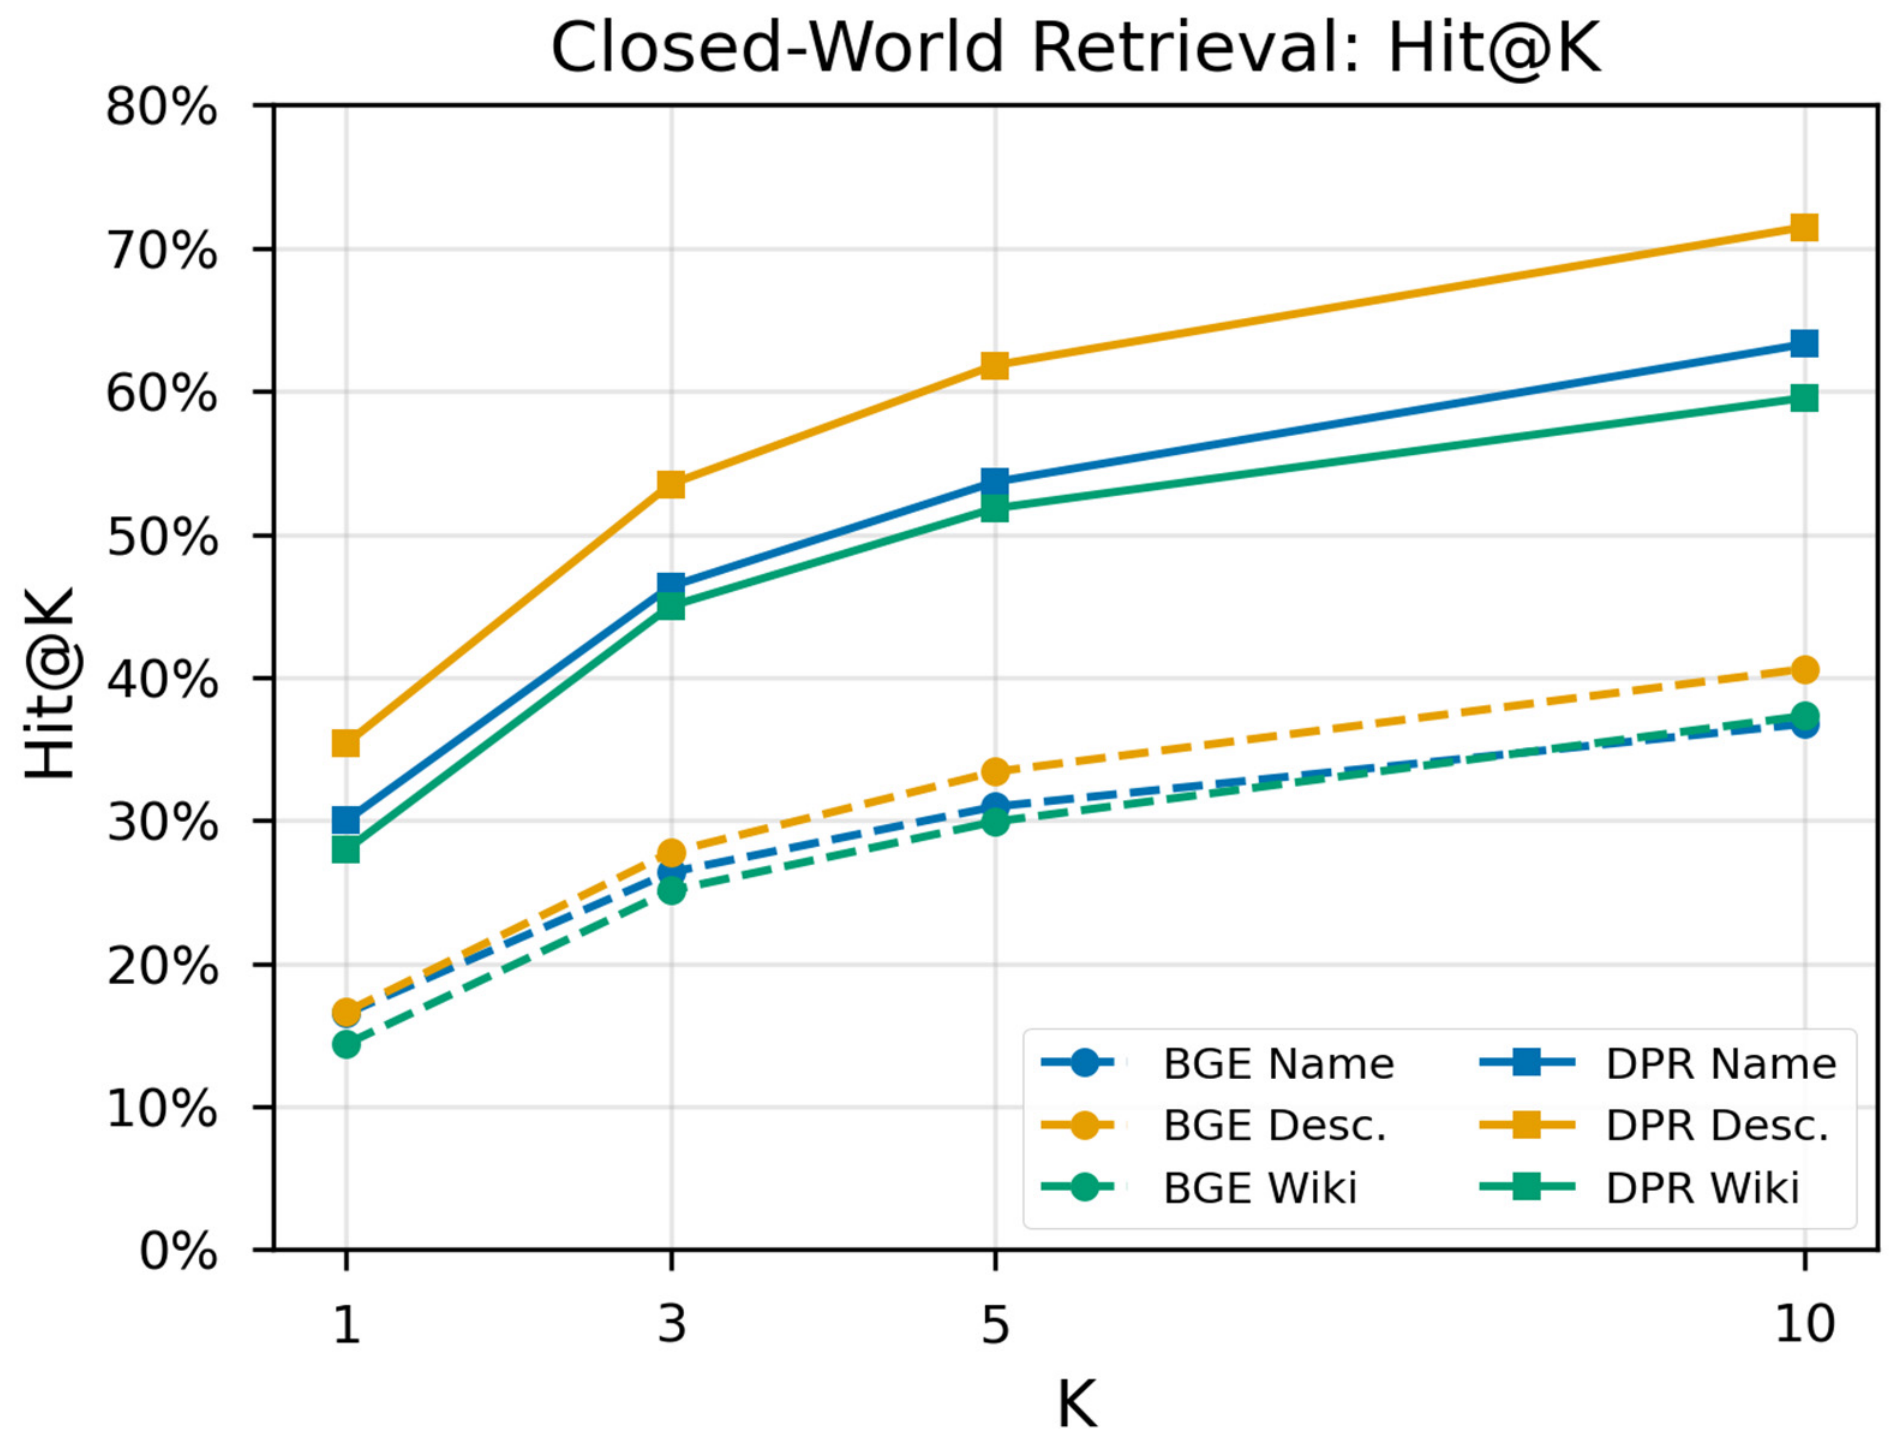
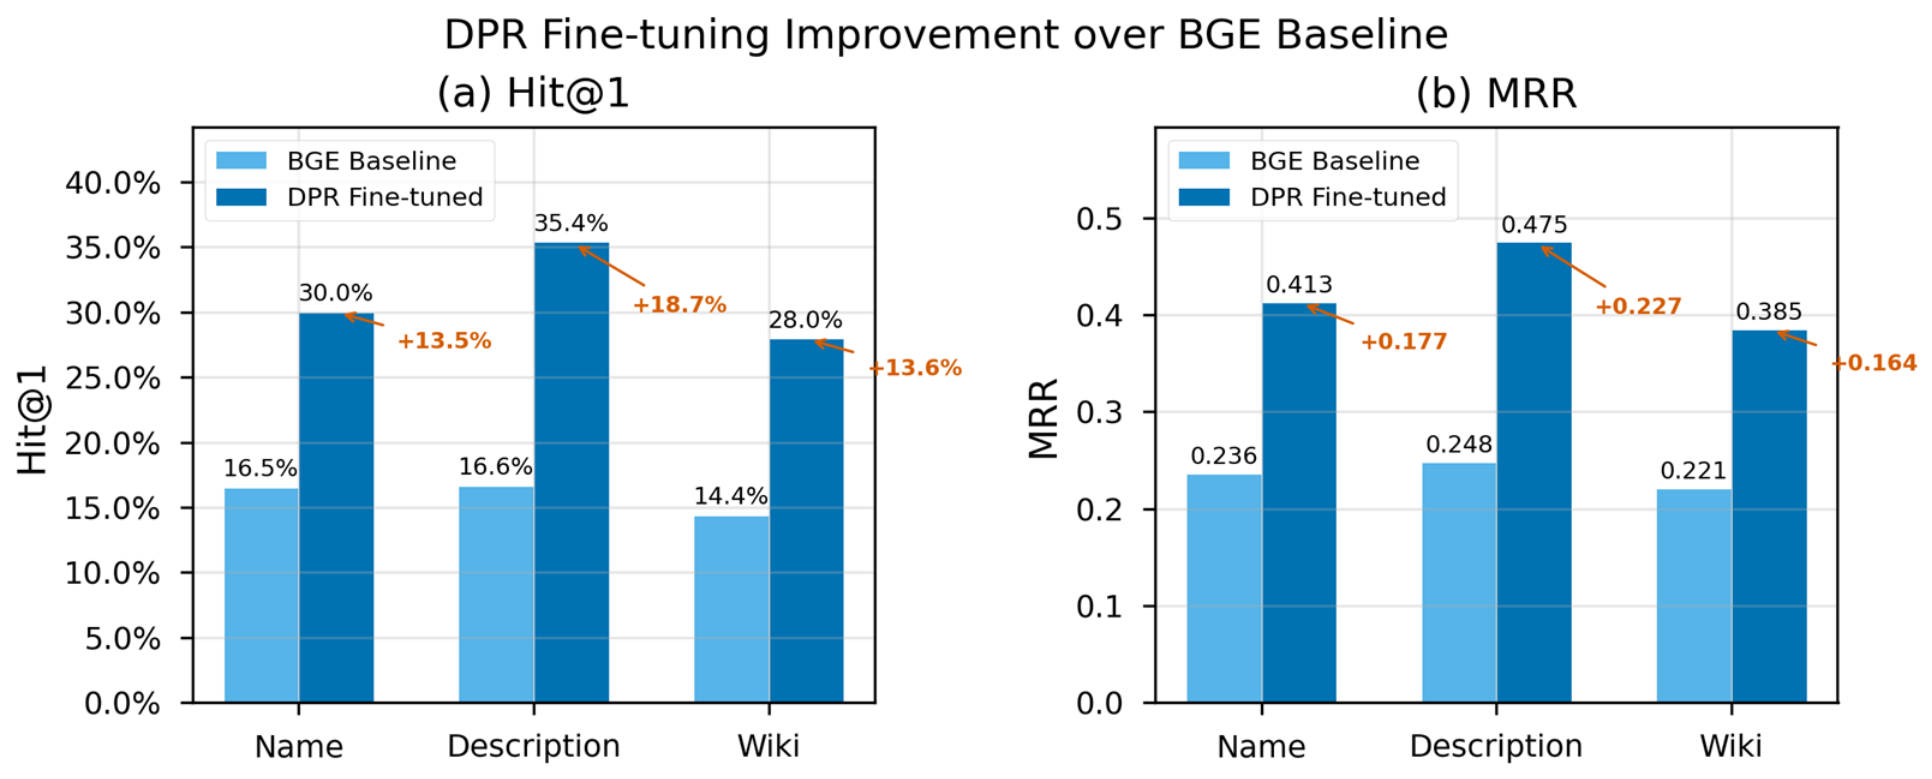
| C1 | BGE (off-the-shelf) | Name | 16.51 | 26.38 | 30.97 | 36.76 | 0.2362 | 22.08 |
| C2 | BGE (off-the-shelf) | Description | 16.64 | 27.78 | 33.41 | 40.60 | 0.2480 | 21.78 |
| C3 | BGE (off-the-shelf) | Wiki | 14.38 | 25.10 | 29.92 | 37.32 | 0.2211 | 19.32 |
| C4 | DPR (fine-tuned) | Name | 30.00 | 46.36 | 53.66 | 63.31 | 0.4131 | 37.10 |
| C5 | DPR (fine-tuned) | Description | 35.38 | 53.51 | 61.82 | 71.49 | 0.4751 | 42.80 |
| C6 | DPR (fine-tuned) | Wiki | 27.95 | 44.98 | 51.82 | 59.55 | 0.3851 | 34.38 |
| Rank | System | Paradigm | Alias-Level Score, % |
|---|---|---|---|
| 1 | C5 (DPR + Description) | Closed | 42.80 |
| 2 | O10 (QLoRA Llama 8B) | Open | 41.42 |
| 3 | O2 (GPT-4o FS) | Open | 38.94 |
| 4 | C4 (DPR + Name) | Closed | 37.10 |
| 5 | O4 (GPT-4.1-mini FS) | Open | 36.89 |
| 6 | C6 (DPR + Wiki) | Closed | 34.38 |
| 7 | O1 (GPT-4o ZS) | Open | 33.30 |
| 8 | O3 (GPT-4.1-mini ZS) | Open | 27.09 |
| Entity Type | n | O1 (GPT-4o ZS) | O2 (GPT-4o FS) | O5 (Llama 8B ZS) | C1 (BGE Name) | C2 (BGE Desc) |
|---|---|---|---|---|---|---|
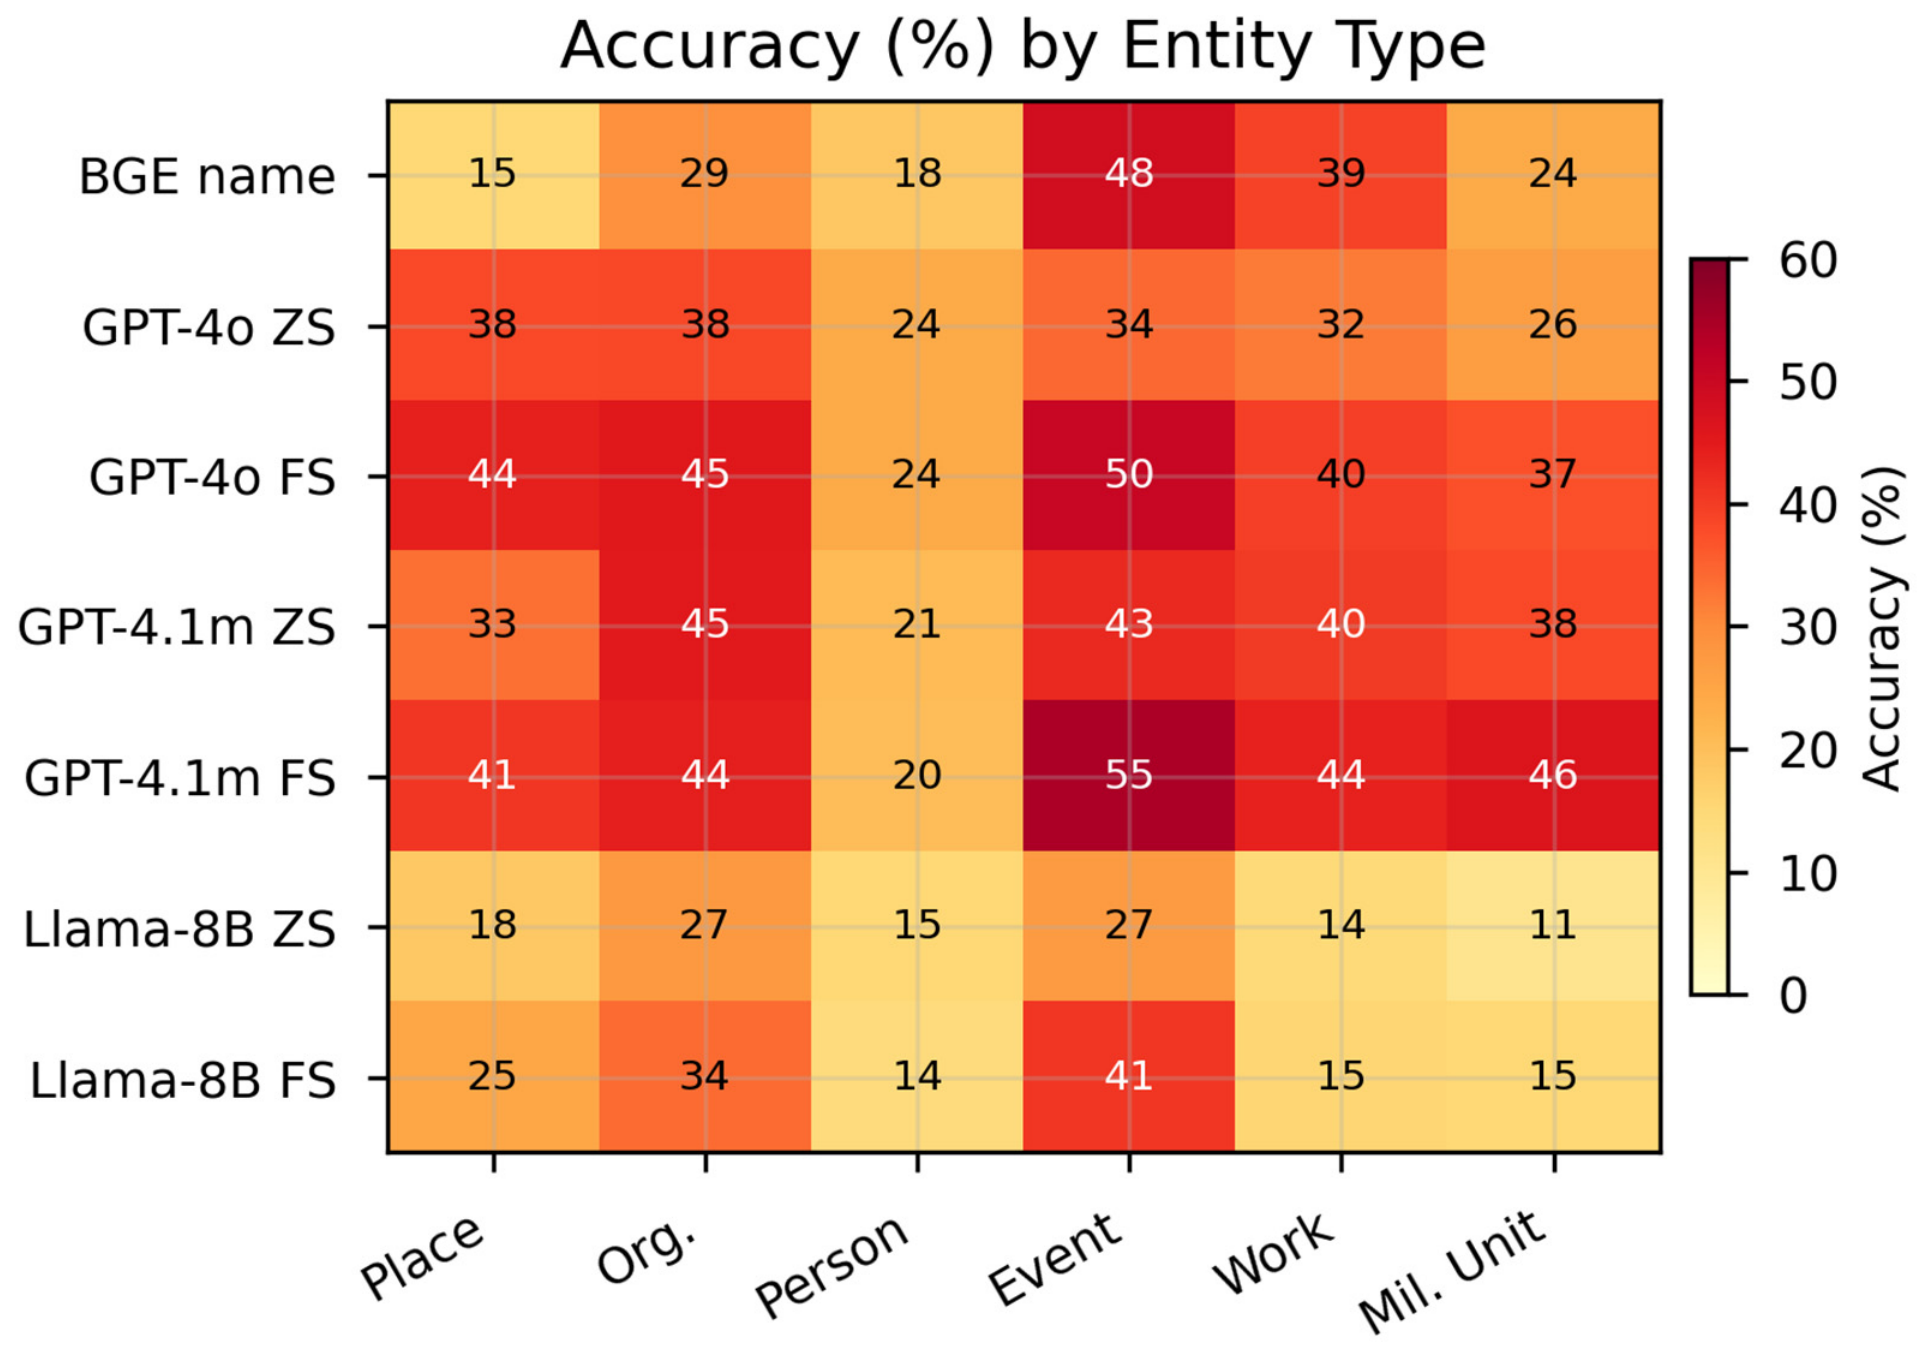
| Place | 2076 | 38.15 | 43.88 | 18.16 | 14.88 | 15.99 |
| Organization | 1152 | 38.28 | 45.31 | 27.34 | 29.17 | 27.17 |
| Person | 698 | 23.82 | 24.07 | 14.90 | 18.34 | 18.62 |
| Event | 273 | 34.43 | 50.18 | 27.11 | 48.35 | 47.25 |
| Work | 215 | 32.09 | 39.53 | 14.42 | 39.07 | 36.74 |
| Military Unit | 121 | 26.45 | 37.19 | 10.74 | 23.97 | 31.40 |
| Other | 98 | 30.61 | 36.73 | 21.43 | 33.67 | 25.51 |
| Error Type | O1 | O2 | O3 | O4 | O5 | O6 |
|---|---|---|---|---|---|---|
| Same-type, unrelated | 43.0 | 42.0 | 43.5 | 45.0 | 52.0 | 46.0 |
| Wrong type | 28.5 | 27.5 | 29.5 | 22.5 | 31.0 | 35.0 |
| Same-type, related | 24.5 | 25.5 | 22.5 | 24.0 | 13.5 | 17.0 |
| Partial match | 3.5 | 4.0 | 3.0 | 6.0 | 2.5 | 1.5 |
| Empty/hallucination | 0.5 | 1.0 | 1.5 | 2.5 | 1.0 | 0.0 |
| # | Claim | Experimental Results |
|---|---|---|
| 1 | Fine-tuning is the most impactful intervention | QLoRA fine-tuning of Llama 3.1 8B raises exact match from 13.92% (O5, zero-shot) to 38.94% (O10), a 2.80× improvement. DPR fine-tuning of BGE raises Hit@1 from 16.64% (C2) to 35.38% (C5), a 2.13× improvement. Both gains are achieved despite zero entity overlap between training and test sets. |
| 2 | QLoRA fine-tuning yields the overall best performance | O10 achieves 38.94% exact match (51.59% Jaccard), surpassing GPT-4o few-shot (31.62% exact, 41.10% Jaccard) by 7.32 pp on exact match and 10.49 pp on Jaccard. This result uses only 6.5 M trainable parameters on top of an 8B-parameter base. |
| 3 | Chain-of-thought does not improve performance | CoT reduces GPT-4.1-mini from 25.71% (zero-shot exact) to 18.93% and Llama 3.1 8B from 13.92% to 6.22%. For GPT-4o, lowering temperature recovers parity with zero-shot but does not exceed it. |
| 4 | Few-shot prompting consistently helps | Adding five demonstrations improves GPT-4o from 27.02% to 31.62% (+4.60 pp), GPT-4.1-mini from 25.71% to 28.66% (+2.95 pp), and Llama 3.1 8B from 13.92% to 17.83% (+3.91 pp). |
| 5 | Entity descriptions are the best retrieval representation | C5 (DPR + description) outperforms C4 (DPR + name) by 5.38 pp on Hit@1 (35.38% vs. 30.00%) and C6 (DPR + wiki) by 7.43 pp (35.38% vs. 27.95%). The same pattern appears with off-the-shelf BGE. |
| 6 | RAG underperforms direct LLM inference | RAG1 reaches 19.71% exact match, which is 5.99 pp below GPT-4.1-mini zero-shot (25.71%) and 8.95 pp below GPT-4.1-mini few-shot (28.66%). The retrieval bottleneck limits the reranking stage. |
| 7 | Model scale matters in the zero-shot regime | GPT-4o zero-shot reaches 27.02% exact match, outperforming Llama 3.1 8B zero-shot at 13.92% by 13.10 pp (McNemar chi-squared = 432.28, p < 0.001). |
| 8 | Retriever Hit@10 reveals strong latent signal | C5 places the gold entity in the top 10 for 71.49% of queries, indicating that DPR shortlists contain useful candidates and can support stronger future reranking approaches. |
| Comparison | Acc A (%) | Acc B (%) | McNemar χ2 | A-Only | B-Only |
|---|---|---|---|---|---|
| O1 vs. O2 (ZS vs. FS, GPT-4o) | 35.06 | 41.11 | 149.69 | 120 | 400 |
| O3 vs. O4 (ZS vs. FS, mini) | 35.16 | 38.72 | 36.18 | 150 | 275 |
| O1 vs. O5 (GPT-4o vs. Llama 8B) | 35.06 | 20.19 | 432.28 | 892 | 203 |
| O1 vs. C2 (Open vs. Closed) | 35.06 | 22.58 | 181.93 | 1204 | 626 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Share and Cite
Aperstein, Y.; Moran, E.; Apartsin, A. IRC-Bench: Recognizing Entities from Contextual Cues in First-Person Reminiscences. Mach. Learn. Knowl. Extr. 2026, 8, 186. https://doi.org/10.3390/make8070186
Aperstein Y, Moran E, Apartsin A. IRC-Bench: Recognizing Entities from Contextual Cues in First-Person Reminiscences. Machine Learning and Knowledge Extraction. 2026; 8(7):186. https://doi.org/10.3390/make8070186
Chicago/Turabian StyleAperstein, Yehudit, Eden Moran, and Alexander Apartsin. 2026. "IRC-Bench: Recognizing Entities from Contextual Cues in First-Person Reminiscences" Machine Learning and Knowledge Extraction 8, no. 7: 186. https://doi.org/10.3390/make8070186
APA StyleAperstein, Y., Moran, E., & Apartsin, A. (2026). IRC-Bench: Recognizing Entities from Contextual Cues in First-Person Reminiscences. Machine Learning and Knowledge Extraction, 8(7), 186. https://doi.org/10.3390/make8070186