
FAdamWav: A Fractional Wavelet Gradient Optimizer for Neural Networks

 ,
 and
Abstract
1. Introduction
- 1.
- ;
- 2.
- ;
- 3.
- ;
- 4.
- ;
- 5.
- There exists so that , a scaling function, is an orthonormal basis for .
- Introduces additional execution time due to the discrete wavelet transform, which has a linear computational complexity;
- Saves memory for the gradients by eliminating high-frequency sub-bands in the wavelet-space;
- Calculates efficiently the momentum and velocity in a low-dimensional wavelet-space;
- Calculates a non-perfect reconstruction for the gradients via the inverse parametric discrete wavelet transform. Then, the recovered approximations of gradients are used to update the neural network parameters;
- Allows to choose a parametric filter for the discrete wavelet transform to provide the best reconstruction for the gradients;
- Enhances the performance compared to its non-fractional wavelet counterparts by considering that fractional gradient optimizer includes the integer case () as special case;
- Saves gradient’s memory preserving competitive performance compared to the original case without wavelet transformation.
2. Materials and Methods
2.1. Parametric Discrete Wavelet Transform
| Algorithm 1 Parametric Discrete Wavelet Transform |
| Require: Signal array: data, Low-pass filter array of length FILTERSIZE: h, High-pass filter array of length FILTERSIZE: g, Number of wavelet decomposition levels: LEVELS |
| 1: procedure PDWT(data, data.length: n, FILTERSIZE, h, g, LEVELS) |
| 2: for to LEVELS do |
| 3: DWTlevel(data, data.length ≫ level, FILTERSIZE, h, g) |
| 4: end for |
| 5: end procedure |
| 6: procedure DWTlevel(data, data.length:n, FILTERSIZE, h, g) |
| 7: if then |
| 8: , |
| 9: tmp ← new array of size n ▹ Temporal array for wavelet coefficients |
| 10: for to step 2 do |
| 11: |
| 12: |
| 13: for to FILTERSIZE do |
| 14: ▹ Low frequency coefficients |
| 15: ▹ High frequency coefficients |
| 16: end for |
| 17: |
| 18: end for |
| 19: data ← tmp ▹ Updated wavelet coefficients |
| 20: end if |
| 21: end procedure |
| Algorithm 2 Parametric Inverse Discrete Wavelet Transform |
| Require: Signal array: data, Low-pass filter array of length FILTERSIZE: Ih, High-pass filter array of length FILTERSIZE: Ig, Number of wavelet decomposition levels: LEVELS |
| 1: Ih, Ig ← InverseFilters(FILTERSIZE, h, g) |
| 2: procedure PIDWT(data, data.length: n, FILTERSIZE, Ih, Ig, LEVELS) |
| 3: for downto 0 do |
| 4: INVTWDLEVEL(data, data.length ≫ level, FILTERSIZE, h, g) |
| 5: end for |
| 6: end procedure |
| 7: procedure INVTWDLEVEL(data, data.length, FILTERSIZE, Ih, Ig) |
| 8: if then |
| 9: |
| 10: |
| 11: |
| 12: for to do |
| 13: |
| 14: for to do |
| 15: |
| 16: |
| 17: |
| 18: |
| 19: end for |
| 20: |
| 21: |
| 22: for to step 2 do |
| 23: |
| 24: |
| 25: end for |
| 26: |
| 27: end for |
| 28: |
| 29: end if |
| 30: end procedure |
| Algorithm 3 Reconstruction filters |
| 1: function InverseFilters() |
| 2: for to do |
| 3: |
| 4: |
| 5: |
| 6: end for |
| 7: return , |
| 8: end function |
2.2. Fractional Derivatives and the Backpropagation Update Formula for MLP
- When the synaptic weights are zero, that yields to the indetermination of for .
- When is rational, we let and s is even (for example and ). Then, if , complex values are generated.
| Algorithm 4 FAdamWav: Fractional Adam with Wavelet Transform |
| Require: Weight matrix W, learning rate , batch size m. Adam decay rates . Iteration T. . Scale factor . Lowpass wavelet filter h, highpass wavelet filter g, Levels k. |
| 1: Initialize |
| 2: repeat |
| 3: ▹ Fractional gradient. See Equation (34) |
| 4: ▹ Save original length. Length() |
| 5: ▹ Gradient PDWT- Analysis |
| 6: ▹ No longer used, memory reduction |
| 7: if then |
| 8: Initialize |
| 9: end if |
| 10: |
| 11: |
| 12: ▹ was set to zero. Update rule, see Equation (10) |
| 13: ▹ PIDWT - Synthesis. Back to the original length |
| 14: ▹ Bias correction |
| 15: ▹ Update weights. Original dimensions for fractional gradients. |
| 16: |
| 17: until |
| 18: return |
| Listing 1. FAdamWav Class: PyTorch Source Code |
|
1 class FAdamWav(Optimizer): 2 def step(self, closure: Callable = None): 3 … 4 for group in self.param_groups: 5 for p in group["params"]: 6 … 7 grad = p.grad 8 grad *= torch.pow(abs(grad)+ epsilon, 1-nu ) 9 grad /= torch.exp(torch.lgamma(torch.tensor( 2.0-nu ) )) 10 gr, original_lengths = pad_batch_to_pow2(grad) 11 pwt = ParametricWaveletTransform () 12 gr = pwt.PDWT(gr, len(gr)) 13 gr = gr[…, :gr.shape[−1] // 2] 14 grad = gr 15 … 16 gr = norm_grad 17 gr = duplicate_with_zeros(gr) 18 gr = pwt.PIDWT(gr, len(gr)) 19 gr = restore_original_lengths(gr, original_lengths) 20 grad = gr.squeeze(0) 21 norm_grad = grad |
3. Results
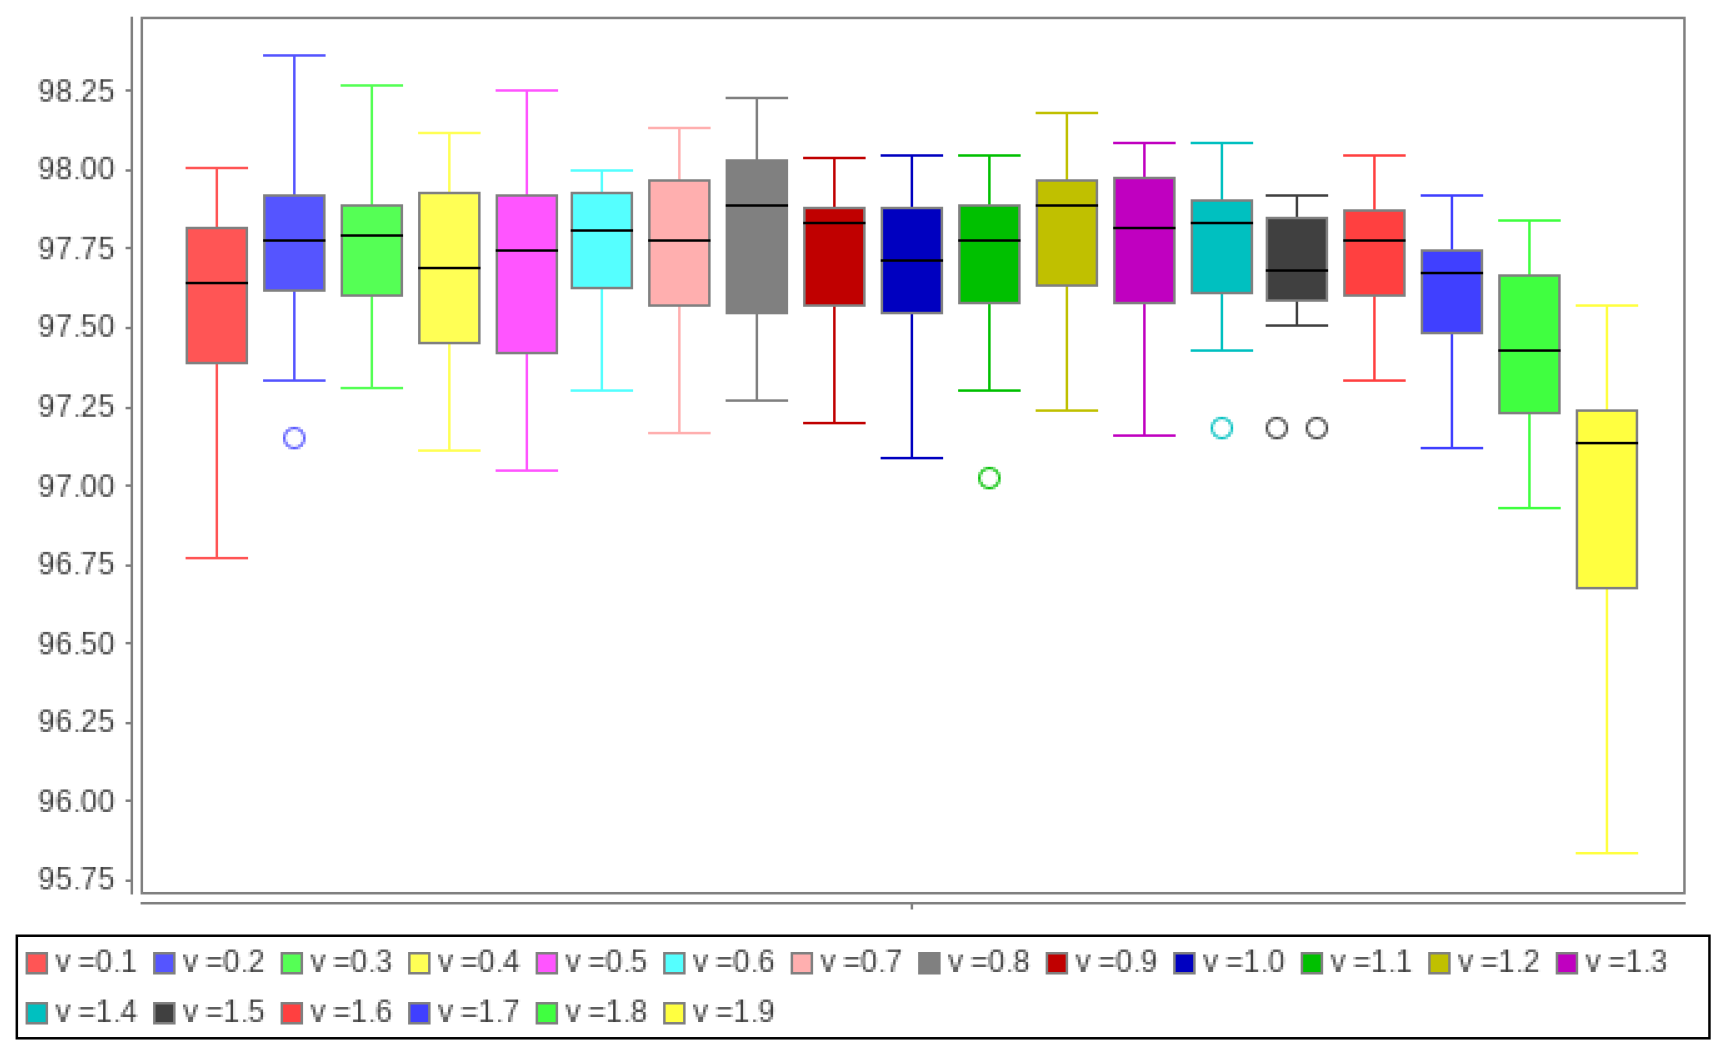
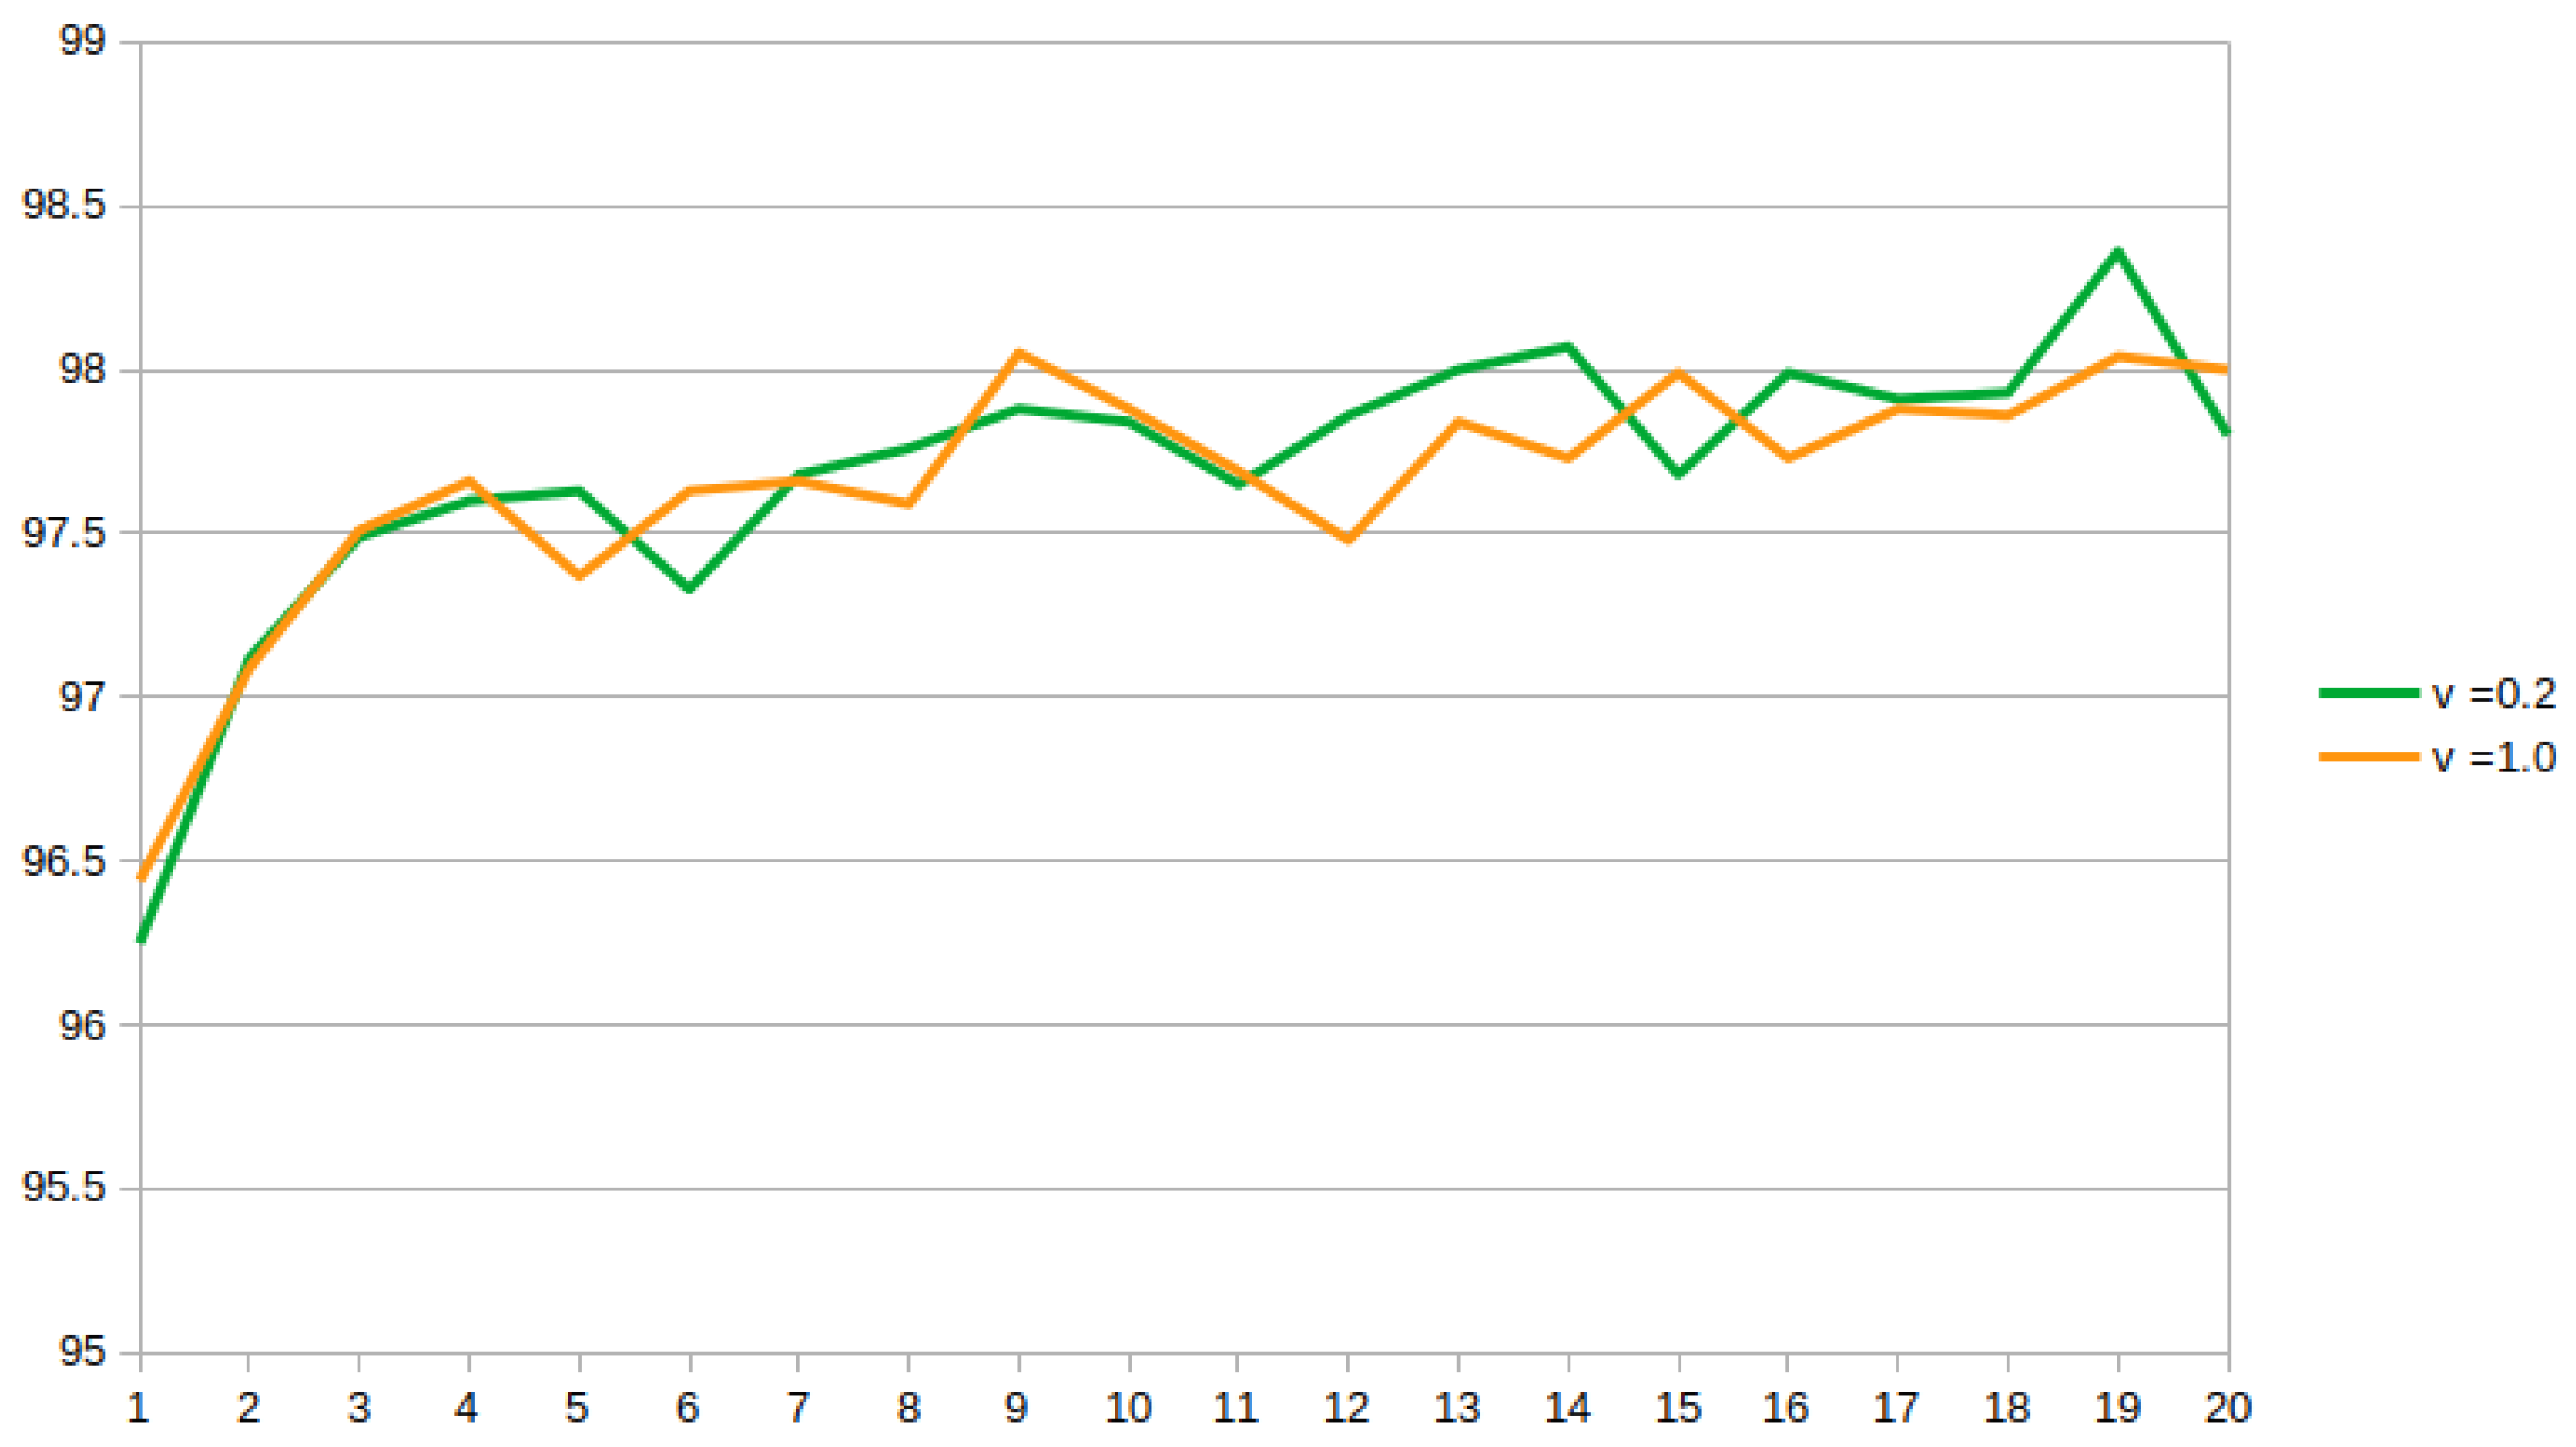
- Experiment 1. (FAdam). It explores the accuracy of a neural network with the following architecture:
- Linear(784, 64)
- ReLU()
- Linear(64, 10)
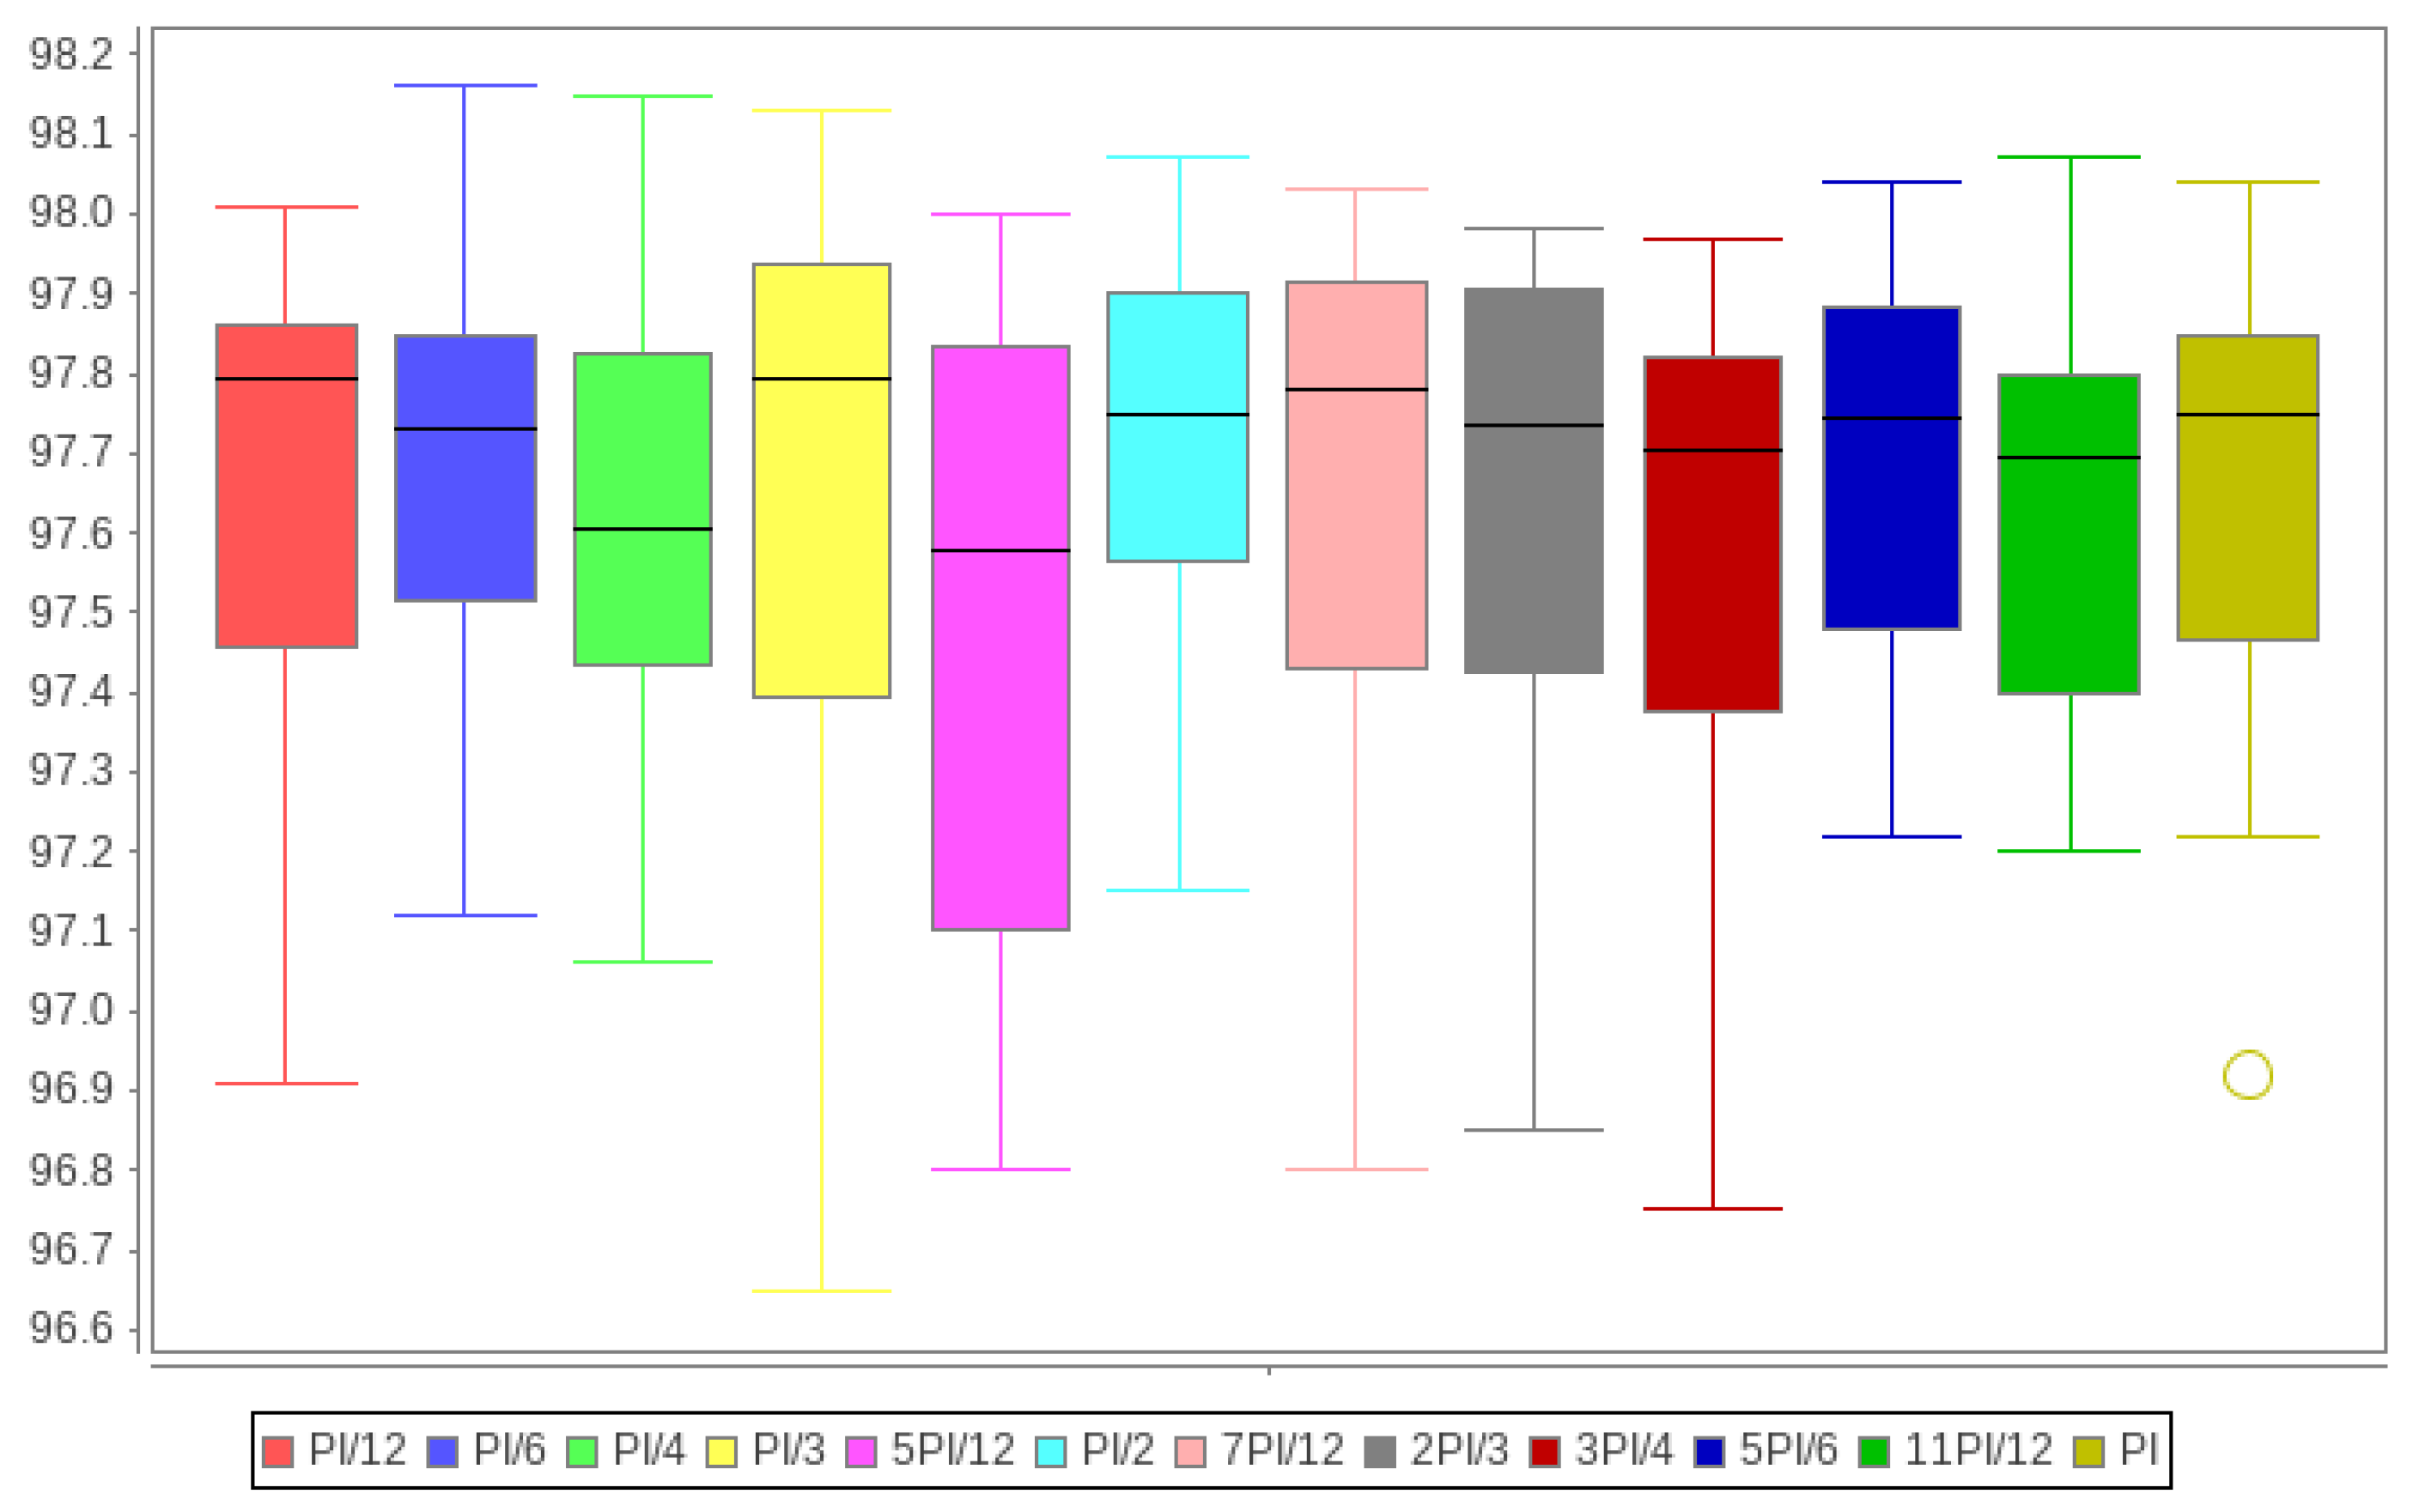
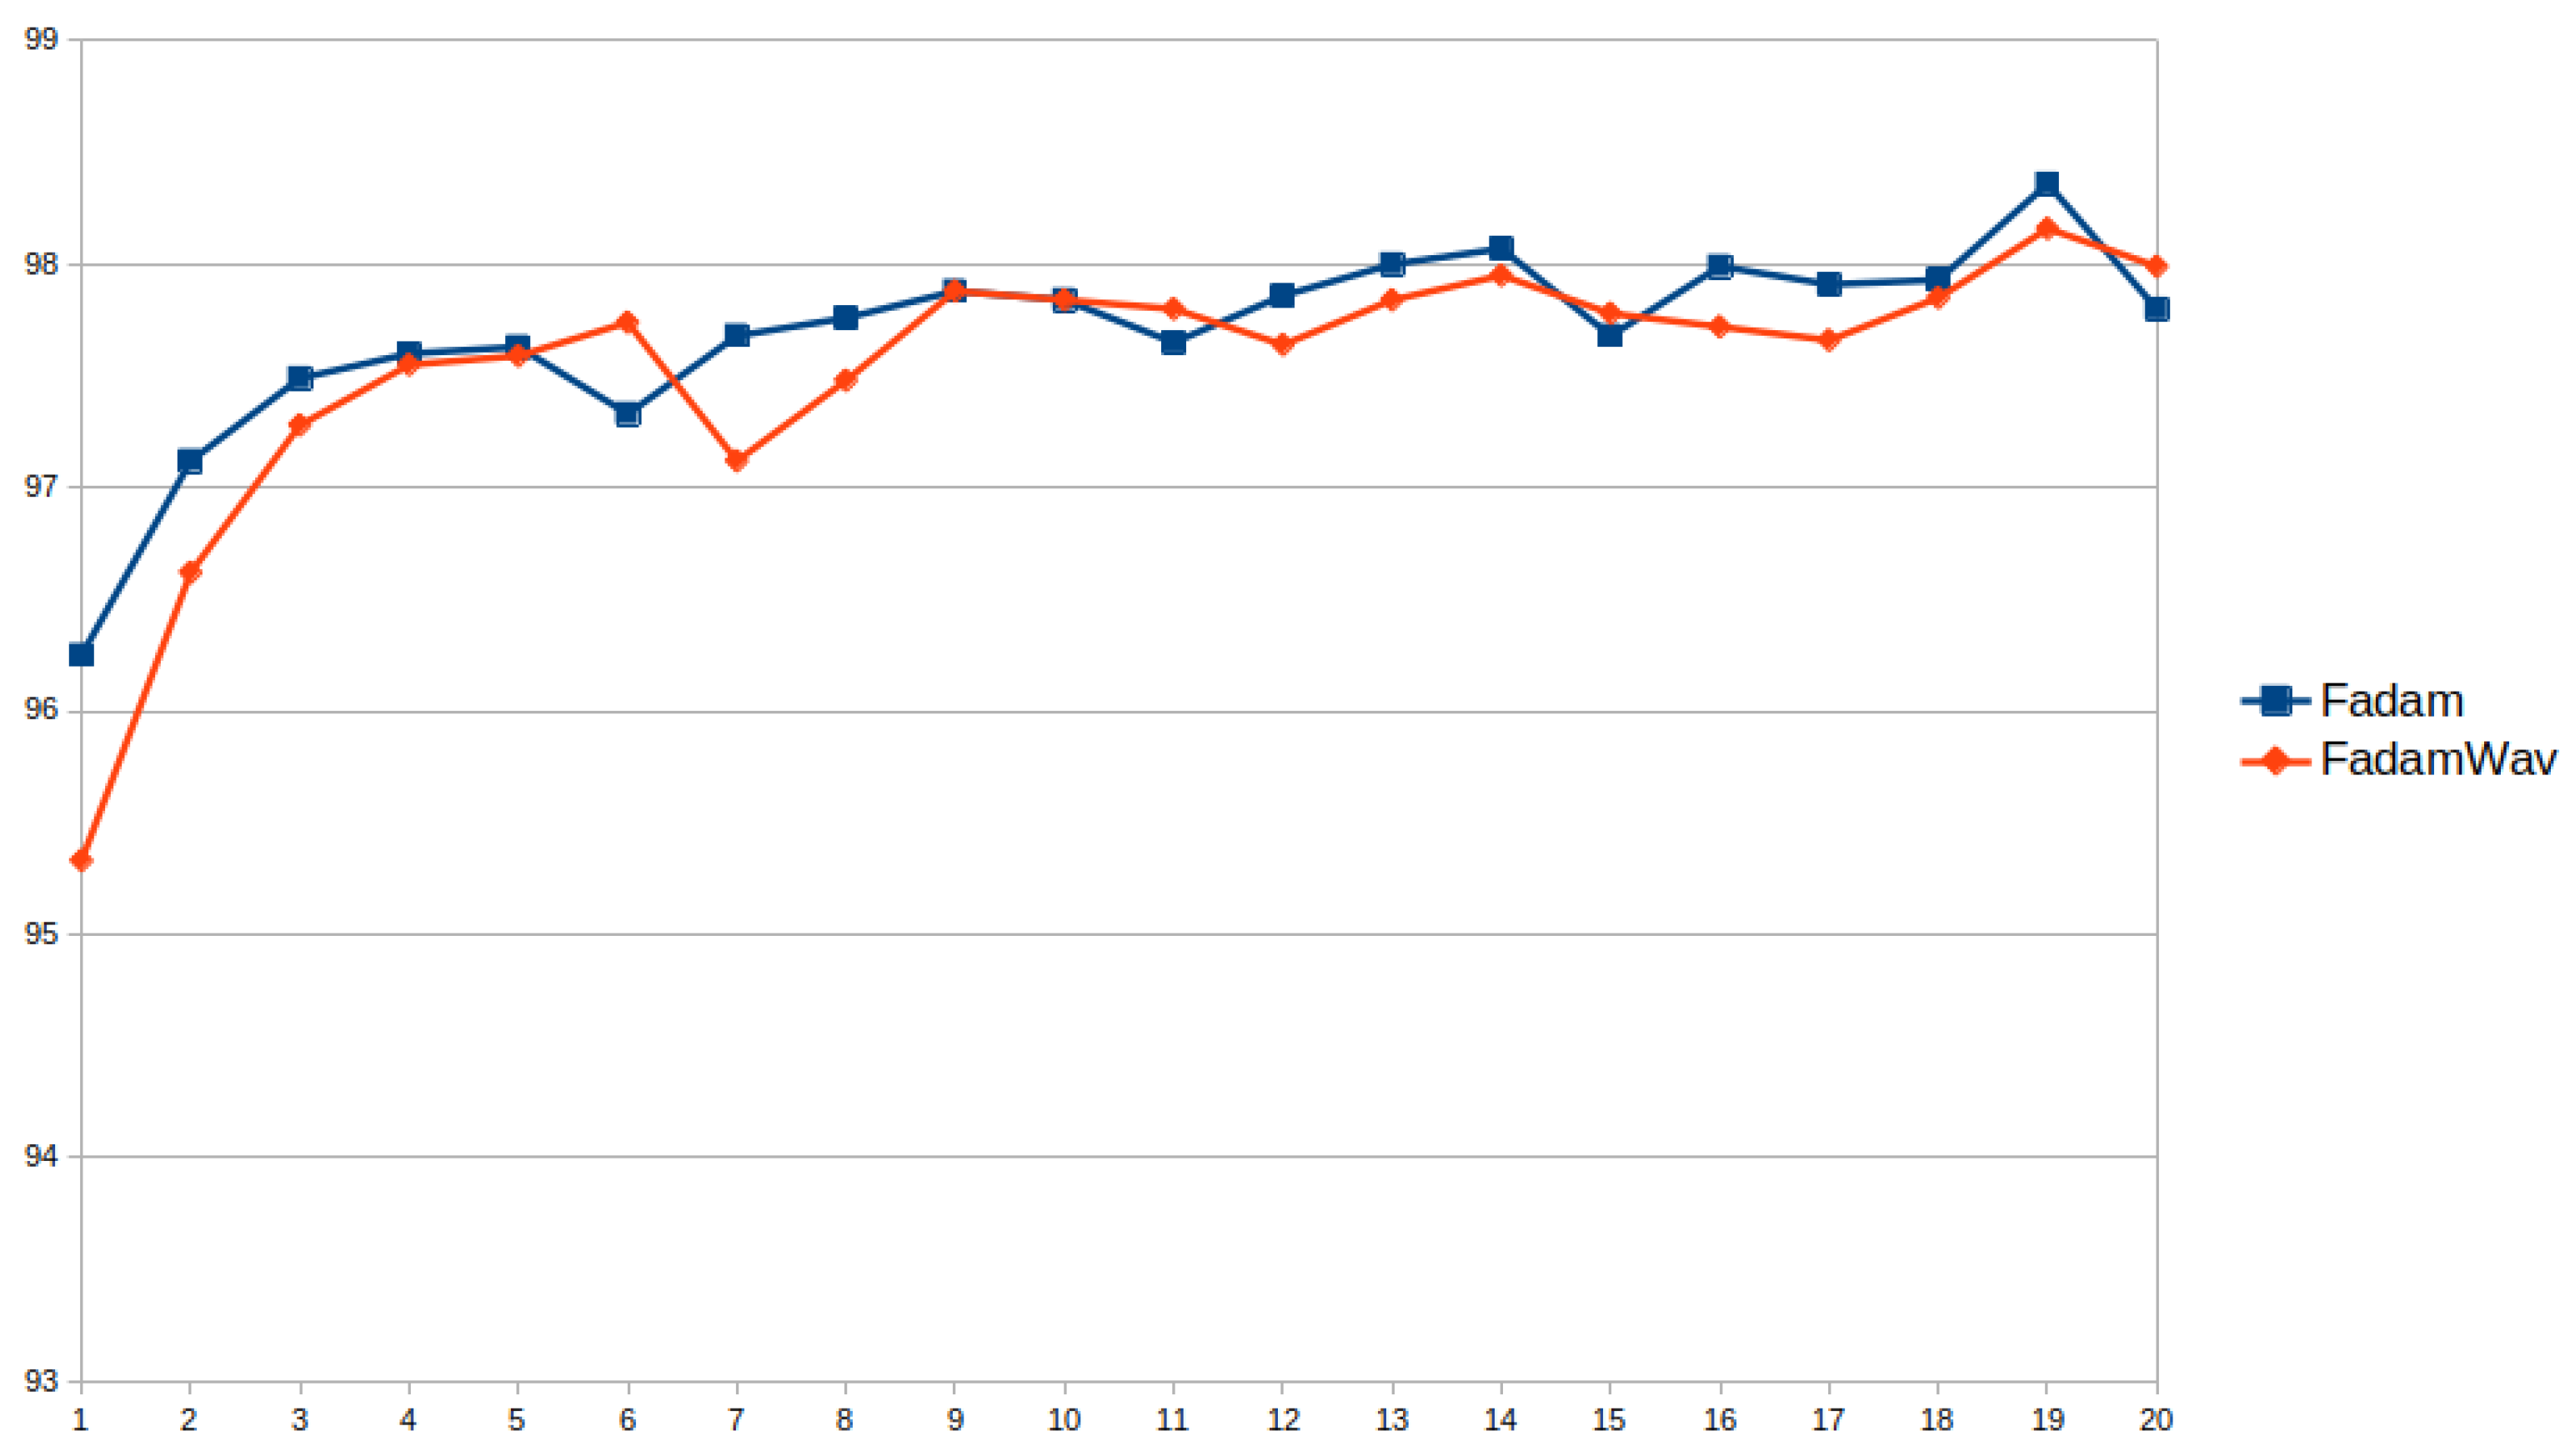
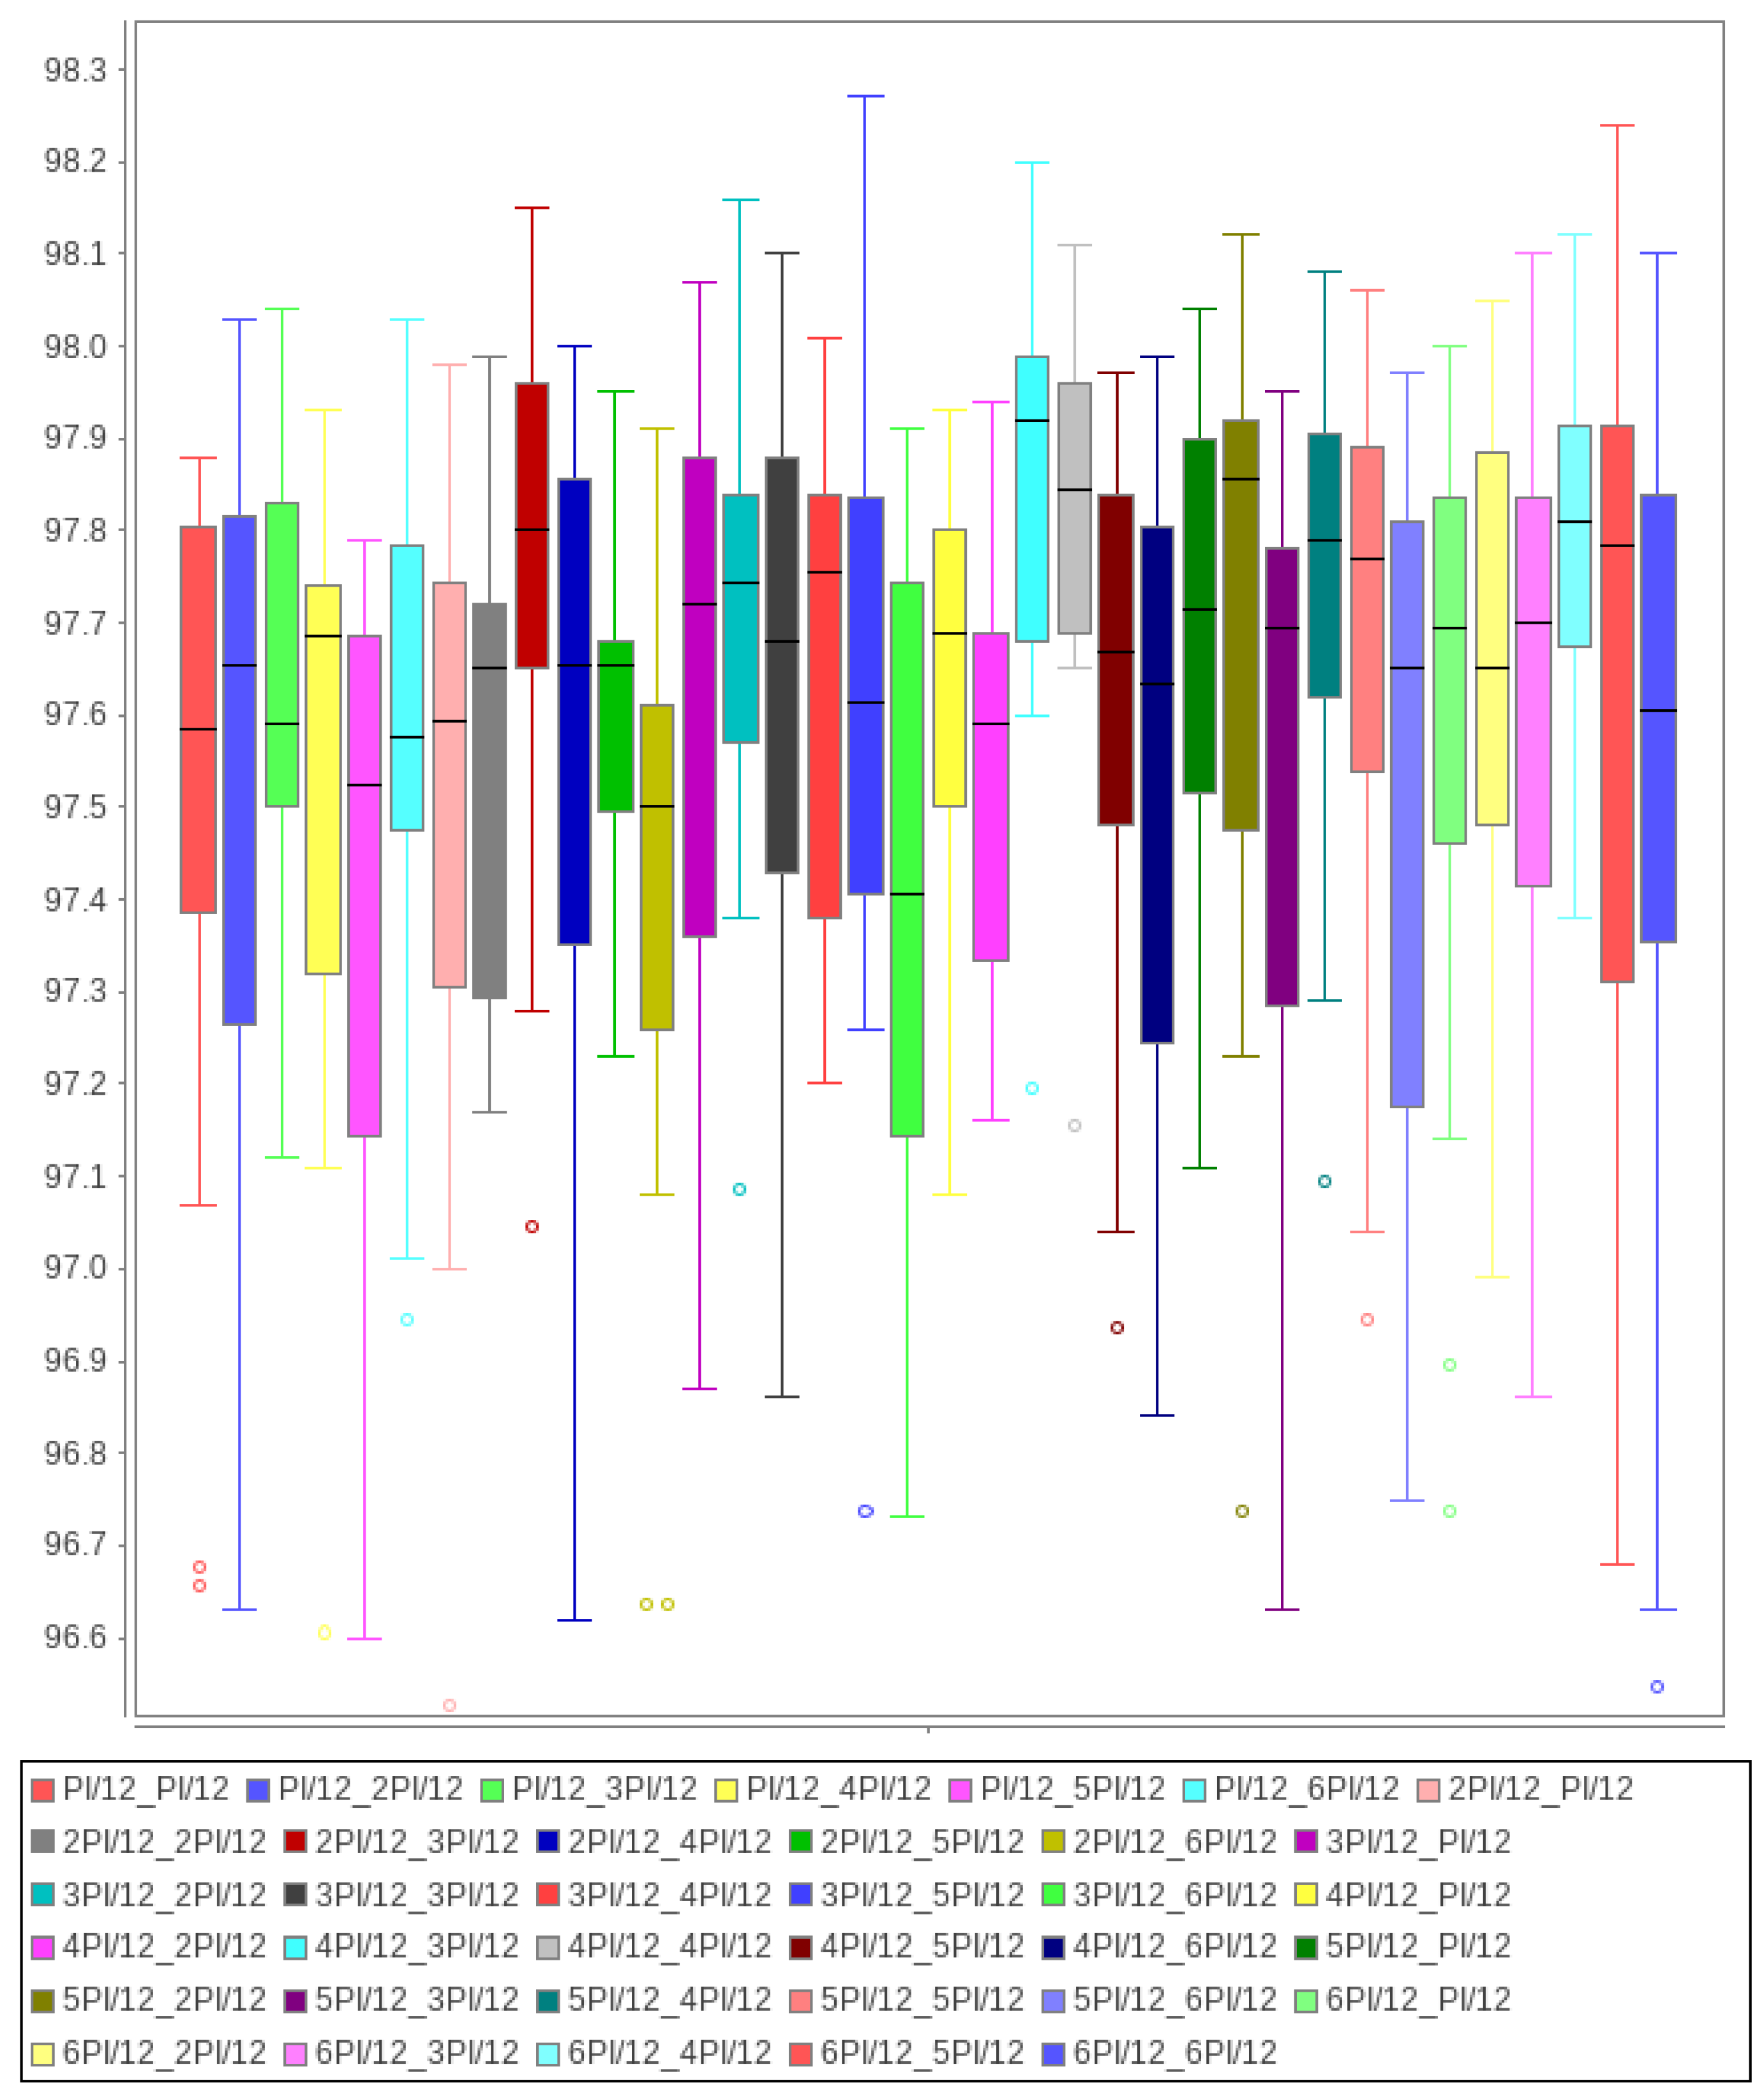
and fractional gradients on the MNIST dataset [34], without applying the parametric discrete wavelet transform. The neural network architecture is enough to match the input size of MNIST images ( pixels) and the output with 10 classes. The MNIST dataset has 60,000 images, divided into a training set of 50,000 and a test set of 10,000. - Experiment 2. (FAdamWav: Length-four filters). Given the same neural network and dataset as in Experiment 1, the second experiment applies the parametric wavelet transform to reduce the FAdam gradient memory by half by considering only the low-pass coefficients and a single transformation level. Several length-four parametric filters are tested varying the parameter for . In this case, the best -value from Experiment 1 is chosen (see below ).
- Experiment 3. (FAdamWav: Length-sixth filters). This experiment is similar to Experiment 2, but it considers length-sixth filters of Equation (20) depending on and . Each parameter independently takes on values equal to , where .
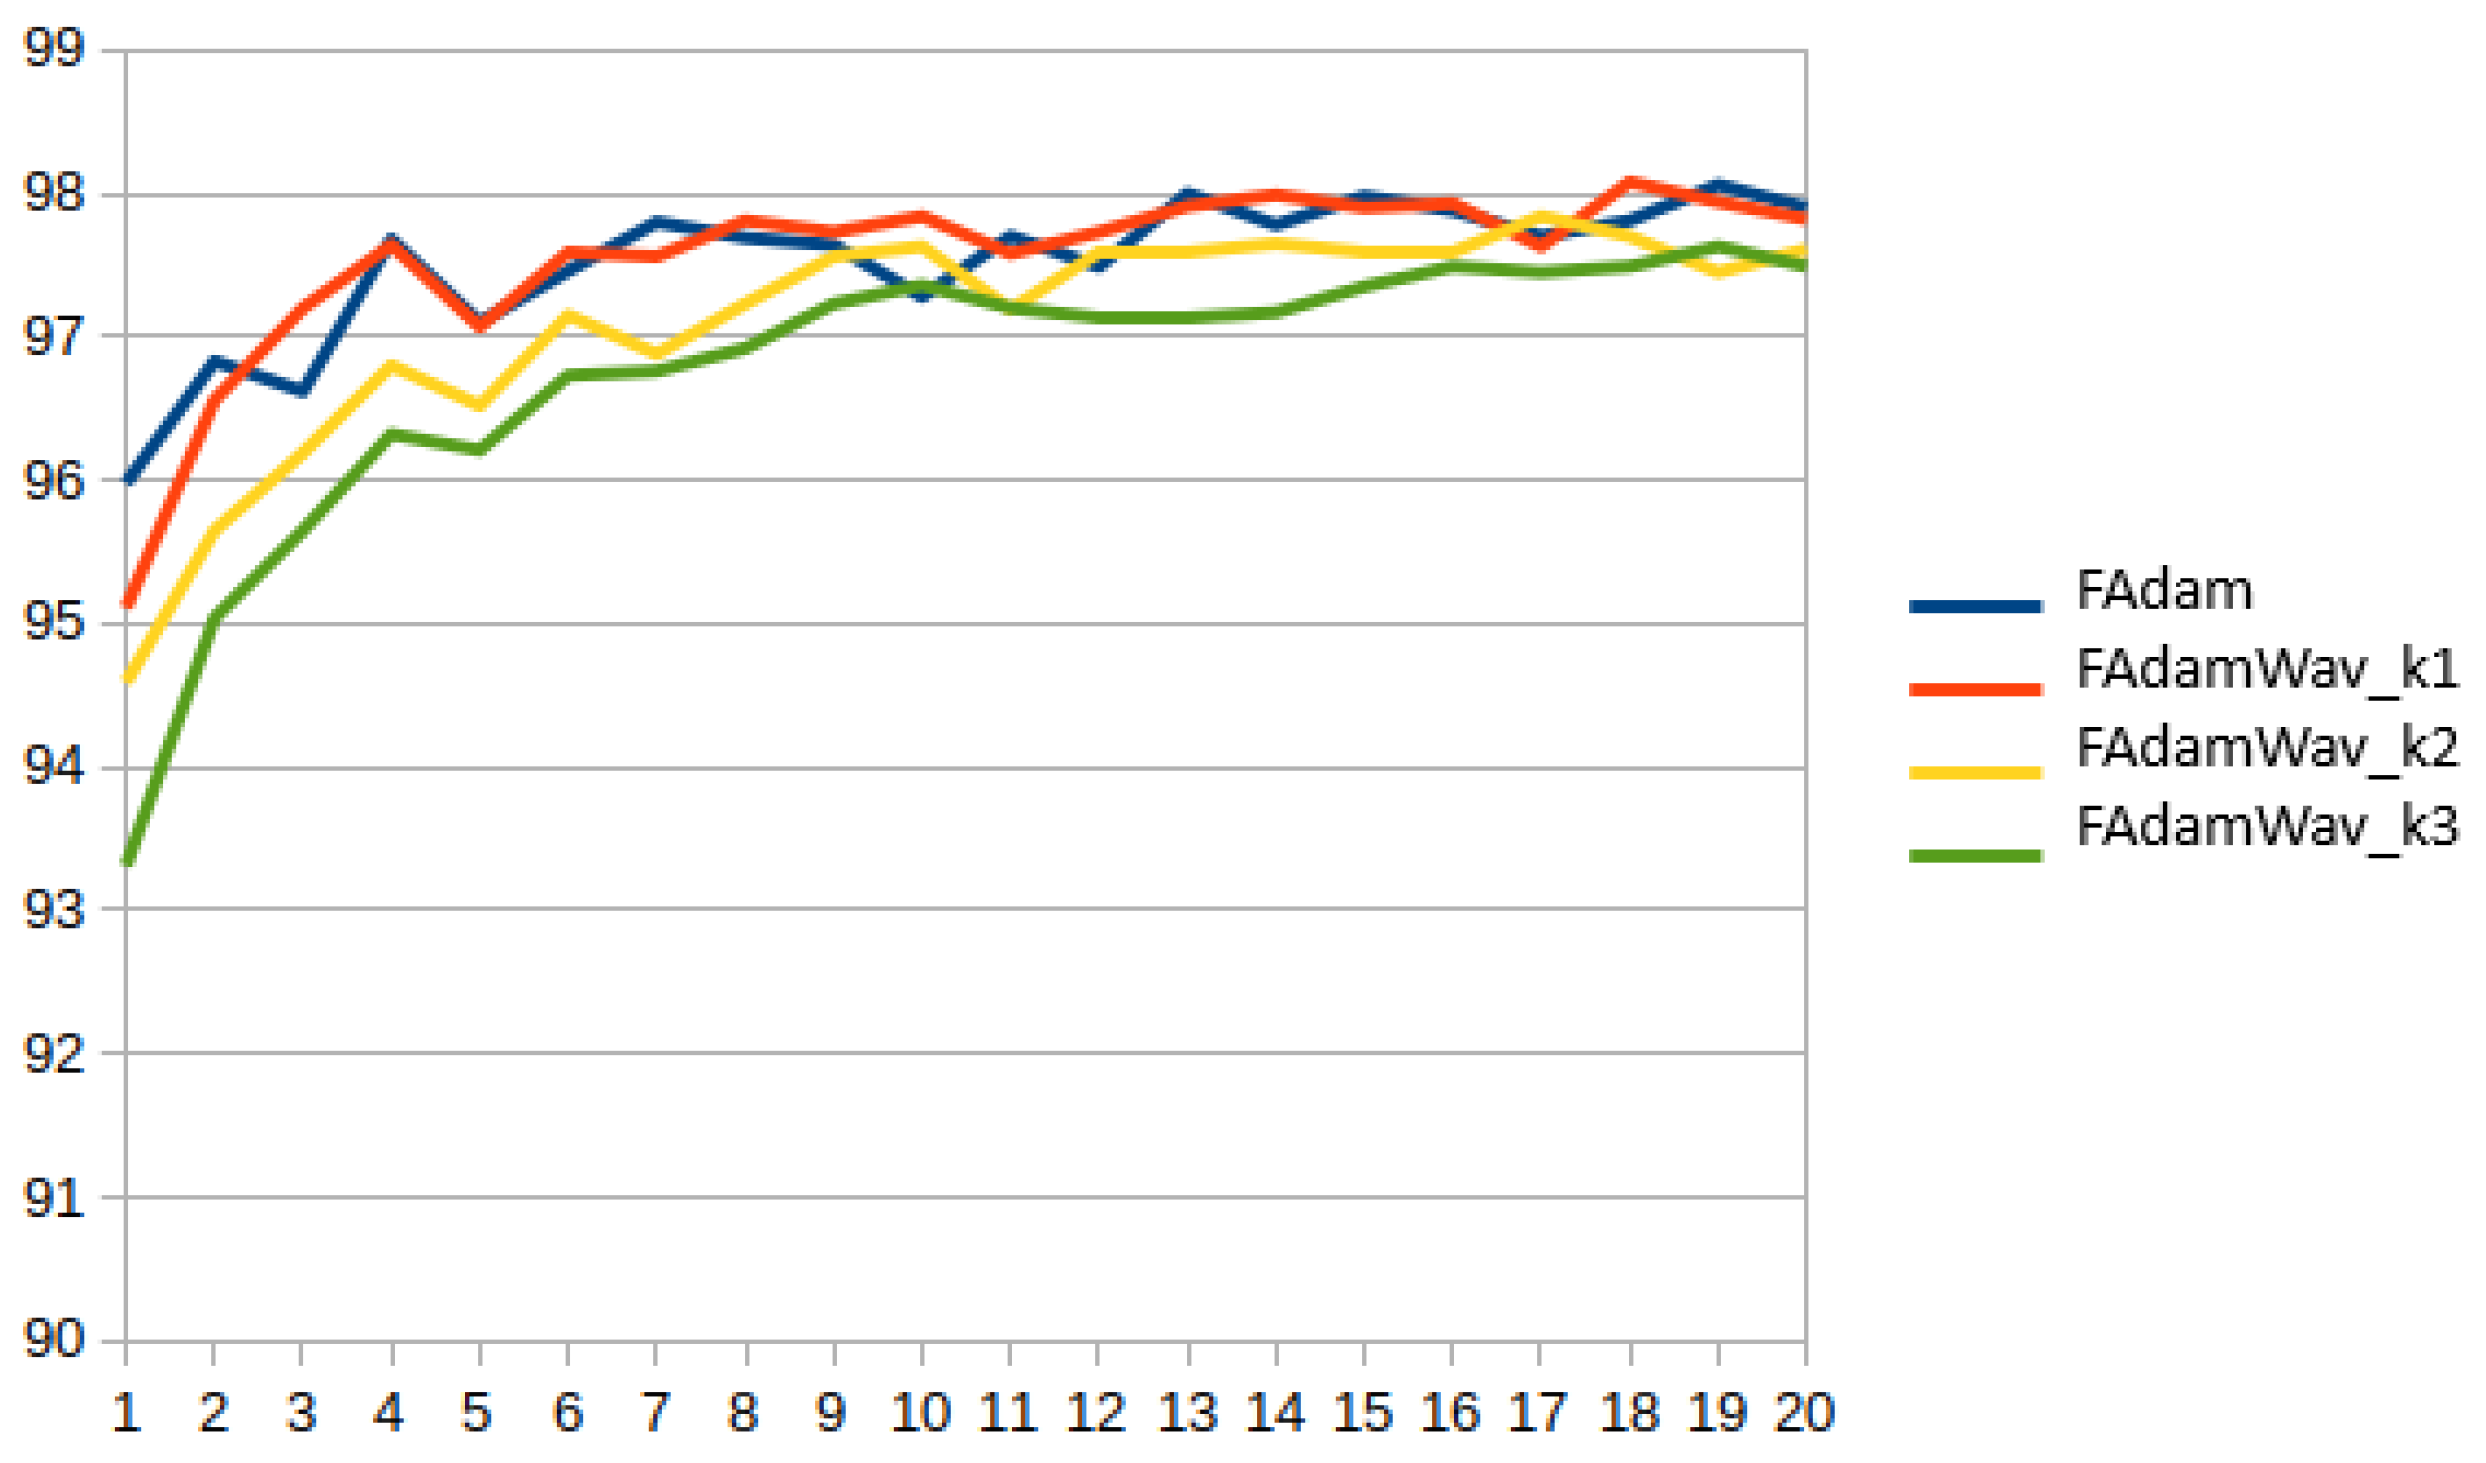
- Experiment 4. (FAdam, FAdamWav_k1, FAdamWav_k2, FAdamWav_k3). This experiment measures and compares the amount of GPU memory required for Adam and FAdamWav applying wavelet transformation levels. The execution time is also compared.
3.1. Experiment 1
3.2. Experiment 2
3.3. Experiment 3
3.4. Experiment 4
- FAdamWav_Level1 has a similar performance compared to FAdam, even though FAdamWav_Level1 saves of GPU memory.
- FAdamWav_Level2 has lower accuracy than FAdam and FAdamWav_k1, but it is still competitive despite the reduction in GPU memory.
- FAdamWav_Level3 has lower performance than FAdamWav_Level2, and no more GPU memory reduction.
- The application of a single wavelet transformation level (FAdamWav_k1) increases the execution time for 50 s with respect to FAdam.
- The application of a second wavelet transformation level (FAdamWav_k2) increses the execution time for 70 s with respect to FAdam.
- The application of a third wavelet transformation level (FAdamWav_k3) increses the execution time to 94 s with respect to FAdam.
4. Discussion
- 1.
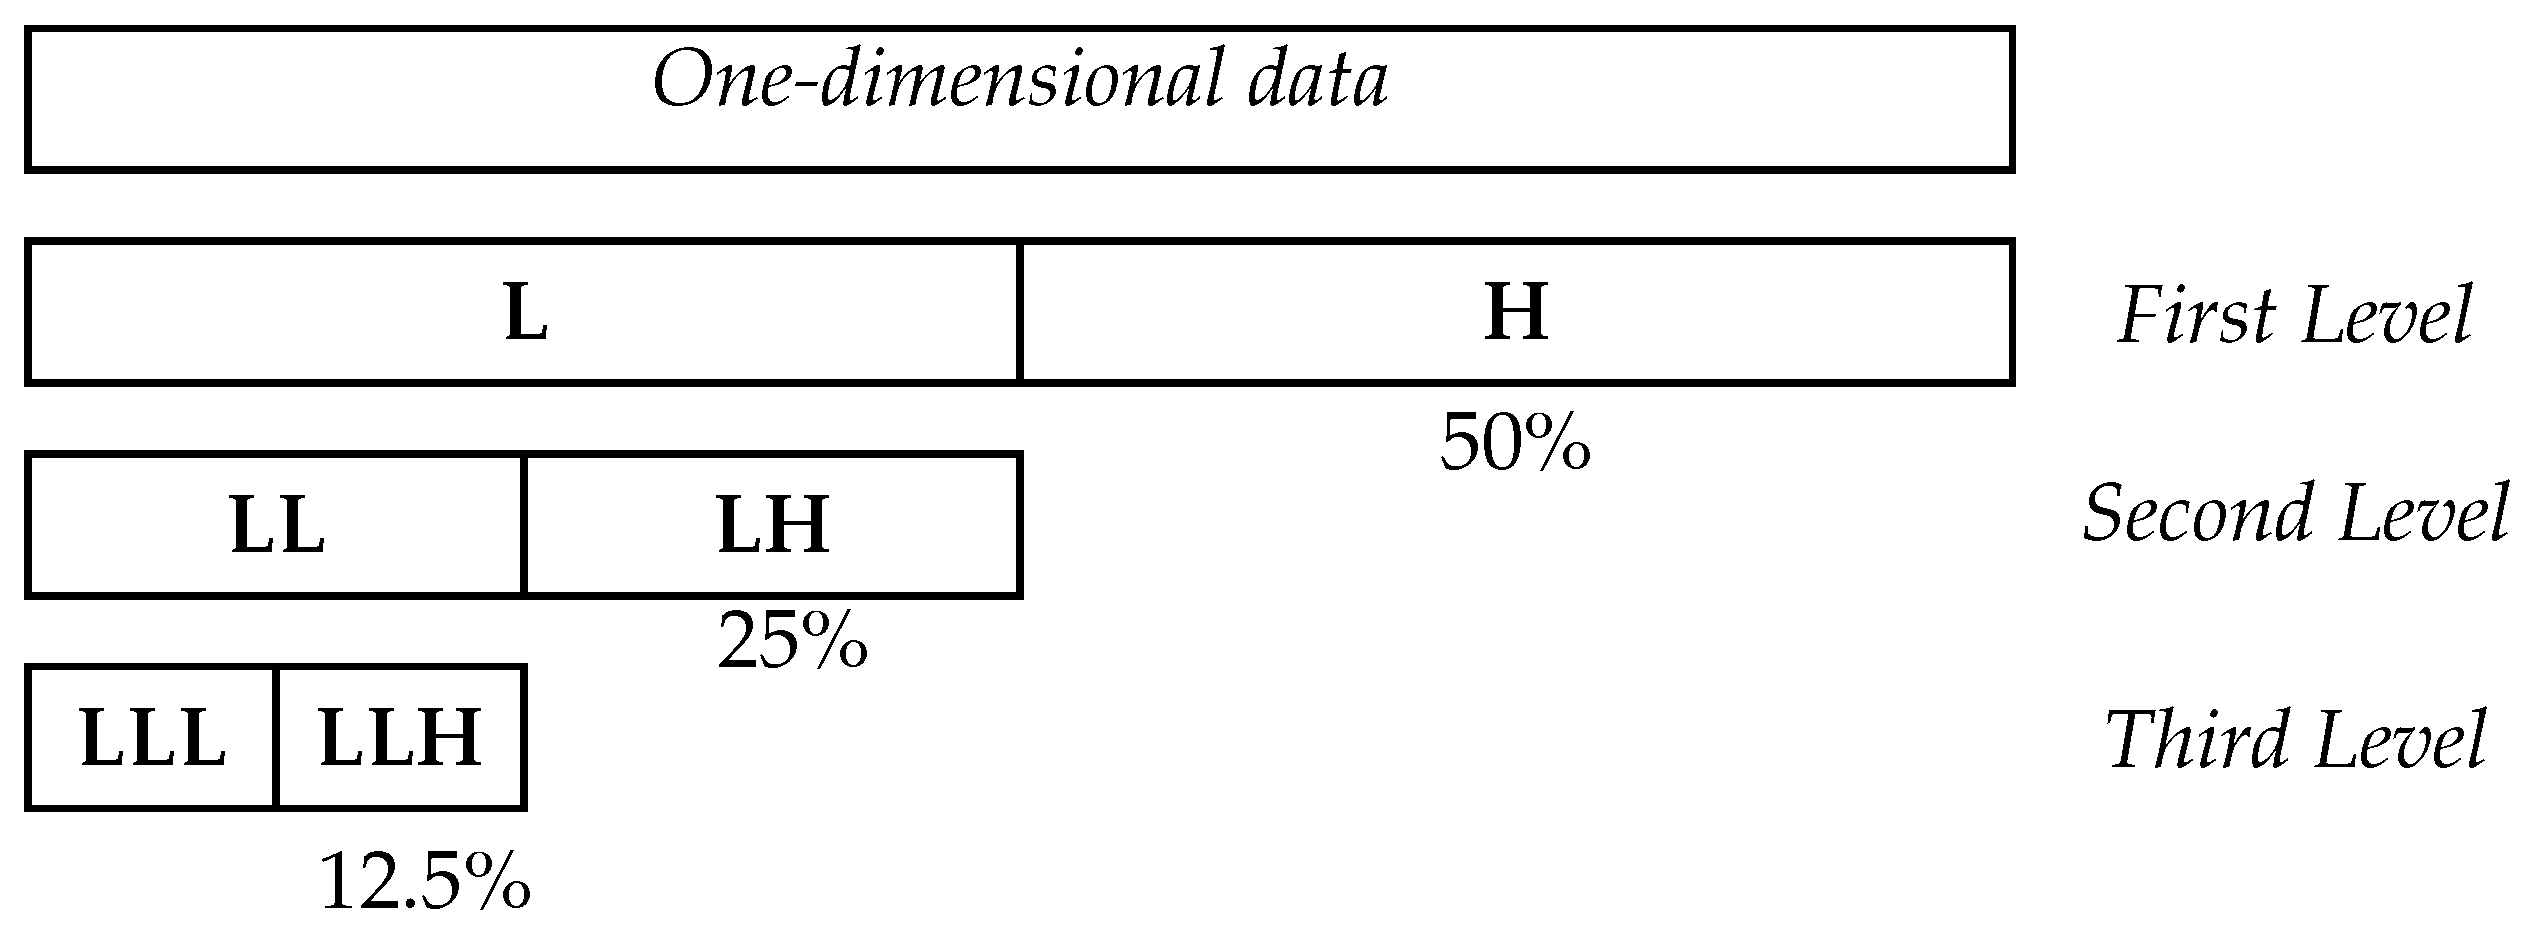
- Wavelet gradient compression. A wavelet-based gradient compression maps the gradient matrix to a reduced space via the parametric discrete wavelet transform with k transformation levels.
- 2.
- Efficient calculation of moments and velocities. Calculating the moments and velocities is efficient because high-frequency bands are removed in the wavelet low-dimensional space. Therefore, the gradients do not contain high frequencies.
- 3.
- Fractional gradient optimization. The fractional -order of the optimizer is variable. Selecting the appropriate value of provides good optimization. Our experiments show that the integer case is not optimal, and that the fractional version outperforms it. For instance, in Experiment 1, the best fractional order was .
- 4.
- Parametric filter selection. FAdamWav allows to select optimal parameter values of the filters for the discrete wavelet transform. The goal is to achieve maximum compression so that, even when the high-frequency coefficients are set to zero, the reconstructed gradients are sufficiently similar to the original.Although the experiments were developed by varying the parameters step by step with discrete values in the range , it is possible to adjust the -order during execution.
- 5.
- Neural network parameter optimization. The inverse parametric discrete wavelet transform restores the gradients to their original dimensions. Once restored, the gradients are used to update the network parameters for each training step.
- 6.
- Wavelet transformation levels. FAdamWav has the possibility of applying k transformation levels, and it is possible to choose a value of k that provides an acceptable trade-off between longer execution time and lower memory usage.
- 7.
- One-dimensional discrete wavelet transform. The discrete wavelet transform is applied in one dimension. However, it is possible to deal with the gradient matrix using a two dimensional wavelet transform, including curvelets or shearlets.
Author Contributions
Funding
Data Availability Statement
Conflicts of Interest
Appendix A. Fractional Derivatives and the Backpropagation Update Formula for MLP
- X is the input layer (input data),
- H is hidden layers,
- O is the output layer,
- L is layers, because of the hidden layers and the output layer,
- is a matrix of synaptic weights, , that connects neuron k of layer with neuron j of layer l,
- are synaptic weights () that connect the first hidden layer with X,
- is the desired output of neuron k at output layer when the ith input data is presented,
- is the activation function in the L layers,
- is the output of neuron k at output layer O, when the ith input data are presented and at layer O,
- is the potential activation of neuron k at layer l, , with inputs . For , considering the jth component of X,
- is the output of neuron k at a hidden layer l, .
References
- Haykin, S.S. Neural Networks and Learning Machines, 3rd ed.; Pearson Education: Upper Saddle River, NJ, USA, 2009. [Google Scholar]
- Robbins, H.; Monro, S. A stochastic approximation method. Ann. Math. Statist. 1951, 22, 400–407. [Google Scholar] [CrossRef] [Scilit]
- Lydia, A.; Francis, S. Adagrad—An Optimizer for Stochastic Gradient Descent. Int. J. Inf. Comput. Sci. 2019, 6, 566–568. [Google Scholar]
- Zeiler, M. ADADELTA: An adaptive learning rate method. arXiv 2012, arXiv:1212.5701. [Google Scholar] [CrossRef] [Scilit]
- Kingma, D.P.; Ba, J. Adam: A Method for Stochastic Optimization. arXiv 2014, arXiv:1412.6980. [Google Scholar]
- Hu, E.J.; Shen, Y.; Wallis, P.; Allen-Zhu, Z.; Li, Y.; Wang, S.; Wang, L.; Chen, W. LoRA: Low-Rank Adaptation of Large Language Models. arXiv 2021, arXiv:2106.09685. [Google Scholar] [CrossRef] [Scilit]
- Zhao, J.; Zhang, Z.; Chen, B.; Wang, Z.; Anandkumar, A.; Tian, Y. Galore: Memory-efficient LLM Training by Gradient Low-rank Projection. arXiv 2024, arXiv:2403.03507. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Yang, Z.; Chen, B.K.; Pu, F.; Li, B.; Gao, T.; Kawaguchi, K. Memory-Efficient LLM Training by Various-Grained Low-Rank Projection of Gradients. arXiv 2025, arXiv:2505.01744. [Google Scholar]
- Wen, Z.; Luo, P.; Wang, J.; Deng, X.; Zou, J.; Yuan, K.; Sun, T.; Li, D. Wavelet Meets Adam: Compressing Gradients for Memory-Efficient Training. arXiv 2025, arXiv:2501.07237. [Google Scholar]
- Daubechies, I. Ten Lectures on Wavelets; Society for Industrial and Applied Mathematics (SIAM): Philadelphia, PA, USA, 1992. [Google Scholar]
- Mallat, S. A Wavelet Tour of Signal Processing: The Sparse Way, 3rd ed.; Academic Press, Inc.: Cambridge, MA, USA, 2008. [Google Scholar]
- Herrera Alcántara, O.; González Mendoza, M. Optimization of Parameterized Compactly Supported Orthogonal Wavelets for Data Compression. In Proceedings of the Advances in Soft Computing; Batyrshin, I., Sidorov, G., Eds.; Springer: Berlin/Heidelberg, Germany, 2011; pp. 510–521. [Google Scholar]
- Lai, M.J.; Roach, D. Parameterizations of Univariate Orthogonal Wavelets With Short Support. In Approximation Theory X: Wavelets, Splines, and Applications; Chui, C.K., Schumaker, L.L., Stoeckler, J., Eds.; Vanderbilt University Press: Nashville, TN, USA, 2001; pp. 1–10. [Google Scholar]
- Roach, D.W. A Subclass of the Length 12 Parameterized Wavelets. In Proceedings of the Approximation Theory XIII: San Antonio 2010; Neamtu, M., Schumaker, L., Eds.; Springer: New York, NY, USA, 2012; pp. 263–275. [Google Scholar]
- Roach, D. The complete length sixteen parametrized wavelets. Sampl. Theory Signal Process. Data Anal. 2025, 23, 12. [Google Scholar] [CrossRef] [Scilit]
- Podlubny, I. Chapter 2—Fractional Derivatives and Integrals. In Fractional Differential Equations;Mathematics in Science and Engineering; Podlubny, I., Ed.; Elsevier: Amsterdam, The Netherlands, 1999; Volume 198, pp. 41–119. [Google Scholar] [CrossRef] [Scilit]
- Miller, K.S.; Ross, B. An Introduction to the Fractional Calculus and Fractional Differential Equations; Wiley-Interscience: Hoboken, NJ, USA, 1993. [Google Scholar]
- Bao, C.; Pu, Y.; Zhang, Y. Fractional-Order Deep Backpropagation Neural Network. Comput. Intell. Neurosci. 2018, 2018, 7361628. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wang, J.; Wen, Y.; Gou, Y.; Ye, Z.; Chen, H. Fractional-order gradient descent learning of BP neural networks with Caputo derivative. Neural Netw. 2017, 89, 19–30. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Herrera-Alcántara, O. Fractional Derivative Gradient-Based Optimizers for Neural Networks and Human Activity Recognition. Appl. Sci. 2022, 12, 9264. [Google Scholar] [CrossRef] [Scilit]
- Herrera-Alcántara, O.; Castelán-Aguilar, J.R. Fractional Gradient Optimizers for PyTorch: Enhancing GAN and BERT. Fractal Fract. 2023, 7, 500. [Google Scholar] [CrossRef] [Scilit]
- Herrera Alcántara, O. On the Best Evolutionary Wavelet Based Filter to Compress a Specific Signal. In Proceedings of the Advances in Soft Computing; Sidorov, G., Hernández Aguirre, A., Reyes García, C.A., Eds.; Springer: Berlin/Heidelberg, Germany, 2010; pp. 394–405. [Google Scholar]
- Herrera-Alcántara, O.; González-Mendoza, M. Inverse formulas of parameterized orthogonal wavelets. Comput. Informat. Numer. Comput. 2018, 100, 715–739. [Google Scholar] [CrossRef] [Scilit]
- Luchko, Y. Fractional Integrals and Derivatives: “True” versus “False”. Mathematics 2023, 11, 3003. [Google Scholar] [CrossRef] [Scilit]
- Wilson, H.; Sircar, S.; Shukla, P. Viscoelastic Subdiffusive Flows: Theory and Computation; Fluid Mechanics and Its Applications; Springer: Singapore, 2024; Volume 138. [Google Scholar] [CrossRef] [Scilit]
- Garrappa, R.; Kaslik, E.; Popolizio, M. Evaluation of Fractional Integrals and Derivatives of Elementary Functions: Overview and Tutorial. Mathematics 2019, 7, 407. [Google Scholar] [CrossRef] [Scilit]
- Taylor, M.E. Tools for PDE: Pseudodifferential Operators, Paradifferential Operators, and Layer Potentials; Mathematical Surveys and Monographs; American Mathematical Society: Providence, RI, USA, 2000; Volume 81. [Google Scholar]
- Bényi, Á.; Maldonado, D.; Naibo, V. What is… a paraproduct. Not. Am. Math. Soc. 2010, 57, 858–868. [Google Scholar]
- Christ, F.M.; Weinstein, M.I. Dispersion of small amplitude solutions of the generalized Korteweg-de Vries equation. J. Funct. Anal. 1991, 100, 87–109. [Google Scholar] [CrossRef] [Scilit]
- Conti, C.; Cotronei, M. Construction of Wavelet Filters: A Revisitation. In Proceedings of the Mathematical and Computational Modelling, Approximation and Simulation; Ibáñez-Pérez, M.J., Lamberti, P., Remogna, S., Sbibih, D., Eds.; Springer: Cham, Switzerland, 2025; pp. 3–21. [Google Scholar]
- Candes, E.J.; Donoho, D.L. Curvelets: A Surprisingly Effective Nonadaptive Representation for Objects with Edges. In Proceedings of the International Conference on Curves and Surfaces, Saint-Malo, France, 1–7 July 1999; pp. 1–10. [Google Scholar]
- Kutyniok, G.; Labate, D. (Eds.) Shearlets: Multiscale Analysis for Multivariate Data, 1st ed.; Applied and Numerical Harmonic Analysis; Springer: New York, Ny, USA, 2012; p. 345. [Google Scholar]
- Paszke, A.; Gross, S.; Massa, F.; Lerer, A.; Bradbury, J.; Chanan, G.; Killeen, T.; Lin, Z.; Gimelshein, N.; Antiga, L.; et al. PyTorch: An Imperative Style, High-Performance Deep Learning Library. In Advances in Neural Information Processing Systems 32; Curran Associates, Inc.: Red Hook, NY, USA, 2019; pp. 8024–8035. [Google Scholar]
- Deng, L. The MNIST database of handwritten digit images for machine learning research. IEEE Signal Process. Mag. 2012, 29, 141–142. [Google Scholar] [CrossRef] [Scilit]
- OpenAI. ChatGPT. Large Language Model. 2023. Available online: https://chat.openai.com/ (accessed on 23 February 2026).
- DeepMind, G. Gemini. Large Language Model Developed by Google DeepMind. 2023. Available online: https://deepmind.google/technologies/gemini/ (accessed on 23 February 2026).
- Grattafiori, A.; Dubey, A.; Jauhri, A.; Pandey, A.; Kadian, A.; Al-Dahle, A.; Letman, A.; Mathur, A.; Schelten, A.; Vaughan, A.; et al. The LLaMA 3 Herd of Models. arXiv 2024, arXiv:2407.21783. [Google Scholar] [CrossRef] [Scilit]
- Montesinos, L.O.A.; Montesinos, L.A.; Crossa, J. Convolutional Neural Networks. In Multivariate Statistical Machine Learning Methods for Genomic Prediction; Springer: Cham, Switzerland, 2022; pp. 533–577. [Google Scholar] [CrossRef] [Scilit]



| Filter | |
|---|---|
| Haar | 0.7853981633974483 |
| Dau4 | 1.3089969389957472 |
| Filter | ||
|---|---|---|
| Haar | 0.7853981633974483 | 0.7853981633974483 |
| Dau4 | 1.3089969389957472 | 1.0471975511965976 |
| Dau6 | 1.7850806990394015 | 1.0742468359786252 |
| Coiflets | 5.7504673989251085 | 3.6052402624389956 |
| 96.25 | 96.46 | 96.53 | 96.04 | 96.44 | 96.34 | 96.89 | 95.84 | 96.03 |
| 97.12 | 97.11 | 97.37 | 97.54 | 97.09 | 97.24 | 96.51 | 97.04 | 96.93 |
| 97.49 | 97.28 | 97.30 | 97.54 | 97.51 | 97.47 | 97.15 | 97.41 | 96.99 |
| 97.60 | 97.63 | 97.63 | 97.67 | 97.66 | 97.55 | 97.43 | 97.33 | 97.10 |
| 97.63 | 97.77 | 97.75 | 97.88 | 97.37 | 98.18 | 97.98 | 97.86 | 97.23 |
| 97.33 | 97.69 | 97.63 | 98.08 | 97.63 | 97.88 | 97.69 | 97.63 | 97.29 |
| 97.68 | 97.64 | 97.78 | 97.48 | 97.66 | 97.95 | 97.57 | 97.61 | 97.39 |
| 97.76 | 97.69 | 97.80 | 97.59 | 97.59 | 97.72 | 97.84 | 97.60 | 97.39 |
| 97.88 | 97.26 | 97.87 | 98.01 | 98.05 | 97.94 | 97.83 | 97.88 | 97.71 |
| 97.84 | 97.36 | 98.00 | 98.10 | 97.88 | 97.84 | 98.09 | 98.05 | 97.45 |
| 97.65 | 97.69 | 97.63 | 97.27 | 97.69 | 97.98 | 97.89 | 97.94 | 97.23 |
| 97.86 | 98.07 | 98.00 | 97.90 | 97.48 | 98.04 | 97.91 | 97.86 | 97.59 |
| 98.00 | 97.75 | 97.88 | 97.92 | 97.84 | 97.98 | 97.65 | 97.74 | 97.76 |
| 98.07 | 97.85 | 97.96 | 98.02 | 97.73 | 97.96 | 97.67 | 97.81 | 97.63 |
| 97.68 | 97.55 | 97.91 | 98.18 | 97.99 | 97.72 | 97.89 | 97.63 | 97.41 |
| 97.99 | 97.91 | 97.95 | 97.67 | 97.73 | 97.88 | 97.83 | 97.63 | 97.59 |
| 97.91 | 98.01 | 97.82 | 97.55 | 97.88 | 97.94 | 97.86 | 97.85 | 97.84 |
| 97.93 | 98.12 | 97.90 | 98.04 | 97.86 | 97.55 | 97.76 | 97.98 | 97.73 |
| 98.36 | 98.12 | 97.94 | 98.23 | 98.04 | 98.05 | 98.06 | 97.83 | 97.75 |
| 97.80 | 97.94 | 97.74 | 97.90 | 98.00 | 97.89 | 98.09 | 97.94 | 97.58 |
| 94.90 | 95.33 | 95.78 | 95.61 | 94.95 | 95.33 | 95.67 | 95.14 | 95.41 | 95.49 | 95.36 | 95.64 |
| 96.47 | 96.62 | 96.62 | 96.65 | 96.80 | 96.63 | 96.80 | 96.85 | 96.75 | 96.57 | 96.57 | 96.89 |
| 96.91 | 97.28 | 97.33 | 97.06 | 97.09 | 97.15 | 97.36 | 97.13 | 97.09 | 97.22 | 97.20 | 97.35 |
| 97.47 | 97.55 | 97.60 | 97.25 | 97.10 | 97.31 | 97.55 | 97.24 | 97.23 | 97.59 | 97.42 | 97.22 |
| 97.14 | 97.59 | 97.49 | 97.78 | 97.10 | 97.69 | 97.23 | 97.47 | 97.38 | 97.23 | 97.38 | 97.75 |
| 97.50 | 97.74 | 97.42 | 97.86 | 97.82 | 97.77 | 97.85 | 97.90 | 97.37 | 97.68 | 97.21 | 97.58 |
| 97.44 | 97.12 | 97.45 | 97.88 | 97.62 | 97.96 | 97.93 | 97.45 | 97.63 | 97.63 | 97.85 | 97.75 |
| 97.76 | 97.48 | 97.48 | 97.68 | 97.08 | 97.53 | 97.81 | 97.61 | 97.71 | 97.47 | 97.42 | 97.79 |
| 97.87 | 97.88 | 97.60 | 97.59 | 97.75 | 97.75 | 97.21 | 97.74 | 97.81 | 97.49 | 97.76 | 97.26 |
| 97.80 | 97.84 | 97.73 | 97.81 | 97.82 | 97.79 | 97.90 | 97.52 | 97.56 | 97.85 | 97.74 | 97.97 |
| 97.72 | 97.80 | 97.88 | 97.99 | 97.48 | 97.73 | 97.57 | 97.40 | 97.49 | 97.81 | 97.67 | 97.69 |
| 97.81 | 97.64 | 97.74 | 97.54 | 97.48 | 97.75 | 97.75 | 97.91 | 97.72 | 97.87 | 97.78 | 97.61 |
| 97.94 | 97.84 | 97.66 | 98.13 | 97.85 | 97.84 | 97.84 | 97.92 | 97.97 | 97.96 | 97.63 | 97.78 |
| 97.81 | 97.95 | 97.61 | 97.68 | 97.87 | 97.60 | 97.50 | 97.86 | 97.74 | 97.90 | 97.72 | 97.69 |
| 98.01 | 97.78 | 97.06 | 97.96 | 97.54 | 98.06 | 97.85 | 97.88 | 97.83 | 97.69 | 97.82 | 97.86 |
| 97.88 | 97.72 | 98.00 | 97.92 | 97.27 | 98.07 | 97.51 | 97.97 | 97.77 | 97.80 | 97.72 | 97.83 |
| 97.79 | 97.66 | 98.15 | 98.03 | 97.82 | 98.05 | 98.03 | 97.98 | 97.92 | 97.85 | 97.99 | 97.94 |
| 97.89 | 97.85 | 97.77 | 97.95 | 98.00 | 97.67 | 97.95 | 97.73 | 97.90 | 97.92 | 97.51 | 97.77 |
| 97.84 | 98.16 | 97.97 | 97.89 | 97.86 | 98.03 | 97.96 | 97.78 | 97.70 | 98.04 | 98.07 | 98.04 |
| 97.85 | 97.99 | 97.88 | 97.24 | 97.98 | 97.84 | 97.95 | 97.91 | 97.86 | 98.01 | 97.90 | 98.01 |
| Memory Saving | FAdam | FAdamWav_k1 | FAdamWav_k2 | FAdamWav_k3 |
|---|---|---|---|---|
| Theoretical (percentage) | 0 MB | 50% MB | 75% MB | 87.5% |
| GPU memory usage (practical measure MB) | 28.8 MB | 23.95 MB | 18.82 MB | 18.82 MB |
| Practical (percentage) | 0 MB | 16.8% MB | 34.6% MB | 34.6% |
| Adam | FAdamWav_k1 | FAdamWav_k2 | FAdamWav_k3 |
|---|---|---|---|
| 95.98 | 95.11 | 94.59 | 93.31 |
| 96.83 | 96.56 | 95.65 | 95.04 |
| 96.62 | 97.20 | 96.19 | 96.15 |
| 97.68 | 97.64 | 96.80 | 96.32 |
| 97.10 | 97.07 | 96.52 | 96.21 |
| 97.46 | 97.59 | 97.15 | 96.73 |
| 97.80 | 97.56 | 96.88 | 96.90 |
| 97.69 | 97.81 | 97.23 | 96.92 |
| 97.64 | 97.73 | 97.26 | 97.03 |
| 97.28 | 97.84 | 97.63 | 97.36 |
| 97.70 | 97.58 | 97.19 | 97.12 |
| 97.49 | 97.73 | 97.60 | 97.14 |
| 98.00 | 97.91 | 97.60 | 97.30 |
| 97.78 | 97.99 | 97.65 | 97.45 |
| 97.98 | 97.98 | 97.59 | 97.49 |
| 97.88 | 97.93 | 97.59 | 97.47 |
| 97.70 | 97.63 | 97.84 | 97.49 |
| 97.81 | 98.08 | 97.70 | 97.49 |
| 98.06 | 97.94 | 97.45 | 97.66 |
| 97.90 | 97.82 | 97.61 | 97.49 |
| FAdam | FAdamWav_Level1 | FAdamWav_Level2 | FAdamWav_Level3 |
|---|---|---|---|
| 131 s | 181 s | 201 s | 225 s |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Share and Cite
Herrera-Alcántara, O.; Arellano-Balderas, S.; Rodríguez-Mondragón, S.; Reyes-Ortíz, J.A.; Navarro-Fuentes, J. FAdamWav: A Fractional Wavelet Gradient Optimizer for Neural Networks. Fractal Fract. 2026, 10, 149. https://doi.org/10.3390/fractalfract10030149
Herrera-Alcántara O, Arellano-Balderas S, Rodríguez-Mondragón S, Reyes-Ortíz JA, Navarro-Fuentes J. FAdamWav: A Fractional Wavelet Gradient Optimizer for Neural Networks. Fractal and Fractional. 2026; 10(3):149. https://doi.org/10.3390/fractalfract10030149
Chicago/Turabian StyleHerrera-Alcántara, Oscar, Salvador Arellano-Balderas, Sandra Rodríguez-Mondragón, José Alejandro Reyes-Ortíz, and Jaime Navarro-Fuentes. 2026. "FAdamWav: A Fractional Wavelet Gradient Optimizer for Neural Networks" Fractal and Fractional 10, no. 3: 149. https://doi.org/10.3390/fractalfract10030149
APA StyleHerrera-Alcántara, O., Arellano-Balderas, S., Rodríguez-Mondragón, S., Reyes-Ortíz, J. A., & Navarro-Fuentes, J. (2026). FAdamWav: A Fractional Wavelet Gradient Optimizer for Neural Networks. Fractal and Fractional, 10(3), 149. https://doi.org/10.3390/fractalfract10030149