Article

Distilling the Complexity of Agent-Based Simulations into Textual Explanations via Large Language Models

by
Noé Y. Flandre
1 and
Philippe J. Giabbanelli
2,*
1
IMT Mines Alès, 6 Av. de Clavières, 30100 Alès, France
2
Office of Enterprise Research and Innovation, Old Dominion University, 1030 University Blvd, Suffolk, VA 23435, USA
*
Author to whom correspondence should be addressed.
Big Data Cogn. Comput. 2026, 10(4), 121; https://doi.org/10.3390/bdcc10040121
Submission received: 9 February 2026 / Revised: 21 March 2026 / Accepted: 2 April 2026 / Published: 15 April 2026
(This article belongs to the Section Large Language Models and Embodied Intelligence)

Abstract

Communicating the design and results of agent-based models (ABMs) to subject matter experts is challenging, which hinders participation and limits trust in simulation-based decision support. Large language models (LLMs) can communicate ABMs as textual summaries, thus complementing traditional disclosure through statistical and visualization techniques. While prior work translated the structure of conceptual models into narratives via LLMs, our extension covers the dynamics of simulation models via an automated simulation-to-text method that extracts contextual information from NetLogo ABMs, performs repeated simulations, and generates narrative descriptions (including the model’s purpose, parameters, and simulation dynamics) using mutimodal LLMs. Furthermore, four summarization algorithms spanning abstractive and extractive methods provide shorter reports. Using Design-of-Experiments methods over three peer-reviewed ABMs, state-of-the-art multimodal LLMs from 2026 (Gemini 3.1 Pro, Qwen 3.5, Kimi K2.5, Claude Opus 4.6) and different prompt elements (e.g., roles, examples, generating insights, statistical analyses), we compare our results with several reference reports (e.g., from associate professors). We find that report quality is determined mainly (i.e., up to 34% of the variance) by the summarization algorithm and its interaction with the LLM, with abstractive summarizers (BART, T5) producing more coherent and readable reports, while Claude Opus 4.6 is the most robust LLM.

1. Introduction

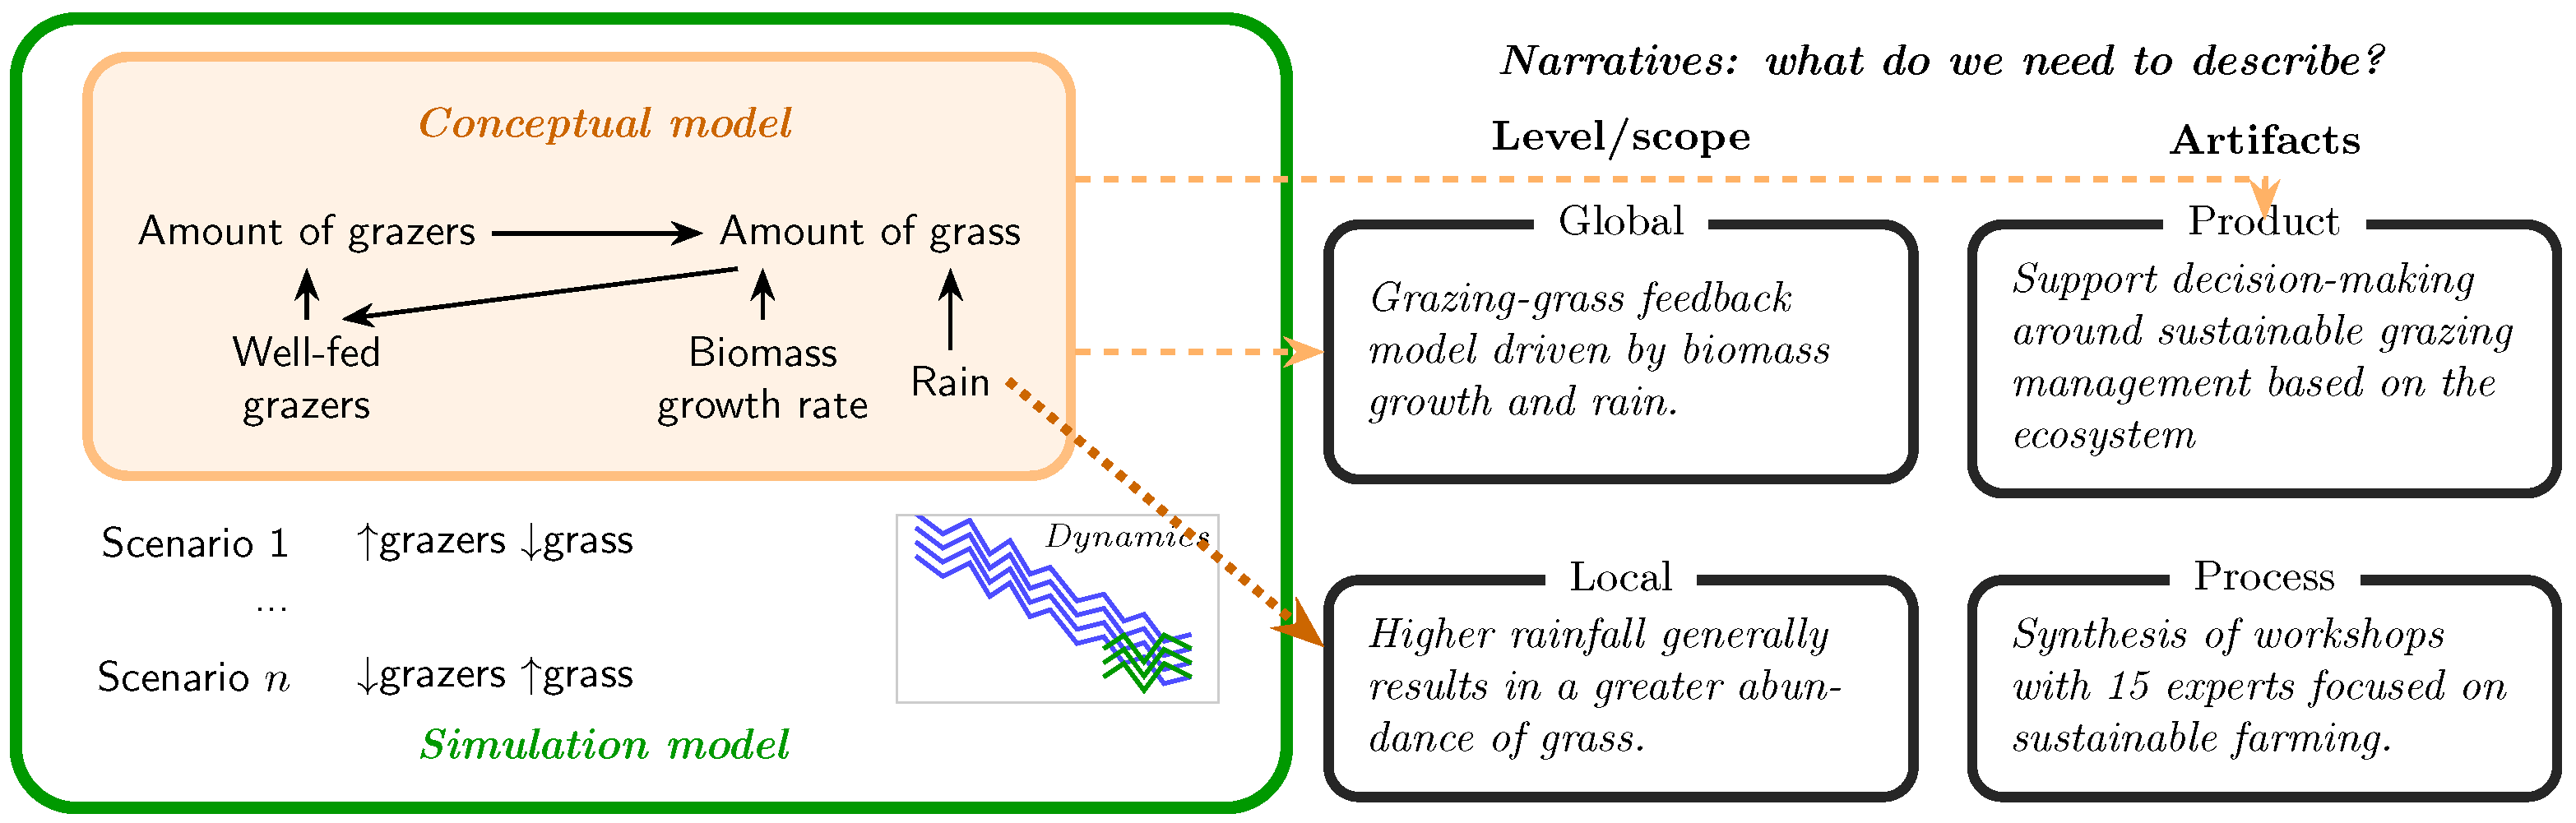
Explainability and transparency are important considerations in Modeling & Simulation (M&S) as they build trust and confidence in the validity of models, thus supporting the translation from a model’s insights into practice. The creation of understandable narratives to accompany models is particularly beneficial for end users who may not have the technical expertise to interpret raw simulation data directly or appreciate the limitations of specific model-building processes [1]. Explainability and transparency are multifaceted, as they can be conducted at the local (e.g., sensitivity to changes in individual parameters [2]) or global level (e.g., comparing point estimates from a simulation with ground truth), and they cover the production of a model [3] (how was it created?) as well as the intended use of the final product (Figure 1). When conceptual models strive to be comprehensive, they are at risk of becoming “spaghetti diagrams” [4], thus turning into unintended illustrations of complexity that offer little support for global explanations of the model and hinder translations into practices. The Foresight Obesity Map is a case in point, as it was depicted by researchers as an “almost incomprehensible web of interconnectedness [in which] the scale and number of interactions make it difficult to see how one might use it in any practical way to develop systemic approaches” [5] with others stating that the model “looks more like a spilled plate of spaghetti than anything of use to policymakers” [6]. The solution is not necessarily to force a model into a reduced scope or to omit mediating effects and multiple consequences [7], as over-simplified models may no longer be fit for purpose [8]. For example, public health models require the integration of biomedical, social, and environmental variables [9], so these models often need to be comprehensive and clearly reflect unintended consequences in order to serve their purpose, even if that initially appears to come at the expense of explainability and transparency.
Given the necessity of keeping models fit for purpose while addressing explainability and transparency, a possible solution could be that modelers provide all necessary descriptions. However, analyses of descriptions surrounding conceptual models and their production repeatedly showed that modelers do not systematically describe the model development process [3,10] or the sources of model elements such as relationships between variables [3]. The realization that the burden cannot solely be placed on modelers to provide more descriptions has resulted in a renewed interest for automation via Natural Language Generation. This is not merely a matter of generating (any) text, as simple templates could produce strings that describe a conceptual model such as “A increases B. B decreases C.” Advances in cognitive sciences show that certain representations of events and causality support language processing tasks in readers [11]; thus, we seek textual descriptions that allow readers to form correct views about the model being described. Generative Artificial Intelligence (GenAI) solutions such as GPT have been used to translate large conceptual models into descriptions at the local level (e.g., model components such as relationships [12,13]) or at the global level (e.g., decomposing a model into blocks [14] or summarizing its comparison with ground-truth data [15]) that have satisfactory readability levels and remain factually correct. This flurry of research on model-to-text transformation complements the significant research growth on text-to-model transformation [16,17,18,19].
Figure 1. Conceptual models (consisting of labeled nodes for concepts and directed edges for causal relationships) have been translated into text using GenAI solutions such as OpenAI’s GPT (dotted arrows), often with a focus on local elements [12,13] and occasionally by using summarization techniques to provide a sense of the entire model. In this paper, we generate text for simulation models, which adds dynamic scenarios.
Bdcc 10 00121 g001
As significant advances have been made on automatically producing narratives for conceptual models by using GenAI, the next frontier is to create descriptions for simulation models. The simulation-to-text task is more challenging than a model-to-text translation because simulations are dynamic systems; thus, we have to convey both the rationale and structure of a model (as in model-to-text transformation) and its dynamics in response to various stimuli or input scenarios (Figure 1). To date, there is a paucity of works in this domain. Notable exceptions include the study of Verduzco et al., who used GPT-4 to describe input files for the Large-scale Atomic/Molecular Massively Parallel Simulator (LAMMPS), thus demonstrating the feasibility of employing GenAI to address lacking descriptions of simulation methods [20]. While GenAI can create narrations by interacting with agents or simulation logs [21], its primary goal was to generate compelling stories for the game industry (e.g., the hero, warrior, wizard, and dragon from Aoki et al. [22]) rather than to increase the explainability or transparency of a simulation serving as a decision-support tool. There is thus a demonstrated need to automatically produce descriptions that alleviate, at least partly, the challenges of conveying simulation models to a target audience.
In this paper, we focus on translating agent-based models (ABMs) into text. ABMs simulate interactions between individual entities (‘agents’) and their environment with successful applications across many domains including ecological and socio-ecological systems [23,24], sociology [25], or political decision making [26]. While ABMs are powerful tools to explore complex systems, their results are notoriously challenging to communicate due to the difficulties in analyzing and interpreting the multidimensional output data [27]. This difficulty is exacerbated when trying to communicate findings [28], particularly to non-experts who need to make informed decisions based on these outcomes [29]. Furthermore, the amount of data generated can be significant for detailed simulation models or those with large search spaces, but readers have a limited cognitive capacity. In other words, trying to solve the challenge of explainability by translating every aspect of a simulation model into an enormous phone book would just displace the problem. ABMs thus require distilling information into concise yet comprehensive insights, requiring sophisticated analytical approaches [27]. Note that we use the term agent exclusively in the context of ABMs to refer to simulated entities. Large language models are treated as external reporting components and are not conceptualized as autonomous or “agentic” systems within this paper.
Our overarching contribution is to generate concise executive-style reports from agent-based model (ABM) simulations with readability levels that suggest potential accessibility for non-modeling experts [30], while acknowledging that dedicated stakeholder studies are needed to fully assess how such reports support understanding and decision making [31]. This overarching aim is realized through three specific contributions:
  • We design, implement, and evaluate a staged design-of-experiments (DoE) methodology to analyze and optimize multi-component LLM-based reporting systems. By combining aggregated ANOVA screening, factorial variance decomposition, and direct level-dominance comparisons, the approach attributes performance variability to individual factors and interaction effects, thereby providing a systematic and generalizable workflow for configuring simulation-to-text methods.
  • We analyze how summarization strategies, prompt elements, and the identity of the large language model jointly influence the quality of generated reports, showing in particular that interactions between summarization algorithms and LLMs explain a substantial share of performance variability.
  • We perform a comparative empirical evaluation across multiple ABMs using four recent large language models (Google’s Gemini 3.1 Pro Preview, Alibaba’s Qwen 3.5 27B, MoonshotAI’s Kimi K2.5, and Anthropic’s Claude Opus 4.6), providing practical guidance on evidence presentation, summarization choices, and model selection for simulation reporting tasks.
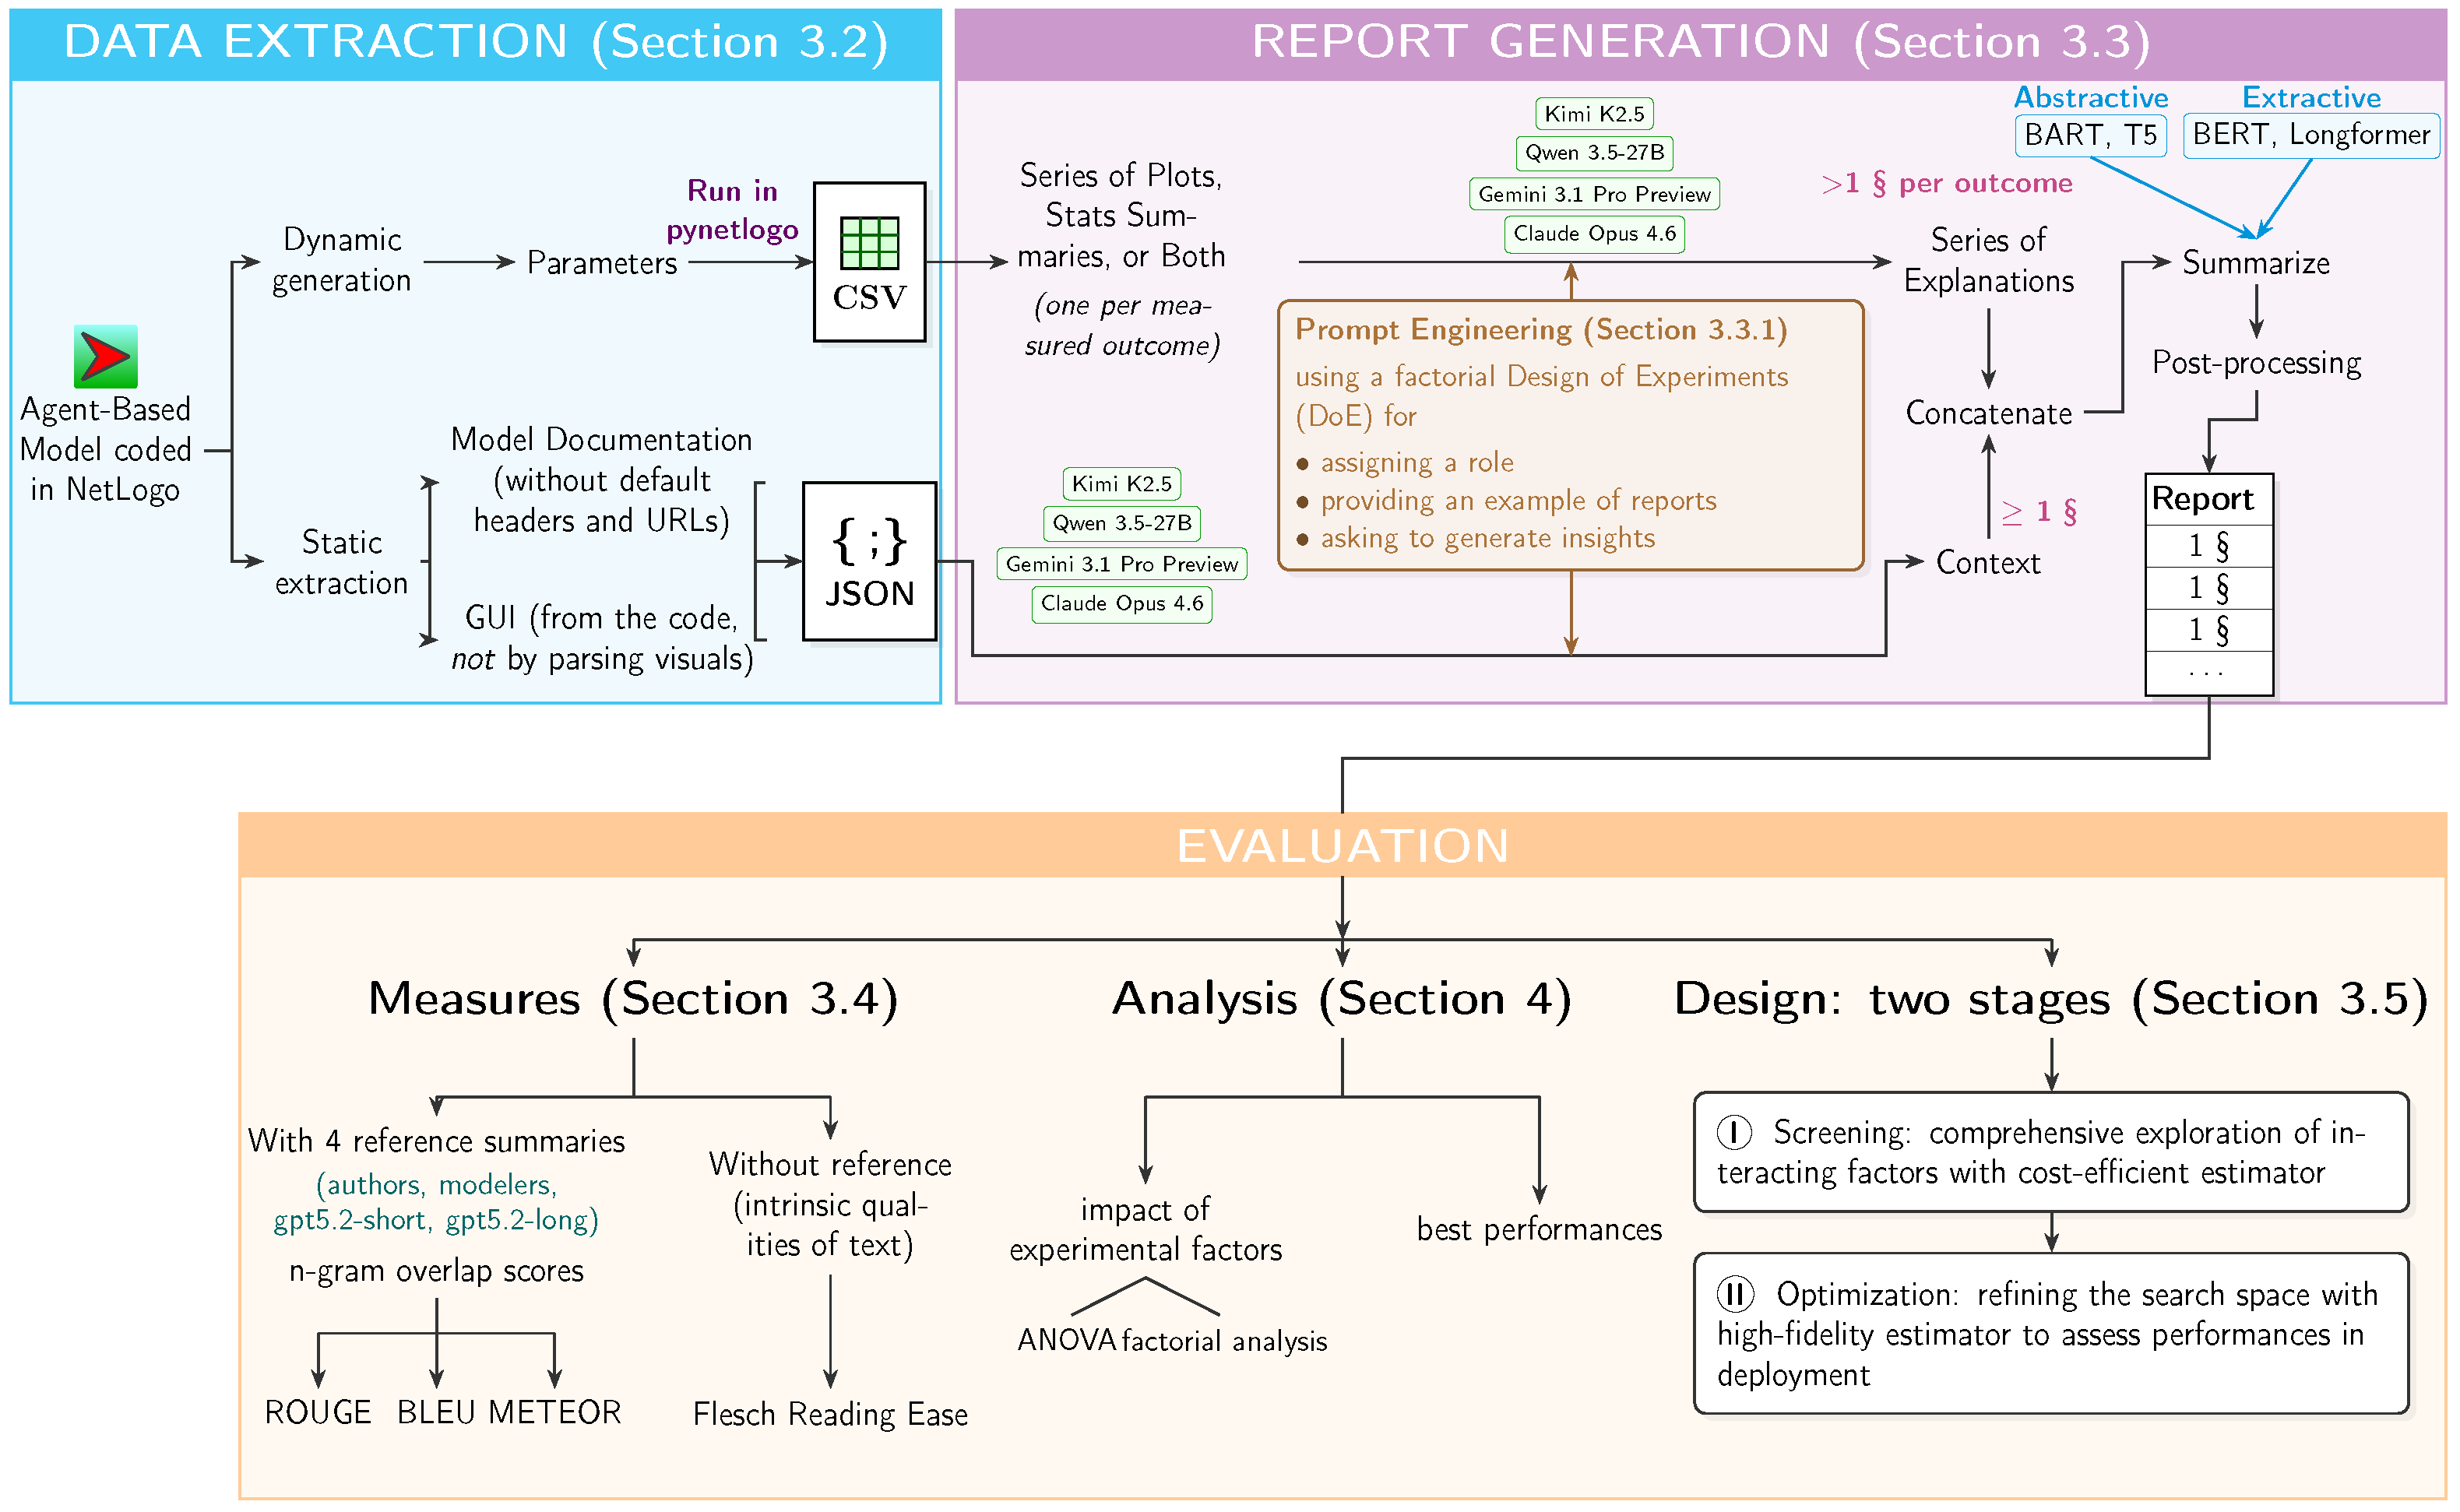
The remainder of this paper is organized as follows. In Section 2, we provide background information to keep the manuscript self-contained with special emphasis on techniques from Generative AI and their intersection with simulations. Building on the technical foundations summarized in our background, we present our methodology in Section 3, including the processes of data extraction, report generation, and our evaluation methods. Our results are presented in Section 4, which are followed by a discussion of our findings in Section 5. Finally, we provide concluding remarks in Section 6, and we support replicability by providing access to our code along with all results, ground truth datasets, and verification of the implementation.

2. Background

Our paper is motivated by the realization that simulation models such as ABMs can be complex and produce large amounts of data, which need to be succinctly conveyed to a variety of end users (Section 2.1). We propose using large language models (LLMs), which have already been employed in several simulation tasks (Section 2.2). We focus on using LLMs to generate reports, which can be evaluated (Section 2.3) in response to different prompt design techniques (Section 2.4).

2.1. Conveying Agent-Based Models to End-Users

ABMs can capture interactions between multiple agents (characterized by a number of dynamic attributes), over several steps (or ‘ticks’), through a variety of scenarios that can be performed multiple times to account for stochasticity. The sheer volume and complexity of the data produced by ABMs can overwhelm users, making it difficult to extract actionable insights directly from the raw outputs [30]. In addition, the design of the ABM and simulation can become complex, as it involves numerous agent attributes, several data- and theory-driven rules, along with various scenarios consisting of combinations of parameter values. This information can be comprehensively captured through standardized approaches to describe ABMs, such as the ODD (Overview, Design concepts, Details) protocol [32] and its extensions [33,34], and some aspects can be covered through a UML diagram (emphasizing software design) or reporting standards for data use in ABMs specifically [35] or the STRESS guidelines for simulations in general [36]. However, these standards and guidelines are not systematically used by the modeling community [37], and they can be challenging for stakeholders and model commissioners, who are not always modelers but need to attain a sense of what the model does and how to use it without parsing large volumes of technical information.
Several works have sought to improve communication for the design of ABMs and/or their simulation results, particularly for non-technical audiences. For example, Hall and Virrantaus used diagrams to convey the rules of ABMs [38], which was more recently echoed by Szangolies and colleagues in creating a visual version of the standardized ODD [39]. Visualizations have been an important tool and research area to communicate ABM for over a decade, across all phases of the modeling process [40], for instance using the popular NetLogo software [41]. While statistical techniques are commonplace in simulations (e.g., choosing a number of repeats for a target confidence interval), they often support modelers [42]. On occasions, statistics have been employed to convey ABMs to practitioners beyond M&S such as statisticians [43] or a broader audience [27]. As shown in the next subsection, advances in GenAI have provided new opportunities to explain ABMs as text, thus complementing studies on visualizations and statistics.

2.2. LLMs and Simulation

LLMs have intersected with simulations in several ways. While only one task (simulation-to-text) is directly relevant to this paper, we briefly discuss the names and techniques involved in three related areas to avoid confusion. First, in generative agent-based modeling or LLM-augmented social simulations [44], the decision-making modules of the agents are replaced or extended with LLMs (Figure 2). This allows agents to react to messages and to explain their reasoning [45,46], and it also transforms the challenge of crafting behavioral rules into a prompt engineering task that accounts for the agents’ attributes [47]. As pointed out by Larooij and Tornberg, “generative ABMs are still in a stage of early experimentation” [48] with prototypes emerging in late 2024 and early 2025. All ABMs used to generate simulations in this paper are ‘traditional’ as they use sets of rules to express behavior rather than LLMs. Second, in Agentic AI, the emphasis is on using a set of specialized agents to interpret a textual request [49]. For example, “approach potential clients” can trigger a market discovery agent that looks for suitable companies, then another agent extracts email addresses, and a third agent crafts tailored emails. In other words, agentic AI decomposes a problem so that it can be solved by a set of specialized, autonomous entities. The goals of the traditional ABMs studied in this paper are different, since they provide simulations as decision-support tools so that end users can estimate the effects of scenarios defined through input parameters. Third, there is a wealth of studies on generating simulations from text (Figure 2), drawing from earlier works on extracting ABM concepts from narratives [50,51], and then using questions and answering systems to automate the extraction [52,53] and finally generating simulation code in a target ABM platform such as NetLogo [54,55]. In this paper, we study the inverse transformation: instead of building an ABM from text, we use existing ABMs to generate a textual description.
As tools such as GPT make it possible to translate simulations into text, the idea of using GPT to explain simulations was proposed [15,56] and realized in a few studies. In particular, Jackson and Rolf noted the technical complexity of simulations and translated them into natural language for domain experts by translating the Python source of inventory management systems into English. While the results use a repetitive style that does not match the readability level expected of a report, this proof-of-concept demonstrated that GenAI could know enough about a simulation model in order to depict it with factually correct sentences [57]. Gürcan also noted that agents equipped with LLMs (i.e., generative ABM) could help with explainability, as the agents “can generate natural language explanations for their actions, decisions, and the underlying mechanics of the simulation” [44].
Note that both approaches can generate a large amount of low-level information either by translating the whole simulation code to text [57] or by asking each agent to explain how it decided and acted [44]. There is thus a need to distill the information, which we accomplish in this paper by using summarization techniques as presented in the next subsection.

2.3. Evaluating LLM-Generated Reports

When the output from LLMs is too verbose for practical use, we can further request that the LLM summarizes it. Several systematic reviews on text summarization cover the variety of methods employed in this field, as shown by Table 2 in [58] or Table 2 from an earlier review in [59]. Among several ways to organize these algorithms (e.g., statistical, deep-learning, LLMs), we consider two broad categories based on how they operate: extractive summarization copy–pastes the most relevant parts of the original text, while abstractive summarization synthesizes information by paraphrasing the text. By design, extractive summarization only provides factual content: it cannot hallucinate sentences that were not present in the input. It is also computationally efficient, and it has long been employed to summarize informative texts. These algorithms are designed to evaluate the importance of sentences (e.g., by computing a score) and assemble them without any changes, which risks creating a fragmented summary with abrupt transitions between sentences. BERT summarizer [60] (Bidirectional Encoder Representations from Transformers) is one of the most well-known extractive summarizers, but its standard context window size is small so it needs a sliding window to process inputs in chunks [61]. LongformerExt overcomes the input length limitation of models by using a sparse attention mechanism [62] that allows it to deal with long documents, which is relevant in the context of this paper.
In contrast, abstractive summarization is closer to the way that people write summaries: we want a text that is about the input material, and we may need to use new words or expressions to retain the essence of the original material. Transfer learning is a common component of abstractive summarization models, since they are pre-trained to generate tokens beyond the original text in order to remain cohesive [63]. As noted by Koh and colleagues, “Bidirectional and Auto-Regressive Transformers (BART) and Text-to-Text Transfer Transformer (T5) are the two most widely used sequence-to-sequence pre-trained models” for abstractive summarization [59]. As general domain encoders, T5 and BART (for abstractive summarization) along with Longformer and variants of BERT (for extractive summarization) remain key elements of current applied studies in summarization [64,65].
Since summarizing is about communicating, it is important to identify the audience and the format [66,67]: do we seek one paragraph for an email to a modeler, a five-minute elevator pitch to a potential model commissioner, or a written overview for subject-matter experts? Executive summaries are a common format that is found across application areas from military simulations [68] to behavioral modeling [69]. Executive summaries typically require concise and focused content yet remain powerful for the readers to take action [70], often coming down to one or two pages with no more than 1000 words [71].
Evaluating the results produced by LLMs involves both quantitative (our focus) and qualitative methods [72,73], which may employ human readers and/or LLMs to evaluate items on a Likert scale [74,75] along with measures of inter-rater agreement [76,77] as further described in Supplementary Material S1. To effectively evaluate LLMs and avoid common pitfalls, it is essential to develop a comprehensive suite of metrics rather than relying on a single metric [78]. Quantitative evaluation often uses metrics such as BLEU, METEOR, and ROUGE, which are standard in summarization tasks, to compare the generated content against a ground truth [79,80]. BLEU (Bilingual Evaluation Understudy) measures the precision of n-grams in the generated text compared to a reference text, using a scale from 0 to 1, where higher scores indicate better quality. Prior studies showed performances reaching 24.58% for this metric on summaries from BART [81] and 63% from BERT [82]. METEOR (Metric for Evaluation of Translation with Explicit ORdering) evaluates translation quality based on precision, recall, and alignment, producing scores ranging from 0 to 1, with higher scores representing better quality. Researchers have reported results on summaries using BART (73.72%) [81] along with BERT (33%) [83]. ROUGE (Recall-Oriented Understudy for Gisting Evaluation) measures recall by comparing the overlap of n-grams between the generated text and reference texts. It includes several variants, such as ROUGE-N (measuring n-gram overlap), ROUGE-L (measuring longest common subsequence), and ROUGE-W (measuring weighted longest common subsequence), with scores typically ranging from 0 to 1, where higher scores indicate better performance. Prior works display results for ROUGE-1 that are approximately 26.60 for BERT summaries and 52.53 for BART summaries [84]; for ROUGE-2, results approach 11.11 for BERT summaries and 21.83 for BART summaries [84], and lastly, for ROUGE-L, we have 24.29 for BERT and 49.75 for BART [84]. In addition, the Flesch Reading Ease [85] assesses the ease of reading a text based on sentence length and word syllable count with scores ranging from 0 to 100. Higher scores indicate easier readability with 90–100 being easily understandable by an average 11-year-old student and 0–30 being best understood by university graduates. Previous studies on LLMs have shown a Flesch Reading Ease between 24.88 and 58.01 [86].

2.4. Prompt Engineering and Experimental Design

Effective prompt engineering is critical for leveraging the capabilities of LLMs in generating high-quality explanations [87]. Rather than relying on random attempts, prompts must be carefully designed to include essential elements such as assigning roles, providing examples, or requesting insights. This structured approach ensures that the generated content is relevant and informative [88]. The design of LLMs can be articulated along several dimensions [89], which can be binary (e.g., whether to define a role and style) or multi-valued (e.g., whether the goal is expressed as looking-up information or creating). A notable challenge is that having more prompt elements does not guarantee better results [90]. Intuitively, ‘throwing the kitchen sink’ at the LLM may confuse it rather than guide it. Since we do not know a priori which elements to include, several prompts can be designed and their effects evaluated empirically.
The M&S studies that used prompt engineering have used several strategies to design their experiments. Several works have used the experimental design of varying one factor at a time [91,92,93], which involves systematically changing a single variable while keeping all other factors constant to isolate its individual effect on the outcome. This simple design avoids the complexity and costs of testing all possible combinations of multiple factors at the expense of missing how prompt choices influence each other. Other studies have used a 2 k factorial design with k binary prompt elements, which allows researchers to study both individual effects and interactions between factors efficiently at the expense of generating more prompts. For example, Zhao and colleagues tested a flat vs. hierarchical word representation (one binary factor) and whether to use a zero-shot approach that does not give information or to provide metaproperties documentation (another binary factor), resulting in a 2 2 design [94]. To date, no study has used a 2 k r factorial design, that is, an experimental setup that also accounts for randomness in the output by performing r repeats of each experiment.
In a 2 k experiment, the analysis involves decomposing the total variance in the outcome (e.g., the BLEU or ROUGE scores) into contributions from main effects (1st order, individual factors) and interactions (2nd order for pairs of factors, higher order for combinations). For example, in the 2 2 design above, results can be decomposed into the individual effect of word representation and documentation and their joint effect. Although the use of a factorial design is scarce to evaluate prompt elements in GenAI, this design of experiments is very well established in the simulation literature [95,96].

3. Materials and Methods

3.1. Overview

Our methods are divided into three main parts (Figure 3). First, we obtain data about the ABM (Section 3.2). Given a set of parameters, we run several simulations to obtain results from the model. We also extract data from the simulation file: we parse the documentation and the Graphical User Interface (GUI). Then, we generate a report using this information (Section 3.3). We transform simulation results into images and statistical summaries, thus leveraging the multimodal ability of the LLMs (Google’s Gemini 3.1 Pro Preview, Alibaba’s Qwen 3.5 27B, MoonshotAI’s Kimi K2.5, Anthropic’s Claude Opus 4.6) to generate a context and several trend analyses. A summarization algorithm reduces the number of paragraphs to the length suitable for an executive report. We optimize the prompt engineering process using a systematic Design of Experiments (DoE) to ensure the generated reports are both accurate and informative. Finally, we evaluate the report (Section 3.4) against full-length reports and a variety of summaries.

3.2. Data Extraction

An ABM that adheres to professional standards may include some documentation (e.g., at least a README file) and a minimal visual interface (i.e., the model is not solely driven from the command line). This provides potentially valuable information about an ABM, as it can explain its purpose or give context to its parameters. We thus extract this static data in addition to running the model to obtain dynamic simulation results. While our implementation uses ABMs coded in NetLogo, the automatic extraction process described below can be modified to accommodate other platforms.
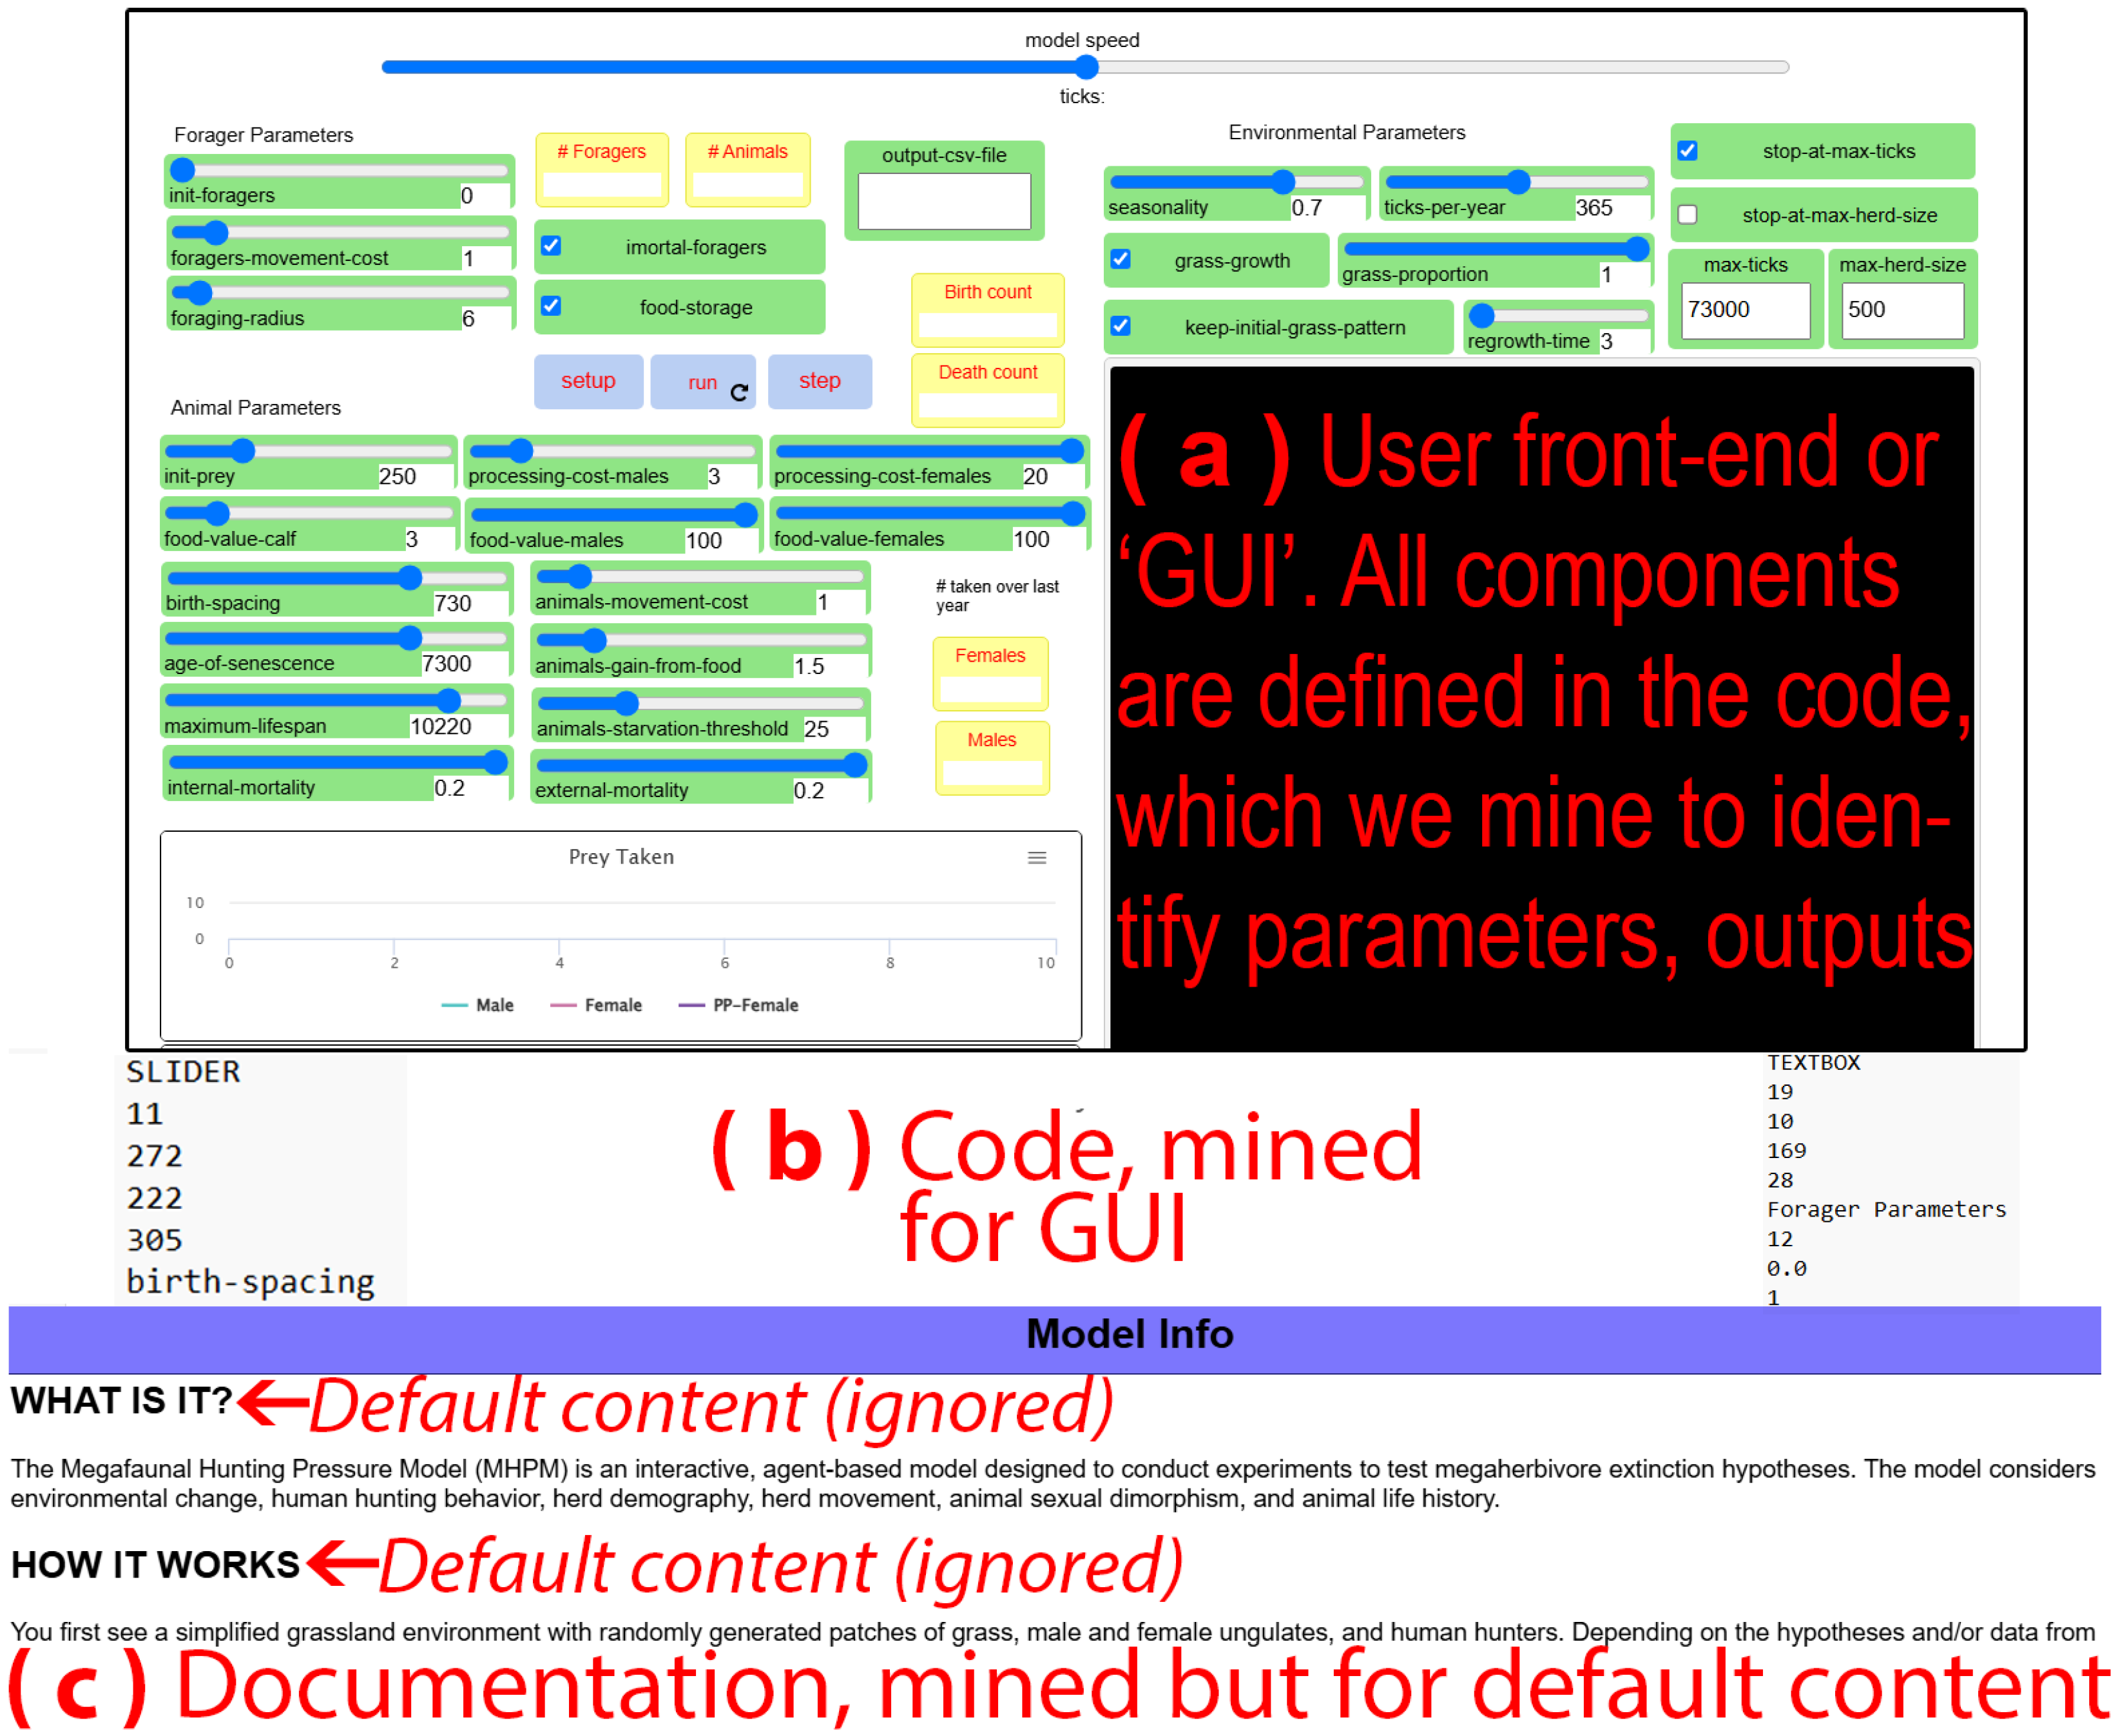
For the static data, we extracted two components (Figure 4). First, we parse the documentation, ensuring that we ignore any default content (e.g., default headers from NetLogo) so that the information extracted was written by modelers specifically for their model. We also ignore URLs, as they may lead LLMs to retrieve information from webpages that create hallucinations. Second, we parse the GUI to identify modifiable elements and their range of values (e.g., sliders) as well as default values. These settings tell us how to interact with the model to generate simulations. The extracted static data provide essential context for the ABM, and we organize it as a JSON file, since the hierarchical format can organize diverse elements like documentation and GUI configurations.
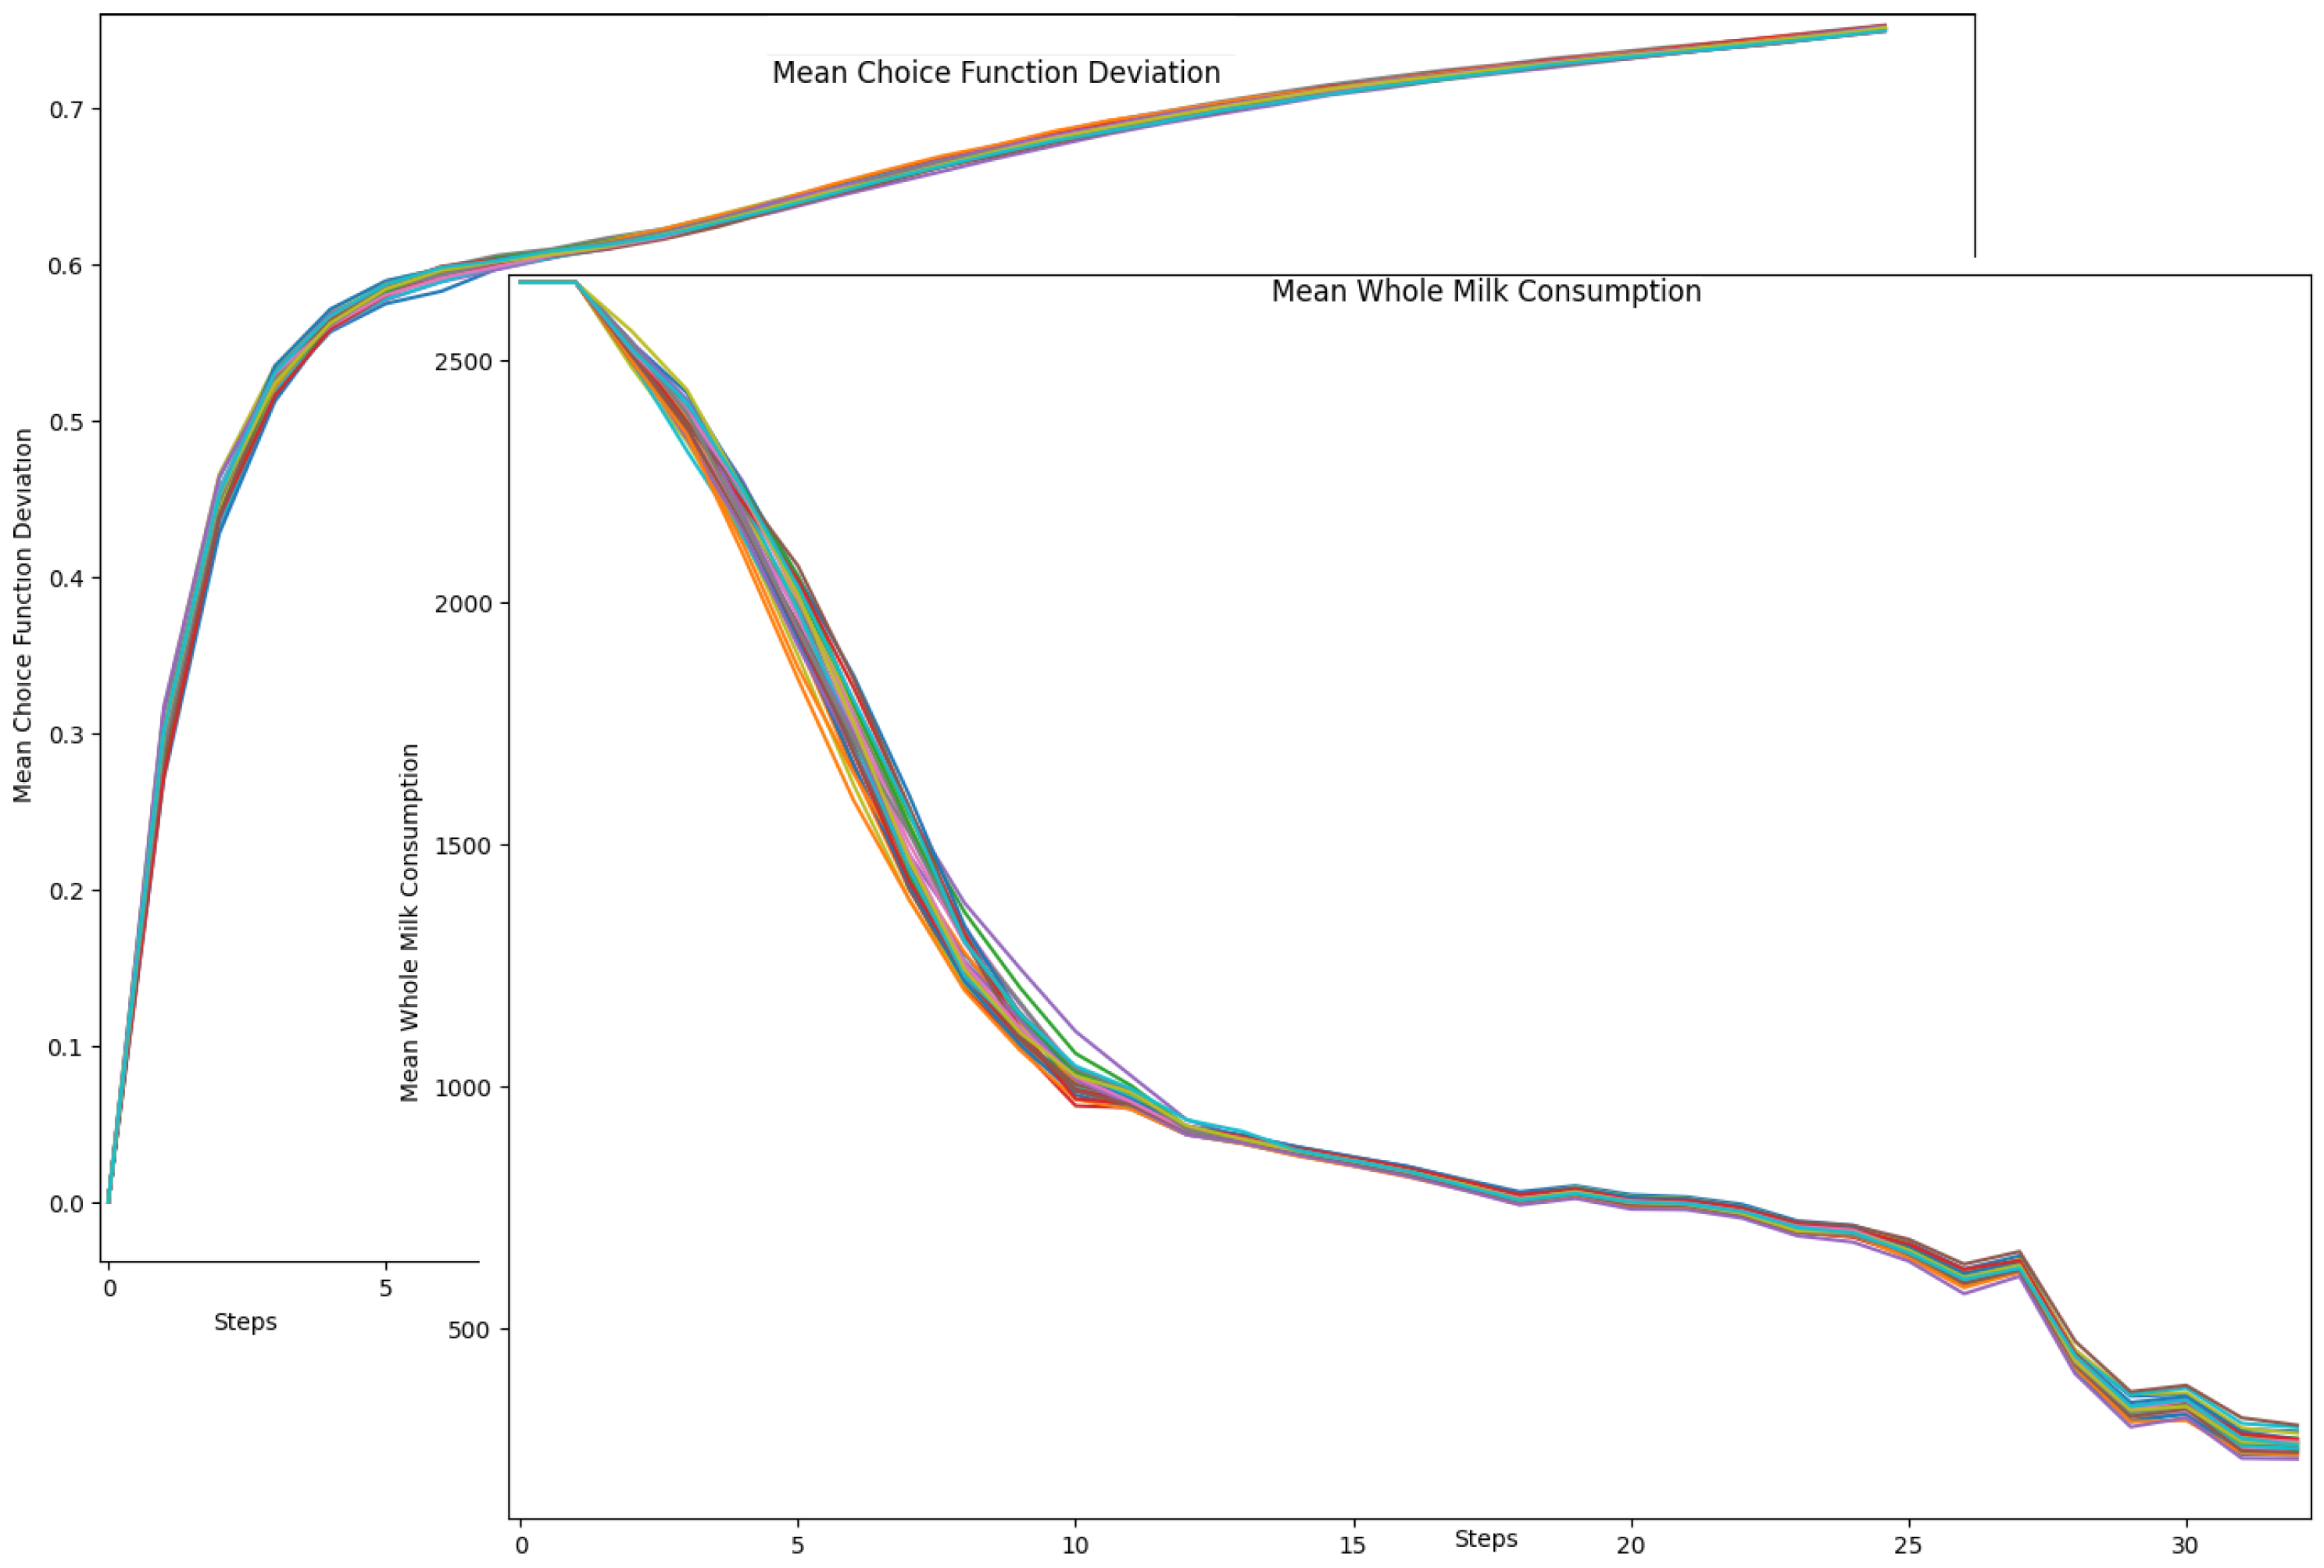
The dynamic data consist of simulations that we run. Thanks to information provided from the model, we identify initial parameter values, the metrics to follow through the experiment, and the halting condition. For example, a parameter is the ‘number of agents: 1000’, a metric is to ‘track the average quantity of milk consumed by the agents’, and a halting condition is to ‘run for 73,000 time steps’. We run simulations by piloting a model externally (i.e., from Python 3.12.2), and we save the results into a CSV file, as it provides a standardized format for storing and analyzing structured data.

3.3. Report Generation by Prompt Engineering

The report is generated in three steps. First, we generate the context (Prompt 1): the purpose of the model, key parameters, and experimental conditions. Second, we describe each of the simulation runs via Prompt 2; that is, the prompt is called repeatedly to transform each dataset into a narrative. Note that these two parts do not have a one-to-one mapping with the static and dynamic features discussed in the previous subsection: the context tells readers about the parameters (static) and how they have been set for simulations (dynamic), while the results (dynamic) are interpreted in light of the model’s structure and aims (static). Third, the descriptions produced by the two prompts are unrestricted in length, but an executive summary needs to be concise. We thus perform post-processing by considering both abstractive and extractive summarization (as well as a case without summarization to generate full length reports) along with cleaning steps for punctuations, repeats, and other symbols. The three parts are detailed in this section.

3.3.1. Prompts and 2 3 Factorial Design

The prompts can be formulated in several ways or include different types of content to support the LLMs in their task. The best options are not all known beforehand; thus, they need to be assessed experimentally (see Section 2.4). To this end, we systematically explored the search space of potential prompt elements by accounting for individual elements as well as their combinations. Our Design of Experiments includes two parts. First, our prompts contain three binary elements: we have two different choices for the role, example, and insight generation. The combinations are captured by a 2 k factorial design, where k = 3 covers the three binary prompt elements. Second, our prompts contain one element with three levels rather than a binary: we can provide simulation outputs to the LLM as visuals, as statistics, or using both. We thus have a 2 k × 3 design where the three binary prompt elements are crossed with a three-level evidence factor. By recording the results for each of these combinations, we assess the effect of the features both independently and in interactions to (i) find the best prompt and (ii) assess which features contribute to prompt effectiveness.
In the following prompts, we use the format «element» to indicate a dynamic element whose value is populated based on the corresponding variable in the experimental design. For example, «Role» would be populated by one of two values for the binary role when the prompt is created. We use the notation «a|b|c» to indicate short options. The prompts are also populated based on the extracted data, which are shown as [data]. Supplementary Material S1 provides a sample instance for the prompts, illustrating how the dynamic elements are replaced by specific instructions.
Prompt 1 sets the task. The only prompt element changed by the experimental design is the role, which is also known as ‘persona’ [88,97]. By telling the LLM that it is an expert in a specific domain, we guide its tone, style, and type of response. We noticed that LLMs tended to go beyond the task of providing a context as they included summaries or conclusions, which were not only unnecessary but also occasionally erroneous since they did not account for simulation results. To prevent LLMs from making broad generalizations just based on the goal of a model and its parameters, we explicitly request not to write any summary or conclusion.
Bdcc 10 00121 i001
Prompt 2 describes the data from the simulation, one variable at a time, which is the appropriate place to make conclusions based on evidence. In addition to the role, this prompt has three dynamic elements. The example illustrates the style of an executive report for simulation models; a sample is provided in our Supplementary Material (page 8, “Here is an example of the style of the report:”). The insight adds “When summarizing trends, provide brief insights about their implications for decision makers.” In principle, a summary tells the reader what is there while insights explain why it matters. However, requesting insights might lead the LLM to hallucinate by seeing causality where the data does not support it (since LLMs are based on patterns in data rather than genuine comprehension [98]), or their tendency to prioritize interesting findings may give the summary a suddenly dramatic flair. Finally, we specify whether data are provided as visuals and/or as statistics, as explained below. Note that the literature has demonstrated the potential of generating insights via LLM when the data consist of a single table, the goals are clear, and the data are clean—as is the case in this paper. If the LLM is intended to navigate a database (e.g., multi-hop reasoning that joins databases), goals are unknown, and the data need fixing (e.g., missing values), then our workflow would need to be revised with an additional processing step. For example, a hypothesis generator can create potential insights [99], which are tested against the data by a query agent [100].
Bdcc 10 00121 i002
Simulation results were extracted as structured data (see Section 3.2), which leaves three options to pass them to the LLM: (i) provide the raw CSV files; (ii) provide visuals as time series; or (iii) provide statistical summaries. While LLMs can interpret results and generate insights, they are not designed for statistically rigorous analyses of numerical accuracy at scale, as a large amount of data may exceed their context size [101], and researchers continue to report issues in directly processing structured data [102]. Having ruled out a direct upload of simulation outputs per option (i), we focused on supporting the next two options. Note that they are not mutually exclusive: we can provide visuals, or we can provide statistics, or both. Uploading time-series images to an LLM can quickly extract high-level insights, especially when trends and anomalies are visually clear. While not as precise as statistical tools, the vision ability of LLMs can identify patterns and generate hypotheses efficiently, which addresses the need to communicate findings in an executive report. We thus supported option (ii) by automatically generating plots from the simulation data and providing them along with the prompt (Figure 5).
To support option (iii), we extracted seven categories of statistics as listed in Table 1. The output of each simulation run is represented as a one-dimensional time series, where each entry corresponds to the value of the system state at a given discrete simulation tick. The signals from multiple simulations are aggregated by computing the tick-wise mean across runs; then, we analyze the aggregated signal using complementary methods drawn from signal processing, non-parametric statistics, and time-series segmentation in order to identify significant structural features such as extrema, inflection points, trends, regime changes, and oscillatory behavior. Basic descriptive statistics include the number of samples, mean, median, variance, standard deviation, and the locations and values of the global minimum and maximum. These summary statistics provide a coarse characterization of the signal’s scale and dispersion. Then, the peak detection algorithm evaluates each point relative to its neighbors and returns the indices of candidate maxima. Additionally, the peak prominence characterizes the magnitude of each peak. Valleys are detected by applying the same algorithm to the negated signal, which effectively transforms minima into maxima. These extrema provide a discrete representation of the signal’s most salient events. We also identify inflection points, which correspond to changes in the curvature of the signal, that is, when the second derivative of the signal changes sign, marking transitions between concave and convex behavior. These locations often correspond to turning points in the system dynamics. Since numerical differentiation tends to amplify high-frequency noise, we first smooth the signal using a Savitzky–Golay filter (which preserves information unlike smoothing by averaging), which performs a local least-squares polynomial fit within a sliding window (set to 10% of the data) and evaluates the fitted polynomial at the center of the window. We set the window size to 10% of the data with three constraints: we need at least 5 data points (to avoid windows that are too small to perform smoothing), we need windows with odd lengths (required by the Savitzky–Golay filter), and we clip to ensure that we stay within the data (e.g., the first two constraints could otherwise request more data points than are available). Because the polynomial representation is differentiable, the filter can compute derivatives directly. That is, the second derivative of the smoothed signal is computed directly from the fitted polynomial, and inflection points are detected by identifying locations where the sign of the second derivative changes.
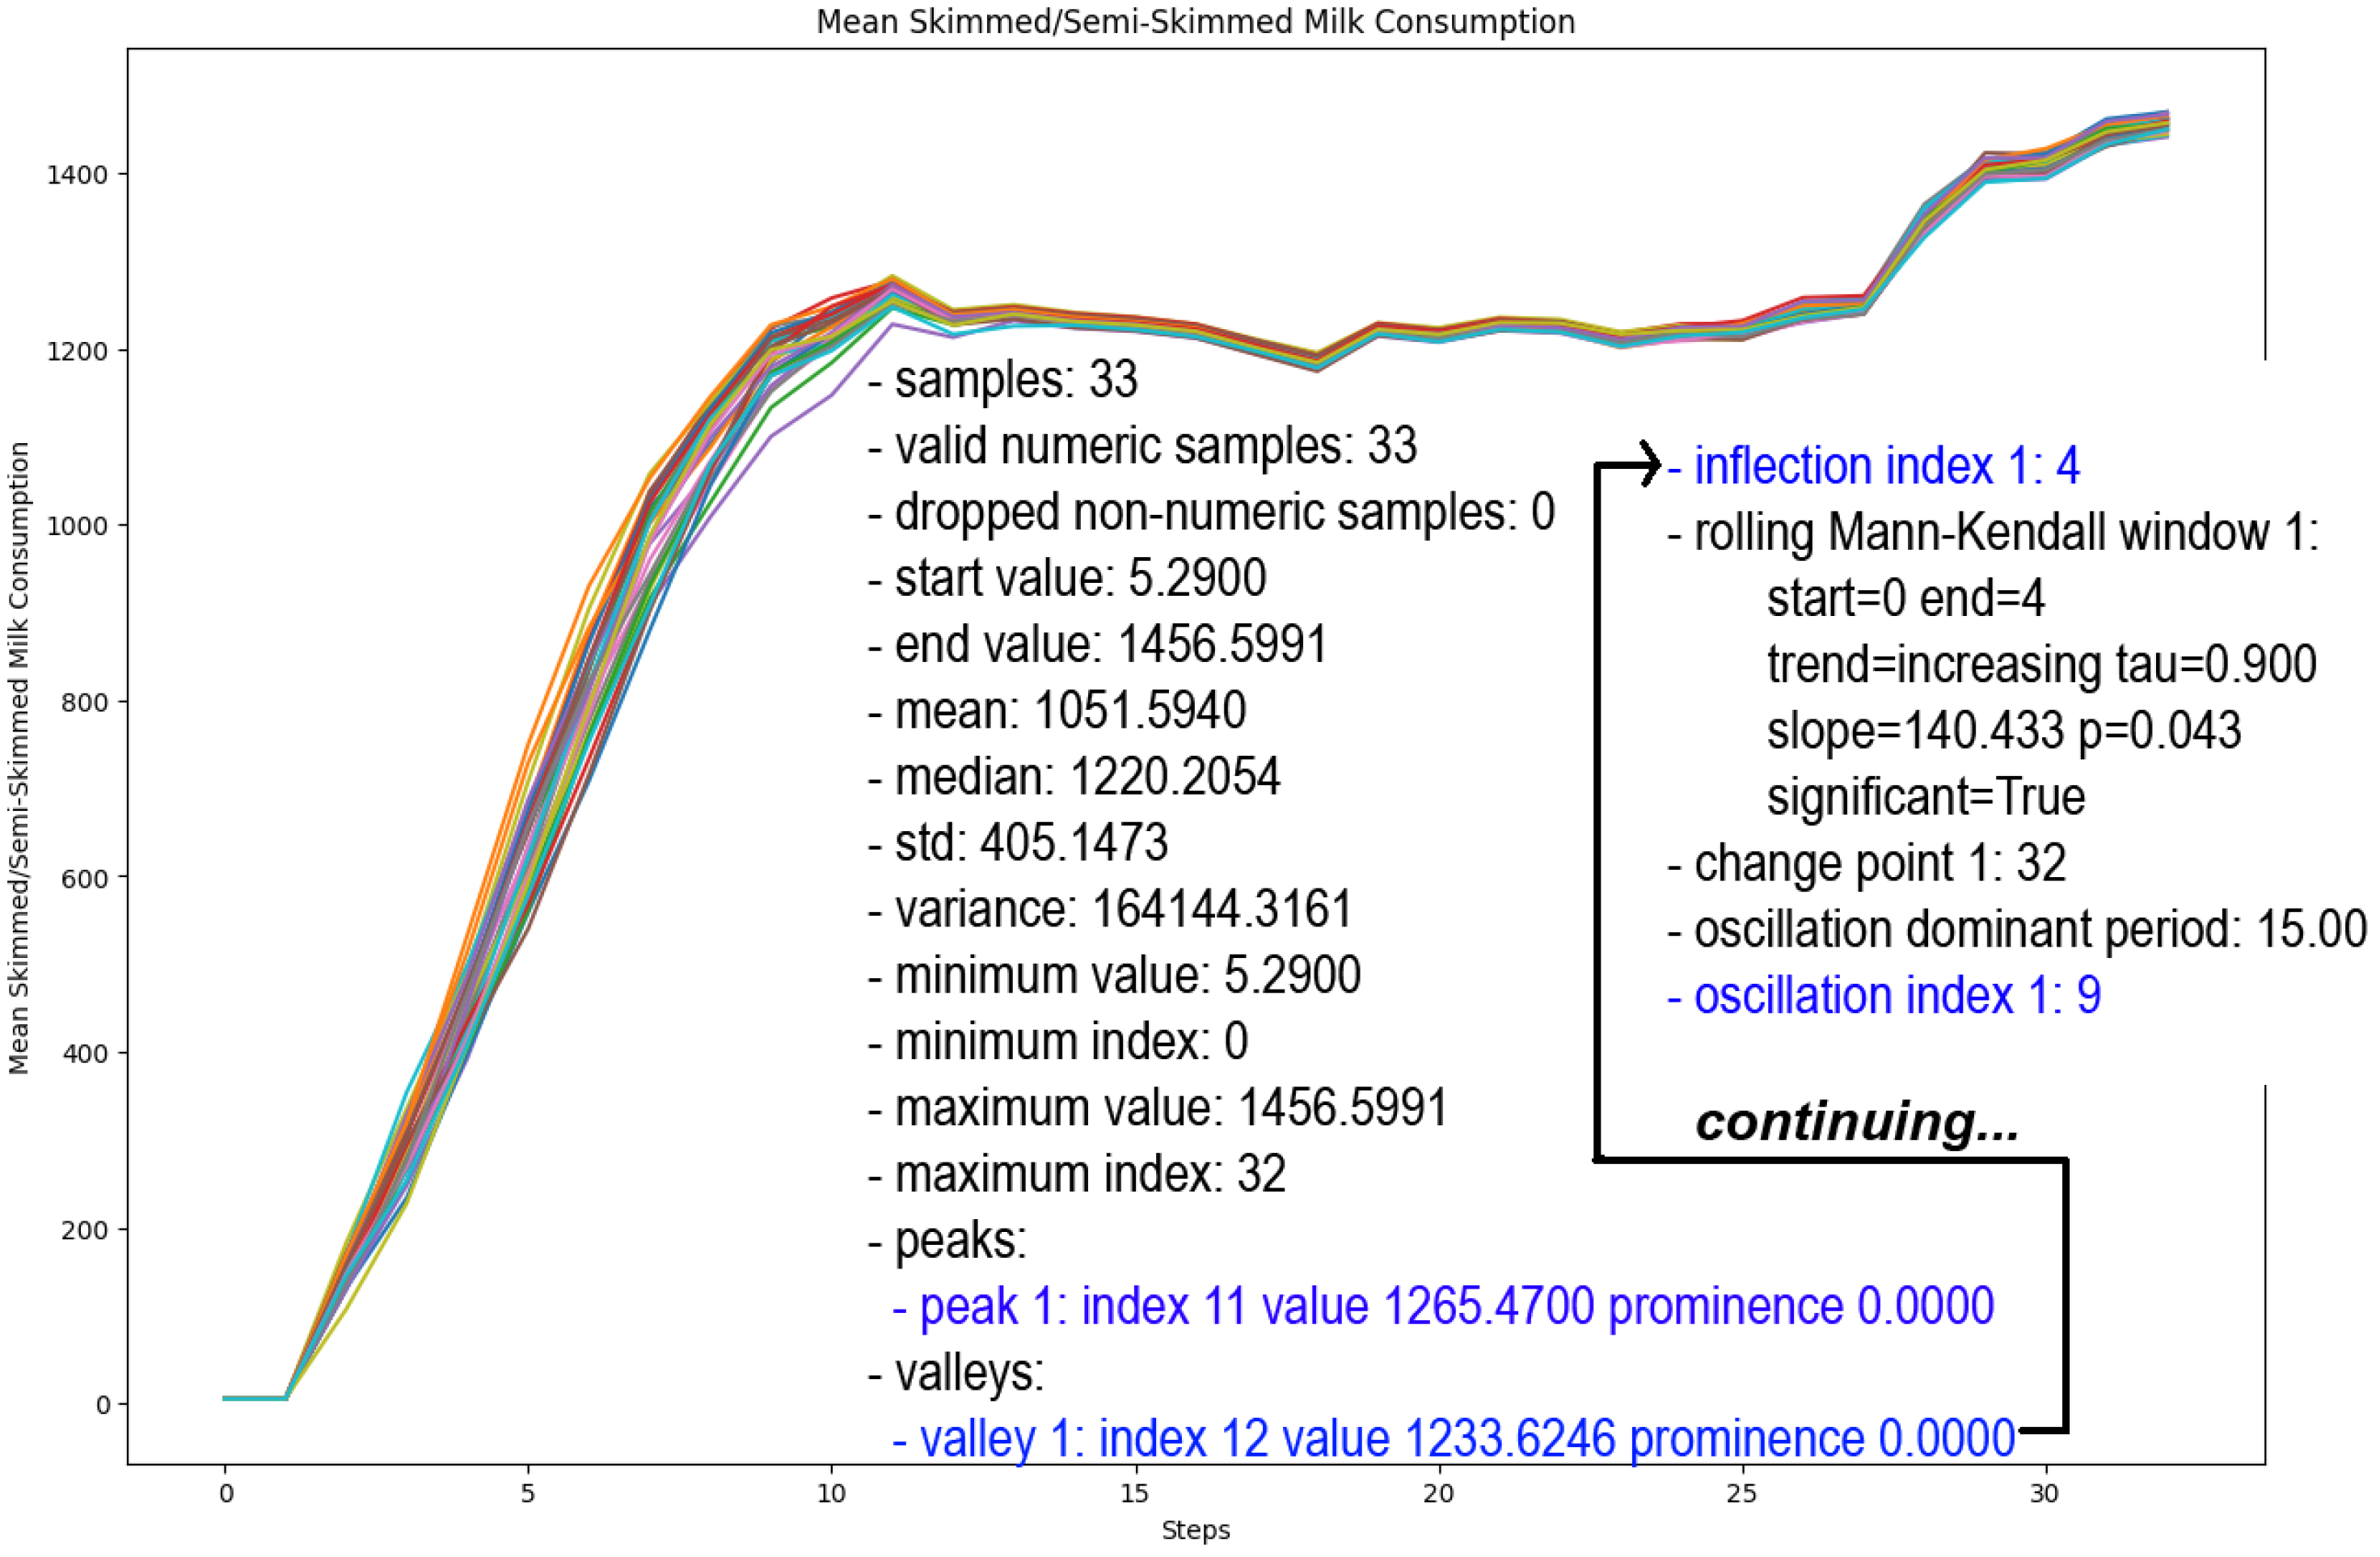
To characterize directional changes in the signal, we use the non-parametric Mann–Kendall statistical test that evaluates whether a time series exhibits a monotonic upward or downward trend. The statistic is normalized to produce Kendall’s τ , which measures the strength of the monotonic association between time and the signal value. To estimate the magnitude of the trend, the test also computes Sen’s slope estimator, which is a non-parametric estimate of the slope that is robust to outliers and does not assume normally distributed residuals. Since we are not interested in determining whether the entire time series follows a single global trend, but rather to identify local trend regimes, we apply the Mann–Kendall test in non-overlapping windows spanning 10% of the data. Again, the window sizes account for constraints such as having at least 5 data points. Windows containing constant values may lead to undefined statistical quantities in the Mann–Kendall test, so we detect and skip cases with fewer than two unique values, thus ensuring that the analysis does not produce misleading trend estimates. To identify abrupt transitions in the statistical structure of the signal, we perform change-point detection with the PELT (Pruned Exact Linear Time) optimization method. This method combines dynamic programming with pruning rules to discard sub-optimal solutions, which allows it to scale well with large datasets. Finally, we identify oscillatory regimes using Continuous Wavelet Transform (CWT). Traditional spectral methods such as the Fourier transform assume stationarity and therefore cannot localize oscillations in time, so we use wavelet analysis to project the signal onto a family of localized wavelet functions that are scaled and translated across the time axis. In this paper, a Morlet wavelet is used because its shape resembles a localized sinusoid and is therefore well suited for detecting periodic structures. An example of a plot and derived statistics is provided in Figure 6. Statistics were provided as a list of key:value pairs with one statistical information per line.

3.3.2. Post-Processing

In line with best practices, we ask the LLM to first generate a full response (i.e., without constraints on lengths); then, we summarize it. The responses can be particularly long, since each variable is either depicted as a visual and/or conveyed as a statistical summary, which are transformed into text. For example, if an ABM has 15 variables, then we create 15 CSV files (each comprising several runs), leading to 15 complete descriptions through Prompt 2. Our process thus consists of generating one output for the context, one output for the trend of each variable (e.g., from 10 to 14 trends depending on the ABM), concatenating all these outputs to create a full length report, and then using a summarization algorithm to produce the summary.
We considered four summarization algorithms, which cover the two main types of techniques: T5 and BART for abstractive summarization and Longformer and BERT for extractive summarization (see Section 2.3). Because of its extractive approach, BERT may combine ‘fragments’ to form sentences. This required further automated corrections including punctuation, spaces in parentheses, hyphens, or setting the first letter of each sentence to upper case. We also identified cases in which a summarization algorithm (e.g., LongFormerExt) produced loops of text, such as “This uniformity in the rate of choices made implies that the agents are continuously evaluating and possibly reevaluating their milk consumption choices, which are influenced by their perceptions, habits, and social interactions. The rate of change in the rate of change in the rate of change […]”. Our final step of post-processing was thus to remove repetitions, which were identified as consecutive identical sentence fragments.

3.4. Evaluation: Comparing LLM Outputs with Reports and Quantifying Readability

We evaluated the output of an LLM using six metrics. The Flesch Reading Ease computes the readability of the report [85], and it does not need a reference report. Reference reports are used to compute five scores (Section 2.3): BLEU [79,103], METEOR, ROUGE-1, ROUGE-2, and ROUGE-L [80,103]. We created four reference reports for each ABM, and all reports are provided for full disclosure in Supplementary Material S2:
  • A summary was jointly written by the authors for each ABM to serve as a ground truth reference. We wrote the summary given the same information as was available to the LLMs, including the time series from each simulation run. These summaries were all written prior to generating text via LLMs, thus ensuring that the ground truth reference provided by our summary was not ‘contaminated’ by sentences that we may read in the LLM output. We refer to these summaries as ‘authors’ in our results and on the files provided in Supplementary Material S2.
  • A summary was written for each ABM by independent associate professors with several peer-reviewed publications on agent-based modeling. That is, the summary for each ABM was written by a different modeler. To ensure consistency in the task, we created the same onboarding form for the modelers, varying only the content of the ABM. From hereon, these summaries are labeled as ‘modelers’ in our results and in Supplementary Material S2, which also contains the onboarding forms.
  • We generated a full report and a summary as follows. We adapt the prompts shown in prior sections to rely on articles instead of the ABM documentation, and we use a state-of-the-art LLM that we did not use in our experimental setup (to avoid the output of an LLM being compared to itself) to generate the description of each plot. As a means to also demonstrate that reports could be produced without documentation from the ComSES.net repository or the NetLogo code, we used contextual augmentation by providing the peer-reviewed article for each ABM in the prompt. We corrected the descriptions of each plot to ensure factuality. Then, these descriptions were combined into a long report (note that it is the only material for comparison that is not a summary), which we call ‘long LLM’ from hereon. Finally, these reports were summarized into a short form using the same state-of-the-art LLM, resulting in the document named ‘short LLM’. We used OpenAI’s GPT 5.2 Thinking (released in December 2025) for this task. Our prompts and the LLM’s raw responses are shown in Supplementary Material S2, where our manual corrections are highlighted. For the fauna model, we made 6 corrections to the values reported in the curve, and we added two sentences on noticeable trends (out of 14 plots). For the milk model, we expanded two sentences and corrected fifteen values (out of 12 plots). No changes were needed for the grazing model.

3.5. Screening and Optimization Design

A commonly used Design of Experiments proceeds in two stages. First, a screening design can perform a large number of experiments (e.g., a 2 k factorial analysis with large k) to identify potentially important factors and interactions using a cost-efficient estimator. As a result, we may learn which factors can be fixed or dropped. For example, if we find that the summarization algorithm has a very large impact and that some algorithms offer clearly more compelling design choices, then we can set them accordingly. In the second stage, the optimization design (or ‘refinement stage’) then proceeds with a smaller search space by focusing on the remaining active factors, using a higher-cost estimator so that predictions are closely aligned with performances in deployment. Intuitively, the early stage offers a broad exploratory design that is only afforded through low-cost estimators, while the later stage focuses on a narrower search space with higher fidelity estimators. Our approach proceeds with these two stages as follows.
For the screening stage, we comprehensively examine a broad range of factors and their interactions using leading open-weight models (a large language model and a smaller model) as cost-efficient estimators. Each of these two models serves to examine 360 combinations of experiments corresponding to 2 3 combinations of prompt designs (the binary prompt elements regarding role, insight, and example) across five summarization approaches (none, BART, BERT, T5, LongFormerExt) and three approaches to present evidence (as a plot only, as a statistical table only, or both) for the three ABMs. Each experiment is performed three times to account for stochasticity, that is, we have an experimental design with replications. Note that each run of an experiment further involves several calls to a model: the LLM is prompted once for the context and then once per plot over 10 to 14 plots depending on the ABM. Across the two models, we thus generate approximately 2 × 360 × 3 × 12 25,920 prompts, where the 12 indicates the average number of variables encountered across ABMs in our case studies (see Section 4.1). As a result of the screening stage, we can comprehensively examine the influence of prompting elements, summarization approaches, and approaches to present evidence. Based on the experimental results, we thus set some of these choices to proceed with the second stage, in which we use the best available LLM based on current benchmarks to provide estimates of overall performance.
Note that our approach for a multi-step cost-efficient design echoes several practices in the LLM literature. Recent studies have indeed demonstrated the benefits of multi-stage cost-efficient optimization strategies. For example, we can start by prototyping and eventually culminate in using state-of-the-art models for deployment [104]. This idea is echoed by FrugalGPT [105] and LLM cascades, where the authors preserved performances but reduced costs by 60% by using cost-efficient LLMs to handle queries and only escalating them to a higher cost model when needed [106].

4. Results

4.1. Experimental Setup

We used four LLMs and three ABMs. The three ABMs were sourced from peer-reviewed publications created by different research groups and covering various topics in order to evaluate the ability of our approach across application domains. The ABMs had to be adequately documented in order to provide sufficient context for our LLMs to operate. Given these criteria, we used three ABMs from the ComSES.net repository:
  • The Megafaunal Hunting Pressure Model (MHPM) by Ullah and colleagues (Figure 4), which was released in late 2024 to “understand how environmental dynamics and human predation preferences interact with ungulate life history characteristics to affect ungulate population dynamics over time” [107].
  • The Milk Adoption ABM from Gibson et al. [108], which was designed to evaluate different mechanisms of consumer decision making in milk choice substitution to better understand and replicate historical trends in British milk consumption as a step toward modeling sustainable dietary shifts.
  • The extended RAGE model [109], which explores how different types of learning (learning-by-doing and social learning) and varying attitudes toward risk influence smallholder farmers’ decisions about livestock management and the resulting outcomes for their livelihoods and the environment.
We chose four multimodal LLMs based on their state-of-the-art performances in their respective categories: proprietary LLMs, open-weight LLMs, and a smaller model. Gemini 3.1 Pro Preview was introduced by Google in February 2026. The Arena text and vision leaderboards (as of 4 March 2026) showed that Gemini 3.1 Pro Preview significantly improved over its predecessor, Gemini 3 Pro, as well as over competing models such as GPT-5.2 [110]; this trend was corroborated by other benchmarks [111]. It was considered to be the leading multimodal LLM at the time of its release on several benchmarks [112]. On the same benchmarks, Moonshot AI’s Kimi K2.5 (released in late January 2026) was the leading open-weight multimodal LLM [113]. Anthropic released Claude Opus 4.6 in February 2026 and also reported very strong performances across benchmarks [114]. Finally, Alibaba released the open-weight Qwen 3.5 in early 2026 [115], which quickly became a popular small language model in its 27B version, outperforming GPT 5 Mini [115]. All LLMs used the hyper-parameter settings recommended by the provider; e.g., we set the temperature to 1. Our experimental setup runs all LLMs through https://openrouter.ai/. For replicability, the libraries used in each part are summarized in Table 2.

4.2. Screening Stage: Moonshot AI’s Kimi K2.5 and Alibaba’s Qwen 3.5 27B

4.2.1. Impact of Experimental Design Factors

Table 3 reports the statistically significant effects of experimental variables across the evaluation metrics. Among all factors, the choice of summarization algorithm consistently exhibits statistically significant effects across every metric. This result is expected because except for the ‘long LLM’ baseline (which evaluates an unsummarized report against a full-length reference), the final text used for evaluation is the summary. Consequently, the summarization step directly determines the lexical structure, sentence selection, and level of compression of the evaluated output, which naturally affects metrics based on lexical overlap (BLEU, METEOR, ROUGE) as well as readability. The ABM and the LLM also frequently show statistically significant effects. This indicates that the results depend partly on the characteristics of the application domain and on stylistic differences between language models. In particular, the three ABMs differ in the number of variables, the complexity of their dynamics, and the domain vocabulary involved, which may influence how easily trends can be described and summarized. Likewise, different LLMs may vary in writing style, verbosity, and the interpretation of prompts, which can affect both lexical overlap metrics and readability scores. The type of simulation evidence provided to the model (statistics, plots, or both) has limited impact on BLEU and METEOR when operating on summaries, but it shows statistically significant effects on the other metrics. This suggests that while the form of evidence may not substantially alter the specific n-grams used in the summaries, it may influence how the LLM structures the explanation of trends and emphasizes particular aspects of the data, thereby affecting other evaluation measures.
In contrast, the prompt engineering factors tend to exhibit weaker or less consistent effects. Providing examples appears to be the least significant construct by itself. However, these results should be interpreted cautiously, as prompt variations may interact with other factors or influence aspects such as tone, framing, or narrative structure that are not fully captured by lexical overlap metrics. Interestingly, when comparing these results with Table S2 in Supplementary Material S1, we observe that newer LLMs appear to be sensitive to a larger number of prompt elements. In the earlier experiments conducted with GPT-4o, Claude 3.5 Sonnet, and DeepSeek R1 7B, none of the three prompt elements had statistically significant effects except on reading ease. In contrast, the newer LLMs used in this paper show significant effects for roles and insights on several ROUGE metrics. This suggests that recent models may be more responsive to prompt design, potentially reflecting improvements in instruction-following capabilities.
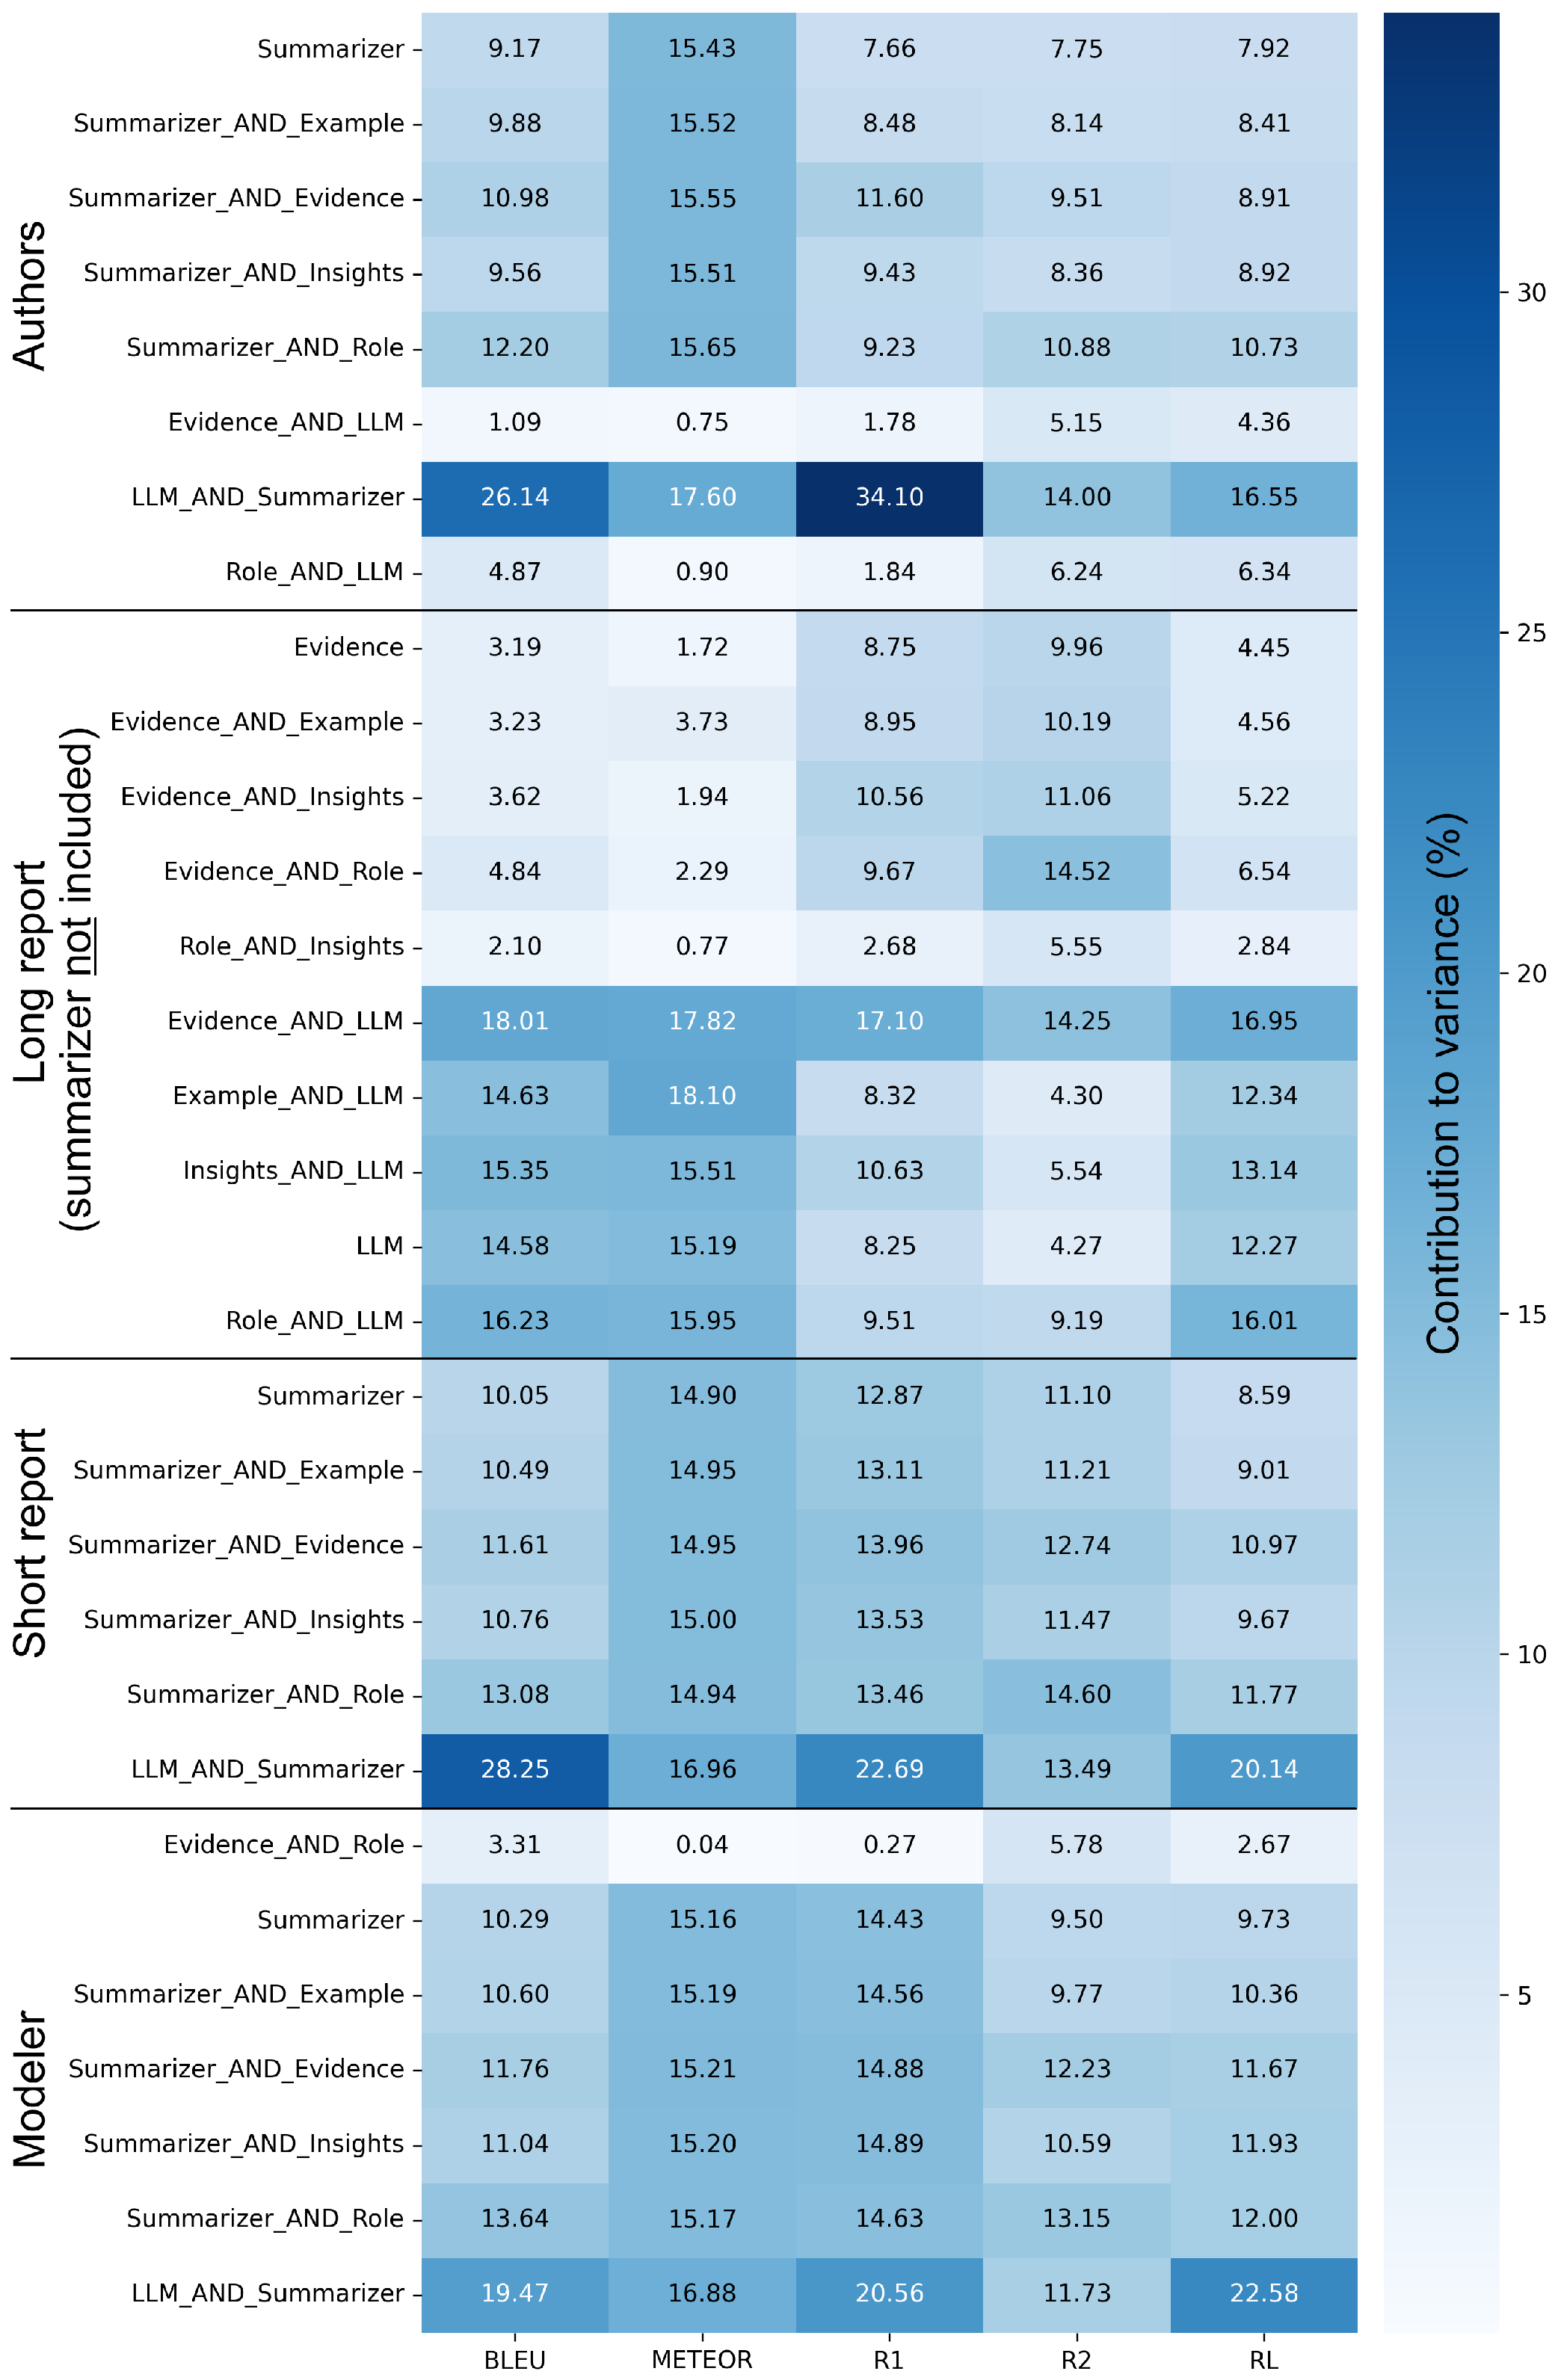
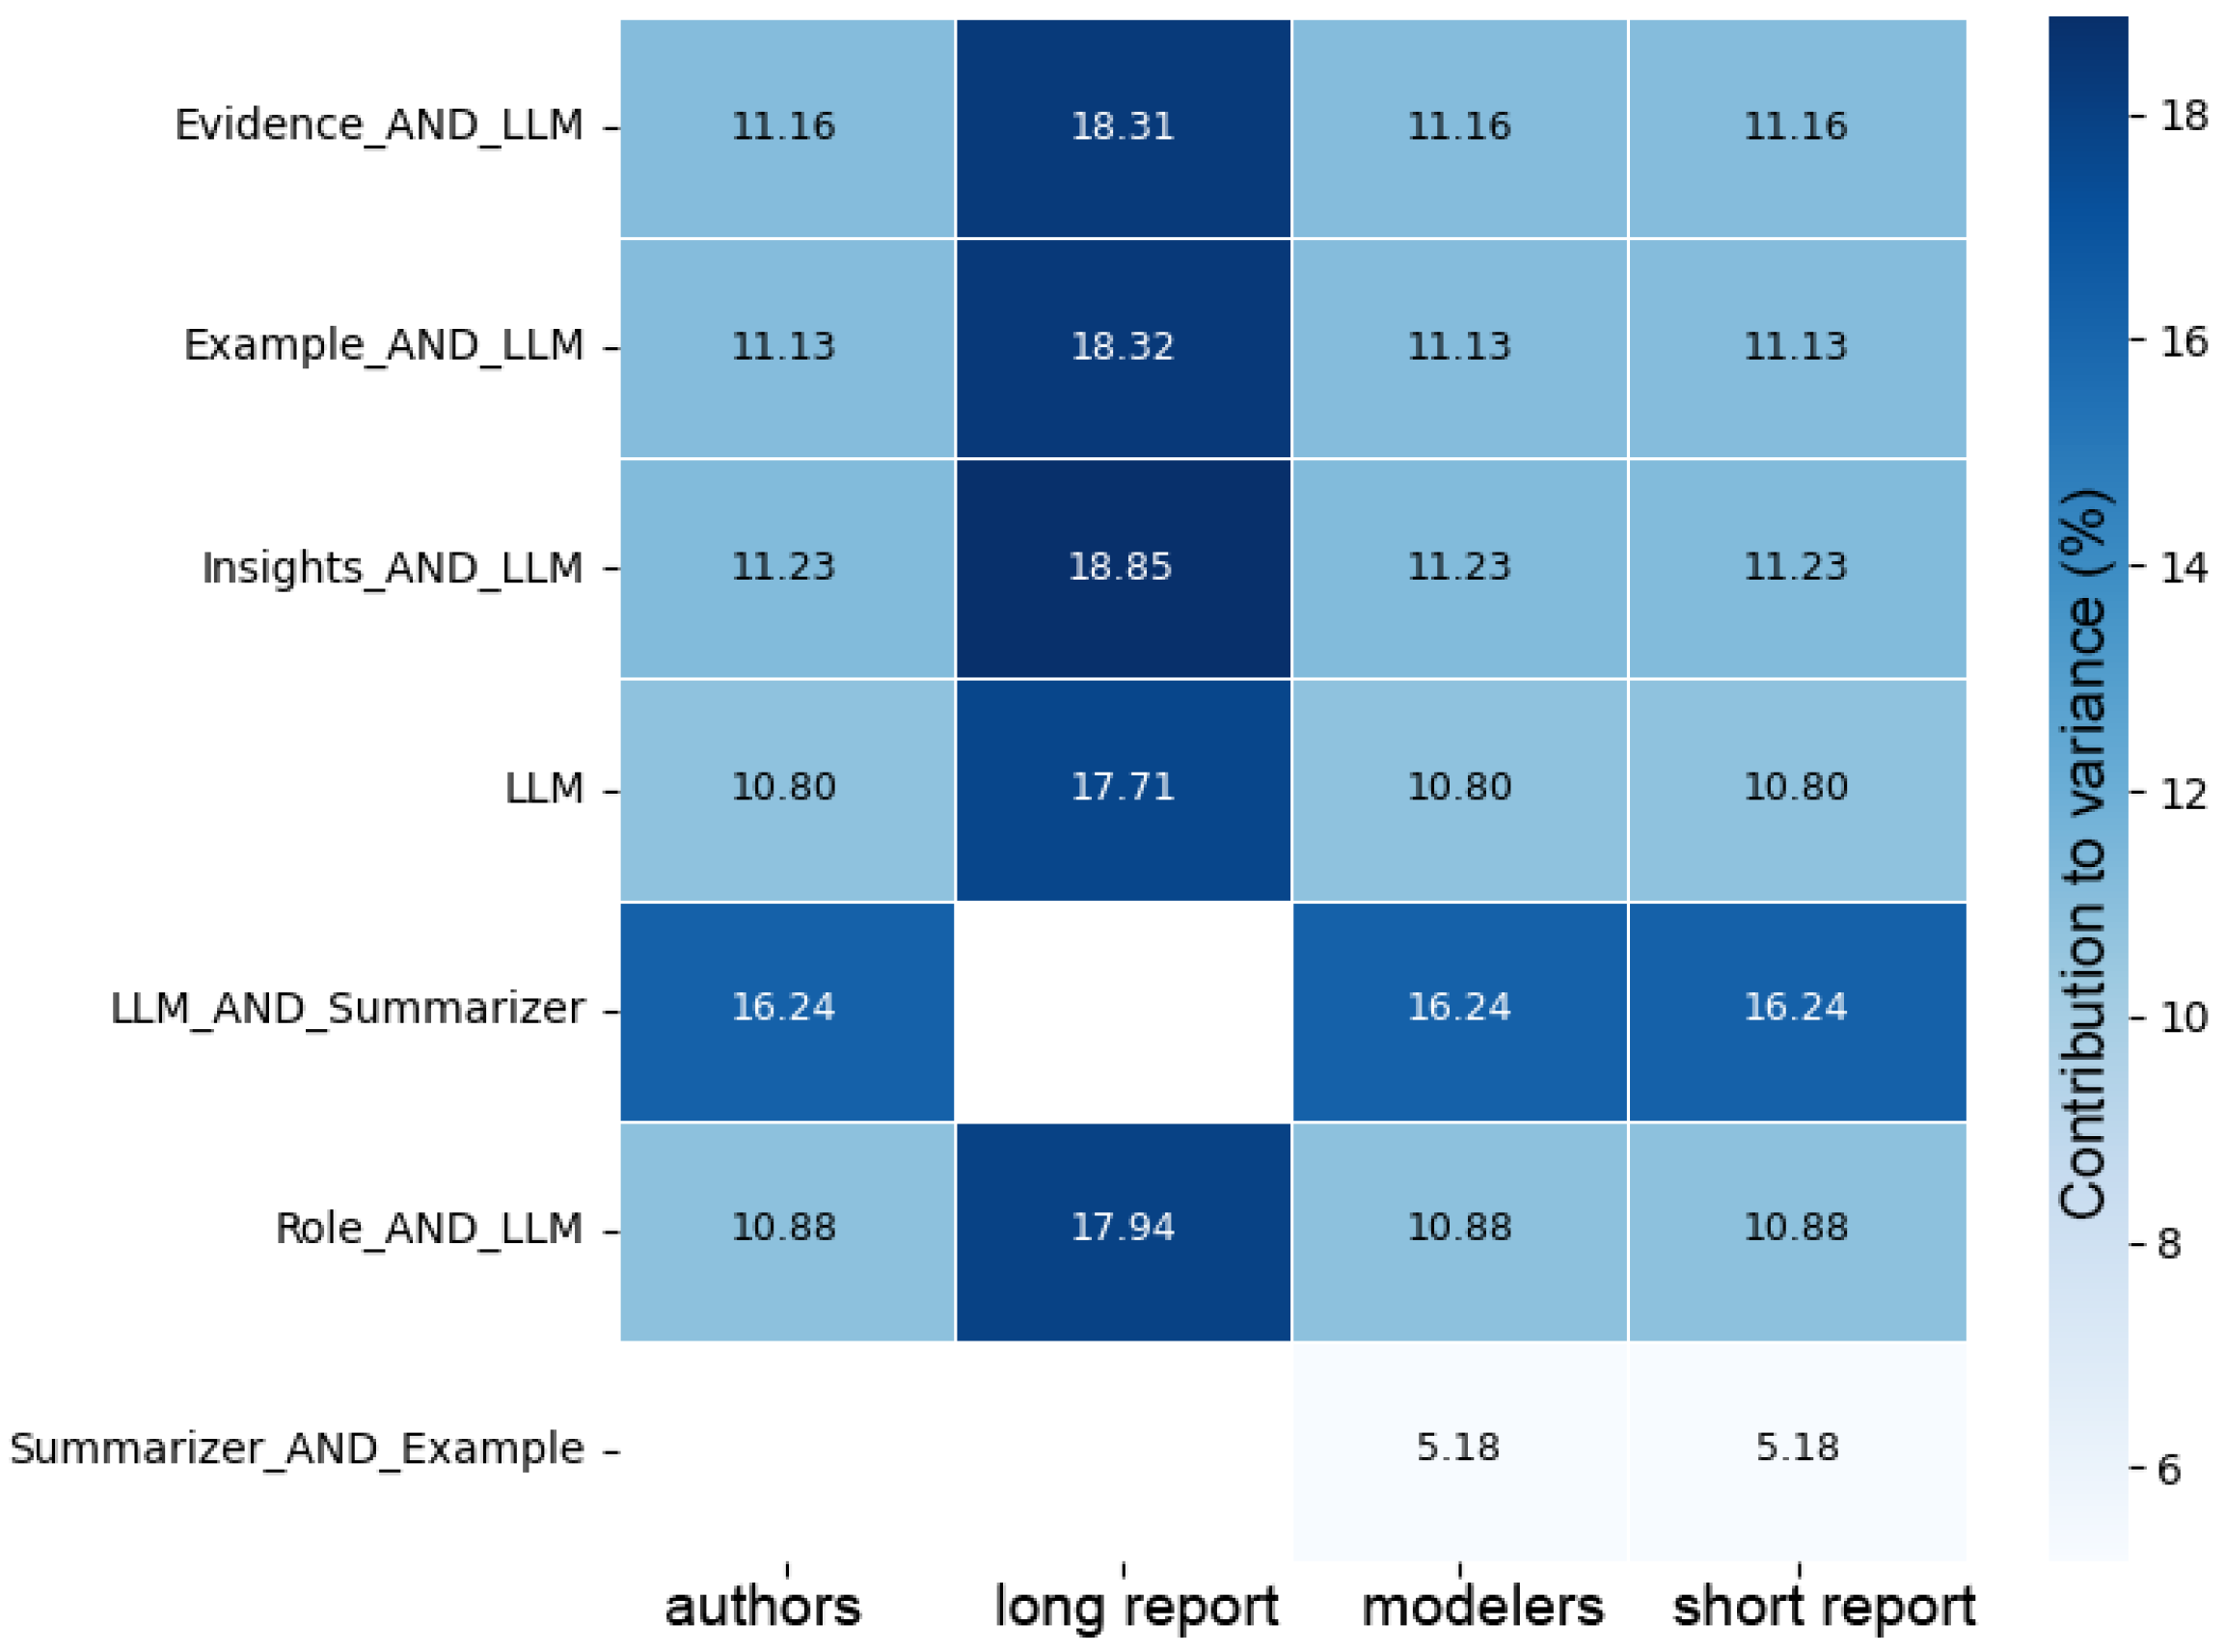
While the ANOVA analysis identifies which experimental variables have statistically significant effects on the evaluation metrics, it does not fully characterize the structure of these effects. In particular, statistical significance alone does not indicate the relative magnitude of each factor’s contribution to the variability of the results nor does it capture how factors interact with each other. This distinction is important in our setting because several components of the pipeline (e.g., prompt design, summarization algorithms, choice of LLM) may influence the final report jointly rather than independently. For example, the impact of a prompt element may depend on the summarization method used or on the LLM generating the text. To better understand these relationships, we therefore analyze the experimental design using a factorial decomposition of variance (Figure 7 and Figure 8). This approach quantifies the proportion of variance explained by each factor and by pairwise interactions between factors.
Given the results from the variance decomposition, we have four observations. First, the summarization algorithm is the most influential individual factor for lexical-overlap metrics (Figure 7), typically explaining around 9–15% of the variance depending on the reference material. This reflects the central role of the summarization step in shaping the final text evaluated by BLEU, METEOR, and ROUGE. Second, the largest effect overall arises from the interaction between the LLM and the summarization algorithm, which explains up to one third of the variance depending on the metric. This indicates that summarization performance depends strongly on the textual characteristics of the underlying LLM output, such as verbosity and narrative structure. Third, the individual prompt elements (examples, insights, and role) contribute relatively small proportions of variance, typically below 5% for lexical metrics, although their interaction terms are more visible for readability (Figure 8). Finally, the representation of simulation evidence and the identity of the LLM contribute moderate yet consistent effects, particularly for readability metrics, reflecting stylistic differences between models and variations in how simulation outputs are interpreted. Overall, these patterns are consistent across the different materials used as ground truth. These results indicate that the pairing of LLMs and summarization is essential in determining report quality.

4.2.2. Optimal Performances

What is best depends on how we look at it. We performed a one-way ANOVA and a Kruskal–Wallis test comparing the distributions of evaluation scores across the four types of reference materials (summaries by authors, modelers, or GPT; or a long report) and found a statistically significant effect (p < 0.01) from the reference family onto all metrics except reading ease. That is, how to create the ‘best report’ depends on the material against which it is judged. Since the previous section revealed the importance of the summarization algorithm, we also examined whether a best algorithm could systematically be found. That is, we assessed the stability in ranking of summarization algorithms across contexts defined by the type of reference material, ABM, and LLM. While ranking stability was high for METEOR (mean Kendall’s τ = 0.76) and reading ease (mean τ = 0.85), it was low for BLEU and ROUGE metrics (mean τ from 0.16 to 0.26), which means that further analyses are needed to identify a best summarization method.
We combined three complementary screening analyses to identify promising configurations (Table 4):
  • We aggregated ANOVA results across evaluation metrics and reference formats to determine how often each experimental factor shows a statistically significant effect. The goal is to establish whether a factor reliably alters evaluation outcomes. For example, the choice of summarization algorithm was statistically significant for all metrics and across all reference summaries. This indicates that changing the summarizer systematically changes report quality, making it a primary factor that would be varied during our next stage of optimization.
  • We aggregated factorial contribution tables that quantify how much variance each factor explains when both main effects and pairwise interactions are considered. For instance, the role instruction does not always appear dominant in the ANOVA tables, yet its interaction with the summarization algorithm or with the LLM can account for a substantial portion of performance variability. This indicates that the effect of role is conditional: it shapes outcomes indirectly by modifying how other components operate.
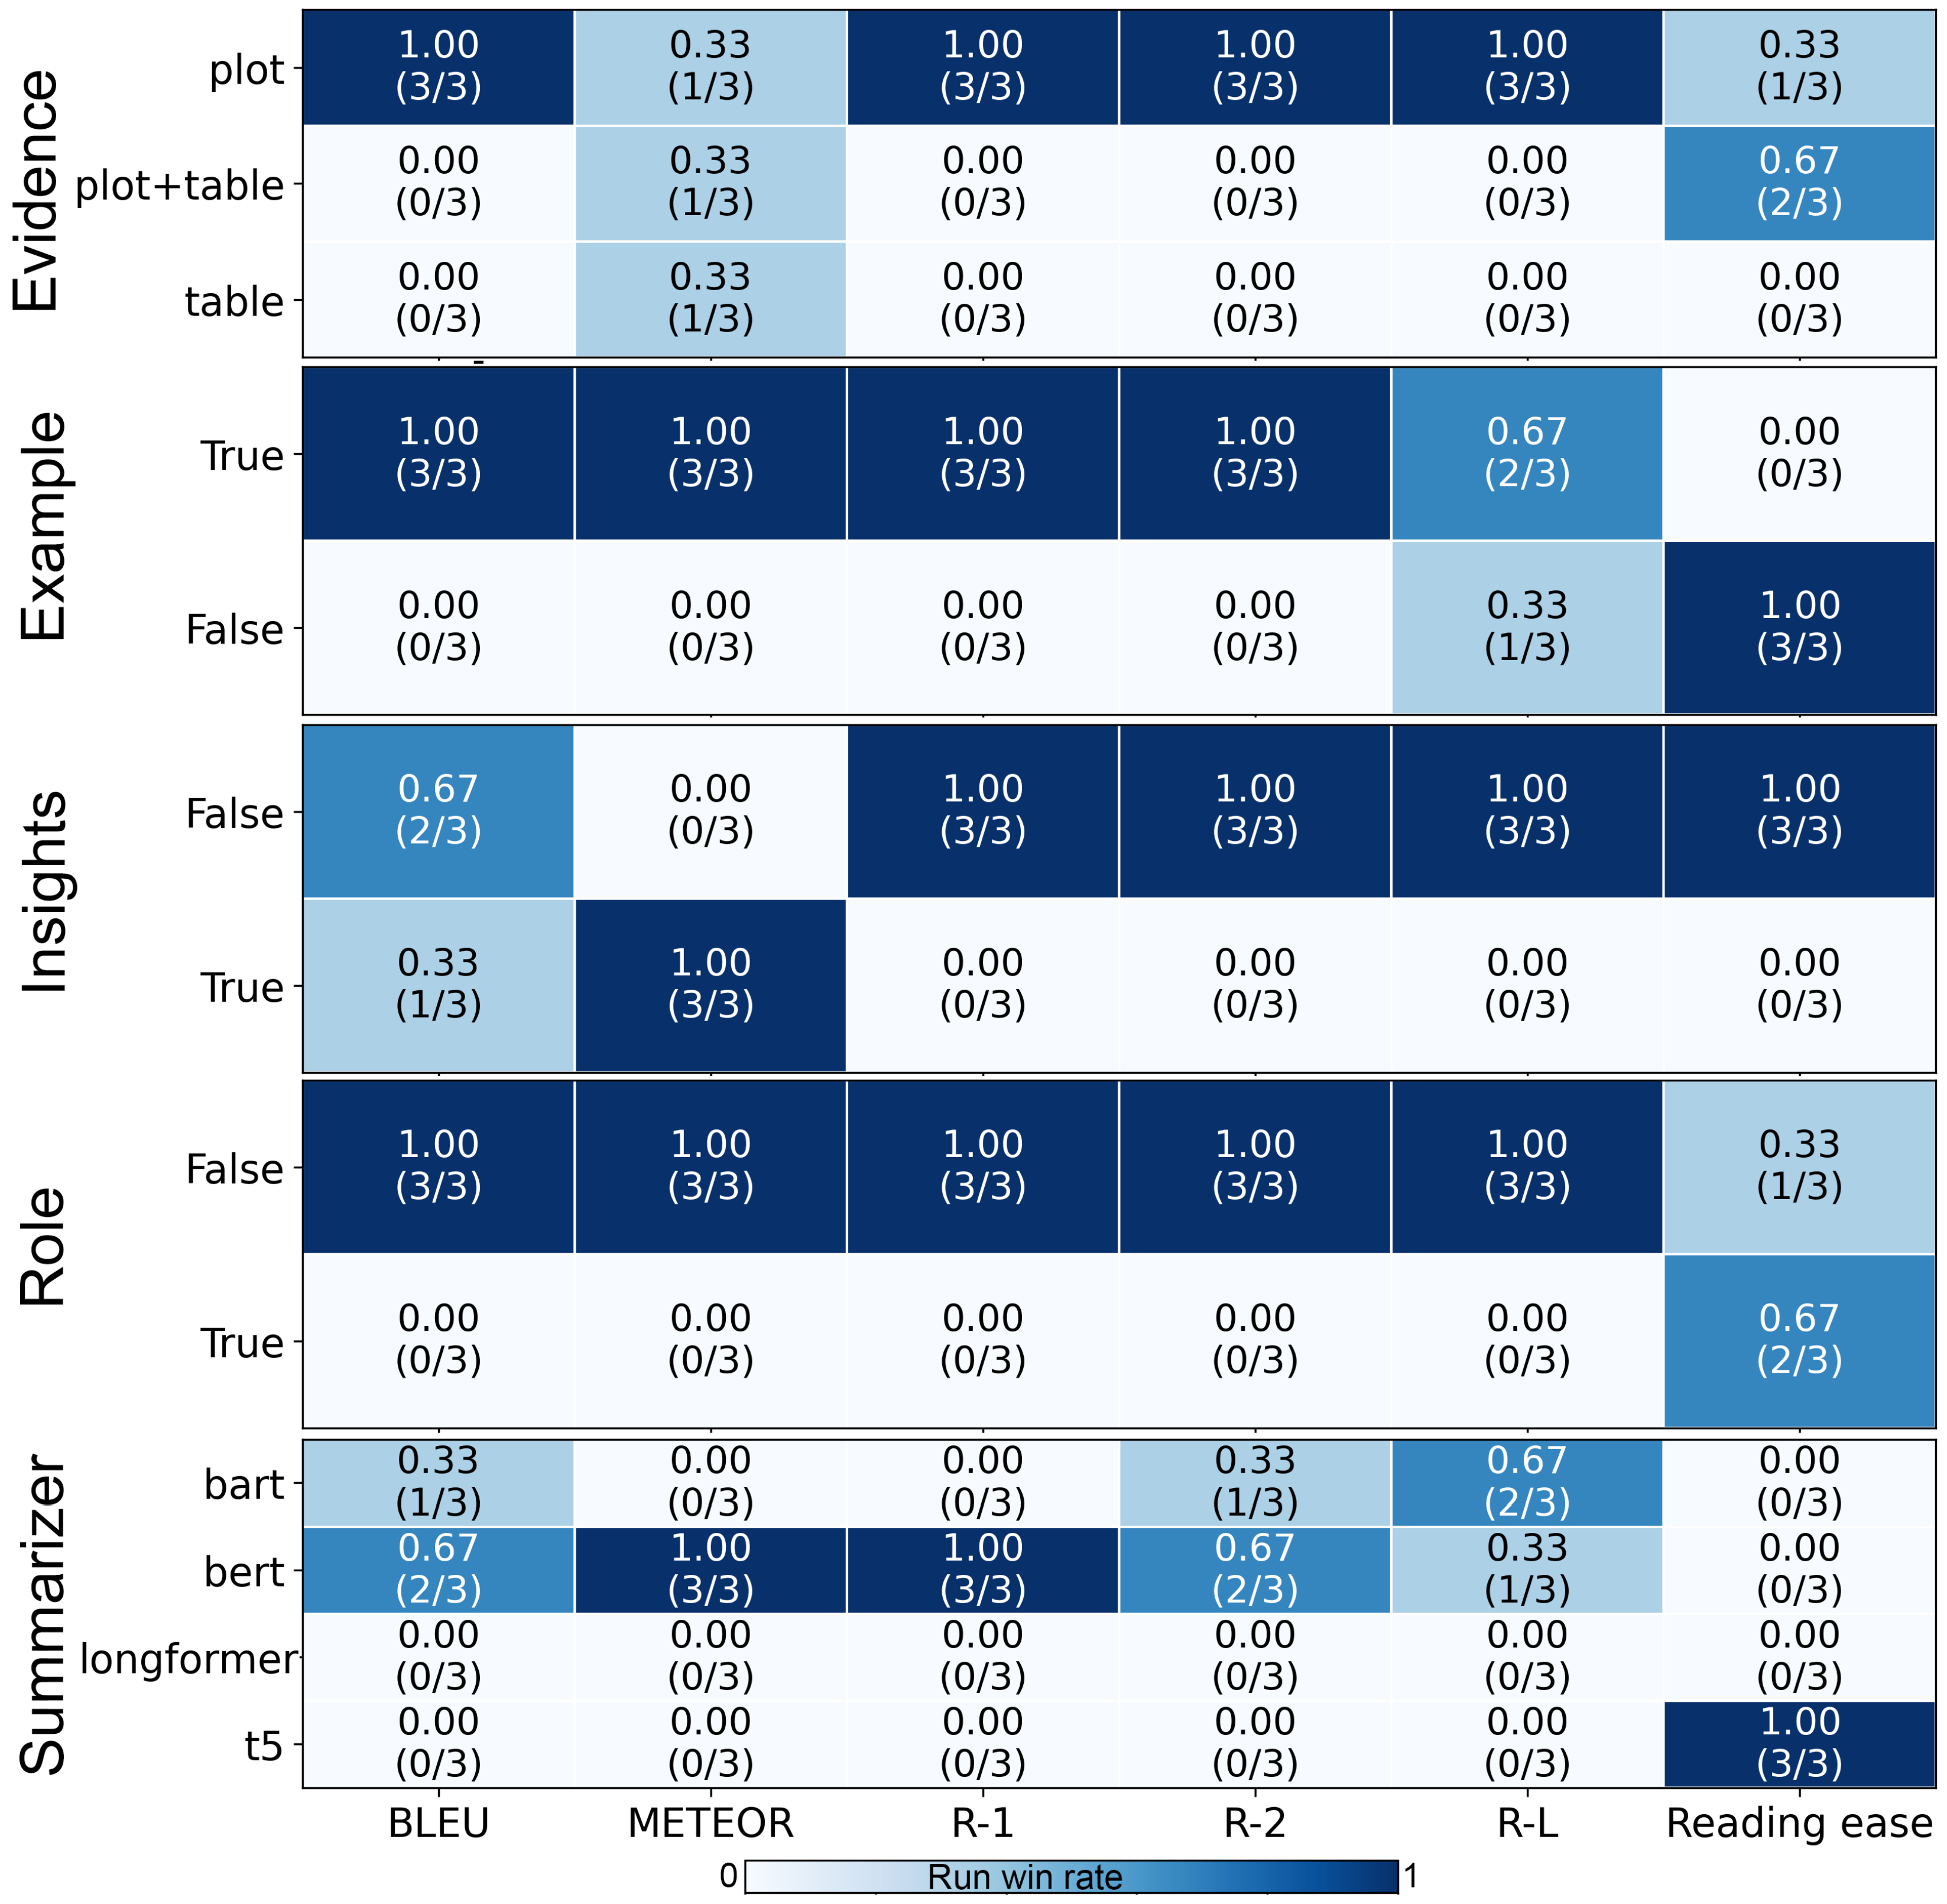
  • To translate statistical influence into actionable design choices, we conducted direct level-vs.-level comparisons (Figure 9). For each factor, we compared competing levels under otherwise identical experimental conditions (same ABM, LLM, evidence format, prompt configuration, and replication). We then counted how often each level produced the best evaluation score.
We define the ANOVA significance rate of a factor as the proportion of evaluated metric–reference combinations in which that factor is found statistically significant (at α = 0.05 ) across the experimental runs. For example, a value of 0.74 means that the factor showed a statistically significant effect in 74% of the situations where we tested it. On this basis, the role prompt has moderate significance rates in the aggregated ANOVA analysis (mean ≈ 0.74), but the aggregated factorial analysis reveals that its contribution is largely interaction-driven rather than consistently dominant as a main effect. This conditional influence is reflected in the level-competition analysis, where disabling the role instruction wins all three configurations for all overlap-based metrics. Including a role thus does not reliably improve performance and may even introduce variability depending on the model or summarization approach. We thus removed the role for the optimization stage.
Having an insight has small-to-moderate statistical importance (mean ANOVA significance rate ≈ 0.57), and the aggregated factorial analysis indicates non-negligible interaction contributions. However, level-competition results reveal a clear directional pattern: not asking for insight wins all replications for ROUGE-1, ROUGE-2, ROUGE-L, and readability, while it only improves METEOR. Consequently, we also removed the insight component of the prompt for the optimization stage.
Unlike role and insights, the inclusion of an example shows a weaker statistical presence in the aggregated ANOVA tables (mean significance rate ≈ 0.24), indicating that it is not always detected as a dominant main effect. However, factorial contribution summaries confirm that examples still participate in performance variation through interactions. Most importantly, the level-competition analysis provides strong practical evidence: including examples wins all three replications on BLEU, METEOR, ROUGE-1, and ROUGE-2; it wins two out of three for ROUGE-L; and disabling examples only improves readability. Therefore, we kept the examples for the optimization stage.
Through direct level-vs.-level comparisons, we noted the clear practical dominance of plot-based inputs for lexical metrics: plots win all three replications for BLEU, ROUGE-1, ROUGE-2, and ROUGE-L, while table-based or combined formats rarely outperform them. Although combining plots and tables sometimes improves readability, plot-only inputs yield the most consistent gains on the reference-based evaluation metrics that guide optimization. For this reason, we retain plot-based evidence presentation for optimization.

4.3. Optimization Stage: Anthropic’s Claude Opus 4.6 and Google’s Gemini 3.1 Pro Preview

We evaluated the performance of two additional state-of-the-art LLMs (Anthropic’s Claude Opus 4.6 and Google’s Gemini 3.1 Pro Preview) using the experimental configuration retained after the screening stage (Table 4). To compare models in a practically meaningful way, we applied the same level-vs.-level dominance analysis used in the screening stage. For each metric and experimental context (reference format, application domain, summarization method, and repetition), we identified which LLM achieved the best score and computed the proportion of contexts in which each model ‘wins’. This approach allows us to assess robust performance dominance. Claude Opus 4.6 achieves the highest win rates across all metrics, while Gemini 3.1 Pro Preview shows comparatively lower dominance frequencies (Figure 10). Despite performances on general benchmarks, we note that performances from Gemini 3.1 Pro Preview are generally low in contrast to other LLMs for our application domain. Overall, these results suggest that the most robust LLMs for deployment would be either the proprietary LLM Claude Opus 4.6 (i.e., at a cost) or the open-weight Qwen 3.5, which can either be instantiated locally (on a professional workstation with sufficient memory) or through an API in a cost-efficient manner.
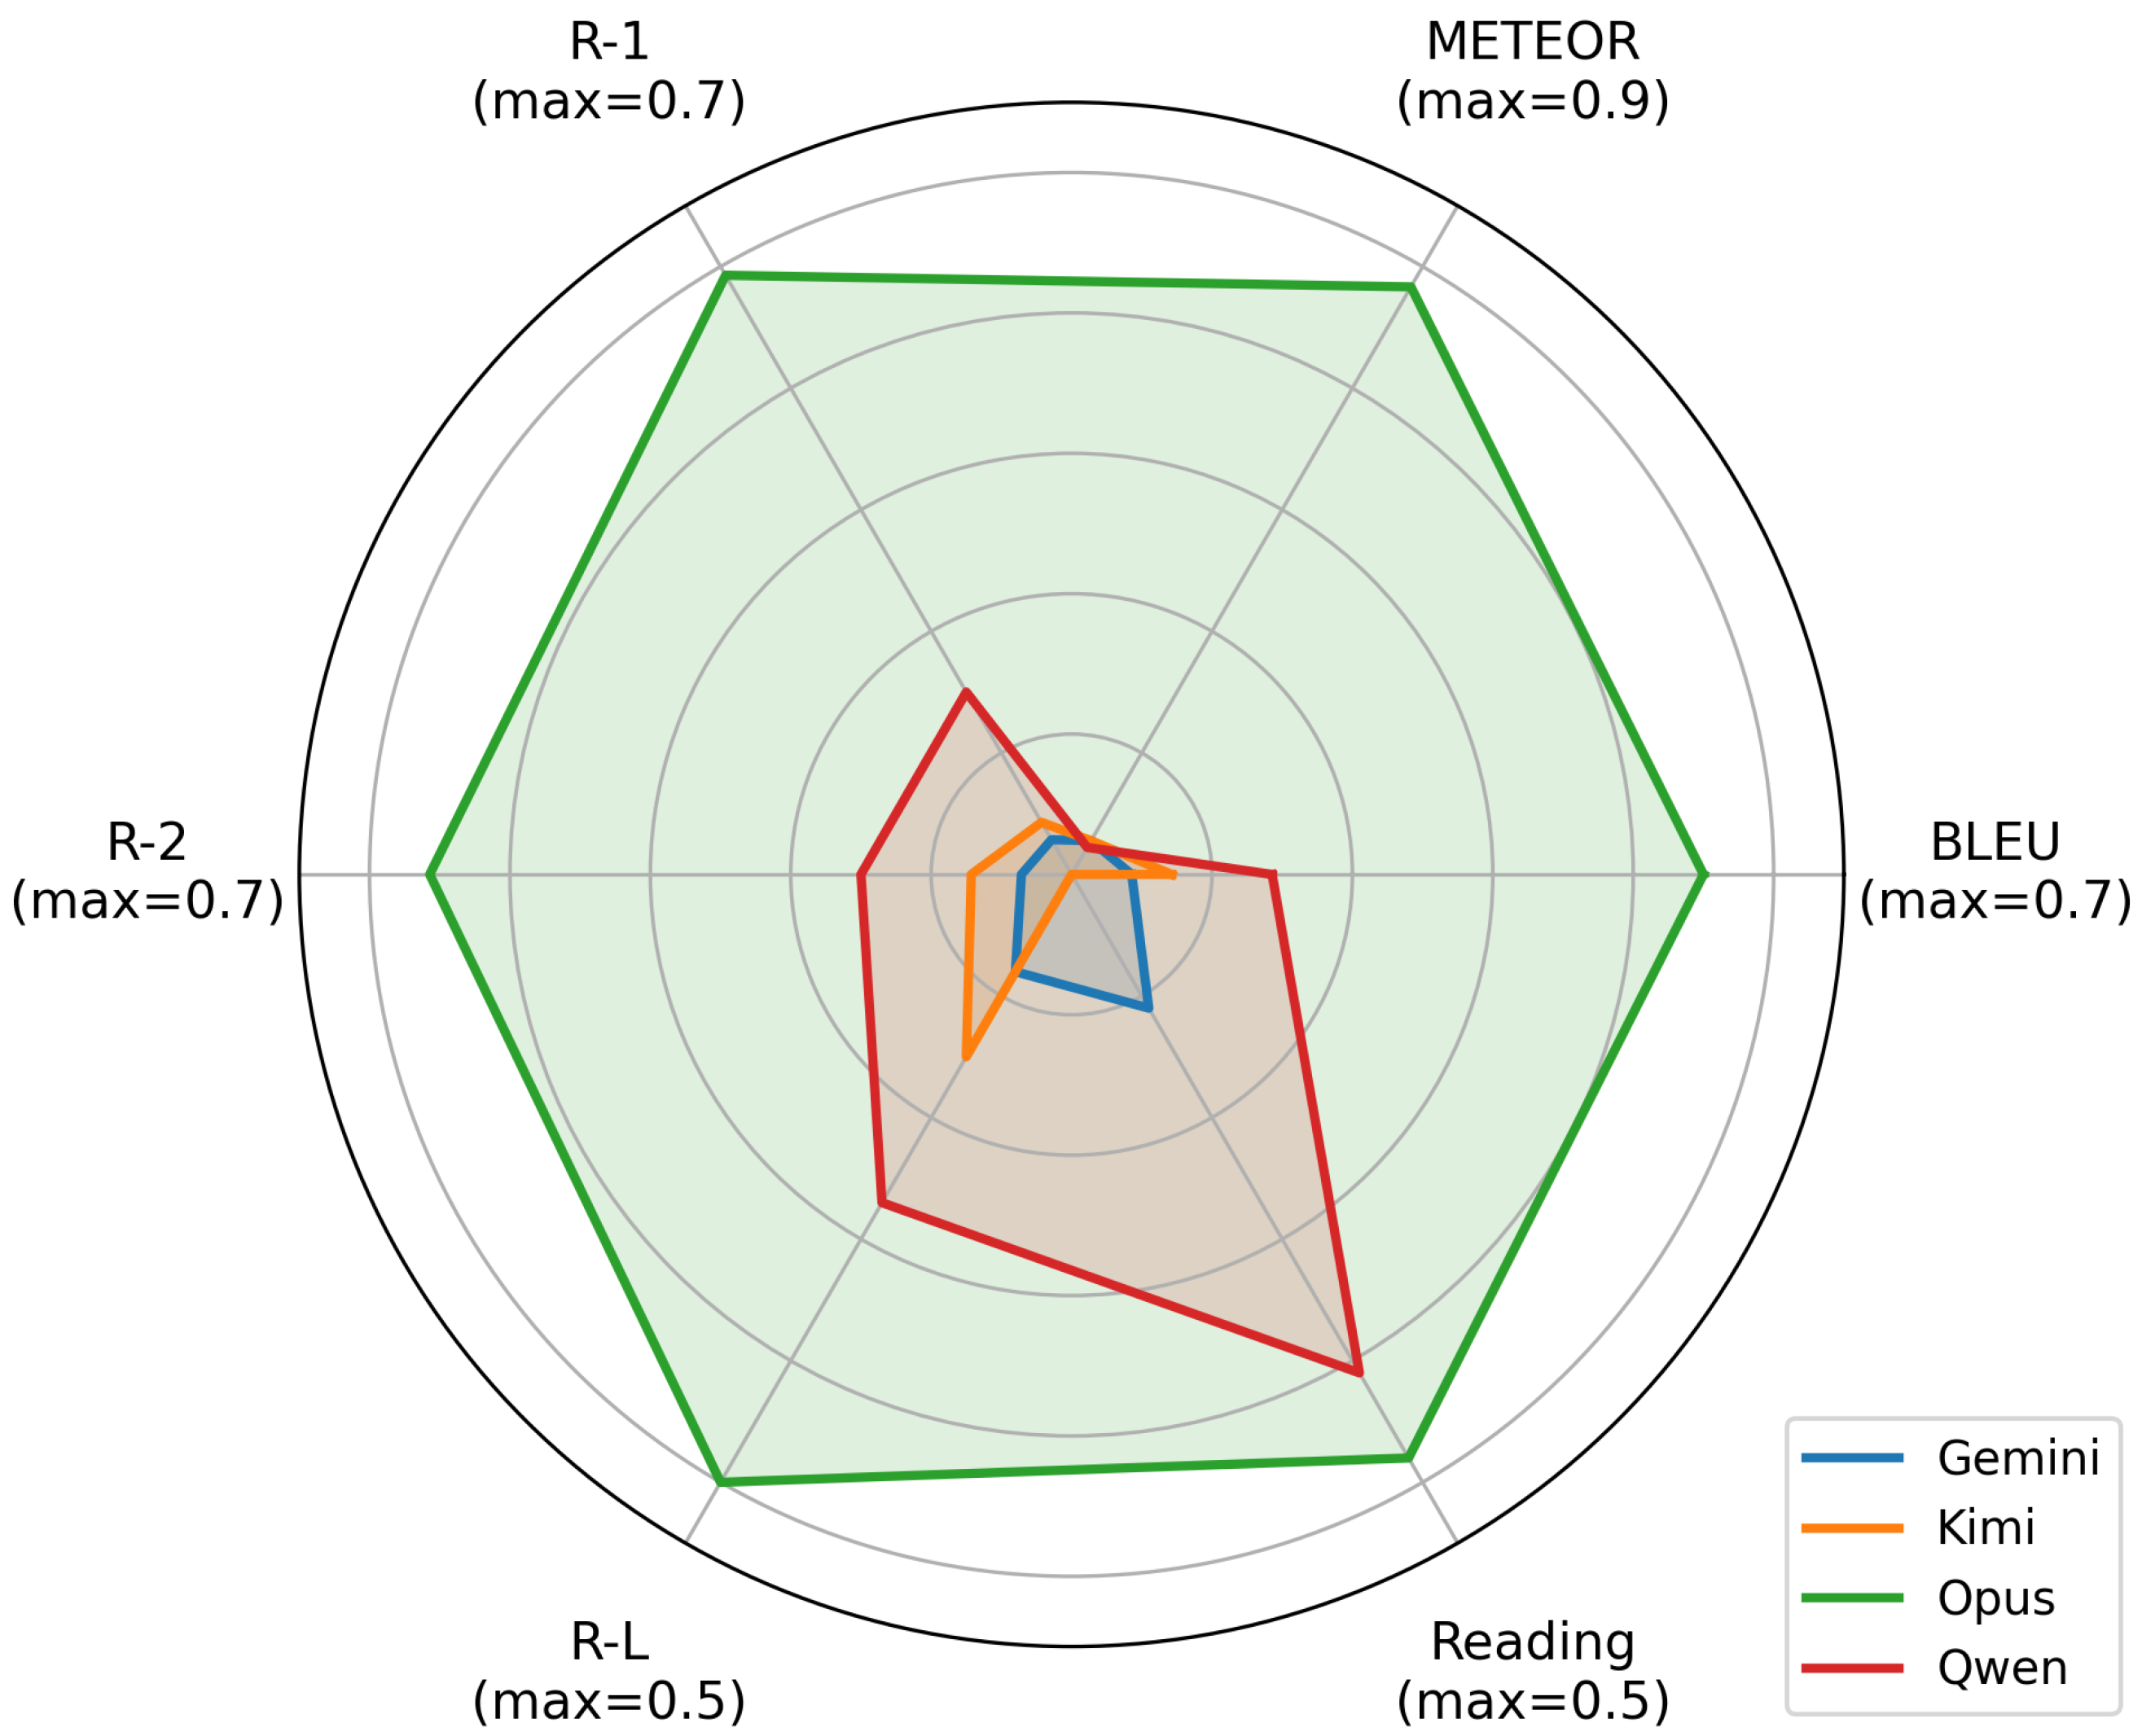
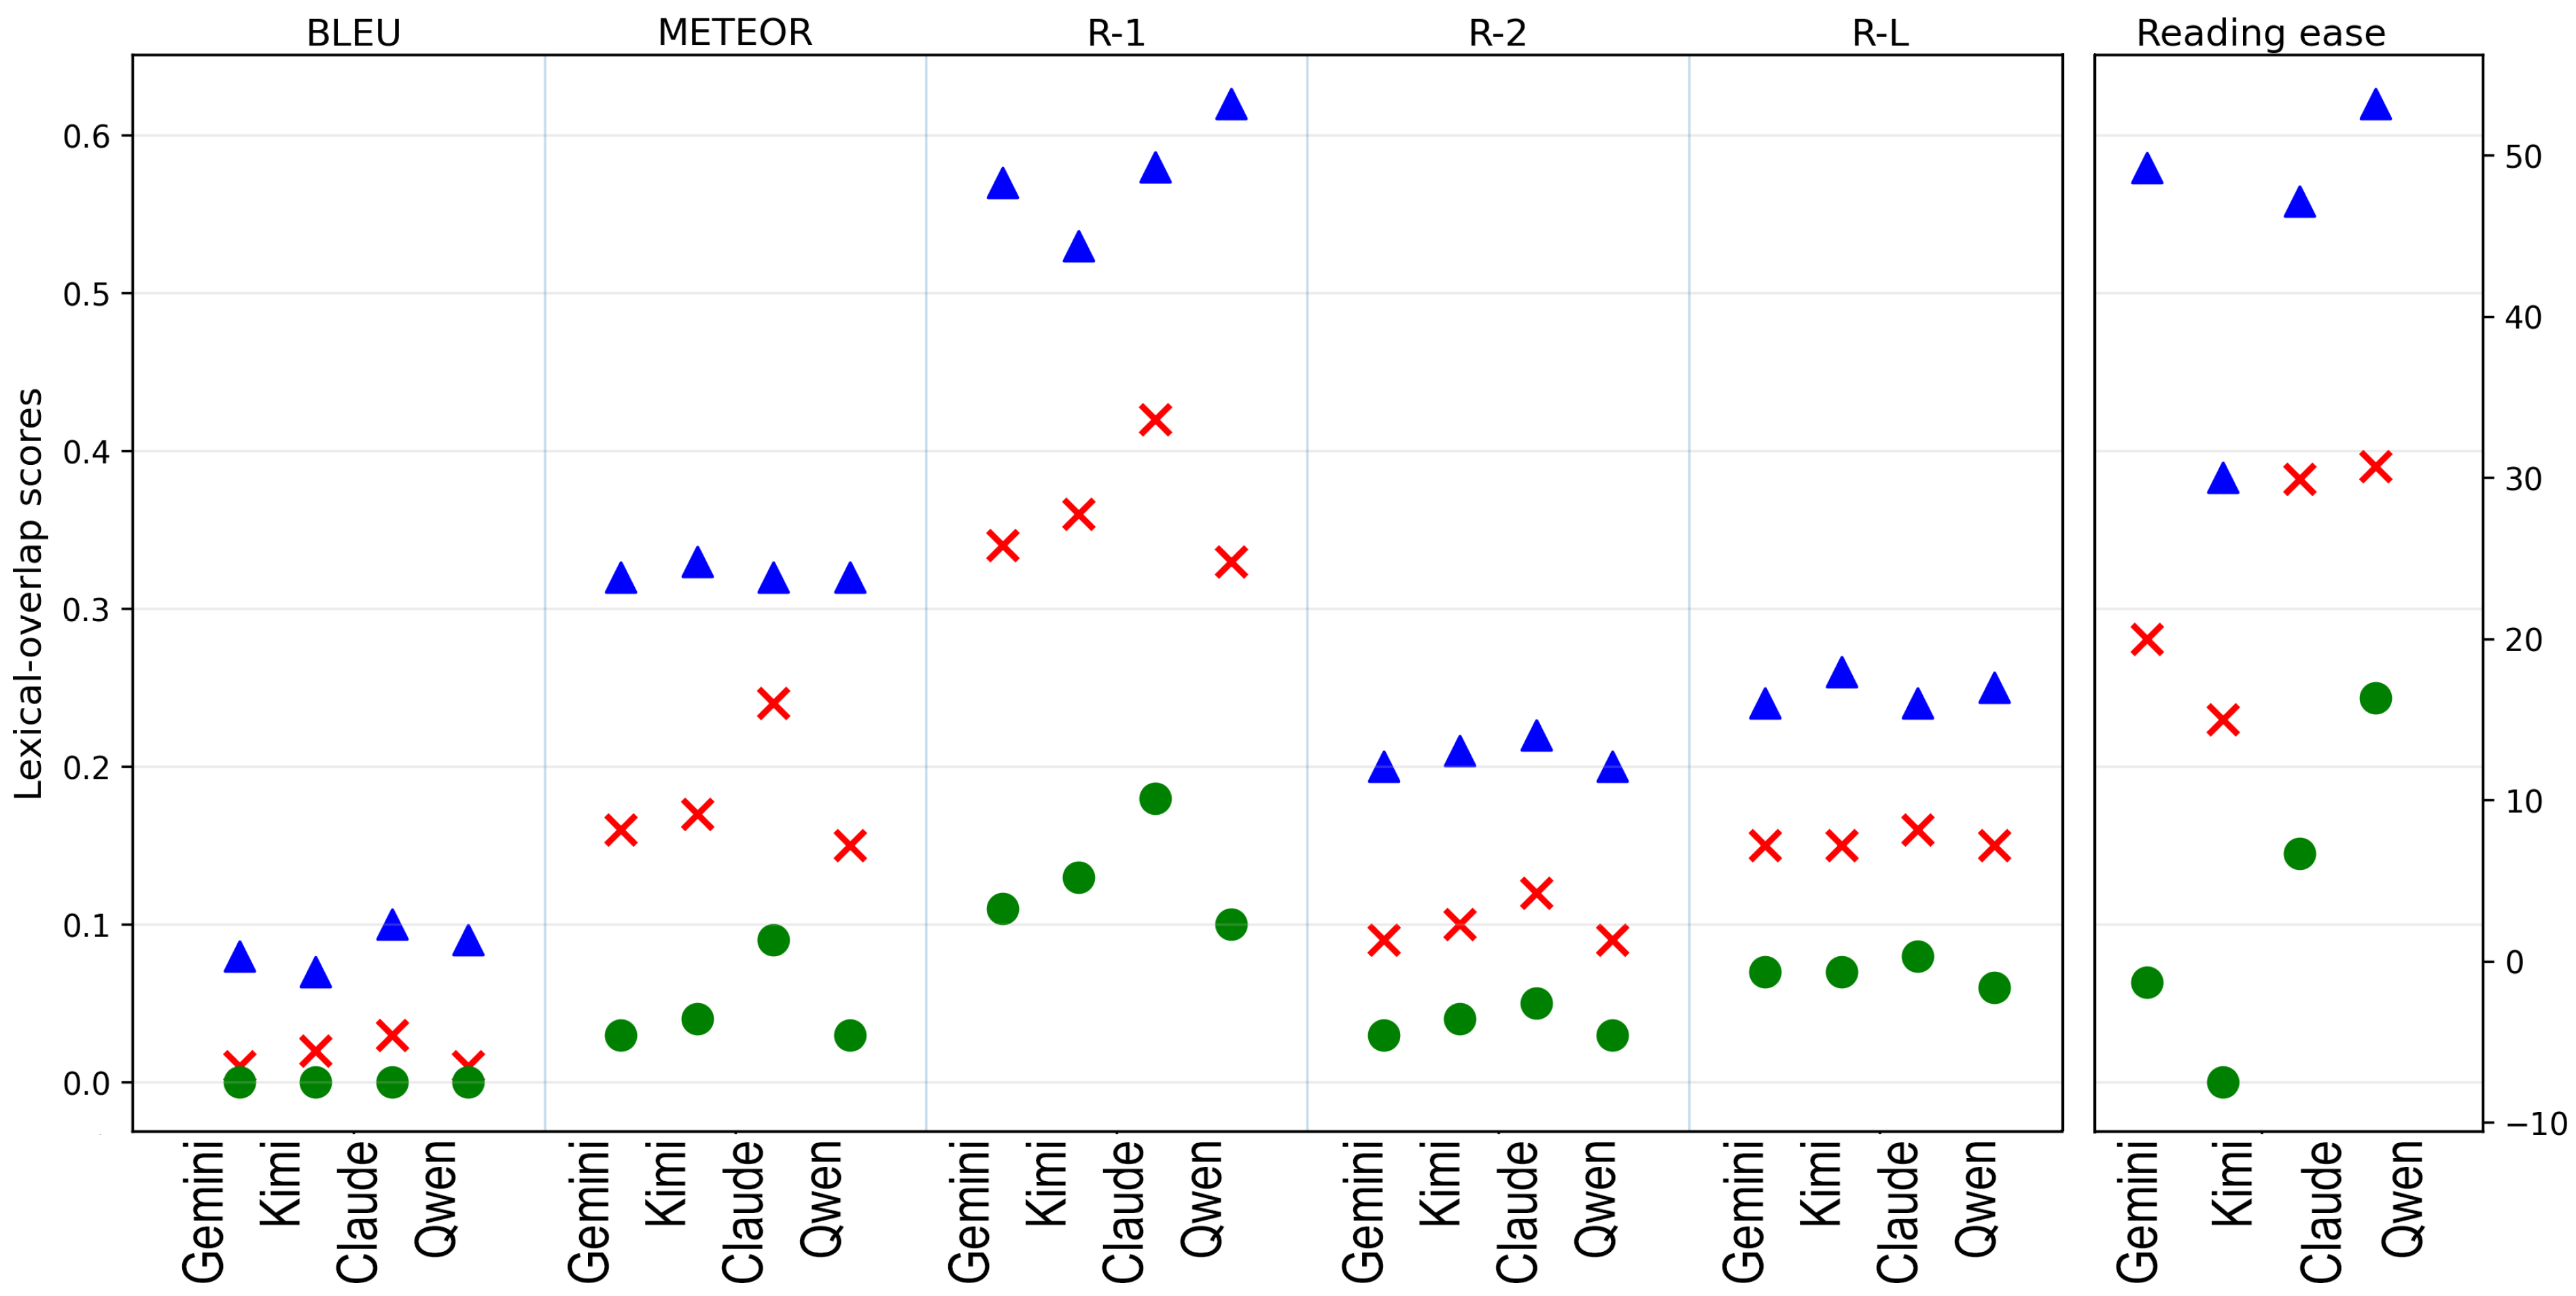
Figure 11 reports the distribution of scores achieved by each LLM across all experimental contexts. Consistent with Figure 10, Claude Opus 4.6 exhibits the strongest overall performance profile, combining high central tendencies with favorable upper bounds on lexical-overlap metrics. For example, Claude reaches maximum ROUGE-2 values close to 0.22 and ROUGE-1 values around 0.58 while maintaining comparatively high mean scores relative to other models. Qwen 3.5 shows a similar but slightly weaker pattern, achieving competitive maximum lexical-overlap scores and comparable variability ranges. In contrast, Gemini 3.1 Pro Preview displays systematically lower mean lexical-overlap performance and wider performance dispersion across contexts, indicating less consistent alignment with reference summaries. Differences are even more pronounced on readability, where abstractive generation capabilities lead to substantial performance gaps between models.
To complement the quantitative comparisons, we conducted a qualitative reading of reports drawn from a stratified sample covering all LLMs, all ABMs, both extractive and abstractive summarization approaches, and varied prompt configurations (Table 5). A consistent pattern emerges when examining both narrative quality and factual reliability. Extractive summaries produced with BERT show the highest number of identified issues, ranging from five errors for Claude and Gemini on the fauna model to seven errors for Kimi under similar conditions. The errors include missing numerical values, abrupt transitions between variables, and ambiguity about which metric is being described. Since such problems occur across multiple LLMs and application domains, it suggests that they are primarily driven by the extractive summarization mechanism rather than by model-specific behavior. In contrast, abstractive summarizers such as BART and T5 generally exhibit fewer factual inconsistencies (e.g., one error for Claude with BART on the grazing model and two errors for Gemini with T5 on the milk model) and produce more coherent, self-contained narratives. While abstractive summaries can sometimes be overly concise or omit secondary details, they rarely display the fragmented sentence juxtaposition characteristic of extractive outputs. These qualitative findings are aligned with expectations: extractive approaches tend to preserve isolated textual fragments at the expense of narrative continuity and factual completeness, whereas abstractive approaches more consistently support intelligible executive-style communication of simulation outcomes.
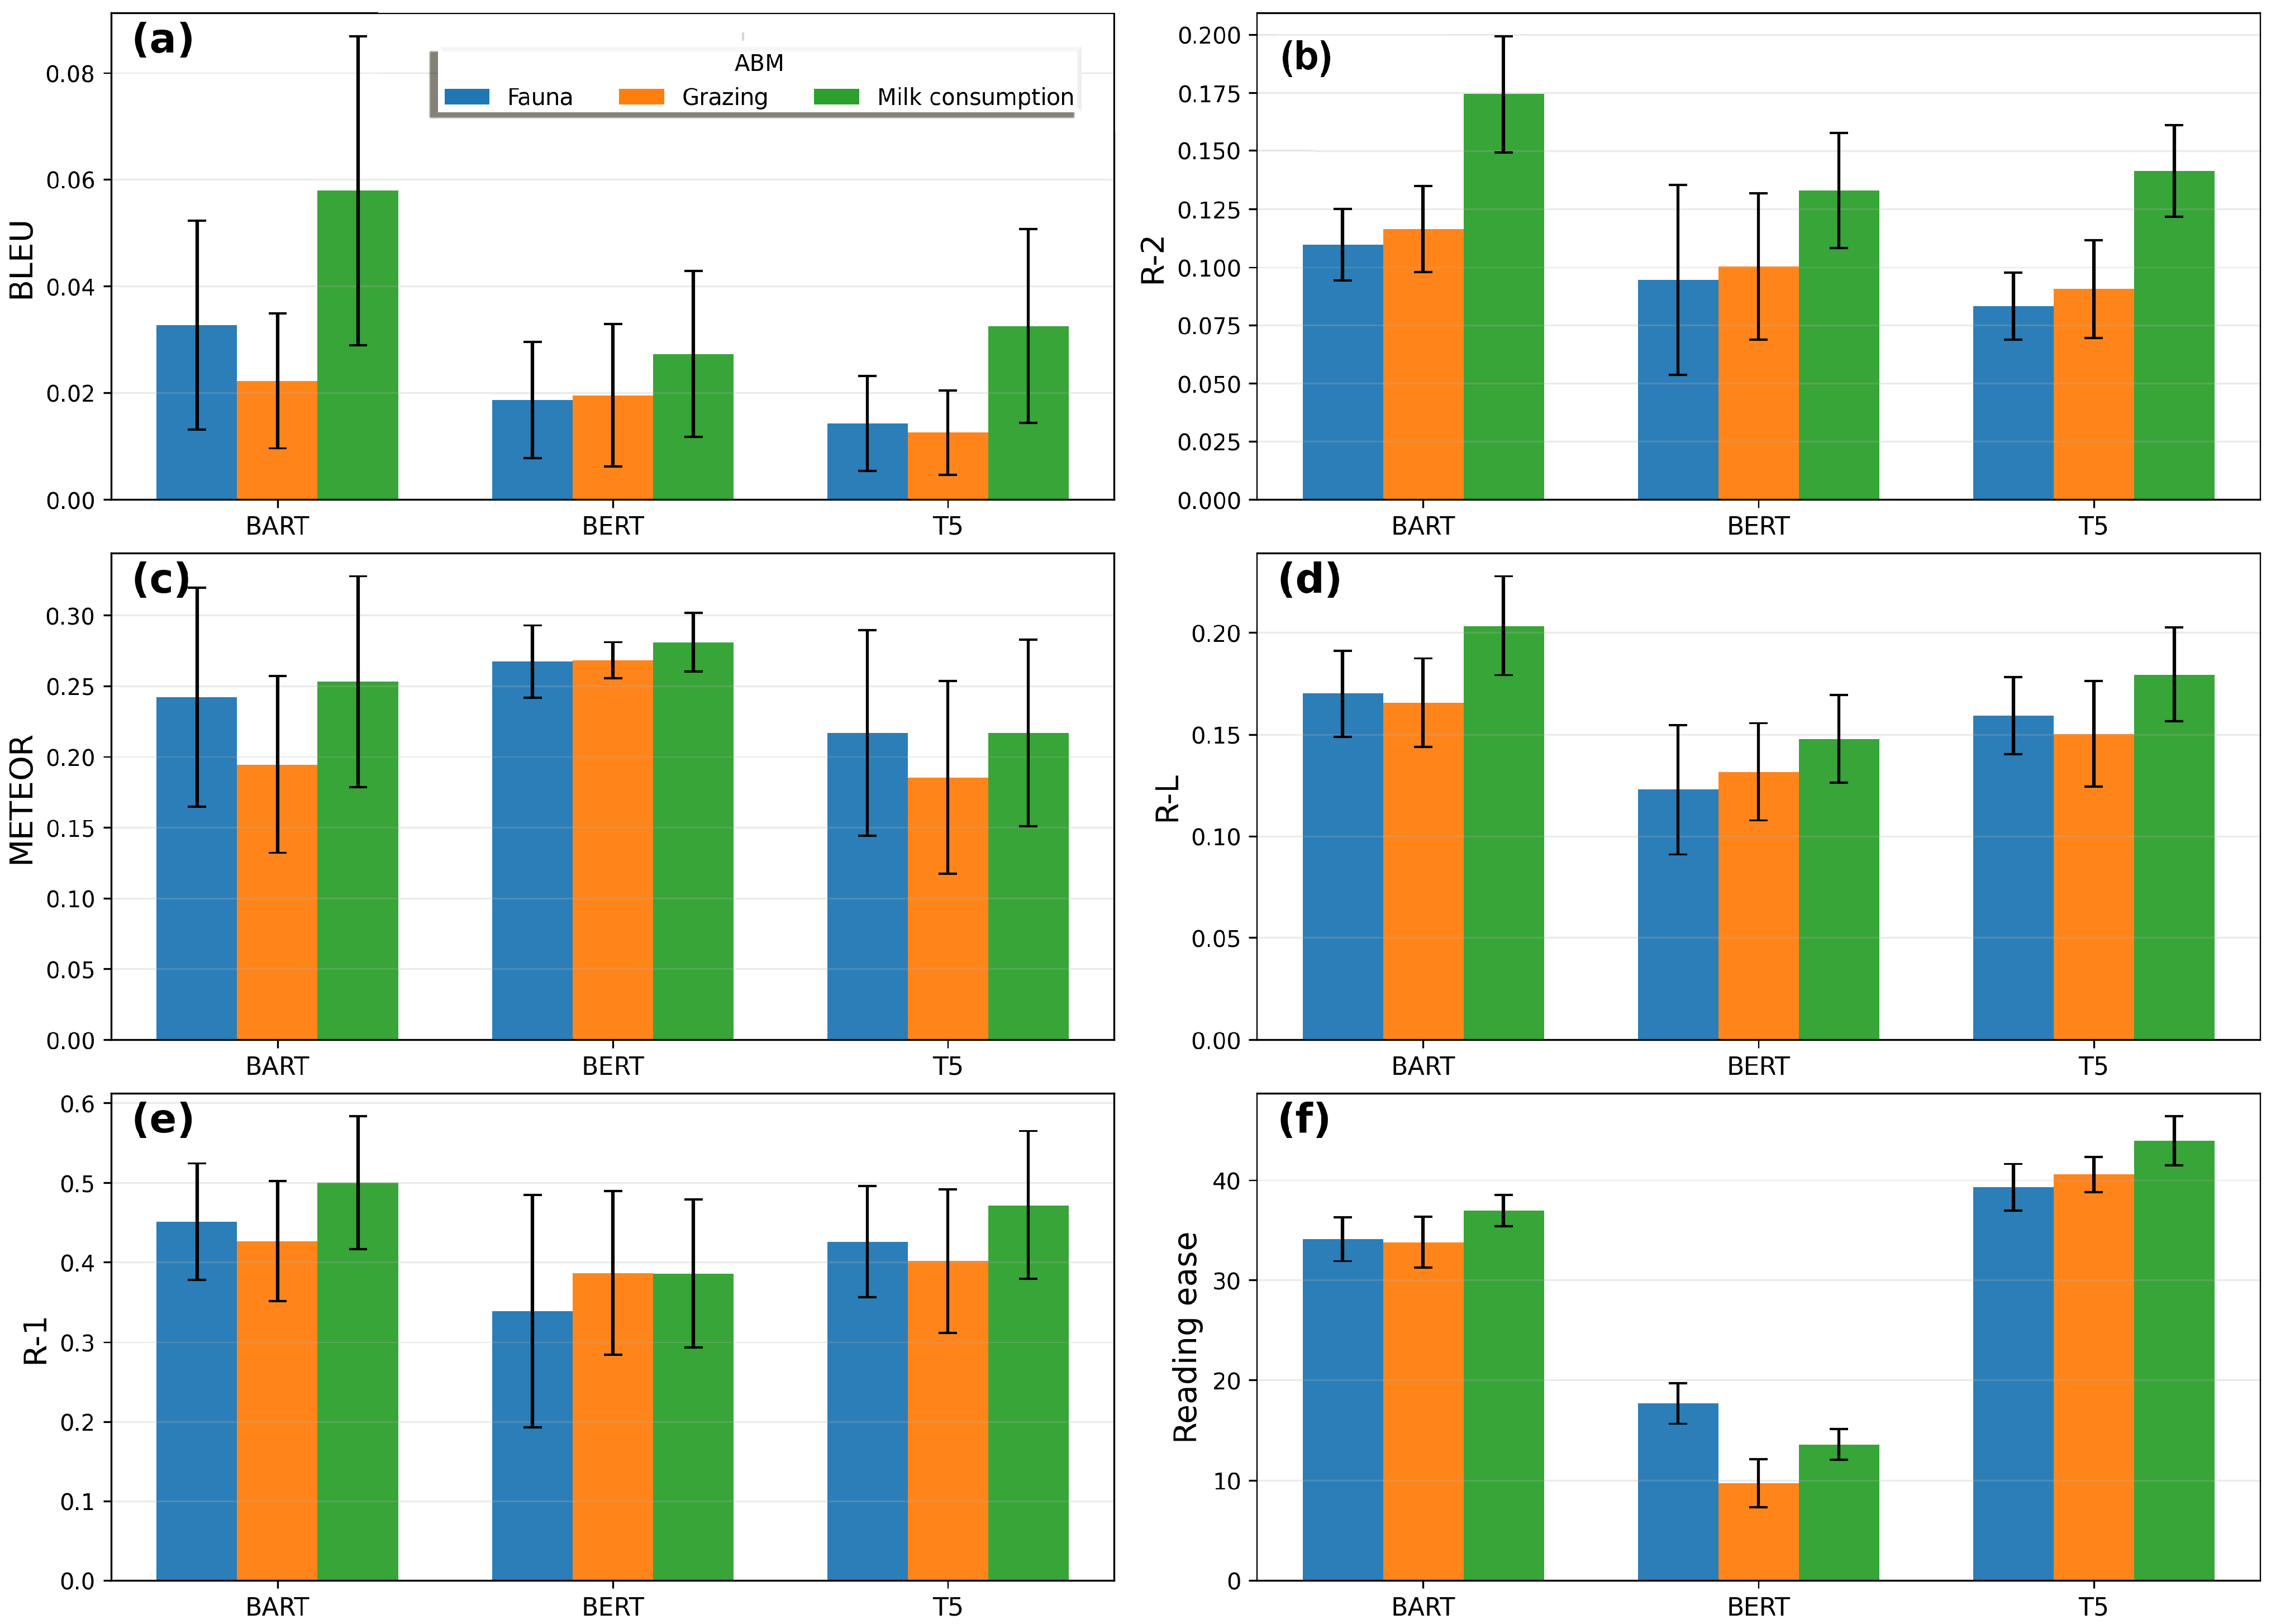
As the most robust LLM, we focus the analysis on Claude Opus 4.6 across ABMs (Figure 12) while noting that our storage bucket provides the results for all LLMs. Results depend on the ABM, which is expected, as each model is built differently, involves a different vocabulary, and produces different dynamics. On lexical-overlap metrics, the milk consumption ABM systematically yields the strongest scores. For instance, with the BART summarizer, BLEU reaches approximately 0.058 for milk consumption compared with 0.033 for fauna and 0.022 for grazing (Figure 12a). We see similar effects for ROUGE metrics: ROUGE-2 peaks near 0.175 for milk consumption using BART compared with about 0.110 for fauna and 0.116 for grazing (Figure 12b), while ROUGE-1 reaches roughly 0.50 under the same configuration (Figure 12e). Reading ease behaves (Figure 12f) differently from lexical-overlap metrics, as we observe that the T5 summarizer consistently produces the highest scores across ABMs (about 39 to 44), whereas BERT produces substantially lower readability (from 9 to 18). The standard deviations across runs are modest relative to mean differences, indicating that these performance patterns are stable. As the results indicate that BERT’s extractive summaries tend to sacrifice fluency and lexical alignment without delivering consistent gains on overlap metrics, we recommend the two abstractive summarization algorithms BART and T5 for deployment.

5. Discussion

5.1. Key Contributions

This paper demonstrates that large language models can be systematically configured to translate well-documented agent-based models (ABMs) into executive-style reports that are quantitatively aligned with reference summaries and exhibit qualitative characteristics consistent with texts intended for non-technical audiences. As detailed in Section 5.3, we note that examining practical usability for such audiences is a study in itself, which would require ethical approval, enrollment of participants, and specific tools to evaluate how people react to text. A central contribution of this paper is the introduction of a staged Design of Experiments (DoE) pipeline for optimizing complex generative reporting systems. Rather than directly tuning high-capacity proprietary models, we first conduct a screening stage using lower-cost or open-weight LLMs to identify influential design factors, quantify interaction effects, and eliminate weak configurations. Aggregated ANOVA significance rates establish which components reliably influence evaluation outcomes, while factorial variance decomposition reveals that the dominant drivers of report quality are the summarization strategy and its interaction with the underlying LLM. Direct level-dominance comparisons then translate statistical influence into actionable configuration choices, enabling a substantial reduction of the experimental search space prior to deployment-stage evaluation.
Beyond methodological advances, the results provide practical insights into the construction of LLM-based reporting pipelines. We show that abstractive summarization consistently supports higher readability and more coherent narrative structure than extractive approaches, which tend to preserve fragmented textual elements that reduce the practical usability of generated reports. We also demonstrate that prompt refinements play a secondary but still actionable role once the core LLM–summarizer pairing is fixed with evidence representation and example-based guidance influencing lexical-alignment metrics more than stylistic prompt elements such as role instructions or insight requests. Overall, the proposed DoE framework illustrates how classical experimental-design principles can be adapted to systematically engineer reliable generative-AI workflows in resource-constrained settings.

5.2. Practical Implications

The optimization stage provides clear practical recommendations for deploying LLM-based reporting pipelines. Among the evaluated models, Claude Opus 4.6 demonstrates the most robust performance profile, combining the highest dominance rates across evaluation metrics with favorable score distributions and limited variability across experimental contexts. At the same time, Qwen 3.5 emerges as a competitive open-weight alternative, offering comparable lexical-overlap performance with lower operational costs and the possibility of local deployment. Prompt configuration also converges toward a stable design: presenting simulation evidence through plots and including illustrative examples consistently improves lexical-alignment metrics, whereas role instructions and additional insight-generation steps introduce variability without delivering systematic performance gains. These findings suggest that once an appropriate summarization strategy and LLM are selected, modern models require relatively limited prompt steering to produce high-quality executive reports.
Performance variations across ABMs further highlight the importance of domain characteristics in generative reporting. Lexical-overlap metrics are consistently higher for the milk-consumption model than for the fauna or grazing models, likely reflecting differences in vocabulary specificity, variable complexity, and the clarity of emergent simulation trends. These domain effects indicate that optimal reporting configurations cannot be fully decoupled from the structure and documentation quality of the underlying simulation. They also underscore the need to evaluate generated reports against multiple forms of reference material, as the perceived summary quality may depend on whether outputs are compared with expert-written summaries, long-form technical descriptions, or alternative machine-generated reports. Overall, these findings suggest that generative reporting pipelines should be configured with sensitivity to both model characteristics and application-domain features.

5.3. Limitations and Future Work

Despite the promising results, several limitations should be acknowledged. First, the proposed reporting pipeline assumes that agent-based models are accompanied by sufficiently detailed and structured documentation. Solidly anchoring generated summaries in factual content requires that the task remains primarily translational rather than speculative, as insufficient contextual grounding may otherwise lead to hallucinations or omissions. The simulation community has repeatedly emphasized the importance of thorough model documentation [36], and repositories such as CoMSES provide many well-documented examples. However, there is no guarantee that any ABM intended for stakeholder communication will meet this standard. In practice, weaker documentation may lead to identifiable failure modes such as missing descriptions of key variables, an incorrect attribution of causal mechanisms, reduced narrative coherence, or overly generic summaries that fail to capture model-specific dynamics. Conducting systematic stress tests across graded documentation regimes (e.g., rich, medium, sparse) would require constructing controlled degraded documentation variants for multiple models, which was beyond the scope of this paper but represents an important direction for future work.
Second, while the staged Design-of-Experiments approach substantially reduces computational cost and enables principled configuration selection, conclusions about optimal configurations remain contingent on the selected ABMs, evaluation metrics, and prompt design space explored. Performance differences observed across application domains suggest that generative reporting effectiveness depends partly on model structure, vocabulary specificity, and the clarity of emergent dynamics. Future research should therefore investigate how configuration choices generalize across broader classes of simulation models and whether the automatic characterization of model features (e.g., number of state variables, degree of stochasticity, interaction topology) can guide the selection of appropriate LLM–summarizer combinations. Empirical evidence indicates that related ABMs often share common “building blocks” [116]— for example, when simulating mobility or interaction processes; automatically detecting these structures could help reconstruct missing contextual explanations and improve report grounding.
Third, the qualitative evaluation relied on targeted sampling rather than an exhaustive inspection of all generated reports. Although recurring error patterns across models and domains increase confidence in the observed trends, larger-scale human evaluations would further strengthen conclusions regarding factual faithfulness and narrative usability. Prior work has highlighted the challenges of consistently assessing conceptual-model summaries and relating textual descriptions to simulation structure [117], suggesting that evaluation protocols tailored to simulation reporting remain an open research need.
Finally, an important direction for future work is the mitigation of documentation limitations through external knowledge integration. Retrieval-augmented generation (RAG) could incorporate information from research articles, repositories, or related simulation models to provide additional contextual grounding. Complementary approaches include clone-detection techniques that recognize similarities with well-documented models, allowing a partial reuse of validated documentation, although care must be taken to ensure that only applicable elements are transferred. As large language models continue to evolve and support longer context windows, further studies are needed to determine how additional evidence sources such as code comments or structured metadata can be incorporated without degrading narrative clarity or increasing sensitivity to prompt configuration.

6. Conclusions

This paper demonstrates that large language models can be systematically configured to translate simulation outcomes from well-documented agent-based models into concise, executive-style reports that remain aligned with reference summaries while exhibiting readability and narrative properties that may support comprehension by non-technical audiences. Across multiple ABMs and LLMs, our results show that report quality depends mostly on the choice of summarization strategy and underlying LLM with abstractive summarizers such as BART and T5 providing more coherent and practically useful narratives than extractive alternatives. This paper suggests that automated simulation-to-text can help bridge the gap between complex simulation outputs and decision support, while future research should examine how these configuration choices generalize to less-documented ABMs and broader classes of simulations.

Supplementary Materials

The following supporting information can be downloaded at: https://www.mdpi.com/article/10.3390/bdcc10040121/s1, File S1: qualitative and quantitative performances on three additional LLMs (GPT-4o, Claude 3.5 Sonnet, DeepSeek R1). File S2: ground-truth datasets created for this study. File S3: detailed explanation of our approach to ensure the correctness of our implementation. File S4: usage data from OpenRouter about which provider was used for each LLM.

Author Contributions

Conceptualization, P.J.G.; methodology, N.Y.F. and P.J.G.; software, N.Y.F.; validation, N.Y.F.; formal analysis, N.Y.F. and P.J.G.; investigation, N.Y.F. and P.J.G.; data curation, N.Y.F.; writing—original draft preparation, N.Y.F. and P.J.G.; writing—original draft revision, N.Y.F. and P.J.G.; visualization, N.Y.F.; supervision, P.J.G. All authors have read and agreed to the published version of the manuscript.

Funding

This research received no external funding.

Institutional Review Board Statement

Not applicable.

Informed Consent Statement

Not applicable.

Data Availability Statement

To support transparency and replicability, our code is provided as a complete pipeline at https://github.com/NoeFlandre/distill-abm, accessed on 1 April 2026. All results across LLMs as well as the results of our code verification can be accessed in our storage bucket at https://huggingface.co/buckets/NoeFlandre/distill-abms-results, accessed on 1 April 2026.

Acknowledgments

The authors are grateful to Ross Gore and Jose Padilla (Research Associate Professors at Old Dominion) and to Christopher Vendome (Associate Professor at Miami University) for writing ground-truth summaries on each of the agent-based models.

Conflicts of Interest

The authors declare no conflicts of interest.

Abbreviations

The following abbreviations are used in this manuscript:
ABMAgent-Based Model
LLMLarge Language Model
M&SModeling and Simulation
ODDOverview, Design concepts, Details

References

  1. Zellner, M.L.; Milz, D.; Lyons, L.; Hoch, C.; Radinsky, J. Finding the balance between simplicity and realism in participatory modeling for environmental planning. Environ. Model. Softw. 2022, 157, 105481. [Google Scholar] [CrossRef] [Scilit]
  2. Grigoryan, G.; Collins, A.J. Feature Importance for Uncertainty Quantification in Agent-Based Modeling. In Proceedings of the 2023 Winter Simulation Conference (WSC); IEEE: New York, NY, USA, 2023; pp. 233–242. [Google Scholar]
  3. Jalali, M.S.; Beaulieu, E. Strengthening a weak link: Transparency of causal loop diagrams—Current state and recommendations. Syst. Dyn. Rev. 2024, 40, e1753. [Google Scholar] [CrossRef] [Scilit]
  4. Allender, S.; Owen, B.; Kuhlberg, J.; Lowe, J.; Nagorcka-Smith, P.; Whelan, J.; Bell, C. A community based systems diagram of obesity causes. PLoS ONE 2015, 10, e0129683. [Google Scholar] [CrossRef] [Scilit]
  5. Siokou, C.; Morgan, R.; Shiell, A. Group model building: A participatory approach to understanding and acting on systems. Public Health Res. Pract. 2014, 25, e2511404. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  6. Jack, A. Foresight report on obesity–Author’s reply. Lancet 2007, 370, 1755. [Google Scholar] [CrossRef] [Scilit]
  7. van Veen, B.L.; Roland Ortt, J. Simplification errors in predictive models. Futur. Foresight Sci. 2024, 6, e184. [Google Scholar] [CrossRef] [Scilit]
  8. Swarup, S. Adequacy: What makes a simulation good enough? In Proceedings of the 2019 Spring Simulation Conference (SpringSim); IEEE: New York, NY, USA, 2019; pp. 1–12. [Google Scholar]
  9. Uleman, J.F.; Stronks, K.; Rutter, H.; Arah, O.A.; Rod, N.H. Mapping complex public health problems with causal loop diagrams. Int. J. Epidemiol. 2024, 53, dyae091. [Google Scholar] [CrossRef] [Scilit]
  10. Hedelin, B.; Gray, S.; Woehlke, S.; BenDor, T.K.; Singer, A.; Jordan, R.; Zellner, M.; Giabbanelli, P.; Glynn, P.; Jenni, K.; et al. What’s left before participatory modeling can fully support real-world environmental planning processes: A case study review. Environ. Model. Softw. 2021, 143, 105073. [Google Scholar] [CrossRef] [Scilit]
  11. Wei, Y.; Knoeferle, P. Causal inference: Relating language to event representations and events in the world. Front. Psychol. 2023, 14, 1172928. [Google Scholar] [CrossRef] [Scilit]
  12. Shrestha, A.; Mielke, K.; Nguyen, T.A.; Giabbanelli, P.J. Automatically explaining a model: Using deep neural networks to generate text from causal maps. In Proceedings of the 2022 Winter Simulation Conference (WSC); IEEE: New York, NY, USA, 2022; pp. 2629–2640. [Google Scholar]
  13. Phatak, A.; Mago, V.K.; Agrawal, A.; Inbasekaran, A.; Giabbanelli, P.J. Narrating causal graphs with large language models. In Proceedings of the Hawaii International Conference on System Sciences 2024 (HICSS-57), Honolulu, HI, USA, 3–6 January 2024. [Google Scholar]
  14. Gandee, T.J.; Giabbanelli, P.J. Combining Natural Language Generation and Graph Algorithms to Explain Causal Maps Through Meaningful Paragraphs. In Proceedings of the International Conference on Conceptual Modeling; Springer: Berlin/Heidelberg, Germany, 2024; pp. 359–376. [Google Scholar]
  15. Giabbanelli, P.J. GPT-based models meet simulation: How to efficiently use large-scale pre-trained language models across simulation tasks. In Proceedings of the 2023 Winter Simulation Conference (WSC); IEEE: New York, NY, USA, 2023; pp. 2920–2931. [Google Scholar]
  16. Schoenberg, W. Building and Learning With Models Using AI. Syst. Dyn. Rev. 2026, 42, e70019. [Google Scholar] [CrossRef] [Scilit]
  17. Hosseinichimeh, N.; Majumdar, A.; Williams, R.; Ghaffarzadegan, N. From text to map: A system dynamics bot for constructing causal loop diagrams. Syst. Dyn. Rev. 2024, 40, e1782. [Google Scholar] [CrossRef] [Scilit]
  18. Veldhuis, G.; van Wermeskerken, F.; Visker, O.; Steinmann, P.; Deuten, S.; van Waas, R. From Data to Model Structure: A Generative Algorithm to Develop System Dynamics Models. SSRN 2024. Available online: https://ssrn.com/abstract=4921086 (accessed on 1 April 2026).
  19. Giabbanelli, P.J.; Gandee, T.J.; Agrawal, A.; Hosseinichimeh, N. Benchmarking and Assessing Transformations Between Text and Causal Maps via Large Language Models. Appl. Ontol. 2025, 20, 125–134. [Google Scholar] [CrossRef] [Scilit]
  20. Verduzco, J.C.; Holbrook, E.; Strachan, A. GPT-4 as an interface between researchers and computational software: Improving usability and reproducibility. arXiv 2023, arXiv:2310.11458. [Google Scholar] [CrossRef] [Scilit]
  21. Méndez, G.; Gervás, P. Using ChatGPT for story sifting in narrative generation. In Proceedings of the 14th International Conference on Computational Creativity, Waterloo, ON, Canada, 19–23 June 2023. [Google Scholar]
  22. Aoki, N.; Mori, N.; OKada, M. Analysis of LLM-based narrative generation using the agent-based simulation. In Proceedings of the 2023 15th International Congress on Advanced Applied Informatics Winter (IIAI-AAI-Winter); IEEE: New York, NY, USA, 2023; pp. 284–289. [Google Scholar]
  23. Achter, S.; Borit, M.; Cottineau, C.; Meyer, M.; Polhill, J.G.; Radchuk, V. How to conduct more systematic reviews of agent-based models and foster theory development-Taking stock and looking ahead. Environ. Model. Softw. 2024, 173, 105867. [Google Scholar] [CrossRef] [Scilit]
  24. DeAngelis, D.L.; Diaz, S.G. Decision-making in agent-based modeling: A current review and future prospectus. Front. Ecol. Evol. 2019, 6, 237. [Google Scholar] [CrossRef] [Scilit]
  25. Bianchi, F.; Squazzoni, F. Agent-based models in sociology. Wiley Interdiscip. Rev. Comput. Stat. 2015, 7, 284–306. [Google Scholar] [CrossRef] [Scilit]
  26. Qiu, L.; Phang, R. Agent-Based Modeling in Political Decision Making. In Oxford Research Encyclopedia of Politics; Oxford Academic: Oxford, UK, 2020. [Google Scholar]
  27. Lee, J.S.; Filatova, T.; Ligmann-Zielinska, A.; Hassani-Mahmooei, B.; Stonedahl, F.; Lorscheid, I.; Voinov, A.; Polhill, J.G.; Sun, Z.; Parker, D.C. The complexities of agent-based modeling output analysis. J. Artif. Soc. Soc. Simul. 2015, 18, 4. [Google Scholar] [CrossRef] [Scilit]
  28. An, L.; Grimm, V.; Turner, B.L., II. Meeting grand challenges in agent-based models. J. Artif. Soc. Soc. Simul. 2020, 23, 13. [Google Scholar] [CrossRef] [Scilit]
  29. Papadopoulou, L.; McEntaggart, K.; Etienne, J. Communicating Scientific Uncertainty in Advice Provision to Decision-Makers: Review of Approaches and Recommendations for UK Statutory Nature Conservation Bodies; JNCC Report No. 617; Joint Nature Conservation Committee: Peterborough, UK, 2018. Available online: https://data.jncc.gov.uk/data/7ade8ea1-c616-4bc1-ac0d-b8c2fb9d1d6e/JNCC-Report-617-FINAL-WEB.pdf (accessed on 11 March 2026).
  30. Sun, Z.; Lorscheid, I.; Millington, J.D.; Lauf, S.; Magliocca, N.R.; Groeneveld, J.; Balbi, S.; Nolzen, H.; Müller, B.; Schulze, J.; et al. Simple or complicated agent-based models? A complicated issue. Environ. Model. Softw. 2016, 86, 56–67. [Google Scholar] [CrossRef] [Scilit]
  31. Giabbanelli, P.J.; Daumas, C.; Flandre, N.Y.; Pitkar, A.; Vazquez-Estrada, J. Promoting empathy in decision-making by turning agent-based models into stories using large-language models. J. Simul. 2025, 1–21. [Google Scholar] [CrossRef] [Scilit]
  32. Grimm, V.; Railsback, S.F.; Vincenot, C.E.; Berger, U.; Gallagher, C.; DeAngelis, D.L.; Edmonds, B.; Ge, J.; Giske, J.; Groeneveld, J.; et al. The ODD protocol for describing agent-based and other simulation models: A second update to improve clarity, replication, and structural realism. J. Artif. Soc. Soc. Simul. 2020, 23, 7. [Google Scholar] [CrossRef] [Scilit]
  33. Müller, B.; Bohn, F.; Dreßler, G.; Groeneveld, J.; Klassert, C.; Martin, R.; Schlüter, M.; Schulze, J.; Weise, H.; Schwarz, N. Describing human decisions in agent-based models–ODD+ D, an extension of the ODD protocol. Environ. Model. Softw. 2013, 48, 37–48. [Google Scholar] [CrossRef] [Scilit]
  34. Laatabi, A.; Marilleau, N.; Nguyen-Huu, T.; Hbid, H.; Ait Babram, M. ODD+ 2D: An ODD based protocol for mapping data to empirical ABMs. J. Artif. Soc. Soc. Simul. 2018, 21, 9. [Google Scholar] [CrossRef] [Scilit]
  35. Achter, S.; Borit, M.; Chattoe-Brown, E.; Siebers, P.O. RAT-RS: A reporting standard for improving the documentation of data use in agent-based modelling. Int. J. Soc. Res. Methodol. 2022, 25, 517–540. [Google Scholar] [CrossRef] [Scilit]
  36. Monks, T.; Currie, C.S.; Onggo, B.S.; Robinson, S.; Kunc, M.; Taylor, S.J. Strengthening the reporting of empirical simulation studies: Introducing the STRESS guidelines. J. Simul. 2019, 13, 55–67. [Google Scholar] [CrossRef] [Scilit]
  37. Giabbanelli, P.J.; Tison, B.; Keith, J. The application of modeling and simulation to public health: Assessing the quality of agent-based models for obesity. Simul. Model. Pract. Theory 2021, 108, 102268. [Google Scholar] [CrossRef] [Scilit]
  38. Hall, A.; Virrantaus, K. Visualizing the workings of agent-based models: Diagrams as a tool for communication and knowledge acquisition. Comput. Environ. Urban Syst. 2016, 58, 1–11. [Google Scholar] [CrossRef] [Scilit]
  39. Szangolies, L.; Rohwäder, M.S.; Ahmed, H.; Jahanmiri, F.; Wagner, A.; Souto-Veiga, R.; Grimm, V.; Gallagher, C. Visual ODD: A Standardised Visualisation Illustrating the Narrative of Agent-Based Models. J. Artif. Soc. Soc. Simul. 2024, 27, 1. [Google Scholar] [CrossRef] [Scilit]
  40. Dorin, A.; Geard, N. The practice of agent-based model visualization. Artif. Life 2014, 20, 271–289. [Google Scholar] [CrossRef] [Scilit]
  41. Kornhauser, D.; Wilensky, U.; Rand, W. Design guidelines for agent based model visualization. J. Artif. Soc. Soc. Simul. 2009, 12, 1. [Google Scholar]
  42. Vandin, A.; Giachini, D.; Lamperti, F.; Chiaromonte, F. Automated and distributed statistical analysis of economic agent-based models. J. Econ. Dyn. Control 2022, 143, 104458. [Google Scholar] [CrossRef] [Scilit]
  43. Hooten, M.; Wikle, C.; Schwob, M. Statistical implementations of agent-based demographic models. Int. Stat. Rev. 2020, 88, 441–461. [Google Scholar] [CrossRef] [Scilit]
  44. Gürcan, Ö. Llm-augmented agent-based modelling for social simulations: Challenges and opportunities. In HHAI 2024: Hybrid Human AI Systems for the Social Good; IOS Press: Amsterdam, The Netherlands, 2024; pp. 134–144. [Google Scholar]
  45. Ferraro, A.; Galli, A.; La Gatta, V.; Postiglione, M.; Orlando, G.M.; Russo, D.; Riccio, G.; Romano, A.; Moscato, V. Agent-Based Modelling Meets Generative AI in Social Network Simulations. In Proceedings of the International Conference on Advances in Social Networks Analysis and Mining; Springer: Berlin/Heidelberg, Germany, 2024; pp. 155–170. [Google Scholar]
  46. Zhong, S.; Japkowicz, N.; Giabbanelli, P. Do we Still Need People? Comparing Human and LLM Personas in Political Modeling and Simulation. In Proceedings of the 2025 ACM/IEEE 28th International Conference on Model Driven Engineering Languages and Systems Companion (MODELS-C); IEEE: New York, NY, USA, 2025; pp. 512–521. [Google Scholar]
  47. Ghaffarzadegan, N.; Majumdar, A.; Williams, R.; Hosseinichimeh, N. Generative agent-based modeling: An introduction and tutorial. Syst. Dyn. Rev. 2024, 40, e1761. [Google Scholar] [CrossRef] [Scilit]
  48. Larooij, M.; Törnberg, P. Validation is the central challenge for generative social simulation: A critical review of LLMs in agent-based modeling. Artif. Intell. Rev. 2025, 59, 15. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  49. Acharya, D.B.; Kuppan, K.; Divya, B. Agentic AI: Autonomous Intelligence for Complex Goals–A Comprehensive Survey. IEEE Access 2025, 13, 18912–18936. [Google Scholar] [CrossRef] [Scilit]
  50. Padilla, J.J.; Shuttleworth, D.; O’Brien, K. Agent-based model characterization using natural language processing. In Proceedings of the 2019 Winter Simulation Conference (WSC); IEEE: New York, NY, USA, 2019; pp. 560–571. [Google Scholar]
  51. Shuttleworth, D.; Padilla, J.J. Towards semi-automatic model specification. In Proceedings of the 2021 Winter Simulation Conference (WSC); IEEE: New York, NY, USA, 2021; pp. 1–12. [Google Scholar]
  52. Khatami, S. AI-Enhanced ABM Development: Facilitating Agent-Based Modeling Using Artificial Intelligence. Ph.D. Thesis, Norwegian University of Science and Technology, Trondheim, Norway, 2025. [Google Scholar]
  53. Davis, C.W.; Jetter, A.J.; Giabbanelli, P.J. Towards an Automatic Construction of Simulation Scenarios: A Systematic Review. In Proceedings of the 2023 Winter Simulation Conference (WSC); IEEE: New York, NY, USA, 2023; pp. 2494–2505. [Google Scholar]
  54. Martínez, J.; Llinas, B.; Botello, J.G.; Padilla, J.J.; Frydenlund, E. Enhancing GPT-3.5’s Proficiency in Netlogo Through Few-Shot Prompting and Retrieval-Augmented Generation. In Proceedings of the 2024 Winter Simulation Conference (WSC); IEEE: New York, NY, USA, 2024; pp. 666–677. [Google Scholar]
  55. Frydenlund, E.; Martínez, J.; Padilla, J.J.; Palacio, K.; Shuttleworth, D. Modeler in a box: How can large language models aid in the simulation modeling process? Simulation 2024, 100, 727–749. [Google Scholar] [CrossRef] [Scilit]
  56. Akhavan, A.; Jalali, M.S. Generative AI and simulation modeling: How should you (not) use large language models like ChatGPT. Syst. Dyn. Rev. 2024, 40, e1773. [Google Scholar] [CrossRef] [Scilit]
  57. Jackson, I.; Rolf, B. Do Natural Language Processing models understand simulations? Application of GPT-3 to translate simulation source code to English. IFAC-Pap. 2023, 56, 221–226. [Google Scholar] [CrossRef] [Scilit]
  58. Zhang, H.; Yu, P.S.; Zhang, J. A systematic survey of text summarization: From statistical methods to large language models. ACM Comput. Surv. 2025, 57, 277. [Google Scholar] [CrossRef] [Scilit]
  59. Koh, H.Y.; Ju, J.; Liu, M.; Pan, S. An empirical survey on long document summarization: Datasets, models, and metrics. ACM Comput. Surv. 2022, 55, 154. [Google Scholar] [CrossRef] [Scilit]
  60. Miller, D. Leveraging BERT for extractive text summarization on lectures. arXiv 2019, arXiv:1906.04165. [Google Scholar] [CrossRef] [Scilit]
  61. Gandee, T.J.; Giabbanelli, P.J. Faithful Narratives from Complex Conceptual Models: Should Modelers or Large Language Models Simplify Causal Maps? Mach. Learn. Knowl. Extr. 2025, 7, 116. [Google Scholar] [CrossRef] [Scilit]
  62. Beltagy, I.; Peters, M.E.; Cohan, A. Longformer: The long-document transformer. arXiv 2020, arXiv:2004.05150. [Google Scholar] [CrossRef] [Scilit]
  63. Raffel, C.; Shazeer, N.; Roberts, A.; Lee, K.; Narang, S.; Matena, M.; Zhou, Y.; Li, W.; Liu, P.J. Exploring the limits of transfer learning with a unified text-to-text transformer. J. Mach. Learn. Res. 2020, 21, 140. [Google Scholar]
  64. Xia, T.C.; Bertini, F.; Montesi, D. Large Language Models Evaluation for PubMed Extractive Summarisation. ACM Trans. Comput. Healthc. 2026, 7, 4. [Google Scholar] [CrossRef] [Scilit]
  65. Gunnu, V.; Shah, S.; Minukuri, A.; Gopu, J. Text Summarization. In Practical Solutions for Modern NLP Challenges: Mastering LLMs and SLMs for Real-World NLP in Cloud and Open-Source; Springer: Berlin/Heidelberg, Germany, 2026; pp. 281–323. [Google Scholar]
  66. August, T.; Lo, K.; Smith, N.A.; Reinecke, K. Know Your Audience: The benefits and pitfalls of generating plain language summaries beyond the “general” audience. In Proceedings of the 2024 CHI Conference on Human Factors in Computing Systems, Honolulu, HI, USA, 11–16 May 2024; pp. 1–26. [Google Scholar]
  67. Giabbanelli, P.J.; Agrawal, A. Towards Personalized Explanations for Health Simulations: A Mixed-Methods Framework for Stakeholder-Centric Summarization. In Proceedings of the AAAI Symposium Series; AAAI: Washington, DC, USA, 2025; Volume 7, pp. 506–515. [Google Scholar]
  68. National Academies of Sciences, Engineering, and Medicine. Executive Summary. In Modeling Human and Organizational Behavior: Application to Military Simulations; The National Academies Press: Washington, DC, USA, 1998. [Google Scholar] [CrossRef] [Scilit]
  69. National Academies of Sciences, Engineering, and Medicine. Executive Summary. In Behavioral Modeling and Simulation: From Individuals to Societies; The National Academies Press: Washington, DC, USA, 2008. [Google Scholar] [CrossRef] [Scilit]
  70. Kho, V. McKinsey Executive Summaries: Short but Powerful. Writ. Univ. Beyond J. First-Year Stud. Writ. UTM 2022, 2, 87–95. [Google Scholar]
  71. Harvard Kennedy School. How to Write an Executive Summary. Writing Workshop with Lauren Brodsky, Communications Program, Harvard Kennedy School, Cambridge, MA, USA, 25 February 2026; Available online: https://www.hks.harvard.edu/events/how-write-executive-summary-0 (accessed on 11 March 2026).
  72. Naismith, B.; Mulcaire, P.; Burstein, J. Automated evaluation of written discourse coherence using GPT-4. In Proceedings of the 18th Workshop on Innovative Use of NLP for Building Educational Applications (BEA 2023), Toronto, ON, Canada, 13 July 2023; pp. 394–403. [Google Scholar]
  73. Moore, S.; Nguyen, H.A.; Chen, T.; Stamper, J. Assessing the quality of multiple-choice questions using gpt-4 and rule-based methods. In Proceedings of the European Conference on Technology Enhanced Learning; Springer: Berlin/Heidelberg, Germany, 2023; pp. 229–245. [Google Scholar]
  74. Fischer, T.; Remus, S.; Biemann, C. Measuring faithfulness of abstractive summaries. In Proceedings of the 18th Conference on Natural Language Processing (KONVENS 2022), Potsdam, Germany, 12–15 September 2022; pp. 63–73. [Google Scholar]
  75. Gatt, A.; Krahmer, E. Survey of the state of the art in natural language generation: Core tasks, applications and evaluation. J. Artif. Intell. Res. 2018, 61, 65–170. [Google Scholar] [CrossRef] [Scilit]
  76. Li, M.; Gao, Q.; Yu, T. Kappa statistic considerations in evaluating inter-rater reliability between two raters: Which, when and context matters. BMC Cancer 2023, 23, 799. [Google Scholar] [CrossRef] [Scilit]
  77. Raghavan, P.; Fosler-Lussier, E.; Lai, A.M. Inter-annotator reliability of medical events, coreferences and temporal relations in clinical narratives by annotators with varying levels of clinical expertise. In Proceedings of the AMIA Annual Symposium, Chicago, IL, USA, 3–7 November 2012; p. 1366. [Google Scholar]
  78. van Schaik, T.A.; Pugh, B. A field guide to automatic evaluation of llm-generated summaries. In Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval, Washington, DC, USA, 14–18 July 2024; pp. 2832–2836. [Google Scholar]
  79. Papineni, K.; Roukos, S.; Ward, T.; Zhu, W.J. Bleu: A method for automatic evaluation of machine translation. In Proceedings of the 40th annual meeting of the Association for Computational Linguistics, Philadelphia, PA, USA, 6–12 July 2002; pp. 311–318. [Google Scholar]
  80. Chin-Yew, L. Rouge: A package for automatic evaluation of summaries. In Proceedings of the Workshop on Text Summarization Branches Out, Barcelona, Spain, 25–26 July 2004; pp. 74–81. [Google Scholar]
  81. Myla, S.D.; Saini, E.R.; Kapoor, E.N. Auto Text Summarization in Natural Language Processing. In Proceedings of the 2024 2nd International Conference on Intelligent Data Communication Technologies and Internet of Things (IDCIoT); IEEE: New York, NY, USA, 2024; pp. 1258–1267. [Google Scholar]
  82. Caparrós-Laiz, C.; García-Díaz, J.A.; Valencia-García, R. Evaluating extractive automatic text summarization techniques in spanish. In Proceedings of the International Conference on Technologies and Innovation; Springer: Berlin/Heidelberg, Germany, 2021; pp. 79–92. [Google Scholar]
  83. Roy, S.S.; Mercer, R.E. Generating extractive and abstractive summaries in parallel from scientific articles incorporating citing statements. In Proceedings of the 4th New Frontiers in Summarization Workshop, Singapore, 6–10 December 2023; pp. 75–86. [Google Scholar]
  84. Guo, Y.; Qiu, W.; Wang, Y.; Cohen, T. Automated lay language summarization of biomedical scientific reviews. In Proceedings of the AAAI Conference on Artificial Intelligence; AAAI: Washington, DC, USA, 2021; Volume 35, pp. 160–168. [Google Scholar]
  85. Cooperman, S.R.; Brandão, R.A. Investigating the proficiency of an AI tool in summarizing foot and ankle literature: A quantitative, qualitative and accuracy analysis. Foot Ankle Surg. Tech. Rep. Cases 2024, 4, 100384. [Google Scholar] [CrossRef] [Scilit]
  86. Wang, Z.; Xu, G.; Ren, M. LLM-Generated Natural Language Meets Scaling Laws: New Explorations and Data Augmentation Methods. arXiv 2024, arXiv:2407.00322. [Google Scholar] [CrossRef] [Scilit]
  87. Chen, B.; Zhang, Z.; Langrené, N.; Zhu, S. Unleashing the potential of prompt engineering for large language models. Patterns 2025, 6, 101260. [Google Scholar] [CrossRef] [Scilit]
  88. Schmidt, D.C.; Spencer-Smith, J.; Fu, Q.; White, J. Towards a catalog of prompt patterns to enhance the discipline of prompt engineering. ACM SIGAda Ada Lett. 2024, 43, 43–51. [Google Scholar] [CrossRef] [Scilit]
  89. Braun, M.; Greve, M.; Kegel, F.; Kolbe, L.M.; Beyer, P.E. Can (A)I have a word with you? A taxonomy on the design dimensions of AI prompts. In Proceedings of the 57th Annual Hawaii International Conference on System Sciences, HICSS 2024. Hawaii International Conference on System Sciences (HICSS), Honolulu, HI, USA, 3–6 January 2024; pp. 559–568. [Google Scholar]
  90. Memmert, L.; Cvetkovic, I.; Bittner, E. The more is not the merrier: Effects of prompt engineering on the quality of ideas generated by gpt-3. In Proceedings of the 57th Hawaii International Conference on System Sciences, Honolulu, HI, USA, 3–6 January 2024. [Google Scholar]
  91. Amini, R.; Norouzi, S.S.; Hitzler, P.; Amini, R. Towards complex ontology alignment using large language models. In Proceedings of the International Knowledge Graph and Semantic Web Conference; Springer: Berlin/Heidelberg, Germany, 2024; pp. 17–31. [Google Scholar]
  92. Gutschmidt, A.; Nast, B. Assessing Model Quality Using Large Language Models. In Proceedings of the IFIP Working Conference on The Practice of Enterprise Modeling; Springer: Berlin/Heidelberg, Germany, 2024; pp. 105–122. [Google Scholar]
  93. Saeedizade, M.J.; Blomqvist, E. Navigating ontology development with large language models. In Proceedings of the European Semantic Web Conference; Springer: Berlin/Heidelberg, Germany, 2024; pp. 143–161. [Google Scholar]
  94. Zhao, Y.; Vetter, N.; Aryan, K. Using large language models for ontoclean-based ontology refinement. arXiv 2024, arXiv:2403.15864. [Google Scholar]
  95. Sanchez, S.M.; Sanchez, P.J.; Wan, H. Work smarter, not harder: A tutorial on designing and conducting simulation experiments. In Proceedings of the 2020 Winter Simulation Conference (WSC); IEEE: New York, NY, USA, 2020; pp. 1128–1142. [Google Scholar]
  96. Sanchez, S.M. Robust design: Seeking the best of all possible worlds. In Proceedings of the 2000 Winter Simulation Conference Proceedings (Cat. No. 00ch37165); IEEE: New York, NY, USA, 2000; Volume 1, pp. 69–76. [Google Scholar]
  97. Stahl, M.; Biermann, L.; Nehring, A.; Wachsmuth, H. Exploring LLM prompting strategies for joint essay scoring and feedback generation. In Proceedings of the 19th Workshop on Innovative Use of NLP for Building Educational Applications (BEA 2024); Association for Computational Linguistics: Stroudsburg, PA, USA, 2024; pp. 283–298. [Google Scholar]
  98. Cuskley, C.; Woods, R.; Flaherty, M. The limitations of large language models for understanding human language and cognition. Open Mind 2024, 8, 1058–1083. [Google Scholar] [CrossRef] [Scilit]
  99. Abaskohi, A.; Ramesh, A.V.; Nanisetty, S.; Goel, C.; Vazquez, D.; Pal, C.; Gella, S.; Carenini, G.; Laradji, I.H. AgentAda: Skill-Adaptive Data Analytics for Tailored Insight Discovery. arXiv 2025, arXiv:2504.07421. [Google Scholar]
  100. Pérez, A.S.; Boukhary, A.; Papotti, P.; Lozano, L.C.; Elwood, A. An LLM-based approach for insight generation in data analysis. In Proceedings of the 2025 Conference of the Nations of the Americas Chapter of the Association for Computational Linguistics: Human Language Technologies; Association for Computational Linguistics: Stroudsburg, PA, USA, 2025; pp. 562–582. [Google Scholar]
  101. Liu, N.F.; Lin, K.; Hewitt, J.; Paranjape, A.; Bevilacqua, M.; Petroni, F.; Liang, P. Lost in the middle: How language models use long contexts. Trans. Assoc. Comput. Linguist. 2024, 12, 157–173. [Google Scholar] [CrossRef] [Scilit]
  102. Li, P.; He, Y.; Yashar, D.; Cui, W.; Ge, S.; Zhang, H.; Rifinski Fainman, D.; Zhang, D.; Chaudhuri, S. Table-gpt: Table fine-tuned gpt for diverse table tasks. Proc. Acm Manag. Data 2024, 2, 176. [Google Scholar] [CrossRef] [Scilit]
  103. Zhang, X.; Li, Y.; Wang, J.; Sun, B.; Ma, W.; Sun, P.; Zhang, M. Large language models as evaluators for recommendation explanations. In Proceedings of the 18th ACM Conference on Recommender Systems, Bari, Italy, 14–18 October 2024; pp. 33–42. [Google Scholar]
  104. Ni, J.; Pu, J.; Yang, Z.; Zhou, K.; Wang, H.; Xiao, X.; Wang, D.; Li, X.; Luo, J.; Hu, C. From large to super-tiny: End-to-end optimization for cost-efficient LLMs. arXiv 2025, arXiv:2504.13471. [Google Scholar]
  105. Chen, L.; Zaharia, M.; Zou, J. FrugalGPT: How to Use Large Language Models While Reducing Cost and Improving Performance. arXiv 2024, arXiv:2305.05176. [Google Scholar]
  106. Yue, M.; Zhao, J.; Zhang, M.; Du, L.; Yao, Z. Large Language Model Cascades with Mixture of Thoughts Representations for Cost-efficient Reasoning. In Proceedings of the International Conference on Learning Representations (ICLR), Vienna, Austria, 7–11 May 2024. [Google Scholar]
  107. Kopels, M.C.; Ullah, I.I. Modeling post-Pleistocene megafauna extinctions as complex social-ecological systems. Quat. Res. 2024, 121, 1–14. [Google Scholar] [CrossRef] [Scilit]
  108. Gibson, M.; Pereira, J.P.; Slade, R.; Rogelj, J. Agent-based modelling of future dairy and plant-based milk consumption for UK climate targets. J. Artif. Soc. Soc. Simul. 2022, 25, 3. [Google Scholar] [CrossRef] [Scilit]
  109. Dressler, G.; Groeneveld, J.; Buchmann, C.M.; Guo, C.; Hase, N.; Thober, J.; Frank, K.; Müller, B. Implications of behavioral change for the resilience of pastoral systems—Lessons from an agent-based model. Ecol. Complex. 2019, 40, 100710. [Google Scholar] [CrossRef] [Scilit]
  110. Arena. Arena AI Leaderboards. Consulted Leaderboards for Text and Vision Models. Available online: https://arena.ai/leaderboard (accessed on 4 March 2026).
  111. Google DeepMind. Gemini 3.1 Pro Model Card. 2026. Available online: https://deepmind.google/models/model-cards/gemini-3-1-pro/ (accessed on 11 March 2026).
  112. Artificial Analysis. Gemini 3.1 Pro Preview: The New Leader in AI. 2026. Available online: https://artificialanalysis.ai/articles/gemini-3-1-pro-preview-new-leader-in-ai (accessed on 11 March 2026).
  113. Moonshot AI. Kimi-K2.5. Hugging Face Model Card. 2026. Available online: https://huggingface.co/moonshotai/Kimi-K2.5 (accessed on 17 March 2026).
  114. Anthropic. Introducing Claude Opus 4.6. Product Announcement. 2026. Available online: https://www.anthropic.com/news/claude-opus-4-6 (accessed on 11 March 2026).
  115. Qwen Team. Qwen3.5-27B. Hugging Face Model Card. 2026. Available online: https://huggingface.co/Qwen/Qwen3.5-27B (accessed on 11 March 2026).
  116. Cheng, S.; Giabbanelli, P.J.; Kuang, Z. Identifying the Building Blocks of Social Simulation Models: A Qualitative Analysis using Open-Source Codes in NetLogo. In Proceedings of the 2023 Annual Modeling and Simulation Conference (ANNSIM); IEEE: New York, NY, USA, 2023; pp. 306–317. [Google Scholar]
  117. Freund, A.J.; Giabbanelli, P.J. Are we modeling the evidence or our own biases? A comparison of conceptual models created from reports. In Proceedings of the 2021 Annual Modeling and Simulation Conference (ANNSIM); IEEE: New York, NY, USA, 2021; pp. 1–12. [Google Scholar]
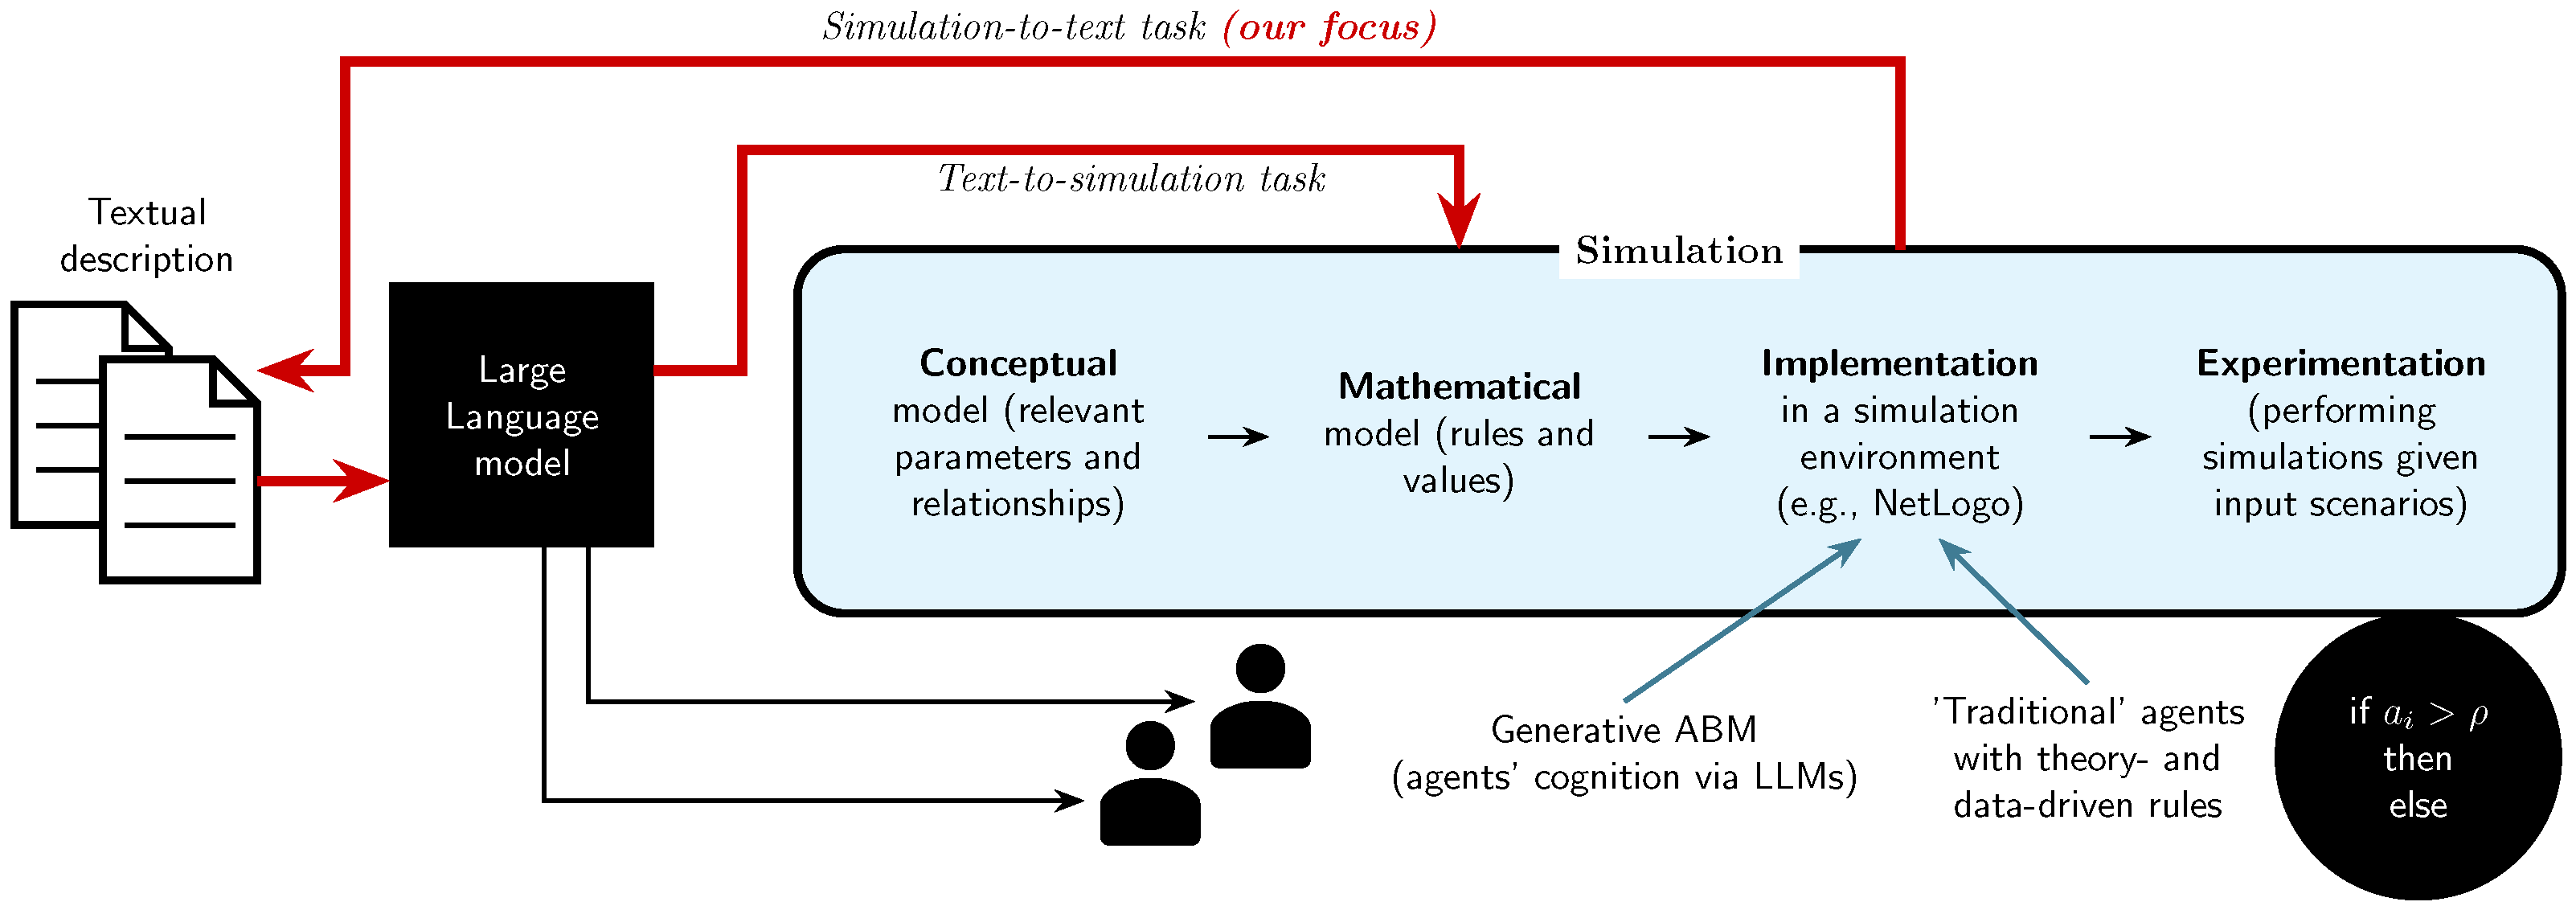
Figure 2. A simulation project consists of several stage, including conceptual modeling, mathematical modeling (i.e., formal specification), implementation, and experimentation. LLMs have been used at several of these stages, particularly to generate simulations from text or to replace the agents’ decision-making module. In this paper, we focus on simulation-to-text transformation.
Bdcc 10 00121 g002
Figure 3. Our procedure consists of three main parts. Each part is explained in turn in a dedicated subsection.
Bdcc 10 00121 g003
Figure 4. A NetLogo model is formed of three tabs: a front end (a), the code that we mine (b), and a documentation that we also mine (c). The code contains both the model logic (‘back end’) and the visuals (‘front end’) such as the location of sliders, their range, and default values. This example is from the Megafaunal Hunting Pressure Model, which is used in our experiments (Section 4.1).
Bdcc 10 00121 g004
Figure 5. Two plots automatically created from CSV files, where each line color correspond to one run of the simulation. They are stacked for a concise presentation in this paper only. Note that the plots do not necessarily have a monotonic increase or decrease; thus, their explanation in textual form and the ensuing summaries have to identify which inflections are worth discussing. These examples are from the Milk Adoption ABM, which is used in our experiments (Section 4.1).
Bdcc 10 00121 g005
Figure 6. We extracted several statistics (Table 1) for each aggregate plot, where each simulation run is shown as one colored line. This example shows the statistics extracted for the plot. When several statistics from the same type were derived, only the first one is shown in blue for brevity. In this example, we had four peaks and four valleys, eight inflections, six Mann–Kendall windows, and twelve oscillation indices.
Bdcc 10 00121 g006
Figure 7. Variance contribution of individual factors and pairs across lexical metrics from low contribution (light blue) to high contribution (dark blue). We only include rows showing significant effects (5% and above) while noting that complete analyses are available in our storage bucket. Results for readability are shown in Figure 8.
Bdcc 10 00121 g007
Figure 8. Variance contribution of individual factors and pairs for readability from low contribution (light blue) to high contribution (dark blue). We only include rows showing significant effects (5% and above).
Bdcc 10 00121 g008
Figure 9. Direct level-vs.-level dominance. Across the three configurations (Qwen, Kimi, Qwen and Kimi), we show the win rate and, below, the number of runs. For example, 0.67 (2/3) indicates that it won in two out of the three configurations.
Bdcc 10 00121 g009
Figure 10. Radar chart of LLM win-rate profiles across metrics in the optimization stage. Each axis is independently scaled to the nearest upper tenth above the best observed win rate for that metric, which is shown below the metric label. Larger radial extent indicates stronger relative dominance on that metric.
Bdcc 10 00121 g010
Figure 11. Performances of the four LLMs (Gemini 3.1 Pro Preview, Kimi K2.5, Claude Opus 4.6, and Qwen 3.5) on lexical-overlap metrics (BLEU, METEOR, ROUGE-1, ROUGE-2, ROUGE-L; left y-axis) and readability (right y-axis). Red crosses denote mean performance, blue triangles indicate maximum observed scores, and green circles indicate minimum observed scores. This visualization covers both central tendencies and variability in performance.
Bdcc 10 00121 g011
Figure 12. Performance of Claude Opus 4.6 across retained summarizers and ABMs. Each panel corresponds to one evaluation metric: (a) BLEU, (b) R-2, (c) METEOR, (d) R-L, (e) R-1, (f) reading ease. Bars show mean scores across repetitions and error bars indicate standard deviations. Within each summarizer, the three ABMs are shown side by side to facilitate a direct comparison of domain effects while keeping metric scales consistent within each panel. Results on all four LLMs are provided in our storage bucket.
Bdcc 10 00121 g012
Table 1. Summary of statistical features extracted from the simulation time series.
FeaturePurposeMethodLibraryOutput
Descriptive statisticsSummarize global properties of the signalDirect statistical computationNumPy/PythonMean, median, variance, standard deviation, min/max values and indices, start/end value, counts of valid/dropped samples
Peaks (local maxima)Identify salient positive eventsPeak detection using
neighbor comparison and prominence estimation
scipy.signalIndices and values of peaks, with prominence
Valleys (local minima)Identify salient negative eventsPeak detection applied to the negated signalscipy.signalIndices and values of valleys, with prominence
Inflection pointsDetect changes in curvature of the signalSavitzky–Golay filtering
and second-derivative
sign analysis
scipy.signalIndices where the second derivative changes sign
Local trendsDetermine monotonic behavior in short segmentsRolling Mann–Kendall trend test with Sen’s slope estimatorpymannkendallStart/end, Trend label, Kendall’s τ , Sen’s slope, p-value, significance flag
Change pointsDetect structural regime shifts in the signalPELT change-point
detection algorithm
rupturesIndices marking boundaries between statistical regimes
Oscillatory regimesIdentify periodic behavior and dominant cyclesContinuous Wavelet Transform (Morlet wavelet)pywt (PyWavelets)Dominant oscillation
period and indices where oscillation occurs
Table 2. Python libraries used including their role in our method.
PartUsePython Library
Data ExtractionRun simulation; export repeated runspynetlogo (0.5.2), pandas (2.2.3)
Extract parameters, docs, and code from NetLogo filesre, json, xml.etree.ElementTree (3.12.2)
Report GenerationPlot repeated-simulation datapandas (2.2.3), matplotlib (3.10.5)
Build statistical table evidencescipy (1.15.2), PyWavelets (1.8.0)
Generate explanationsopenai (2.15.0)
Convert images to base64base64 (3.12.2)
Combine prompt features and sweep settingsitertools (3.12.2)
Summarize source texttransformers (4.49.0), torch (2.10.0), sentencepiece (0.2.1), bert-extractive-summarizer (0.10.1)
EvaluationText/reference scoringnltk (3.8.1), rouge_score (0.1.2), textstat (0.7.7)
DoE/ANOVA analysispandas (2.2.3), scipy (1.15.2), statsmodels (0.14.2)
Table 3. p-value from a one-way ANOVA between our six experimental variables (including the three dynamic prompt elements in the bottom rows) and our six quantitative metrics, where ‘R’ denotes ROUGE. Statistically significant p-values are shown in green; others are shown in red.
Reference FamilyVariable/MetricBLEUMETEORR-1R-2R-LReading Ease
authorAgent-based model<0.01<0.01<0.01<0.01<0.01<0.01
authorSummarization algorithm<0.01<0.01<0.01<0.01<0.01<0.01
authorSimulation evidence0.050.71<0.01<0.01<0.01<0.01
authorLLM<0.01<0.010.02<0.01<0.01<0.01
authorUse of roles<0.01<0.01<0.01<0.01<0.010.74
authorGenerating insights0.680.480.02<0.01<0.01<0.01
authorProviding examples0.430.050.110.180.65<0.01
long LLMAgent-based model<0.010.74<0.01<0.01<0.01<0.01
long LLMSummarization algorithmN/AN/AN/AN/AN/AN/A
long LLMSimulation evidence<0.01<0.01<0.01<0.01<0.01<0.01
long LLMLLM<0.01<0.01<0.01<0.01<0.01<0.01
long LLMUse of roles<0.01<0.01<0.01<0.01<0.010.94
long LLMGenerating insights0.010.07<0.01<0.01<0.01<0.01
long LLMProviding examples0.84<0.010.270.560.80<0.01
short LLMAgent-based model<0.01<0.01<0.01<0.01<0.01<0.01
short LLMSummarization algorithm<0.01<0.01<0.01<0.01<0.01<0.01
short LLMSimulation evidence0.840.64<0.01<0.01<0.01<0.01
short LLMLLM<0.01<0.01<0.01<0.01<0.01<0.01
short LLMUse of roles<0.010.22<0.01<0.01<0.010.74
short LLMGenerating insights0.580.050.80<0.01<0.01<0.01
short LLMProviding examples0.720.060.020.510.15<0.01
modelerAgent-based model<0.01<0.01<0.01<0.01<0.01<0.01
modelerSummarization algorithm<0.01<0.01<0.01<0.01<0.01<0.01
modelerSimulation evidence0.080.300.16<0.01<0.01<0.01
modelerLLM<0.01<0.01<0.010.520.08<0.01
modelerUse of roles<0.010.770.02<0.01<0.010.74
modelerGenerating insights0.910.430.13<0.01<0.01<0.01
modelerProviding examples0.900.200.280.550.90<0.01
Table 4. Retained vs. discarded factor levels after cross-run screening analyses. Decisions are based on aggregated ANOVA significance rates, factorial involvement shares, and cross-run level dominance comparisons.
FactorRetained Level (s)Discarded Level (s)Rationale
EvidenceplotTable, plot + tableDominates lexical metrics across runs; most consistent winner
ExampleTrueFalseSystematically improves BLEU and ROUGE metrics
InsightsFalseTrueTurning insights off improves most lexical metrics and readability
RoleFalseTrueRole instructions reduce performance in most comparisons
SummarizerBERT, BART, T5longformer_extBERT wins overlap metrics; T5 wins readability; BART wins R-L
Table 5. Number of factual errors (#errors) and issues in a sample of summaries selected across combinations of LLMs, ABMs, extractive/abstractive summarizer, and other prompt parameters.
LLMABMPromptSummarizer#errorsNotes
ClaudeFaunaPlot, ExamplesBERT5Lacks transitions between trend descriptions. Abrupt transitions from describing one graph to another, which confuses the reader regarding which metric is described. Overestimates some values or ticks. The report describes variable per variable rather than chronology. The report is overall very accurate but omits details.
GrazingBART1Confuses some values set to certain metrics. There is more consistency in the way metrics are introduced or the way transitions are made. Sentences make sense and the reader does not become confused regarding which metric is being described. It is better self-contained even though it misses some information. A bit too concise.
GeminiMilkT52Very short report, missing a lot of information. Misses some numbers and lacks clarity on the exact metrics described.
Poor transitions.
FaunaBERT5Many numbers missing. Many parameter values wrongly reported. Overestimates some values.
QwenGrazingPlot + TableBART0Very short and not informative enough. Omits a vast amount of information. Its formulations and trend descriptions do not fully support understanding.
MilkTable, Insights,
role
LongFormer1Juxtaposition of sentences which makes it really hard to understand and contextualize which metric is being described. Poor coherence and narrative. The report is very short and not very informative.
KimiFaunaPlot + Table,
Insights, role
BERT7Some numbers missing. Hallucinated the number of simulations. Describes the trend of a metric without ever mentioning that metric, thus confusing the reader in thinking it still talks about the previous metric. Abrupt transitions.
GrazingTable, Examples,
insights, role
T54Imprecise on the specific metrics described. Does not present the parameters. Omits information. Describes the trend of a metric without ever mentioning that metric, thus confusing the reader by thinking it is still talks about the previous metric.
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.